Journal Description
Future Internet
Future Internet
is an international, peer-reviewed, open access journal on internet technologies and the information society, published monthly online by MDPI.
- Open Access— free for readers, with article processing charges (APC) paid by authors or their institutions.
- High Visibility: indexed within Scopus, ESCI (Web of Science), Ei Compendex, dblp, Inspec, and other databases.
- Journal Rank: JCR - Q2 (Computer Science, Information Systems) / CiteScore - Q1 (Computer Networks and Communications)
- Rapid Publication: manuscripts are peer-reviewed and a first decision is provided to authors approximately 15 days after submission; acceptance to publication is undertaken in 3.7 days (median values for papers published in this journal in the first half of 2026).
- Recognition of Reviewers: Reviewers whose reports are timely and of high quality receive an APC discount voucher for a future publication in an MDPI journal. Become a reviewer.
- Journal Clusters of Network and Communications Technology: Future Internet, IoT, Telecom, Journal of Sensor and Actuator Networks, Network, Signals.
Impact Factor:
4.6 (2025);
5-Year Impact Factor:
3.9 (2025)
Latest Articles
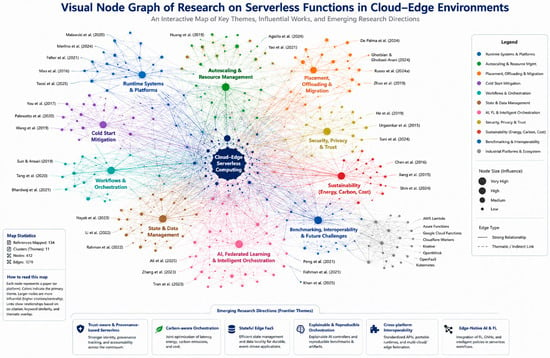
Serverless Functions in Cloud–Edge Environments: A Comprehensive Critical Review and Taxonomy
Future Internet 2026, 18(9), 496; https://doi.org/10.3390/fi18090496 (registering DOI) - 20 Sep 2026
Abstract
Cloud–edge continuums are driving the shift of cloud-native applications from centralized data centers to latency-, mobility-, privacy-, and energy-saving applications. The serverless architecture provides an attractive “Function-as-a-Service” (FaaS) model in this transition, as it is driven by events, elastic and fine-grained, and controlled
[...] Read more.
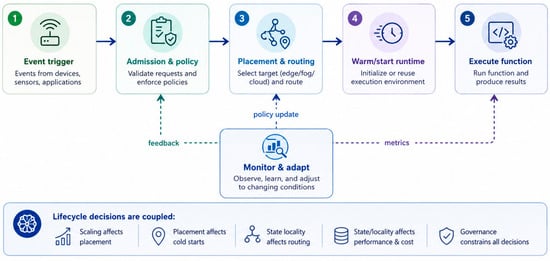
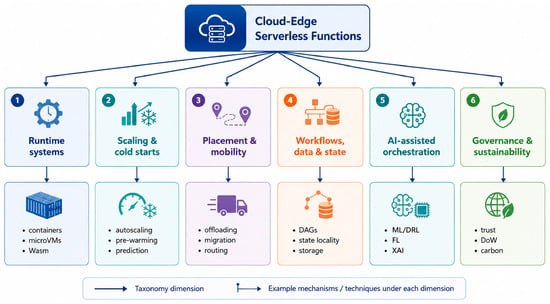
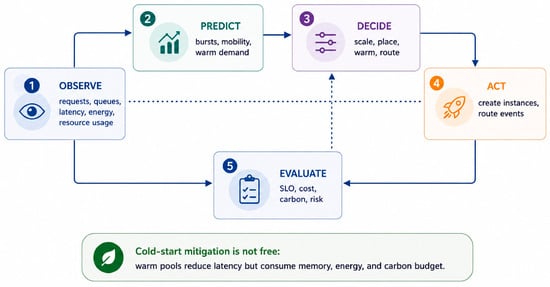
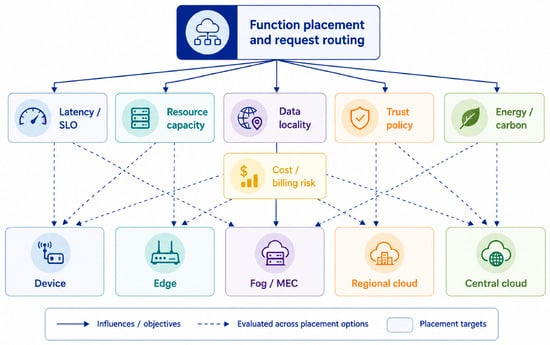
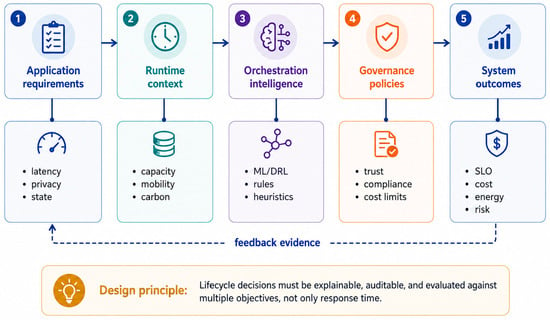
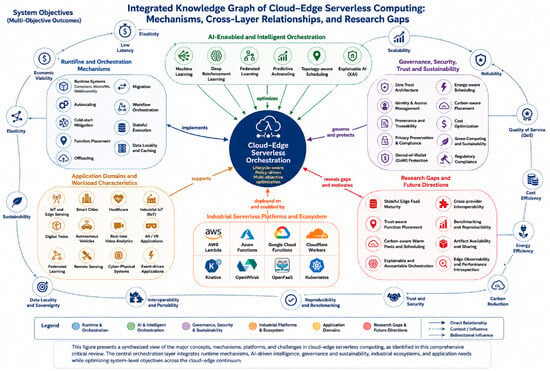
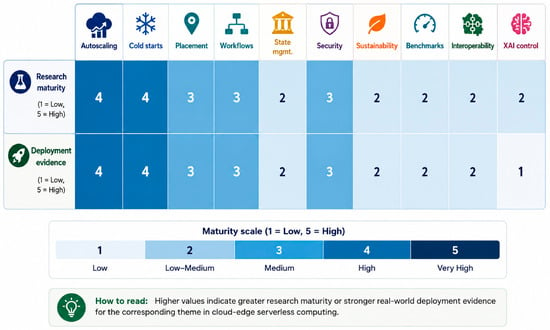
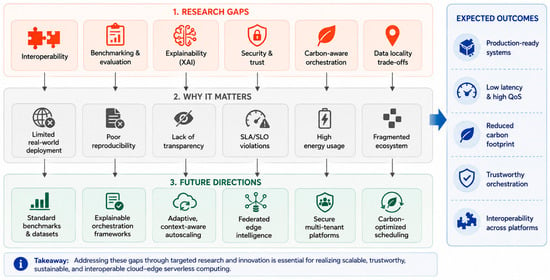
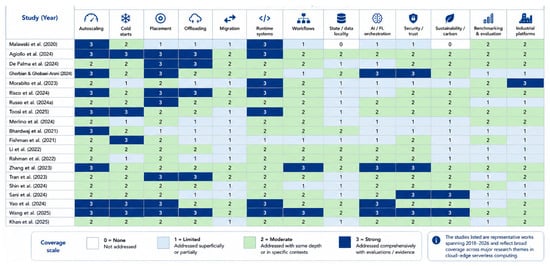
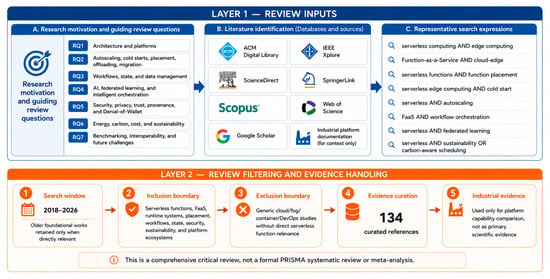
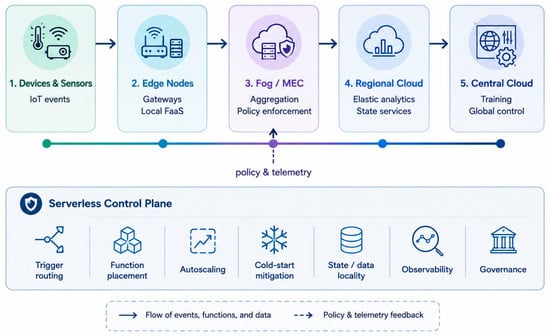
Cloud–edge continuums are driving the shift of cloud-native applications from centralized data centers to latency-, mobility-, privacy-, and energy-saving applications. The serverless architecture provides an attractive “Function-as-a-Service” (FaaS) model in this transition, as it is driven by events, elastic and fine-grained, and controlled by the platform. But introducing a mix of heterogeneous edge nodes, fog/MEC resources, regional clouds, and hyperscale data centers creates a seemingly simple FaaS deployment problem to solve with a set of multi-objective orchestration challenges: runtime selection, autoscaling, cold start mitigation, placement, migration, workflow coordination, state management, trust, cost, energy, and carbon. In this article, we provide an extensive critical review of serverless functions in cloud–edge environments. While some surveys are narrowly focused on aspects of autoscaling, offloading, IoT, or security, the review brings together architectural evolution, runtime mechanisms, platform ecosystems, governance issues, sustainability issues, and emerging applications using AI. It builds a multidimensional taxonomy ranging from runtime systems, autoscaling, cold start mitigation, function placement, and offloading/migration, to workflow orchestration, state and data management, intelligent scheduling, security, sustainability, and industrial serverless platforms. It also presents a built-in conceptual model that connects application needs, runtime environment, orchestration intelligence, governance policies, and system-level results. The synthesis reveals that cloud–edge serverless systems need accountable placement, state-aware workflows, reproducible benchmarking, trustworthy orchestration, and carbon-aware lifecycle control, which can be achieved only by going beyond latency and elasticity. The paper ends with research directions on adaptive, interoperable, explainable, and sustainable serverless systems on the cloud–edge continuum.
Full article
(This article belongs to the Special Issue Distributed, Cloud, Edge, and Fog Computing in Next-Generation Wireless Networks)
►
Show Figures
Open AccessArticle
HFS-SVE: A Hybrid Feature Selection and Soft Voting Ensemble for Android Malware Detection
by
Hany F. Atlam and Samyak M. Jeevane
Future Internet 2026, 18(9), 495; https://doi.org/10.3390/fi18090495 (registering DOI) - 20 Sep 2026
Abstract
Android malware continues to evolve in complexity, creating challenges for detection systems that must distinguish malicious applications from increasingly heterogeneous benign applications. Although machine learning provides effective mechanisms for learning malware characteristics, the high dimensionality of Android malware datasets can introduce redundant and
[...] Read more.
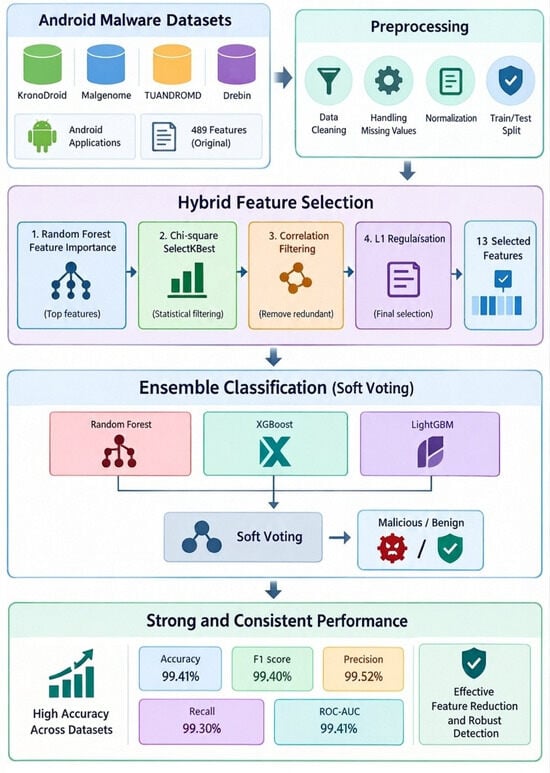
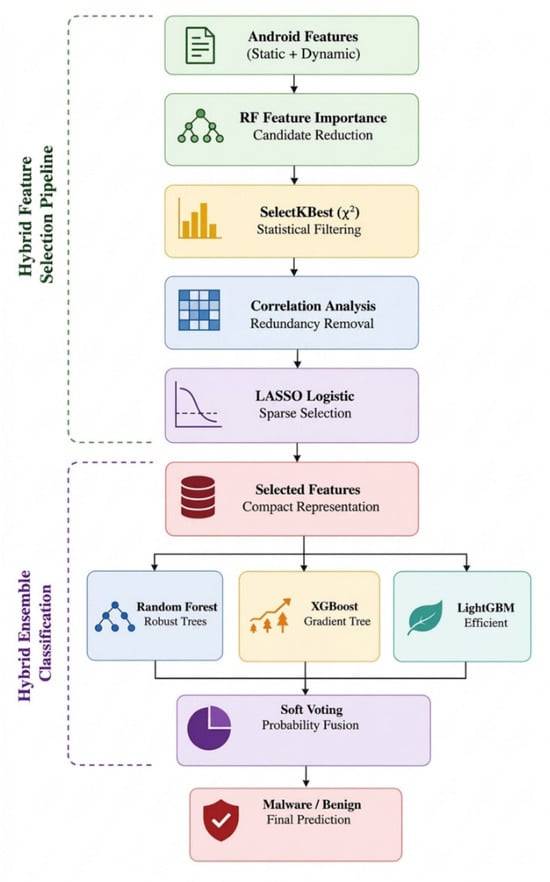
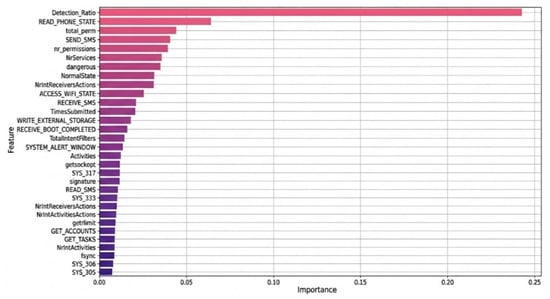
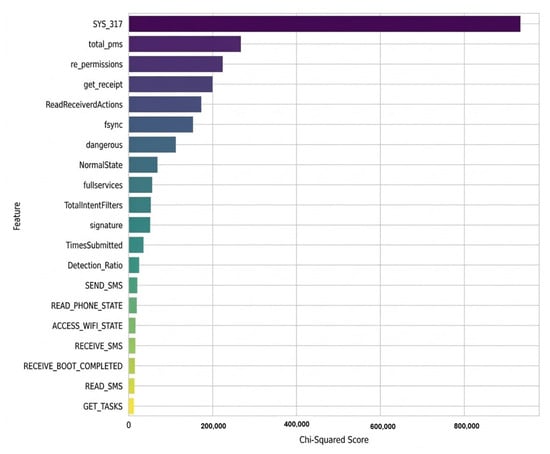
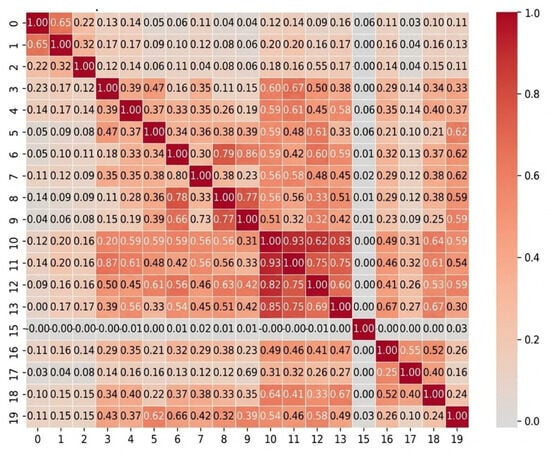
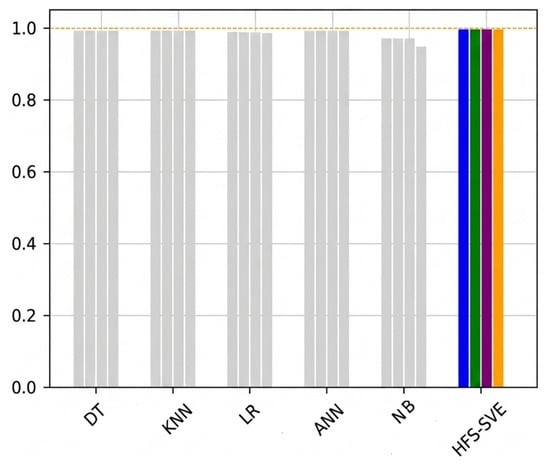
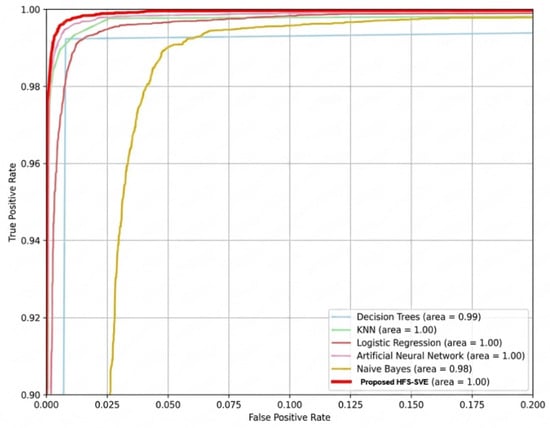
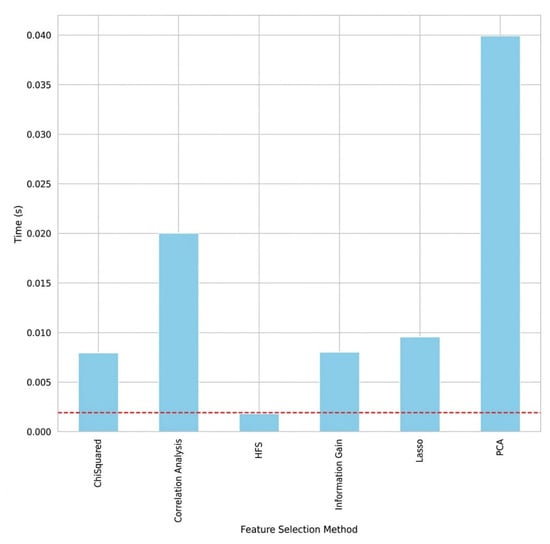
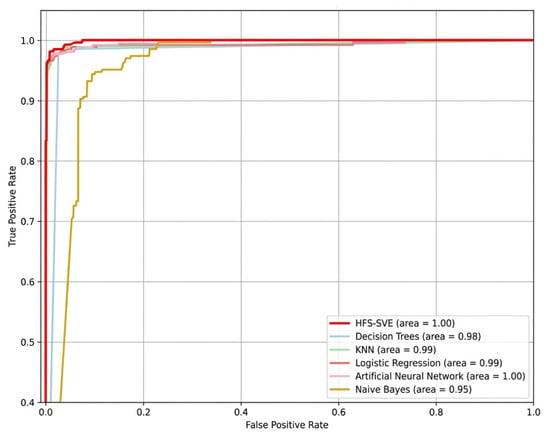
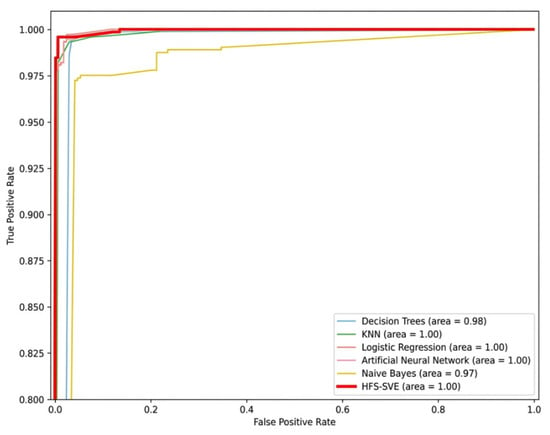
Android malware continues to evolve in complexity, creating challenges for detection systems that must distinguish malicious applications from increasingly heterogeneous benign applications. Although machine learning provides effective mechanisms for learning malware characteristics, the high dimensionality of Android malware datasets can introduce redundant and weakly informative features and increase computational requirements. To address this problem, this paper proposes a Hybrid Feature Selection and Soft-Voting Ensemble (HFS-SVE) framework that integrates complementary feature-selection and ensemble-learning strategies. The proposed framework sequentially applies Random Forest (RF) feature importance, Chi-square-based SelectKBest, correlation filtering, and L1 regularisation, reducing the original 489-feature representation to 13 selected features. These features are subsequently classified using RF, XGBoost, and LightGBM, whose probability outputs are combined through soft voting. Experimental results on the KronoDroid dataset demonstrate that the proposed HFS-SVE achieves 99.41% accuracy, 99.52% precision, 99.30% recall, 99.40% F1-score, and 99.41% ROC-AUC. The proposed framework also records the lowest measured detection time among the evaluated feature-selection strategies. Cross-dataset evaluation on Malgenome, TUANDROMD, and Drebin achieves accuracy above 98% on each dataset. The findings demonstrate that the proposed HFS-SVE can combine substantial feature-space reduction with strong Android malware detection performance, while the cross-dataset results highlight the importance of dataset variation and feature provenance when assessing generalisation.
Full article
(This article belongs to the Special Issue Cybersecurity and Resilience in IoT and Distributed Networks (Including AI‑Enabled Approaches))
►▼
Show Figures

Graphical abstract
Open AccessArticle
Comparative Analysis of Transfer Learning Architectures for Human Posture Classification Using Silhouette Images
by
Ajit Kumar Pradhan, Sarita Tripathy, Kalaiarasi Sonai Muthu Anbananthen, Prasant Kumar Pattnaik and Amirthaa Anbananthen
Future Internet 2026, 18(9), 494; https://doi.org/10.3390/fi18090494 (registering DOI) - 20 Sep 2026
Abstract
►▼
Show Figures
Human posture classification is an important computer vision task for intelligent monitoring, rehabilitation, assistive systems, and human–machine interaction. This study presents a comparative evaluation of four transfer learning configurations, TL-ResNet-18, TL-ResNet-50, TL-MobileNet, and TL-Xception, under a common experimental protocol—for classifying four human postures
[...] Read more.
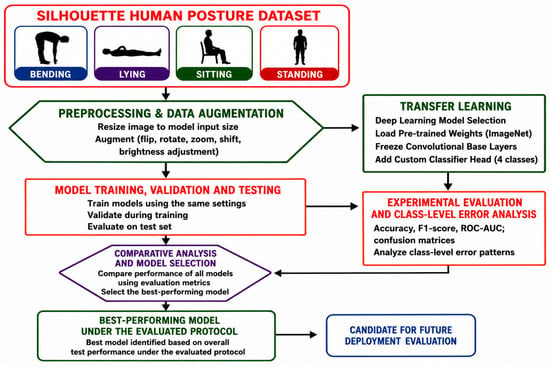
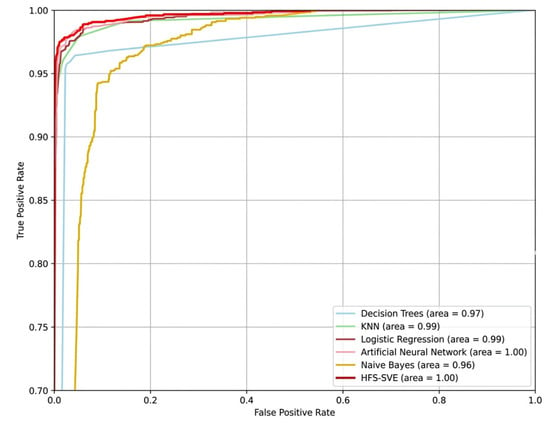
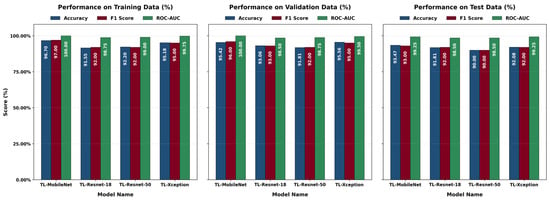
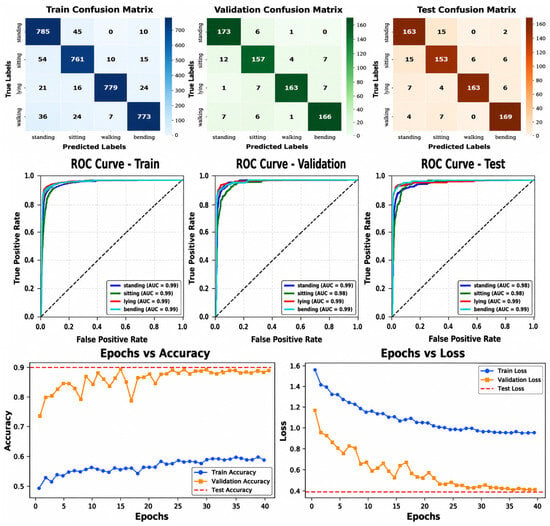
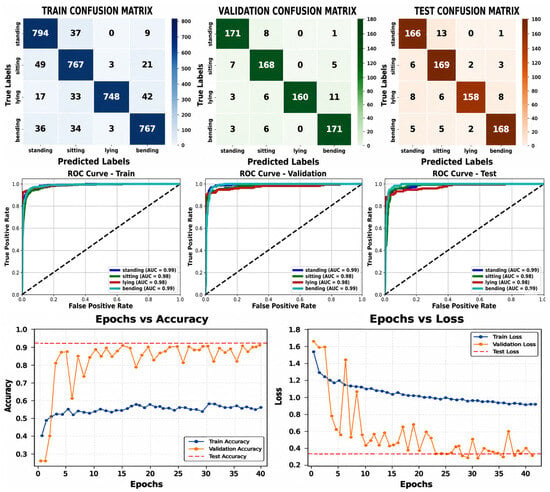
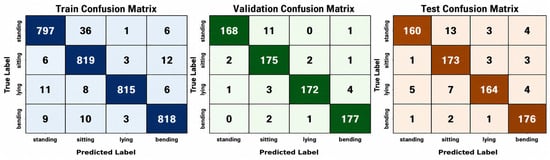
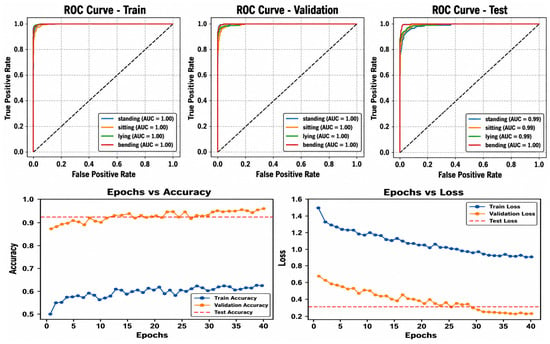
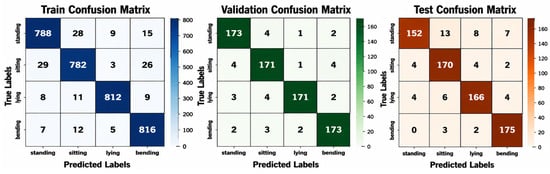
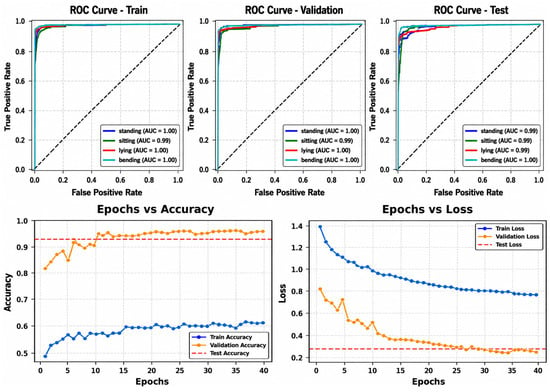
Human posture classification is an important computer vision task for intelligent monitoring, rehabilitation, assistive systems, and human–machine interaction. This study presents a comparative evaluation of four transfer learning configurations, TL-ResNet-18, TL-ResNet-50, TL-MobileNet, and TL-Xception, under a common experimental protocol—for classifying four human postures (standing, sitting, lying, and bending) from silhouette images. The architectures were evaluated under a common experimental protocol using the same dataset partitioning, preprocessing, augmentation procedures, and principal training settings, while retaining architecture-specific fine-tuning configurations. Performance was assessed using accuracy, F1-score, and ROC-AUC across the training, validation, and test partitions. Among the evaluated architectures, TL-MobileNet achieved the strongest overall held-out classification performance, with a test accuracy of 93.47%, an F1-score of 93.00%, and a ROC-AUC of 99.25%. TL-Xception achieved the same test ROC-AUC of 99.25%, but a lower test accuracy of 92.08%, while TL-ResNet-18 and TL-ResNet-50 achieved test accuracies of 91.81% and 90.00%, respectively. The results demonstrate performance differences among the evaluated transfer learning configurations. Within the evaluated ResNet configurations, greater network depth did not correspond to improved classification performance under the evaluated conditions. Silhouette-based posture classification shows potential for supporting future human-centered smart applications while reducing reliance on appearance-rich imagery. Further evaluation is required to establish cross-dataset generalizability, computational efficiency, and real-time deployment performance.
Full article

Figure 1
Open AccessArticle
Toward a Physical Operating System for Agentic Commerce: The Emerging Role of Amazon Supply Chain Services
by
Chihiro Watanabe, Shanyu Lei, Akira Nagamatsu and Yuji Tou
Future Internet 2026, 18(9), 493; https://doi.org/10.3390/fi18090493 (registering DOI) - 19 Sep 2026
Abstract
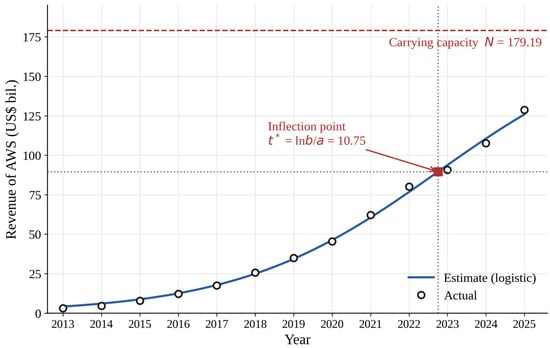
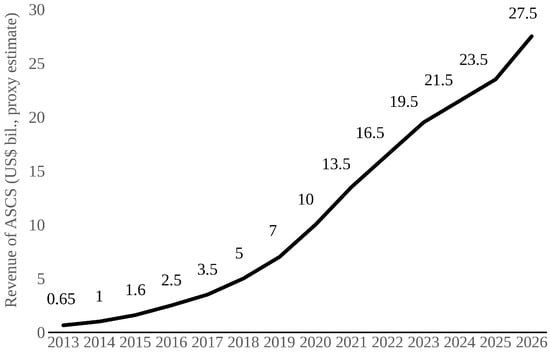
This study examines the Physical Execution Layer, in which AI agents extend digital decision-making into real-world tasks. It asks why Amazon Supply Chain Services (ASCS), launched in May 2026, may be structurally favored as infrastructure for this transition and evaluates it as an
[...] Read more.
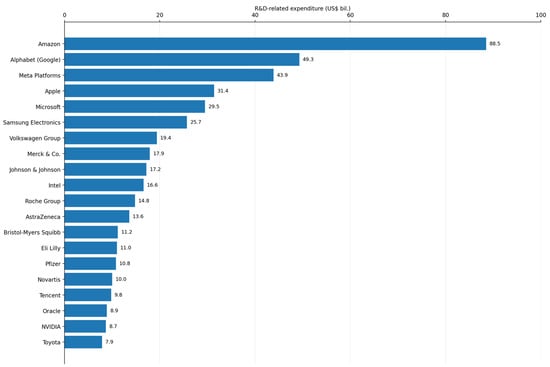
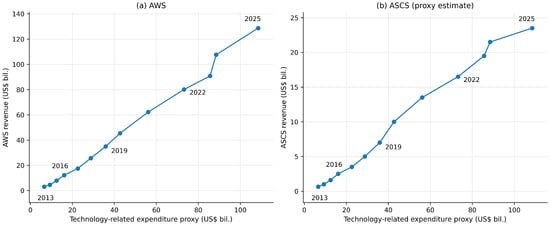
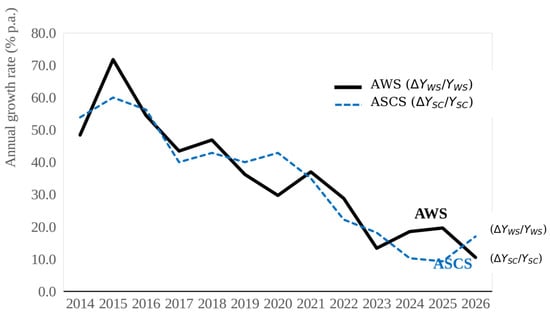
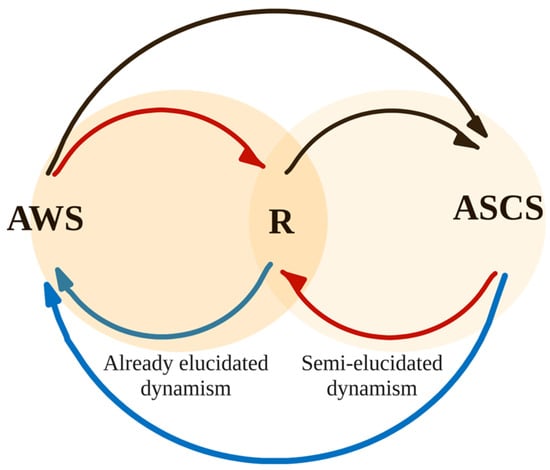
This study examines the Physical Execution Layer, in which AI agents extend digital decision-making into real-world tasks. It asks why Amazon Supply Chain Services (ASCS), launched in May 2026, may be structurally favored as infrastructure for this transition and evaluates it as an emerging Physical Operating System (Physical OS) candidate. Based on Amazon’s 10-K filings for 2013–2025 and an exploratory proxy series for ASCS revenue, the study applies logistic curve fitting and regression analysis with sensitivity analysis to compare the growth trajectories of Amazon Web Services (AWS) and ASCS from 2013 to 2026, including an exploratory 2026 reference year. AWS revenue is closely fitted in-sample by a logistic S-curve, whereas the ASCS proxy reflects a more physically constrained trajectory; their growth rates nevertheless exhibit substantial co-movement. The pattern is consistent with a proposed Dual-OS architecture in which AWS supplies compute, inference, and optimization while ASCS supports real-world execution within a shared technology and infrastructure investment base. CX physicalization and system-level supply-chain decarbonization may further increase the strategic importance of logistics performance. The findings are descriptive and correlational, not causal, and the ASCS series is a proxy. The Dual-OS architecture is presented as an analytical framework for future digital-physical execution networks and manufacturing reconfiguration.
Full article
(This article belongs to the Special Issue Advances in Smart Environments and Digital Twin Technologies—2nd Edition)
►▼
Show Figures

Figure 1

Open AccessArticle
Assessing Generative Artificial Intelligence Tools Usage Guidelines at the Top 200 Universities Worldwide
by
Midrar Ullah and Maged N. Kamel Boulos
Future Internet 2026, 18(9), 492; https://doi.org/10.3390/fi18090492 (registering DOI) - 19 Sep 2026
Abstract
This study aimed to evaluate the guidelines for the use of GenAI tools available on the websites of the world’s top 200 universities. We collected all publicly available guidelines from the websites of the top 200 universities listed in the 2026 QS World
[...] Read more.
This study aimed to evaluate the guidelines for the use of GenAI tools available on the websites of the world’s top 200 universities. We collected all publicly available guidelines from the websites of the top 200 universities listed in the 2026 QS World University Rankings. These guidelines were evaluated using the same 24-item checklist developed for our 2024 survey of the top 50 universities worldwide. The assessment revealed that 180 institutions have publicly available guidelines. All universities permit the use of GenAI tools under specific conditions. These policies are primarily established by academic bodies that focus on teaching, learning, and innovation. Most guidelines emphasize the use of university-licensed options to enhance data security. The most cited GenAI tools included ChatGPT, Microsoft Copilot, and Google Gemini (formerly Bard). More than 80% of the guidelines covered academic integrity, the limitations of GenAI tools, data privacy, the integration of GenAI in teaching and assessment, and the need to acknowledge its use. However, the operation of AI algorithms, reporting mechanisms for non-permitted use, documentation of prompts, and adoption of outputs were addressed in fewer than 40% of the guidelines. A comparison with our 2024 data for the subset of 50 universities re-evaluated in 2026 shows progress in guidelines coverage, reflecting institutions’ rapid responses to the evolving AI landscape. Despite the QS top 200’s concentration in wealthy nations, our checklist and findings are actionable for universities across the Global South.
Full article
(This article belongs to the Special Issue 2026 and 2027 Feature Papers from Future Internet’s Editorial Board Members)
Open AccessArticle
Performance Evaluation of ADS-B Receivers Implemented Using Software-Defined Radio Platforms and GNU Radio
by
Vlad-Stefan Hociung, Alexandru-Gabriel Gherghina, Cezar-Petrut Onu, Calin Vladeanu and Alexandru Martian
Future Internet 2026, 18(9), 491; https://doi.org/10.3390/fi18090491 (registering DOI) - 19 Sep 2026
Abstract
Automatic Dependent Surveillance-Broadcast (ADS-B) is one of the most critical technologies utilized in contemporary air traffic control, providing an automated and broadcast means of periodically sending aircraft identification and location, as well as velocity and other state-related information. This paper assesses the receiving
[...] Read more.
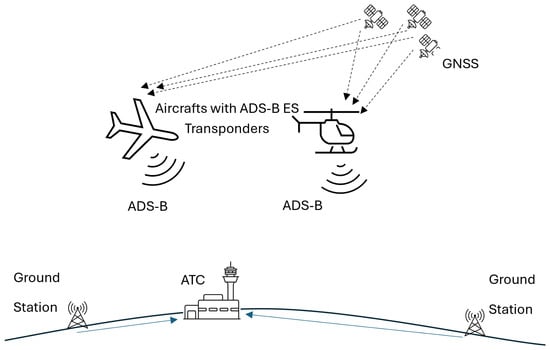
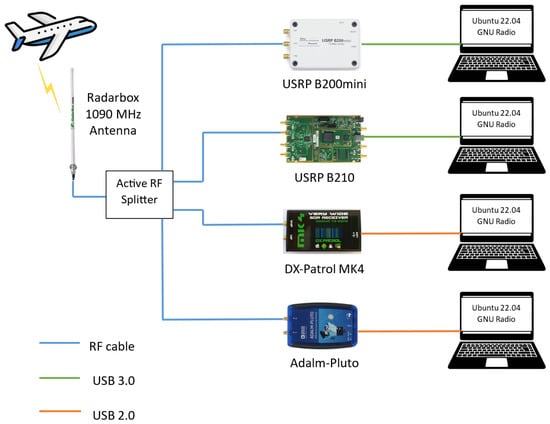
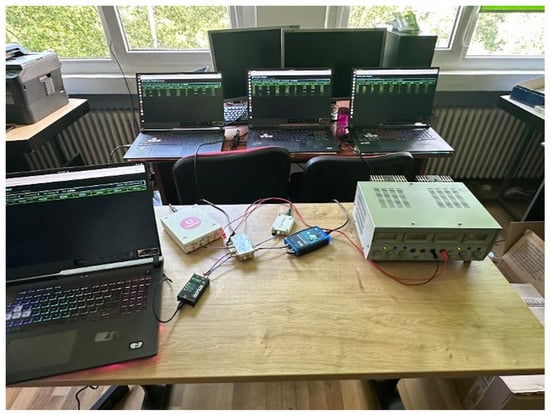
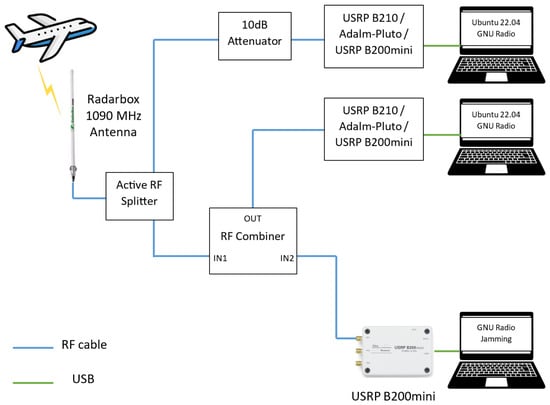
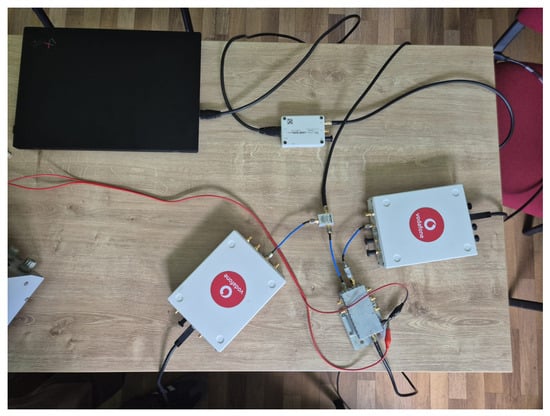
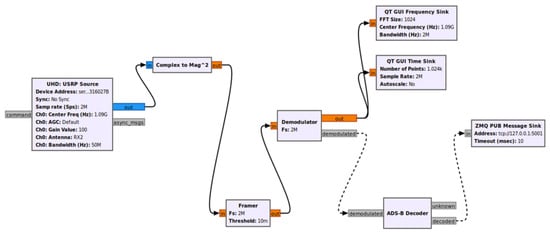
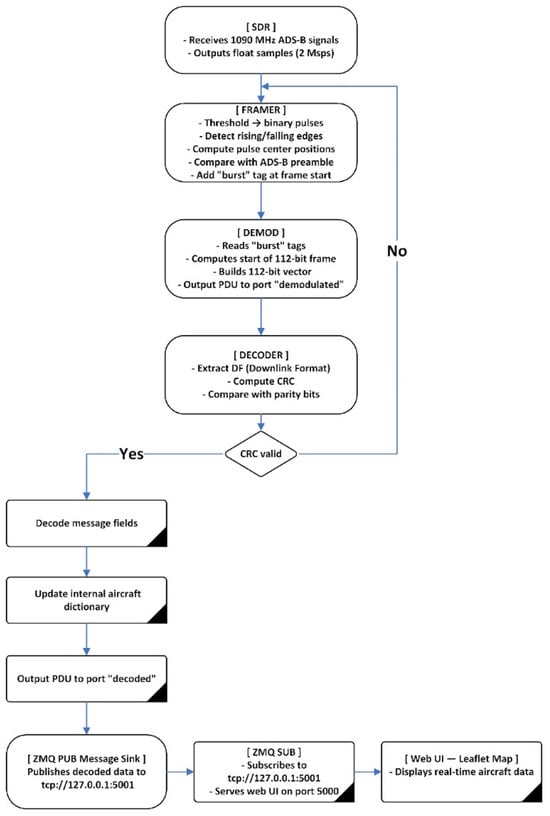
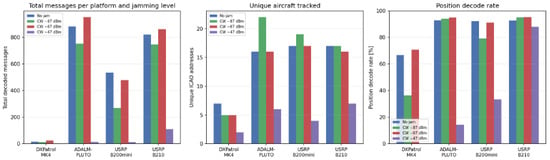
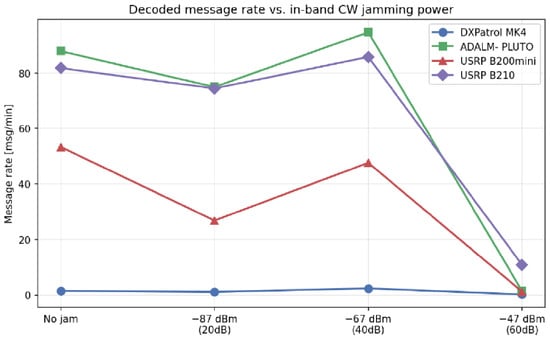
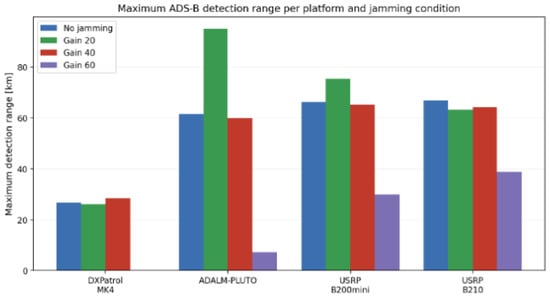
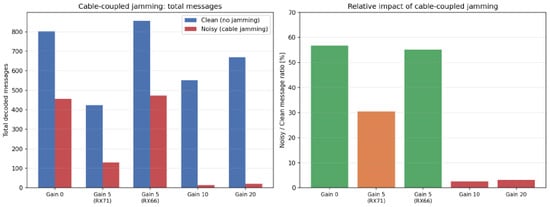
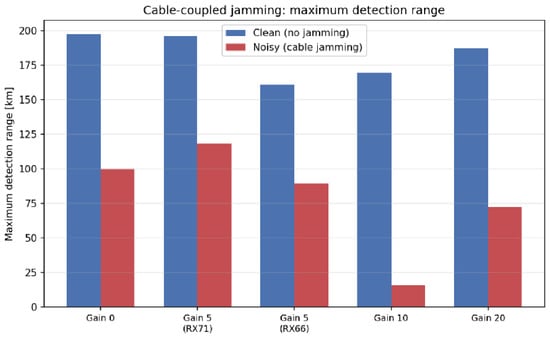
Automatic Dependent Surveillance-Broadcast (ADS-B) is one of the most critical technologies utilized in contemporary air traffic control, providing an automated and broadcast means of periodically sending aircraft identification and location, as well as velocity and other state-related information. This paper assesses the receiving performance of ADS-B signals utilizing multiple software-defined radio (SDR) platforms. Four different SDR platforms (DX Patrol MK4, Adalm-Pluto, USRP B200mini and USRP B210) were considered for evaluation, using a single antenna feed distribution via an active RF splitter. Each receiver’s performance was evaluated by measuring the rate at which each platform was able to decode messages from aircraft, the number of aircraft that were detected, the number of valid position reports received from each aircraft, the distance from the receiver to the aircraft at which each platform could receive valid position reports and each platform’s susceptibility to various forms of interference. The results indicate that the best cost-performance in case of interference-free ADS-B reception is obtained for the Adalm-Pluto platform (882 ADS-B messages received in the analyzed period, 2.84 cost/message), whereas the USRP B210 SDR exhibits the best performance in the presence of strong interference (109 ADS-B messages received). These findings provide insight into the relative trade-offs between low-cost SDR platforms and higher-performance SDR platforms, specifically related to analog-to-digital converter (ADC) resolution, RF front-end architecture, host interface, sensitivity and decoding reliability.
Full article
(This article belongs to the Special Issue Efficient and Secure Wireless Communications and Networking: Architecture and Applications)
►▼
Show Figures

Figure 1
Open AccessArticle
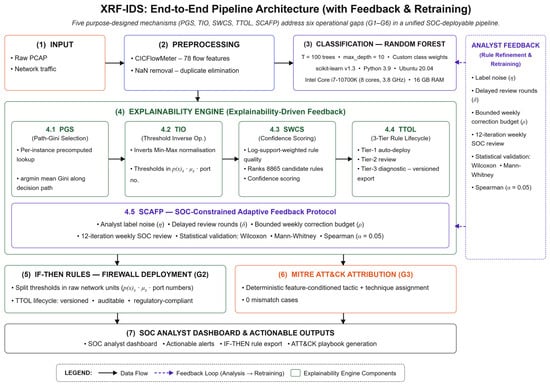
Explainable and Analyst-Driven Random Forest for Intrusion Detection
by
Saloua Bellouch, Mostapha Zbakh, Siham Aouad and An Braeken
Future Internet 2026, 18(9), 490; https://doi.org/10.3390/fi18090490 (registering DOI) - 18 Sep 2026
Abstract
Random Forest and other tree-ensemble classifiers achieve high accuracy in network intrusion detection; however, their aggregate decision logic prevents analysts from auditing or deploying individual predictions as operational rules. Post hoc explanation methods introduce latencies incompatible with security operation center (SOC) requirements and
[...] Read more.
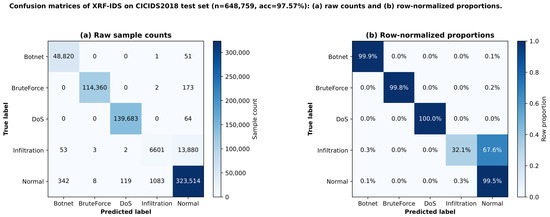
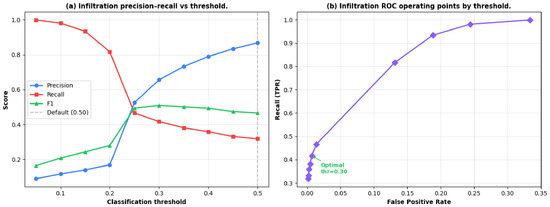
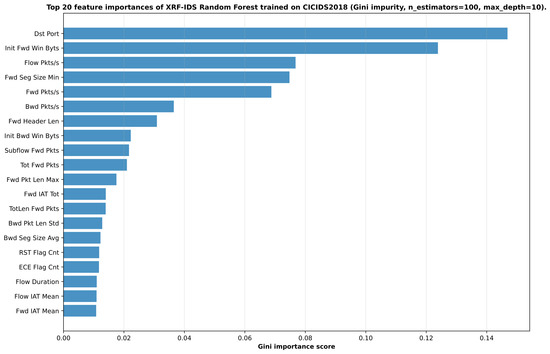
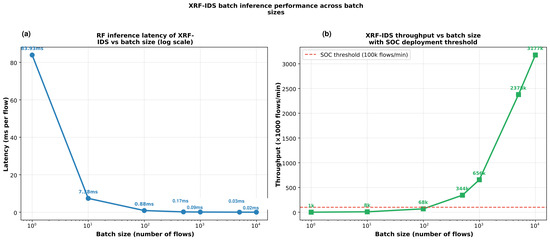
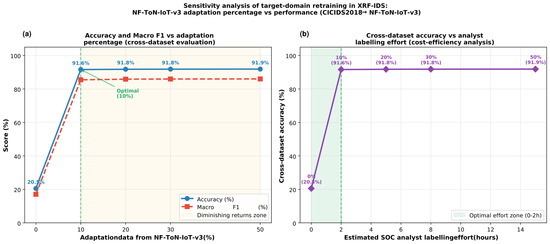
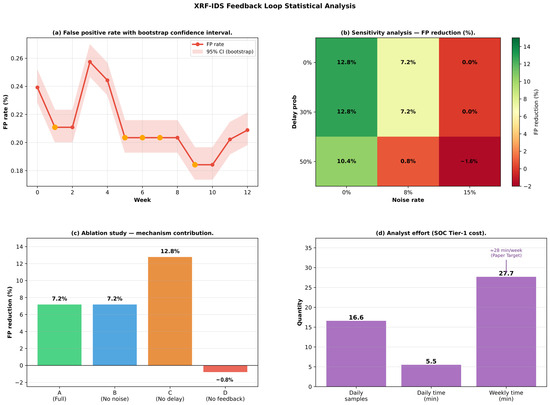
Random Forest and other tree-ensemble classifiers achieve high accuracy in network intrusion detection; however, their aggregate decision logic prevents analysts from auditing or deploying individual predictions as operational rules. Post hoc explanation methods introduce latencies incompatible with security operation center (SOC) requirements and produce conditions unsuitable for firewall configuration. Among the systems reviewed in this study, none unifies intrinsic explanation, rule deployment, ATT&CK attribution, cross-dataset validation, and adaptive feedback in one pipeline. This work presents a depth-limited Random Forest with deterministic, per-instance explanations at a fraction of gradient-based attribution latency. Complementary mechanisms generate analyst-deployable rule specifications, technique-level adversary attribution, and a feedback protocol that models label noise, missed reviews, and bounded correction budget. Evaluated on a large, multi-category network-traffic benchmark, the system attains high detection accuracy (macro recall , driven substantially by the majority normal-traffic class at of flows) while sustaining throughput beyond SOC requirements; a stealthy reconnaissance-and-exploitation category remains markedly harder to detect under this class imbalance. Cross-dataset evaluation on a more recent benchmark attains strong performance after limited target-domain retraining. The adaptive feedback protocol yields a statistically significant false-positive reduction over repeated simulated reviews, requiring only modest weekly analyst effort. Together, these capabilities enable auditable and SOC-integrable detection pipelines.
Full article
(This article belongs to the Section Cybersecurity)
►▼
Show Figures

Figure 1
Open AccessArticle
An Effective Cooperative Coevolution–Differential Evolution Algorithm for Improving the Performance and Robustness of Ridesharing Systems with Trust Requirements
by
Fu-Shiung Hsieh
Future Internet 2026, 18(9), 489; https://doi.org/10.3390/fi18090489 (registering DOI) - 18 Sep 2026
Abstract
Despite the growth of ridesharing services worldwide, the adoption of ridesharing remains low compared with other modes of transportation. Five important factors influencing the willingness to consider ridesharing include time/cost, service experience, traffic/environment, privacy, and safety. Information from social networks can provide potential
[...] Read more.
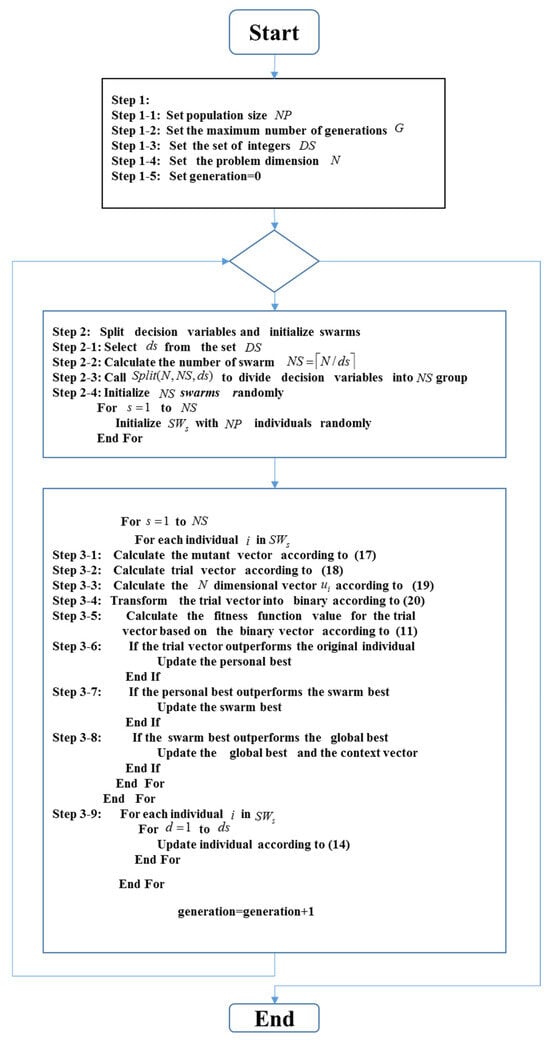
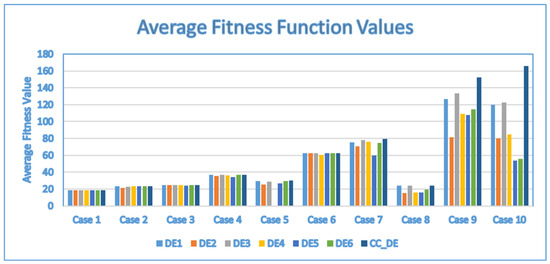
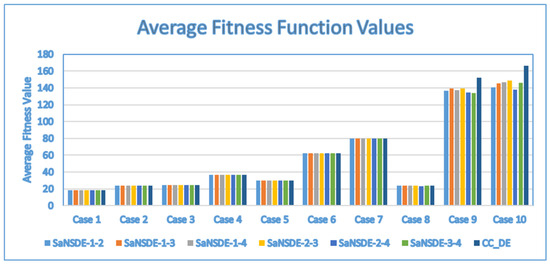
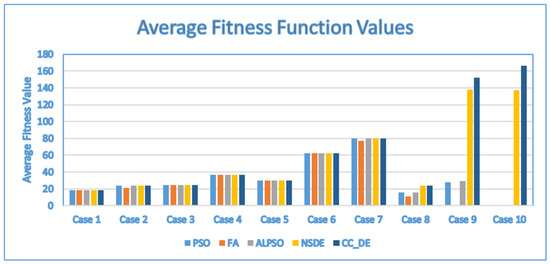
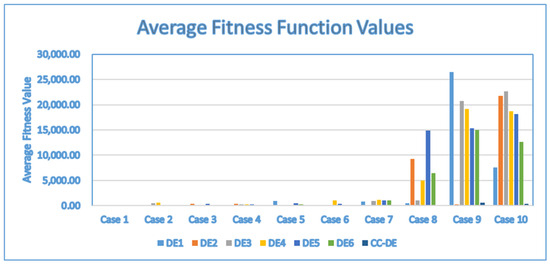
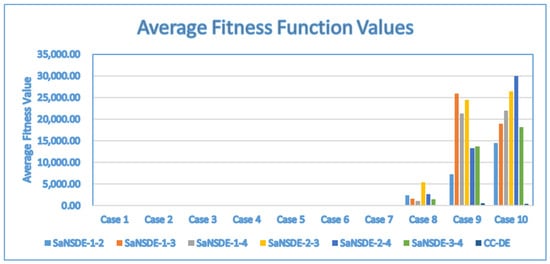
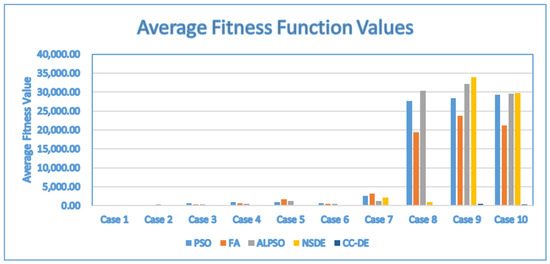
Despite the growth of ridesharing services worldwide, the adoption of ridesharing remains low compared with other modes of transportation. Five important factors influencing the willingness to consider ridesharing include time/cost, service experience, traffic/environment, privacy, and safety. Information from social networks can provide potential value for improving service experience and trustworthiness of ridesharing services. However, the problem of optimizing ridesharing decisions based on consideration of trust requirements of participating drivers and riders and other constraints in ridesharing systems poses a challenge in the development of a solution algorithm due to high computational complexity. In addition, a ridesharing optimization problem considering trust requirements is typically non-convex and non-linear with discrete decision variables, making exact methods not applicable. Metaheuristic approaches can be applied to find solutions for non-convex and non-linear discrete constrained optimization problems. The goal of this paper is to develop an effective solution algorithm to improve the performance of ridesharing systems with trust requirements. To achieve the goal of this study, we develop a variant of the Differential Evolution (DE) algorithm by combining the Cooperative Coevolution approach with the DE approach. To verify the effectiveness of the new algorithm for solving the ridesharing optimization problem with trust requirements, we conducted experiments and compared the results obtained by the new algorithm with those obtained by sixteen other competitive algorithms. Comparison with other competitive algorithms based on the experimental results shows that the proposed algorithm significantly outperforms other competitive algorithms in terms of performance and robustness. The CC–DE algorithm achieves the highest average fitness values for all test cases, whereas the other algorithms achieve the highest average fitness values for at most 80% of the test cases. The CC–DE algorithm achieves a zero standard deviation of fitness function values for all test cases, whereas the other algorithms achieve a zero standard deviation for at most 80% of the test cases. For the two largest test cases, the CC–DE algorithm outperforms the other algorithms by at least 9.246% and 12.9867%, respectively, in terms of performance.
Full article
(This article belongs to the Special Issue Intelligent Computational Methods for Urban Traffic Management and Control)
►▼
Show Figures

Figure 1
Open AccessArticle
COAu-IoD: A Cloud and Offline Computing-Assisted Authentication Framework for Lightweight UAV Communication in IoD
by
Pingyuan Zhang, Chen Fu and Qikun Zhang
Future Internet 2026, 18(9), 488; https://doi.org/10.3390/fi18090488 (registering DOI) - 18 Sep 2026
Abstract
The Internet of Drones (IoD) enables efficient communications among unmanned aerial vehicles (UAV) via wireless links. Restricted by limited onboard computing resources and complicated operating environments, such a network is vulnerable to external or internal security threats. It is therefore urgent to deploy
[...] Read more.
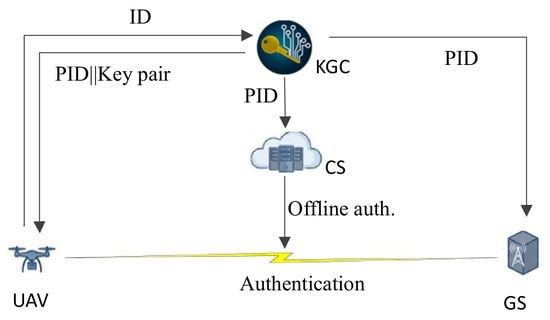
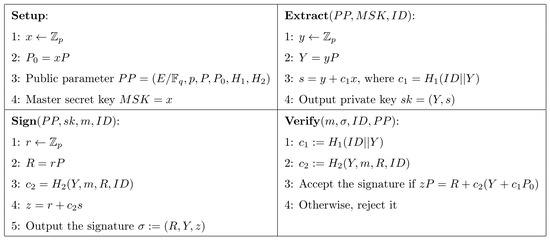
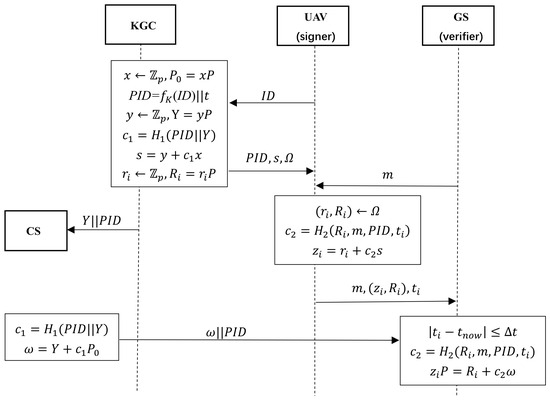
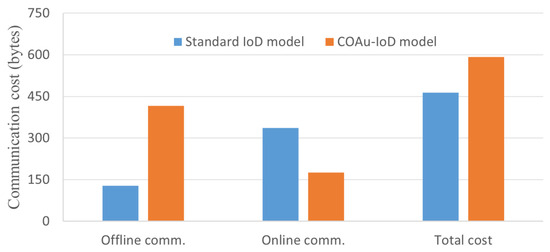
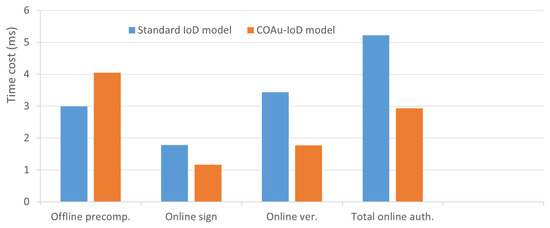
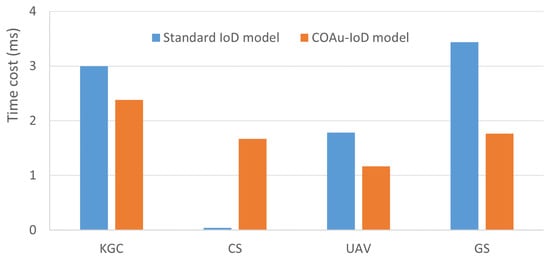
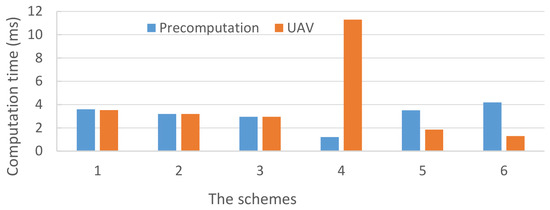
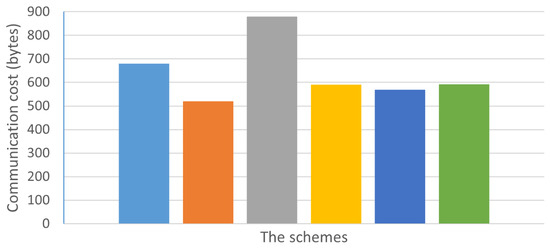
The Internet of Drones (IoD) enables efficient communications among unmanned aerial vehicles (UAV) via wireless links. Restricted by limited onboard computing resources and complicated operating environments, such a network is vulnerable to external or internal security threats. It is therefore urgent to deploy an effective authentication mechanism to isolate malicious attackers prior to UAV communications. Nevertheless, the conventional identity-based IoD authentication schemes must account for total computation and communication overhead, regardless of the effective instant of authentication messages. In this work, we consider the offline precomputation in the authentication phase before the message is available and add cloud servers as an extra component in IoD to assist limited onboard resources to share partial authentication calculation. As a result, this work proposes a new cloud- and offline-computing-assisted authentication framework, known as COAu-IoD, to provide lightweight communication between a UAV and ground station by transferring heavy computation overhead to the offline phase. We give a security model for this authentication framework and provide an efficient construction based on this framework and a known identity-based signature scheme. What is more, we give its security proof and evaluate its performance using the standard and recent state-of-the-art IoD authentication schemes. The results demonstrate that our COAu-IoD scheme achieves lower online computation and communication overhead for UAVs, at the cost of acceptable offline precomputation overhead.
Full article
(This article belongs to the Section Internet of Things)
►▼
Show Figures

Figure 1
Open AccessArticle
GDPR Dark Patterns in Cookie Consent: An Automated Study of High-Traffic Websites Accessed from Denmark
by
Christos Ntemkas, Laura Vieira Teixeira, Lejla Islami, Gaurav Choudhary and Nicola Dragoni
Future Internet 2026, 18(9), 487; https://doi.org/10.3390/fi18090487 (registering DOI) - 17 Sep 2026
Abstract
This paper examines how often GDPR-relevant dark patterns appear in cookie-consent banners and how often users receive a choice that is free and informed. We use an adapted version of CCrawler to crawl 99 high-traffic websites accessed from Denmark, detect consent interfaces, and
[...] Read more.
This paper examines how often GDPR-relevant dark patterns appear in cookie-consent banners and how often users receive a choice that is free and informed. We use an adapted version of CCrawler to crawl 99 high-traffic websites accessed from Denmark, detect consent interfaces, and extract first-layer choice pathways and settings-layer elements for compliance-risk coding. We then assess detected banners against four GDPR-informed interface-level criteria: first-layer refusal availability, absence of pre-ticked or default-enabled options, relative accept/reject prominence, and non-obstructive presentation. These operational criteria are observable interface proxies rather than final legal determinations of GDPR compliance. Cookie banners were detected on 90 of 99 sites; the nine non-detections are reported separately and are not treated as evidence of non-compliance. The results indicate a structural imbalance: acceptance is usually available on the first layer, while refusal is often placed behind additional steps or settings dialogues. A subset of reachable settings interfaces also contained pre-ticked options. To place these observations in the European context, we compare the two directly comparable first-layer choice indicators with a recent 31-country study. Acceptance availability is close to that study’s Denmark-specific estimate, whereas first-layer rejection in our high-traffic Denmark-accessed sample lies between its Denmark-specific estimate and its 31-country aggregate. These cross-study comparisons are descriptive and are not treated as matched statistical estimates because the sampling frames and measurement procedures differ. The findings provide Denmark-specific, time-bounded evidence that known consent-interface asymmetries remain visible on high-traffic websites, together with a reproducible workflow for future audits.
Full article
Open AccessArticle
Transformer-Based Generation of Route Opening Patterns for Crowd Evacuation
by
Akihiro Morita, Koichi Kobayashi and Yuh Yamashita
Future Internet 2026, 18(9), 486; https://doi.org/10.3390/fi18090486 (registering DOI) - 17 Sep 2026
Abstract
Developing methods for achieving safe and efficient crowd evacuation is an important research issue. In particular, controlling pedestrian flows based on predictions from a mathematical model is important. In this paper, we propose a new method for generating route opening patterns. The target
[...] Read more.
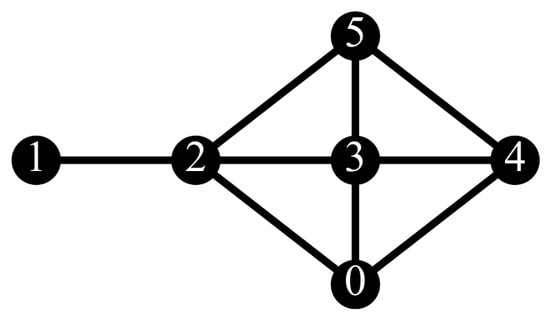
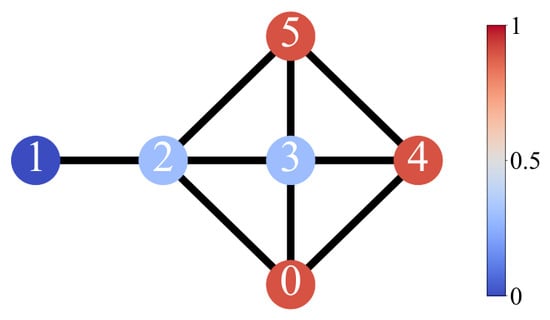
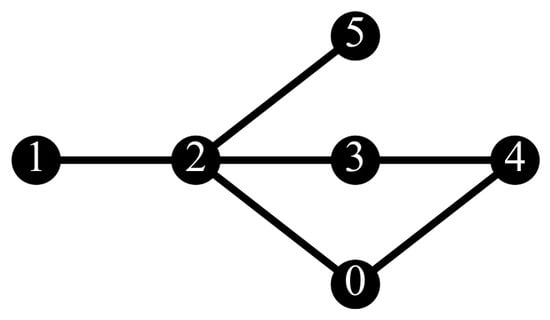
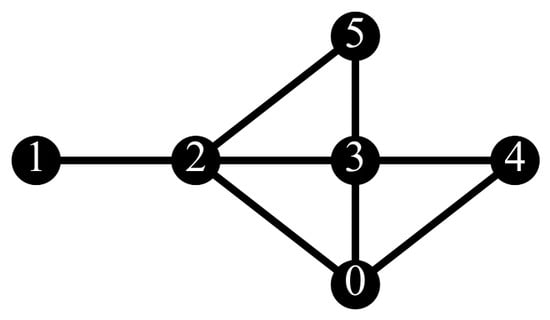
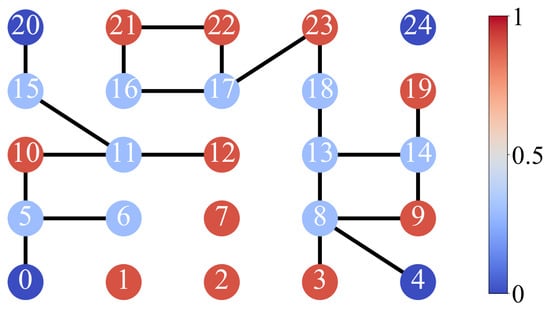
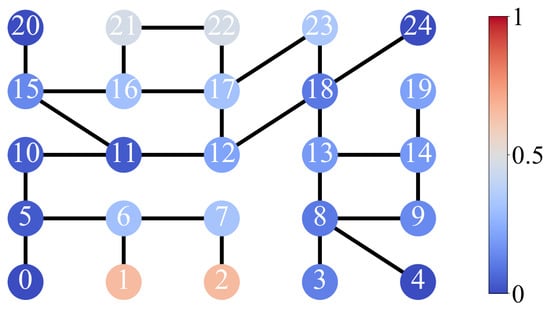
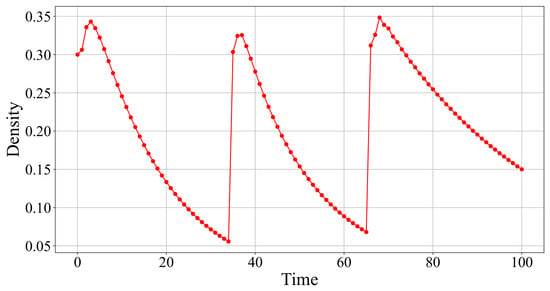
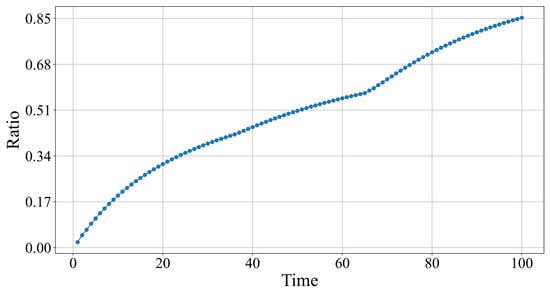
Developing methods for achieving safe and efficient crowd evacuation is an important research issue. In particular, controlling pedestrian flows based on predictions from a mathematical model is important. In this paper, we propose a new method for generating route opening patterns. The target area is modeled by an undirected graph, and pedestrian flows are represented by the temporal change in density at each vertex. We assume that the density at each vertex can be observed using equipment such as IoT devices. Based on the model predictive control framework, we consider the problem of finding a route opening pattern that minimizes a safety-related penalty. To solve this problem, we propose a Transformer-based solution method that combines offline and online computations. The effectiveness of the proposed method is demonstrated through a numerical simulation. In the numerical example, a route opening pattern satisfying the Signal Temporal Logic (STL) formula was obtained using the proposed method. The evacuation rate, which represents the proportion of pedestrians whose movement is complete, was , the penalty was 2193, and the maximum online computation time was s. In the offline computation, the training dataset for the Transformer model was generated using a genetic algorithm (GA). By combining offline and online computations, we confirmed that an appropriate route opening pattern can be generated during online computation.
Full article
(This article belongs to the Special Issue Smart Technology: Artificial Intelligence, Robotics and Algorithms)
►▼
Show Figures

Figure 1
Open AccessArticle
An Explainable AI Framework for Identity Document Authentication in AML/KYC Verification
by
Eldeena Huey Yinn Lim and Tee Connie
Future Internet 2026, 18(9), 485; https://doi.org/10.3390/fi18090485 - 16 Sep 2026
Abstract
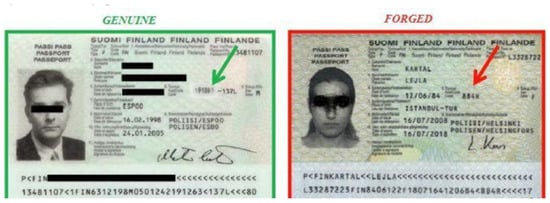
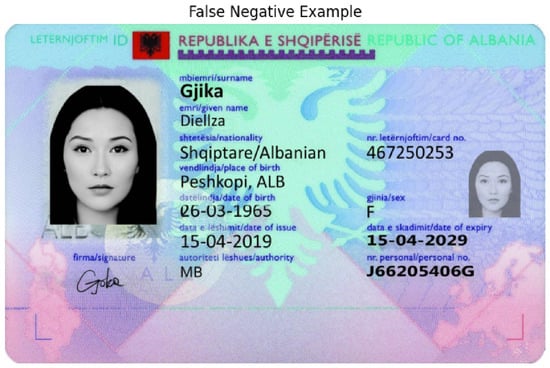
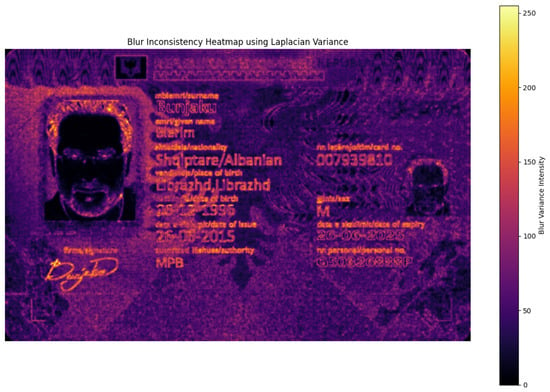
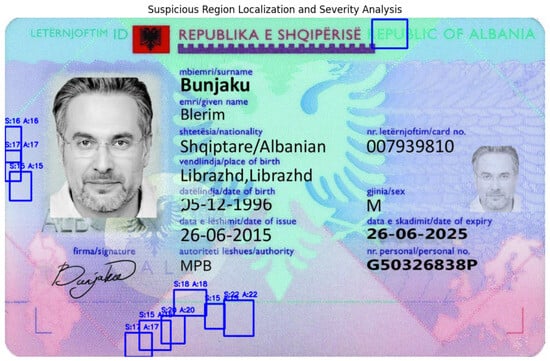
This study investigates the development of an AI-driven document authentication framework for Anti-Money Laundering (AML) and Know Your Customer (KYC) verification environments. Conventional manual inspection and rule-based verification techniques often fail to detect sophisticated forged identity documents containing subtle visual or semantic manipulations.
[...] Read more.
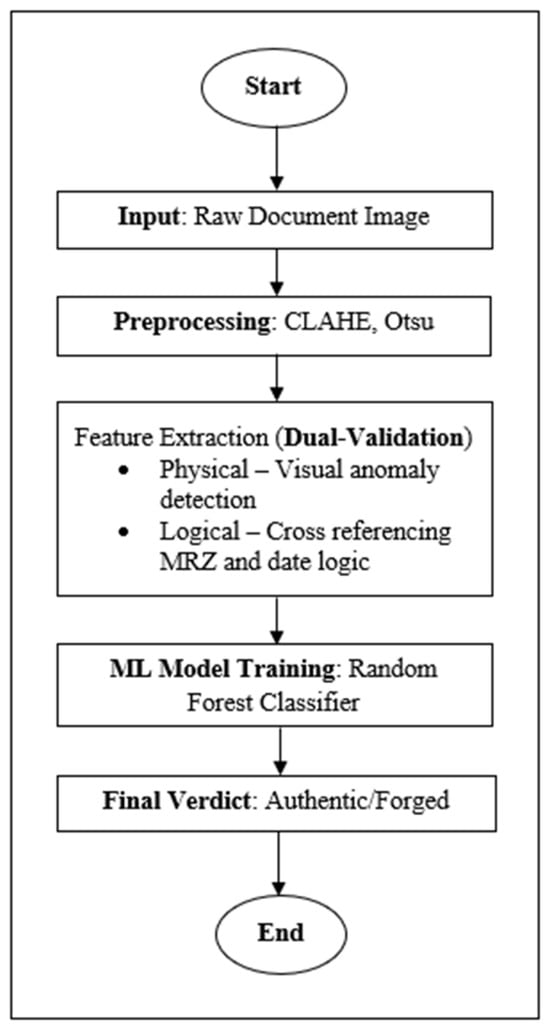
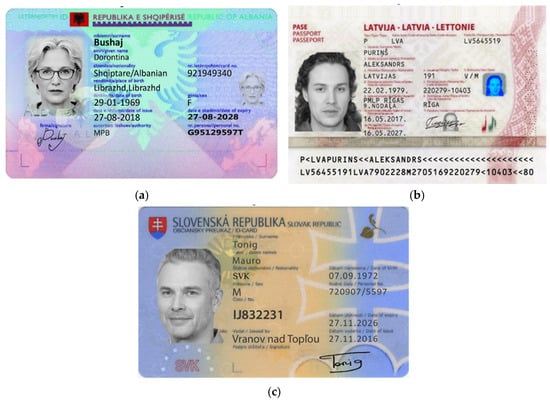
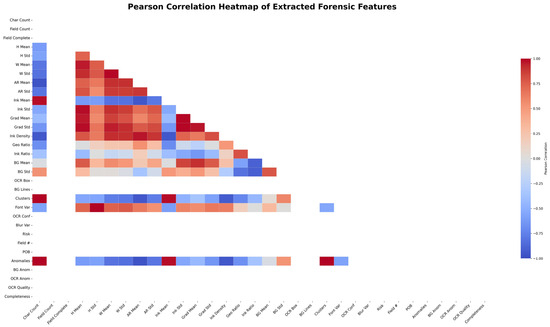
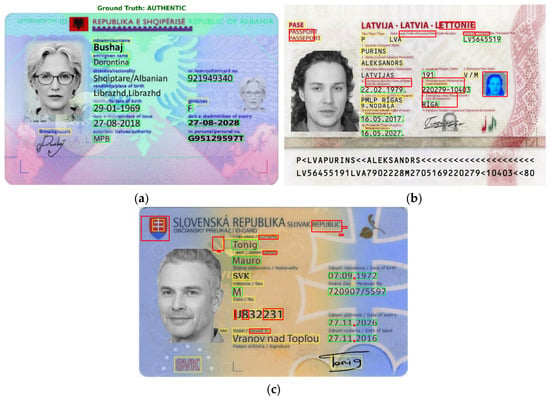
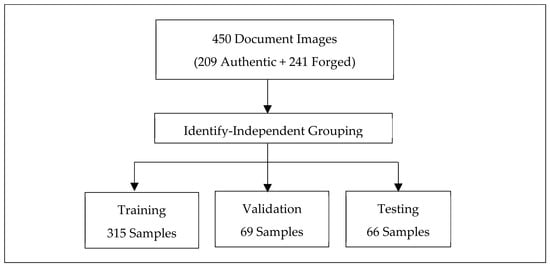
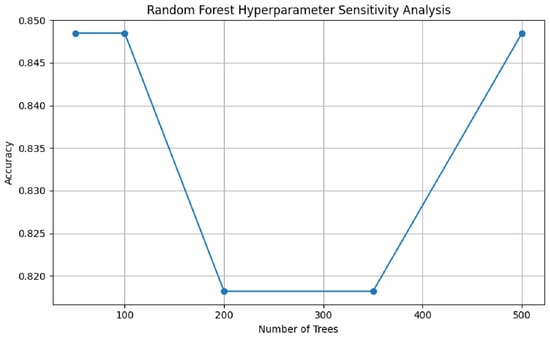
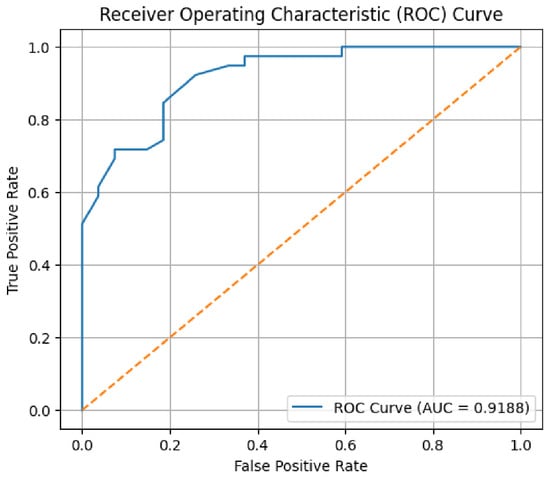
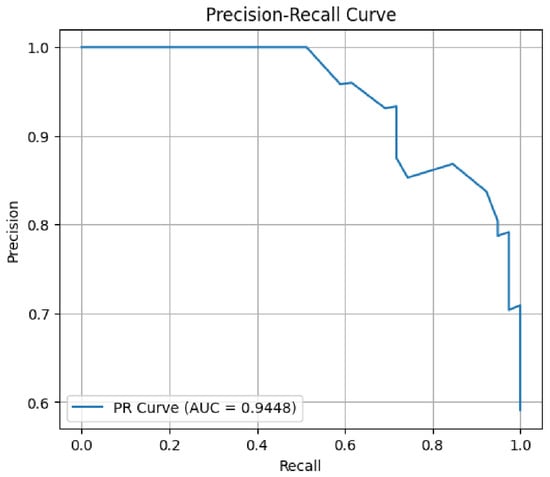
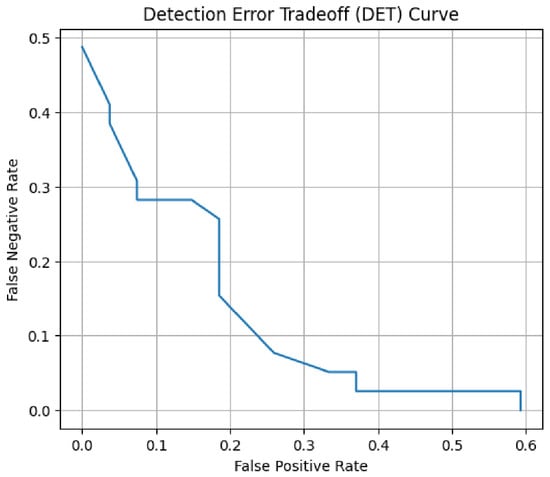
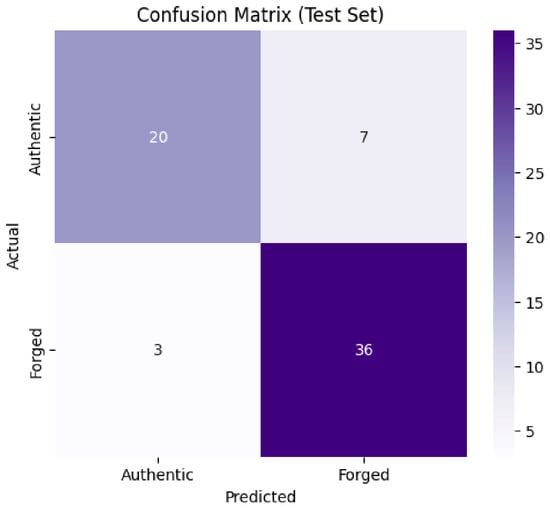
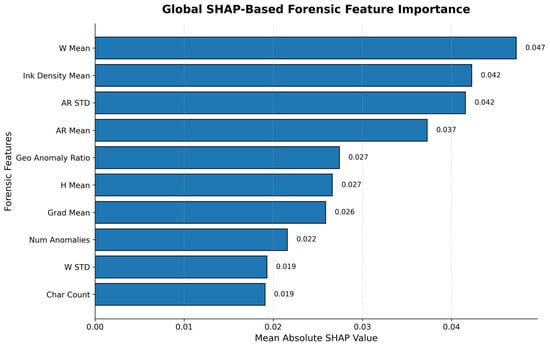
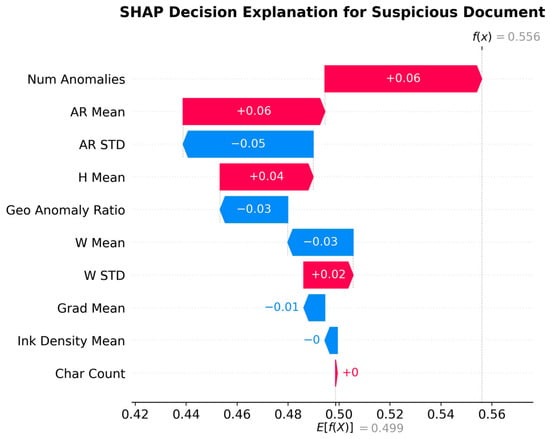
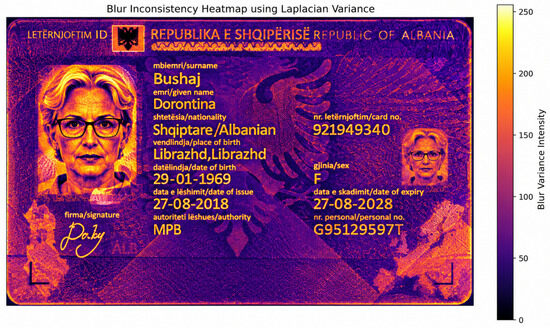
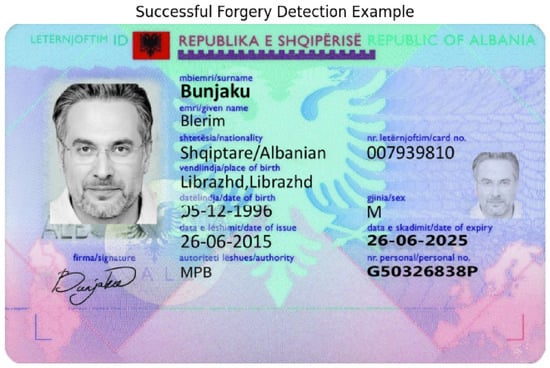
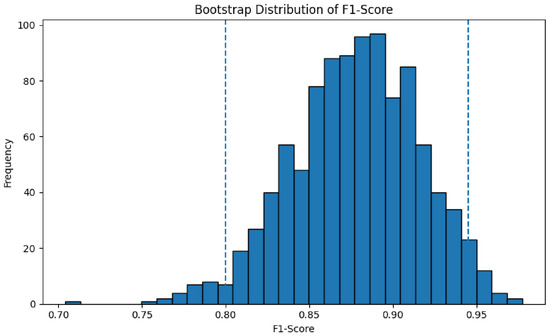
This study investigates the development of an AI-driven document authentication framework for Anti-Money Laundering (AML) and Know Your Customer (KYC) verification environments. Conventional manual inspection and rule-based verification techniques often fail to detect sophisticated forged identity documents containing subtle visual or semantic manipulations. To address this limitation, the proposed framework combines handcrafted forensic feature extraction, OCR-driven semantic analysis, rule-based semantic field extraction and Random Forest classification to identify inconsistencies within identity documents captured under realistic mobile imaging conditions. Experimental evaluation was conducted using selected MIDV-2020 identity document subsets consisting of Albanian identity cards, Latvian passports, and Slovakian identity cards. The proposed framework achieved a recall rate of 92.31% and an overall accuracy of 84.85% on the held-out test set, while maintaining interpretable forensic feature analysis suitable for regulated AML/KYC environments. The results demonstrate that lightweight and explainable machine learning approaches can provide effective forged-document detection without requiring computationally intensive deep learning architectures.
Full article
(This article belongs to the Special Issue Securing Artificial Intelligence Against Attacks)
►▼
Show Figures

Figure 1

Open AccessArticle
Understanding Differential Privacy in Decentralized Federated Learning: A Controlled Privacy–Utility Comparison
by
Alsharif Hasan Mohamad Aburbeian, Manuel Fernández-Veiga, Ana Fernández-Vilas, Majdi Owda and Amani Yousef Owda
Future Internet 2026, 18(9), 484; https://doi.org/10.3390/fi18090484 - 16 Sep 2026
Abstract
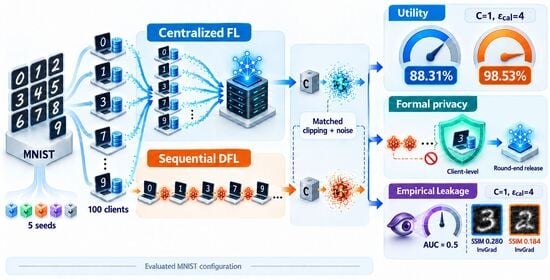
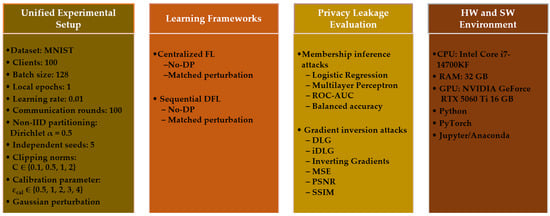
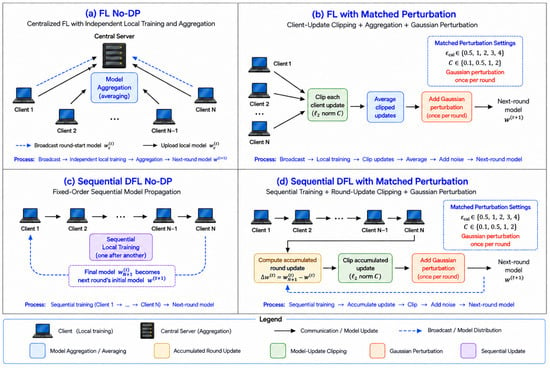
Centralized Federated Learning (FL) enables collaborative model training without sharing raw data. Differential privacy (DP) is widely used to protect sensitive information in FL; however, its behavior in decentralized environments remains poorly understood. This study empirically compares centralized FL and sequential Decentralized Federated
[...] Read more.
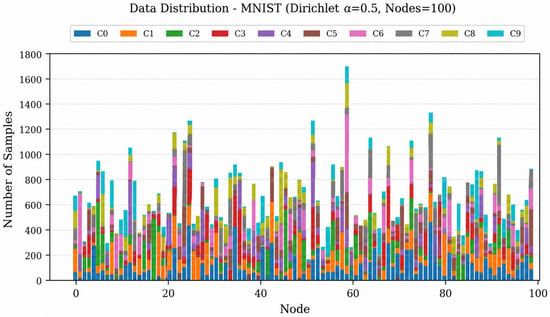
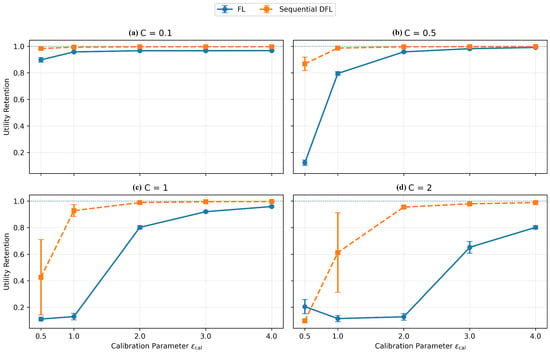
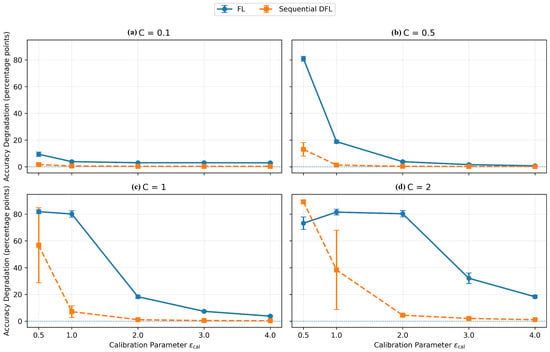
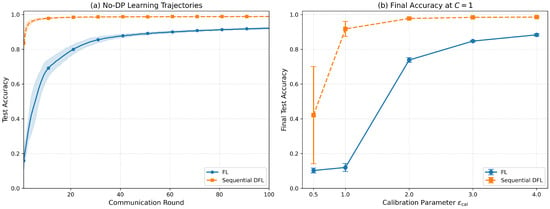
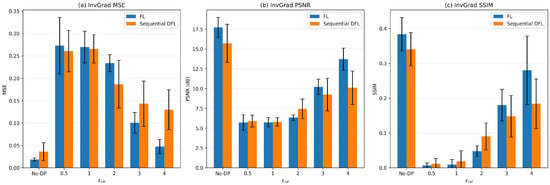
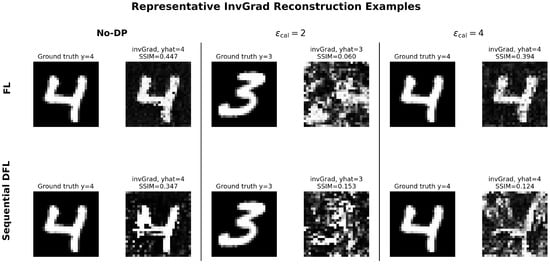
Centralized Federated Learning (FL) enables collaborative model training without sharing raw data. Differential privacy (DP) is widely used to protect sensitive information in FL; however, its behavior in decentralized environments remains poorly understood. This study empirically compares centralized FL and sequential Decentralized Federated Learning (DFL) under matched clipping and perturbation settings to examine model utility and privacy leakage. Both frameworks were evaluated under a common experimental setup with non-IID data, and each configuration was evaluated across five independent seeds. Utility was evaluated under matched experimental perturbation parameters, whereas formal client-level privacy accounting was applied to the perturbed round-end model releases, with each client’s complete dataset treated as the protected unit. Empirical leakage was evaluated separately using membership inference and gradient inversion attacks. Within the evaluated MNIST configuration, the results show that clipping, perturbation, and the learning procedure jointly influence the observed privacy–utility behavior. At and , the mean final accuracy was for FL and for sequential DFL. At , InvGrad reconstruction for FL produced an MSE of , PSNR of , and SSIM of , compared with , , and for sequential DFL, respectively. Future research will investigate topology-aware privacy mechanisms and adaptive noise allocation for decentralized systems.
Full article
(This article belongs to the Special Issue Privacy-Preserving and Secure Machine Learning)
►▼
Show Figures

Graphical abstract
Open AccessArticle
On the Role of Data Normalization in Adversarial Robustness Evaluation: A Comparative Analysis of XGBoost and Random Forest for IoT Network Intrusion Detection
by
Inas Mostefai, Sofiane Boukli-Hacene and Abdelhafid Abouaissa
Future Internet 2026, 18(9), 483; https://doi.org/10.3390/fi18090483 - 16 Sep 2026
Abstract
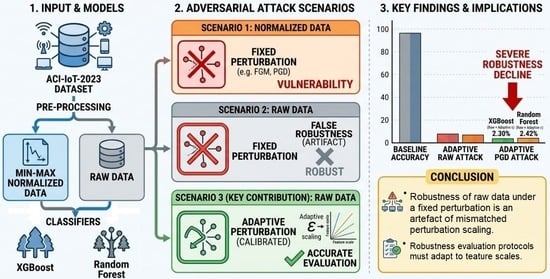
Intrusion detection systems (IDS) based on machine learning (ML) have demonstrated remarkable effectiveness in detecting cyber-attacks in Internet of Things (IoT) environments. Despite their high predictive performance, the robustness of these systems against adversarial attacks remains insufficiently understood, particularly with regard to the
[...] Read more.
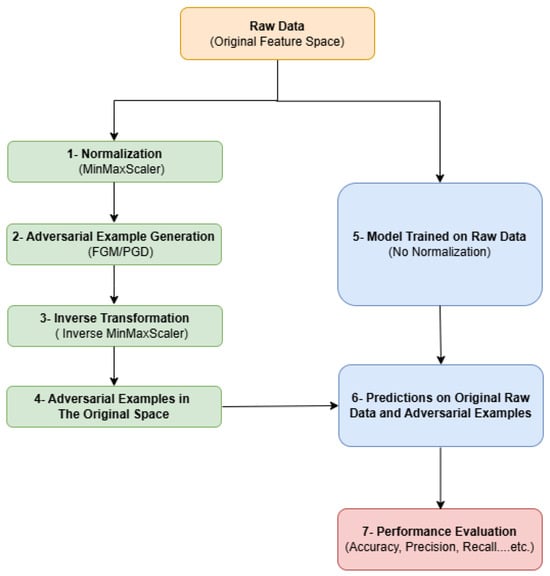
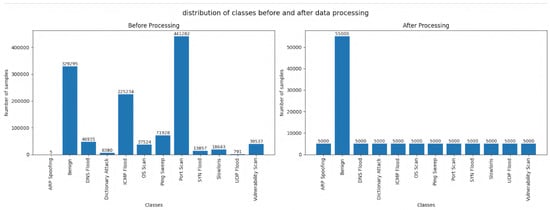
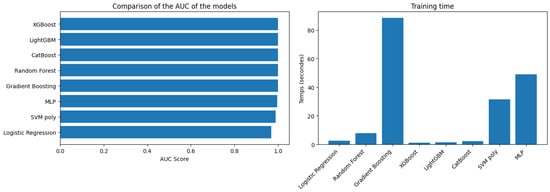
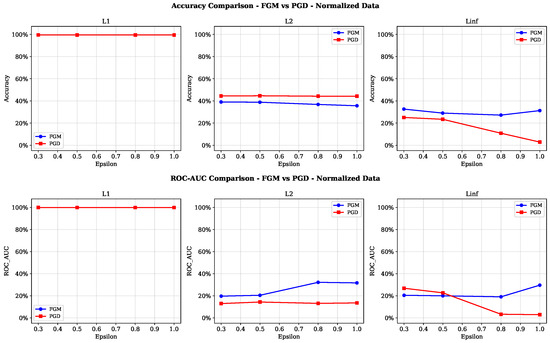
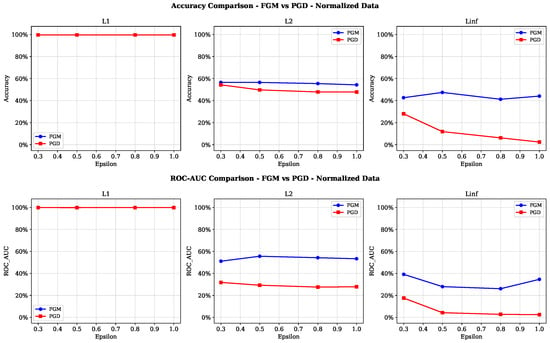
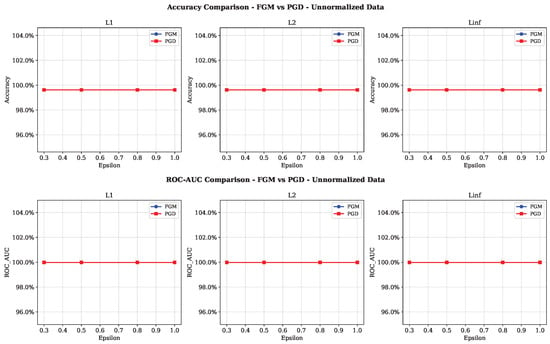
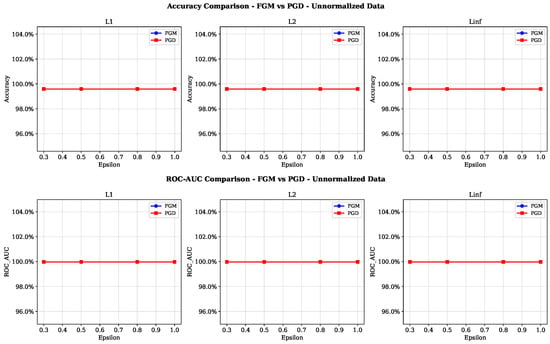
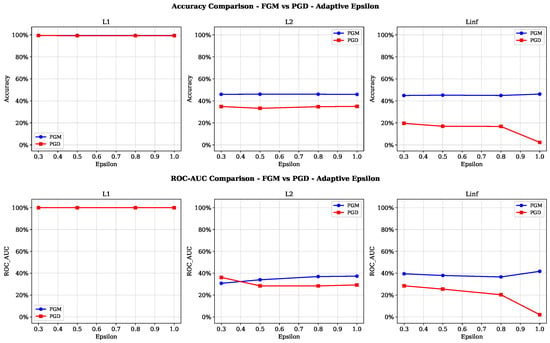
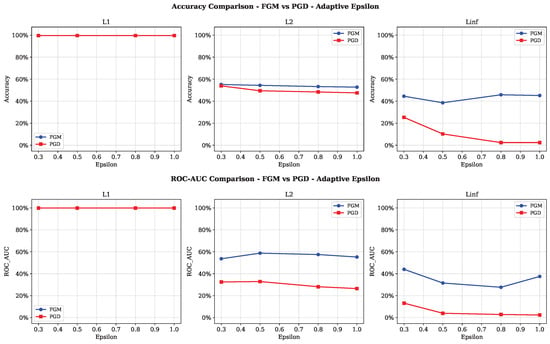
Intrusion detection systems (IDS) based on machine learning (ML) have demonstrated remarkable effectiveness in detecting cyber-attacks in Internet of Things (IoT) environments. Despite their high predictive performance, the robustness of these systems against adversarial attacks remains insufficiently understood, particularly with regard to the influence of data pre-processing techniques such as feature normalisation. This study examines the impact of Min-Max normalisation on the robustness of two widely used tree-based classifiers, XGBoost and Random Forest, against adversarial attacks of the Fast Gradient Method (FGM) and Projected Gradient Descent (PGD) types. Using the ACI-IoT-2023 dataset, we conduct comprehensive experiments across three scenarios: models trained on normalized data and evaluated using a fixed perturbation magnitude ( ), models trained on raw data and evaluated using the same fixed , and models trained on raw data and evaluated using an adaptive calibrated to the scale of each feature. Our results demonstrate that Min-Max normalization alone does not inherently make these models robust against adversarial attacks. The apparent robustness observed on non-normalised data with a fixed perturbation budget is an artefact caused by a misalignment in the scaling of the perturbation. When using an adaptive epsilon strategy calibrated according to feature scales, the accuracies of XGBoost and Random Forest decreased to 2.30% and 2.42% respectively under the norm with the PGD attack. These results highlight the crucial importance of taking feature scaling into account when assessing robustness against adversarial attacks and provide practical recommendations for the design of reliable evaluation protocols for intrusion detection systems in the Internet of Things.
Full article
(This article belongs to the Section Internet of Things)
►▼
Show Figures

Graphical abstract
Open AccessEditorial
Software-Defined Networking (SDN) and Network Function Virtualization (NFV) for a Hyperconnected World
by
Faycal Bouhafs and Sachin Sharma
Future Internet 2026, 18(9), 482; https://doi.org/10.3390/fi18090482 - 15 Sep 2026
Abstract
Data networks are a fundamental infrastructure of modern societies, supporting industries, transport, communication, government services, finance, etc [...]
Full article
(This article belongs to the Special Issue Software-Defined Networking (SDN) and Network Function Virtualization (NFV) for a Hyperconnected World)
Open AccessArticle
From Semantic Retrieval to Conversational Agent: A Web-Based RAG Architecture for Interactive System Dynamics Modeling
by
Pavel Kyurkchiev and Anton Iliev
Future Internet 2026, 18(9), 481; https://doi.org/10.3390/fi18090481 - 15 Sep 2026
Abstract
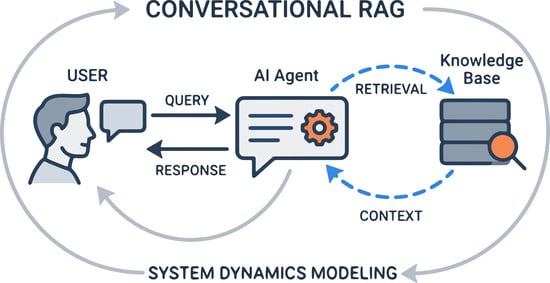
Keyword-based semantic search performs poorly on complex knowledge repositories such as System Dynamics model databases, where users know the behavior they want to simulate but not the structural vocabulary needed to retrieve it. We replace the static search field with an interactive web-based
[...] Read more.
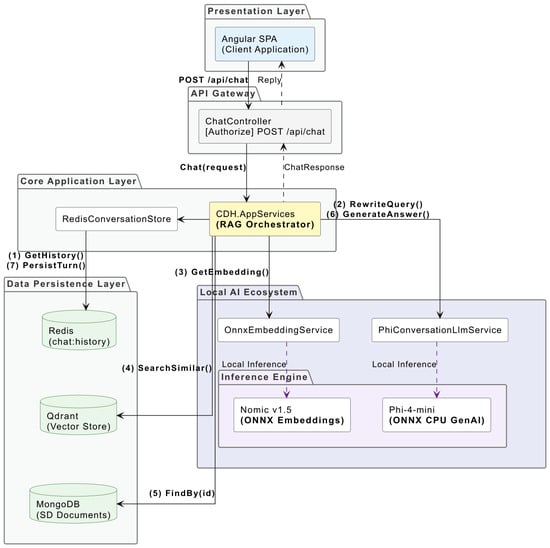
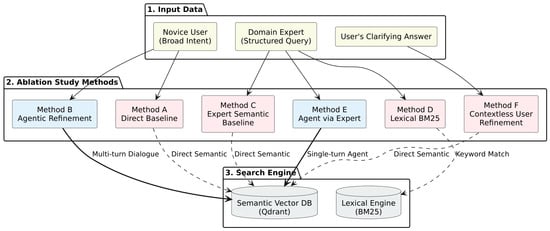
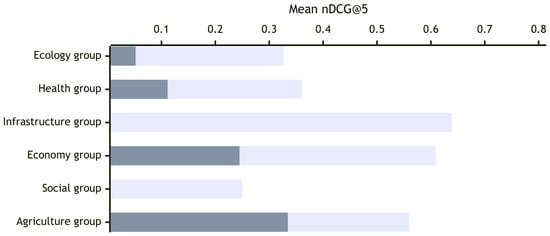
Keyword-based semantic search performs poorly on complex knowledge repositories such as System Dynamics model databases, where users know the behavior they want to simulate but not the structural vocabulary needed to retrieve it. We replace the static search field with an interactive web-based conversational agent, built as a Retrieval-Augmented Generation architecture in which the system asks context-aware clarifying questions to narrow the search scope across multiple turns. The architecture was evaluated in an ablation study of 37 benchmark scenarios over a curated corpus of 63 models, comparing six retrieval strategies against an expert semantic baseline using Precision@5, Recall@5, MRR@5, nDCG@5 and Hit@5. Conversational refinement raised mean nDCG@5 from 0.1066 to 0.4422 and Hit@5 from 0.1892 to 0.5946. The improvement over the broad-intent baseline is significant on nDCG@5 and MRR@5 under Holm-corrected Wilcoxon signed-rank tests. This comparison aggregates the clarification exchange with the additional user input it elicits. A separate condition that bypasses the generative rewriting step bounds the contribution of that step. A residual gap to the expert semantic baseline (nDCG@5 = 0.5750) remains and is significant on MRR@5. Lexical BM25 applied to expert queries outperformed dense retrieval on every metric (nDCG@5 = 0.8053), showing that sparse matching retains a decisive advantage where the structural vocabulary is exact. We conclude that conversational elicitation is an effective mechanism for narrowing the expertise gap in this domain, and that the lexical results motivate pairing it with hybrid sparse–dense retrieval.
Full article
(This article belongs to the Special Issue Human-Centered Artificial Intelligence—2nd Edition)
►▼
Show Figures

Graphical abstract
Open AccessArticle
Privacy-Preserving Information Fusion of Heterogeneous Cross-Jurisdictional Sources for Traffic Accident Severity Prediction
by
Ashik Shah Jahangeer and Shanmugavadivu Pichai
Future Internet 2026, 18(9), 480; https://doi.org/10.3390/fi18090480 - 14 Sep 2026
Abstract
Road safety authorities each hold accident records that, when combined, could train stronger severity prediction models, yet these records can be neither centralized, for privacy and governance reasons, nor naively merged, because jurisdictions encode severity under incompatible ontologies. This paper recasts that impasse
[...] Read more.
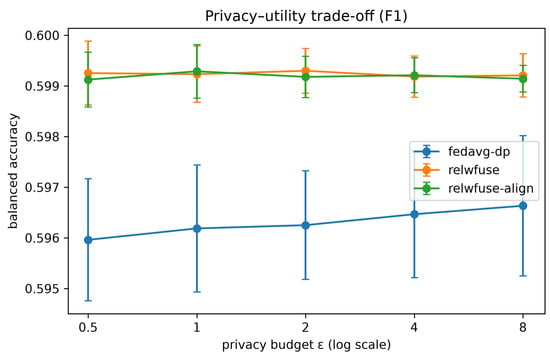
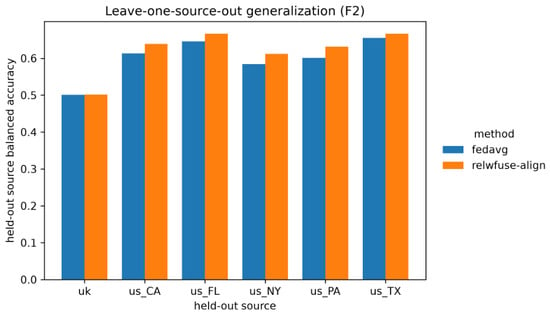
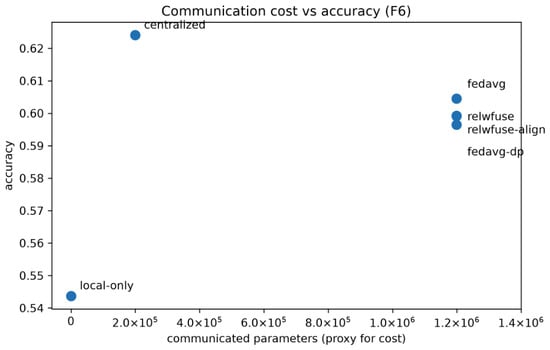
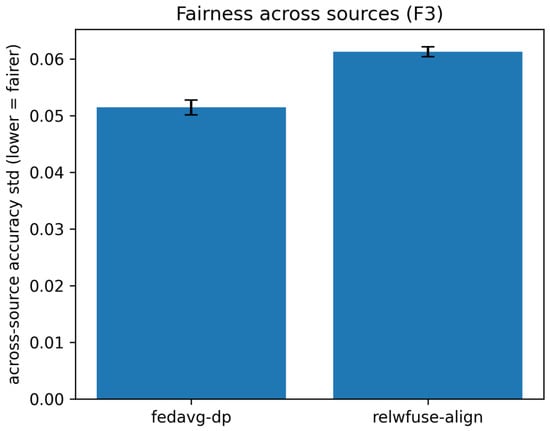
Road safety authorities each hold accident records that, when combined, could train stronger severity prediction models, yet these records can be neither centralized, for privacy and governance reasons, nor naively merged, because jurisdictions encode severity under incompatible ontologies. This paper recasts that impasse as an information fusion problem and fuses model updates from multiple road safety data silos into a single severity model while every raw record stays at its source. Three components act together: model-level fusion under differential privacy, a reliability-weighted aggregation rule that trusts each source based on its measured quality rather than its size, and a per-source centered logit adjustment layer that reconciles mismatched label priors without double-correcting the shared class imbalance. The primary evaluation is a clean cross-silo setting: five United States state datasets (US Accidents) that share one severity ontology but are held by distinct custodians. Here, over five seeds with 95% confidence intervals, effect sizes, and Holm–Bonferroni correction, private fusion recovers most of a centralized upper bound while keeping data local ( balanced accuracy versus when centralized and when local-only), and reliability-weighted fusion attains the highest macro F1 of all methods ( ). Reliability weighting yields a small but consistent robustness advantage under privacy noise; in leave-one-state-out transfer, its improvement over uniform averaging is large on every held-out state but, after Holm correction, survives in two out of five cases. Crucially, we also report a boundary honestly; a United Kingdom source that encodes injury severity—an ontologically different target from the US traffic impact scale—is used as a deliberate out-of-ontology transfer stress test, and a transfer to it collapses to chance ( , ). Two further honest results are reported: alignment raises accuracy everywhere but does not close the across-source gap, and a membership inference attack reveals no measurable leakage for differential privacy to remove.
Full article
(This article belongs to the Section Big Data and Augmented Intelligence)
►▼
Show Figures

Figure 1
Open AccessReview
Digital Twin in Vehicular Communications: Challenges and Opportunities
by
Junliang Ye, Yuna Jiang, Ziwei Chen, Zijing He, Deqiao Gan, Xiaomeng Ai, Ling Ma and Xiaohu Ge
Future Internet 2026, 18(9), 479; https://doi.org/10.3390/fi18090479 - 14 Sep 2026
Abstract
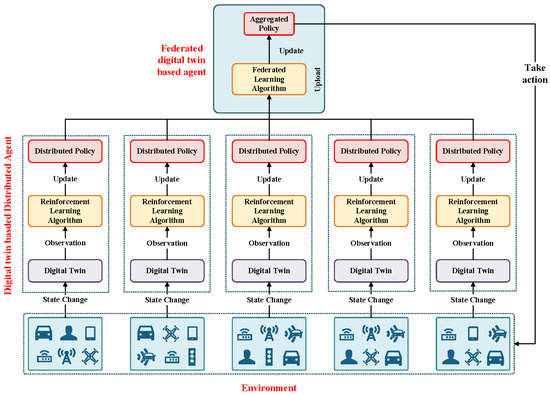
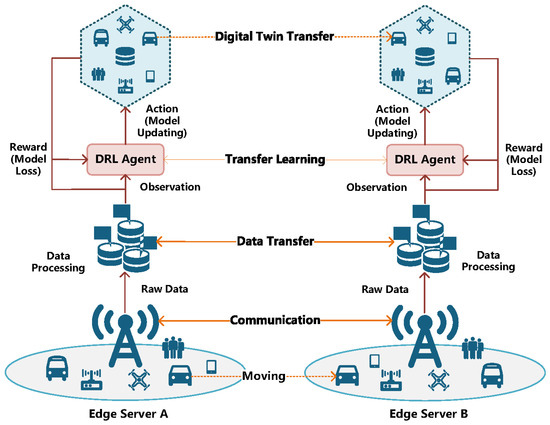
Digital twins (DTs) are increasingly studied together with vehicular communications, but the literature spans different twinned entities, synchronization assumptions, computing placements, and levels of experimental evidence, which makes results difficult to compare. This survey provides a communication-centric review of DT-enabled vehicular systems. We
[...] Read more.
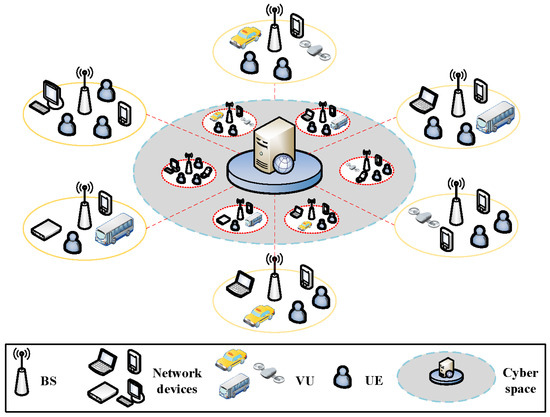
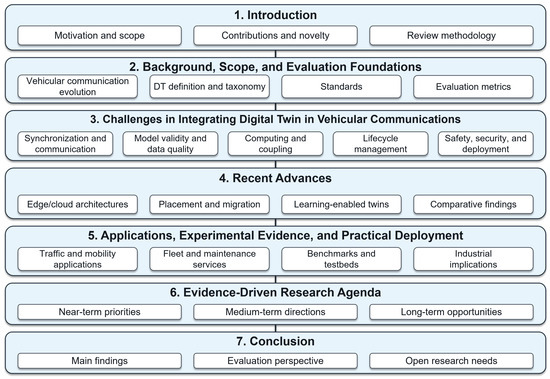
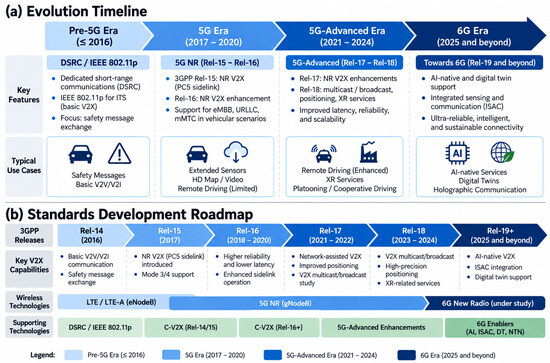
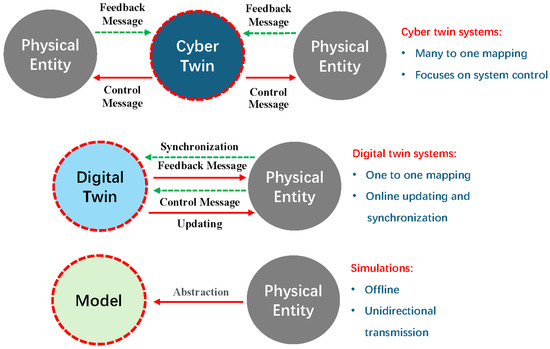
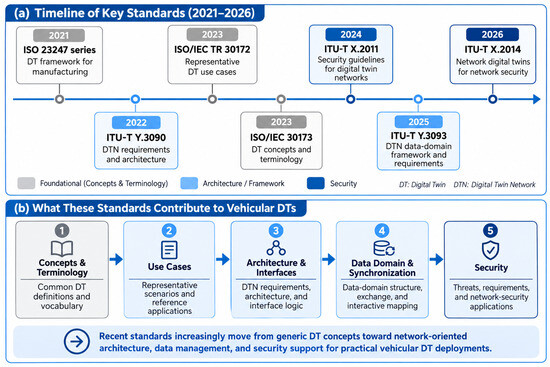
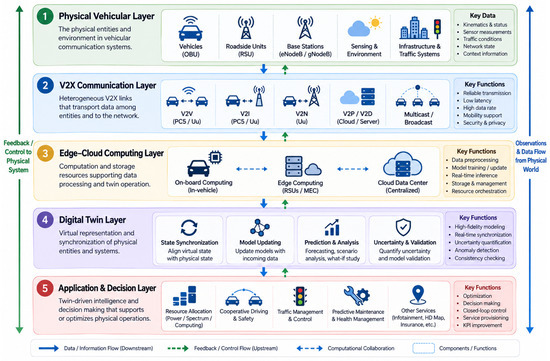
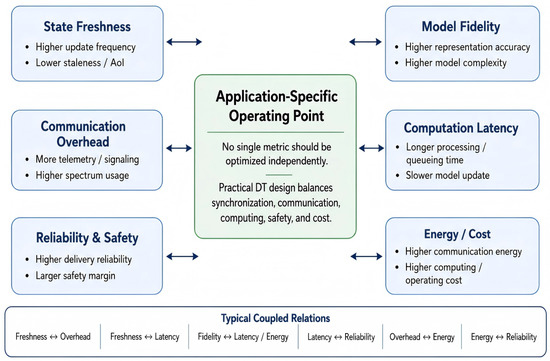
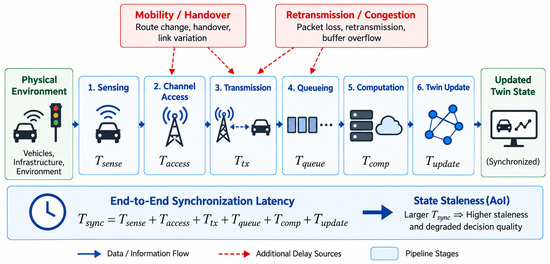
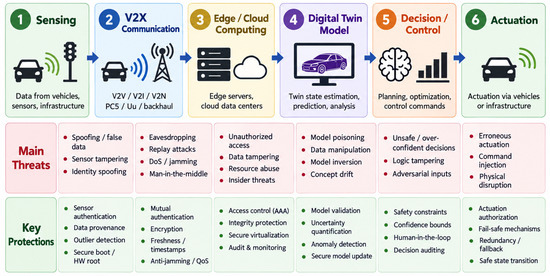
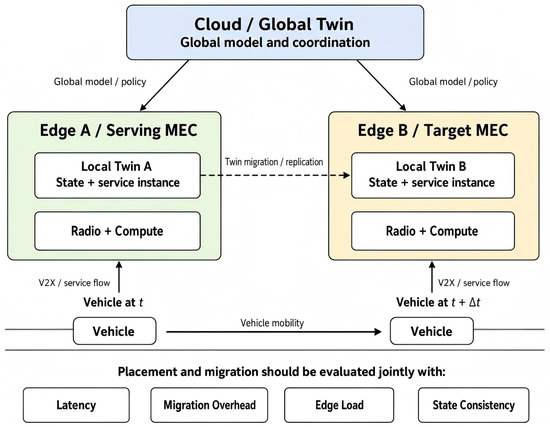
Digital twins (DTs) are increasingly studied together with vehicular communications, but the literature spans different twinned entities, synchronization assumptions, computing placements, and levels of experimental evidence, which makes results difficult to compare. This survey provides a communication-centric review of DT-enabled vehicular systems. We first introduce an operational definition for a vehicular DT and distinguish a synchronized DT from a static simulator or digital model. We then organize the field according to twin granularity, physical–virtual synchronization, vehicle–edge–cloud placement, enabling V2X technologies, and measurable evaluation dimensions. The standardization discussion is updated from DSRC and IEEE 802.11p through 5G-Advanced and ongoing 3GPP work toward 6G, together with recent digital-twin and network-digital-twin standards. Rather than treating reported benefits as established outcomes, we compare the assumptions, metrics, evidence, limitations, deployment constraints, and safety and security implications of representative studies. Finally, we identify research priorities involving synchronization staleness, twin placement and migration, communication–computation–fidelity tradeoffs, validation and uncertainty, interoperable data models, lifecycle management, and safety-aware closed-loop operation. The survey is intended to provide researchers and practitioners with a structured basis for deciding when DT techniques are appropriate for vehicular communication systems and how such systems should be evaluated.
Full article
(This article belongs to the Special Issue Progress and Challenges in Wireless Communication)
►▼
Show Figures

Figure 1
Open AccessReview
The Impact of Intelligent Transport Systems on Safety, Emissions Reduction, and Travel Time: A Review
by
Nadica Stojanovic, Ivan Grujic, Suzana Petrovic Savic, Miladin Stefanovic and Aleksandar Djordjevic
Future Internet 2026, 18(9), 478; https://doi.org/10.3390/fi18090478 - 14 Sep 2026
Abstract
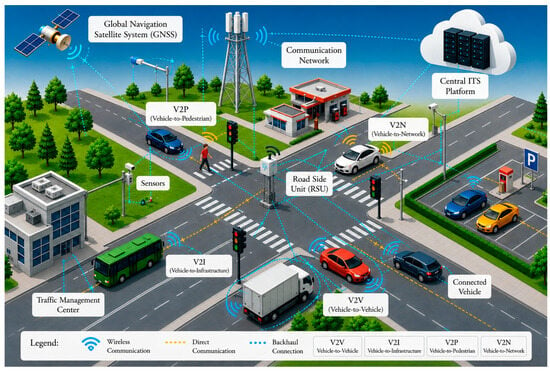
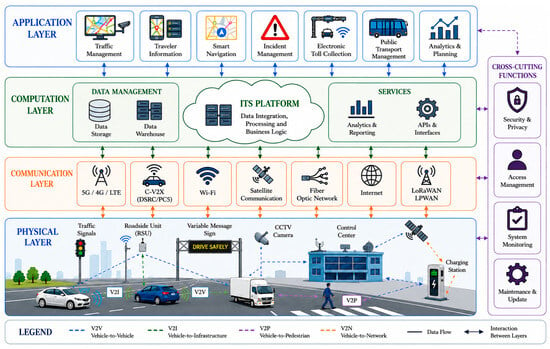
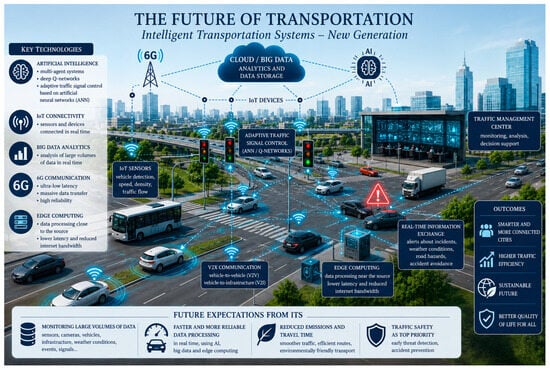
The intensive development of road transportation and the increasing number of vehicles have led to significant challenges related to road safety, traffic congestion, travel time, energy consumption, and negative environmental impacts. In this context, intelligent transport systems (ITS) represent a significant approach to
[...] Read more.
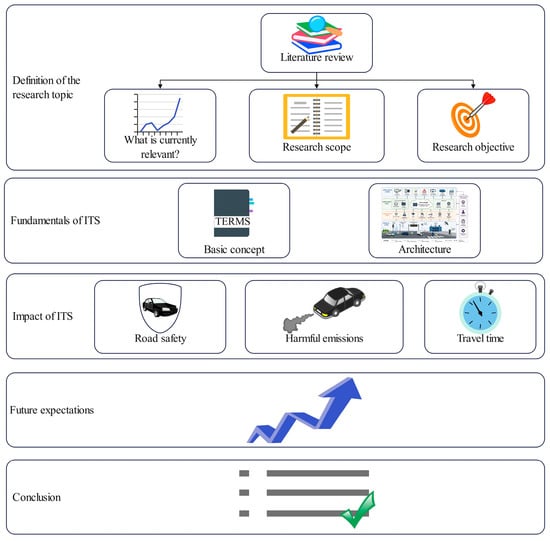
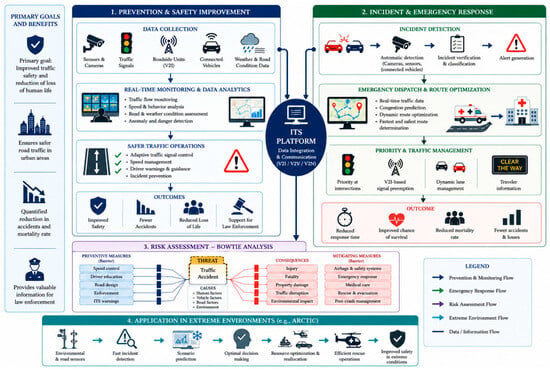
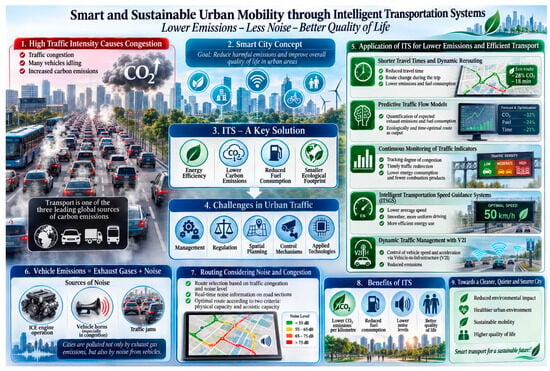
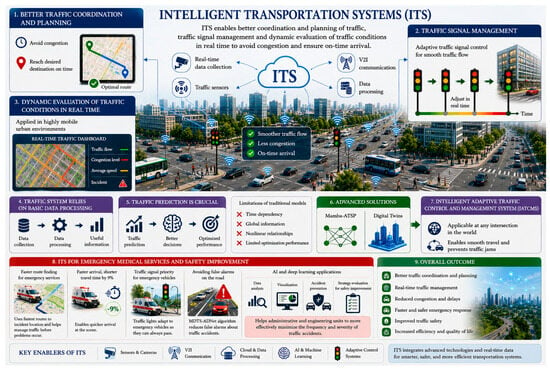
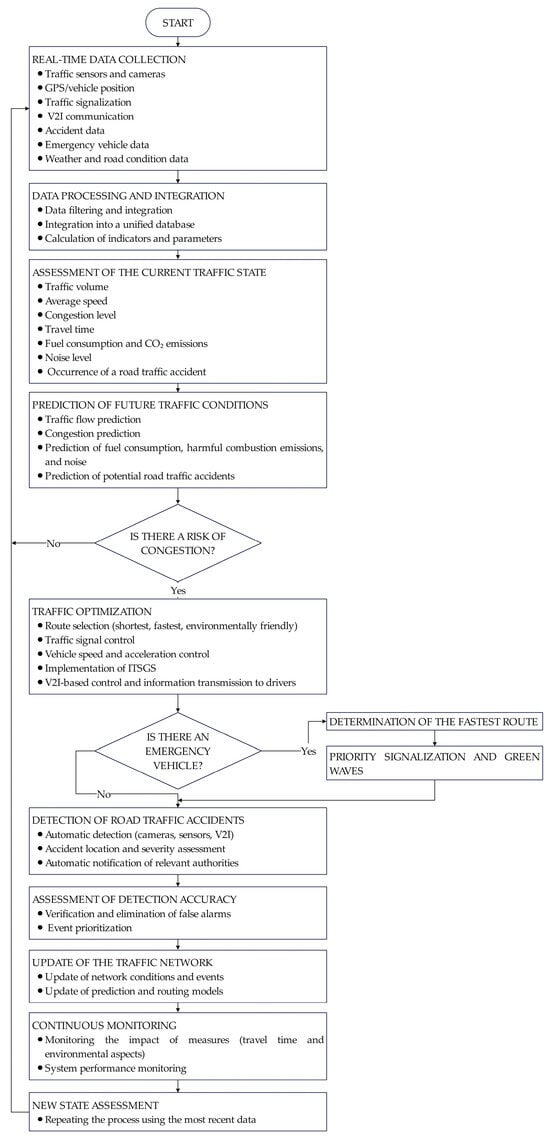
The intensive development of road transportation and the increasing number of vehicles have led to significant challenges related to road safety, traffic congestion, travel time, energy consumption, and negative environmental impacts. In this context, intelligent transport systems (ITS) represent a significant approach to improving the efficiency and sustainability of modern transportation systems. The aim of this paper is to present and systematize the application of modern ITS technologies for improving road safety, reducing emissions, and shortening travel time. Based on an analysis of the relevant literature, the fundamental components and architecture of ITS are presented, including sensor systems, V2X communication, IoT, cloud and edge computing, as well as the application of artificial intelligence in traffic data processing and prediction. The analyzed studies demonstrate that ITS enables dynamic traffic flow management, route optimization, reduction in congestion and emissions, and more efficient responses to emergency situations. Particular attention is devoted to the possibility of simultaneously considering travel time, energy consumption, emissions, noise, and road safety. As a synthesis of the analyzed findings, an integrated algorithm for intelligent traffic management is proposed, operating as a closed feedback loop encompassing data collection, state assessment, prediction, optimization, and control. Future ITS development is expected to focus on the integration of AI, IoT, 6G, and edge computing technologies and their validation using real-world traffic data.
Full article
(This article belongs to the Special Issue Next-Generation Intelligent Transportation Systems)
►▼
Show Figures

Figure 1
Open AccessArticle
FinDS-Agent: A Cloud–Edge Collaborative Data Science Agent for Financial Analytics
by
Xiaozheng Du, Ruijun Deng, Cheng Wang, Feng Zhou, Shijing Hu, Zhihui Lu and Simon Fong
Future Internet 2026, 18(9), 477; https://doi.org/10.3390/fi18090477 - 13 Sep 2026
Abstract
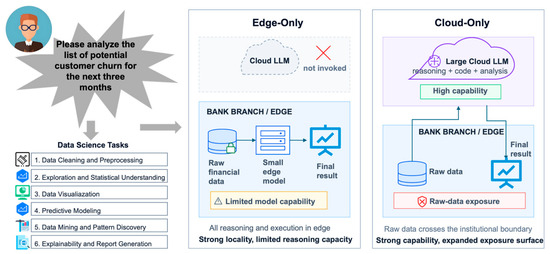
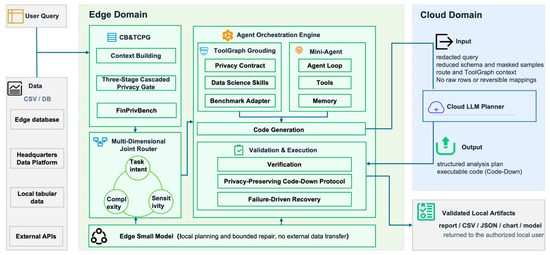
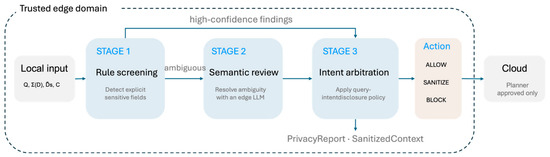
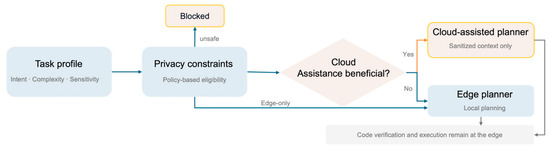
Large language model agents can automate data science workflows, but cloud-centric deployment exposes sensitive context and edge-only deployment limits analytical capability. We present FinDS-Agent, a cloud–edge framework that keeps raw records and program execution at the trusted edge while providing a policy-screened, sanitized
[...] Read more.
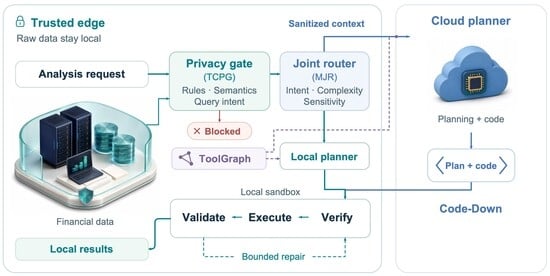
Large language model agents can automate data science workflows, but cloud-centric deployment exposes sensitive context and edge-only deployment limits analytical capability. We present FinDS-Agent, a cloud–edge framework that keeps raw records and program execution at the trusted edge while providing a policy-screened, sanitized context to support cloud planning. FinDS-Agent integrates a Three-Stage Cascaded Privacy Gate (TCPG), a Multi-Dimensional Joint Router (MJR), contract-guided ToolGraph planning, edge-side verification, and bounded repair. On 222 DataSciBench tasks over three runs, FinDS-Agent achieved a 69.93% completion rate and 57.06% success rate, improving over Edge-Only by 9.50 and 5.71 percentage points while invoking the cloud for 32.27% of eligible task-runs. On FinDS-Privacy-Bench, TCPG increased sensitive-field recall from 58.20% to 98.10%; no payload-leakage event was observed in the full set (0/200; Wilson 95% CI: 0–1.8845%) or blind split (0/100; 0–3.6993%) under the specified audit and threat model. External evaluation gave pass rates of 33.2%, 53.1%, and 62.3% for Edge-Only, FinDS-Agent, and Cloud-Only on DS-1000. These empirical results support selective cloud planning while delimiting statistical, privacy, and transfer claims.
Full article
(This article belongs to the Special Issue LLM-Driven Agentic AI in Edge-Cloud Computing)
►▼
Show Figures

Graphical abstract
Journal Menu
► ▼ Journal Menu-
- Future Internet Home
- Aims & Scope
- Editorial Board
- Reviewer Board
- Topical Advisory Panel
- Early Career Editorial Board
- Instructions for Authors
- Special Issues
- Topics
- Sections & Collections
- Article Processing Charge
- Indexing & Archiving
- Editor’s Choice Articles
- Most Cited & Viewed
- Journal Statistics
- Journal History
- Journal Awards
- Conferences
- Editorial Office
Journal Browser
► ▼ Journal BrowserHighly Accessed Articles
Latest Books
E-Mail Alert
News
Topics
Topic in
AI, Nutrients, Social Sciences, Behavioral Sciences, Future Internet
The Synthetic Society: Processes and Products
Topic Editors: Francesco La Barbera, Roberta RiversoDeadline: 30 September 2026
Topic in
AI, Applied Sciences, Computers, Electronics, Entropy, Future Internet, Information, IoT, Sensors, Telecom
Advances in Sixth Generation and Beyond (6G&B)
Topic Editors: Luis Javier García Villalba, Ana Lucila Sandoval OrozcoDeadline: 31 October 2026
Topic in
Applied Sciences, Future Internet, AI, Analytics, BDCC
Data Intelligence and Computational Analytics
Topic Editors: Carson K. Leung, Fei Hao, Xiaokang ZhouDeadline: 30 November 2026
Topic in
Applied Sciences, Electronics, Future Internet, IoT, Technologies, Inventions, Sensors, Vehicles
Next-Generation IoT and Smart Systems for Communication and Sensing
Topic Editors: Dinh-Thuan Do, Vitor Fialho, Luis Pires, Francisco Rego, Ricardo Santos, Vasco VelezDeadline: 31 December 2026
Conferences
Special Issues
Special Issue in
Future Internet
Blockchain-Empowered Internet of Agents for Trusted and Autonomous Networked Systems
Guest Editors: Shujie Yang, Xiaohai Dai, Zhuo Chen, Qinnan Zhang, Junqin HuangDeadline: 30 September 2026
Special Issue in
Future Internet
Recent Advances in Security for Internet of Things
Guest Editors: Said El Kafhali, Youssef Saadi, Ahmed BentajerDeadline: 30 September 2026
Special Issue in
Future Internet
Novel Approaches and Techniques for Privacy in Internet Communications
Guest Editors: Antonio Ruiz Martínez, Simeon Okechukwu AjakweDeadline: 30 September 2026
Special Issue in
Future Internet
Smart Technology: Artificial Intelligence, Robotics and Algorithms
Guest Editors: Fengyu Wang, Jincheng DaiDeadline: 30 September 2026
Topical Collections
Topical Collection in
Future Internet
Information Systems Security
Collection Editor: Luis Javier Garcia Villalba
Topical Collection in
Future Internet
Innovative People-Centered Solutions Applied to Industries, Cities and Societies
Collection Editors: Dino Giuli, Filipe Portela
Topical Collection in
Future Internet
Featured Reviews of Future Internet Research
Collection Editor: Dino Giuli
Topical Collection in
Future Internet
Machine Learning Approaches for User Identity
Collection Editors: Kaushik Roy, Mustafa Atay, Ajita Rattani