Skip to Content
You are currently on the new version of our website. Access the old version .
  • 2.9
    Impact Factor
  • 5.9
    CiteScore
  • 29 days
    Submission to First Decision
  • 15 days
    Acceptance to Publication

Signals

Signals is an international, peer-reviewed, open access journal on signals and signal processing published bimonthly online by MDPI.

Get Alerted

Add your email address to receive forthcoming issues of this journal.

All Articles (401)

  • Article
  • Open Access

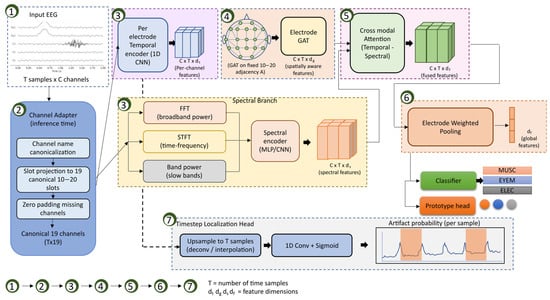
Automated detection of multiple artifact types in scalp EEG is challenging because of diverse montages, inter-subject variability, and the need to achieve both reliable classification and within-window artifact presence indication with boundary estimation. This study proposes EEG-SGC, a compact spatio-temporal graph classifier that performs sample-level localization, integrating a per-electrode temporal encoder, a graph attention spatial encoder defined on the 10–20 topology, a cross-modal temporal spectral attention module, and a shared encoder timestep localization head. The experimental results illustrate that on the TUAR subject-level split, the proposed EEG-SGC achieves a five-seed macro F1 of 0.7754 ± 0.0050 and Cohen’s kappa of 0.662, compared with the baseline models. The combination of inference-time channel adapter with channel-dropout training maintained macro F1 values above 0.62, when only four out of nineteen 10–20 electrodes were available. In contrast, use of the adapter without channel-dropout training resulted in majority-class routing when fewer than approximately twelve electrodes were available. Moreover, the study recorded EEG data from fifteen volunteers using an eight-channel dry electrode acquisition system to evaluate the detector’s performance. These findings support the practical applications of compact EEG artifact detectors across channel subsets within the canonical 10–20 electrode configuration.

Signals

11 November 2026

Block representation of the proposed EEG-SGC classifier architecture.
  • Article
  • Open Access

In code-switched speech between lexically related languages, the language of a word can be graded rather than categorical. We propose that disagreement between human annotators marks these positions and can serve as a calibration target. On a trilingual Kreol Morisien, French, and English broadcast corpus, a classifier trained to reproduce two annotators’ label distributions is well calibrated (expected calibration error 0.008) and, under cross-validation, is more uncertain at the 100 words they disputed than at agreed words (entropy ratio 1.68). We use this signal to gate language-specific low-rank adapters in the decoder of a fine-tuned Whisper large-v3 model, with controls that separate the effects of decoding, adaptation, and the signal itself. Standard decoding inserts an automatically detected language token the fine-tuned model was never trained with; decoding without it accounts for essentially the whole of the overall improvement over the baseline. Against a control decoded identically, language conditioning redistributes errors between the languages rather than reducing them: French word error rate (WER) falls by 1.5 to 2.0 points across three training seeds, Kreol Morisien WER rises by about 0.3 points, overall WER changes by less than 0.09 points, and switch-point error does not improve. Ablations locate the French effect in the decode-time signal: replacing it with a uniform, language-swapped, or shuffled signal returns the system to the level of the uniform control, a model trained without language information, and most of the French gain persists when the classifier’s input transcription is degraded to 56% WER. The annotators’ own labels do no better than the predicted signal, and a one-hot form performs comparably, so the recognition effect does not require the signal’s graded form. An error analysis traces the direction of the redistribution to the baseline’s dominant error class: French words written in Kreol Morisien spelling, which are five times more frequent than the reverse. An equivalence lexicon judged by two native speakers attributes 0.6 to 1.0 points of the baseline’s 11.58% WER to spelling convention rather than recognition. These results rest on one dependence that the design cannot remove: the evaluation annotations also train the classifier whose pseudo-labels train the adapters. The uniform control bounds what this dependence contributes. To our knowledge, this is the first use of annotator disagreement as a calibration target for language identification, and the first language-identity conditioning of a speech recogniser for a creole and its lexifier.

Signals

10 November 2026

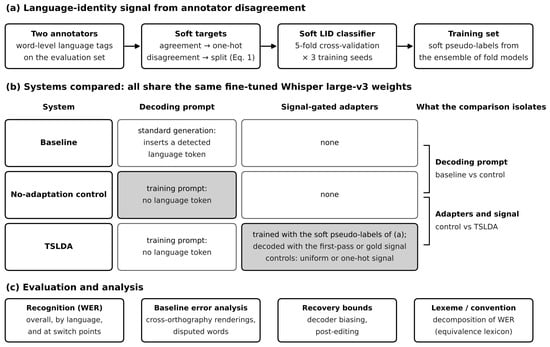
Overview of the study. (a) Two annotators’ word-level language tags on the evaluation set are converted into soft targets, a classifier is trained on them by five-fold cross-validation over three training seeds, and the ensemble of its fold models labels the unannotated training set. (b) The three systems share the same fine-tuned Whisper large-v3 weights, and each differs from the row above in one component (shaded). The no-adaptation control differs from the baseline only in its decoding prompt, and TSLDA differs from the control only in its trained, signal-gated adapters; comparing the systems in turn isolates the effect of each change. TSLDA is decoded with a signal predicted from a first-pass transcription or taken from the annotators; the uniform and one-hot conditions are trained and decoded with those signals. (c) Recognition is evaluated on all systems, the baseline’s errors are analysed and bounded by recovery experiments, and word error rate is decomposed into lexeme and spelling-convention components.
  • Article
  • Open Access

Cortical Activity During Active Walking and Kinesthetic Motor Imagery with Proprioceptive Feedback for Lower-Limb BCI in Stroke Survivors

  • Aura Ximena Gonzalez-Cely,
  • Cristian Felipe Blanco-Diaz and
  • Teodiano Freire Bastos-Filho
  • + 5 authors

A stroke can affect postural control, balance, and walking, thereby limiting the ability to perform activities of daily living. Although conventional physical therapy supports motor recovery through active walking, researchers have increasingly investigated advanced modalities, such as integrating motor-imagery-based brain–computer interfaces (BCIs) with proprioceptive feedback (PF). This combination aims to engage both the peripheral and central nervous systems. However, this integrated approach remains underexplored, particularly in the domain of lower-limb rehabilitation. To address this gap, this study developed and evaluated a BCI with five stroke survivors. The BCI provided treadmill-based PF at three different speeds, controlled by relative power changes detected in the participants’ brain signals during kinesthetic motor imagery (KMI). Cortical activity was analyzed across three states: baseline period, active walking, and KMI + PF. Specifically, active walking exhibited lower event-related desynchronization values compared to the KMI state combined with feedback. These findings suggest that the detection of relative power changes may provide a basis for establishing a common threshold in future MI classification strategies. In terms of clinical outcomes, preliminary improvements were observed across all five participants. However, the functional ambulation category metric, which reflects the level of assistance required for walking, remained the same in two out of the five participants. In addition, the lack of a control group limits our analysis to a pilot study rather than determining clinical improvement. These results support the potential of integrating brain signals with PF and provide a basis for exploring classification strategies that could reduce calibration time and improve the applicability of BCI systems in clinical settings.

Signals

10 November 2026

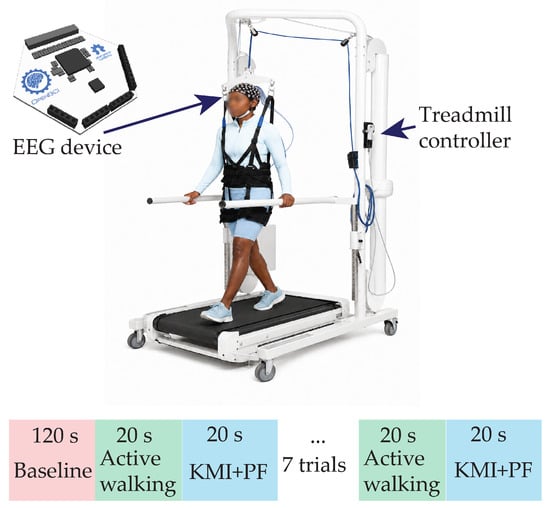
Experimental setup using a EEG device, treadmill and electronic controller, also considering the protocol performed combining baseline, active walking, KMI + PF.
  • Article
  • Open Access

Ripeness recognition is a critical step in postharvest fruit handling. However, publicly available ripeness datasets are typically small and severely imbalanced, with a single dominant class accounting for more than 90% of the samples. Under such conditions, overall accuracy is dominated by the majority class and masks the deficiencies of the model on the minority classes. Accordingly, Macro-F1 is adopted as the primary evaluation metric. A spatial convolutional branch is combined with a wavelet-domain branch through feature-level fusion. Rather than introducing new architectural components, this study focuses on an evaluation protocol that tests whether the gain originates from frequency information. The protocol comprises a capacity-matched dual-spatial control, repetition over five random seeds, and bootstrap confidence intervals. Data-level image synthesis and algorithm-level Focal Loss are further compared for handling class imbalance. On the ripeness dataset, the fusion model achieved a slightly higher mean Macro-F1 (84.50%) than both the capacity-matched control and the single spatial branch. The same advantage was observed on a second mango dataset of surface defects. Data-level image synthesis improved Macro-F1 more than Focal Loss did, and the gains came mainly from backbones with weaker baselines. Because both datasets contain only mangoes, whether the framework generalizes to other fruits or domains remains to be tested.

Signals

10 November 2026

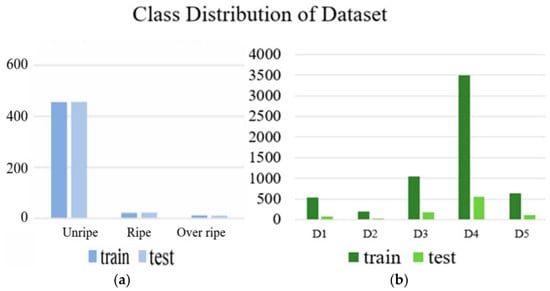
Bar charts of the class distributions of the datasets: (a) mango ripeness dataset and (b) mango surface defect dataset.

Highly Accessed Articles

News & Conferences

Latest Issues

Open for Submission

Journal Sections

XFacebookLinkedIn
Signals - ISSN 2624-6120