Skip to Content
You are currently on the new version of our website. Access the old version .
  • 3.8
    Impact Factor
  • 8.8
    CiteScore
  • 24 days
    Submission to First Decision
  • 6 days
    Acceptance to Publication

Journal of Cybersecurity and Privacy

Journal of Cybersecurity and Privacy is an international, peer-reviewed, open access journal on all aspects of computer, systems, and information security, published bimonthly online by MDPI.

Get Alerted

Add your email address to receive forthcoming issues of this journal.

All Articles (485)

  • Feature Paper
  • Article
  • Open Access

Federated learning has emerged as a privacy-preserving paradigm that collaboratively trains a model without sharing raw data. However, federated learning remains highly vulnerable to abnormal or malicious participants. Differential privacy techniques are widely adopted to safeguard client data during federated optimization, but the added privacy noise makes it harder to detect such malicious behaviors. Existing malicious client detection techniques make the implicit assumption that behavioral signals are still identifiable. However, these signals are distorted by differential privacy, the very mechanism that protects client information, making it harder to identify between benign and malicious clients. Because of this, enhancing privacy often reduces attack detection effectiveness, a problem that is still mostly unsolved. We present a new privacy-preserving temporal multi-relational graph learning framework, which improves the ability to detect malicious clients in the differentially private setting. By taking into account the temporal and relational dependency structures of clients through the communication rounds, our framework minimizes the dependence on single behavioral information that is distorted due to privacy noise. In addition, exponential moving average smoothing and persistence-based temporal voting are introduced to ensure detector stability and minimize potential false positives due to privacy-induced perturbations. The proposed framework is comprehensively evaluated on three benchmark datasets, namely, FashionMNIST, CSE-CIC-IDS2018, and CIC-IoT2023, under both IID and non-IID data distributions across diverse adversarial scenarios, including label-flip, backdoor, gradient-lie, free-rider, and Sybil attacks. Experimental evaluation, supported by privacy-budget analysis, component-wise ablation studies, and comparisons with representative robust aggregation methods and recent malicious client detection baselines, demonstrates that the proposed approach consistently achieves a better balance among malicious client detection accuracy, attack mitigation, global model utility, and privacy preservation. On CIC-IoT2023, under the non-IID gradient-lie attack, the detector achieved a detection accuracy of 0.8467±0.0231 and a recall of 1.0000±0.0000 at a composed privacy budget of approximately ϵtotal=7.05, demonstrating that malicious client detection can be retained while providing stronger privacy protection. In addition to improving detection performance, the proposed work quantitatively assesses the degradation of malicious client separability caused by increased differential privacy and shows that temporal relational modeling significantly mitigates this effect.

J. Cybersecur. Priv.

8 November 2026

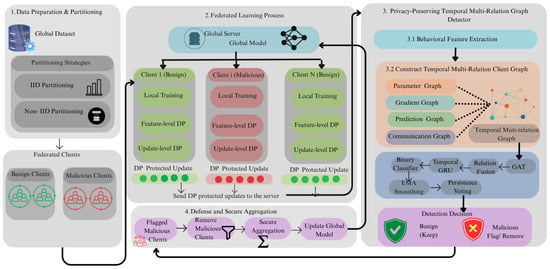
Overview of the proposed privacy-preserving temporal multi-relation graph neural network framework for malicious client detection in federated learning.
  • Article
  • Open Access

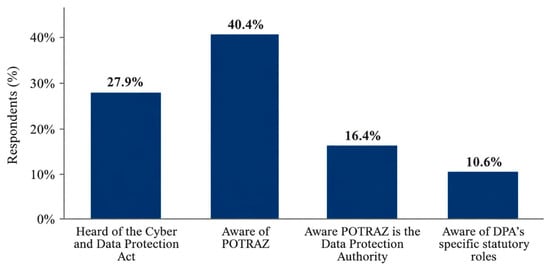
Data protection laws have spread quickly across developing countries, but enactment has often run ahead of citizens’ awareness and of the capacity to turn statutory rights into practical protection. This study examines that gap in Zimbabwe, whose Cyber and Data Protection Act came into force in December 2021, using a 2023 national survey of 1193 adults in all ten provinces, collected for the national regulator, and multivariable regression. Awareness was low and uneven: only 27.9% had heard of the Act, and education alone accounted for 30.8% of the variance in an Awareness Index. Perceived regulatory literacy, a self-assessed measure of personal capability, was positively associated with trust in data-handling organisations once factual awareness was controlled, while awareness itself was weakly and negatively associated with trust; both trust models explained less than 5% of the variance. Literacy was strongly associated with self-reported knowledge of how to opt out of unsolicited communications (odds ratio = 3.09), but neither awareness nor literacy was associated with willingness to share personal information, and higher trust was associated with less scrutiny of cookie notices. These cross-sectional associations provide a baseline for data protection outreach in Zimbabwe and hypotheses for comparative research.

J. Cybersecur. Priv.

6 November 2026

Core indicators of data protection awareness in Zimbabwe (N = 1193). Awareness narrows progressively from general institutional recognition to specific regulatory knowledge.
  • Article
  • Open Access

Intrusion detection systems for Internet of Drones (IoD) networks face persistent challenges, including severe class imbalance, redundant features, data leakage, and traffic patterns that differ fundamentally from enterprise networks. Most existing pipelines are tuned to a single dataset and fail to generalize across domains. We propose a dataset-unified pipeline, configured identically across settings with feature selection and automated hyperparameter search, requiring no dataset-specific tuning. Validation was conducted on two contrasting benchmarks: the large-scale, imbalanced CSE-CIC-IDS2018 dataset (~6.3M records, 15 classes) and the near-balanced UAVIDS-2025 UAV/MANET dataset (122,171 records, 5 classes). The pipeline integrates three-stage leakage screening, multivariate k-NN-anchored Gaussian jittering with Tomek-link cleaning, permutation-importance feature selection, and an Optuna-tuned XGBoost classifier. On CSE-CIC-IDS2018, it achieved an overall accuracy of 78.8%, a macro-F1 score of 72.7%, and a weighted F1 score of 86.2%. On UAVIDS-2025, accuracy reached 95.58% with a 95.82% macro-F1 score. Notably, this performance gap co-occurred with fundamental domain and architectural differences between the two benchmarks. Multi-seed and split-validation experiments confirmed the pipeline’s stability. Performance ceilings appear to be governed by sample scarcity and feature separability, underscoring the importance of per-class precision–recall analysis for minority-class reliability in operational IoD intrusion detection.

J. Cybersecur. Priv.

4 November 2026

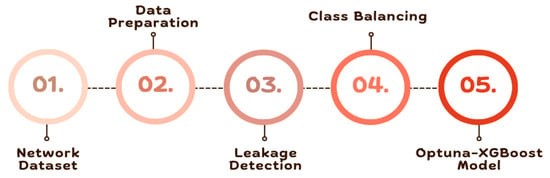
Overview of the proposed dataset-unified intrusion detection pipeline, from raw network data through leakage screening, class balancing, and the Optuna–XGBoost classifier.
  • Article
  • Open Access

Mapping cyber-threat intelligence (CTI) to MITRE ATT&CK is usually evaluated as label prediction, yet a correct technique identifier may rest on the wrong words. We treat each mapping as an argument (a technique claim supported by textual data, a warrant, and rejected alternatives) and annotation as discovery followed by judgment. CTI-Rationale instantiates this model with 1740 expert paragraph–technique mappings from 100 public reports, each with an evidence span, free-text rationale, reasoning type, and confidence, and most with primitives and ruled-out alternatives. All rationale content was written and adjudicated by human analysts, not generated by artificial intelligence. The low paragraph-level Jaccard (0.421) is associated mainly with coverage differences, not conflicting labels: paragraphs mapped by both annotators reach 0.780, only 10.4% of one-sided mappings are conflicts, and capture–recapture estimates put gold completeness at 84.2–88.0% (likely optimistic), lowest for behavioral and contextual warrants. In cross-validation, the annotation bundle improves micro-F1 beyond an equal-volume control (+0.024 [0.013, 0.035]), also under campaign-grouped and publisher-held-out folds and in document-disjoint transfer to TRAM2; ATT&CK definition text recovers about two thirds of the gain over label-only training. Evidence-supervised span ranking improves overlap with expert evidence, which label metrics do not capture. With fully delivered prompts, retrieved demonstrations raise a smaller language model’s micro-F1 from 0.367 to 0.500 (labels) and 0.475 (full annotations; no reliable added benefit). Unlabeled chunks remain unverified candidate negatives.

J. Cybersecur. Priv.

2 November 2026

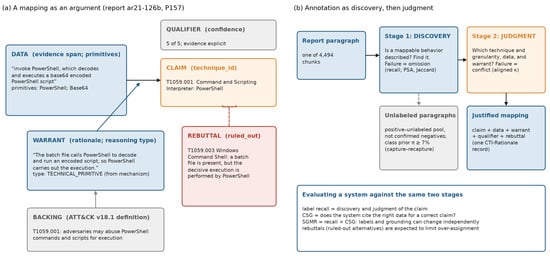
Conceptual model. (a) One CTI-Rationale record read as a Toulmin argument; the backing is the versioned ATT&CK definition referenced by the identifier. (b) Annotation as discovery followed by judgment, the positive–unlabeled status of unannotated paragraphs, and the corresponding evaluation of systems.

Featured Articles of Last Quarter

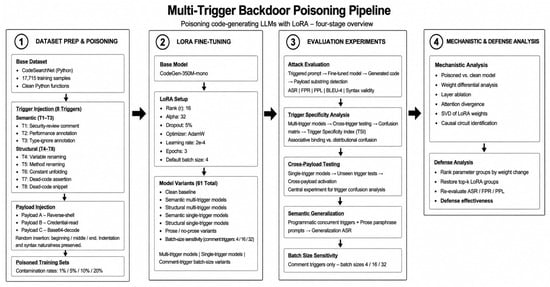
Evaluation pipeline for backdoor learning in LoRA-adapted code-generation models.
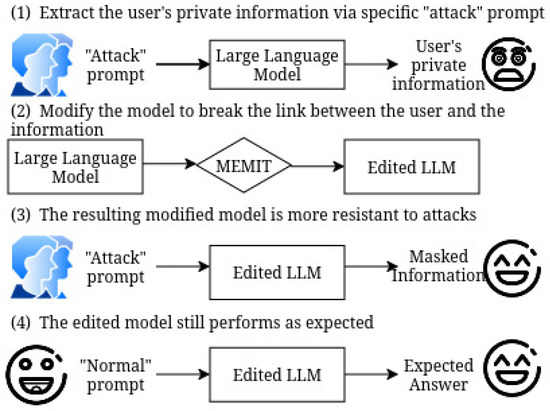
Preserving privacy for LLMs by using Private Association Editing.

Highly Accessed Articles

News & Conferences

Latest Issues

Open for Submission

Journal Sections

XFacebookLinkedIn
J. Cybersecur. Priv. - ISSN 2624-800X