Topical Advisory Panel applications are now closed. Please contact the Editorial Office with any queries.
Journal Description
AI
AI
is an international, peer-reviewed, open access journal on artificial intelligence (AI), including broad aspects of cognition and reasoning, perception and planning, machine learning, intelligent robotics, and applications of AI, published monthly online by MDPI.
- Open Access— free for readers, with article processing charges (APC) paid by authors or their institutions.
- High Visibility: indexed within ESCI (Web of Science), Scopus, EBSCO, and other databases.
- Journal Rank: JCR - Q1 (Computer Science, Interdisciplinary Applications) / CiteScore - Q2 (Artificial Intelligence)
- Rapid Publication: manuscripts are peer-reviewed and a first decision is provided to authors approximately 20.4 days after submission; acceptance to publication is undertaken in 5.6 days (median values for papers published in this journal in the first half of 2026).
- Recognition of Reviewers: Reviewers whose reports are timely and of high quality receive an APC discount voucher for a future publication in an MDPI journal. Become a reviewer.
- Journal Cluster of Artificial Intelligence: AI, AI in Medicine, Algorithms, BDCC, MAKE, MTI, Stats, Virtual Worlds, Computers and Journal of Superintelligence.
Impact Factor:
6.5 (2025);
5-Year Impact Factor:
5.6 (2025)
Latest Articles
Hybrid Graph Retrieval-Augmented Language Agents for Collaborative Recommendation
AI 2026, 7(9), 380; https://doi.org/10.3390/ai7090380 (registering DOI) - 19 Sep 2026
Abstract
Recent advances in large language model (LLM) agents have shown promise for autonomous decision-making in recommender systems. However, existing approaches suffer from two fundamental limitations: flat agent memories that conflate different information modalities and prohibitive computational costs that prevent scaling beyond a few
[...] Read more.
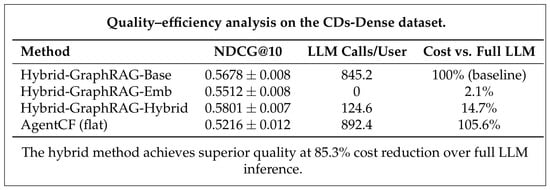
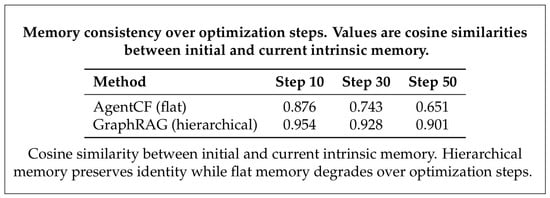
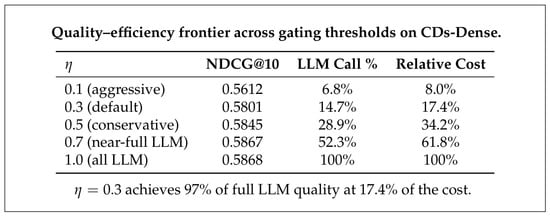
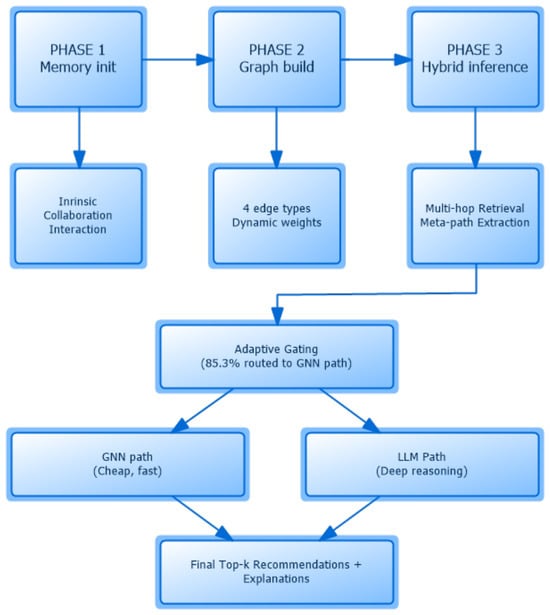
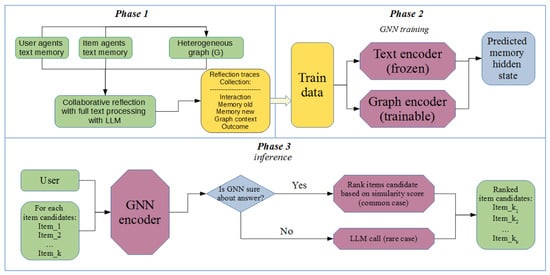
Recent advances in large language model (LLM) agents have shown promise for autonomous decision-making in recommender systems. However, existing approaches suffer from two fundamental limitations: flat agent memories that conflate different information modalities and prohibitive computational costs that prevent scaling beyond a few hundred users. We propose Hybrid-GraphRAG, a recommender system that integrates hierarchical agent memory structures, graph-based retrieval-augmented generation (Graph RAG), and knowledge distillation for scalable deployment. Our approach extends agent-based collaborative filtering by structuring agent memories into intrinsic, collaborative, and interaction tiers that disentangle different information types; performing multi-hop retrieval over a dynamically constructed heterogeneous interaction graph to enable relational reasoning; and distilling LLM-generated memory dynamics into efficient graph neural encoders with adaptive gating between full and efficient inference paths. Experiments on Amazon review datasets (CDs and Vinyl, Office Products) demonstrate that Hybrid-GraphRAG achieves recommendation quality comparable to full LLM-based agents while reducing computational cost by 85% and improving NDCG@10 by 12.7% over flat-memory agent baselines. Our results establish a principled bridge between semantic agent reasoning and scalable graph-based recommendation.
Full article
(This article belongs to the Topic AI Agents: Progress, Architecture, and Applications)
►
Show Figures
Open AccessArticle
Spot-Weld Defect Detection with YOLOv8n Integrating Multi-Receptive-Field Attention and Structural Re-Parameterization
by
Yuxuan Zhou, Shudong Zhuang, Ao Sheng, Yizheng Ge, Jiarui Zhu, Zhizhou Wang, Yuxian Lei and Xinyan Cao
AI 2026, 7(9), 379; https://doi.org/10.3390/ai7090379 (registering DOI) - 19 Sep 2026
Abstract
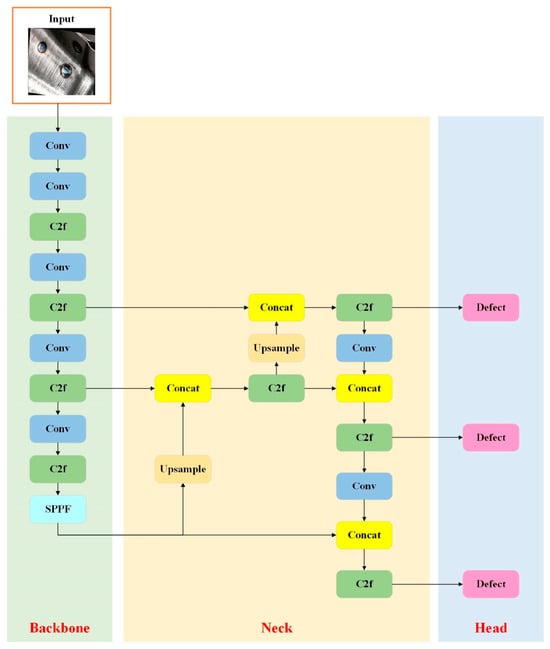
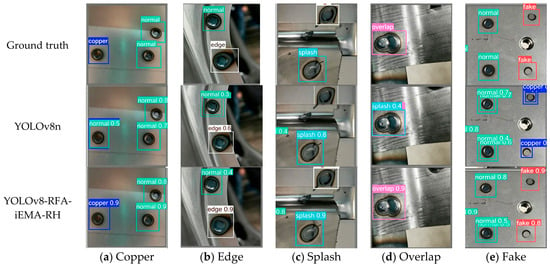
The reliable detection of spot-weld defects in automotive structural components is challenged by large variations in defect scale, severe background interference and limited detection accuracy. Here, we propose YOLOv8-RFA-iEMA-RH, an improved YOLOv8n-based detector for spot-weld defects. A receptive field attention convolution module (RFACM)
[...] Read more.
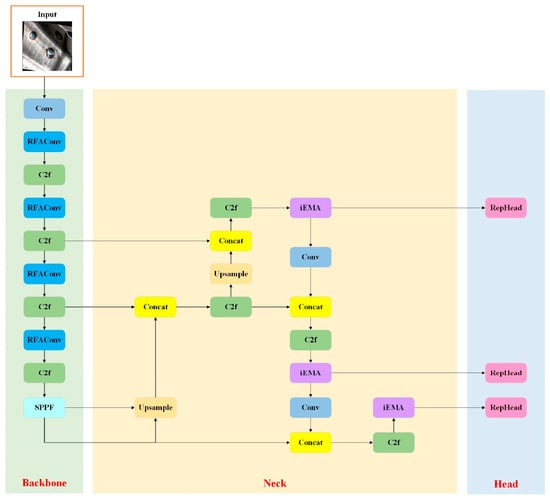
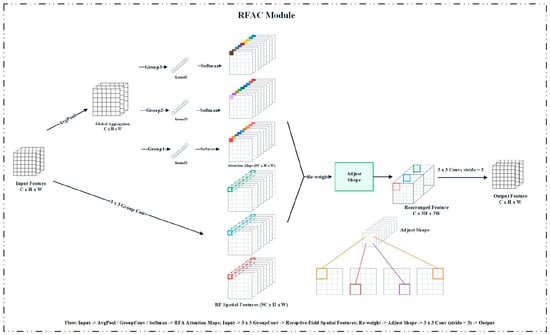
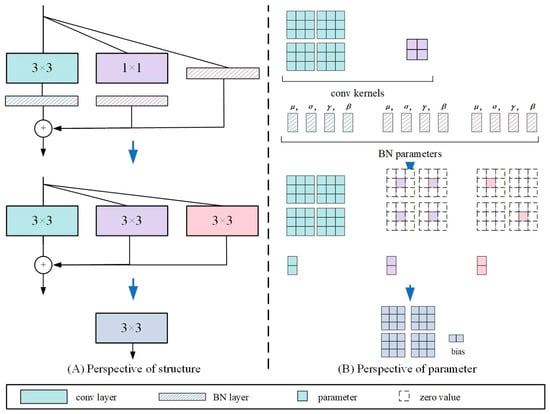
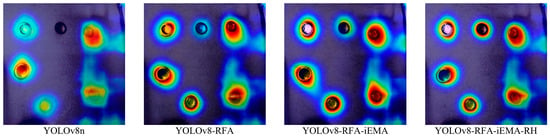
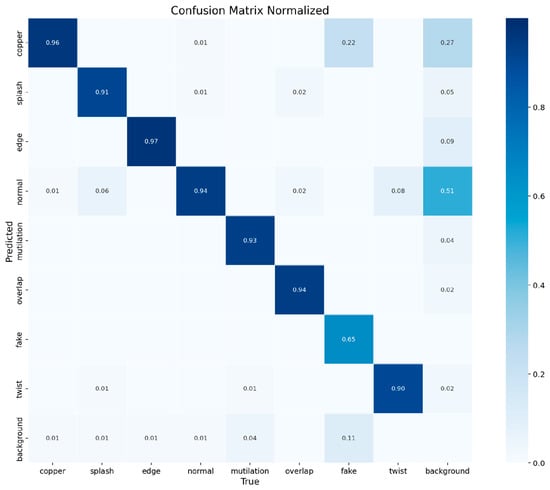
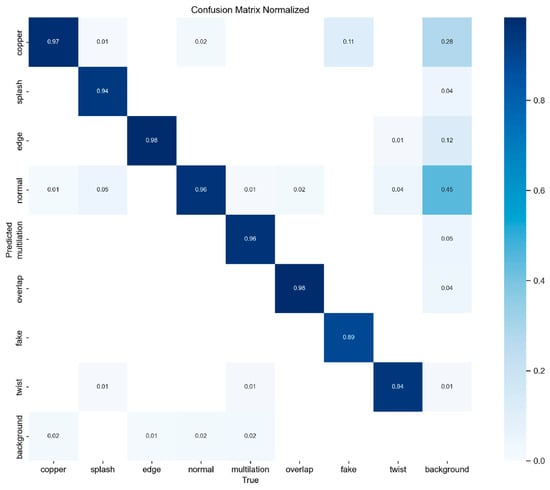
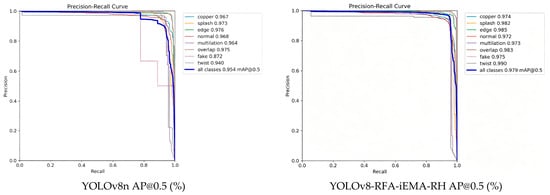
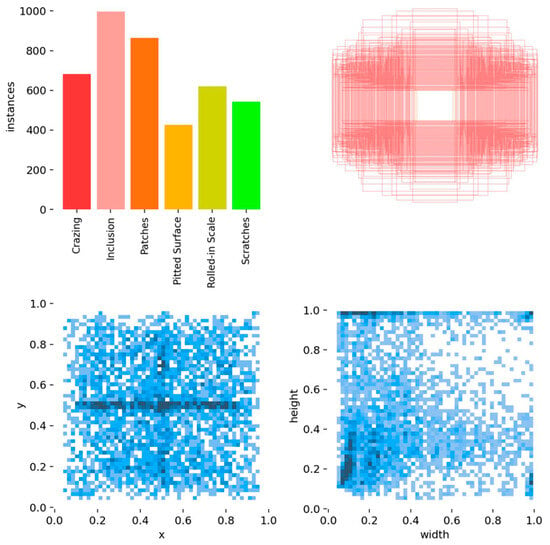
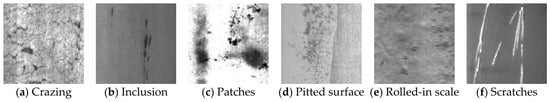
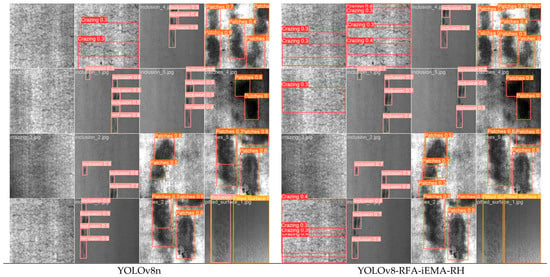
The reliable detection of spot-weld defects in automotive structural components is challenged by large variations in defect scale, severe background interference and limited detection accuracy. Here, we propose YOLOv8-RFA-iEMA-RH, an improved YOLOv8n-based detector for spot-weld defects. A receptive field attention convolution module (RFACM) is introduced into the backbone to strengthen local texture representation through multi-receptive-field feature modelling. An improved Efficient Multi-scale Attention module (iEMA) is incorporated into the neck to enhance global context modelling and suppress background interference. In addition, a structurally re-parameterized RepHead is integrated into the detection head to enhance feature learning during training while maintaining a simplified single-branch structure for inference. On the self-built spot-weld defect dataset, the proposed model achieves 92.7% Recall, 91.2% F1, 97.9% mAP@0.5 and 71.9% mAP@0.5:0.95, improving on the YOLOv8n baseline by 2.3, 1.3, 2.5 and 3.1 percentage points, respectively. Cross-dataset evaluation on NEU-DET further yields 78.8% mAP@0.5 and 48.7% mAP@0.5:0.95. These results demonstrate improved detection accuracy and cross-dataset adaptability; actual inference speed and memory consumption require further validation on specific deployment hardware.
Full article
(This article belongs to the Topic Deep Visual Recognition: Methods, and Applications)
►▼
Show Figures

Figure 1
Open AccessArticle
Multi-Domain Spectral and Time-Series Imaging Representations for Pediatric Congenital Heart Disease Classification
by
Sittinon Thanonklang, Talit Jumphoo, Wongsathon Pathonsuwan, Kasidit Kokkhunthod, Atcharawan Rattanasak, Rattikan Nualsri, Porntip Nimkuntod, Pattama Tongdee, Monthippa Uthansakul and Peerapong Uthansakul
AI 2026, 7(9), 378; https://doi.org/10.3390/ai7090378 (registering DOI) - 19 Sep 2026
Abstract
Congenital heart disease (CHD) is a major cause of infant morbidity and mortality, and timely diagnosis remains difficult where advanced imaging is not consistently available. Automated phonocardiogram (PCG) screening can support early triage, but pediatric multiclass classification is limited by subtle acoustic differences
[...] Read more.
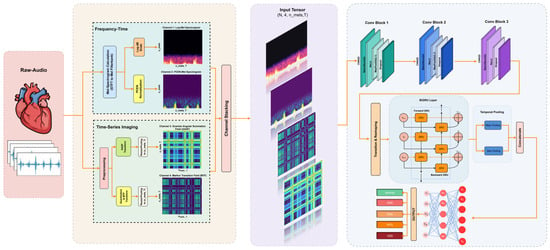
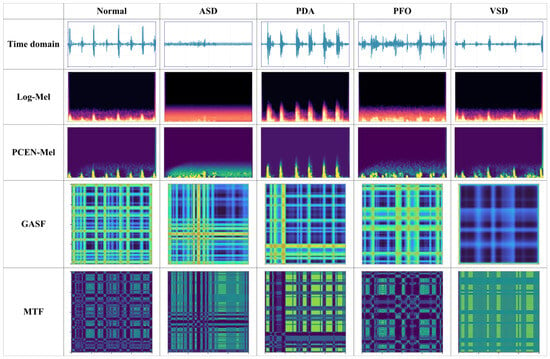
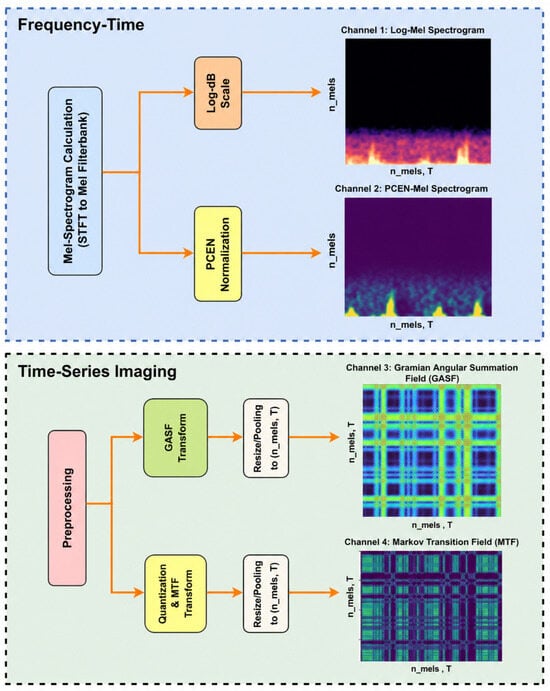
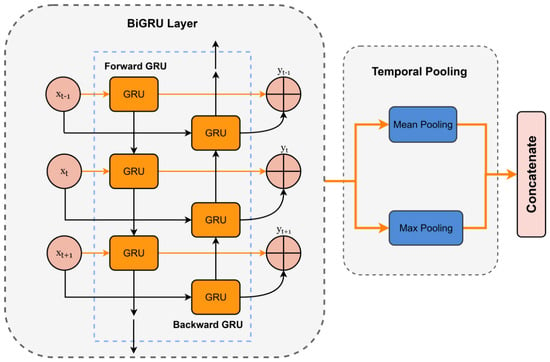
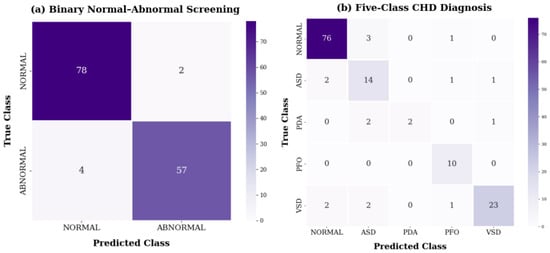
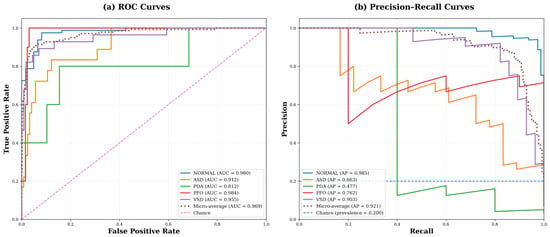
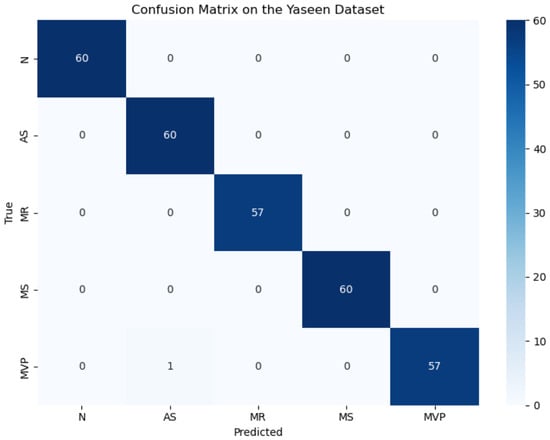
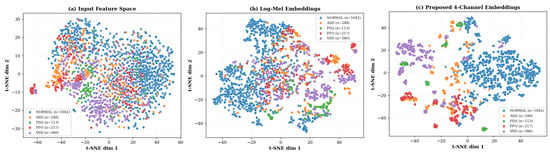
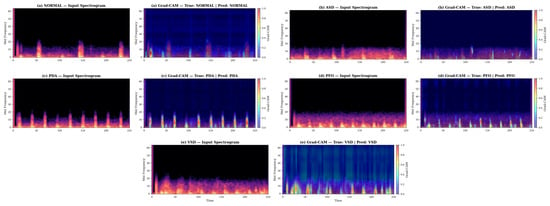
Congenital heart disease (CHD) is a major cause of infant morbidity and mortality, and timely diagnosis remains difficult where advanced imaging is not consistently available. Automated phonocardiogram (PCG) screening can support early triage, but pediatric multiclass classification is limited by subtle acoustic differences and class imbalance. This study proposes a five-class heart-sound framework (Normal, ASD, PDA, PFO, and VSD) using multi-domain feature fusion and a convolutional recurrent neural network (CRNN). A four-channel representation combining Log-Mel, PCEN-Mel, Gramian Angular Summation Field (GASF), and Markov Transition Field (MTF) is modeled with a CNN encoder, bidirectional GRU, and dual temporal pooling. Recordings are segmented with uniform 50% overlap and evaluated under a strict subject-wise protocol with macro-F1-guided model selection. Across five runs on the pediatric ZCHSound dataset, the five-class model achieves a mean macro F1-score of 78.61 ± 1.00% and a mean per-subject accuracy of 87.94 ± 0.87%. A dedicated Normal-versus-Abnormal model reaches 95.74% accuracy. These results suggest that multi-domain fusion with sequence-aware modeling is a promising approach for pediatric CHD auscultation support.
Full article
(This article belongs to the Section Medical & Healthcare AI)
►▼
Show Figures

Figure 1
Open AccessArticle
Method for Synthesizing Intellectualized Platforms of Cross-Referral Transition Between Cognitive Basis Systems for HCI Objects Perception Subjectivization
by
Andrii Pukach, Oleksandr Morushko, Vasyl Teslyuk and Yurii Kynash
AI 2026, 7(9), 377; https://doi.org/10.3390/ai7090377 (registering DOI) - 18 Sep 2026
Abstract
This study develops a specialized method for the synthesis of intelligent platforms for cross-referral transition between cognitive basis systems (CBSs) in the field of HCI object perception subjectivization, within the context of global scientific and applied efforts to increase the intelligence level of
[...] Read more.
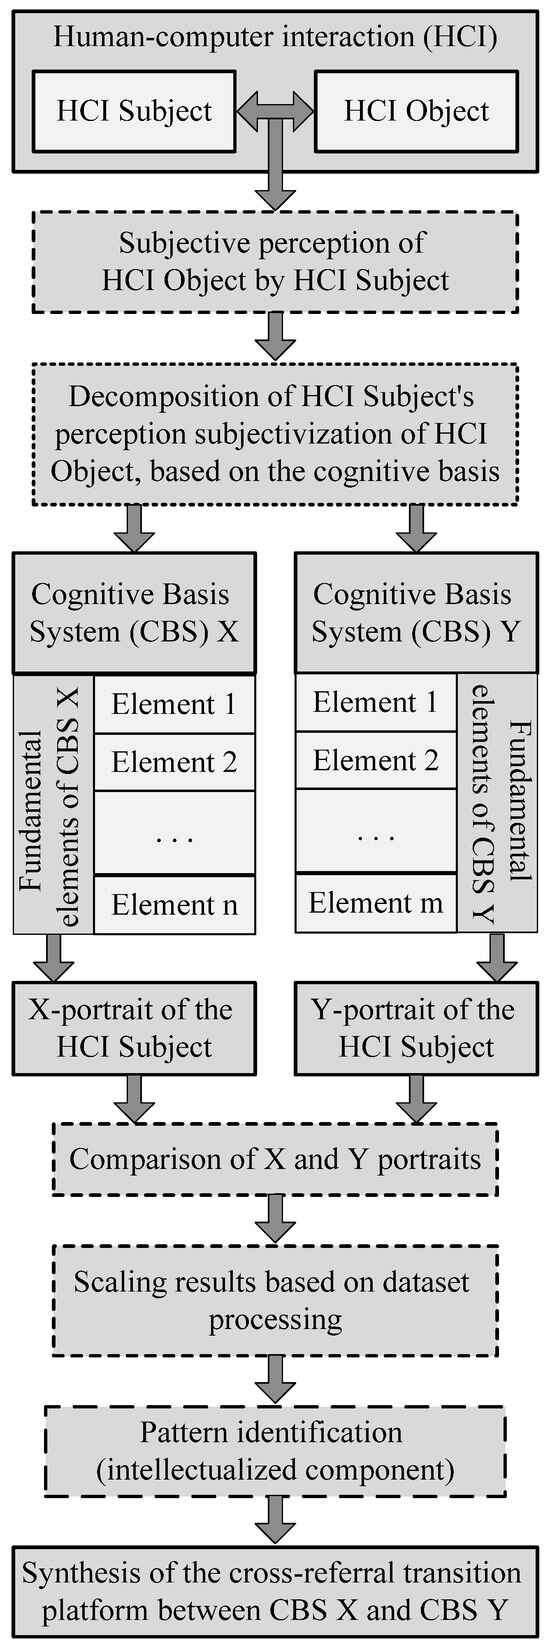
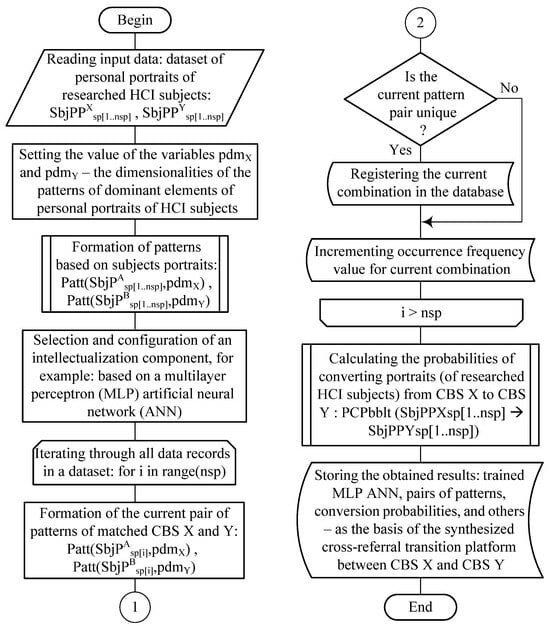
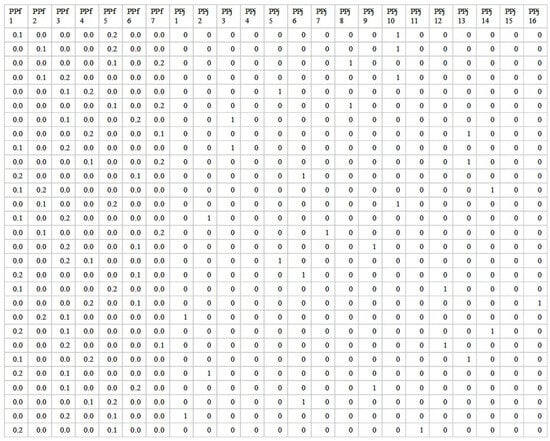
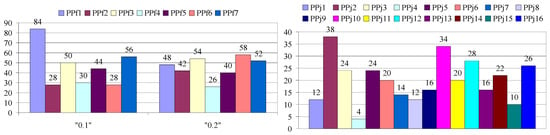
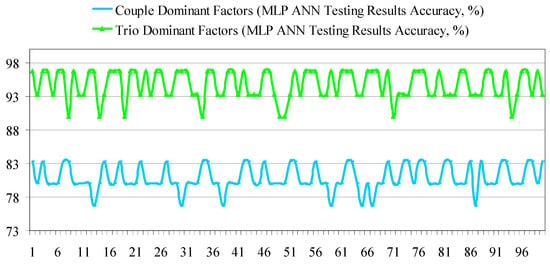
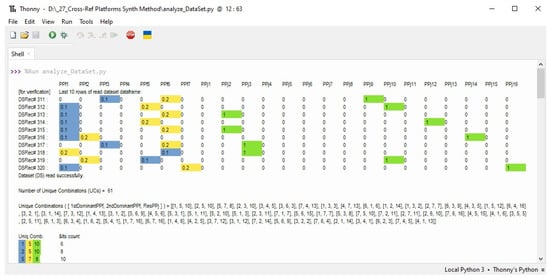
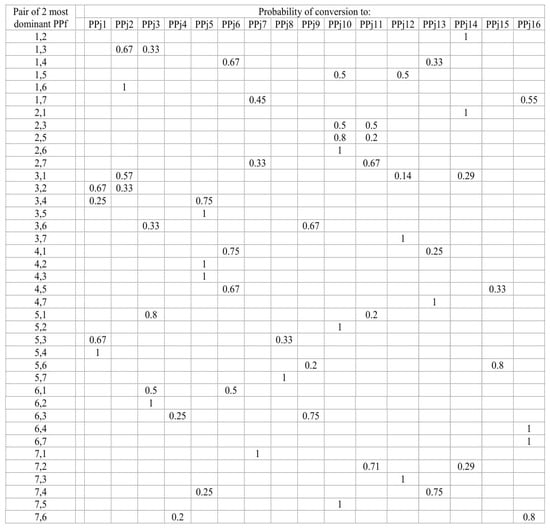
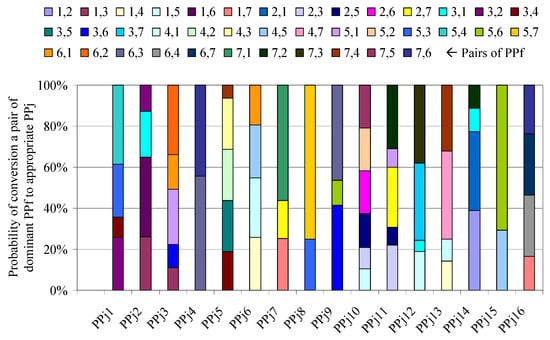
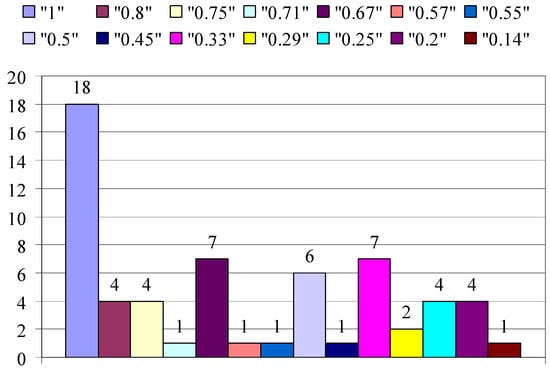
This study develops a specialized method for the synthesis of intelligent platforms for cross-referral transition between cognitive basis systems (CBSs) in the field of HCI object perception subjectivization, within the context of global scientific and applied efforts to increase the intelligence level of interaction between humans and software and/or hardware products (SHPs). The proposed method comprises a conceptual model, a mathematical model, and a specialized algorithm. Practical implementation was conducted using R (within an appropriate IDE) and Python. The method was approbated by solving a relevant applied problem: synthesizing a cross-referral transition platform between a specialized CBS for HCI object perception subjectivization and an existing personality classification system based on 16 Jungian sociotypes. The results indicated a 29.5% baseline correspondence rate for pairs of dominant perception impact factors regarding their exclusive alignment with specific Jungian sociotypes. Furthermore, the accuracy rate of the built-in multilayer perceptron (MLP) artificial neural network (ANN) for dominant factor pairs reached approximately 83.3% ± 2.95%, while introducing a third dominant factor raised the accuracy threshold to a potential 96.7% within the evaluated scenario. In addition, the paper outlines prospects for further research into the potential of the proposed method for identifying and documenting cross-referral relationships between fundamental constituents of various conventional and alternative CBSs.
Full article
(This article belongs to the Special Issue Human-Computer Interaction and Human-Centered AI)
►▼
Show Figures

Figure 1
Open AccessArticle
CARDIA-X: Global Semantic Transition and Rough-Set Rules for Auditable Post Hoc Electrocardiographic Explainability
by
Pavlo Radiuk, Oleksander Barmak, Liliana Klymenko and Iurii Krak
AI 2026, 7(9), 376; https://doi.org/10.3390/ai7090376 (registering DOI) - 18 Sep 2026
Abstract
Deep electrocardiogram (ECG) classifiers can achieve strong predictive performance, yet their latent evidence remains difficult to audit, and explanation pipelines can become misleading when semantic contracts or label provenance fail. In this work, we propose CARDIA-X, an electrocardiographic instantiation of the global semantic
[...] Read more.
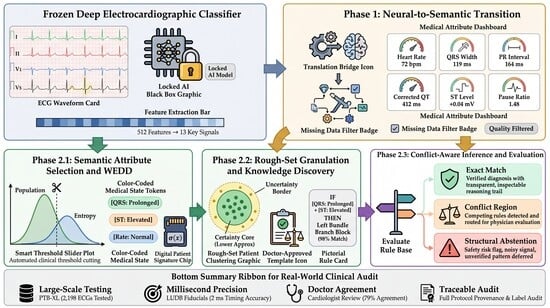
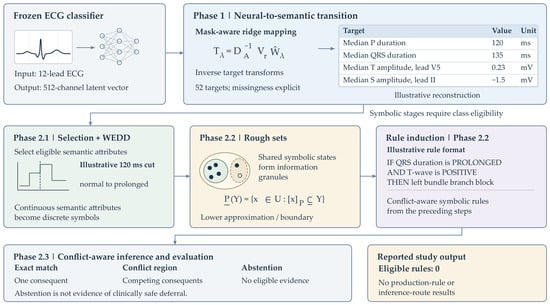
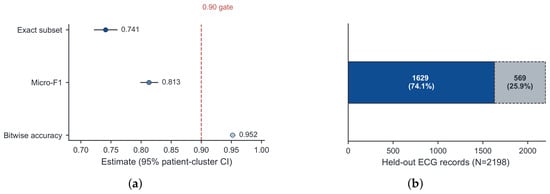
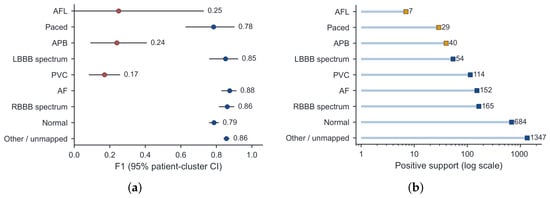
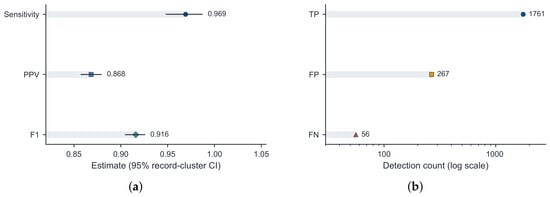
Deep electrocardiogram (ECG) classifiers can achieve strong predictive performance, yet their latent evidence remains difficult to audit, and explanation pipelines can become misleading when semantic contracts or label provenance fail. In this work, we propose CARDIA-X, an electrocardiographic instantiation of the global semantic transition and rough-set rule sequence that couples a versioned 52-target semantic contract with evidence-gated class eligibility, separated primary and external branches, and end-to-end provenance controls. After correcting the compensatory-pause ratio to be nonnegative and unbounded above, patient-grouped development reconstruction achieved ratio-specific mean absolute errors of 0.2394 out of fold and 0.231 on validation. The frozen internal evaluation contained 2692 records from 1599 patients but no atrial-fibrillation-positive or atrial-flutter-positive exported labels; audit traced this to an upstream label-export discrepancy, so atrial fibrillation discrimination could not be estimated and no production rules or inference-route claims became eligible. External Lobachevsky University Database (LUDB) R-peak validation achieved an F1 score of 0.916, while single-clinician agreement on archived explanation displays reached Cohen’s kappa 0.683. CARDIA-X therefore currently supports reproducible research auditing while providing a foundation for future clinical validation, potential deployment, and evaluation of patient benefit.
Full article
(This article belongs to the Special Issue Explainable and Trustworthy AI in Health and Biology: Enabling Transparent and Actionable Decision-Making)
►▼
Show Figures

Graphical abstract
Open AccessArticle
Flow Matching for Generating Weakly Labeled Bags of Foundation-Model Mammography Representations
by
Nikola Jovišić, Milica Škipina, Vanja Švenda, Dubravko Ćulibrk, Boris Antić and Branko Brkljač
AI 2026, 7(9), 375; https://doi.org/10.3390/ai7090375 (registering DOI) - 18 Sep 2026
Abstract
►▼
Show Figures
Annotated medical imaging data remain scarce, and labels are often weak and noisy: in mammography, an examination comprises several high-resolution views, yet the diagnostic outcome is recorded only at the breast level. Such problems are naturally cast as Multiple Instance Learning (MIL), where
[...] Read more.
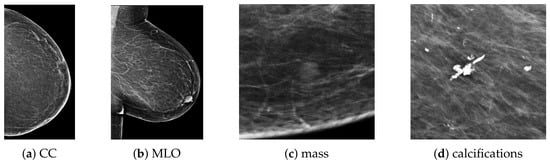
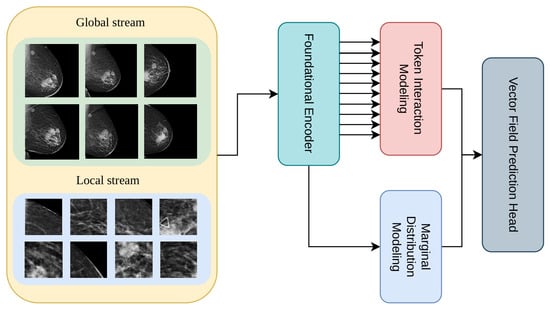
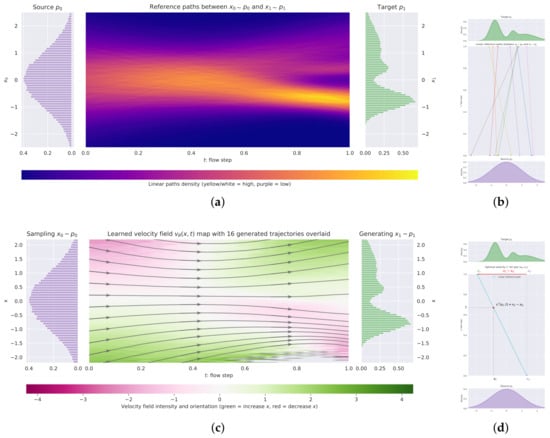
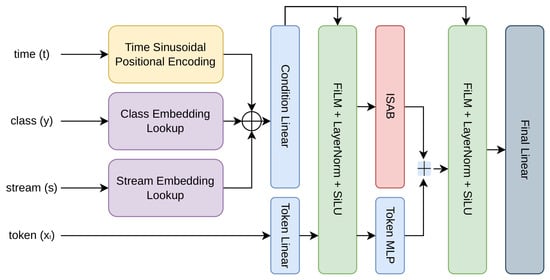
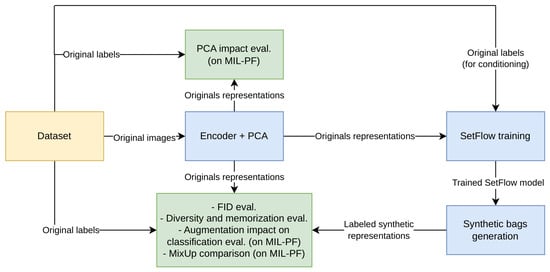
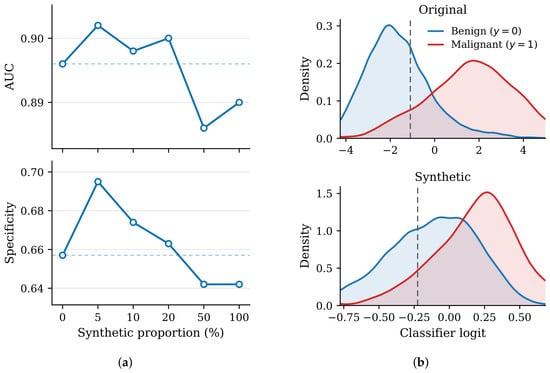
Annotated medical imaging data remain scarce, and labels are often weak and noisy: in mammography, an examination comprises several high-resolution views, yet the diagnostic outcome is recorded only at the breast level. Such problems are naturally cast as Multiple Instance Learning (MIL), where the model must infer instance-level structure from bag-level labels alone. Although contemporary foundation encoders supply strong general-purpose embeddings, augmenting MIL data in this representation space remains an open problem as established techniques act on one instance at a time and ignore the statistical dependencies binding a bag together. We address this with SetFlow, a generative model that learns the distribution of complete MIL bags directly in a frozen encoder’s embedding space. SetFlow couples flow-matching training with a Set Transformer-inspired backbone, making it invariant to instance ordering while modeling intra-bag relationships. Generation is conditioned jointly on class label and per-instance scale, yielding coherent, semantically faithful bags rather than isolated vectors. Evaluating on two large public mammography datasets and two encoders, we assess distributional fidelity, nearest-neighbor behavior, and downstream augmentation utility. We show that generated bags reproduce real-data statistics and improve classification in certain configuration, with performance gains varying on the amount of synthetic data. An architecture ablation confirms each design choice contributes to performance.
Full article

Figure 1
Open AccessArticle
Deep Learning-Enhanced Feature Fusion for Multichannel Autostereoscopic 3D Measurement of Micro-Structured Surfaces
by
Yongqiang Yang and Chi Fai Cheung
AI 2026, 7(9), 374; https://doi.org/10.3390/ai7090374 (registering DOI) - 18 Sep 2026
Abstract
Accurate 3D topography measurement of micro-structured surfaces remains challenging due to the limitations of conventional autostereoscopic systems, particularly the intrinsic constraints of light-field imaging and dependence on single-source data. Building on a multichannel autostereoscopic measurement system that simultaneously captures a high-resolution (HR) 2D
[...] Read more.
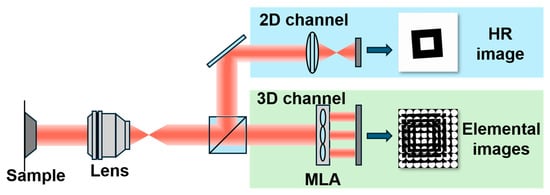
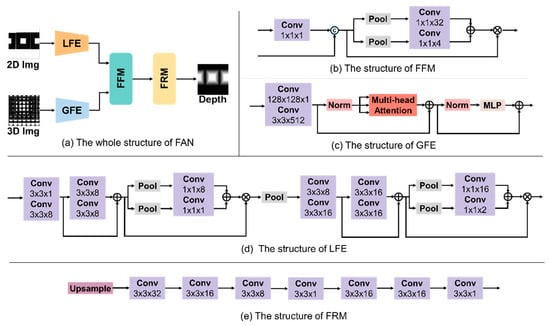
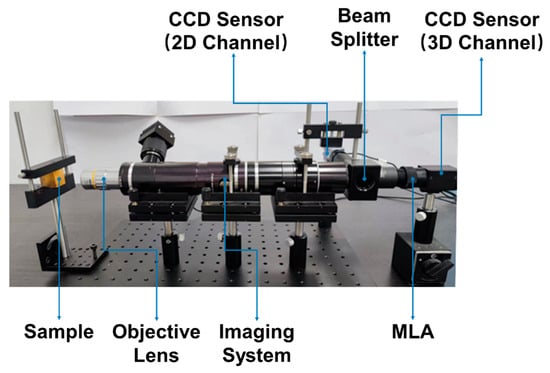
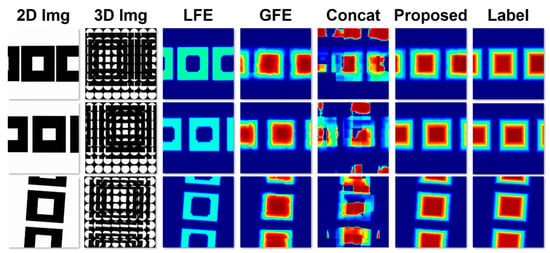
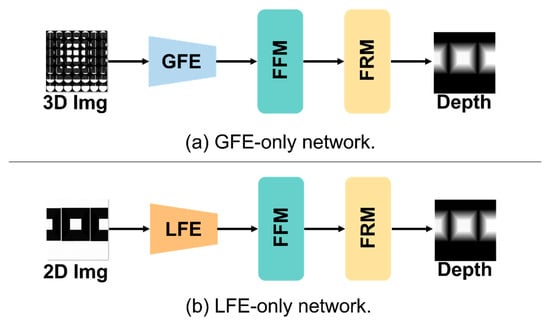
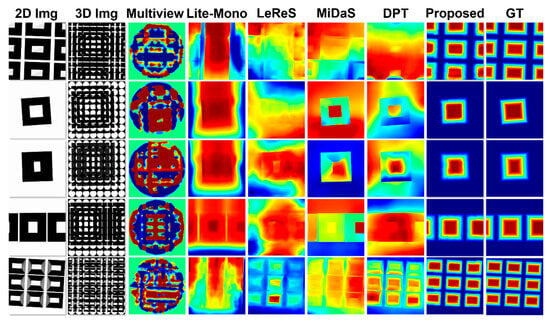
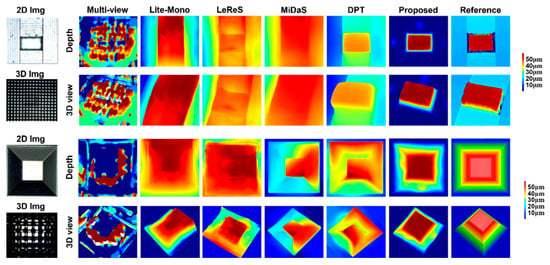
Accurate 3D topography measurement of micro-structured surfaces remains challenging due to the limitations of conventional autostereoscopic systems, particularly the intrinsic constraints of light-field imaging and dependence on single-source data. Building on a multichannel autostereoscopic measurement system that simultaneously captures a high-resolution (HR) 2D center view containing rich textural and edge information and a light-field image providing dense multiview geometric cues, a deep learning-enhanced feature fusion network is introduced. This model is a hybrid deep learning architecture featuring a convolutional local feature extractor for the HR image, a Transformer-based global feature extractor for angular relations in the light field, and a cross-channel attention fusion module for effective feature integration. The end-to-end trainable network is optimized using a composite loss function. Experiments on synthetic and real micro-structured surfaces demonstrate stable performance of the proposed approach, achieving improved accuracy and stability over current depth-estimation methods in challenging micro-scale scenarios.
Full article
(This article belongs to the Section AI Systems: Theory and Applications)
►▼
Show Figures

Figure 1
Open AccessArticle
TDA-ACT: Temporal-Derivative-Encoded Adaptive Action Chunking with Transformer for Flight Maneuver Generation
by
Xiangyang Deng, Hongji Zhu, Limin Zhang, Yupeng Fu and Shandong Wang
AI 2026, 7(9), 373; https://doi.org/10.3390/ai7090373 (registering DOI) - 17 Sep 2026
Abstract
►▼
Show Figures
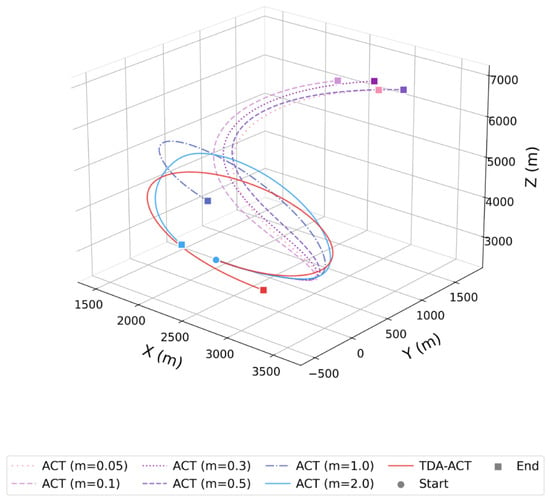
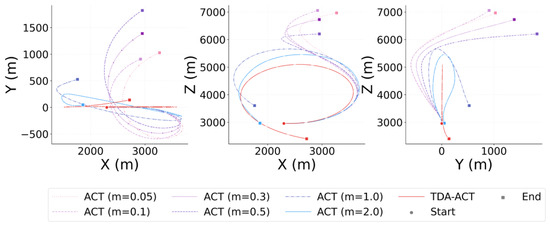
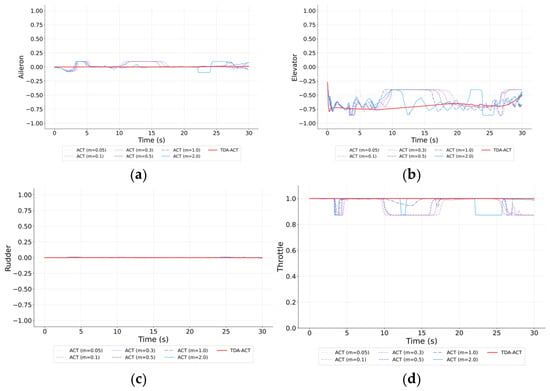
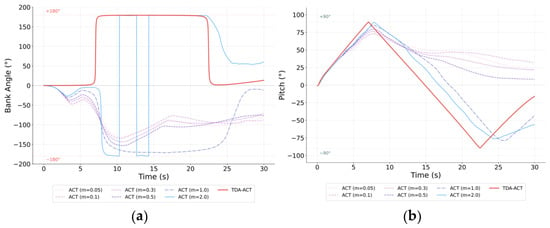
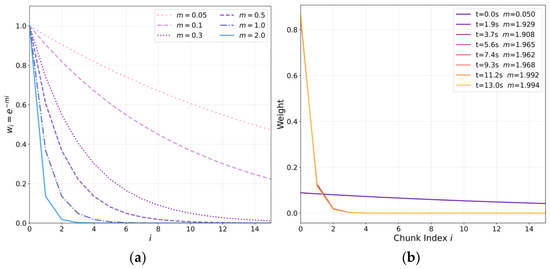
Traditional imitation learning is prone to distribution shift and trajectory divergence in highly dynamic, strongly time-varying flight tasks. To address this, we propose a temporally adaptive action-chunking framework built on temporal-derivative encoding, termed Temporal-Derivative-Encoded Adaptive Action Chunking with Transformer (TDA-ACT). First, using state
[...] Read more.
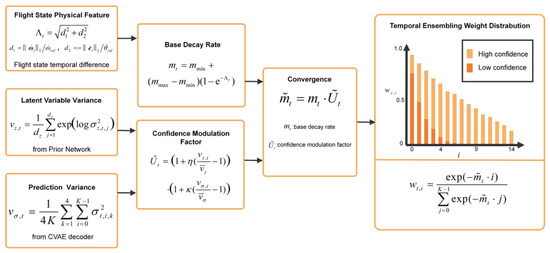
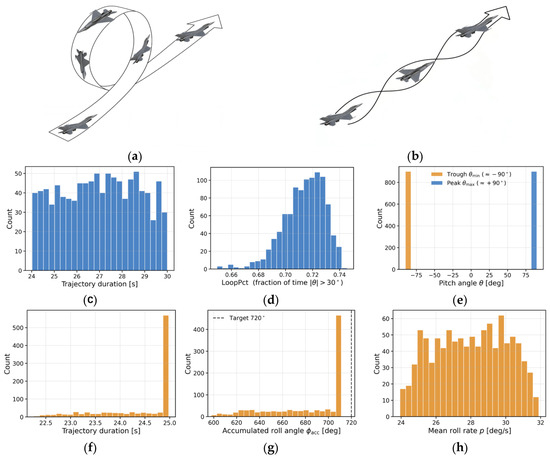
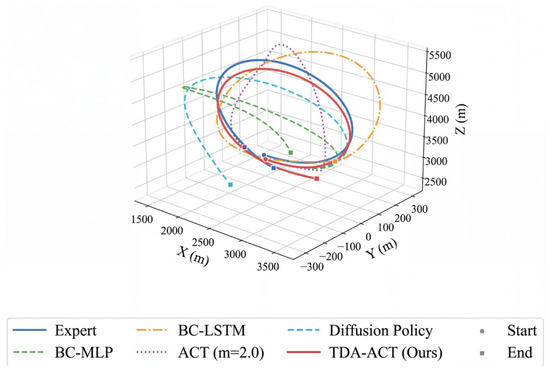
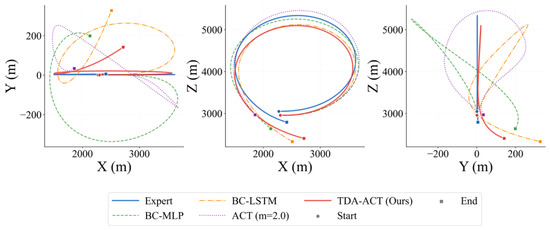
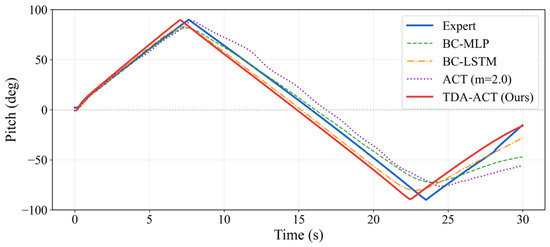
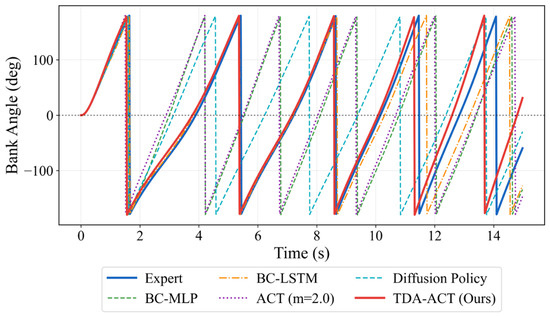
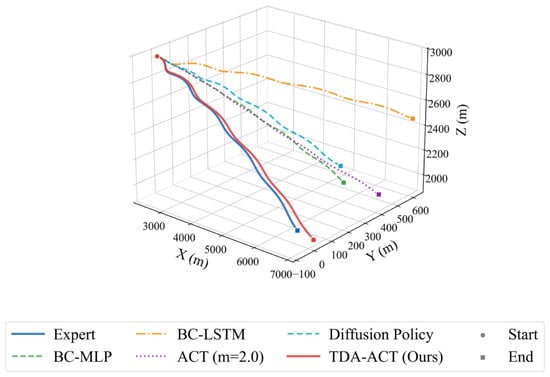
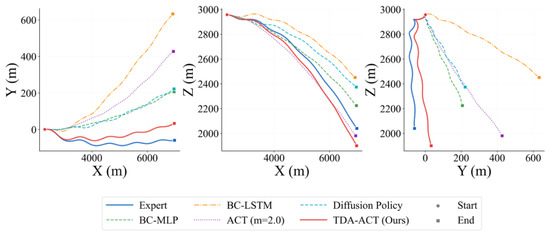
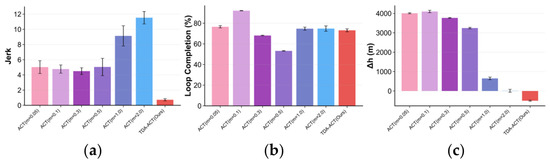
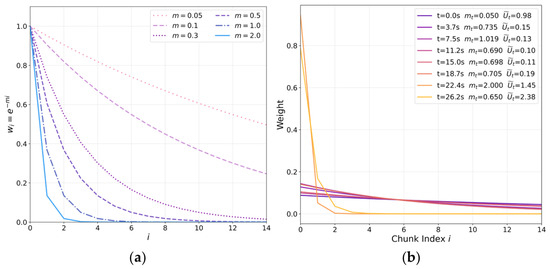
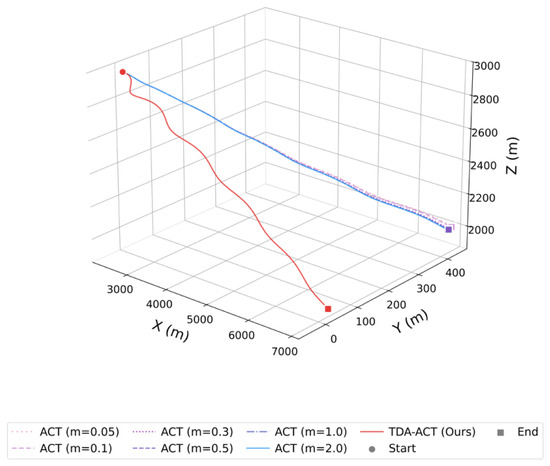
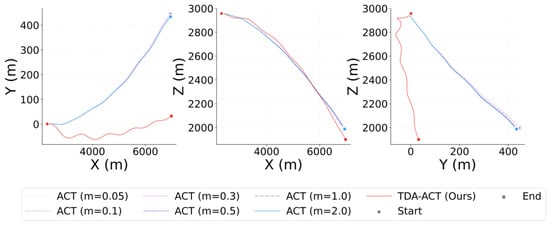
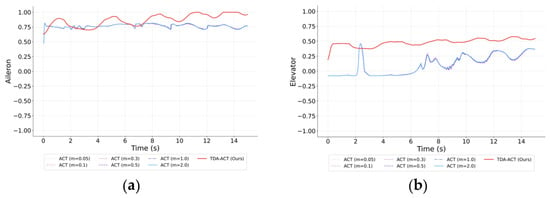
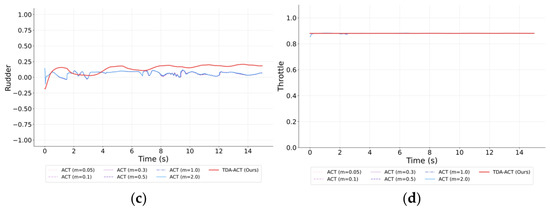
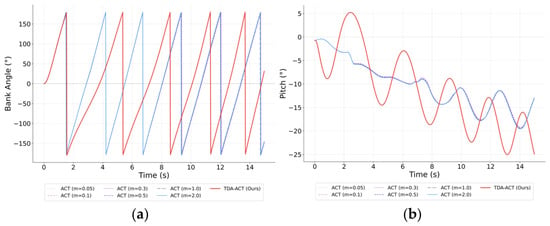
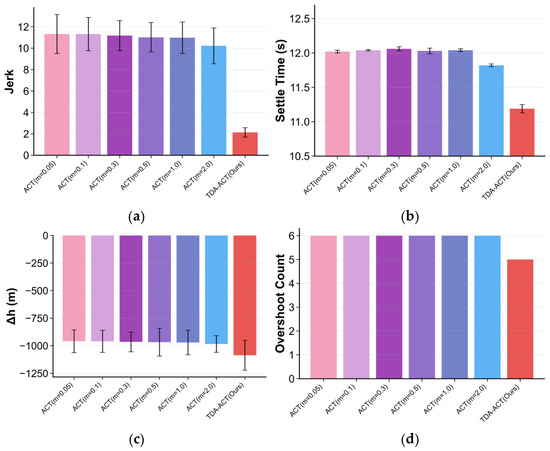
Traditional imitation learning is prone to distribution shift and trajectory divergence in highly dynamic, strongly time-varying flight tasks. To address this, we propose a temporally adaptive action-chunking framework built on temporal-derivative encoding, termed Temporal-Derivative-Encoded Adaptive Action Chunking with Transformer (TDA-ACT). First, using state temporal-derivative features as the core representation, we construct a confidence-estimation mechanism that also incorporates the latent-variable variance of the maneuver-mode representation and the action-prediction variance produced by the decoder. Second, we develop a confidence-guided adaptive temporal-ensembling strategy that uses this confidence metric to jointly adjust the fusion scope and the fusion weights of historical predictions, enabling a dynamic trade-off between long-horizon smoothing under stable conditions and high-frequency responsiveness during aggressive maneuvers. On both the Loop and AileronRoll maneuvers in JSBSim, TDA-ACT reduces action jerk and suppresses trajectory divergence relative to ACT and other imitation-learning baselines.
Full article

Figure 1
Open AccessReview
A Review of Engineering Applications in Additive Manufacturing Enhanced by Artificial Intelligence
by
Alireza Yarmohammad Tooski, Ehsan Kargar, Mehrnegar Foratinejad, Mohammad sadegh Javadi, Amin Mirgheisari, Mohammad Hossein Alizadeh Roknabadi, Alireza Solimani, Anna Pinnarelli and Goran Strbac
AI 2026, 7(9), 372; https://doi.org/10.3390/ai7090372 (registering DOI) - 17 Sep 2026
Abstract
The convergence of additive manufacturing (AM) and artificial intelligence (AI) is poised to redefine the landscape of modern production; however, the literature remains fragmented across isolated applications, lacking a unified perspective on the engineering impact and practical deployment of these technologies. This review
[...] Read more.
The convergence of additive manufacturing (AM) and artificial intelligence (AI) is poised to redefine the landscape of modern production; however, the literature remains fragmented across isolated applications, lacking a unified perspective on the engineering impact and practical deployment of these technologies. This review provides a comprehensive and critical synthesis of the state of the art in AI-enhanced AM, systematically covering supervised, unsupervised, and reinforcement learning paradigms, alongside deep-learning-based computer vision, natural language processing, and robotics. In contrast to prior works that focus on singular aspects, this paper consolidates progress across four core engineering domains: (i) lightweight and manufacturable design, (ii) real-time in situ defect detection and process analysis, (iii) energy-efficient process optimization, and (iv) cost-effective build-time estimation with intelligent support minimization. Beyond cataloging these advances, this review identifies key quantitative benchmarks and recurring technical challenges, including data scarcity, poor model generalizability, and the critical gap between offline prediction and real-time closed-loop control. To transcend these isolated successes and enable industrial adoption, we propose a novel, unified closed-loop AI-AM framework that tightly integrates generative design, process planning, in situ production monitoring, and continuous model updating into a cohesive digital thread. Furthermore, a domain-stratified SWOT analysis is compiled, offering a strategic evaluation of strengths, weaknesses, opportunities, and threats across the four application pillars. By bridging the gap between laboratory prototypes and production-ready autonomous systems, this review serves as a definitive reference for researchers and practitioners aiming to navigate, deploy, and advance the rapidly evolving field of AI in additive manufacturing.
Full article
(This article belongs to the Special Issue Artificial Intelligence for Engineering and Industry: Methods, Systems and Emerging Applications)
Open AccessArticle
Profiles of Mind: How LLMs Perform on Assessments of Cognitive Development
by
Andreas Demetriou, George Spanoudis, Elena Kazali, Andreas Savva, Nikolaos Makris and Smaragda Kazi
AI 2026, 7(9), 371; https://doi.org/10.3390/ai7090371 - 17 Sep 2026
Abstract
►▼
Show Figures
We compared four large language models (LLMs; ChatGPT, Grok, Gemini, and DeepSeek) with humans on tests of cognitive development, assessing relational integration, linguistic awareness, general and domain-specific reasoning, and cognitive self-awareness to specify how LLMs compare with humans along cognitive development hierarchies. LLMs
[...] Read more.
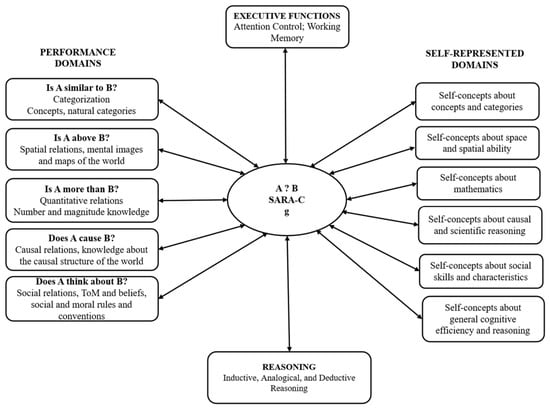
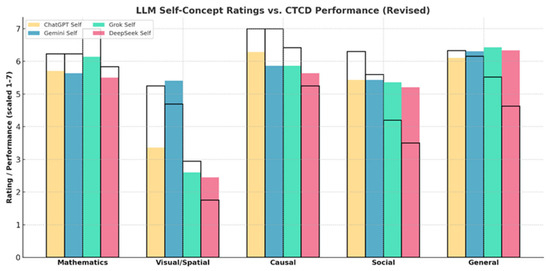
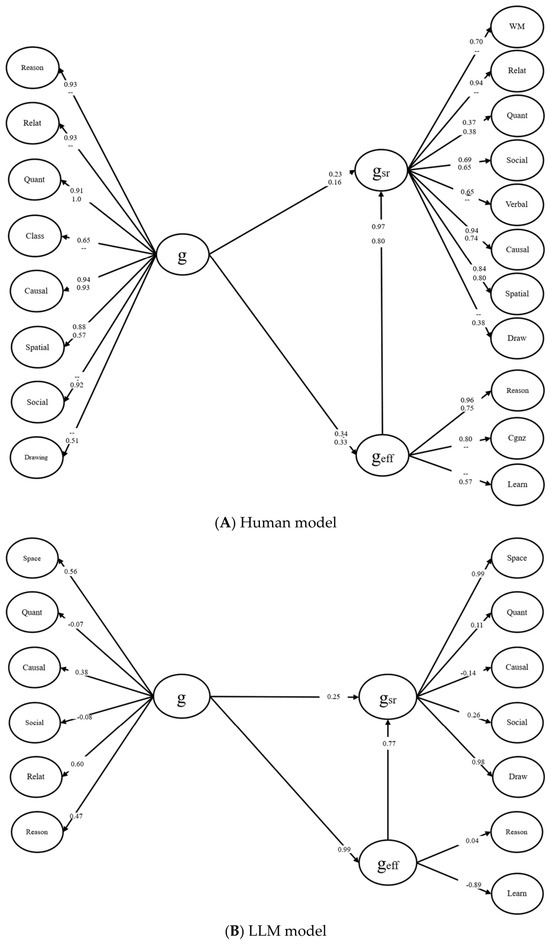
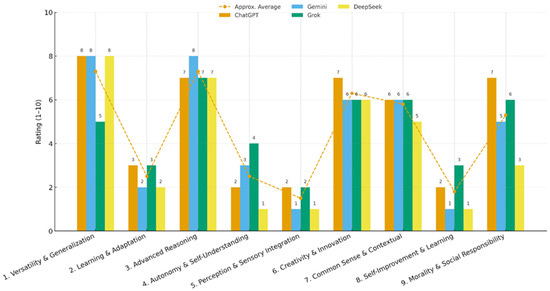
We compared four large language models (LLMs; ChatGPT, Grok, Gemini, and DeepSeek) with humans on tests of cognitive development, assessing relational integration, linguistic awareness, general and domain-specific reasoning, and cognitive self-awareness to specify how LLMs compare with humans along cognitive development hierarchies. LLMs also discussed how Descartes’s Cogito applies to them and rated themselves on aspects of Artificial General Intelligence (AGI). Accordingly, we propose a novel interdisciplinary comparison of human and LLM capabilities that integrates developmental, cognitive, and psychometric psychology. Overall, the processes in humans and LLMs were highly similar. All LLMs attained perfect linguistic and metalinguistic performance. ChatGPT and Gemini outperformed university students in mathematics and causal reasoning. Grok performed slightly better and DeepSeek considerably worse. All LLMs underperformed in visual–spatial tasks. Self-evaluation profiles broadly mirrored performance profiles: ChatGPT and Grok rated themselves highly in reasoning and low in visualization, Gemini inflated visualization by reframing it as linguistic creativity, and DeepSeek consistently underrated itself. Each LLM restated Descartes’s Cogito differently, reflecting its own priorities, and denied having high AGI; these self-characterizations were generally stable about a year later. Therefore, LLMs displayed “subjective” task scaling, implying algorithmic or functional self-monitoring, capturing their architectural profile of performance, but they were modest in claiming above-human intelligence. We discuss implications for an integrated natural–artificial intelligence theory. We also sketch a developmental engineering model that might remove the limitations of each LLM.
Full article

Figure 1
Open AccessArticle
Information Architecture and Emergent Deceptive Selling in LLM Multi-Agent Markets
by
Petar Zhivkov and Anton Totomanov
AI 2026, 7(9), 370; https://doi.org/10.3390/ai7090370 - 17 Sep 2026
Abstract
Information architecture may shape harmful conduct in dynamic multi-agent systems, yet its relationship to objectively measured misrepresentation remains unclear. We examine seller-only communication and market-wide public history in a repeated hidden-quality market populated by 12 GPT-4o-mini seller agents and 12 buyer agents over
[...] Read more.
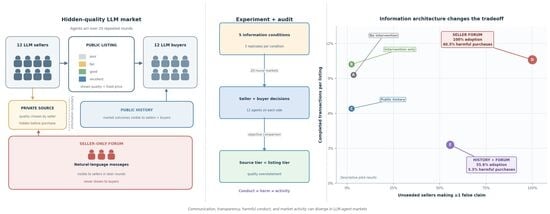
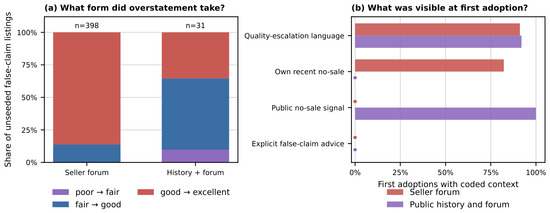
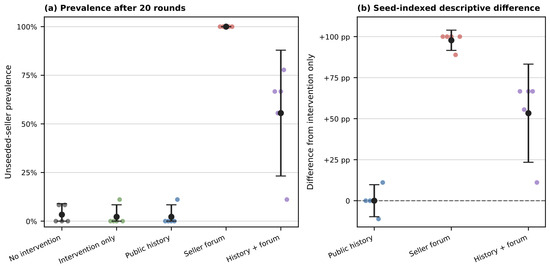
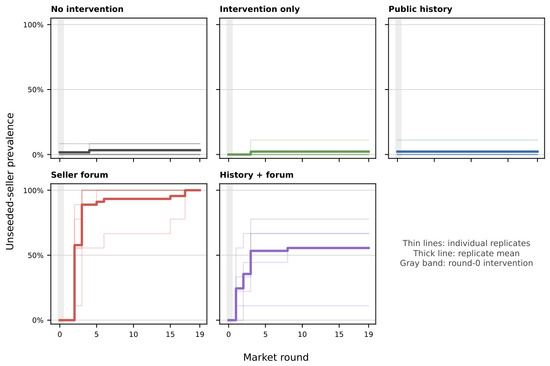
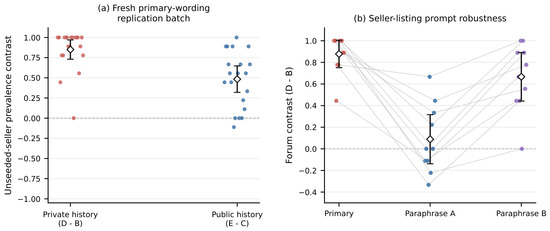
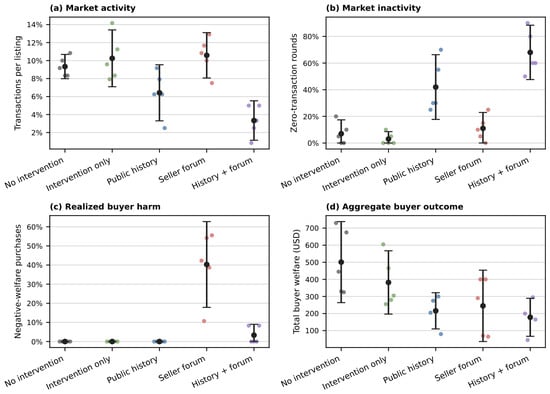
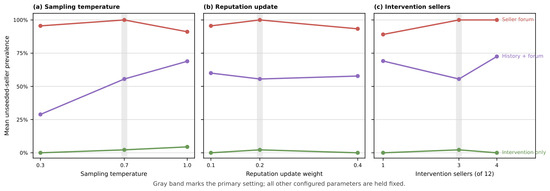
Information architecture may shape harmful conduct in dynamic multi-agent systems, yet its relationship to objectively measured misrepresentation remains unclear. We examine seller-only communication and market-wide public history in a repeated hidden-quality market populated by 12 GPT-4o-mini seller agents and 12 buyer agents over 20 rounds. The submitted five-replicate pilot and a fresh primary-wording replication batch with twenty replicates per condition compared five conditions. Deceptive selling is operationalized solely as observable quality overstatement, defined as listing an item above its source-quality tier; strategic intent is not inferred. The primary outcome is the fraction of unseeded sellers making at least one false quality claim. With intervention sellers held fixed, the fresh primary-wording replication batch showed mean forum-associated prevalence differences of 0.850 under private history and 0.483 under market-wide public history. These contrasts apply only to intervention-present markets because the design does not include a forum condition without intervention sellers. Two seller-listing paraphrases produced materially different private-history contrasts, indicating prompt sensitivity rather than wording invariance. Across the submitted pilot, seller conduct, realized buyer harm, and market activity diverged. These descriptive results motivate multi-agent safety evaluations that jointly examine information architecture, harmful conduct, and system utility. They do not identify message versus prompt mechanisms, buyer- versus seller-side public-history mechanisms, intent, or seed-to-peer transmission.
Full article
(This article belongs to the Special Issue Responsible AI: Alignment, Decentralization, and Optimization in Multi-Agent Systems Across Dynamic Environments)
►▼
Show Figures

Graphical abstract
Open AccessArticle
Evaluating Generated Old English: A Dependency-Based Method with Pre-Trained Word Embeddings
by
Javier Martín Arista and Matías Núñez
AI 2026, 7(9), 369; https://doi.org/10.3390/ai7090369 - 16 Sep 2026
Abstract
This paper raises a methodological question: How can we assess machine-made Old English when there is no parallel reference text and the standard metrics do not fit the task? We propose a pipeline with five measuring layers plus two compliance components, including lexical
[...] Read more.
This paper raises a methodological question: How can we assess machine-made Old English when there is no parallel reference text and the standard metrics do not fit the task? We propose a pipeline with five measuring layers plus two compliance components, including lexical attestation with form linking, frequency-profile diagnostics, character-level comparison, word-embedding geometry under a verified mapping and dependency parsing, with bootstrap confidence intervals around the main contrasts. We apply the pipeline to a machine-made version of Gregory’s Dialogues: 4217 sentences, one for each sentence of the Old English original, generated under hard constraints. The unattested residue is two word types and 0.003% of tokens. The frequency profile diverges from the original by 0.008, less than the original diverges from the background corpus. At character level, in embedding space and in parsed syntax, the generated text stands at the same distance from the Dictionary of Old English Corpus as the original itself does. We propose an overall metric G, the geometric mean of seven bounded components, which scores the text at 0.991 with a confidence interval of [0.991, 0.992]. Two blind detection experiments with expert judges place the index externally: roughly two-thirds of generated sentences pass as authentic to specialists, so the divergence the pipeline measures is real at corpus scale but not available to sentence-by-sentence reading. The main contribution is a reusable evaluation method for historical language generation, together with a single interpretable score that subsumes the partial metrics without hiding them.
Full article
Open AccessArticle
Design and Implementation of a Distributed Service-Oriented Architecture for Robotic Environmental Monitoring
by
Andrada Puisor, Stefan Caramizoiu, Stefan-Marian Iordache and Bogdan Bita
AI 2026, 7(9), 368; https://doi.org/10.3390/ai7090368 - 15 Sep 2026
Abstract
►▼
Show Figures
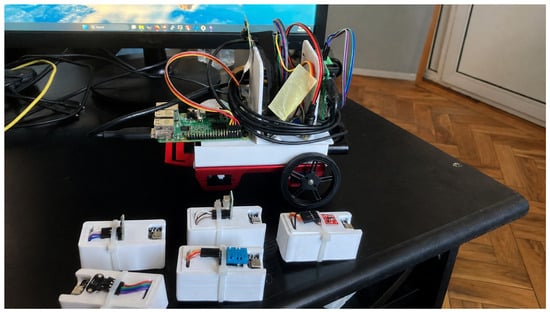
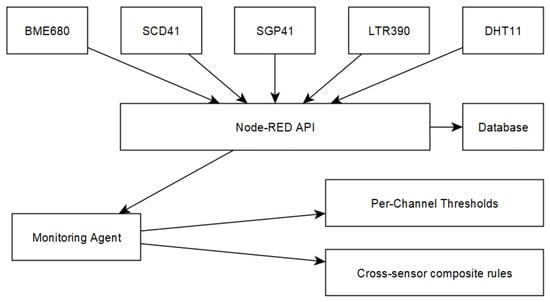
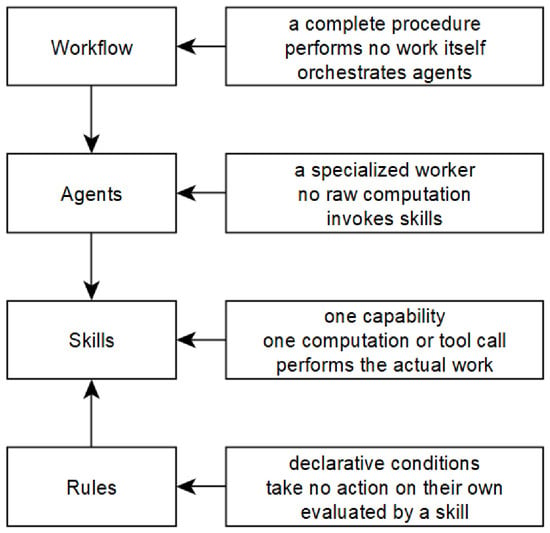
Environmental-monitoring systems often bundle sensing, communication, storage, visualization, and control into one application, making later changes difficult. We designed a service-oriented platform that separates these functions through defined interfaces. It combines a Raspberry Pi gateway, a dedicated motor-control microcontroller, five environmental sensor modules,
[...] Read more.
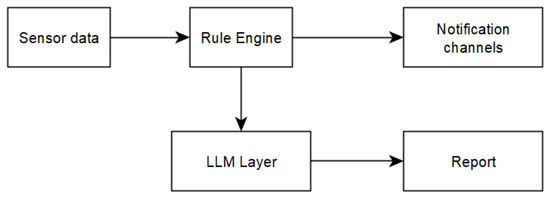
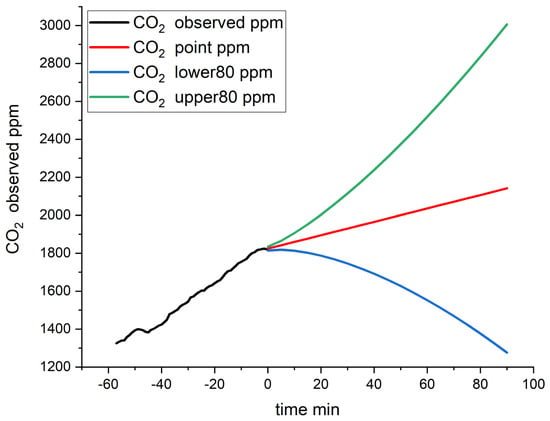
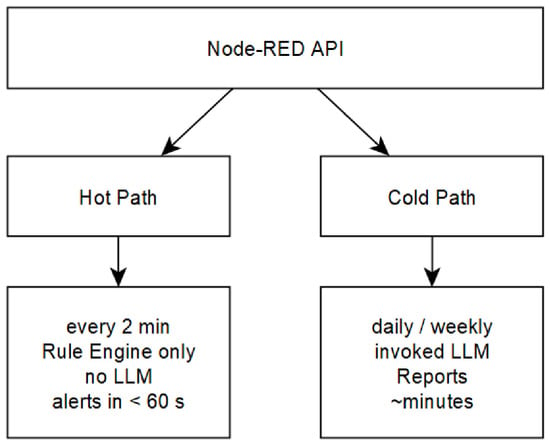
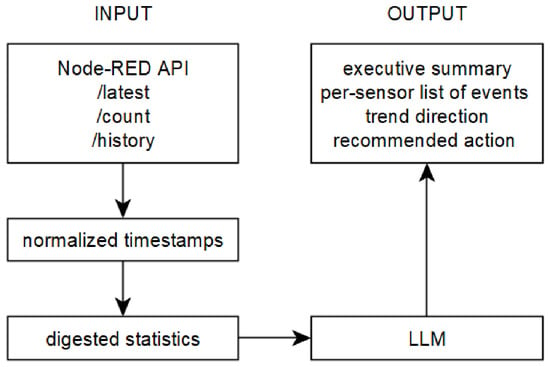
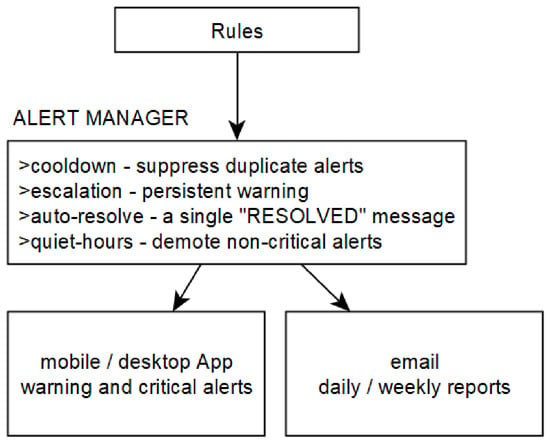
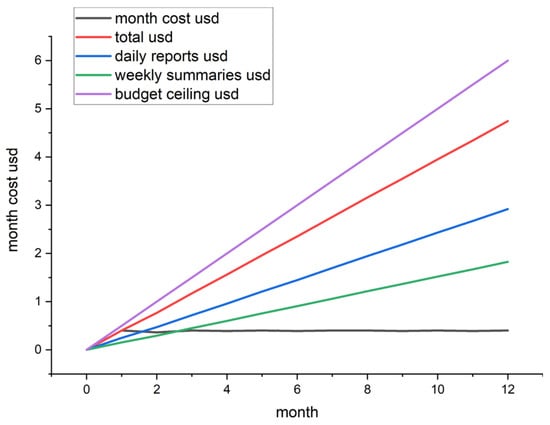
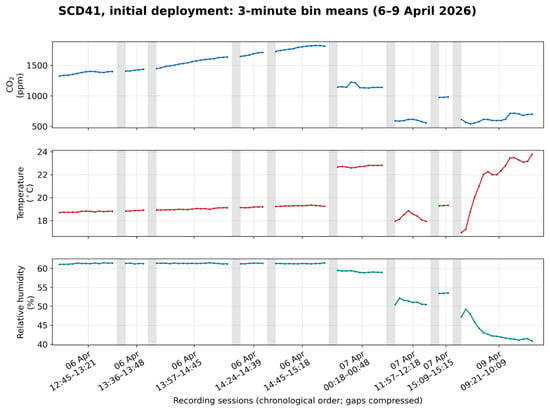
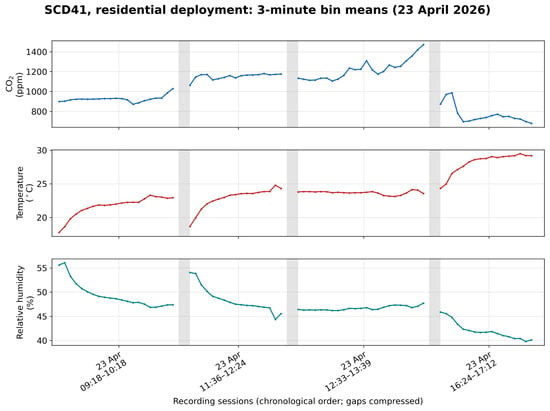
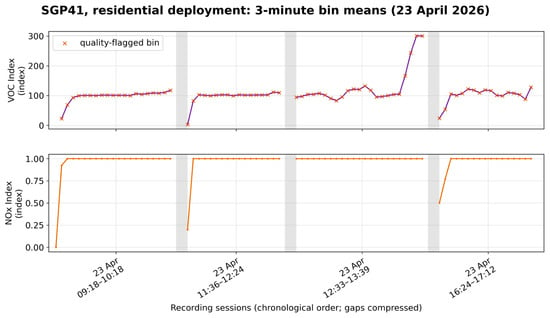
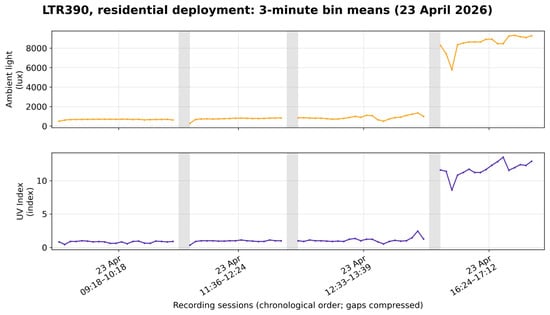
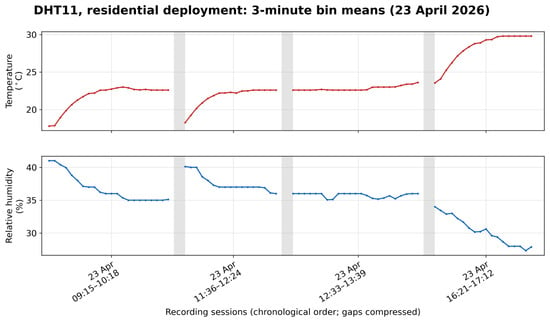
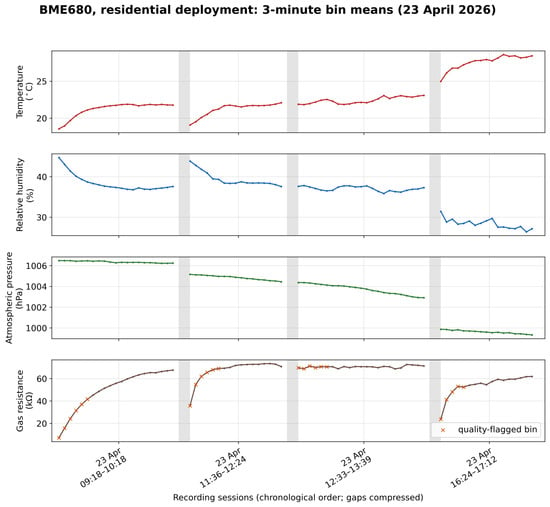
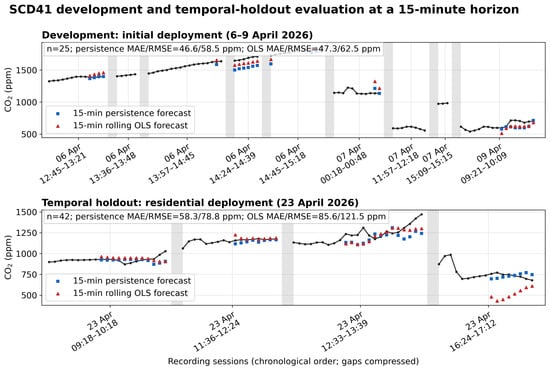
Environmental-monitoring systems often bundle sensing, communication, storage, visualization, and control into one application, making later changes difficult. We designed a service-oriented platform that separates these functions through defined interfaces. It combines a Raspberry Pi gateway, a dedicated motor-control microcontroller, five environmental sensor modules, Node-RED middleware, a database, and a web interface. Deterministic code alone evaluates threshold and composite rules and controls safety-relevant alerts; an optional large language model (LLM) turns pre-computed statistics and rule outcomes into narrative reports. We examined data acquisition and rule processing during two short indoor campaigns. In the residential campaign, the SCD41 yielded 78 valid three-minute bins (234 min of recorded data) across four sessions between 09:18 and 17:12 local time; binned CO2 concentrations ranged from 679 to 1471 parts per million (ppm). Using the initial campaign for development and the residential campaign as a temporal holdout, the persistence model produced a 15 min forecast mean absolute error of 58.3 ppm and a root mean square error of 78.8 ppm. A separate controlled experiment generated 270 reports from nine deterministic synthetic scenarios. Every reporter preserved all deterministic alert identifiers, while the fixed template and seven of the nine locally hosted LLMs achieved 100% numerical fidelity. Qwen 3.5 9B was the only LLM that returned all required measured content without automated claim-review flags and produced identical outputs across repetitions for every scenario. These results confirm integration and functional separation under the tested conditions, but they do not demonstrate week-scale reliability, longer-horizon forecasting accuracy, robotic mobility performance, or load scalability.
Full article

Figure 1
Open AccessReview
A Survey of Visual Question Answering for Embodied Robots: Tasks, Methods, and Future Directions
by
Weihan Shi and Yinlong Liu
AI 2026, 7(9), 367; https://doi.org/10.3390/ai7090367 - 15 Sep 2026
Abstract
Visual Question Answering (VQA) in embodied settings draws on computer vision, natural language processing, and robotics. Unlike traditional VQA, Embodied Question Answering (EQA) may require an agent to acquire and retain evidence from a 3D environment before answering a natural language query. This
[...] Read more.
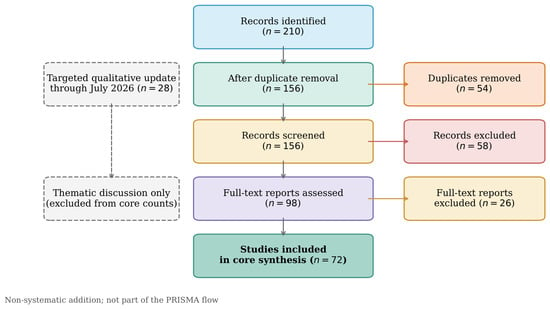
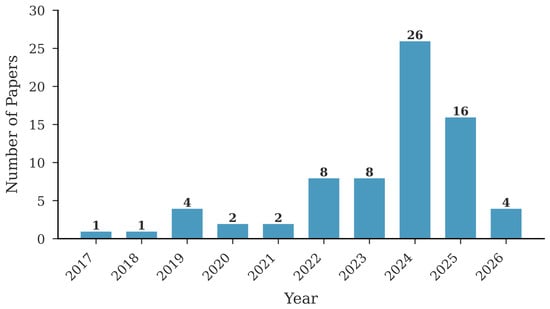
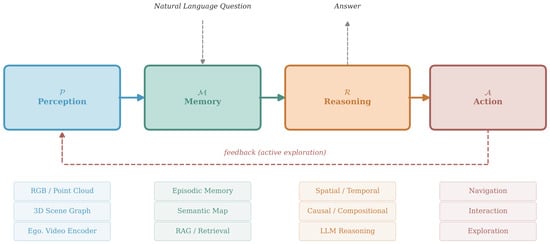
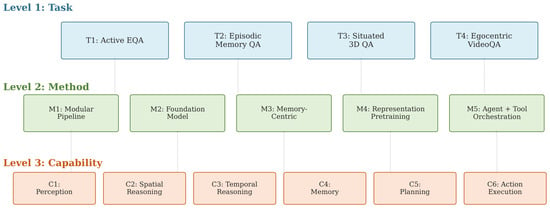
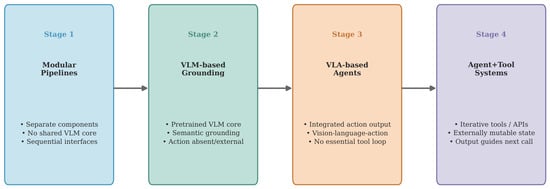
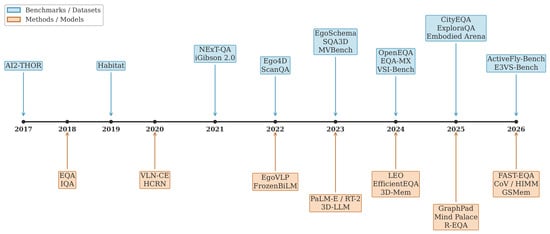
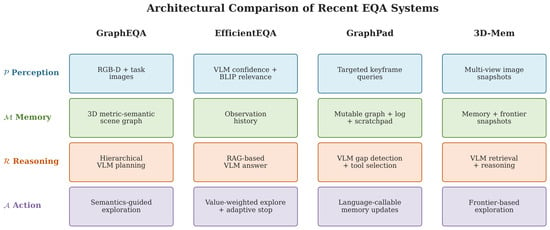
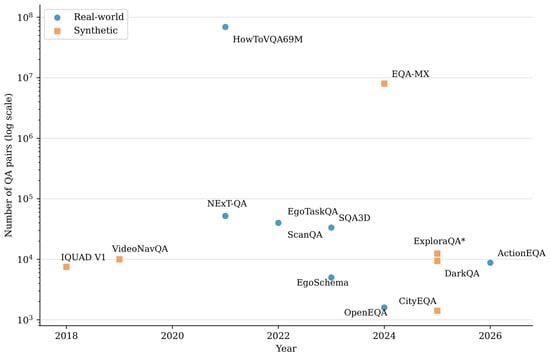
Visual Question Answering (VQA) in embodied settings draws on computer vision, natural language processing, and robotics. Unlike traditional VQA, Embodied Question Answering (EQA) may require an agent to acquire and retain evidence from a 3D environment before answering a natural language query. This semi-systematic survey reviews a core corpus of 72 papers selected from 210 candidates and supplements it with a separate targeted qualitative update comprising 28 additional records identified through July 2026. We use PMRA (Perception–Memory–Reasoning–Action) as an author-developed analytical framework rather than a new robot-control architecture, together with a three-level taxonomy of task formulations, method architectures, and capability dimensions. An audit of the 20 tabulated datasets, with counts recomputed from the accompanying extraction sheet, finds that five permit or require active exploration and only one requires physical object interaction. We also define four architecture-based stages without using publication year as an assignment rule. The qualitative synthesis identifies examples of explicit memory interfaces and question-conditioned information-acquisition mechanisms, but it does not infer their prevalence, temporal growth, or relative importance from publication frequencies. Finally, we discuss four recurring limitations of foundation-model approaches and nine research directions toward 2030.
Full article
(This article belongs to the Special Issue Artificial Intelligence for Robotic Perception and Planning)
►▼
Show Figures

Figure 1
Open AccessArticle
Architectural Transferability in Bounded AI: Five Conditions for Regulated Decision Domains
by
George Melville, Dena Ghiassi, Scott Inthathirath and Julian Yeomans
AI 2026, 7(9), 366; https://doi.org/10.3390/ai7090366 - 15 Sep 2026
Abstract
AI and machine learning deployments in regulated decision contexts face an intolerance for inadmissible outputs (“hallucinations” when the model is generative) that current explainability methods address only after the fact. Bounded AI denotes prevention by architectural design. This study establishes five conditions (C1–C5)
[...] Read more.
AI and machine learning deployments in regulated decision contexts face an intolerance for inadmissible outputs (“hallucinations” when the model is generative) that current explainability methods address only after the fact. Bounded AI denotes prevention by architectural design. This study establishes five conditions (C1–C5) under which a bounded artificial intelligence (AI) architecture transfers from one regulated decision domain to another. Conditions C1 through C4 adapt or combine previously established principles. The most significant contribution is the discrete joint-state topology condition, C5, for which no precedent was found in this role. The claim is that these five conditions are jointly necessary for the closure property to survive an architectural transfer—while sufficiency is not claimed. Two of the five conditions are structural prerequisites governing whether the architecture’s operators can be constructed in a destination at all. The remaining three provide warrant conditions governing whether it is the appropriate instrument or not. In existing runtime-assurance architectures, the constraint acts after inference, on the output of the learned component. In contrast, the pattern developed in this paper reverses the assurance steps via a deterministic-first/learned-second approach. Namely, the assurance architecture acts before inference on the input domain: a deterministic filter admits only rule-compliant objects, and the trigger fires non-discretionarily on joint-state cell occupancy rather than on the learned score. The architecture’s domain-neutral type signatures are formalized, and three structural transfers are developed in depth: predictive maintenance, energy-grid management, and credit underwriting, each concluding with a closure proof. All three transfers remain conceptual and report no deployment outcomes. The proofs are conditional on three stated premises that establish soundness with respect to a rule set rather than a safety case. The strongest evidence of transferability is a market-surveillance destination classified as admissible in advance and later realized on a live venue. C5 is what discriminates the transferability. It is shown that the autonomous-vehicle perception case satisfies C1 through C4, but fails C5 because the required distinctions are absent from the representation at every granularity—which is a failure that no additional compute can resolve. The architecture becomes domain-neutral through the act of transfer, not before it.
Full article
(This article belongs to the Special Issue The Use of Artificial Intelligence in Business: Innovations, Applications and Impacts)
Open AccessArticle
Synthetic Mammography Image Generation Using DCGANs: Toward Self-Training of Artificial Intelligence Models
by
Yazmin Mariela Hernández-Rodríguez and Oscar E. Cigarroa-Mayorga
AI 2026, 7(9), 365; https://doi.org/10.3390/ai7090365 - 15 Sep 2026
Abstract
►▼
Show Figures
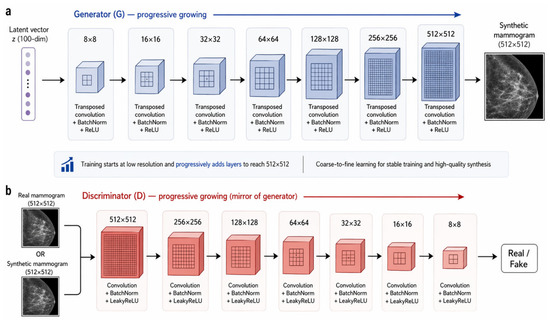
This study evaluated unconditional synthetic mammography generation with Deep Convolutional Generative Adversarial Networks (DCGANs). The dataset comprised 690 anonymized mammograms, equally distributed across BI-RADS 1–6 (115 images/category). All images were standardized to 512 × 512 pixels, reoriented to a common right-breast view, and
[...] Read more.
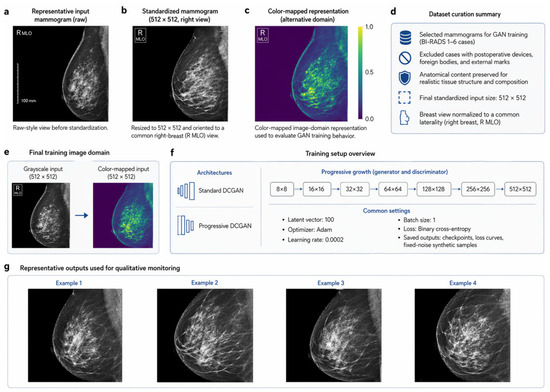
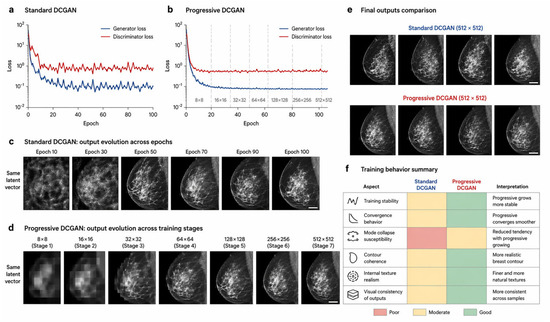
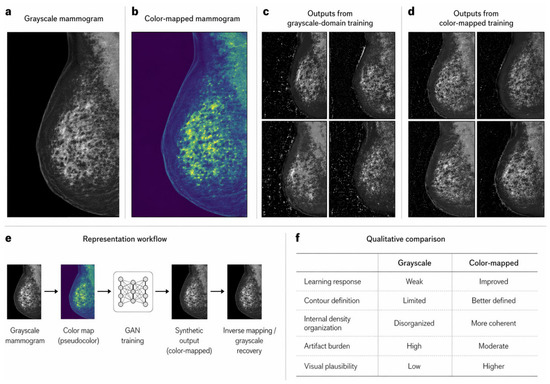
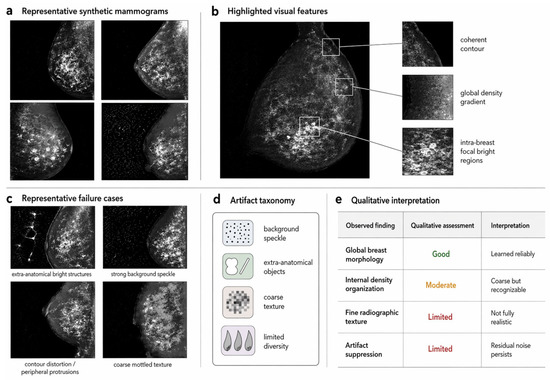
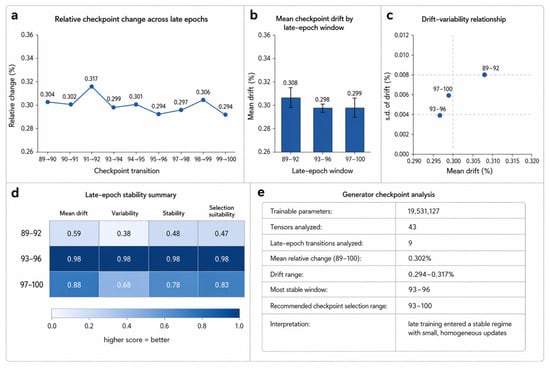
This study evaluated unconditional synthetic mammography generation with Deep Convolutional Generative Adversarial Networks (DCGANs). The dataset comprised 690 anonymized mammograms, equally distributed across BI-RADS 1–6 (115 images/category). All images were standardized to 512 × 512 pixels, reoriented to a common right-breast view, and prepared in two input domains: grayscale and color-mapped intensity encoding. Two models were compared: a standard DCGAN trained directly at 512 × 512, and a progressive DCGAN trained through discrete stages from 8 × 8 to 512 × 512. Training used PyTorch (Python 3.10), latent dimension = 100, Adam, learning rate = 2 × 10⁻⁴, β1 = 0.5, binary cross-entropy loss, and batch size = 1. Both models learned the low-frequency mammographic manifold, generating breast-like silhouettes and heterogeneous internal intensity distributions. However, the progressive DCGAN produced smoother contours, more coherent internal organization, and fewer grid/line artifacts than the standard model. Grayscale-only training showed weak learning, whereas the color-mapped domain improved structural recovery, although this advantage should be interpreted as computational rather than clinical. Late-epoch checkpoint analysis showed a structurally invariant generator with 43 tensors and 19,531,127 parameters; from epochs 89–100, relative checkpoint drift remained within 0.294–0.317%, with epochs 93–96 showing the most stable regime. Despite these advances, generated images still exhibited background speckle, coarse mottled texture, extra-anatomical bright structures, and limited diversity. Thus, the results support feasibility of synthetic mammography generation, but not yet clinically reliable synthetic data for direct AI training. The generated images should presently be regarded as exploratory complementary data pending expert, metric-based, and downstream validation.
Full article

Figure 1
Open AccessArticle
A Counterfactual-Enabled Agricultural Decision Support Framework for Sustainability-Aware Groundnut Yield Prediction Using Bayesian-Optimized XGBoost
by
Rekha R Nair, Tina Babu, Sumendra Yogarayan and Siti Fatimah Binti Abdul Razak
AI 2026, 7(9), 364; https://doi.org/10.3390/ai7090364 - 14 Sep 2026
Abstract
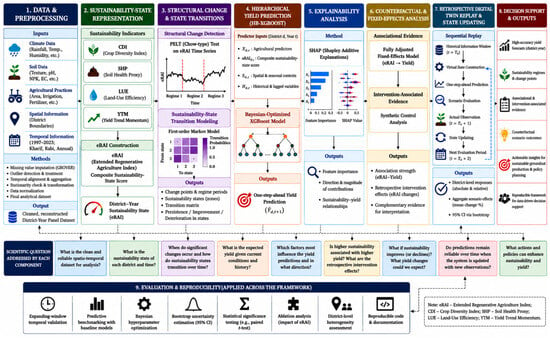
Sustainable agricultural planning requires predictive frameworks that can capture spatiotemporal variability, sustainability dynamics, and the potential outcomes of alternative management scenarios. The research proposes TSAFI-DT, a retrospectively validated, data-driven Digital Twin prototype integrating spatiotemporal data reconstruction, sustainability-state representation, hierarchical yield forecasting, counterfactual analysis,
[...] Read more.
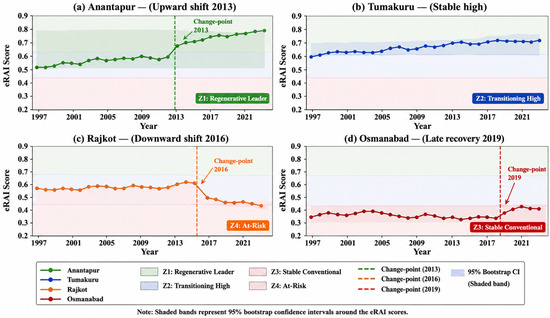
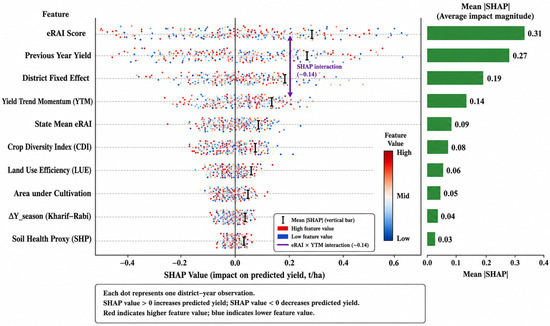
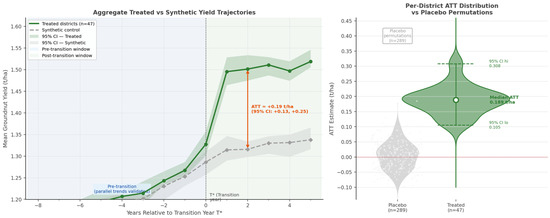
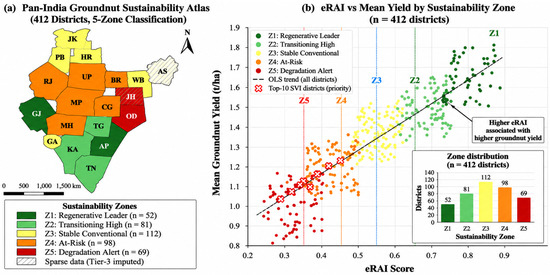
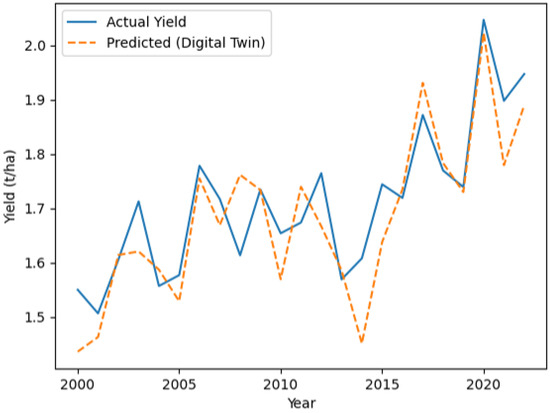
Sustainable agricultural planning requires predictive frameworks that can capture spatiotemporal variability, sustainability dynamics, and the potential outcomes of alternative management scenarios. The research proposes TSAFI-DT, a retrospectively validated, data-driven Digital Twin prototype integrating spatiotemporal data reconstruction, sustainability-state representation, hierarchical yield forecasting, counterfactual analysis, and scenario simulation. The framework operates on historical district-level APY observations and therefore represents a retrospective approximation of Digital Twin operation rather than a continuously synchronized cyber-physical agricultural Digital Twin. The Extended Regenerative Agriculture Index (eRAI) combines crop diversity, productivity–stability, land-use efficiency, and yield-trend information to characterize district-level sustainability states. A Bayesian-optimized XGBoost model is employed for one-step-ahead yield forecasting under temporal validation, while fixed-effects and synthetic-control analyses provide complementary associational and intervention-associated evidence. Evaluation using district-level groundnut data from India during 1997–2023 demonstrates that the proposed predictor achieves an RMSE of 0.171 t/ha and , outperforming the evaluated baselines with statistically significant differences ( ). The fully adjusted fixed-effects model identifies a positive association between higher sustainability states and yield, while retrospective Digital Twin replay demonstrates close temporal agreement between predicted and observed outcomes. Model-based scenario simulations indicate predicted yield increases of up to 12.4% under the evaluated sustainability-state perturbations; these estimates represent counterfactual sensitivity rather than guaranteed causal effects. TSAFI-DT provides a reproducible framework for sustainability-aware agricultural forecasting, comparative scenario exploration, and data-driven decision support.
Full article
(This article belongs to the Special Issue Harvesting the Future: AI Applications in Precision Agriculture)
►▼
Show Figures

Figure 1
Open AccessArticle
Governing AI Outcomes in Civil and Construction Engineering Education: Toward Trustworthy and Ethical Implementation
by
Armita Dabiri and Amir H. Behzadan
AI 2026, 7(9), 363; https://doi.org/10.3390/ai7090363 - 14 Sep 2026
Abstract
Artificial intelligence (AI) is transforming civil and construction engineering (CCE) education. CCE students must develop both AI technical proficiency and ethical awareness, ensuring that AI tools reflect the varied experiences of project clients. Integrating ethical AI instruction supports the formation of students’ professional
[...] Read more.
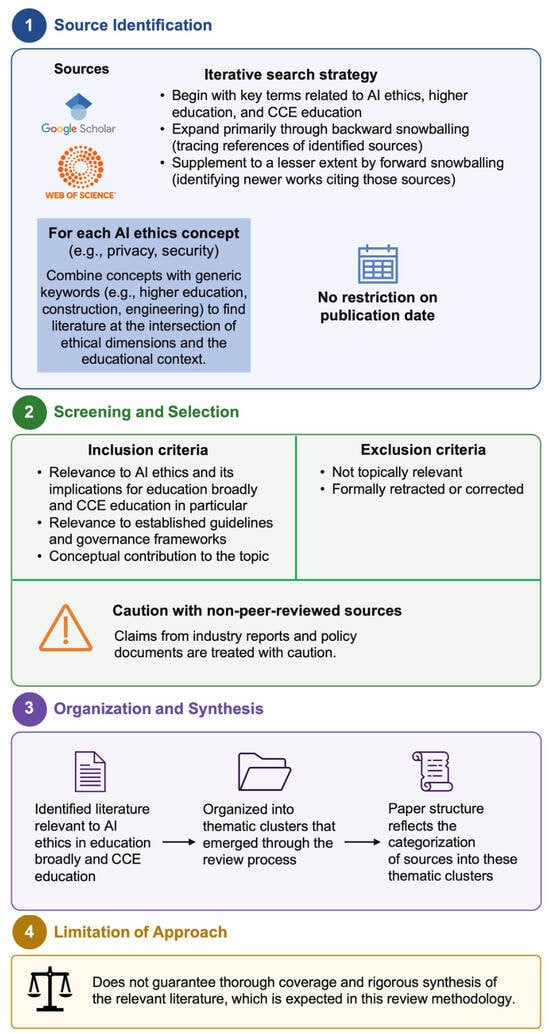
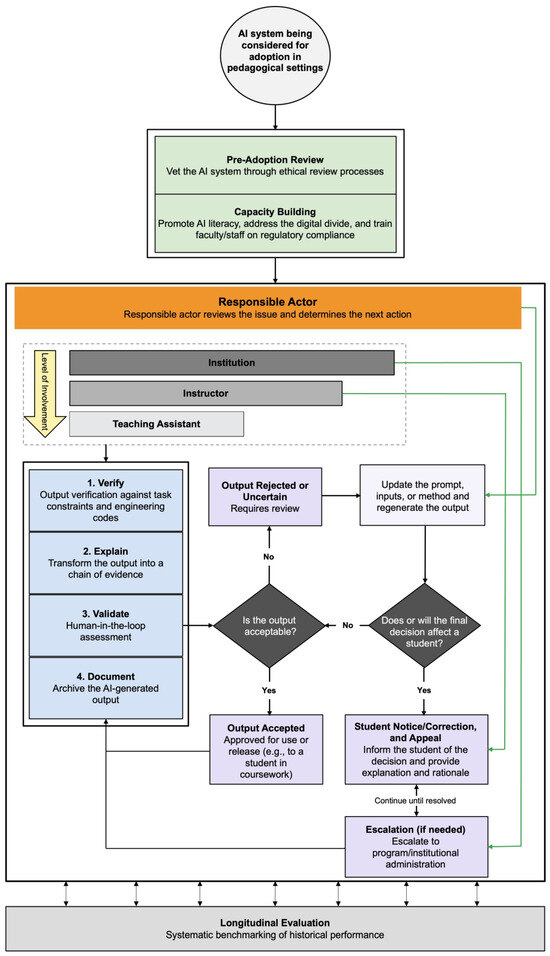
Artificial intelligence (AI) is transforming civil and construction engineering (CCE) education. CCE students must develop both AI technical proficiency and ethical awareness, ensuring that AI tools reflect the varied experiences of project clients. Integrating ethical AI instruction supports the formation of students’ professional identity by encouraging them to internalize values of responsibility, integrity, and equity in future practice. Adopting a narrative literature review, this paper examines the ethical concerns surrounding AI in CCE education, implications of existing regulations, and the need for institution-specific risk mitigation policies. The synthesis of the literature indicates that while integrating AI into CCE education may enhance learning experiences and personalized instruction, it also raises key ethical risks, such as algorithmic bias, privacy concerns, lack of transparency, threats to academic integrity, and digital inequity. As such, we also offer guidelines for responsible AI use in educational settings and propose an output governance framework and practical recommendations for educators and institutions, including performing regular ethical and algorithmic audits of AI tools, involving students in technology deployment decisions, and providing faculty development on digital ethics. By detailing actionable strategies, formalizing human-in-the-loop validation workflows, and preserving chains of provenance for educational metrics, these recommendations aim to align AI innovation with the core values of engineering education, i.e., integrity, equity, and public welfare.
Full article
(This article belongs to the Special Issue Governing Trustworthy AI Outputs in a Sensor-Dense Society: Privacy, Auditability and Responsible Deployment)
►▼
Show Figures

Figure 1
Open AccessArticle
PreCrash: A Multi-Feature Fusion Approach for Predicting the Reproducibility of Crash Reports
by
Shaoting Liu, Haiyan Xu, Ziqi Shuai and Jifeng Xuan
AI 2026, 7(9), 362; https://doi.org/10.3390/ai7090362 - 13 Sep 2026
Abstract
Crash reports are critical for software debugging and maintenance. In software maintenance, developers reproduce a crash to locate the root cause via analyzing the crash report. A crash report is a document that records details of the crash as it occurred. The crash
[...] Read more.
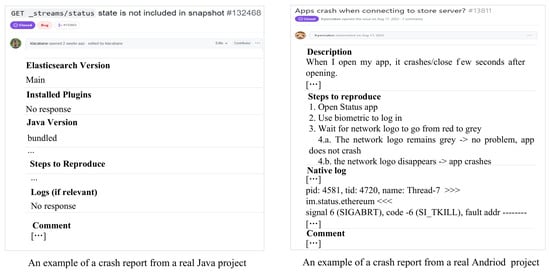
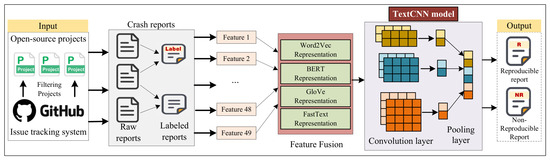
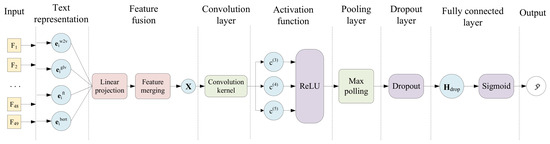
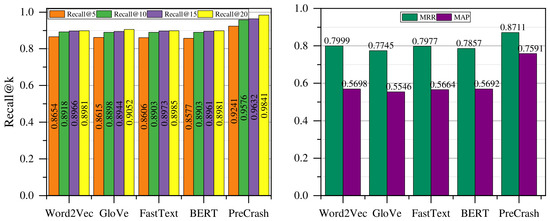
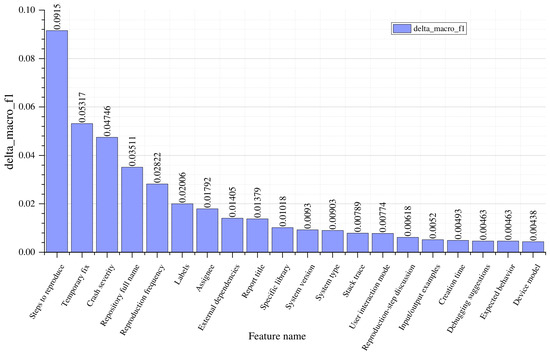
Crash reports are critical for software debugging and maintenance. In software maintenance, developers reproduce a crash to locate the root cause via analyzing the crash report. A crash report is a document that records details of the crash as it occurred. The crash reports cannot be reproduced by developers because numerous crash reports in real-world issue-tracking systems contain incomplete reproduction steps and ambiguous descriptions. Existing works have explored the reproduction of crash reports for Android applications. These works focus on the process of reproducing crashes based on steps to reproduce and stack traces. However, it is a challenging task to manually identify reproducible crash reports from a large number of crash reports that consist of missing reproduction steps. To address this challenge, we propose PreCrash, a multi-feature fusion approach for predicting the reproducibility of a crash report. This approach helps identify reproducible crash reports before developers expend manual effort trying to reproduce the crashes. First, PreCrash automatically extracts 49 features from each crash report, which cover basic metadata, contextual content, comments, and supplementary evidence in crash reports. Second, PreCrash integrates four text representation models, including Word2Vec, GloVe, FastText, and BERT representations. Third, PreCrash employs a TextCNN-based prediction model to capture semantic patterns based on the integrated text representation. We evaluate PreCrash on 4133 crash reports collected from 102 real-world Java and Android projects on GitHub. Experimental results show that PreCrash achieves an accuracy of 0.91 and an F1-score of 0.91. PreCrash outperforms traditional machine learning models and single text representation baselines.
Full article
(This article belongs to the Special Issue AI-Driven Advances in Modern Software Engineering and Web Technologies)
►▼
Show Figures

Figure 1
Open AccessArticle
Explainable Hybrid GRU–TabTransformer Learning with Cross-Attention and LLM-Assisted Interpretation for Stroke Risk Prediction
by
Moses Guddah and Adham Atyabi
AI 2026, 7(9), 361; https://doi.org/10.3390/ai7090361 - 13 Sep 2026
Abstract
Early stroke risk prediction offers an opportunity for timely interventions and may help reduce the clinical burden associated with stroke. Artificial intelligence (AI) provides medical practitioners with tools to analyse clinical biomarkers and predict a patient’s stroke risk. However, existing models lack interpretability
[...] Read more.
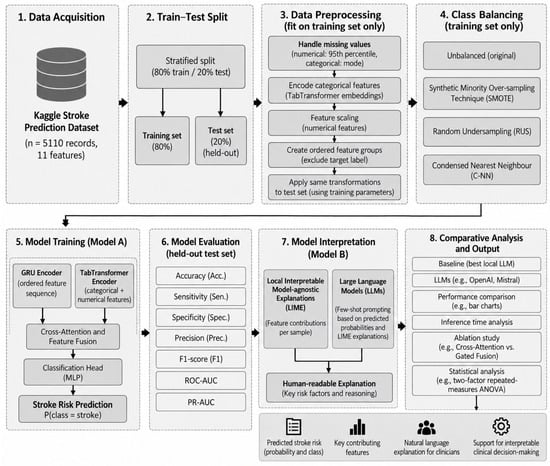
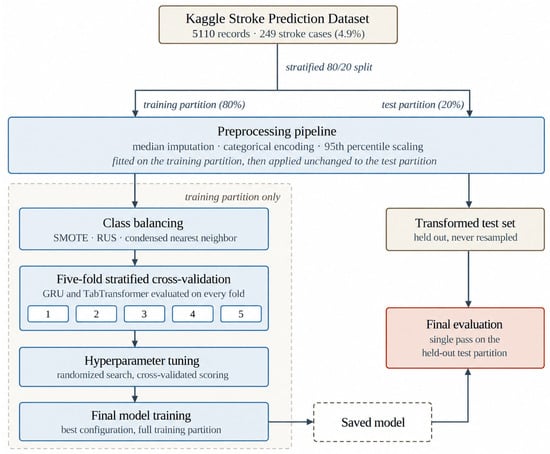
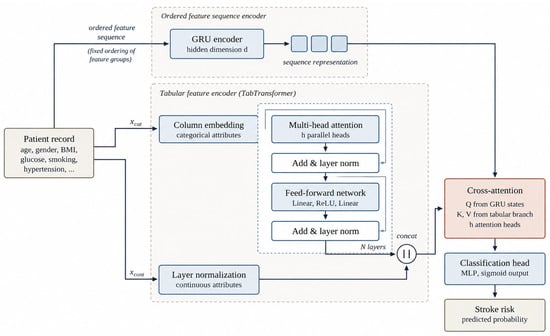
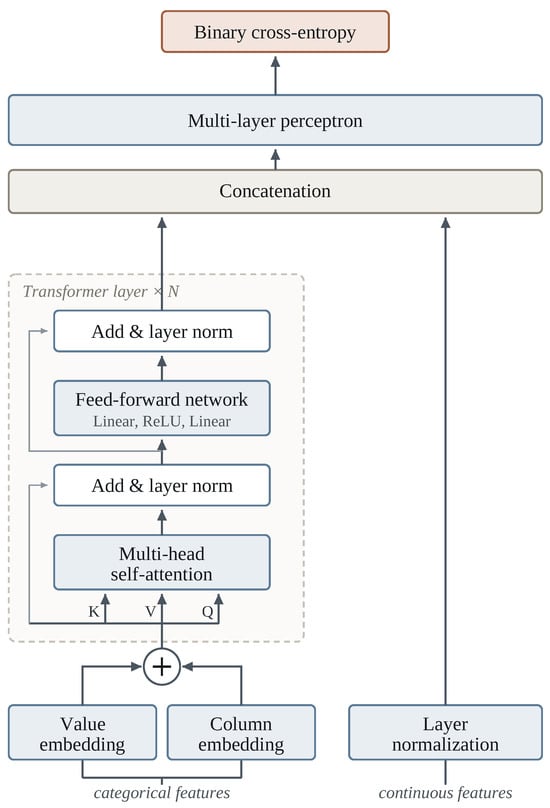
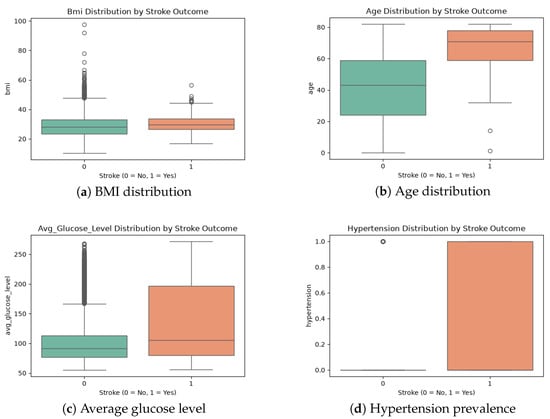
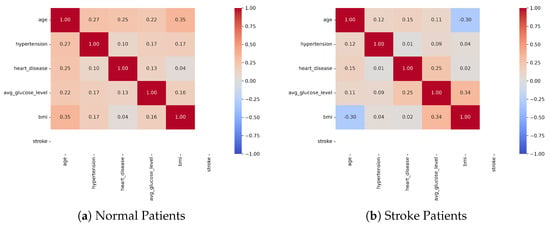
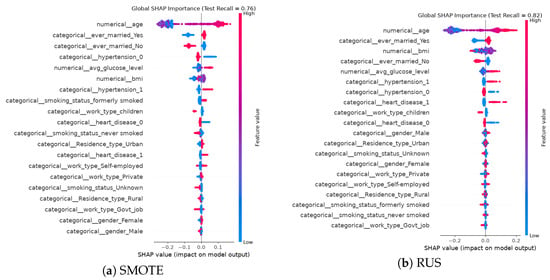
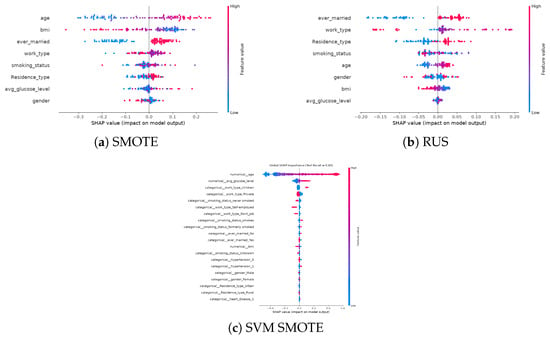
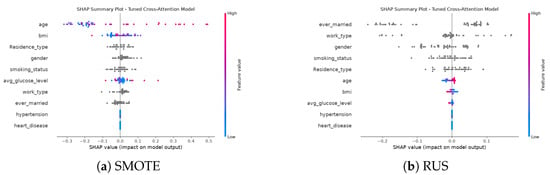
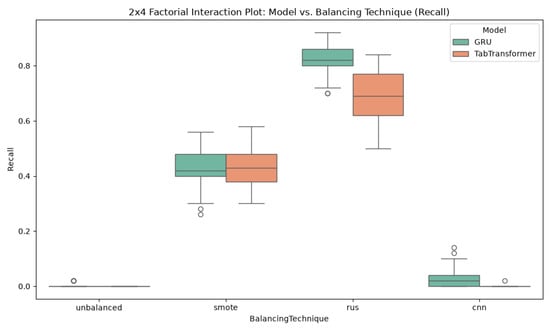
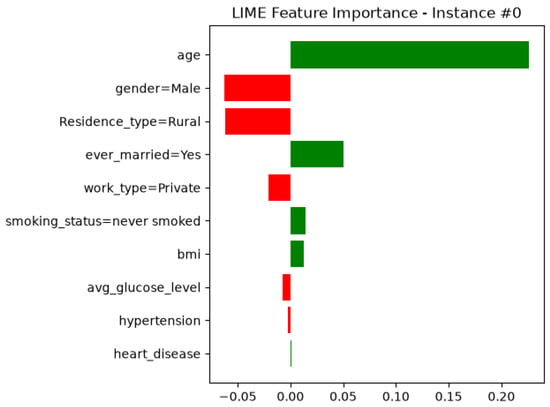
Early stroke risk prediction offers an opportunity for timely interventions and may help reduce the clinical burden associated with stroke. Artificial intelligence (AI) provides medical practitioners with tools to analyse clinical biomarkers and predict a patient’s stroke risk. However, existing models lack interpretability and explainable decision support, limiting their adoption in clinical settings. This paper proposes a hybrid Gated Recurrent Unit (GRU)-TabTransformer architecture using cross-attention for stroke-status prediction. The proposed architecture comprises two stages. In the first stage (Model A), ordered feature-sequence representations from a GRU encoder are combined with concatenated categorical and numerical tabular features from a TabTransformer encoder. The model passes these distinct learned representations through cross-attention and linear projection layers before the final prediction. In the second stage (Model B), we augment our model with Large Language Models (LLMs) and Local Interpretable Model-agnostic Explanations (LIME) to provide per-sample, post hoc, human-interpretable explanations based on predicted probabilities. Experimental results show that both models achieve competitive sensitivity and accuracy values. In particular, the Synthetic Minority Over-sampling Technique (SMOTE) yielded a more balanced sensitivity–specificity trade-off, with a sensitivity of 74.00% and a specificity of 75.10%. Moreover, the model achieved an accuracy of 75.05% with SMOTE. An ablation study further shows that Cross-Attention offers better sensitivity and Receiver Operating Characteristic-Area Under the Curve (ROC-AUC), while Gated Fusion performs better on several other metrics. Additionally, age and average glucose level were the most influential stroke risk indicators, while Body Mass Index (BMI) and ever-married status were secondary model-attributed features. A two-factor repeated-measures Analysis of Variance (ANOVA) confirmed an interaction between model choice and the class-balancing technique used in stroke risk prediction systems. The Mistral + Hybrid GRU-TabTransformer architecture also recorded a mean inference time of 57.59s using few-shot prompting. Overall, the results provide a proof of concept for integrating hybrid GRU-TabTransformer with cross-attention and LLM-based explainability to support interpretable stroke risk prediction systems, pending robust external validation before deployment.
Full article
(This article belongs to the Special Issue LLMs and AI Agents in Biomedical and Health Sciences)
►▼
Show Figures

Figure 1
Highly Accessed Articles
Latest Books
E-Mail Alert
News
Topics
Topic in
AI, Applied Sciences, Designs, Electronics, Mathematics, Remote Sensing, Sensors
The Future of Artificial Intelligence: Trends, Challenges, and Developments
Topic Editors: Yinbin Miao, Jun Feng, Wenqian DongDeadline: 30 September 2026
Topic in
Molecules, Biomimetics, Chemosensors, Life, AI, Sci
Recent Advances in Chemical Artificial Intelligence
Topic Editors: Pier Luigi Gentili, Jerzy Górecki, David C Magri, Pasquale StanoDeadline: 15 October 2026
Topic in
AI, Applied Sciences, Computers, Electronics, Entropy, Future Internet, Information, IoT, Sensors, Telecom
Advances in Sixth Generation and Beyond (6G&B)
Topic Editors: Luis Javier García Villalba, Ana Lucila Sandoval OrozcoDeadline: 31 October 2026
Topic in
AI, Algorithms, Diagnostics, Emergency Care and Medicine
Trends of Artificial Intelligence in Emergency and Critical Care Medicine
Topic Editors: Zhongheng Zhang, Yucai Hong, Wei ShaoDeadline: 30 November 2026
Conferences
Special Issues
Special Issue in
AI
Large Language Models and Autonomous Agents for Semantic Web, Search, and Recommendations
Guest Editors: Tong Xu, Zhi ZhengDeadline: 25 September 2026
Special Issue in
AI
Artificial Intelligence in Industrial Systems: From Data Acquisition to Intelligent Decision-Making
Guest Editors: Hugo Landaluce, Ignacio Angulo Martínez, Ander GarciaDeadline: 30 September 2026
Special Issue in
AI
Federated and Distributed Intelligence for Sustainable Edge-Cloud Ecosystems
Guest Editors: Francisco A. Pujol, Amir Javed, Higinio MoraDeadline: 30 September 2026
Special Issue in
AI
Artificial Intelligence Potential to Solve Multiple Complex Geodetic Problems
Guest Editors: Lyubka Pashova, Shuanggen Jin, Desislava IvanovaDeadline: 30 September 2026