
- Article

32 Pages
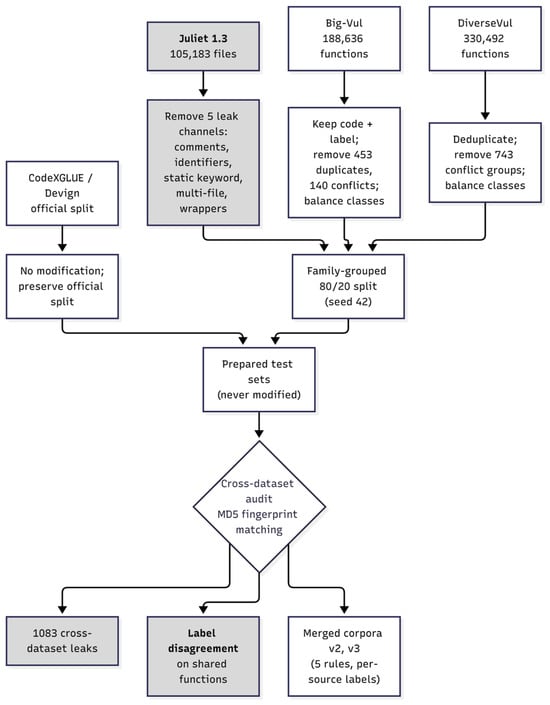
Machine-learning research on software vulnerability detection measures progress against a small set of public benchmark datasets, treated as a shared yardstick for comparing models. This approach rests on the untested premise that benchmarks agree: if two datasets have the same function, they give it the same label. We test this assumption by comparing four popular C and C++ benchmarks against one another on their complete data. Label agreement is a symmetric relation, but its strength is uneven. The two benchmarks that derive labels from CVE-linked fixing commits disagree on only 0.68% of 75,019 shared functions, whereas a third disagrees with them on 51.21% and 41.28%. Leakage, in contrast, is directed: we identify 1083 instances in which training data from one benchmark reappears in test data from another, with different counts in each direction. A manual check of 30 contradictory functions traces the disagreements to commit-level labeling and to treating functions left unchanged by a fix as safe. The costs are asymmetric: contradictory labels impair training only slightly, while up to 3.12% of a test set carries a contradicted label, shifting measured accuracy by up to two points. Therefore, reported accuracy reflects both model capabilities and benchmark selection.
Symmetry
23 October 2026