Skip to Content
  • 2.2
    Impact Factor
  • 3.9
    CiteScore
  • 23 days
    Submission to First Decision
  • 5 days
    Acceptance to Publication

Journal of Eye Movement Research

Journal of Eye Movement Research (JEMR) is an international, peer-reviewed, open access journal on all aspects of oculomotor functioning including methodology of eye recording, neurophysiological and cognitive models, attention, reading, as well as applications in neurology, ergonomy, media research and other areas, and published bimonthly online by MDPI (from Volume 18, Issue 1 - 2025).
  • Open Access— free for readers, with article processing charges (APC) paid by authors or their institutions.
  • High Visibility: indexed within Scopus, SCIE (Web of Science), PubMed, PMC, and other databases.
  • Journal Rank: JCR - Q2 (Ophthalmology) / CiteScore - Q2 (Ophthalmology)
  • Rapid Publication: manuscripts are peer-reviewed and a first decision is provided to authors approximately 22.9 days after submission; acceptance to publication is undertaken in 4.5 days (median values for papers published in this journal in the first half of 2026).
  • Recognition of Reviewers: Reviewers whose reports are timely and of high quality receive an APC discount voucher for a future publication in an MDPI journal. Become a reviewer.

Get Alerted

Add your email address to receive forthcoming issues of this journal.

All Articles (722)

  • Article
  • Open Access

For individuals with limited limb function, conventional manual control methods such as joysticks are not readily applicable to assistive robot operation, highlighting the need for a hands-free control method. Eye movements, as natural signals of human intention, offer advantages in intuitiveness and accessibility and are particularly suitable for such scenarios. However, prior studies have primarily focused on fixation-based gaze interaction, and relying solely on fixation is inadequate for human–robot interaction tasks that involve both robot movement and target selection. This paper presents an assistive human–robot interaction (HRI) system based on eye-movement behavior recognition. First, an eye-movement dataset named GazeRobDB containing four eye-movement behavior classes was constructed. Representative eye-movement features were then extracted and analyzed to support eye-movement behavior classification. Next, a feature-based recognition approach using machine-learning classifiers was developed to distinguish the four eye-movement behavior classes—fixation, saccade, intentional fixation, and intentional movement. Among the evaluated classifiers, random forest (RF) achieved the highest overall classification performance and was combined with the extracted eye-movement features to form the eye-movement behavior recognition module of the proposed HRI system. The recognized intentional fixation and intentional movement behaviors were then mapped to target selection and robot movement control, respectively. The resulting system was evaluated with 10 participants. These results demonstrate the feasibility of the proposed framework for hands-free robot control under the evaluated conditions and highlight its potential for assistive human–robot interaction.

J. Eye Mov. Res.

6 November 2026
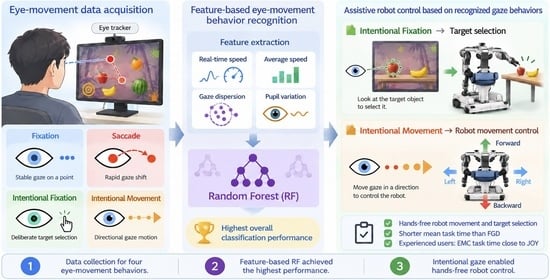
Overall framework of the proposed eye-movement-based assistive human–robot interaction system. Arrows indicate the data flow and behavior-to-control mapping. Dashed boxes delineate the main processing stages, and the red box highlights the selected RF classifier.
  • Review
  • Open Access

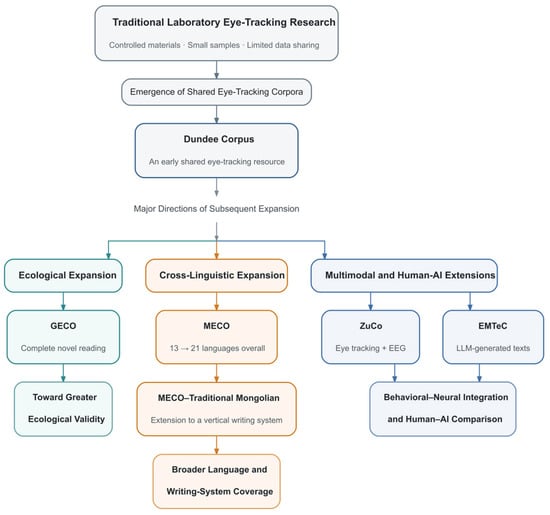
Eye-tracking corpora integrate authentic linguistic materials from natural reading contexts with eye-movement data. They provide a new methodological paradigm for investigating cognitive processing during reading with relatively high ecological validity. At present, significant progress has been made internationally in both the development and application of eye-tracking corpora. In China, however, research in this area began relatively late. A clear and comprehensive understanding of this field is still lacking, which has constrained the further development of related research in China. Therefore, this article systematically reviews the basic characteristics of eye-tracking corpora, major research advances, and key methodological issues. It also discusses future directions for the field. The review aims to provide researchers in China with a comprehensive overview of the field and methodological guidance for developing eye-tracking corpora for Chinese and minority languages spoken in China, while drawing on these regional examples to illustrate broader international challenges in data harmonization, cross-linguistic comparability, and reproducibility.

J. Eye Mov. Res.

6 November 2026
Developmental trajectory and major directions of expansion in eye-tracking corpus research on reading. References mentioned in the figure: Dundee Corpus [8], MECO [9,10], MECO–Traditional Mongolian [20], GECO [29], ZuCo [32], and EMTeC [33].
  • Article
  • Open Access

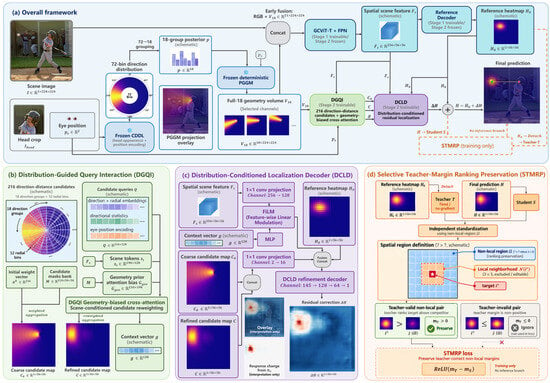
Given a static image and a selected person, general gaze following predicts the person’s likely gaze target. Ambiguous head cues can leave several geometrically plausible targets. We develop a scene-conditioned localization framework that retains directional uncertainty instead of collapsing it into one gaze direction. Building on a fixed, previously published geometry-guided reference, Distribution-Guided Query Interaction (DGQI) refines direction–distance candidates using scene evidence, the Distribution-Conditioned Localization Decoder (DCLD) adjusts the reference heatmap through residual prediction, and Selective Teacher-Margin Ranking Preservation (STMRP) protects selected correct spatial rankings during training. On the GazeFollow official test set, the final model reaches a pooled/global AUC of 0.9190, an original-resolution per-image AUC of 0.9342, and a normalized distance error of 0.1289 compared to the published baseline values of 0.9066, 0.9214, and 0.1423, respectively. Within-reference controls distinguish module effects from cross-generation changes in the scene backbone. DCLD yields the clearest localization gains; DGQI contributes a smaller discrimination gain; and STMRP improves per-image AUC at a localization cost. This separation has revealed that discrimination and peak localization need not improve together. Zero-shot experiments on VideoAttentionTarget and a coverage-limited ChildPlay subset expose further domain sensitivity. These results motivate protocol-aware, multi-metric evaluation of gaze predictions.

J. Eye Mov. Res.

4 November 2026

Geometry-guided target-commitment framework. (a) Overall framework. The frozen CDDL–PGGM branch preserves directional uncertainty and constructs the full-18 geometry volume, which is fused with RGB input to establish the GCViT-T/FPN geometry-guided reference. DGQI and DCLD are optimized in the second stage on top of the frozen reference, whereas STMRP is used only during training. (b) DGQI forms 216 structured direction–distance candidates from 18 direction groups and 12 radial bins, combines candidate queries with scene tokens under a geometry-biased cross-attention prior, and produces the coarse and refined candidate maps C0 and C together with the context vector g. (c) DCLD conditions the spatial scene feature using g, projects the coarse and refined candidate maps, and combines these signals with H0 to predict the residual correction ΔH; the response-change visualizations are interpretation aids rather than additional inference outputs. (d) STMRP uses the detached reference prediction H0 as a teacher and the final prediction H as a student, standardizes them using statistics from the non-local region, excludes the 3 × 3 target neighborhood from ranking preservation, and penalizes only the reductions in teacher-valid non-local margins. Schematic elements are labeled explicitly; unlabeled embedded response maps show outputs from the representative sample used in the figure. The sample image is from the GazeFollow dataset [8].
  • Article
  • Open Access

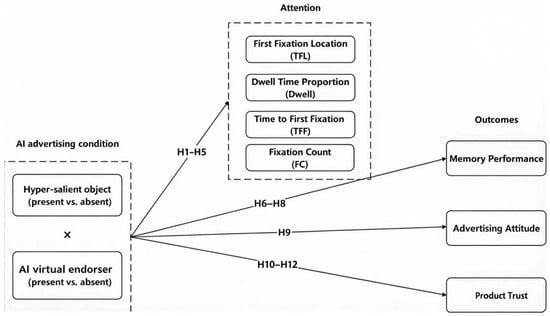
Generative artificial intelligence (AI) advertising, defined as advertising content created or substantially assisted by generative AI systems (AIGC), has introduced new visual features that combine algorithmically generated objects with human-like representations. Hyper-salient objects, defined by exaggerated perceptual prominence and semantic incongruity, and AI-generated virtual endorsers, represented by human-like AI-created figures, have become increasingly common in such advertisements. However, little is known about how these distinct visual cues compete for consumers’ limited attentional resources when presented together. Drawing on visual attention and scene perception perspectives, this study investigated how hyper-salient objects and AI-generated virtual endorsers influence visual attention allocation in AI-generated advertising. A 2 (hyper-salient object: present vs. absent) × 2 (AI endorser: present vs. absent) between-subjects eye-tracking experiment was conducted with 160 participants in a controlled laboratory setting using static AI-generated advertisements. Eye movements were recorded, and memory was assessed using signal detection measures (d′) from a recognition task involving target and distractor advertisements. Advertising attitude and product trust were measured using established scales. Results from linear and generalized linear mixed-effects models showed that hyper-salient objects increased early fixation probability and attracted a larger dwell time proportion, demonstrating strong attentional capture. AI-generated endorsers also attracted attention when presented alone, but their proportional attention share decreased when hyper-salient objects were simultaneously present. The effects of these visual elements on memory and product trust were conditional on their co-occurrence rather than uniform across conditions. Within the specific set of experimentally constructed stimuli and four sampled product categories, this research contributes to AIGC advertising literature by developing a visual competition perspective on how multiple AI-generated visual cues interact under limited attentional capacity, offering implications for designing effective generative AI advertisements.

J. Eye Mov. Res.

2 November 2026

Research model. Note: × denotes the interaction between the two experimental factors (hyper-salient object and AI virtual endorser).

Featured Articles of Last Quarter

Highly Accessed Articles

News & Conferences

Latest Issues

Open for Submission

Journal Sections

XFacebookLinkedIn
J. Eye Mov. Res. - ISSN 1995-8692