1. Introduction
Accurately predicting dam inflow is a public safety and resource management challenge. By better predicting the volume of water flowing into the reservoir from rainstorms or snowmelt, water managers can gain time to safely release stored water and increase storage capacity for the management of floods. This can moderate the peak inflow of the flood and protect downstream structures from damage. This can turn a natural disaster into a manageable event, protecting lives and property. In areas where reservoir storage is important, forecasting inflows enables reliable planning of drinking water supply and agricultural irrigation for future seasons [
1]. For hydroelectric dams, inflow forecasting is directly related to optimizing power generation. This process enables operators to maximize production when demand is high and maintain grid stability [
2]. This function ensures good water management for homes, farms, and industries.
Traditional methods struggle with complex, nonlinear time series due to their reliance on assumptions of stationarity and linearity, leading to poor capture of shifts, trends, and temporal dependencies [
3,
4]. Machine learning (ML) excels at finding complex, nonlinear patterns within large datasets that are often impossible for physical models or human analysts to discern. In general, machine learning improves performance in most fields, including transportation [
5], agriculture, and hydrology [
6]. By training on historical hydrologic data—including rainfall, snowpack, soil moisture, temperature, and past inflow rates—ML models can learn the unique features of a watershed’s response to weather events [
7]. This allows ML models to make highly accurate inflow forecasts by processing real-time data from weather forecasts and sensor networks. Unlike complex physical hydrological models that require detailed knowledge of the terrain and soil properties, ML models can often achieve robust predictions directly from the data, making them particularly valuable in data-scarce or rapidly changing environments. The practical benefits of this are transformative for reservoir management. ML models can process vast amounts of data in near-real time, providing forecasts with a longer and more reliable lead time. This gives operators a crucial window to make proactive decisions, such as pre-releasing water to create flood storage or conserving water in anticipation of a drought. Furthermore, ML enables ensemble prediction, where multiple scenarios are run simultaneously, quantifying the probability and uncertainty of different inflow outcomes [
8]. This shift from a single “most likely” forecast to a probabilistic range empowers operators to assess risks more comprehensively and make smarter, more informed choices.
The practical value of these advanced models is confirmed through successful real-world implementations. For instance, ensemble ML methods and deep learning models are increasingly being deployed for operational forecasting at major dams, directly enhancing water management decisions. A case study from the Gezhouba Dam on the Yangtze River by Zhang et al. [
9] provides compelling evidence, where machine learning models delivered highly accurate short-term inflow forecasts. Lee et al. [
10] introduced a multi-inflow prediction ensemble (MPE) model for dam inflow forecasting, leveraging auto-sklearn to integrate ensemble models tailored for high- and low-inflow regimes. By assigning datasets based on flow conditions, the MPE model significantly improves prediction accuracy compared to conventional ensemble approaches. It achieves notable reductions in RMSE (22.1%) and MAE (24.9%) for low inflows, while boosting R
2 and NSE by 21.9% and 35.8%, respectively. Latif and Ahmed [
11] explored the generalization of support vector regression (SVR) models for reservoir inflow forecasting using daily, weekly, and monthly inflow and rainfall data. Four SVR kernels—RBF, linear, normalized polynomial, and sigmoid—were tested across two climate-diverse case studies: Dokan Dam (Iraq) and Warragamba Dam (Australia). Results showed that daily data and the RBF kernel yielded the best performance at Dokan Dam (RMSE = 145.7, R
2 = 0.85), but failed to generalize effectively to Warragamba Dam. Deb et al. [
12] evaluated the predictive capabilities of five machine learning models—Bidirectional Long Short-Term Memory (Bi-LSTM), Convolutional Neural Networks (CNNs), eXtreme Gradient Boosting (XGBoost), Light Gradient Boosting Machine (LGBM), and Random Forest (RF) —for daily reservoir inflow forecasting at the Sri Ram Sagar Project, Telangana, India. Using 15.5 years of hydrological and climate data, seven input combinations (S1–S7) were tested, with hyperparameter tuning via the Tree-Structured Parzen Estimator. Bi-LSTM with input set S7 achieved the highest performance (Kling–Gupta efficiency = 0.92 training, 0.87 testing).
Quantum Machine Learning (QML) holds significant promise for time series prediction by addressing fundamental computational limitations of classical methods. Time series data, especially in finance or hydrology fields, often involves modeling highly nonlinear patterns and interactions between a vast number of variables. Classical models, such as deep neural networks, struggle with the curse of dimensionality, where computational costs grow exponentially with data complexity [
13]. QML offers a pathway to overcome this by leveraging the inherent properties of quantum mechanics. The core importance lies in quantum computing’s ability to process information in a massively parallel way. Through quantum superposition, a system of qubits can represent a multitude of possible data states simultaneously. Furthermore, quantum feature maps can naturally encode classical data into an exponentially large feature space, allowing QML models to identify complex, hidden patterns in the data that are computationally prohibitive for classical computers to uncover. This intrinsic capability makes QML exceptionally suited for capturing the intricate dependencies and stochastic nature inherent in real-world time series. Niu et al. [
14] proposed a hybrid ELM–QPSO model for hydrologic time-series prediction, addressing limitations of traditional single-layer feedforward networks (SLFNs) and gradient-based learning. Extreme Learning Machine (ELM) offers fast training and strong nonlinear mapping, but suffers from random parameter initialization. To overcome this, the model integrates quantum-behaved particle swarm optimization (QPSO) to optimize ELM’s input-hidden weights and biases, while output weights are computed analytically via the Moore–Penrose inverse. Applied to daily runoff data from China’s Xinfengjiang Reservoir (2000–2014), the ELM–QPSO model demonstrated superior generalization performance, validating QPSO as an effective alternative for ELM parameter tuning. Grzesiak and Thakkar [
15] applied quantum machine learning (QML) for enhancing flood forecasting, focusing on daily flood events along Germany’s Wupper River in 2023. They integrated a hybrid framework of classical models (Support Vector Machines (SVM), K-Nearest Neighbors (KNN), regression, and Autoregressive (AR)) with QML techniques (SVM, KNN, Adaboost, Quantum Variational Circuits, QBoost, and QSVC_ML), leveraging quantum properties such as superposition and entanglement. Comparative analysis revealed that QML models deliver competitive training times and superior prediction accuracy. Vajpayee et al. [
16] proposed a quantum optimization framework integrated with Geographic Information Systems (GISs) to enhance flood risk management. By reviewing existing literature, analyzing case studies, and comparing classical and quantum optimization methods, the research demonstrated that quantum algorithms offer faster and more accurate solutions for complex flood scenarios. The approach improves resource allocation, prediction accuracy, and overall resilience to flooding events. The findings underscore the value of merging emerging quantum technologies with traditional disaster management strategies to address the growing challenges posed by climate change and urbanization.
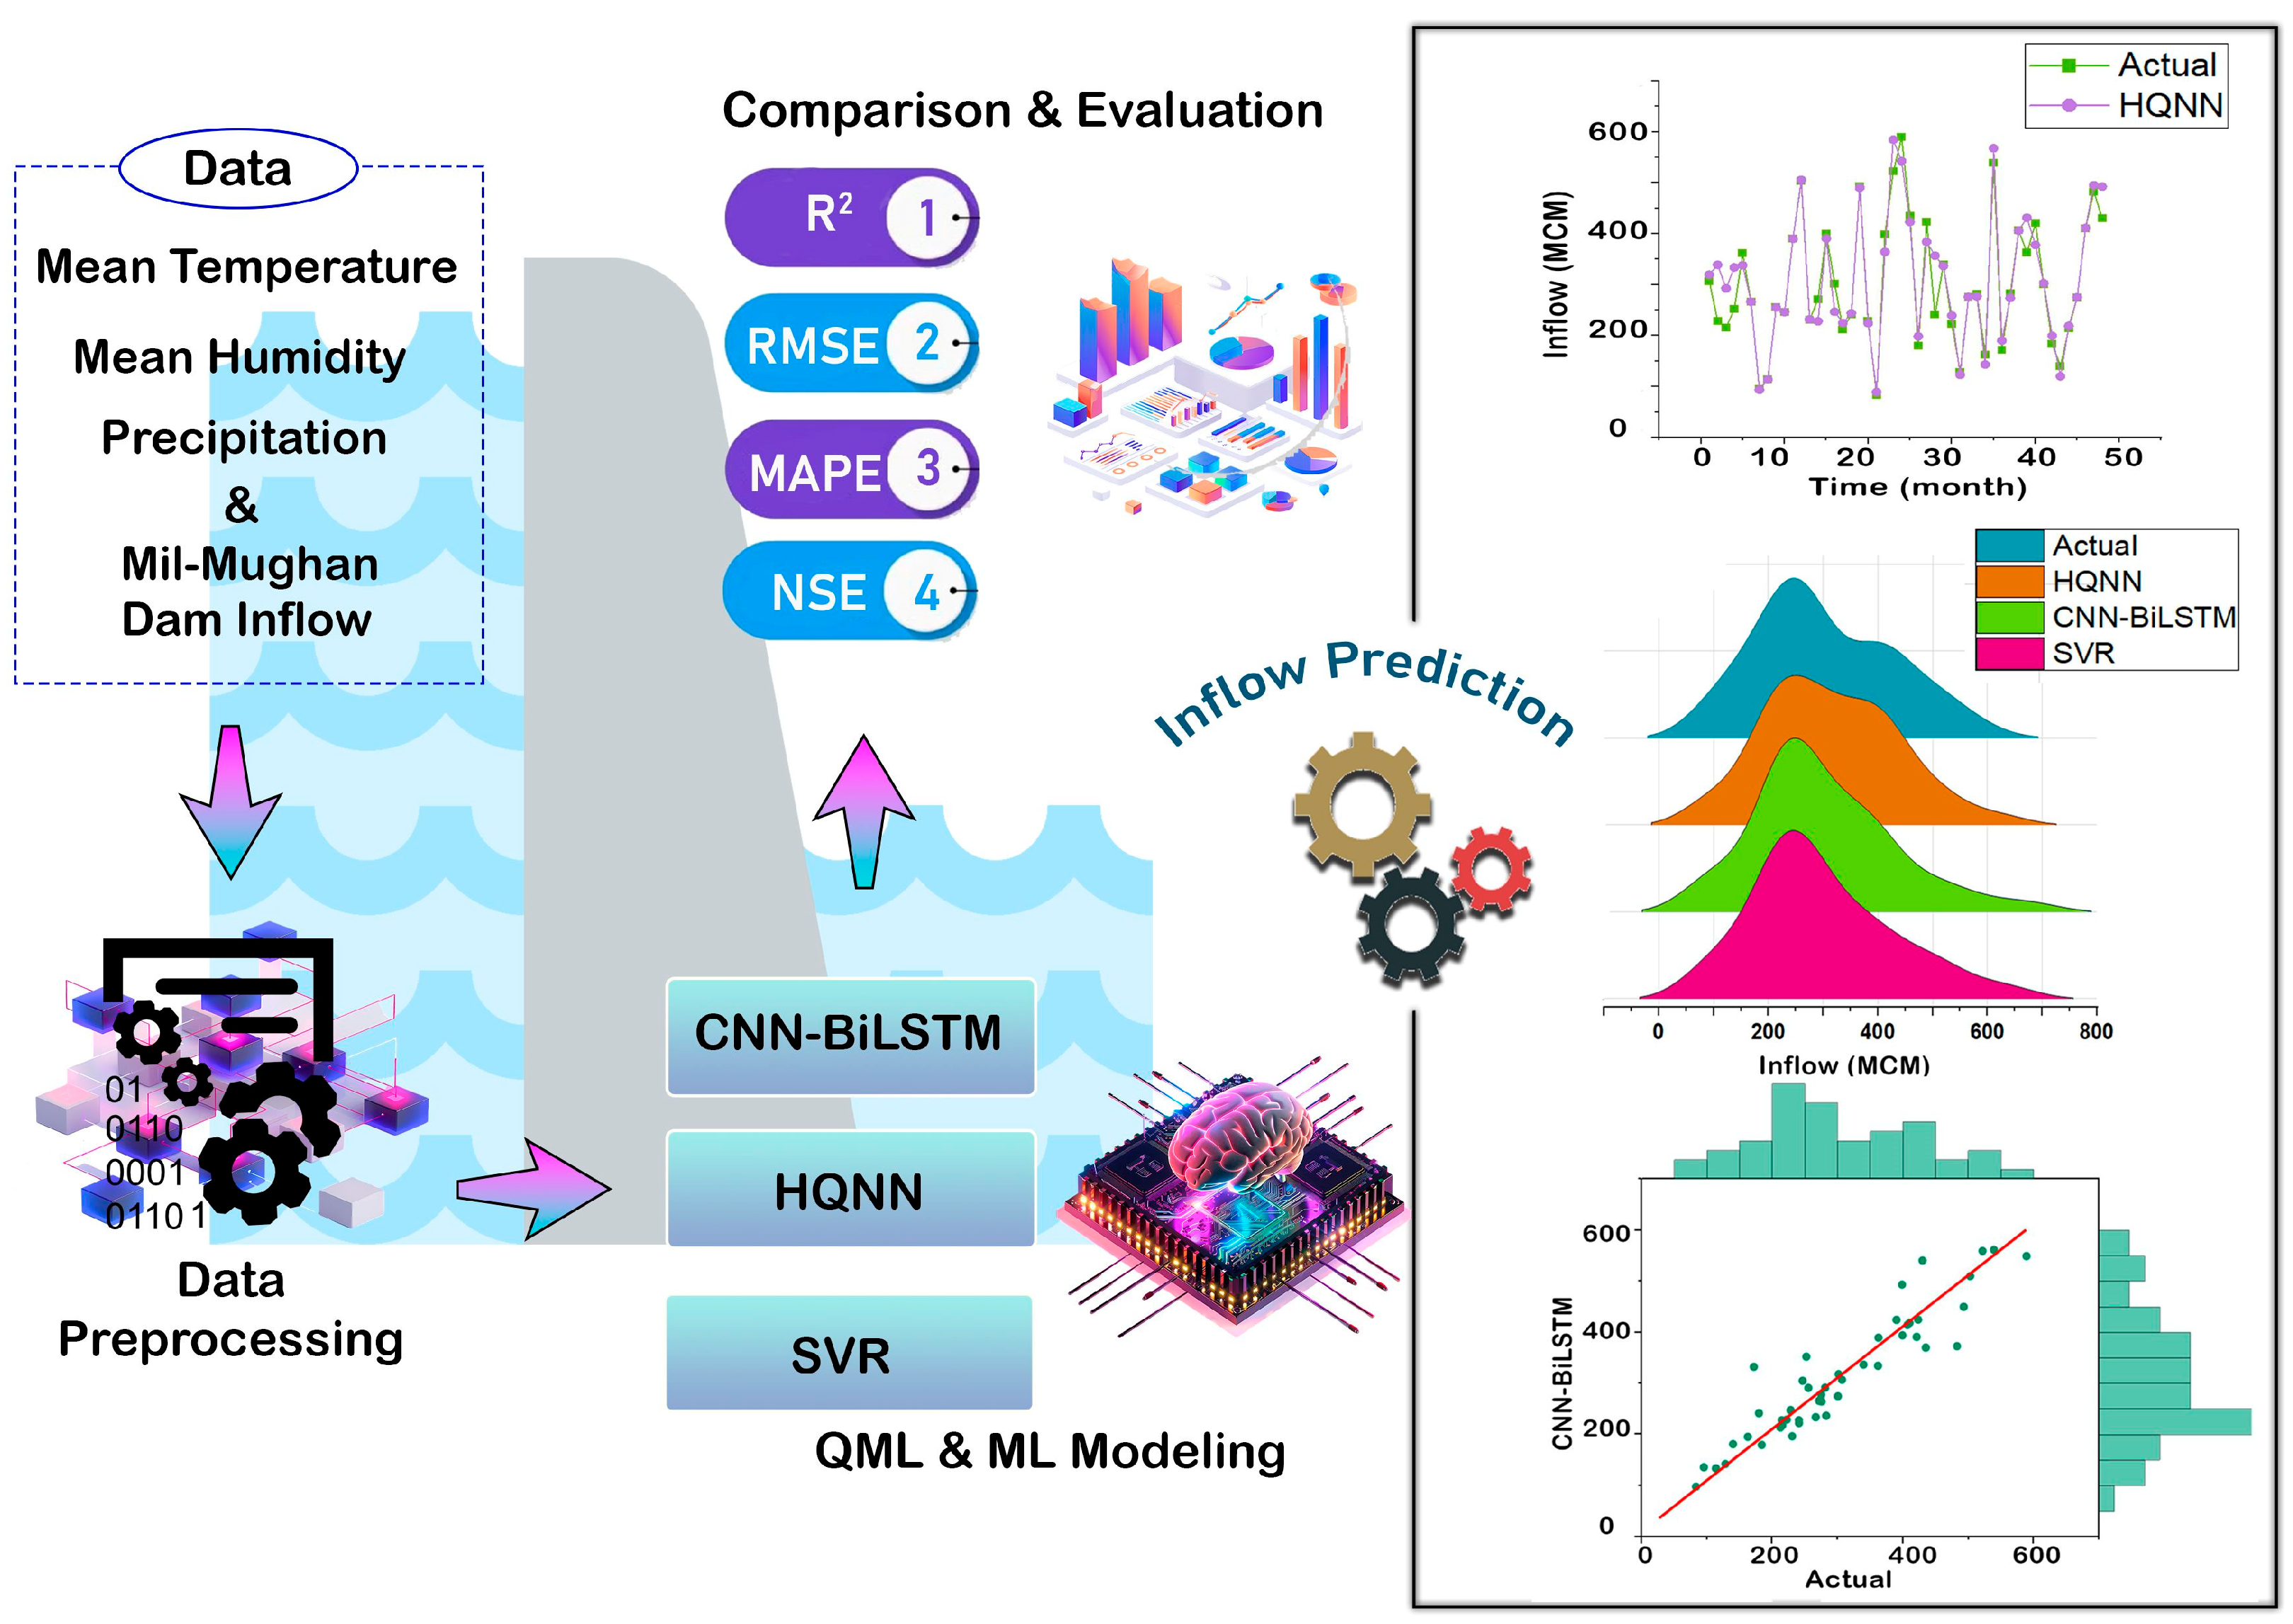
Although accurate inflow forecasting is vital for dam safety and water resource management, comparative analyses of quantum-inspired and advanced classical models for this purpose remain scarce. To address this gap, the primary aim of this study is to conduct a comprehensive comparative analysis of three distinct machine learning architectures—a Hybrid Quantum Neural Network (HQNN), a Convolutional Neural Network–Bidirectional Long Short-Term Memory (CNN-BiLSTM) model, and Support Vector Regression (SVR)—for predicting inflow into the Mile Mughan Dam. The investigation is designed to evaluate model performance under two key forecasting scenarios: a univariate framework that utilizes only historical inflow lags, and a multivariate framework that incorporates both inflow lags and meteorological parameters. By benchmarking the nascent HQNN model against established classical deep learning and statistical benchmarks, this research seeks to elucidate the potential advantages and limitations of quantum-inspired machine learning in capturing the complex, nonlinear temporal dynamics inherent in hydrological systems.
3. Results and Discussion
Mean temperature, mean humidity, and precipitation are three of the most influential climatic factors for predicting dam inflow because they collectively determine the processes of evapotranspiration, snowmelt, and runoff generation within a watershed. Each plays a distinct hydrological role that affects total water availability and inflow variability to reservoirs. Mean temperature affects dam inflow primarily through its influence on evaporation and snowmelt. Higher temperatures accelerate snow and glacier melt in mountainous basins, leading to short-term inflow increases, while simultaneously enhancing evapotranspiration, which reduces surface runoff and long-term inflow volumes. Studies, such as those by Han et al. [
33], have shown that rising temperatures lead to overall declines in inflow, even when precipitation increases, due to stronger evaporation losses. Temperature also plays a role in modifying soil moisture, infiltration capacity, and antecedent flow conditions—all key predictors in machine learning inflow models.
Mean or relative humidity is closely linked to both evapotranspiration control and precipitation formation. Higher humidity reduces potential evapotranspiration, sustaining more effective runoff generation and maintaining baseflow contributions to inflows. Conversely, lower humidity enhances water loss from soil and vegetation surfaces, decreasing available inflow. Therefore, humidity serves as a significant balancing factor modulating evaporation–precipitation interactions in inflow regimes [
34].
Precipitation is the dominant direct driver of dam inflow variability. It determines short-term runoff peaks and seasonal inflow rhythms, particularly during the wet season when catchment saturation is high. Machine learning and statistical studies consistently identify precipitation as the most sensitive and highly correlated variable with inflow magnitude across different temporal scales (daily to monthly). Inflow prediction models using only precipitation already capture significant inflow variability, but combining precipitation with temperature and humidity markedly improves accuracy for both dry and wet periods.
Also, three-month lags represent the time it typically takes for upstream precipitation in the Kura and Aras basins to translate into measurable discharge at Mughan and Mil collectors. Water that infiltrates or accumulates in irrigation zones and reservoirs (such as Takhtakorpu and Shamkirchay) traverses multiple conveyance systems—open canals, drainage channels, and groundwater channels—before reaching downstream storage, such as Mil Mughan. Thus, including a 3-month lag (1-, 2-, and 3-month lag) in models helps capture subsurface and delayed surface runoff patterns that significantly affect inflow predictability.
Table 2 presents the categorization of scenarios assessed for forecasting dam inflow using three distinct models: SVR, CNN-BiLSTM, and HQNN.
Inflow prediction for Mil Mughan Dam was carried out using two distinct input scenarios designed to assess the influence of meteorological variables and antecedent inflow data on forecasting accuracy. The first scenario integrated mean temperature, mean humidity, precipitation, and inflow values lagged by three months, representing a comprehensive dataset that reflects both climatic conditions and historical inflow trends. The second scenario, in contrast, utilized only three-month lagged inflow values, aiming to evaluate the models’ capacity to predict dam inflow based strictly on observed antecedent hydrological patterns, which is vital when meteorological data are unavailable or uncertain.
The comparative results in
Table 3 demonstrate that the HQNN model provided the highest predictive accuracy for the Mil Mughan Dam inflow across both input scenarios, notably with meteorological and lagged inflow variables included. In the testing step, it achieved an R
2 of 0.915, an RMSE of 37.318 MCM, an NSE of 0.908, and an MAPE of 8.343% when leveraging all input features, indicating superior goodness-of-fit, low prediction error, and strong efficiency compared to observed inflows. When restricted to lagged inflow values alone, HQNN remained robust, only slightly declining in performance, highlighting its advanced capability to model nonlinear and temporal relationships in hydrological forecasting. The CNN-BiLSTM model demonstrated good predictive capabilities, particularly when meteorological variables were included. This can be attributed to its proficiency in modeling both temporal dynamics and spatial correlations. Performance metrics R
2 = 0.867, RMSE = 46.506 MCM, NSE = 0.858, and MAPE = 10.795% positioned it between HQNN and SVR, outperforming the latter but falling short of the former. Notably, its accuracy showed greater sensitivity to the absence of meteorological inputs. When the model relied solely on lagged inflow data, its effectiveness diminished, underscoring the value of incorporating external predictors in deep learning architectures. The SVR model delivered reliable, albeit consistently lower, predictive outcomes in both scenarios, with a maximum R
2 of 0.846 and the largest RMSE and MAPE values. SVR’s kernel-based structure is competent for basic regression but less effective in modeling the highly nonlinear and complex dynamic patterns evident in dam inflow data. The comparison validates that hybrid and deep learning models—particularly those enhanced with quantum optimization—are favored for operational water inflow forecasting due to their capacity for processing multi-source data and capturing subtle relationships essential for effective reservoir management.
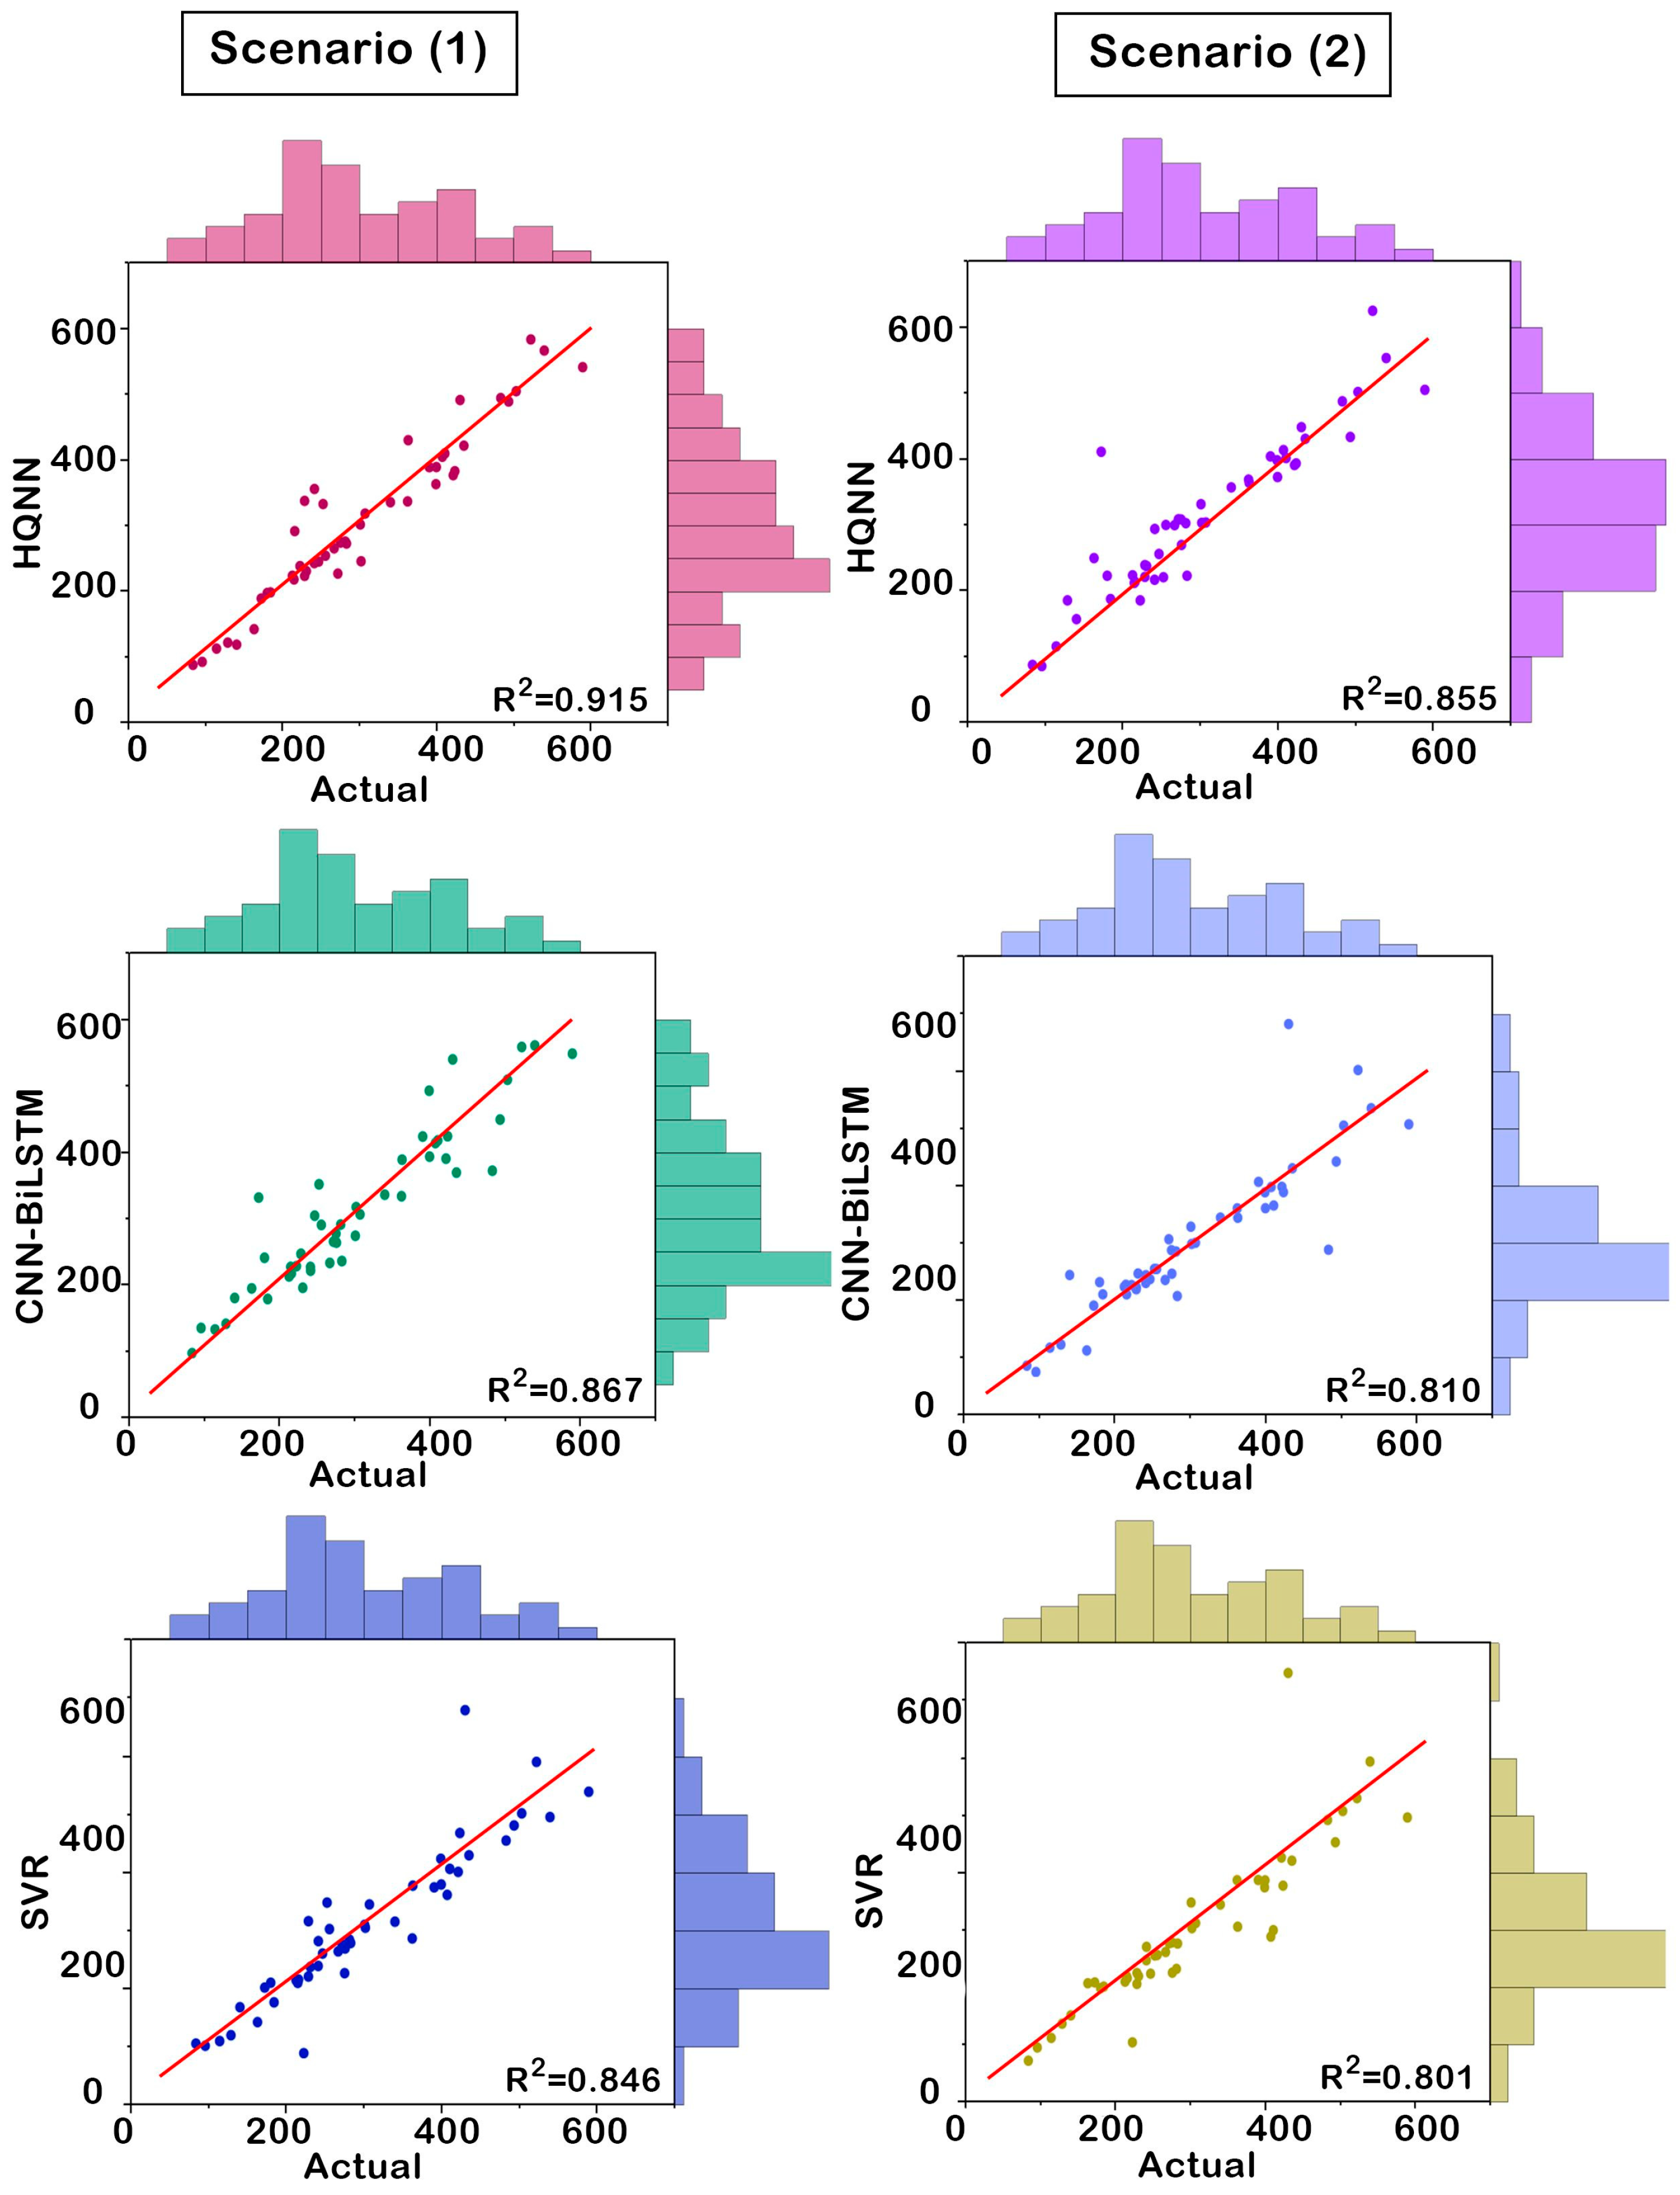
Figure 6 presents scatter plots with marginal histograms illustrating the correlation between actual and predicted dam inflow for the Mil Mughan Dam across two scenarios using three models: HQNN, CNN-BiLSTM, and SVR. Each scatter plot shows individual prediction points, with the red diagonal line representing perfect agreement (where predicted equals actual inflow). Points closer to this line indicate higher prediction accuracy. The distribution of points around the line reflects the model’s predictive performance, with tighter clustering signifying better agreement. Marginal histograms on the top and right of each scatter plot display the frequency distribution of actual and predicted inflows, respectively. A similar shape and spread in these histograms imply that the model successfully captures the overall inflow distribution pattern.
The marginal histogram profiles for HQNN are highly aligned between actual and predicted values, supporting this model’s ability to reproduce the observed inflow distribution, including peaks and variability. This visual evidence corroborates the model’s outstanding R2 of 0.915, outperforming the other methods. For CNN-BiLSTM, the scatter in Scenario 1 remains satisfactorily close to the diagonal, but there is a slightly broader dispersion, especially for higher inflow values. The corresponding marginal histograms are similar in shape, confirming that the model captures the general character of the inflow, but the increased spread and a few more outliers highlight that its predictions in some high- or low-inflow instances are less precise compared to HQNN. When the input is restricted to lagged values only in Scenario 2, the performance of CNN-BiLSTM declines, with points drifting further from the diagonal and increased vertical scatter, revealing a greater sensitivity to the exclusion of meteorological features. SVR, as shown in both scenarios, consistently exhibits the widest spread of points from the diagonal and less overlap between actual and predicted marginal histograms. This indicates systematic under- or over-estimation in various ranges and reflects insufficient modeling of nonlinear dependencies or temporal patterns. Its scatter plots often underestimate at higher inflow ranges and overestimate at the lower ranges, contributing to its lower R2 and higher error statistics. The contrast between models is especially pronounced in Scenario 2, where SVR’s predictive limitations are magnified, underscoring the superior generalizability and resilience of HQNN and, to a lesser degree, CNN-BiLSTM for operational dam inflow forecasting, particularly when limited data inputs are available.
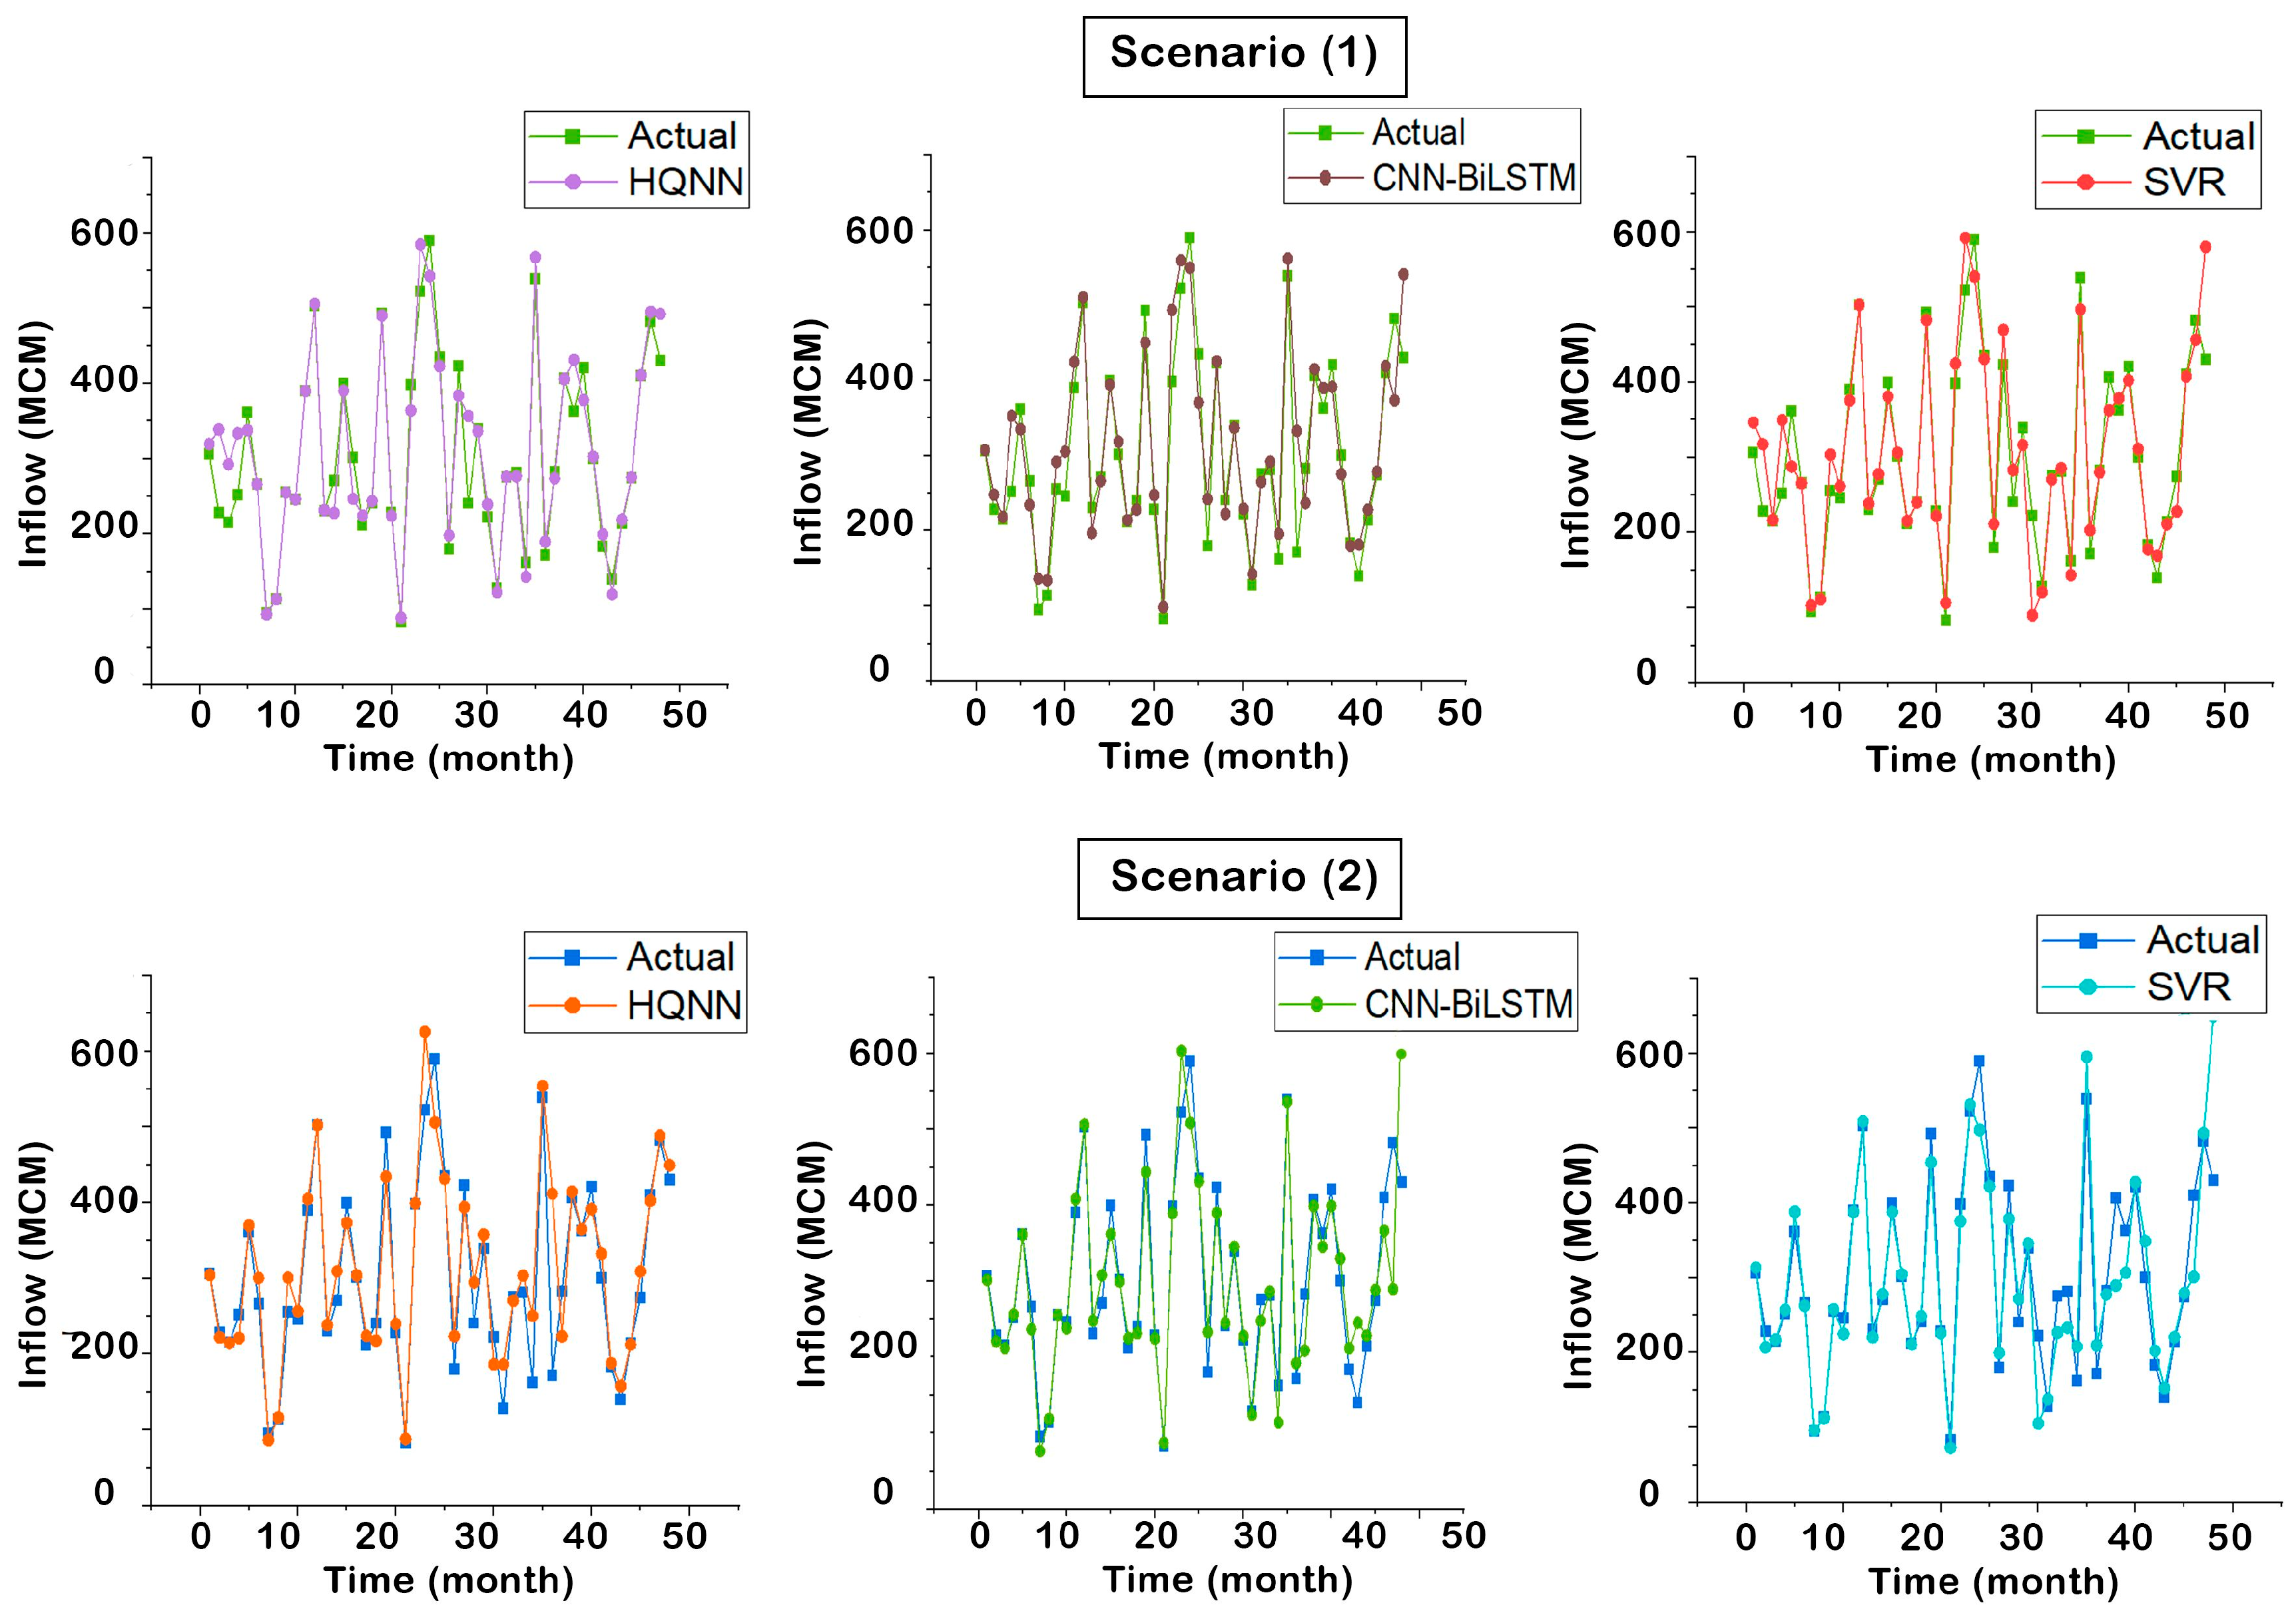
The time series plots in
Figure 7 compare the actual monthly inflow (in million cubic meters, MCM) with predicted inflow values from the HQNN, CNN-BiLSTM, and SVR models under two different scenarios for Mil Mughan Dam. In Scenario 1, which includes mean temperature, humidity, and precipitation along with three-month lagged inflow values, the HQNN prediction closely traces the actual inflow pattern with minimal deviation, preserving both the peaks and low-flow periods effectively. This tight alignment indicates the model’s excellent ability to capture complex nonlinear relationships and dynamic inflow fluctuations using rich meteorological and lagged data. CNN-BiLSTM’s predictions also reflect the general trends well but show slightly more divergence at some peaks or dips, which manifests as fluctuating overlaps and minor lags behind actual values. The SVR model generally captures the inflow dynamics but visibly underestimates peak inflows and exhibits more variability in deviation, highlighting less precision and sensitivity to hydrological extremes. Under Scenario 2, which only relies on lagged inflow values, the prediction accuracy for all models generally decreases. HQNN, while still producing close approximations of the actual inflow, shows more lag and variation around peak flows, indicating its reliance on meteorological data for optimal precision. CNN-BiLSTM follows a similar declining trend, with increasing mismatches during sudden inflow changes. SVR’s predictions become less aligned overall, with noticeable departures from actual values across several months, especially during high inflow events. This highlights its limitations when external climate features are unavailable.
Overall, these time series confirm that HQNN’s hybrid and quantum-enhanced architecture lends it superior predictive fidelity, particularly when utilizing comprehensive and multi-source inputs. CNN-BiLSTM is a competent alternative but is more dependent on richer input data to maintain accuracy, while SVR serves as a baseline with consistent but comparatively coarser approximations. These visualizations complement numerical evaluations and substantiate HQNN as the most reliable model for dam inflow prediction in both data-rich and data-limited contexts.
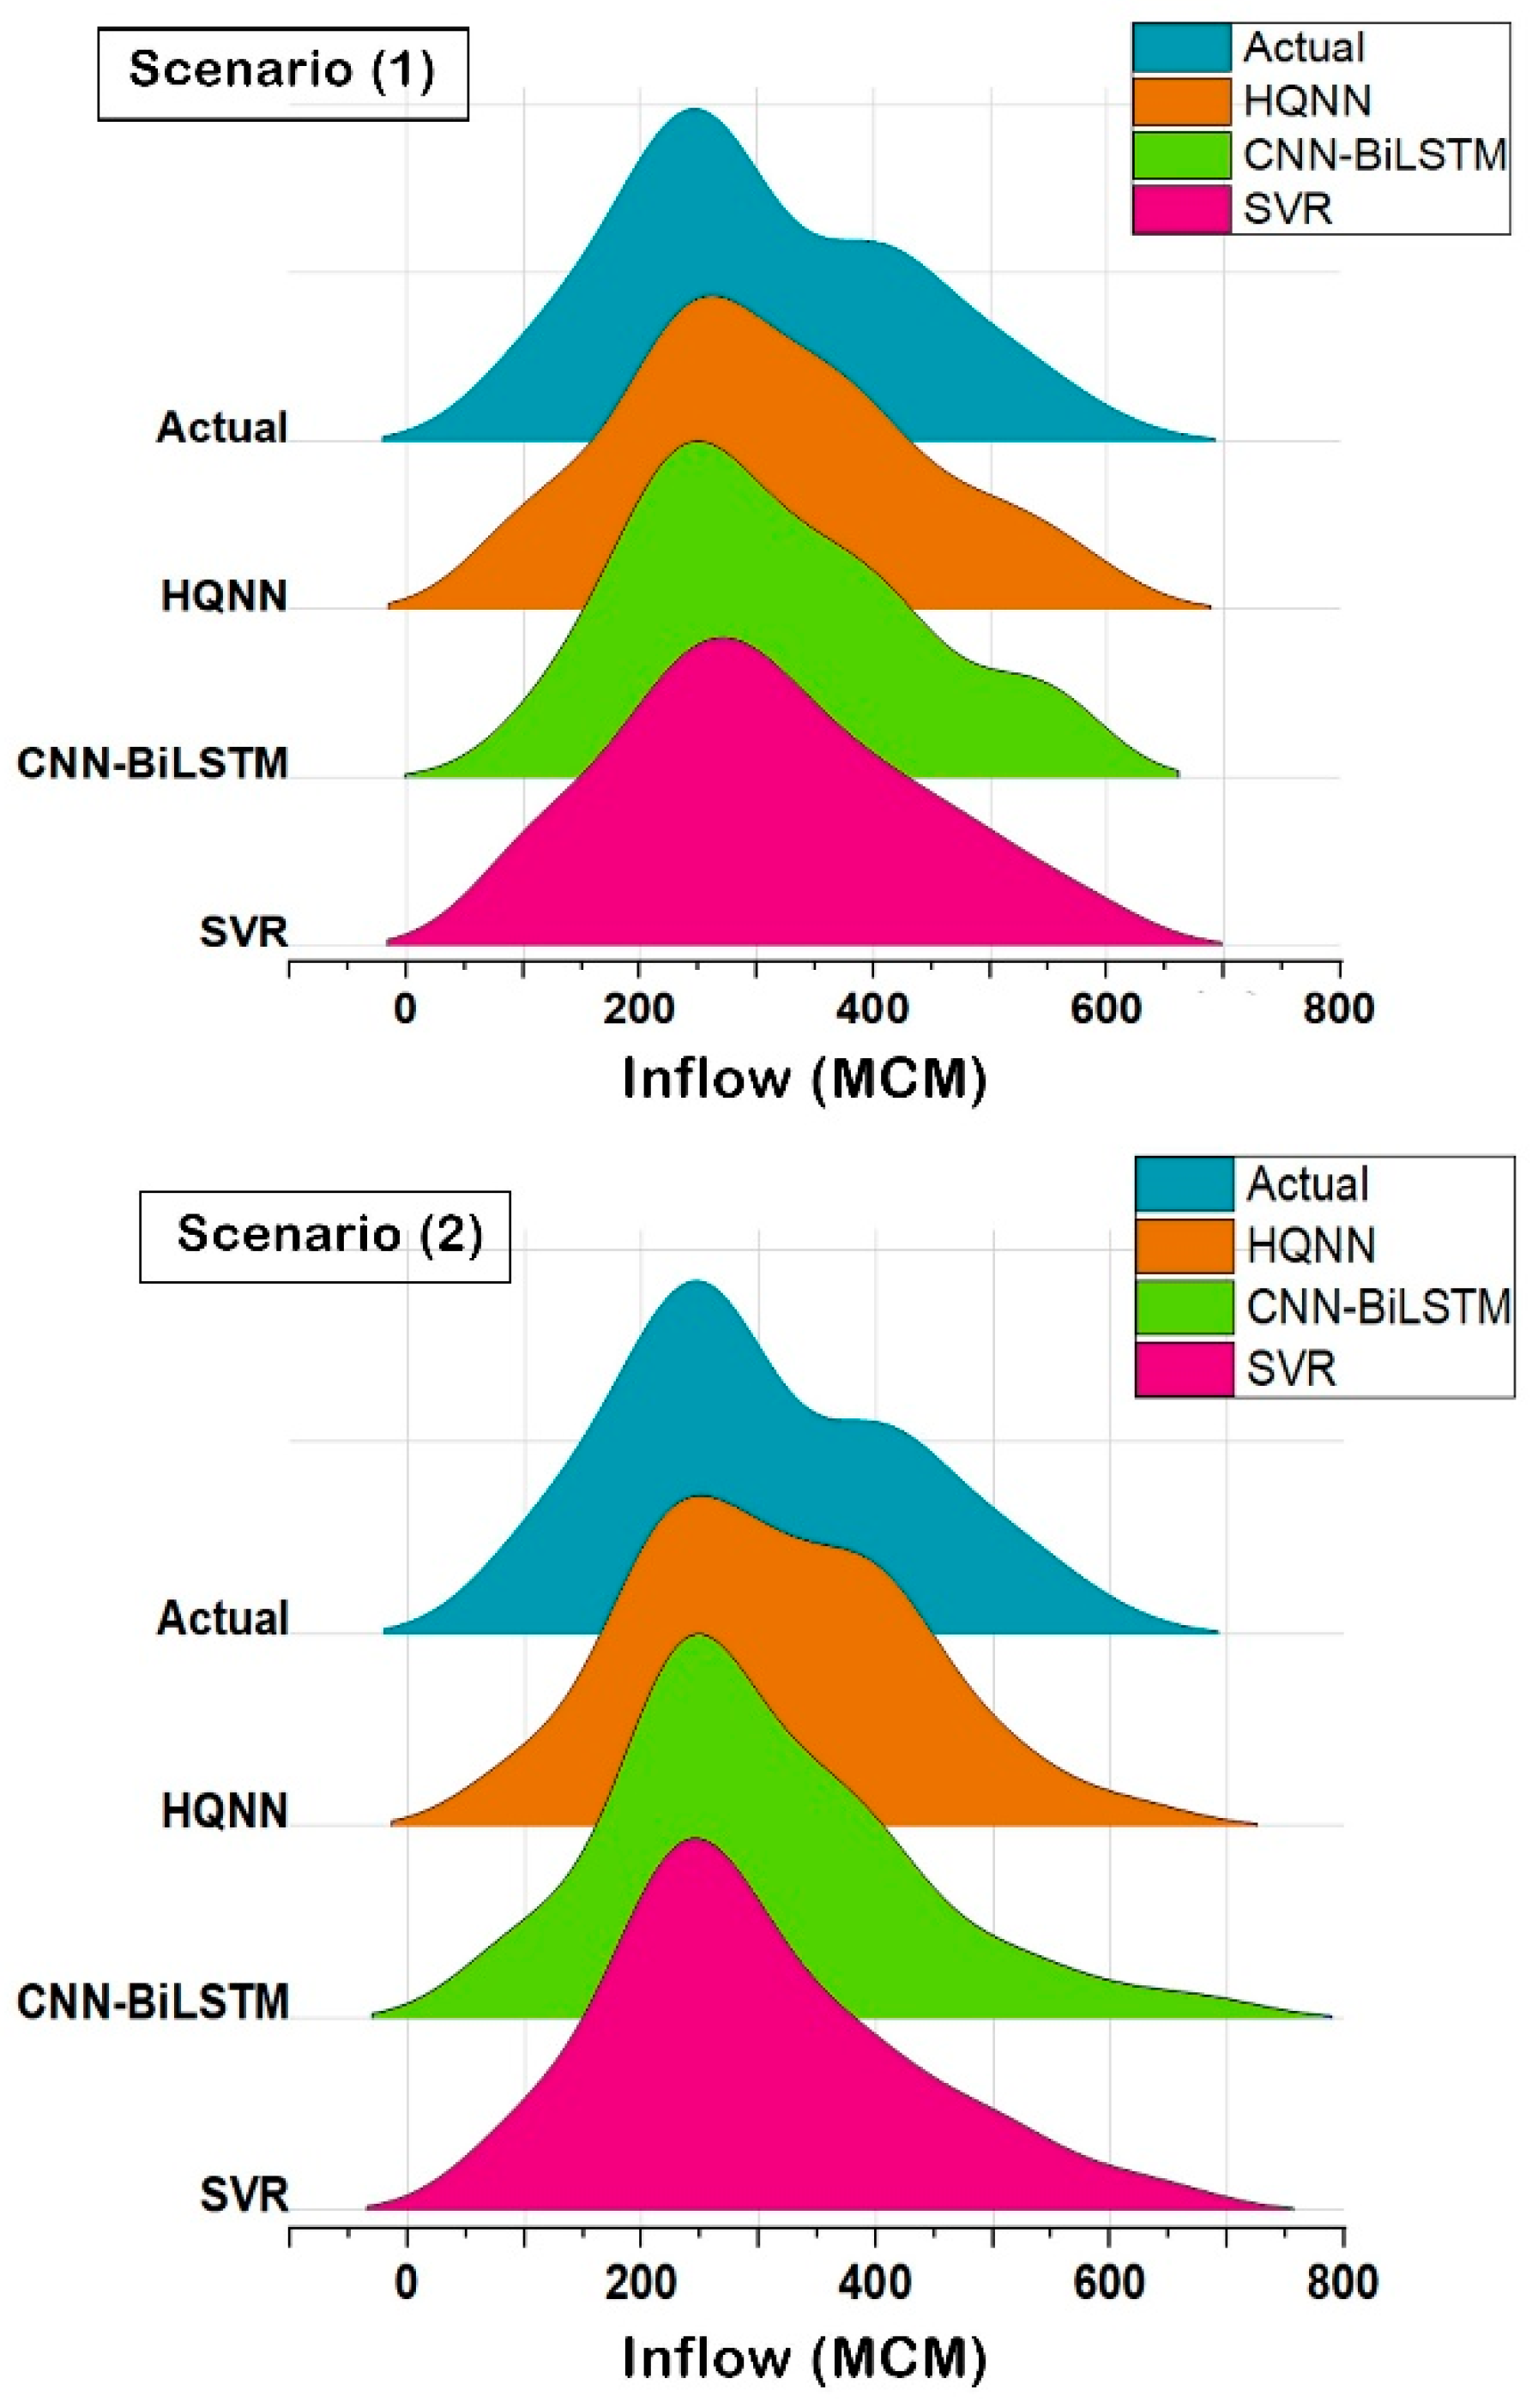
The performance of each model was visualized using overlapping ridgeline plots in
Figure 8, where the distribution of predicted inflow values was compared to the actual inflow distribution. In Scenario 1, where meteorological variables are included alongside lagged inflow data, the HQNN and CNN-BiLSTM models demonstrate good performance for the actual inflow distribution. The HQNN’s curve nearly mirrors the curve of actual inflow, indicating its superior ability to capture nonlinear relationships influenced by climate dynamics. CNN-BiLSTM, with its curve, also shows strong alignment, benefiting from its dual capacity to extract spatial and temporal features. In contrast, SVR under Scenario 1 exhibits a broader and less concentrated curve, deviating from the actual inflow distribution. This dispersion implies that SVR struggles to model the complex interactions between meteorological inputs and inflow behavior. While SVR is known for robustness in simpler regression tasks, its limitations become evident when tasked with high-dimensional, nonlinear hydrological forecasting.
Scenario 2, which relies solely on lagged inflow data, exposes the models to a more constrained learning environment. Here, HQNN maintains a relatively strong performance, indicating its resilience in capturing temporal dependencies even without external variables. However, CNN-BiLSTM shows a noticeable drop in precision, with its curve diverging from the actual inflow distribution. This suggests that HQNN’s strength lies in integrating heterogeneous data sources—without them, its predictive edge diminishes. SVR, again, underperforms, with its distribution remaining diffuse and misaligned, reinforcing its limited adaptability to autoregressive-only inputs.
In addition to the visual comparison in the ridgeline plots (
Figure 8), distribution similarity was evaluated using Jensen–Shannon distance (JS), and Wasserstein (Earth Mover’s) distance between the predicted and observed inflow distributions for each model and scenario. Lower values of these metrics indicate closer agreement between the model’s distribution and the actual inflow, complementing the qualitative assessment from the ridgeline plots. Across both scenarios, the HQNN consistently yielded the smallest JS and Wasserstein distances to the actual inflow distribution, followed by CNN-BiLSTM, while SVR exhibited substantially larger distances, confirming the superior distributional fidelity of the HQNN observed visually in
Figure 8.
Inclusion of climate and humidity predictors provides demonstrable improvements in model performance, especially in reservoirs subject to high seasonal variability or complex climate interactions. The clear separation in error metrics between HQNN and SVR further underscores the importance of advanced, data-driven approaches for accurate hydrological forecasting and sustainable dam operation. The adoption of deep learning and hybrid models has been widely recommended in the recent literature for their ability to handle nonlinearities and multivariable dependencies in reservoir inflow series. Thus, the presented approach and findings not only support operational decision-making for the Mil Mughan Dam but also offer a transferable framework relevant to other dam-regulated systems globally.
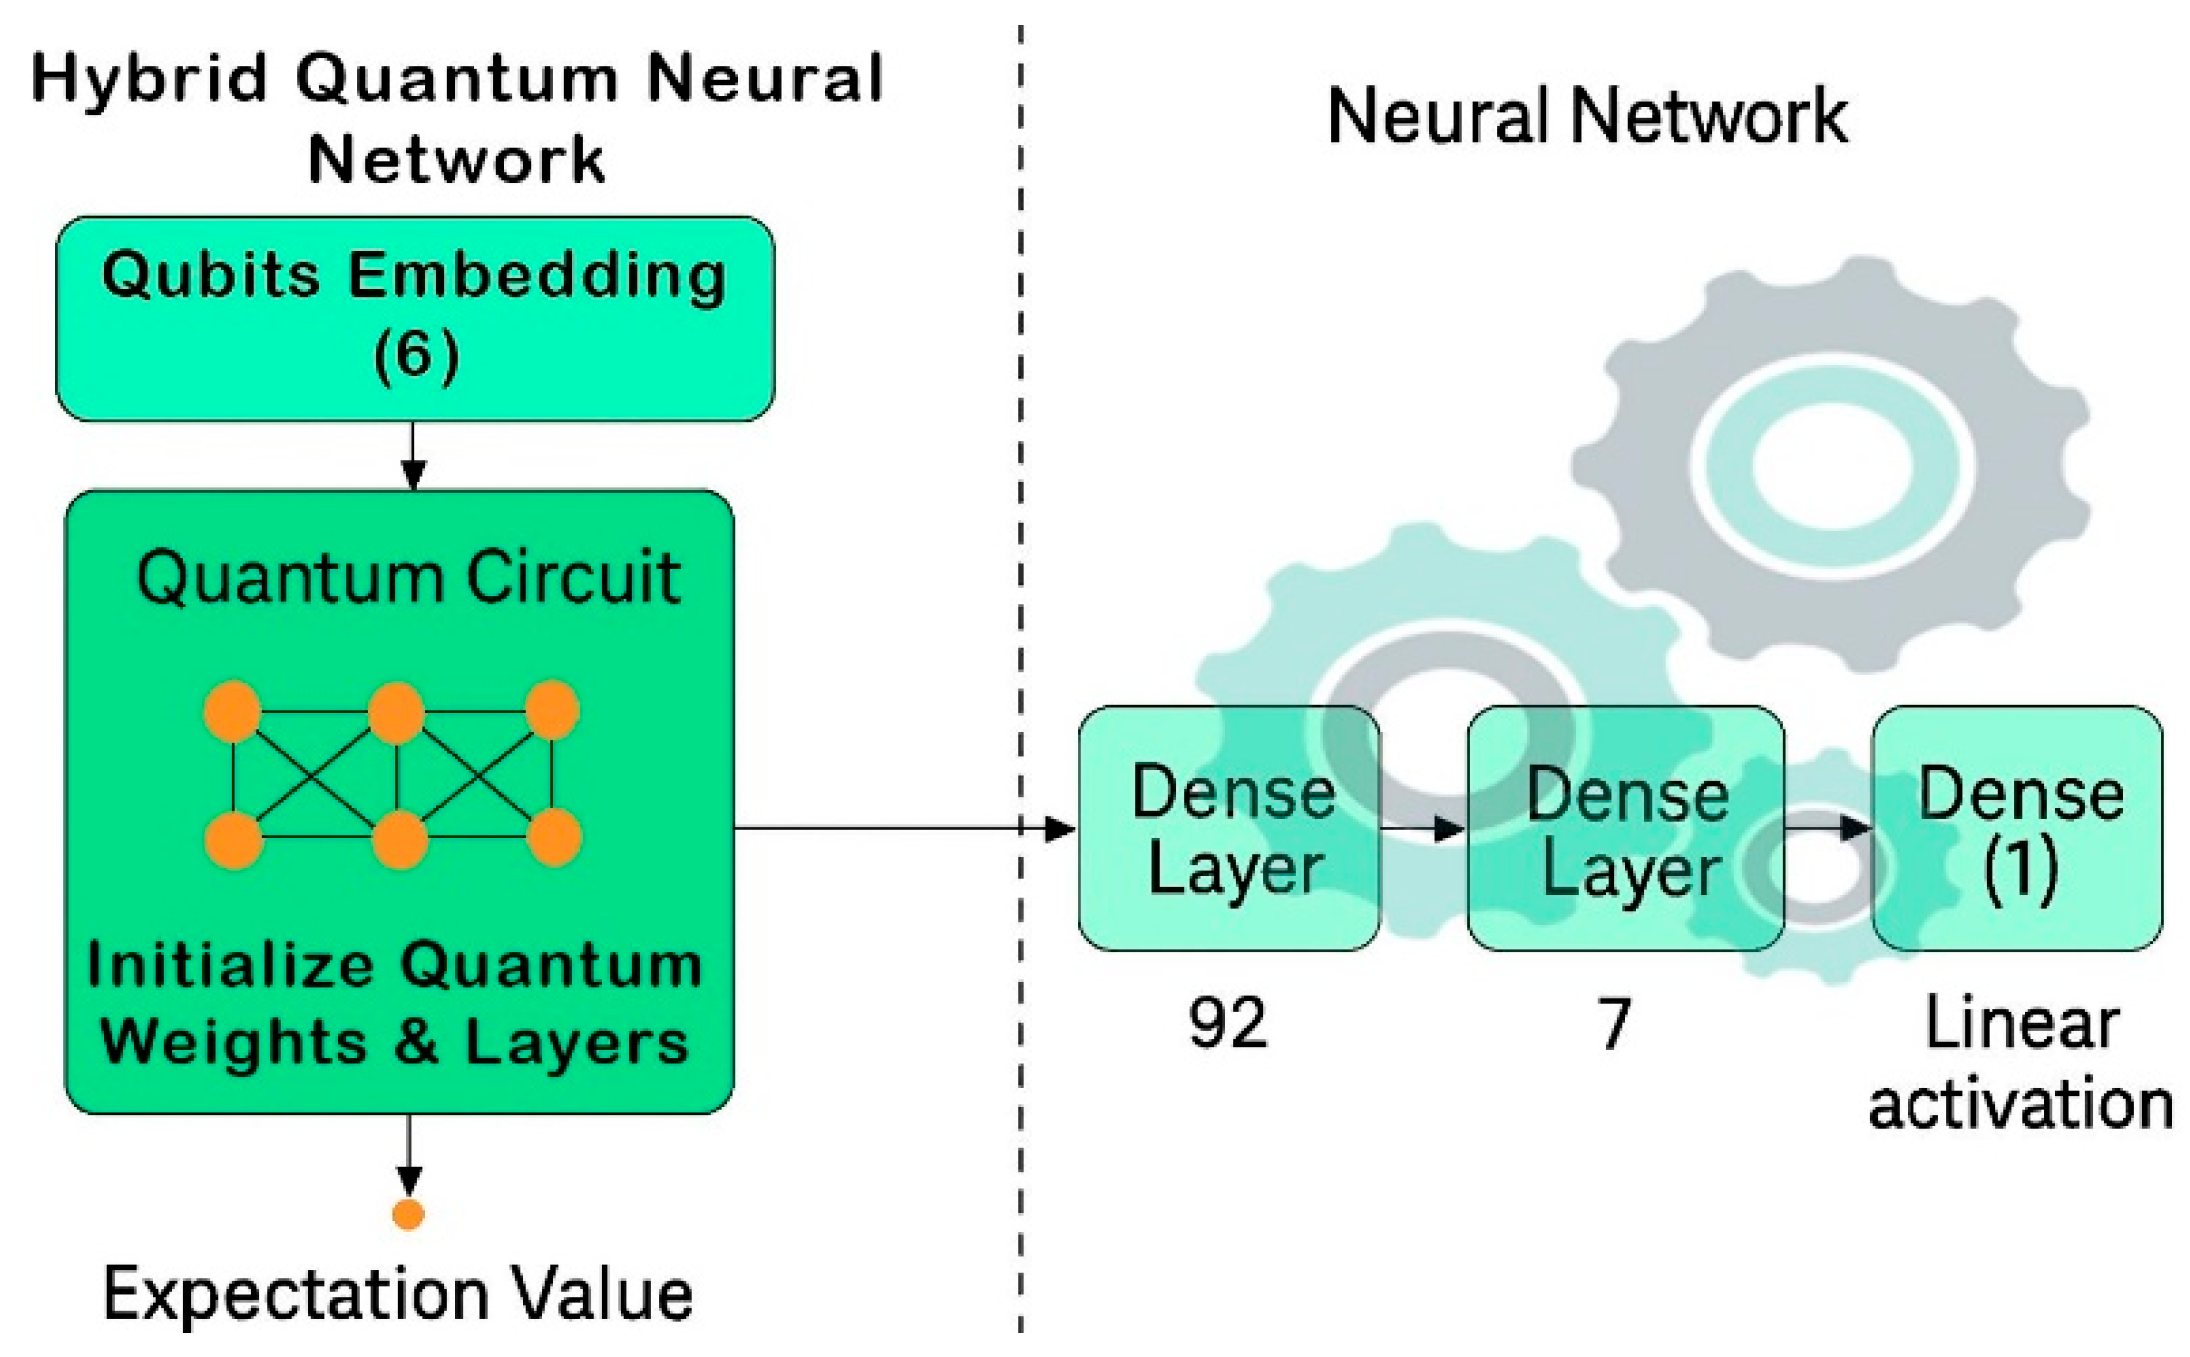
The quantum hybrid neural network (HQNN) outperformed classical machine learning counterparts largely due to its enhanced optimization capabilities and complex feature representation. Quantum-inspired algorithms used in HQNN improve the model’s ability to find global optima during training, effectively navigating intricate, high-dimensional data landscapes such as those arising from meteorological and hydrological time series. This enables HQNN to avoid common pitfalls like parameter trapping and local minima, leading to more stable and generalizable predictions. Furthermore, the hybrid structure of HQNN integrates both quantum state encoding and deep learning, allowing for improved modeling of long-term dependencies and interactions among lag and climate variables, which are crucial for accurate dam inflow forecasting under varied environmental conditions.
The importance of QML in hydrology lies in its ability to handle nonlinear, high-dimensional problems and uncertain data—limitations that conventional models often face. Results confirm the high performance of Quantum Machine Learning (QML) models in hydrological prediction, consistent with recent advancements in the field. For instance, Khemapatapan and Thepsena [
35] demonstrated the effectiveness of quantum classifiers on real weather data from the Pa Sak Jolasid Dam, where the Quantum Support Vector Machine (QSVM) achieved an accuracy of 85.3%, outperforming both the Variational Quantum Classifier (VQC) and Quantum Neural Network (QNN). Similarly, Fellner [
36] highlighted the advantages of quantum reservoir computing and QNNs in time series prediction, noting their ability to accelerate training and reduce generalization errors compared to classical deep learning models. Also, findings resonate with those of Zhen and Bărbulescu [
37], who reported that QNNs surpassed classical models such as LSTM, Backpropagation Neural Network (BPNN), and CNN-LSTM in predicting river discharge, particularly under extreme conditions. Their QNN model achieved an R
2 of 84.36%, with notably low MSE and MAE values. Furthermore, the application of Variational Quantum Regression (VQR) by Zhen and Bărbulescu [
38] demonstrated enhanced predictive accuracy over both classical and hybrid AI models, reinforcing the practical viability of quantum approaches in hydrological modeling. Moreover, it demonstrated remarkable capability in predicting monthly discharge maxima, highlighting its potential as a robust and reliable approach for hydrological forecasting in complex, nonlinear, and highly variable data environments. Findings from these studies indicate that the quantum algorithm enhances the performance of classical machine learning models and boosts their reliability—aligning well with the outcomes observed in this investigation.
4. Conclusions
Accurate dam inflow prediction is a critical component of modern water resource management, essential for flood mitigation, hydropower optimization, and ensuring water security. This study underscores the significant potential of QML, particularly through its enhanced optimization capabilities and superior feature representation in high-dimensional spaces, to advance the state-of-the-art in hydrological forecasting. Quantum-inspired algorithms excel at navigating complex, nonlinear data landscapes, effectively avoiding local minima and capturing intricate temporal dependencies that often challenge classical models.
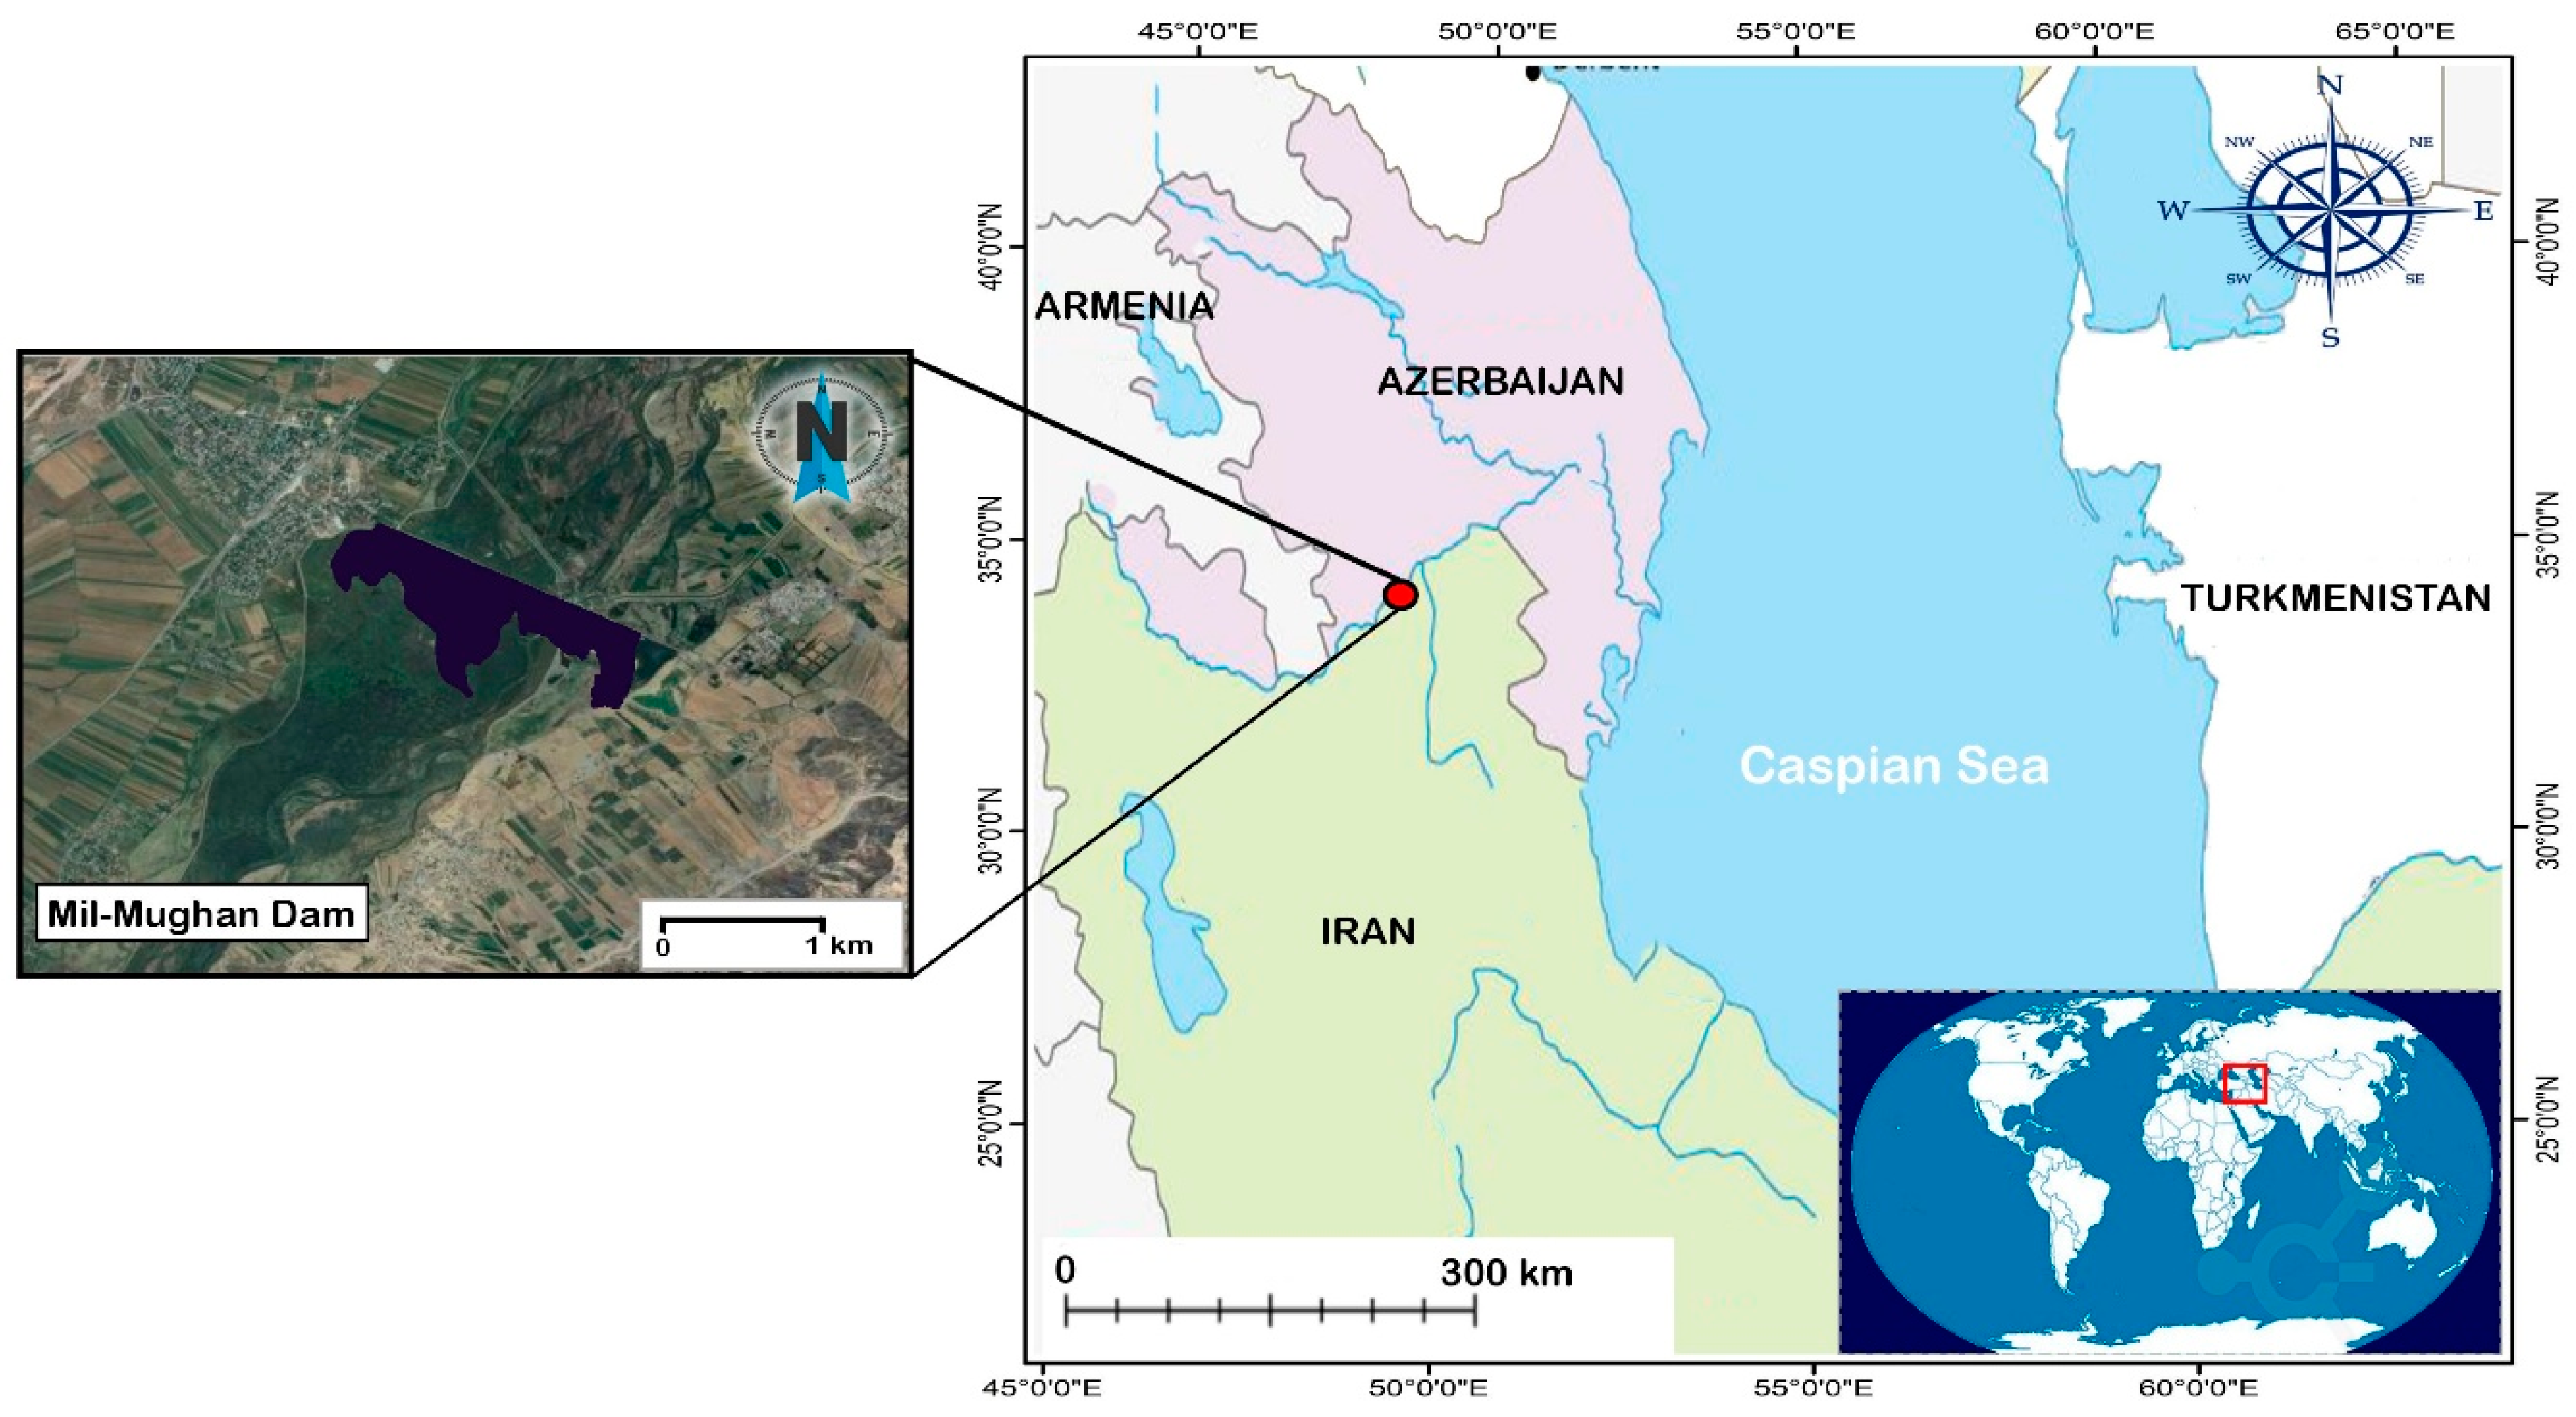
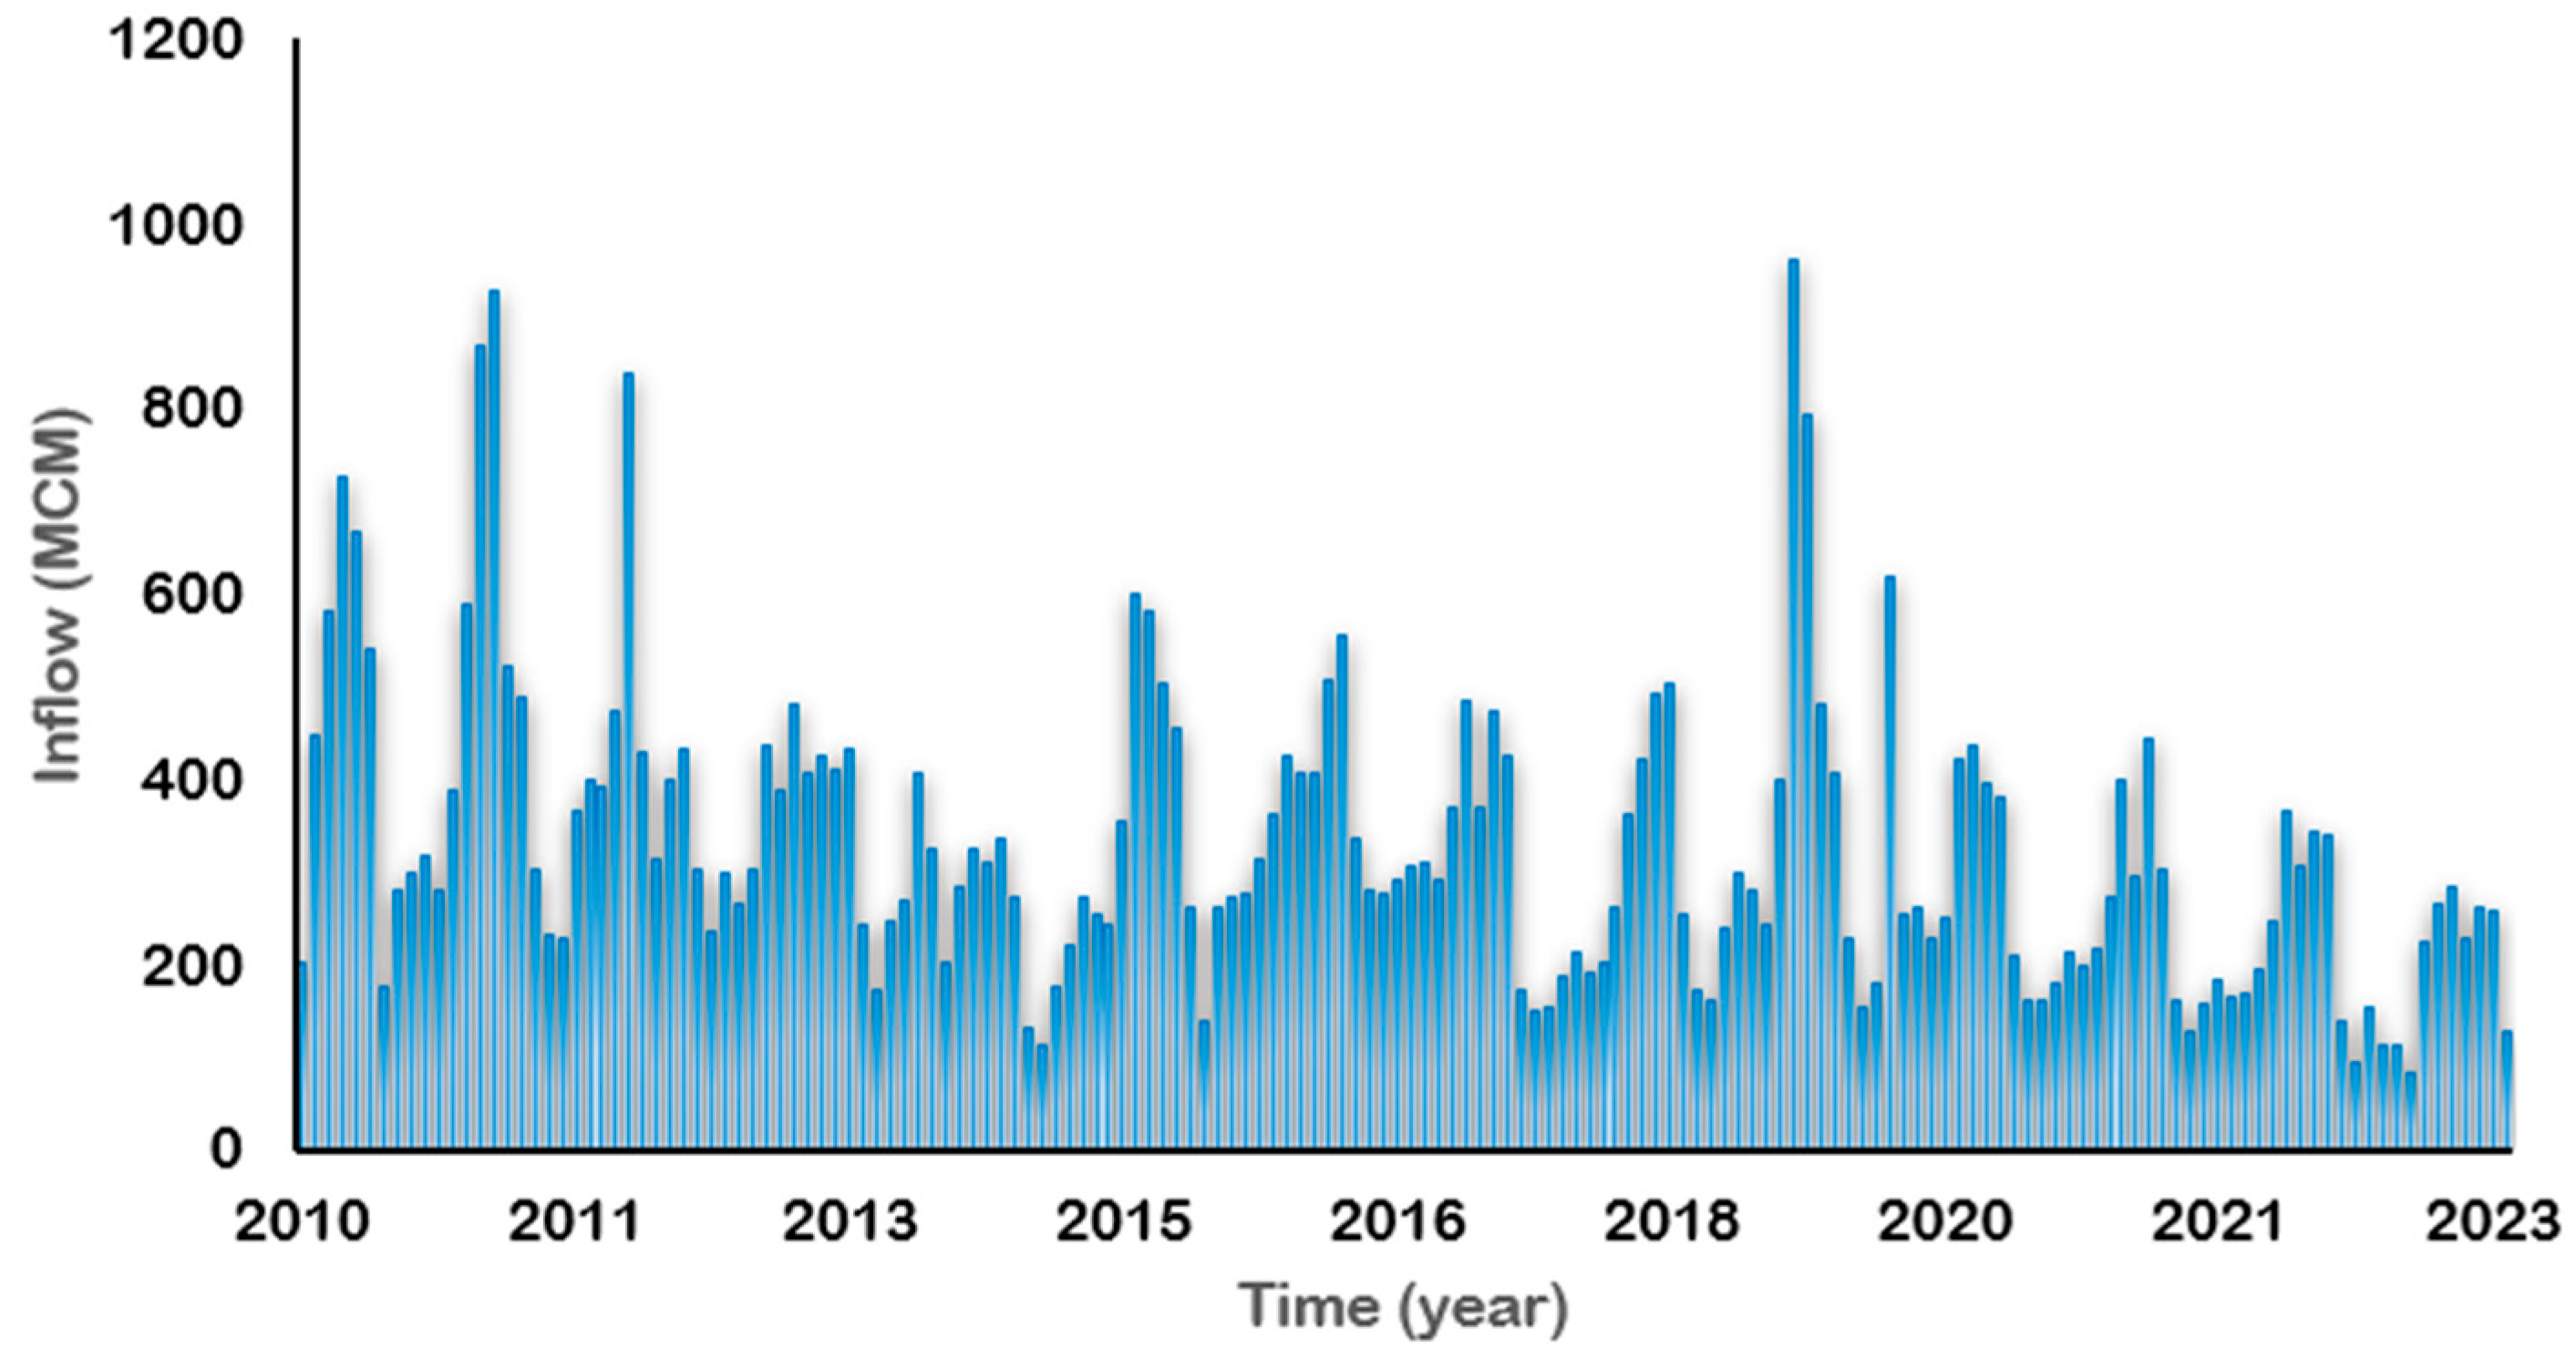
The research was conducted using a 14-year dataset from the transboundary Mil Mughan Dam on the Aras River, a vital hydroelectric and irrigation resource for Azerbaijan and Iran. To perform a comprehensive comparative analysis, three distinct machine learning architectures were implemented and evaluated under two forecasting scenarios: a multivariate framework incorporating meteorological variables (mean temperature, mean humidity, precipitation) alongside three-month lagged inflow data, and a univariate framework relying solely on the historical inflow lags. The models considered were SVR, a hybrid CNN-BiLSTM model, and a HQNN. The HQNN demonstrated superior performance, achieving a prediction accuracy of approximately 92%. It successfully explained over 91% of the variance in the dam’s inflow data. The classical deep learning model (CNN-BiLSTM) also performed strongly with an accuracy of around 89–90%, while the Support Vector Regression (SVR) model served as a solid baseline with approximately 87% accuracy.
Despite the results, this study has certain limitations that improved upon for future research. A primary constraint is its focus on a single case study. The model was developed and validated specifically for the Mil Mughan Dam, which features a semi-arid climate. Consequently, the generalizability of the HQNN to dams in significantly different hydrological regimes—such as snowmelt-dominated alpine reservoirs or tropical watersheds with monsoon climates—remains unverified and requires further investigation. Furthermore, the current implementation operates within a simulated quantum environment. While this demonstrates the conceptual value of quantum-inspired algorithms, it does not leverage the computational advantages of actual quantum hardware, nor does it account for real-world quantum challenges like noise and decoherence. Finally, the model’s input scope is limited to monthly data and a core set of meteorological variables, potentially overlooking the finer temporal dynamics of inflow events and the influence of other factors like snowpack or large-scale climate indices.
To address these limitations and advance the field, several key directions for future work are proposed. First, it is essential to validate and benchmark the HQNN framework across multiple dams in diverse geographical and climatic settings. This would rigorously test its transferability and robustness. Concurrently, as quantum hardware matures, a critical goal will be to transition the HQNN model from classical simulation to execution on real Noisy Intermediate-Scale Quantum (NISQ) processors, exploring tangible quantum advantage in hydrological forecasting. To enhance predictive power, future research should also focus on integrating multi-scale and novel data sources, such as high-resolution remote sensing data for soil moisture and snow cover, as well as climate teleconnection indices like ENSO. Also, time series cross-validation techniques, such as TimeSeriesSplit or blocked cross-validation, tailored to hydrological data can be explored to verify model robustness on limited samples and reduce the risks of overfitting.
Beyond model performance, future efforts will aim to improve the operational utility and transparency of the HQNN. Developing Explainable AI (XAI) techniques tailored for quantum-classical hybrids is crucial for building trust with water managers by clarifying the model’s decision-making process. The ultimate objective is to evolve this research into a robust operational forecasting system. This involves creating automated pipelines for real-time data ingestion and, importantly, enhancing the model to provide probabilistic forecasts with uncertainty quantification. Such advancements will empower dam operators with reliable, risk-informed insights, solidifying the role of quantum machine learning in building resilient water management systems for the future.
The computational complexity of the proposed models, particularly the HQNN, poses substantial challenges for practical implementation. The sophisticated nature of HQNN, alongside CNN-BiLSTM and SVR, requires a high level of expertise in advanced artificial intelligence (AI) techniques, including quantum machine learning and deep learning architectures. However, personnel at dam facilities, such as those operating the Mil Mughan Dam, may lack familiarity with these cutting-edge methodologies, limiting their ability to effectively deploy and maintain such models in operational settings. This complexity could hinder real-time applications, where rapid and reliable inflow predictions are critical for public safety, water resource management, and hydropower generation. Furthermore, the computational demands of these models may necessitate advanced infrastructure, which may not be readily available in resource-constrained environments, further exacerbating implementation challenges.
Conversely, a significant advantage of this study lies in its regional and international relevance, stemming from the location of the Mil Mughan Dam on the Aras River, a transboundary watercourse forming part of the border between Azerbaijan and Iran in the South Caucasus. This geopolitical context underscores the potential for this work to foster cross-border scientific collaboration and support joint management of shared water resources. The robust performance of the HQNN model in both data-rich and data-limited scenarios (R2 = 0.855, RMSE = 48.56 MCM in Scenario 2) provides a reliable framework for inflow forecasting that can enhance cooperative decision-making, ensuring sustainable water allocation and hydropower operations across national boundaries. This dual advantage—high predictive accuracy and the facilitation of international collaboration—positions the study as a valuable contribution to both hydrological modeling and transboundary water resource management.