


Abstract
Technical documents differ from general text corpora in ways that complicate retrieval-augmented generation (RAG). Evidence for a single answer is often distributed across numbered clauses, tables, figures, captions, and ordered procedures rather than expressed in one passage. Standard RAG pipelines typically flatten these elements into independent chunks. This can break the document relations needed for exact evidence tracing. We introduce TechDocRAG, a relation-preserving framework for technical document question answering. The framework represents each document as a heterogeneous element graph and aligns three retrieval views for each element: technical identifiers, semantic summaries, and raw evidence. At query time, retrieval proceeds from identifier-aware recall to summary-level reranking and raw evidence bundling. We evaluate TechDocRAG on four benchmarks with more than 7500 evaluated question–answer pairs covering product manuals, engineering documents, and long multimodal PDFs. Across the suite, TechDocRAG improves the mean end-to-end score by 20.3 points over the strongest flat baseline and by 9.3 points over the strongest non-flat baseline. On the evidence-annotated subset, the strict raw evidence hit rate increases from 0.510 to 0.942. Resource profiling shows query time latency comparable to standard hybrid retrieval. Robustness tests show gradual degradation under relation loss, but clear sensitivity to severe identifier corruption. Overall, the results indicate that reliable RAG for technical documents depends less on retrieving more passages than on preserving the relations that make evidence interpretable.
1. Introduction
Technical documents are core references in engineering practice. Specifications, user guides, product manuals, and standards describe how systems are designed, configured, and operated. They differ from open-domain prose in both structure and evidentiary form. Evidence is often distributed across clauses, tables, figures, captions, and procedures. A definition may appear in one clause, while the valid range appears in a table and the operating condition is clarified in a later step. Benchmarks on manuals, engineering documents, and long multimodal PDFs show that this pattern is common and that text-only passage retrieval is often insufficient [1,2,3,4].
RAG provides a useful basis for this problem because it grounds generation in external evidence rather than relying only on model memory [5]. Recent general-purpose RAG methods improve the retrieval pipeline in several ways. Self-RAG adds adaptive retrieval and self-reflection [6]. CRAG repairs weak retrieval results [7]. RAPTOR searches over recursive summary trees [8]. GraphRAG, LightRAG, and HippoRAG 2 use graph structure or memory-like propagation [9,10,11]. VisRAG extends retrieval to visual document representations [12]. These methods provide strong comparison points, but their retrieval units are usually passages, summaries, entities, graph communities, or pages.
Technical document QA often requires a smaller and more precise evidence unit. Many queries are anchored by exact identifiers, such as clause numbers, parameter names, figure labels, or revision tags. The answer also depends on a linked set of elements. Examples include a clause and its cited table, a figure and its caption, or a troubleshooting step and its neighboring steps. A generic retriever may find related text without returning the complete evidence chain.
Failures may also arise before retrieval. OCR and PDF parsing can distort identifiers, units, layout, or figure–caption alignment. Retrieval then starts from a damaged representation. OCR Hinders RAG shows that such errors propagate into both retrieval and generation [13]. For technical documents, high recall alone is therefore not enough. The system must also preserve the relations that make the evidence interpretable.
TechDocRAG addresses this problem by keeping document elements and their links explicit. It parses each document into typed elements, including clauses, paragraphs, tables, figures, captions, sections, and procedure steps. It then performs retrieval in three stages: identifier-aware recall, summary-level reranking, and raw evidence bundling. The parsed elements remain retrieval units throughout the pipeline instead of being reduced to anonymous text chunks.
2. Related Work
2.1. Hybrid and Lexical–Semantic Retrieval
Hybrid retrieval combines exact lexical matching with dense semantic retrieval. It is a common baseline for document QA, especially when queries mix domain terms with natural-language paraphrases. In technical documents, two limitations are recurrent. First, OCR errors, formatting changes, or token fragmentation can damage exact identifiers. Second, linked evidence is easily separated. A system may retrieve the relevant clause but miss the table or figure cited by that clause. Hybrid retrieval is therefore competitive, but it does not fully address technical document QA.
2.2. Adaptive and Corrective RAG
Self-RAG and CRAG make retrieval more selective. Self-RAG learns when to retrieve and how to critique a draft answer [6]. CRAG estimates retrieval quality and repairs weak results [7]. These mechanisms are useful in noisy corpora and serve as strong general baselines. Their focus, however, is not the same as ours. Technical document QA often fails because the retrieved material omits linked evidence, not because the system simply chose the wrong number of passages. Self-RAG and CRAG do not explicitly model those element-to-element relations.
2.3. Hierarchical, Graph-Based, and Memory-Oriented RAG
RAPTOR, GraphRAG, LightRAG, and HippoRAG 2 organize retrieval with richer structures. RAPTOR uses recursive summary trees [8]. GraphRAG builds graph communities and summarizes them for a query [9]. LightRAG combines graph indexing with dual-level retrieval [10]. HippoRAG 2 treats retrieval as a memory problem and uses graph propagation with deeper passage integration [11]. These methods improve long-document retrieval and reasoning. Their structures are mainly semantic, however. They do not directly preserve literal document relations such as clause references, caption links, table lookups, and procedure order.
2.4. Multimodal Document RAG and Evidence Fidelity
VisRAG highlights an important issue in document QA: visual layout may be part of the evidence, and text extraction can discard it [12]. OCR Hinders RAG reaches a related conclusion from the parsing side. When the parsed representation is wrong, downstream retrieval quality drops [13]. Technical-document QA therefore needs more than a cleaned text transcript. It requires raw evidence objects and explicit links among them.
2.5. Technical Document QA Benchmarks and Positioning
Recent benchmarks clarify the scope of the task. MPMQA uses product manuals and evaluates both page retrieval and answer generation [1]. DesignQA tests grounded understanding over engineering regulations, CAD images, and drawings [2]. MMLongBench-Doc and LongDocURL focus on long-document reasoning, cross-page evidence, and evidence location in visually rich PDFs [3,4]. These benchmarks show that the hard part is not only finding related text. The system must also localize and connect different evidence types. TechDocRAG targets this gap. Compared with adaptive and corrective RAG, it focuses on relation-preserving evidence units. Compared with hierarchical and graph-based RAG, it focuses on document-element connectivity rather than abstract knowledge organization. Compared with multimodal document RAG, it adds identifier-aware retrieval and raw evidence traceability for technical documents.
3. Problem Definition
3.1. Technical Documents as Heterogeneous Element Graphs
Let denote a corpus of technical documents. Each document d may be a specification, user guide, maintenance manual, or technical standard. We represent d as a heterogeneous element graph
where each node is one document element. Examples include a clause, paragraph, table, figure, caption, section, or procedure step. Each node has the form
where is the element type, is the raw document object, is the set of technical identifiers and keywords, is a semantic summary, and is metadata. The metadata include the page index, bounding box, section path, document type, version, and normative label.
The edge set preserves both structure and references. Structural edges include contains, precedes, same_section, and step_next. Referential edges include clause_ref, table_ref, figure_ref, caption_of, same_identifier, version_of, and supersedes. The graph therefore keeps dependencies that flat chunking usually removes.
3.2. Task Formulation
For a query q, retrieval should return more than isolated passages. It should return an evidence subgraph over the corpus-level graph . The target subgraph must be relevant and structurally complete. We write the objective as
where measures lexical and semantic relevance, measures evidence connectivity and completeness, measures metadata consistency such as version or document type, and represents retrieval and context-construction cost.
The answer generator is conditioned on the selected evidence subgraph:
where stores provenance links from generated claims to raw evidence nodes. This formulation makes the retrieval target explicit. The goal is to recover the connected evidence needed for grounded technical QA, not merely to find semantically related content.
4. Proposed Framework
4.1. System Overview
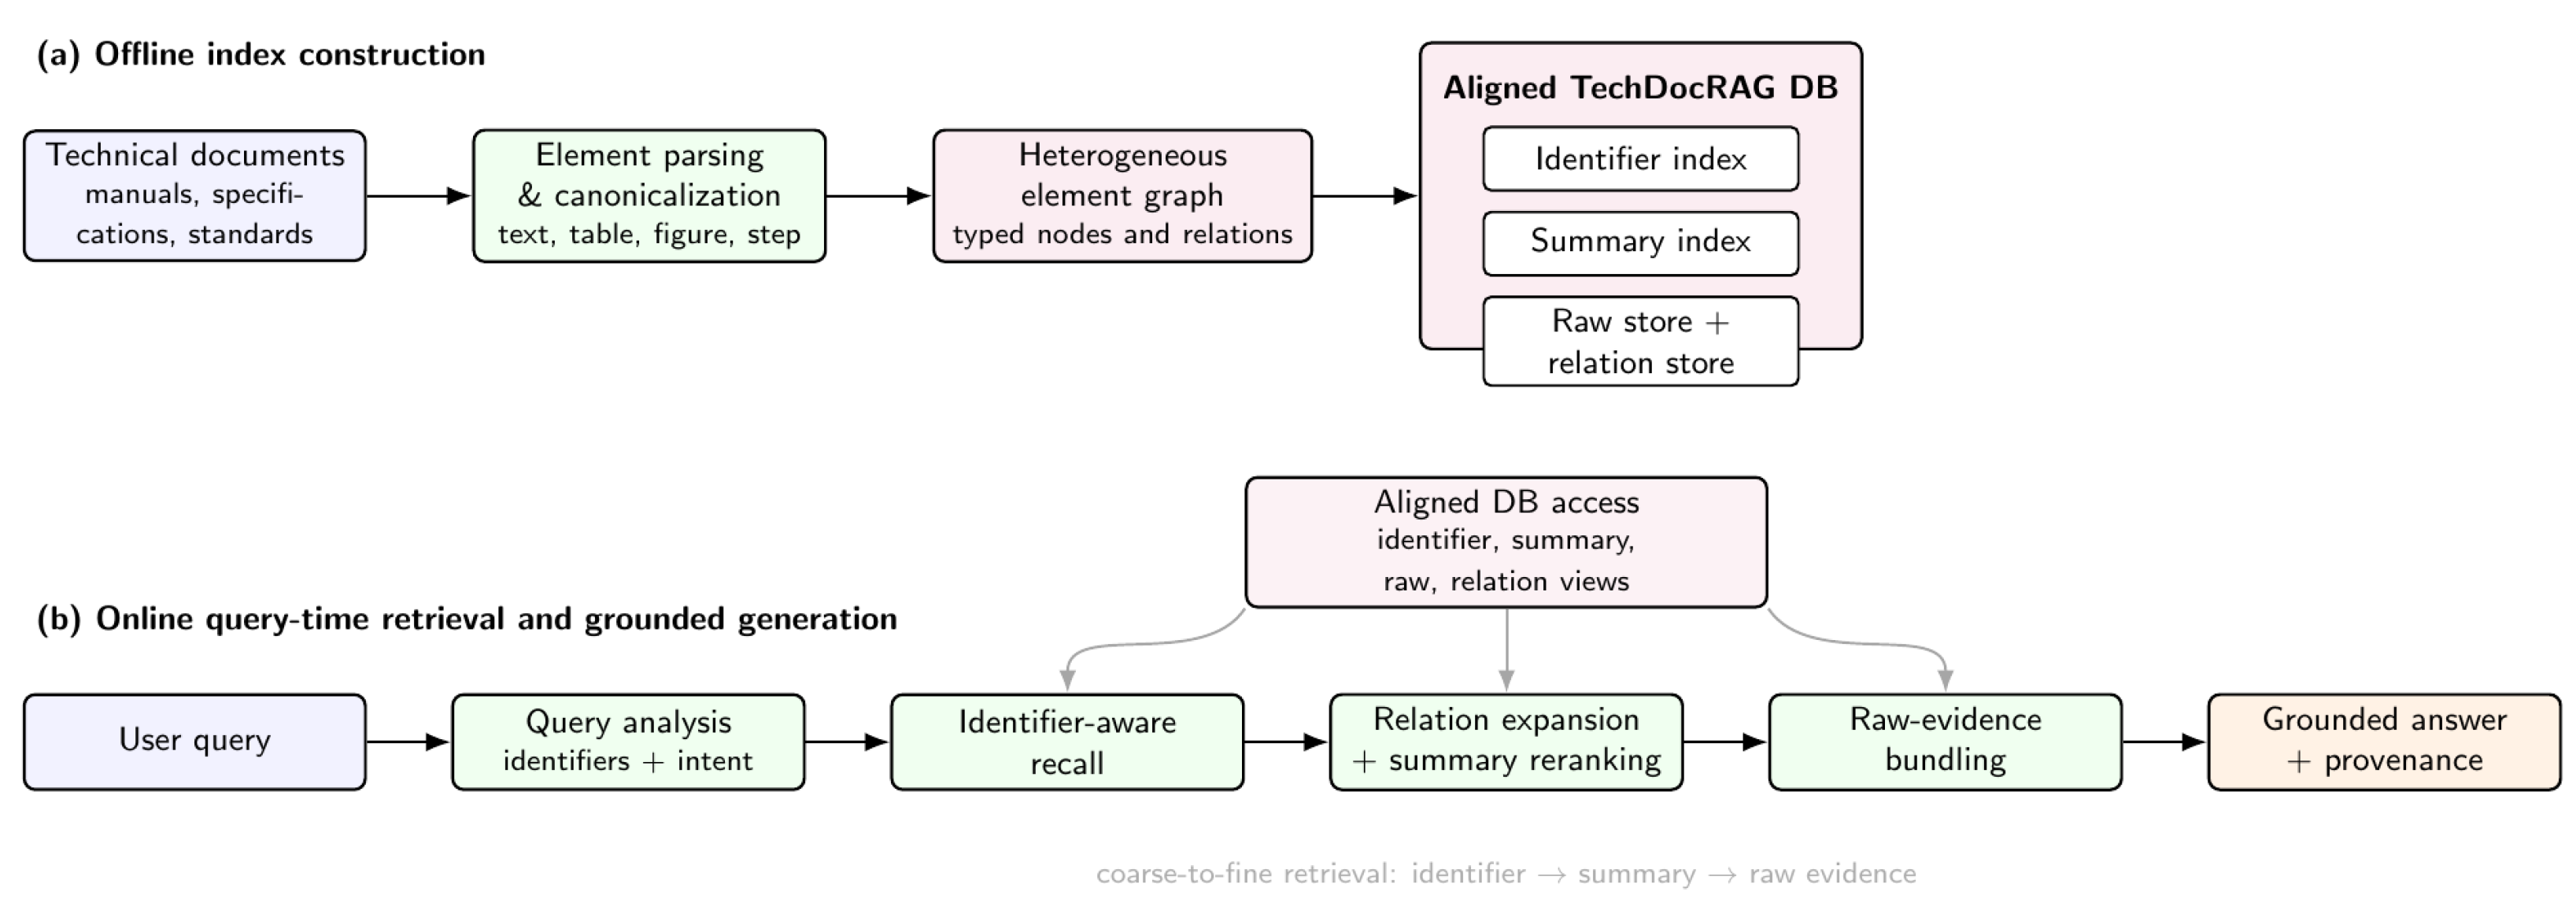
TechDocRAG operates in four stages. It first parses each document into heterogeneous elements and records structural and referential links. It then aligns each element with three views: technical identifiers, semantic summaries, and raw document objects. At query time, it infers the retrieval intent and selects the relation types used for expansion. Retrieval then proceeds from identifier recall to summary-level reranking and raw evidence bundling before the answer is generated with provenance.
Figure 1 summarizes the architecture. The figure separates offline index construction from online query-time retrieval and grounded generation.
Figure 1.
Block diagram of the proposed TechDocRAG framework.
4.2. Relation-Preserving Parsing and Canonicalization
Document parsing follows the units that readers use to navigate technical material: headings, clauses, paragraphs, tables, figures, captions, list items, and procedure steps. The system converts these units into typed graph nodes and stores layout metadata such as page position, bounding boxes, section hierarchy, and local order.
This stage also canonicalizes technical identifiers. The same evidential concept may appear under several surface forms, including variant clause citations, parameter aliases, command syntax, release names, and version labels. We normalize these identifiers before indexing. For each node v, identifier extraction and summary generation are defined as
where denotes the local relation neighborhood of v. The local neighborhood is included because many elements are only interpretable with nearby context.
4.3. Identifier–Summary–Raw Database Construction
After parsing, each element is stored in three aligned views. For each element v, the identifier set, summary, raw object, and metadata remain tied to the same element identity:
At the corpus level, the database is defined as
where is the identifier index, is the summary index, is the raw evidence store, and is the relation store. The stores serve different purposes. The identifier index keeps sparse lexical evidence, including clause numbers, section paths, parameter names, command tokens, API names, error codes, figure labels, table identifiers, units, and other domain-specific anchors. The summary index stores compact semantic summaries for elements and their local contexts. The raw store preserves modality-native evidence, such as verbatim text spans, structured tables, figure regions paired with captions, and ordered procedure segments.
4.4. Query Analysis and Intent-Aware Graph Expansion
Technical document queries require different retrieval paths. We therefore decompose each query into three components:
where is the set of extracted technical identifiers and keywords, is the semantic query representation, and is the query intent. Typical intents include definition lookup, requirement lookup, procedural guidance, troubleshooting, comparison, multimodal interpretation, and version-sensitive reasoning. The predicted intent determines the graph expansion policy .
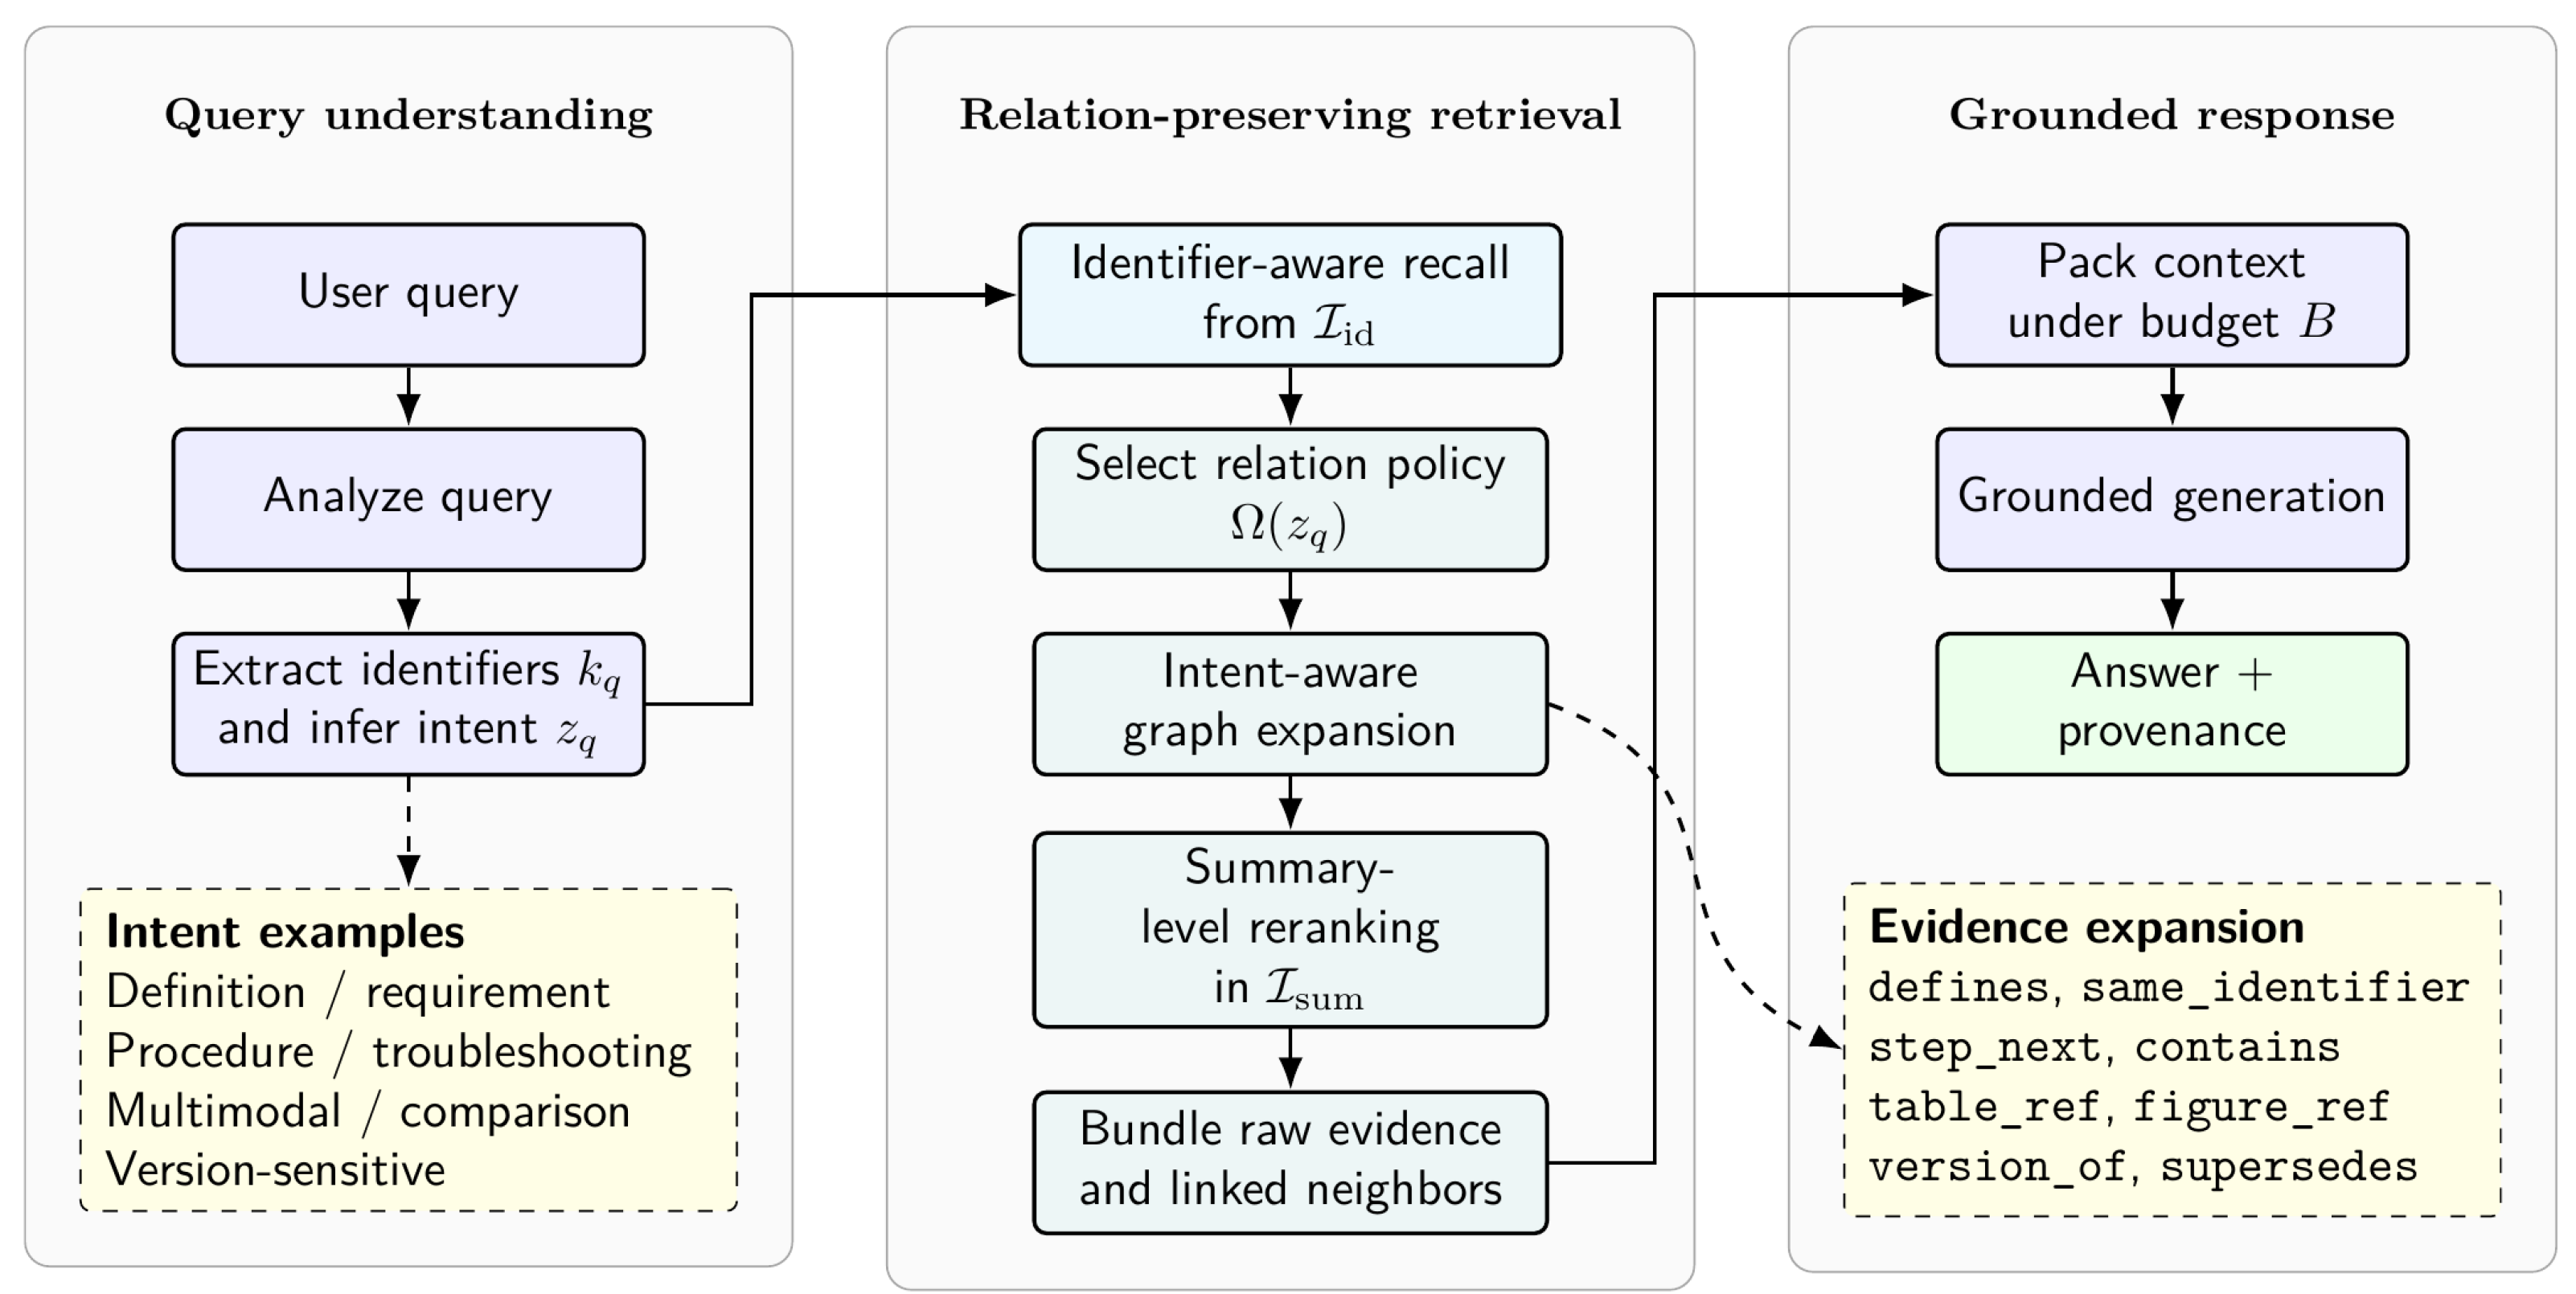
Figure 2 shows the query-time control flow. The flowchart focuses on online decisions rather than the full system architecture. It shows how identifier extraction and intent prediction select the relation expansion policy before summary reranking, raw evidence bundling, and grounded generation.
Figure 2.
Query-time flowchart of TechDocRAG.
Table 1 makes the query-time policy explicit by listing the relation types, traversal depth, and evidence bundles used for each intent class.
Table 1.
Intent-specific relation expansion and evidence bundling policy.
4.5. Coarse-to-Fine Retrieval and Grounded Generation
At query time, retrieval has three steps: identifier-aware recall, summary-level reranking, and raw evidence resolution. The first step retrieves candidate elements from the identifier index:
This step captures exact anchors such as clause numbers, parameter identifiers, release tags, command strings, and table or figure labels. The second step expands the candidate set according to the intent-specific relation policy,
and reranks the expanded candidates in summary space:
The third step resolves reranked summary nodes into raw evidence bundles:
Bundling assembles relation-complete evidence units. Examples include a clause with its referenced table, or a figure crop with its caption and referring paragraph. The final evidence set is packed under a context budget B,
and passed to the answer generator:
Algorithm 1 summarizes the retrieval and bundling procedure.
| Algorithm 1 TechDocRAG coarse-to-fine retrieval pipeline. | |
| Require: Query q; element graph ; indices ; budget B; intent policy | |
| Ensure: Grounded answer and provenance set | |
| Query analysis | |
| 1: | ▹ Extract identifiers, query embedding, and intent |
| Level 1: Identifier-aware recall | |
| 2: | ▹ Direct target recall |
| Level 2: Intent-aware graph expansion | |
| 3: | |
| 4: for all do | |
| 5: | |
| 6: end for | |
| Level 3: Summary-level reranking | |
| 7: | ▹ Filter via semantic similarity |
| Level 4: Raw evidence bundling | |
| 8: | |
| 9: for all do | |
| 10: | |
| 11: end for | |
| Generation | |
| 12: | |
| 13: | |
| 14: return | |
We define provenance at the claim level as
where is a generated claim and is the set of raw evidence objects supporting that claim.
5. Experimental Setup
5.1. Datasets
The evaluation uses four benchmarks. MPMQA covers multimodal question answering on product manuals. Its PM209 corpus includes 209 manuals and 22,021 human-annotated question–answer pairs [1]. DesignQA focuses on engineering document understanding with Formula SAE regulations, CAD images, and engineering drawings [2]. MMLongBench-Doc serves as a long-context stress test. It contains 1062 expert-annotated questions over 130 lengthy PDFs, with an average length of 49.4 pages [3]. LongDocURL provides 2325 question–answer pairs spanning more than 33,000 pages. It separates understanding, reasoning, and locating tasks [4]. The parenthetical counts in Table 4 indicate the full benchmark scale. To keep the comparison balanced, the controlled evaluation protocol uses a curated subset of more than 7500 question–answer pairs across the four benchmarks.
5.2. Baselines
The comparison includes simple retrieval baselines and recent general-purpose RAG systems. We include standard flat baselines based on dense retrieval and a dense+BM25 hybrid. We then compare against Self-RAG [6], CRAG [7], RAPTOR [8], GraphRAG [9], LightRAG [10], HippoRAG 2 [11], and VisRAG [12]. Together, they cover adaptive retrieval, corrective retrieval, hierarchical retrieval, graph-based retrieval, memory-oriented retrieval, and multimodal document retrieval.
5.3. Fair Comparison and Implementation Details
CRAG is restricted to corpus-only retrieval; no external web search is allowed. Methods without native raw-visual access operate on the same canonicalized OCR/text+table representation. In Table 2 and Table 3, all systems use the same answer generator, Gemini-3.1-Flash-Lite-Preview. They use the same evidence budget whenever their design permits it. For page- or region-level retrievers, the final context is normalized to an equivalent budget of 2048 text tokens and 10 visual regions.
Table 2.
Fair-comparison conditions across baselines.
Table 3.
Implementation details of TechDocRAG.
5.4. Evaluation Metrics
We evaluate standard retrieval metrics—Recall@k, MRR, and nDCG@k—at three granularities: identifier, element, and evidence bundle. Answer quality is measured with EM, token-level F1, task accuracy, or the benchmark-specific metric, depending on the dataset. Because the paper focuses on evidence chains, we also report relation-aware grounding metrics.
Let Q denote the evaluation query set. For query q, let and be the gold evidence nodes and edges, and let , , and be the retrieved summary nodes, raw evidence nodes, and relation edges.
We define the Raw Evidence Hit Rate:
We define Summary-to-Raw Trace Accuracy:
We define Evidence Connectivity Recall:
For version-sensitive tasks, we define the Version Consistency Score:
For procedure-centric queries, we additionally report Procedure Order Accuracy:
Finally, we measure the Claim Support Rate:
6. Results
We first report end-to-end performance, followed by grounding quality, query-type behavior, component ablations, and robustness analyses.
6.1. Overall Performance
Table 4 summarizes end-to-end answer quality on the four-benchmark evaluation suite. TechDocRAG is best on all four benchmarks, reaching 68.5 on MPMQA, 62.2 on DesignQA, 58.4 on MMLongBench-Doc, and 55.2 on LongDocURL. Averaged across the four benchmarks, the margin over the strongest flat baseline, Hybrid (Dense+BM25), is 20.3 points, while the margin over the strongest non-flat baseline, VisRAG, is 9.3 points. The improvement is not confined to a single dataset or question type. It appears across manuals, engineering documents, and long visually rich PDFs.
Table 4.
End-to-end answer performance on the full evaluation suite. Parenthetical counts denote benchmark scale; the reported comparison is computed on the balanced 7500+ QA evaluation subset described in Section 5.
6.2. Grounding Quality
The grounding results show a similar pattern. Table 5 compares raw evidence hit rate under progressively relaxed matching criteria. At the strictest level (L0, exact identifier match), TechDocRAG reaches 0.942, whereas the hybrid baseline reaches 0.510. The gap narrows as the criterion is relaxed, but it does not disappear. This indicates that TechDocRAG is not merely retrieving semantically related context. It more often recovers the exact evidential node or its immediate neighborhood.
Table 5.
Retrieval performance under extended strategy relaxation.
Table 6 reports the same comparison on the evidence-annotated subset. The same pattern appears in Recall@10, MRR, SRTA, ECR, and CSR. The gains in SRTA and ECR are especially relevant. They show that the summary layer and relation layer do more than rerank generic passages; they preserve the path from a retrieved summary to the raw evidence used in the final answer.
Table 6.
Retrieval and grounding performance on the full evidence-annotated subset.
6.3. Breakdown by Query Type
Table 7 shows where the gains are largest. The margin is modest on clause lookup and parameter questions, where strong lexical baselines already do reasonably well. It becomes much larger on procedures, text–table questions, cross-reference resolution, and version-sensitive questions. These are the cases in which retrieval must carry structural information forward instead of treating evidence as independent chunks.
Table 7.
Performance breakdown by technical document query type.
6.4. Ablation Study
The ablation results match the intended role of each component in Table 8. Removing identifier-aware recall causes the sharpest drop in REHR. This is expected because exact anchors are often the most reliable entry point into a technical document. Removing relation edges hurts ECR the most. This indicates that graph connectivity is what allows the system to reconstruct the evidence chain after initial recall. Removing raw bundling mainly hurts CSR. This suggests that answer quality deteriorates when the generator receives disconnected fragments instead of coherent evidence bundles. The query-type analysis mirrors this pattern: relation edges matter most for cross-reference and procedure queries, raw bundling matters most for text–table and text–figure questions, and version metadata is decisive for version-sensitive cases.
Table 8.
Ablation study of the proposed framework.
6.5. Resource Costs and Technical Requirements
Table 9 summarizes the resource profile. TechDocRAG requires more offline indexing time than flat retrieval because it has to construct the element graph and align identifiers, summaries, and raw evidence. Even so, it remains lighter than the graph-intensive baseline. On DesignQA, indexing is roughly twice as fast as HippoRAG 2 and the resulting index is considerably smaller. More importantly, the query-time latency is close to standard hybrid retrieval. The main gains therefore do not appear to come from larger context windows or a much larger online compute budget.
Table 9.
Resource and technical requirements measured on DesignQA.
6.6. Robustness Under Identifier Corruption and Relation Dropout
We also evaluate sensitivity to noisy parsing. Table 10 separates two perturbations. In Experiment 2A, OCR-like identifier corruption is injected into clause IDs, parameter names, and figure/table labels. In Experiment 2B, key structural edges such as table_ref and step_next are randomly removed. The results separate two failure modes. Identifier corruption is tolerable up to about 10%, after which performance collapses sharply. Relation loss is much less damaging: even after dropping 30% of the relevant edges, ECR decreases only moderately. Thus, TechDocRAG is robust once retrieval is anchored correctly, but first-stage identifier recall still depends on reasonably faithful parsing.
Table 10.
Robustness analysis under parsing and relation perturbation.
7. Discussion
The results point to a consistent pattern. Performance improves when retrieval returns a connected evidence set rather than an isolated chunk. Technical questions usually do not fail because no related text is found. They fail because the retrieved context is incomplete. For example, a clause may appear without the table that constrains it, or a procedure step may appear without the surrounding steps that make it interpretable. The gains in REHR, SRTA, and ECR support this interpretation.
7.1. The Evidence-Chain Gap
The hybrid baseline is already competitive on standard retrieval tasks. Graph-based baselines are also strong in long-context reasoning. The remaining gap comes from another source. OCR and PDF parsing make technical identifiers brittle, and small formatting changes can break lexical matching. Even when a baseline retrieves the right clause text, it still has to recover the evidence linked to that clause. Without explicit document relations, this second step is unreliable. The strict REHR contrast between Hybrid RAG and TechDocRAG illustrates the point. Both systems can find related text, but TechDocRAG more consistently retrieves the exact evidential node and its immediate support.
7.2. Resource Profile and Robustness
The additional experiments show that these gains do not require an impractical resource budget. TechDocRAG adds offline work because it constructs an element graph and aligns three retrieval views. At query time, however, latency remains close to standard hybrid retrieval and well below the heavier graph baseline in the profiling study. Thus, the method improves grounding without a larger inference budget.
The robustness results also clarify the limitations. Relation dropout causes gradual degradation. This suggests that summary–raw alignment provides redundancy when part of the graph is missing. Identifier corruption is more damaging. Performance remains stable under moderate corruption, but it collapses when the parser damages technical anchors too severely. The system is therefore more tolerant of partial relation loss than of severe identifier loss in the first retrieval stage.
7.3. Limitations and Practical Mitigations
TechDocRAG still depends on document parsing quality. Errors in table extraction, caption alignment, or clause numbering can remove the relations that retrieval relies on [13]. The system also handles explicit references more reliably than implicit ones. Many manuals and standards use layout conventions or shorthand references that are clear to readers but difficult to recover automatically. Cross-version ambiguity remains another limitation. Closely related revisions often reuse identifiers while changing the conditions attached to them. Finally, relation-aware grounding metrics require manual evidence annotation, which limits how broadly they can be applied.
Several mitigations are practical. Confidence-based OCR filtering can flag low-quality pages before graph construction. Selective parser fallback or re-parsing can target pages with corrupted identifiers. Rule-based validation of clause IDs, figure labels, and version tags can catch common normalization failures. Relation-confidence thresholds can also help when table–caption or figure–caption alignment is uncertain. These steps do not remove the problem entirely, but they reduce the chance that retrieval starts from a damaged representation.
Cost-aware parsing is also important for deployment. High-accuracy parsing does not need to be applied uniformly to every page. A lightweight first pass can extract text blocks, bounding boxes, section paths, and candidate technical identifiers. Rule-based validators can then check whether clause numbers, table labels, figure labels, units, and version tags are internally consistent. More expensive OCR, layout analysis, or vision-based extraction can be reserved for low-confidence pages or regions. This includes pages with corrupted identifiers or inconsistent cross-references. Nonstandard layouts and overlapping logical structures do not need to be forced into a single tree. The graph can represent the same element with multiple relation edges and confidence scores. When confidence remains low, the system can fall back to page-level or region-level retrieval and mark the provenance as uncertain. This cascaded strategy can reduce average parsing cost while limiting the effect of parser failures on downstream retrieval.
8. Conclusions
This paper examined retrieval-augmented generation for technical documents, focusing on manuals, engineering documents, and standards. In technical document QA, the main difficulty is not document length alone. The evidence for one answer is usually spread across different kinds of document objects and tied together by explicit references and local structure. Standard chunk-based retrieval tends to break those links.
TechDocRAG addresses this problem by keeping document elements and their relations explicit throughout the pipeline. Each element is indexed through identifiers, summaries, and raw evidence; retrieval moves from exact anchors to semantic reranking and finally to bundled supporting evidence. Across four benchmarks and more than 7500 evaluated question–answer pairs, the method improves answer quality, grounding quality, and relation recovery relative to strong generic RAG baselines. The mean end-to-end improvement is 20.3 points over the strongest flat baseline and 9.3 points over the strongest non-flat baseline, while strict raw evidence hit rate rises from 0.510 to 0.942 on the evidence-annotated subset.
The profiling and robustness results clarify both the strengths and the limits of the approach. Query-time latency stays close to standard hybrid retrieval, but the method still relies on reasonably faithful parsing at the identifier stage. Future work should therefore focus on cost-aware technical document parsing, stronger handling of nonstandard layouts and implicit references, and more robust conflict resolution across document versions. Appendix A summarizes the notation used in the formulation, and Appendix B lists representative structural and referential relations used in the element graph.
Author Contributions
Conceptualization, S.L.; methodology, S.L.; software, S.L.; validation, S.L.; formal analysis, S.L.; investigation, S.L.; resources, S.L.; data curation, S.L.; writing—original draft preparation, S.L.; writing—review and editing, S.L. and M.C.; visualization, S.L.; supervision, M.C.; project administration, M.C. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
Public benchmark datasets were analyzed in this study. These datasets are available from the sources cited in the manuscript, including MPMQA, DesignQA, MMLongBench-Doc, and LongDocURL. No new large-scale benchmark dataset was created. Derived annotations, prompts, and implementation details supporting the findings of this study are available from the first author upon request.
Acknowledgments
The authors thank the maintainers of the public technical document benchmarks used in this study.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| RAG | Retrieval-Augmented Generation |
| QA | Question Answering |
| OCR | Optical Character Recognition |
| MRR | Mean Reciprocal Rank |
| EM | Exact Match |
| REHR | Raw Evidence Hit Rate |
| SRTA | Summary-to-Raw Trace Accuracy |
| ECR | Evidence Connectivity Recall |
| VCS | Version Consistency Score |
| CSR | Claim Support Rate |
Appendix A. Notation Summary
Table A1 summarizes the main symbols used in the problem formulation and retrieval pipeline.
Table A1.
Notation summary.
Appendix B. Representative Relation Types
Table A2 lists representative structural and referential relations used by TechDocRAG.
Table A2.
Representative relation types used in the element graph.
References
- Zhang, L.; Hu, A.; Zhang, J.; Hu, S.; Jin, Q. MPMQA: Multimodal Question Answering on Product Manuals. arXiv 2023, arXiv:2304.09660. [Google Scholar] [CrossRef] [Scilit]
- Doris, A.C.; Grandi, D.; Tomich, R.; Alam, M.F.; Ataei, M.; Cheong, H.; Ahmed, F. DesignQA: A Multimodal Benchmark for Evaluating Large Language Models’ Understanding of Engineering Documentation. arXiv 2024, arXiv:2404.07917. [Google Scholar] [CrossRef] [Scilit]
- Ma, Y.; Zang, Y.; Chen, L.; Chen, M.; Jiao, Y.; Li, X.; Lu, X.; Liu, Z.; Ma, Y.; Dong, X.; et al. MMLongBench-Doc: Benchmarking Long-context Document Understanding with Visualizations. arXiv 2024, arXiv:2407.01523. [Google Scholar]
- Deng, C.; Yuan, J.; Bu, P.; Wang, P.; Li, Z.Z.; Xu, J.; Li, X.H.; Gao, Y.; Song, J.; Zheng, B.; et al. LongDocURL: A Comprehensive Multimodal Long Document Benchmark Integrating Understanding, Reasoning, and Locating. arXiv 2024, arXiv:2412.18424. [Google Scholar]
- Lewis, P.; Perez, E.; Piktus, A.; Petroni, F.; Karpukhin, V.; Goyal, N.; Küttler, H.; Lewis, M.; Yih, W.t.; Rocktäschel, T.; et al. Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. In Proceedings of the Advances in Neural Information Processing Systems, Vancouver, BC, Canada, 6–12 December 2020. [Google Scholar]
- Asai, A.; Wu, Z.; Wang, Y.; Sil, A.; Hajishirzi, H. Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection. arXiv 2023, arXiv:2310.11511. [Google Scholar] [CrossRef] [Scilit]
- Yan, S.Q.; Gu, J.C.; Zhu, Y.; Ling, Z.H. Corrective Retrieval Augmented Generation. arXiv 2024, arXiv:2401.15884. [Google Scholar] [CrossRef] [Scilit]
- Sarthi, P.; Abdullah, S.; Tuli, A.; Khanna, S.; Goldie, A.; Manning, C.D. RAPTOR: Recursive Abstractive Processing for Tree-Organized Retrieval. In Proceedings of the The Twelfth International Conference on Learning Representations, Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Edge, D.; Trinh, H.; Cheng, N.; Bradley, J.; Chao, A.; Mody, A.; Truitt, S.; Metropolitansky, D.; Ness, R.O.; Larson, J. From Local to Global: A GraphRAG Approach to Query-Focused Summarization. arXiv 2024, arXiv:2404.16130. [Google Scholar]
- Guo, Z.; Xia, L.; Yu, Y.; Ao, T.; Huang, C. LightRAG: Simple and Fast Retrieval-Augmented Generation. arXiv 2024, arXiv:2410.05779. [Google Scholar]
- Gutiérrez, B.J.; Shu, Y.; Qi, W.; Zhou, S.; Su, Y. From RAG to Memory: Non-Parametric Continual Learning for Large Language Models. arXiv 2025, arXiv:2502.14802. [Google Scholar] [CrossRef] [Scilit]
- Yu, S.; Tang, C.; Xu, B.; Cui, J.; Ran, J.; Yan, Y.; Liu, Z.; Wang, S.; Han, X.; Liu, Z.; et al. VisRAG: Vision-based Retrieval-augmented Generation on Multi-modality Documents. arXiv 2024, arXiv:2410.10594. [Google Scholar]
- Zhang, J.; Zhang, Q.; Wang, B.; Ouyang, L.; Wen, Z.; Li, Y.; Chow, K.H.; He, C.; Zhang, W. OCR Hinders RAG: Evaluating the Cascading Impact of OCR on Retrieval-Augmented Generation. arXiv 2024, arXiv:2412.02592. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.