


Abstract
Consolidated bioprocessing (CBP) has been widely studied as an integrated route for converting biomass into biofuels and bioproducts, yet most quantitative modeling work has focused on ethanol as a single response. Because CBP systems can generate multiple products and co-products, this study develops a literature-derived benchmark for multi-product CBP modeling using a standardized dataset assembled from published endpoint experiments. Product prediction is formulated as both an observed-only product-wise problem and a joint multi-output problem, allowing direct comparison under study-aware grouped validation. The modeling space integrates biomass composition, pretreatment descriptors, microbial and consortium characteristics, reactor information, operating conditions, and engineered categorical descriptors of feedstock, pretreatment family, and process configuration. Predictive performance was strongly product-dependent and was shaped by target support and missing-label structure. The observed-only product-wise formulation consistently outperformed the joint missing-as-zero multi-output strategy, indicating that naive zero-filling of unreported products is not well suited to sparse literature-derived CBP data. Among the evaluated products, butanol showed the clearest predictive signal, ethanol was only moderately learnable, and the sparsest co-products remained too weakly supported for strong quantitative inference. Overall, this study provides a benchmark for multi-product CBP modeling and clarifies both the potential and the current limitations of literature-derived data for broader data-driven biorefinery analysis.
1. Introduction
1.1. Background and Motivation
Consolidated bioprocessing (CBP) is widely regarded as a promising route for converting lignocellulosic biomass into fuels and chemicals because enzyme production, biomass hydrolysis, and fermentation can be integrated within a single process configuration [1,2,3]. By reducing dependence on externally supplied hydrolytic enzymes and simplifying process integration, CBP has been proposed as a strategy to lower operating costs and improve the feasibility of lignocellulosic biorefineries [3,4,5]. Recent advances in synthetic cellulosomes, engineered cellulolytic hosts, and artificial microbial consortia have further expanded the scope of CBP beyond proof-of-concept demonstrations toward more versatile biomass conversion platforms [4,5,6].
At the same time, much of the CBP literature remains centered on bioethanol, reflecting ethanol’s longstanding role in lignocellulosic biofuel development and its comparatively frequent reporting in experimental studies [2,7,8]. In parallel, the broader biorefinery concept increasingly emphasizes product diversification, in which biomass is converted not only to ethanol but also to value-added organic acids, higher alcohols, polymers, and other specialty products [2,9,10]. This shift motivates a broader analytical perspective on CBP systems, in which feedstock properties, pretreatment choices, microbial configurations, and reactor conditions are examined in relation to multiple possible outputs rather than to a single product alone.
1.2. From Ethanol-Centric Modeling to Multi-Product Analysis
Most experimental and modeling studies in CBP remain ethanol-centric. Recent examples include engineered cellulolytic or ethanologenic hosts, consortium-based ethanol production systems, and optimization-oriented studies focused primarily on ethanol endpoint responses [5,6,7,11,12]. This emphasis is understandable because ethanol remains both a major fuel target and one of the most frequently reported products in lignocellulosic fermentation studies [7,8].
Nevertheless, CBP is not limited to ethanol alone. Recent studies have reported CBP routes to butanol [13,14], malic acid [15], itaconic acid [16], and polyhydroxyalkanoates [17], while engineered and artificial microbial consortia have broadened the range of accessible conversion strategies and product outcomes [9,18]. These developments indicate that CBP can support a broader product portfolio, but they also expose a methodological challenge: the underlying data are fragmented across studies, product definitions, reporting conventions, feedstocks, and microbial systems. As a result, the field still lacks a unified empirical framework for examining how CBP design variables relate to multiple endpoint products.
1.3. Research Gap
Although machine learning, hybrid modeling, and data-driven process analytics are becoming more common in bioprocess engineering [19,20,21,22,23], their application to CBP remains comparatively limited and is still dominated by ethanol-focused studies or process-specific optimization tasks. Prior CBP modeling work has included mechanistic and cybernetic formulations, scale-up models, response surface optimization, and single-product machine-learning studies [11,12]. However, literature-derived CBP data do not appear to be systematically organized into a multi-product predictive framework that jointly examines ethanol and co-products within a unified endpoint-level dataset.
This gap is not only computational but also data-structural. Literature-derived CBP datasets are inherently heterogeneous, spanning different feedstocks, pretreatment methods, microbial strains or consortia, operating conditions, and output-reporting practices. Product coverage is also highly uneven: ethanol is reported frequently, whereas many co-products appear in only a relatively small number of studies. These characteristics make CBP a difficult but informative setting for evaluating multi-output learning, missing-label handling, and reference-aware validation. Addressing this gap can help clarify which products are meaningfully learnable from the current literature-derived data and where predictive performance remains limited by sparse support, heterogeneous study design, and missing-label structure.
1.4. Objectives and Contributions
This study extends CBP modeling from an ethanol-centric perspective to a literature-derived multi-product learning framework for ethanol and co-products. The work makes four main contributions.
First, a standardized CBP dataset is constructed and harmonized from sources in the literature, integrating endpoint records across multiple biomass types, pretreatment strategies, microbial systems, and reactor conditions into a common modeling structure.
Second, CBP product prediction is formulated as both a product-wise and multi-output learning problem, enabling direct comparison between single-target and joint-target modeling strategies under the same reference-aware evaluation protocol.
Third, this study assesses the extent to which shared CBP descriptors support prediction across ethanol and co-products while identifying where predictive performance remains strongly product-dependent due to sparse support, heterogeneous study designs, and missing-label structure.
Fourth, the resulting framework is used as a benchmark to discuss the implications of data availability, feature engineering, validation design, and target sparsity for future CBP modeling and digital biorefinery analysis. In this sense, the present work is intended not as evidence of uniformly accurate multi-product prediction but as a data-centric and methodological assessment of how far current literature-derived CBP data can support robust multi-product learning.
2. Dataset Construction and Problem Formulation
2.1. Literature-Derived Dataset
A structured literature search was conducted to construct the literature-derived CBP dataset analyzed in this study. The search was restricted to peer-reviewed studies on consolidated bioprocessing (CBP) of lignocellulosic biomass and excluded studies based on separate hydrolysis and fermentation (SHF) or simultaneous saccharification and fermentation (SSF) because the objective was to build a dataset specific to CBP systems. Records were retrieved from Scopus and Google Scholar using keyword combinations centered on ‘consolidated bioprocessing’, ‘CBP’, ‘lignocellulosic biomass’, and reported products or co-products such as ethanol, butanol, acetate, lactate, formate, succinic acid, D-glucaric acid, and hydrogen, together with descriptors related to pretreatment, microbial system configuration, and operating conditions. Backward and forward citation screening complemented the database search. Study selection and reporting were guided by established systematic review reporting recommendations [24]. Only peer-reviewed CBP studies with extractable endpoint-level product measurements and sufficient associated process descriptors were retained, whereas SHF- and SSF-based studies, review articles, and studies lacking usable endpoint or process metadata were excluded. Because reporting conventions differed across source papers, the product names, units, and experimental descriptors were standardized during harmonization into a common endpoint-level modeling structure.
The final dataset comprised 640 records and 118 variables after removal of near-constant binary descriptors. Each record represented a single experimental endpoint and included a study-level grouping identifier, together with feedstock, pretreatment, microbial system, reactor, and operating condition descriptors, as well as one or more reported product titers. An endpoint-level representation was adopted because it supports direct comparison of ethanol and co-products within a common supervised-learning framework while preserving traceability to the source literature. Because the literature sources reported product measurements with inconsistent sampling schedules and uneven temporal detail, the dataset was harmonized at the experimental-endpoint level rather than as a unified time-resolved panel. In other words, each row represents a single reported endpoint observation for a given experimental condition, rather than a standardized sequence of measurements across common time points. A unified time-resolved panel was not feasible because many studies reported only endpoint titers, while others used different sampling intervals, cultivation durations, and reporting formats. Additional details on dataset structure and variable descriptions are provided in the Supplementary Information.
2.2. Selection of Products and Output Harmonization
Eight endpoint products were considered as supervised targets: ethanol, acetate, lactate, formate, butanol, succinic acid, D-glucaric acid, and hydrogen. Reported product names and alternative spellings were harmonized into a unified set of response variables. Liquid-phase products were standardized to g L−1, whereas hydrogen was represented in mmol L−1. Product support was highly unbalanced across the dataset, with ethanol reported most frequently and several co-products available only for a limited subset of records. This imbalance motivated evaluating both joint and product-specific prediction settings. A detailed description of product harmonization, response units, and per-product coverage is provided in the Supplementary Information.
2.3. Input Variables and Feature Groups
Predictor variables were organized into four groups reflecting the CBP workflow. The first group describes biomass and feedstock characteristics, including source category and compositional attributes such as cellulose, hemicellulose, and lignin content. The second group captures pretreatment conditions, including reagent information, temperature, residence time, pH, washing, detoxification, and severity-related descriptors. The third group represents the microbial system, including inoculum level, consortium structure, and indicators of microbial composition. The fourth group describes reactor and operating conditions, including working volume, substrate loading, temperature, pH, residence time, agitation, and scale-related descriptors.
2.4. Feature Engineering
Feature engineering was used to translate heterogeneous literature annotations into modeling-ready descriptors while preserving the interpretability of the process. The derived variables captured feedstock class, pretreatment family, principal reagent category, microbial system configuration, kingdom composition, reactor scale, microorganism presence, and informative missingness in partially reported pretreatment fields. Near-constant binary descriptors were removed to reduce redundancy and improve model stability.
2.5. Missing Data Handling and Data Preprocessing
All preprocessing steps were performed independently within each training fold to avoid information leakage from the held-out validation data. Here, information leakage refers to the unintended use of validation fold information during preprocessing or model fitting, which could lead to overly optimistic performance estimates. Numeric predictors were imputed using the median and scaled, whereas categorical predictors were imputed using the most frequent category and encoded for model input. Features with zero variance after preprocessing were removed.
Missing response values were addressed using two complementary formulations. In the primary observed-only product-wise formulation, a separate model was trained for each product using only records in which that product was reported. This formulation avoided imposing assumptions on unreported outcomes. In the secondary joint zero-filled multi-output formulation, missing product values in the training data were provisionally set to zero for model fitting, whereas evaluation remained restricted to observed validation targets. This second formulation was included only as a simple sensitivity analysis for sparse and uneven product reporting, not as a claim that unreported products represented true zero formation.
Outlier handling was also carried out within training folds only. Eligible numeric predictors were screened using an interquartile-range rule, and records with the greatest aggregate predictor-level outlier burdens were removed, subject to a maximum trimming fraction of 30%. Validation records were not trimmed.
The trimming procedure was introduced as a robustification step for heterogeneous literature-derived predictor data, not as a target-dependent filtering mechanism. It was learned separately within each training fold and based only on predictor-space outlier burden, thereby reducing the influence of highly irregular descriptor combinations while avoiding target leakage into validation. The maximum trimming fraction of 30% was imposed as an upper safeguard rather than a desired removal level. Because preprocessing choices can affect absolute predictive performance, the reported results should be interpreted in light of the trimming design.
2.6. Problem Definition
The primary task was endpoint-level prediction of multiple CBP products from feedstock, pretreatment, microbial, and reactor descriptors. Let denote the predictor vector for experiment i, and let denote the corresponding vector of harmonized product responses. Two prediction settings were examined: an observed-only product-wise formulation, in which separate models were trained for individual products using only observed labels, and a joint zero-filled multi-output formulation, in which a single model predicted the full product vector after zero-filling missing training targets. This dual formulation enabled direct comparison between target-specific learning and shared-output learning under sparse literature-derived labeling.
3. Modeling Methodology
3.1. Observed-Only Product-Wise Formulation
Under the observed-only product-wise formulation, a separate model was trained for each product using only records with observed values for that product. This formulation avoided imposing assumptions on unreported outcomes and served as the primary analytical basis. The benchmark model set was intentionally compact and comprised a mean-response baseline, ridge regression, partial least squares (PLS) regression, random forests, and extremely randomized trees [25,26,27]. These models were selected to span a range of inductive biases, including constant prediction, linear shrinkage, latent-variable regression, and nonlinear tree-based ensembling. A compact benchmark set was preferred to support stable comparisons under nested cross-validation on a sparse, heterogeneous literature-derived dataset.
3.2. Joint Zero-Filled Multi-Output Formulation
Under the joint zero-filled multi-output formulation, a single model was trained to simultaneously predict the full product vector. Because literature-derived CBP studies often report only a subset of products, missing target values in the training data were provisionally set to zero for model fitting, whereas validation metrics were computed only for targets explicitly reported in the corresponding validation records. This formulation was included as a deliberately simple secondary sensitivity analysis to test, in a transparent baseline setting, whether shared CBP descriptors could support joint prediction across sparsely reported outputs. However, because an unreported product does not necessarily indicate confirmed zero formation, this formulation was not treated as the primary analytical basis. More specialized missing-label approaches, including masked multi-task learning, censored-response models, and two-stage occurrence/magnitude formulations, may be better suited to literature-derived product data, but these were beyond the scope of the present compact benchmark, whose primary aim was to compare target-handling strategies under grouped validation on a sparse and heterogeneous dataset [28,29].
3.3. Training and Hyperparameter Tuning
Model development followed a nested cross-validation design in which hyperparameters were selected within inner folds and performance was assessed only in outer folds. The tuning space was intentionally modest. For ridge regression, the regularization parameter was varied over . For PLS regression, the number of latent components was varied over . For Random Forest, the number of trees was fixed at 300 while tree depth and minimum leaf size were varied. For extremely randomized trees, the number of trees was fixed at 400 while tree depth and minimum leaf size were varied. Inner-loop model selection was based on mean macro-averaged RMSE. For PLS regression, the effective number of latent components was additionally constrained by the rank and sample support available within each training fold. After inner-loop selection, the chosen model was refit on the full outer training fold and used to generate outer-fold predictions.
3.4. Grouped Validation Strategy
To reduce optimistic bias arising from related experiments reported within the same source study, all data splitting was performed with study-aware grouping. The outer loop used five grouped folds and the inner loop used three grouped folds, subject to the number of distinct studies available. This design ensured that records from the same source were not split across training and validation sets within a given evaluation round. Group-aware validation was especially important because multiple records could share a study-specific context, including feedstock selection, microbial design, and experimental practice [30,31].
3.5. Performance Metrics
Predictive performance was evaluated using root mean squared error (RMSE), mean absolute error (MAE), coefficient of determination (), and Spearman rank correlation. All metrics were computed from outer-fold predictions only. Under the joint zero-filled multi-output formulation, metrics were calculated separately for each product using only observed validation entries and then summarized using macro-averaged values across targets. RMSE and MAE were emphasized because they preserve the physical units of the response variables, whereas and Spearman correlation were included to assess explained variance and rank-order consistency under pronounced target imbalance.
3.6. Model Interpretation
Model interpretation was handled cautiously and focused on relative variable importance and the stability of model behavior across products and validation folds. Interpretation was used to assess whether certain descriptor groups showed consistent associations with predictive performance across targets, while avoiding strong mechanistic claims for products with limited statistical support. Given the heterogeneity of the source literature and the sparse support for several co-products, all interpretation was treated as association-based rather than causal.
The modeling pipeline comprised dataset harmonization, fold-wise preprocessing with training-only trimming, comparison of the observed-only product-wise formulation and the joint zero-filled multi-output formulation, and shared benchmarking under grouped nested cross-validation, as shown in Figure 1.
Figure 1.
Simplified methodological workflow for literature-derived multi-product CBP modeling. The pipeline branches only at the target-handling step, contrasting the observed-only product-wise formulation with the joint zero-filled multi-output formulation, while preprocessing, benchmarking, grouped nested cross-validation, and evaluation remain shared across formulations.
3.7. Computational Reproducibility
The analyses were implemented in Python 3.13.5 and developed in Visual Studio Code version 1.117.0, with a fixed random seed of 42. The workflow used NumPy 2.3.2, pandas 2.3.1, Matplotlib 3.10.3, SciPy 1.16.0, scikit-learn 1.7.1, and joblib 1.5.1.
4. Results and Discussion
4.1. Dataset Support and Missingness
As summarized in Table 1, the literature-derived CBP dataset comprised 640 experimental endpoint records described by 118 variables and eight supervised product targets. The dataset integrates mixed biomass, pretreatment, microbial system, reactor, and operating descriptors within a common endpoint-level representation. This unified structure enables joint benchmarking across products, but it also introduces substantial heterogeneity that must be considered when interpreting predictive performance.
Table 1.
Short summary of the literature-derived CBP dataset used in this study.
Target support was highly uneven across products, as shown in Figure 2. Ethanol was the only well-supported response, with 543 observed records out of 640 total entries (84.8%). All other products were much sparser, including acetate (147, 23.0%), butanol (46, 7.2%), lactate (41, 6.4%), formate (26, 4.1%), hydrogen (24, 3.8%), succinic acid (12, 1.9%), and D-glucaric acid (10, 1.6%). This imbalance is a defining feature of the dataset and indicates that predictive learnability is likely to vary strongly by product rather than remaining uniform across outputs.
Figure 2.
Observed and unreported records by product in the literature-derived CBP dataset. For each product, ‘unreported’ denotes experimental endpoints for which that product was not reported in the source study and therefore has no observed harmonized value in the curated dataset. These entries are treated as unobserved labels rather than true zero production.
For most co-products, unreported outcomes far outnumber observed outcomes, limiting statistical support and increasing sensitivity to missing-label assumptions. The product-level results that follow should therefore be interpreted primarily as evidence of differential learnability in a sparse, heterogeneous literature-derived dataset rather than as evidence of uniformly reliable multi-product prediction. A complete per-product coverage summary and additional supporting details are provided in the Supplementary Information.
4.2. Final Model Selection and Tuning
Across both target-handling formulations, Random Forest was selected as the final model with the same regularized configuration: 300 trees, maximum depth of 8, and minimum leaf size of 3 (Table 2). This convergence indicates that the main difference between formulations did not arise from a different preferred model class, but from how missing response values were handled.
Table 2.
Selected Random Forest configuration and best inner cross-validation performance for each formulation.
Inner cross-validation performance supports this interpretation. The observed-only product-wise formulation achieved a lower mean inner macro RMSE (7.27) than the joint zero-filled multi-output formulation (10.69), despite selecting the same model family and hyperparameter configuration. Thus, the two formulations converged on the same model class, but not on the same level of tuning performance.
4.3. Comparison of Target-Handling Strategies
The two target-handling formulations were compared using nested grouped cross-validation. Under the joint zero-filled multi-output formulation, missing product values were set to zero during training and evaluation was restricted to observed validation targets. Under the observed-only product-wise formulation, a separate model was trained for each product using only records with observed labels. In both settings, Random Forest was selected as the best overall model, but the observed-only product-wise formulation consistently yielded stronger out-of-fold performance, as summarized in Table 3.
Table 3.
Best-model out-of-fold macro metrics by target-handling formulation. In both cases, Random Forest was selected as the best overall model.
The observed-only product-wise formulation reduced macro RMSE from 12.68 to 10.49 and macro MAE from 9.40 to 6.16 relative to the joint zero-filled multi-output formulation. Macro improved from to , and macro Spearman correlation increased from approximately zero to 0.255. Although absolute performance remained imperfect, the direction and consistency of these changes indicate that zero-filling missing targets degraded both calibration and rank preservation, as summarized in Table 3.
The broader model-by-formulation comparison supports the same conclusion. Across candidate models, the observed-only product-wise formulation generally achieved a lower macro RMSE, whereas macro remained weak or unstable in several settings despite its relative improvement over the joint zero-filled multi-output formulation, as shown in Figure 3 and Figure 4. These results indicate that target handling is a consequential modeling choice in this sparse literature-derived dataset rather than a minor preprocessing detail.
Figure 3.
Nested cross-validation macro RMSE across candidate models and target-handling formulations (95% confidence intervals). The observed-only product-wise formulation generally yields lower error than the joint zero-filled multi-output formulation.
Figure 4.
Nested cross-validation macro across candidate models and target-handling formulations (95% confidence intervals). Although the observed-only product-wise formulation improves relative performance, remains weak or unstable in several model settings.
4.4. Outer-Fold Model Ranking and Selection Stability Under the Preferred Formulation
Because the observed-only product-wise formulation emerged as the preferred approach, the relative performance of candidate models within this setting is informative. Averaged across outer folds, Random Forest achieved the lowest macro RMSE (6.54), followed closely by Extra Trees (6.59), the mean-response baseline (6.87), ridge regression (7.13), and partial least squares regression (7.18), as shown in Table 4. This ranking indicates that tree-based ensembles were the most competitive model class under the preferred formulation, although the margin over the simplest baseline was modest.
Table 4.
Mean outer-fold macro performance of candidate models under the preferred observed-only product-wise formulation.
The outer-fold selection frequencies provide a complementary view of the same result. Under the preferred observed-only product-wise formulation, Random Forest ranked first in three of five outer folds, while Extra Trees ranked first in the remaining two. Under the joint zero-filled multi-output formulation, Random Forest ranked first in all five outer folds, and no linear model or mean-response baseline ranked first in either formulation, as summarized in Table 5. Taken together, these results indicate a stable preference for nonlinear ensemble methods across folds rather than a conclusion driven by a single favorable split.
Table 5.
Outer-fold best-model frequency under each target-handling formulation.
Random Forest was therefore retained as the main reference model for the subsequent product-specific analysis. Although Extra Trees was numerically close, Random Forest provided the strongest overall balance in the aggregate comparison while remaining the most frequently selected model under the preferred formulation.
4.5. Effect of Fold-Wise Trimming
Trimming was learned exclusively from the training folds, thereby avoiding leakage into validation data. Even with this precaution, the trimming burden differed substantially between the two formulations. The joint zero-filled multi-output formulation consistently required heavier row removal than the observed-only product-wise formulation, and in the final fitted model, it reached the prespecified trimming ceiling of 30%. This pattern is important because the joint zero-filled multi-output formulation not only performed worse but also depended on more aggressive filtering to do so, as summarized in Table 6 and Figure 5.
Table 6.
Summary of trimming burden for the final selected formulations.
Figure 5.
Mean fold-wise trimming burden on training folds. The joint zero-filled multi-output formulation consistently requires heavier filtering than the observed-only product-wise formulation.
The product-specific trimming record under the preferred observed-only product-wise formulation provides further context. In the final target-wise fit, trimming removed 29.8% of ethanol rows, 19.7% of acetate rows, 29.2% of hydrogen rows, and 20.0% of D-glucaric acid rows, but only 2.2% of butanol rows and none of the formate or succinic acid rows. This uneven burden suggests that part of the product-specific variation in predictive performance reflects differences in data regularity in addition to differences in raw target support, as shown in Table 7.
Table 7.
Product-specific row support and trimming burden for the final observed-only product-wise Random Forest fit.
This variation in trimming burden is consistent with the trimming definition used in the workflow. Trimming was performed separately within each product-specific observed training subset and was based on predictor-space outlier burden rather than on the product value itself. Accordingly, higher trimmed fractions for products such as ethanol and hydrogen likely reflect greater heterogeneity in the associated feedstocks, pretreatments, microbial systems, and operating conditions across the supporting studies. By contrast, lower trimmed fractions for butanol, formate, and succinic acid are consistent with smaller and, in some cases, more homogeneous observed subsets. At the same time, very low or zero trimming for sparsely supported products should not be interpreted as inherently better data quality because small subsets provide fewer opportunities for rows to be flagged under an IQR-based rule.
4.6. Product-Specific Performance and Support-Dependent Learnability
Predictive performance was strongly product-dependent. Under the observed-only product-wise formulation, butanol showed the clearest evidence of learnability, with RMSE decreasing from 7.17 to 5.92 and Spearman correlation increasing from 0.220 to 0.612 relative to the joint zero-filled multi-output formulation. Ethanol also improved, with RMSE decreasing from 15.42 to 14.82 and Spearman correlation increasing from 0.390 to 0.476. Acetate changed only marginally between formulations, lactate remained weak in both settings, and hydrogen improved from an RMSE of 39.18 to 29.83 but remained weak overall. The sparsest products, including succinic acid and D-glucaric acid, remained too data-limited to support robust quantitative conclusions, as shown in Figure 6.
Figure 6.
Per-product RMSE under the two target-handling formulations. The observed-only product-wise formulation shows the clearest gains for butanol, hydrogen, and ethanol, whereas the sparsest products remain weak overall.
These results indicate that the current literature-derived dataset supports learnability only for a subset of products, rather than providing uniformly accurate multi-product regression. Product support was clearly important, but it was not sufficient on its own to guarantee a strong predictive structure. Under the preferred observed-only product-wise formulation, ethanol remained the most frequently reported product (), yet showed only moderate rank recovery (Spearman ), whereas butanol, despite much lower support (), showed the strongest rank agreement (Spearman ). By contrast, acetate, lactate, and hydrogen remained weakly recoverable under the same workflow, as summarized in Table 8.
Table 8.
Observed support and best-model out-of-fold performance under the preferred observed-only product-wise formulation for products with sufficient evaluable support.
This comparison also suggests that products differed in their recoverable signal under the current feature space. Ethanol likely benefited from high support but remained heterogeneous because it aggregated diverse feedstocks, pretreatments, and microbial systems. Butanol appeared more recoverable relative to its sample size, possibly reflecting a more coherent subset of study designs or more structured process–response behavior. In contrast, acetate and hydrogen showed weak calibration and unstable rank ordering, while lactate showed low absolute error largely because of a narrow response range rather than strong predictive recovery. Detailed per-product values are provided in Supplementary Table S5.
Butanol showed the clearest learnability within the present benchmark, but this result should be interpreted cautiously. Although only 46 butanol records were available, they were distributed across 33 study labels rather than arising from a single dominant source, suggesting that the signal was not purely study-specific. At the same time, some concentration remained within a limited number of studies, so part of the observed performance may reflect repeated or closely related experimental condition sweeps. The butanol values also spanned a substantial range, indicating that the result cannot be explained simply by an artificially narrow response distribution. Taken together, these observations suggest that butanol may be comparatively learnable within the current literature-derived dataset, but this conclusion should be viewed as provisional and conditional on the structure and support of the available butanol subset.
4.7. Diagnostic Error Structure for Moderate-to-Weakly Learnable Products
The parity and residual diagnostics for acetate and lactate indicate that the main limitation of the current framework is not purely random error, but systematic compression toward lower predicted values. For acetate, the two formulations produced nearly identical RMSE values, yet both parity plots show substantial deviation from the 1:1 line at higher observed concentrations, and the residual plots show increasingly negative errors as the observed value increases. This pattern indicates persistent underprediction of larger acetate responses, even under the observed-only product-wise formulation. The slight improvement in rank agreement under the observed-only product-wise formulation therefore appears to reflect only a modest gain in relative ordering rather than a substantial improvement in calibration, as shown in Figure 7 and Figure 8.
Figure 7.
Parity diagnostics for acetate and lactate under the two target-handling formulations. For both products, predictions remain compressed toward low values, and departures from the 1:1 line become more evident at higher observed responses. The observed-only product-wise formulation provides only limited improvement in calibration.
Figure 8.
Residual diagnostics for acetate and lactate under the two target-handling formulations. Both products show increasingly negative residuals at higher observed values, indicating persistent underprediction of upper-range responses. The observed-only product-wise formulation reduces this bias only modestly.
Lactate showed a related but even more weakly structured pattern. Absolute RMSE was small because the response range was narrow, but both parity and residual diagnostics indicated that larger observed values were still poorly recovered. The observed-only product-wise formulation modestly improved Spearman correlation relative to the joint zero-filled multi-output formulation, yet the overall fit remained weak and the residuals remained predominantly negative at the upper end of the observed range. In practical terms, these plots show that the low absolute error for lactate should not be overinterpreted as evidence of robust predictability, as shown in Figure 7 and Figure 8.
Taken together, these diagnostics indicate that the observed-only product-wise formulation is the more defensible approach for sparse literature-derived CBP data. At the same time, they show that product-specific bias remains substantial even for responses with relatively favorable error magnitudes. The current framework is therefore best interpreted as a benchmark of product-dependent learnability rather than as a uniformly accurate predictive platform across CBP products, as shown in Figure 7 and Figure 8.
4.8. Limitations
Several limitations shape the interpretation of the present results. First, the dataset was assembled from independent CBP studies and therefore inherits substantial cross-study heterogeneity in feedstock characterization, pretreatment descriptions, microbial system reporting, reactor operation, sampling practices, and analytical measurements. Such variability is characteristic of the current CBP literature and cannot be fully removed through endpoint-level harmonization alone [1,2,3,5]. Consequently, part of the observed prediction error likely reflects differences in study design and reporting quality rather than solely biological or process-level behavior.
Second, target support was highly uneven across products. Ethanol was comparatively well represented, whereas several co-products were available for only a small subset of records. This imbalance limited statistical support for sparse products and contributed to strongly product-dependent predictive performance. The resulting framework is therefore more defensible as a benchmark of data-supported learnability than as a uniformly accurate predictive model for all CBP outputs.
Third, missing labels remain intrinsically ambiguous in the literature-derived CBP data. An unreported product may reflect true absence, concentration below detection, selective reporting, or omission from the experimental objective. Although the observed-only product-wise formulation proved more reliable than the joint zero-filled multi-output formulation for this dataset, neither strategy fully resolved the underlying missingness mechanism. This issue is especially important in heterogeneous bioprocess datasets, where reporting practices can vary substantially across studies [19,20,22].
Fourth, the analysis was limited to endpoint prediction. CBP systems are inherently dynamic, and endpoint titers do not capture temporal interactions among hydrolysis, growth, intermediate accumulation, and product conversion. As a result, the present models cannot resolve kinetic behavior, transient pathway competition, or timing-dependent trade-offs that are central to many CBP systems [4,6,18].
Finally, the benchmark was intentionally conservative. Grouped nested cross-validation and fold-wise trimming reduced optimistic bias, but the final comparison still relied on tabular descriptors and relatively robust model classes suited to sparse, mixed-type data. The resulting interpretation remains association-based rather than causal, and the identified variables should not be interpreted as definitive process drivers [19,20,23]. In addition, although the comparative difference between formulations remained informative, the absolute metric values should be interpreted with appropriate caution because trimming constitutes a preprocessing choice that may influence fitted model behavior on a heterogeneous literature-derived dataset.
4.9. Implications and Future Directions
Taken together, the results support the interpretation of this study as a benchmark and methodological contribution rather than as evidence of uniformly accurate multi-product prediction across all CBP outputs. The unified literature-derived framework proved feasible, but predictive signal remained uneven across products and was strongly shaped by target support, missingness, and cross-study heterogeneity. Among the evaluated products, butanol showed the clearest evidence of learnability, ethanol showed only moderate structure, and the sparsest co-products remained weakly constrained. The observed-only product-wise formulation consistently outperformed the joint zero-filled multi-output formulation and required less trimming, indicating that for literature-derived CBP datasets with substantial label sparsity, treating unreported products as missing is more defensible than assigning them a value of zero.
The main contribution is therefore methodological as much as it is predictive. This study establishes a grouped nested cross-validation workflow for multi-product CBP analysis, shows that missing-label assumptions materially affect model behavior, and highlights product support as a primary determinant of learnability in literature-derived bioprocess data. The results also indicate that learnability is product-dependent and, to some extent, model-class-dependent.
Future progress in multi-product CBP modeling will depend first on stronger data resources. Expansion of the literature-derived dataset should be accompanied by tighter unit harmonization, clearer handling of detection limits, and richer metadata for feedstock composition, pretreatment severity, microbial configuration, reactor design, and analytical method. More consistent reporting of co-products and operating conditions across CBP studies would improve comparability and reduce ambiguity in downstream modeling [1,2,10].
A second priority is more explicit treatment of sparse and partially observed targets. Two-stage formulations that separate product occurrence from product magnitude, as well as censored, zero-inflated, masked-multitask, or hierarchical models, may be better suited to literature-derived CBP data than a single regression formulation applied uniformly across all products [19,20,21,22].
A third direction is the integration of temporal and mechanistic structure. Time-resolved CBP datasets would enable prediction of product trajectories rather than final titers alone, while hybrid approaches could combine process knowledge with machine learning to represent coupled phenomena such as hydrolysis, uptake, and by-product formation more realistically [4,6,18,23].
Model interpretation and validation should also be strengthened. Future studies should include target-specific dependence analysis, local explanation methods, uncertainty-aware attribution, and stratified error analysis across feedstock classes, pretreatment families, and microbial system types. External validation using source-wise holdout sets, temporal splits, and independent datasets will also be needed to assess transportability beyond the present literature pool [10,19,20].
The long-term objective is not only to improve predictive accuracy but also to determine which CBP products are reliably learnable from current evidence, which additional descriptors most improve generalization, and how data-centric design can better support biorefinery-oriented process development [9,10].
5. Summary and Conclusions
This study developed a literature-derived modeling framework for consolidated bioprocessing (CBP) that extends analysis beyond ethanol to a multi-product setting. A standardized endpoint-level dataset was assembled from heterogeneous CBP studies, and grouped validation was used to reduce leakage across related experiments while accommodating mixed numerical and categorical descriptors. Product prediction was evaluated under two target-handling formulations to assess how missing-label assumptions affect model behavior.
Across the evaluated models, Random Forest provided the strongest overall balance of performance and robustness. The observed-only product-wise formulation consistently outperformed the joint zero-filled multi-output formulation and generally required less aggressive trimming. These results indicate that missing-label treatment is a central modeling decision in literature-derived CBP data.
Predictive performance remained strongly product-dependent. Butanol showed the clearest evidence of learnability, ethanol showed only moderate predictive structure, and several sparsely reported co-products remained too weakly supported for robust quantitative conclusions. The results therefore indicate both the feasibility and the present limits of multi-product CBP learning: a unified benchmarking framework can be constructed, but recoverable signal depends strongly on target support, missingness structure, and cross-study heterogeneity.
The principal contribution of this study is methodological as much as it is predictive. The framework establishes a grouped nested cross-validation workflow for multi-product CBP analysis, shows that missing-target assumptions materially affect model conclusions, and highlights product support as a primary determinant of learnability in literature-derived bioprocess datasets. This study should therefore be interpreted as a benchmark for multi-product CBP modeling rather than as evidence of uniformly accurate prediction across all outputs.
Supplementary Materials
The following supporting information can be downloaded at https://www.mdpi.com/article/10.3390/fermentation12050224/s1. Supplementary Table S1, Full variable dictionary for the primary harmonized analysis dataset; Supplementary Table S2, Observed coverage of product-response variables in the primary harmonized analysis dataset; Supplementary Table S3, Source and reference mapping for grouped study-level traceability and literature sources used to construct the dataset [6,13,14,15,16,32,33,34,35,36,37,38,39,40,41,42,43,44,45,46,47,48,49,50,51,52,53,54,55,56,57,58,59,60,61,62,63,64,65,66,67,68,69,70,71,72,73,74,75,76,77,78,79,80,81,82,83,84,85,86,87,88,89,90,91,92,93,94,95,96,97,98,99,100,101,102,103,104,105,106,107,108,109,110,111,112,113,114,115,116]; Supplementary Table S4, Per-product out-of-fold metrics for the best model (Random Forest) under each formulation. Cells marked—were not available in the current observed-only summary; and Supplementary Table S5, Outer-fold best-performing model and macro RMSE under each formulation. The Supplementary Material also includes additional details on dataset harmonization, variable definitions, response units, missingness handling, and source traceability.
Author Contributions
Conceptualization, M.K.Y.; methodology, M.K.Y.; validation, M.K.Y. and A.A.; formal analysis, M.K.Y.; investigation, M.K.Y. and N.Y.A.; data curation, M.K.Y.; visualization, M.K.Y.; writing—original draft preparation, M.K.Y.; writing—review and editing, N.Y.A. and A.A.; supervision, N.Y.A. and A.A. All authors have read and agreed to the published version of the manuscript.
Funding
This work was partly supported by the German Academic Exchange Service (DAAD) under the programme Research Grants—Bi-nationally Supervised Doctoral Degrees/Cotutelle (Grant No. 57693451).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The original contributions presented in this study are included in the article/Supplementary Material. Further inquiries can be directed to the corresponding authors.
Acknowledgments
The authors acknowledge support from the Open Access Publication Fund of the University of Duisburg-Essen, the German Academic Exchange Service (DAAD), and the KNUST Engineering Education Project (KEEP).
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Singhania, R.R.; Patel, A.K.; Singh, A.; Haldar, D.; Soam, S.; Chen, C.W.; Tsai, M.L.; Dong, C.D. Consolidated bioprocessing of lignocellulosic biomass: Technological advances and challenges. Bioresour. Technol. 2022, 354, 127153. [Google Scholar] [CrossRef] [Scilit]
- Li, Z.; Waghmare, P.R.; Dijkhuizen, L.; Meng, X.; Liu, W. Research advances on the consolidated bioprocessing of lignocellulosic biomass. Eng. Microbiol. 2024, 4, 100139. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.J.; Li, B.; Feng, Y.; Cui, Q. Consolidated bio-saccharification: Leading lignocellulose bioconversion into the real world. Biotechnol. Adv. 2020, 40, 107535. [Google Scholar] [CrossRef] [Scilit]
- Tsai, S.L.; Sun, Q.; Chen, W. Advances in consolidated bioprocessing using synthetic cellulosomes. Curr. Opin. Biotechnol. 2022, 78, 102840. [Google Scholar] [CrossRef] [Scilit]
- Sharma, J.; Kumar, V.; Prasad, R.; Gaur, N.A. Engineering of Saccharomyces cerevisiae as a consolidated bioprocessing host to produce cellulosic ethanol: Recent advancements and current challenges. Biotechnol. Adv. 2022, 56, 107925. [Google Scholar] [CrossRef] [Scilit]
- Minnaar, L.; den Haan, R. Engineering natural isolates of Saccharomyces cerevisiae for consolidated bioprocessing of cellulosic feedstocks. Appl. Microbiol. Biotechnol. 2023, 107, 7013–7028. [Google Scholar] [CrossRef] [Scilit]
- Periyasamy, S.; Beula Isabel, J.; Kavitha, S.; Karthik, V.; Mohamed, B.A.; Gizaw, D.G.; Sivashanmugam, P.; Aminabhavi, T.M. Recent advances in consolidated bioprocessing for conversion of lignocellulosic biomass into bioethanol—A review. Chem. Eng. J. 2023, 453, 139783. [Google Scholar] [CrossRef] [Scilit]
- Yeboah, M.K.; Asiedu, N.Y.; Dogbe, S.; Addo, A. Performance of Machine Learning Based-Modelling Approach in Consolidated Bioprocessing with Microbial Consortium for Bioethanol Production. Ind. Biotechnol. 2024, 20, 77–97. [Google Scholar] [CrossRef] [Scilit]
- Maitra, S.; Singh, V. A consolidated bioprocess design to produce multiple high-value platform chemicals from lignocellulosic biomass and its technoeconomic feasibility. J. Clean. Prod. 2022, 377, 134383. [Google Scholar] [CrossRef] [Scilit]
- Long, B.; Zhang, F.; Dai, S.Y.; Foston, M.; Tang, Y.J.; Yuan, J.S. Engineering strategies to optimize lignocellulosic biorefineries. Nat. Rev. Bioeng. 2025, 3, 230–244. [Google Scholar] [CrossRef] [Scilit]
- Madhuvanthi, S.; Jayanthi, S.; Suresh, S.; Pugazhendhi, A. Optimization of consolidated bioprocessing by response surface methodology in the conversion of corn stover to bioethanol by thermophilic Geobacillus thermoglucosidasius. Chemosphere 2022, 304, 135242. [Google Scholar] [CrossRef] [Scilit]
- Yeboah, M.K.; Söffker, D. Consolidated Bioprocessing of Lignocellulosic Biomass: A Review of Experimental Advances and Modeling Approaches. Bioresour. Bioprod. 2026, 2, 4. [Google Scholar] [CrossRef] [Scilit]
- Wen, Z.; Ledesma-Amaro, R.; Lu, M.; Jin, M.; Yang, S. Metabolic engineering of Clostridium cellulovorans to improve butanol production by consolidated bioprocessing. ACS Synth. Biol. 2020, 9, 304–315. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wen, Z.; Li, Q.; Liu, J.; Jin, M.; Yang, S. Consolidated bioprocessing for butanol production of cellulolytic Clostridia: Development and optimization. Microb. Biotechnol. 2020, 13, 410–422. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; Chen, B.; Gu, S.; Zhao, Z.; Liu, Q.; Sun, T.; Zhang, Y.; Wu, T.; Liu, D.; Sun, W.; et al. Coordination of consolidated bioprocessing technology and carbon dioxide fixation to produce malic acid directly from plant biomass in Myceliophthora thermophila. Biotechnol. Biofuels 2021, 14, 186. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Schlembach, I.; Hosseinpour Tehrani, H.; Blank, L.M.; Büchs, J.; Wierckx, N.; Regestein, L.; Rosenbaum, M.A. Consolidated bioprocessing of cellulose to itaconic acid by a co-culture of Trichoderma reesei and Ustilago maydis. Biotechnol. Biofuels 2020, 13, 207. [Google Scholar] [CrossRef] [Scilit]
- Kumar, V.; Fox, B.G.; Takasuka, T.E. Consolidated bioprocessing of plant biomass to polyhydroxyalkanoate by co-culture of Streptomyces sp. SirexAA-E and Priestia megaterium. Bioresour. Technol. 2023, 376, 128934. [Google Scholar] [CrossRef] [Scilit]
- Fang, H.; Deng, Y.; Pan, Y.; Li, C.; Yu, L. Distributive and collaborative push-and-pull in an artificial microbial consortium for improved consolidated bioprocessing. AIChE J. 2022, 68, e17844. [Google Scholar] [CrossRef] [Scilit]
- Helleckes, L.M.; Hemmerich, J.; Wiechert, W.; von Lieres, E.; Grünberger, A. Machine learning in bioprocess development: From promise to practice. Trends Biotechnol. 2023, 41, 817–835. [Google Scholar] [PubMed]
- Mondal, P.P.; Galodha, A.; Verma, V.K.; Singh, V.; Show, P.L.; Awasthi, M.K.; Lall, B.; Anees, S.; Pollmann, K.; Jain, R. Review on machine learning-based bioprocess optimization, monitoring, and control systems. Bioresour. Technol. 2023, 370, 128523. [Google Scholar] [CrossRef] [Scilit]
- Khanal, S.K.; Tarafdar, A.; You, S. Artificial intelligence and machine learning for smart bioprocesses. Bioresour. Technol. 2023, 375, 128826. [Google Scholar] [CrossRef] [Scilit]
- Cheng, Y.; Bi, X.; Xu, Y.; Liu, Y.; Li, J.; Du, G.; Lv, X.; Liu, L. Artificial intelligence technologies in bioprocess: Opportunities and challenges. Bioresour. Technol. 2023, 369, 128451. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Agharafeie, R.; Ramos, J.R.C.; Mendes, J.M.; Oliveira, R. From shallow to deep bioprocess hybrid modeling: Advances and future perspectives. Fermentation 2023, 9, 922. [Google Scholar] [CrossRef] [Scilit]
- Page, M.J.; McKenzie, J.E.; Bossuyt, P.M.; Boutron, I.; Hoffmann, T.C.; Mulrow, C.D.; Shamseer, L.; Tetzlaff, J.M.; Akl, E.A.; Brennan, S.E.; et al. The PRISMA 2020 statement: An updated guideline for reporting systematic reviews. BMJ 2021, 372, n71. [Google Scholar] [CrossRef] [Scilit]
- Rajan, M. An efficient Ridge regression algorithm with parameter estimation for data analysis in machine learning. SN Comput. Sci. 2022, 3, 171. [Google Scholar] [CrossRef] [Scilit]
- Mishra, P.; Nikzad-Langerodi, R. Partial least square regression versus domain invariant partial least square regression with application to near-infrared spectroscopy of fresh fruit. Infrared Phys. Technol. 2020, 111, 103547. [Google Scholar] [CrossRef] [Scilit]
- Heddam, S. Extremely randomized trees versus random forest, group method of data handling, and artificial neural network. In Handbook of Hydroinformatics; Elsevier: Amsterdam, The Netherlands, 2023; pp. 291–304. [Google Scholar]
- Zhang, Y.; Yang, Q. A survey on multi-task learning. IEEE Trans. Knowl. Data Eng. 2021, 34, 5586–5609. [Google Scholar] [CrossRef] [Scilit]
- Tardy, M.; Mateus, D. Leveraging multi-task learning to cope with poor and missing labels of mammograms. Front. Radiol. 2022, 1, 796078. [Google Scholar] [CrossRef] [Scilit]
- Moscovich, A.; Rosset, S. On the cross-validation bias due to unsupervised preprocessing. J. R. Stat. Soc. Ser. B Stat. Methodol. 2022, 84, 1474–1502. [Google Scholar]
- Kumar, C.; Walton, G.; Santi, P.; Luza, C. Random cross-validation produces biased assessment of machine learning performance in regional landslide susceptibility prediction. Remote Sens. 2025, 17, 213. [Google Scholar]
- Althuri, A.; Gujjala, L.K.S.; Banerjee, R. Partially consolidated bioprocessing of mixed lignocellulosic feedstocks for ethanol production. Bioresour. Technol. 2017, 245, 530–539. [Google Scholar] [CrossRef] [Scilit]
- Anandharaj, M.; Lin, Y.J.; Rani, R.P.; Nadendla, E.K.; Ho, M.C.; Huang, C.C.; Cheng, J.F.; Chang, J.J.; Li, W.H. Constructing a yeast to express the largest cellulosome complex on the cell surface. Proc. Natl. Acad. Sci. USA 2020, 117, 2385–2394. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Argyros, D.A.; Tripathi, S.A.; Barrett, T.F.; Rogers, S.R.; Feinberg, L.F.; Olson, D.G.; Foden, J.M.; Miller, B.B.; Lynd, L.R.; Hogsett, D.A.; et al. High Ethanol Titers from Cellulose by Using Metabolically Engineered Thermophilic, Anaerobic Microbes. Appl. Environ. Microbiol. 2011, 77, 8288–8294. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Bao, T.; Hou, W.; Wu, X.; Lu, L.; Zhang, X.; Yang, S.T. Engineering Clostridium cellulovorans for highly selective n-butanol production from cellulose in consolidated bioprocessing. Biotechnol. Bioeng. 2021, 118, 2703–2718. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Begum, S.; Dahman, Y. Enhanced biobutanol production using novel clostridial fusants in simultaneous saccharification and fermentation of green renewable agriculture residues. Biofuels Bioprod. Biorefin. 2015, 9, 529–544. [Google Scholar] [CrossRef] [Scilit]
- Bokinsky, G.; Peralta-Yahya, P.P.; George, A.; Holmes, B.M.; Steen, E.J.; Dietrich, J.; Lee, T.S.; Tullman-Ercek, D.; Voigt, C.A.; Simmons, B.A.; et al. Synthesis of three advanced biofuels from ionic liquid-pretreated switchgrass using engineered Escherichia coli. Proc. Natl. Acad. Sci. USA 2011, 108, 19949–19954. [Google Scholar] [CrossRef] [Scilit]
- Brethauer, S.; Studer, M.H. Consolidated bioprocessing of lignocellulose by a microbial consortium. Energy Environ. Sci. 2014, 7, 1446–1453. [Google Scholar] [CrossRef] [Scilit]
- Bu, Y.; Alkotaini, B.; Salunke, B.K.; Deshmukh, A.R.; Saha, P.; Kim, B.S. Direct ethanol production from cellulose by consortium of Trichoderma reesei and Candida molischiana. Green Process. Synth. 2019, 8, 416–420. [Google Scholar] [CrossRef] [Scilit]
- Chuengcharoenphanich, N.; Watsuntorn, W.; Qi, W.; Wang, Z.; Hu, Y.; Chulalaksananukul, W. The potential of biodiesel production from grasses in Thailand through consolidated bioprocessing using a cellulolytic oleaginous yeast, Cyberlindnera rhodanensis CU-CV7. Energy 2023, 263, 125759. [Google Scholar] [CrossRef] [Scilit]
- Chung, D.; Cha, M.; Snyder, E.N.; Elkins, J.G.; Guss, A.M.; Westpheling, J. Cellulosic ethanol production via consolidated bioprocessing at 75 °C by engineered Caldicellulosiruptor bescii. Biotechnol. Biofuels 2015, 8, 163. [Google Scholar] [CrossRef] [Scilit]
- Davison, S.A.; Keller, N.T.; van Zyl, W.H.; den Haan, R. Improved cellulase expression in diploid yeast strains enhanced consolidated bioprocessing of pretreated corn residues. Enzym. Microb. Technol. 2019, 131, 109382. [Google Scholar] [CrossRef] [Scilit]
- Dempfle, D.B. Model-Based Scale-Up of a Continuously Operated Consolidated Bioprocess Based on a Microbial Consortium for the Production of Ethanol. Ph.D. Thesis, EPFL, Lausanne, Switzerland, 2022. [Google Scholar]
- Drosos, A.; Boura, K.; Dima, A.; Karabagias, I.K.; Nigam, P.S.; Kanellaki, M.; Koutinas, A.A. Consolidated bioprocessing of starch based on a bilayer cell factory without genetic modification of yeast. Environ. Technol. Innov. 2021, 24, 101844. [Google Scholar] [CrossRef] [Scilit]
- Fan, L.H.; Zhang, Z.J.; Yu, X.Y.; Xue, Y.X.; Tan, T.W. Self-surface assembly of cellulosomes with two miniscaffoldins on Saccharomyces cerevisiae for cellulosic ethanol production. Proc. Natl. Acad. Sci. USA 2012, 109, 13260–13265. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Fang, H.; Zhao, C.; Li, C.; Song, Y.; Yu, L.; Song, X.; Wu, J.; Yang, L. Direct consolidated bioprocessing for D-glucaric acid production from lignocellulose under subcritical water pretreatment. Chem. Eng. J. 2023, 454, 140339. [Google Scholar] [CrossRef] [Scilit]
- Fang, H.; Li, Y.; Song, Y.; Yu, L.; Song, X.; Zhao, C. Consolidated bioprocessing of lignocellulosic wastes in Northwest China for D-glucaric acid production by an artificial microbial consortium. Bioprocess Biosyst. Eng. 2024, 47, 1999–2010. [Google Scholar] [CrossRef] [Scilit]
- Gaida, S.M.; Liedtke, A.; Jentges, A.H.W.; Engels, B.; Jennewein, S. Metabolic engineering of Clostridium cellulolyticum for the production of n-butanol from crystalline cellulose. Microb. Cell Fact. 2016, 15, 6. [Google Scholar] [CrossRef] [Scilit]
- Gupte, A.P.; Di Vita, N.; Myburgh, M.W.; Cripwell, R.A.; Basaglia, M.; van Zyl, W.H.; Viljoen-Bloom, M.; Casella, S.; Favaro, L. Consolidated bioprocessing of the organic fraction of municipal solid waste into bioethanol. Energy Convers. Manag. 2024, 302, 118105. [Google Scholar] [CrossRef] [Scilit]
- He, Q.; Hemme, C.L.; Jiang, H.; He, Z.; Zhou, J. Mechanisms of enhanced cellulosic bioethanol fermentation by co-cultivation of Clostridium and Thermoanaerobacter spp. Bioresour. Technol. 2011, 102, 9586–9592. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Higashide, W.; Li, Y.; Yang, Y.; Liao, J.C. Metabolic engineering of Clostridium cellulolyticum for production of isobutanol from cellulose. Appl. Environ. Microbiol. 2011, 77, 2727–2733. [Google Scholar] [CrossRef] [Scilit]
- Hong, J.; Yang, H.; Zhang, K.; Liu, C.; Zou, S.; Zhang, M. Development of a cellulolytic Saccharomyces cerevisiae strain with enhanced cellobiohydrolase activity. World J. Microbiol. Biotechnol. 2014, 30, 2985–2993. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Jeon, E.; Hyeon, J.; Lee, S.E.; Park, B.S.; Kim, S.W.; Lee, J.; Han, S.O. Cellulosic alcoholic fermentation using recombinant Saccharomyces cerevisiae engineered for the production of Clostridium cellulovorans endoglucanase and Saccharomycopsis fibuligera β-glucosidase. FEMS Microbiol. Lett. 2009, 301, 130–136. [Google Scholar] [CrossRef] [Scilit]
- Jiang, Y.; Lv, Y.; Wu, R.; Lu, J.; Dong, W.; Zhou, J.; Zhang, W.; Xin, F.; Jiang, M. Consolidated bioprocessing performance of a two-species microbial consortium for butanol production from lignocellulosic biomass. Biotechnol. Bioeng. 2020, 117, 2985–2995. [Google Scholar] [CrossRef] [Scilit]
- Jin, M.; Gunawan, C.; Balan, V.; Dale, B.E. Consolidated bioprocessing (CBP) of AFEX-pretreated corn stover for ethanol production using Clostridium phytofermentans at a high solids loading. Biotechnol. Bioeng. 2012, 109, 1929–1936. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kavitha, S.; Gajendran, T.; Saranya, K.; Selvakumar, P.; Manivasagan, V.; Jeevitha, S. An insight—A statistical investigation of consolidated bioprocessing of Allium ascalonicum leaves to ethanol using Hangateiclostridium thermocellum KSMK1203 and synthetic consortium. Renew. Energy 2022, 187, 403–416. [Google Scholar] [CrossRef] [Scilit]
- Kavitha, S.; Gajendran, T.; Saranya, K.; Manivasagan, V. Bioconversion of Sargassum wightii to ethanol via consolidated bioprocessing using Lachnoclostridium phytofermentans KSM 1203. Fuel 2023, 347, 128465. [Google Scholar] [CrossRef] [Scilit]
- Kavitha, S.; Gajendran, T.; Saranya, K.; Selvakumar, P.; Manivasagan, V. Study on consolidated bioprocessing of pre-treated Nannochloropsis gaditana biomass into ethanol under optimal strategy. Renew. Energy 2021, 172, 440–452. [Google Scholar] [CrossRef] [Scilit]
- Kiyoshi, K.; Furukawa, M.; Seyama, T.; Kadokura, T.; Nakazato, A.; Nakayama, S. Butanol production from alkali-pretreated rice straw by co-culture of Clostridium thermocellum and Clostridium saccharoperbutylacetonicum. Bioresour. Technol. 2015, 186, 325–328. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Ho, S.H.; Sasaki, K.; den Haan, R.; Inokuma, K.; Ogino, C.; van Zyl, W.H.; Hasunuma, T.; Kondo, A. Engineering of a novel cellulose-adherent cellulolytic Saccharomyces cerevisiae for cellulosic biofuel production. Sci. Rep. 2016, 6, 24550. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Maleki, F.; Changizian, M.; Zolfaghari, N.; Rajaei, S.; Akbari Noghabi, K.; Shahbani Zahiri, H. Consolidated bioprocessing for bioethanol production by metabolically engineered Bacillus subtilis strains. Sci. Rep. 2021, 11, 13731. [Google Scholar] [CrossRef] [Scilit]
- Malherbe, S.J.M.; Cripwell, R.A.; Favaro, L.; van Zyl, W.H.; Viljoen-Bloom, M. Triticale and sorghum as feedstock for bioethanol production via consolidated bioprocessing. Renew. Energy 2023, 206, 498–505. [Google Scholar] [CrossRef] [Scilit]
- Mattila, H.; Kačar, D.; Mali, T.; Lundell, T. Lignocellulose bioconversion to ethanol by a fungal single-step consolidated method tested with waste substrates and co-culture experiments. AIMS Energy 2018, 6, 866–879. [Google Scholar] [CrossRef] [Scilit]
- Minty, J.J.; Singer, M.E.; Scholz, S.A.; Bae, C.H.; Ahn, J.H.; Foster, C.E.; Liao, J.C.; Lin, X.N. Design and characterization of synthetic fungal–bacterial consortia for direct production of isobutanol from cellulosic biomass. Proc. Natl. Acad. Sci. USA 2013, 110, 14592–14597. [Google Scholar] [CrossRef] [Scilit]
- Mohapatra, S.; Jena, S.; Jena, P.K.; Badhai, J.; Acharya, A.N.; Thatoi, H. Partial consolidated bioprocessing of pretreated Pennisetum sp. by anaerobic thermophiles for enhanced bioethanol production. Chemosphere 2020, 256, 127126. [Google Scholar] [CrossRef] [Scilit]
- Munoz-Gutierrez, I.; Oropeza, R.; Gosset, G.; Martinez, A. Cell surface display of a beta-glucosidase employing the type V secretion system on ethanologenic Escherichia coli for the fermentation of cellobiose to ethanol. J. Ind. Microbiol. Biotechnol. 2012, 39, 1141–1152. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Nagarajan, D.; Lee, D.J.; Chang, J.S. Recent insights into consolidated bioprocessing for lignocellulosic biohydrogen production. Int. J. Hydrogen Energy 2019. [Google Scholar] [CrossRef] [Scilit]
- Nakatani, Y.; Yamada, R.; Ogino, C.; Kondo, A. Synergetic effect of yeast cell-surface expression of cellulase and expansin-like protein on direct ethanol production from cellulose. Microb. Cell Fact. 2013, 12, 66. [Google Scholar] [CrossRef] [Scilit]
- Nakayama, S.; Kiyoshi, K.; Kadokura, T.; Nakazato, A. Butanol production from crystalline cellulose by cocultured Clostridium thermocellum and Clostridium saccharoperbutylacetonicum N1-4. Appl. Environ. Microbiol. 2011, 77, 6470–6475. [Google Scholar] [CrossRef] [Scilit]
- Nielsen, D.R.; Leonard, E.; Yoon, S.H.; Tseng, H.C.; Yuan, C.; Prather, K.L.J. Engineering alternative butanol production platforms in heterologous bacteria. Metab. Eng. 2009, 11, 262–273. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Nongthombam, G.D.; Sarangi, P.K.; Singh, T.A.; Sharma, C.K.; Talukdar, N.C. Bioethanol production from Ficus fruits (Ficus cunia) by Fusarium oxysporum through consolidated bioprocessing system. 3 Biotech 2022, 12, 178. [Google Scholar] [CrossRef] [Scilit]
- Pang, J.; Hao, M.; Shi, Y.; Li, Y.; Zhu, M.; Hu, J.; Liu, J.; Zhang, Q.; Liu, Z. Enhancing the ethanol yield from Salix using a Clostridium thermocellum and Thermoanaerobacterium thermosaccharolyticum co-culture system. BioResources 2018, 13, 5377–5393. [Google Scholar] [CrossRef] [Scilit]
- Papathoti, N.K.; Mendam, K.; Thepbandit, W.; Burgula, N.; Sangpueak, R.; Saengchan, C.; Hoang, N.H.; Keshav, P.K.; Thanh, T.L.; Buensanteai, N. Bioethanol production from alkali-pretreated cassava stem waste via consolidated bioprocessing by ethanol-tolerant Clostridium thermocellum ATCC 31924. Biomass Convers. Biorefin. 2024, 14, 6821–6833. [Google Scholar] [CrossRef] [Scilit]
- Park, E.Y.; Naruse, K.; Kato, T. One-pot bioethanol production from cellulose by co-culture of Acremonium cellulolyticus and Saccharomyces cerevisiae. Biotechnol. Biofuels 2012, 5, 1–11. [Google Scholar] [CrossRef] [Scilit]
- Perez, C.L.; Milessi, T.S.; Sandri, J.P.; Ramos, M.D.N.; Carvalho, B.T.; Claes, A.; Demeke, M.M.; Thevelein, J.M.; Zangirolami, T.C. Evaluation of consolidated bioprocessing of sugarcane biomass by a multiple hydrolytic enzyme producer Saccharomyces yeast. BioEnergy Res. 2023, 16, 1973–1989. [Google Scholar] [CrossRef] [Scilit]
- Petitdemange, E.; Fond, O.; Caillet, F.; Petitdemange, H.; Gay, R. A novel one step process for cellulose fermentation using mesophilic cellulolytic and glycolytic clostridia. Biotechnol. Lett. 1983, 5, 119–124. [Google Scholar] [CrossRef] [Scilit]
- Podleśny, M.; Szymczak, T.; Kucharska, J.; Szymajda, M. Consolidated bioprocessing of inulin-containing feedstock to succinic acid by newly isolated Enterobacter sp. GAP1. Biotechnol. Rep. 2025, 48, e00929. [Google Scholar] [CrossRef] [Scilit]
- Ramos, M.D.N.; Sandri, J.P.; Claes, A.; Carvalho, B.T.; Thevelein, J.M.; Zangirolami, T.C.; Milessi, T.S. Effective application of immobilized second generation industrial Saccharomyces cerevisiae strain on consolidated bioprocessing. New Biotechnol. 2023, 78, 153–161. [Google Scholar] [CrossRef] [Scilit]
- Restiawaty, E.; Dewi, A.; Wibisono, T.A.S.E.; Budhi, Y.W. Lignocellulosic bioethanol production using Neurospora intermedia in consolidated bioprocessing (CBP) system. Biofuels 2023, 14, 343–352. [Google Scholar] [CrossRef] [Scilit]
- Ryu, S.; Karim, M.N. A whole cell biocatalyst for cellulosic ethanol production from dilute acid-pretreated corn stover hydrolyzates. Appl. Microbiol. Biotechnol. 2011, 91, 529–542. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Salimi, F.; Mahadevan, R. Characterizing metabolic interactions in a clostridial coculture for consolidated bioprocessing. BMC Biotechnol. 2013, 13, 95. [Google Scholar] [CrossRef] [Scilit]
- Schadeweg, V.; Boles, E. Increasing n-butanol production with Saccharomyces cerevisiae by optimizing acetyl-CoA synthesis, NADH levels and trans-2-enoyl-CoA reductase expression. Biotechnol. Biofuels 2016, 9, 257. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Schmidt, V.K.O.; Ferreira, P.B.; Kelbert, M.; de Oliveira, D.; Carciofi, B.A.M. Clostridium sp.: A versatile microbial platform for advancing the consolidated bioprocessing of lignocellulosic residues. J. Environ. Chem. Eng. 2025, 13, 116802. [Google Scholar] [CrossRef] [Scilit]
- Selvakumar, P.; Kavitha, S.; Sivashanmugam, P. Optimization of process parameters for efficient bioconversion of thermo-chemo pretreated Manihot esculenta Crantz YTP1 stem to ethanol. Waste Biomass Valorization 2019, 10, 2177–2191. [Google Scholar] [CrossRef] [Scilit]
- Seo, H.; Singh, P.; Wyman, C.E.; Cai, C.M.; Trinh, C.T. Rewiring metabolism of Clostridium thermocellum for consolidated bioprocessing of lignocellulosic biomass poplar to produce short-chain esters. Bioresour. Technol. 2023, 384, 129263. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Shen, C.R.; Lan, E.I.; Dekishima, Y.; Baez, A.; Cho, K.M.; Liao, J.C. Driving forces enable high-titer anaerobic 1-butanol synthesis in Escherichia coli. Appl. Environ. Microbiol. 2011, 77, 2905–2915. [Google Scholar] [CrossRef] [Scilit]
- Singh, N.; Gupta, A.; Mathur, A.S.; Barrow, C.; Puri, M. Integrated consolidated bioprocessing for simultaneous production of omega-3 fatty acids and bioethanol. Biomass Bioenergy 2020, 137, 105555. [Google Scholar] [CrossRef] [Scilit]
- Sukma, A.C.T.; Budiyono, B.; Al-Baarri, A.N. Integrated consolidated bioprocessing with fungal pretreatment for bioethanol production from rice straw using a microbial consortium. Biomass Convers. Biorefin. 2026, 16, 36. [Google Scholar] [CrossRef] [Scilit]
- Wen, F.; Si, T.; Xu, J.H.; Zhao, H. Direct conversion of xylan to ethanol by recombinant Saccharomyces cerevisiae strains displaying an engineered minihemicellulosome. Appl. Environ. Microbiol. 2012, 78, 3837–3845. [Google Scholar] [CrossRef] [Scilit]
- Tang, H.; Wang, J.; Wang, S.; Shen, Y.; Petranovic, D.; Hou, J.; Bao, X. Efficient yeast surface-display of novel complex synthetic cellulosomes. Microb. Cell Fact. 2018, 17, 122. [Google Scholar] [CrossRef] [Scilit]
- Tsai, S.L.; Oh, J.; Singh, S.; Chen, R.Z.; Chen, W. Functional assembly of minicellulosomes on the Saccharomyces cerevisiae cell surface for cellulose hydrolysis and ethanol production. Appl. Environ. Microbiol. 2009, 75, 6087–6093. [Google Scholar] [CrossRef] [Scilit]
- Tsai, S.L.; Goyal, G.; Chen, W. Surface display of a functional minicellulosome by intracellular complementation using a synthetic yeast consortium and its application to cellulose hydrolysis and ethanol production. Appl. Environ. Microbiol. 2010, 76, 7514–7520. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Tsai, S.L.; DaSilva, N.A.; Chen, W. Functional display of complex cellulosomes on the yeast surface via adaptive assembly. ACS Synth. Biol. 2013, 2, 14–21. [Google Scholar] [CrossRef] [Scilit]
- Vaid, S.; Nargotra, P.; Bajaj, B.K. Consolidated bioprocessing for biofuel-ethanol production from pine needle biomass. Environ. Prog. Sustain. Energy 2017, 37, 546–552. [Google Scholar] [CrossRef] [Scilit]
- Vaid, S.; Sharma, S.; Dutt, H.C.; Mahajan, R.; Bajaj, B.K. One pot consolidated bioprocess for conversion of Saccharum spontaneum biomass to ethanol-biofuel. Energy Convers. Manag. 2021, 250, 114880. [Google Scholar] [CrossRef] [Scilit]
- Varriale, L.; Kuka, K.; Tippkötter, N.; Olsson, L.; Ulber, R. Development of a consolidated bioprocess for the production of citric acid using Aspergillus niger as biocatalyst. Biofuels Bioprod. Biorefin. 2025, 19, 1622–1630. [Google Scholar] [CrossRef] [Scilit]
- Wang, N.; Yan, Z.; Liu, N.; Zhang, X.; Xu, C. Synergy of Cellulase Systems between Acetivibrio thermocellus and Thermoclostridium stercorarium in Consolidated-Bioprocessing for Cellulosic Ethanol. Microorganisms 2022, 10, 502. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, X.; Gou, C.; Zheng, H.; Guo, N.; Li, Y.; Liao, A.; Liu, N.; Tian, H.; Huang, J. Optimization of consolidated bioprocessing fermentation of uncooked sweet potato residue for bioethanol production by using a recombinant amylolytic Saccharomyces cerevisiae strain via the orthogonal experimental design method. Fermentation 2024, 10, 471. [Google Scholar] [CrossRef] [Scilit]
- Wen, F.; Sun, J.; Zhao, H. Yeast surface display of trifunctional minicellulosomes for simultaneous saccharification and fermentation of cellulose to ethanol. Appl. Environ. Microbiol. 2010, 76, 1251–1260. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wen, Z.; Wu, M.; Lin, Y.; Yang, L.; Lin, J.; Cen, P. Artificial symbiosis for acetone-butanol-ethanol (ABE) fermentation from alkali extracted deshelled corn cobs by co-culture of Clostridium beijerinckii and Clostridium cellulovorans. Microb. Cell Factories 2014, 13, 1–11. [Google Scholar] [CrossRef] [Scilit]
- Xiong, W.; Maness, P.C.; Michener, W.E.; Chou, K.J. Engineering cellulolytic bacterium Clostridium thermocellum to co-ferment cellulose- and hemicellulose-derived sugars simultaneously. Biotechnol. Bioeng. 2018, 115, 1755–1763. [Google Scholar] [CrossRef] [Scilit]
- Xu, L.; Tschirner, U. Improved ethanol production from various carbohydrates through anaerobic thermophilic co-culture. Bioresour. Technol. 2011, 102, 10065–10071. [Google Scholar] [CrossRef] [Scilit]
- Yang, X.; Xu, M.; Yang, S.T. Metabolic and process engineering of Clostridium cellulovorans for biofuel production from cellulose. Metab. Eng. 2015, 32, 39–48. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhang, J.; Zong, W.; Hong, W.; Zhang, Z.T.; Wang, Y. Exploiting endogenous CRISPR-Cas system for multiplex genome editing in Clostridium tyrobutyricum and engineering the strain for high-level butanol production. Metab. Eng. 2018, 47, 49–59. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Sun, T.; Wu, T.; Li, J.; Hu, D.; Liu, D.; Li, J.; Tian, C. Consolidated bioprocessing for bioethanol production by metabolically engineered cellulolytic fungus Myceliophthora thermophila. Metab. Eng. 2023, 78, 192–199. [Google Scholar] [CrossRef] [Scilit]
- Zuroff, T.R.; Xiques, S.B.; Curtis, W.R. Consortia-mediated bioprocessing of cellulose to ethanol with a symbiotic Clostridium phytofermentans/yeast co-culture. Biotechnol. Biofuels 2013, 6, 1–12. [Google Scholar] [CrossRef] [Scilit]
- Jiang, Y.; Guo, D.; Lu, J.; Dürre, P.; Dong, W.; Yan, W.; Zhang, W.; Zhou, J.; Jiang, M.; Xin, F. Consolidated bioprocessing of butanol production from xylan by a thermophilic and butanologenic Thermoanaerobacterium sp. M5. Biotechnol. Biofuels 2018, 11, 89. [Google Scholar] [CrossRef] [Scilit]
- Li, Q.; Wu, M.; Wen, Z.; Jiang, Y.; Wang, X.; Zhao, Y.; Liu, J.; Jin, M.; Yang, S. Optimization of n-butanol synthesis in Lactobacillus brevis via the functional expression of thl, hbd, crt and ter. J. Ind. Microbiol. Biotechnol. 2020, 47, 1099–1108. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Lin, P.P.; Mi, L.; Morioka, A.H.; Yoshino, K.M.; Konishi, S.; Xu, S.C.; Papanek, B.A.; Riley, L.A.; Guss, A.M.; Liao, J.C. Consolidated bioprocessing of cellulose to isobutanol using Clostridium thermocellum. Metab. Eng. 2015, 31, 44–52. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Cao, G.; Zheng, J.; Fu, D.; Song, J.; Zhang, J.; Zhao, L.; Yang, Q. Developing a mesophilic co-culture for direct conversion of cellulose to butanol in consolidated bioprocess. Biotechnol. Biofuels 2015, 8, 84. [Google Scholar] [CrossRef] [Scilit]
- Wen, Z.; Minton, N.P.; Zhang, Y.; Li, Q.; Liu, J.; Jiang, Y.; Yang, S. Enhanced solvent production by metabolic engineering of a twin-clostridial consortium. Metab. Eng. 2017, 39, 38–48. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yu, E.K.C.; Chan, M.K.Y.; Saddler, J.N. Butanol production from cellulosic substrates by sequential co-culture of Clostridium thermocellum and C. acetobutylicum. Biotechnol. Lett. 1985, 7, 509–514. [Google Scholar] [CrossRef] [Scilit]
- Xin, F.X.; He, J.Z. Characterization of a thermostable xylanase from a newly isolated Kluyvera species and its application for biobutanol production. Bioresour. Technol. 2013, 135, 309–315. [Google Scholar] [CrossRef] [Scilit]
- Tri, C.L.; Kamei, I. Butanol production from cellulosic material by anaerobic co-culture of white-rot fungus Phlebia and bacterium Clostridium in consolidated bioprocessing. Bioresour. Technol. 2020, 305, 123065. [Google Scholar] [CrossRef] [Scilit]
- Kunze, G.; Hähnel, U. Production of butanol by fermentation in Arxula sp. European Patent No. EP 2508597, 10 October 2012. [Google Scholar]
- Svetlitchnyi, V.A.; Kensch, O.; Falkenhan, D.A.; Korseska, S.G.; Lippert, N.; Prinz, M.; Sassi, J.; Schickor, A.; Curvers, S. Single-step ethanol production from lignocellulose using novel extremely thermophilic bacteria. Biotechnol. Biofuels 2013, 6, 31. [Google Scholar] [CrossRef] [Scilit]
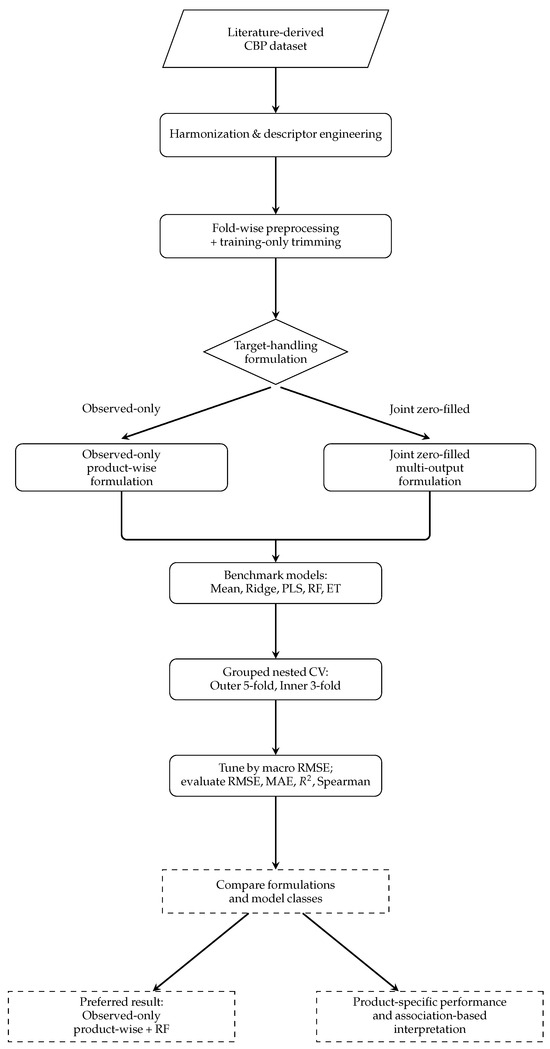
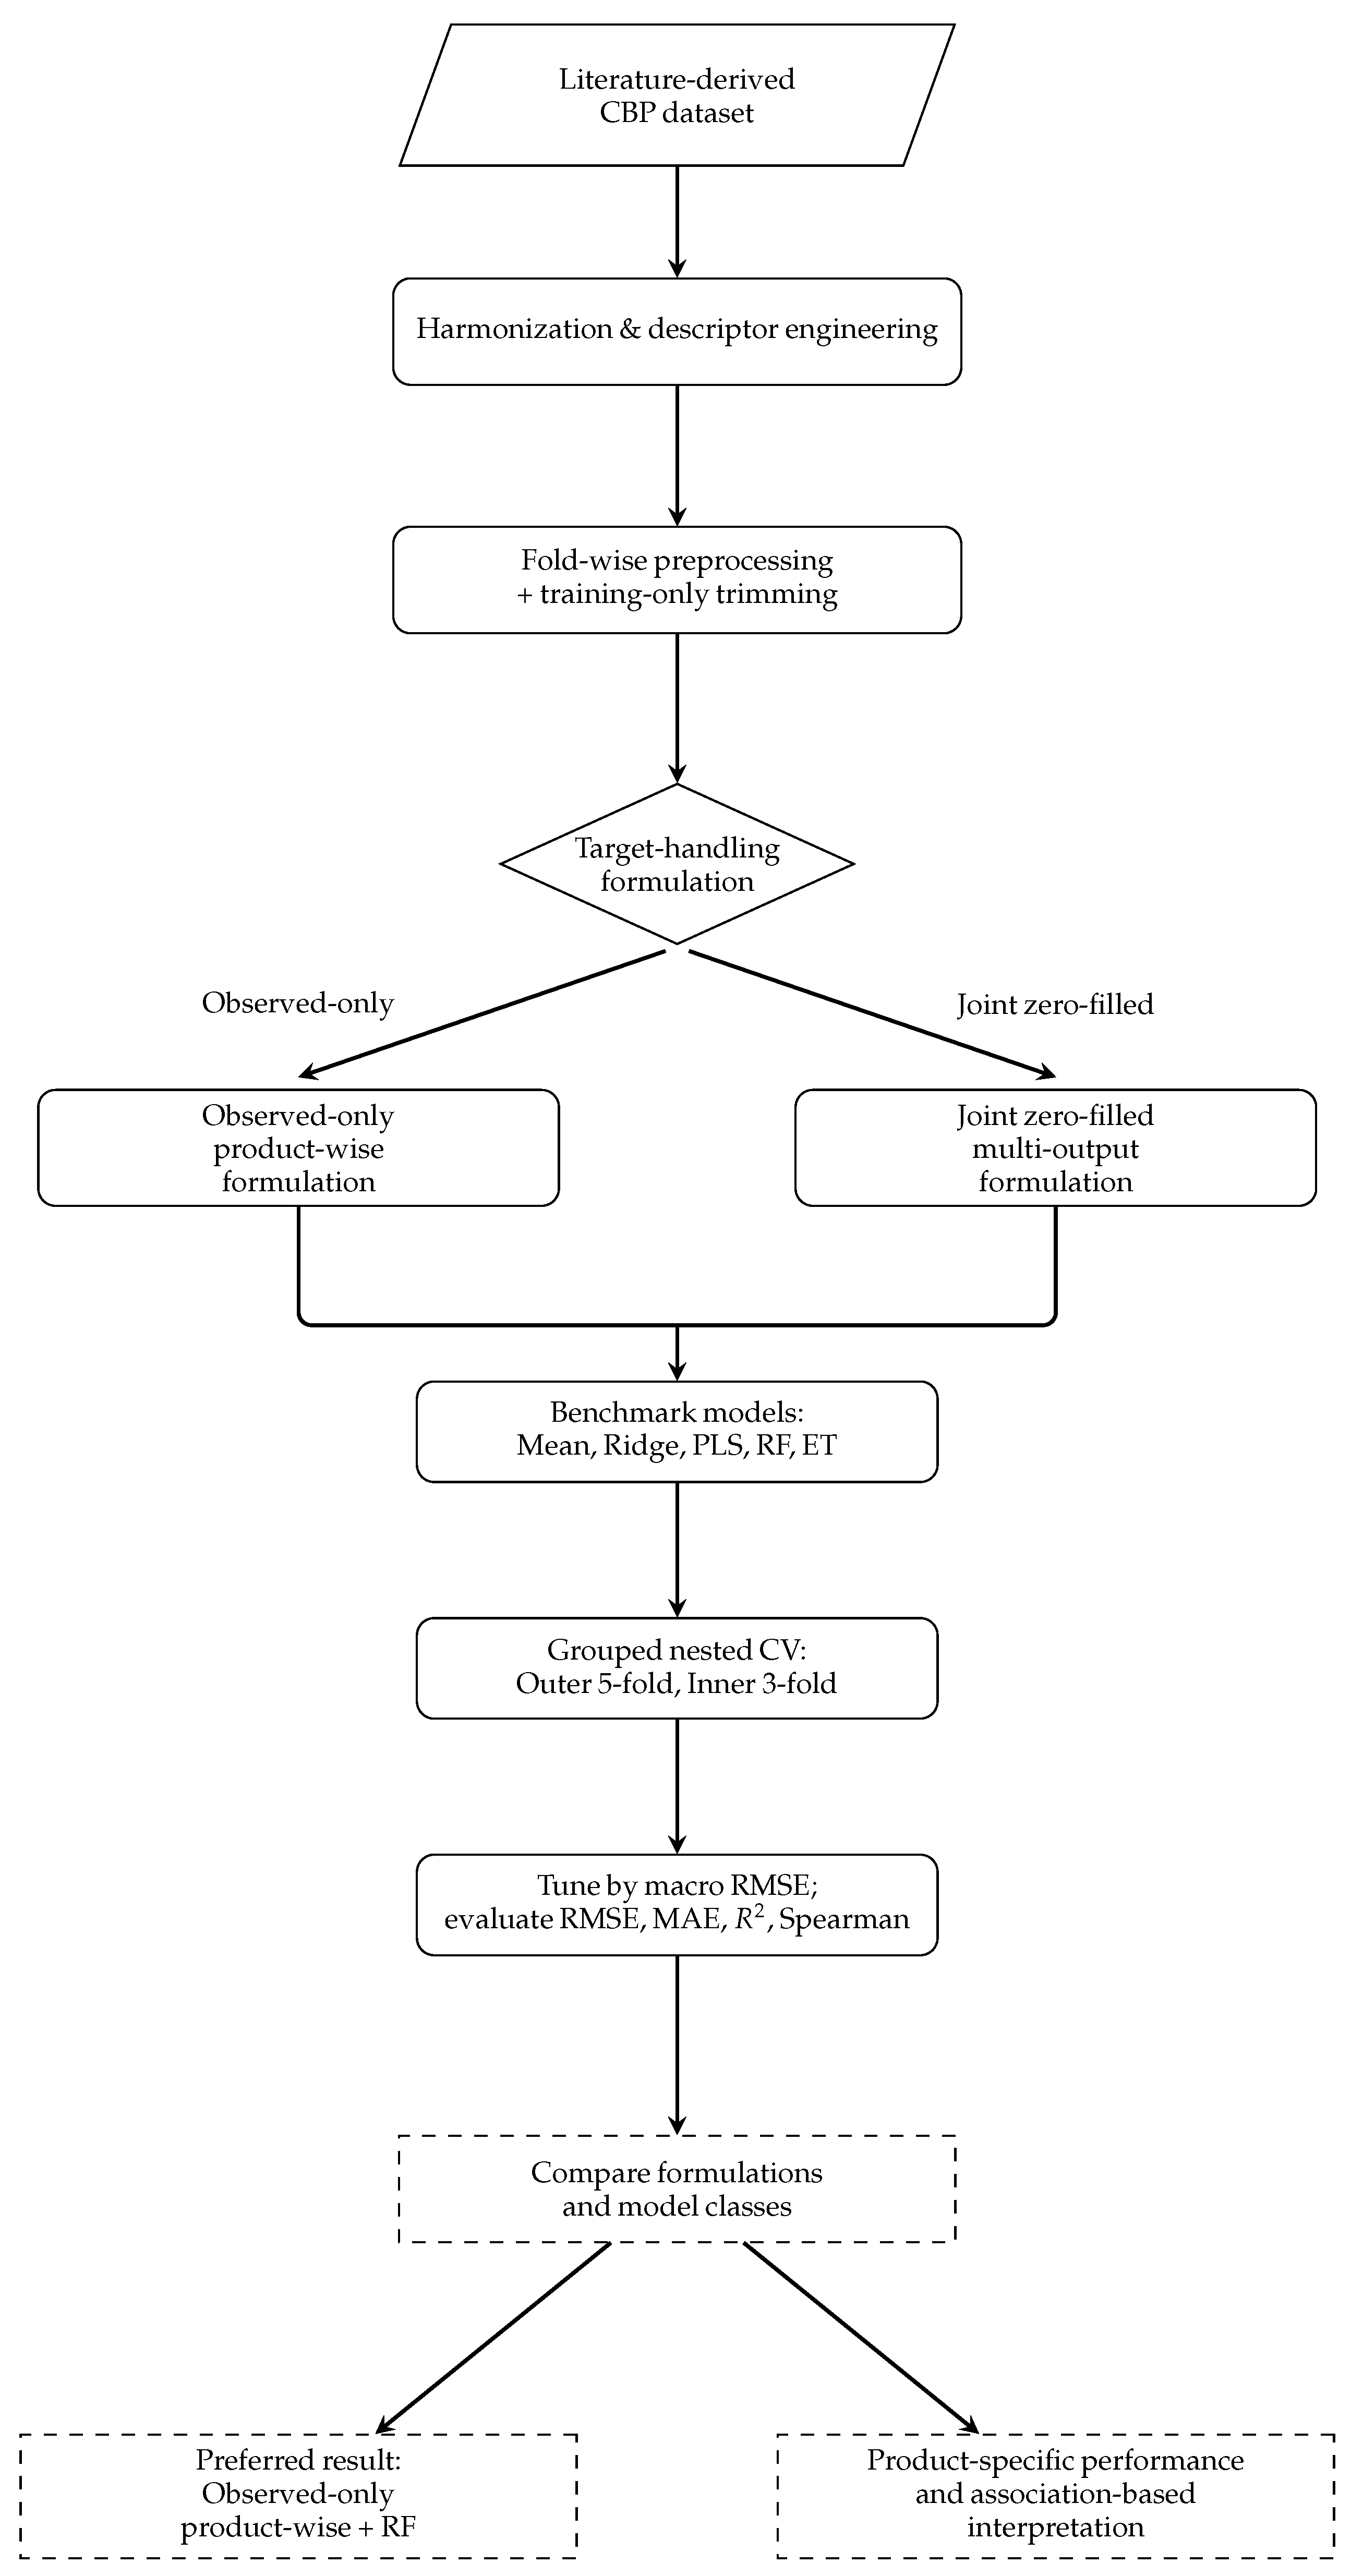
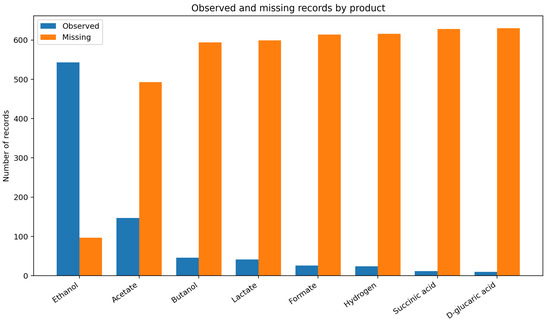
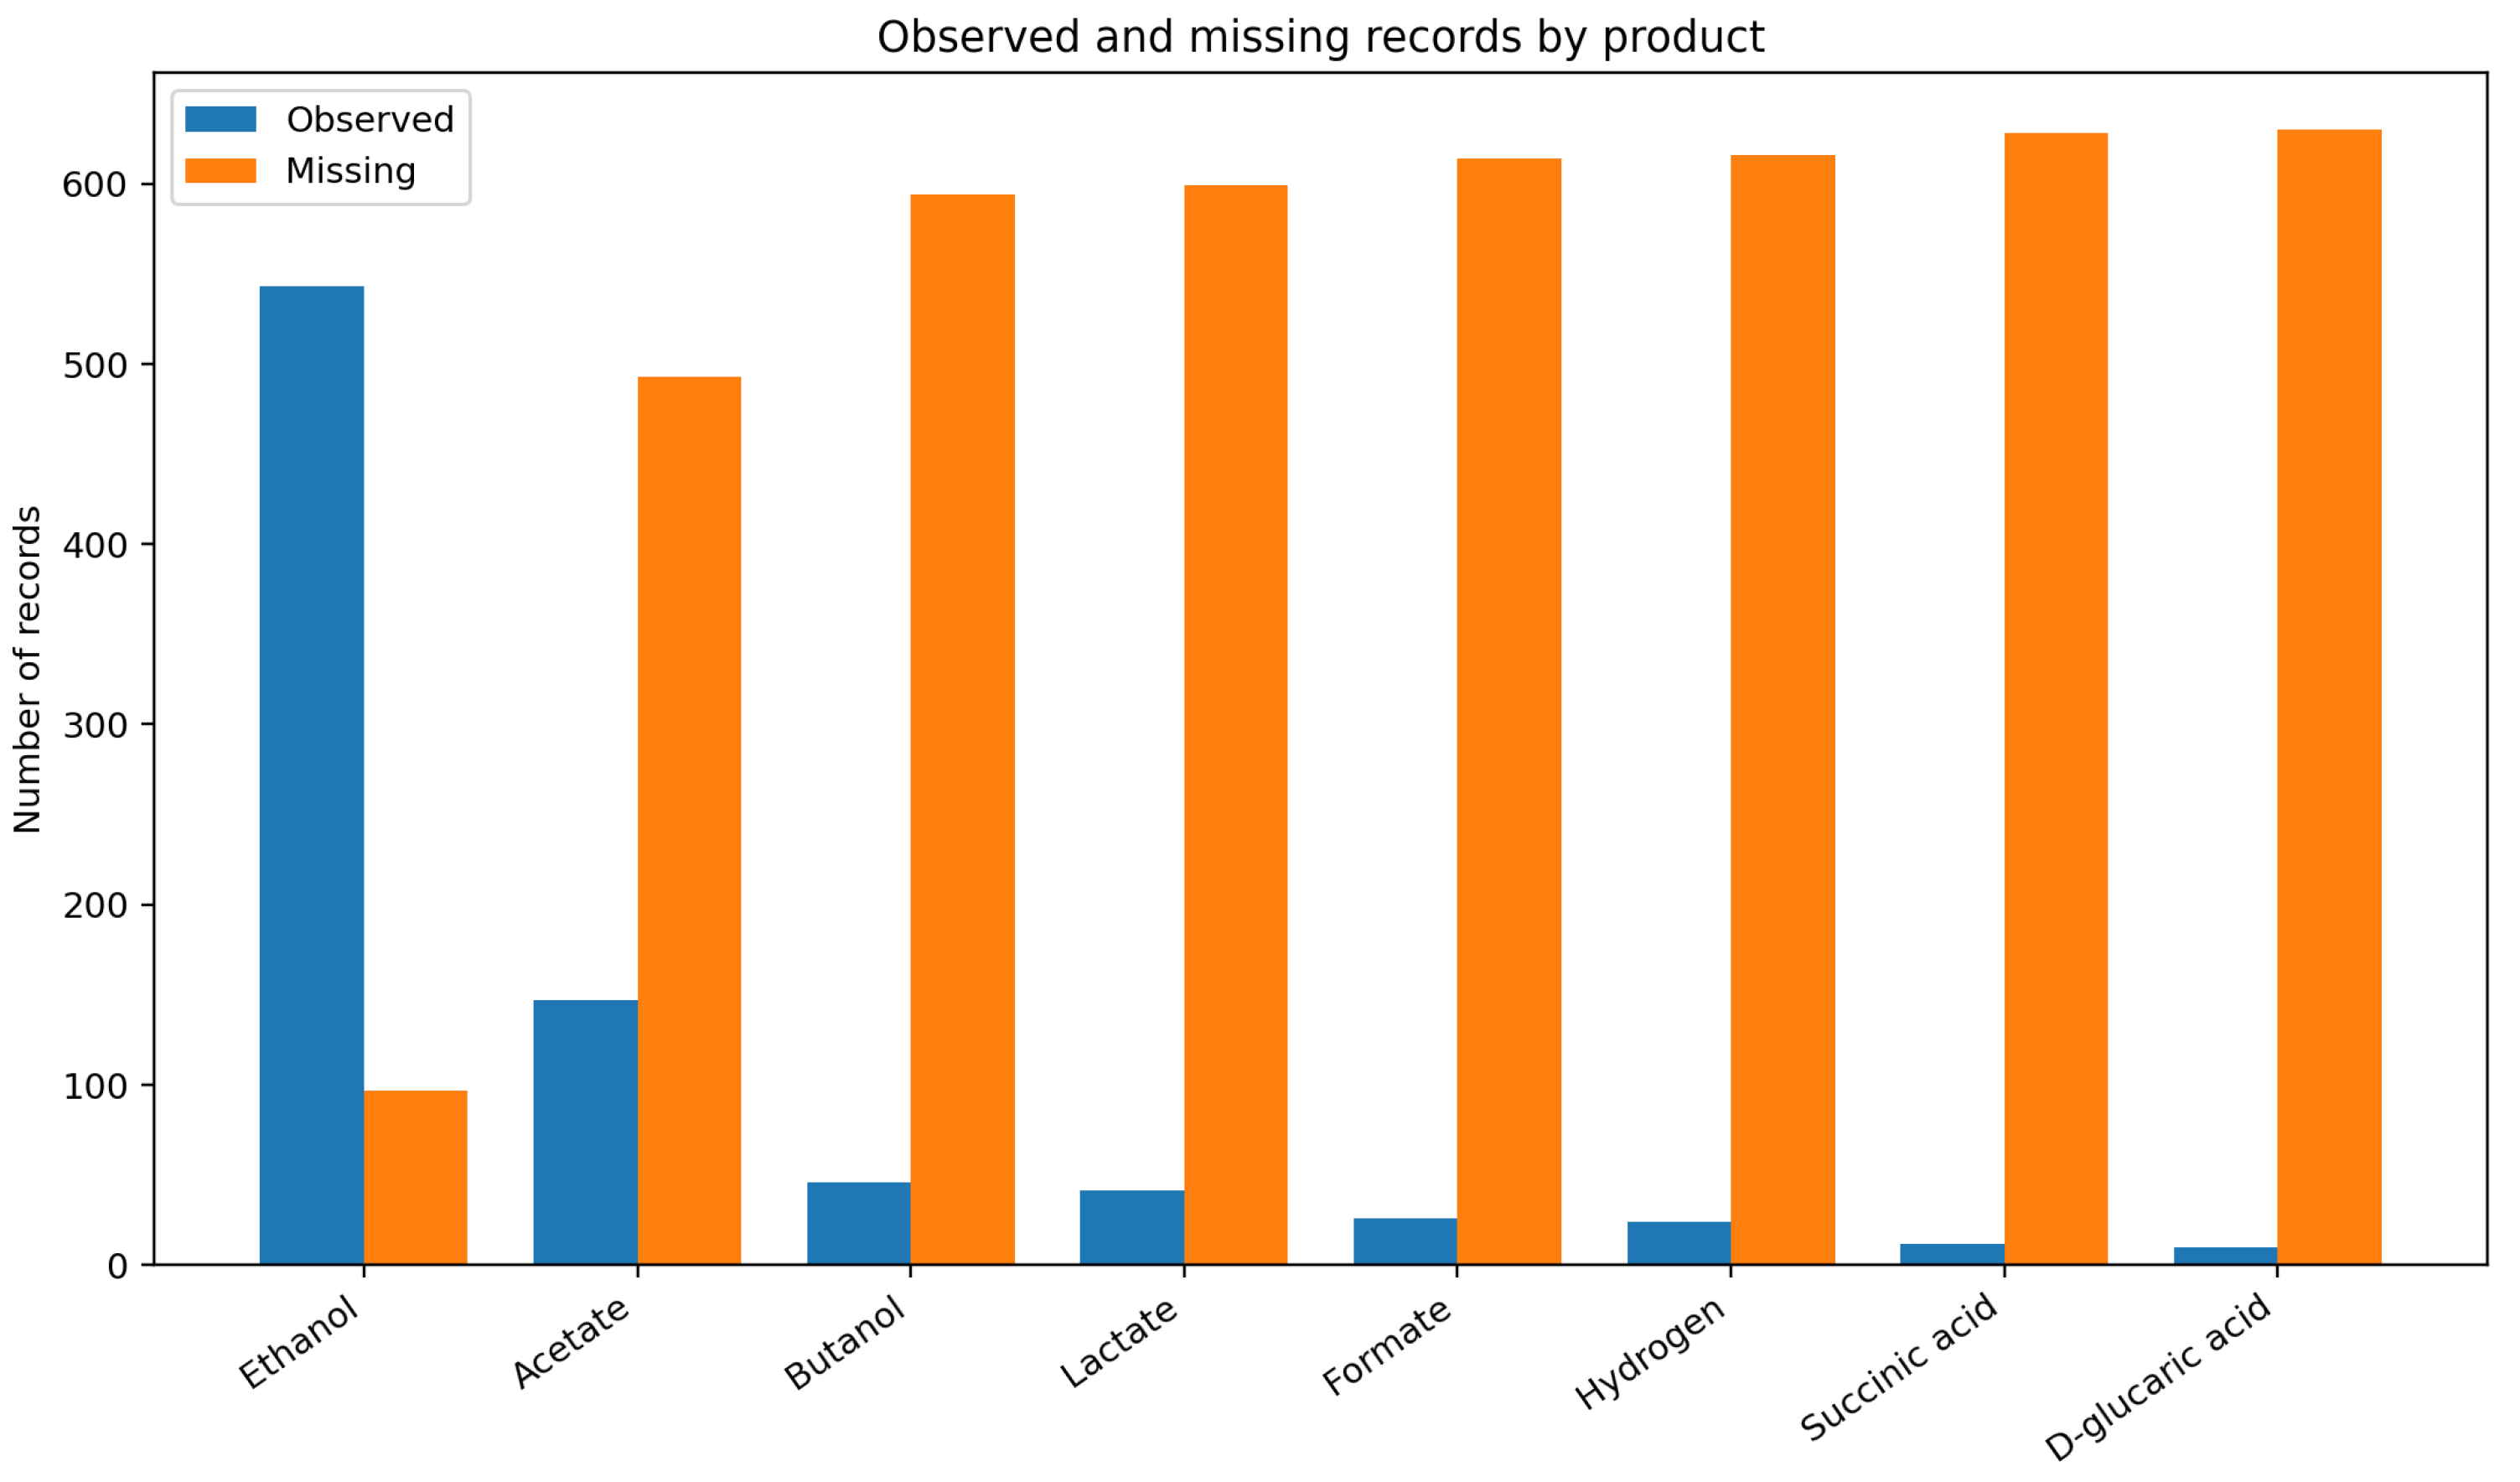
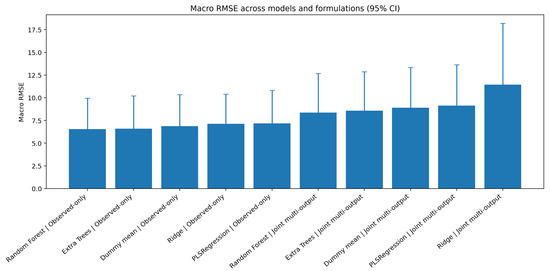
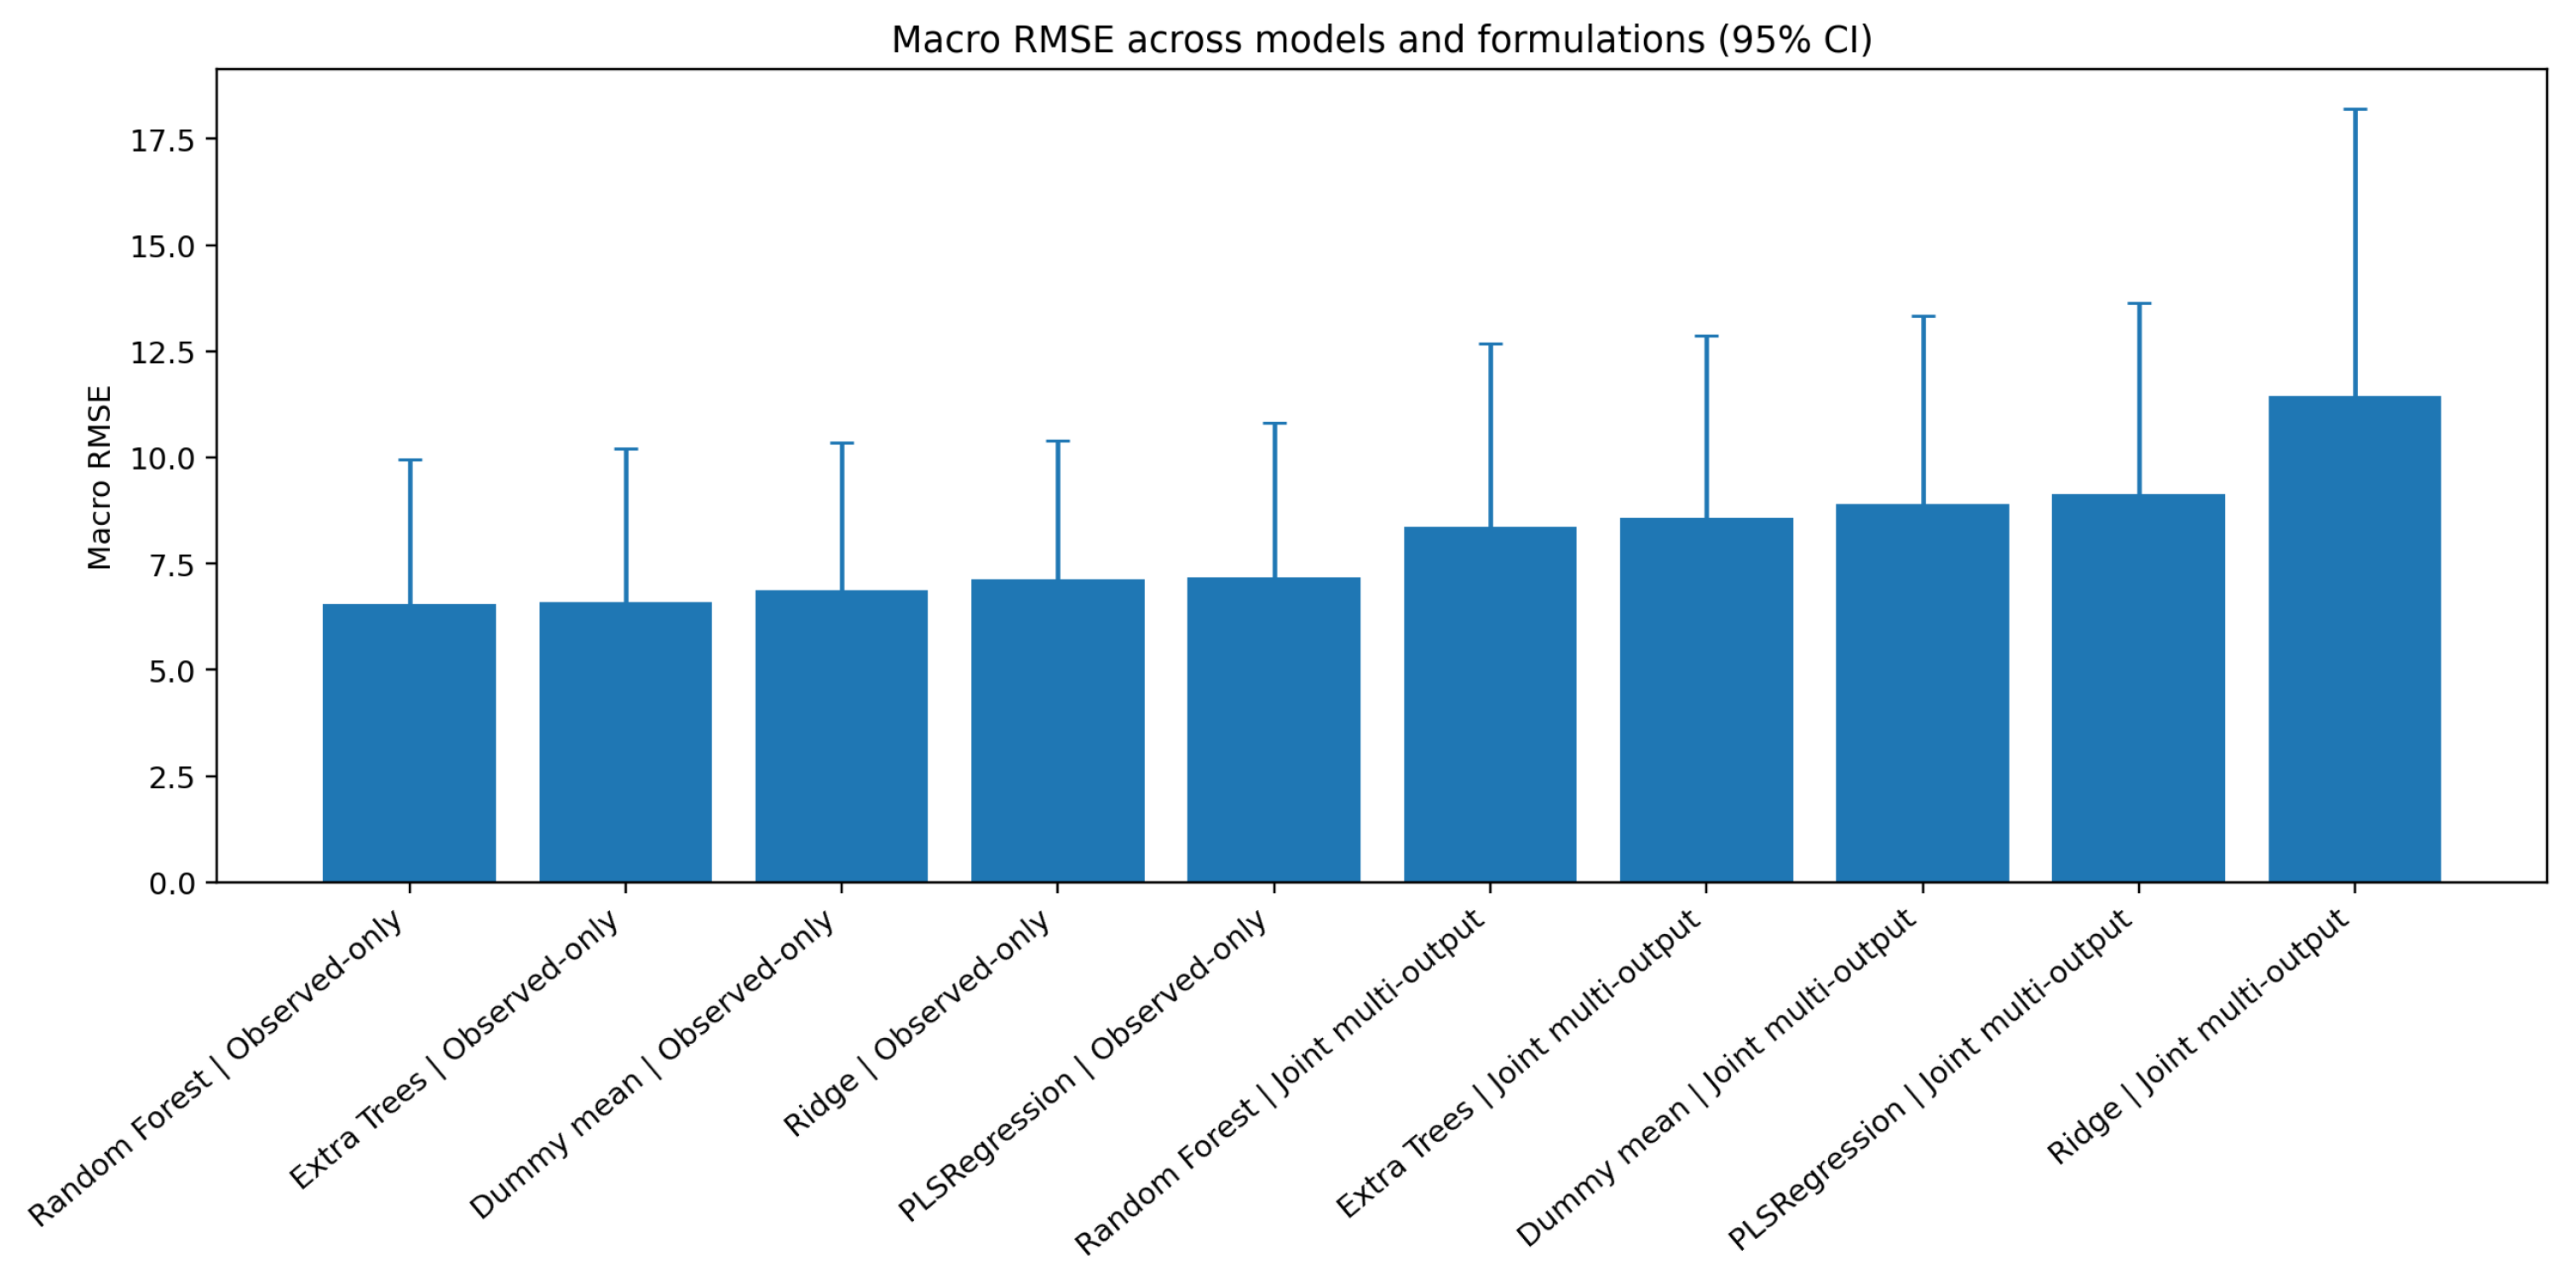
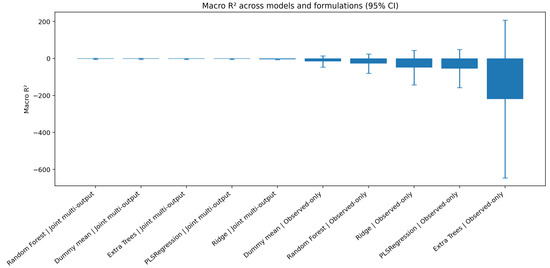
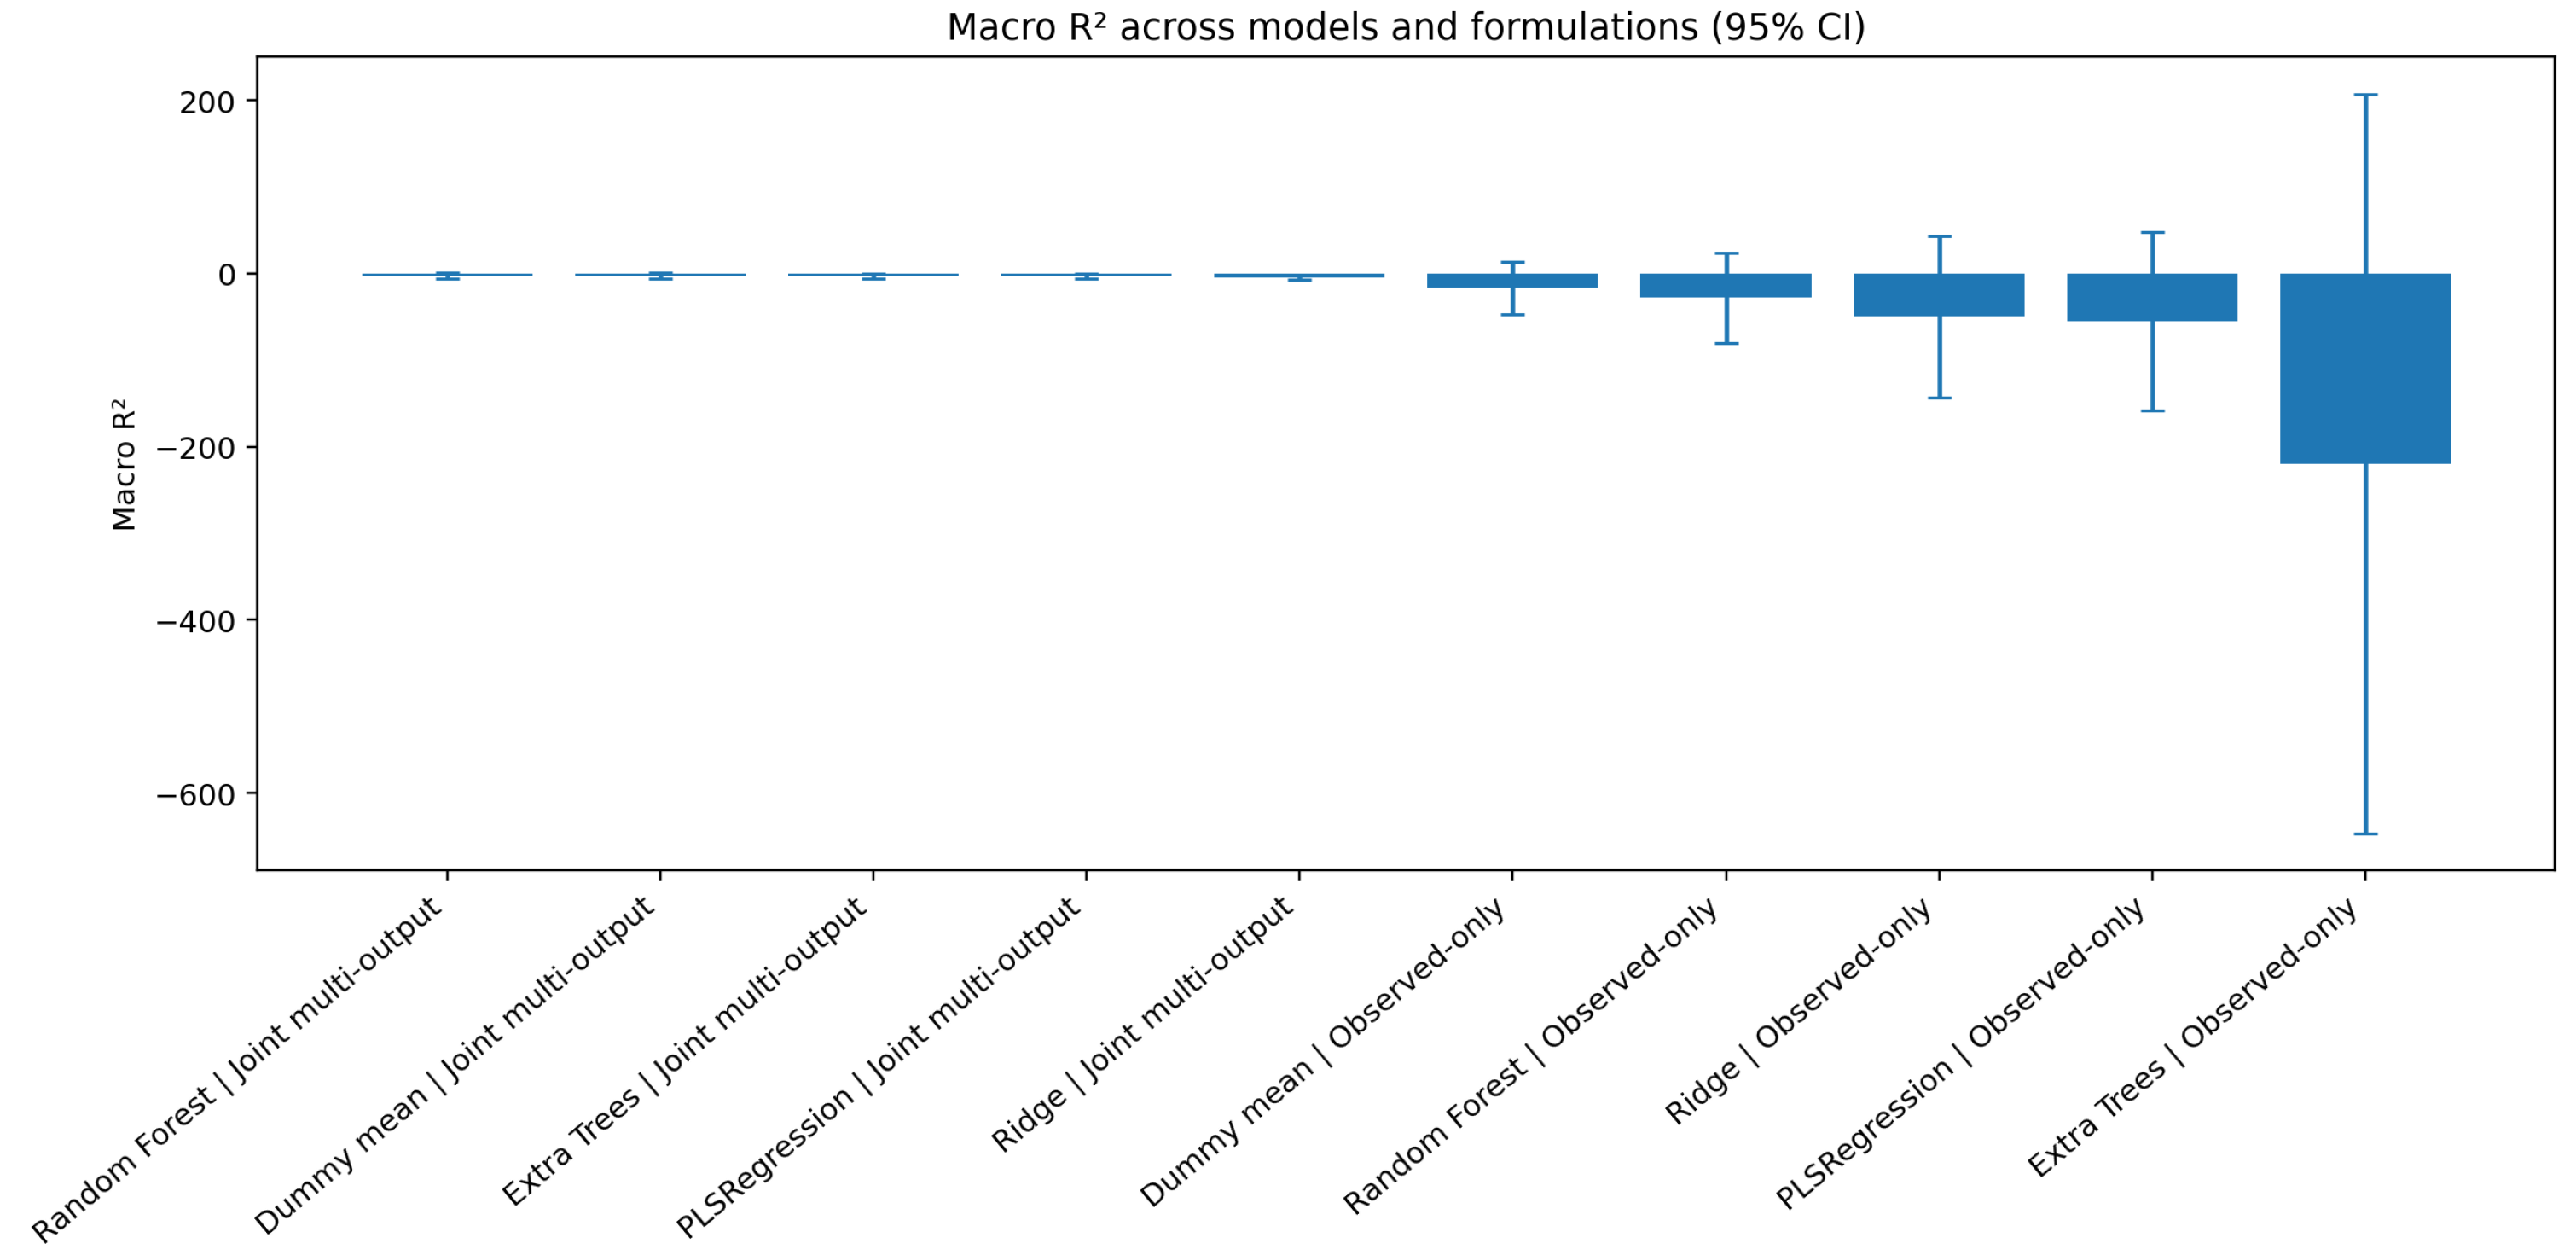
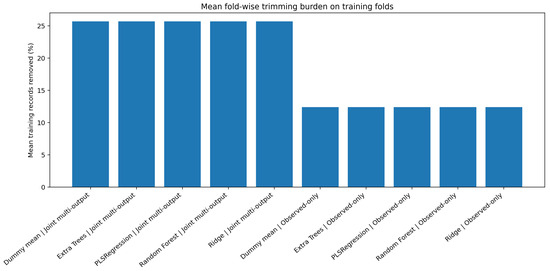
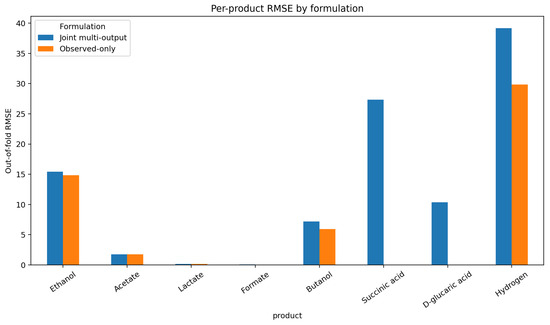
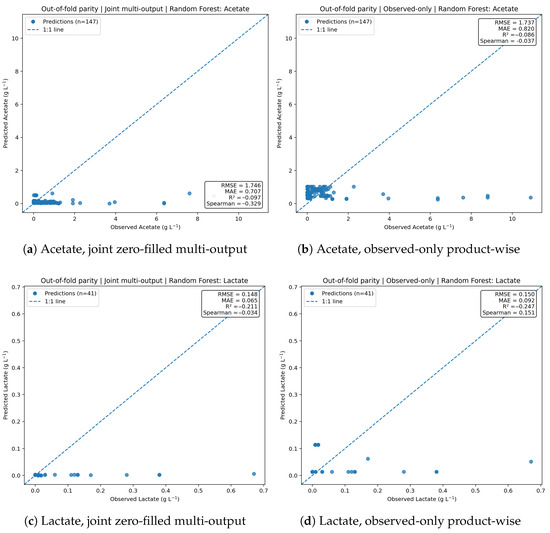
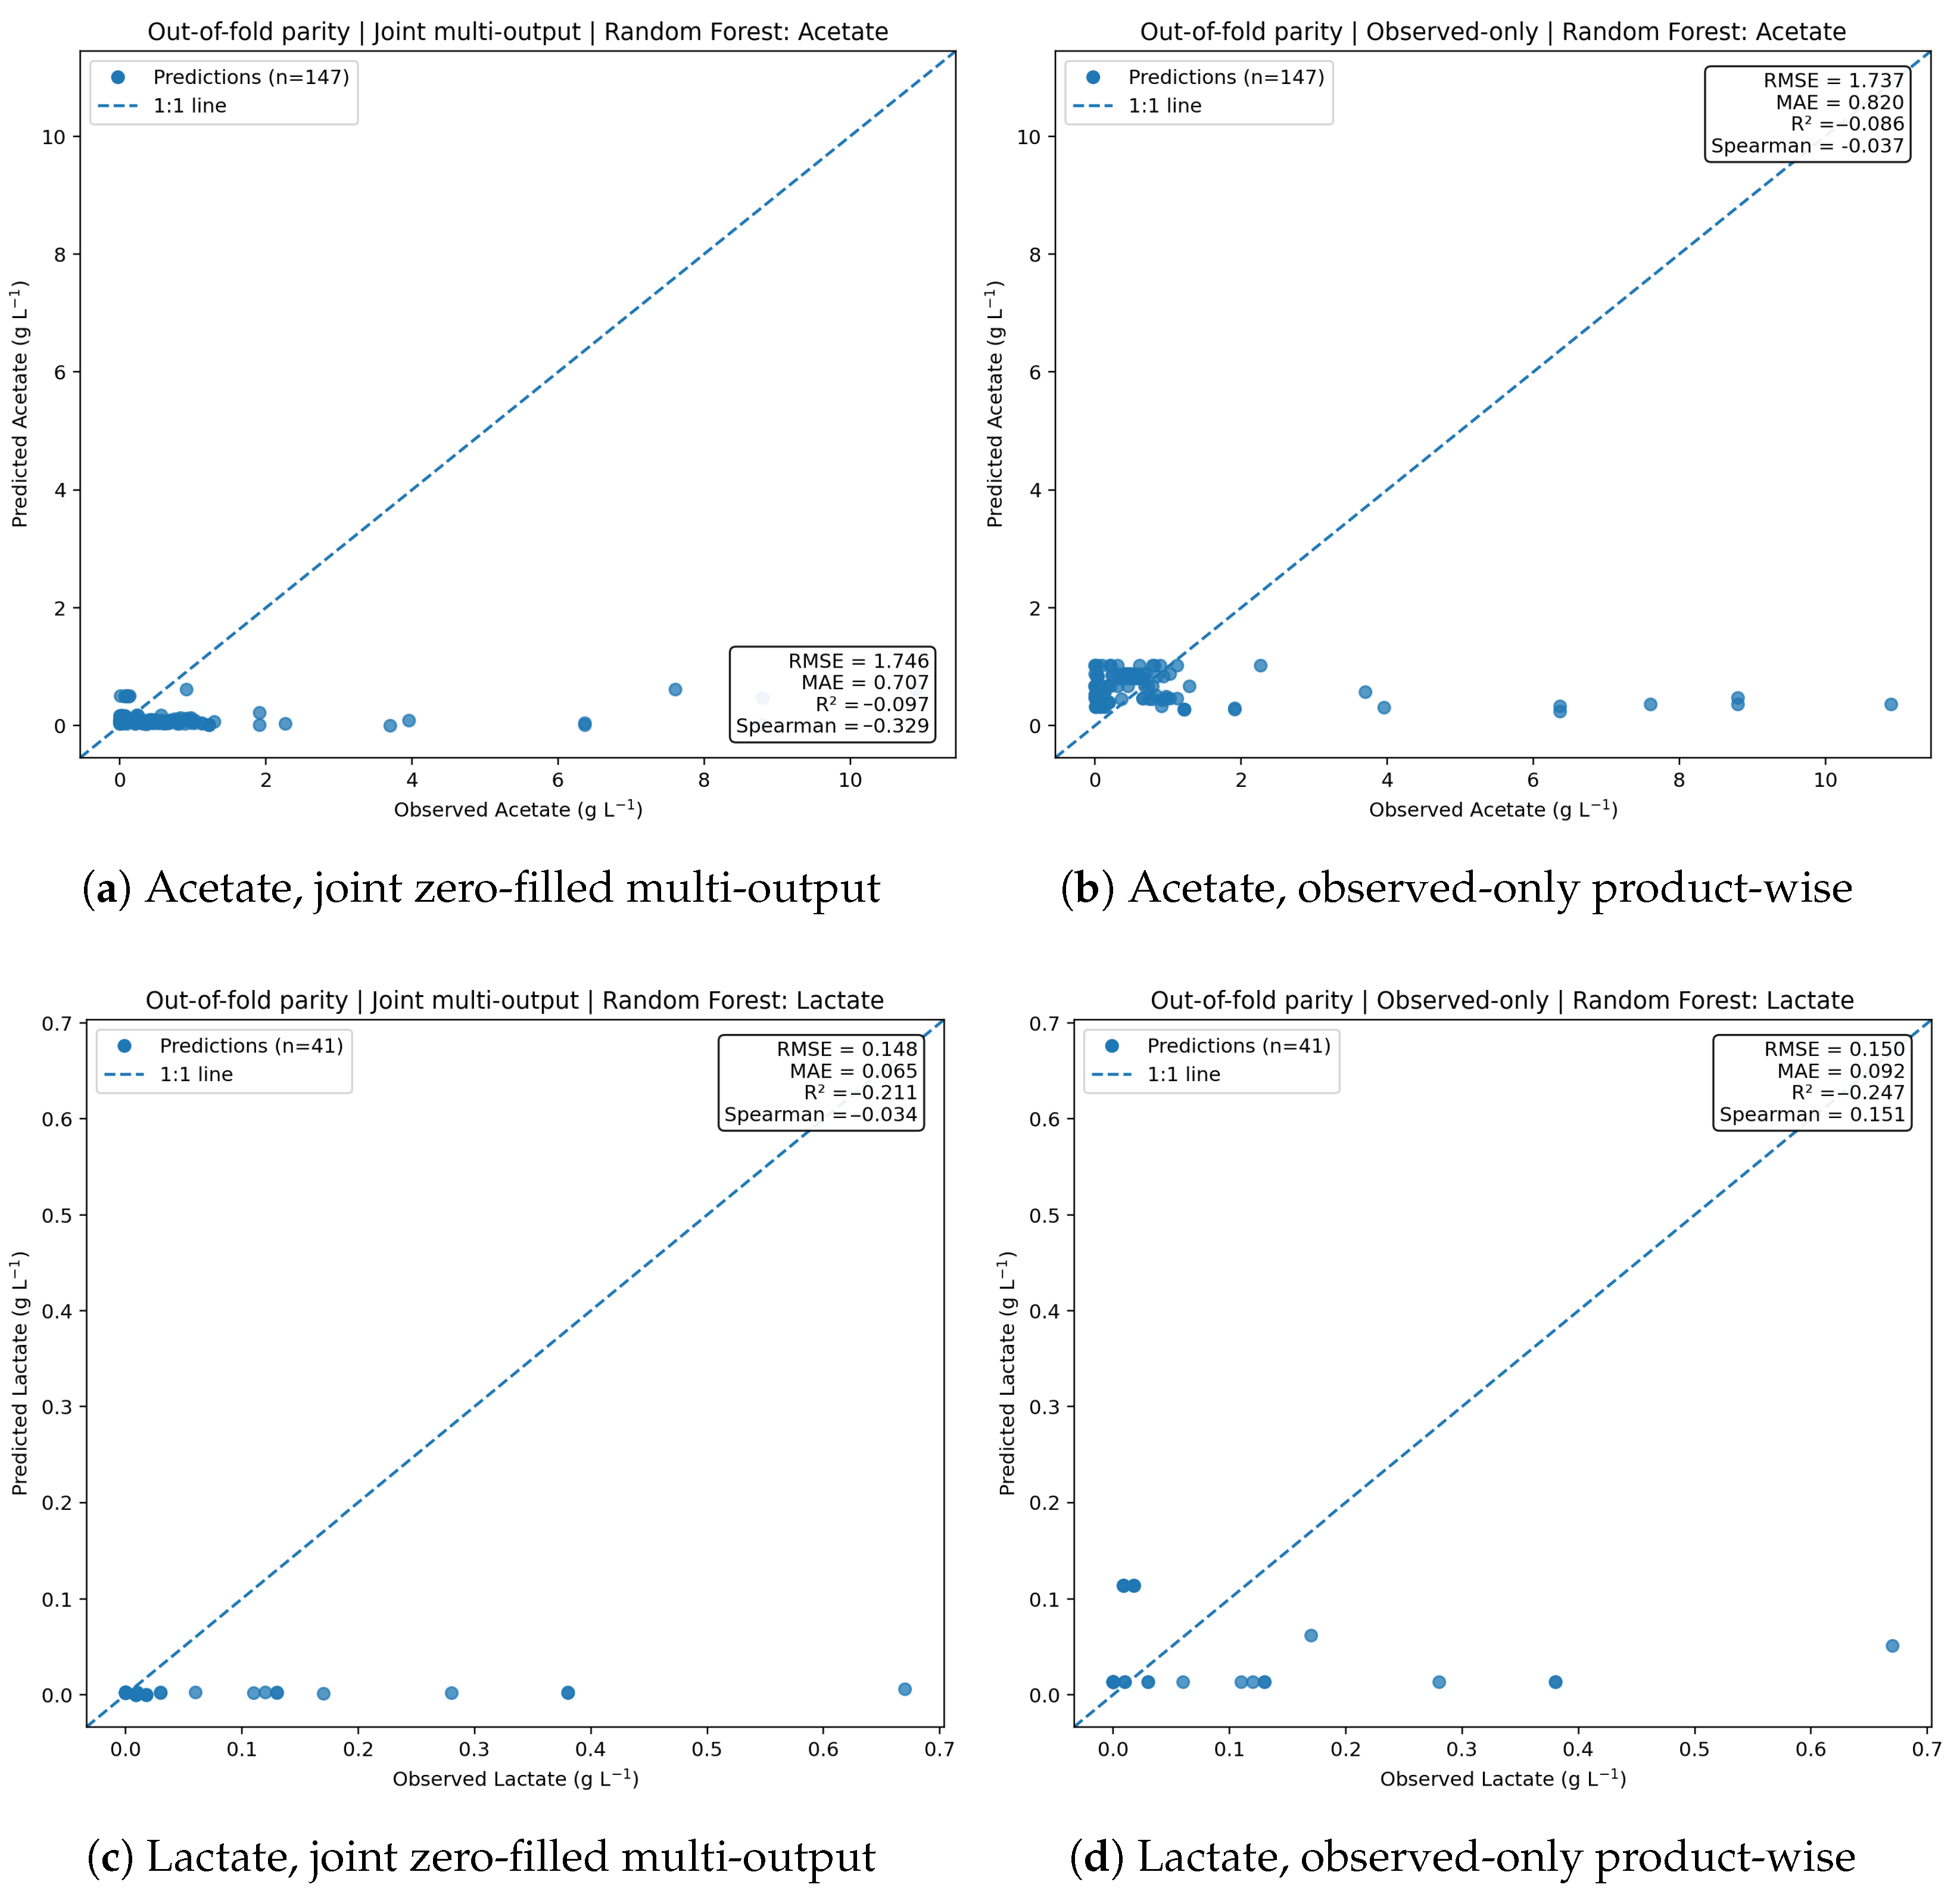
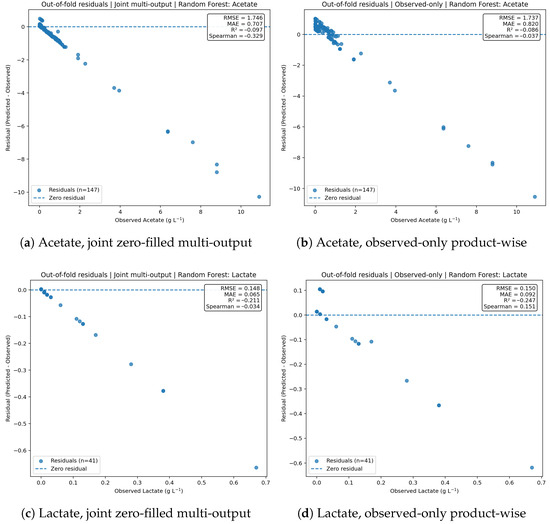
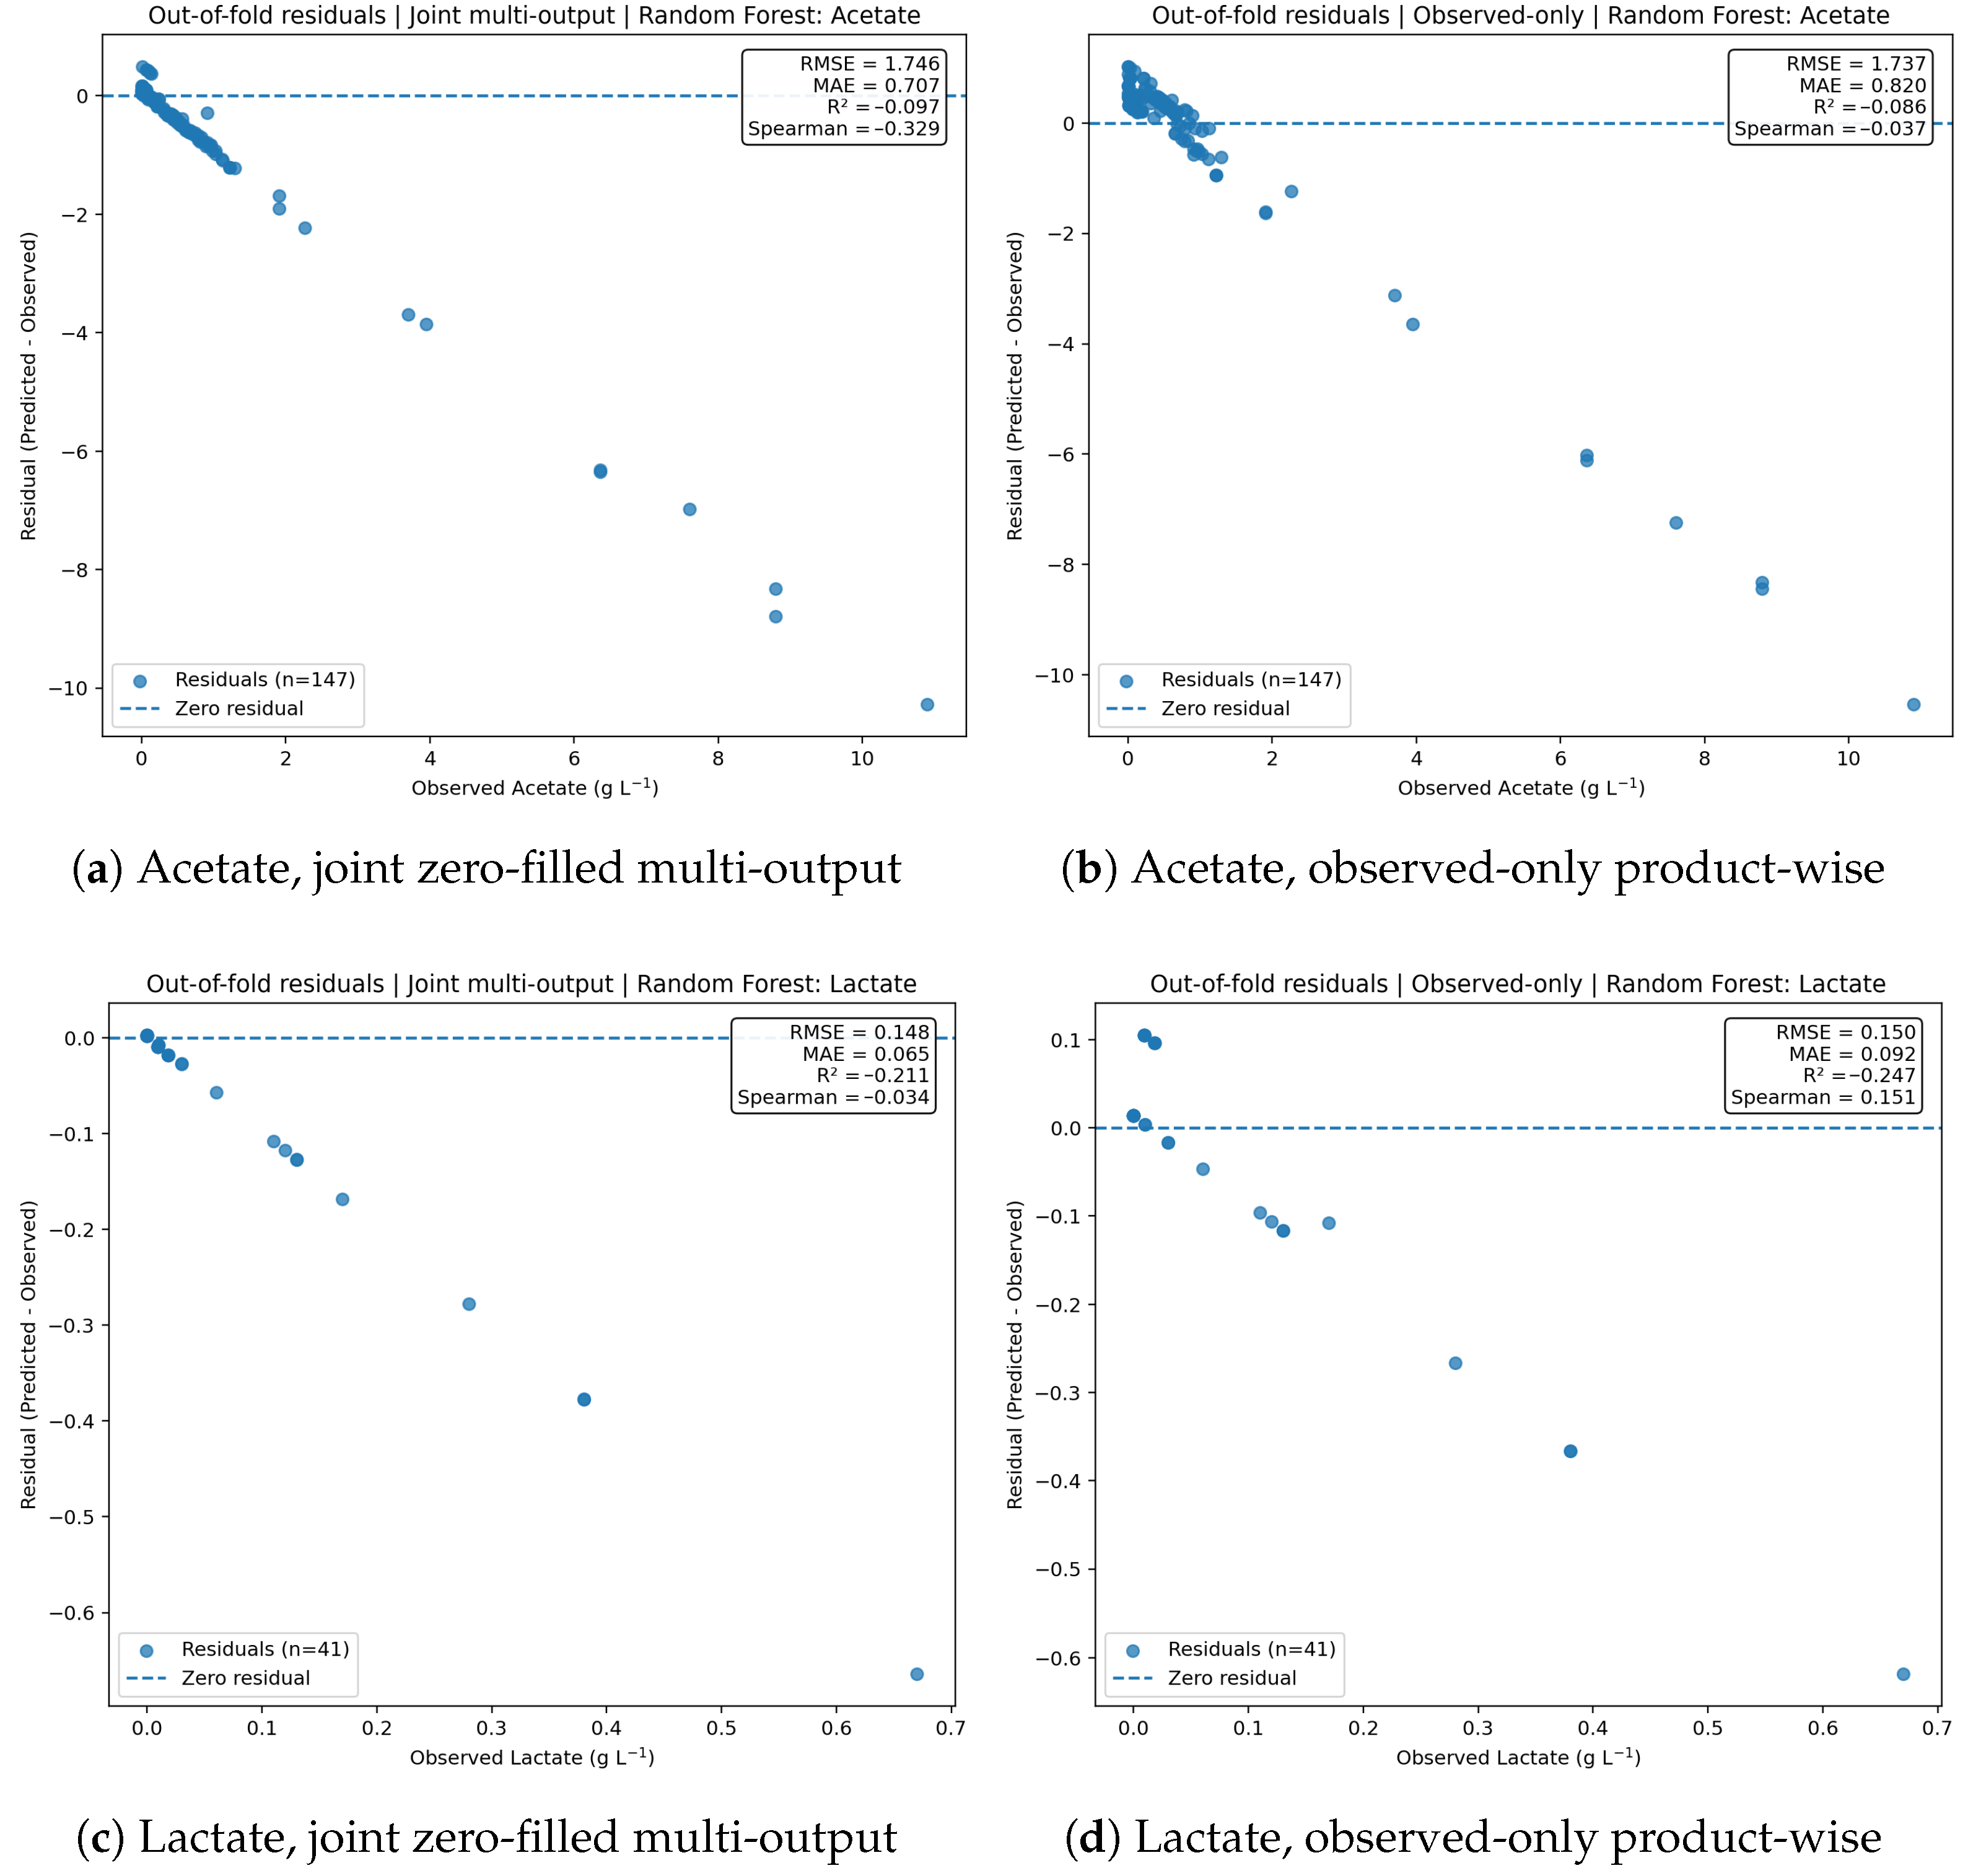

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.