


Abstract
Background: Researchers dealing with software engineering often express some concern about the lack of a core theory for this discipline. In fact, even the most basic concepts of software engineering—like the organization of software development life cycles—are usually described informally, with no reference to an underlying theory. Methods: In this paper, a well-known model for requirements and specifications is used as a basis for a rigorous and uniform description of software development activities. Results: The proposed approach proved suitable to describe the most popular software life cycles, as well as to describe the properties of software development activities. The proposed approach was also used to describe the properties of the software product in a way that is precise enough to support the definition of metrics. Conclusions: The proposed approach seems suitable for describing most software engineering issues and reasoning about them.
1. Introduction
When software life cycle models were first proposed, they had the great merit of contributing to the systematic organization of software development. However, the proposed models [1] were no more than “boxes-and-arrows” diagrams, whose meaning were explained only in terms of the experience that brought to the definition of such life cycles and phases. So, on the one hand, one could feel quite relieved to know that someone had devised methods to organize software development, an activity that could otherwise very easily turn into a rather cumbersome process; on the other hand, one was a bit disappointed by the lack of theoretical foundations and methodological guidance.
The rather naive approach to modeling and organizing the software development process was probably justified in the 1970s. Unfortunately, if you look into a modern software engineering textbook, you will still find boxes-and-arrows diagrams [2]. More precisely, you will find several different life cycle models, all described at the same informal level as the waterfall model described in 1970 [1].
In this paper, a notation to precisely describe software life cycles is proposed, with the aim of making reasoning about life cycles and their characteristics easier and more rigorous.
The proposed notation is based on the formula
which was proposed by Jackson [3]. In (1), R indicates the stakeholder’s requirements, i.e., “conditions over the phenomena of the environment that we wish to make true by installing the machine” while E expresses “conditions over the phenomena of the environment that we know to be true irrespective of the properties and behavior of the machine” [3]. S is the specification of the machine, expressed in terms of the phenomena that are shared by the environment and the machine. In practice, S is specified in terms of I/O elements: in Jackson’s terminology, phenomena controlled by the environment and visible to the machine—i.e., inputs—and phenomena controlled by the machine and visible to the environment—i.e., outputs.
Thus, Formula (1) is an entailment that reads: if the environment in which the machine is located behaves as specified in E and the machine behaves as specified in S, then the requirements described in R are satisfied. The logical entailment A ⊢ B states that by assuming A, we can prove B; hence, entailment is often called provability.
It is important to note that the level of formality of Formula (1) can vary. In fact, the formality of the formula depends on the formality of the descriptions E, S and R. It is possible to provide informal, text-based descriptions, as well as completely formal specifications, depending on the intended use of these descriptions. If E, R and S are described formally, it is possible to prove that the truth of R descends from the truth of E and S, while informal descriptions allow only for argumentations that the truth of R descends from the truth of E and S.
According to the ISO/IEC 12207 standard [4], a life cycle is the evolution of a system, product, service, project or other human-made entity from conception through retirement; a life cycle model is a framework of processes and activities concerned with the life cycle that may be organized into stages, which also acts as a common reference for communication and understanding.
Many different software life cycle models were proposed [5], including several models that implement agile processes. Life cycle models indicate what processes and activities are carried out through the life cycle—hence what roles and resources are used—and what relations exist among processes and activities, in terms of coordination (precedence, parallelism, …) and shared artifacts. In general, life cycle models are quite abstract; they describe processes and activities like black boxes. It is specified what is done and what artifacts are used and produced. For the sake of generalizability, life cycle models do not prescribe how (i.e., with what methods, techniques and tools) activities are carried out.
According to [4], life cycle models are useful for communication and understanding. Actually, they are useful for many purposes. From a management point of view, life cycle models provide a framework for estimating development cost and duration, for control (thanks to the possibility of associating milestones to the completion of stages, the release of artifacts, etc.), for staffing (according to the roles required by life cycle activities), etc. From a technical point of view, life cycle models provide a framework for technical decisions, like choosing the techniques and tools to be used in specific activities or the languages and notations to be used for describing artifacts that are shared among multiple activities. Life cycle models also provide a model for reasoning about the organization of software development and the optimization of the development process.
Several life cycle models were proposed, both to improve software development and to cope with the needs of different software projects, which can call for different life cycle stages, differently organized and differently scheduled and coordinated. Unfortunately, life cycle models are still described (and taught) via boxes-and-arrows diagrams, whose semantics is generally not well defined.
In this paper, we propose a methodological framework for the precise definition of software life cycles, software artifacts and development activities in general. The methodology is based on the extensive use of Formula (1) and similar entailments concerning various software artifacts.
As software life cycles can be considered the basis for software engineering, the ability to describe them precisely—even formally, if required—by means of a single simple formula looks like a necessary—though possibly not sufficient—condition for establishing a “core theory” of software engineering.
Besides modeling life cycles, the proposed approach applies to multiple aspects of software engineering, as demonstrated throughout the paper. Among these are (i) reasoning about life cycles’ activities, (ii) reasoning about software artifacts and their characteristics, (iii) supporting software project management activities, and (iv) describing software properties and defining measures. In this respect, this paper extends the usage of entailment (1) well beyond the usage made by Jackson, who never used the formula to describe life cycles or address the issued treated in Section 8, Section 9, Section 10 and Section 11.
The paper is organized as follows. Section 2 discusses previous work concerning software life cycle modeling. Section 3 provides some additional remarks concerning the basic entailment () used throughout the paper. Section 4 shows how Formula (1) can be used to model the waterfall life cycle, while Section 5, Section 6 and Section 7 show how the formula can be used to model other popular life cycles, namely the prototype, incremental and agile processes. Section 8 illustrates, via examples, the expressive power of the proposed notation and its ability to support reasoning about software artifacts and their characteristics. Section 9 shows that the proposed notation can be used also to deal with management issues. Section 10 shows how to detail the description of individual software development activities. Section 11 describes the properties of the software product in a way that is precise enough to support the definition of metrics. Section 12 provides some considerations concerning the usage of the proposed methodology in practice. Section 13 discusses the limitations of the proposed framework. Finally, Section 14 draws some conclusions.
2. Background and Related Work
In most software engineering books, the waterfall life cycle is represented via a “boxes-and-arrows”notation, as shown in Figure 1 (sometimes without the backwards arrows).
Figure 1.
The traditional representation of the waterfall life cycle.
The explanations of the development phases are not very precise either. For instance, requirements analysis and definition can be described as follows: “The system’s services, constraints, and goals are established by consultation with system users. They are then defined in detail and serve as a system specification.” [2].
Other authoritative sources, such as the ISO standard concerning software life cycle processes [4] or the Guide to the Software Engineering Body of Knowledge [6], provide similar definitions.
Although software engineering concepts and practices are still generally described informally and without the help of an underlying theory, some awareness of the need for software theories seems to exist.
Hall and Rapanotti suggested that a simple elegant formula can possibly relate the most important concepts in software engineering [7].
Johnson et al. expressed some concern about the lack of a core theory for software engineering [8]. They suggest that many theories exist, but none proved to be comprehensive or sound or effective enough to win the consensus of the whole software engineering community.
SEMAT (Software Engineering Methods and Theory) started an ambitious initiative for a general theory of software engineering. It resulted in the definition of the “SEMAT kernel of essential elements that are universal to all software development efforts, and a simple language to describing methods and practices.” [9]. SEMAT adopts an approach that is quite different form the one presented here. According to Jacobson, “Essence is just what is common for all [software development] methods – it is a common ground. It includes things that every method has” [10]. As a consequence, it is oriented to modeling and guiding practical development aspects, like teamwork, project organization and management, etc. Specifically, requirements are an “alpha,” characterized by states form “conceived” to “fulfilled” (state progressions help determining which factors are most important at a particular point of development [11]). The framework proposed in this paper is situated at a higher level: for instance, requirements do not have a state attribute; instead, they have a role in one or more entailments. The actual state of requirements is determined by the existence of other artifacts: e.g., if holds, requirements R have been fulfilled. Accordingly, SEMAT is not directly comparable with the proposed framework; instead, it can be considered a complementary instrument.
To summarize, the proposed framework shares by construction the foundations layed by Jackson [3], but deals with a much wider set of activities and concepts that Jackson did. With respect to SEMAT, instead of trying to make sense and order existing concepts and methods into a sort of taxonomy, the proposed framework offers higher-level expressive means that can be used—at least in principle and to extent show in this paper—to represent multiple life cycle models, relationships among activities and artifacts, and software properties. However, the proposed framework supports the usage of several notations when it comes to provide lower-level descriptions (see for instance Section 12.1). To this end, one can consider using the SEMAT kernel language [12], as well as BPMN [13], or SysML2 [14].
In this paper, a well-known model for requirements and specifications is used as a basis for rigorously and uniformly describing software development activities, as well as for supporting reasoning about most software engineering issues.
3. More on Formula
This section provides some additional remarks concerning the basic entailment () used throughout the paper.
3.1. Basics
In the entailment , the combination of E and S satisfies R, i.e., it makes all the assertions in R true (see also Appendix A). This means that E and S interact in a way that makes the behavior of the E&S system different from the behavior of E alone, and compliant with R. S is a specification, i.e., a description of a condition over the shared phenomena at the interface between the machine and the environment: as such, it does not explain the mechanisms through which the described behavior of S is obtained.
For instance, let us consider the following case. E describes a room and its characteristics (volume, insulation, etc.). E also describes how the temperature in the room varies, depending on multiple factors that can result in injecting heat in the room or draining heat from it. The room is equipped with a heating system and a thermometer: the characteristics of both these devices are properly described in E. According to the description, the temperature in the room can reach as low as −8 °C.
R states that the temperature in the room must never be less than 19 °C, with at most one degree of tolerance for no longer than 5 min.
S is the description of a system that, based on data received from the thermometer, switches the heating system on or off. S specifies the criteria that govern the decision to switch the heating system on or off. For instance, the criteria could be expressed as follows:
Note that, following Jackson [15], temp is a phenomenon controlled by the environment and visible to the specified machine, while switchOn and switchOff are phenomena controlled by the machine and visible to the environment.
Based on the characteristics of the room and the heating system given in E, it must be possible to prove that the behavior of the combination of E and S satisfies R, i.e., makes the statements in R true.
S is a description of a black box that receives some inputs (temp) and generates some outputs (switchOn and switchOff) according to some well-defined relationships. To make the system work in practice, specifications S have to be implemented. It is noticeable that we do not always need a computer for this purpose: e.g., a person in the room could read the thermometer and operate the heating system exactly as specified.
In general, we are interested into a computer-based solution. In this case, the solution is usually given by a programmable platform M whose behavior is customized via a program P. The HW/SW system encompassing M and P receives the same inputs as S and produces the same outputs as S. From the point of view of the environment (the room), it is impossible to say if requirements R are satisfied via a person or via a HW/SW system, as long as both behave as specified by S. Similarly, different HW/SW systems can implement the same specification.
For a HW/SW system M&P to be a proper implementation of S, it must be possible to substitute S by M&P in the entailment, thus obtaining , while preserving the satisfaction of R. That is, if a “to be” solution interacting with E and behaving as specified in S satisfying R—which is also the actual solution consisting of the HW/SW system—M&P must interact with E as specified in S and cause the behavior of the system encompassing E, M and P to satisfy R.
Concerning the interface between E and M&P, we can observe that, in general, M&P is built according to the specifications S. Hence, it has, by design, the same input and output as S and interfaces with the environment exactly as S. However, it is possible that after having defined S, we discover that a M&P system compatible with S already exists. This is the case when M&PP is able to do “more” than specified in S. For instance, M&P can use more inputs than available or can produce more output than expected. If the additional outputs can be simply ignored and the additional input are not needed to achieve the specified behaviour, then M&P can replace S in the entailment. An example of this situation is given by the typical software “productivity” tools: if you need an instrument to create text files, you will probably choose an existing tool that is able to do much more than described in your specifications. E.g., you will never supply the tool with a text written in a language that you do not know and use; similarly, you will receive (and ignore) several non-requested and non-needed outputs. Nonetheless, your requirements will be fully satisfied.
Additional information about the entailment and the notation used throughout the paper is available in Appendix A.
3.2. Modifying the Environment
With respect to [3], it is worth noting that to obtain the desired effects R, part of the environment E has to interact with the machine S: for instance, someone (or something) has to feed input data to the machine, and someone (or something) has to use the outputs. To this end, Formula (1) can be rewritten as
where is the part of the environment that is given and that we cannot change (at least, not as part of software development activities), while indicates the part of the environment whose behavior can be designed to comply with our objectives. For instance, could be laws, business rules, the market, corporate policies, etc. could be the behavior of the personnel who has to interact with the machine: they can be instructed to operate in a suitable way. By distinguishing from , we make explicit that both and S contribute to solving the problem of achieving R in E.
Descriptions , , S and R can be classified—coherently with the view suggested by Jackson [3,16]—as follows:
- The description of is indicative. Its properties are given and cannot be changed.
- The description of R is optative. It represents the users’ goals, which can be negotiated and possibly changed; the constraint is that the final formulation of R represents a satisfactory solution of users’ problems.
- The descriptions of and S are designed. We can decide the behavior of the machine and of the part of environment we control.
As an example, let us consider the case described in Section 3.1 above. describes precisely (possibly formally) the room and the physical laws that determine the temperature in the room. R describes precisely (possibly formally) how the temperature in the room has to be constrained. describes precisely (possibly formally) the modifications of the environment that can support the satisfaction of the requirements. For instance, if the room described by is not equipped with a heating system and a thermometer, will describe these devices, which are introduced in the environment to make the requirements satisfiable.
For simplicity, for the remainder of this paper, Formula (1) is used instead of Formula (2), intending that .
To show that Formula (1) can be used to define precisely the most fundamental concepts of software engineering, a few among the most popular software life cycles and related development activities are modeled in this paper.
In this paper, we do not go into detail about how to write E, R and S, and how to show that . The interested reader can find guidelines and examples in the literature [17].
4. Waterfall Life Cycle
A widely acknowledged merit of the waterfall model [1,18] is that it highlights the phases of development and the artifacts that are produced within each phase. Accordingly, we expect that Formula (1) can be used to precisely describe phases and artifacts, as well as the relationships that link phases and artifacts.
The waterfall life cycle has many shortcomings [19]; this paper does not intend to endorse this life cycle, but only to show that it can be properly described by means of Formula (1) and related entailments.
4.1. Requirements Analysis and Specification
In (1), R is the artifact that specifies users’ requirements and E is the artifact that describes the properties of the part of the environment that is relevant to the problem: having specified E and R, we are in a situation that could be described as
In (3), the presence of the question mark makes explicit that this is a problem statement: we have an environment that behaves (according to its own rules) unsatisfactorily, we have some desires, and we are looking for a way to make the environment behave as desired.
4.2. Solution Specification and Requirements Validation
Up to a few decades ago—when programmable computers are not available—the only possible way to satisfy user requirements was to instruct some part of the environment to behave in a way that led to satisfying requirements. This situation can be modeled as
For instance, if R involved collecting news in the first half of the eighteenth century, would likely involve couriers and horses.
Today, we look for a machine specification S such that . Being able to specify S is important for at least two reasons:
- If we can build a convincing argument that , then we have verified that R can actually be satisfied. In fact, it may be possible that Formula (3) has no solution at all: in such a case, requirements R have to be modified.
- The specification S is the input for the design phase.
It is important to note that S is not unique. In general, Formula (3) can be satisfied by multiple machine specifications: ; ; …; . Examples can be found in [20]. Accordingly, the specification phase involves identifying and assessing multiple machine specifications, and possibly helping the stakeholders choose which specification should be implemented.
4.3. Implementation (Design and Coding) Phases
Specifications S are the input to the design and coding phases, whose expected output is a machine that implements S. Usually, the machine is not built from scratch, because it would be too expensive and it would take a very long time; instead, a given programmable HW/SW platform M is “configured” by means of a program P in order to behave as specified in S. For instance, M could be a Linux machine equipped with suitable software (e.g., JavaScipt, MySQL, etc.): the developers’ task is to build a program that runs on the given platform according to the given specifications. Note that, in general, P has to be built, while M can be chosen among several available alternatives. For instance, one could use one of the many virtual machines available in the cloud.
The relationship that links P and S is quite similar to the relationship that links S and R. We can write
meaning that the platform M running program P behaves as specified in S.
It must be stressed that S is defined in terms of the “phenomena” that are shared by the world (modeled by E) and the machine (M&P). In practical terms, S is a description of the machine in terms of I/O.
4.4. Verification
Verification aims to show that the proposed implementation actually satisfies the specifications, i.e., that (4) holds.
In principle, the verification can be a formal proof, based on the formal descriptions of M, P and S. However, this is generally impractical, because a formal and accurate description of both M and P would be needed, and writing such descriptions is very difficult and expensive. In fact, formal proofs are usually carried out only on small fragments of S that are considered very critical and hence worth the effort of deriving formal proofs.
Usually, verification is performed by means of testing, i.e., running the program and checking that it behaves as specified. The following discussion makes reference to verification via testing.
Before proceeding, we need to notice that E, S and R are descriptions [15]. During testing, we use the real platform and the actual program . So, the goal of verification is ideally to show that
where Formula (5) states that the combination of and behaves in a way that conforms to the specifications under all possible circumstances that may occur in the environment. In fact, description S is expressed in terms of all the phenomena that are shared by the machine and the environment. Since experimentally proving the truth of Entailment (5) under all possible circumstances is generally not possible, the actual testing activity consists of checking that
where is expressed in terms of the relatively small set of phenomena occurring during testing (i.e., the set of inputs supplied to the machine and the set of corresponding outputs). These phenomena can be originated in the real environment or can be simulated in the testing laboratory. In both cases, the set of testing phenomena can be considered as originated by an environment , whose phenomena and behaviors are subsets of E’s.
Since and are exercised in a subset of the conditions and situations that may occur in the real world, the proved behavior is usually only a subset of the specified behavior S (that is, ). In general, verification is considered successful if (6) holds and the difference includes only situations that are considered hardly relevant or “essentially equivalent” to situations in . Under such conditions, it is assumed that if (6) holds, then (5) holds as well.
4.5. Validation
When considering the validation of the proposed solution, we have to verify that the proposed implementation satisfies user requirements, i.e.,
Note that specifications S do not appear in Formula (7). In fact, specifications S are just an artifact of the software development process. Since proceeding directly from the problem statement (3) to the solution described in (7) is generally exceedingly complex and difficult, specifications S were introduced to make the development process a viable step-by-step activity.
Ideally, validation should prove that
where represents the real environment, and describes the real needs of the users.
During development, it is customary to assume that , i.e., that the documented requirements match the actual user requirements, and , that is, the description of the environment is an accurate and effective representation of the actual environment. Unfortunately, both assumptions may be false in practice: In such cases, the implemented system can fail to cope with unexpected (hence, undocumented) environmental conditions and/or fails to satisfy actual user needs (which have not been understood or properly expressed).
Since validation is typically performed via testing as well, the huge number of relevant phenomena in the real world makes it generally impossible to experimentally prove (8). Being aware of the situations, stakeholders (customers, developers, users, etc.) can define a suitable subset of R as the target of the tests. Therefore, validation can be described as follows:
where is the subset of the environment actually used in the tests (it is generally different from , i.e., the achievement of requirements is tested via a different set of test cases with respect to the one used to verify the achievement of specifications). is the description of the observed effects in the environment caused by and . is the minimum subset of R to be observed.
is the pass condition for the test. It states that the observed consequences on the environment () should include all what is described in . If , i.e., if some effect on the environment non described in was observed, we need to check if it is fine with respect to R, i.e., . If the latter does not hold, there are two possibilities. If the unexpected observed effects are a violation of requirements, the implementation (&) is not correct and needs to be modified. Instead, if the unexpected observed effects are fine with users and customers, we just need to extend R to include them (i.e., we discovered that they belong to but were not included in R). After this amendment, (9) will be satisfied.
) indicates that is coherent with the “real” requirements . By definition, at validation time, the latter have not been described, neither informally nor formally, and they often have not even been clearly conceived. That is, there is no artifact that describes the real requirements. Accordingly, whether is true or false is decided by stakeholders based on subjective judgment. It is also possible that turns out to be coherent with R but it is not acceptable. In this case, it is actually R that fails to represent ; hence, it is necessary to both change R and modify &.
4.6. Representing the Waterfall Life Cycle
Using the formulae introduced above, it is possible to rewrite the representation of the waterfall life cycle as shown in Figure 2. For each stage, the delivered artifacts are specified, together with the relationships that should hold. Specifying such relationships contributes to clarifying the meaning and intended usage of artifacts.
Figure 2.
The representation of the waterfall life cycle according to the proposed approach.
In Figure 2, activities are described as black boxes, in which the work to be done depends on what is available at the beginning of the activity and what has to be achieved. For instance, before design and coding, we have specifications S that satisfy R in E, and we are looking for a machine (i.e., a computing platform M equipped with a program P) that satisfies S. Hence, the purpose of the design and coding phase is to define M and P such that . The proposed approach can also be used to describe development processes at finer granularity levels. An example showing how to describe some details of the design and coding phase is given in Section 10.
The relationships among artifacts defined in the model also explain the presence of loops. Consider for instance the feedback from the specification to requirements analysis: it occurs when it is not possible to define S such that . The cause may be that requirements R are too challenging, or the description of E is wrong or incomplete. Similarly, the loop from design and coding to specification occurs when it is not possible to achieve , i.e., we are not able to build a program P that, executed on a machine M, satisfies the specifications. In such a case, specifications must be modified (i.e., a different way to satisfy R must be defined), or the requirements R themselves must be modified (usually going back to requirements analysis and looking for a less ambitious but still satisfactory definition R).
Descriptions in Figure 2 could also be made more formal: for instance, you backtrack from specifications to requirements analysis when , where means that S appears to be implementable at reasonable costs and in reasonable time.
4.7. Development Activities as Learning Processes
In Figure 2, development activities are described as black boxes, having some properties that hold at the beginning of the activity, and aiming to satisfy some property that has to hold at the end of the activity.
It has been observed that the steps carried out within a development activity involve exploration, learning, interaction with the world and with the stakeholders. Those operations are guided by the evaluation of contingencies, the identification of options, and decision-making. Modeling these activities is important, because the learning process, in which knowledge is collected and refined, is at the core of software development.
Considering the specification phase as an example, let us analyze the role of learning in moving from a situation when S does not exist to the delivery of satisfactory S: S describes the data flow between the environment and the machine, and managing such data flow (i.e., supplying the input data and consuming the output) involves some operating costs; therefore, the definition of S delivered by the specification activity should satisfy the condition that the operating costs of S are acceptable. This involves the definition of the “operating cost” property of S, and of lower-level attributes of S (such as the size and frequency of inputs, or the complexity of outputs), upon which the operating costs are defined. All this requires talking with the user (who knows the threshold below which operating costs are fair) and analyzing details of S (i.e., of the interaction between the environment and the HW/SW machine). The very notion of operating costs could be the result of a learning process during which the point of view of the user is explored and the properties of S related to operating costs are identified.
In the subsequent design and coding phase, it could happen that no implementation can be found, whose development costs are reasonable. This causes backtracking to the specification phase, where alternative definitions of S are sought. It is possible that some knowledge is provided by developers concerning costs of implementing specifications, so that when looking for alternative specifications, the analysts can exclude the most expensive candidates. In this case, we have some knowledge that flows back from a development stage to the preceding one.
This learning process can be described à la Jackson: e.g., at the end of the specification phase ; similarly, the end of the design and coding phase, , where .
5. Prototype Life Cycle
There are several possible reasons to build a prototype. Here, we assume that the prototype is used to clarify requirements by obtaining early feedback from the users that lets developers better understand their needs. Initially, requirements are uncertain, that is, we have written R, but the “real requirements” could be different. In practice, we are addressing problem while we should address . In this—quite common—situation, we risk to build a machine S that yields , so that the real user’s requirements are not fully satisfied.
To clarify the requirements, the prototype life cycle prescribes that we build a prototype program that runs on platform M and implements , a subset of specifications S. The reason why the prototype usually implements only a subset of the specifications is that it must be available in short time and at little cost, and it needs to concentrate only on , the subset of R that contains the uncertain requirements to be clarified. Therefore, prototype aims to implement only part of the machine features () and satisfy only part of the user requirements ():
When the prototype is run, it is shown that
where is the actual (visible) effect of the execution of the prototype in the environment. is assessed by the user: based on this assessment, requirements are possibly revised, i.e., the problem is reformulated as . When writing the new version of requirements :
- (a)
- The part of that has been approved by the user and was already in R is retained.
- (b)
- The part of that has been approved by the user and was not in R is added.
- (c)
- The part of that was in R but has been disapproved by the user is suitably changed. In fact, a strong point of the prototype life cycle is that usually the user does not just reject parts of ; instead, he/she provides indications on how to change the system’s behavior to make it acceptable.
- (d)
- The user may also identify missing requirements, i.e., requirements that are neither in nor in R; these are added.
Concerning point (c), part of the knowledge concerning usually applies to parts of R not included in as well. For instance, if the user approved the visualization of data and information as implemented in , then the same type and style of visualization is likely to be usable in the rest of the system. In any case, the user can be explicitly asked questions on issues raised by the approval or rejection of features.
If we are not confident with the new formulation of requirements , we can build a second prototype , execute it (), evaluate and so on.
When we are confident that the specification of requirements is correct, we can either throw away the prototype and restart the implementation from scratch or build on the prototype. In the latter case, the program will incorporate the final prototype , so that
where ΔP is the part of the program that is added to the prototype to complete the implementation, and is the description of requirements based on the clarifications yielded by the prototypes.
6. Iterative Incremental Development
Iterative development life cycles are organized into iterations, each one aiming at implementing a new chunk of requirements. To this end, it must be possible to partition requirements into pieces, as follows:
Note that being empty is not always guaranteed.
The first iteration addresses :
is tested as described in the waterfall section: the only difference being that here is tested against and , not against the whole specifications and requirements, as in the waterfall life cycle. In what follows the description of testing is skipped for the sake of simplicity.
The following iterations are typically aimed at:
- (a)
- Satisfying more requirements;
- (b)
- Correcting defects found in previous implementations;
- (c)
- Taking into considerations changes of already implemented requirements.
If there are no changes in requirements and no defects to correct, the work done in the second iteration is described by the following pair of formulae:
Note that during the first iteration, it is possible that is changed (e.g., because the user changed his/her mind). In such case, changing does not imply changing any other artifacts. It is also possible that was not entirely known earlier, and its description is completed just before the beginning of the second one.
Concerning , it could be necessary in some cases to change to make it communicate properly with . However, a careful choice of the architecture of should make it possible to add without changing .
If there are defects to correct and no changes in requirements, the specifications are unchanged and the implementation work is described by the following formula:
where is the corrected version of .
If there are changes in already implemented requirements (i.e., was replaced by ) and no defects to correct, we may be lucky and discover that satisfies ; however, in general, the work done in the second iteration involves redefining S1 and correcting , as described by the following pair of formulae:
If there are both changes in already implemented requirements (i.e., was replaced by ) and defects to correct, the work done in the second iteration is still described by the pair of Formulae (14). This stresses the fact that the work carried out in an iteration is useful to both correct defects and address changes in requirements.
The remaining iterations can be described along the same line as the second one.
7. Definitions of Agile Processes and Related Techniques
Researchers and practitioners started proposing agile development methods in the 90’s. In 2001 the Agile Manifesto was published, stating the values and principles of agile processes [21]. Since then, agile processes increasingly gained consensus: today they are very popular and widely practiced [22].
There are several proposals that can be classified as agile techniques (e.g., Scrum, Extreme Programming, Feature Driven Development, etc.). Because of space reasons we cannot discuss them all in this paper: in this section, a few selected “typical” aspects of agile processes are modeled. It is expected that these selected aspects are representative of most agile process features, so that being able to successfully cope with them makes the readers confident that the proposed approach is generally applicable in the context of agile process.
Agile processes are generally characterized by the prioritization of requirements. That is, requirements are partitioned into pieces and arranged in order of priority. For instance, in Scrum [23], each sprint addresses the piece of backlog that brings the greatest value for the user. If we call the piece of requirements addressed by the ith sprint, we have that
After the ith sprint, , where P is the program obtained through the first i sprints.
The iterative incremental development works as described in Section 6. However, a few practices that are typical of agile processes need to be precisely defined, as discussed below.
7.1. Refactoring
Refactoring involves changing the implementation of a given specification to improve its structural qualities, while preserving its functionality: the new code has to implement exactly the same specification as the original code. So, before refactoring, we have
After refactoring:
where is the improved code obtained via refactoring: it implements the same specifications S as P, and passes the same tests (see Section 4.4) as P.
It should be possible to prove that some measures (e.g., those dealing with code complexity, cohesion, coupling, etc.) are better for than for P.
7.2. Dealing with Changes
A most relevant characteristic of agile processes is their ability to cope with change. Changes can be:
- In the environment E.
- In the user requirements R (e.g., the user “changes his/her mind”).
- In the specification S, i.e., in the way requirements R will be satisfied.
- In the way S is implemented, that is, in P, assuming that the hardware/software platform M is not changed.
- In the platform M.
In cases 1 and 2, it could be the developers’ understanding of E or R to change: the effect in practice is the same as E or R actually changed. Of course, several of the above changes may occur at the same time: here, we consider only one type of change at a time for clarity.
Case 1: E changes into . This may also require that R changes into . In any case, S has generally to be changed as well, leading to . Consequently, the code is updated to implement : .
Case 2: R changes into . This implies that the specifications are revised to accommodate for the new requirements: . Consequently, the code is updated to implement : . Exceptionally, it may be possible that , that is, the original specifications also satisfy the new requirements; thus, nothing has to be changed, except for the description of requirements.
Case 3: is changed into . Accordingly, a new program is needed to satisfy : . Note: This is one of the points where agile processes are most different from traditional processes. In fact, traditional “design for change” techniques could sometimes ease the transition from P to . Agile processes, which predicate the simplicity in design and the YAGNI (you aren’t gonna need it) principle, will possibly require non-trivial changes of P to get .
Case 4: is unchanged. We need a new that satisfies M, . may be needed because some quality of P is not acceptable. Quite often, P is changed to make it easier to extend in the following sprints.
Case 5: Usually, platform M is not controlled by the software developers who have to satisfy R. Hopefully, the changes in M are “backward compatible” so that there is no need to change P as a consequence of changes of M, that is, implies . However, it may be the case that some change is required, i.e., .
7.3. Test-Driven Development
Test-driven development (TDD) is a technique that—though not exclusive of agile processes—is an essential component of many agile development processes. TDD assumes that unit-level test cases are written first, then the code that passes the test is written. Therefore, we first need to introduce the concept of unit (alias module).
To organize the system into modules, both specifications and requirements are decomposed into pieces: and . Hence,
Ideally, each module implements a fraction of the specifications:
The implementation of the whole system involves that
In the context of agile processes, the specification of a module is usually very informal and often rather imprecise. We can represent this situation (maybe a bit radically) as . However,
- (1)
- Building the program making reference to the requirements is exceedingly complex and error prone (in fact, this is why specifications are introduced in the classical waterfall life cycle).
- (2)
- In any case, the program has to be tested to verify if it complies with the given requirements. To this end, we have to design a set of test cases that exercise the program in a representative set of conditions for all requirements (as discussed in Section 4.4).
The novelty of test-driven development is that test cases are designed before implementation, rather than afterwards. So, test cases guide the development instead of specifications. In other words, the goal of implementation is not implementing a program that satisfies the given specifications; instead, it is implementing a program that passes the tests: a program that passes the tests is assumed to satisfy requirements. Clearly, the test cases have to be carefully devised, so as to properly exercise the requirements.
All this can be modeled by means of the proposed method as follows. Given the requirements to be satisfied, tests are designed first. Designing tests involves identifying a subset of the environment in which the program will be executed. This subset of the environment, named , includes phenomena that cause the machine (still to be implemented) to react, thus causing the expected effects . As is a subset of E, is a subset of :
A condition for effective testing is that showing that , , holds is sufficient evidence that holds as well.
An important quality of test-driven development—possibly the very reason for adopting it—is that programmers are in charge of writing the test cases at the unit level. To define test cases—i.e., to identify and the corresponding outcome —programmers have to gain a good understanding of requirements, while this is not required in the waterfall life cycle, where specifications somehow hide requirements from programmers.
The presence of in Formula (16) stresses that tests are defined when how requirements will be satisfied has not yet been devised. After having defined the tests, code is implemented and tested:
where represent the actual observed effects of the executions in the environment. If (i.e., if causes some undesired effects), is modified; this process is iterated (in the following sprints) until .
In this way, specifications may remain unspoken, but—since they are the set of phenomena and relations that in conjunction with E entail —they are implicitly defined via test cases.
7.4. More on Refactoring
Refactoring is started when we have a program that satisfies tests (as described in the previous section) but does not satisfy other needs. In the context of agile processes, it is often the case that it is hard to integrate new features into the program.
The typical situation is when the ith iteration is complete, hence , but it is difficult to write so that .
So, the goal of refactoring is to write that can substitute so that
- (1)
- ;
- (2)
- Building so that is relatively easy.
Note that, in general, creating does not require changing all the modules. If the system is properly architected, changing just a few modules is sufficient.
is approved if
An important point is that often is obtained by means of a sequence of small changes. Therefore, it is possible to run the tests—as in (4)—as soon as any small change has been implemented, so that the refactoring process is continuously under control.
8. Explanatory Power of the Proposed Approach
The expressive power of the proposed notation and its ability to support reasoning about software artifacts and their characteristics is illustrated in the following sections, via a set of examples.
8.1. Verification vs. Validation
If we look for definitions of software verification and validation activities, it is very likely that we find the following ones [24]:
- Validation: Are we building the right product?
- Verification: Are we building the product right?
The definition of validation suggests that the product must be right from the point of view of the user, while the definition of the verification suggests that it is the building of the project that must be right, i.e., it must be correct from a technical point of view.
Although these definitions convey a general idea of the meaning of verification and validation, they are by no means precise.
Consider the definitions using Jackson’s formulae:
- Verification deals with proving that ;
- Validation deals with proving that .
Not only is the latter formulation more precise than traditional definitions, but it supports better reasoning about the considered activities. For instance, our formulae highlight the difference between descriptions (like E and S) and the actual artifacts (like and ). In fact, “Are we building the right product?” could refer to R—the description of the user requirements as they were understood and documented, and possibly reported in the contract—or to —the actual requirements, i.e., what users have in mind.
Proving may be inconclusive when R is imprecise or incomplete. The proof can be sufficient to demonstrate that contract obligations have been satisfied, but it does not imply that the user is actually satisfied with the delivered product.
Finally, we can observe that our notation supports reasoning about how to carry out verification and validation via testing, as discussed in Section 4.4 and Section 4.5 above.
8.2. The “What” and the “How”
A very popular way of describing software specifications is that they indicate what has to be developed, as opposed to design, which concerns how the software is built. This is correct only in the machine domain. Specifications S indicate the behavior of the machine in terms of interactions with the world; how S is satisfied depends on P and M.
However, let us look at formula , which does not involve the implementation, as it represents the point of view of the stakeholders, domain experts, users, customers, etc. To these people, S specifies how requirements are satisfied. In fact, S is the solution of the problem expressed as .
8.3. Explaining the Difference Between Proofs and Actual Behaviour
Donald Knuth’s famous statement “Beware of bugs in the above code; I have only proved it correct, not tried it” [25] can be explained in terms of (1), (4), (7) and their real-world counterparts.
Knuth’s statement has multiple meanings.
The first meaning is that Knuth proved , but not . In other words, the code implements correctly a given specification, but this does not guarantee that when we use the program in the environment, it will satisfy the user’s needs. Quite interestingly, this situation may lead to the recurring situation when the user blames the programmer (“your program does not work!”) and the programmer blames the user (“you are not using my program as it was supposed to be used!”).
A second possibility is that Knuth proved , but the description of the word E fails to represent the actual behavior of the word (it could be incomplete, incorrect, not enough detailed, etc.). Consequently, may not hold. This is the case of the famous Ariane 5 disaster [26]: (where describes the Ariane 4 environment) held, so it was assumed that (where describes the Ariane 5 environment) held as well. The demonstration that the latter assumption was false was quite spectacular and expensive.
Another possibility is that an ideal model of the machine M executing P was used in the proof. In practice, the machine is subject to failures or is not fast enough, or has some other problem, so that does not hold. This is the case for the famous Pentium floating point unit bug [27]: a correct program may not achieve the desired results because of failures in the real machine.
8.4. Reasoning About Software Development Organization
In the requirements analysis phase, requirements are optative, since they describe “the desired condition over the phenomena of the environment”, as stated by Jackson. However, E and R are given to the specification phase, as shown in (3): people who are responsible for writing the specifications S cannot change the requirements R; if there is a problem with defining S, we have to go back to the requirements analysis phase to change R. Is this organization of work optimal? An alternative could be a single phase in which both R and S are defined in parallel or in an interleaved manner.
Similarly, in the design and coding phase of a waterfall life cycle, R and S are to be considered indicative: people in charge of implementation cannot change the requirements or the specifications, because they may not have a full understanding of the reasons why R and S were defined as they were. The situation can be very different in agile processes, where developers can also be in charge of maintaining requirements.
8.5. Extending the Model Scope Beyond the Software Life Cycle
In general, software development is carried out to achieve some high-level business needs: the situation can be expressed via formula , where N describes the business needs. In principle, it is possible to devise S such that . However, this is difficult, because we should devise a strategy for achieving N and the specification of the machine that implements such strategy in a single step. Moreover, S would be a mixed-up description of the strategy adopted to achieve N and the specification of the machine that implements the strategy.
Let us consider the following example: a retail company wants to inform potential clients about the available products, with the ultimate goal of increasing sales: this is described via N. Now, there are several ways (strategies) to satisfy need N: classical TV ads, distributing paper catalogs, notifying known clients via social apps, etc. Requirements R describe the chosen strategy (if it is decided to adopt multiple strategies concurrently, each one can be described by a document R). So, R can be seen as a solution to achieve N. The relationship between the problem and solution elements can be synthetically expressed by the following system of formulae [20]:
The system of Formulae (18) shows that to satisfy the business needs N, we need to look for both an effective strategy (i.e., R satisfies N) and an effective implementation of the strategy (i.e., S satisfies R). A perfect implementation of an ineffective strategy will not achieve the needed results; of course, a defective implementation of a good strategy will fail similarly. Interestingly, it is possible—though quite unlikely—that a defective implementation of an ineffective strategy achieves the sought objectives.
It is important to observe that needs are typically expressed by people that are deeply concerned with the business, but have little knowledge about software technologies, so they are usually not able to express requirements for software: e.g., they could express requirements that are excessively hard to achieve (i.e., they could be too expensive, or could require excessively long development time) or unnecessarily constrained (i.e., the available technology and development methods make it possible to achieve much more effective and efficient solutions with approximately the same effort and cost). It is therefore essential that business analysts make a good design (!) work by not only understanding users’ needs, but also helping end users in shaping and formulating software requirements for which viable and convenient software solutions exist.
9. Supporting Management
The proposed approach can be used to support the management of projects, as shown via a few examples.
9.1. What Should Be Defined in a Software Development Contract?
The concepts introduced in the previous sections support some considerations about software development contracts.
The object of the contract is typically the construction of a program P such that, given M and S , makes the entailment true. Even though the user/customer is ultimately interested in R, we saw that there are many S such that , and these S are usually characterized by different costs and performances; thus, it is reasonable that a specific S is chosen as the object of the contract.
Even though S is the main object of the contract, it is often the case that the contract mentions also several other artifacts, including the following:
- The machine M that will be “configured” by means of P is usually described in the contract, i.e., it is said on which platform the program P is expected to run.
- Some characteristics of P are often constrained. For instance, P should use an existing database or interface with an existing system.
- The environment in which the program has to contribute to the achievement of the requirements should be specified as well.
- The acceptance test of P is also generally described. This involves specifying (see Section 4.5).
Having defined the development phases as described in the previous sections, it is easy to relate costs to phases or to the delivery of artifacts. The cost of code implementation is the cost of creating P such that . The cost of code implementation may include testing, that is, defining and making sure that , where SR is expressed in terms of the phenomena shared between and the machine.
9.2. Effort Estimation
A life cycle model should be useful also for supporting software development management. To illustrate how, here we consider the problem of effort estimation when the waterfall life cycle model is used.
It is reasonable to assume that the development effort depends on the artifacts to be created or used in the process; that is, we can write an equation like the following:
where indicates a set of measures of artifact X.
By reasoning on the artifacts and their nature, we could identify function f, as well as the measures needed. For instance, (1) is coherent with the intermediate version of the COCOMO model [28], which involves the size of the program being developed (a measure of P), and a set of parameters like the required reliability (a measure of R), the volatility of the machine (a measure of M), and the amount of data to be managed (a measure of E).
Thus, it appears possible to identify a set of artifacts and their characteristics from our life cycle model and use them to build a model of the development effort. However, having a precise definition of the life cycle lets us go beyond COCOMO. If—as is fairly usual—effort estimation is performed at the end of the specification phase and concerns the subsequent activities, the model of the waterfall life cycle given in Section 4.6 suggests that the measure of the size of P is not available at estimation time; instead, S is available for measuring. Originally, COCOMO adopted lines of code—a measure of P—as a proxy of the measure of S. The problem with this choice is that the given specifications S can be satisfied by different programs like and ( and ) having different sizes, i.e., .
This problem was solved by Albrecht, who proposed a measure of S (the Function Point [29]), which does not depend on the technology used for implementing S, on the programmers and on any other characteristic of the development environment.
Going back to (19), we can thus redefine f so that it uses a measure of the size of S, instead of a measure of the size of P. Quite noticeably, COCOMO II [30] allows for using measures of the size of S.
So, our definitions can be used to explain the motivations that induced Albrecht to define a technology-independent measure of size, and to explain one of the differences between COCOMO ’82 and COCOMO II.
We can proceed further by considering that the development effort also depends on how some activities are carried out. Let us consider verification and validation: the definitions of these activities given in Section 4.4 and Section 4.5 suggests that the cost of verification depends on the extent of , while the cost of validation depends on the extent of . Accordingly, (19) should be rewritten as follows:
9.3. Project Monitoring
One of the most important activities of project management consists in monitoring the progress of the development process. Some monitoring activities concern the measurement of relevant properties of the software products: examples of how the proposed approach can be used in supporting product property measurement are given in Section 11.1, which deals with robustness, and in Section 11.2, which deals with usability. Here, we deal with the measurement of process activities.
In our approach, activities are specified via entailments. For instance, with formula (4) we represent the goal of the implementation phase. Implementation starts when P is not existent, i.e., , and ends when the goal expressed by Formula (4) has been achieved. Monitoring the implementation activity involves evaluating “to what extent” Formula (4) holds. In fact, at a given moment during development, we have that
where is the partial implementation of P achieved when the observation is performed, and is the fraction of the specifications implemented by .
To measure the progress of the activity, Formula (21) suggests that we have two possibilities:
- (1)
- Measuring the partial implementation . In this case, we can produce a measure ), where the function m to be applied to depends on the technology used to implement , which could be lines of code, the number of classes and methods, etc. The limit of this approach is that it provides only absolute indications, not relative ones. For instance, we may know that 10,000 LoC have been coded, but we still do not know if we are close to finish the coding or if we are just halfway through the coding, since we do not know the size in LoC of the final product P.
- (2)
- Measuring the progress in terms of how much of S has been satisfied. In this case, we can provide a suitable measure ); for instance, we could measure how many function points are currently implemented by . We could also provide the measure of , which tells us what fraction of the specifications has been implemented.
Measuring ) is usually suitable for iterative and agile processes, where each iteration or sprint is expected to implement an additional “chunk” of S and R. However, in other contexts, measuring ) could provide little insight into the state of development: for instance, if development is almost complete, but a single small function used by all the others is missing, we would have , since no working functionality has been provided yet.
Other types of process measures can be devised using the same type of reasoning described above. In fact, with the proposed notation, a generic activity is described via entailment E, X ⊢ Y. At any moment before the conclusion of the activity, the situation can be described by . So, it is generally possible to measure , , and .
It could be observed that the specification of monitoring activities should include the indication of when the measures are carried out. To this end, we can associate time to our formulae; for instance, specifies that at time t the existence of in environment E satisfies . It is thus possible to specify that a given measure has to be performed at a given time: e.g., indicates that at time t we get the measure of .
Finally, we can note that the considered measures make reference to S and P: being S and P well defined, it is easier to have similarly well defined measures. The more formal the definitions of E, P, S , and R, the more precise the definitions of , , , and .
10. Reasoning About Life Cycles’ Activities
This section shows how the details of a given activity can be disclosed, by refining the description of the activity, to support reasoning that depends on those details.
As an example, let us consider the design and coding activity (Figure 3).
Figure 3.
The design and coding activity.
It is well known that the volatility of the hardware/software platform can increase the duration and cost of development (e.g., machine volatility is one of the cost drivers in COCOMO [28]). Since, in general, such volatility is not known in advance (as it depends on hardware manufacturers, operating systems developers, cloud service availability, etc.), it can be seen as a cause of duration and cost variability. If we want to model this variability, we have to highlight the sub-activities that are affected by changes in the platform.
In Figure 4, it is shown that the design and coding activity actually consists of two sub-activities: a first one in which the platform M is chosen, and a second one in which design and coding are carried out to produce a program P that runs on M. Note that although in many cases M is “given,” multiple activities concerning possible updates and configurations of M usually need to be carried out. In practice, the configuration activity is equivalent to choosing the platform M.
Figure 4.
A more detailed description of the design and coding activity.
Figure 5.
Changing M affects the design and coding activity.
Figure 6 shows a process that takes into account the change of platform M occurring when the program has already been partly implemented, i.e., is available, such that, together with M, it implements a subset of specifications S. The adaptation activity (a sort of refactoring) converts into program , which implements the same specifications as did, but running on . Finally, a second design and coding stage enhances to obtain a new program P that fully implements S running on .
Figure 6.
Model including sub-activities required to account for M changing in the design and coding activity.
By comparing Figure 4 with Figure 6, it is clear that if M changes, the overall development duration and effort increase by the amount required by the Adaptation activity. The number of platform changes that occur during the development is not known a priori, but it can be estimated, based on experience.
11. Software Properties and Measures
In this section, it is shown how to describe the properties of the software product in a way that is precise enough to support the definition of metrics. Robustness and usability are the two properties used as examples to illustrate the process.
11.1. Robustness
Robustness has been defined in several more or less similar ways:
- “The degree to which a system or component can function correctly in the presence of invalid inputs or stressful environmental conditions” [31].
- “The ability of software systems to react appropriately to abnormal conditions” [32].
The above definitions are somewhat ambiguous: what does it mean that the system has to behave “correctly” or “appropriately”? What are abnormal conditions, invalid inputs and stressful environmental conditions?
By making reference to formula , it is possible to provide a precise definition of robustness.
In a normal development process, the environment is described by E, user requirements are described by R, and software development deals realizing P such that holds. Actually, well-written software development contracts explicitly report E and R, and usually mention M (e.g., to specify how/where the system has to be deployed). In particular, it is important that E is well specified, since many programs yield different results in different environments (i.e., operating conditions).
Robustness deals with the behavior of a program when used under conditions that do not comply with E. With the proposed notation, Robustness can be defined as
Definition (22) considers that the hardware/software systems operates in conditions (described by ) that are broader than the originally envisioned conditions (described by E). Nonetheless, the outcomes (described by ), though possibly broader than the envisioned outcomes (described by R), are acceptable for the users.
Based on the notion of robustness defined by (22), it is possible to define measures that quantify how robust a system (M and P) is. Intuitively, a system is more robust if it behaves acceptably when the operating conditions are more distant form the originally envisioned ones. So,
In (23), the measure of robustness is defined as the maximum distance between the envisioned environment behavior E and the unexpected environment behavior for which the system still behaves acceptably. Assuming—as reasonable—that , (23) explicitly excludes the existence of environment behaviors that are at a greater distance from E and still let the system behave acceptably.
For instance, let us consider the following conditions:
- E specifies that no more than 10 users are ever simultaneously connected to the system.
- R prescribes that the response time of the system is not greater than 0.5 s.
- indicates the number of connected users (in ) exceeding the maximum number stated in E (i.e., 10).
- ) indicates that when the number of users in is greater than the maximum number of users in E, the maximum tolerable response time is 0.55.
Now, suppose that the following situation holds, e.g., because indicates that the response time is 0.55 s, while indicates that it is 0.6 s:
The measure of the robustness of the system indicates that two users more than the expected maximum number of users are tolerated by the system, while more than two cause can the system’s performance to become unacceptable.
Similarly, one could specify via that the difference between the response time in and R must not be greater than 0.04 times the difference between the users in and E.
11.2. External Properties of Software: The Case of Usability
The external manifestations of software are described by S; accordingly, most properties of software are properties of S.
However, properties like usability involve also the behavior of users. Accordingly, usability is best assessed when considering the formula that highlights the behavior of users: (2). Thus, usability can be evaluated via the analysis of in connection with S.
More precisely, we have
- Some operating conditions, as described in .
- People that operate as described in , to achieve one of the goals as described in R.
- People that operate as described in , interacting with the machine as described in S.
The interaction with the machine (in each operating condition and for each goal) can be observed, measured or assessed from the point of view of usability. A measure of usability can then be defined, based on the evaluations of each observed interaction. For instance, could be needed to generate a set of inputs and interpret a set of outputs to achieve a specific goal in R. The number of inputs and outputs, as well as the time taken by to achieve the goal, could contribute to a measure of the usability of the machine (P and M) with respect to the considered goal.
12. Using the Proposed Methodology in Practice
This section addresses the practical applicability of the proposed methodological framework. Although it is not possible to address all the issues that can arise in practice, some of the most relevant issues are considered here.
12.1. Notation and Tools
To apply the proposed methodology in practice, the usage of tools can be convenient. Among the many notations and tools that are available, UML is particularly interesting. In fact, UML is a notation that can be used with different methodologies, and it is supported by several tools. In addition, come with OCL (Object Constraint Language), which can be used to predicate about models.
Suppose that the problem at hand involved building a controller for a sluice gate equipped with a motor that can be used to raise or lower the gate. The environment consists of the gate and the motor, which have to be described via E. Via UML, it is fairly easy to describe E. The elements of the environment can be described via component diagrams, as in Figure 7. We can specify that the environment consists of two elements (components) that are interconnected (via the interface GateMotor). The internals of each component are described via classes, which support the specification of the relevant characteristics (e.g., the position of the gate and the state of the motor) as well as the operations provided (e.g., the motor can be switched on and off). It is also possible to specify how to interact with these elements (via the Sluice Operations and State Notification interfaces).
Figure 7.
Describing the environment E via UML component diagrams.
UML component diagrams are perfectly suited to provide a static representation of the environment, but their ability to specify behavioral aspects is limited. In fact, to this end, UML provides specific diagrams, like state diagrams and sequence diagrams. These diagrams can be used, for instance, to specify the effect of the commands received by the motor; an example is given by the statechart in Figure 8. Note that state 5 is undefined; this means that this state is unpredictable and should be avoided. In the case of the sluice gate, this is the state obtained when the working direction is changed while the motor is on. This operation should be avoided, because it risks breaking the motor.
Figure 8.
Describing the environment behavior via UML statecharts.
However, UML also provides the OCL (Object Constraint Language) that can be used to specify behavioral properties of the environment. Suppose, for instance, that we want to specify that the gate is lowering (i.e., closing) if and only if the motor is on and working anticlockwise, and the position of the gate is less than 1 (i.e., not completely closed), this property can be specified via OCL as follows:
| context Gate&Motor inv: | ||
| SluiceGate.IsClosing | = | (SluiceMotor.IsOn and |
| not SluiceMotor.ClockW and | ||
| SluiceGate.position<1) |
In case time-dependent properties have to be described, extensions of OCL to deal with time are also available [33].
12.2. Software Development Processes Using AI
Currently, it is often the case that AI tools or autonomous agents are used in development activities. It is thus useful commenting on how they fit in the proposed framework.
In most cases, the usage of an AI tool is confined within an activity. For instance, AI tools can be used to analyze the interviews with stakeholder to create descriptions that belong to E or R. Similarly, AI tools can be used to create code that belongs to P. Accordingly, the usage of AI would not change the descriptions of life cycles given in Section 4, Section 5, Section 6 and Section 7. Instead it should be taken into account when describing the internal details of development activities.
Let us consider the validation activity. AI can be used to obtain optimal risk-based coverage, based on requirements, code and possibly additional information, such as profile risks and the results obtained via previous tests. In such case, the role of AI can be explicitly represented as in Figure 9, which is an expansion of the validation activity.
Figure 9.
AI-supported test definition.
If needed, the properties of can be expressed using the techniques described in Section 11.
13. Limitations
Software development is a very complex activity [34]. Although the proposed methodological framework can help deal with some aspects of that complexity, it by no means can eliminate it.
An aspect of the complexity of software development is due to the role of people in the process. Software engineering is socio-technical, and though an appropriate methodological approach can help in understanding and communicating, it cannot change the socio-technical nature of the process and the consequent problems. The proposed framework is useful for explaining and organizing software development activities, but it cannot guarantee that these activities are carried out correctly, hence that the software artifacts have all the desirable properties, like completeness, correctness, etc.
Another aspect of the complexity is derived from the characteristics of the available technical instruments. Let us consider testing, for instance. The proposed framework represents what happens in the real world, where testing covers necessarily a relatively small subset of the situations that can occur in the environment. Nonetheless, it is assumed to provide sufficient assurance that the system behaves as specified. We must be aware of this situation and deal with it. So, Formula (6) shows that , rather than S, is verified. Hence, we have to decide whether this situation is acceptable, i.e., if the difference includes only situations that are considered hardly relevant or “essentially equivalent” to situations in .
Finally, although in this paper the proposed framework has been used in a sufficiently wide range of situations, it is clear that software development can create many more situations, problems and issues than described here. Developers who think worthwhile adopting the proposed approach will have undoubtedly to extend and adapt it.
14. Conclusions
This paper was inspired by the observation that basic software engineering concepts—like software life cycles—are usually described in a rather abstract and imprecise way, both in textbooks and in recognized international standards. This lack of a rigorous framing of software engineering activities is also found in practical software development: e.g., the difference between user needs, requirements, and specifications is often not well understood, so that these concepts get mixed up or not properly addressed.
To improve this situation, a methodological framework based on the extensive usage of the entailment proposed by Jackson [3] has been proposed. Using this framework (or suitable adaptations and extensions), it should be possible to specify what software development is and how it can be organized in terms of artifacts and activities.
In fact, the proposed framework was used to describe several life cycles. Different levels of descriptions were addressed: business needs, requirements, specifications and programs. In addition, it was shown that the formula can be used to explain various properties and relationships that link software artifacts.
Overall, it seems that formula can be used to describe and explain many concepts and phenomena of software engineering in a somewhat straightforward way. It can also be considered a first step towards a unifying theory for software engineering, in that the same type of entailment can be used to describe relationships among different types of software artifacts in different life cycles.
In this paper, the proposed framework has been assessed in terms of its ability to represent multiple life cycle models, development activities, artifact relationships, and software properties, but an extensive empirical validation is still missing. Since the proposed approach appears promising, the software engineering community should consider using the proposed framework and contribute to improve and enhance it, thus also empirically validating this framework.
Funding
This research received no external funding.
Data Availability Statement
No new data were created or analyzed in this study. Data sharing is not applicable to this article.
Conflicts of Interest
The author declares no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| HW | Hardware |
| SW | Software |
| UAT | User Acceptance Test |
| TDD | Test Driven Development |
| YAGNI | “You Aren’t Gonna Need It” |
| SEMAT | Software Engineering Methods and Theory |
| ISO | International Organization for Standardization |
| IEEE | Institute of Electrical and Electronics Engineers |
| LoC | Lines of Code |
| COCOMO | Constructive Cost Model |
Appendix A. Notes on the Formalism
E, R, S, etc., are descriptions that can be written using any suitable formalism. In several cases, natural language is fine. For instance, a sentence like “the sluice gate raises when the motor is on and set to operate the driving screw clockwise” could be part of the description of the environment E. However, one could opt for a simple logic language. In such a case, the statement would be something like “motorState=On ∧ motorDirection=Clockwise ⇒ sluiceGareState=MovingUp.” One could also use temporal logic, state machines, timed automata, etc.
P is typically a program and is hence usually represented via source code. However, pseudo-code could also be suitable, depending on the development phase and the goal at hand. For instance, to build an argument that , pseudo-code could be fine. Instead, if the satisfaction of S has to be verified via testing, code is needed.
Concerning the entailment operator, Jackson explains the meaning of as follows: “If a machine whose behavior satisfies S is installed in the environment, and the environment has the properties described in E, then the environment will exhibit the properties described in R. The essence of the relationship is that R can be deduced from E and S with no further knowledge of the environment.” [3]. To fully understand this explanation, we have to consider also that S “is an optative description of a condition over the shared phenomena at the interface between the machine and the environment,” and E and R are sets of indicative and, respectively, optative assertions concerning the environment.
So, conceptually A, B ⊢C means that C can be proved based on the truth of A and B. However, the real meaning depends on the formalisms used to express A, B and C: If A, B and C are described formally, it is possible to formally prove the entailment. If A, B and C are described informally, we can generally build a convincing argument that A and B verify C. For instance, one may say that “when the sluice gate is moving up, it will eventually be completely open, unless it is stopped before reaching the complete open position.” Of course, the same argument could be expressed in temporal logic or in several other formalisms. At any rate, descriptions like E or R contain multiple assertions: an entailment A, B ⊢ C states that the truth of all the assertions in A and B causes all the assertions in C to be true.
It is worth noting that some parts of the environment can be described formally and some other parts informally. In general, developers want to be able to formally prove the most critical parts of the system, while an informal correctness argument is deemed acceptable for non-critical parts.
Concerning operators, descriptions E, R, etc., are sets of assertions. Hence, the usual set operations can be used. So, for instance, indicates the union of the set of assertions in with the set of assertions in . Similarly, indicates that the set of assertions in R is a superset of the set of assertions in , etc.
Since E, R, S, etc., can be written using different formalism, the notion of “assertions” depends on the used formalism. In some case, a strict set-theoretic interpretation of the operators is not possible. Let us consider E, for instance. We need to specify how many users are requiring a given service at the same time. In such a case, an environment in which 11 users simultaneously request the service is “broader” than an environment E‣ in which only 10 users simultaneously request the service. Hence, we write . The set containment would apply strictly if is characterized by just one assertion “The number of simultaneous users is usually not greater than 10,” while is characterized by that assertion and a second assertion: “Occasionally, 11 users can simultaneously request the service.”
Those who are not comfortable with this usage of the set containment operators can define and use an ad hoc operator that indicates that a description is broader than anther, meaning that it is true in a larger set of cases. For instance, in Formula (22), one could write instead of . The “broader” operator ≽ could then be defined as suitable. E.g., in the considered case, it could be .
Coherently with the original proposal by Jackson, in an entailment , the specifications S are written in terms of the phenomena shared with the environment described by E. These are phenomena controlled by the environment and visible to the machine, and phenomena controlled by the machine specified via S and visible to the environment. When an HW/SW implementation of S, made by a platform M and a program P, becomes available, it can be substituted in the entailment, thus obtaining , provided that M&P interact with the environment via and , and behave as specified in S. M&P may be able to view a set of phenomena wider than ; similarly, it could produce a set of phenomena wider than ; this is irrelevant as long as M&P behaves as specified by S when and are concerned.
To be applicable in general, a methodological framework cannot be too specific or constraining. In our case, software developers are free to extend the proposed framework as needed. In fact, we already observed that in Formula (23), the user-defined notion of distance was used.
References
- Royce, W.W. Managing the development of large software systems: Concepts and techniques. In Proceedings of the 9th international conference on Software Engineering, Monterey, CA, USA, 30 March–2 April 1987; pp. 328–338. [Google Scholar]
- Sommerville, I. Software Engineering, 10th ed.; Pearson: Harlow, UK, 2016. [Google Scholar]
- Jackson, M. The meaning of requirements. Ann. Softw. Eng. 1997, 3, 5–21. [Google Scholar] [CrossRef] [Scilit]
- ISO/IEC/IEEE 12207:2026; Systems and Software Engineering, Software Life Cycle Processes, 2nd ed. International Organization for Standardization: Geneva, Switzerland, 2026.
- McConnell, S. Rapid Development: Taming Wild Software Schedules; Pearson Education: Harlow, UK, 1996. [Google Scholar]
- Washizaki, H. Guide to the Software Engineering Body of Knowledge v4.0a; IEEE Computer Society: Los Alamitos, CA, USA, 2025. [Google Scholar]
- Hall, J.G.; Rapanotti, L. Beauty in software engineering. Computer 2013, 46, 85–87. [Google Scholar] [CrossRef] [Scilit]
- Johnson, P.; Ekstedt, M.; Jacobson, I. Where’s the theory for software engineering? IEEE Softw. 2012, 29, 96. [Google Scholar] [CrossRef] [Scilit]
- Jacobson, I.; Ng, P.W.; McMahon, P.E.; Spence, I.; Lidman, S. The Essence of Software Engineering: Applying the SEMAT Kernel; Addison-Wesley: Boston, MA, USA, 2013. [Google Scholar]
- Jacobson, I.; McMahon, P.E.; Racko, R. 24 Questions–SEMAT and Essence: The Why’s, What’s and How’s to See the Difference. Available online: https://www.ivarjacobson.com/publications/white-papers/24-questions-semat-essence (accessed on 16 August 2026).
- Ng, P.W. Integrating software engineering theory and practice using essence: A case study. Sci. Comput. Program. 2015, 101, 66–78. [Google Scholar] [CrossRef] [Scilit]
- Object Management Group. Essence–Kernel and Language for Engineering Methods Version 2.0; OMG: Needham, MA, USA, 2024. [Google Scholar]
- Object Management Group. Business Process Model and Notation (BPMN) Version 2.0.2; OMG: Needham, MA, USA, 2013. [Google Scholar]
- Object Management Group. OMG Systems Modeling Language (SysML) Version 2.0—Part 1: Language Specification; OMG: Needham, MA, USA, 2026. [Google Scholar]
- Gunter, C.A.; Gunter, E.L.; Jackson, M.; Zave, P. A reference model for requirements and specifications. IEEE Softw. 2002, 17, 37–43. [Google Scholar]
- Jackson, M. Software Specifications and Requirements: A Lexicon of Practice, Principles and Prejudices; Addison-Wesley: New York, NY, USA, 1995. [Google Scholar]
- Jackson, M. Problem Frames: Analyzing and Structuring Software Development Problems; Addison-Wesley Longman Publishing Co., Inc.: Boston, MA, USA, 2000. [Google Scholar]
- Benington, H.D. Production of large computer programs. Ann. Hist. Comput. 2008, 5, 350–361. [Google Scholar] [CrossRef] [Scilit]
- Theofanos, M.F.; Pfleeger, S.L. Wavefront: A goal-driven requirements process model. Inf. Softw. Technol. 1996, 38, 507–519. [Google Scholar] [CrossRef] [Scilit]
- Lavazza, L. Business goals, user needs, and requirements: A problem frame-based view. Expert Syst. 2013, 30, 215–232. [Google Scholar] [CrossRef] [Scilit]
- Fowler, M.; Highsmith, J. The agile manifesto. Softw. Dev. 2001, 9, 28–35. [Google Scholar]
- Project Management Institute (PMI). The Future of Project Work: Pulse of the Profession® 2024; Project Management Institute (PMI): Newtown Square, PA, USA, 2024. [Google Scholar]
- Takeuchi, H.; Nonaka, I. The new new product development game. Harv. Bus. Rev. 1986, 64, 137–146. [Google Scholar]
- Boehm, B.W. Verifying and validating software requirements and design specifications. IEEE Softw. 1984, 1, 75. [Google Scholar] [CrossRef] [Scilit]
- Knuth, D. Comment to Peter van Emde Boas. Available online: http://www-cs-faculty.stanford.edu/~knuth/faq.html (accessed on 16 August 2026).
- Lions, J.L.; Luebeck, L.; Fauquembergue, J.L.; Kahn, G.; Kubbat, W.; Levedag, S.; Mazzini, L.; Merle, D.; O’Halloran, C. Ariane 5 Flight 501 Failure Report by the Inquiry Board, 1996. Available online: https://www.csm.ornl.gov/~sheldon/cs422/ariane5fr.html (accessed on 16 August 2026).
- Pratt, V. Anatomy of the Pentium bug. In Proceedings of the Colloquium on Trees in Algebra and Programming; Springer: Berlin/Heidelberg, Germany, 1995; pp. 97–107. [Google Scholar]
- Boehm, B.W. Software engineering economics. IEEE Trans. Softw. Eng. 1984, 1, 4–21. [Google Scholar] [CrossRef] [Scilit]
- Albrecht, A. Function-Point Method (Measuring Applications Development Productivity). In Proceedings of the IBM Application Development Joint Share and Guide Symposium, Monterey, CA, USA, 14–17 October 1979. [Google Scholar]
- Boehm, B.W.; Abts, C.; Brown, A.W.; Chulani, S.; Clark, B.K.; Horowitz, E.; Madachy, R.; Reifer, D.; Steece, B. Software Cost Estimation with Cocomo II; Prentice Hall: Upper Saddle River, NJ, USA, 2000. [Google Scholar]
- Std 610.12; IEEE Standard Glossary of Software Engineering Terminology. IEEE: New York, NY, USA, 1990.
- ISO/IEC 14143-1:2007; Information Technology–Software Measurement–Functional Size Measurement—Part 1: Definition of Concepts. ISO/IEC: Geneva, Switzerland, 2007.
- Lavazza, L.; Morasca, S.; Morzenti, A. A dual language approach to the development of time-critical systems. Electron. Notes Theor. Comput. Sci. 2005, 116, 227–239. [Google Scholar] [CrossRef] [Scilit][Green Version]
- Brooks, F.; Kugler, H. No Silver Bullet; IEEE Computer Society: Los Alamitos, CA, USA, 1987. [Google Scholar]
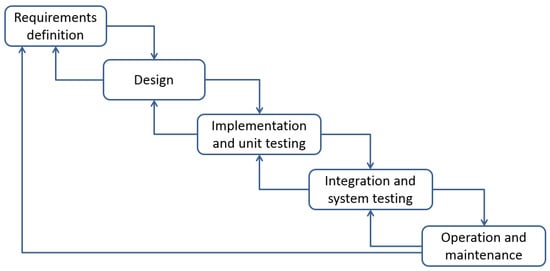
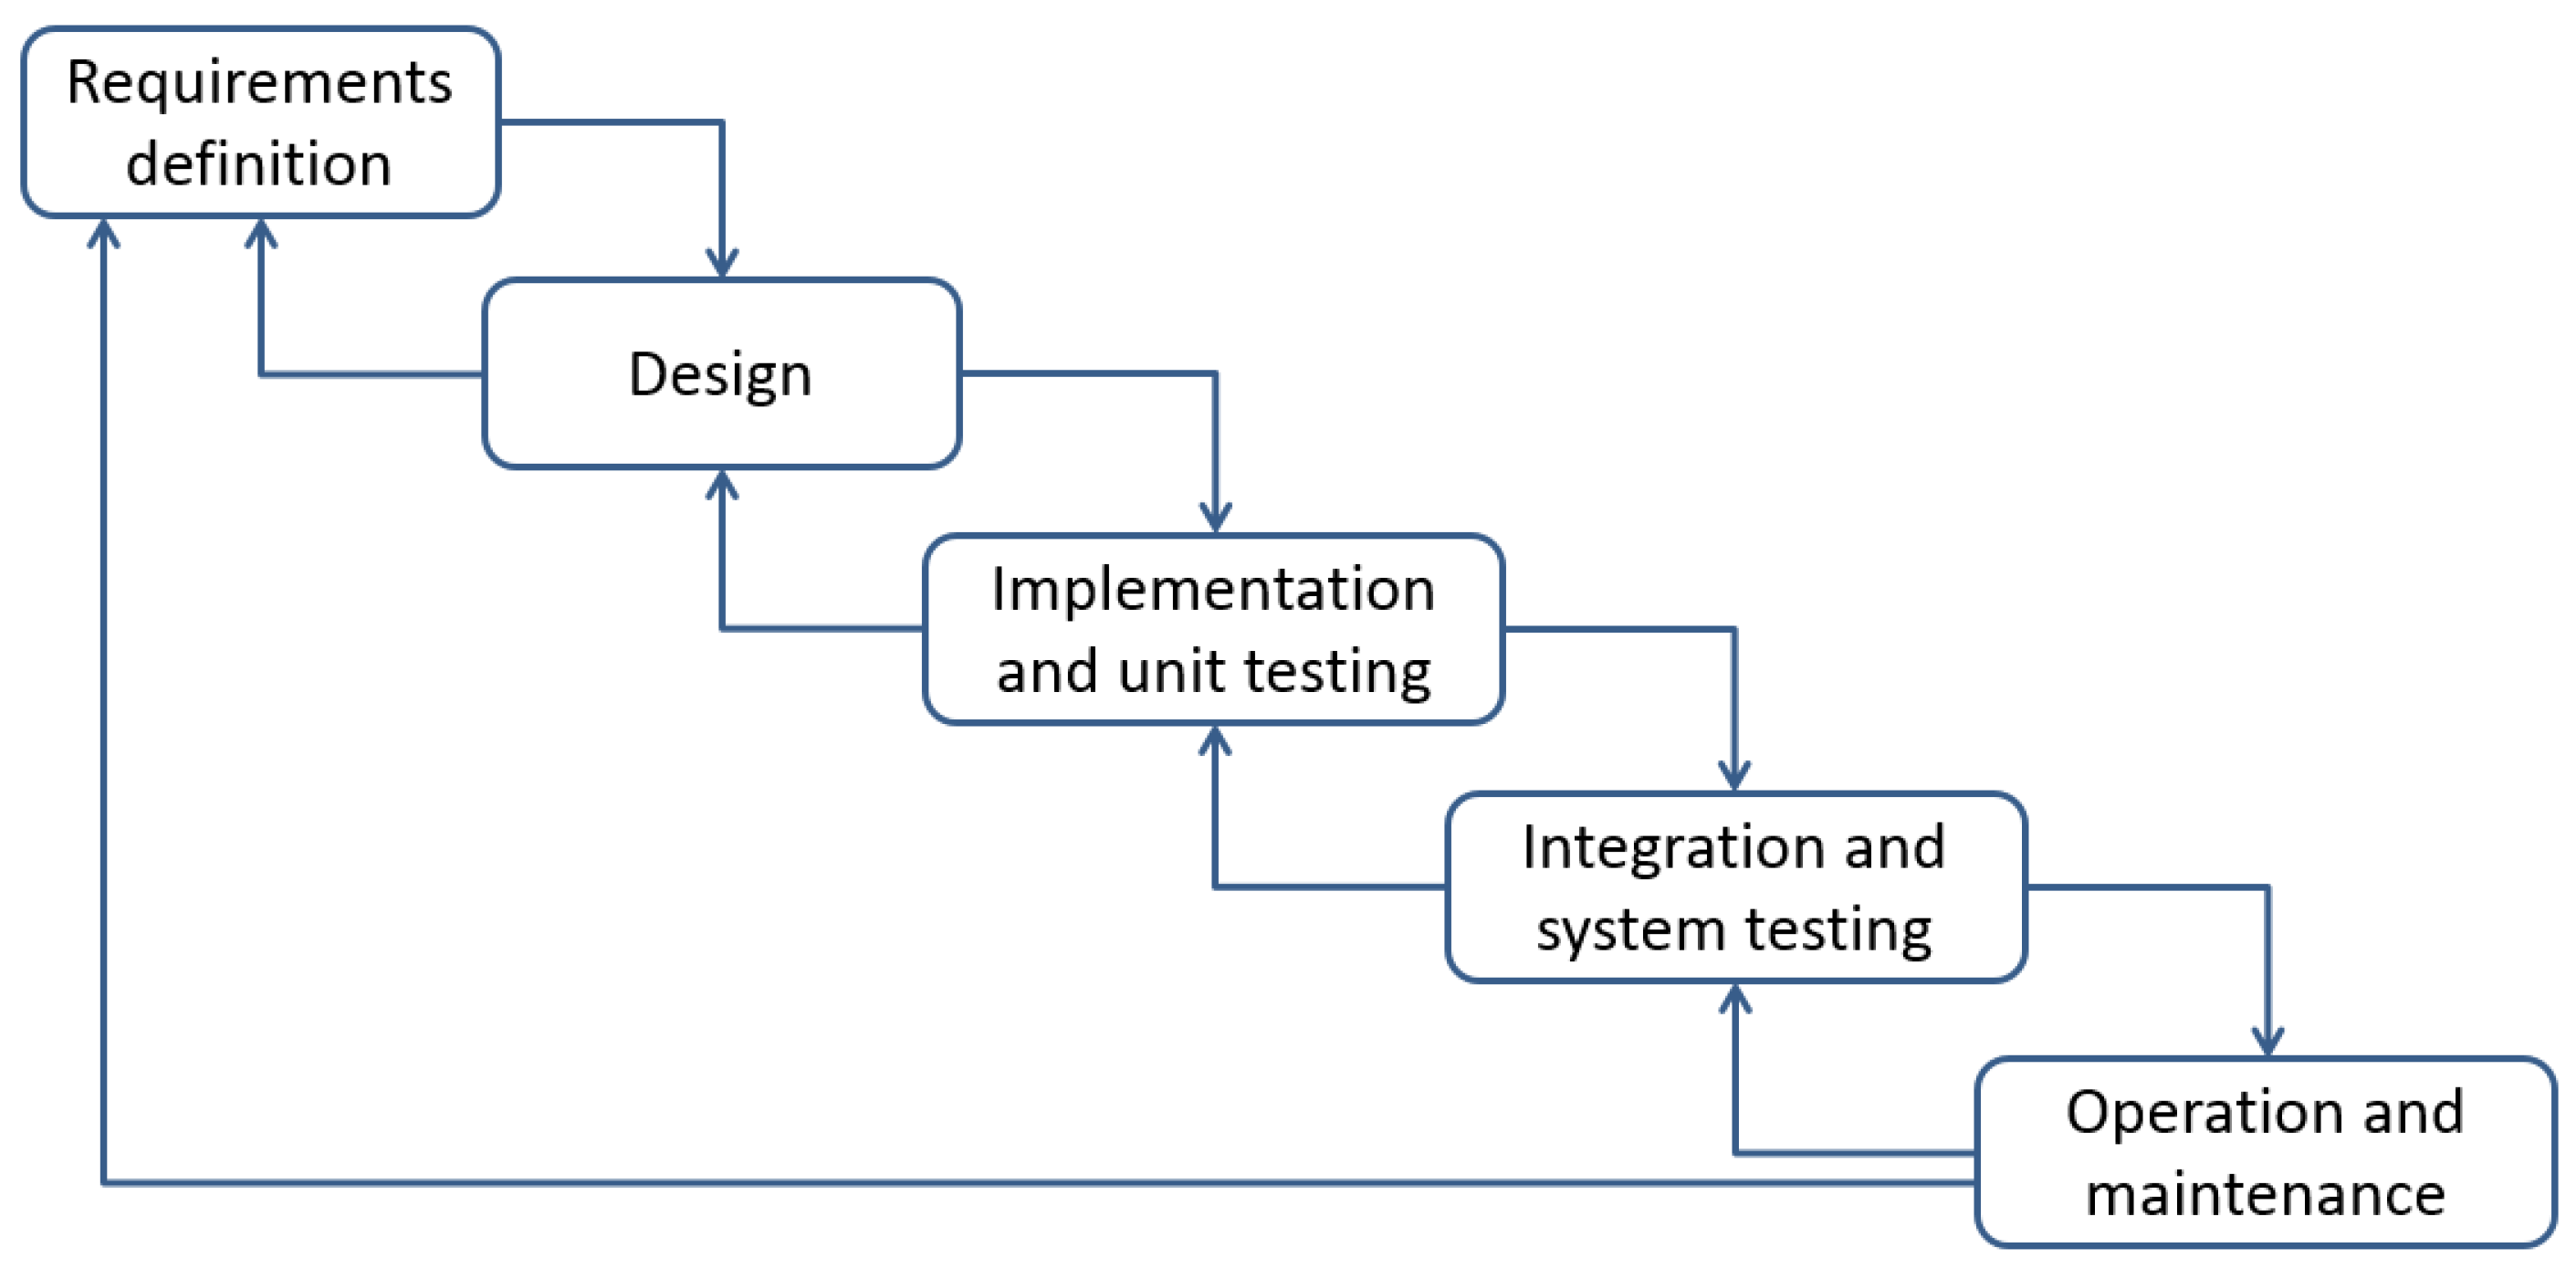
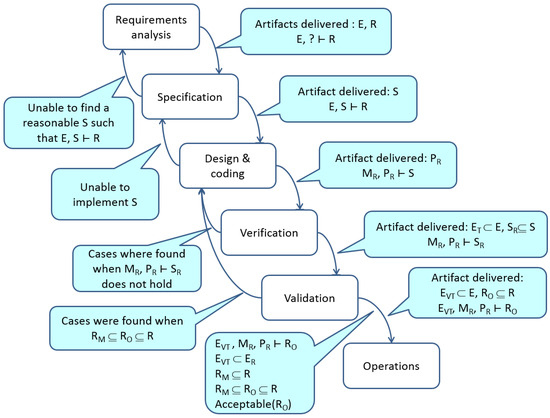
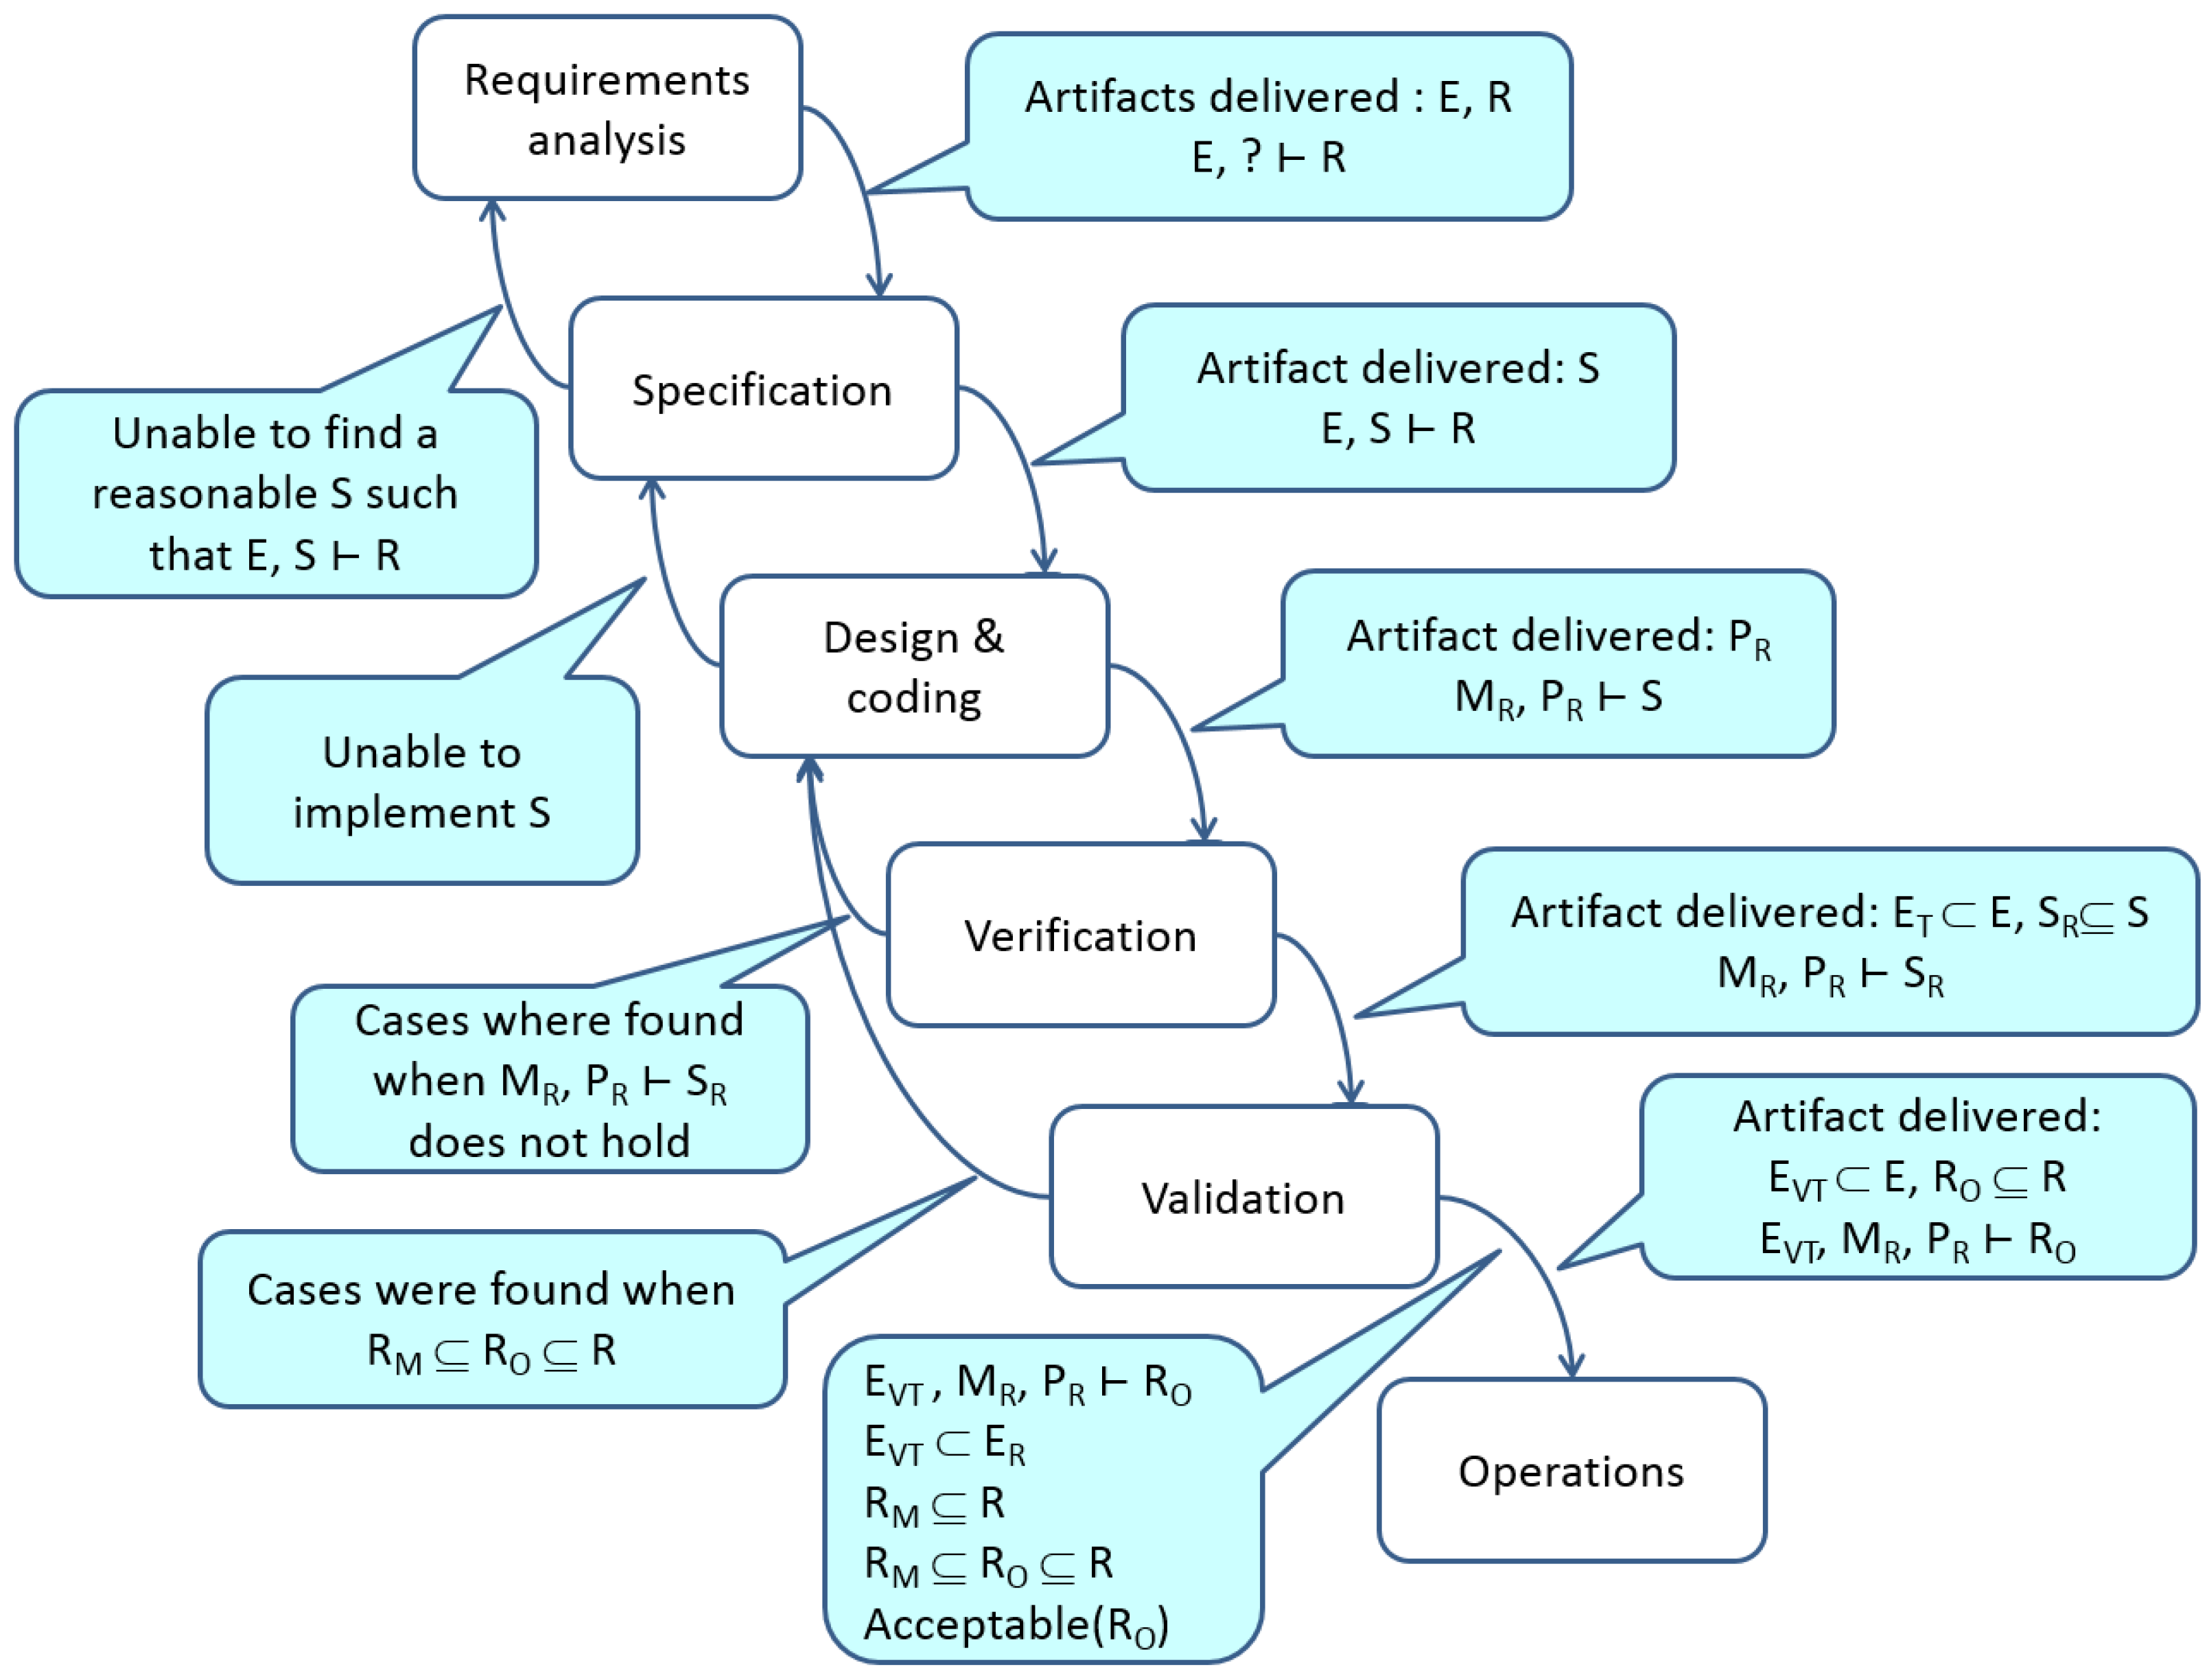
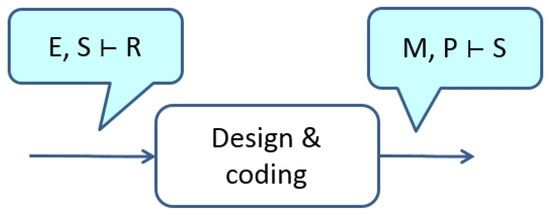
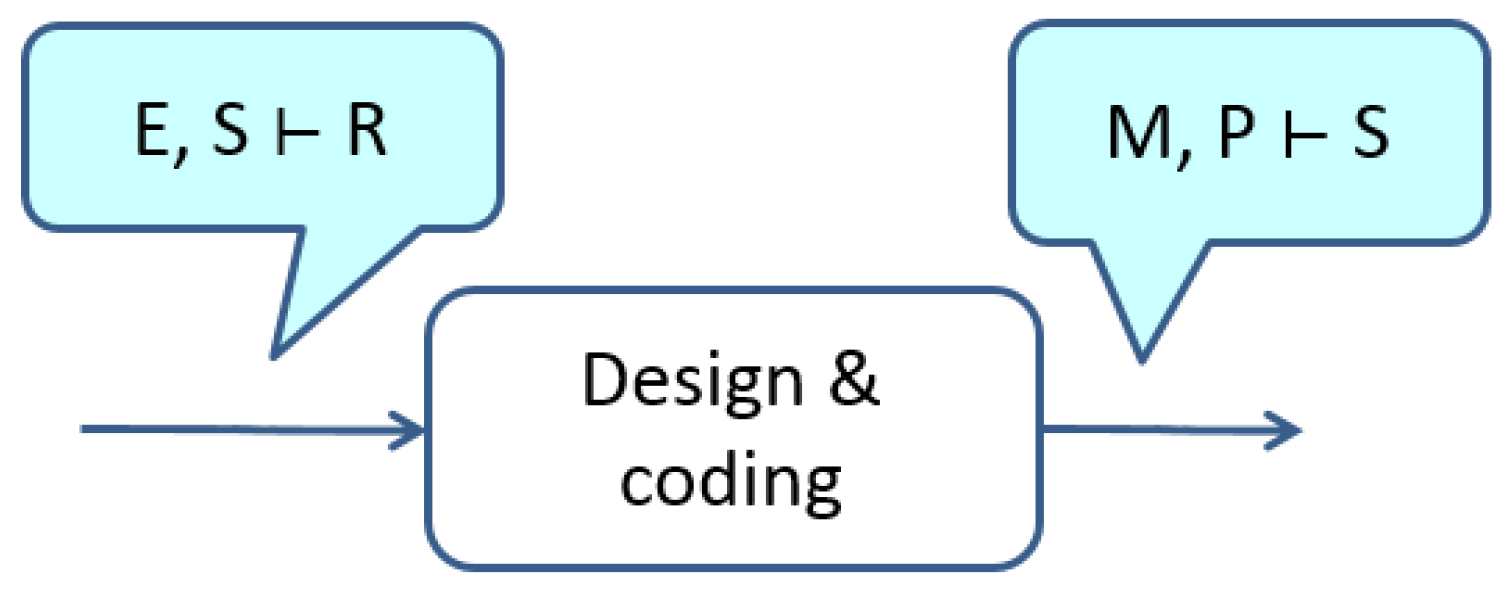
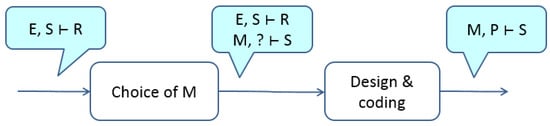
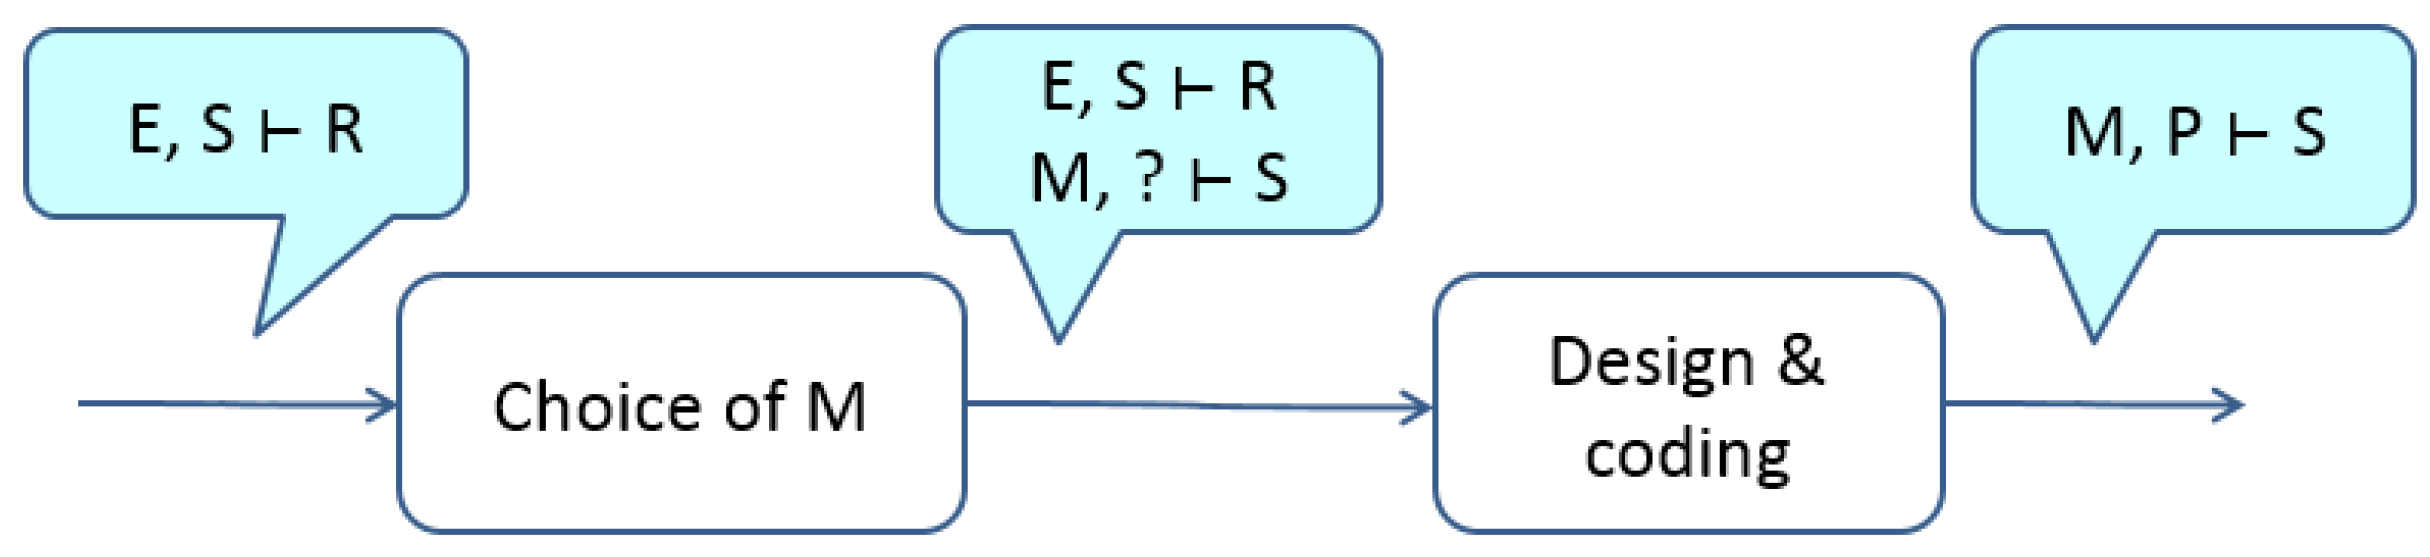
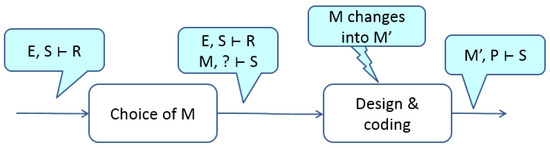
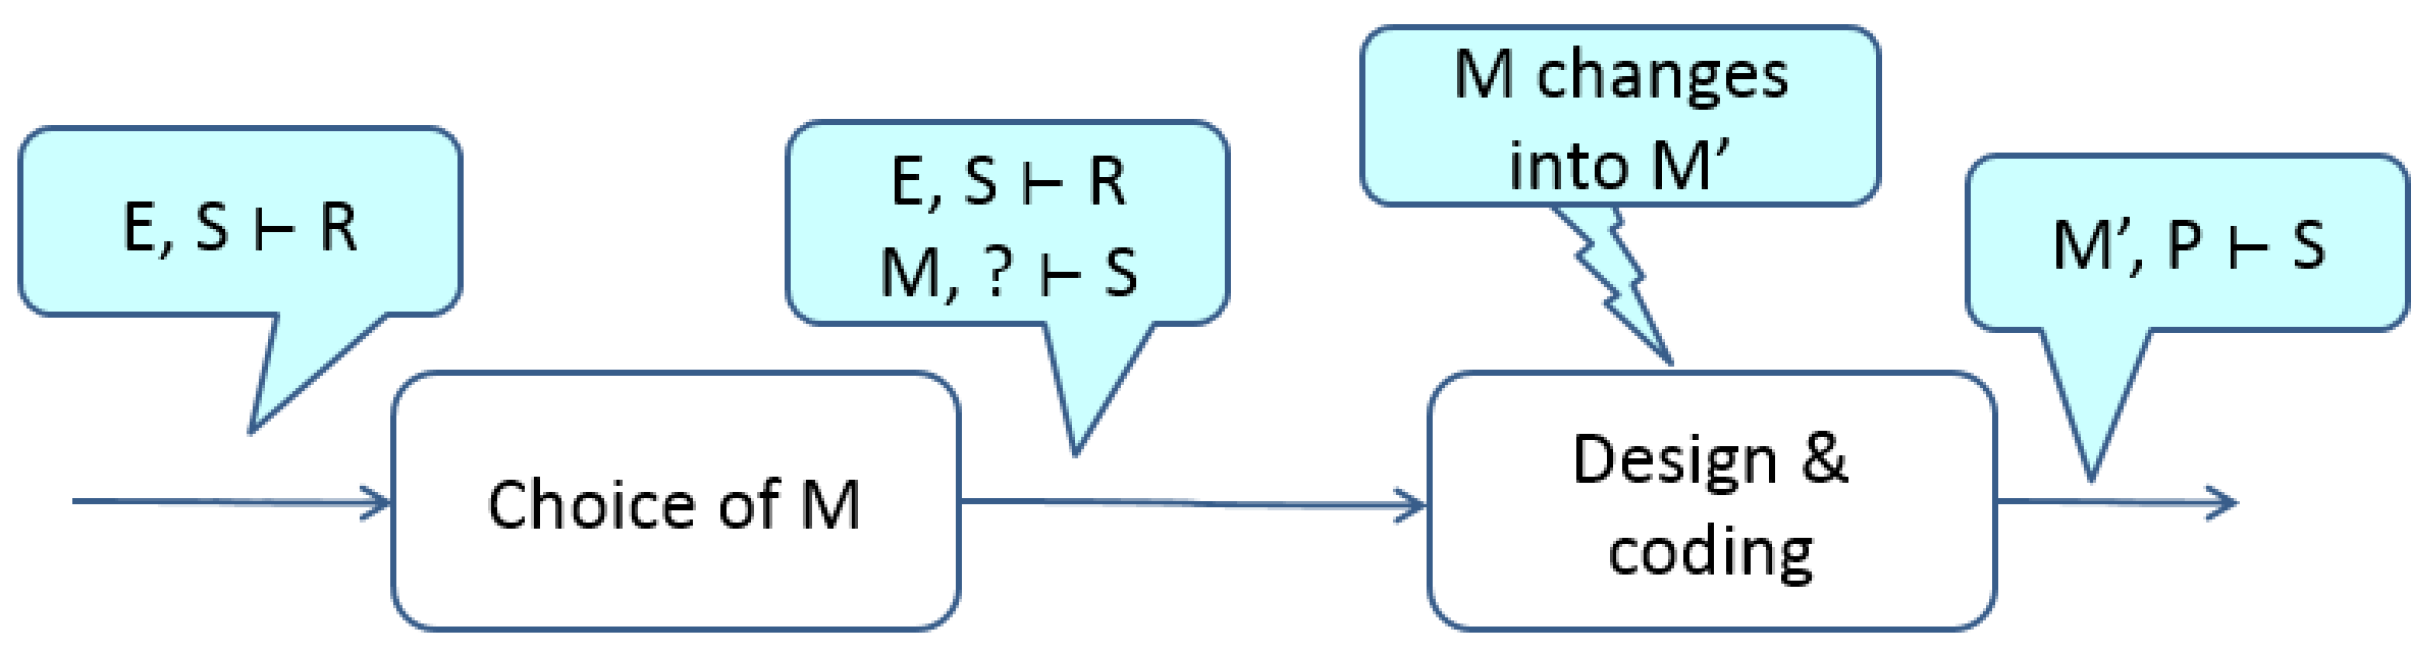
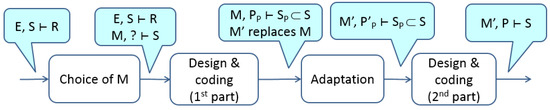
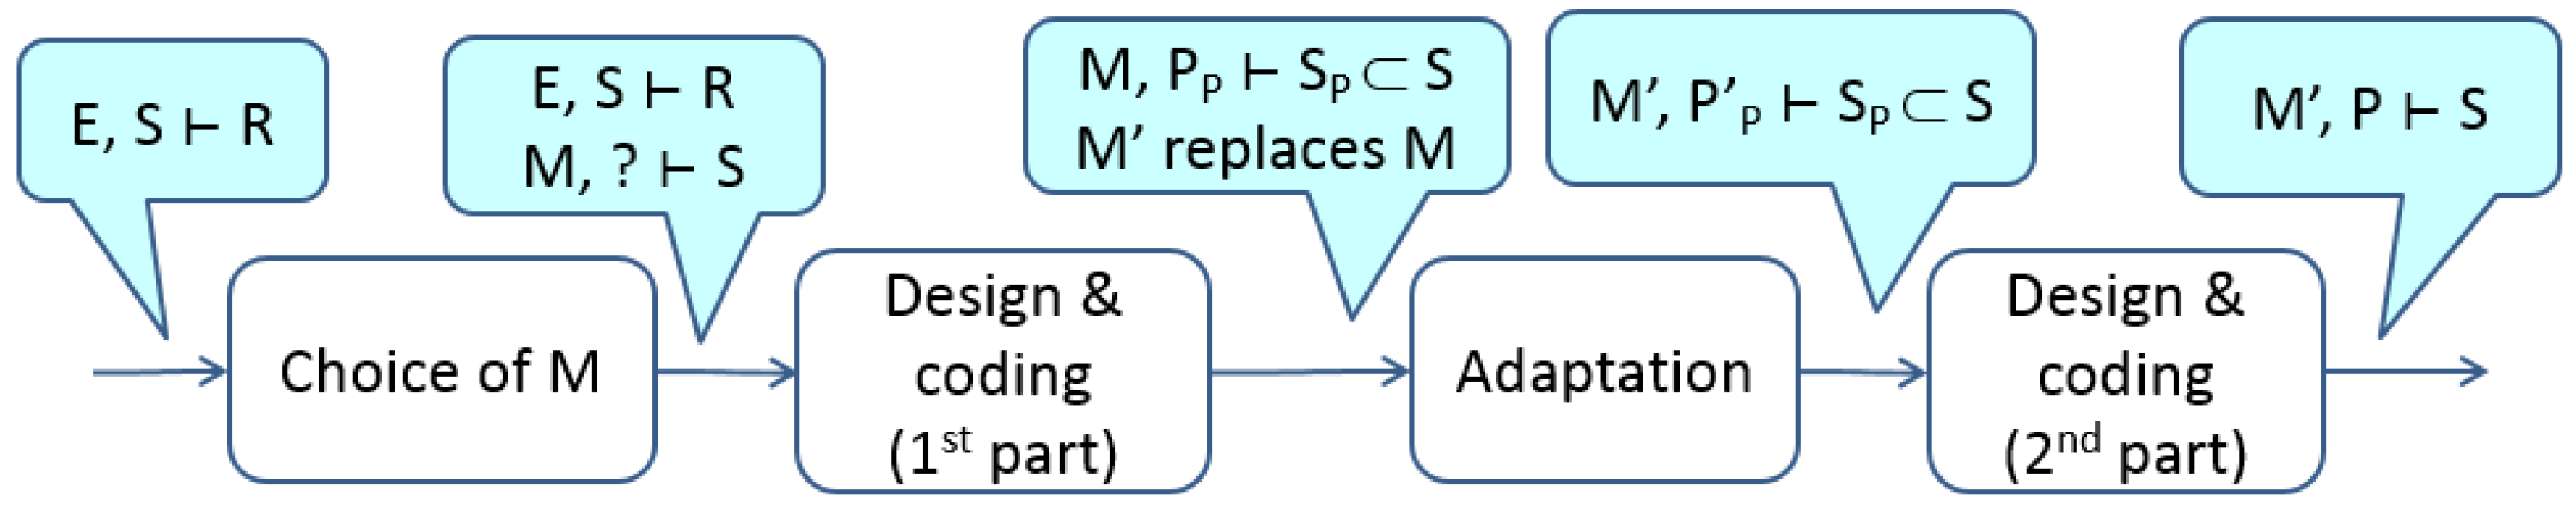
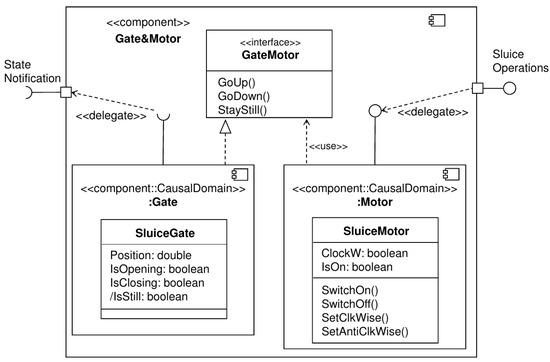
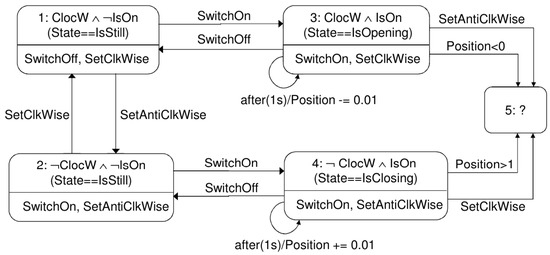
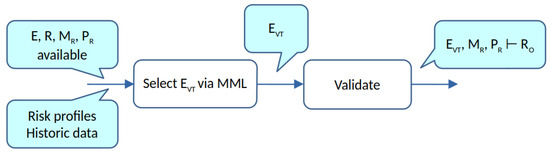
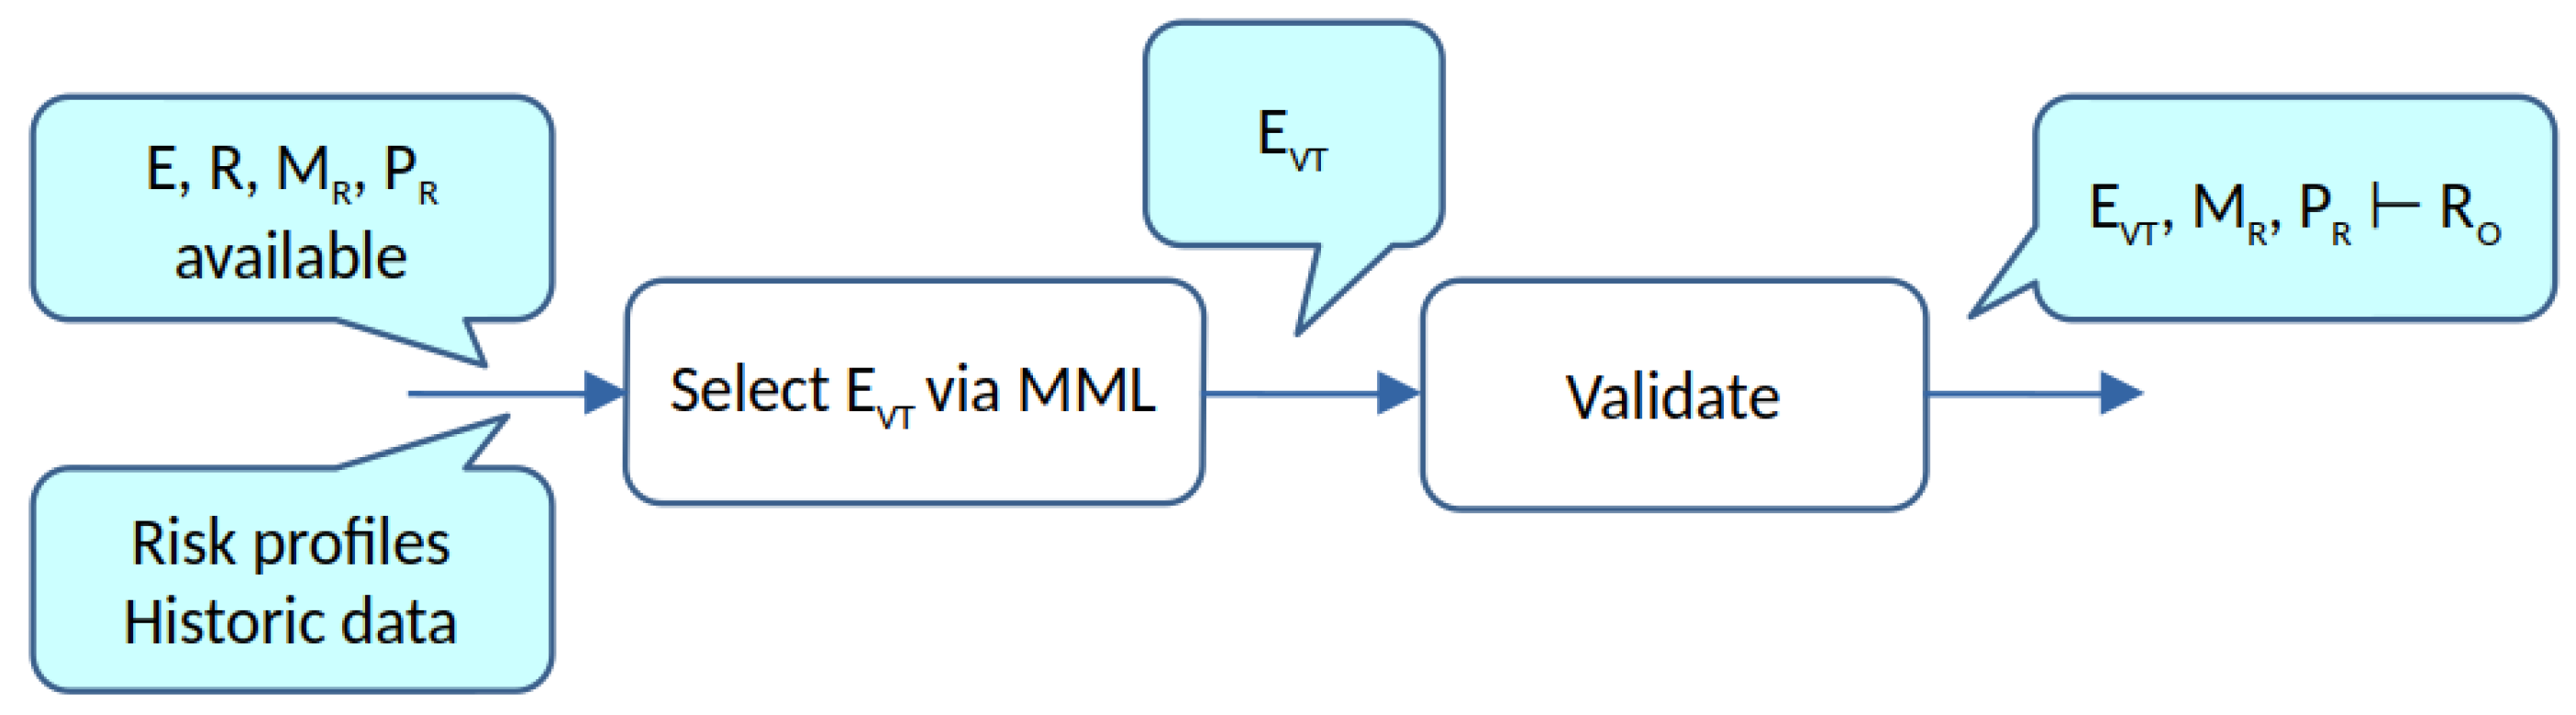
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the author. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.