Article

Artificial Intelligence Recommendations and Booking Abandonment in Online Hotel Reservation Platforms: A Cognitive Load and Information Foraging Perspective

1
Department of MBA and Research Centre, RNS Institute of Technology, Bengaluru 560098, India
2
Department of MBA, Global Academy of Technology, Bengaluru 560098, India
*
Author to whom correspondence should be addressed.
Tour. Hosp. 2026, 7(8), 228; https://doi.org/10.3390/tourhosp7080228
Submission received: 9 June 2026 / Revised: 21 July 2026 / Accepted: 24 July 2026 / Published: 6 August 2026

Abstract

I-driven recommendation systems are widely assumed to ease decision-making in online hotel booking, yet little is known about whether two of their defining characteristics—perceived serendipity (unexpected but relevant suggestions) and perceived similarity (resemblance among suggested properties)—impose cognitive costs that contribute to booking cart abandonment. Objective: This study examines how perceived serendipity and perceived similarity in AI recommendations influence cognitive load, and how this load in turn affects booking abandonment, drawing on Cognitive Load Theoryand Information Foraging Theory. Methodology: Cross-sectional survey data were collected from 624 Indian consumers with recent AI-assisted hotel booking experience, sampled from the user communities of three online travel platforms, and analyzed using partial least squares structural equation modeling (PLS-SEM) in SmartPLS 4.0. Results: AI-driven personalization increased both perceived serendipity (β = 0.777) and perceived similarity (β = 0.824), each of which independently elevated cognitive load (β = 0.518 and β = 0.464, respectively); cognitive load in turn was significantly associated with greater booking abandonment (β = 0.530), and the indirect effects of serendipity and similarity on abandonment via cognitive load were also significant. Conclusions: In this exploratory, single-sample study, AI personalization did not uniformly ease booking decisions: when recommendations were perceived as highly serendipitous or excessively similar, the associated cognitive load coincided with greater cart abandonment. These preliminary, cross-sectional associations tentatively suggest that hospitality platforms may benefit from calibrating personalization intensity rather than maximizing it, pending confirmatory replication with stronger measurement-invariance and discriminant-validity testing.

1. Introduction

The landscape of hospitality commerce has undergone profound transformation through the integration of artificial intelligence technologies. Contemporary online hotel reservation platforms employ sophisticated machine learning algorithms to synthesize historical booking behaviors, user preferences, and contextual information to generate personalized property recommendations (Lu et al., 2015; Q. Zhang et al., 2020). These algorithmic systems represent a fundamental shift in how travel consumers navigate the accommodation selection process, moving from passive browsing of static catalogs to interactive engagement with dynamically personalized suggestions designed to facilitate informed decision-making (Shin, 2020).
The theoretical premise underlying AI recommendation deployment in hospitality contexts posits that algorithmic curation of accommodation options reduces information search burden, accelerates decision velocity, and enhances satisfaction with selected properties (Lee & Hosanagar, 2020; Stöckli & Khobzi, 2020). Industry stakeholders have embraced recommendation technology as a strategic mechanism for differentiating user experiences and capturing competitive advantage within densely populated online travel agency markets (Bawack et al., 2022). However, emerging evidence from behavioral science research suggests potential unintended consequences: AI-generated suggestions, particularly when characterized by unexpected novelty or substantive overlap with previously encountered options, may paradoxically increase rather than diminish cognitive strain experienced during property selection (Wu et al., 2024).
Booking abandonment represents a significant challenge for the online hospitality sector. Contemporary research indicates that abandonment rates within hotel reservation contexts substantially exceed those observed in general e-commerce environments, with industry analytics reporting abandonment frequencies approaching 80% during 2023–2024 (Gelder, 2024). This phenomenon signals a critical disconnect between platform design, recommendation system implementation, and user cognitive capacities. While scholarly attention has examined product-specific factors (property characteristics, pricing structures, review authenticity) and platform-level variables (payment security, interface usability, shipping policies) (Huang et al., 2018; Tang & Lin, 2018; Kapoor & Vij, 2021), systematic investigation into the cognitive mechanisms by which AI recommendation characteristics precipitate booking abandonment remains relatively underdeveloped.
This research addresses this theoretical and practical gap by developing an integrative model that explicates how AI recommendation characteristics—specifically, the degree of perceived novelty relative to user expectations and the extent of similarity among suggested options—generate cognitive load through information processing demands (Cognitive Load Theory; Sweller, 2019). The study incorporates two complementary theoretical frameworks: Cognitive Load Theory, which elucidates how task complexity and presentation design interact with limited working memory capacity to influence performance outcomes (Debue & Van De Leemput, 2014; Plass & Kalyuga, 2019); and Information Foraging Theory, which characterizes how individuals navigate complex information environments by evaluating informational cues to optimize search efficiency (Pirolli & Card, 1999; Li et al., 2017).
Our empirical investigation, conducted among 624 Indian consumers with recent hotel booking platform experience, yields evidence that higher perceived serendipity and greater perceived similarity in AI recommendations both independently elevate cognitive load during the booking process. This increased cognitive demand, in turn, significantly increases the likelihood of booking abandonment. These findings carry important implications for hospitality technology design, recommender system configuration, and online travel agency revenue optimization strategies.

1.1. Research Motivation and Contribution

Three primary considerations motivate this investigation. First, the exponential growth in AI-driven personalization technologies has far outpaced systematic examination of their psychological and behavioral consequences within hospitality contexts. While technical literature emphasizes algorithmic advancement and accuracy metrics (Afoudi et al., 2021; Venkatesan et al., 2023), consumer-centric research investigating how users experience and respond to these systems remains sparse. Understanding the phenomenological and behavioral dimensions of AI recommendation engagement represents an important avenue for advancing hospitality consumer behavior scholarship (Dwivedi et al., 2019).
Second, the phenomenon of booking abandonment in online hotel reservation environments presents a critical business challenge and an important research problem. Industry data consistently demonstrates that abandonment rates substantially exceed those in general e-commerce contexts (Song, 2019; Wong et al., 2018), suggesting hospitality-specific factors merit dedicated investigation. While previous research has identified various contributors to abandonment—including payment security concerns (Gong et al., 2019), pricing uncertainty (Kukar-Kinney & Close, 2009), and property information inadequacy (Roy & Shaikh, 2024)—the role of AI recommendation system characteristics in precipitating abandonment decisions has received minimal scholarly attention. This investigation directly addresses this omission by examining how AI recommendation properties influence cognitive demands and behavioral outcomes.
Third, theoretical integration of Cognitive Load Theory and Information Foraging Theory provides a robust framework for understanding the complex mechanisms linking AI recommendation exposure to behavioral outcomes. While these theoretical traditions have been independently applied in various digital commerce contexts (Deck & Jahedi, 2015; Drichoutis & Nayga, 2020), their combined application to examine AI-driven information foraging behaviors within hospitality settings represents a novel theoretical contribution. This integrative approach illuminates how users navigate algorithmically mediated choice environments and provides actionable insights for optimizing recommendation system design (Dwivedi et al., 2019).
A recent study examined a related relationship using Information Foraging Theory, finding that peer shopping-cart exploration on a general e-commerce platform reduces cart abandonment, an effect mediated by perceived diagnosticity and serendipity, with diagnostic information reducing abandonment while serendipitous information increased it. This finding—that serendipity raises abandonment risk—is consistent with the direction of our H3 and H5 results. The present study differs in three respects: it examines system-generated AI recommendations rather than peer-shared carts as the source of information cues; it situates the phenomenon within the hospitality booking context, where property selection involves multi-attribute, experience-good evaluation distinct from the general retail goods studied previously; and it introduces perceived similarity as a second, theoretically distinct antecedent of cognitive load alongside serendipity, allowing the present model to show that excessive similarity, not only excessive novelty, can independently drive abandonment—a mechanism not addressed by the cart-exploration study.

1.2. Scope and Status of This Study

We present this study as exploratory and hypothesis-generating rather than confirmatory, and we ask that the results below be read accordingly. Three methodological choices motivate this framing. First, the analytic sample pools respondents recruited from three online travel platforms (MakeMyTrip, Agoda, and Goibibo) without a formal test of measurement invariance across them; we therefore treat the pooled sample as the unit of analysis and do not claim the reported effects are uniform across, or generalizable beyond, this pooled population. Second, discriminant validity between the two focal recommendation-characteristic constructs is assessed using the Fornell–Larcker criterion, a conventional but comparatively lenient test, rather than the stricter Heterotrait–Monotrait (HTMT) ratio. Third, common method bias is assessed using Harman’s single-factor test alone rather than a stronger technique such as the unmeasured latent method factor test. Each of these is a defensible starting point for an initial, theory-building investigation of a relatively underexamined phenomenon, but none is sufficient on its own to support confirmatory claims about the size or population-level generality of the reported effects. We have written the Abstract, Discussion, and Conclusions to reflect this status throughout: we report the observed pattern of association among AI recommendation characteristics, cognitive load, and booking abandonment as a preliminary finding, consistent with Cognitive Load Theory and Information Foraging Theory, that motivates a confirmatory follow-up study rather than an established, generalizable effect.

2. Literature Review and Theoretical Foundations

2.1. AI Recommendation Systems in Hospitality Contexts

Recommendation systems have become integral to hospitality e-commerce operations. These algorithmic tools examine extensive datasets encompassing user interaction histories, property characteristics, temporal patterns, and behavioral indicators to generate suggestions predicted to align with individual preferences (Lu et al., 2015). Within online hotel booking platforms, recommendation engines serve multiple strategic functions: reducing the cognitive burden of evaluating numerous accommodation options, personalizing user experiences to enhance engagement (Alamdari et al., 2020), and ultimately facilitating conversion from browsing to completed reservations (Lee & Hosanagar, 2020).
Previous scholarship examining recommendation systems has predominantly concentrated on three research streams: algorithmic development and refinement, user interface design optimization, and consumer trust formation. The algorithmic stream emphasizes technical innovations in filtering mechanisms, data utilization approaches, and prediction accuracy enhancement (Konstan & Riedl, 2012; Y. Zhang & Chen, 2020). The interface design stream investigates how recommendation presentation—layout, visual emphasis, narrative framing—influences user engagement and decision quality (Cremonesi et al., 2016; Smits & Van Turnhout, 2023). The trust stream examines how system transparency, explainability, and perceived fairness cultivate consumer confidence in algorithmic suggestions (Shahzad et al., 2024; Mayer et al., 2024; Pathak & Bansal, 2024).
Notably underexamined within existing literature is the consumer-side experience of engaging with AI recommendations. Specifically, how do users phenomenologically experience the serendipitous discovery aspect of recommendations (Yi et al., 2017)? Do unexpected suggestions facilitate satisfaction or generate dissonance (Faraji-Rad & Pham, 2017)? When multiple suggested properties share substantial characteristic overlap, how does this similarity influence user cognition and choice confidence (Barta et al., 2022; Laporte & Briers, 2018)? These questions remain substantially under-investigated within hospitality scholarship despite their direct relevance to understanding booking abandonment dynamics.

2.2. Booking Abandonment in Online Hospitality Contexts

Booking abandonment—the situation where consumers add accommodation options to their reservation basket but fail to complete the purchase transaction—represents a persistent challenge within online travel agency operations. Industry analytics consistently document abandonment rates substantially exceeding those observed in general e-commerce sectors (Gelder, 2024). This elevated abandonment frequency suggests that hospitality-specific factors warrant dedicated investigation.
Existing research has identified multiple contributors to abandonment decisions. Property-related factors include pricing concerns (Kukar-Kinney & Close, 2009), insufficient review coverage or review authenticity questions (Huang et al., 2018), and inadequate descriptive or visual documentation (Roy & Shaikh, 2024). Platform-level factors encompass security assurance mechanisms (Gong et al., 2019), payment option availability, interface intuitiveness, and information transparency (Kapoor & Vij, 2021). Psychological factors include decision confidence, perceived financial commitment magnitude (Rubin et al., 2020), and temporal urgency evaluation (Ong et al., 2022). Notably, systematic investigation into how AI recommendation system characteristics interact with cognitive processing capacities to influence abandonment decisions remains limited (Wu et al., 2024).

2.3. Cognitive Load Theory: Theoretical Foundations

Cognitive Load Theory posits that human cognitive resources operate under inherent capacity limitations (Sweller, 2019). This theory differentiates three categories of cognitive demands. Intrinsic load reflects the inherent complexity of the task itself—in booking contexts, this involves the fundamental complexity of evaluating numerous properties across multiple dimensions (Sweller et al., 1998). Extraneous load encompasses cognitive demands imposed by task presentation and design choices—how the platform structures information, sequences decisions, or visualizes options (Debue & Van De Leemput, 2014). Germane load represents cognitive resources devoted to constructing meaningful mental models and integrating new information with existing knowledge structures (Sweller et al., 1998). In CLT’s original formulation, germane load is the beneficial counterpart to intrinsic and extraneous load: it is the effort invested in schema construction, and instructional design typically seeks to protect, not minimize, it. We nonetheless model germane load as a component of the higher-order cognitive load construct predicting abandonment for a booking-specific reason rather than a learning-specific one: unlike a single learning episode in which schema construction is a one-time investment, a booking session under highly serendipitous or similar recommendations can require repeated re-construction of comparison criteria as new, unanticipated, or barely differentiated options are encountered. Germane effort that must be expended repeatedly, without ever resulting in a stable mental model the user can act on, still depletes finite working-memory resources within the time-bounded booking task, even though each individual instance of that effort is, in isolation, productive. It is this repeated, unresolved demand on a time-constrained task—not germane load as such—that we propose contributes to abandonment, and we flag this as a boundary condition on CLT’s original characterization of germane load rather than a contradiction of it.
The central proposition of Cognitive Load Theory suggests that excessive cognitive demands relative to available processing capacity degrade decision quality, reduce satisfaction with outcomes, and decrease likelihood of completing intended actions (Barta et al., 2022). Within hospitality booking contexts, when AI recommendation systems or platform design characteristics elevate overall cognitive load beyond user capacity, the theory predicts increased booking abandonment as users terminate processes perceived as cognitively exhausting. Research in educational contexts has demonstrated that cognitive overload impairs learning and task completion (Partarakis & Zabulis, 2023), with similar mechanisms likely operating in digital commerce environments (Fan et al., 2019).

2.4. Information Foraging Theory: Mechanisms of Decision Support

Information Foraging Theory characterizes how individuals navigate information-rich environments by employing strategies designed to optimize the ratio of information value obtained relative to search effort expended (Pirolli & Card, 1999). The theory emphasizes that information seekers evaluate available cues—termed ‘information scent’—to assess whether pursuing particular informational patches promises sufficient value justification (Pirolli & Fu, 2003). When information scent suggests limited relevant content, users terminate engagement with that information patch and redirect attention elsewhere (Yi et al., 2017).
Applied to AI-driven hotel booking contexts, Information Foraging Theory illuminates how users evaluate recommendation information scent. Recommendations characterized by strong information scent—apparent relevance and novelty—attract user attention and encourage deeper engagement (Liu et al., 2018). Conversely, recommendations perceived as offering limited relevance or presenting numerous redundant suggestions frustrate foraging goals and may trigger discontinuation of booking exploration (Li et al., 2017; Nakayama & Wan, 2020). The integration of Information Foraging Theory with Cognitive Load Theory provides a comprehensive understanding of how recommendation characteristics both attract user engagement and potentially overwhelm cognitive capacities (Dwivedi et al., 2019). Within the present model, the two recommendation characteristics under study map directly onto these IFT constructs: perceived serendipity reflects unanticipated information scent that diverges from a user’s existing search patch, while perceived similarity reflects redundant scent across the recommended patch of properties. Both conditions disrupt efficient foraging—the former by introducing cues that fall outside the user’s expected information diet, the latter by collapsing apparent scent differences across options—and it is this disruption, rather than IFT in isolation, that is hypothesized (H1–H4) to translate into the elevated cognitive load tested in the structural model below.

3. Conceptual Model and Research Hypotheses

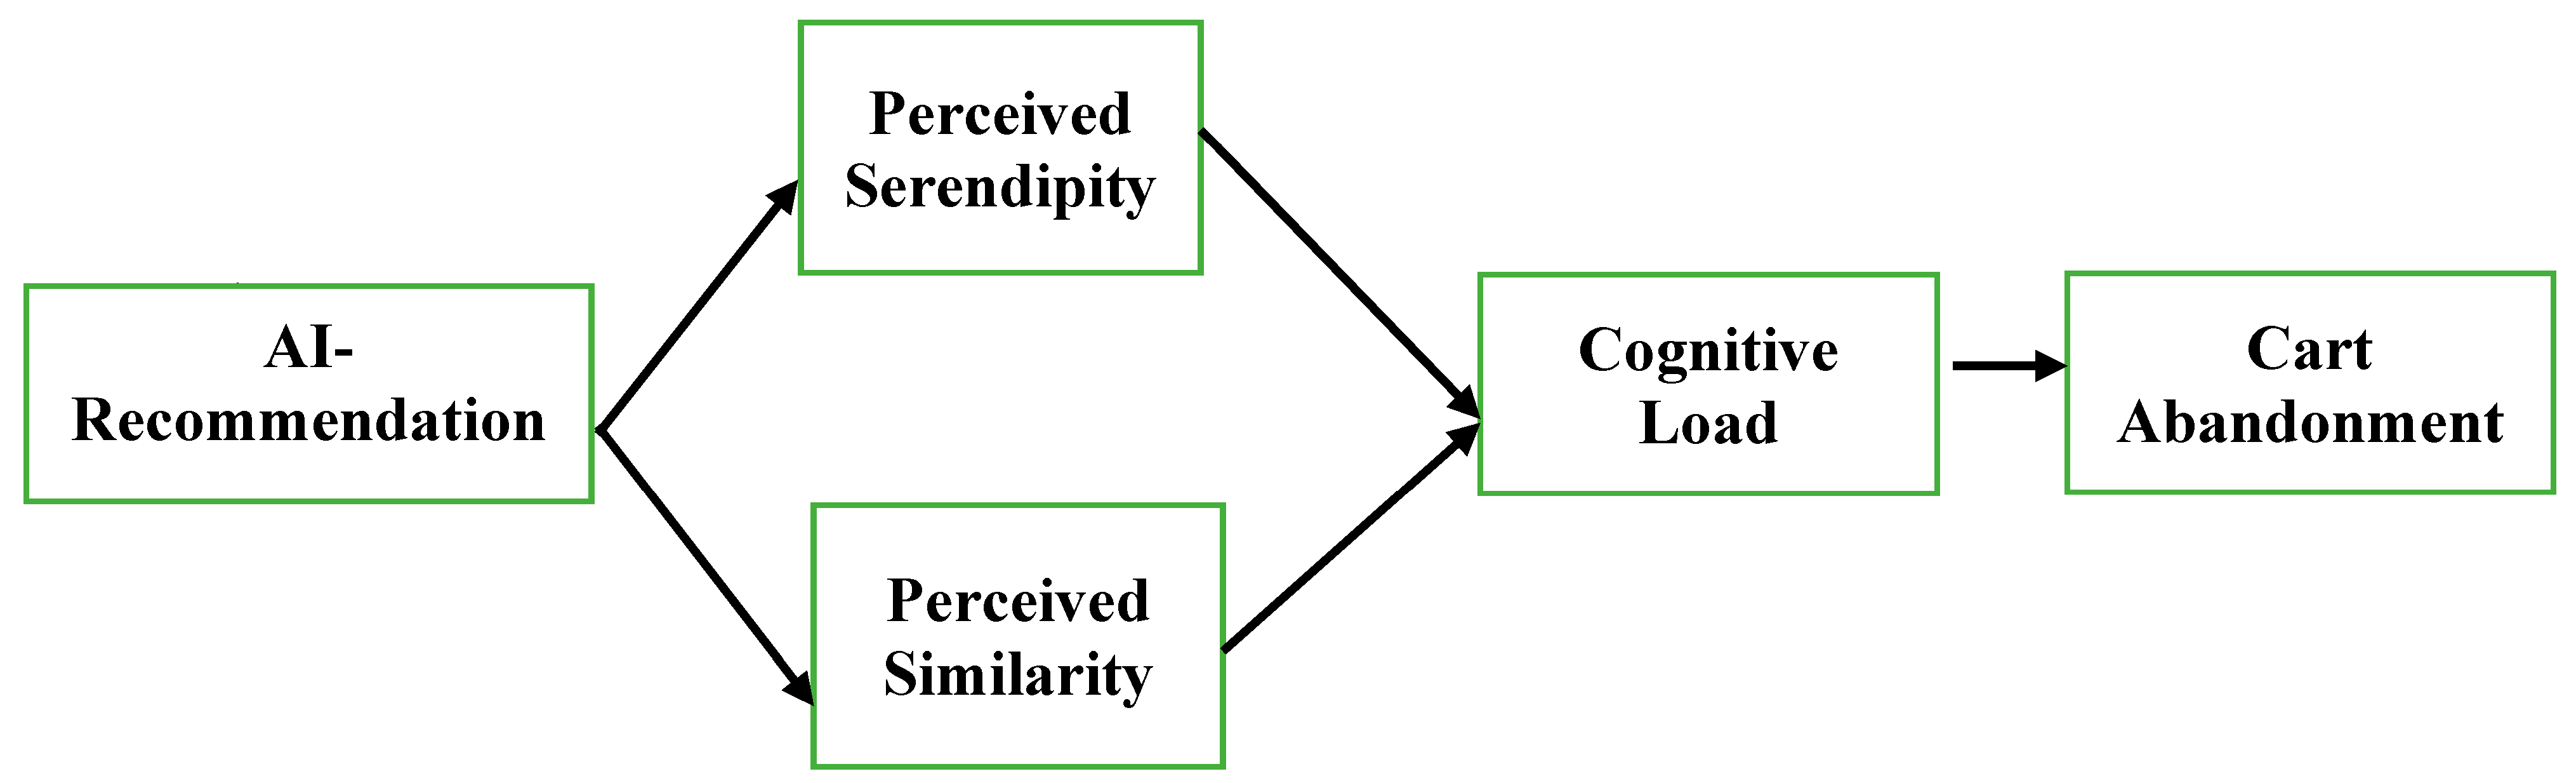
This investigation proposes an integrative model examining how AI recommendation characteristics generate cognitive load, which subsequently influences booking abandonment likelihood. The model identifies two primary recommendation characteristics—perceived serendipity and perceived similarity—as antecedents of cognitive load. Higher cognitive load, in turn, increases booking abandonment probability. This framework integrates contemporary understanding of algorithmic personalization (Christensen et al., 2024) with cognitive capacity constraints and digital commerce behavioral outcomes as shown in Figure 1.

Perceived Serendipity, Perceived Similarity, and Cognitive Load

Serendipitous discovery—the experience of encountering unexpected yet relevant options—represents an important dimension of algorithmic recommendations (Afridi & Outay, 2020; Ziarani & Ravanmehr, 2021). More personalized AI systems, by definition, generate suggestions more specifically tailored to individual preference profiles. This precise alignment paradoxically may increase perception of unexpected novelty if tailoring involves discovery of accommodation types, locations, or features previously unconsidered by the user. However, excessive serendipity creates cognitive conflict: users encounter options that challenge existing preference frameworks or require reconciling unexpected suggestions with established mental models (Reisenzein et al., 2019; Kim et al., 2021). This sits in tension with a substantial body of recommender-systems literature in which serendipity is treated as an unambiguously positive design goal that raises satisfaction and engagement (Yi et al., 2017; Ziarani & Ravanmehr, 2021). We propose that this tension is resolved by distinguishing the degree and timing of unexpectedness from its mere presence. Low-to-moderate serendipity—a suggestion adjacent to, but not disconnected from, the user’s existing preference structure—is more likely to be experienced as a welcome discovery, consistent with the positive framing in prior work. High serendipity encountered late in a time-pressured booking session, by contrast, forces costly revision of an already-forming decision frame rather than simply adding an option to an open consideration set, which is the condition under which we expect—and, in this study, find—serendipity to function as a cognitive burden. The present design cannot establish the precise threshold at which serendipity shifts from delight to burden; we flag this as a question for future experimental work that manipulates serendipity magnitude and timing directly (see Section 6.3).
H1. 
AI recommendation personalization intensity positively influences perceived serendipity in suggested accommodations.
H2. 
AI recommendation personalization intensity positively influences perceived similarity among suggested accommodations.
Conversely, highly personalized recommendations aggregate options closely matching user preference profiles. This concentration on preference-aligned properties naturally produces greater similarity among suggestions (Mejía et al., 2020). Users encounter multiple properties sharing common characteristics, price ranges, and locations. While such similarity theoretically facilitates comparison by emphasizing relevant differentiating attributes (Ahn et al., 2021), excessive similarity paradoxically increases cognitive demands by creating ‘choice overload’ situations where meaningful differentiation becomes difficult (Scheibehenne et al., 2010; Bollen et al., 2010).
H3. 
Elevated perceived serendipity in AI recommendations increases cognitive load during accommodation selection processes.
When recommendations present unexpected properties challenging existing mental frameworks, users must engage additional cognitive resources to evaluate and integrate these surprising options (Reisenzein et al., 2019; Skavronskaya et al., 2020). This increased mental effort—attempting to rationalize why unexpected properties might merit consideration, assessing compatibility with unstated needs, reconciling surprising suggestions with existing preferences—elevates cognitive load beyond the baseline demands of property evaluation (Wu et al., 2024).
H4. 
Elevated perceived similarity in AI recommendations increases cognitive load during accommodation selection processes.
Similarly, when recommendations present numerous options with substantive overlap, users must invest greater cognitive effort to identify meaningful differentiation (Barta et al., 2022). Excessive similarity creates ambiguity regarding which property distinction justifies selection. This comparison difficulty, combined with uncertainty regarding whether meaningful alternatives exist beyond the presented recommendations, elevates cognitive demands as users attempt discrimination among insufficiently differentiated options (Sarma et al., 2024).
H5. 
Cognitive load mediates the relationship between perceived serendipity in AI recommendations and booking cart abandonment.
H6. 
Cognitive load mediates the relationship between perceived similarity in AI recommendations and booking cart abandonment.
The mediation hypotheses propose that the path linking recommendation characteristics to abandonment operates through cognitive load elevation. Serendipity and similarity independently increase cognitive demands, which subsequently reduce completion likelihood (Varga & Albuquerque, 2023). This mediation pathway suggests that interventions targeting cognitive load reduction might indirectly mitigate abandonment, regardless of recommendation content itself (Sarma et al., 2024).
H7. 
Elevated cognitive load during accommodation selection significantly increases the probability of booking cart abandonment.
This direct effect hypothesis proposes that when cognitive demands exceed user capacity, users experience motivation to terminate engagement. Abandoning the booking process represents a rational response to perceived cognitive overwhelm, allowing users to defer decisions until cognitive resources are replenished or to switch to alternative accommodation discovery strategies perceived as less demanding (Chernev et al., 2015; Sethuraman et al., 2022).

4. Research Methodology

4.1. Research Design and Sample

This investigation employs a cross-sectional survey design targeting Indian consumers with recent hotel booking experience using AI recommendation features. Respondents were drawn from the user communities of three online travel platforms—MakeMyTrip, Agoda, and Goibibo—via their respective Instagram community groups, from which publicly available email addresses of members reporting hotel-booking experience were identified. Because all three platforms deploy comparable AI-based recommendation functionality (personalized property suggestions generated from browsing and booking history) and respondents were screened on their experience with this functionality rather than on platform identity, responses across the three platforms were treated as a single sample reflecting a common underlying phenomenon—consumer experience of AI-generated hotel recommendations—rather than platform-specific effects. This pooling decision reflects a conceptual rather than a purely statistical argument: because the survey items assess respondents’ generic experience of personalized suggestion features (Section 4.2) rather than any platform-specific interface element, and because respondents across all three platforms were screened using an identical operational definition of AI recommendation use, the underlying construct being measured is common across platforms even though the platforms’ proprietary algorithms may differ in their internal logic. We did not, however, formally test measurement invariance across the three platform sub-samples, and we flag this—rather than the pooling decision itself—as the more precise methodological caveat, which we now state explicitly in Section 6.3. In this study, “AI recommendations” refers specifically to personalized property-suggestion features (as opposed to generative AI assistants or general search ranking), operationalized through three items capturing reliance on, and time invested in, these suggestions. Consistent with this definition, survey items referred generically to the platform’s personalized property-suggestion feature—the type of module commonly labelled “Recommended for you” or “Similar properties you may like” across booking platforms—rather than to any single named on-screen element, since the specific interface label differs across MakeMyTrip, Agoda, and Goibibo even though the underlying function (algorithmically generated, preference-based property suggestions) is common to all three. Respondents were not asked to evaluate search ranking, pricing algorithms, or generative AI chat features, which fall outside the scope of “AI recommendations” as operationalized here. Respondents received invitations to complete a 37-item questionnaire administered through SurveyMonkey (Podsakoff, 2003). A screening question restricted participation to individuals who had utilized AI recommendation features while booking accommodations online within the previous twelve months.
Platform of origin (MakeMyTrip, Agoda, or Goibibo) was recorded for each respondent at the point of recruitment, which would make a formal invariance test possible in a future confirmatory study. For the present, exploratory study (Section 1.2), we instead treat the pooling decision as defining the scope of our claims: because measurement invariance and between-platform comparability were not formally tested, the reported paths characterize AI recommendation experience among the pooled community of respondents across these three platforms treated as a single population, and we neither claim nor imply that the effects are uniform across, or generalizable beyond, this pooled sample. This is a stated boundary condition on what the study shows, not a gap we treat as already resolved.
Among 5410 questionnaires distributed between 10 October and 10 November 2024, 668 individuals responded. After excluding observations with straight-lining (e.g., identical responses across 15 or more consecutive items) and other data-quality flags, 624 valid responses were retained for analysis (Cohen, 2013), corresponding to a 12.3% response rate. We acknowledge this rate is lower than the figure originally reported and, while not atypical for unsolicited social-media-sourced samples, raises the same non-response bias concern noted below: more digitally engaged community members were more likely to respond.
Sample characteristics demonstrate appropriate demographic diversity. Gender distribution comprised 245 males (39.3%) and 379 females (60.7%), reflecting gender dynamics within online hotel booking user populations (Media Infoline, 2024). Age distribution concentrated among 20–39 year-olds (69.9%), matching documented demographic patterns of active online travel consumers (KANTAR & IAMAI, 2023). Educational attainment indicated 89% possessed bachelor’s or advanced degrees, suggesting appropriate respondent capacity for comprehending complex survey items (Nigam et al., 2022). Booking platform experience revealed 75% had utilized online hotel reservations for more than four years, ensuring substantial familiarity with digital hospitality commerce processes.

4.2. Measurement Instruments

All measurement items employed five-point Likert scales (1 = Strongly Disagree, 5 = Strongly Agree) to assess construct dimensions. AI recommendation system quality was measured through three items adapted from Kankanhalli et al. (2005) and Venkatesh et al. (2003), assessing perceived appropriateness of suggestions and prediction accuracy in matching user preferences. Perceived serendipity was measured through four items from Yi et al. (2017) examining the subjective experience of discovering unexpected yet relevant property suggestions. Perceived similarity was measured through four items from Barta et al. (2022) evaluating the extent to which recommended properties demonstrated substantive overlap in characteristics and attributes.
Cognitive load was conceptualized as a multidimensional construct comprising three components adapted from Leppinks et al. (2013). Intrinsic load—reflecting fundamental task complexity—was measured through three items. Extraneous load—reflecting unnecessary cognitive demands imposed by information presentation—was measured through three items. Germane load—reflecting cognitive resources devoted to meaningful learning and mental model construction—was measured through four items (Debue & Van De Leemput, 2014). This operationalization follows established measurement approaches within cognitive load literature (Sweller, 2019).
Booking cart abandonment was measured through four items from Kukar-Kinney and Close (2009) assessing abandonment frequency, time interval between property selection and decision finalization, and propensity to defer booking decisions. Control variables included demographic factors (age, gender, education), booking platform tenure, and contextual factors (cost sensitivity, use of cart for comparison versus genuine purchase evaluation). Harman’s single-factor test (Podsakoff, 2003), examining common method bias, demonstrated that the first factor explained only 48.88% of total variance, substantially below the 50% threshold indicative of problematic common method effects.

4.3. Analysis Approach

Structural equation modeling employing partial least squares methodology via Smart PLS 4.0 (Sarstedt et al., 2022) was utilized for analysis. The analysis proceeded through sequential stages: (1) measurement model evaluation assessing reliability and validity; (2) higher-order construct validation examining cognitive load dimensionality; (3) goodness-of-fit assessment using standardized root mean square residual (SRMR) criteria (Hu & Bentler, 1999); and (4) structural model estimation examining hypothesized relationships and mediating mechanisms. Composite reliability (Hair et al., 2013), average variance extracted (Sarstedt et al., 2020), and Fornell-Larcker criteria (Fornell & Larcker, 1981) assessed measurement quality. Bootstrap resampling procedures (5000 iterations) generated confidence intervals and significance testing for path coefficients (Soper, 2023).
Two further checks would strengthen a confirmatory version of this model. The Heterotrait–Monotrait ratio (HTMT; Henseler et al., 2015) is a stricter discriminant validity test than Fornell–Larcker and would be particularly informative for perceived serendipity and perceived similarity, the highest-correlated construct pair in this study. A common method bias test beyond Harman’s single-factor test, such as the unmeasured latent method factor technique (Podsakoff, 2003), would likewise strengthen confidence that the reported paths are not inflated by shared method variance. Consistent with the exploratory, hypothesis-generating status of this study (Section 1.1), we rely here on Fornell–Larcker and Harman’s single-factor tes-he discriminant-validity and common-method-bias screens conventionally reported at this stage of theory development—and we present the resulting path estimates as a preliminary pattern rather than a confirmatory finding. We identify HTMT and the unmeasured latent method factor technique as the specific tests a confirmatory replication should apply before these patterns are treated as established effects.

5. Results

5.1. Measurement Model Assessment

Measurement model evaluation confirmed adequate reliability and validity. Composite reliability values ranged from 0.834 to 0.927, substantially exceeding the 0.70 threshold recommended by Hair et al. (2013). Average variance extracted values ranged from 0.617 to 0.881, surpassing the 0.50 benchmark established by Sarstedt et al. (2020). All item loadings exceeded 0.60 as per Hair et al. (2013) recommendations, indicating appropriate convergent validity. Fornell and Larcker (1981) discriminant validity assessment confirmed that each construct’s average variance extracted exceeded squared correlations with other constructs, demonstrating adequate discriminant validity. Higher-order cognitive load construct validation, following Sarstedt et al. (2022) methodology, confirmed the multidimensional structure, with intrinsic, extraneous, and germane components substantively contributing to the latent factor. Item-level descriptive statistics (means, standard deviations) and loadings are reported in Table 1, and the discriminant validity matrix is reported in Table 2, below.
To make the quality indicators in Table 1 interpretable independent of the thresholds cited above, each captures a distinct property of the measurement model. Item loadings indicate how strongly an individual survey item reflects its intended construct, with higher values showing the item is a purer indicator of that construct and not of something else; the lowest loading retained here (AI3 = 0.601) is close to the conventional 0.60 floor and was retained only because dropping it did not materially improve composite reliability or AVE for that construct. Cronbach’s alpha and composite reliability (CR) both estimate internal consistency-whether the items measuring a construct move together—with CR generally preferred in PLS-SEM because it does not assume all items are equally reliable; the two indicators agree closely for every construct in Table 1. Average variance extracted (AVE) indicates the average proportion of item variance explained by the construct itself rather than by measurement error, and is the basis for the Fornell–Larcker discriminant validity test reported in Table 2: a construct’s AVE exceeding its squared correlation with every other construct indicates the construct shares more variance with its own items than with items belonging to other constructs. As Section 4.3 notes, this study relies on Fornell–Larcker alone; the HTMT criterion, a stricter test better suited to conceptually adjacent constructs, has not yet been computed and is reported as a required next step rather than a completed check.

5.2. Structural Model Results

Structural model estimation supported most hypothesized relationships. AI recommendation personalization demonstrated strong positive effects on both perceived serendipity (β = 0.777, t = 43.538, p < 0.001) and perceived similarity (β = 0.824, t = 49.841, p < 0.001), supporting H1 and H2. Both recommendation characteristics independently elevated cognitive load: perceived serendipity (β = 0.518, t = 22.037, p < 0.001) and perceived similarity (β = 0.464, t = 19.103, p < 0.001), confirming H3 and H4. Cognitive load demonstrated a direct effect on booking cart abandonment (β = 0.530, t = 13.387, p < 0.001), strongly confirming H7 that elevated cognitive demands increase abandonment likelihood.
Mediation analysis following the bootstrapping procedures recommended by Hair et al. (2013) confirmed significant indirect pathways. The effect of serendipity on abandonment through cognitive load was substantial (β = 0.214, t = 13.706, p < 0.001), supporting H5. The effect of similarity on abandonment through cognitive load was also significant (β = 0.203, t = 8.607, p < 0.001), supporting H6. These results indicate that cognitive load represents the critical mechanism through which recommendation characteristics influence abandonment behaviors. Among control variables, cost concerns positively predicted abandonment, while using the reservation cart as a comparison tool reduced abandonment likelihood, consistent with findings from Kukar-Kinney and Close (2009).

5.3. Model Fit and Predictive Capacity

Model fit assessment, employing standardized root mean square residual (SRMR) criteria per Hu and Bentler (1999), indicated borderline model specification. The SRMR of 0.104 exceeded the conventional 0.08 threshold recommended by Hu and Bentler (1999); we report this value transparently as a study limitation rather than reinterpreting it as acceptable, since we are not aware of a published criterion that relaxes the threshold to 0.10 for PLS path models of this complexity. R-squared values indicate the proportion of variance in each endogenous construct explained by its antecedents (not the reverse): AI-driven personalization explained 60.4% of the variance in perceived serendipity (R2 = 0.604) and 68.0% of the variance in perceived similarity (R2 = 0.680); perceived serendipity and perceived similarity jointly explained 89.9% of the variance in cognitive load (R2 = 0.899); and cognitive load, together with the control variables, explained 80.4% of the variance in booking cart abandonment (R2 = 0.804). The R2 for cognitive load is unusually high for consumer behavior research; we discuss this, and the steps taken to assess common method bias beyond Harman’s single-factor test, in Section 6.3 (Limitations).

6. Discussion

6.1. Theoretical Contributions

This investigation contributes to hospitality consumer behavior scholarship through multiple theoretical pathways. First, while existing literature emphasizes algorithmic technical advancement and accuracy metrics (Konstan & Riedl, 2012; Afoudi et al., 2021), this research shifts focus to consumer-side experience dimensions. By examining how serendipity and similarity in AI recommendations influence user cognition (Yi et al., 2017; Faraji-Rad & Pham, 2017), this work advances understanding of the phenomenological experience of algorithmic mediation in hospitality contexts. This consumer-centric perspective complements and extends existing technical-focused research (Dwivedi et al., 2019).
Second, the investigation operationalizes Cognitive Load Theory within hospitality digital commerce contexts, distinguishing intrinsic, extraneous, and germane load components (Leppinks et al., 2013; Debue & Van De Leemput, 2014). This operationalization extends cognitive load theory beyond traditional educational applications (Partarakis & Zabulis, 2023) to investigate how choice architecture and recommendation characteristics interact with cognitive capacity limitations to influence consequential behaviors (booking completion versus abandonment) (Sweller, 2019). The present pattern of associations is consistent with cognitive load theory’s applicability to hospitality commerce outcomes (Fan et al., 2019); we frame this as support for, rather than a validation of, the theory’s extension to this domain, since a single cross-sectional study cannot establish that the theorized mechanism, as opposed to an alternative explanation for the same correlational pattern, is the one actually operating.
Third, the integration of Cognitive Load Theory with Information Foraging Theory (Pirolli & Card, 1999; Li et al., 2017) provides a comprehensive framework explaining how algorithmic systems simultaneously support and potentially hinder user decision processes. Information Foraging Theory illuminates how recommendation characteristics influence user engagement and information-seeking persistence (Nakayama & Wan, 2020; Yi et al., 2017), while Cognitive Load Theory explains how these engagement patterns interact with cognitive resource limitations to determine behavioral outcomes (Sweller, 2019). This dual-theory approach advances integrated understanding of AI-mediated decision environments (Dwivedi et al., 2019).
A note on interpretive status: the three contributions above are theoretical framings that this study’s results are consistent with, not claims the data directly establish. What the data directly establish is narrower and is restated at the start of Section 6.1’s successor paragraph below: two self-reported recommendation characteristics (serendipity, similarity) are associated with a self-reported cognitive-load measure, which is in turn associated with a self-reported abandonment measure, in a single cross-sectional Indian sample. The theoretical interpretation of why these associations hold—in terms of working-memory capacity, information scent, and information-patch disruption—is a plausible and literature-consistent account, not an independently tested one; competing accounts (for example, that both cognitive load and abandonment items simply share respondent-level negative affect, addressed as a common-method-bias question in Section 4.3) cannot be ruled out on the present evidence.
Beyond these three theoretical pathways, the pattern of results itself merits closer interpretation, since it clarifies where the study’s scientific contribution lies. The near-complete mediation of the serendipity–abandonment and similarity–abandonment relationships through cognitive load (indirect effects of β = 0.214 and β = 0.203, respectively, against a total cognitive-load-to-abandonment effect of β = 0.530) indicates that recommendation characteristics do not appear to drive abandonment directly; instead, their association with abandonment runs almost entirely through their association with users’ processing demands. This is a substantively different claim from the one implicit in prior work linking serendipity or assortment similarity directly to disengagement (e.g., Wu et al., 2024; Scheibehenne et al., 2010): it relocates the proposed mechanism from the content of the recommendation itself to the finite cognitive resources available to the user evaluating it, and this relocation of mechanism—rather than the existence of the serendipity–abandonment or similarity–abandonment associations on their own—is the study’s central contribution. Practically, this reframing implies that the lever available to platforms is not the wholesale elimination of serendipitous or similar suggestions, both of which remain, in moderation, desirable design goals elsewhere in the recommender-systems literature (Yi et al., 2017; Ahn et al., 2021); rather, it is the management of the cognitive burden such suggestions impose, for example through interface support that reduces extraneous load without suppressing the informational value of the recommendations themselves.

6.2. Managerial Implications

These findings yield direct implications for online travel agency strategic decision-making and platform optimization. While AI recommendation implementation aims to enhance user experience and facilitate conversion (Bawack et al., 2022), the associations reported here suggest—though, given the cross-sectional design, do not confirm—that excessive personalization, producing either high serendipity or high similarity, coincides with elevated cognitive demand and greater abandonment (Wu et al., 2024). The recommendations below should accordingly be read as hypotheses for platforms to test via their own A/B experimentation, not as findings whose effectiveness this study has already demonstrated. Platforms should recalibrate recommendation algorithms to balance personalization intensity with cognitive load management (Shin, 2020).
Specifically, recommendation systems should be designed to present moderate novelty—suggesting properties with meaningful differentiation from user baselines without introducing overwhelming unexpectedness (Reisenzein et al., 2019; Kim et al., 2021). Similarly, recommendation sets should balance specificity with diversity, avoiding recommendation clusters with excessive feature overlap that creates false choice proliferation (Scheibehenne et al., 2010; Bollen et al., 2010). User-controllable recommendation filtering mechanisms might empower users to adjust personalization intensity to match their cognitive preferences (Cremonesi et al., 2016).
Additionally, platform interface design should minimize extraneous cognitive load through improved information architecture, logical decision sequencing, and visual emphasis on meaningful property differentiators (Debue & Van De Leemput, 2014; Plass & Kalyuga, 2019). Providing comparison tools explicitly highlighting property distinctions, offering reduced-choice decision paths for time-pressured users, and implementing progressive disclosure of property attributes could mitigate cognitive overwhelming (Fan et al., 2019).
Furthermore, recognizing that cost concerns strongly predict abandonment (consistent with findings by Kapoor & Vij, 2021) suggests that pricing transparency, offering price-matching guarantees, and clearly communicating total fees facilitate completion. Platforms should highlight value justification and reduce pricing uncertainty through transparent cost presentation (Gong et al., 2019).

6.3. Limitations and Future Research Directions

This investigation is subject to several limitations warranting acknowledgment. The cross-sectional design precludes causal inference, and language throughout this paper describing relationships among constructs should be read as associative rather than causal. A further validity concern, not previously acknowledged, is that perceived serendipity and perceived similarity were measured through self-report: most consumers cannot reliably identify which features of a recommendation interface are AI-driven, nor accurately recall the specific characteristics of recommendations encountered during a past booking session. Our items therefore capture respondents’ retrospective impressions of recommendation novelty and overlap rather than verified properties of the algorithmic output itself; this is a limitation common to self-report studies of algorithmic experience and warrants triangulation with behavioral or clickstream data in future work. A concrete remedy for future studies is a manipulation check comparing respondents’ self-reported recommendation exposure against platform-side logs of what was actually served to them; absent such verification here, we restrict our conclusions throughout this paper to how users experience and respond to what they take to be AI-generated suggestions, rather than to the causal properties of the underlying recommendation algorithms themselves, and we have edited residual instances of the latter, stronger framing where we found them. This constraint is particularly salient for perceived serendipity and perceived similarity, both of which presuppose that respondents can attribute a given suggestion to the platform’s algorithm rather than to their own memory, general browsing, or non-personalized listings; our design cannot verify this attribution. Accordingly, the reported associations should be interpreted as reflecting respondents’ subjective impressions of the recommendation environment rather than objectively verified properties of the underlying algorithmic output, and we have revised the wording of our claims throughout the paper to reflect this distinction. Self-reported data also introduce common method bias risk more broadly; Harman’s single-factor test (Podsakoff, 2003) indicated the first factor explained 48.88% of variance, but this test is increasingly viewed as an insufficient sole safeguard against common method bias, and we did not additionally implement a marker-variable or unmeasured-latent-method-factor test; this is noted as a constraint on the strength of the CMB conclusion rather than a resolved concern. The sample, while spanning three major platforms, was drawn from the Instagram community followers of MakeMyTrip, Agoda, and Goibibo rather than from a single platform’s full user base or via probability sampling, and from Indian respondents specifically; both factors may limit generalizability to other booking platforms, recruitment channels, and cultural contexts where digital commerce attitudes, cognitive processing patterns, and technology trust operate differently (Nigam et al., 2022). The 12.3% response rate, while not unusual for survey research conducted through social-media-based outreach, raises potential non-response bias concerns favoring more digitally engaged respondents.
Consolidated response to the discriminant validity, common method bias, and sample-pooling concerns raised in review: three of the methodological issues raised in review—discriminant validity beyond Fornell–Larcker, a common method bias test beyond Harman’s single-factor test, and formal measurement invariance across the three recruitment platforms—are related in that each asks whether the reported path coefficients reflect the hypothesized constructs specifically, rather than shared method variance, overlapping constructs, or an inappropriately pooled sample. Rather than treat this as an outstanding checklist item, we have revised the status of the entire study accordingly: Section 1.2 now states explicitly that this is an exploratory, hypothesis-generating study, not a confirmatory one, precisely because these three checks have not been performed. We identify the single pair of constructs (perceived serendipity and perceived similarity, r = 0.861) for which the discriminant validity concern is most acute, and we specify, in Section 4.1 and Section 4.3, the exact tests—permutation-based MICOM, HTMT, and the unmeasured latent method factor technique—that a confirmatory replication would need to apply. We consider this an honest characterization of what the present, pooled, self-report, cross-sectional evidence supports: a preliminary pattern worth reporting and worth testing further, not a fully validated effect.
Future investigations should employ longitudinal designs examining how familiarity with AI recommendations influences cognitive load and abandonment over extended periods (Wang et al., 2024). Behavioral data collection—clickstream patterns, session duration, eye-tracking during recommendation engagement—would provide objective measures supplementing self-reported cognition (Shi et al., 2020). Cross-cultural replication would establish boundary conditions for the proposed relationships (Yang et al., 2024). Experimental manipulation of recommendation serendipity and similarity would enable stronger causal inference than observational designs permit (Christensen et al., 2024).
Investigation of moderating mechanisms warrants attention. Do individual differences in cognitive style, technology comfort, or personality dimensions (e.g., openness to experience, need for cognitive closure) moderate the relationship between recommendations and cognitive load (Deck & Jahedi, 2015; Drichoutis & Nayga, 2020)? Do temporal pressures or booking urgency influence how recommendation characteristics affect abandonment (Ong et al., 2022)? Examination of these potential moderators would enhance theoretical sophistication and practical applicability (Sethuraman et al., 2022).

7. Conclusions

This investigation provides cross-sectional evidence that AI recommendation characteristics are associated with booking abandonment through cognitive load mechanisms (Sweller, 2019). Perceived serendipity and similarity in algorithmic suggestions are each independently associated with elevated cognitive processing demands, which in turn are associated with greater booking abandonment likelihood; because the design is cross-sectional, these relationships should be interpreted as associative rather than as established causal pathways. These findings contrast with popular industry narratives suggesting that AI personalization uniformly enhances user experience and conversion. Rather, the relationship proves more nuanced: excessive personalization can overwhelm cognitive capacities and precipitate abandonment (Wu et al., 2024; Sarma et al., 2024).
For online travel agencies and hospitality technology providers, these preliminary results tentatively point to the value of calibrating recommendation algorithm parameters to balance personalization benefits against cognitive load risks (Bawack et al., 2022); we frame this as a hypothesis for platforms to test through their own experimentation rather than a demonstrated prescription. Cognitive limitations plausibly represent real constraints on user capacity to process information and make confident decisions (Debue & Van De Leemput, 2014), consistent with the pattern observed here. On this basis, strategic implementation of cognitive load reduction through recommendation refinement, interface optimization, and progressive information disclosure is a promising avenue to test for improving conversion metrics and reducing abandonment (Fan et al., 2019; Plass & Kalyuga, 2019).
The integration of Cognitive Load Theory and Information Foraging Theory provides a valuable framework for understanding AI-mediated decision environments. As artificial intelligence applications proliferate across digital commerce contexts, understanding these mechanisms becomes increasingly critical for both academics and practitioners (Dwivedi et al., 2019; Christensen et al., 2024). Future research advancing theoretical understanding of human-AI interaction and empirically validating optimization strategies will continue advancing this vital domain of hospitality commerce and consumer behavior research. As Section 1.1 makes explicit, the present findings are offered as a preliminary, exploratory pattern rather than a confirmed effect; the natural next step is a confirmatory replication that applies permutation-based measurement-invariance testing across recruitment platforms, the HTMT discriminant-validity criterion, and a common-method-bias test beyond Harman’s single-factor test to establish whether the pattern reported here holds under stricter methodological scrutiny.

Author Contributions

Conceptualization, A.P.; Methodology, A.P.; Formal analysis, G.V.M.S.; Validation, G.V.M.S.; Writing—original draft preparation, A.P.; Writing—review and editing, U.B., G.V.M.S. and A.G.H.; Supervision, U.B.; Project administration, U.B. All authors have read and agreed to the published version of the manuscript.

Funding

This research received no external funding.

Data Availability Statement

The data presented in this study are available on request from the corresponding author. The data are not publicly available due to privacy and confidentiality considerations associated with the survey respondents.

Conflicts of Interest

The authors declare no conflict of interest.

References

  1. Afoudi, Y., Lazaar, M., & Achhab, M. A. (2021). Hybrid recommendation system combined content-based filtering and collaborative prediction using artificial neural network. Simulation Modelling Practice and Theory, 113, 102375. [Google Scholar] [CrossRef] [Scilit]
  2. Afridi, A. H., & Outay, F. (2020). Triggers and connection-making for serendipity via user interface in recommender systems. Personal and Ubiquitous Computing, 25(1), 77–92. [Google Scholar] [CrossRef] [Scilit]
  3. Ahn, J., Kim, J., & Sung, Y. (2021). AI-powered recommendations: The roles of perceived similarity and psychological distance on persuasion. International Journal of Advertising, 40(8), 1366–1384. [Google Scholar] [CrossRef] [Scilit]
  4. Alamdari, P. M., Navimipour, N. J., Hosseinzadeh, M., Safaei, A. A., & Darwesh, A. (2020). A systematic study on the recommender systems in the E-commerce. IEEE Access, 8, 115694–115716. [Google Scholar] [CrossRef] [Scilit]
  5. Barta, S., Gurrea, R., & Flavián, C. (2022). Using augmented reality to reduce cognitive dissonance and increase purchase intention. Computers in Human Behavior, 140, 107564. [Google Scholar]
  6. Bawack, R. E., Wamba, S. F., Carillo, K. D. A., & Akter, S. (2022). Artificial intelligence in E-commerce: A bibliometric study and literature review. Electronic Markets, 32(1), 297–338. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  7. Bollen, D., Knijnenburg, B. P., Willemsen, M. C., & Graus, M. (2010, September 26–30). Understanding choice overload in recommender systems. 2010 ACM Conference (pp. 63–70), Barcelona, Spain. [Google Scholar]
  8. Chernev, A., Böckenholt, U., & Goodman, J. (2015). Choice overload: A conceptual review and meta-analysis. Journal of Consumer Psychology, 25(2), 333–358. [Google Scholar]
  9. Christensen, J., Hansen, J. M., & Wilson, P. (2024). Understanding the role and impact of generative artificial intelligence hallucination within consumers’ tourism decision-making processes. Current Issues in Tourism, 27(1), 1–16. [Google Scholar]
  10. Cohen, J. (2013). Statistical power analysis for the behavioral sciences. Routledge. [Google Scholar]
  11. Cremonesi, P., Elahi, M., & Garzotto, F. (2016). User interface patterns in recommendation-empowered content intensive multimedia applications. Multimedia Tools and Applications, 76(4), 5275–5309. [Google Scholar] [CrossRef] [Scilit]
  12. Debue, N., & Van De Leemput, C. (2014). What does germane load mean? An empirical contribution to the cognitive load theory. Frontiers in Psychology, 5, 1099. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  13. Deck, C., & Jahedi, S. (2015). The effect of cognitive load on economic decision making: A survey and new experiments. European Economic Review, 78, 97–119. [Google Scholar] [CrossRef] [Scilit]
  14. Drichoutis, A. C., & Nayga, R. M. (2020). Economic rationality under cognitive load. The Economic Journal, 130(632), 2382–2409. [Google Scholar] [CrossRef] [Scilit]
  15. Dwivedi, Y. K., Hughes, L., Ismagilova, E., Aarts, G., Coombs, C., Crick, T., Duan, Y., Dwivedi, R., Edwards, J., Eirug, A., Galanos, V., Ilavarasan, P. V., Janssen, M., Jones, P., Kar, A. K., Kizgin, H., Kronemann, B., Lal, B., Lucini, B., … Williams, M. D. (2019). Artificial intelligence: Multidisciplinary perspectives on emerging challenges, opportunities, and agenda for research, practice and policy. International Journal of Information Management, 57, 101994. [Google Scholar]
  16. Fan, X., Chai, Z., Deng, N., & Dong, X. (2019). Adoption of augmented reality in online retailing and consumers’ product attitude: A cognitive perspective. Journal of Retailing and Consumer Services, 53, 101986. [Google Scholar]
  17. Faraji-Rad, A., & Pham, M. T. (2017). Uncertainty increases the reliance on affect in decisions. Journal of Consumer Research, 44(1), 1–21. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  18. Fornell, C., & Larcker, D. F. (1981). Structural equation models with unobservable variables and measurement error. Journal of Marketing Research, 18(3), 382–388. [Google Scholar] [CrossRef] [Scilit]
  19. Gelder, K. V. (2024). Shopping cart abandonment rate worldwide 2022, by industry. Statista. [Google Scholar]
  20. Gong, X., Zhang, K. Z., Chen, C., Cheung, C. M., & Lee, M. K. (2019). What drives trust transfer from web to mobile payment services? Information and Management, 57(7), 103250. [Google Scholar]
  21. Hair, J. F., Ringle, C. M., & Sarstedt, M. (2013). Partial least squares structural equation modeling: Rigorous applications, better results and higher acceptance. Long Range Planning, 46(1–2), 1–12. [Google Scholar] [CrossRef] [Scilit]
  22. Henseler, J., Ringle, C. M., & Sarstedt, M. (2015). A new criterion for assessing discriminant validity in variance-based structural equation modeling. Journal of the Academy of Marketing Science, 43(1), 115–135. [Google Scholar] [CrossRef] [Scilit]
  23. Hu, L., & Bentler, P. M. (1999). Cutoff criteria for fit indexes in covariance structure analysis. Structural Equation Modeling, 6(1), 1–55. [Google Scholar] [CrossRef] [Scilit]
  24. Huang, G., Korfiatis, N., & Chang, C. (2018). Mobile shopping cart abandonment: The roles of conflicts, ambivalence, and hesitation. Journal of Business Research, 85, 165–174. [Google Scholar] [CrossRef] [Scilit]
  25. Kankanhalli, N., Tan, N., & Wei, N. (2005). Contributing knowledge to electronic knowledge repositories: An empirical investigation. MIS Quarterly, 29(1), 113–143. [Google Scholar] [CrossRef] [Scilit]
  26. KANTAR & IAMAI. (2023). Internet in India 2023 report. Media Infoline. [Google Scholar]
  27. Kapoor, A. P., & Vij, M. (2021). Following you wherever you go: Mobile shopping cart-checkout abandonment. Journal of Retailing and Consumer Services, 61, 102553. [Google Scholar] [CrossRef] [Scilit]
  28. Kim, A., Affonso, F. M., Laran, J., & Durante, K. M. (2021). Serendipity: Chance encounters in the marketplace enhance consumer satisfaction. Journal of Marketing, 85(4), 141–157. [Google Scholar] [CrossRef] [Scilit]
  29. Konstan, J. A., & Riedl, J. (2012). Recommender systems: From algorithms to user experience. User Modeling and User-Adapted Interaction, 22(1–2), 101–123. [Google Scholar] [CrossRef] [Scilit]
  30. Kukar-Kinney, M., & Close, A. G. (2009). The determinants of consumers’ online shopping cart abandonment. Journal of the Academy of Marketing Science, 38(2), 240–250. [Google Scholar] [CrossRef] [Scilit]
  31. Laporte, S., & Briers, B. (2018). Similarity as a double-edged sword. Journal of Consumer Research, 45(6), 1331–1349. [Google Scholar]
  32. Lee, D., & Hosanagar, K. (2020). How do product attributes and reviews moderate the impact of recommender systems? Management Science, 67(1), 524–546. [Google Scholar]
  33. Leppinks, J., Paas, F., Van Der Vleuten, C. P. M., Van Gog, T., & Van Merriënboer, J. J. G. (2013). Development of an instrument for measuring different types of cognitive load. Behavior Research Methods, 45(4), 1058–1072. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  34. Li, M., Tan, C., Wei, K., & Wang, K. (2017). Sequentiality of product review information provision. MIS Quarterly, 41(3), 867–892. [Google Scholar] [CrossRef] [Scilit]
  35. Liu, D., Chou, Y., Chung, C., & Liao, H. (2018). Recommender system based on social influence and the virtual house bandwagon effect. Kybernetes, 47(3), 587–604. [Google Scholar] [CrossRef] [Scilit]
  36. Lu, J., Wu, D., Mao, M., Wang, W., & Zhang, G. (2015). Recommender system application developments: A survey. Decision Support Systems, 74, 12–32. [Google Scholar] [CrossRef] [Scilit]
  37. Mayer, C. J., Mahal, J., Geisel, D., Geiger, E. J., Staatz, E., Zappel, M., Lerch, S. P., Ehrenthal, J. C., Walter, S., & Ditzen, B. (2024). User preferences and trust in hypothetical analog, digitalized and AI-based medical consultation scenarios. Computers in Human Behavior, 161, 108419. [Google Scholar] [CrossRef] [Scilit]
  38. Media Infoline. (2024). Internet in India 2023 report by IAMAI and Kantar. Media Infoline. [Google Scholar]
  39. Mejía, V. D., Aurier, P., & Huaman-Ramirez, R. (2020). Disentangling the respective impacts of assortment size and alignability on perceived assortment variety. Journal of Retailing and Consumer Services, 59, 102386. [Google Scholar]
  40. Nakayama, M., & Wan, Y. (2020). A quick bite and instant gratification: A simulated Yelp experiment on consumer review information foraging behavior. Information Processing and Management, 58(1), 102391. [Google Scholar] [CrossRef] [Scilit]
  41. Nigam, A., Dewani, P., Behl, A., & Pereira, V. (2022). Consumer’s response to conditional promotions in retailing: An empirical inquiry. Journal of Business Research, 144, 751–763. [Google Scholar] [CrossRef] [Scilit]
  42. Ong, A. K. S., Dejucos, M. J. R., Rivera, M. A. F., Muñoz, J. V. D., Obed, M. S., & Robas, K. P. E. (2022). Utilizing SEM-RFC to predict factors affecting online shopping cart abandonment. Heliyon, 8(11), e11293. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  43. Partarakis, N., & Zabulis, X. (2023). Applying cognitive load theory to eLearning of crafts. Multimodal Technologies and Interaction, 8(1), 2. [Google Scholar] [CrossRef] [Scilit]
  44. Pathak, A., & Bansal, V. (2024). AI as decision aid or delegated agent: The effects of trust dimensions on the adoption of AI digital agents. Computers in Human Behavior Artificial Humans, 2(2), 100094. [Google Scholar] [CrossRef] [Scilit]
  45. Pirolli, P., & Card, S. (1999). Information foraging. Psychological Review, 106(4), 643–675. [Google Scholar] [CrossRef] [Scilit]
  46. Pirolli, P., & Fu, W. (2003). SNIF-ACT: A model of information foraging on the world wide web. In Lecture notes in computer science (pp. 45–54). Springer. [Google Scholar]
  47. Plass, J. L., & Kalyuga, S. (2019). Four ways of considering emotion in cognitive load theory. Educational Psychology Review, 31(2), 339–359. [Google Scholar] [CrossRef] [Scilit]
  48. Podsakoff, P. M. (2003). Common method biases in behavioral research: A critical review of the literature and recommended remedies. Journal of Applied Psychology, 88(5), 879–903. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  49. Reisenzein, R., Horstmann, G., & Schützwohl, A. (2019). The cognitive-evolutionary model of surprise: A review of the evidence. Topics in Cognitive Science, 11(1), 50–74. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  50. Roy, R., & Shaikh, A. (2024). The impact of online consumer review confusion on online shopping cart abandonment. Journal of Retailing and Consumer Services, 81, 103941. [Google Scholar] [CrossRef] [Scilit]
  51. Rubin, D., Martins, C., Ilyuk, V., & Hildebrand, D. (2020). Online shopping cart abandonment: A consumer mindset perspective. Journal of Consumer Marketing, 37(5), 487–499. [Google Scholar] [CrossRef] [Scilit]
  52. Sarma, A. D., Sarkar, J. G., & Sarkar, A. (2024). E-tail format, cognitive orientation and device: Shaping variety’s impact on online cart abandonment. Journal of Consumer Marketing. Advanced online publication. [Google Scholar]
  53. Sarstedt, M., Hair, J. F., & Ringle, C. M. (2022). PLS-SEM: Indeed a silver bullet. Journal of Marketing Theory and Practice, 31(3), 261–275. [Google Scholar] [CrossRef] [Scilit]
  54. Sarstedt, M., Ringle, C. M., & Hair, J. F. (2020). Handbook of market research. Springer. [Google Scholar]
  55. Scheibehenne, B., Greifeneder, R., & Todd, P. M. (2010). Can there ever be too many options? A meta-analytic review of choice overload. Journal of Consumer Research, 37(3), 409–425. [Google Scholar] [CrossRef] [Scilit]
  56. Sethuraman, R., Gázquez-Abad, J. C., & Martínez-López, F. J. (2022). The effect of retail assortment size on perceptions, choice, and sales. Journal of Retailing, 98(1), 24–45. [Google Scholar] [CrossRef] [Scilit]
  57. Shahzad, M. F., Xu, S., An, X., & Javed, I. (2024). Assessing the impact of AI-chatbot service quality on user e-brand loyalty. Journal of Retailing and Consumer Services, 79, 103867. [Google Scholar] [CrossRef] [Scilit]
  58. Shi, S., Gong, Y., & Gursoy, D. (2020). Antecedents of trust and adoption intention toward artificially intelligent recommendation systems. Journal of Travel Research, 60(8), 1714–1734. [Google Scholar] [CrossRef] [Scilit]
  59. Shin, D. (2020). How do users interact with algorithm recommender systems? Computers in Human Behavior, 109, 106344. [Google Scholar] [CrossRef] [Scilit]
  60. Skavronskaya, L., Moyle, B., Scott, N., & Schaffer, V. (2020). Novelty, unexpectedness and surprise: A conceptual clarification. Tourism Recreation Research, 46(4), 548–552. [Google Scholar] [CrossRef] [Scilit]
  61. Smits, A., & Van Turnhout, K. (2023). Towards a practice-led research agenda for user interface design of recommender systems. In Lecture notes in computer science (pp. 170–190). Springer. [Google Scholar]
  62. Song, J. (2019). A study on online shopping cart abandonment: A product category perspective. Journal of Internet Commerce, 18(4), 337–368. [Google Scholar] [CrossRef] [Scilit]
  63. Soper, D. (2023). A-priori sample size calculator for structural equation models. Available online: https://www.danielsoper.com/statcalc (accessed on 31 January 2024).
  64. Stöckli, D. R., & Khobzi, H. (2020). Recommendation systems and convergence of online reviews. Decision Support Systems, 142, 113475. [Google Scholar] [CrossRef] [Scilit]
  65. Sweller, J. (2019). Cognitive load theory and educational technology. Educational Technology Research and Development, 68(1), 1–16. [Google Scholar] [CrossRef] [Scilit]
  66. Sweller, J., Van Merrienboer, J. J., & Paas, F. G. (1998). Cognitive architecture and instructional design. Educational Psychology Review, 10, 251–296. [Google Scholar] [CrossRef] [Scilit]
  67. Tang, H., & Lin, X. (2018). Curbing shopping cart abandonment in C2C markets. Electronic Markets, 29(3), 533–552. [Google Scholar] [CrossRef] [Scilit]
  68. Varga, M., & Albuquerque, P. (2023). The impact of negative reviews on online search and purchase decisions. Journal of Marketing Research, 61(5), 803–820. [Google Scholar] [CrossRef] [Scilit]
  69. Venkatesan, V. K., Ramakrishna, M. T., Batyuk, A., Barna, A., & Havrysh, B. (2023). High-performance artificial intelligence recommendation of quality research papers. Systems, 11(2), 81. [Google Scholar] [CrossRef] [Scilit]
  70. Venkatesh, N., Morris, N., Davis, N., & Davis, N. (2003). User acceptance of information technology: Toward a unified view. MIS Quarterly, 27(3), 425–478. [Google Scholar] [CrossRef] [Scilit]
  71. Wang, Z., Wang, J., Tian, C., Ali, A., & Yin, X. (2024). Adopting AI teammates in knowledge-intensive crowdsourcing contests. Kybernetes. Advanced online publication. [Google Scholar] [CrossRef] [Scilit]
  72. Wong, R. M. M., Wong, S. C., & Ke, G. N. (2018). Exploring online and offline shopping motivational values in Malaysia. Asia Pacific Journal of Marketing and Logistics, 30(2), 352–379. [Google Scholar] [CrossRef] [Scilit]
  73. Wu, W., Wang, X., & Xia, Q. (2024). Why leave items in the shopping cart? Information Processing and Management, 61(6), 103854. [Google Scholar] [CrossRef] [Scilit]
  74. Yang, S., Hussain, M., Zahid, R. A., & Maqsood, U. S. (2024). The role of artificial intelligence in corporate digital strategies. Kybernetes. Advanced online publication. [Google Scholar] [CrossRef] [Scilit]
  75. Yi, C., Jiang, Z., & Benbasat, I. (2017). Designing for diagnosticity and serendipity. Information Systems Research, 28(2), 413–429. [Google Scholar] [CrossRef] [Scilit]
  76. Zhang, Q., Lu, J., & Jin, Y. (2020). Artificial intelligence in recommender systems. Complex and Intelligent Systems, 7(1), 439–457. [Google Scholar] [CrossRef] [Scilit]
  77. Zhang, Y., & Chen, X. (2020). Explainable recommendation: A survey and new perspectives. Foundations and Trends in Information Retrieval, 14(1), 1–101. [Google Scholar] [CrossRef] [Scilit]
  78. Ziarani, R. J., & Ravanmehr, R. (2021). Deep neural network approach for a serendipity-oriented recommendation system. Expert Systems with Applications, 185, 115660. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Conceptual Model. Source(s): Author’s work.
Tourismhosp 07 00228 g001
Table 1. Item Loadings, Descriptive Statistics, and Reliability/Validity (Source: Author’s data, N = 624).
ConstructItemMean (SD)LoadingCronbach’s αCRAVE
AI recommendationsAI13.64 (1.04)0.9170.7000.8250.682
AI23.67 (0.79)0.858
AI33.51 (0.85)0.601
Perceived SerendipityPSR13.20 (1.15)0.8650.9070.9350.782
PSR23.28 (1.06)0.917
PSR33.40 (1.00)0.903
PSR43.37 (1.14)0.851
Perceived SimilarityPS13.53 (0.89)0.8220.8890.9230.751
PS23.41 (1.02)0.866
PS33.73 (1.07)0.909
PS43.49 (0.93)0.867
Intrinsic Cognitive LoadIL13.58 (0.93)0.9270.9000.9370.832
IL23.66 (1.04)0.931
IL33.30 (0.98)0.877
Extrinsic Cognitive LoadEL13.66 (0.93)0.8410.8050.8850.719
EL23.39 (1.18)0.872
EL33.10 (1.21)0.832
Germane LoadGL13.47 (1.11)0.8280.8110.8770.643
GL22.92 (1.10)0.845
GL33.23 (1.08)0.848
GL43.58 (0.98)0.671
Cart AbandonmentSC13.63 (0.91)0.7120.8650.9090.717
SC23.16 (0.98)0.845
SC33.30 (1.15)0.906
SC43.36 (1.13)0.909
Cost ConcernCC13.42 (1.00)0.7910.8750.9150.728
CC23.32 (1.05)0.872
CC33.35 (1.06)0.895
CC43.31 (0.95)0.853
Research ToolRC13.39 (0.85)0.7020.7260.8480.651
RC23.45 (1.11)0.874
RC33.46 (0.98)0.835
Table 2. Discriminant Validity (Fornell-Larcker Criterion). Diagonal values (bold) are the square root of AVE for each construct; off-diagonal values are inter-construct correlations. AI = AI recommendations; CC = Cost Concern; PS = Perceived Similarity; PSR = Perceived Serendipity; RC = Research Tool (control); SC = Cart Abandonment. HTMT ratios were not computed in the original analysis; we report the Fornell-Larcker criterion as originally analyzed and note this as a methodological limitation in Section 6.3, recommending HTMT as a stronger discriminant-validity test for future replications.
AICCPSPSRRCSC
AI0.825
CC0.6280.853
PS0.8240.7730.866
PSR0.7770.7390.8610.884
RC0.6700.8000.6900.7610.807
SC0.6680.8330.8330.7800.7250.847
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.