1. Introduction
As infrastructure and construction have skyrocketed in China, brick-and-mortar structures have become a staple in the nation’s building boom, particularly in seismic hotspots where they are even more prevalent. Unfortunately, these masonry wonders can take a pounding during tremors. Take the 2008 Wenchuan quake [
1], for instance: in the hardest-hit zones, the masonry edifices were riddled with cracks and suffering major damage, whereas in less intense zones, the harm was relatively minor. The same was true for the 2014 Ludian quake and the 2022 Luding quake [
2,
3], where masonry buildings took a beating across the board. The first telltale sign of a building’s woe is the appearance of cracks. Gathering and assessing post-earthquake crack data and ensuring structural integrity is crucial, especially for swift emergency evaluations and repairs [
4].
In masonry structures, fissures represent the most prevalent form of deterioration and provide a critical foundation for evaluating structural integrity. The safety of buildings must be assessed in compliance with established regulations, taking into account both the structural configuration and the nature of these cracks. As noted by Huang Zhenghua [
5] in 2008, fractures in masonry are instrumental in gauging a building’s safety. When cracks emerge, it often signals that the structure has reached its maximum load-bearing capacity, necessitating thorough inspection and risk analysis to decide if reinforcement measures are warranted. Per the “Earthquake Field Work Part 3: Survey Specifications,” post-seismic evaluations should concentrate on the most affected levels and the orientation of wall fractures. During rapid safety checks, attributes like crack direction and length help identify structural compromise, while crack width influences decisions about repairing load-bearing walls. Metrics such as crack width, length, depth, and orientation serve as vital benchmarks for classifying a building’s hazard rating. These parameters, combined with national guidelines, enable a comprehensive assessment of crack severity and inform the overall damage analysis.
In the wake of an earthquake, seasoned experts often have to rely on manual tools to inspect the fissures in structures. This old-school technique is not precisely reliable, tends to have room for error, and is both labor-intensive and a real time sinker, not to mention the safety hazards involved. Generally, the safety checks post-disaster are wrapped up in about a 10-day span, a process that requires a mountain of effort and heaps of pressure on the inspectors. Take the Wenchuan earthquake for instance; the assessment zone in Guangyuan City sprawled over 444,000 square meters, meaning each worker had to evaluate about 14,800 square meters daily—a massive load. These conventional methods are more of a drag, especially when you are racing against the clock and trying to manage a colossal number of buildings to inspect. Thanks to the advancements in artificial intelligence, the latest deep learning, and computer vision tech have been unleashed in civil engineering, making for a lightning-fast and efficient identification of any crack-related damage.
CNNs, or Convolutional Neural Networks, are a popular breed of deep neural networks that have gained traction in the realms of image classification and object detection. In the pursuit of innovative methods, Lei Zhang and his team embraced deep CNN techniques for the detection of road cracks, harnessing the power of features extracted from affordable sources such as smartphone sensors [
6]. It is interesting to note that much of the crack detection research tends to concentrate on structures like bridges and roads, leaving the masonry wall crack detection playing second fiddle. Enter Liu Shengxin, who took a different approach with semantic segmentation for the detection of masonry cracks, only to find that the limitations of the negative sample database limited the model’s adaptability [
7]. NAV RAJ BHATT came along with a solution that blended CNNs and Grad-CAM to classify and pinpoint masonry damage, yet there remains a gap in dealing with intricate details [
8]. Zhang Hanyu, on the other hand, employed Mask-RCNN for the masonry crack detection [
9], intertwining the specifics of building location with crack characteristics to evaluate structural integrity. Yet, despite these advancements, practical applications reveal that accuracy can vary due to the uniqueness of building structures and the variables in filming conditions. All told, CNNs have proven to be a valuable tool in masonry crack detection, significantly enhancing our ability to pinpoint and categorize cracks with greater precision, which in turn offers robust data essential for conducting structural safety evaluations.
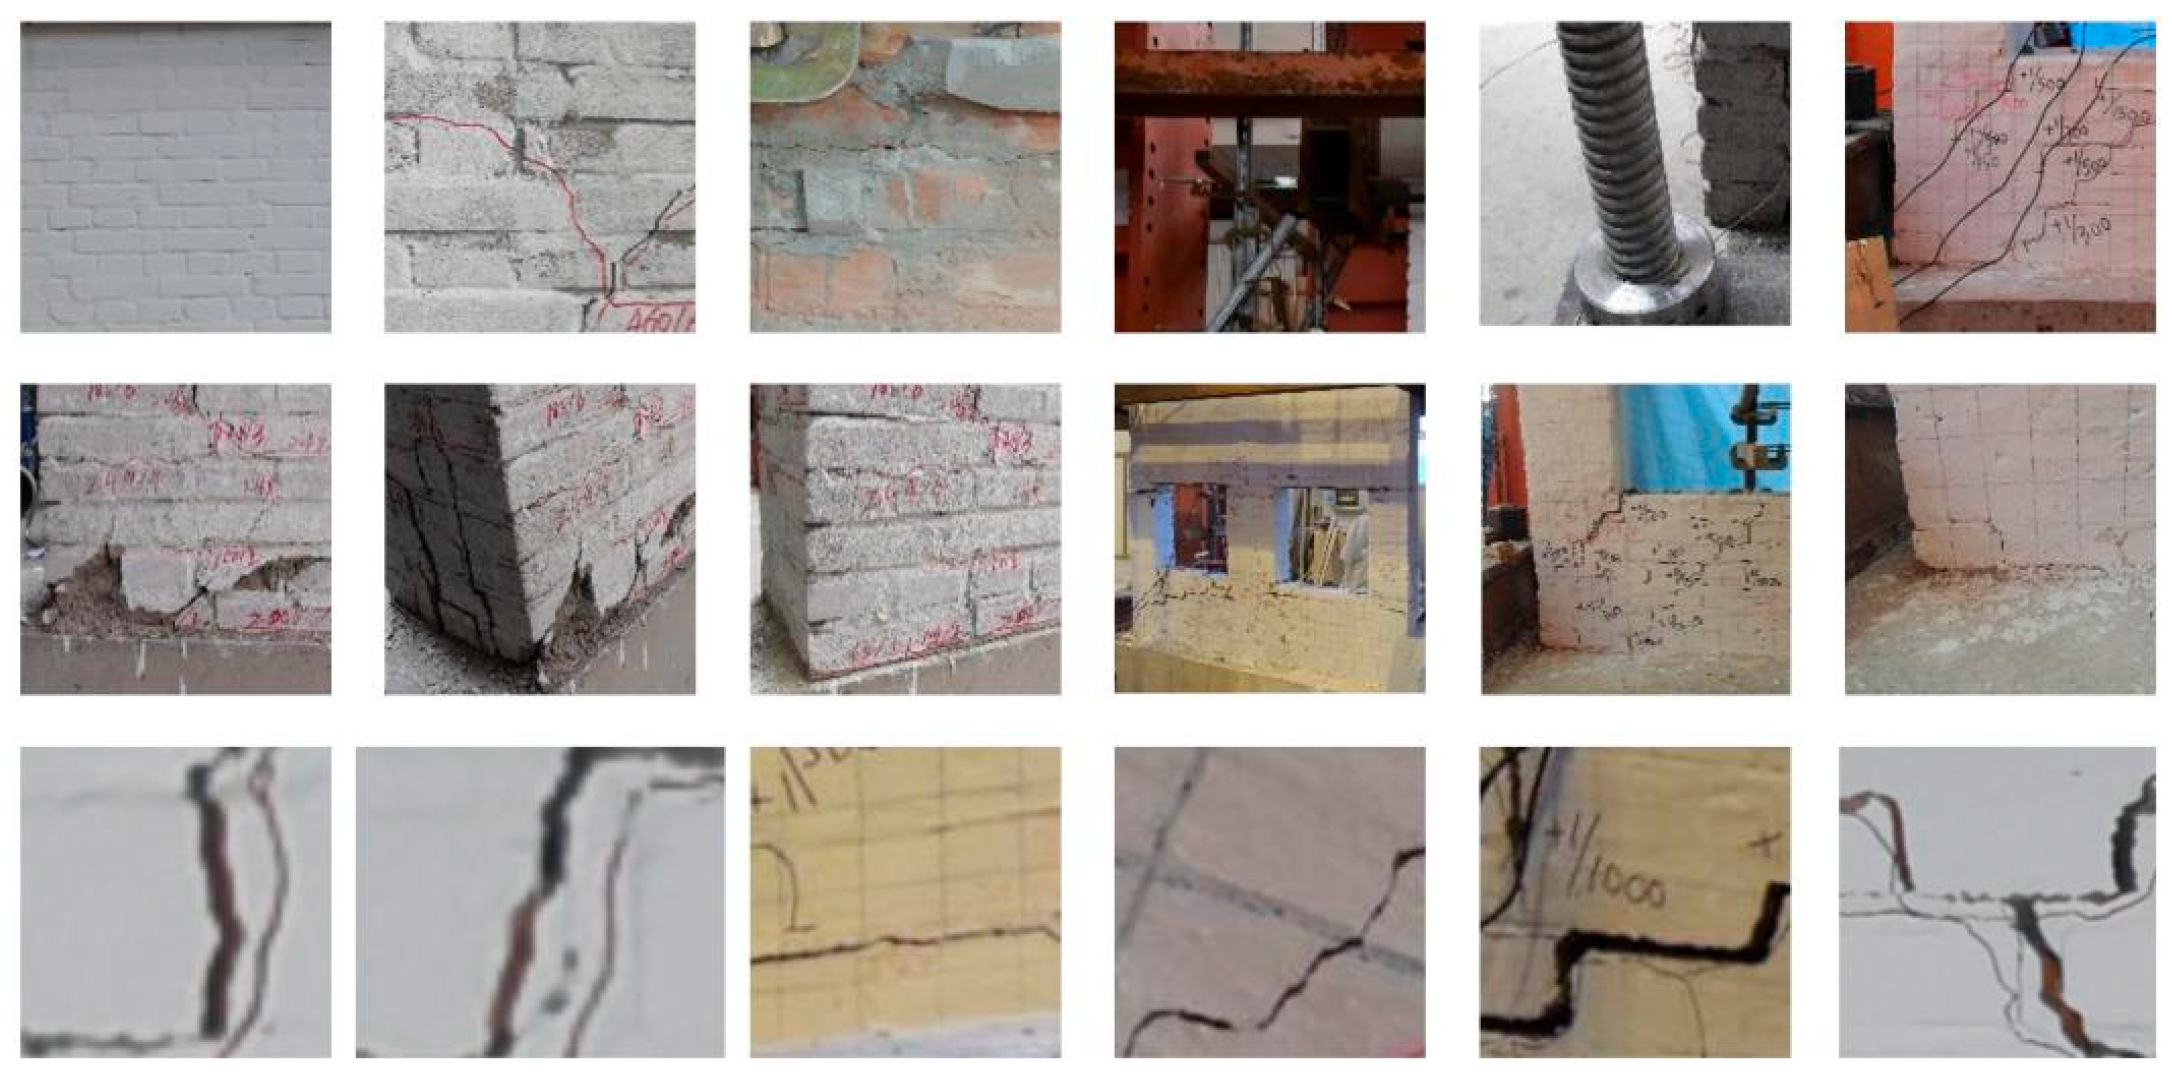
In light of the critical need to evaluate the structural integrity of masonry walls through image analysis, this study tackles the challenge of identifying cracks in load-bearing masonry by introducing a novel approach using Convolutional Neural Networks (CNNs). The goal is to step up the game in terms of both precision and speed for crack detection. Leveraging a dataset of crack images from block masonry walls gathered in lab-based experiments, we implemented a dual-scale CNN algorithm to pull out multi-scale features from the imagery. We crafted and fine-tuned two CNN models with varying input dimensions, drawing inspiration from VGG-16 and GoogleNet architectures through transfer learning techniques. The findings demonstrate that this strategy hits the mark with impressive accuracy and rapid processing times for crack identification, making it a solid bet for practical engineering use by offering dependable technical backing.
4. Training and Testing
4.1. Model Hyperparameter Settings and Training Strategy
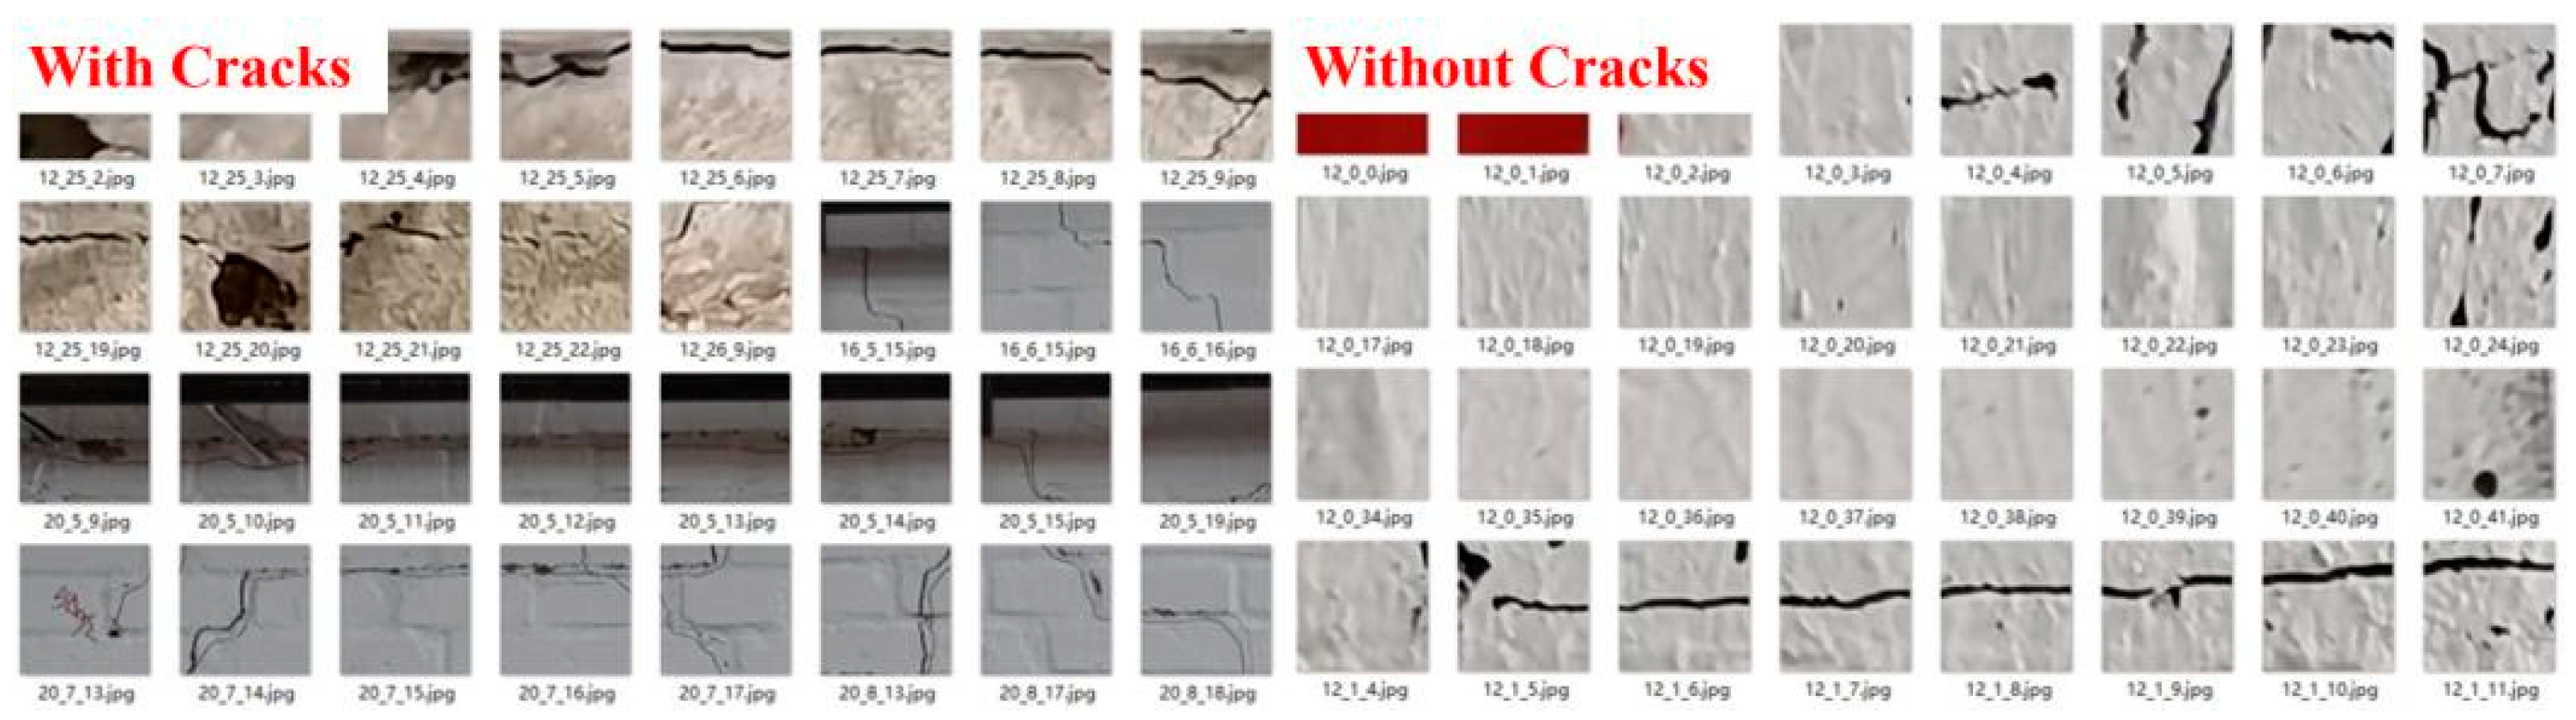
The masonry database is divided into two categories based on whether the image tiles contain cracks. When generating the model training set, 32 image tiles are read from the database for each class. The training batch size is set to 64, and the dataset is split into training and testing sets in a 7:3 ratio. The learning rate is set to 1 × 10⁻³, the optimizer is set to stochastic gradient descent (SGD), with a momentum of 0.9, weight decay of 0.0001, and a learning rate scheduler that reduces the learning rate by 0.8 every 10 epochs. The loss function used is the Cross-Entropy Loss function. Each model is trained for 500 epochs to ensure recognition capability for both cracks and background. The models used in this study are all pre-trained on the large-scale ImageNet database. The pre-trained model, as a feature extractor, can extract basic features that represent natural objects (such as lines, edges, corner points, textures, color gradients, etc.) and more abstract deep features contained within these basic features. This study adopts the concept of transfer learning, where the parameters of the pre-trained model are imported into the model, and then fine-tuned with the specific images collected from various experiments to further learn from the information contained in this study’s database based on the “knowledge” previously learned.
4.2. Model Architecture
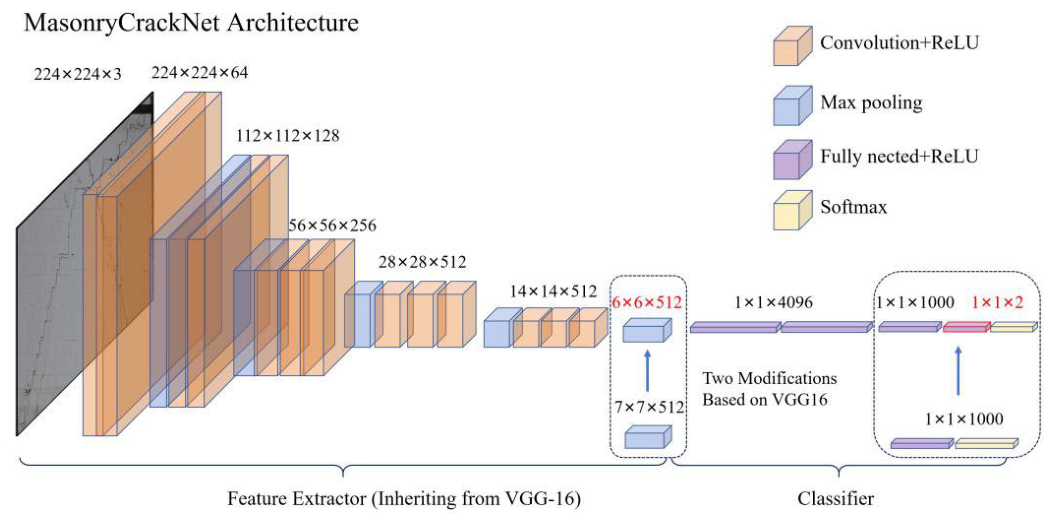
This study first employed three convolutional neural network (CNN) models for training and comparison: AlexNet, GoogleNet, and the improved VGG16 model. AlexNet (2012) was the first convolutional neural network variant applied to image classification. It learns from the features themselves and introduces ReLU, Dropout, and data augmentation techniques, significantly improving the accuracy of image classification. GoogleNet is a novel deep learning architecture that greatly enhances computational efficiency and classification performance through the innovative Inception module, while reducing the number of parameters. VGG16 is a classic convolutional neural network model that improves feature extraction and classification performance by increasing the network depth.
In this study, due to the smaller input image size, different modifications were made to the CNN models used (
Figure 6). The standard GoogleNet architecture was improved by using the initial convolutional layers, max pooling layers, and some Inception modules from GoogleNet, while removing some of the deeper layers. This approach reduces the complexity of the model, speeds up the training process, and reduces the demand for computational resources. Additionally, an Adaptive Average Pooling layer (AdaptiveAvgPool2d) was added to improve the model’s generalization ability. A 1 × 1 convolutional layer was then used for feature reduction, followed by two fully connected layers for classification. This design allows for more effective integration and utilization of the extracted features, thus improving classification accuracy. The complexity of the model was reduced while maintaining good feature extraction capability. The standard VGG16 model was also modified and renamed as MasonryCrackNet. The feature extraction part is the same as the VGG16 architecture, using 13 convolutional layers and 5 pooling layers. The last pooling layer was modified to 3 × 3, which more effectively reduces the feature map size while retaining more spatial information. An additional fully connected layer was added to the classifier part to enhance the model’s expressive capability. The standard AlexNet network was also modified. The feature extraction part remains the same as the standard AlexNet, with five convolutional layers and three max pooling layers. A custom classifier was introduced, adding a Dropout layer to prevent overfitting. In the classifier part, the output of the first fully connected layer was changed from 4096 to 2048, a new fully connected layer with 1000 neurons was added, and the output categories were changed to 2.
4.3. Model Evaluation
The improved models were trained, and after training, we performed model evaluation on the validation set to monitor the model’s generalization performance. When evaluating the performance of convolutional neural network (CNN) models, we calculated the following metrics: Accuracy (Acc) is the degree to which the model’s predicted results match the true labels; Specificity (True Negative Rate, TNR) is the proportion of correctly identified negative samples by the model; Precision (Pre) is the proportion of true positive samples among the results predicted as positive by the model; Recall (Re) is the proportion of correctly identified positive samples by the model; and the F1-score is the harmonic mean of precision and recall, used to evaluate the overall performance of the model. These metrics were used to assess the quality of the classification algorithm model.
As shown in the metrics in
Table 2, GoogleNet performs the best across multiple metrics, particularly excelling in specificity (TNR), indicating its stronger ability in handling negative samples. The overall performance of Masonry_Crack_Net is similar to that of GoogleNet, while AlexNet performs noticeably worse than the other two models. Based on these results, this study selects Masonry_Crack_Net and GoogleNet as the foundation for the dual-scale model.
4.4. Model Validation
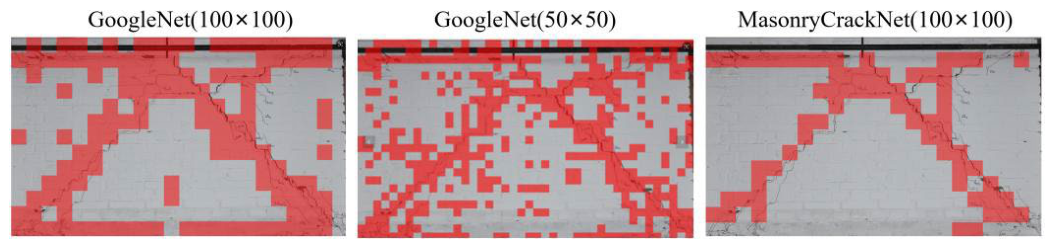
Through experimental analysis, it was found that using CNN alone for large-scale crack detection often overlooks finer cracks in the image. When applying the model to the original large-sized crack images, it was observed that using a single CNN model struggles to cover all cracks in the image. As shown in
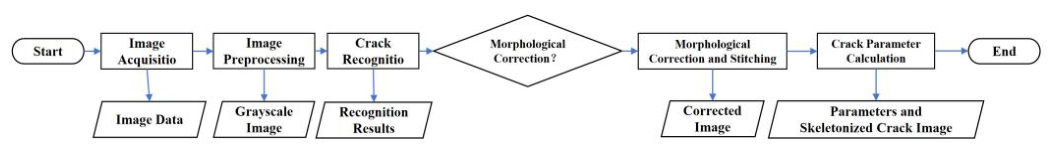
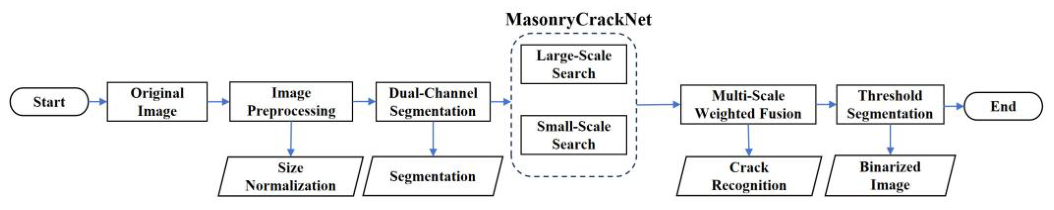
Figure 7, using MasonryCrackNet is more suitable for detecting cracks with larger widths, while GoogleNet performs better in recognizing finer cracks. Based on this, a dual-scale convolutional neural network model is adopted for crack recognition, which can improve the crack detection rate. The original image is scanned twice: using MasonryCrackNet for sliding window traversal with 100 × 100 large-scale image blocks and using GoogleNet for searching with 50 × 50 small-scale image blocks. By performing two scans on the original image with the dual-scale CNN model and combining the global perspective of the large-scale model with the detail-capturing ability of the small-scale model, the precision and robustness of crack detection can be significantly improved.
4.5. Crack Feature Calculation
4.5.1. Crack Width Calculation
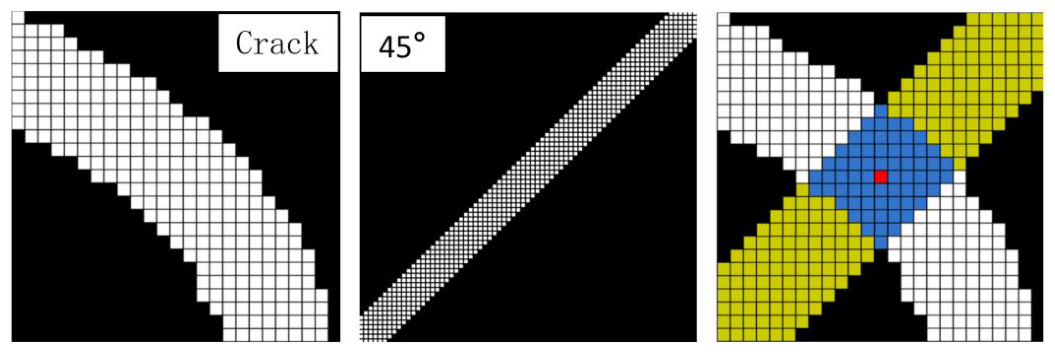
The image filter method based on two-dimensional convolution operations used in this study performs convolution between the crack and a series of strip templates at different angles. When the convolution result reaches its minimum, it is considered that the strip template is perpendicular to the crack at that location. The convolution result at this point is the product of the strip width of the convolution kernel and the crack width. The crack width can be obtained from the strip width of the convolution kernel, and the calculation results are shown in
Table 3. The crack width measured by the comprehensive crack testing device is denoted as
, while the crack width obtained from the original crack image using the above algorithm is denoted as
.
4.5.2. Crack Length Calculation
The crack length is determined by calculating the distance between adjacent pixels in the crack skeleton. Skeletonization is a process that reduces morphological structural elements to a width of just one pixel, maintaining the geometric properties of the shape. For the skeletonized crack image, the coordinates of all non-zero pixels are extracted. By traversing these coordinates, the distance between each pair of adjacent points is calculated. If the adjacent pixels are neighboring in the horizontal or vertical direction, the distance is 1; if they are adjacent in the diagonal direction, the distance is . Finally, these distance values are accumulated to obtain the total crack length.
4.5.3. Crack Angle Calculation
The calculation of the crack angle is based on analyzing the overall orientation of the skeleton line points. First, the coordinates of the skeleton line points are extracted. While traversing these coordinate points, the angle between each pair of adjacent points is calculated using the arctangent function. These angles are expressed in degrees, ranging from -180 degrees to 180 degrees. Then, the average of all these angles is computed to obtain the overall directional characteristic of the crack. Based on this average angle, the crack type can be determined and classified as horizontal cracks (0–22.5 degrees and 157.5–180 degrees), vertical cracks (67.5–112.5 degrees), or diagonal cracks (other angle ranges).