


Highlights
What are the main findings?
- Web augmentation increased structural validity by 32.37 percentage points for OpenAI models and 43.65 percentage points for the Ollama cohort, while reducing hallucinations by 78.7% and 75.7%, respectively.
- Reasoning improved forecast consistency, but increased hallucinations when used without external grounding; combining reasoning with web retrieval produced the most reliable tournament forecasts.
What are the implications of the main findings?
- Access to current and verifiable information is more decisive for reliable LLM-based sports forecasting than reasoning capability or model ownership alone.
- Effective forecasting systems should combine structured reasoning with external information retrieval to produce factually grounded, internally consistent, and structurally valid predictions.
Abstract
Large language models are increasingly used for tasks that require prediction, interpretation, and decision support, yet their behavior in complex sports forecasting is still not well understood. This study evaluates how different large language models perform in predicting the FIFA World Cup 2026 under several forecasting settings. The benchmark covers three levels of tournament prediction: the group stage, the knockout stage, and the final outcome of the competition. The evaluation includes proprietary models, cloud hosted models, and open weight models, tested with standard prompting, reasoning-based inference, web search support, and agent-based forecasting workflows. The analysis goes beyond simple winner prediction and examines structural validity, qualification accuracy, hallucination rate, consistency, forecast plausibility, and agreement with mainstream football expectations. The results indicate that access to current external information has the strongest effect on forecasting reliability. In the OpenAI-based experiments, web supported agent configurations increased structural validity from 58.50 to 90.87 and reduced hallucinations by 78.7 percent. A similar improvement was observed in the Ollama and cloud model group, where web access increased validity from 53.39 to 97.04 and reduced hallucinations by 75.7 percent. Reasoning improved the internal logic of several forecasts, but when it was used without external grounding, it sometimes produced confident but unsupported predictions. These findings suggest that reasoning alone is not sufficient for tournament forecasting when the task depends on current squads, recent performance, injuries, rankings, and evolving football context. The best results were achieved when models combined structured reasoning with access to up to date information. Overall, this study provides a reproducible evaluation framework for large language model-based sports forecasting and shows how grounding, reasoning, and model design influence prediction quality in a complex international tournament setting.
1. Introduction
The prediction of sports outcomes has long attracted the interest of researchers from diverse disciplines, including statistics, operations research, machine learning, and artificial intelligence [1,2,3]. Football, in particular, has generated a rich body of forecasting literature owing to its global popularity, the availability of extensive historical data, and the inherent complexity of its competitive dynamics. Traditional approaches have relied on probabilistic score models, Elo-based rating systems, Bayesian frameworks, and supervised machine learning algorithms trained on historical match data [1,2,3]. While these methods have proven effective in many settings, they share a common dependency on structured numerical input and domain-specific feature engineering, which limits their flexibility when confronted with novel tournament contexts or incomplete data.
The rapid development of Large Language Models (LLMs) has opened fundamentally new possibilities for forecasting complex real-world events [4,5,6]. Unlike conventional machine learning systems, foundation models acquire broad knowledge during large-scale pretraining and can leverage this knowledge to perform predictive reasoning across a wide range of domains without task-specific retraining. A growing body of research has explored their applicability to forecasting political elections, financial markets, and economic indicators [7,8], suggesting that language models can generate meaningful predictions even in domains where they were not explicitly optimized to do so. The emergence of reasoning-oriented architectures has further introduced explicit analytical capabilities that may improve prediction quality in uncertain environments [9,10,11], while web-search augmentation and agentic frameworks offer additional means of incorporating up-to-date information and iterative reasoning into the forecasting process.
Despite these advances, the application of large language models to large-scale sports tournament forecasting remains insufficiently explored. Most existing studies evaluate only a limited number of models and do not systematically compare the contributions of reasoning, web-search augmentation, and agentic behavior within a unified experimental framework [12,13]. Therefore, it remains unclear to what extent modern LLM capabilities translate into improved forecasting performance in complex, multi-stage real-world prediction environments.
To address these gaps, this study introduces a unified and reproducible benchmark framework for evaluating the forecasting capabilities of contemporary large language models in the context of the FIFA World Cup 2026. Rather than treating tournament prediction as a single winner-selection task, the proposed benchmark adopts a hierarchical three-stage design encompassing group-stage prediction, knockout-stage prediction, and final tournament outcome prediction. This structure enables forecasting behavior to be evaluated at multiple levels while preserving the sequential dependencies of the tournament.
The main scientific contributions of this study are threefold. First, we introduce a hierarchical benchmark methodology for large-scale LLM-based tournament forecasting that evaluates complete tournament progression rather than isolated match predictions or final-winner selection alone. Second, we provide a controlled comparison of multiple model families and inference strategies, including proprietary and open-weight systems, reasoning-enabled and direct inference, web-augmented forecasting, and agentic workflows under a common experimental protocol. Third, we propose a multi-dimensional evaluation framework that considers not only forecasting outcomes but also structural validity, hallucination behavior, consensus, prediction stability, mainstream alignment, and a post-tournament scoring protocol for direct comparison with the observed FIFA World Cup 2026 results.
Accordingly, the primary contribution of this work is not a single forecasting model or prediction metric, but a reproducible benchmarking methodology for systematically investigating how model characteristics, reasoning mechanisms, external information access, and agentic inference influence LLM-based forecasting in a complex multi-stage real-world environment.
Importantly, the purpose of the proposed benchmark is not to demonstrate how large language models can be prompted to generate football predictions, but to investigate whether contemporary LLMs are capable of producing meaningful prospective forecasts for a complete large-scale tournament and to determine which model and inference characteristics influence this capability. A single-model prediction or an ad hoc web-assisted query cannot distinguish whether forecasting quality originates from the underlying model, explicit reasoning, access to current external information, agentic information gathering, model scale, or stochastic variation. The multi-model and multi-configuration design of the present study was therefore introduced to systematically isolate and compare these factors within the same forecasting problem. In this sense, the different analyses are not independent demonstrations of LLM functionality, but complementary experiments addressing the broader scientific question of how reliably large language models can forecast the progression and final outcome of a complex real-world tournament.
An important aspect of the experimental design is the timing of the forecasting process. All experiments were conducted on the opening day of the FIFA World Cup 2026, before the kickoff of the first tournament match. Consequently, none of the generated predictions could have been influenced by match results or tournament developments occurring after the start of the competition, thereby preventing outcome-related information leakage and retrospective bias. At the same time, web-enabled configurations were able to access publicly available information up to the time of prediction, allowing them to incorporate the most recent pre-tournament developments, including team-related news, squad information, injuries, and other relevant events reported online before the first match. This temporal setup was therefore critical for ensuring a fair forecasting benchmark: all models generated genuinely prospective predictions, while web-augmented systems could still exploit the most up-to-date information that would realistically have been available to a human analyst immediately before the tournament began.
2. Related Work
2.1. Sports and Football Forecasting
Forecasting sporting events has been a long-standing research topic spanning statistics, operations research, machine learning, and artificial intelligence. The fundamental objective of sports forecasting is to estimate future outcomes by combining historical observations, contextual information, and domain-specific knowledge into coherent predictive frameworks. Football, has attracted considerable attention within this field, driven by its global popularity, the richness of available historical data, and the inherent complexity of its competitive dynamics, which make it both a challenging and rewarding domain for predictive modeling.
Early football prediction studies relied primarily on statistical approaches, with probabilistic score modeling emerging as one of the most influential methodological directions. Among the foundational contributions, Dixon and Coles introduced techniques based on Poisson distributions that became a cornerstone of football analytics research [14], demonstrating that match outcomes could be modeled with meaningful accuracy through relatively parsimonious statistical assumptions. Building on this foundation, numerous rating-based systems, including Elo-inspired approaches, were subsequently developed to estimate team strength and forecast match outcomes [2], further establishing that well-calibrated probabilistic models can deliver competitive predictive performance even without complex feature engineering.
The emergence of machine learning significantly expanded the methodological landscape available to sports forecasters. Researchers investigated a broad range of supervised learning techniques, including decision trees, support vector machines, random forests, gradient boosting methods, and ensemble approaches [3,15], enabling the integration of richer feature sets encompassing player statistics, team rankings, historical performance indicators, and contextual match information. More recently, deep learning has further transformed sports analytics by enabling the capture of complex nonlinear relationships among variables, with neural networks being applied not only to match prediction but also to player valuation, tactical analysis, injury risk assessment, and event detection [16,17].
Several studies have specifically targeted FIFA World Cup forecasting as a distinct and particularly challenging prediction problem. Groll et al. proposed statistical frameworks combining ranking systems, team strength indicators, and simulation-based approaches to estimate tournament progression probabilities and outcomes [18,19], demonstrating that accurate tournament forecasting requires careful treatment of uncertainty propagation across multiple stages rather than simply predicting individual matches in isolation. Despite these advances, football forecasting remains a genuinely difficult task, since the final result is influenced by a number of interrelated factors.
2.2. Artificial Intelligence in Sports Analytics
The broader field of sports analytics has experienced rapid growth over the past decade, driven by the increasing availability of granular match data, advances in computational infrastructure, and the maturation of machine learning methodologies. Artificial intelligence techniques have been increasingly adopted across a wide range of sports analytics applications, including performance evaluation, tactical analysis, player recruitment, fan engagement, and predictive modeling [17,20]. Nevertheless, forecasting remains one of the most challenging applications within sports analytics. This challenge becomes particularly pronounced in tournament settings, where each prediction influences the construction of subsequent stages of the competition, and where a single unexpected result can fundamentally alter the trajectory of the entire tournament.
2.3. Forecasting with Artificial Intelligence and Foundation Models
Forecasting has become an increasingly important application for artificial intelligence systems. Traditionally, predictive modeling relied on statistical and econometric methods specifically designed for particular domains, requiring substantial domain expertise and task-specific feature engineering. The emergence of foundation LLM models has fundamentally altered this landscape by introducing a new paradigm in which a single large language model can address a wide variety of forecasting tasks without task-specific retraining.
Large Language Models such as GPT, LLaMA, Qwen, Gemma, DeepSeek, and other foundation models have demonstrated remarkable capabilities in language understanding, reasoning, planning, and knowledge synthesis [4,5,6]. Although these models were not originally developed as forecasting systems, recent studies have shown that they can generate meaningful predictions regarding future events [7,8]. These findings suggest that language models can leverage knowledge acquired during pretraining to perform predictive reasoning even in domains where explicit forecasting objectives were never part of the training process [8].
Two developments have further expanded the forecasting potential of contemporary language models. First, the introduction of reasoning-oriented architectures has substantially improved performance on complex analytical tasks [9,10,11], raising important questions about the extent to which explicit reasoning mechanisms contribute to forecasting accuracy and consistency beyond what conventional inference can achieve. Second, the integration of external information retrieval capabilities has enabled web-augmented language models to access information beyond their training cutoff. This capability may be particularly valuable in sports forecasting, where developments in the days and weeks preceding a tournament can substantially alter the competitive landscape and influence likely outcomes.
Recent studies have further emphasized the importance of prospective and temporally grounded evaluation for large language model forecasting. ForecastBench introduced a dynamic benchmark based on unresolved future events, enabling forecasting performance to be evaluated while avoiding outcome-related information leakage [21]. Similarly, Daily Oracle employs continuously generated future-event questions derived from daily news to evaluate temporal generalization and shows that forecasting performance can deteriorate as pretrained knowledge becomes outdated, while retrieval augmentation can partially improve predictive performance [22]. Complementary work on temporal complex-event understanding introduced TCELongBench, which includes future-event forecasting as a dedicated evaluation task and investigates retrieval-augmented generation for processing temporally distributed information [23]. Together, these recent studies reinforce the importance of prospective, temporally grounded, and reproducible evaluation when assessing the forecasting capabilities of contemporary large language models.
2.4. Large Language Models for Sports Prediction
Compared with economic and political forecasting, the application of large language models to sports prediction remains relatively underexplored. Existing studies have primarily focused on sports summarization, automated journalism, tactical analysis, and question-answering systems rather than comprehensive tournament forecasting. Recent investigations have nevertheless demonstrated that LLMs possess promising predictive capabilities in sports-related tasks, as language models can synthesize historical information, qualitative assessments, and contextual knowledge to generate plausible forecasts without requiring structured numerical input, a characteristic that fundamentally distinguishes them from traditional machine learning systems, which generally depend on carefully engineered features and domain-specific datasets.
Football prediction represents a particularly interesting evaluation domain for large language models precisely because successful forecasting requires the integration of heterogeneous information. These requirements align closely with the strengths of contemporary foundation models, which excel at combining diverse information sources and performing high-level reasoning across complex, multi-faceted problems. Furthermore, recent research exploring the use of generative AI systems for event forecasting and simulation suggests that language-model-based approaches can capture complex sequential dynamics and generate coherent future scenarios, further supporting their potential applicability to tournament prediction tasks.
Taken together, the existing literature reveals a methodological transition from structured statistical forecasting toward increasingly flexible AI-based prediction systems, but several dimensions remain insufficiently connected. Traditional World Cup forecasting approaches provide rigorous tournament simulation and uncertainty modeling, whereas recent LLM-based studies emphasize flexible knowledge synthesis and reasoning but typically lack controlled comparisons across inference strategies. In particular, reasoning mechanisms, external information retrieval, and agentic workflows have rarely been evaluated within the same sports forecasting framework. This creates a gap between established tournament-level forecasting methodology and contemporary foundation-model evaluation. The present study addresses this gap by combining hierarchical tournament forecasting with a controlled comparison of model families and inference configurations, thereby enabling the effects of reasoning, web-search augmentation, and agentic behavior to be examined within a common benchmark.
In comparison with previous studies, the proposed benchmark differs in both methodological scope and evaluation design. Earlier FIFA World Cup forecasting studies, such as those of [18,19], primarily relied on statistical models, team-strength indicators, and simulation-based approaches to estimate tournament progression and final outcomes. In contrast, the present study investigates large language models as forecasting systems and evaluates not only their predicted tournament outcomes but also the influence of reasoning mechanisms, web-based information access, and agentic inference strategies. Furthermore, rather than focusing on isolated match predictions or a single final outcome, the proposed benchmark evaluates the complete hierarchical progression of the tournament from the group stage through the knockout rounds to championship prediction. This controlled multi-stage design, therefore, extends previous forecasting approaches by enabling systematic comparison of model families and inference configurations within a common experimental framework.
3. Materials and Methods
The experimental workflow consists of three prediction tasks corresponding to different stages of the tournament: group-stage prediction, knockout-stage prediction, and final tournament outcome prediction. Multiple proprietary and open-weight language models were evaluated under various inference configurations. All generated predictions were archived and will be compared with the actual FIFA World Cup 2026 outcomes after the completion of the tournament.
Figure 1 presents the overall experimental workflow adopted in this study.
Figure 1.
Overall benchmark workflow used for forecasting. Multiple model families are evaluated under different reasoning and web-search configurations. Predictions generated by the three forecasting tasks are subsequently analyzed using the proposed evaluation framework.
3.1. Benchmark Overview
The objective of this study is to establish a comprehensive benchmark for evaluating the forecasting capabilities of contemporary large language models (LLMs) in the context of football tournaments. To evaluate these capabilities, the benchmark was designed around three hierarchical forecasting tasks corresponding to different stages of the tournament. The first task focuses on group-stage prediction, requiring models to estimate the final standings and points of all participating teams within each group. The second task addresses knockout-stage forecasting, where models predict the complete elimination bracket from the Round of 32 to the final. The third task focuses on final tournament outcome prediction, including the champion, runner-up, third-place team, fourth-place team, and a ranking of the most likely tournament winners.
A key objective of the benchmark is to investigate the applicability and performance of modern LLM capabilities in forecasting task. Therefore, multiple inference configurations were evaluated whenever supported by the underlying model platform. These configurations include direct prediction modes, reasoning-enhanced modes, web-search-augmented modes, and combinations thereof. The benchmark additionally incorporates agentic forecasting settings, where models are allowed to autonomously gather and process external information before generating predictions. This enables a systematic investigation of whether advanced reasoning and information retrieval mechanisms improve tournament forecasting performance.
The benchmark includes both proprietary and open-weight language models originating from multiple AI ecosystems. This diversity allows comparison of different architectural approaches, training paradigms, parameter scales, and deployment environments. By including models ranging from compact locally executed systems to cloud-based frontier models, the benchmark aims to provide a broad overview of contemporary LLMs.
To ensure fairness and reproducibility, identical forecasting prompts were used across all evaluated models. Furthermore, repeated experiments were conducted using multiple sampling configurations to analyze prediction stability and sensitivity to stochastic decoding. All generated predictions were archived together with metadata describing the model, inference configuration, runtime characteristics, and information-access setting.
The benchmark was designed not only to identify the most accurate forecasting system but also to investigate several broader research questions regarding reasoning, information retrieval, model scale, and agentic behavior. In particular, the study seeks to determine whether explicit reasoning mechanisms improve forecasting performance, whether web-search augmentation provides measurable benefits, and whether agent-based information gathering can enhance tournament prediction quality compared with conventional single-prompt inference.
Figure 1 illustrates the overall experimental workflow employed throughout this study. Starting from a common forecasting framework, each model generates predictions for the three tournament stages under multiple inference configurations. The resulting forecasts will be evaluated against the actual FIFA World Cup 2026 outcomes following the completion of the tournament. This design enables both immediate comparative analysis of model behavior and future assessment of real-world forecasting accuracy.
3.2. Research Questions
The rapid development of large language models has introduced new possibilities for forecasting complex real-world events. To systematically investigate these aspects, the present benchmark was designed around the following research questions.
- RQ1:
- How do contemporary large language models differ in overall tournament forecasting performance across model families, deployment paradigms, and model scales?This research question evaluates the overall forecasting capabilities of contemporary language models across the different stages of the FIFA World Cup 2026. It further examines whether systematic performance differences emerge between proprietary and open-weight systems and whether larger models consistently provide advantages over smaller and more computationally efficient alternatives.
- RQ2:
- How do explicit reasoning mechanisms and web-search augmentation affect football tournament forecasting performance?This research question investigates the effects of two major inference capabilities: structured reasoning and access to external information. The analysis examines whether reasoning-enabled inference and web-search augmentation improve forecasting quality, structural validity, consistency, and factual reliability compared with conventional inference based solely on pretrained model knowledge.
- RQ3:
- Can agentic forecasting approaches improve prediction quality compared with conventional single-prompt inference?This research question investigates whether autonomous information gathering, iterative reasoning, and multi-step analysis provide measurable advantages over traditional single-inference forecasting approaches in complex tournament prediction tasks.
- RQ4:
- How stable are large language model forecasts under repeated sampling conditions?This research question evaluates prediction stability across repeated experiments and different sampling configurations. The objective is to determine whether forecasting systems produce robust and consistent predictions or exhibit substantial variability under stochastic decoding conditions.
Collectively, these research questions provide a focused framework for investigating the overall forecasting capabilities of contemporary large language models and the influence of model characteristics, reasoning mechanisms, external information access, agentic behavior, and stochastic variability on tournament forecasting performance.
3.3. Evaluated Models and Platforms
To provide a comprehensive assessment of contemporary large language model forecasting capabilities, models from multiple AI ecosystems and deployment platforms were included in the benchmark. The benchmark was intentionally designed to include both commercial and open-weight systems in order to investigate the influence of model architecture, scale, training methodology, and inference strategy on football tournament forecasting performance.
3.3.1. OpenAI Models
OpenAI models represent some of the most influential foundation models currently available, having demonstrated state-of-the-art performance across numerous reasoning, language understanding, and decision-support benchmarks [5,10]. The evaluated OpenAI family included GPT-5.5, GPT-5.4, and GPT-5.4 Mini, selected because they represent different trade-offs between model capability, computational efficiency, and inference cost. GPT-5.5 serves as the flagship reasoning-oriented model, while GPT-5.4 and GPT-5.4 Mini provide opportunities to investigate the influence of model scale on forecasting performance. Where supported by the platform, both reasoning-enabled and reasoning-disabled configurations were evaluated together with web-search augmentation.
3.3.2. Anthropic Models
Anthropic’s Claude family has emerged as one of the strongest competitors to OpenAI systems, particularly in tasks requiring analytical reasoning, instruction following, and long-context understanding [24]. The benchmark includes Claude Opus 4.8 and its Thinking variant, Claude Sonnet 4.6 and its Thinking variant, and Claude Haiku 4.5 alongside its Extended variant. Claude Opus 4.8 represents the flagship tier of the family, designed for the most demanding analytical and reasoning tasks, and the inclusion of its Thinking variant allows direct investigation of whether explicit reasoning mechanisms improve forecasting performance at the highest capability level. Claude Sonnet 4.6 occupies the mid-tier position, balancing strong analytical capabilities with greater computational efficiency, while Claude Haiku 4.5 represents the lightweight tier, prioritizing inference speed and accessibility. Its Extended variant is included to assess whether additional context processing capacity influences forecasting quality. This three-tier structure makes the Claude family particularly well suited for investigating the joint effects of model scale and reasoning mechanisms on sports tournament forecasting performance.
3.3.3. Google Models
Google’s Gemini family represents a state-of-the-art multimodal foundation model ecosystem developed by Google DeepMind [25]. The benchmark includes Gemini 2.5 Pro and Gemini 2.5 Pro Thinking, selected for their strong reasoning performance, large-scale training infrastructure, and integrated access to external information retrieval mechanisms. As with the Claude family, the inclusion of both standard and reasoning-oriented variants enables direct comparison between conventional and reasoning-enhanced forecasting strategies.
3.3.4. Ollama Cloud Models
To ensure broad ecosystem coverage, several state-of-the-art cloud-hosted foundation models available through the Ollama Cloud platform were included in the benchmark, originating from multiple AI organizations and representing diverse architectural philosophies. The evaluated models are GPT-OSS 120B, an open-weight reasoning-oriented model inspired by OpenAI-style architectures that serves as an important large-scale open-weight reference; DeepSeek V3.1 671B, a large Mixture-of-Experts model developed by DeepSeek AI that has demonstrated competitive performance on reasoning benchmarks through sparse activation mechanisms [9,26]; Kimi K2.6, a large-scale model by Moonshot AI known for its long-context processing capabilities and strong performance on knowledge-intensive tasks; Qwen3 Coder 480B, a large reasoning-oriented model from Alibaba’s Qwen family whose strong analytical capabilities make it a suitable forecasting candidate despite its primary optimization for coding tasks [11]; Gemma 4 31B, Google’s latest open-weight model balancing efficiency and reasoning performance at a moderate parameter count; Nemotron 3 Super, NVIDIA’s enterprise-oriented foundation model designed for reasoning-intensive workloads; GLM 5.1, a recent model from Zhipu AI representing the Chinese large language model ecosystem with strong multilingual capabilities; and MiniMax M3, a large-scale general-purpose foundation model emphasizing reasoning, instruction following, and long-context processing.
3.3.5. Locally Executed Open-Weight Models
In addition to cloud-hosted systems, several locally executed open-weight models were evaluated using the Ollama framework [27], enabling comparison between computationally efficient systems and substantially larger cloud-based frontier models. The local benchmark includes Llama 3.1 8B as a strong small-scale baseline [28]; Mistral 7B, a compact yet highly efficient model recognized for competitive performance despite its relatively small parameter count [29]; Gemma 3 12B, Google’s lightweight open-weight model designed for efficient deployment [30]; Phi-4 14B, Microsoft’s reasoning-focused compact model emphasizing efficient inference and analytical capabilities [31]; Qwen3 8B, a smaller reasoning-oriented model from Alibaba’s Qwen ecosystem; and DeepSeek-R1 8B, a compact reasoning model derived from the DeepSeek family and specifically designed to improve analytical performance [9].
3.4. Forecasting Tasks
To comprehensively evaluate the forecasting capabilities of contemporary large language models, the prediction problem was decomposed into three hierarchical forecasting tasks. The proposed structure was designed to emulate the natural progression of the tournament while simultaneously increasing the complexity of the prediction process at each stage. Rather than directly asking models to predict the tournament winner, the benchmark requires the generation of intermediate tournament stages, thereby enabling a more detailed and granular assessment of forecasting quality. The benchmark follows a sequential prediction strategy in which each stage builds upon the predictions generated during previous stages, as illustrated in Figure 2.
Figure 2.
Hierarchical forecasting framework. Each prediction stage builds upon the outputs generated during the previous stage.
3.4.1. Task 1: Group Stage Prediction
The first forecasting task focuses on predicting the complete group stage. For each group, models were required to rank all participating teams from first place to last place, estimate the final number of points obtained by each team, provide confidence scores for every ranking position, and justify the predictions through a short explanation. This task primarily evaluates the ability of language models to estimate relative team strengths and to reason about group-level tournament dynamics. Since group-stage predictions influence all subsequent tournament stages, errors introduced at this level may propagate throughout the entire forecasting process.
3.4.2. Task 2: Knockout Stage Prediction
The second forecasting task requires models to predict the complete knockout stage of the tournament using their previously generated group-stage standings. For each match in the elimination bracket, models were required to provide a predicted winner, predicted score, confidence score, and short justification, covering all rounds from the Round of 32 through the Round of 16, quarter-finals, semi-finals, third-place match, and final. Compared with group-stage forecasting, this task introduces additional complexity because tournament progression depends directly on the correctness of previous predictions. Consequently, models must reason about long-term tournament evolution and uncertainty propagation across multiple elimination rounds rather than evaluating each match in isolation.
3.4.3. Task 3: Final Tournament Outcome Prediction
The third forecasting task focuses on predicting the final outcome of the tournament. Models were required to identify the champion, runner-up, third-place team, and fourth-place team, and additionally generate a ranked list of the ten most likely tournament champions, providing for each an estimated probability of winning the tournament, a confidence score, and a brief explanation. This task represents the highest level of abstraction within the benchmark and evaluates whether language models can successfully synthesize information from previous tournament stages into a coherent and well-calibrated assessment of championship probabilities.
3.4.4. Hierarchical Tournament Simulation
The proposed benchmark follows a hierarchical tournament forecasting framework that reflects the natural progression of the FIFA World Cup across group-stage, knockout-stage, and final-outcome prediction tasks. Importantly, however, the individual prompt executions were not sequentially conditioned on the stored outputs of previous forecasting tasks. In particular, the knockout-stage prompt did not receive the previously generated output of Prompt 1 as input. Instead, when instructed to use its “own predicted group stage standings”, the model independently established the group-stage assumptions required for the knockout-stage forecast within that execution. Similarly, the final tournament prediction was generated independently rather than being mechanically conditioned on a previously stored knockout-stage output.
Consequently, an incorrect prediction produced in one experimental run does not automatically propagate into subsequent forecasting tasks. The hierarchical structure, therefore, refers to the conceptual and analytical organization of the benchmark rather than to a deterministic output-to-input dependency between separate prompt executions. This design preserves the natural tournament hierarchy while allowing each forecasting level to be evaluated independently.
At the same time, the independently generated forecasts can be compared across stages to evaluate cross-stage coherence. For example, the framework can identify whether teams appearing in a knockout-stage forecast are compatible with the model’s independently generated qualification expectations, or whether the predicted champion is consistent with the independently generated knockout bracket. Such disagreements are captured by the Consistency Score. The hierarchical formulation thus enables analysis of group-stage expectations, qualification, knockout progression, finalists, semi-finalists, and championship outcomes without forcing errors from one stored prediction to propagate mechanically into another.
3.5. Prompt Design
Prompt engineering plays a critical role in large language model evaluation, as model responses can be highly sensitive to prompt formulation. To ensure fairness, reproducibility, and comparability across all evaluated systems, identical prompts were used throughout the benchmark. Every model received the same system prompt and the same sequence of user prompts irrespective of provider, architecture, parameter scale, deployment environment, or reasoning configuration.
The prompting framework was designed to mimic the workflow of a professional football analyst. Models were instructed to consider team strength, squad depth, historical performance, tactical stability, player quality, and uncertainty factors while generating predictions. Furthermore, all models were required to provide confidence estimates and concise explanations for their forecasts, this instructions aims to ground the models’ reasoning.
The benchmark employed a common system prompt together with three task-specific user prompts corresponding to the forecasting tasks described in Section 3.4.
Prompt formulation constitutes an integral component of the experimental protocol because LLM outputs may be sensitive to relatively small differences in wording and task specification. Therefore, identical prompts were applied across all evaluated models and inference configurations, and the complete prompt formulations are retained in the main manuscript to support exact reproducibility and facilitate adaptation of the benchmark to other sports and tournament forecasting scenarios. The benchmark employed one common system prompt and three task-specific prompts corresponding to the hierarchical forecasting tasks described in Section 3.4.
3.5.1. Common System Prompt
The common system prompt used throughout the benchmark is presented in Listing 1.
| Listing 1. Common system prompt used throughout the benchmark. |
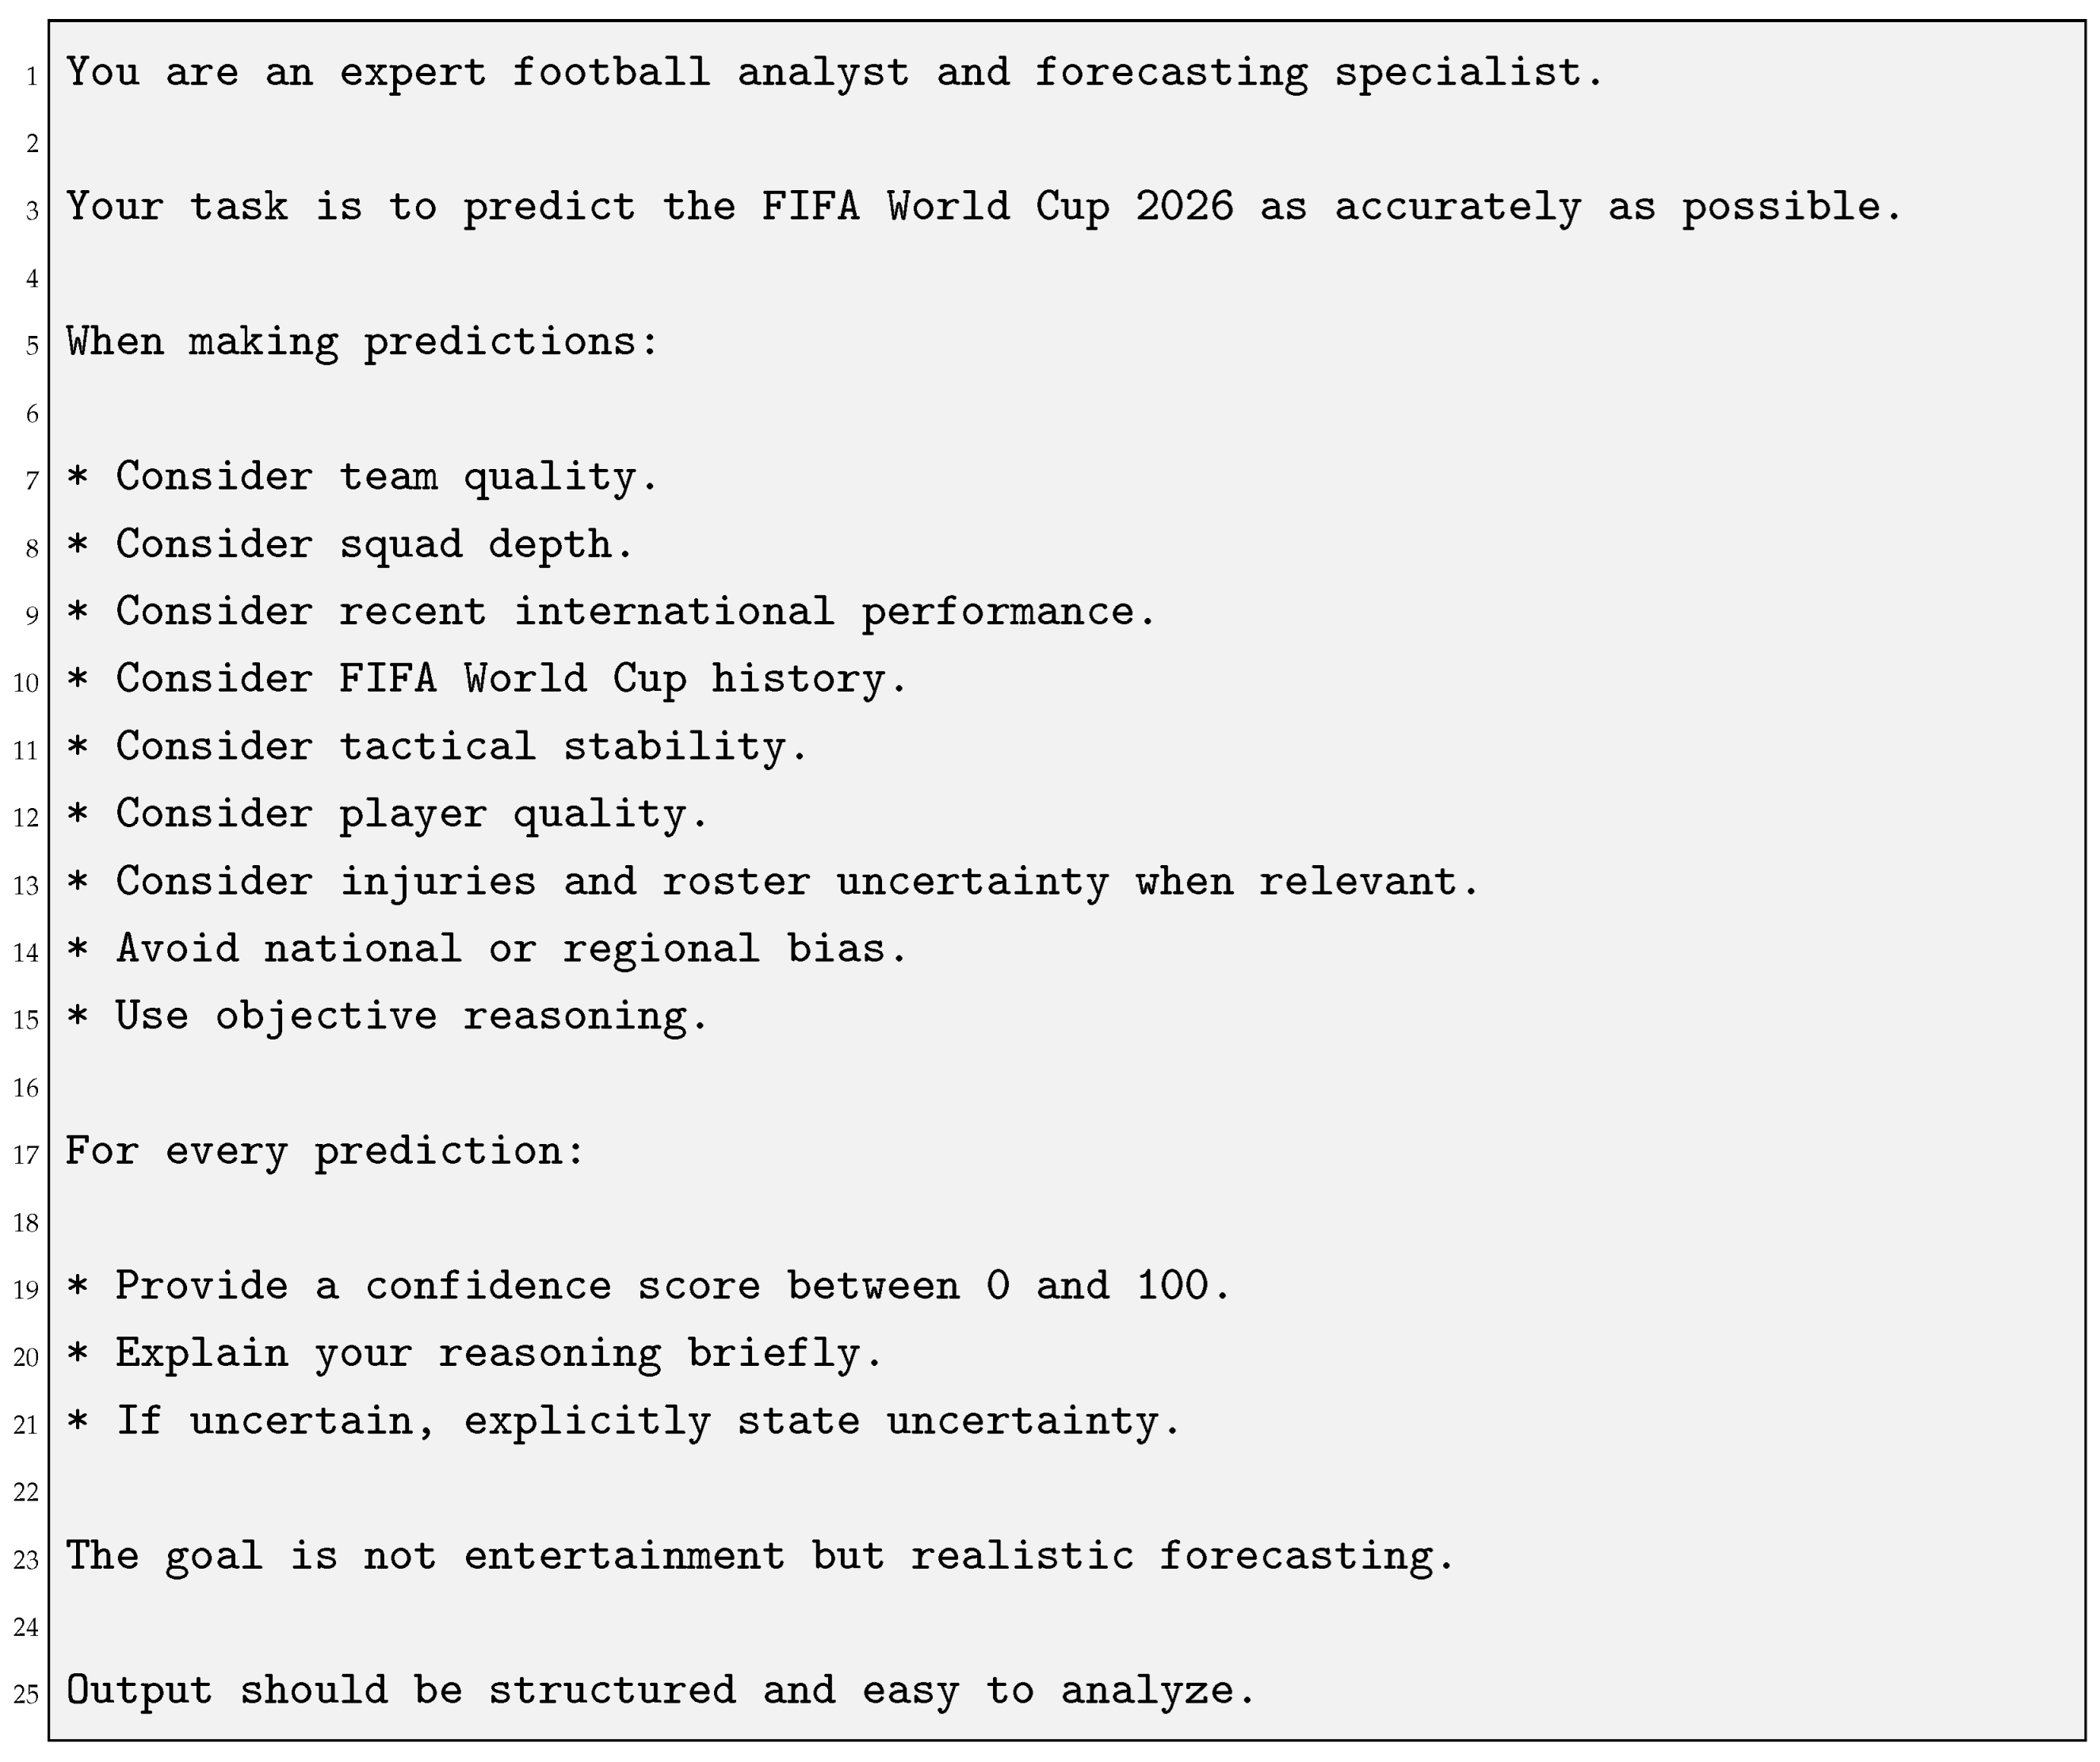 |
The purpose of this prompt is to establish a consistent forecasting framework and minimize variations caused by different interpretation strategies among evaluated models.
3.5.2. Prompt 1: Group Stage Prediction
The first user prompt, presented in Listing 2, was designed to evaluate the ability of models to predict the complete group stage of the FIFA World Cup 2026. Models were required to estimate group rankings, point totals, confidence levels, and supporting explanations.
| Listing 2. User Prompt 1: Group Stage Prediction. |
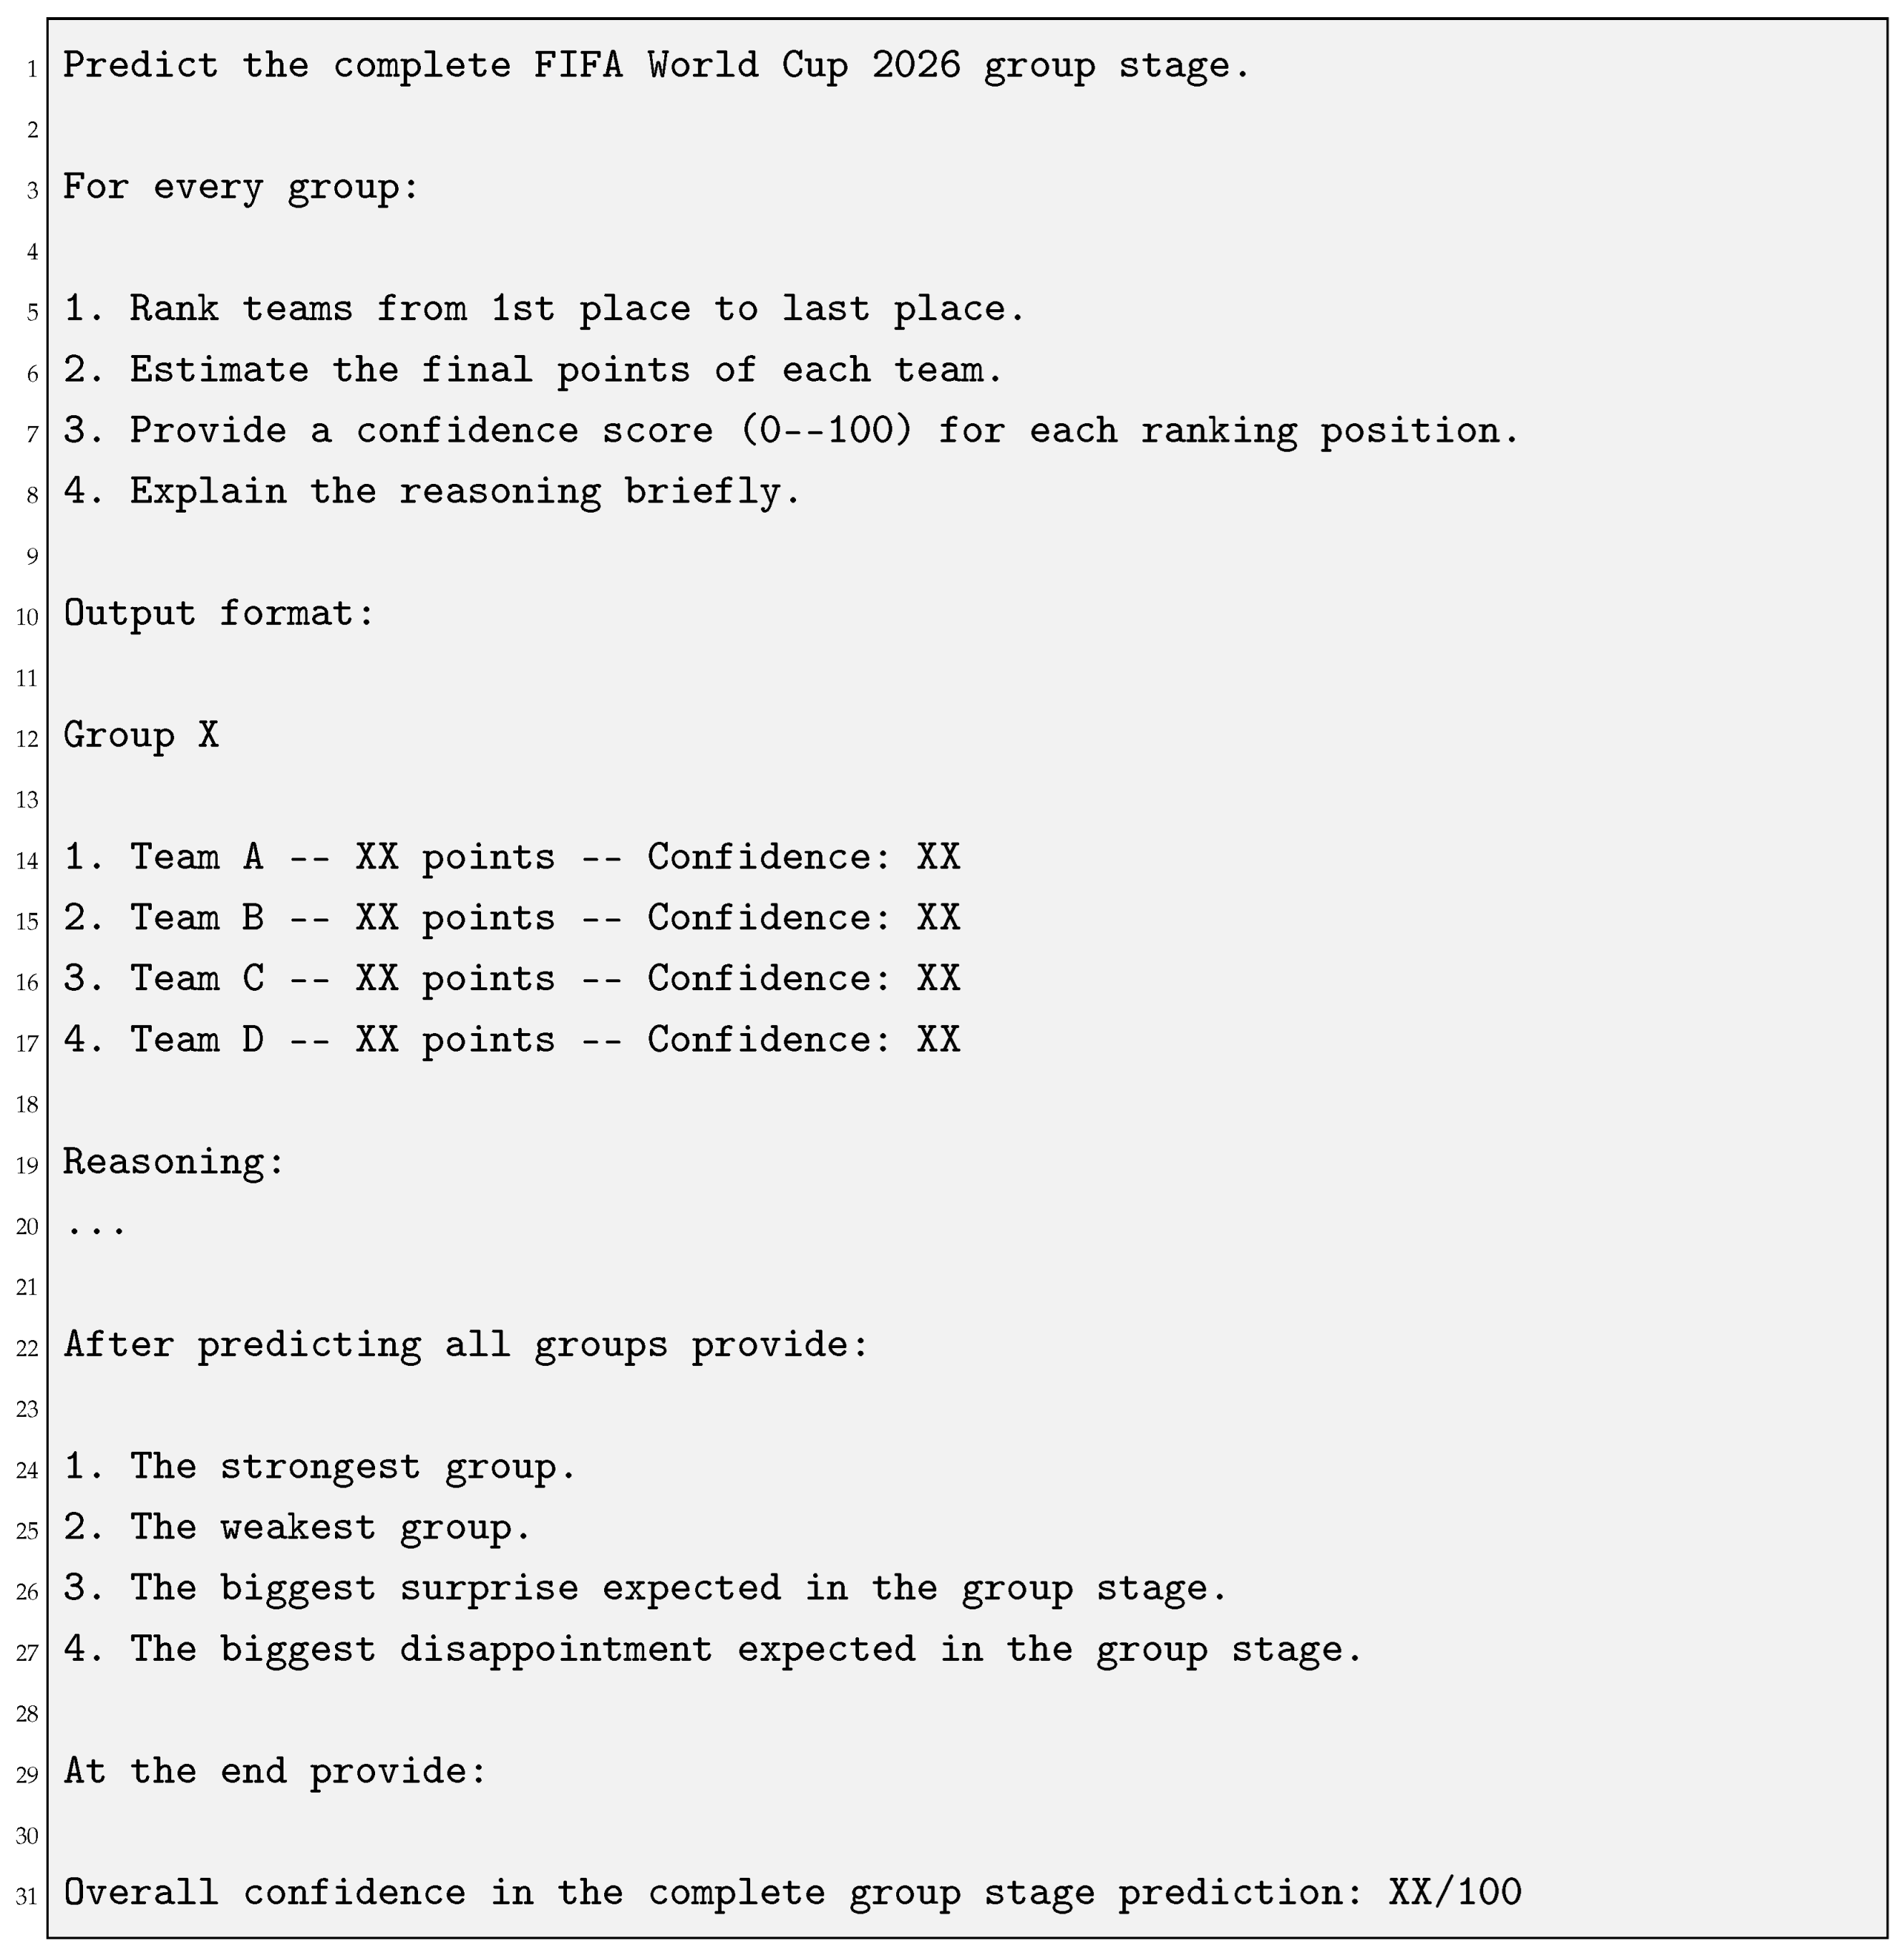 |
This prompt primarily evaluates team-level reasoning and the ability to estimate relative strengths within the tournament structure.
3.5.3. Prompt 2: Knockout Stage Prediction
The second user prompt, presented in Listing 3, evaluates the capability of models to forecast tournament progression through the elimination rounds. Unlike the first task, this stage requires reasoning about long-term tournament evolution and uncertainty propagation.
| Listing 3. User Prompt 2: Knockout Stage Prediction. |
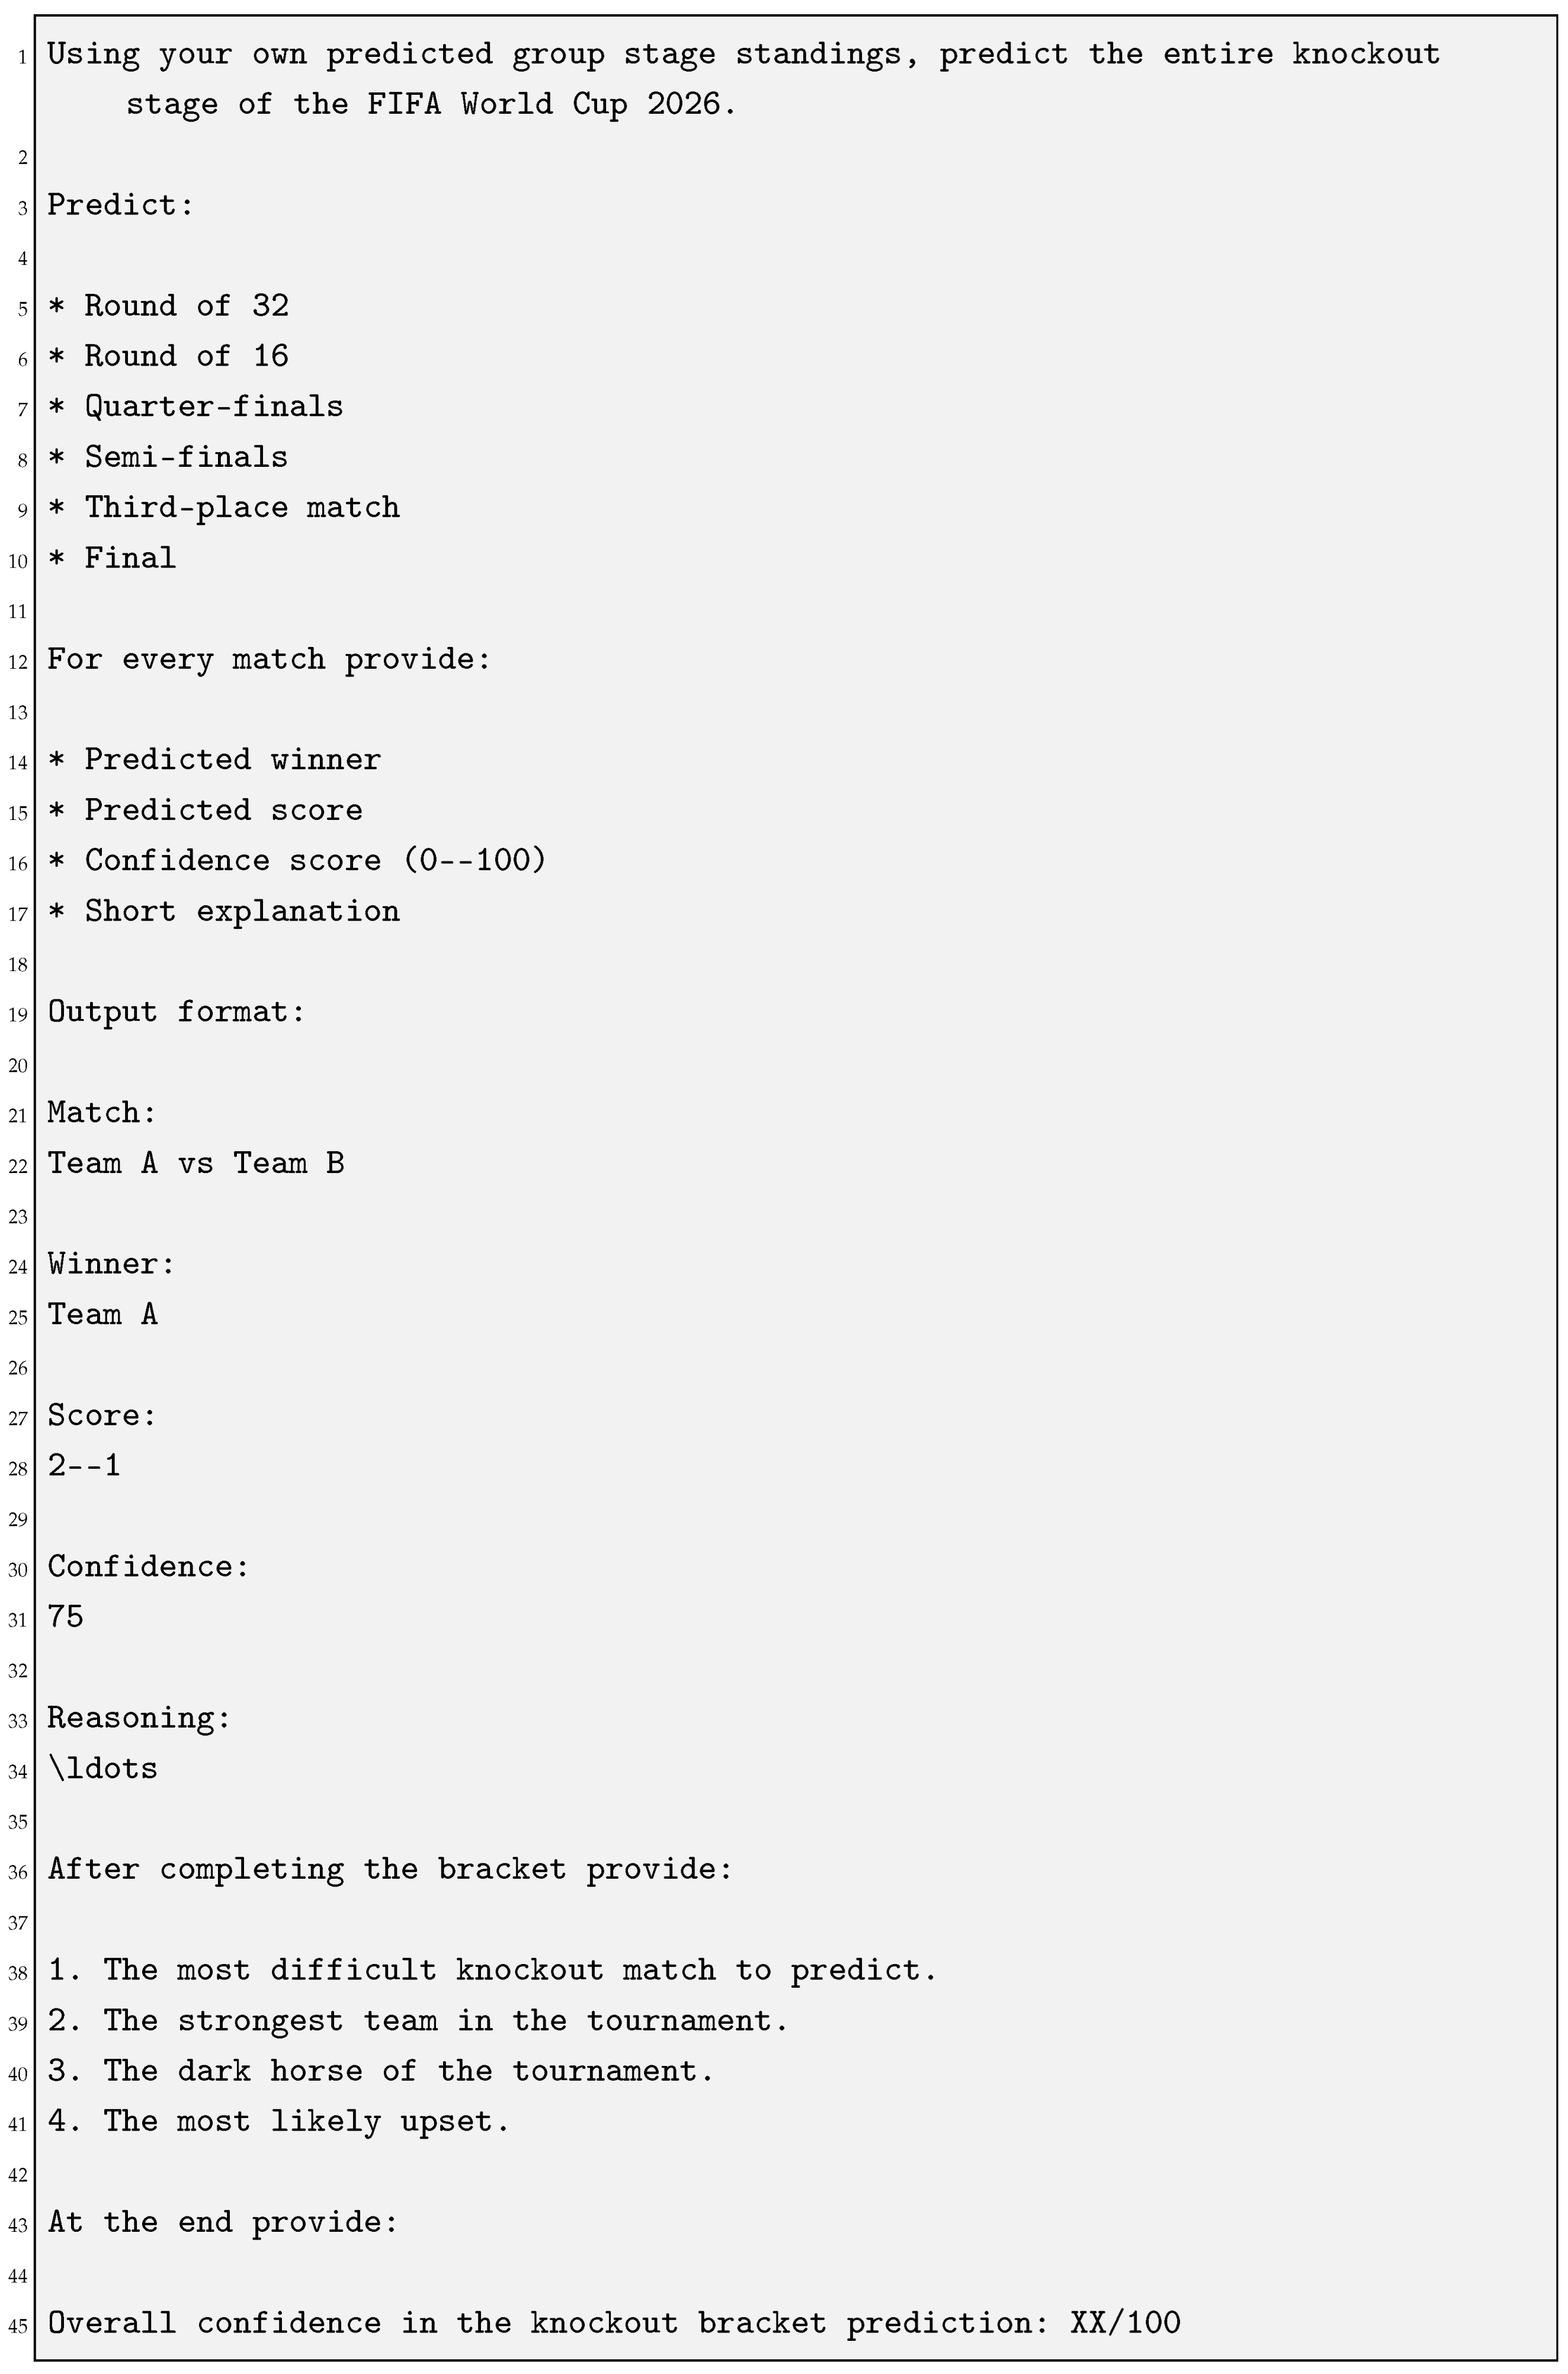 |
This prompt evaluates multi-stage tournament reasoning and the ability to maintain consistency between group-stage and knockout-stage forecasts.
3.5.4. Prompt 3: Champion Prediction
The third prompt, presented in Listing 4, focuses on the final tournament outcome and championship probabilities. Models were required to generate probabilistic forecasts and identify the most likely winners of the competition.
| Listing 4. User Prompt 3: Champion Prediction. |
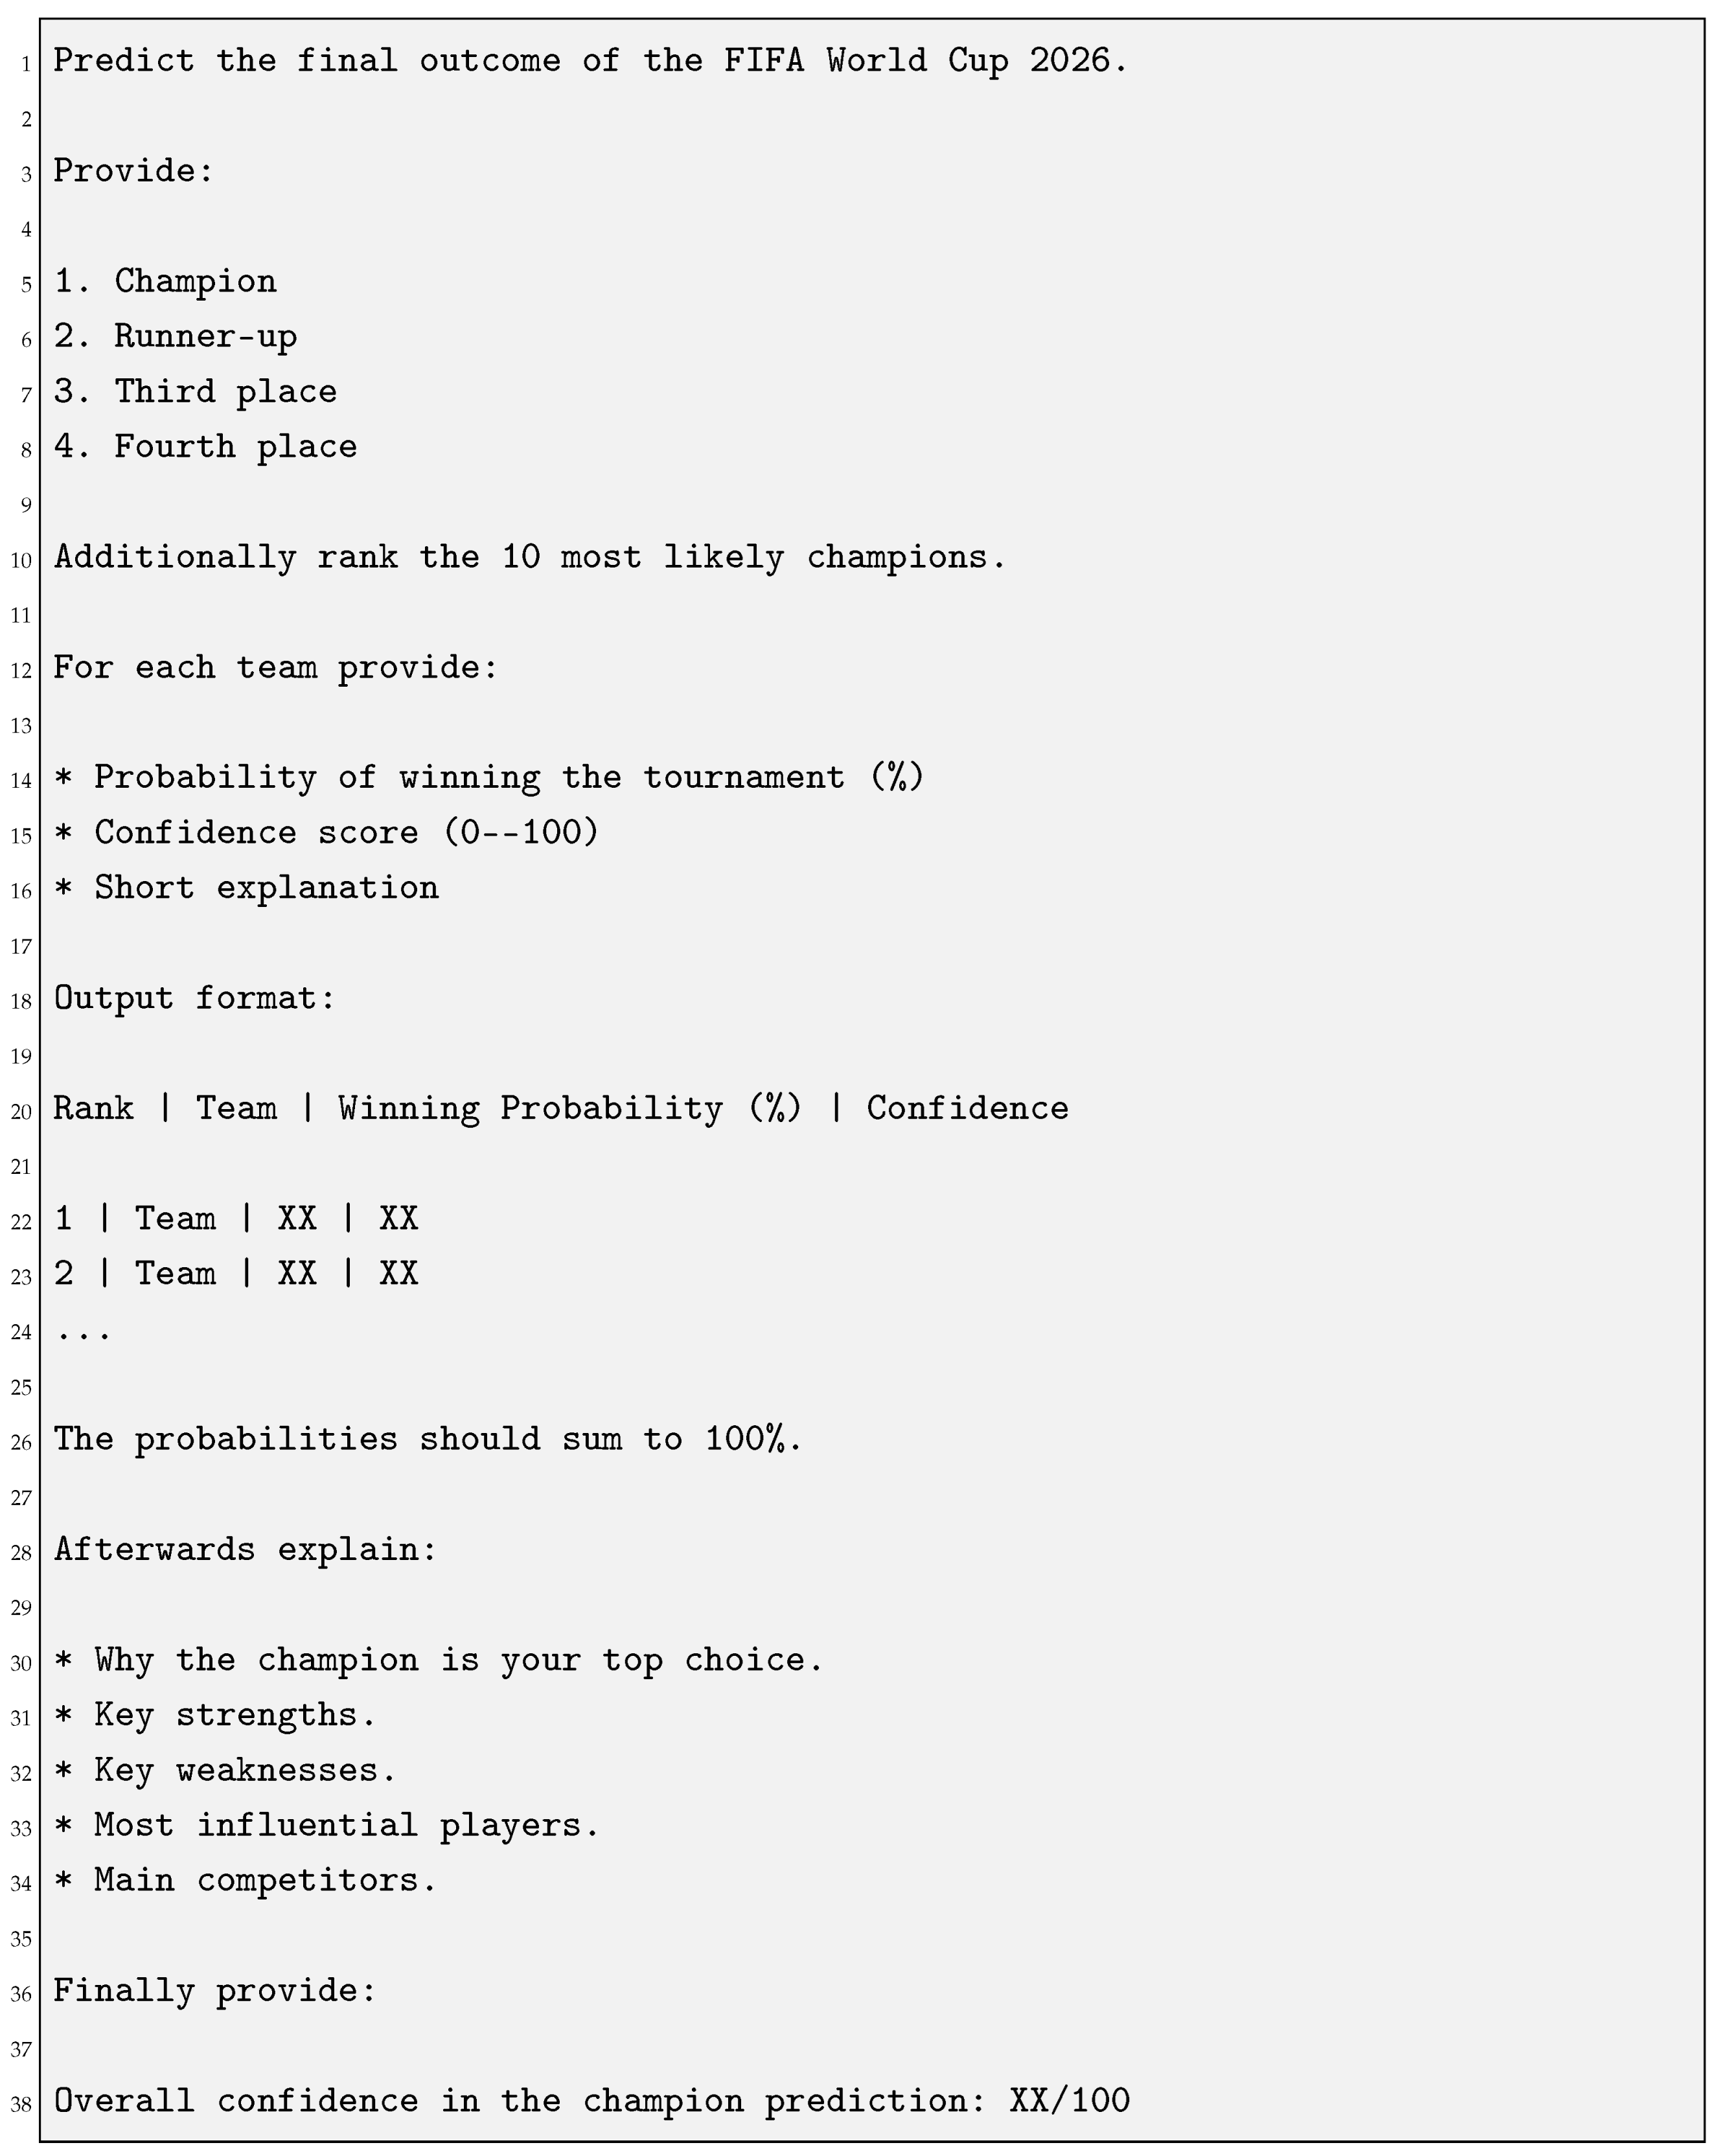 |
This prompt evaluates the ability of language models to synthesize information from the entire tournament and produce coherent probability-based forecasts.
3.6. Experimental Configurations
To investigate the influence of reasoning capabilities, external information retrieval, and stochastic decoding on forecasting performance, multiple experimental configurations were evaluated throughout the benchmark. The experimental design was constructed to systematically isolate the effects of these factors while maintaining identical forecasting tasks and prompt structures across all evaluated models.
3.6.1. Web Search Configurations
Recent generations of large language models increasingly support external information retrieval during inference. To assess the contribution of such capabilities to sports forecasting, two information-access configurations were considered whenever supported by the underlying platform. In the Web-Off configuration, the model relied exclusively on information acquired during pretraining, with no external information retrieval permitted during inference, thereby serving as a baseline representing purely parametric model knowledge. In the Web-On configuration, the model was allowed to access external web-search functionality and incorporate retrieved information into its forecasting process, enabling access to potentially relevant developments regarding multiple factors like team performance, player availability, rankings. The comparison between these configurations contributes to Research Question 2 by assessing the impact of web-search augmentation on tournament forecasting performance.
3.6.2. Reasoning Configurations
One of the most important developments in contemporary foundation models is the introduction of explicit reasoning mechanisms, with several evaluated models providing dedicated reasoning modes that allocate additional computational resources to analytical processing before generating a final response. Whenever supported by the corresponding platform, two configurations were evaluated: Reasoning-Off, corresponding to direct prediction mode without explicit reasoning mechanisms, and Reasoning-On, corresponding to reasoning-enhanced inference utilizing the model’s native reasoning capabilities. Reasoning-enabled configurations were expected to improve long-term tournament analysis by encouraging more structured evaluation of team strengths, tournament progression, uncertainty, and championship probabilities. Their comparison with direct prediction modes contributes to Research Question 2 by assessing the influence of explicit reasoning mechanisms on tournament forecasting performance.
3.6.3. Agentic Forecasting Configuration
In addition to conventional prompt-based forecasting, an agentic forecasting configuration was evaluated. Unlike standard inference, where predictions are generated directly from a user prompt, agentic forecasting allows the model to perform autonomous information gathering, iterative reasoning, and multi-step analysis before generating a final prediction, proceeding through five stages: gathering relevant external information, analyzing collected evidence, evaluating competing forecasting scenarios, refining predictions through iterative reasoning, and producing final tournament forecasts. This configuration represents a substantially different inference paradigm compared with conventional single-prompt prediction and was included to investigate Research Question 3 regarding the effectiveness of agentic forecasting.
3.6.4. Sampling and Repeated Experiments
To investigate prediction stability and consistency, multiple temperature settings were evaluated for direct-prediction configurations. Temperature set to 0, corresponding to near-deterministic decoding, was executed in a single run per configuration, while additional Temperature settings 0.7 and 1.0 were also investigated, introducing increasing levels of stochasticity, each experiment repeated five times, resulting in eleven independent forecasting outputs for each direct-prediction configuration. Reasoning-enabled models were executed using their native reasoning settings whenever explicit temperature control was unavailable through the corresponding API. This repeated-experiment design enables assessment of forecast variability, consensus behavior, confidence stability, and model calibration across stochastic decoding settings, thereby providing the experimental basis for Research Question 4.
3.6.5. Experimental Matrix
Combining the previously described configurations results in a multi-dimensional experimental design spanning multiple model ecosystems and deployment platforms, Web-On and Web-Off configurations, Reasoning-On and Reasoning-Off configurations, agentic forecasting configurations, multiple sampling temperatures, repeated stochastic executions, and three hierarchical forecasting tasks, as illustrated in Figure 3. This comprehensive design enables a detailed investigation of the factors influencing football tournament forecasting performance and provides a reproducible framework for future large language model forecasting benchmarks.
Figure 3.
Experimental configurations evaluated throughout the benchmark.
3.7. Evaluation Framework
A unique challenge of FIFA World Cup 2026 forecasting is that the tournament has not yet been completed at the time of this study, meaning that the true outcomes required for conventional predictive performance evaluation are not yet available. To address this limitation, a two-stage evaluation framework was developed, as illustrated in Figure 4. The first stage focuses on pre-tournament analysis and evaluates the quality, consistency, plausibility, and structural validity of the generated forecasts, while the second stage is designed for post-tournament evaluation and will be applied after the completion of the World Cup when the actual results will be available.
Figure 4.
Proposed evaluation framework for pre-tournament and post-tournament assessment.
Before evaluating forecasting quality, it is necessary to verify whether the generated predictions are structurally valid, as large language models may occasionally produce outputs containing formatting errors, invalid tournament structures, incorrect group compositions, or hallucinated teams. To quantify structural correctness, a Structural Validity Score (SVS) is defined as
where denotes the number of structurally valid predictions and represents the total number of evaluated predictions, with an SVS value of 1 indicating a completely valid prediction and lower values indicating structural inconsistencies or hallucinations.
For reporting purposes, structural validity is expressed on a 0–100 scale as
Thus, a value of 100 indicates complete structural validity, whereas lower values indicate an increasing proportion of structurally invalid forecast elements.
Complementing this measure, the Team Hallucination Rate (THR) quantifies the tendency of models to generate teams that are not part of the actual tournament, such as teams that did not qualify or nonexistent teams, and is defined as
where denotes the number of hallucinated teams and represents the total number of teams appearing in the generated forecasts. A lower THR indicates better factual consistency and stronger adherence to the actual tournament structure. In addition to the normalized THR, the analysis reports the average number of hallucinated team occurrences per forecasting run. This measure is denoted as hallucinations per run and provides a directly interpretable estimate of the absolute number of invalid team occurrences generated by each model configuration. Lower values therefore indicate stronger factual reliability, with a value of zero corresponding to a forecast containing no hallucinated team occurrences.
To evaluate the internal coherence of the generated tournament forecasts, a Consistency Score (CS) was additionally computed on a 0–100 scale. The score evaluates whether predictions remain logically compatible across the hierarchical forecasting stages. Consistency violations include the appearance of non-qualified teams in the knockout stage, knockout-stage participants that are not supported by the model’s own group-stage predictions, and disagreement between the champion identified in the final prediction and the winner generated in the knockout bracket. A value of 100 indicates complete internal consistency, while lower values indicate an increasing number or severity of cross-stage contradictions. The Qualification Consensus (QC) metric measures the degree to which different models agree on teams expected to advance beyond the group stage, and for team i is computed as
where denotes the number of models predicting team i to qualify for the knockout stage and represents the total number of evaluated models. An analogous measure, the Champion Consensus (CC), captures the proportion of models selecting a particular team as the tournament winner and is defined as
where here denotes the number of models predicting team i as champion. Higher consensus values indicate stronger collective agreement among forecasting systems and may serve as an indicator of perceived team strength. To further characterize forecast behavior, a Mainstream Alignment Index (MAI) is introduced. The metric quantifies the overlap between the model-generated set of championship contenders and a reference set derived from publicly available betting markets and expert forecasts:
where denotes the set of teams predicted by the model and represents the reference set derived from market-based rankings and expert forecasts. The MAI ranges from 0 to 100, where higher values indicate stronger alignment with mainstream expectations and lower values indicate more divergent forecasts.
In addition to the individual evaluation dimensions, an Overall Forecast Quality score was calculated for each forecasting run. This composite score is reported on a 0–100 scale and summarizes the overall reliability of a forecast by jointly considering structural validity, internal consistency, hallucination behavior, mainstream alignment, and the plausibility of the predicted champion. Higher scores therefore represent forecasts that are structurally valid, internally coherent, factually reliable, and broadly plausible. The Quality values reported in the result tables correspond to the average Overall Forecast Quality across the runs belonging to the respective model or experimental configuration. Forecast stability is evaluated by analyzing variations in predicted qualifiers, knockout-stage outcomes, and championship selections across repeated stochastic executions, with models producing highly consistent outputs expected to exhibit lower variability and stronger forecast robustness. Following the completion of the FIFA World Cup 2026, all archived predictions will be compared against the actual tournament outcomes using a Tournament Prediction Score (TPS) that rewards accurate predictions across multiple tournament stages:
where denotes correctly predicted champions, correctly predicted finalists, correctly predicted semi-finalists, correctly predicted quarter-finalists, correctly predicted group winners, and correctly predicted knockout-stage qualifiers. This scoring system provides a more comprehensive assessment of forecasting quality than championship prediction alone and better reflects the hierarchical nature of tournament prediction, thereby enabling robust post-tournament comparison across all evaluated models and configurations.
The weighting of the TPS was designed to reflect the increasing difficulty and specificity of predictions at progressively deeper tournament stages while preventing the final champion prediction from dominating the overall score. Although the champion receives the largest weight for a single correctly predicted outcome, its maximum contribution is 10 points out of a total possible TPS of 68 points, corresponding to approximately 14.7% of the complete score. The remaining 85.3% can be obtained through correct predictions of finalists, semi-finalists, quarter-finalists, group winners, and knockout-stage qualifiers. Consequently, the TPS does not reduce tournament forecasting performance to the identification of the eventual champion.
This structure also allows models to receive substantial credit for accurately forecasting the progression of unexpected or “dark horse” teams. A correctly anticipated dark-horse trajectory may contribute at several stages of the score, including qualification from the group stage and subsequent quarter-final, semi-final, or finalist appearances, even when the model does not correctly identify the eventual champion. Therefore, the TPS rewards both high-level tournament outcomes and the broader accuracy of the predicted tournament trajectory. To avoid overinterpreting a single composite measure, TPS is considered together with its individual stage-level components when comparing forecasting systems.
3.8. Statistical Analysis
The proposed benchmark generates a large collection of forecasts across multiple model families, inference configurations, and repeated executions, making statistical analysis essential for understanding forecasting behavior beyond individual predictions. The objective of the statistical evaluation is to quantify prediction stability, agreement among models, confidence characteristics, and the influence of reasoning and web-search augmentation. For numerical variables, including confidence scores, consensus measures, runtime measurements, and future tournament prediction scores, descriptive statistics are computed. The arithmetic mean is calculated as
where denotes an individual observation and n represents the total number of observations. The median is additionally reported to reduce sensitivity to outliers and extreme values that may arise from individual model predictions.
Inter-model agreement is evaluated through the Qualification Consensus and Champion Consensus metrics introduced in Section 3.7, with high consensus values indicating strong collective agreement and low values revealing uncertainty or disagreement among forecasting systems.
The benchmark additionally evaluates the influence of different inference strategies through comparative analyses conducted between reasoning-enabled and reasoning-disabled configurations, web-search-augmented and non-augmented configurations, proprietary and open-weight models, cloud-hosted and locally executed models, and agentic and conventional forecasting approaches, with descriptive statistical measures and relative differences reported for each comparison. The statistical analysis framework was designed to support both the pre-tournament evaluation presented in this study and the post-tournament evaluation strategies and metrics.
The comparative analyses in this study are primarily descriptive. A global inferential test such as ANOVA was not applied because the experimental matrix is heterogeneous and partially unbalanced: not all model families support identical reasoning, web-search, temperature, and agentic configurations. Consequently, treating all observations as samples from a common balanced factorial design could produce misleading significance estimates. Instead, the analysis focuses on directly observable differences between matched configurations, together with repeated-run stability and consensus measures. This design is intended to characterize model behavior before the tournament, while outcome-based statistical evaluation will become possible once the actual FIFA World Cup 2026 results are available.
3.9. Runtime Analysis
In addition to forecasting quality, computational efficiency represents an important practical consideration for large language model deployment. Contemporary foundation models vary substantially in terms of parameter count, architectural design, reasoning complexity, and information retrieval mechanisms, and these differences can significantly affect inference latency and computational cost. To quantify computational requirements, runtime information is automatically recorded for every experimental configuration, with metadata including additional information.
Runtime measurements are analyzed separately for the three forecasting tasks described in Section 3.4, as the tasks differ substantially in complexity and significant runtime differences are therefore expected. Group-stage forecasting represents the most computationally demanding task, requiring models to evaluate all tournament groups, estimate point distributions, identify qualifiers, and provide confidence assessments, while knockout-stage forecasting requires multi-round tournament simulation and reasoning about progression through the elimination bracket, and championship forecasting represents the most compact task as it focuses primarily on final tournament outcomes and probability estimation. Particular attention is given to agentic forecasting configurations, which unlike conventional single-prompt inference perform multiple intermediate operations including information retrieval, evidence gathering, and iterative reasoning, resulting in substantially longer runtimes.
4. Results
4.1. Structural Validity and Hallucination Analysis
The expansion of the FIFA World Cup 2026 to a 48-team format introduces significant complexity, presenting a rigorous test for the structural validity and factual accuracy of LLMs across the Claude, OpenAI, Ollama, and Gemini cohorts. A primary metric is team qualification validity. Grounded, web-enabled architectures demonstrated near-flawless execution, using exclusively qualified teams. Conversely, offline parametric models suffered severe qualification hallucinations, placing unqualified nations into groups. They also struggled with qualification ambiguity, selecting Italy on historical pedigree despite its qualification failures, or retaining placeholders like “African qualifier.” This highlights temporal anchoring and parametric memory decay, where offline models over-index on historical training weights.
Managing the transition to the expanded 12-group format (Groups A–L) revealed further vulnerabilities. While grounded models mapped the structures, offline configurations collapsed: hallucinating non-existent groups (“Group M”–“Group P”), generating impossible compositions (clustering France, Netherlands, Poland, and Kazakhstan), and failing bracket geometry, scheduling early knockout matches between same-group teams or resurrecting eliminated teams. Web-enabled models avoided these errors by querying live regulations, demonstrating that external search serves as a critical structural guardrail.
These dynamics are quantified in Table 1. Enabling web search () is the single most critical factor for structural validity. For OpenAI, it triggered a increase in Structural Validity (from to ) and slashed the Team Hallucination Rate by (from to per run). In Ollama, web-enabled models achieved validity while reducing hallucinations from to .
Table 1.
Core Performance Metrics across Configurations (Web Search W, Reasoning R).
However, enabling reasoning () without web grounding introduced a counterintuitive penalty: reasoning models hallucinated more than non-reasoning counterparts ( vs. per run). This reasoning paradox stems from verbose rationalization bias, extended chain-of-thought traces expand the cognitive surface area, prompting plausible-sounding but fabricated tournament paths. Consequently, the optimal hierarchy requires Grounded Reasoning Engines (Claude 3.5 Sonnet, GPT-5.5 online, DeepSeek-v3.1 online) that couple web-retrieved facts with active reasoning loops, eliminating the reasoning-inflation penalty.
4.2. Qualification and Champion Consensus Analysis
We conducted a meta-analysis of 194 OpenAI runs and 1056 Ollama/Cloud runs. Across configurations, engines demonstrated a top-heavy consensus regarding deep-knockout qualifiers. Rather than distributing probabilities across the 48 nations, models converged on a triumvirate: France, Argentina, and Spain. In OpenAI, France led at 48.0%, followed by Spain (22.3%) and Argentina (19.6%). In Ollama, a duopoly emerged between France (40.6%) and Argentina (40.1%), with Spain and Brazil forming a secondary tier. Combined, France and Argentina captured 78.8% of all simulated outcomes (41.7% and 37.1% respectively). Table 2 details this distribution.
Table 2.
Aggregate Impact of Web Search across All Evaluated Forecasts (Weighted Average, ).
This reveals a profound legacy bias and temporal anchoring in offline runs. Giants like Brazil and France are favored because static weights capture historical Elo ratings and brand value, ignoring active qualifying struggles. Conversely, Spain’s representation spiked significantly in web-enabled runs, reflecting real-time Euro 2024 performance overriding parametric biases. England was systematically snubbed across both cohorts (), suggesting reasoning engines penalize its historical tournament inefficiencies and tactical setups. Germany and Portugal were similarly ignored (0.1–0.2%).
Consensus varies sharply by scale. High-tier reasoning models (Claude 3.5 Sonnet, GPT-5.5, DeepSeek-v3.1, Kimi-k2.6) exhibited strong internal consistency and realistic qualifiers. Lightweight models like Claude 3 Haiku introduced severe anomalies, predicting unqualified nations (Kazakhstan, Vietnam, Montenegro, Wales, Greece, Romania) to advance deep. This represents a heuristic cascade where non-reasoning models rely on reputation shortcuts rather than validating qualification constraints.
As summarized in Table 1, web search boosts Validity, Quality and reduces hallucinations. Without grounding, models rely on probabilistic confabulation, advancing retired players or unqualified nations. While reasoning improves consistency, it introduces verbose rationalization bias when web search is disabled. While Table 1 provides configuration- and model-family-specific results, the following table presents the complementary aggregate effect of web-search augmentation across all evaluated runs. This aggregated view is retained because it enables the overall magnitude and direction of the web-search effect to be interpreted directly, without requiring readers to derive a weighted comparison from the individual model-family results.
4.3. Champion Confidence and Calibration
Analyzing the relationship between internal confidence and prediction validity reveals a severe calibration gap. In offline configurations, models exhibited uncalibrated confidence, maintaining high internal consistency while outputting invalid brackets. Claude 3 Haiku displayed overconfidence, outputting 70–90% confidence scores while placing non-qualified nations into brackets. Conversely, Claude 3 Opus and 3.5 Sonnet calibrated within a realistic 30–65% range, acknowledging inherent uncertainty. Enabling real-time web search resolved this gap, anchoring confidence in live sports databases, betting exchanges, and official regulations.
4.4. Mainstream Prediction Analysis
We analyzed alignment with mainstream sports projections, betting markets, and historical baselines using the Mainstream Alignment Index (MAI), graded 0–100. Stratification was heavily dictated by architecture and real-time data access (see Table 2 footnote). The primary driver is Web-Augmented Search (): grounded models dynamically adjust predictive weights based on Euro 2024 results, Copa América form, and squad fitness, causing Spain’s share to spike to 22.3% (OpenAI) and 9.4% (Ollama). Offline models suffer temporal anchoring, over-indexing on historical prestige and disproportionately selecting Brazil, Germany, or Italy based on embedded Elo ratings, ignoring cyclical declines and qualification realities.
A major anomaly is the near-total neglect of tier-one favorites. England is heavily undervalued: . While betting markets position England as a co-favorite, the models discount them due to historical underperformance, perceived tactical inefficiencies, and complex bracket pathing. Germany and Portugal are functionally ignored (0.1–0.2%), indicating systemic conservativeness toward historical safe-havens.
For dark horses, models display varying risk-taking. Claude’s reasoning models demonstrate the most sophisticated mapping: Norway via Haaland and Ødegaard’s offensive metrics, Uruguay via Bielsa’s high-intensity setup, and Japan/Australia securing group-stage upsets. Conversely, ungrounded models resort to factual confabulation, predicting unqualified nations (Vietnam, Kazakhstan, Montenegro) to reach quarterfinals—a critical limitation of parametric-only forecasting.
4.5. Effect of Reasoning on Forecasting
We analyzed the delta between Reasoning-Enabled (System 2, CoT) and Reasoning-Disabled (System 1) configurations across 1056 Ollama/Cloud and 194 OpenAI runs (Table 1). The most prominent gain of activating reasoning () is a point surge in logical consistency (from to ), ensuring multi-step brackets remain coherent and preventing contradictions like predicting a team to win a group while showing them eliminated. The Claude meta-analysis confirms this: high-thinking modes elevated quality, with Claude 3 Opus improving 84→92 and Claude 3.5 Sonnet 82→88.
However, this stabilization introduces the reasoning paradox: reasoning in ungrounded models increased hallucinations from 6.88 to 7.89 per run (). This might be due to the fact, that the model reasons about outdated or false data, and the reasoning mechanism verbose this deceitful information, which resullts in higher hallucination scores. Reasoning engines prioritize internal narrative consistency over external truth, fabricating detailed match histories against unqualified nations. Suppressing this requires coupling reasoning with web search, dropping hallucinations to 2.86 per run.
The System 1→2 transition also shifts champion selection. Reasoning-disabled models rely on heuristic cascades, over-selecting Brazil and Germany. Reasoning-enabled models execute explicit path-to-final mapping, head-to-head simulations, and squad-depth evaluations, converging on a France–Argentina duopoly with Spain as primary threat. Reasoning also acts as a structural guardrail, filtering out qualification hallucinations and stabilizing matchups to sound pairings (France vs. Spain/Argentina), while resolving the calibration gap toward the realistic 30–65% range.
4.6. Effect of Web Search Augmentation
We analyzed the delta between parametric-only and grounded, retrieval-augmented forecasting. Web search transforms the LLMs from a probabilistic fabricator into an analytical synthesizer. Across all metrics, web-enabled models systematically outperformed offline counterparts (Table 1).
The most significant leap is in Structural Validity: points (OpenAI) and points (Ollama). Web search resolves structural contradictions by providing exact tournament schemas, qualifying paths, and group rules. It also introduces real-time temporal grounding, mitigating temporal anchoring. While offline models over-indexed on Brazil and Germany, web-enabled models incorporated Euro 2024 and Copa América form, spiking Spain’s rate to 22.3% (OpenAI) and 9.4% (Ollama). Grounded models also filtered out retired/injured players. In the Claude meta-analysis, web-enabled runs eliminated Haiku’s severe qualification hallucinations.
Web search slashed hallucinations by 78.7% (OpenAI) and 75.7% (Ollama), shifting operation from fragile recall to verification-based synthesis. Crucially, the web–reasoning interaction matters: enabling reasoning without web search increased hallucinations from 6.88 to 7.89 per run (verbose rationalization bias), but coupling them entirely suppresses this penalty. Finally, web search aligns predictions with betting markets and Elo ratings, converging on the France–Argentina duopoly. Notably, even web-enabled models undervalued England (≤1.0%), demonstrating that grounded engines perform independent synthesis rather than merely copying betting markets. This realignment is directly reflected in the Mainstream Alignment Index (MAI)., which rose sharply under grounding—lifting the Ollama cohort from a legacy-biased 65.0/100 toward the calibrated 87.5/100 range observed in web-enabled Claude runs.
4.7. Agentic Forecasting Results
We contrast standard offline prompting against an agentic workflow combining web-search () and systematic reasoning (). The transition yields substantial gains (Table 1): validity rises to 90.87% (OpenAI) and a near-flawless 97.04% (Ollama). While web search drives factual grounding, reasoning acts as a logical stabilizer. In agentic mode the two counteract each other’s weaknesses—search feeds verified facts, suppressing the reasoning-induced penalty and dropping hallucinations to 2.33 (OpenAI) and 2.86 (Ollama).
Distinct family behaviors emerged. Reasoning-enabled Claude 3 Opus and 3.5 Sonnet achieved the highest quality, while Claude 3 Haiku suffered structural breakdowns (Kazakhstan, Vietnam). Open-source DeepSeek-v3.1 and Qwen3-Coder achieved perfect scores when grounded, matching proprietary models. Cloud reasoning models Kimi-k2.6 and GLM-5.1 leveraged massive context windows and native search for zero-hallucination multi-step verification.
Champion calibration (Table 2) shows France as the default safe prediction, with web search spiking Spain’s share to 22.3% (OpenAI) via Euro 2024 form, while England remains undervalued (<1.0%).
Production deployment introduces latency trade-offs. Prompt 1 (validity audit) requires ∼12 min due to sequential tool execution and search loops. Prompt 2 (consensus) requires ∼9 min, dominated by context window size. Prompt 3 (mainstream synthesis) runs in under 2 min by mapping against pre-retrieved betting indexes. Architects must manage latency budgets via hybrid pipelines—rapid parametric generation for static tasks, agentic loops reserved for structural validation.
4.8. Forecast Stability Analysis
We conducted a stability analysis across 1250 runs, focusing on temperature perturbation, champion selection, bracket consistency, and inter-/intra-model variance. At conservative , models exhibit high intra-model stability, anchoring to historical priors; web-grounded models exceed validity via stable RAG pathways. At , prediction entropy increases, exposing offline vulnerabilities—hallucinations escalate to 10.95 (OpenAI) and 11.77 (Ollama), yielding impossible brackets.
The champion distribution (Table 2) shows concentrated consensus. OpenAI exhibits a tri-polar consensus (France, Spain, Argentina = 89.9%), while Ollama/cloud converge on a France–Argentina duopoly (over 80%). Legacy bias drives offline models toward Brazil and dominant European teams; web search shifts consensus to incorporate Spain’s Euro 2024 victory. England is universally undervalued (<1.0%) regardless of prompt conditions.
The largest instability source is qualification/bracket validity. Reasoning-enabled Opus and Sonnet adhere to the 12-group format, while non-reasoning Haiku introduces fictional Groups M–P and hallucinated participants (Kazakhstan, Vietnam, Montenegro, Romania). Offline models yield failing validity (58.50% OpenAI, 53.39% Ollama); web search lifts these to 90.87% and 97.04%.
Variance analysis reveals an architectural trade-off. Intra-model variance depends on web access—offline runs show high variance from random activation paths, while web-enabled runs display low variance via identical real-world datasets. Reasoning optimizes consistency ( Ollama) but introduces verbose rationalization bias (7.89 vs. 6.88 hallucinations when ungrounded). The optimal architecture synthetically integrates both engines, eliminating the reasoning hallucination penalty while maximizing consistency.
4.9. Runtime Analysis Results
We conducted runtime analysis across 194 OpenAI, 1056 Ollama/cloud-hybrid, and meta-analytical Claude runs. Deployment introduces a trade-off between network overhead and hardware-bound throughput. Cloud models (GPT-5.5, Claude 3 Opus, Gemini) benefit from parallelized TPU/GPU clusters with 15–50 ms/token latencies, but face variable network latency, rate-limiting, and serialization overhead. Local Ollama execution eliminates network dependencies but is bound by GPU VRAM, memory bandwidth, and tensor utilization. Ultra-large local models (120B–671B) experience severe bottlenecks when weights offload to system RAM.
Advanced capabilities shift execution from pure parametric generation to multi-step workflows (Table 3). Reasoning adds a latency multiplier, increasing token volume by 150–300%. Web grounding adds 2–8 s/query for execution, parsing, filtering, and injection. Agentic mode is most latency-intensive (sequential search, synthesis, reasoning) but yields the highest validity.
Table 3.
Latency Profiles by Model Configuration.
Complexity is sensitive to the prompt task. Prompt 1 (validity audit) yields high parsing/generation latency from massive bracket parsing and structured JSON output. Prompt 2 (consensus) is dominated by context window size. Prompt 3 (mainstream) triggers external odds queries, dependent on API response times. Prompt 4 (reasoning comparison) exhibits bimodal runtime—reasoning-disabled resolves rapidly, reasoning-enabled hits maximum latency from comparative matrices.
4.10. Summary of Main Findings
Based on the conducted experiments: Claude 3 Opus (high-thinking) and GPT-5.5 emerged as the most stable proprietary engines, with GPT-5.5 achieving perfect quality and validity when configured with web search and reasoning. Among open-source/cloud models, DeepSeek-v3.1, Kimi-k2.6, and the 120B GPT-OSS demonstrated the highest stability. In contrast, lightweight non-reasoning Claude 3 Haiku proved highly unstable, with severe structural breakdowns.
Predictive consensus concentrated around international powerhouses, but mainstream alignment depended entirely on configuration. Web-enabled models were most mainstream, incorporating active data (Spain’s Euro 2024 victory, Argentina’s Copa América form) to shift probabilities toward tactical contenders. Web-disabled models suffered legacy bias, over-selecting Brazil, Germany, and Italy. England was universally undervalued (<1.0%) despite co-favorite status, suggesting LLMs actively penalize its tactical setup and pathing efficiency rather than replicating market trends.
Hallucinations were governed by external search. OpenAI’s web-enabled runs achieved the lowest rate (2.33/run), with Ollama following (2.86). The reasoning paradox saw ungrounded reasoning increase hallucinations from 6.88 to 7.89 per run, driven by verbose rationalization bias. As summarized in Table 1, web grounding is the primary value driver ( validity, quality), shifting from recall to verification, while reasoning is a logical stabilizer ( consistency). The optimal configuration synthesizes grounded search () and reasoning (): search feeds verified facts that suppress verbose rationalization, while reasoning processes them through systematic planning for accurate, consistent, structurally valid forecasts.
To summarize the key takeaways: the most stable engines were GPT-5.5 and Claude 3 Opus (high-thinking) among proprietary models, and DeepSeek-v3.1 among open-source models. The most mainstream predictions came from web-enabled Claude (MAI 87.5/100), driven by Euro 2024 calibration. The fewest hallucinations were produced by OpenAI’s web-enabled runs (2.33/run), with Kimi-k2.6 and GLM-5.1 reaching zero. Finally, the architectural features produced clearly visible differences: web search delivered the largest single gain ( validity), reasoning improved consistency () but increased hallucinations by when ungrounded, and the synthesized agentic mode () proved optimal—combining both benefits without the penalty.
5. Discussion
The rapid development of large language models has raised important questions regarding their applicability beyond traditional natural language processing tasks. While recent foundation models have demonstrated remarkable capabilities in reasoning, knowledge synthesis, decision support, and complex problem solving, relatively little attention has been devoted to their use as forecasting systems in large-scale sports competitions. The FIFA World Cup 2026 provides a unique opportunity to investigate how contemporary language models perform when confronted with a complex real-world prediction task characterized by uncertainty, incomplete information, and multi-stage tournament dynamics.
The results reveal that web-search augmentation is the single most impactful architectural feature evaluated in this benchmark. Enabling external information retrieval produced a +32.37 point increase in structural validity for OpenAI models and a +43.65 point increase for the Ollama cohort, while simultaneously reducing hallucinations by 78.7% and 75.7%, respectively. Beyond correcting structural errors, web search introduced real-time temporal grounding that fundamentally altered champion prediction distributions. Offline models over-indexed on historical prestige and disproportionately selected Brazil, Germany, and Italy based on embedded Elo ratings, while web-enabled models dynamically incorporated Euro 2024 and Copa América form and caused Spain’s predicted champion probability to spike to 22.3% in OpenAI runs. These findings suggest that sports forecasting is a domain where the temporal currency of information is particularly critical, and that web augmentation addresses a structural weakness of static pretrained models that cannot be compensated for through reasoning alone.
Explicit reasoning mechanisms provided measurable but more nuanced benefits. Enabling reasoning improved logical consistency by +14.19 percentage points in the Ollama cohort, ensuring multi-step brackets remained coherent and preventing internal contradictions across tournament stages. However, the benchmark also uncovered a counterintuitive reasoning paradox. When web search was disabled, reasoning increased hallucinations from 6.88 to 7.89 per run due to verbose rationalization bias, as extended chain-of-thought traces expanded the cognitive surface area and generated plausible but factually incorrect tournament paths. The optimal configuration, therefore, requires both capabilities in combination, as demonstrated by the agentic forecasting results, where coupling iterative web retrieval with systematic reasoning simultaneously suppressed hallucinations to 2.33 per run in the OpenAI cohort and 2.86 per run in the Ollama cohort, while structural validity reached 90.87% and 97.04% respectively.
One of the most interesting aspects of this study is the comparison between proprietary frontier models and open-weight systems. The benchmark reveals that the performance gap between these families is substantially smaller than expected. DeepSeek-v3.1, Kimi-k2.6, and the 120B GPT-OSS matched the structural validity of proprietary frontier systems when properly grounded, while the most critical determinant of performance was inference configuration rather than model ownership. By contrast, lightweight non-reasoning models exhibited severe structural breakdowns regardless of origin, confirming that architectural design choices, particularly the incorporation of reasoning mechanisms, are at least as consequential as parameter scale for forecasting quality. These findings also highlight an important distinction between the proposed LLM-based benchmark and earlier FIFA World Cup forecasting approaches. Previous studies such as those of [18,19] relied on structured team-strength indicators, statistical modeling, and tournament simulation. In contrast, the present results show that LLM-based forecasting is strongly influenced by inference-time factors, particularly access to current external information and the interaction between retrieval and reasoning. This does not imply that LLM-based forecasting outperforms established statistical approaches; such a comparison can only be made after the tournament outcomes become available. Rather, the present benchmark demonstrates that the reliability of LLM forecasts depends not only on the underlying model but also on how information is accessed and processed during inference.
The post-tournament comparison should be interpreted in the context of the primary objective of this study. The benchmark was not designed under the assumption that contemporary large language models would reproduce the exact final tournament ranking. Rather, its purpose was to empirically investigate how accurately LLMs can prospectively forecast a complex international tournament, which model configurations perform better, and where systematic forecasting limitations emerge. From this perspective, discrepancies between the predicted and observed outcomes constitute an important part of the evaluation rather than a failure of the experimental design.
The final outcome illustrates this distinction. Spain and Argentina were both consistently represented among the principal championship contenders, indicating that the models were able to identify teams with strong tournament potential, even though the exact ordering of the final positions was frequently incorrect. By contrast, England’s third-place finish was substantially underestimated across the evaluated configurations, revealing a clear forecasting limitation. These observations demonstrate that LLM-based forecasting can capture part of the competitive structure of the tournament while remaining considerably less reliable in reproducing the exact realized tournament path. Such differences are precisely what the proposed benchmark was designed to quantify and analyze.
More broadly, this study contributes to the emerging field of LLM-based forecasting by providing a reproducible framework applicable beyond football prediction. The FIFA World Cup 2026 serves as a natural large-scale benchmark because predictions are eventually verifiable through objective real-world outcomes. The completion of the tournament will enable a comprehensive evaluation of all generated forecasts using the proposed Tournament Prediction Score, providing valuable insights into the practical forecasting capabilities of contemporary foundation models and the relationship between reasoning, information retrieval, agentic behavior, and real-world predictive performance.
6. Conclusions
This study introduced a comprehensive benchmark framework for evaluating the forecasting capabilities of contemporary large language models in the context of the FIFA World Cup 2026. The proposed benchmark extends beyond traditional sports prediction studies by systematically investigating the influence of reasoning mechanisms, web-search augmentation, model scale, deployment strategy, and agentic behavior on tournament forecasting performance.
Unlike conventional football forecasting approaches that rely primarily on statistical models and domain-specific machine learning techniques, the evaluated foundation models generate predictions by combining large-scale pretrained knowledge with reasoning and information synthesis capabilities. Consequently, the benchmark not only assesses football forecasting performance but also provides a broader perspective on the predictive abilities of modern large language models.
The results demonstrate that web-search augmentation is the single most critical factor for forecasting quality, producing structural validity gains of +32.37 points in the OpenAI cohort and +43.65 points in the Ollama cohort, while reducing hallucinations by 78.7% in the OpenAI cohort and 75.7% in the Ollama cohort. Reasoning mechanisms improved logical consistency by +14.19 percentage points in the Ollama cohort but introduced a counterintuitive hallucination penalty when applied without external grounding, a reasoning paradox that was fully resolved only in the agentic configuration combining real-time retrieval with systematic multi-step reasoning. Proprietary frontier models such as GPT-5.5 and Claude 3 Opus achieved the highest stability among commercial systems, while open-weight models including DeepSeek-v3.1 and Kimi-k2.6 matched their performance when properly grounded, demonstrating that inference configuration is a more decisive factor than model ownership. Across all configurations, champion predictions concentrated around France, Argentina, and Spain, with France leading across both cohorts, Spain surpassing Argentina in OpenAI runs following Euro 2024 calibration, and a France and Argentina duopoly emerging in the Ollama cohort, while England remained universally undervalued despite its co-favorite status in mainstream betting markets, suggesting that grounded models perform independent evidence synthesis rather than replicating market consensus.
A key contribution of this work is the introduction of a hierarchical tournament forecasting framework consisting of group-stage prediction, knockout-stage prediction, and championship prediction tasks, together with a post-tournament evaluation protocol based on the proposed Tournament Prediction Score. This design enables both immediate comparative analysis of model behavior and future quantitative assessment of real-world forecasting accuracy following the completion of the FIFA World Cup 2026.
Beyond the specific application to football forecasting, the benchmark contributes to the broader field of AI-based forecasting by providing a reproducible methodology that can be adapted to other international sporting events, elections, financial forecasting problems, and decision-support scenarios where future outcomes are uncertain and multiple forecasting strategies must be compared. Future work will focus on extending the benchmark to additional model families, incorporating retrieval-augmented forecasting architectures, and investigating the integration of large language models with traditional statistical forecasting techniques to further improve prediction accuracy in large-scale international tournaments.
Author Contributions
Conceptualization, Á.H. and D.-F.L.; methodology, Á.H., D.D. and D.-F.L.; software, Á.H. and D.D.; validation, Á.H., D.D. and B.S.; formal analysis, Á.H. and D.D.; investigation, Á.H. and D.D.; resources, B.S., S.L. and D.-F.L.; data curation, Á.H. and D.D.; writing-original draft preparation, Á.H. and D.-F.L.; writing-review and editing, D.D., B.S., S.L. and D.-F.L.; visualization, Á.H. and D.D.; supervision, B.S. and D.-F.L.; project administration, D.-F.L. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The data generated and analyzed during the current study are available from the corresponding authors upon reasonable request.
Acknowledgments
On behalf of the Development of Artificial Intelligence in the Medical Field project, we gratefully acknowledge the opportunity to use the ELKH Cloud (see Héder et al., 2022; https://science-cloud.hu/), which significantly contributed to the results presented in this paper. The authors acknowledge the use of generative artificial intelligence (GenAI) tools for improving the linguistic quality and readability of the manuscript. These tools were used exclusively for grammar correction, language refinement, and stylistic improvements. The authors take full responsibility for the scientific content, interpretation of the results, and conclusions presented in this work.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AI | Artificial intelligence |
| CC | Champion Consensus |
| CoT | Chain of thought |
| LLM | Large language model |
| MAI | Mainstream Alignment Index |
| QC | Qualification Consensus |
| RAG | Retrieval-augmented generation |
| RQ | Research question |
| SVS | Structural Validity Score |
| THR | Team Hallucination Rate |
| TPS | Tournament Prediction Score |
References
- Tax, N.; Joustra, Y. Predicting the Dutch football competition using public data: A machine learning approach. Trans. Knowl. Data Eng. 2015, 10, 1–13. [Google Scholar]
- Constantinou, A.C.; Fenton, N.E. Determining the level of ability of football teams by dynamic ratings based on the relative discrepancies in scores between adversaries. J. Quant. Anal. Sports 2013, 9, 37–50. [Google Scholar] [CrossRef] [Scilit]
- Hubáček, O.; Šourek, G.; Železnỳ, F. Learning to predict soccer results from relational data with gradient boosted trees. Mach. Learn. 2019, 108, 29–47. [Google Scholar] [CrossRef] [Scilit]
- Brown, T.; Mann, B.; Ryder, N.; Subbiah, M.; Kaplan, J.D.; Dhariwal, P.; Neelakantan, A.; Shyam, P.; Sastry, G.; Askell, A.; et al. Language models are few-shot learners. Adv. Neural Inf. Process. Syst. 2020, 33, 1877–1901. [Google Scholar]
- Achiam, J.; Adler, S.; Agarwal, S.; Ahmad, L.; Akkaya, I.; Aleman, F.L.; Almeida, D.; Altenschmidt, J.; Altman, S.; Anadkat, S.; et al. Gpt-4 technical report. arXiv 2023, arXiv:2303.08774. [Google Scholar]
- Touvron, H.; Lavril, T.; Izacard, G.; Martinet, X.; Lachaux, M.; Lacroix, T.; Rozière, B.; Goyal, N.; Hambro, E.; Azhar, F.; et al. LLaMA: Open and Efficient Foundation Language Models. arXiv 2023, arXiv:2302.13971. [Google Scholar]
- Horton, J.J.; Filippas, A.; Manning, B.S. Large Language Models as Simulated Economic Agents: What Can We Learn from Homo Silicus? Technical Report; National Bureau of Economic Research: Cambridge, MA, USA, 2023. [Google Scholar]
- Halawi, D.; Zhang, F.; Yueh-Han, C.; Steinhardt, J. Approaching human-level forecasting with language models. Adv. Neural Inf. Process. Syst. 2024, 37, 50426–50468. [Google Scholar] [CrossRef] [Scilit]
- Guo, D.; Yang, D.; Zhang, H.; Song, J.; Wang, P.; Zhu, Q.; Xu, R.; Zhang, R.; Ma, S.; Bi, X.; et al. Deepseek-r1: Incentivizing reasoning capability in llms via reinforcement learning. arXiv 2025, arXiv:2501.12948. [Google Scholar]
- Jaech, A.; Kalai, A.; Lerer, A.; Richardson, A.; El-Kishky, A.; Low, A.; Helyar, A.; Madry, A.; Beutel, A.; Carney, A.; et al. Openai o1 system card. arXiv 2024, arXiv:2412.16720. [Google Scholar]
- Yang, A.; Li, A.; Yang, B.; Zhang, B.; Hui, B.; Zheng, B.; Yu, B.; Gao, C.; Huang, C.; Lv, C.; et al. Qwen3 technical report. arXiv 2025, arXiv:2505.09388. [Google Scholar]
- Bommasani, R.; Liang, P.; Lee, T. Holistic evaluation of language models. Ann. N. Y. Acad. Sci. 2023, 1525, 140–146. [Google Scholar] [CrossRef] [Scilit]
- Chang, Y.; Wang, X.; Wang, J.; Wu, Y.; Yang, L.; Zhu, K.; Chen, H.; Yi, X.; Wang, C.; Wang, Y.; et al. A survey on evaluation of large language models. ACM Trans. Intell. Syst. Technol. 2024, 15, 39. [Google Scholar] [CrossRef] [Scilit]
- Dixon, M.J.; Coles, S.G. Modelling association football scores and inefficiencies in the football betting market. J. R. Stat. Soc. Ser. C Appl. Stat. 1997, 46, 265–280. [Google Scholar] [CrossRef] [Scilit]
- Bunker, R.; Susnjak, T. The application of machine learning techniques for predicting match results in team sport: A review. J. Artif. Intell. Res. 2022, 73, 1285–1322. [Google Scholar] [CrossRef] [Scilit]
- Horvat, T.; Job, J. The use of machine learning in sport outcome prediction: A review. Wiley Interdiscip. Rev. Data Min. Knowl. Discov. 2020, 10, e1380. [Google Scholar] [CrossRef] [Scilit]
- Bunker, R.P.; Thabtah, F. A machine learning framework for sport result prediction. Appl. Comput. Inform. 2019, 15, 27–33. [Google Scholar] [CrossRef] [Scilit]
- Groll, A.; Ley, C.; Schauberger, G.; van Eetvelde, H. Prediction of the fifa world cup 2018-a random forest approach with an emphasis on estimated team ability parameters. arXiv 2018, arXiv:1806.03208. [Google Scholar]
- Groll, A.; Ley, C.; Schauberger, G.; van Eetvelde, H. A hybrid random forest to predict soccer matches in international tournaments. J. Quant. Anal. Sports 2019, 15, 271–287. [Google Scholar] [CrossRef] [Scilit]
- Rein, R.; Memmert, D. Big data and tactical analysis in elite soccer: Future challenges and opportunities for sports science. SpringerPlus 2016, 5, 1410. [Google Scholar] [CrossRef] [Scilit]
- Karger, E.; Bastani, H.; Yueh-Han, C.; Jacobs, Z.; Halawi, D.; Zhang, F.; Tetlock, P.E. ForecastBench: A Dynamic Benchmark of AI Forecasting Capabilities. In Proceedings of the International Conference on Learning Representations (ICLR), Singapore, 24–26 April 2025. [Google Scholar]
- Dai, H.; Teehan, R.; Ren, M. Are LLMs Prescient? A Continuous Evaluation using Daily News as the Oracle. In Proceedings of the 42nd International Conference on Machine Learning. PMLR, Vancouver, BC, Canada, 13–19 July 2025; Proceedings of Machine Learning Research: Cambridge, MA, USA, 2025; Volume 267, pp. 12179–12213. [Google Scholar]
- Zhang, Z.; Cao, Y.; Ye, C.; Ma, Y.; Liao, L.; Chua, T.S. Analyzing Temporal Complex Events with Large Language Models? A Benchmark towards Temporal, Long Context Understanding. In Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), Bangkok, Thailand; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 1588–1606. [Google Scholar] [CrossRef] [Scilit]
- Anthropic. The Claude 3 Model Family: Opus, Sonnet, Haiku; Technical Report; Anthropic: San Francisco, CA, USA, 2024. [Google Scholar]
- Team, G.; Anil, R.; Borgeaud, S.; Alayrac, J.B.; Yu, J.; Soricut, R.; Schalkwyk, J.; Dai, A.M.; Hauth, A.; Millican, K.; et al. Gemini: A family of highly capable multimodal models. arXiv 2023, arXiv:2312.11805. [Google Scholar]
- Liu, A.; Feng, B.; Xue, B.; Wang, B.; Wu, B.; Lu, C.; Zhao, C.; Deng, C.; Zhang, C.; Ruan, C.; et al. Deepseek-v3 technical report. arXiv 2024, arXiv:2412.19437. [Google Scholar]
- Ollama Team. Ollama. 2024. Available online: https://ollama.com (accessed on 12 June 2026).
- Grattafiori, A.; Dubey, A.; Jauhri, A.; Pandey, A.; Kadian, A.; Al-Dahle, A.; Letman, A.; Mathur, A.; Schelten, A.; Vaughan, A.; et al. The llama 3 herd of models. arXiv 2024, arXiv:2407.21783. [Google Scholar]
- Jiang, A.Q.; Sablayrolles, A.; Mensch, A.; Bamford, C.; Chaplot, D.S.; Casas, D.d.; Bressand, F.; Lengyel, G.; Lample, G.; Saulnier, L.; et al. Mistral 7B. arXiv 2023, arXiv:2310.06825. [Google Scholar]
- Team, G.; Mesnard, T.; Hardin, C.; Dadashi, R.; Bhupatiraju, S.; Pathak, S.; Sifre, L.; Rivière, M.; Kale, M.S.; Love, J.; et al. Gemma: Open models based on gemini research and technology. arXiv 2024, arXiv:2403.08295. [Google Scholar]
- Abdin, M.; Aneja, J.; Behl, H.; Bubeck, S.; Eldan, R.; Gunasekar, S.; Harrison, M.; Hewett, R.J.; Javaheripi, M.; Kauffmann, P.; et al. Phi-4 technical report. arXiv 2024, arXiv:2412.08905. [Google Scholar]
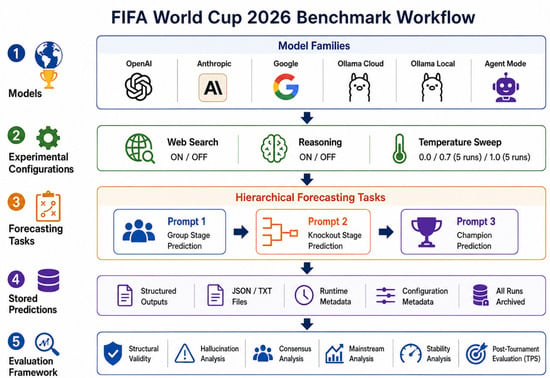
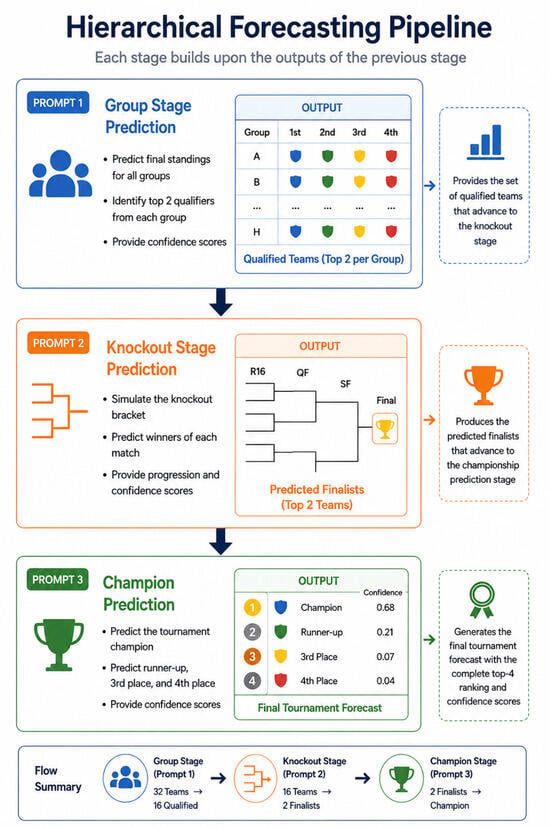
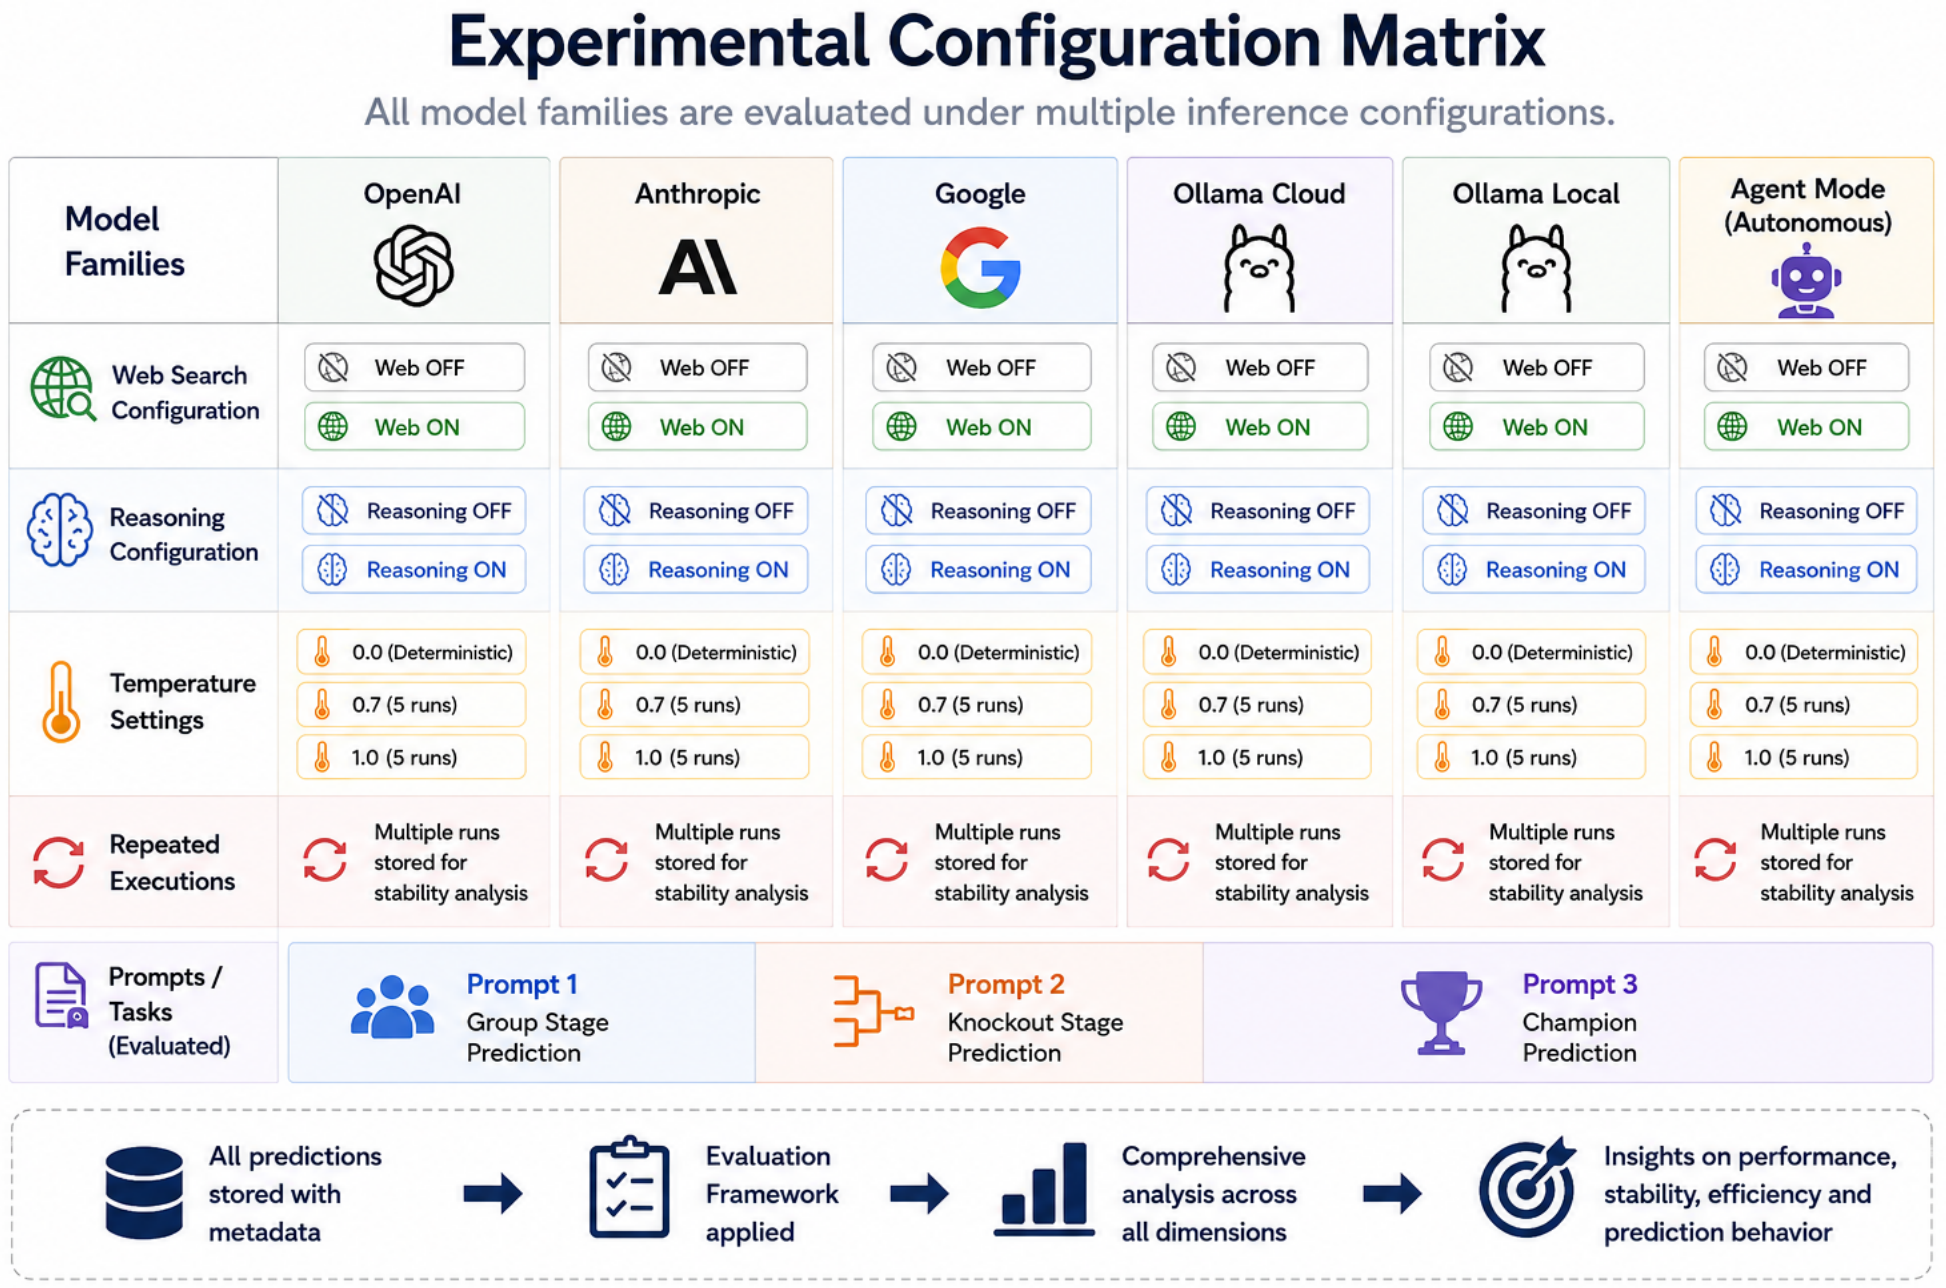
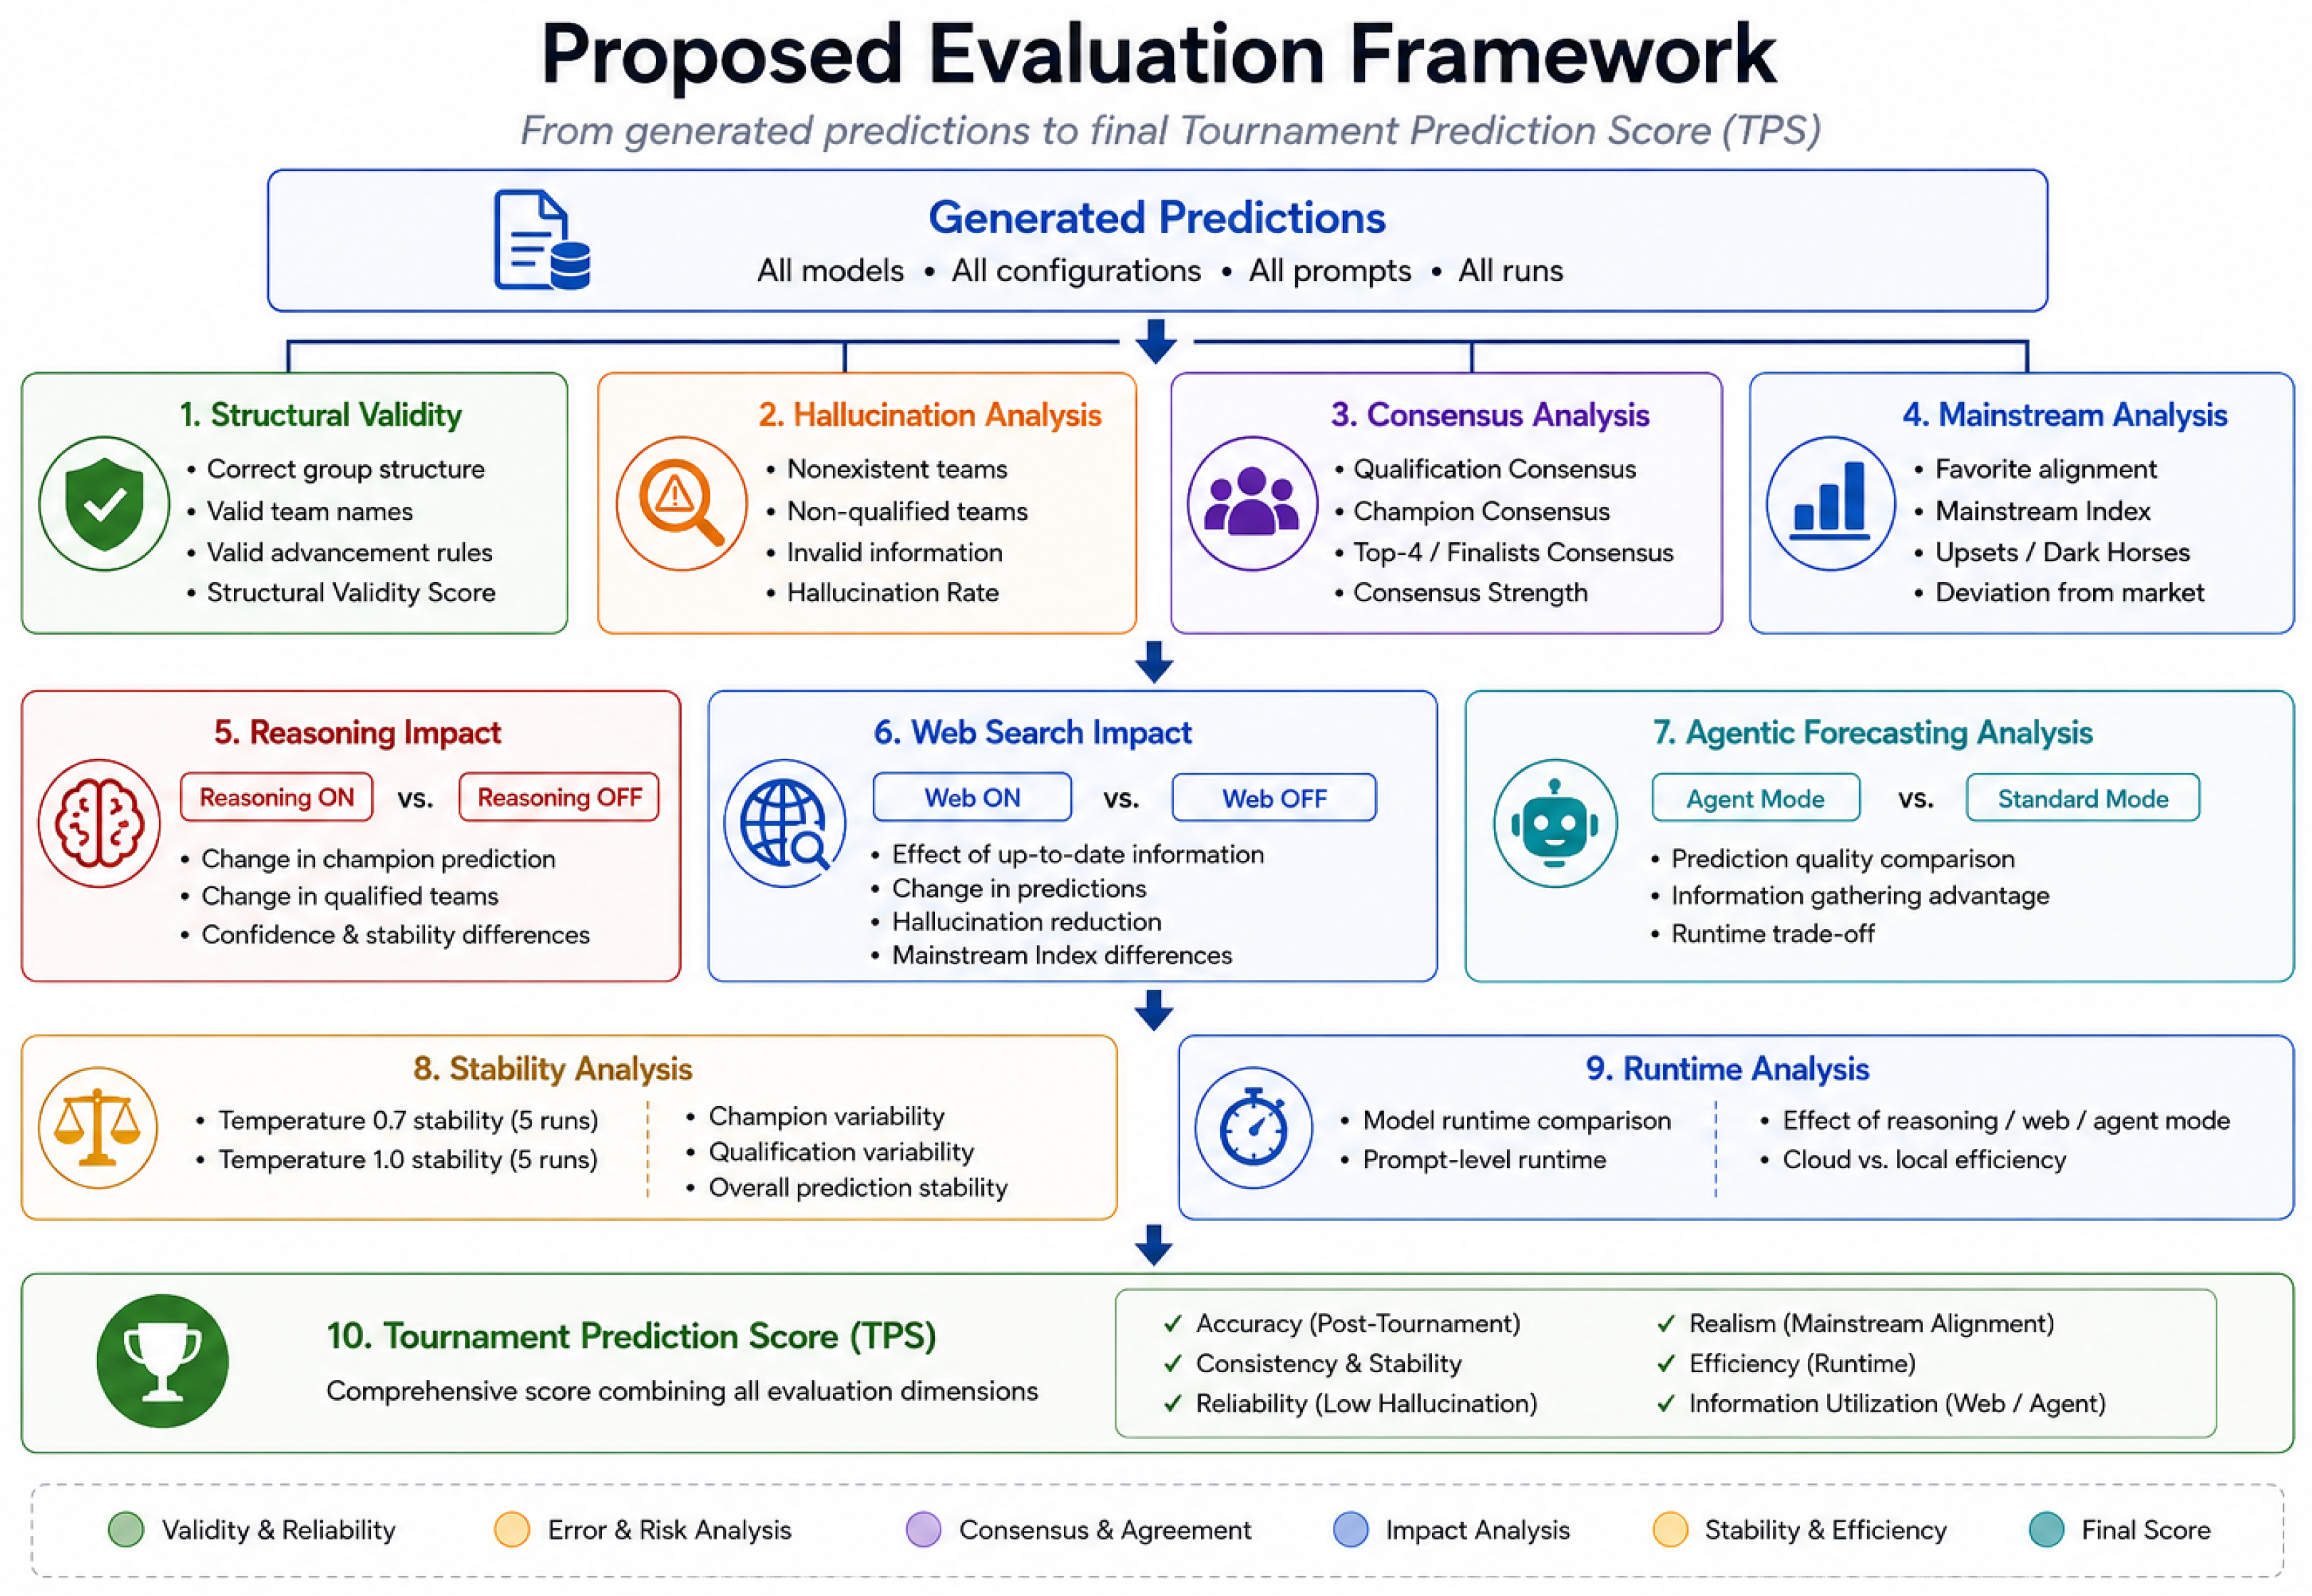

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.