


Abstract
Product reviews on the marketplace are interesting to research. Aspect-based sentiment analysis (ABSA) can be used to find in-depth information from a review. In one review, there can be several aspects with a polarity of sentiment. Previous research has developed ABSA, but it still has limitations in detecting aspects and sentiment classification and requires labeled data, but obtaining labeled data is very difficult. This research used a graph-based and semi-supervised approach to improve ABSA. GCN and GRN methods are used to detect aspect and opinion relationships. CNN and RNN methods are used to improve sentiment classification. A semi-supervised model was used to overcome the limitations of labeled data. The dataset used is an Indonesian-language review taken from the marketplace. A small part is labeled manually, and most are labeled automatically. The experiment results for the aspect classification by comparing the GCN and GRN methods obtained the best model using the GRN method with an F1 score = 0.97144. The experiment for sentiment classification by comparing the CNN and RNN methods obtained the best model using the CNN method with an F1 score = 0.94020. Our model can label most unlabeled data automatically and outperforms existing advanced models.
1. Introduction
The user reviews on the marketplace are written freely and independently. So that the review data can be used to determine the assessment of opinions and sentiments that appear on the products being sold, sentiment analysis can be used to find out an opinion that has been written in a review [1]. In sentiment analysis, there are several levels; namely, the sentence or document level is used to find out the overall opinion of a review [2,3], and the aspect level is used to find out several opinions contained in a review, and each opinion can have sentiment polarity [4,5,6]. Deep-learning models have been developed for sentiment analysis focusing on a document or sentence level [7,8] and aspect level [6,9,10]. In addition, aspect-based sentiment analysis (ABSA) can be used to obtain opinions and sentiment polarity in a review [11].
Previous research has developed ABSA using deep learning. For example, [12] using the attention mechanism is claimed to improve the LSTM model for Indonesian ABSA. The convolutional neural network (CNN) method can extract high-level semantic features. The feature extraction results are entered in a bidirectional long short-term memory (Bilstm) layer to obtain a contextual feature representation of a text. The results of experiments using public datasets are claimed to have increased for ABSA [13]. Researchers generally develop deep-learning models by utilizing labeled data, but obtaining labeled data is very difficult, so a particular approach is needed to solve it [14].
Several approaches have been used to develop deep-learning models, namely supervised learning [15,16,17], unsupervised learning [18,19,20,21], and semi-supervised learning [22,23,24]. The challenge in developing deep-learning models lies in labeled data [25]. Obtaining labeled data is challenging and requires experts [26,27]. The semi-supervised learning approach can overcome data-labeling problems by utilizing little labeled data and many unlabeled data [28].
Semi-supervised has been used to develop ABSA by utilizing deep-learning algorithms [29,30], while semi-supervised deep learning for Indonesian ABSA has not been widely developed. So, the development of ABSA Indonesia is open using semi-supervised deep learning. However, much research on Indonesian ABSA is still trying to improve accuracy in extracting aspects and polarity of sentiment [12,31,32,33]. A graph-based approach has been widely used to overcome problems in increasing accuracy in developing ABSA English models [9,34]. A graph-based approach is used with several deep-learning methods to build ABSA models in English, such as graph neural network [35,36], graph convolutional neural network [34,37], and graph attention network [38,39].
In this study, we develop graph-based semi-supervised deep learning to improve aspect-based sentiment analysis in Indonesian. Semi-supervised learning is used to overcome problems in data labeling, while a graph-based approach is used to enhance accuracy results in developing deep-learning models for Indonesian ABSA.
2. Literature Review
Several studies discuss different problems in Indonesian-language ABSA. For example, Nayoan et al. [40] utilized Indonesian tourism review data taken from the Tripadvisor travel website, and the ABSA model was developed using convolutional neural networks (CNN) to extract aspects and sentiments from tourism reviews. Several experiments were carried out to obtain the best model by comparing the CNN, CNN-LSTM, and CNN-GRU models. The result was that CNN combined with the POS tag outperformed other models.
Tedjojuwono et al. [41] developed a dynamic dashboard to display restaurant information in Indonesia, using data obtained from online restaurant reviews on the Tripadvisor platform. The approach used is semi-supervised ABSA. Although machine-learning tools are used to extract aspects and sentiments, the accuracy analysis results are less than ideal due to the lack of negative sentiment datasets that affect the model during training.
Cendani et al. [12] introduce Indonesian ABSA using a long short-term memory (LSTM) model with an attention mechanism. Indonesian-language hotel review data are used to develop the model. The data obtained consist of five aspects and three sentiments. Several experiments with different parameters resulted in the best model performance with an F1 value of 0.7628. The attention mechanism is stated to improve the LSTM model for ABSA.
ABSA has been used to determine the character traits of legislative candidates in the Indonesian presidential election and has been studied [42] by utilizing Twitter data during the Indonesian presidential election campaign period in 2018 and 2019. The Indonesian-language tweet text data are annotated with labels as candidate targets and aspects as character traits and sentiments. Furthermore, a comparison of machine-learning algorithms is used to classify datasets automatically. The comparison results show that the support vector machine algorithm performs better than naïve Bayes and k-nearest neighbor.
Yanuar et al. [43] utilize reviews to develop a decision support system in the tourism sector. The data used come from the TripAdvisor platform. ABSA is used to overcome problems in analyzing the complexity of Indonesian tourist attractions’ reviews. Aspect extraction is an essential component in developing ABSA. Bidirectional encoder representations from transformers (BERT) is used to extract aspects by training the model using Indonesian-language review sentences. BERT successfully extracted aspects with an accuracy value of 0.799 and an F1 value of 0.738.
CNN and B-LSTM were used to improve ABSA in reviews of Indonesian-language restaurants [32] by adapting research in which F1 reached the highest value in SemEval 2016. The experiment results obtained aspect classification with an F1 value of 0.870, opinion extraction with an F1 value of 0.787, and sentiment polarity classification with an F1 value of 0.764.
ABSA has been used [31] for aspect detection and sentiment classification. The Indonesian review from the online marketplace Tokopedia was used as a two-stage experiment. The first stage performs aspect detection by comparing two deep neural network models using a gated recurrence unit (GRU) and Fully Connected. The second stage performs sentiment classification by comparing the deep neural network approach using sentiment lexicon and CNN. The developed model is claimed to be better than previous research using SVM and rule-based methods.
The English ABSA has been developed to analyze restaurant, laptop, and Twitter reviews [34]. The graph convolutional network (GCN) and recurrent neural network (RNN) methods were used to develop ABSA by comparing five datasets. The results stated that the developed model could outperform the existing model, and the gate mechanism was said to be able to improve performance with an F1 score of 66.64~76.80%.
Chakraborty [44] used the graph neural network (GNN) method for ABSA in English. Graph Fourier transform-based network with the spectral domain is proposed to develop ABSA. The dataset used is laptops, restaurants, men’s t-shirts, and television reviews. Based on the test results, it is stated that the developed model is able to obtain the best results on the laptop and restaurant domain dataset. In addition, the proposed model can be competitive on other datasets from the e-commerce domain, with the highest F1 score of 78.77.
The relational graph attention network (R-GAT) was used to develop ABSA in English [39]. First, the dependency tree is used to detect aspects that are connected with the word opinion in the review, and then R-GAT is used to predict the sentiment of each aspect obtained. The experimental results using the SemEval 2014 and Twitter datasets show that the relationship between aspects and opinions is well detected. In addition, the R-GAT is stated to be able to improve the model performance with an F1 score of 81.35.
The dual graph convolutional networks (DualGCN) model was developed in ABSA to simultaneously obtain the syntactic structure and semantic relationships [45]. The SynGCN module is used to reduce dependency parsing errors while obtaining semantic relationships using the SemGCN module. After testing using a dataset from SemEval 2014 (domain: restaurant and laptop) and Twitter, the results were obtained with the highest F1 score of 78.08. Therefore, the DualGCN model is declared to outperform existing methods.
The Sentic GCN model was developed for ABSA [46] by utilizing the public domain laptop and restaurant dataset from SemEval 2014, SemEval 2015, and SemEval 2016. Graph convolutional networks are integrated with dependency trees and affective knowledge to improve sentence dependency graphs so that words containing contextual, opinion, and aspects can be detected. The experimental results stated that the developed model could outperform the existing method, with the highest F1 score of 75.91.
Table 1 summarizes related research in aspect-based sentiment analysis in Indonesian and English.
Table 1.
The summary of related research.
Contribution
After conducting a literature review, several limitations were identified. Research in recent years related to Indonesian ABSA has widely applied deep-learning algorithms [12,31,32,40,43] and used machine-learning algorithms [42]. In general, previous research in the Indonesian-language domain has not tried to use a graph approach to develop the Indonesian-language ABSA. While the development of ABSA in English has generally used a deep-learning graph approach, the datasets used are generally public datasets which, of course, are labeled data. Based on the literature review, there are still opportunities to improve the model in the Indonesian-language ABSA task.
Contributions in this study can be summarized as follows:
- Graph dependency parse is used to extract aspect and opinion relationship words.
- The extraction results are used to assist the multi-label labeling process. In addition, semi-supervised learning is used to overcome problems in data labeling by utilizing little labeled data and many unlabeled data.
- GCN and GRN are used for aspect and opinion extraction. CNN and RNN are used for sentiment classification.
- The experimental results show an improvement in our proposed model in the Indonesian-language ABSA task.
3. Materials and Methods
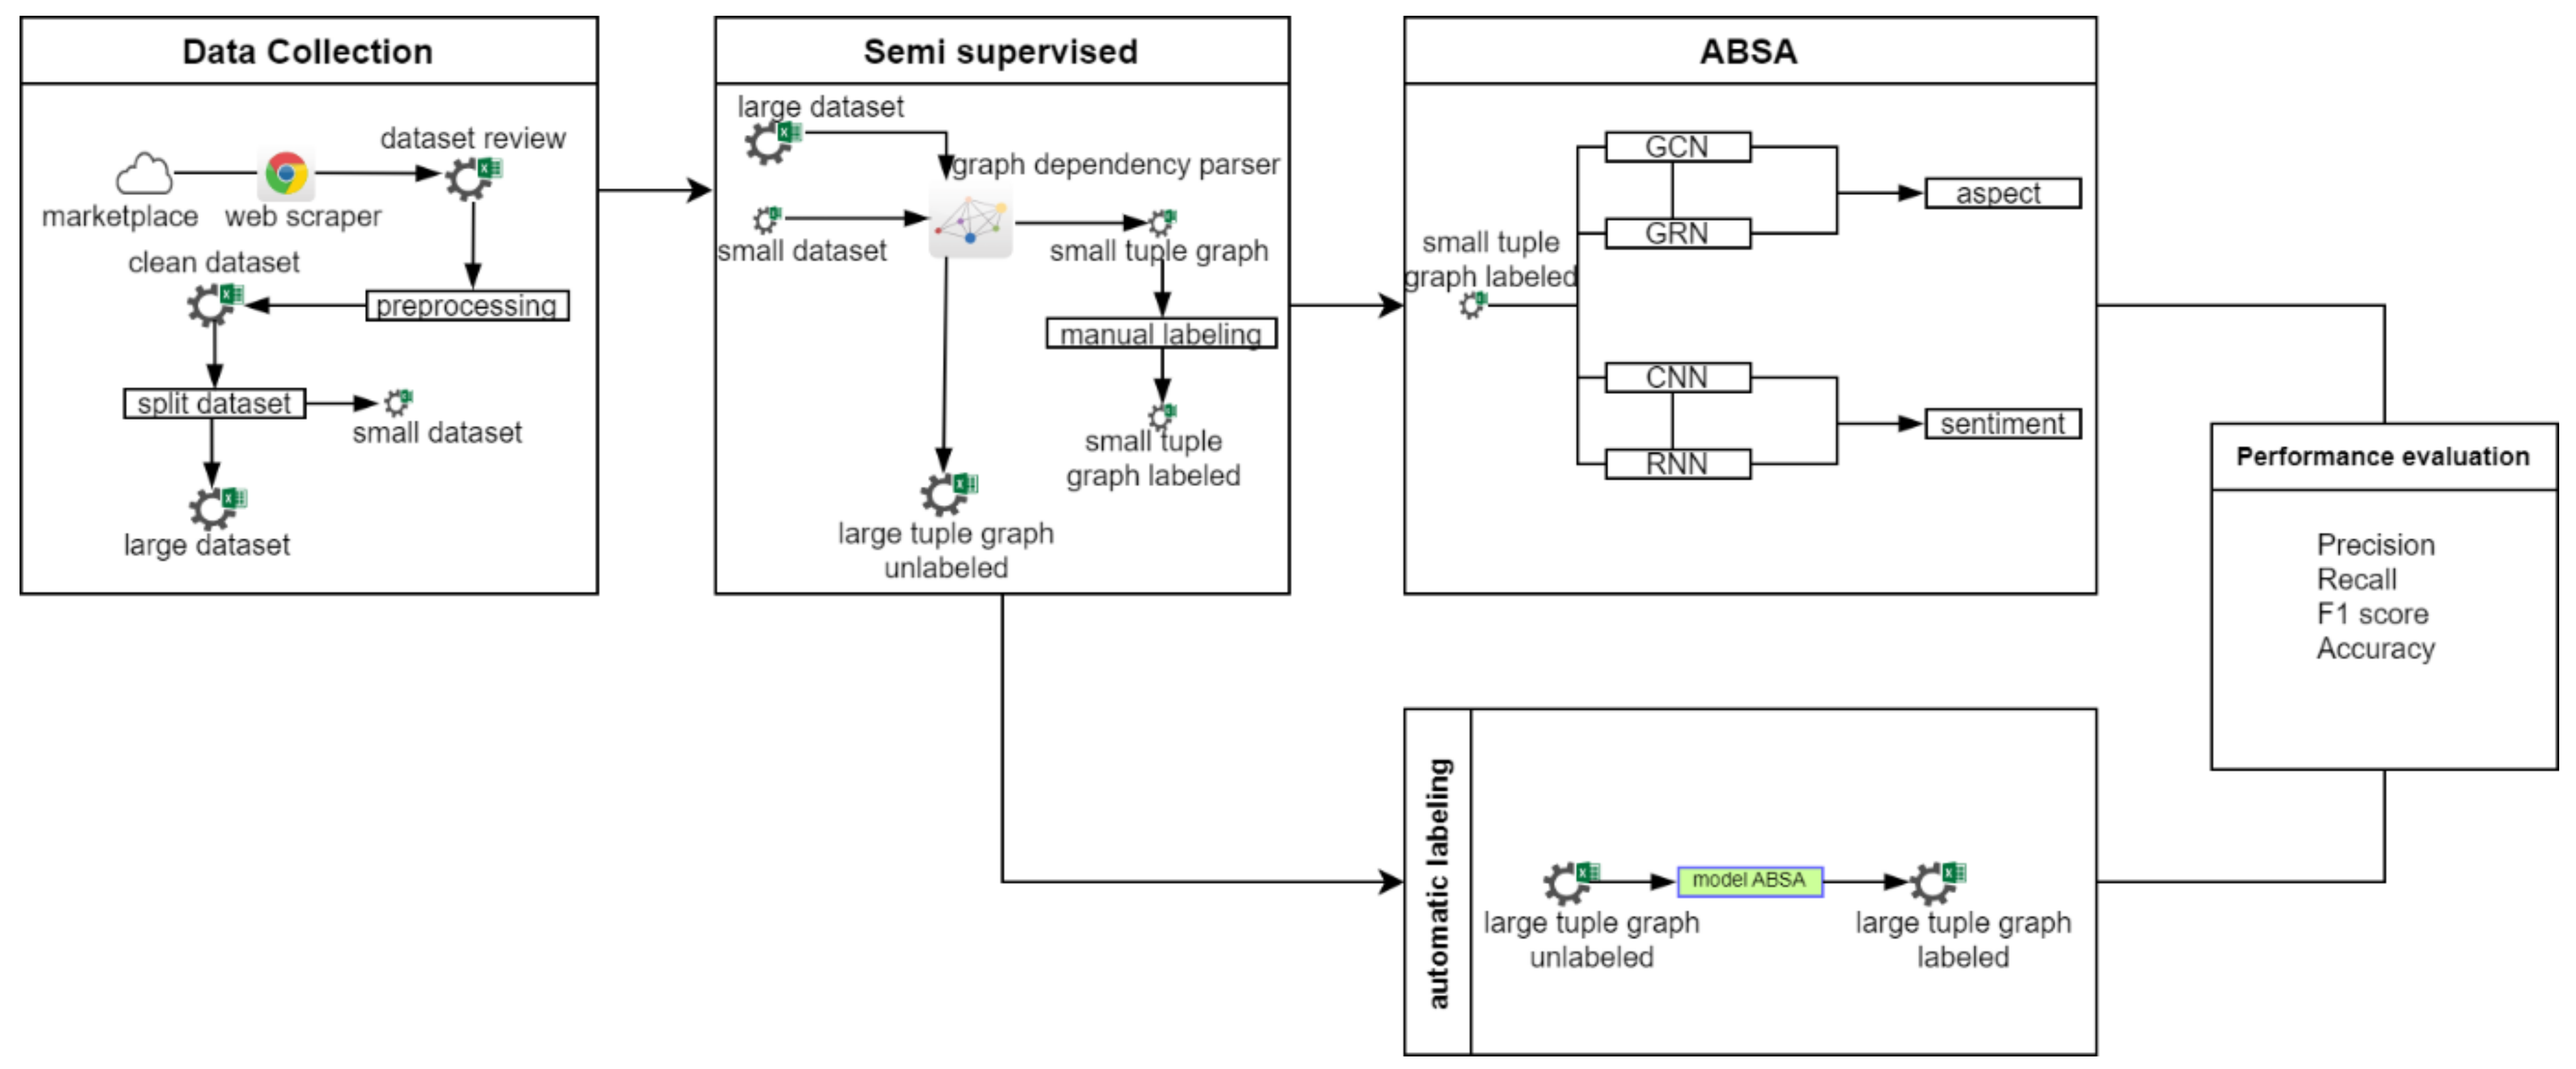
This research was conducted in several stages: data collection, semi-supervised, build model, automatic labeling, and performance evaluation. The whole process in this study is shown in Figure 1.
Figure 1.
Research methods.
3.1. Data Collection
In this study, we use review data for men’s t-shirts from the Indonesian marketplace. The data are obtained by scraping using Chrome Web Scraper tools. The scraping results obtained 15,237 data from product reviews on the Indonesian marketplace. The review data obtained were preprocessed by tokenization, stop-word removal, and stemming. After preprocessing, the data are split with details of 3894 data being labeled manually and 11,343 data being labeled automatically.
3.2. Semi-Supervised and Graph-Based
The semi-supervised principle uses little labeled data and many unlabeled data. Graph dependency parse is used to extract aspect and opinion words from 3894 data after being extracted to 4307 data. A data-labeling process follows the result. The results of data labeling, for example, are shown in Table 2.
Table 2.
An example of dependency parse result and labeled data.
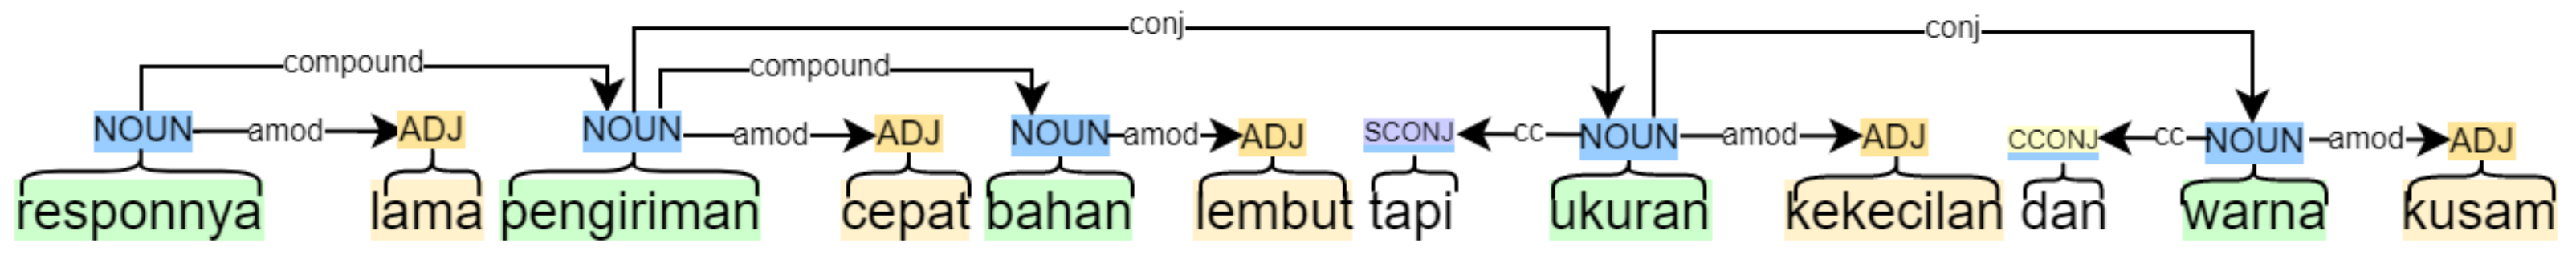
Figure 2 shows an example of using dependency parse using the stanza library (http://stanza.run/ (accessed on 17 October 2022) in the review sentence: “responnya lama pengiriman cepat bahan lembut tapi ukuran kekecilan dan warna kusam”, which in English is “the response is long, fast delivery, soft material but the size is too small and the color is dull”.
Figure 2.
An example of using dependency parse.
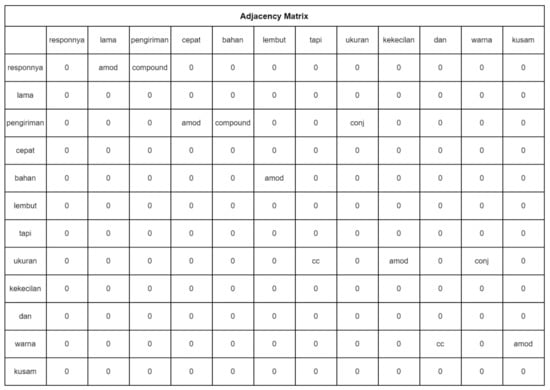
The result of using dependency parse is made in an adjacency matrix, as shown in Figure 3.
Figure 3.
An example adjacency matrix of the dependency parse.
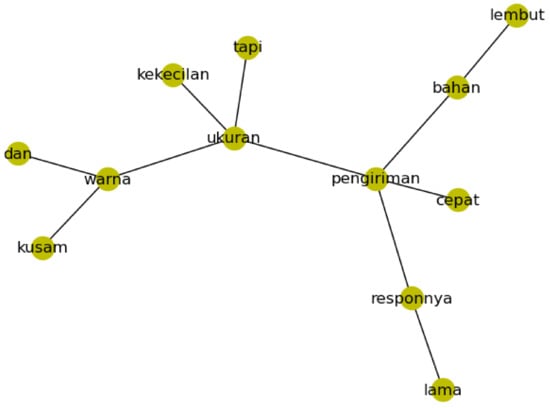
The results of the adjacency matrix are visualized in graph form using the library network (https://networkx.org/documentation/stable/ (accessed on 17 October 2022), as shown in Figure 4. The extraction results from the review sentences can be seen to have relationships between words and contain aspects and opinions. They are making it more accessible in the data-labeling process.
Figure 4.
An example of graph networks.
The research started using a simple graph [47] , including a set of nodes , one set of edges , and an adjacency matrix containing the weight of edges . The value of is shown in Equation (1).
is the weight of the edge, and for unweighted graphs. A node has a set of neighbors that is defined as . Graph has a node feature matrix , where each row represents the feature vector of the node .
The aspect and opinion columns result from extracting review sentences using a dependency parse. True tuple, sentiment, and class aspects are performed manually. A true tuple consists of 1 = there are aspects, 0 = there is no aspect. Sentiment consists of 1 = positive, 0 = no sentiment, and −1 = negative. The class aspect consists of material (bahan), size (ukuran), color (warna), sewing (jahitan), quality (kualitas), price (harga), delivery (pengiriman), and service (pelayanan).
The statistical dataset used to build the model is shown in Table 3.
Table 3.
The statistics of labeled data.
3.3. Build Model
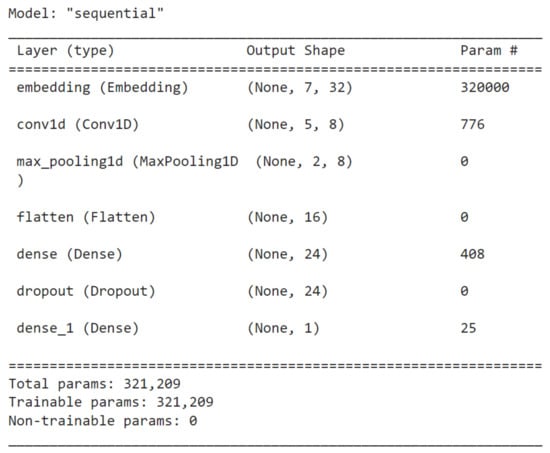
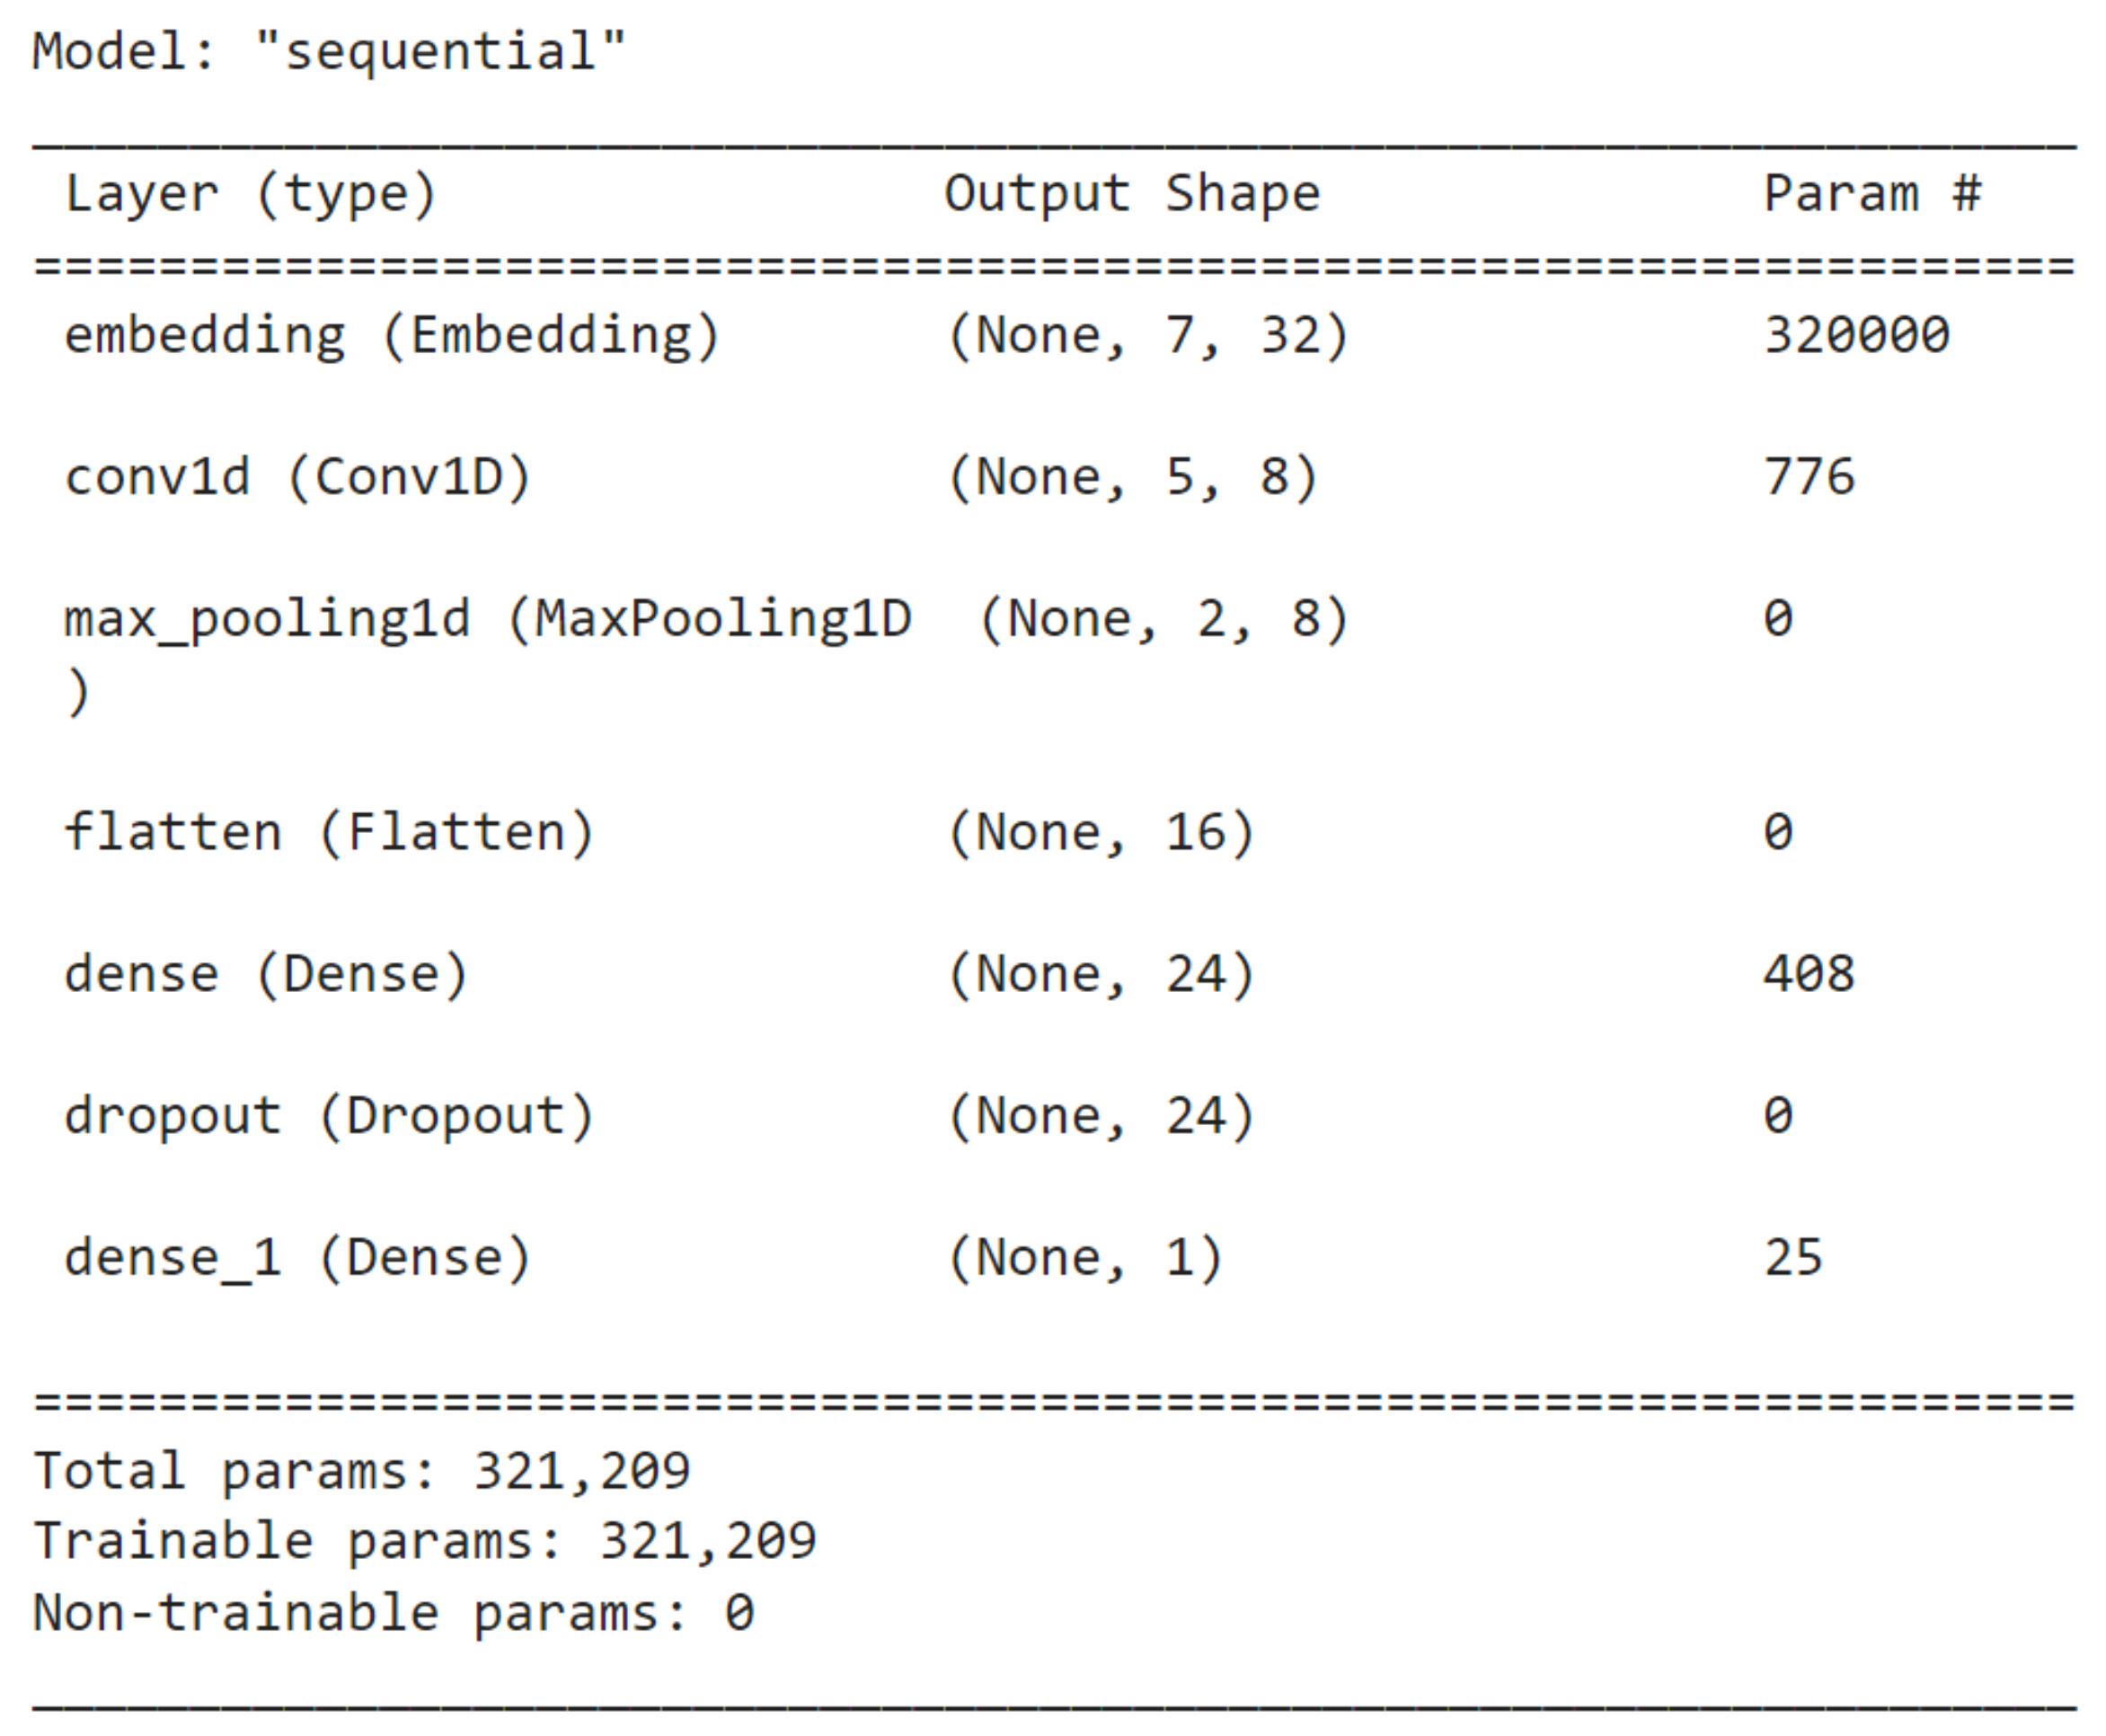
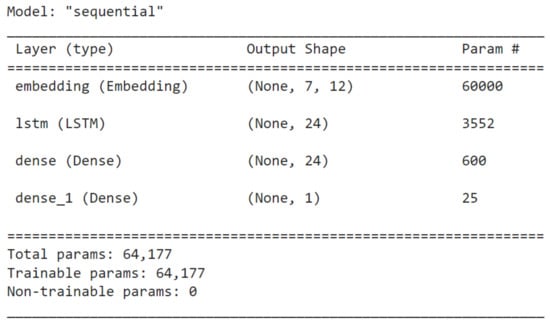
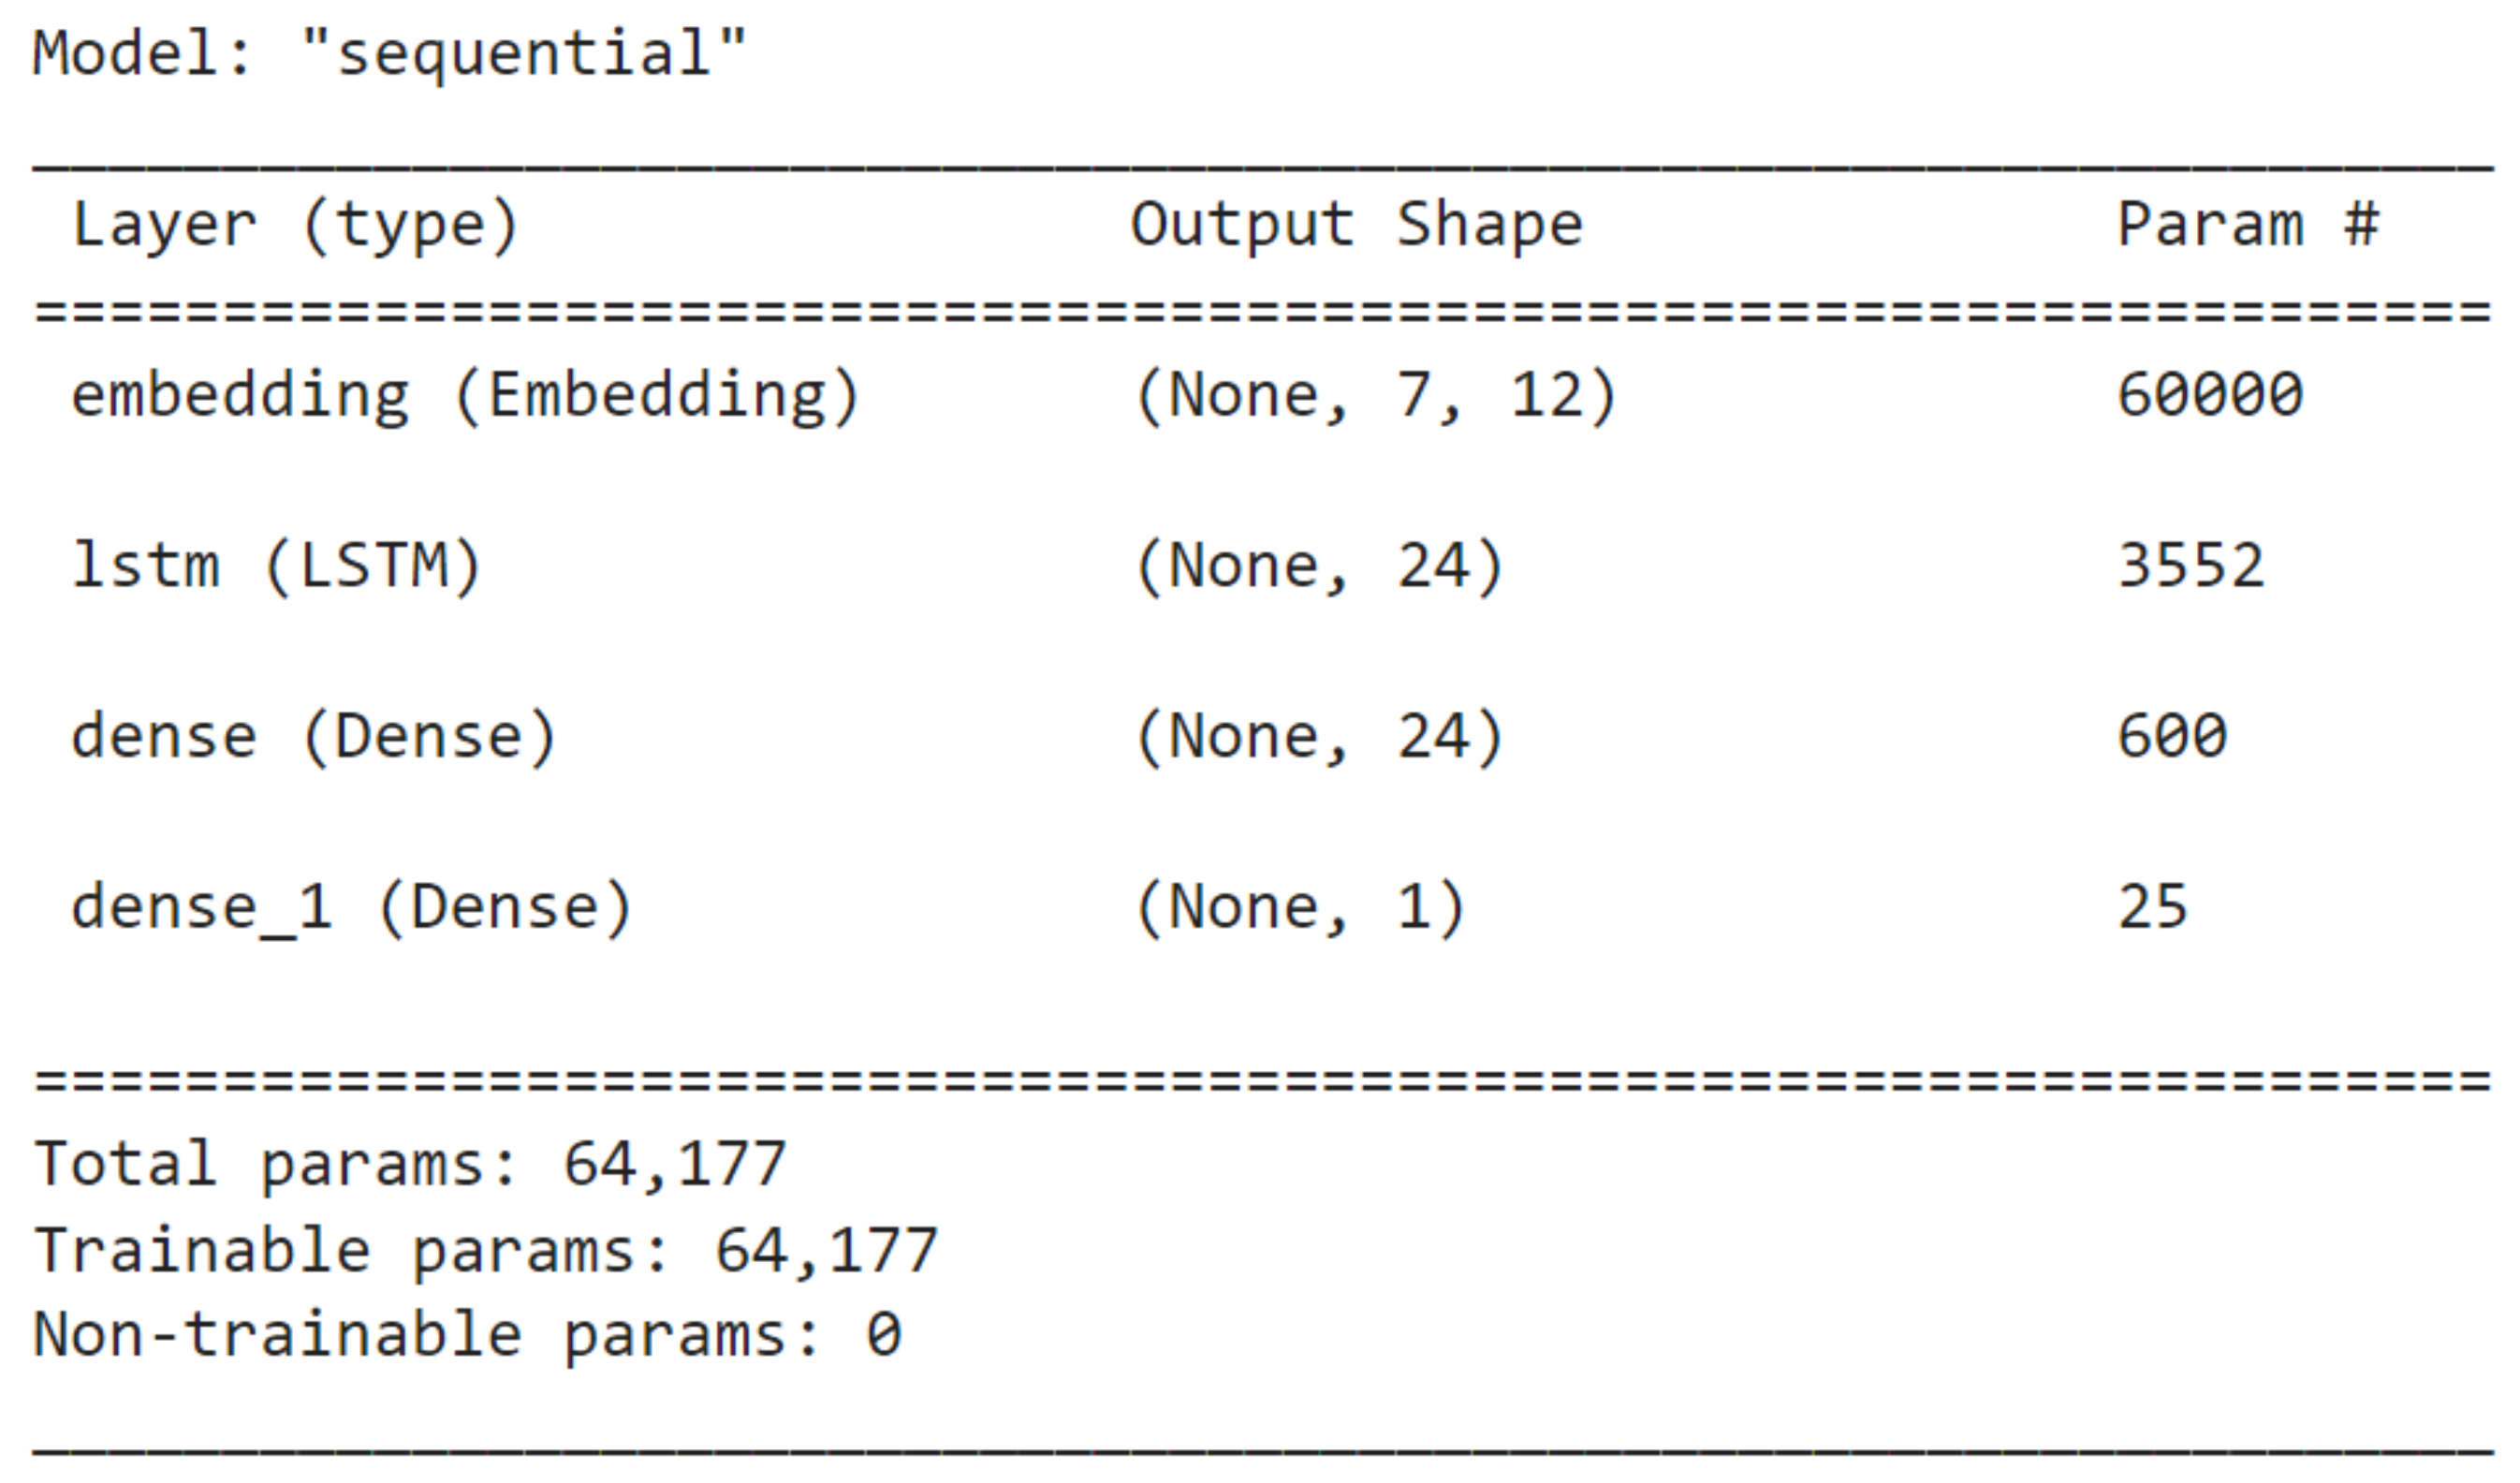
In this study, several scenarios will be used. Scenario 1 builds an ABSA model using graph convolutional network (GCN) and graph recurrent network (GRN) to detect aspects. GCN and GRN architecture for aspect detection as shown in Figure 5 and Figure 6.
Figure 5.
GCN architecture for aspect.
Figure 6.
GRN architecture for aspect.
The GCN architecture to detect aspects is built using a sequential model, consisting of input layers with 10,000, 32, convolution layers with filters = 8 activation = relu, max-pooling layers using pool_size = 2, flatten layers, hidden layers with 24 activation = sigmoid, dropout layers = 0.5, and output layer = 1 activation = sigmoid.
The GRN architecture for detecting aspects is built using a sequential model, consisting of input layer = 5000, 12, LSTM layer = 24, hidden layer = 24 activation = relu, and output layer = 1 activation = sigmoid.
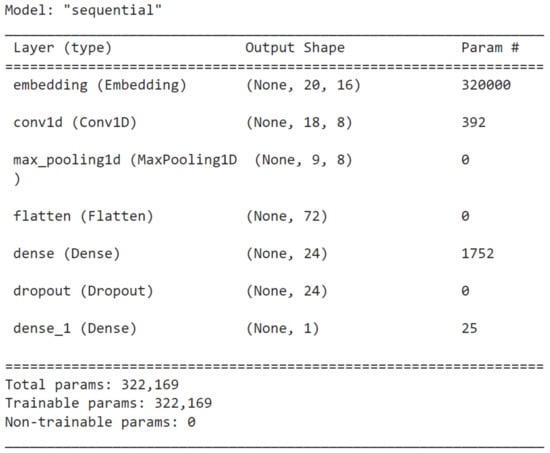
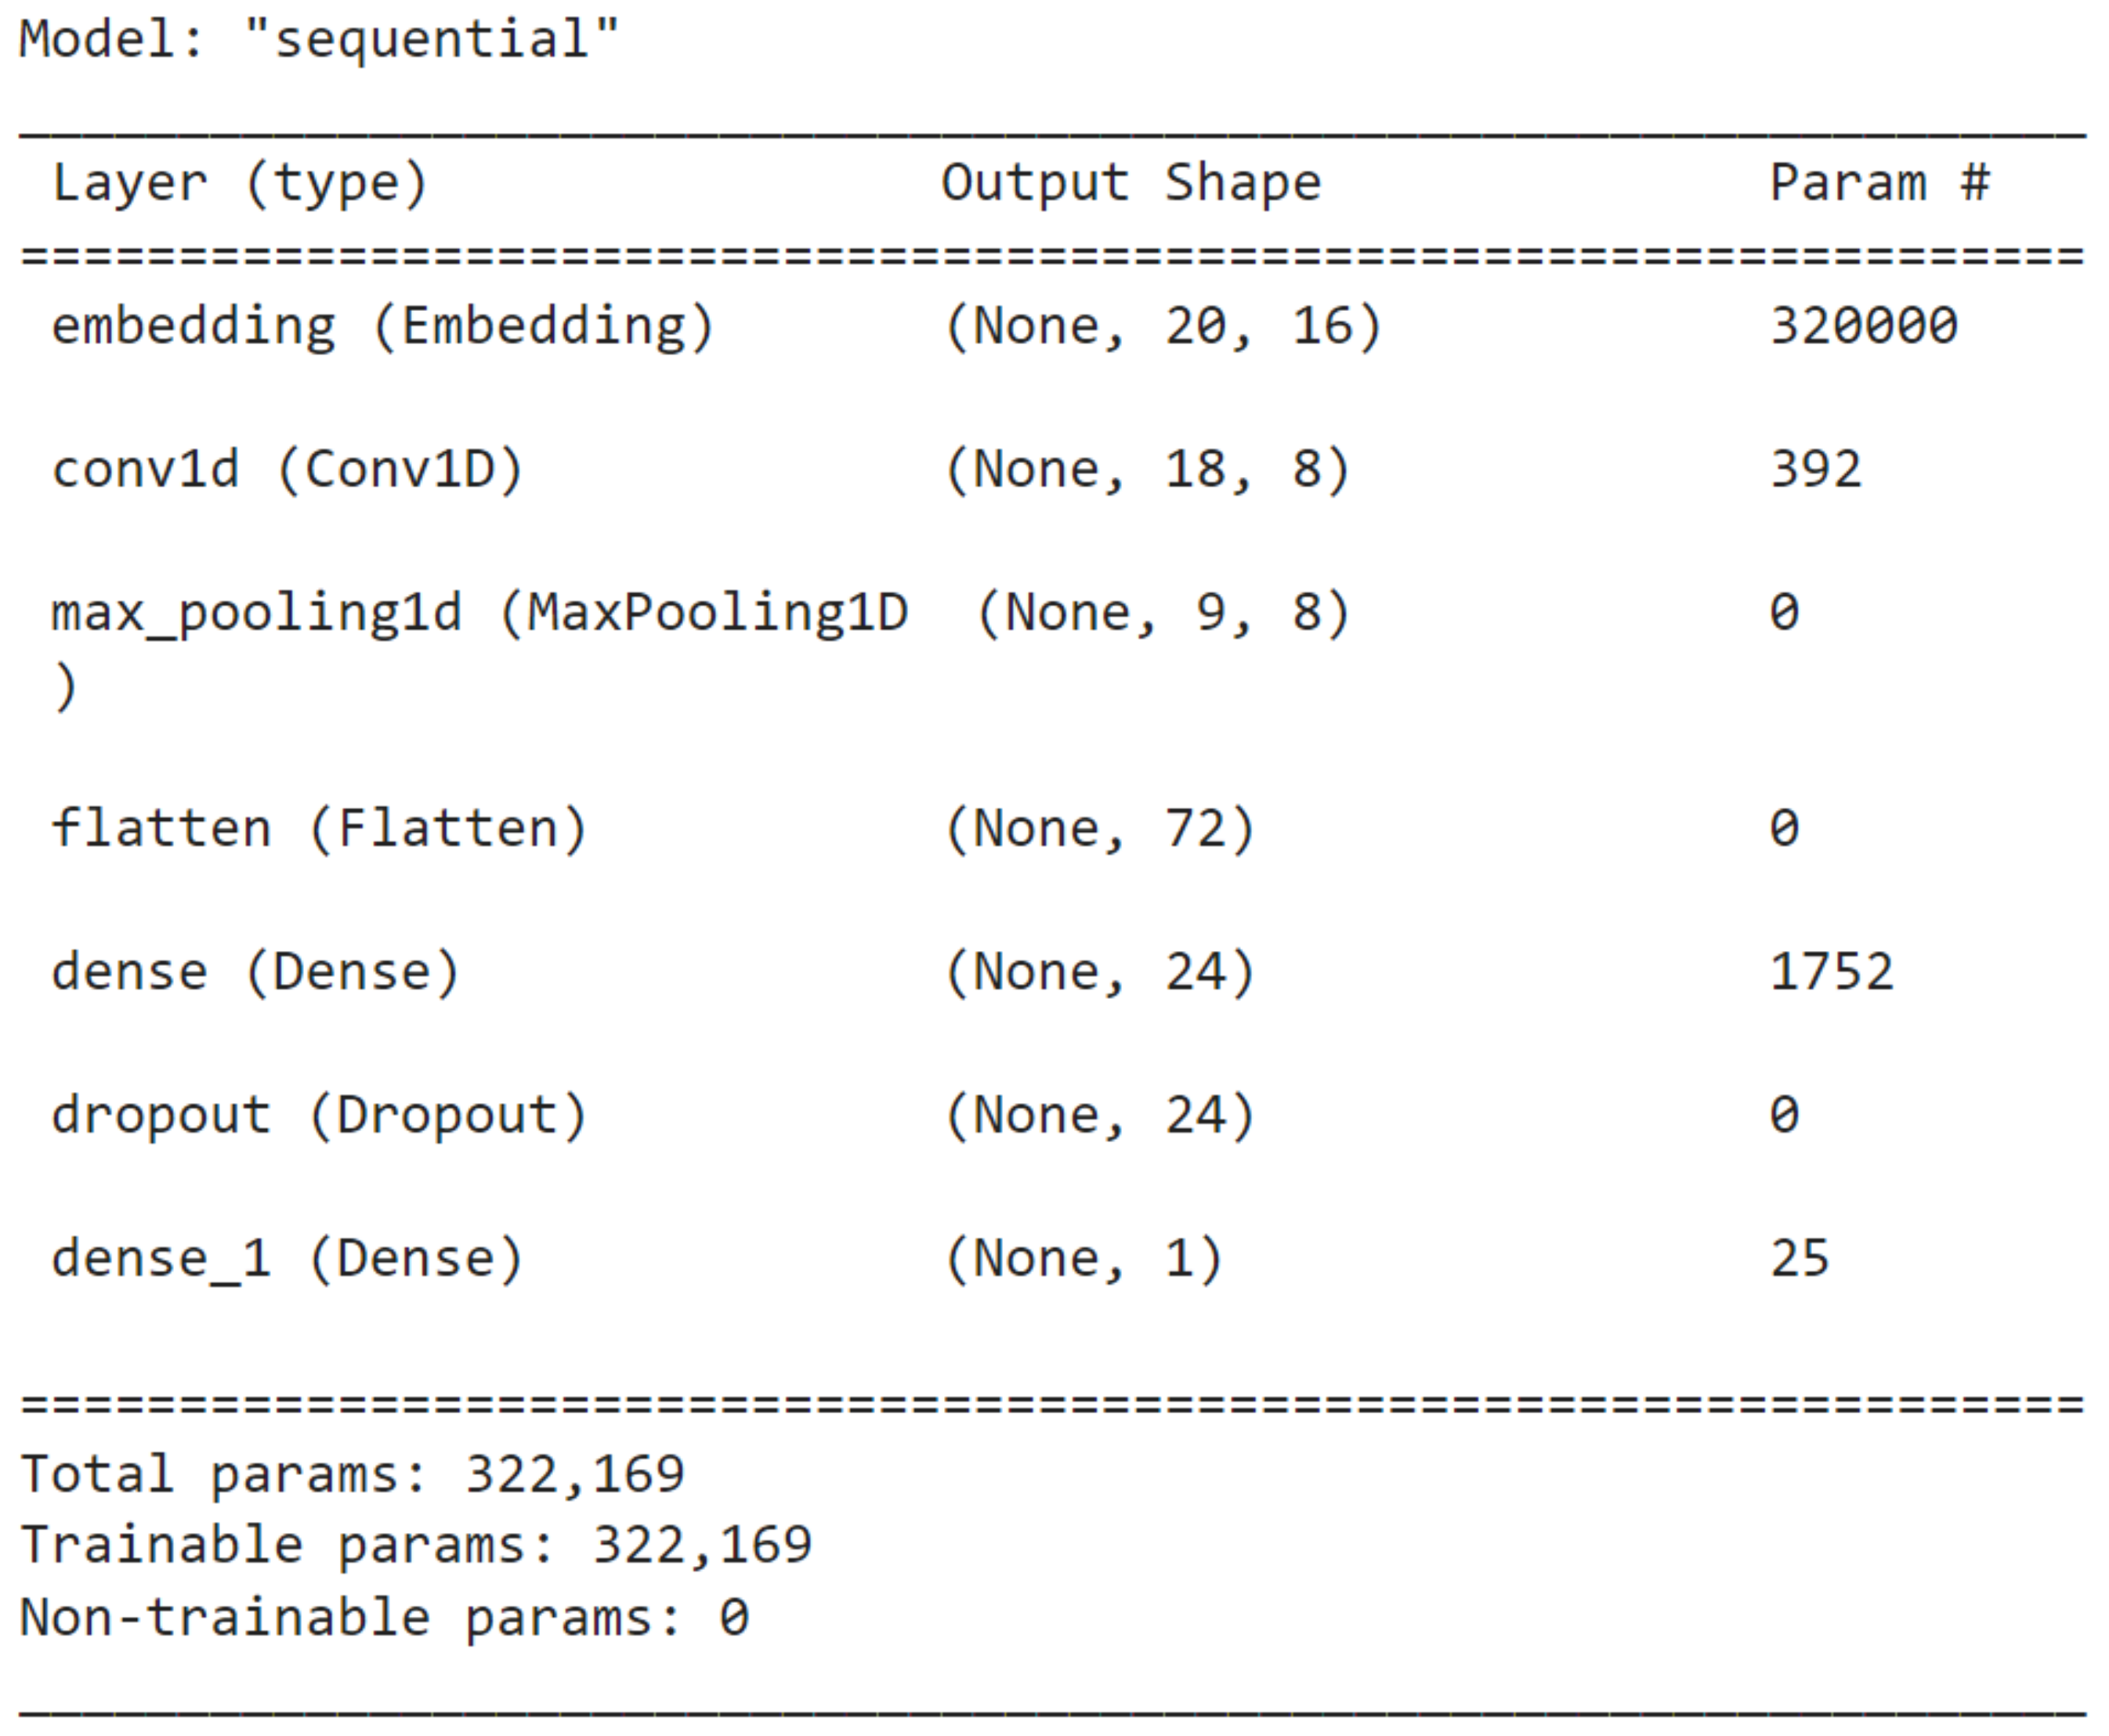
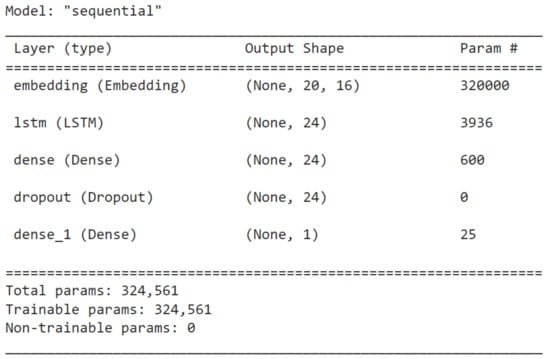
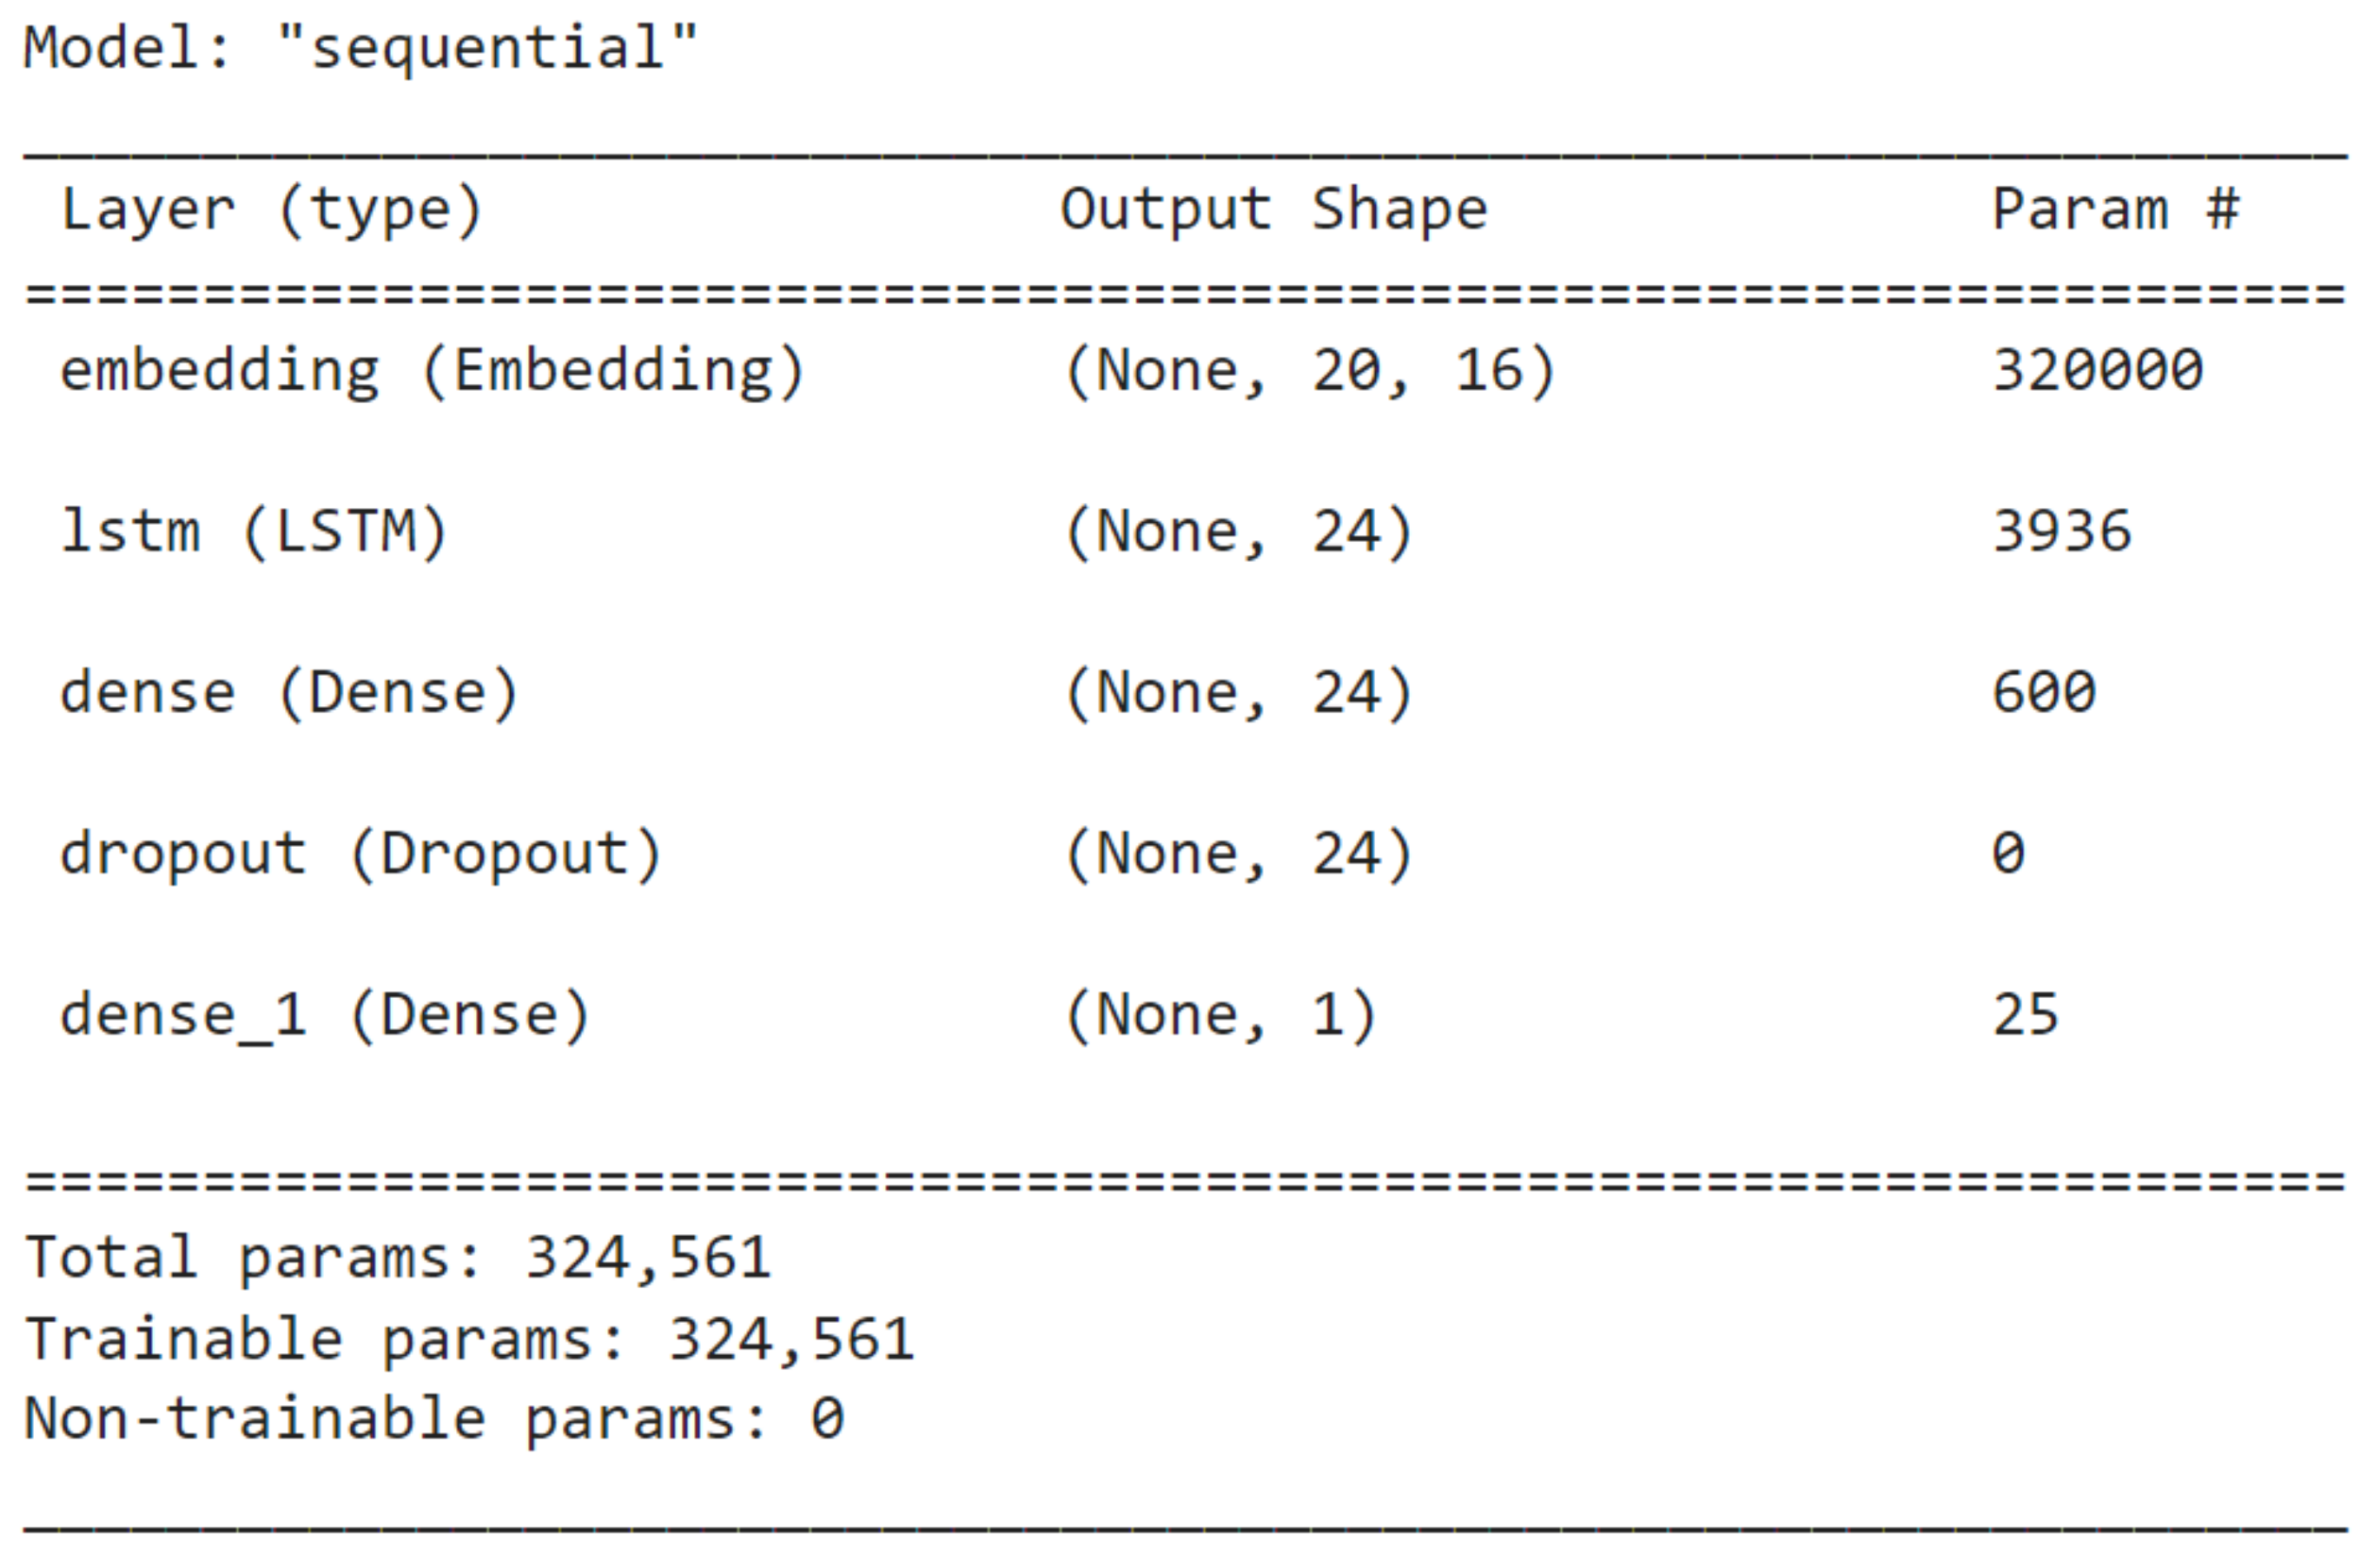
Scenario 2 builds the ABSA model using CNN and RNN for sentiment classification. CNN and RNN architecture are used for sentiment classification as shown in Figure 7 and Figure 8.
Figure 7.
CNN architecture for sentiment.
Figure 8.
RNN architecture for sentiment.
CNN architecture for sentiment classification is built using a sequential model, consisting of an input layer with 20,000, 16, convolution layer with activation = relu, max pooling layer using pool_size = 2, flatten layer, hidden layer = 24 with activation = sigmoid, dropout layer = 0.5, and output layer = 1 with activation = sigmoid.
The RNN architecture for sentiment classification is built using a sequential model, consisting of input layer = 20,000, 16, LSTM layer = 24, hidden layer = 24 with activation = sigmoid, dropout layer = 0.5, and output layer = 1 with activation = sigmoid.
3.4. Automatic Labeling
Before automatic labeling, 11.343 data were extracted using the stanza library to 11,270 data. The GCN and GRN models that have been built are used for aspect labeling, and the CNN and RNN models are used for sentiment labeling automatically for 11,270 data.
3.5. Performance Evaluation
To evaluate the performance of the model, a confusion matrix was used [47] as in (2)–(5).
TP is a true positive, TN is a true negative, FN is a false negative, and FP is a false positive.
4. Results and Discussion
The GCN and GRN model training process for aspect classification uses parameters, as shown in Table 4. Parameters are used to obtain the right combination of parameters to obtain the best model. The model training process for aspect classification using GCN and GRN is visualized as shown in Figure 9 and Figure 10. If the best model is obtained, the training process will stop. For example, the GRN model training process uses an epoch val =100, but at epoch 59, the training process has stopped because the model with the best accuracy has been obtained. In the training process, the GCN model uses an epoch value =100. After epoch 9, the training process stopped because the best model had been obtained with the highest accuracy.
Table 4.
The parameters of the training model GCN and GRN.
Figure 9.
The data training process using GCN.
Figure 10.
The data training process using GRN.
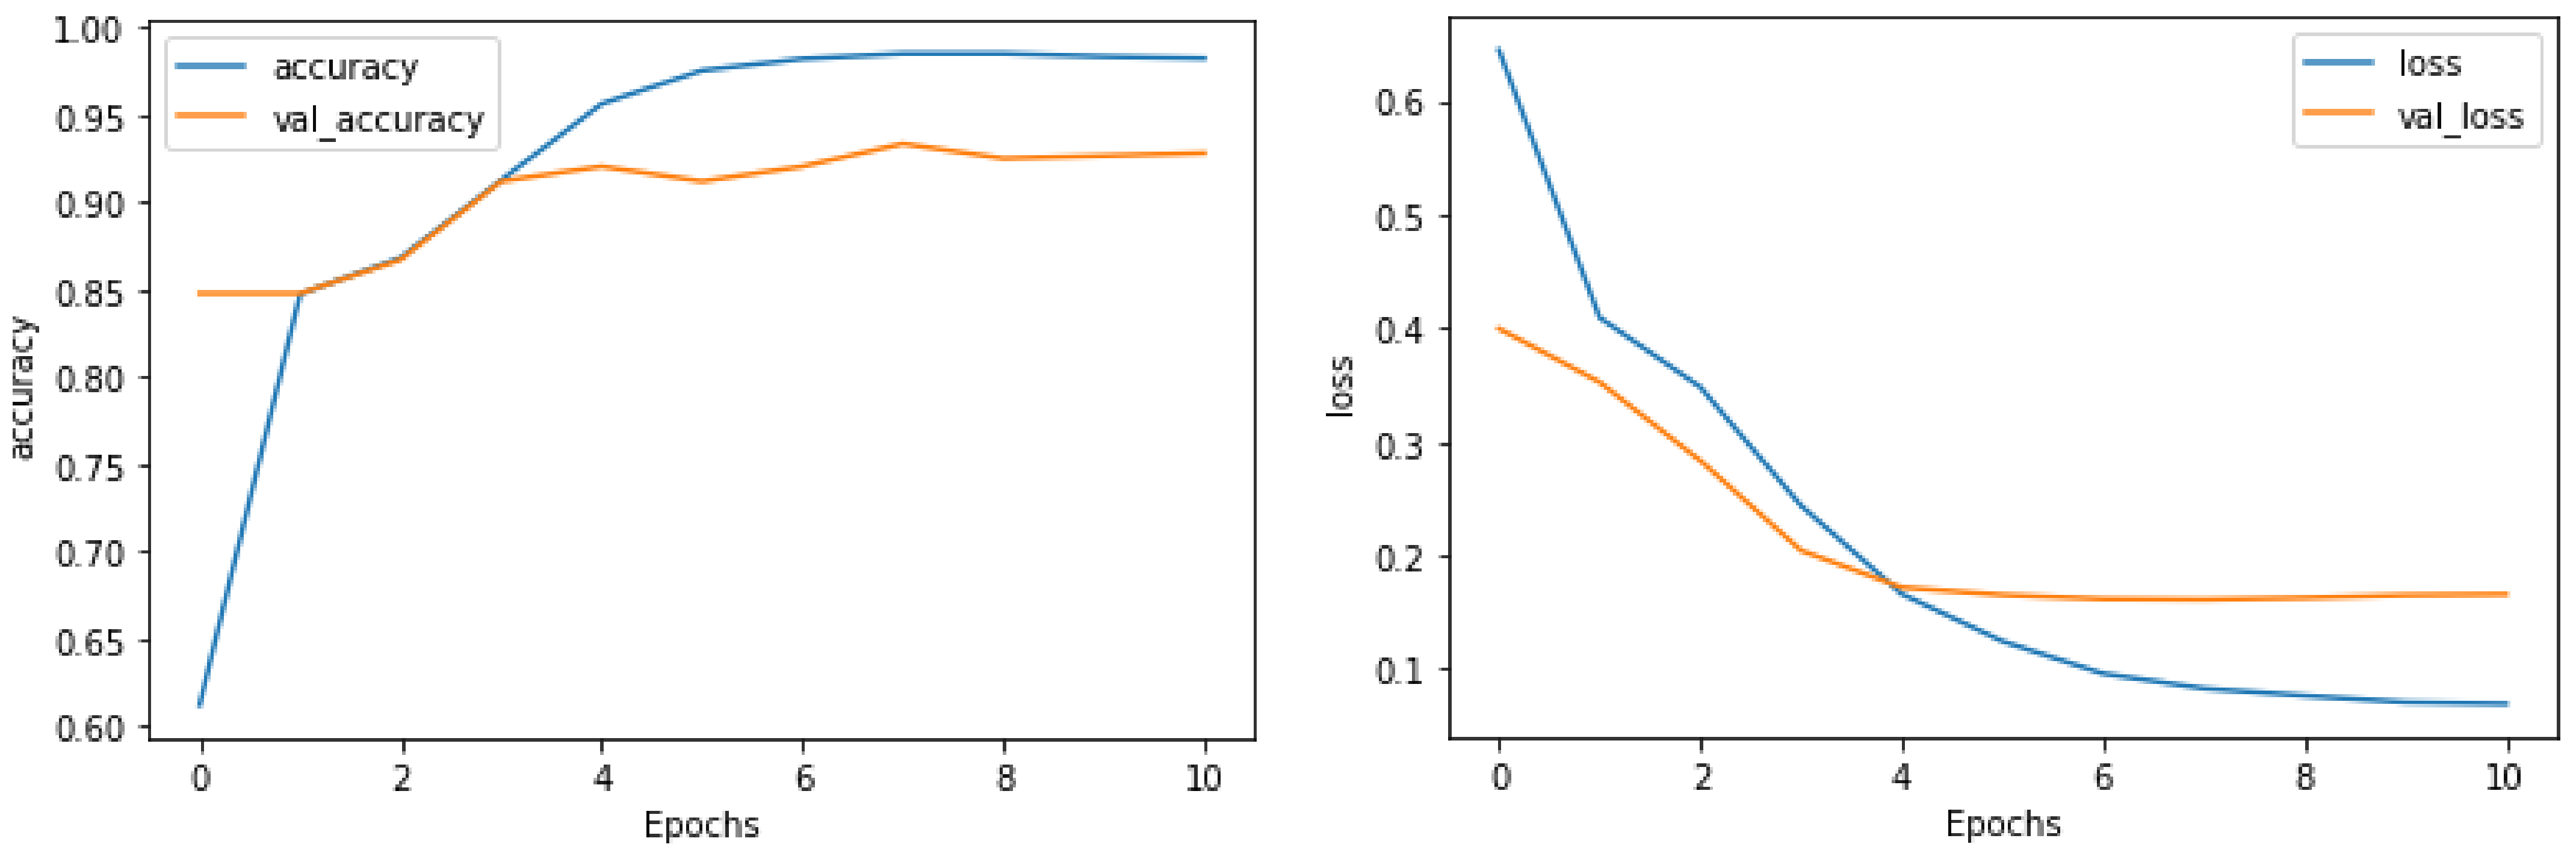
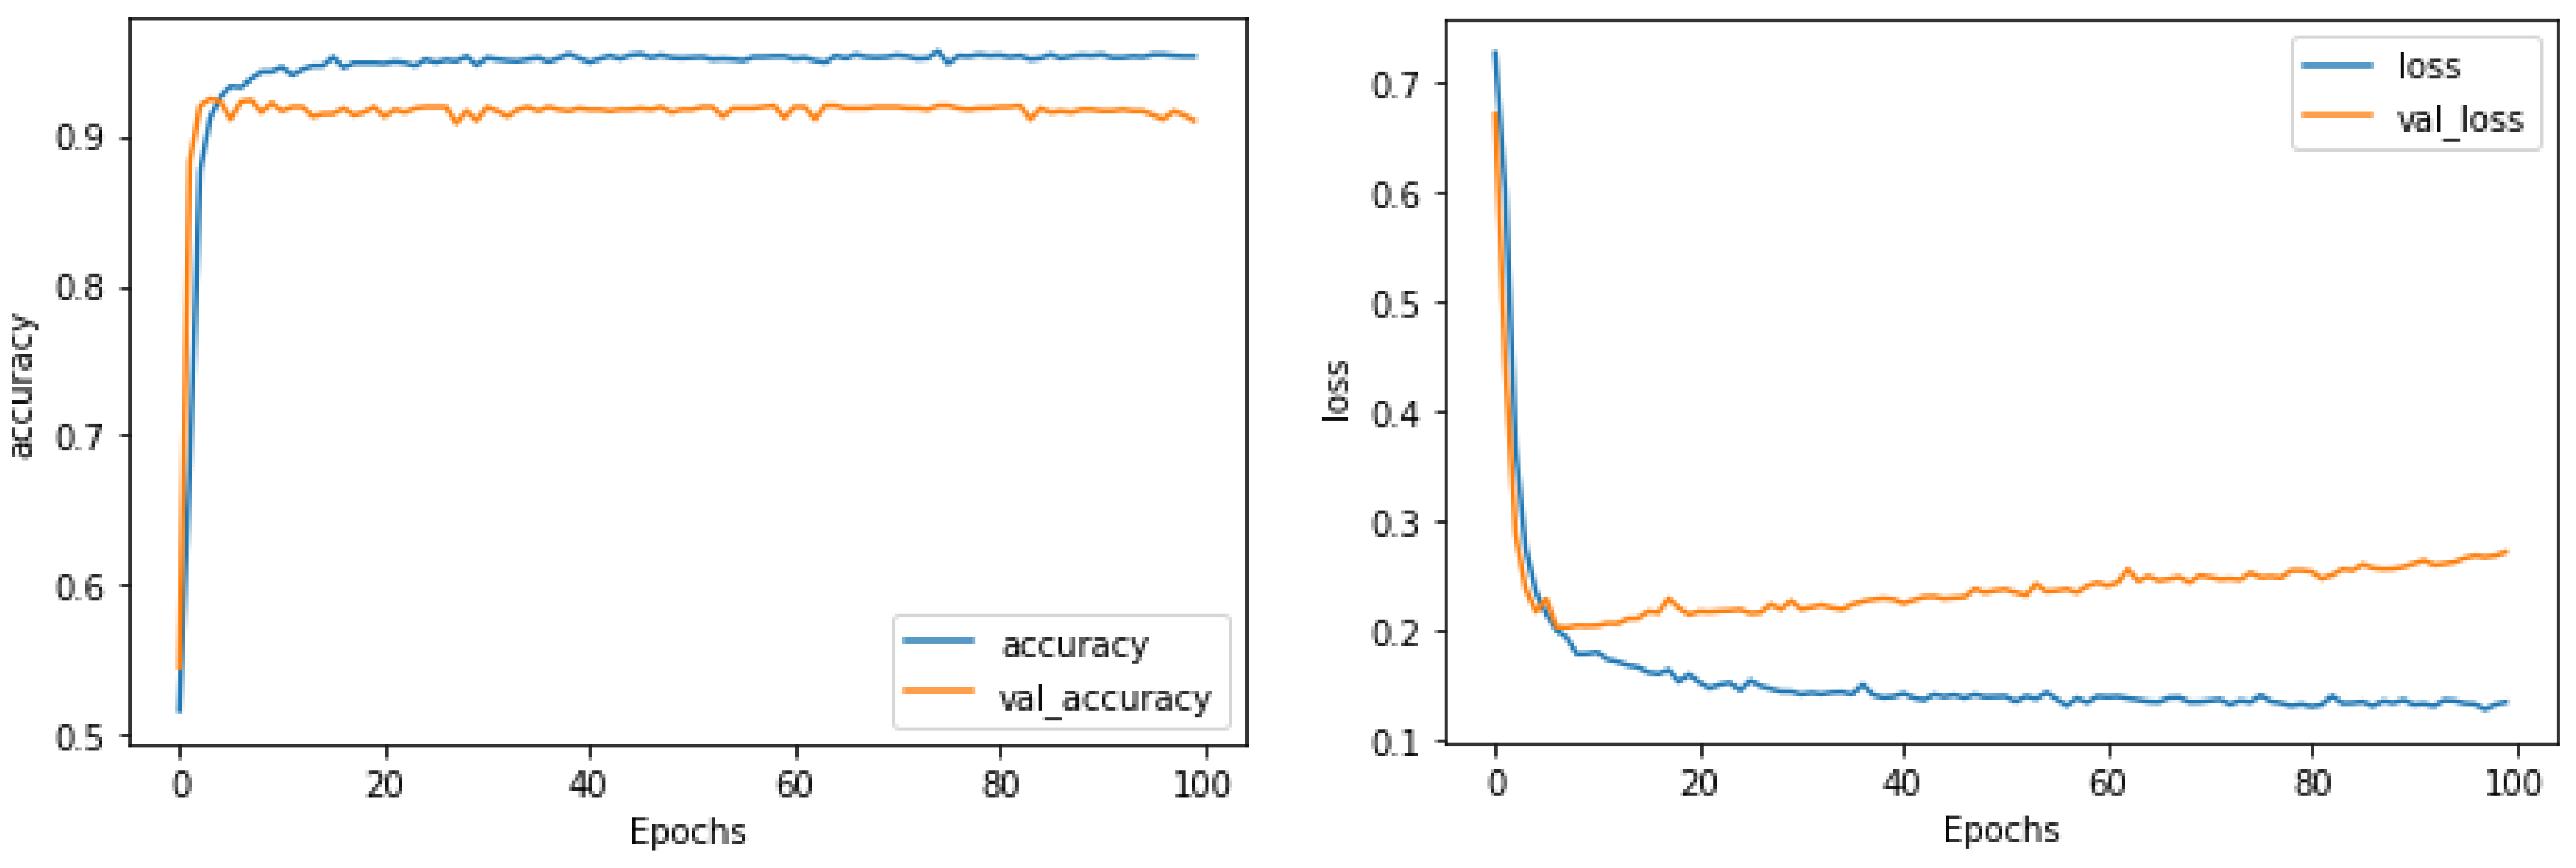
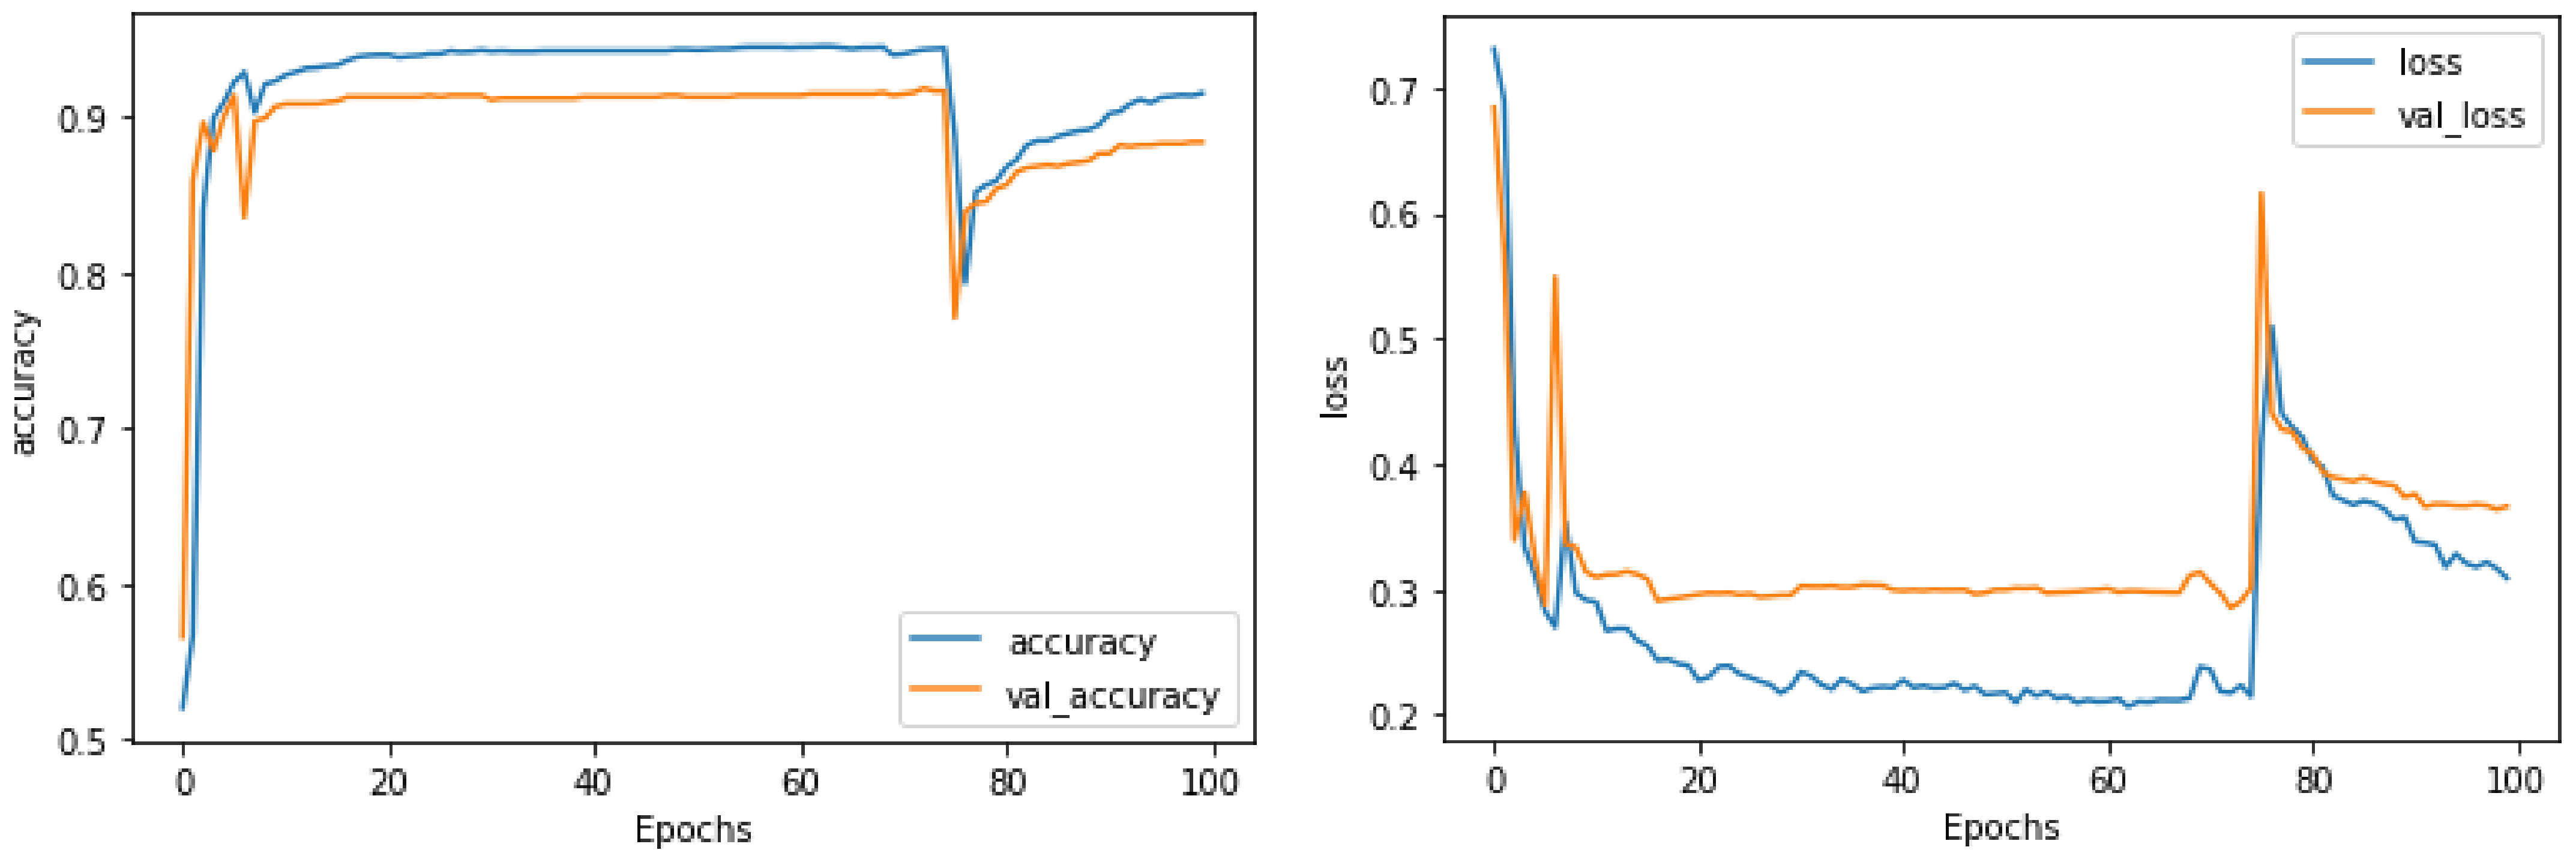
The CNN and RNN model training process for sentiment classification is shown in Figure 11 and Figure 12. The parameters used in the sentiment classification model training process are shown in Table 5. Based on the visualization of the training model process, the highest accuracy value and the slightest loss value can be seen. The CNN and RNN model training process uses an epoch value = 100. In the process, the training continues until it reaches 100 epochs, and the best model is obtained with the highest accuracy.
Figure 11.
The data training process using CNN.
Figure 12.
The data training process using RNN.
Table 5.
The parameters of the training model CCN and RRN.
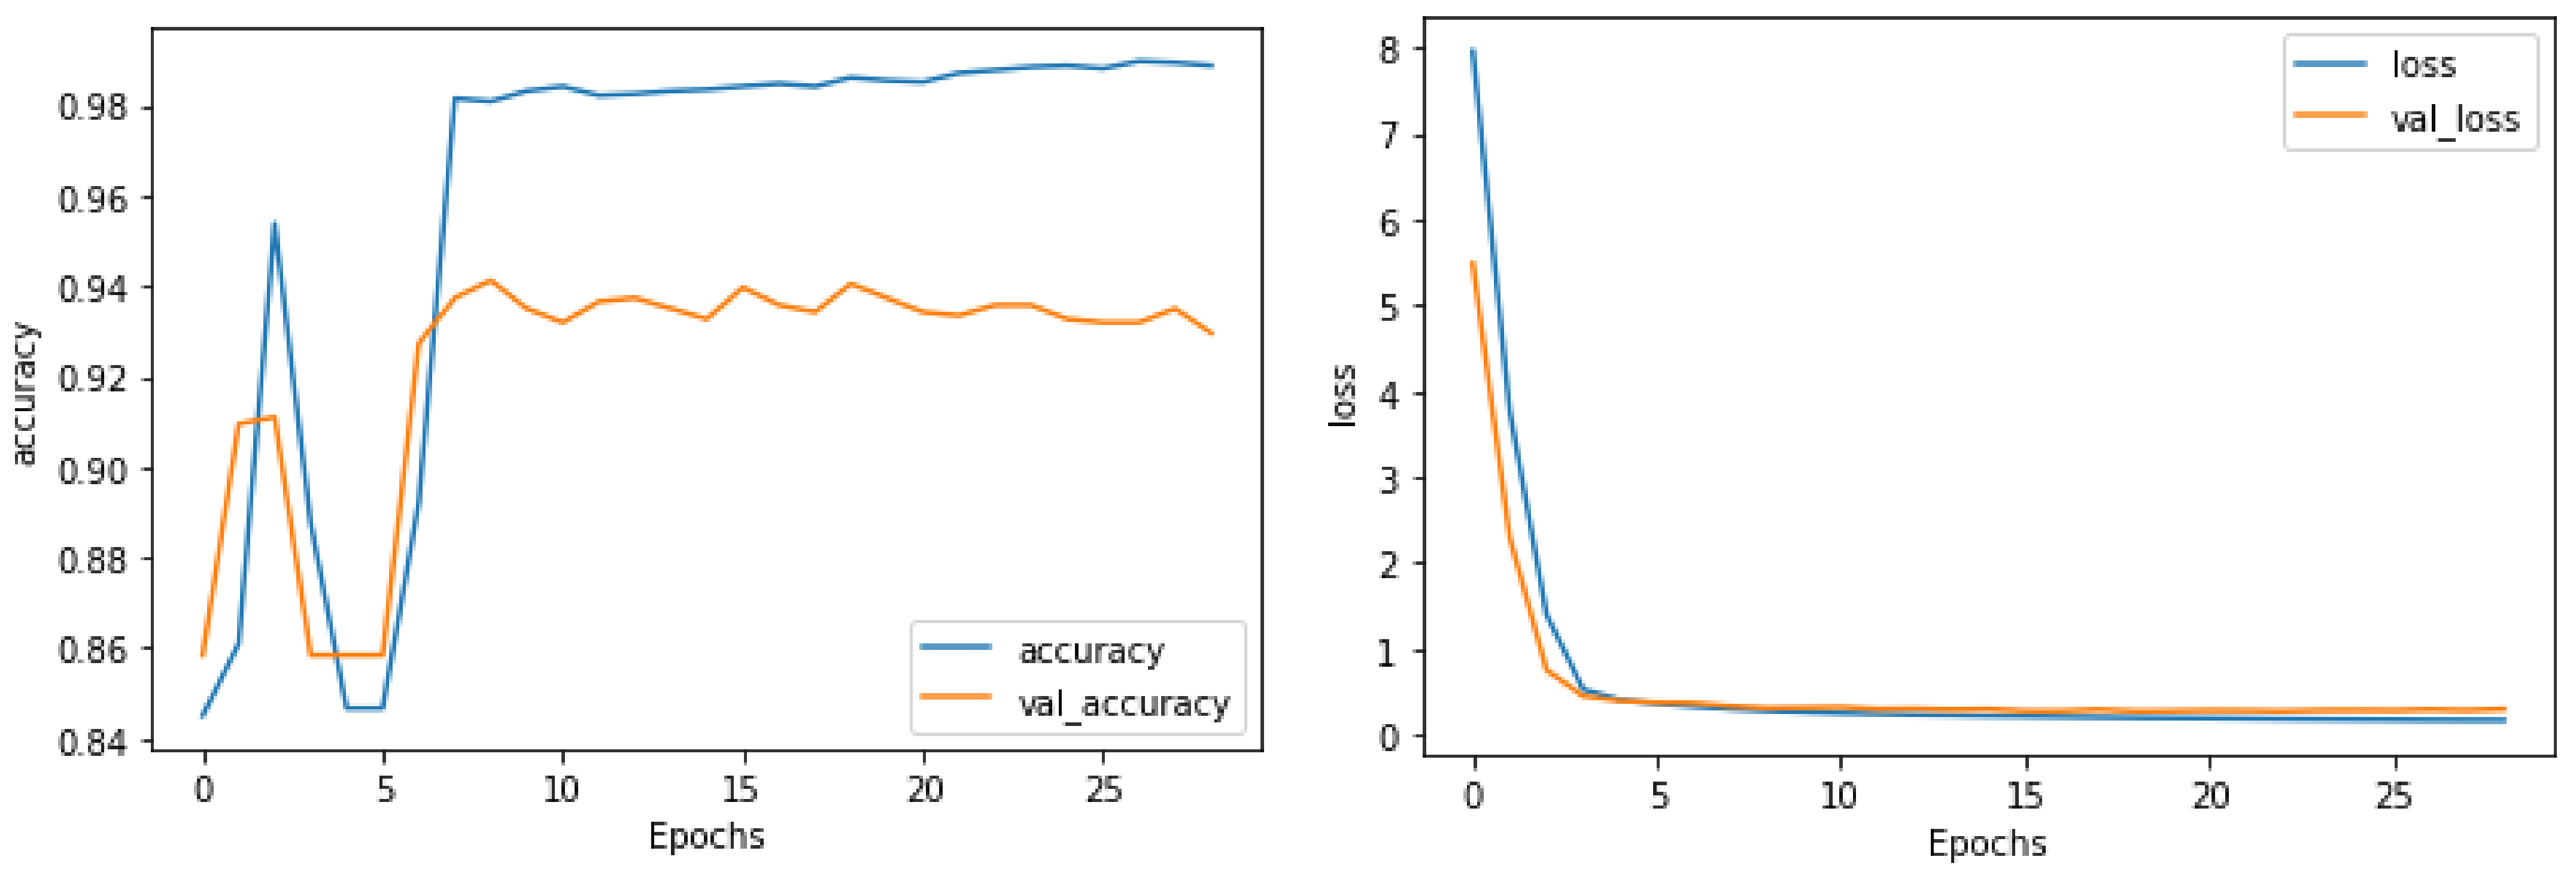
In Figure 10 and Figure 12, during the training process, there is a decrease in the accuracy curve and an increase in the loss curve because the use of Adam optimization allows the model to escape local maximum accuracy. So, from epoch 0 to before 5, the model is at a local minimum. There is no difference in the problem of loss because the loss calculation is carried out in a macro-average manner, while validation is carried out in binary. In epoch 80, due to the use of the Adam evaluation model, the stagnation in the previous epoch made the model try to move areas, fearing it would become stuck at the local maximum. At a loss, a model evaluation is also carried out to avoid a local minimum.
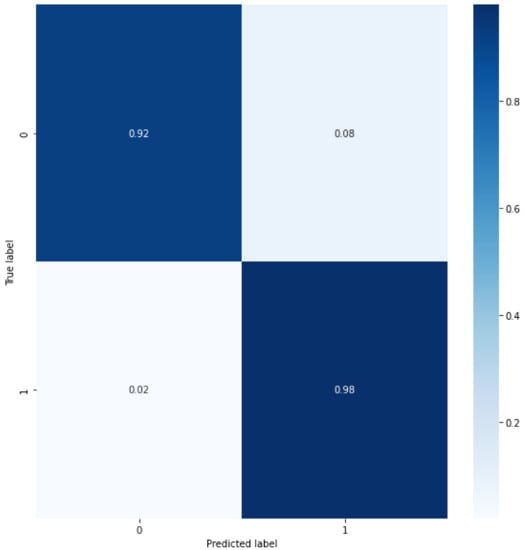
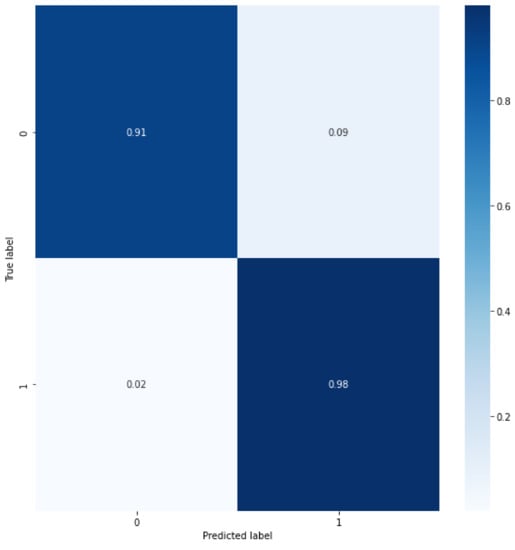
After carrying out the training process for the GCN and GRN models for aspect classification and CNN and RNN models for sentiment classification, it is followed by evaluating the performance of each model. The results of the performance evaluation of the GCN and GRN models use a confusion matrix, as shown in Figure 13 and Figure 14. The results of the performance evaluation of the GCN model are known so that the model can predict which aspect should be predicted correctly as aspect = 0.98 and which should not be predicted as not aspect = 0.92. The results of the GRN model are known to predict what should be predicted as aspect = 0.98 and which should not be predicted, not aspect = 0.91. The results of the calculation of the GCN and GRN model score evaluations for each aspect are shown in Table 6 and Table 7.
Figure 13.
The result of the confusion matrix GCN.
Figure 14.
The result of the confusion matrix GRN.
Table 6.
The experiment results of the GCN model in every aspect.
Table 7.
The experiment results of the GRN model in every aspect.
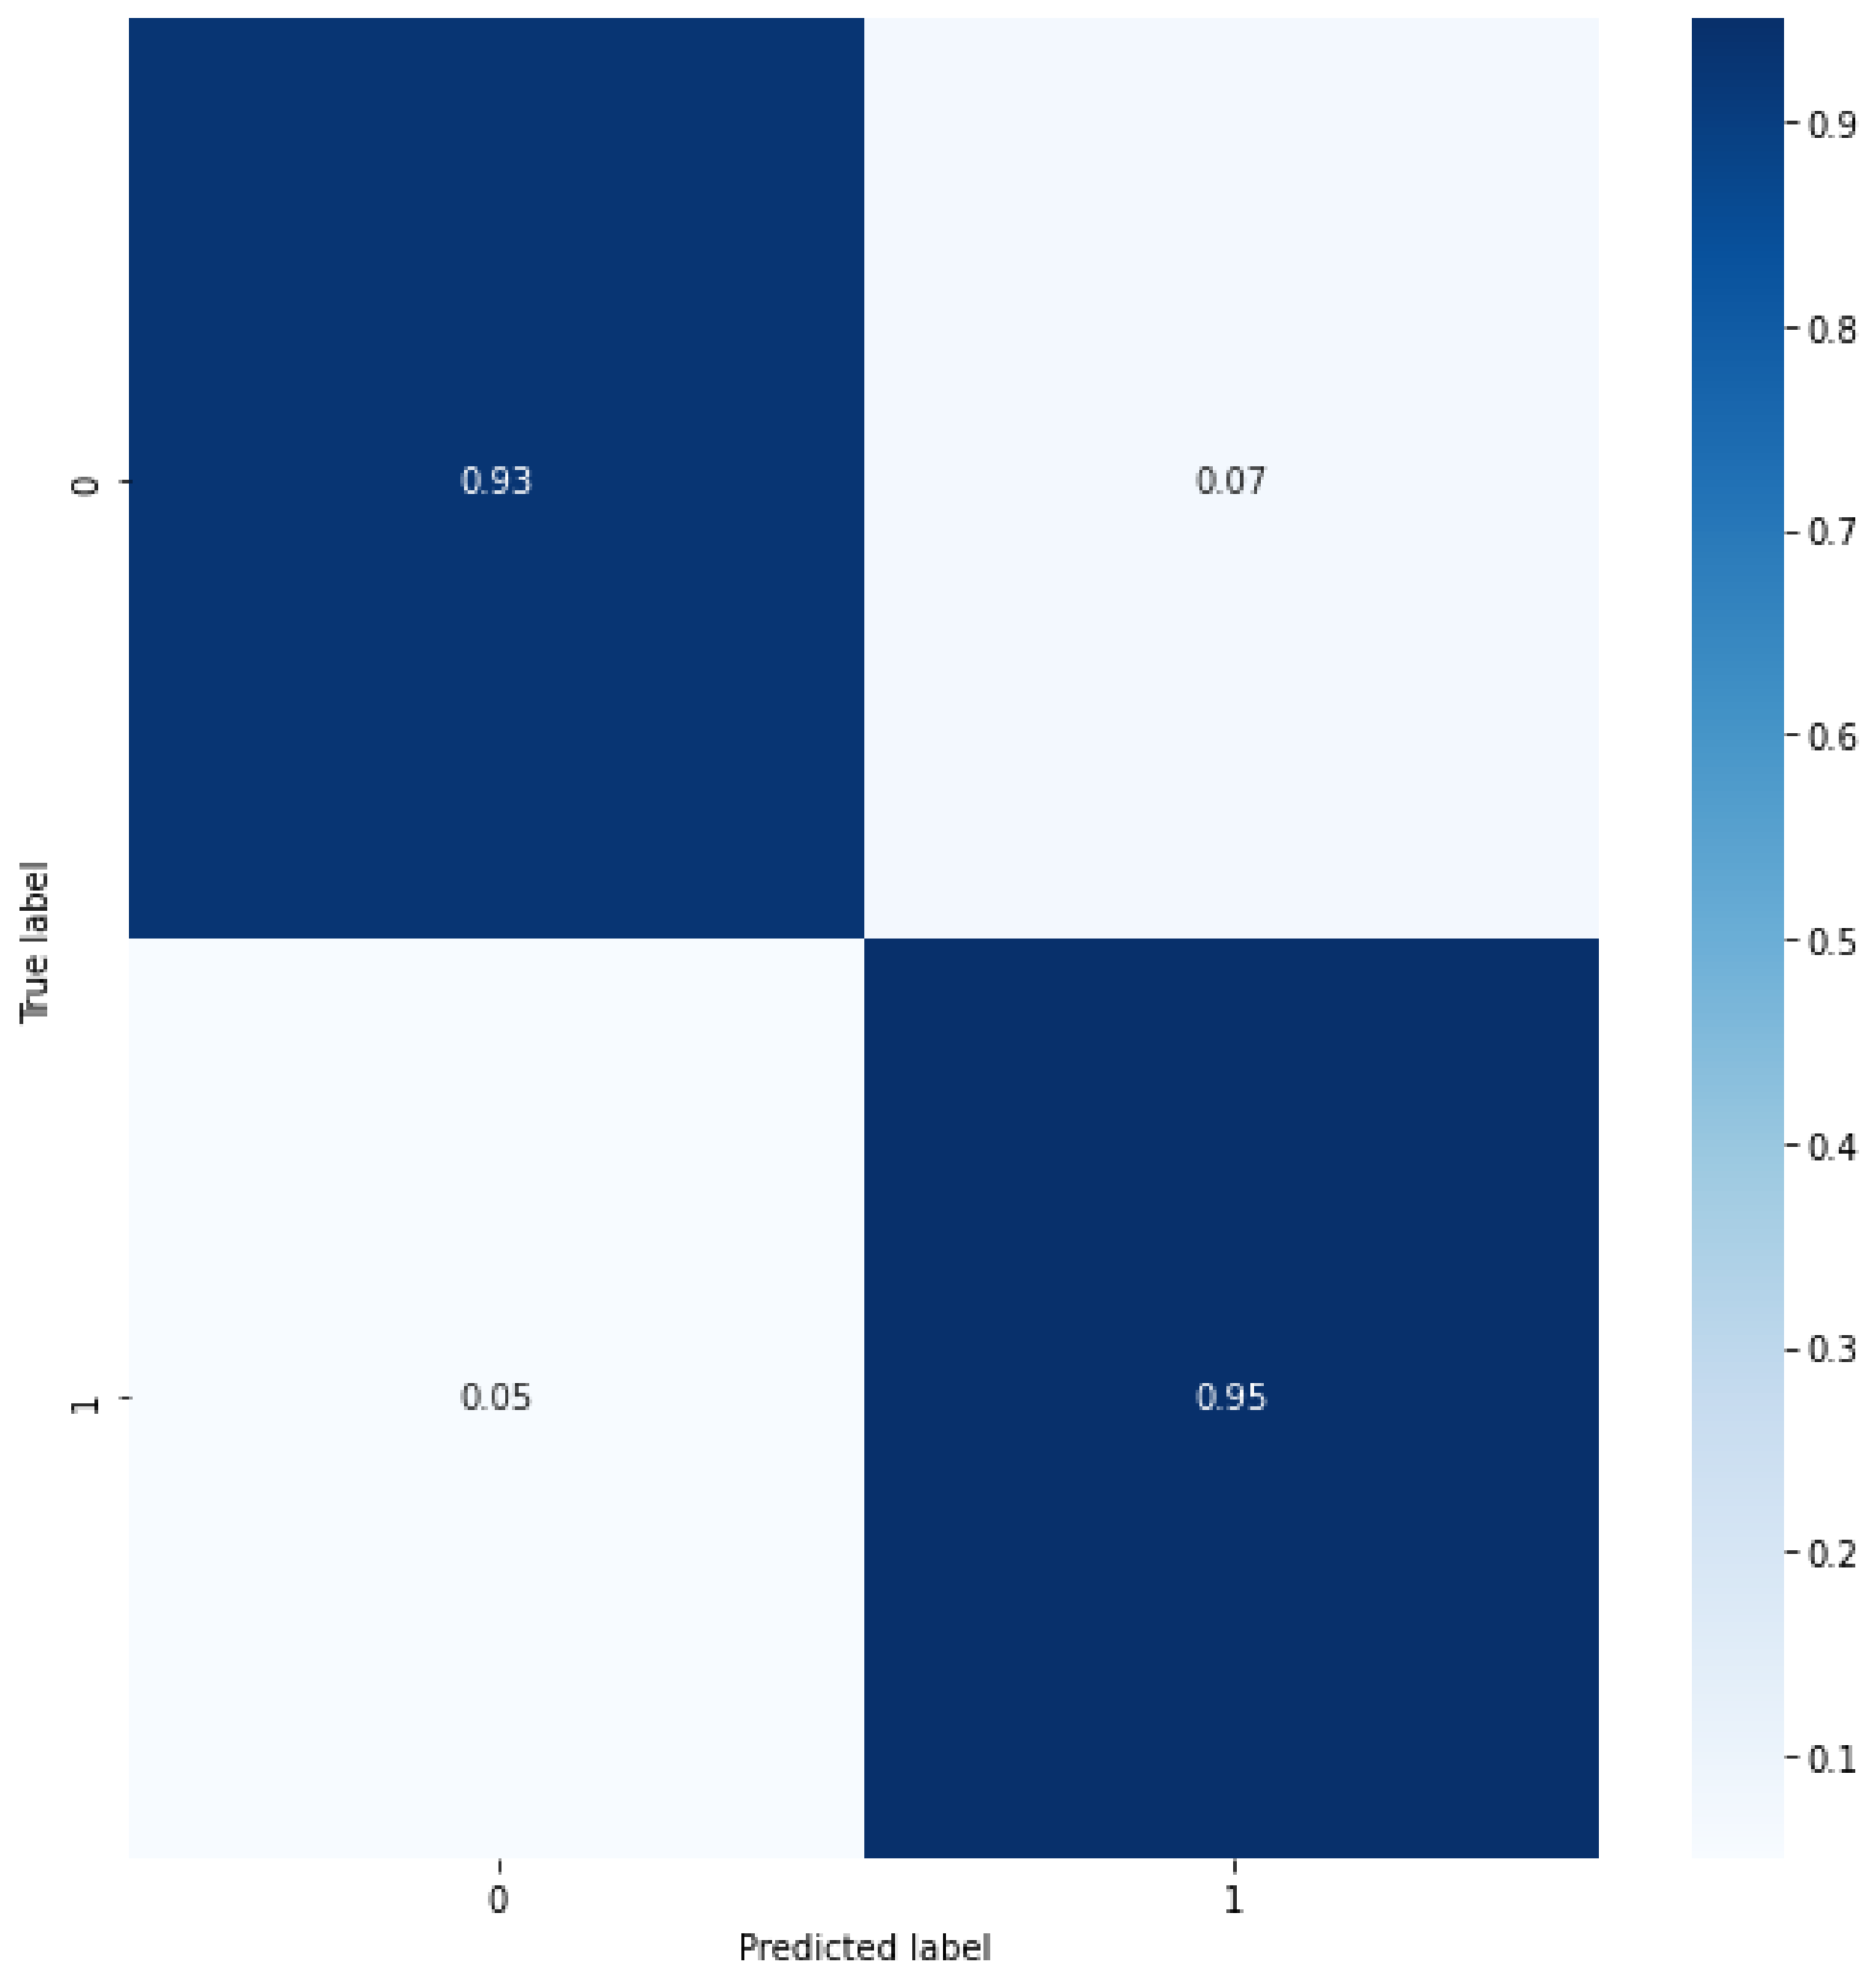
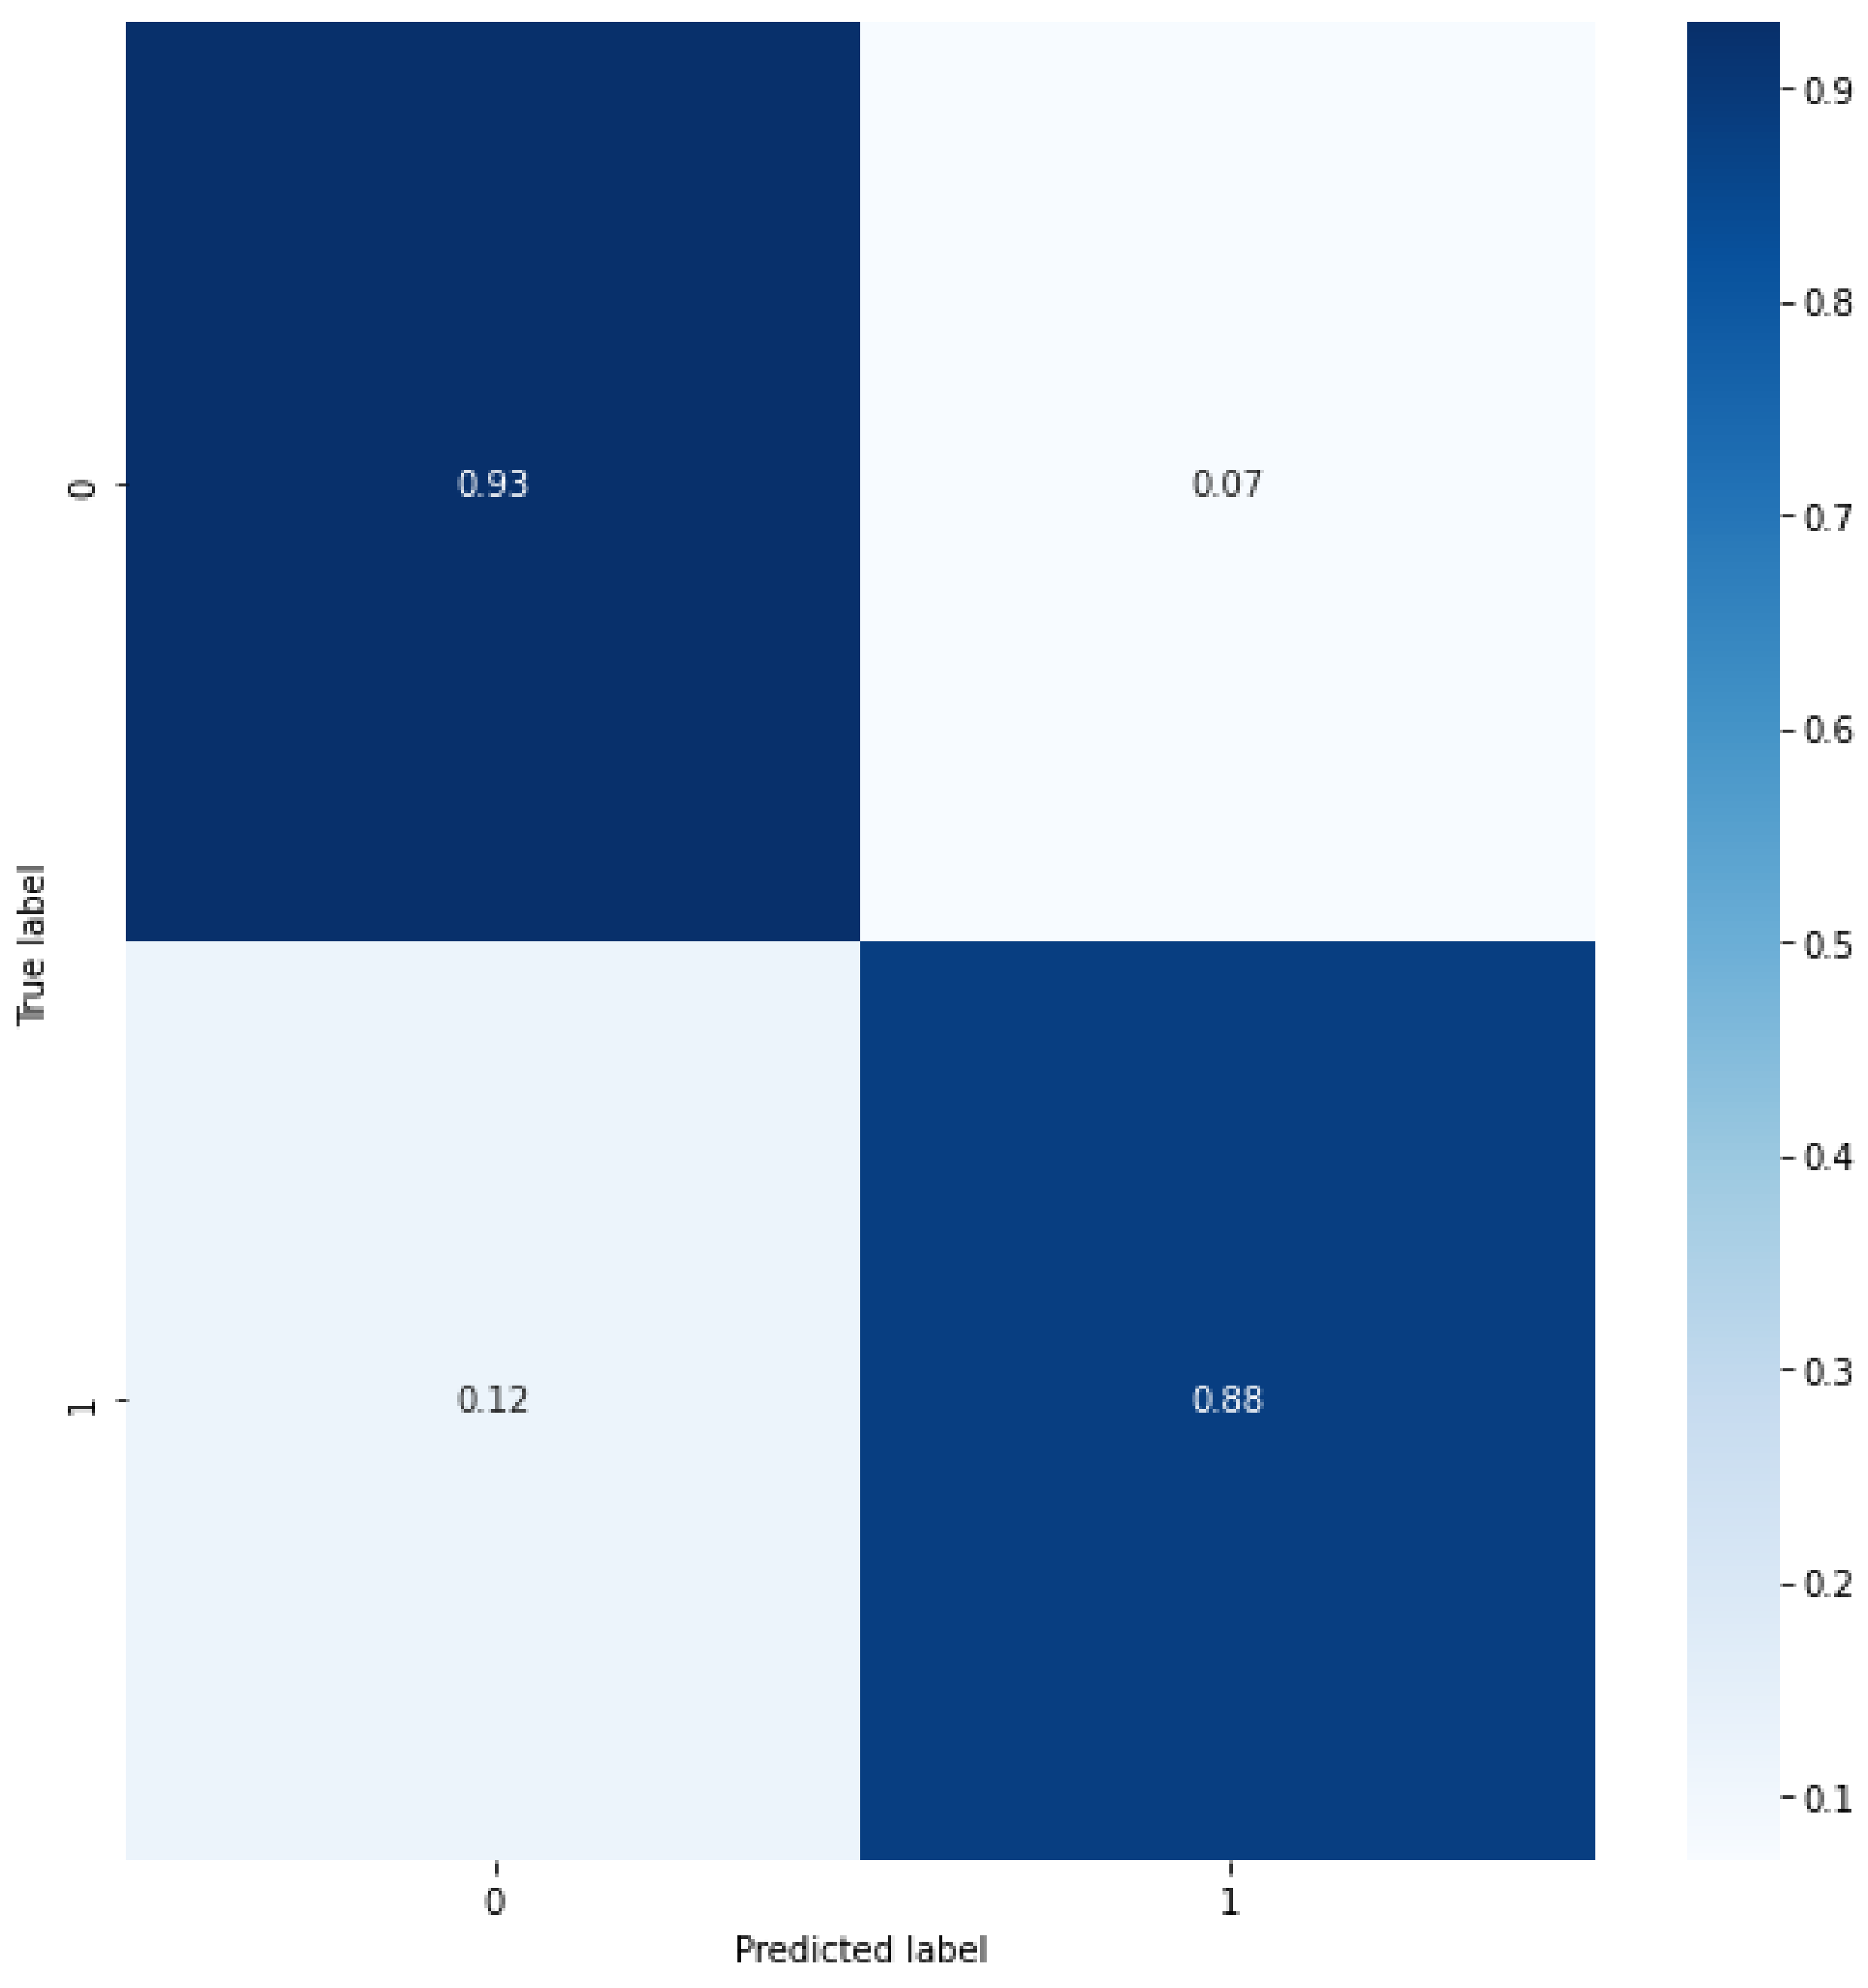
The experimental results of the CNN and RNN models for sentiment classification are shown in Figure 15 and Figure 16. The experimental results of the CNN model are known to predict positive sentiment with a prediction of positive = 0.95 and negative sentiment with a prediction of negative = 0.93. On the other hand, the RNN model can predict positive sentiment, which is predicted to be positive = 0.88, and negative sentiment is predicted to be negative = 0.93. The experimental results of CNN and RNN models for sentiment classification on each aspect are shown in Table 8 and Table 9.
Figure 15.
The result of the confusion matrix CNN.
Figure 16.
The result of the confusion matrix RNN.
Table 8.
The experiment results of the CNN model in every aspect of sentiment classification.
Table 9.
The experiment results of the RNN model in every aspect of sentiment classification.
In Table 8 and Table 9, it can be seen that there is imbalanced data; actually, in the process, aspect classifications are not considered features. All data are considered equal, so the difference in the data amount is not affected. The process of grouping aspects is carried out without a training model but from the key phrases in the aspect sentences. So, the difference in the amount of data does not affect the classification process.
The comparison results of the GCN and GRN models for aspect classification are shown in Table 10. The comparison results of CNN and RNN models for sentiment classification are shown in Table 11. The comparison results show that the GRN model is superior to the GCN model for aspect classification with an F1 score of 0.97144, and the CNN model is excellent to the RNN model for sentiment classification with an F1 score of 0.94020. Based on the experimental results, the ABSA model built in this study can outperform the existing advanced models [39,40].
Table 10.
The evaluation comparison of each model for aspect classification.
Table 11.
The evaluation comparison of each model for sentiment classification.
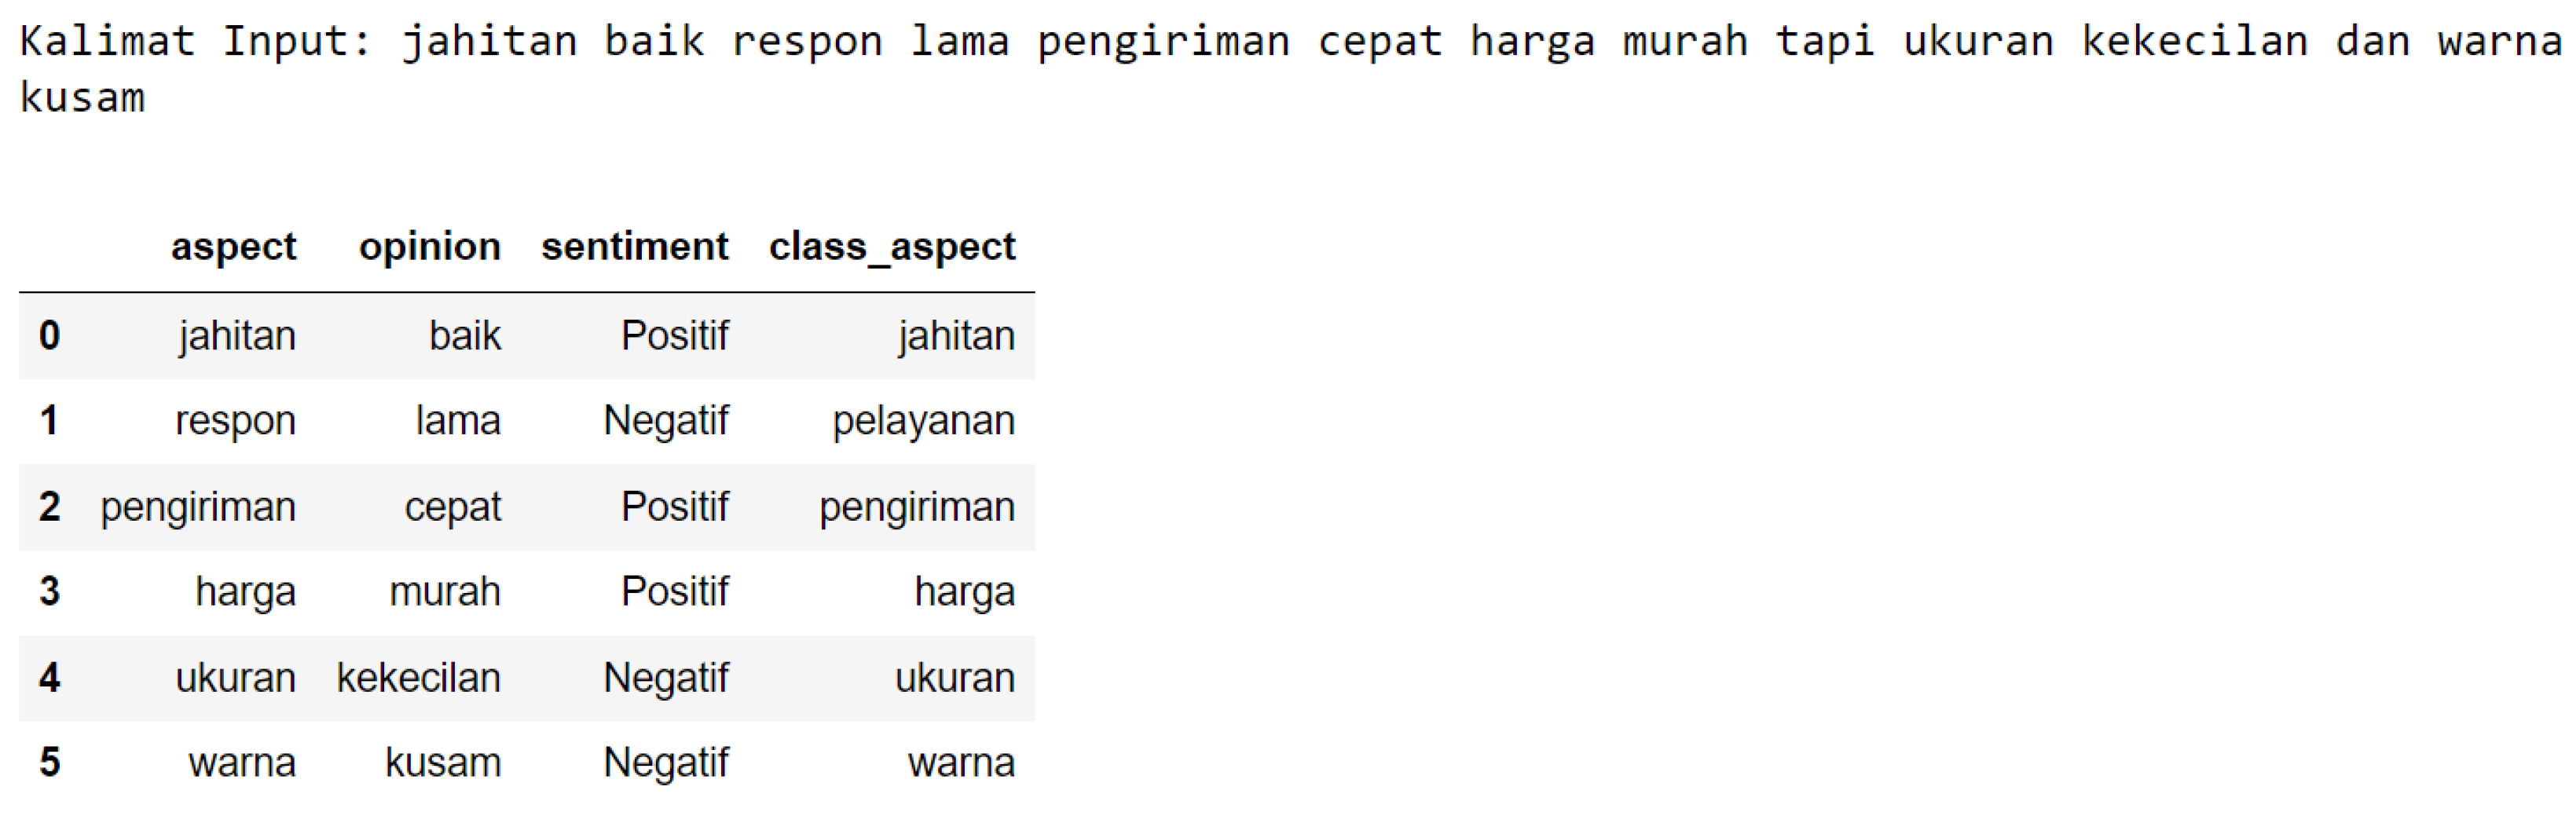
Our ABSA model is tested using a combination of the best models that we have obtained in this study, testing the sample reviews “jahitan baik respon lama pengiriman cepat harga murah tapi ukuran kekecilan dan warna kusam”, which in English is “good sewing long response fast delivery cheap price but the size is too small, and the color is dull”. The result is shown in Figure 17.
Figure 17.
The example-1 of using the ABSA model.
The ABSA results in Figure 17 obtained six aspects, with details:
- Aspect: “jahitan” “sewing”; opinion: “baik” “good”; sentiment: “positif” “positive”; class_aspect: “jahitan” “sewing”.
- Aspect: “respon” “response”; opinion: “lama” “long”; sentiment: “negatif” “negative”; class_aspect: “pelayanan” “service”.
- Aspect: “pengiriman” “delivery”; opinion: “cepat” “fast”; sentiment: “positif” “positive”; class_aspect: “pengiriman” “delivery”.
- Aspect: “harga” “price”; opinion: “murah” “cheap”’; sentiment: “positif” “positive”; class_aspect: “harga” “price”.
- Aspect: “ukuran” “size”; opinion: “kekecilan” “too small”; sentiment: “negatif” “negative”; class_aspect: “ukuran” “size”.
- Aspect: “warna” “color”; opinion: “kusam” “dull”; sentiment: “negatif” “negative”; class_aspect: “warna” “color”.
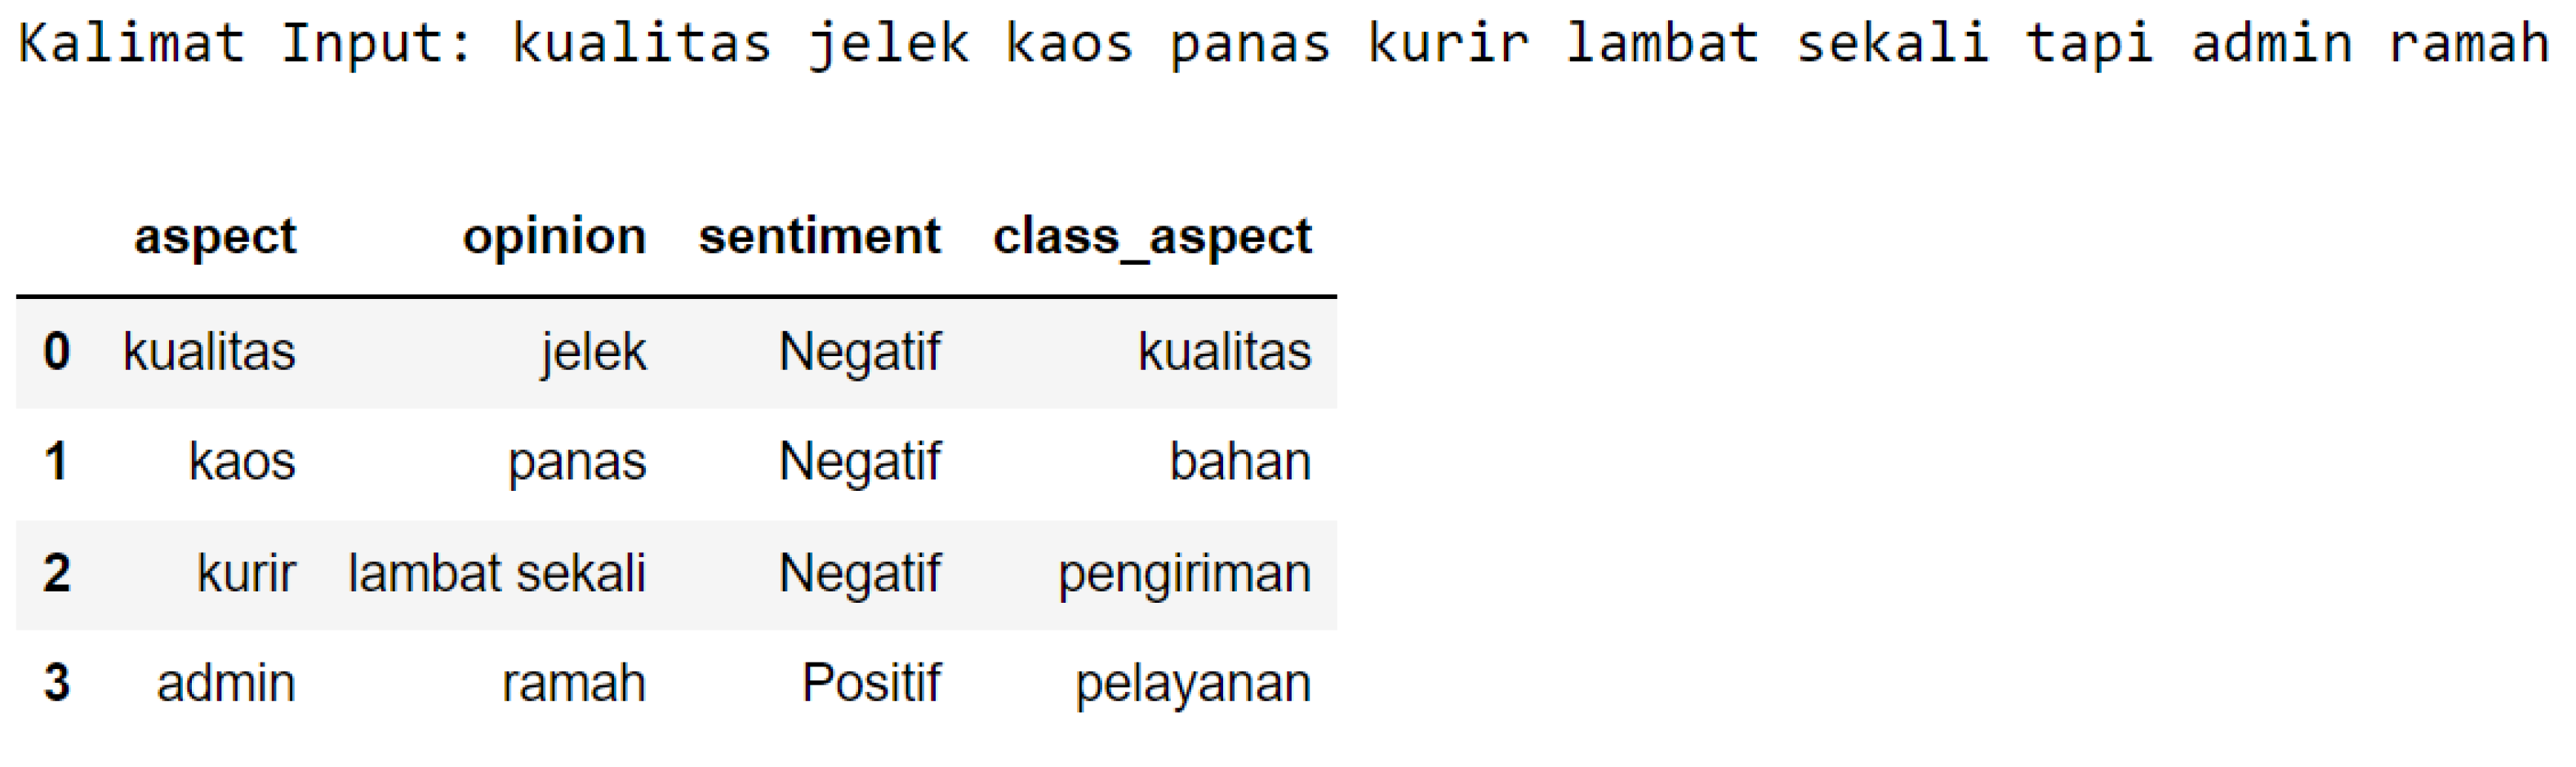
We tried another review example: “kualitas jelek kaos panas kurir lambat sekali tapi admin ramah”, which in English is “bad quality hot t-shirts courier is very slow, but admin is friendly”. The result is shown in Figure 18.
Figure 18.
The example-2 of using ABSA model.
The ABSA results in Figure 18 obtained four aspects, with details:
- Aspect: “kualitas” “quality”; opinion: “jelek” “bad”; sentiment: “negatif” “negative”; class_aspect: “kualitas” “quality”.
- Aspect: “kaos” “t-shirts”; opinion: “panas” “hot”; sentiment: “negatif” “negative”; class_aspect: “bahan” “material”.
- Aspect: “kurir” “courier”; opinion: “lambat sekali” “very slow”; sentiment: “negatif” “negative”; class_aspect: “pengiriman” “delivery”.
- Aspect: “admin” “admin”; opinion: “ramah” “friendly”; sentiment: “positif” “positive”; class_aspect: “pelayanan” “service”.
Based on the results of using ABSA for the example above, the ABSA model we developed can detect aspect, opinion, and sentiment classification well.
The ABSA model that has been built automatically labels 11,270 unlabeled tuple graph data. The result is a total of 10,582 data detected as an aspect and 688 data detected as non-aspect, as shown in Table 12.
Table 12.
The results of automatic labeling using the ABSA model.
The model that we have built has the weakness of not being able to detect if only one word is input; for example, the model cannot detect the word “barang” “item”, and that is because the model we developed is in the form of aspect-based sentiment; our model is built using a dependency parser (https://nlp.stanford.edu/software/lex-parser.shtml (accessed on 2 December 2022) [6,38,39] that is used to detect relationships between words in a sentence so that there must be two or more words inputted for the model to be able to detect aspects and sentiments. In certain cases, there are weaknesses in the GRN model; for example, the word “tidak bagus” “not good” detects positive sentiments that should be negative. However, after we tested it on the GCN model, the word “tidak bagus” “not good” was detected with negative sentiment. Even though GRN’s F1 score shows that it is superior to GCN, GRN has these deficiencies in this case. Apart from that, other shortcomings have been not being able to detect slang words, abbreviations, or non-standard words, for example, “brg jlk”, which the model cannot detect. For example, with the abbreviation for the word “brg jelek” “bad brg” the model can still detect aspects and sentiments well. Even so, the model we have built is proven to be able to detect aspects and sentiments well with a minimum of two input words written by common words. Our trials show that our model is better than the previous sophisticated model [39,40].
5. Conclusions
The results of this study obtained the best Indonesian ABSA model. The GRN model is the best model for detecting aspects and opinions, with an F1 score of 0.97144. Meanwhile, the best model for sentiment classification was obtained using CNN with an F1 score of 0.94020. Based on the experimental results, the model developed in this study can outperform the best existing models [39,40] for ABSA in Indonesian and English. The ABSA model we have developed can automatically label 11,270 data, so we obtained 10,582 aspects and 688 non-aspects. For future research, we will develop this model for a wider domain and try to explore a graph-based approach for a wider domain.
Author Contributions
Conceptualization, A.A.C.; methodology, A.A.C., W., and R.K.; software, A.A.C.; validation, A.A.C., W., and R.K.; formal analysis, W. and R.K.; visualization, A.A.C.; supervision, W. and R.K. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The data are available on request from the corresponding author, Ahmad Abdul Chamid. Please email chamid@students.undip.ac.id to request access.
Acknowledgments
This work is supported by a post-graduate research grant with contract number 345-25/UN7.6.1/PP/2022. This research was supported by Muria Kudus University and the Laboratory of Computer Modelling, Faculty of Science and Mathematics, Diponegoro University, Semarang, Indonesia.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Yeasmin, N.; Mahbub, N.I.; Baowaly, M.K.; Singh, B.C.; Alom, Z.; Aung, Z.; Azim, M.A. Analysis and Prediction of User Sentiment on COVID-19 Pandemic Using Tweets. Big Data Cogn. Comput. 2022, 6, 65. [Google Scholar] [CrossRef] [Scilit]
- Al Shamsi, A.A.; Abdallah, S. Sentiment Analysis of Emirati Dialects. Big Data Cogn. Comput. 2022, 6, 57. [Google Scholar] [CrossRef] [Scilit]
- Khabour, S.M.; Al-Radaideh, Q.A.; Mustafa, D. A New Ontology-Based Method for Arabic Sentiment Analysis. Big Data Cogn. Comput. 2022, 6, 48. [Google Scholar] [CrossRef] [Scilit]
- Ettaleb, M.; Barhoumi, A.; Camelin, N.; Dugué, N. Evaluation of weakly-supervised methods for aspect extraction. Procedia Comput. Sci. 2022, 207, 2688–2697. [Google Scholar] [CrossRef] [Scilit]
- Venugopalan, M.; Gupta, D. An enhanced guided LDA model augmented with BERT based semantic strength for aspect term extraction in sentiment analysis. Knowl.-Based Syst. 2022, 246, 108668. [Google Scholar] [CrossRef] [Scilit]
- Shi, L.; Han, D.; Han, J.; Qiao, B.; Wu, G. Dependency graph enhanced interactive attention network for aspect sentiment triplet extraction. Neurocomputing 2022, 507, 315–324. [Google Scholar] [CrossRef] [Scilit]
- Almalis, I.; Kouloumpris, E.; Vlahavas, I. Sector-level sentiment analysis with deep learning. Knowl.-Based Syst. 2022, 258, 109954. [Google Scholar] [CrossRef] [Scilit]
- Sharma, M.; Kandasamy, I.; Vasantha, W.B. Comparison of neutrosophic approach to various deep learning models for sentiment analysis. Knowl.-Based Syst. 2021, 223, 107058. [Google Scholar] [CrossRef] [Scilit]
- Yu, H.; Lu, G.; Cai, Q.; Xue, Y. A KGE Based Knowledge Enhancing Method for Aspect-Level Sentiment Classification. Mathematics 2022, 10, 3908. [Google Scholar] [CrossRef] [Scilit]
- Al-Dabet, S.; Tedmori, S.; AL-Smadi, M. Enhancing Arabic aspect-based sentiment analysis using deep learning models. Comput. Speech Lang. 2021, 69, 101224. [Google Scholar] [CrossRef] [Scilit]
- Ismail, H.; Khalil, A.; Hussein, N.; Elabyad, R. Triggers and Tweets: Implicit Aspect-Based Sentiment and Emotion Analysis of Community Chatter Relevant to Education Post-COVID-19. Big Data Cogn. Comput. 2022, 6, 99. [Google Scholar] [CrossRef] [Scilit]
- Cendani, L.M.; Kusumaningrum, R.; Endah, S.N. Aspect-Based Sentiment Analysis of Indonesian-Language Hotel Reviews Using Long Short-Term Memory with an Attention Mechanism; Springer International Publishing: Berlin/Heidelberg, Germany, 2023; Volume 147, ISBN 9783031151910. [Google Scholar] [CrossRef] [Scilit]
- Ayetiran, E.F. Attention-based aspect sentiment classification using enhanced learning through CNN-BiLSTM networks. Knowl.-Based Syst. 2022, 252, 109409. [Google Scholar] [CrossRef] [Scilit]
- Chen, L.; Wang, Y.; Li, H. Enhancement of DNN-based multilabel classification by grouping labels based on data imbalance and label correlation. Pattern Recognit. 2022, 132, 108964. [Google Scholar] [CrossRef] [Scilit]
- Jasmir, J.; Nurmaini, S.; Tutuko, B. Fine-grained algorithm for improving knn computational performance on clinical trials text classification. Big Data Cogn. Comput. 2021, 5, 60. [Google Scholar] [CrossRef] [Scilit]
- Kanavos, A.; Iakovou, S.A.; Sioutas, S.; Tampakas, V. Large scale product recommendation of supermarket ware based on customer behaviour analysis. Big Data Cogn. Comput. 2018, 2, 11. [Google Scholar] [CrossRef] [Scilit]
- Didi, Y.; Walha, A.; Wali, A. COVID-19 Tweets Classification Based on a Hybrid Word Embedding Method. Big Data Cogn. Comput. 2022, 6, 58. [Google Scholar] [CrossRef] [Scilit]
- Ebrahimi, P.; Basirat, M.; Yousefi, A.; Nekmahmud, M.; Gholampour, A.; Fekete-farkas, M. Social Networks Marketing and Consumer Purchase Behavior: The Combination of SEM and Unsupervised Machine Learning Approaches. Big Data Cogn. Comput. 2022, 6, 35. [Google Scholar] [CrossRef] [Scilit]
- Ng, Q.X.; Yau, C.E.; Lim, Y.L.; Wong, L.K.T.; Liew, T.M. Public sentiment on the global outbreak of monkeypox: An unsupervised machine learning analysis of 352,182 twitter posts. Public Health 2022, 213, 1–4. [Google Scholar] [CrossRef] [Scilit]
- García-Pablos, A.; Cuadros, M.; Rigau, G. W2VLDA: Almost unsupervised system for Aspect Based Sentiment Analysis. Expert Syst. Appl. 2018, 91, 127–137. [Google Scholar] [CrossRef] [Scilit]
- Yadav, A.; Jha, C.K.; Sharan, A.; Vaish, V. Sentiment analysis of financial news using unsupervised approach. Procedia Comput. Sci. 2020, 167, 589–598. [Google Scholar] [CrossRef] [Scilit]
- Kaur, G.; Kaushik, A.; Sharma, S. Cooking is creating emotion: A study on hinglish sentiments of youtube cookery channels using semi-supervised approach. Big Data Cogn. Comput. 2019, 3, 37. [Google Scholar] [CrossRef] [Scilit]
- Macrohon, J.J.E.; Villavicencio, C.N.; Inbaraj, X.A.; Jeng, J. A Semi-Supervised Approach to Sentiment Analysis of Tweets during the 2022 Philippine Presidential Election. Information 2022, 13, 484. [Google Scholar] [CrossRef] [Scilit]
- Deng, Y.; Zhang, C.; Yang, N.; Chen, H. FocalMatch: Mitigating Class Imbalance of Pseudo Labels in Semi-Supervised Learning. Appl. Sci. 2022, 12, 10623. [Google Scholar] [CrossRef] [Scilit]
- Tu, E.; Wang, Z.; Yang, J.; Kasabov, N. Deep semi-supervised learning via dynamic anchor graph embedding in latent space. Neural Networks 2022, 146, 350–360. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zaks, G.; Katz, G. ReCom: A deep reinforcement learning approach for semi-supervised tabular data labeling. Inf. Sci. 2022, 589, 321–340. [Google Scholar] [CrossRef] [Scilit]
- Riyadh, M.; Omair Shafiq, M. Towards Multi-class Sentiment Analysis with Limited Labeled Data. In Proceedings of the 2021 IEEE International Conference on Big Data (Big Data), Orlando, FL, USA, 15–18 December 2021. [Google Scholar] [CrossRef] [Scilit]
- De Santo, A.; Galli, A.; Moscato, V.; Sperlì, G. A deep learning approach for semi-supervised community detection in Online Social Networks. Knowl.-Based Syst. 2021, 229, 107345. [Google Scholar] [CrossRef] [Scilit]
- Li, N.; Chow, C.Y.; Zhang, J.D. SEML: A semi-supervised multi-task learning framework for aspect-based sentiment analysis. IEEE Access 2020, 8, 189287–189297. [Google Scholar] [CrossRef] [Scilit]
- Zheng, H.; Zhang, J.; Suzuki, Y.; Fukumoto, F.; Nishizaki, H. Semi-Supervised Learning for Aspect-Based Sentiment Analysis. In Proceedings of the 2021 International Conference on Cyberworlds (CW), Caen, France, 28–30 September 2021. [Google Scholar] [CrossRef] [Scilit]
- Ilmania, A.; Abdurrahman; Cahyawijaya, S.; Purwarianti, A. Aspect Detection and Sentiment Classification Using Deep Neural Network for Indonesian Aspect-Based Sentiment Analysis. In Proceedings of the 2018 International Conference on Asian Language Processing, Bandung, Indonesia, 15–17 November 2018; IEEE: Piscataway, NJ, USA, 2018; pp. 62–67. [Google Scholar] [CrossRef] [Scilit]
- Cahyadi, A.; Khodra, M.L. Aspect-Based Sentiment Analysis Using Convolutional Neural Network and Bidirectional Long Short-Term Memory. In Proceedings of the 2018 5th International Conference on Advanced Informatics: Concept Theory and Applications (ICAICTA), Krabi, Thailand, 14–17 August 2018; pp. 124–129. [Google Scholar] [CrossRef] [Scilit]
- Wahyudi, E.; Kusumaningrum, R. Aspect Based Sentiment Analysis in E-Commerce User Reviews Using Latent Dirichlet Allocation (LDA) and Sentiment Lexicon. In Proceedings of the 3rd International Conference on Informatics and Computational Sciences, Semarang, Indonesia, 29–30 October 2019. [Google Scholar]
- Kim, D.; Kim, Y.J.; Jeong, Y.S. Graph Convolutional Networks with POS Gate for Aspect-Based Sentiment Analysis. Appl. Sci. 2022, 12, 134. [Google Scholar] [CrossRef] [Scilit]
- An, W.; Tian, F.; Chen, P.; Zheng, Q. Aspect-Based Sentiment Analysis with Heterogeneous Graph Neural Network. IEEE Trans. Comput. Soc. Syst. 2022; early access. [CrossRef] [Scilit]
- Gu, T.; Zhao, H.; He, Z.; Li, M.; Ying, D. Integrating external knowledge into aspect-based sentiment analysis using graph neural network. Knowl.-Based Syst. 2022, 259, 110025. [Google Scholar] [CrossRef] [Scilit]
- Yang, J.; Dai, A.; Xue, Y.; Zeng, B.; Liu, X. Syntactically Enhanced Dependency-POS Weighted Graph Convolutional Network for Aspect-Based Sentiment Analysis. Mathematics 2022, 10, 3353. [Google Scholar] [CrossRef] [Scilit]
- Wu, H.; Zhang, Z.; Shi, S.; Wu, Q.; Song, H. Phrase dependency relational graph attention network for Aspect-based Sentiment Analysis. Knowl.-Based Syst. 2022, 236, 107736. [Google Scholar] [CrossRef] [Scilit]
- Wang, K.; Shen, W.; Yang, Y.; Quan, X.; Wang, R. Relational Graph Attention Network for Aspect-based Sentiment Analysis. In Proceedings of the Association for Computational Linguistics; Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; pp. 3229–3238. [Google Scholar] [CrossRef] [Scilit]
- Nayoan, R.A.N.; Fathan Hidayatullah, A.; Fudholi, D.H. Convolutional Neural Networks for Indonesian Aspect-Based Sentiment Analysis Tourism Review. In Proceedings of the 9th International Conference on Information and Communication Technology (ICoICT), Yogyakarta, Indonesia, 3–5 August 2021; IEEE: Piscataway, NJ, USA, 2021; pp. 60–65. [Google Scholar] [CrossRef] [Scilit]
- Tedjojuwono, S.M.; Neonardi, C. Aspect Based Sentiment Analysis: Restaurant Online Review Platform in Indonesia with Unsupervised Scraped Corpus in Indonesian Language. In Proceedings of the 1st International Conference on Computer Science and Artificial Intelligence (ICCSAI), Jakarta, Indonesia, 28 October 2021; Volume 1, pp. 213–218. [Google Scholar] [CrossRef] [Scilit]
- Manik, L.P.; Febri Mustika, H.; Akbar, Z.; Kartika, Y.A.; Ridwan Saleh, D.; Setiawan, F.A.; Atman Satya, I. Aspect-Based Sentiment Analysis on Candidate Character Traits in Indonesian Presidential Election. In Proceedings of the 2020 International Conference on Radar, Antenna, Microwave, Electronics, and Telecommunications (ICRAMET), Tangerang, Indonesia, 18–20 November 2020; pp. 224–228. [Google Scholar] [CrossRef] [Scilit]
- Yanuar, M.R.; Shiramatsu, S. Aspect Extraction for Tourist Spot Review in Indonesian Language using BERT. In Proceedings of the 2020 International Conference on Artificial Intelligence in Information and Communication (ICAIIC), Fukuoka, Japan, 19–21 February 2020; pp. 298–302. [Google Scholar] [CrossRef] [Scilit]
- Chakraborty, A. Aspect Based Sentiment Analysis Using Spectral Temporal Graph Neural Network. arXiv 2022, arXiv:2202.06776v1. [Google Scholar]
- Li, R.; Chen, H.; Feng, F.; Ma, Z.; Wang, X.; Hovy, E. Dual graph convolutional networks for aspect-based sentiment analysis. In Proceedings of the ACL-IJCNLP 2021—59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing, Proceedings of the Conference, Online, 1–6 August 2021; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 6319–6329. [Google Scholar] [CrossRef] [Scilit]
- Liang, B.; Su, H.; Gui, L.; Cambria, E.; Xu, R. Aspect-based sentiment analysis via affective knowledge enhanced graph convolutional networks. Knowl.-Based Syst. 2022, 235, 107643. [Google Scholar] [CrossRef] [Scilit]
- Phan, H.T.; Nguyen, N.T.; Hwang, D. Aspect-level sentiment analysis: A survey of graph convolutional network methods. Inf. Fusion 2023, 91, 149–172. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2022 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).