


Abstract
The paper presents a model for the design and management of metadata that enables the efficient compilation of specialised datasets from large, heterogeneous data collections. The metadata are represented as a typed property graph that facilitates the FAIR principles in data compilation: Findable, Accessible, Interoperable, Reusable. The representation is general and independent of the modality and format of the data. The graph-based design of the metadata supports the incremental extension of categories and relationships without requiring the migration of existing data. Its feasibility is demonstrated through the use of a graph database, in which the metadata for 689,645 Bulgarian textual data units are combined with a web-based filtering interface. Metadata retrieval is implemented through Cypher queries executed as graph traversals, enabling the extraction of thematic and application-oriented data subsets based on combinations of selection criteria. The application validates the suitability of the graph-based metadata design for compiling specialised datasets for training and fine-tuning large language models and other NLP applications.
1. Introduction
The paper presents a model for organising and managing metadata for large datasets, enabling the efficient compilation of sub-datasets based on specific selection criteria. The model can be applied in data science, artificial intelligence, computational linguistics, and more specifically, in managing metadata for large-scale datasets, including for the pre-training and fine-tuning of large language models and the development and training of artificial intelligence applications. As the volume, heterogeneity, and provenance complexity of data continue to grow, the ability to locate, analyse, and recombine diverse resources in an organised and controllable manner has become a prerequisite for reproducible and methodologically sound research in natural language processing and artificial intelligence.
Several significant limitations persist in current practice regarding dataset management. Metadata schemata across data collections remain isolated and highly dependent on the initial task for which they were compiled, which impedes cross-collection retrieval and subsequent reuse. The reliability and compositional structure of datasets used in large-model training are rarely captured in an analysable form, and considerable effort is required to obtain an overview of a dataset and evaluate its applicability for a particular task. The relationships between resources, such as sources or domain affiliation, are rarely stated explicitly in the description of dataset units, although they are central to assessing the coverage, quality and applicability of the data. The filtering and selection of training and evaluation datasets for specific tasks, domains or languages rely, to a large extent, on pre-established procedures rather than on data-driven, unified and queryable representations of the available resources.
The present model aims to fill these gaps by proposing a structured and organised model for metadata description as a typed property graph, independent of the modality and format of the data. Moreover, the graph-designed metadata offers the possibility to provide a direct link both to the original document (the source), the processed document (converted into an adopted unified format), as well as other versions of the documents in various formats or modalities if available (audio/video, transcribed, normalised, annotated, etc.).
The graph-based design is demonstrated through its implementation in the Neo4j graph database, where the metadata of 689,645 Bulgarian textual data units are stored. Metadata retrieval is supported by a web-based filtering interface that executes Cypher queries as graph traversals, enabling the extraction of thematic and application-oriented data subsets according to combinations of user-specified selection criteria.
The graph-based metadata coupled with an efficient and flexible representation as a graph database are designed to enforce and facilitate the FAIR principles in data compilation: Findable, Accessible, Interoperable, Reusable.
The present work is guided by the following research questions:
RQ1. Can a typed property graph provide a unified metadata representation across heterogeneous datasets, while preserving its expressive power to support both general-purpose and task-specific dataset compilation?
RQ2. Does the proposed graph model support efficient retrieval of specialised datasets from big data using multi-criteria queries?
The remainder of the paper addresses these questions by situating the proposed model within related work (Section 2) and outlining its objectives and motivation (Section 3). Its conceptual architecture and underlying graph schema are presented (Section 4). The validity of the metadata model is demonstrated through an application for database management of textual data in Bulgarian and a web interface for dataset filtering and compilation (Section 5), which also illustrates its applications for metadata management in contemporary artificial intelligence (Section 6). The paper concludes with directions for future work (Section 7).
2. Related Works
Many resources use metadata tailored to the specific nature of their underlying content and the application tasks they are designed to support. Although metadata description originated in the context of textual corpora, the same principles increasingly apply to other large datasets: audio, image, video, and multimodal collections, used to develop language technologies, computer vision systems, and large language models.
This overview of metadata representation practices focuses on aspects central to the proposed model: metadata design, and the search and discovery interfaces provided by the surveyed resources.
2.1. Metadata Design
The metadata designs observed in contemporary large-scale language resources reveal substantial diversity in metadata descriptions and formats, with varying properties, expressive power and processing efficiency that depend largely on their intended uses. Closer examination illustrates how metadata design reflects both the provenance of the data and the different aspects of the description of the units in a dataset. Web-scale and curated textual resources, in particular, have converged on a relatively small number of serialisation formats while diverging considerably in the fields they specify.
- OSCAR 23.01 (Open Super-large Crawled Aggregated coRpus) [1] (https://oscar-project.org/, accessed on 25 May 2026) provides a multilingual web-crawled corpus derived from Common Crawl, distributed as JSONL (JSON Lines) files in Zstandard-compressed form, with document-level metadata including language identification confidence, quality scores, harmful-content annotations, perplexity-based filtering indicators, and crawl provenance.
- CulturaX [2] (https://huggingface.co/datasets/uonlp/CulturaX, accessed on 25 May 2026) offers a cleaned and deduplicated multilingual corpus combining mC4 and OSCAR sources, stored as Parquet shards, with document-level metadata covering language labels, URL provenance, timestamps, and quality indicators derived from a multi-stage filtering pipeline.
- HPLT Monolingual 3.0 (High Performance Language Technologies Monolingual Release 3.0) [3] (https://hplt-project.org/datasets/v3.0, accessed on 25 May 2026) is distributed in both JSONL and Parquet formats, with document-level metadata fields covering language identification, document- and segment-level quality estimates, web register labels, personally identifiable information annotations, and crawl provenance.
- ParlaMint (Parliamentary Corpora of the Comparable and Multilingual Type) [4,5] (https://www.clarin.eu/parlamint, accessed on 25 May 2026) provides comparable parliamentary corpora encoded in TEI/Parla-CLARIN XML (https://clarin-eric.github.io/parla-clarin/, accessed on 25 May 2026), which offers extensive metadata description capabilities through the TEI schema [6], together with CoNLL-U derivatives for linguistic annotation. The corpora include structured metadata describing speakers (e.g., name, gender, party affiliation and parliamentary role), sessions, legislative terms, and meetings, as well as topic annotations and government/opposition status indicators.
- MARCELL (Multilingual Resources for CEF.AT in the Legal Domain) [7] (https://marcell-project.eu/, accessed on 25 May 2026) provides comparable national legislative corpora for seven languages (Bulgarian, Croatian, Hungarian, Polish, Romanian, Slovak and Slovenian), distributed in CoNLL-U Plus format with four additional columns beyond the standard ten. The documents are tokenised, sentence- and paragraph-split, lemmatised, morphologically analysed, and dependency parsed, and are further enriched with named entity labels together with term and descriptor annotations from IATE (Interactive Terminology for Europe, the European Union’s interinstitutional terminology database) (https://iate.europa.eu/, accessed on 25 May 2026) and EuroVoc (multilingual, multidisciplinary thesaurus of the European Union, maintained by the Publications Office, https://op.europa.eu/en/web/eu-vocabularies, accessed on 25 May 2026) providing a topic classification for each legislative document. The metadata for the seven languages are synchronised and include existing (or obtainable) key elements such as identifier, document title, document date, document issuer, keywords, topic, and URL. Metadata are presented at the beginning of each document in key–value format.
- CURLICAT (Curated Multilingual Language Resources for CEF.AT) [8] (https://nytud.hu/en/tender/curlicat-curated-multilingual-language-resources-for-cef-at-2, accessed on 25 May 2026) provides curated multilingual corpora in seven languages (Bulgarian, Croatian, Hungarian, Polish, Romanian, Slovak and Slovenian), drawn from copyright-free parts of national corpora and other available copyright-free resources, and covering domains relevant to the European Digital Service Infrastructures, including eHealth, Europeana, eGovernment, education, and science. The data are represented in CoNLL-U Plus format, and are tokenised, sentence- and paragraph-split, lemmatised, morphologically analysed, and dependency parsed, and annotated for named entities, noun phrases, and IATE terms. Uniform metadata are applied across all language sub-corpora, containing obligatory and optional metadata fields and increasing the number of fields compared with the MARCELL metadata. Again, metadata are placed at the beginning of each file as key–value pairs.
A brief review of some recent publicly available datasets with metadata shows that metadata usually include administrative fields that support management, preservation, and access, as well as provenance fields that record origin and processing history. Only rarely do metadata describe the quality and reliability of the data units. In terms of standardisation, the metadata presented are mostly dataset- or project-specific, with the exception of the MARCELL and CURLICAT datasets, which are produced by the same consortium. Another conclusion is that the most widely used are document-level metadata (such as source URL, publication date and language), again with some exceptions for MARCELL and CURLICAT, where paragraph and sentence boundaries and sentence IDs are provided.
The same diversity, accompanied by similar tendencies and conventions, is evident across modalities in non-textual language and other modality resources. Audio collections, in particular, highlight the need for richer, more expressive metadata to support the structured taxonomies and temporal alignments required for downstream tasks such as classification, retrieval, and speech recognition.
- AudioSet [9] (https://research.google.com/audioset/, accessed on 25 May 2026) uses a hierarchically organised JSON ontology of 632 audio classes together with CSV indices of YouTube video identifiers annotated with 10-s start and end offsets and multi-label class assignments. The ontology encodes parent–child relationships, textual descriptions and category restriction markers for each class, thereby supporting hierarchical retrieval, taxonomy-aware evaluation, and the selective construction of balanced or class-specific subsets for sound event detection, audio tagging, and weakly supervised learning.
- LibriSpeech ASR Corpus [10] (https://www.openslr.org/12, accessed on 25 May 2026) combines speaker-, chapter-, and book-level metadata with utterance-aligned transcripts derived from English audiobooks distributed through LibriVox. Per-utterance records include speaker identifiers, chapter and book identifiers, and transcription text, while speaker metadata additionally specify gender and the total duration of contributed audio. The corpus is partitioned into predefined clean and other subsets reflecting differences in recording quality and speech recognition difficulty.
- The Million Song Dataset (MSD) [11] (http://millionsongdataset.com/, accessed on 25 May 2026) stores dozens of metadata and audio-analysis attributes per track in HDF5 format, including artist and album identifiers, release year, listener-derived tags, MusicBrainz cross-references, and artist similarity information, together with low-level acoustic descriptors such as tempo, key, time signature, loudness, segment-level pitch and timbre vectors, and beat- and bar-level onset times. A companion SQLite database provides indexed catalogue access, enabling efficient queries by artist, year, or tag, and supports tasks such as music recommendation, cover song identification, and large-scale music information retrieval.
The scale and heterogeneity of computer vision datasets place additional demands on metadata and annotation schemata, particularly for representing image and video content, licensing information, provenance, and annotation structures.
- COCO (Common Objects in Context) [12] (https://cocodataset.org/, accessed on 25 May 2026) presents metadata in a single JSON file, structured around the fields info, licenses, categories, images, and annotations. Image-level metadata record dimensions, file name, URL, capture date, and licence identifier, while annotation entries encode bounding boxes, segmentation masks, keypoints, area, and crowd flags, linked by category and image identifiers.
- LAION-5B (Large-scale Artificial Intelligence Open Network, 5 billion image–text pairs) [13] (https://laion.ai/blog/laion-5b/, accessed on 25 May 2026) comprises 5.85 billion image–text records as Parquet shards enriched with CLIP cosine similarity, NSFW and watermark probability scores, image width and height, source URL, alt-text language identification, and an image hash, enabling subset selection by language, resolution, aesthetic quality, or safety threshold.
- YouTube-8M [14] (https://research.google.com/youtube8m/, accessed on 25 May 2026) provides large-scale video annotation and feature data as TFRecord files containing precomputed frame-level visual and audio embeddings, together with a CSV vocabulary of more than 4800 Knowledge Graph entities organised into 24 thematic verticals. Per-video metadata record the video identifier, duration, and multi-label entity assignments, enabling large-scale video classification, retrieval, and representation learning without requiring access to the raw media.
All three modalities (text, audio, and video datasets) typically include descriptive metadata (title, language, keywords), administrative metadata (licence, ownership, version, provenance) and technical metadata describing file characteristics. However, unlike text datasets, audio and video datasets may be accompanied by semantic annotations supporting retrieval, classification, and machine learning, as well as quality indicators and confidence scores for annotations.
The three modalities present similar challenges for interoperability. Most large-scale datasets define project-specific metadata designs tailored to their intended tasks rather than adopting common metadata standards. As a result, equivalent concepts such as temporal segments, quality measures and provenance are represented differently across datasets, limiting cross-resource integration and reuse.
Taken together, these examples indicate that, although individual resources have developed internally consistent metadata conventions, there is no unified representational framework. The naming, granularity and structure of metadata categories differ substantially between resources, even when they describe comparable data (e.g., document language, source, licence, quality). Metadata schemata are even more varied across modalities, which impedes the systematic cross-resource integration, comparison and reuse of large-scale linguistic resources.
2.2. Metadata Management
The database technologies used to store and query dataset metadata are particularly important for efficiency and integration in various applications. However, the surveyed collections are predominantly released as file-based resources using various metadata formats: JSONL, Parquet, XML, CoNLL-U Plus, HDF5, TFRecord, CSV, TSV.
Exceptions include the Million Song Dataset, which uses a SQLite database alongside its HDF5 feature files, and, to some extent, ParlaMint, MARCELL, and CURLICAT, which are primarily distributed in file formats but are available through CLARIN repositories that provide query interfaces (Korp, NoSketchEngine, etc.) backed by corpus databases.
Historically, relational databases have been a common choice for representing and storing metadata, typically built on PostgreSQL, MySQL, or distributed NewSQL stores such as MySQL Cluster. Metadata are managed either as a first-class object alongside the data they describe [15] or through shared-nothing distributed back ends to overcome the scalability limits of single-node implementations [16].
NoSQL document-oriented databases offer schema flexibility, native support for nested and semi-structured records, and horizontal scalability. This approach is particularly well suited to settings in which metadata categories are heterogeneous, evolve over time, or accompany large collections of diverse data, where rigid relational schemata would impose excessive maintenance overhead [17]. However, these advantages are less compelling when metadata conform to a well-defined and relatively stable information model.
In large-scale dataset management, metadata management at the level of data lakes and lakehouse catalogues offers significant advantages. Large volumes of heterogeneous raw data are stored in object stores such as Amazon S3, while a dedicated catalogue layer maintains structural, descriptive, and provenance metadata to support efficient discovery and querying. Industrial-scale systems demonstrate that such catalogues combine relational and key–value storage, automated metadata extraction, and schema evolution support [18]. Sawadogo and Darmont [19] present a methodological survey systematising architectural choices, metadata typologies, and functional requirements.
Linked Data represent metadata as RDF triples expressed through shared ontologies and queried via SPARQL endpoints, with the goal of making resources discoverable and interoperable across institutional and disciplinary boundaries. This paradigm has been particularly developed for linguistic resources, where dedicated vocabularies and workflows have been consolidated into a coherent methodological framework [20]. More recent work has further demonstrated how fragmented language-resource metadata can be harmonised into unified RDF representations [21].
In recent years, growing attention has been devoted to knowledge graphs and graph databases, in which entities and their relationships are represented natively as nodes and typed edges using property-graph engines such as Neo4j or RDF triple stores, and queried using languages such as Cypher or SPARQL. These representations are particularly well suited to highly interconnected metadata, where traversals and pattern-matching queries can be expressed concisely and executed efficiently [22]. The same paradigm has also been extended to FAIR semantic publishing infrastructures for research datasets [23].
In summary, metadata management for large-scale data follows a trajectory from the relational paradigm, through the descriptive richness of data-lake catalogues, to the modelling of inter-resource and inter-category relationships using graph-based representations.
3. Motivation and Objectives of the Present Model
The principal challenges that arise in the design of metadata organisation and management can be grouped into the following interrelated dimensions:
- (i)
- Metadata design and descriptive coverage: the definition of metadata through a set of categories that is sufficient to accommodate metadata for a diversity of data modalities, types, and provenance contexts encountered in practice, and to capture metadata entries that are equivalent but named differently across resources.
- (ii)
- Expressive power and semantic integration: the capacity to represent and exploit relationships between metadata entries, both internally and through the integration of external resources such as ontologies, terminological databases, and controlled vocabularies, so as to support semantically informed retrieval and reasoning.
- (iii)
- Storage and processing efficiency: the storage and management technologies appropriate to the intended applications, ensuring that the application can sustain the range of ingestion, update, and query workloads required for routine cataloguing and on-demand dataset extraction.
- (iv)
- Flexibility and scalability: the ability of the metadata design and the underlying technical implementation to accommodate metadata for new resource types, evolving descriptive requirements, and growth in data volume without structural redesign.
- (v)
- Access and interoperability: the provision of well-defined access levels and interfaces that enable integration into larger infrastructures and direct use in downstream natural language processing and artificial intelligence applications, including the training and fine-tuning of large language models.
A range of metadata schemata aim to provide general or interoperable standards for resource description, including Dublin Core for general-purpose bibliographic and digital-object metadata [24], the TEI Guidelines for the encoding of textual resources [6], and the Component MetaData Infrastructure (CMDI), developed within CLARIN for language resources [25], among others. In practice, however, none of these has achieved universal adoption, owing to a combination of factors: the heterogeneity of resource types and disciplinary requirements, the granularity mismatch between general-purpose and domain-specific descriptors, and the cost of retrofitting collections. More recent examples of standardisation efforts specifically tailored to datasets used in machine learning and NLP are MIFA (Metadata, Incentives, Formats, and Accessibility) [26], which provides guidelines for describing and sharing bioimage datasets intended for training AI models, and Croissant [27], a JSON-LD-based metadata standard designed specifically for machine learning datasets that has been integrated into platforms such as Hugging Face, Kaggle, OpenML, and Google Dataset Search.
An additional requirement, increasingly recognised in current practice, is the incorporation of external knowledge resources, including ontologies, terminological databases, controlled vocabularies, and other semantic resources that establish both hierarchical and non-hierarchical relations among metadata fields, and provide greater semantic expressiveness, since such resources enable consistent annotation, cross-collection alignment, and semantically informed retrieval that purely descriptive metadata cannot support on their own.
A recent illustration of this integrative trend is the Metadata Enrichment Model proposed by Ignatowicz et al. [28], which combines fine-tuned computer vision models, large language models, and structured knowledge graphs to enrich the metadata of digitised cultural heritage collections, demonstrating how neural representations and explicit semantic resources can be jointly mobilised to overcome the limitations of either approach in isolation.
The present model builds on the principles established in the compilation of the Bulgarian National Corpus (BulNC) [29,30] (https://dcl.bas.bg/bulnc/, accessed on 25 May 2026), a large reference corpus of Bulgarian (approx. 240,000 text samples) with document-level metadata, organised into administrative, editorial, structural, descriptive, classificatory, analytical, and statistical categories, some of which are linked by hierarchical and other relations.
Key features guiding the design and management of metadata include the heterogeneity of the underlying data, the semantic richness and fine-grained interlinking of metadata categories, and the need for flexible, selective data extraction to support the training and fine-tuning of large language models. Accordingly, the model presented in this work adopts a graph-based metadata organisation as its core representation, allowing metadata categories and their semantic relationships to be modelled explicitly while facilitating domain-specific, application-oriented dataset extraction across heterogeneous data collections.
4. Main Characteristics of the Metadata Model
The proposed approach organises metadata as a typed property graph, making graph representation the core abstraction for metadata management. In this representation, the principal metadata categories are modelled as node types, semantic relationships as typed edges, and supplementary metadata as node properties. This organisation naturally captures the rich semantic interconnections among metadata entities and enables flexible, application-oriented extraction of data subsets from heterogeneous collections.
At a descriptive level, the metadata are organised into three classes of categories: obligatory categories, which must be assigned a value for every data unit; data-specific obligatory categories, which are mandatory for particular data unit types; and optional categories, whose values are populated where possible by extraction from the original source, by automated heuristics, or by post hoc data analysis. In all cases, values may be discrete, continuous or free-text, may be represented using numerical, textual, or Boolean data types.
Further, the metadata categories fall into seven broad types, which together provide a comprehensive description of each data unit. Administrative metadata capture information related to the management and curation of the resource, such as identifiers, processing history and access to the data entries. Editorial metadata record the provenance of the entry, including its source, date of acquisition, licensing terms and version. Structural metadata describe the internal organisation of the resource and the relationships among its constituent parts. Descriptive metadata characterise its content through titles, summaries, keywords and other content-oriented indicators. Classification metadata assign the resource to categories defined by taxonomies or ontologies, such as genre, style and domain. Analytical metadata report the results of linguistic, acoustic, visual or other automated analyses applied to the resource. Statistical metadata summarise quantitative properties of the entry, such as size, length, frequency counts or distributional measures derived from its content.
Obligatory categories are usually restricted to those for which a value can in principle be determined for any entry, regardless of modality, provenance, or processing history. They typically belong to the administrative, editorial, and structural types of metadata, which together establish the identity, origin, and basic structure of the data unit, without which the unit cannot be located, lawfully reused, or meaningfully compared with others.
Data-specific obligatory categories are mandatory only for particular data types, modalities or application domains, e.g., audio-related metadata for speech data, such as speaker, date of recording, etc.
Optional categories, by contrast, encompass the descriptive, classification, analytical and statistical types of metadata, whose population depends on the presence of particular data in the original source, on analytical procedures and tools that can be applied to enrich the data, or on the needs of the specific application context. Their absence does not compromise the basic identifiability of the unite or its intended use in standard scenarios.
Within the proposed typed property graph model, selected metadata categories are modelled as nodes, while complementary descriptive attributes are stored as node properties. Directed, typed edges capture the semantic relationships between nodes, reflecting real-world dependencies among metadata entities. Together, these relationships form hierarchical structures, such as domain and genre taxonomies, and non-hierarchical associations, including links to source resources and temporal relationships.
For example, William Shakespeare is a value of the category Author and is represented as a node of type Author, while Science is a node of type Domain. Relationships are represented by directed edges, e.g., Science HAS_SUBDOMAIN Chemistry and Chemistry IS_SUBDOMAIN_OF Science. Both nodes and relationships are typed and can store properties represented by key–value pairs (e.g., properties of nodes labelled DataUnit include Identifier: value; DocumentTitle: value; PublicationDate: value, etc.).
To evaluate the proposed metadata model, we applied it to the IfGPT dataset (https://ifgpt.dcl.bas.bg/en/ifgpt-dataset-en/, accessed on 25 May 2026). The metadata were organised as the content of the nodes in a metadata graph, comprising the following categories:
- DataUnit: a node type representing the metadata of a textual unit. It carries document-specific properties, including Identifier, DocumentTitle, PublicationDate, URL, etc.), the per-sentence analytical vectors PersonallyIdentifiableInformation and BiasedInformation, and is connected to other nodes carrying information about the DataUnit.
- Author: a node type storing the name of the author and, where available, optional biographical categories such as period of activity, principal language and primary professional role.
- Language: a node type for different language codes that facilitates the management of multilingual datasets.
- Domain: a node type representing a subject area drawn from a controlled taxonomy comprising 45 top-level domains and more than 150 subdomains. The hierarchical organisation of the taxonomy is expressed through the relationships between Domain nodes.
- Style, Type, Medium: representing, respectively, the stylistic register of the document (such as legal, journalistic, administrative, or scientific), its genre (such as book, journal article, administrative document, or news report), and medium (written, spoken), all drawn from controlled vocabularies and instantiated once per distinct value so that documents sharing the same register, genre, or medium are attached to the same node.
- Source: a node type representing the publishing organisation, media outlet, web platform, or other institutional originator from which the document was acquired, linked to SourceType nodes (representing various source categories such as newspaper, journal, repository, broadcaster, etc.).
- Licence: a node type representing the licensing regime under which the document is distributed, identified by name and by a classification of permitted use (open, attribution-only, non-commercial, restricted, etc.), with an optional URL pointing to the full text of the licence; in addition, each licence is automatically mapped to one of two broader categories, free or restricted, defined as a node LicenceCategory, which supports rapid filtering of the collection at retrieval time according to the licensing requirements of the downstream application.
- TranslatedDocument: a node type comprising information about the originals of translated data entries.
- TaskCategory: a node type representing various LLM and NLP tasks for which the DataUnit is suitable.
- Year: a node type representing a calendar reference and instantiated once per distinct value in the collection. Data units attached to a Year node can be retrieved together through a single traversal.
Relationships between the nodes are represented as directed edges, each capturing a single, semantically distinct connection, as shown in Table 1.
Table 1.
Relation types in the metadata graph schema, with the principal direction between connected node types.
The two analytical categories PersonallyIdentifiableInformation and BiasedInformation stored in the metadata are represented as per-sentence vectors (the array of values is aligned to the list of sentences in the data file stored in the data layer) rather than as a generalised document-level summary statistics. This preserves the internal distribution of the property across the document (instead of collapsing them into a document-level measure) and allows downstream applications to filter or weight sentences individually.
Graph representation offers several important advantages, the most significant being the ability to model relationships that connect metadata (nodes) via edges. Other key features of graphs include flexibility, meaning they can model a wide variety of relations such as directed and undirected relationships and weighted connections; support for integration from multiple sources; and scalability, meaning they can handle very large datasets with billions of nodes and edges. Graph representation helps identify hidden structures, capture complex relationships, discover clusters, highlight nodes that are “important” by being linked to many other nodes, and detect cycles. Finally, graph representation allows straightforward storage and traversal in graph databases, which can retrieve connected data more efficiently than traditional relational databases.
The typed property graph of metadata can be handled in different formats, such as XML or JSON; however, for fast and efficient retrieval, a graph database is the most suitable option.
5. Application for Proof-of-Concept
To demonstrate the feasibility and practical utility of the proposed metadata graph model, an application has been implemented for the management of metadata associated with the IfGPT Dataset, a large dataset of textual data in Bulgarian intended for the training and fine-tuning of large language models [31].
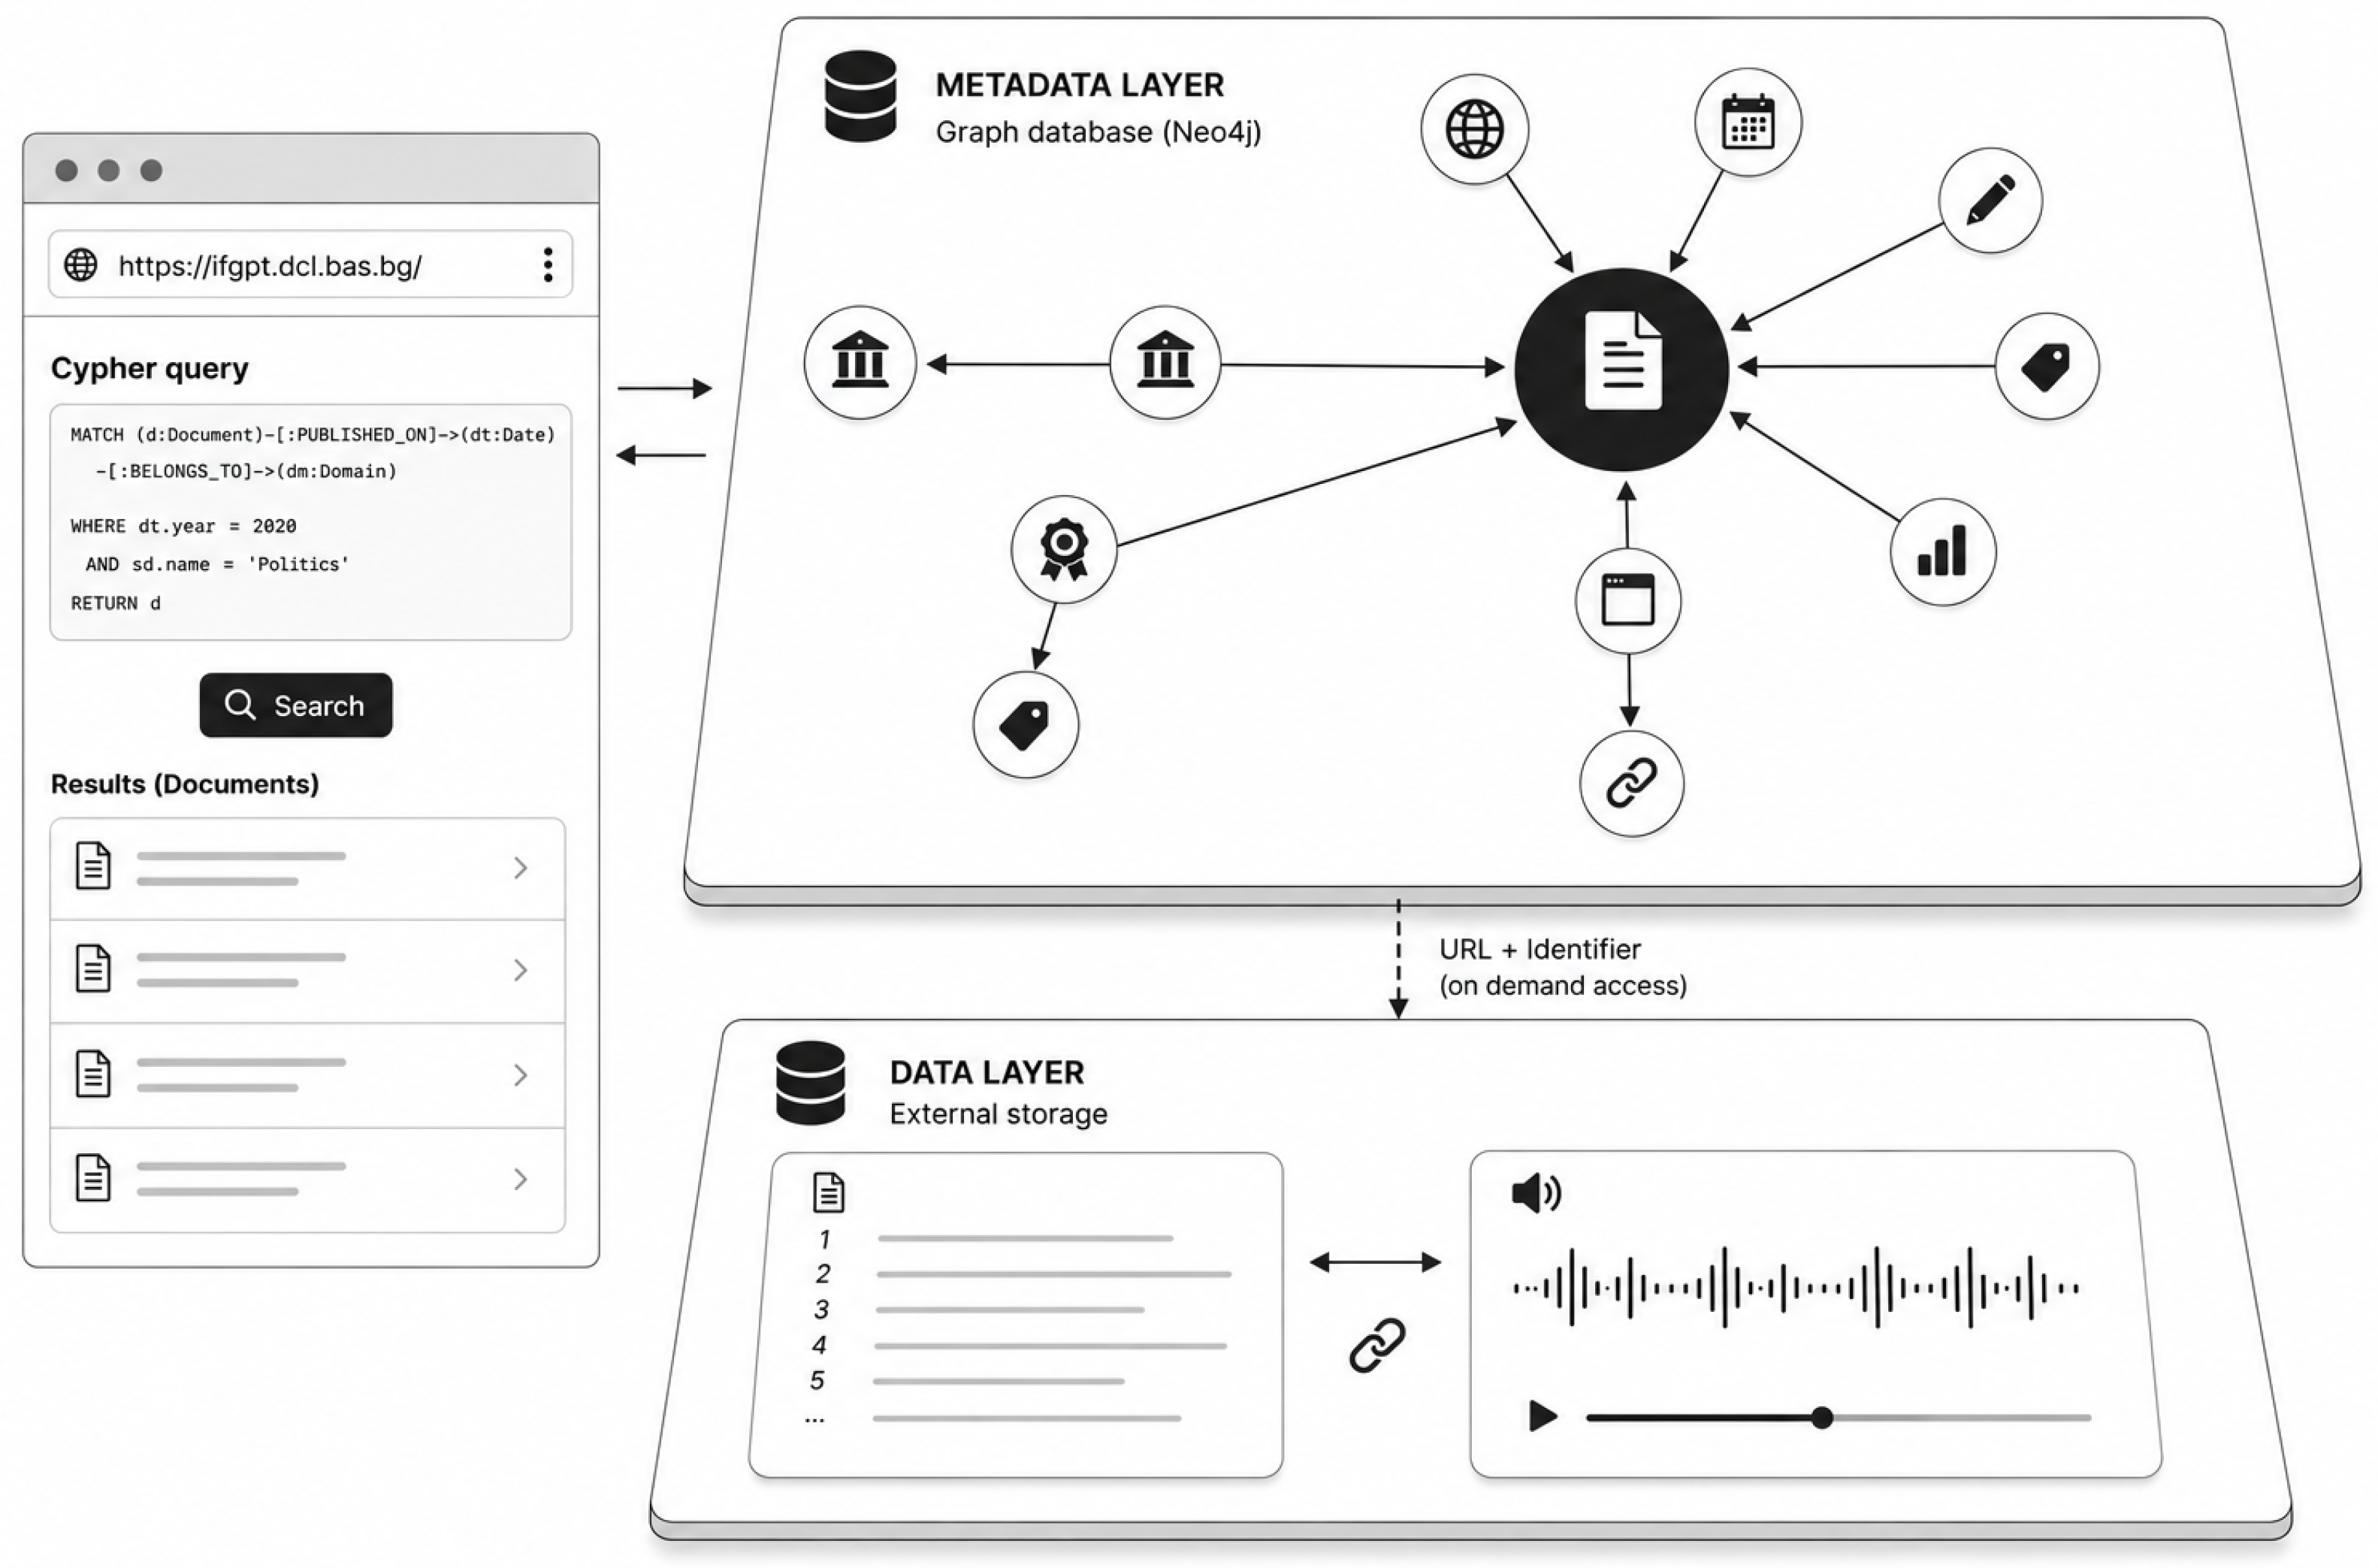
For efficient access and dataset management, we consider two separate layers: (i) the metadata, a description of each dataset unit; and (ii) the data, processed and converted into a unified format suitable for various tasks. The data reside in a separate storage layer (on a server) and are accessed through URLs recorded in the metadata. The work presented here focuses on the metadata layer, which is organised as a typed property graph and managed in a Neo4j graph database. This separation of the two layers is essential for the implementation: the graph engine handles only metadata values and their relationships, never raw content. This improves efficiency, since raw data, which are usually large and more costly to access, are retrieved only on demand for the final result dataset filtered by the metadata. Figure 1 illustrates the general principles of layered dataset management. The data processing is discussed in Koeva et al. [32] and Koeva and Stoyanova [31].
Figure 1.
Architecture of the dataset management.
5.1. Organisation and Management of Metadata in a Graph Database
The metadata are organised and managed in the Neo4j graph database (https://neo4j.com/, accessed on 25 May 2026), where multiple node types are connected through relationships that capture the semantic dependencies among metadata categories.
The resulting metadata graph offers a flexible representation that supports both the extraction of specialised subsets from the overall collection of textual data and a range of analytical tasks. These include traversing category hierarchies (e.g., domain taxonomies), computing distributions across time periods or domains, and analysing the distribution of metadata categories and their values throughout the collection.
The adoption of a graph database for managing metadata associated with large data collections offers several advantages over relational or document-oriented alternatives. Relationships among metadata categories are represented as first-class objects, which allows both hierarchical (taxonomic) and non-hierarchical (associative or descriptive) structures to be modelled natively rather than reconstructed through joins or nested elements. The schema can be enriched incrementally with new categories and new types of relations without migrating existing data, which is particularly valuable in the context of evolving research and application requirements and large volumes of heterogeneous data.
The graph database supports the efficient addition of new node and relationship types without restructuring the existing graph or migrating previously stored data. For example, if new domains need to be added to the hierarchy, they are integrated via the SUBCATEGORY_OF relationship, which links a domain to its parent domain. In this way, a hierarchical domain classification is maintained, and the metadata can accommodate new domains and subdomains without restructuring the database.
In the application, the metadata model is implemented in the graph database through a set of node types, each characterised by an appropriate set of properties (Table 2).
Table 2.
Node types with their properties in the graph database.
The capacity of the graph database to accommodate metadata evolution without migrating existing data was demonstrated through the introduction of the LicenceCategory node type and the HAS_LICENCE_CATEGORY relationship, which were added after the database had been initially populated. The aim was to support efficient filtering by broad licence category without enumerating individual licence variants in every query. The addition required only the creation of two LicenceCategory nodes (representing free and restricted licence categories) and the establishment of HAS_LICENCE_CATEGORY relationships from each existing Licence node. No modification of the DataUnit nodes or of the pre-existing LICENSED_WITH relationships was necessary, and queries that did not refer to the new category continued to execute unchanged.
The graph database comprises metadata for 689,645 text documents, accordance with the schema introduced above. These documents cover texts of 878.6 million words. Authors, domains, licences, sources, styles, types, and task categories are modelled as separate node types, so that recurrent values are stored once and shared across documents.
New documents are incorporated into the dataset by creating corresponding document nodes, whose properties include the URLs identifying the locations where the data units are stored, and by establishing directed relationships to existing or newly created nodes representing domains, authors, sources, licences, and other associated metadata.
If the dataset is extended to include multilingual data, a node type Language can be introduced, together with an IS_WRITTEN_IN relationship from a DataUnit node to a Language node. The introduction of the Language node also enables an IS_TRANSLATED_FROM relationship, which represents translation relationships between documents.
5.2. Web Interface
The Neo4j graph database supports declarative querying through the Cypher language [33], which allows complex retrieval tasks to be expressed through intuitive patterns that closely reflect the underlying graph structure. This makes the language particularly accessible to domain experts who are not necessarily trained in database programming, while remaining expressive enough to support sophisticated retrieval logic.
Within the proposed application, the model supports the extraction of subdatasets based on combinations of structural, descriptive, and analytical criteria, the computation of comparative and distributional metadata statistics, and the application of specialised graph algorithms, including community detection, centrality measures, shortest-path traversal, and similarity-based clustering. Such operations are natively supported by graph database engines, often through dedicated algorithmic libraries, and can be composed with retrieval queries to define analytical pipelines that would otherwise require external processing.
A further advantage lies in query performance for the multi-hop traversal patterns typical of the proposed model. Traversal of an edge in a property graph database is an operation of approximately constant complexity with respect to the size of the database, since adjacent nodes are reached through direct pointers rather than through index lookups over the global relation. Equivalent operations in a relational database, when expressed as recursive join operations, incur a cost that grows rapidly with the depth of the traversal, as each level adds a further join over potentially large tables. This performance gap has been documented empirically in comparative studies [34,35].
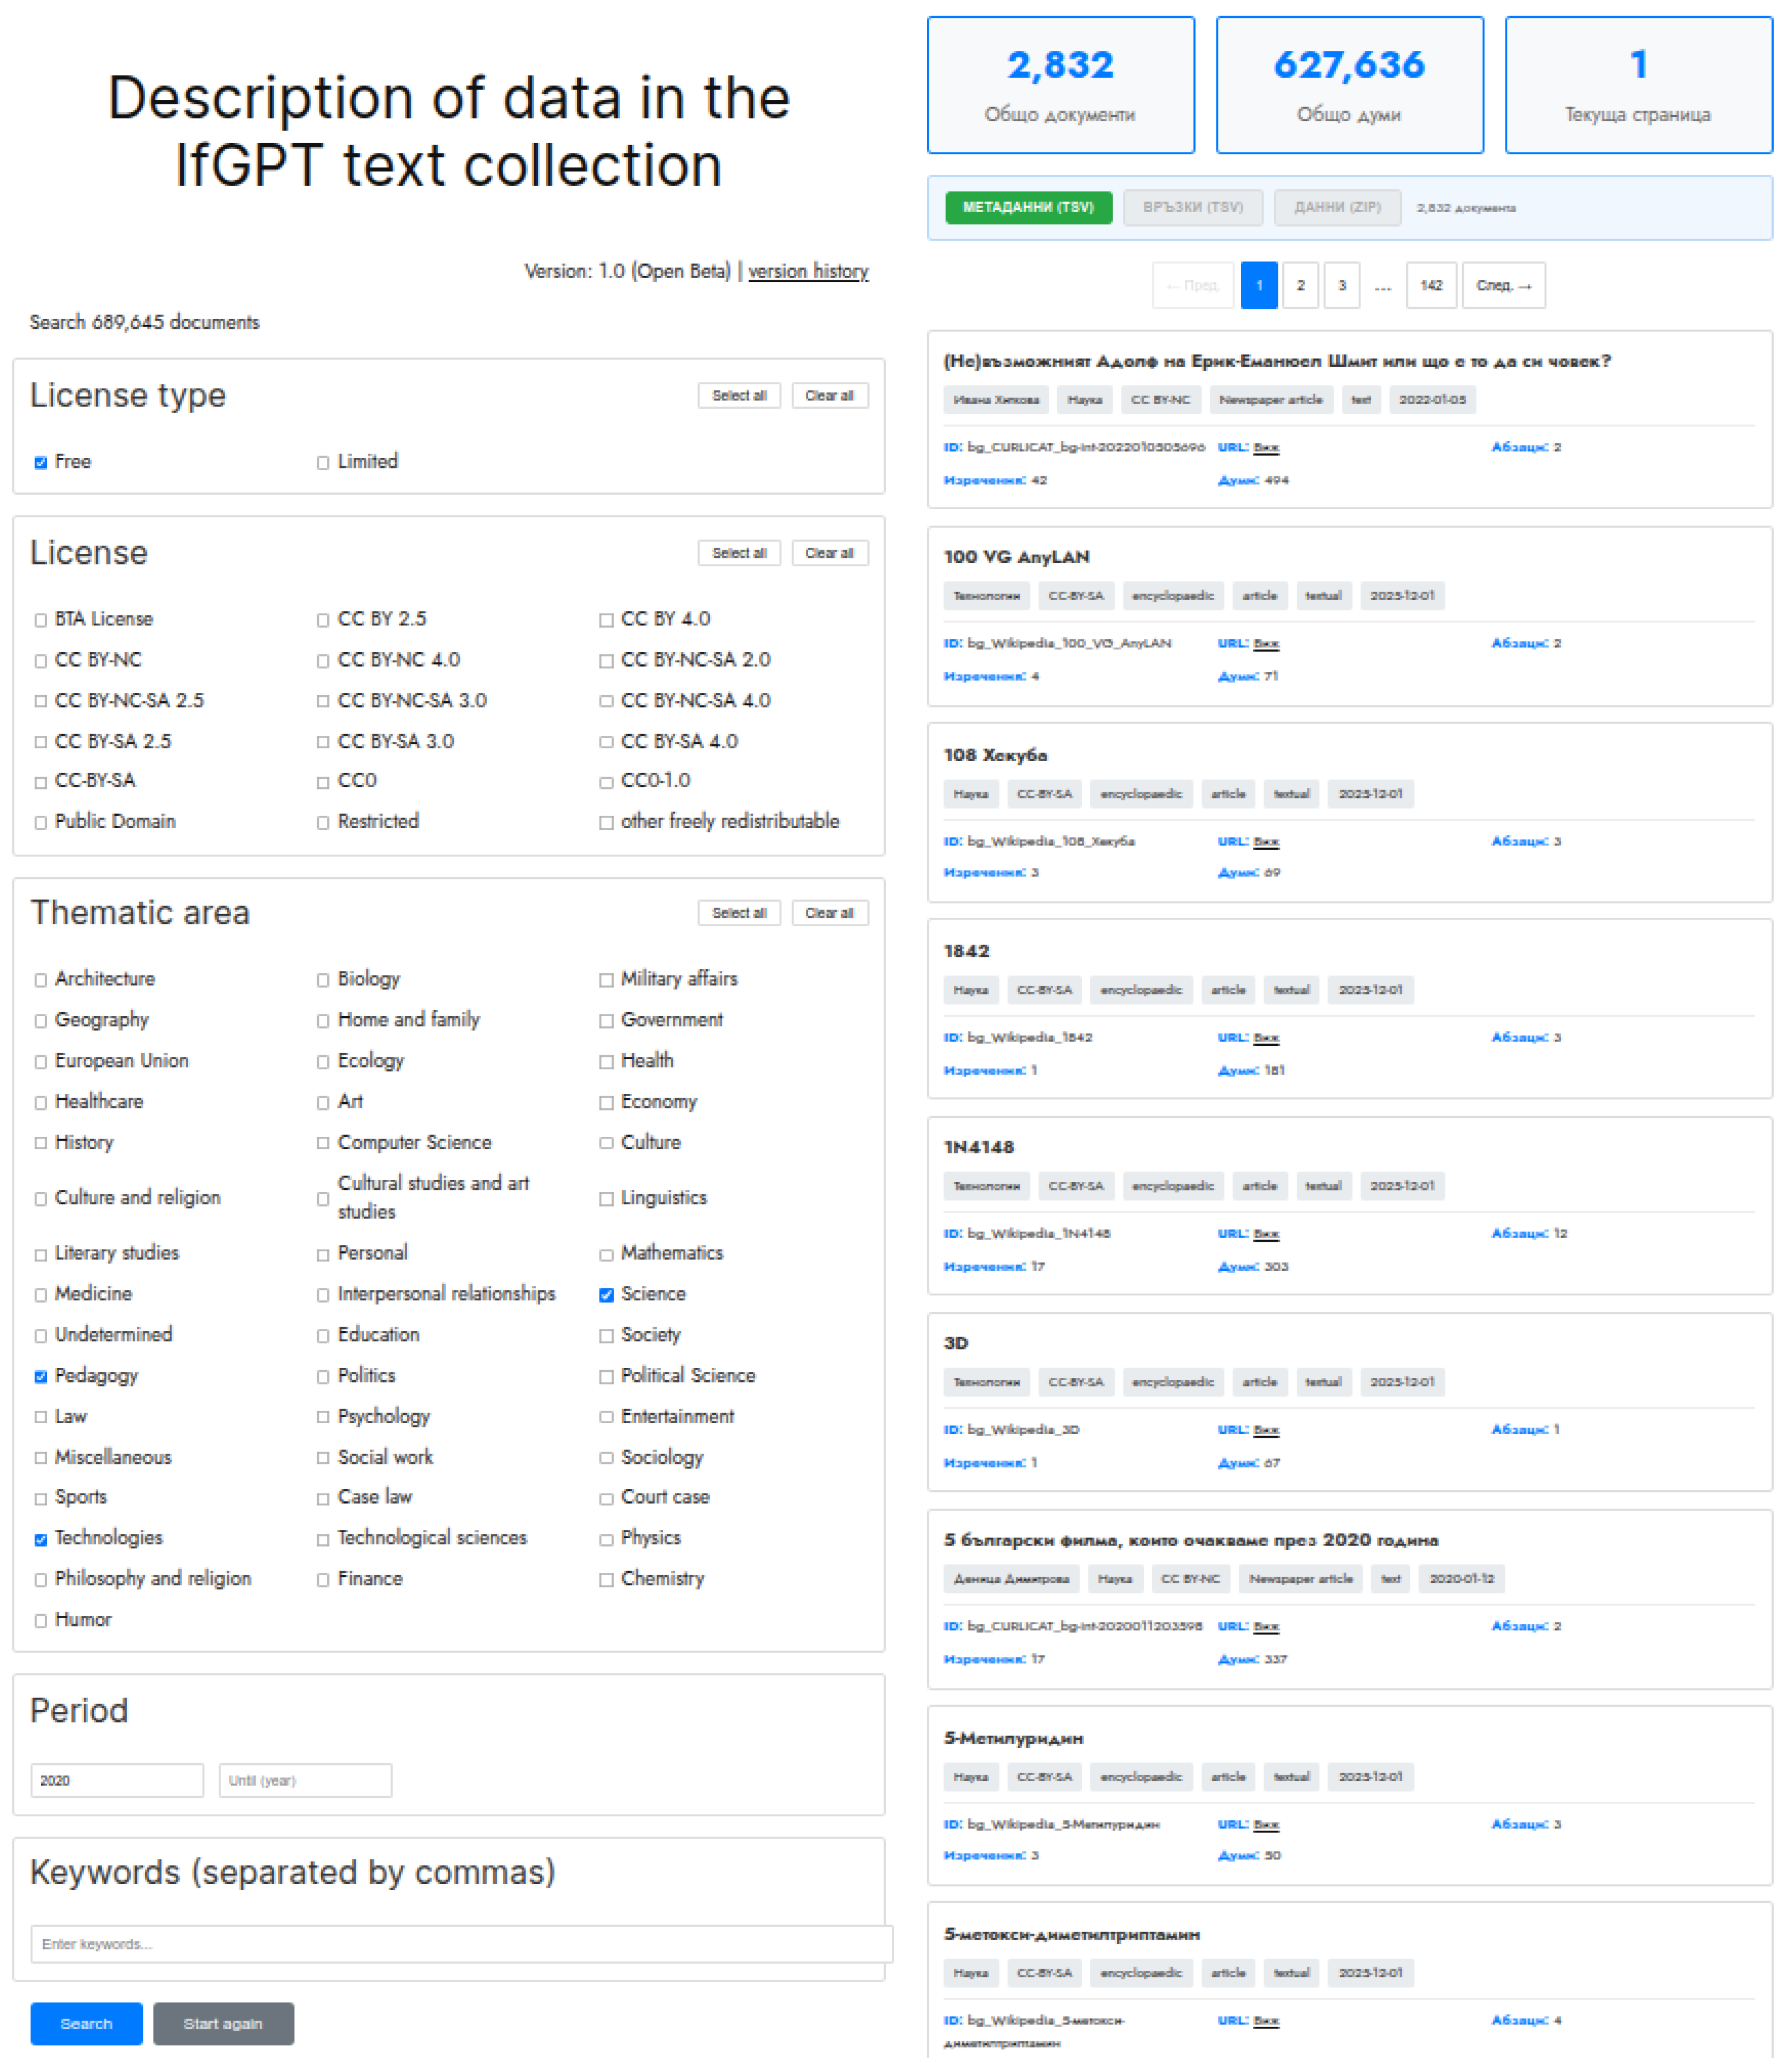
The application includes a web interface that allows users to access the graph database to view the complete collection of document metadata, and to search for and retrieve subsets of data based on the metadata system.
The application is intended for users of LLMs and LLM-related datasets, with a focus on Bulgarian. The queries supported by the system reflect the selection patterns that typically arise in this setting: assembling domain-specific subdatasets for continued pre-training; selecting stylistically or generically homogeneous subsets for fine-tuning; filtering training material by licence to comply with redistribution constraints.
Four filtering mechanisms are currently available.
- Licence filter. Users can restrict results by licence type, selecting either general or specific licences, for example all Creative Commons licences or specific licences, as well as categories such as open licences or restrictive licences.
- Domain filter. Documents can be filtered by selecting one or more domains. The graph database also allows for the addition of more complex search and filtering functions via logical operations (and, or, not), which are not implemented in the initial application.
- Filter by time period. Users can specify a range of publication years by entering a start and/or end year to limit the results to a specific period (if one of the limits is omitted, the corresponding default value is applied, the earliest or latest year in the database). It is possible to implement more complex queries (two or more periods), as well as more precise time ranges (by month or specific date) for cases where the text items contain more detailed metadata.
- Keyword filter. Free-text search is supported for multiple keywords, entered as a comma-separated list. In the application, keyword search covers various text fields in the metadata such as the title, author, domains and subdomains, and other relevant metadata categories.
The search results are displayed as a paginated list of documents, with each text item showing the document title, domain tags, licence, document type, publication date, source, link to the original source and quantitative characteristics (number of paragraphs, sentences and words).
The interface offers three options for downloading the results:
- a full description of the metadata for the selected documents in TSV format;
- a list of links to the original sources in TSV format;
- full-text data as a ZIP archive, upon confirmation of the details and agreement to the terms of use, including the restrictions imposed by the individual licences of the original documents.
The search web interface and the results from the search are shown in Figure 2.
Figure 2.
Search interface of the application (https://ifgpt.dcl.bas.bg/ifgpt-dataset/, accessed on 25 May 2026).
5.3. A Simple Evaluation of the Graph Database
To assess the feasibility of the application and the practical performance of the graph-based representation, a set of representative Cypher queries was designed and executed against the populated database. The queries span several selectivity cases of growing complexity and are intended to give an indicative rather than exhaustive overview of the model’s behaviour.
Direct empirical comparisons with a relational baseline (for example, PostgreSQL with an equivalent normalised schema) are beyond the scope of the present study. The principal advantages of the model concern the expressiveness of the metadata representation and the use of graph traversals to support multi-criterion retrieval patterns required for the compilation of specialised datasets, rather than a uniform speed advantage over alternative paradigms. The choice of a graph database over other approaches is based on reported findings that relational systems remain competitive for queries that involve few joins and shallow relationships, whereas graph databases offer measurable advantages on multi-hop traversals that would require recursive joins or many nested subqueries [34,35].
Test case 1: Low complexity: single-criterion retrieval over a disjunctive set of values, evaluating the performance of a domain-filtering traversal. (Some values in the queries are shown in English for simplicity, while the original values are in Bulgarian).
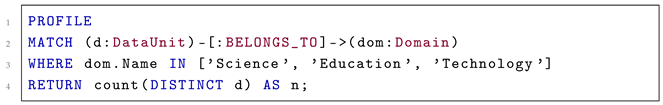
The query locates three Domain nodes through an index seek over the Domain.Name property and traverses the incoming BELONGS_TO relationships to return 91,636 distinct documents. The query completes in a median time of 99 ms (across three executions) with 274,917 database hits, of which the dominant cost is the expansion of the BELONGS_TO edges (91,639 database hits) and the subsequent label-filter step that confirms the matched nodes (183,272 database hits). This is the expected behaviour for a graph database with an indexed property on the Domain node: most of the work directly contributes to the answer through edge traversals, and the cost is proportional to the size of the result rather than to the total size of the collection.
Test case 2: Moderate complexity: two-criterion retrieval combining the domain filter from Test Case 1 with a disjunctive licence filter.
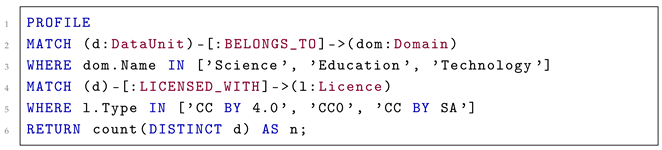
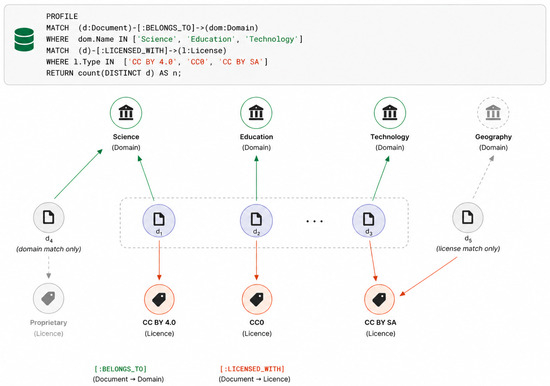
The query reaches the three Domain nodes through an index seek, expands the incoming BELONGS_TO relationships to retrieve the 91,636 candidate documents identified in Test Case 1, then expands forward through the LICENSED_WITH relationships and filters by licence type to return 71,605 distinct documents. The query completes in a median time of 144 ms (across three executions), with 837,546 database hits. The dominant additional cost relative to Test Case 1 is the expansion of the LICENSED_WITH edges (200,897 database hits) and the licence-type filter (361,732 database hits). The total cost is proportional to the size of the intermediate set rather than to the total size of the collection, and the addition of a second filtering criterion increases the cost by approximately a factor of 3 in database hits and 1.5 in time. This confirms that multi-criterion graph retrieval scales with the size of the intermediate result rather than with the depth of the query.
Test case 3: Moderate complexity: three-criterion retrieval combining the domain and licence filters from Test case 2 with a publication-date range.
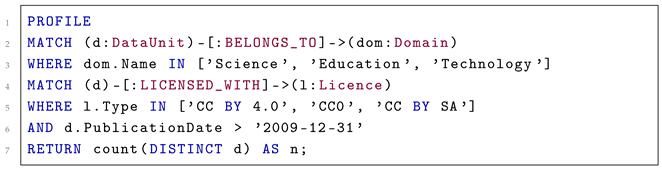
The query introduces a third filtering criterion in the form of a range predicate on the PublicationDate property of the DataUnit node. With a B-tree index defined on this property, the query planner reorders execution and now anchors the traversal in the date-range index rather than in the Domain index used in Test cases 1 and 2: a NodeIndexSeekByRange operator returns the 397,641 documents published from 2010 onwards, which are then expanded through BELONGS_TO and filtered by domain, and subsequently through LICENSED_WITH and filtered by licence type. The query returns 50,424 distinct documents satisfying all three criteria, completing in a median time of 537 ms (across three executions) with 2,090,476 database hits. The cost increase relative to Test case 2 is concentrated in the initial index-range scan and the subsequent domain expansion (397,142 database hits) and filter (933,358 database hits), reflecting the fact that the date range alone selects a large candidate set that is only progressively narrowed by the additional filters. This illustrates a general property of multi-criterion retrieval in a graph database, where the absolute cost is sensitive to the selectivity of the operator chosen by the planner as the starting point of the traversal.
Test case 4: High complexity: four-criterion retrieval extending Test case 3 with a keyword search distributed over several text fields of the metadata, representing the typical pattern of compiling a thematically focused subset where the topic of interest is more narrow than the specified domains.
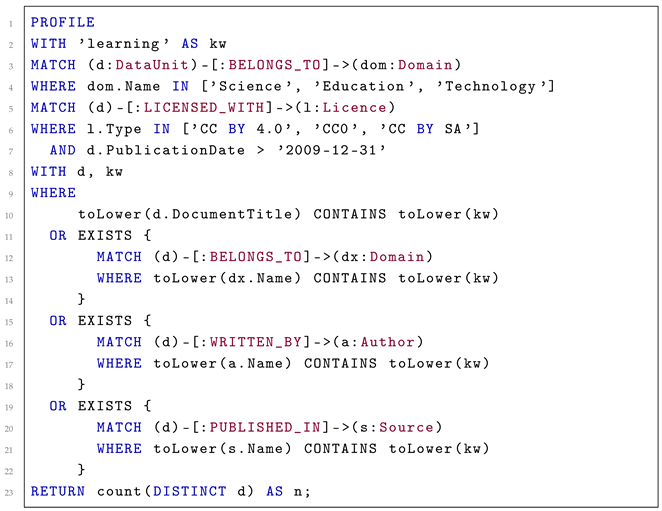
The query takes the candidate set produced by the three filters of Test case 3 and intersects it with a keyword search across five text fields associated with each DataUnit node: the document title, and the names of the connected Domain, Author, and Source nodes reached through the corresponding edges. The search is expressed as a disjunctive condition and is implemented as a combination of a property-level CONTAINS predicate on the DataUnit node and four EXISTS subqueries for the neighbouring nodes. The query returns 53 distinct documents completing in a median time of 763 ms (across three executions, with a cold-cache first run of 1967 ms) and 2,242,016 database hits. The cost increase relative to Test case 3 is modest (a factor of 1.4 in time and only 1.07 in database hits, i.e., approximately a 7% increase in storage access). This pattern reflects the way the graph engine evaluates the disjunction: most of the data required for the keyword evaluation are already in cache after the earlier expansions, so the additional cost is dominated by the CPU evaluation of the CONTAINS predicates and the existence checks, rather than by further storage access.
This case closely resembles a realistic multi-faceted user query in an LLM-oriented dataset compilation workflow. An equivalent query in a relational database would require a set of UNION-connected subqueries, each performing the appropriate sequence of joins across the underlying tables, while the SQL planner must reason about the disjunction across all join paths, and the resulting plan is typically less efficient than a single coherent traversal. The Cypher query above, by contrast, expresses the same retrieval logic in a form that mirrors the structure of the data, and the graph engine handles the disjunction natively through its SelectOrSemiApply operator.
Figure 3 illustrates the principles of a two-criterion search modelled as a graph traversal using the BELONGS_TO relationships and the LICENSED_WITH relationships (Test case 2).
Figure 3.
Cypher traversal for the two-criterion query (Test case 2).
The metadata are instantiated in a Neo4j graph database accessible through a Cypher-based web interface that supports the extraction of domain-specific and application-oriented subdatasets according to combinations of selective criteria.
The implementation confirms that the proposed approach scales to realistic volumes of metadata, supports the expressive retrieval queries required in practice, and integrates with external semantic resources (e.g., ontology of domains) without modification of the underlying schema, thereby validating the principal design advantages of the model.
6. Advantages of the Model
The principal advantages of the model, as demonstrated by the application, are as follows:
- 1.
- Expressive representation of relationships. The model captures the rich relationships between the descriptive characteristics of textual documents (domain, licence, source, author, keywords, etc.), making the resulting metadata more expressive for representing and querying data units across heterogeneous data collections.
- 2.
- Hierarchical and non-hierarchical structures. The graph database allows a natural representation of the complex hierarchical and non-hierarchical relationships between the metadata categories of data units.
- 3.
- Retrieval through graph traversals. Complex queries are formulated and executed as graph traversals, ensuring effective extraction of subsets and comparative analyses.
- 4.
- Extensibility of the metadata model. New node types and relationship types can be introduced without modifying the overall description schema or migrating existing data.
- 5.
- Cross-modal applicability. The metadata model is designed to accommodate large datasets across textual, audio, image, video and multimodal collections, rather than being restricted to a single modality, as is the case for most existing resources.
- 6.
- Orientation towards LLM and AI applications. The schema includes metadata categories relevant to LLM development (ratings for personally identifiable information, ratings for biased content, licence link and licence type, and information on applicability to various categories of automated tasks), which makes it suitable both for the construction of training and fine-tuning datasets and for other applications in the field of artificial intelligence.
A short survey on the usability of the application was conducted among 21 students, researchers and IT specialists working on LLM development and use. The survey was carried out by Nayden Naydenov as part of the project “Infrastructure for Fine-tuning Pre-trained Large Language Models” (https://ifgpt.dcl.bas.bg/ifgpt-dataset/, accessed on 25 May 2026). Participants assessed the dataset and its web interface along several dimensions, including data quality, documentation, metadata coverage, structure and usability, yielding an average rating of 4.33/5 for the quality of the data and access functions. The respondents identified access to large-scale Bulgarian textual data (81%) and curated data selection (76%) as the principal advantages.
7. Conclusions
The proposed model for the representation, description, and management of metadata using a typed property graph implemented in a graph database, together with its support for the extraction of specialised subdatasets based on combinations of structural, descriptive, and analytical criteria, is suitable for industrial applications in LLM development, artificial intelligence, and other data-intensive systems, as well as for a broad range of research and development activities.
The proposed application serves as a proof of concept, demonstrating the applicability of the graph-based metadata model in a low-resource setting. It is validated on a large collection of Bulgarian textual data, where the graph-based representation enables the construction of specialised subdatasets according to diverse selection criteria. The metadata model can readily be extended with additional modality-specific and domain-specific categories, making it applicable to heterogeneous data collections. The application is suitable for compiling datasets for the pre-training and fine-tuning of LLMs, including multimodal models, as well as for retrieval-augmented generation (RAG) and other NLP applications for Bulgarian.
The graph-based metadata model has been developed in accordance with the FAIR principles for the management of research data [36], ensuring that the units of the underlying collection are Findable, Accessible, Interoperable, and Reusable, both individually and as part of the collection as a whole.
8. Limitations
The graph database application reported in this paper is subject to several limitations.
Evaluation of advantages of the Neo4j graph database solution. The expected performance advantages of the chosen storage paradigm are supported by published comparative studies rather than by a direct empirical benchmark conducted on the present dataset. Published benchmarks indicate that the relative performance of graph and relational systems depends strongly on the workload profile: relational systems retain advantages for aggregation-intensive and OLAP-style queries [34,37], while graph databases typically offer performance advantages for multi-hop traversal and pattern-matching workloads [34,35]. The queries that motivate the present model fall predominantly into the latter category, but a direct comparison with PostgreSQL or a comparable relational baseline on the IfGPT dataset itself has not yet been performed.
Scalability. The evaluation was conducted on a single database instance and at a moderate scale. The methodology did not examine performance under heavy workloads or at larger document volumes, where edge-traversal performance may degrade. Informal observations on the extended database suggest that the traversal cost of the most common query patterns remains approximately linear in the size of the candidate set rather than in the size of the full collection. A systematic scaling study at this and larger sizes is an objective of future work.
Limitations of the presented application. The current implementation is limited to Bulgarian textual data. Although the metadata schema and the graph-based representation are designed to be independent of language and data modality, their applicability to datasets in additional languages, modalities (e.g., audio, image, video and multimodal data), and source collections has not yet been validated experimentally.
Human evaluation of the application. The web interface was assessed through a small online survey of 21 respondents representing the principal target audiences of the application. A task-based usability study or a comparative evaluation against established dataset search platforms such as the Hugging Face dataset viewer or the CLARIN repository interfaces is left for future work.
Taking these limitations into account, the paper describes an application that is functionally suitable for the use case: the compilation of specialised subdatasets from large heterogeneous text collections for a low-resource language such as Bulgarian. Its validation at larger scales, under heavier workloads, and against alternative paradigms remains the subject of further investigation.
Author Contributions
Conceptualization, S.K.; methodology, S.K. and I.S.; software, I.S.; investigation, S.K. and I.S.; resources, S.K. and I.S.; writing: original draft preparation, review and editing, S.K. and I.S.; visualization, I.S.; project administration, S.K. All authors have read and agreed to the published version of the manuscript.
Funding
The work presented here is funded as part of the project “Infrastructure for Fine-tuning Pre-trained Large Language Models”, Grant Agreement No. ПВУ–55 from 12.12.2024/BG-RRP-2.017-0030-C01/.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data presented in the study are openly available in Hugging Face (https://huggingface.co/datasets/DCL-IBL/IfGPT-Dataset/, accessed on 25 May 2026) or through the web interface (https://ifgpt.dcl.bas.bg/ifgpt-dataset/, accessed on 25 May 2026).
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Abadji, J.; Ortiz Suárez, P.; Romary, L.; Sagot, B. Towards a Cleaner Document-Oriented Multilingual Crawled Corpus. In Proceedings of the 13th Language Resources and Evaluation Conference (LREC), Marseille, France, 20–25 June 2022; pp. 4344–4355. [Google Scholar]
- Nguyen, T.; Van Nguyen, C.; Lai, V.D.; Man, H.; Ngo, N.T.; Dernoncourt, F.; Rossi, R.A.; Nguyen, T.H. CulturaX: A Cleaned, Enormous, and Multilingual Dataset for Large Language Models in 167 Languages. In Proceedings of the Joint International Conference on Computational Linguistics, Language Resources and Evaluation (LREC-COLING), Torino, Italy, 20–25 May 2024; pp. 4226–4237. [Google Scholar]
- Burchell, L.; De Gibert Bonet, O.; Arefyev, N.; Aulamo, M.; Bañón, M.; Chen, P.; Fedorova, M.; Guillou, L.; Haddow, B.; Hajič, J.; et al. An Expanded Massive Multilingual Dataset for High-Performance Language Technologies (HPLT). In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics, Vienna, Austria, 27 July–1 August 2025 (Volume 1: Long Papers); Che, W., Nabende, J., Shutova, E., Pilehvar, M.T., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2025; pp. 17452–17485. [Google Scholar] [CrossRef] [Scilit]
- Erjavec, T.; Ogrodniczuk, M.; Osenova, P.; Ljubešić, N.; Simov, K.; Pančur, A.; Rudolf, M.; Kopp, M.; Barkarson, S.; Steingrímsson, S.; et al. The ParlaMint corpora of parliamentary proceedings. Lang. Resour. Eval. 2022, 57, 415–448. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Erjavec, T.; Kopp, M.; Ljubešić, N.; Kuzman, T.; Rayson, P.; Osenova, P.; Ogrodniczuk, M.; Çöltekin, Ç.; Koržinek, D.; Meden, K.; et al. ParlaMint II: Advancing comparable parliamentary corpora across Europe. Lang. Resour. Eval. 2025, 59, 2071–2102. [Google Scholar] [CrossRef] [Scilit]
- TEI Consortium. TEI P5: Guidelines for Electronic Text Encoding and Interchange. TEI Consortium, Version 4.9.0 ed. 2024. Available online: https://tei-c.org/Vault/P5/4.7.0/doc/tei-p5-doc/en/Guidelines.pdf (accessed on 25 May 2026).
- Váradi, T.; Koeva, S.; Yamalov, M.; Tadić, M.; Sass, B.; Nitoń, B.; Ogrodniczuk, M.; Pęzik, P.; Barbu Mititelu, V.; Ion, R.; et al. The MARCELL Legislative Corpus. In Proceedings of the 12th Language Resources and Evaluation Conference (LREC), Marseille, France, 11–16 May 2020; pp. 3761–3768. [Google Scholar]
- Váradi, T.; Nyéki, B.; Koeva, S.; Tadić, M.; Štefanec, V.; Ogrodniczuk, M.; Nitoń, B.; Pęzik, P.; Barbu Mititelu, V.; Irimia, E.; et al. Introducing the CURLICAT Corpora: Seven-language Domain Specific Annotated Corpora from Curated Sources. In Proceedings of the 13th Language Resources and Evaluation Conference (LREC), Marseille, France, 20–25 June 2022; pp. 100–108. [Google Scholar]
- Gemmeke, J.F.; Ellis, D.P.W.; Freedman, D.; Jansen, A.; Lawrence, W.; Moore, R.C.; Plakal, M.; Ritter, M. Audio Set: An Ontology and Human-Labeled Dataset for Audio Events. In Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), New Orleans, LA, USA, 5–9 March 2017; pp. 776–780. [Google Scholar]
- Panayotov, V.; Chen, G.; Povey, D.; Khudanpur, S. LibriSpeech: An ASR Corpus Based on Public Domain Audio Books. In Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Brisbane, Australia, 19–24 April 2015; pp. 5206–5210. [Google Scholar]
- Bertin-Mahieux, T.; Ellis, D.P.W.; Whitman, B.; Lamere, P. The Million Song Dataset. In Proceedings of the 12th International Society for Music Information Retrieval Conference (ISMIR), Miami, FL, USA, 24–28 October 2011; pp. 591–596. [Google Scholar]
- Lin, T.Y.; Maire, M.; Belongie, S.; Hays, J.; Perona, P.; Ramanan, D.; Dollár, P.; Zitnick, C.L. Microsoft COCO: Common Objects in Context. In Proceedings of the European Conference on Computer Vision (ECCV), Zurich, Switzerland, 6–12 September 2014; pp. 740–755. [Google Scholar]
- Schuhmann, C.; Beaumont, R.; Vencu, R.; Gordon, C.; Wightman, R.; Cherti, M.; Coombes, T.; Katta, A.; Mullis, C.; Wortsman, M.; et al. LAION-5B: An Open Large-Scale Dataset for Training Next Generation Image–Text Models. In Proceedings of the 36th International Conference on Neural Information Processing Systems (NeurIPS), New Orleans, LA, USA, 28 November–9 December 2022; pp. 25278–25294. [Google Scholar]
- Abu-El-Haija, S.; Kothari, N.; Lee, J.; Natsev, P.; Toderici, G.; Varadarajan, B.; Vijayanarasimhan, S. YouTube-8M: A Large-Scale Video Classification Benchmark. arXiv 2016, arXiv:1609.08675. [Google Scholar]
- Pinoli, P.; Ceri, S.; Martinenghi, D.; Nanni, L. Metadata management for scientific databases. Inf. Syst. 2019, 81, 1–20. [Google Scholar] [CrossRef] [Scilit]
- Niazi, S.; Ismail, M.; Grohsschmiedt, S.; Ronström, M.; Haridi, S.; Dowling, J. HopsFS: Scaling Hierarchical File System Metadata Using NewSQL Databases. In Proceedings of the 15th USENIX Conference on File and Storage Technologies (FAST’17), Santa Clara, CA, USA, 27 February–2 March 2017; pp. 89–104. [Google Scholar]
- He, J.; Wang, F.; Ren, H. The Metadata Management Based on MongoDB for EAST Experiment. Fusion Eng. Des. 2023, 195, 113896. [Google Scholar] [CrossRef] [Scilit]
- Halevy, A.; Korn, F.; Noy, N.F.; Olston, C.; Polyzotis, N.; Roy, S.; Whang, S.E. Goods: Organizing Google’s Datasets. In Proceedings of the 2016 ACM SIGMOD International Conference on Management of Data, San Francisco, CA, USA, 26 June–1 July 2016; pp. 795–806. [Google Scholar] [CrossRef] [Scilit]
- Sawadogo, P.N.; Darmont, J. On Data Lake Architectures and Metadata Management. J. Intell. Inf. Syst. 2021, 56, 97–120. [Google Scholar] [CrossRef] [Scilit]
- Cimiano, P.; Chiarcos, C.; McCrae, J.P.; Gracia, J. Linguistic Linked Data: Representation, Generation and Applications; Springer: Cham, Switzerland, 2020. [Google Scholar] [CrossRef] [Scilit]
- Liang, Z. Harmonizing Metadata of Language Resources for Enhanced Querying and Accessibility. arXiv 2025. [Google Scholar] [CrossRef] [Scilit]
- Ulrich, H.; Kock-Schoppenhauer, A.-K.; Duhm-Harbeck, P.; Ingenerf, J. Using Graph Tools on Metadata Repositories. In German Medical Data Sciences: A Learning Healthcare System; Studies in Health Technology and Informatics; IOS Press: Amsterdam, The Netherlands, 2018; Volume 253, pp. 55–59. [Google Scholar] [CrossRef] [Scilit]
- Abu Ahmad, R.; D’Souza, J.; Zloch, M.; Otto, W.; Rehm, G.; Oelen, A.; Dietze, S.; Auer, S. Toward FAIR Semantic Publishing of Research Dataset Metadata in the Open Research Knowledge Graph. arXiv 2024. [Google Scholar] [CrossRef] [Scilit]
- DCMI Usage Board. DCMI Metadata Terms. Available online: https://www.dublincore.org/specifications/dublin-core/dcmi-terms/ (accessed on 25 May 2026).
- Broeder, D.; Windhouwer, M.; Van Uytvanck, D.; Goosen, T.; Trippel, T. CMDI: A Component Metadata Infrastructure. In Proceedings of the Describing LRs with Metadata: Towards Flexibility and Interoperability in the Documentation of LR, Workshop at LREC 2012, Istanbul, Turkey, 22 May 2012; pp. 1–4. [Google Scholar]
- Zulueta-Coarasa, T.; Jug, F.; Mathur, A.; Moore, J.; Muñoz Barrutia, A.; Babalola, K.; Bankhead, P.; Gilloteaux, P.; Gogoberidze, N.; Jones, M.; et al. MIFA: Metadata, Incentives, Formats, and Accessibility Guidelines to Improve the Reuse of AI Datasets for Bioimage Analysis. arXiv 2023. [Google Scholar] [CrossRef] [Scilit]
- Akhtar, M.; Benjelloun, O.; Conforti, C.; Foschini, L.; Gijsbers, P.; Giner-Miguelez, J.; Goswami, S.; Jain, N.; Karamousadakis, M.; Krishna, S.; et al. Croissant: A Metadata Format for ML-Ready Datasets. In Proceedings of the Eighth Workshop on Data Management for End-to-End Machine Learning (DEEM ’24); Curran Associates, Inc.: New York, NY, USA, 2024; Volume 37, pp. 1–6. [Google Scholar] [CrossRef] [Scilit]
- Ignatowicz, J.; Kutt, K.; Nalepa, G.J. Position Paper: Metadata Enrichment Model: Integrating Neural Networks and Semantic Knowledge Graphs for Cultural Heritage Applications. arXiv 2025. [Google Scholar] [CrossRef] [Scilit]
- Koeva, S.; Stoyanova, I.; Leseva, S.; Dimitrova, T.; Dekova, R.; Tarpomanova, E. The Bulgarian National Corpus: Theory and Practice in Corpus Design. J. Lang. Model. 2012, 1, 65–110. [Google Scholar] [CrossRef] [Scilit]
- Koeva, S.; Stoyanova, I.; Todorova, M.; Leseva, S.; Dimitrova, T. Metadata extraction, representation and management within the Bulgarian National Corpus. In Proceedings of the 4th Workshop on Challenges in the Management of Large Corpora, Portorož, Slovenia, 28 May 2016; pp. 33–39. [Google Scholar]
- Koeva, S.; Stoyanova, I. IfGPT, a Large Dataset Representing Bulgarian, with the Bulgarian National Corpus as Its Core. In Proceedings of the 12th Workshop on Challenges in the Management of Large Corpora (CMLC-12) @ LREC 2026; Bański, P., Knight, D., Kupietz, M., Witt, A., Wróblewska, A., Eds.; Language Resources Association (ELRA): Palma de Mallorca, Spain, 2026; pp. 12–24. [Google Scholar]
- Koeva, S.; Stoyanova, I.; Kralev, J. IfGPT: A Dataset in Bulgarian for Large Language Models. In Proceedings of the 1st Workshop on Advancing NLP for Low-Resource Languages (LowResNLP), associated with the International Conference RANLP 2025, Varna, Bulgaria, 11–13 September 2025; pp. 65–75. [Google Scholar] [CrossRef] [Scilit]
- Francis, N.; Green, A.; Guagliardo, P.; Libkin, L.; Lindaaker, T.; Marsault, V.; Plantikow, S.; Rydberg, M.; Selmer, P.; Taylor, A. Cypher: An Evolving Query Language for Property Graphs. In Proceedings of the 2018 International Conference on Management of Data (SIGMOD ’18), Houston, TX, USA, 10–15 June 2018; pp. 1433–1445. [Google Scholar] [CrossRef] [Scilit]
- Kotiranta, P.; Junkkari, M.; Nummenmaa, J. Performance of Graph and Relational Databases in Complex Queries. Appl. Sci. 2022, 12, 6490. [Google Scholar] [CrossRef] [Scilit]
- Do, T.T.T.; Mai-Hoang, T.B.; Nguyen, V.Q.; Huynh, Q.T. Query-based Performance Comparison of Graph Database and Relational Database. In Proceedings of the 11th International Symposium on Information and Communication Technology, New York, NY, USA, 1–3 December 2022; pp. 375–381. [Google Scholar] [CrossRef] [Scilit]
- Wilkinson, M.D.; Dumontier, M.; Aalbersberg, I.J.; Appleton, G.; Axton, M.; Baak, A.; Blomberg, N.; Boiten, J.W.; da Silva Santos, L.B.; Bourne, P.E.; et al. The FAIR Guiding Principles for Scientific Data Management and Stewardship. Sci. Data 2016, 3, 160018. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Fotache, M.; Teacă, N.; Eşanu, C.S.; Cluci, M.I.; Pinzaru, C.; Gasner, P. Query Performance Comparison of PostgreSQL vs. Neo4j. A Basic Distributed Setup on OpenStack. In Proceedings of the 23rd RoEduNet Conference: Networking in Education and Research (RoEduNet), Bucharest, Romania, 19–20 September 2024; pp. 1–6. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.