


Abstract
We study a single-machine scheduling problem to minimize the total completion time of the given set of jobs, which have to be processed without job preemptions. The lower and upper bounds on the job duration is the only information that is available before scheduling. Exact values of the job durations remain unknown until the completion of the jobs. We use the optimality region for the job permutation as an optimality measure of the optimal schedule. We investigate properties of the optimality region and derive -algorithm for calculating a quasi-perimeter of the optimality set (i.e., the sum of lengths of the optimality segments for n given jobs). We develop a fast algorithm for finding a job permutation having the largest quasi-perimeter of the optimality set. The computational results in constructing such permutations show that they are close to the optimal ones, which can be constructed for the factual durations of all given jobs.
1. Introduction
A lot of real-life scheduling problems involve different forms of uncertainties. For dealing with uncertain scheduling problems, several approaches have been developed in the literature. In a stochastic approach, job durations are assumed to be random variables with the specific probability distributions known before scheduling [1,2]. If there is no sufficient information to determine the probability distribution for each random duration of the given job, other approaches have to be used [3,4,5]. In the approach of seeking a robust schedule [3,6], a decision-maker prefers a schedule that hedges against the worst-case scenario. A fuzzy approach [7,8,9] allows a scheduler to find best schedules with respect to fuzzy durations of the given jobs. A stability approach [10] is based on the stability analysis of the optimal schedules to possible variations of the job durations. In this paper, we apply the stability approach to the single-machine scheduling problem with interval durations of the given jobs.
In Section 2, we present settings of the uncertain scheduling problems, the related literature and closed results. In Section 3, we investigate properties of the optimality region for the job permutation, which is used for processing given jobs. Efficient algorithms for calculating a quasi-perimeter of the optimality region are derived in Section 4. In Section 5, we show how to find a job permutation with the largest quasi-perimeter of the optimality region and develop algorithm for finding an approximate solution for the uncertain scheduling problem. In Section 6, we report on the computational results for finding solutions for the tested instances. The paper is concluded in Section 7.
2. Problem Descriptions, The Related Literature and Closed Results
There is given a set of jobs to be processed on a single machine. The duration of the job can take any real value from the given segment , where the inequalities hold. The exact value of the job duration remains unknown until the completion time of the job .
Let denote a set of all non-negative n-dimensional real vectors, , where is space of n-dimensional real vectors. The set of all vectors of the feasible durations is presented as the Cartesian product of the segments :
A vector of the job durations is called a scenario. Let denote a set of all permutations of the given jobs .
Given a scenario and a permutation , let denote the completion time of the job in the schedule determined by the permutation . The criterion denotes the minimization of the following sum of the completion times:
where the permutation is optimal. From the equality (1), it follows that only semi-active schedule [11] may be optimal. Each permutation determines exactly one semi-active schedule.
The above uncertain scheduling problem is denoted as using the three-field notation [12], where denotes the processing system, characterizes conditions for processing the jobs and determines the criterion.
2.1. The Related Literature
If a scenario is fixed before scheduling (i.e., the equality holds for each job ), then the uncertain problem is turned into the deterministic one . In what follows, we use the notation to indicate an instance of the deterministic problem with scenario . Any instance is solvable in time [13] due to the following necessary and sufficient condition for the optimality of the job permutation .
Theorem 1.
The job permutation is optimal for the instance if and only if the following inequalities hold:
If the strict inequality holds, then the job precedes the job in any optimal job permutation .
Since the scenario is not fixed in the uncertain problem , the completion time of the job cannot be determined for the permutation before completing the job . Thus, the value of the objective function for the permutation remains uncertain until all jobs have been completed. Since for the uncertain problem , there does not usually exist an optimal schedule for all feasible scenarios p from the set T, an additional objective or some agreements are used in the literature.
A robust schedule minimizing the worst-case regret has been developed in [3,8,14,15,16,17,18]. For any permutation and any feasible scenario , the difference is called the regret for the permutation . In the above notation , the objective function is equal to for the permutation under scenario p and the optimal value of the objective function is equal to for the optimal permutation under scenario p. The value of is called the worst-case absolute regret. The value of is called the worst-case relative regret.
While the deterministic problem is polynomially solvable [13], finding a permutation minimizing the worst-case absolute regret or the relative regret for the problem are binary NP-hard even for two possible scenarios [3,17,19]. Discrete sets of the uncertain scenarios have been investigated in [3,17,19].
The complexity of minimizing the total flow time with continues data T is characterized in [20], where it is proven that finding a permutation minimizing the worst-case absolute regret for the problem is binary NP-hard. For a special case of this problem, where all intervals of uncertainty have the same center, it is shown that this problem can be solved in time if the number of jobs is even, and remains NP-hard if the number of jobs is odd [20]. In [6], a branch-and-bound algorithm was developed for finding a permutation minimizing the absolute regret for the problem , where the jobs have different weights . The computational experiments showed that the developed algorithm is able to find such a permutation for the instances with up to 40 jobs.
The fuzzy scheduling technique was used in [7,8,9,21] to develop a fuzzy analogue of dispatching rules or to solve mathematical programming problems to determine a schedule that minimizes a fuzzy-valued objective function.
In [22], several heuristics were developed for the problem . The computational experiments including different probability distributions of the job durations showed that there was at least one heuristic among all performing heuristics with the error of the optimal objective function value obtained after completing the given jobs when their factual durations became known.
2.2. The Stability Approach to Single-Machine Scheduling Problems
Let M denote a subset of the set . In [23,24], an optimality box for the job permutation for the uncertain problem is defined as follows.
Definition 1.
The maximal rectangular box is called an optimality box for the permutation (with respect to T), if the permutation being optimal for the instance with the scenario remains optimal for the instance with any scenario . If there does not exist a scenario such that the permutation is optimal for the instance , it is assumed that .
In Section 3, we use the following remark for the definition of the optimality segment for the job in the permutation .
Remark 1.
Any variation of the duration of the job within the maximal segment indicated in Definition 1 cannot violate the optimality of the permutation provided that the inclusion holds. The non-empty maximal segment indicated in Definition 1 with the inequality and the length is called an optimality segment for the job in the permutation . We denote the optimality segment as follows: .
If the maximal segment indicated in Definition 1 is empty for the job , we say that this job has no optimality segment in the permutation . It is clear that if the job has no optimality segment in the permutation , then the strict inequality holds. In [23,24], it is shown that for calculating the optimality box , one can calculate the optimality box for the modified instance , where the segments for the possible job durations are reduced, , based on the following formulas:
The following theorem has been proven in [24].
Theorem 2.
The optimality box for the permutation for the problem is equal to the optimality box for the same permutation for the problem with the feasible segments , , determined in (3).
In [23], it is shown that Theorem 2 remains correct for the problem with the different weights prescribed to the jobs .
Following [23,24], the notion of a block for the jobs is determined for the problem as follows.
Definition 2.
A maximal subset of the set , for which the inequality holds, is called a lock. The segment , where equalities and hold, is called a core of the block .
The following claim was proven in [23].
Lemma 1.
For the problem , the set of all blocks can be uniquely determined in time.
If the job belongs to a single block, we say that the job is fixed in this block. We say that the block is virtual, if there is no fixed job in this block. We say that the job is non-fixed, if the job belongs to two or more blocks and at least one of these blocks is not virtual.
Remark 2.
Any permutation determines a distribution of all non-fixed jobs to the blocks. Due to such fixings of the positions of the non-fixed jobs, some virtual blocks from the set B may be destroyed for the fixed permutation . Furthermore, the cores of some non-virtual blocks may be increased in the permutation .
Each block in the set B has the following properties proven in [23].
Lemma 2.
At most two jobs in the block may have optimality segments in the permutation .
Lemma 3.
If , then any two jobs and , which are fixed in different blocks, , must be ordered in the permutation with decreasing left bounds (and right bounds as well) of the cores of their blocks, i.e., the permutation looks as follows: , where the inequality holds.
In what follows, we assume that all blocks in the set are numbered according to decreasing left bounds of their cores, i.e., the strict inequality implies the strict inequality . Due to Definition 2, each block may include jobs of the four types as follows.
If and , we say that job is a core job in the block . If , we say that job is a left job in the block . If , we say that job is a right job in the block . Let denote the set of all core jobs. The set (the set ) is the set of all left (right) jobs in the block . Some jobs may be left-right jobs in the block , since it is possible that condition holds.
The jobs and are identical if both equalities and hold. If the set is a singleton, , then the equality holds. The following theorem was proven in [24].
Theorem 3.
For the problem , any permutation has an empty optimality box, , if and only if for each block , either condition holds or condition holds and all jobs in the set (in the set ) are identical and both inequalities and hold.
The following criterion was proven in [23].
Theorem 4.
Let all jobs from the set be fixed in their blocks from the set B. Then the permutation with the largest optimality box may be constructed in time.
The rest of this paper is devoted to an optimality set (it is called an optimality region), which is a superset of the optimality box for the same permutation .
3. The Optimality Region
For the permutation , we formally define the optimality region such that the inclusion holds.
Definition 3.
The maximal closed subset of the set is called the optimality region for the permutation (with respect to T) if the permutation is optimal for the instance with any scenario . If there does not exist a scenario such that the permutation is optimal for the instance , it is assumed that .
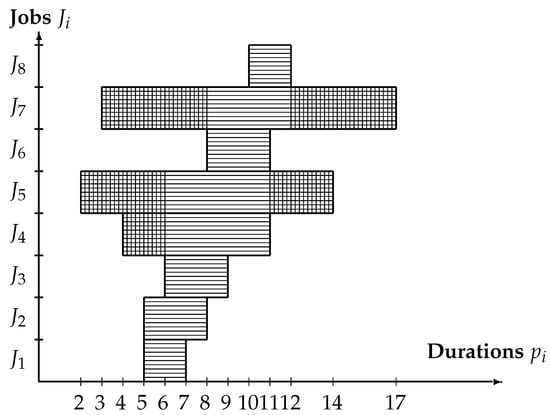
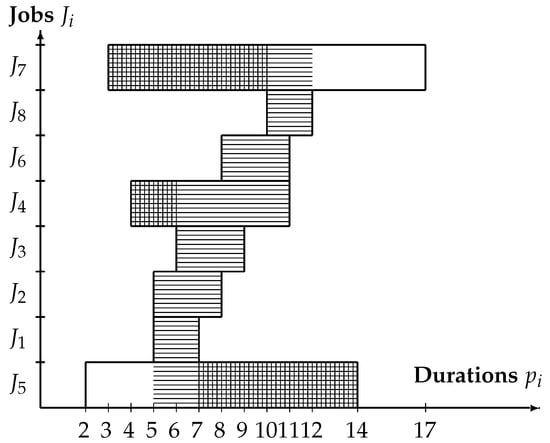
We demonstrate the above definitions and notions on the instance of the problem with jobs. The segments defining all possible durations of the jobs are given in Table 1. The segments of the job durations are also represented in a coordinate system in Figure 1 for the permutation . The abscissa axis indicates the segments determining durations of the jobs. The ordinate axis indicates all jobs . There are three blocks in this instance. The jobs , , , , and belong to the block . The segment is a core of the block . The jobs , , , , and belong to the block . The one-point segment is a core of the block . The jobs , , , and belong to the block . The segment is a core of the block . The jobs , , , , and are non-fixed jobs. The jobs and are fixed in their blocks.
Table 1.
Input data for the instance of the problem .
Figure 1.
The segments of non-optimality (double-shaded) and the segments of conditional optimality (shaded) for the jobs in the permutation .
Due to the optimality criterion (2) for the permutation given in Theorem 1, one can distinguish three types of segments for each job , which characterize a possibility for the permutation to be optimal, namely:
the segment of optimality ;
the segment of conditional optimality ;
and the segment of non-optimality .
The segment of optimality for the job in the permutation is formally determined in Definition 1 and Remark 1.
The segment of non-optimality for the job in the permutation is a maximal (with respect to the inclusion) segment such that for any point , the permutation cannot be optimal for an instance with any scenario . Thus, due to the necessary and sufficient condition (2) for the permutation to be optimal for the instance , we conclude that either there exists a job such that the inequality holds along with the following condition:
or there exists a job such that and the following condition holds:
Furthermore, due to Definition 1, the segment of non-optimality for the job in the permutation has no common point with the open interval of optimality for the job :
In Figure 1, the segments of non-optimality for all jobs in the permutation are double-shaded.
The segment of conditional optimality for the job in the permutation is a maximal (with respect to the inclusion) segment such that each point does not belong to the open interval of non-optimality, , and there exists a job , , with the following inclusion: . Thus, one can conclude that for some points , the permutation is optimal for the instance , where , while for other points , the permutation cannot be optimal for the instance , where .
The segment of conditional optimality for the job in the permutation has no common point with the open interval of optimality and no common point with the open interval of non-optimality :
If the segment of conditional optimality is empty for the job , we say that this job has no conditional optimality in the permutation .
In Figure 1, all segments of conditional optimality for the jobs in the permutation are shaded.
Remark 3.
Due to Theorem 1, for each job in the permutation , there may exist at most one segment of optimality, at most two segments of conditional optimality and at most two segments of non-optimality.
In Figure 1, job has one segment of non-optimality and one segment of conditional optimality . Job has two segments of non-optimality and and one segment of conditional optimality .
The following claim is based on Remark 3 and the above definitions of the segments of optimality, non-optimality and conditional optimality.
Lemma 4.
Each segment of possible durations of the job is the union of the segments of optimality, non-optimality and conditional optimality for the job in the permutation .
We next show that for constructing the optimality region for the permutation , it is sufficient to construct the optimality region for the instance with the reduced segments of job durations: . To construct the reduced segments for the permutation , we use the equalities (9) for all jobs :
We denote One can prove the following claim similarly to the proof of Theorem 2 proven in [24].
Theorem 5.
The optimality region for the permutation for the instance is equal to the optimality region for the same permutation for the instance with the reduced segments of the possible durations of jobs determined in (9).
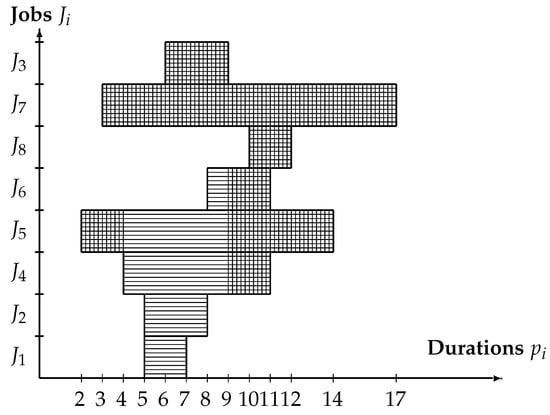
Figure 2 represents the segments of non-optimality and conditional optimality for jobs in the permutation for the instance with the input data T given in Table 1.
Figure 2.
The segments of non-optimality (double-shaded) and the segments of conditional optimality (shaded) for the jobs in the permutation .
From Definition 3 and Theorem 5, one can directly derive the following claim.
Lemma 5.
For the instance with the reduced segments , , of the job durations determined in (9), the open interval of optimality for the job in the permutation has no common point with the segment of possible durations of any job , , i.e., the following equality holds:
We next prove a criterion for the extreme case when the equality holds.
Theorem 6.
The optimality region for the permutation is empty, if and only if there exists at least one job with the inequality in the permutation , which has no segment of optimality and no conditional optimality.
Proof.
Sufficiency. Let there exist a job in the permutation , which has no segment of optimality and no conditional optimality. Due to the inequality and Lemma 4, the relations hold, and either there exists a job such that and the condition (4) holds or there exists a job such that and the condition (5) holds.
In the former case, the inequality holds for each duration of the job and for each duration of the job . In the latter case, the inequality holds for each duration of the job and for each duration of the job .
Due to Theorem 1, in both cases the permutation cannot be optimal for the instance with any scenario . Hence, the optimality region for the permutation is empty: . Sufficiency is proven.
Necessity. We prove necessity by a contradiction. Let the equality hold. However, we assume that there is no job with the inequality in the permutation , which has no segment of optimality and no conditional optimality.
Due to Definition 3, the equality means that there is no scenario such that the permutation is optimal for the instance with the scenario p.
However, we show next how to construct a scenario with the inclusion . If the segment of optimality of the job in the permutation is not empty, then there exists a point . We choose the value of as the duration of the job .
If the segment of optimality of the job in the permutation is empty, then due to the above assumption, the segment of conditional optimality for the job in the permutation is not empty. We choose the value of as the duration of the job , i.e., . Thus, we determine the scenario . From the equalities (7) and (8) and Lemma 5 with the equality (10), it follows that the permutation is optimal for the instance with the scenario . Thus, and the relations hold contradicting to our assumption that . The proof of Theorem 6 is completed. □
From Theorem 6, one can directly derive the following claim.
Corollary 1.
If the condition holds, then the dimension of the optimality region is equal to n.
In Figure 1, there is no job in the permutation , which has no segment of optimality and no conditional optimality. Thus, due to Theorem 6, the optimality region for the permutation is not empty, i.e., .
In Figure 2, for the segment of non-optimality for the job in the permutation , the following equalities hold. Thus, there exists a job in the permutation , which has no segment of optimality and no conditional optimality. Due to Theorem 6, one can conclude that the optimality region for the permutation is empty, i.e., .
We next prove a criterion for another extreme case for the optimality region , namely, we prove the necessary and sufficient condition for the equality when the optimality region is maximally possible.
Theorem 7.
The optimality region for the permutation is maximally possible (i.e., the equality holds), if and only if for each job in the permutation the following equality holds:
Proof.
Sufficiency. Let the equality (11) hold for each job in the permutation .
Due to Definition 1 and Remark 1, the following equalities hold: where . From Definition 1, it follows that the permutation is optimal for the instance with any scenario . Thus, due to Definition 3, we obtain the desired equality . Sufficiency is proven.
Necessity. Let the equality hold. However, we assume that there is a job in the permutation such that the equality (11) does not hold.
Due to Lemma 4, either there exists a segment of non-optimality or a segment of conditional optimality for job in the permutation In the former case, the equality (6) holds. In the latter case, the equality (8) holds.
Thus, in both cases, there exists a scenario , where , such that the permutation is not optimal for the instance with the scenario . Hence, due to Definition 3 we obtain a contradiction with the above assumption. This contradiction completes the proof of Theorem 7. □
In the rest of this paper, we show how to use the above results for solving the uncertain scheduling problem approximately.
4. Algorithms for Calculating a Quasi-Perimeter of the Optimality Region for the Fixed Permutation
We next present Algorithm 1 for testing the equality . If it appears that the optimality region is not empty for the permutation , i.e., , then Algorithm 1 constructs an instance with the reduced segments of possible durations for the jobs .
| Algorithm 1: Construction of the instance with the reduced segments of possible durations |
| Input: The segments for all jobs ; the permutation . Output: The reduced segments for all jobs if .
|
In steps 1, 2, 3 and 6 of Algorithm 1, the equality is tested. If , then the problem with the reduced segments of the feasible durations of the jobs is constructed in steps 2–5. It takes time to realize Algorithm 1.
4.1. A Quasi-Perimeter of the Optimality Region
Due to Theorem 5, the optimality region for the permutation for the problem coincides with the optimality region for the same permutation for the problem with the reduced segments of the feasible durations of the jobs . Therefore, in what follows, we consider the problem instead of the problem .
Definition 4.
A maximal permutation , where and is called a section of the permutation , if for each real number , there exists a job with such that the inclusion holds. The segment is called a scope of the section . The section consisting of a single job, , is called a trivial section.
It is clear that for each fixed permutation , a set of all sections is uniquely determined. Note that index w in the last section coincides with index w of the job , which is the first job in the section of the permutation .
Remark 4.
Definition 4 implies that each job either belongs to a single section of the permutation or this job does not belong to any section of the permutation . Furthermore, if there exists at least one job , which does not belong to any section from the set , then this job has no segment of optimality and no conditional optimality and, due to Theorem 6, the equality holds.
From Remark 4 and Theorem 6, one can derive the following claim.
Corollary 2.
The condition holds if and only if .
If the section is trivial, i.e., the equality holds, then is a scope of the section . If the section is not trivial and , then we partition the scope of the section into the maximal (with respect to the inclusion) semi-intervals of the optimality and conditional optimality:
In the equality (12), the semi-intervals differ one from another in a way such that for different subsets of the set of jobs , where , the inclusion holds for each job . Let denote a permutation of all jobs from the set . Note that the permutation is a part of the permutation , where index i in the permutation coincides with index i of the job , which is the first job in the permutation .
Let the condition hold. We can calculate a quasi-perimeter of the optimality region . We define a quasi-perimeter of the optimality region as a sum of all lengths (cardinalities) of the segments (sets) , where jobs occupy optimal positions in the permutation :
A sum of the lengths (of the cardinalities) for the job in the permutation may be calculated as follows:
where the value of is a length of the segment of the optimality for the job in the permutation . In the equality (14), the value of determines a cardinality of the optimality subset, which is based on a single segment or on both segments and (see Remark 3) of the conditional optimality of the job in the permutation .
To calculate the value of , we use the partition (12) of the scope of the section such that the job belongs to the set determined for the section , i.e., the inequalities hold. Because of the condition , one can conclude (due to remark 4) that there exists a single section containing the job . The value of may be calculated as follows:
The correctness of the equality (15) follows from the fact that the cardinality of the optimality subset for the job , which is based on the semi-interval of the optimality or conditional optimality for the job , is equal to the following fraction:
since, due to Theorem 1, a position of the job may be optimal in the permutation , only if the following inequalities (17) hold:
4.2. How to Calculate a Quasi-Perimeter for the Fixed Permutation
We next demonstrate the above notations and formulas on the calculation of the quasi-perimeter for the permutation presented in Figure 3.
Figure 3.
The segments of optimality, non-optimality (double-shaded) and conditional optimality (shaded) for the jobs in the permutation .
For the permutation , there exists a single section , , with the scope . We obtain the following partition (12) of the scope :
For the obtained nine semi-intervals in the above partition of the scope , the following equalities hold: , , , , , , , , . Using the equality (14), we calculate the optimality set for the job in the permutation as follows:
where the value of is calculated based on the equality (15), namely:
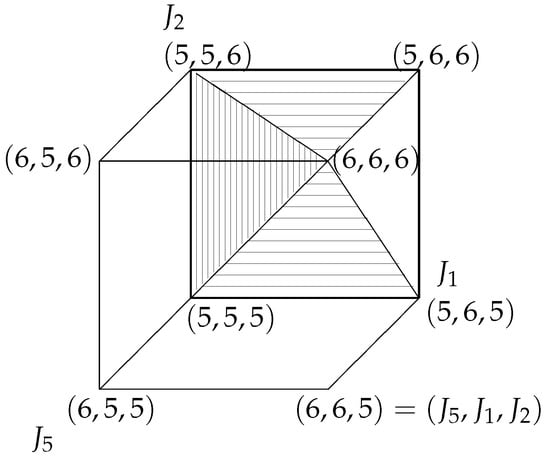
A cardinality of the optimality set is illustrated on Figure 4, where the pyramid of the optimality subset for the job , which is based on the semi-interval for the permutation that is a part of the permutation . The volume of the pyramid is determined by the system of inequalities (17), where , , .
Figure 4.
The pyramid of the optimality subset for the job , which is based on the semi-interval for the permutation that is a part of the permutation .
Similarly, we can calculate the following values: , , , , , , . Using the equality (13), we calculate the quasi-perimeter of the optimality region for the permutation as follows:
It should be noted that the above quasi-perimeter is equal to the length of the scope of the single section of the permutation . The following theorem shows that such an equality is not accidental.
Theorem 8.
If the condition holds, one can calculate the quasi-perimeter of the optimality region for the permutation as follows:
where is a length of the scope of the section .
Proof.
Due to Corollary 2, the above condition implies the equality Therefore, the following equality also holds:
where denotes a quasi-perimeter of the optimality region for the section . Let denote a quasi-perimeter of the optimality region for the permutation of all jobs from the set .
For calculating the quasi-perimeter of the optimality region , we will use a summation of the values through all jobs in the permutation . Thus, instead of the formulas (13)–(15), we use the equality (16) and the equalities (20) and (21):
The equality (20) follows from the above definition of . The equality (21) follows from the definition of . Using the equalities (16) and (21) we obtain
Theorem 8 is proven. □
5. The Largest Quasi-Perimeter of the Optimality Region for the Problem
We call the permutation an effective permutation, if this permutation has the largest quasi-perimeter of the optimality region among all permutations in the set S. The following claim follows directly from Theorem 8.
Corollary 3.
If the following equality holds:
for the permutation , then this permutation is effective.
Since the equality (24) holds for the permutation , one can conclude that this permutation is effective due to Corollary 3.
We next show how to find an effective permutation in the general case of the problem . Similarly to the proof of Theorem 4 given in [23], we can prove the following claim.
Theorem 9.
Let all jobs from the set be fixed in their blocks from the set B. Then the effective permutation may be constructed in time.
Thus, due to Theorem 9, the main problem, which must be solved for the construction of the effective permutation , is the optimal distribution of all non-fixed jobs between the effective sub-permutations of the jobs fixed in the block , those fixed in the block , and so on, those fixed in the block . Let denote a set of all non-fixed jobs of the set . The following lemma shows that we also need to find optimal positions for some fixed jobs of the set in the desired effective permutation .
Theorem 10.
An effective sub-permutation of all jobs, which are fixed in the block , exists if and only if there is no job such that the following conditions hold simultaneously:
Proof.
Hence, there exist at least two different jobs and such that the inequalities and hold. The effective sub-permutation of all jobs, which are fixed in the block looks as follows , where all jobs from the set are located between jobs and and their order may be arbitrary.
Hence, an optimal position of the job is either the first position or the last position in the effective sub-permutation of all jobs, which are fixed in the block . This choice for the job depends from the positions of other such jobs in the blocks in the effective permutation and from the positions of jobs from the set in the effective permutation . □
The following Algorithm 2 is based on Theorem 10.
| Algorithm 2: Construction of the effective permutation of the jobs fixed in the block |
| Input: The segments for all jobs from the set , which are fixed in the block , . Output: The effective sub-permutation of the subset of the set , , which are fixed in the block .
|
The asymptotic complexity of Algorithm 2 is equal to . The set is either empty or contains a single job for which both conditions (25) and (26) hold. The set is either empty or contains a single job for which both conditions and hold.
Let denote a set of all jobs , which are fixed in their blocks and both conditions (25) and (26) hold. The following Algorithm 3 constructs an effective permutation for the general case of the problem .
| Algorithm 3: Construction of the effective permutation |
| Input: The segments for all jobs ; the effective sub-permutations , sets and sets for all blocks . Output: The effective job permutation .
|
6. Computational Results
In the computational experiments, we tested six classes of hard instances . Algorithms 1–3 were coded in C# and tested on a PC with Intel Core (TM) 2 Quad, 2.5 GHz, 4.00 GB RAM. For all tested instances, inequalities hold for all jobs . Table 2 presents computational results for randomly generated instances of the problem with {50, 100, 500, 1000, 5000, 10,000}.
Table 2.
Computational results for randomly generated instances with a single block (class 1).
The segments of possible durations have been randomly generated as follows. An integer center C of the segment was generated using a uniform distribution in the range . The lower bound of the possible duration was determined using the equality where denotes the maximal relative error of the durations due to the given segments . The upper bound was determined using the equality For each job , the point was generated using a uniform distribution in the range . In order to generate instances, where all jobs belonged to a single block, the segments of the possible durations were modified as follows: , where
Since the inclusion holds, each constructed instance contained a single block, . The maximum absolute error of the uncertain durations , , is equal to , and the maximum relative error of the uncertain durations , , is not greater than . We say that these instances belong to class 1.
Three distribution laws were used in our computational experiments to determine the factual durations of the jobs. If inequality holds, then the factual duration of the job becomes known only after completing the job .
We call the uniform distribution as the distribution law with number 1, the gamma distribution with the parameters and as the distribution law with number 2, and the gamma distribution with the parameters , and as the distribution law with number 3. In each instance of class 1, for generating the factual durations for different jobs of the set , the number of the distribution law was randomly chosen from the set . We solved 15 series of the randomly generated instances from class 1. Each series contained 10 instances with the same combination of n and .
In the computational experiments, we answered the question of how large the obtained relative error of the value of the objective function was for the effective permutation with respect to the actually optimal objective function value calculated for the factual durations , which were known after completing all the jobs.
The number n of jobs in the instance is given in column 1 in Table 2. The half of the maximum possible errors of the random durations (in percentage) is given in column 2. Column 3 gives the average error for the effective permutation . Column 4 presents the average CPU-time in seconds. The smallest errors, average errors, largest errors for the tested series of the instances are presented in the last rows of Table 2.
In the second part of our computational experiments, Algorithms 1–3 were applied to randomly generated instances from other classes 2–6 of the problem . We randomly generated non-fixed jobs , which belong to blocks , , …, of the randomly generated fixed jobs. The lower bound and the upper bound on the feasible values of of the durations of the fixed jobs, , were generated as follows.
We determined a bound of blocks for generating the cores of the blocks and for generating the segments for the durations of jobs from all blocks , , .
Each instance in class 2 or in class 3 had a single non-fixed job , whose bounds were determined as follows: . Classes 2 and 3 of the solved instances differed one from another by the numbers of non-fixed jobs and the distribution laws used for choosing the factual durations of the jobs .
Each instance from classes 4 and 5 had two non-fixed jobs. In each instance from classes 2, 4, 5 and 6, for generating the factual durations for the jobs , the numbers of the distribution laws were randomly chosen from the set , and they were indicated in column 4 in Table 3. In the instances of class 6, the cores of the blocks were determined in order to generate different numbers of non-fixed jobs in different instances. The numbers of non-fixed jobs were randomly chosen from the set .
Table 3.
Computational results for randomly generated instances from classes 2–6.
The numbers n of the jobs are presented in column 1 in Table 3. Column 2 represents the number of blocks in the solved instance and column 3 the number of non-fixed jobs. The distribution laws used for determining the factual durations of the jobs are indicated in column 4 in Table 3. Column 6 presents average numbers of the maximal number of the variants of the non-dominated distributions of the jobs in the effective permutation while it was constructed on the iterations of Algorithm 3. Each solved series contained 10 instances with the same combination of n and the other parameters. The obtained smallest, average and largest values of for each series of the tested instances are presented in column 5 in Table 3 at the end of series.
7. Concluding Remarks
The uncertain scheduling problem attracts the attention of the researchers since this problem is applicable in real-life scheduling and is commonly used in many multiple-resource scheduling systems, where one of the available machines is the bottleneck and uncertain machine. The optimal scheduling decisions allow the plant to reduce the costs of productions due to a better utilization of the available machines.
In Section 2, Section 3, Section 4 and Section 5, we used a notion of the optimality region of a job permutation and proved useful properties of the optimality region . We investigated the permutation with the largest quasi-perimeter of the optimality region. Using these properties, we derived algorithms for constructing a job permutation with the largest quasi-perimeter of the optimality region .
From the computational experiments, it follows that the effective permutation is close to the optimal permutation, which can be determined after completing all jobs when their durations became known. We tested classes 1–6 of the problems . The minimal, average and maximal errors of the objective function values were , and , respectively, for the effective permutations.
An attractive direction for a further research is a generalization of the obtained results to the problem , where the given jobs may have different weights. It is also useful to find precedence constraints on the set of jobs such that the effective job permutation may be constructed similarly to Section 5.
Author Contributions
Y.N. proved theoretical results; Y.N. and N.E. jointly conceived and designed the algorithms; N.E. performed the experiments; Y.N. and N.E. analyzed the data; Y.N. wrote the paper.
Funding
This research received no external funding.
Acknowledgments
The authors are grateful to anonymous referees for their useful remarks and suggestions.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Davis, W.J.; Jones, A.T. A real-time production scheduler for a stochastic manufacturing environment. Int. J. Prod. Res. 1988, 1, 101–112. [Google Scholar] [CrossRef] [Scilit]
- Pinedo, M. Scheduling: Theory, Algorithms, and Systems; Prentice-Hall: Englewood Cliffs, NJ, USA, 2002. [Google Scholar]
- Daniels, R.L.; Kouvelis, P. Robust scheduling to hedge against processing time uncertainty in single stage production. Manag. Sci. 1995, 41, 363–376. [Google Scholar] [CrossRef] [Scilit]
- Sabuncuoglu, I.; Goren, S. Hedging production schedules against uncertainty in manufacturing environment with a review of robustness and stability research. Int. J. Comput. Integr. Manuf. 2009, 22, 138–157. [Google Scholar] [CrossRef] [Scilit]
- Sotskov, Y.N.; Werner, F. Sequencing and Scheduling with Inaccurate Data; Nova Science Publishers: Hauppauge, NY, USA, 2014. [Google Scholar]
- Pereira, J. The robust (minmax regret) single machine scheduling with interval processing times and total weighted completion time objective. Comput. Oper. Res. 2016, 66, 141–152. [Google Scholar] [CrossRef] [Scilit]
- Grabot, B.; Geneste, L. Dispatching rules in scheduling: A fuzzy approach. Int. J. Prod. Res. 1994, 32, 903–915. [Google Scholar] [CrossRef] [Scilit]
- Kasperski, A.; Zielinski, P. Possibilistic minmax regret sequencing problems with fuzzy parameters. IEEE Trans. Fuzzy Syst. 2011, 19, 1072–1082. [Google Scholar] [CrossRef] [Scilit]
- Özelkan, E.C.; Duckstein, L. Optimal fuzzy counterparts of scheduling rules. Eur. J. Oper. Res. 1999, 113, 593–609. [Google Scholar] [CrossRef] [Scilit]
- Sotskov, Y.N.; Egorova, N.M.; Lai, T.-C. Minimizing total weighted flow time of a set of jobs with interval processing times. Math. Comput. Model. 2009, 50, 556–573. [Google Scholar] [CrossRef] [Scilit]
- Tanaev, V.S.; Sotskov, Y.N.; Strusevich, V.A. Scheduling Theory: Multi-Stage Systems; Kluwer Academic Publishers: Dordrecht, The Netherlands, 1994. [Google Scholar]
- Graham, R.L.; Lawler, E.L.; Lenstra, J.K.; Rinnooy Kan, A.H.G. Optimization and approximation in deterministic sequencing and scheduling. Ann. Discr. Appl. Math. 1979, 5, 287–326. [Google Scholar]
- Smith, W.E. Various optimizers for single-stage production. Naval Res. Logist. Q. 1956, 3, 59–66. [Google Scholar] [CrossRef] [Scilit]
- Burdett, R.L.; Kozan, E. Techniques to effectively buffer schedules in the face of uncertainties. Comput. Ind. Eng. 2015, 87, 16–29. [Google Scholar] [CrossRef] [Scilit]
- Goren, S.; Sabuncuoglu, I. Robustness and stability measures for scheduling: Single-machine environment. IIE Trans. 2008, 40, 66–83. [Google Scholar] [CrossRef] [Scilit]
- Kasperski, A.; Zielinski, P. A 2-approximation algorithm for interval data minmax regret sequencing problems with total flow time criterion. Oper. Res. Lett. 2008, 36, 343–344. [Google Scholar] [CrossRef] [Scilit]
- Kouvelis, P.; Yu, G. Robust Discrete Optimization and Its Application; Kluwer Academic Publishers: Boston, MA, USA, 1997. [Google Scholar]
- Lu, C.-C.; Lin, S.-W.; Ying, K.-C. Robust scheduling on a single machine total flow time. Comput. Oper. Res. 2012, 39, 1682–1691. [Google Scholar] [CrossRef] [Scilit]
- Yang, J.; Yu, G. On the robust single machine scheduling problem. J. Combin. Optim. 2002, 6, 17–33. [Google Scholar] [CrossRef] [Scilit]
- Lebedev, V.; Averbakh, I. Complexity of minimizing the total flow time with interval data and minmax regret criterion. Discr. Appl. Math. 2006, 154, 2167–2177. [Google Scholar] [CrossRef] [Scilit]
- Harikrishnan, K.K.; Ishii, H. Single machine batch scheduling problem with resource dependent setup and processing time in the presence of fuzzy due date. Fuzzy Optim. Decis. Mak. 2005, 4, 141–147. [Google Scholar] [CrossRef] [Scilit]
- Allahverdi, A.; Aydilek, H.; Aydilek, A. Single machine scheduling problem with interval processing times to minimize mean weighted completion times. Comput. Oper. Res. 2014, 51, 200–207. [Google Scholar] [CrossRef] [Scilit]
- Lai, T.-C.; Sotskov, Y.N.; Egorova, N.G.; Werner, F. The optimality box in uncertain data for minimising the sum of the weighted job completion times. Int. J. Prod. Res. 2018, 56, 6336–6362. [Google Scholar] [CrossRef] [Scilit]
- Sotskov, Y.N.; Egorova, N.M. Single machine scheduling problem with interval processing times and total completion time objective. Algorithms 2018, 75, 66. [Google Scholar] [CrossRef] [Scilit]
- Sotskov, Y.N.; Lai, T.-C. Minimizing total weighted flow time under uncertainty using dominance and a stability box. Comput. Oper. Res. 2012, 39, 1271–1289. [Google Scholar] [CrossRef] [Scilit]
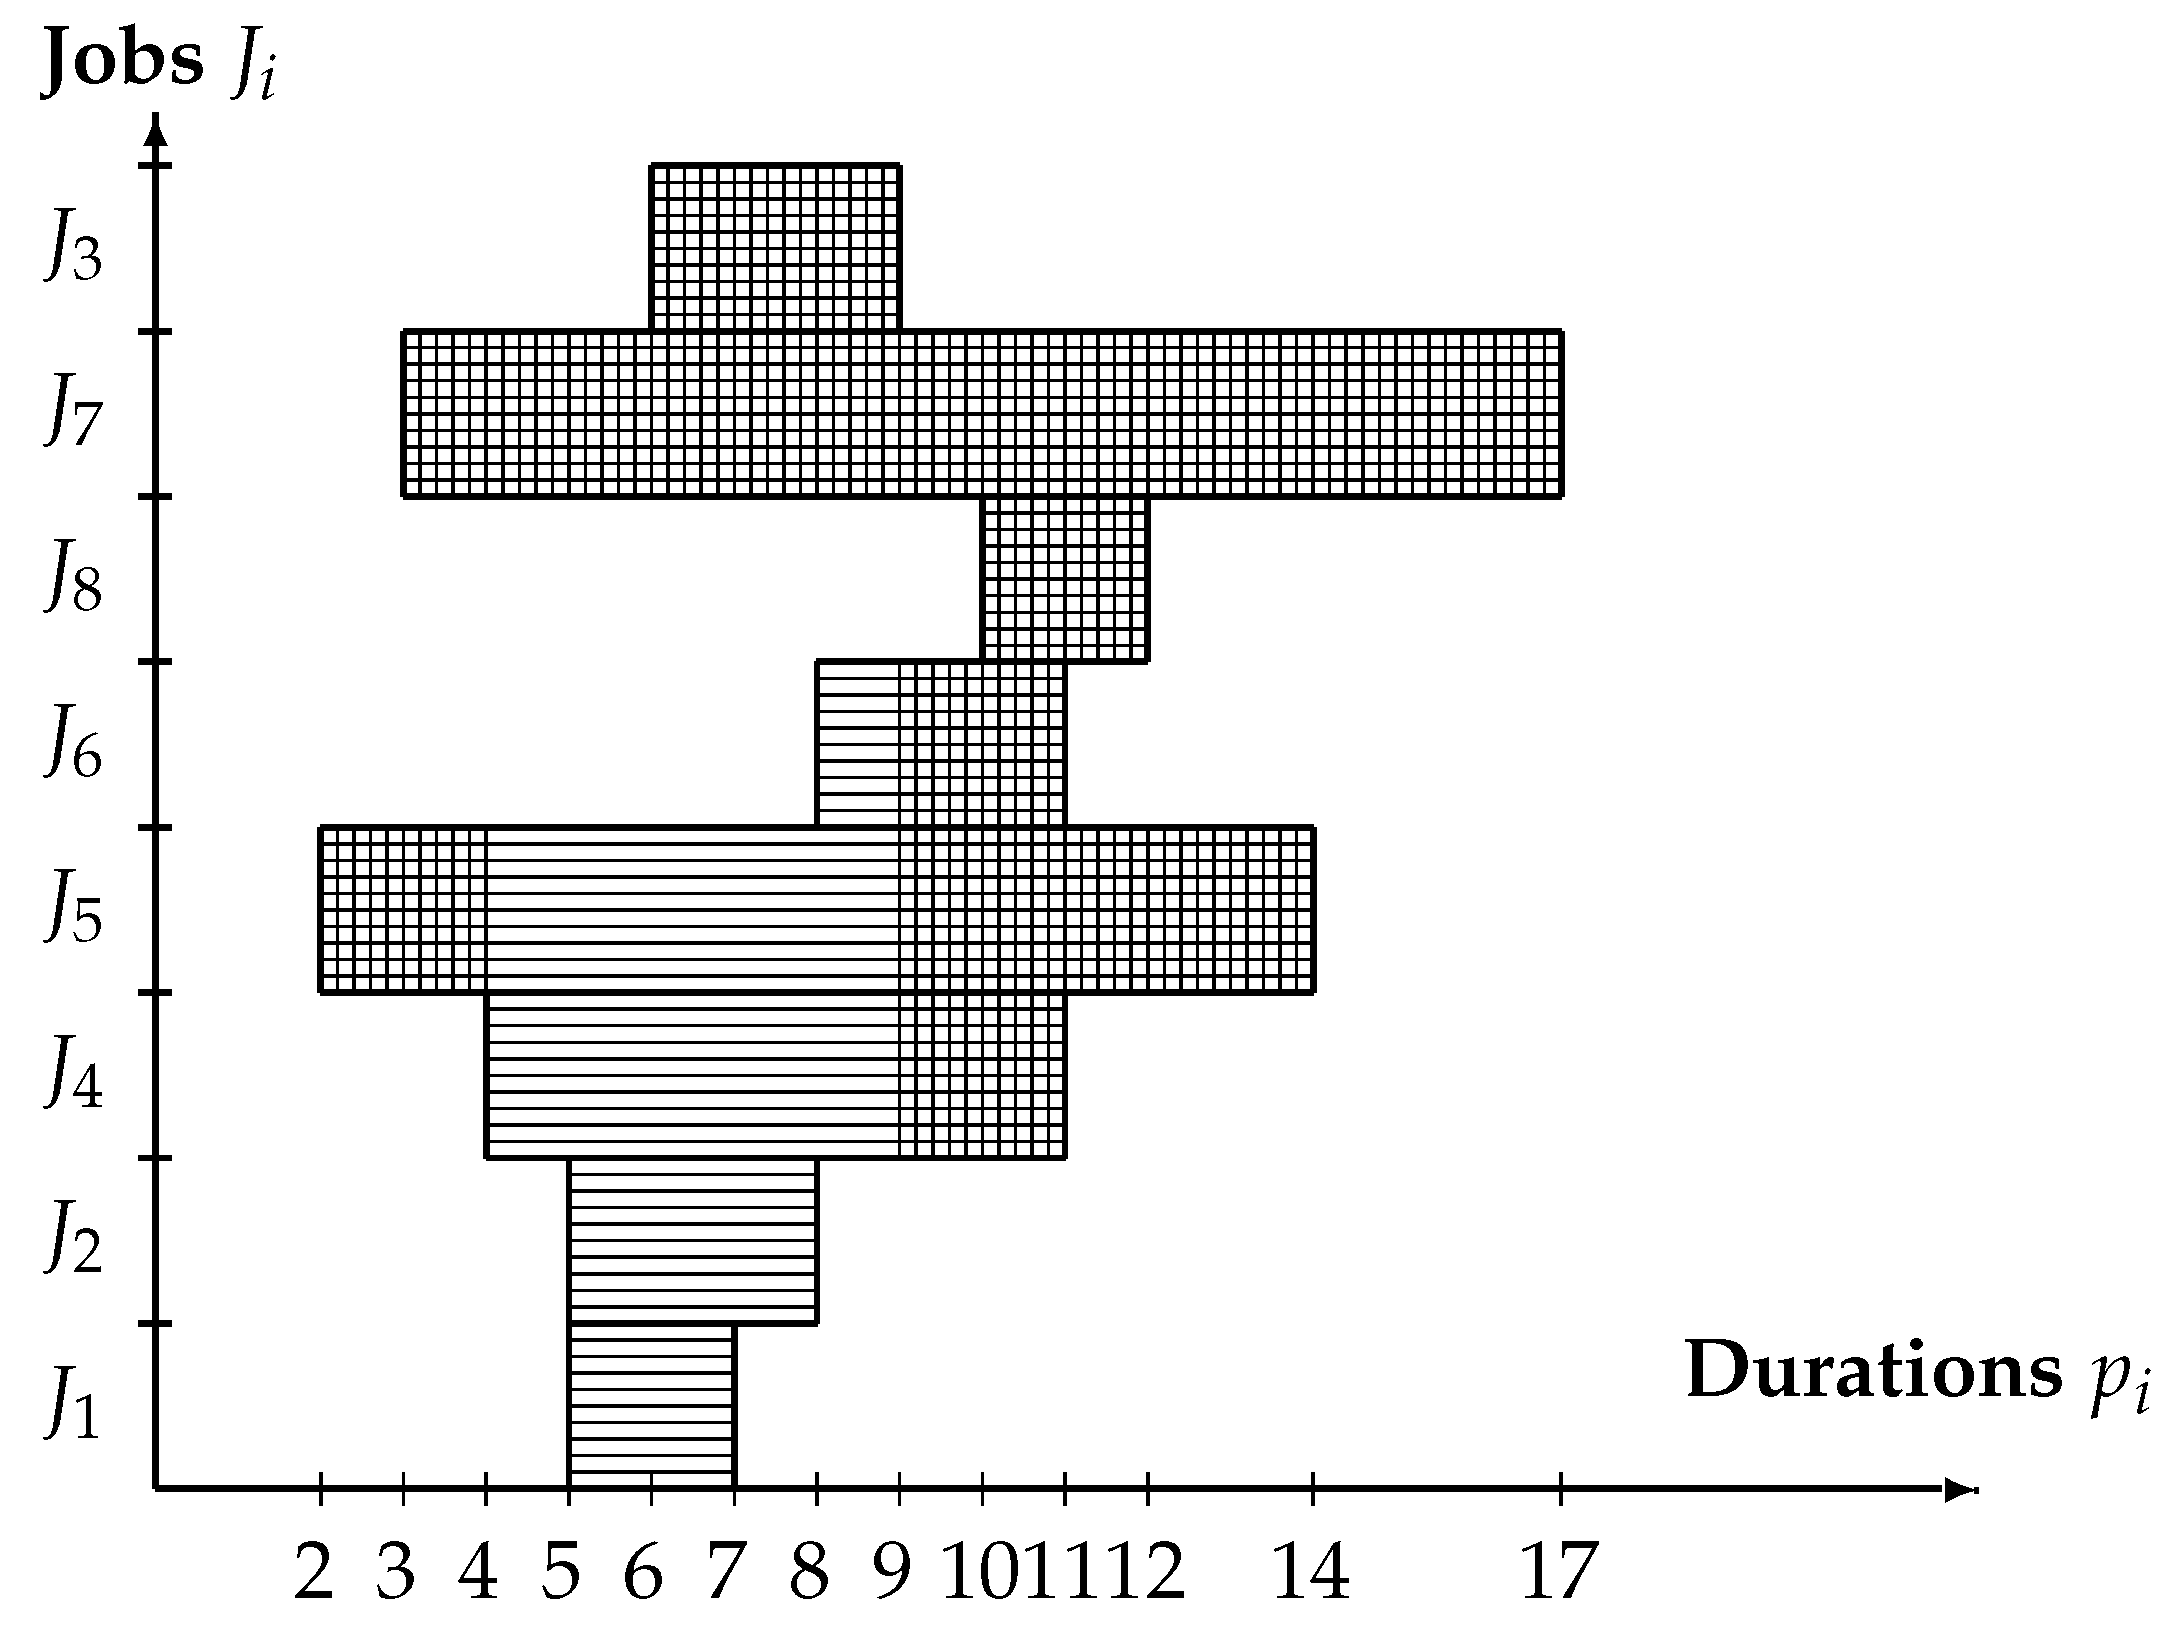

© 2019 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).