Article

AMUSE++: A Mamba-Enhanced Speech Enhancement Framework with Bi-Directional and Advanced Front-End Modeling

1
Department of Electrical Engineering, National Chi Nan University, Nantou County 545301, Taiwan
2
Department of Computer Science and Information Engineering, National Taiwan Normal University, Taipei City 106308, Taiwan
*
Author to whom correspondence should be addressed.
Electronics 2026, 15(2), 282; https://doi.org/10.3390/electronics15020282

Submission received: 10 December 2025 / Revised: 4 January 2026 / Accepted: 6 January 2026 / Published: 8 January 2026

Abstract

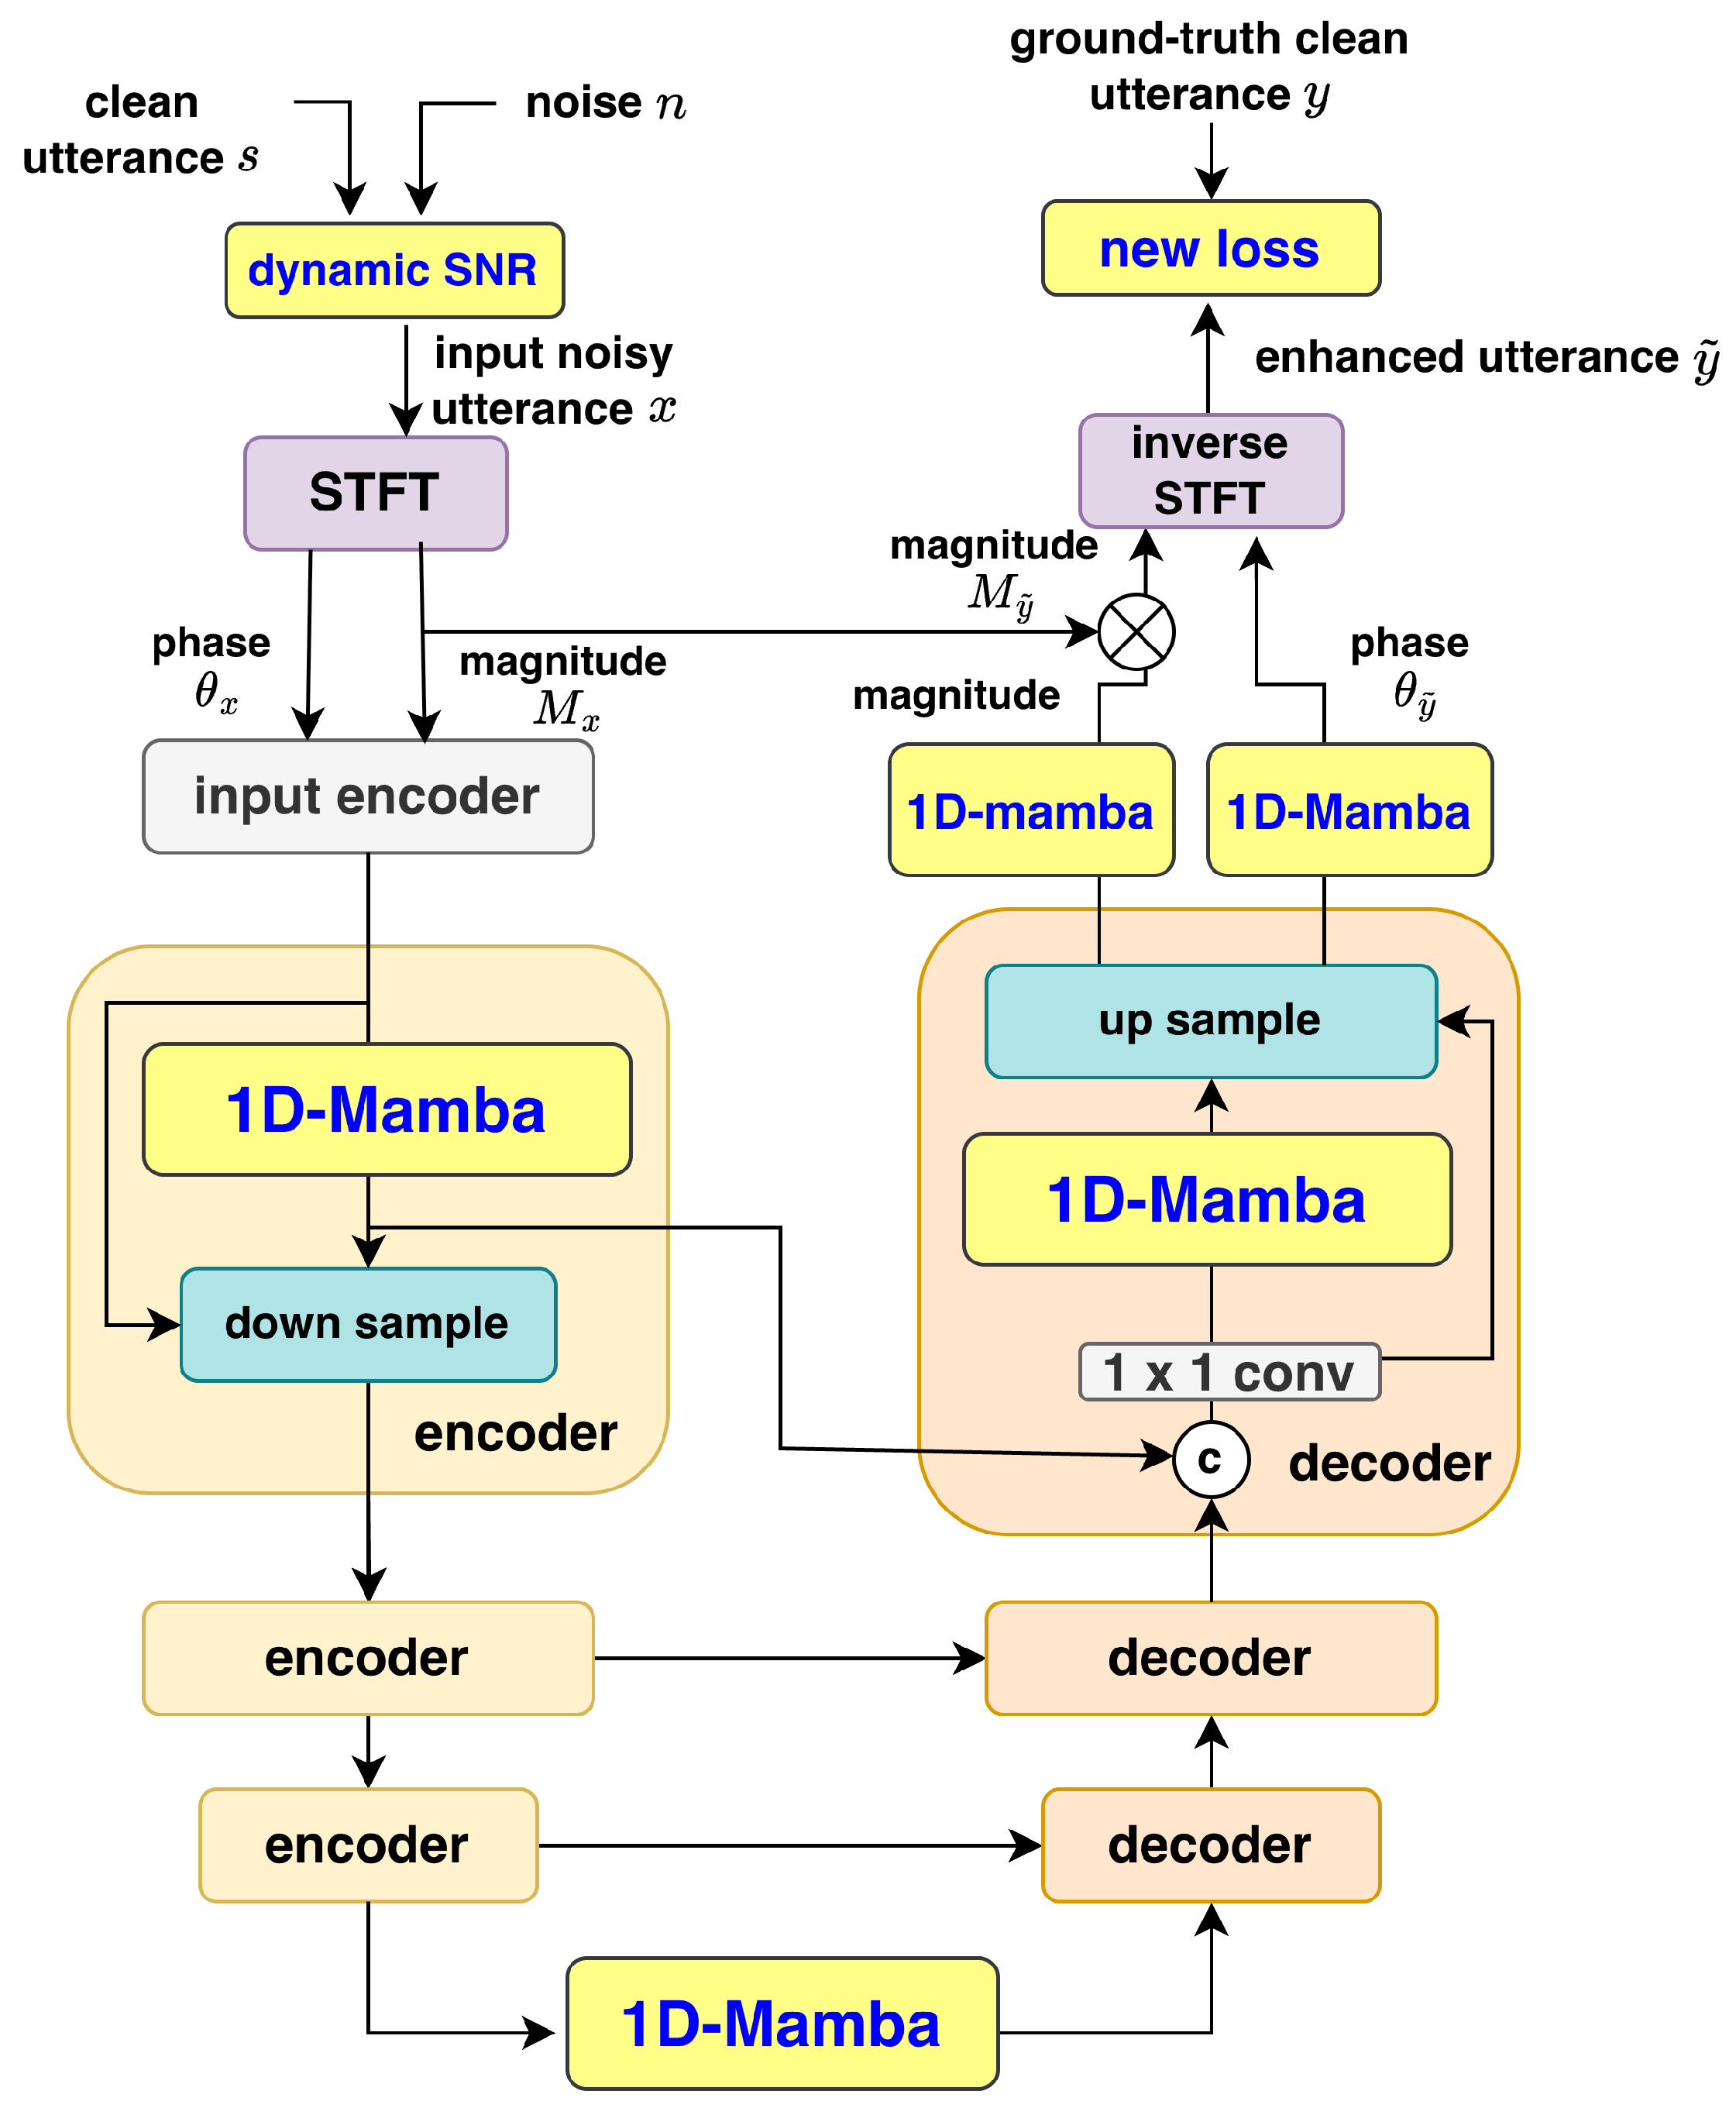
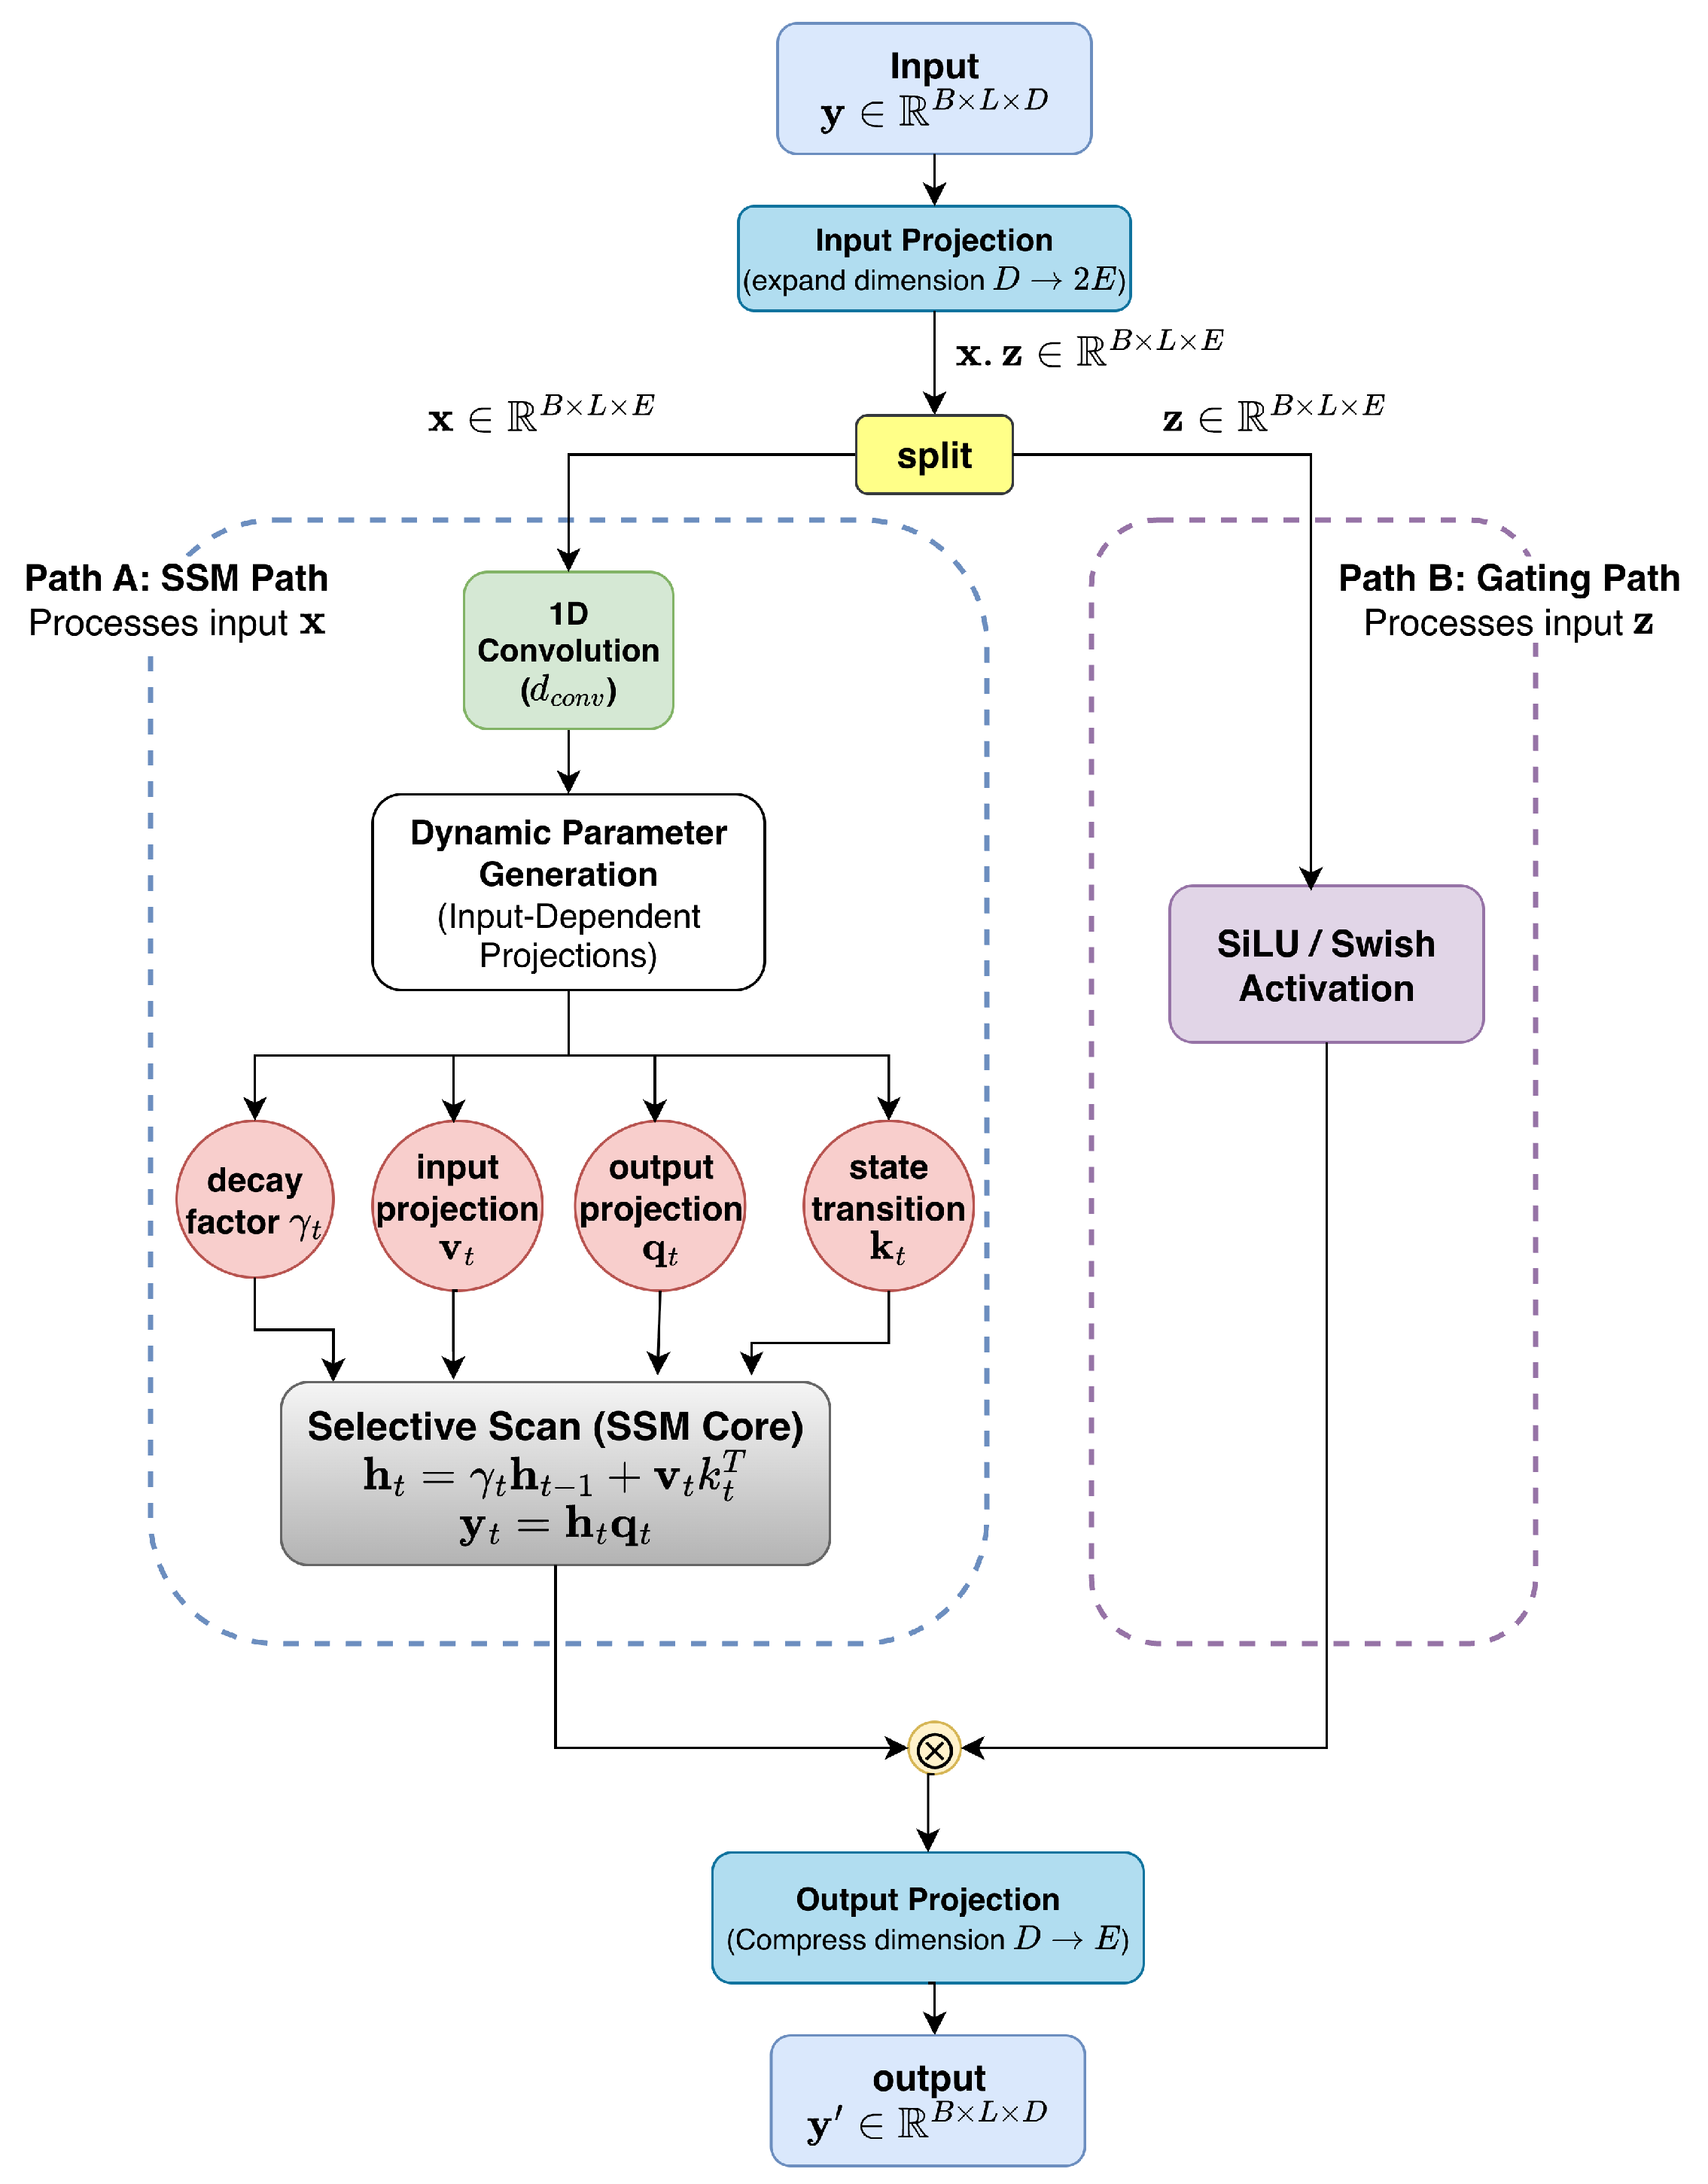
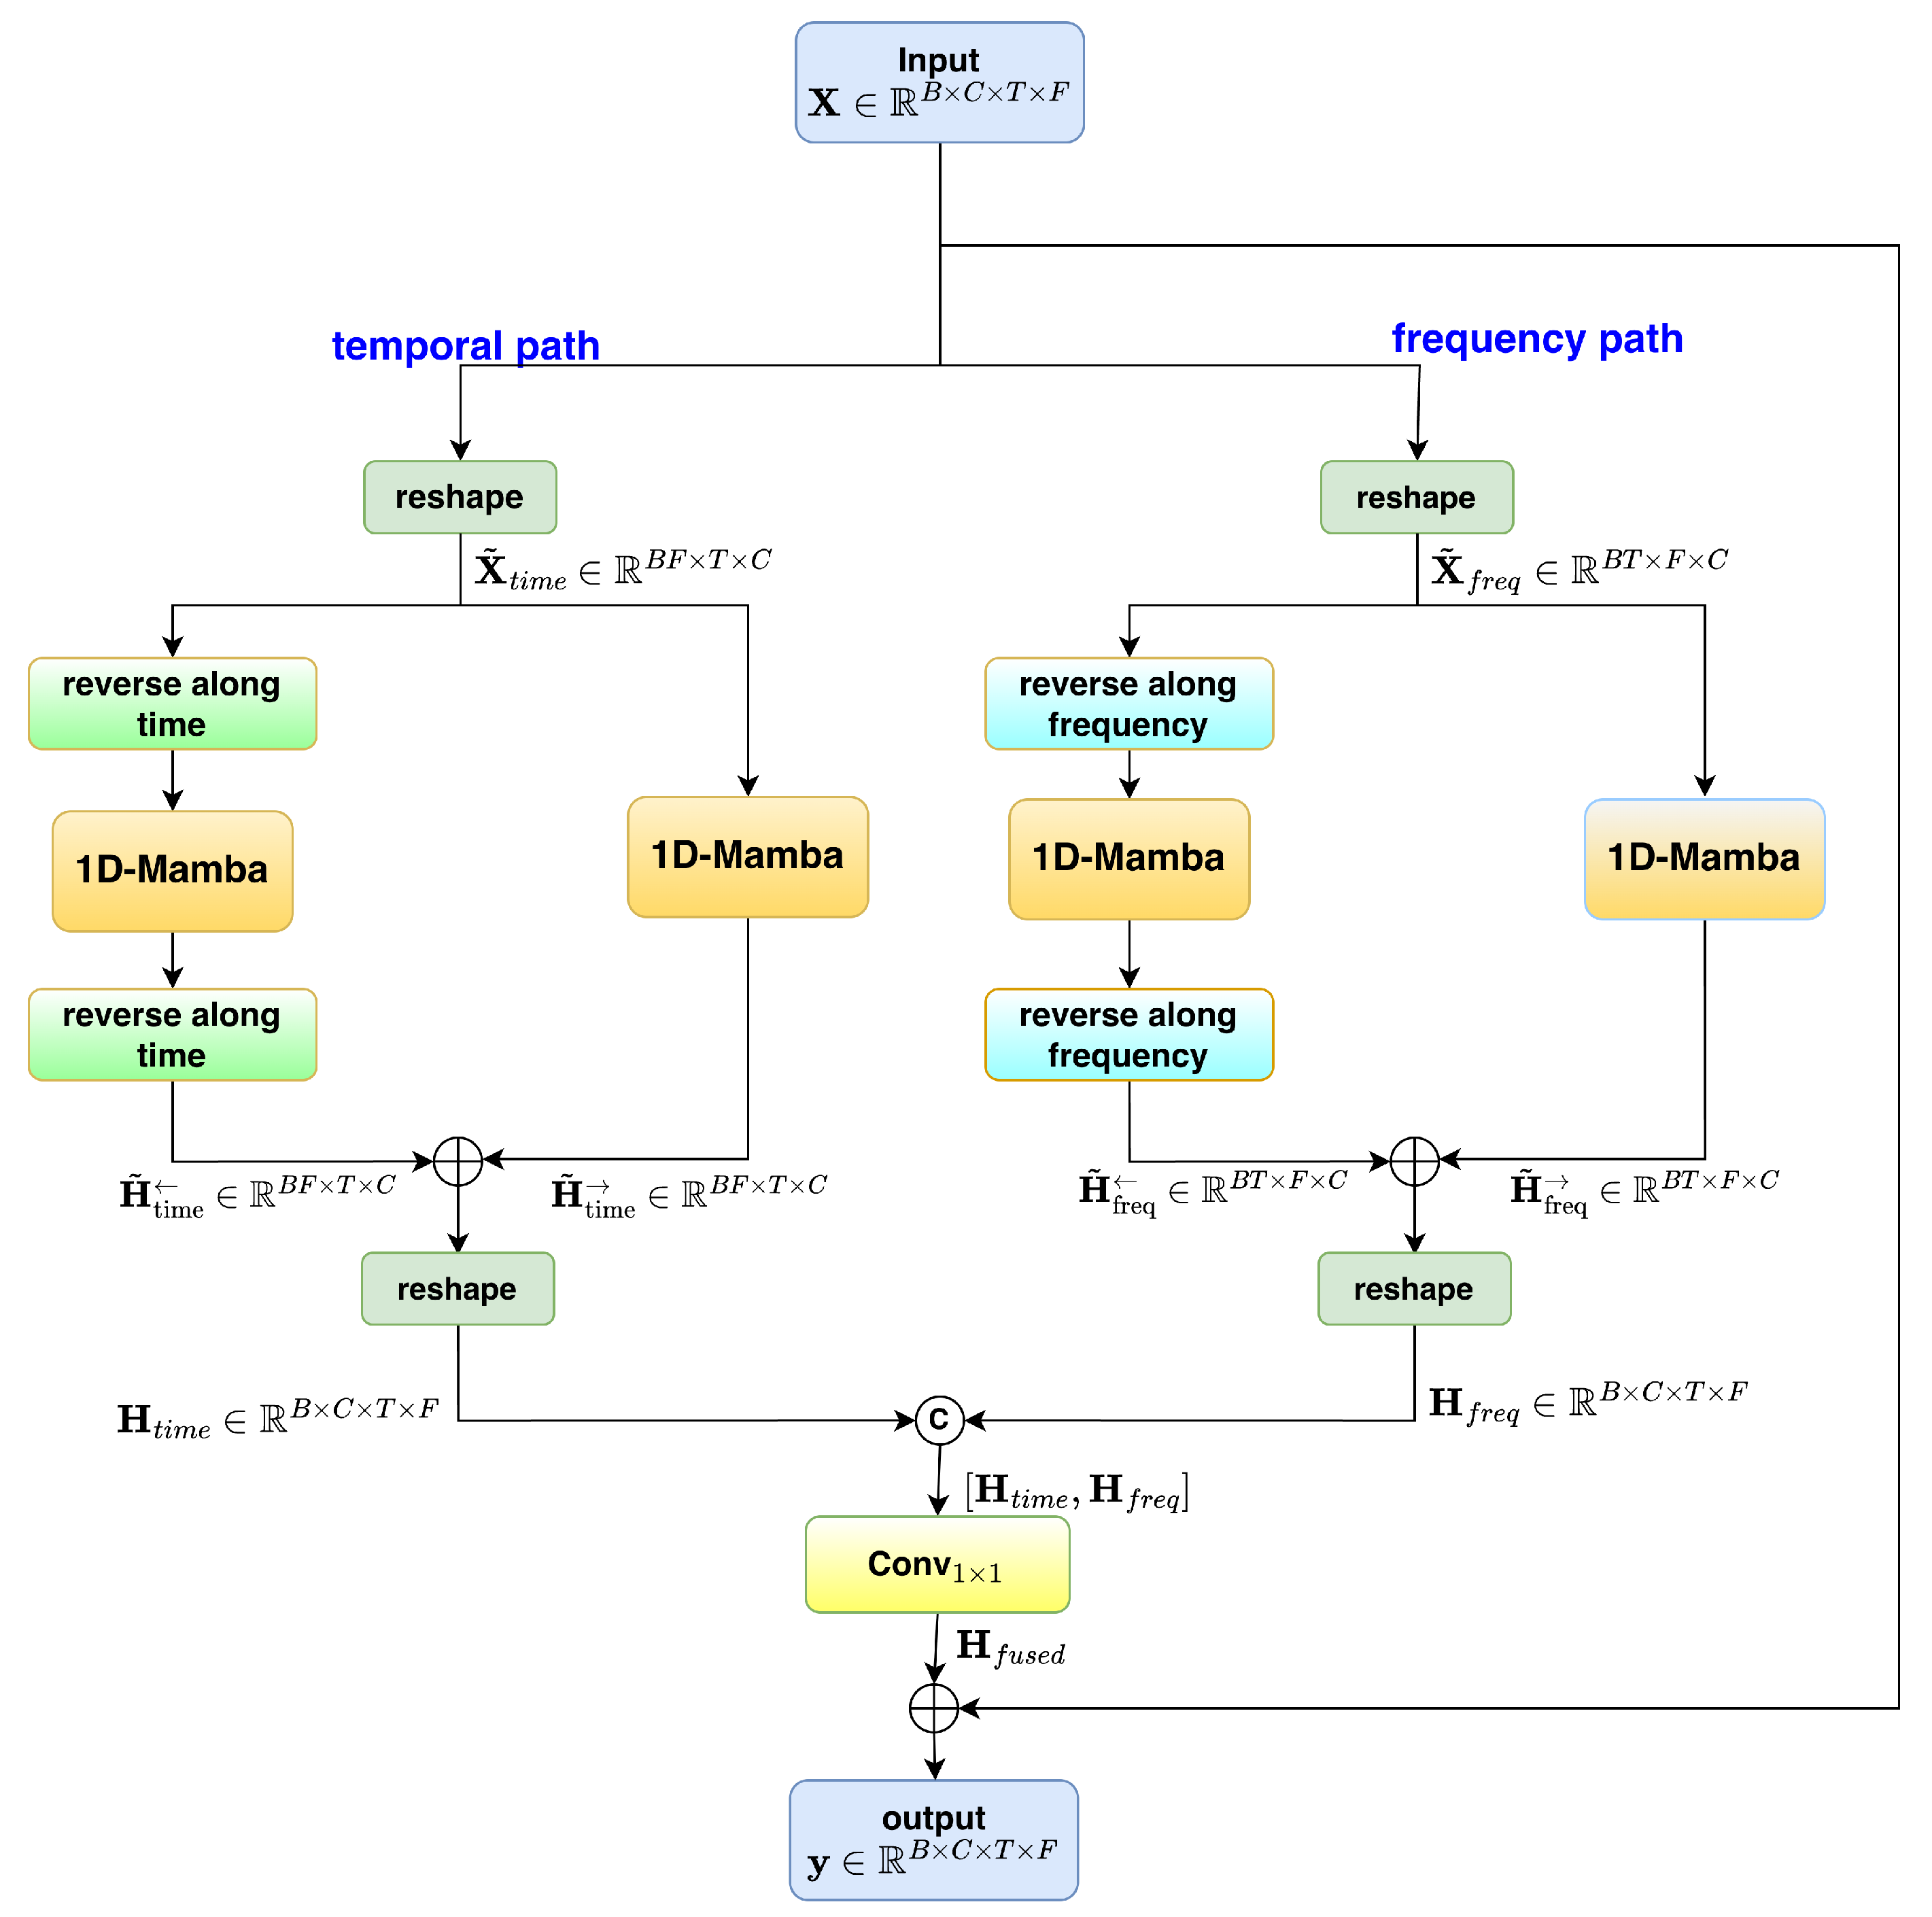
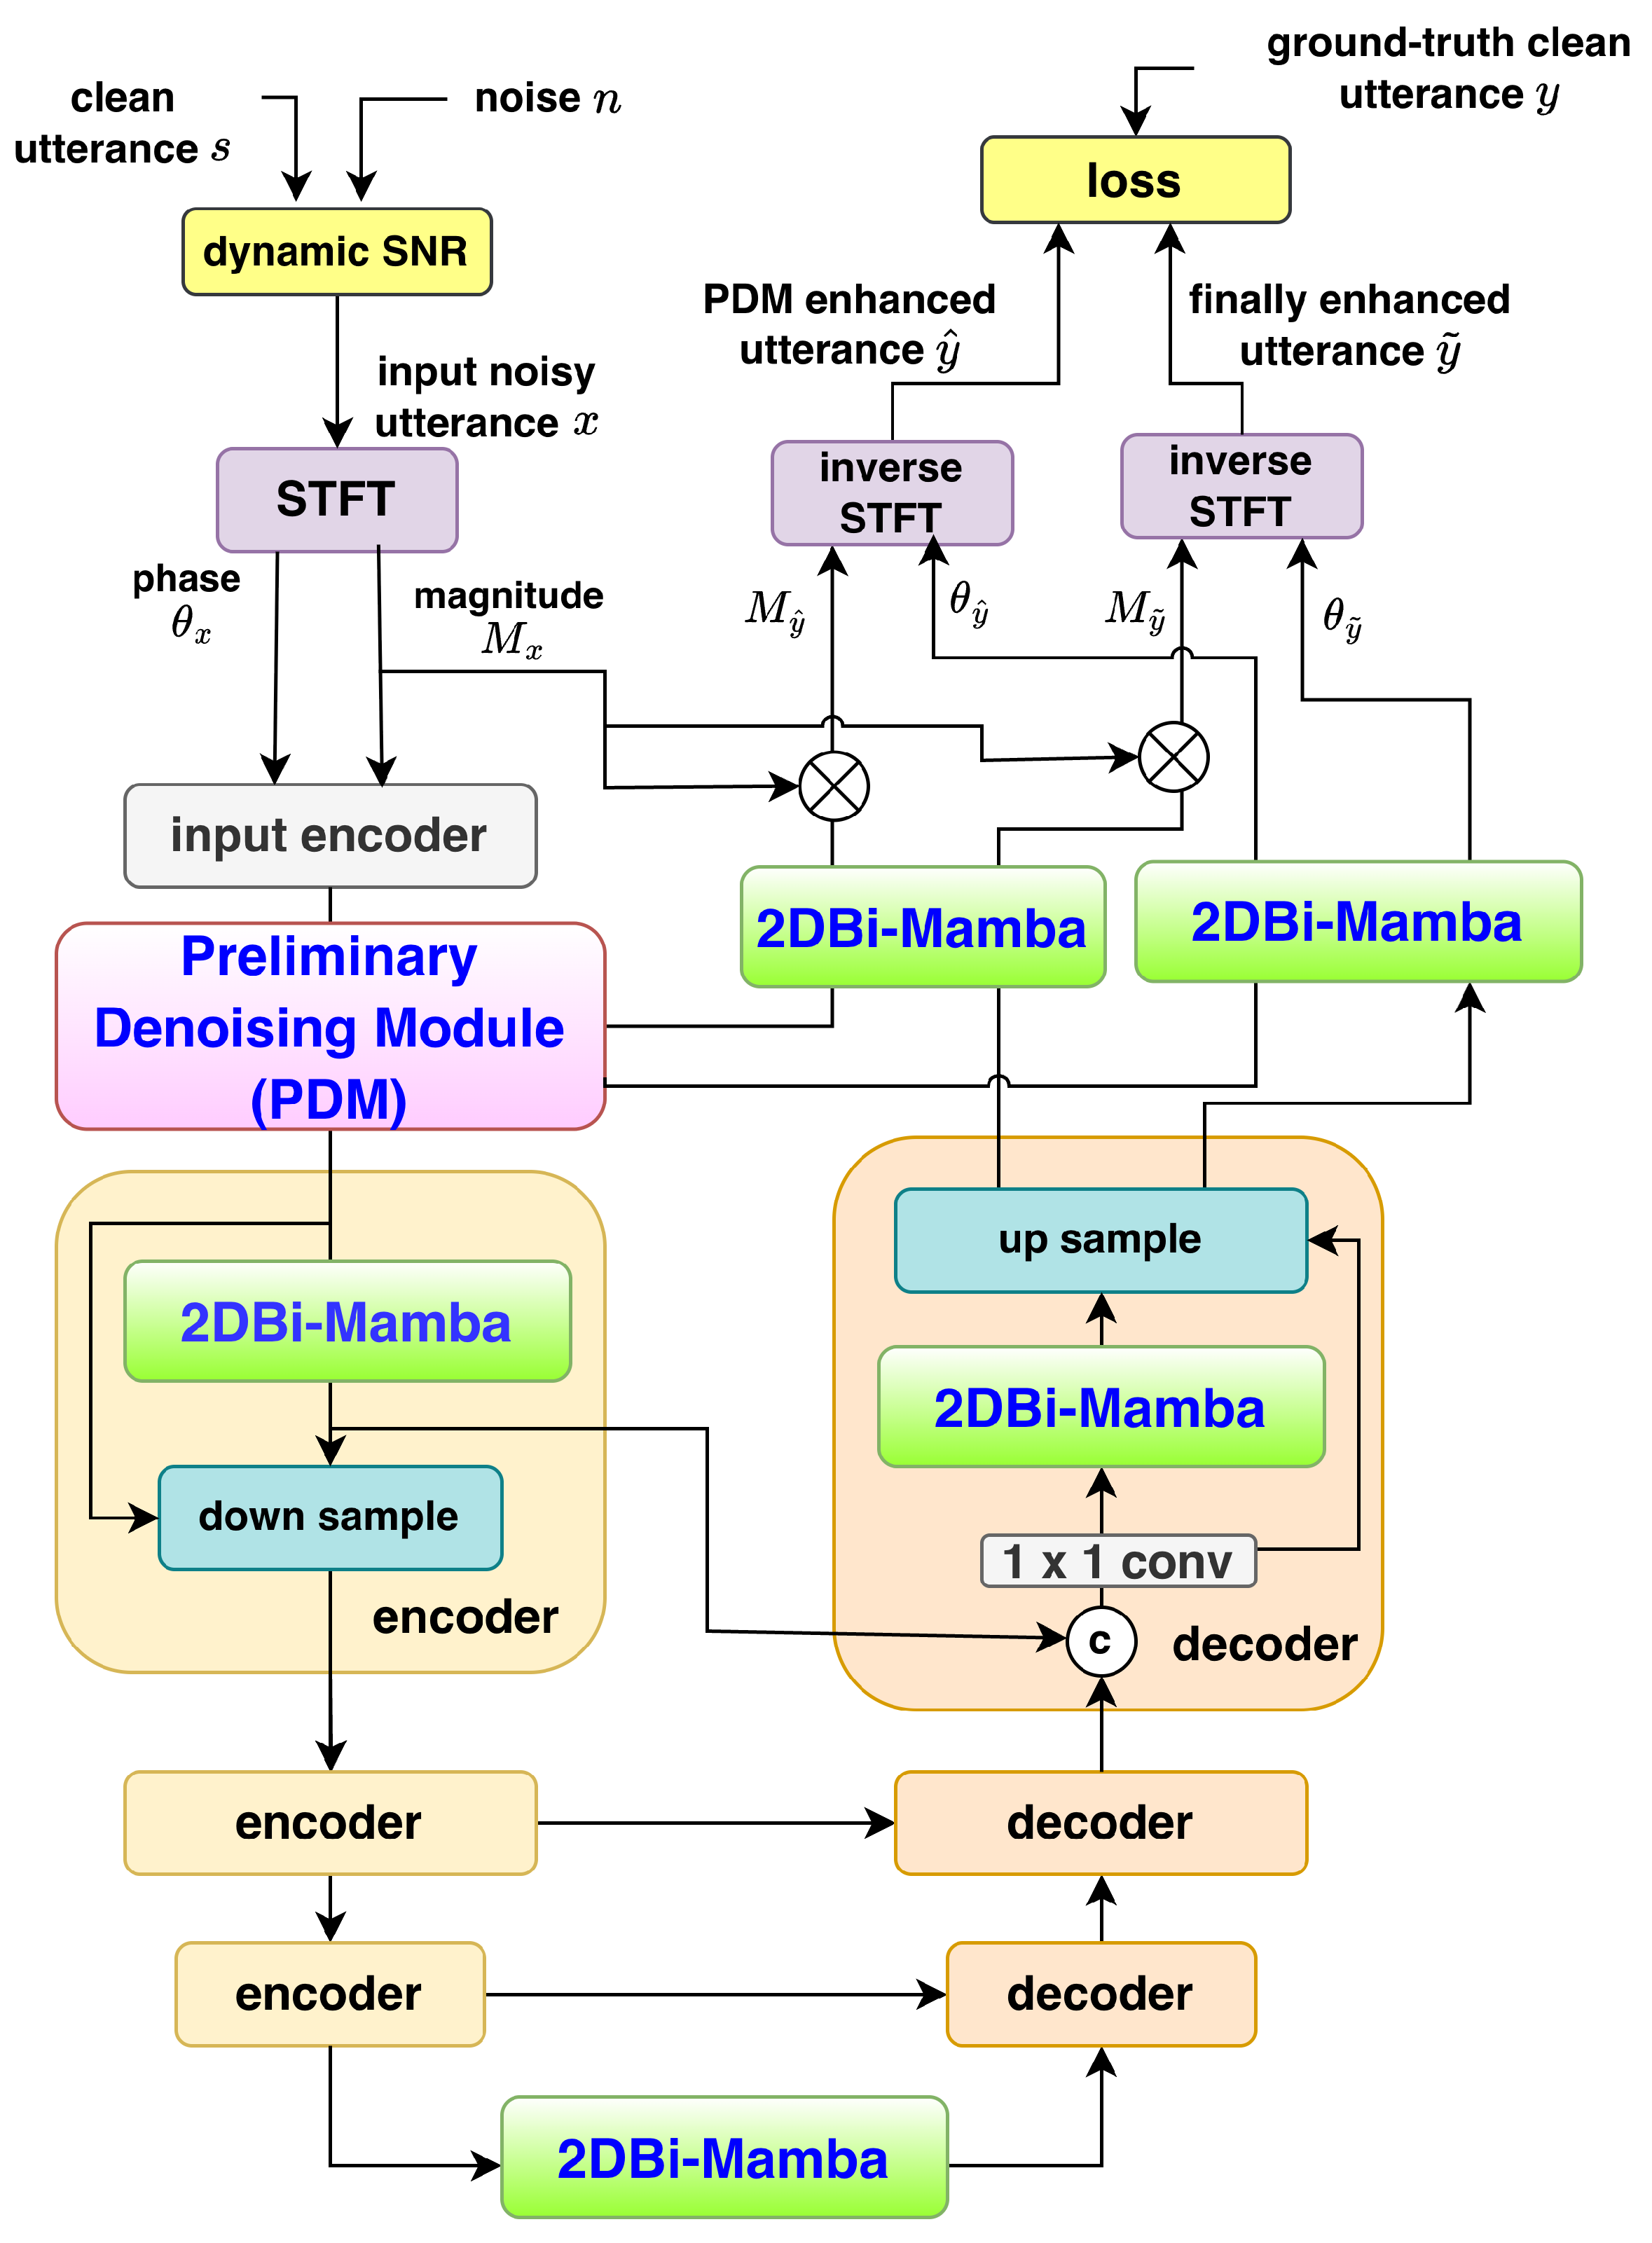
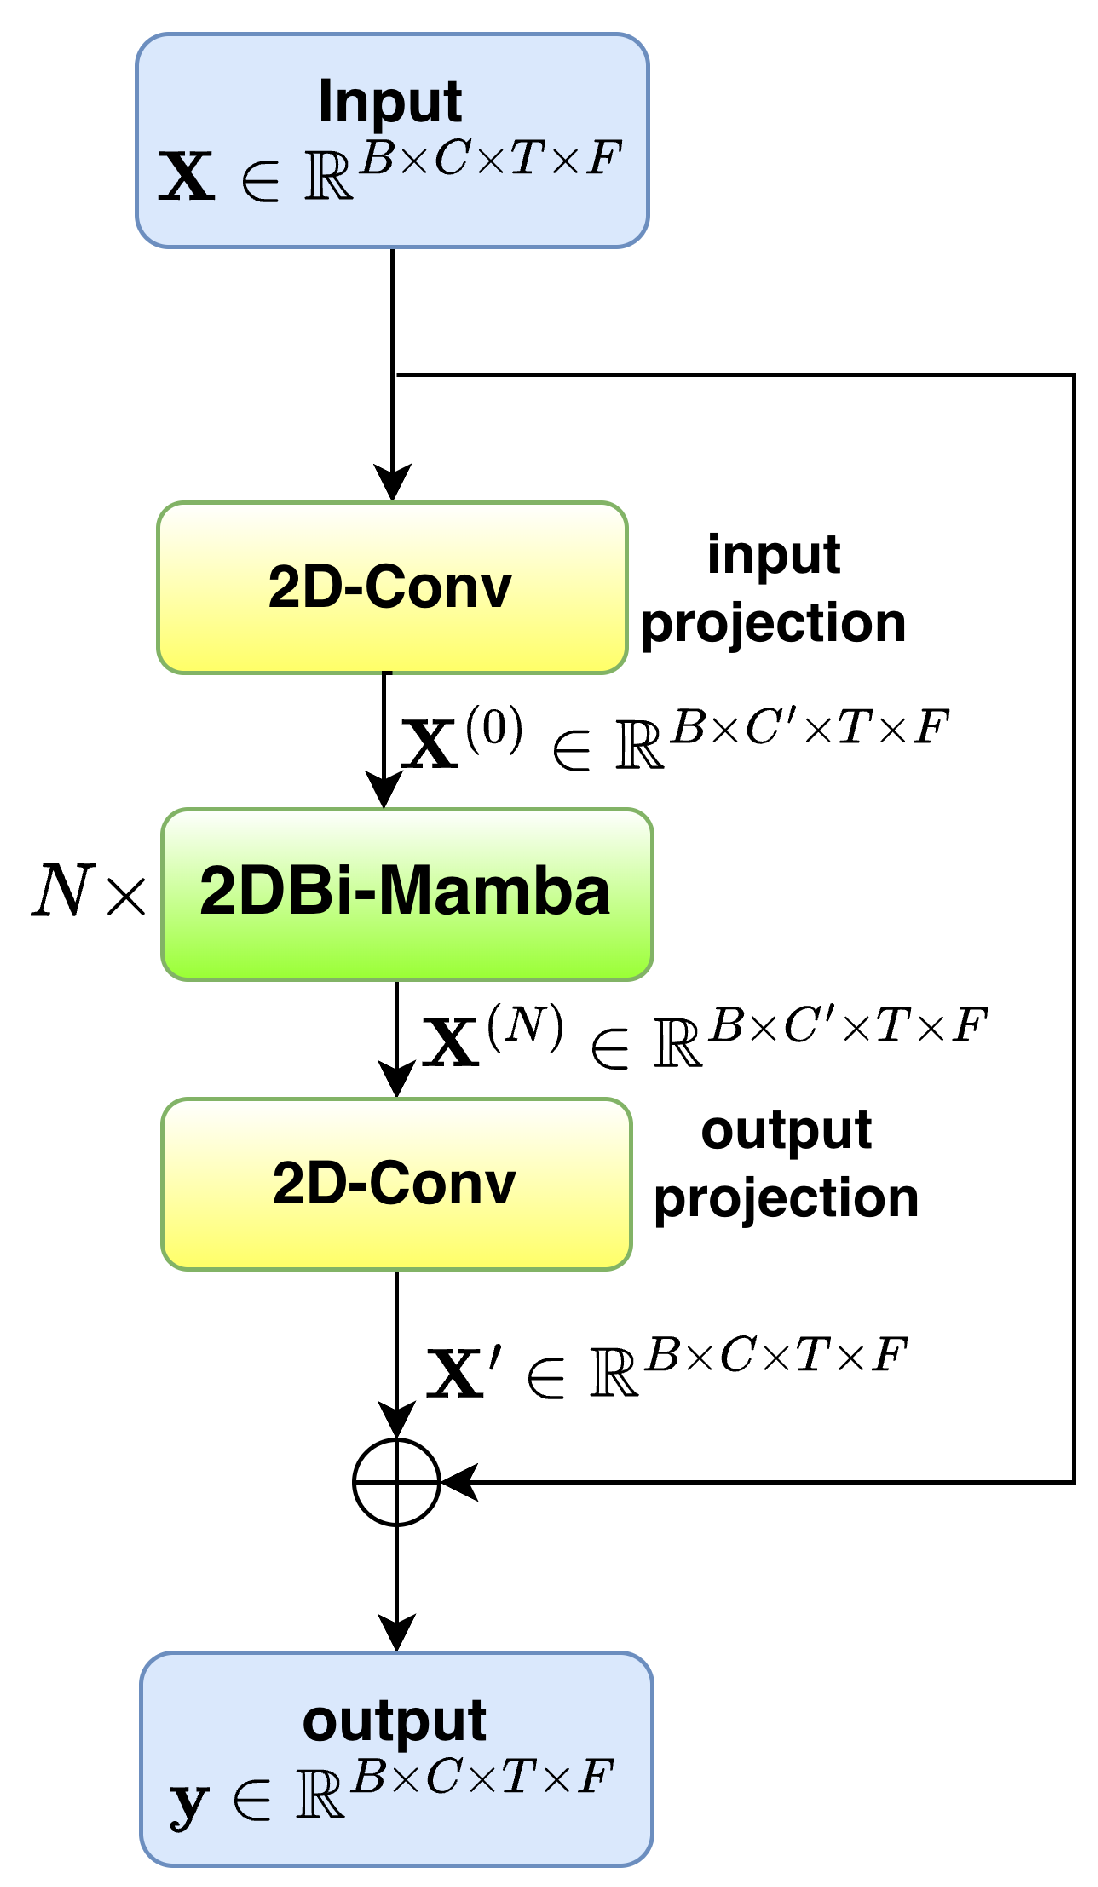
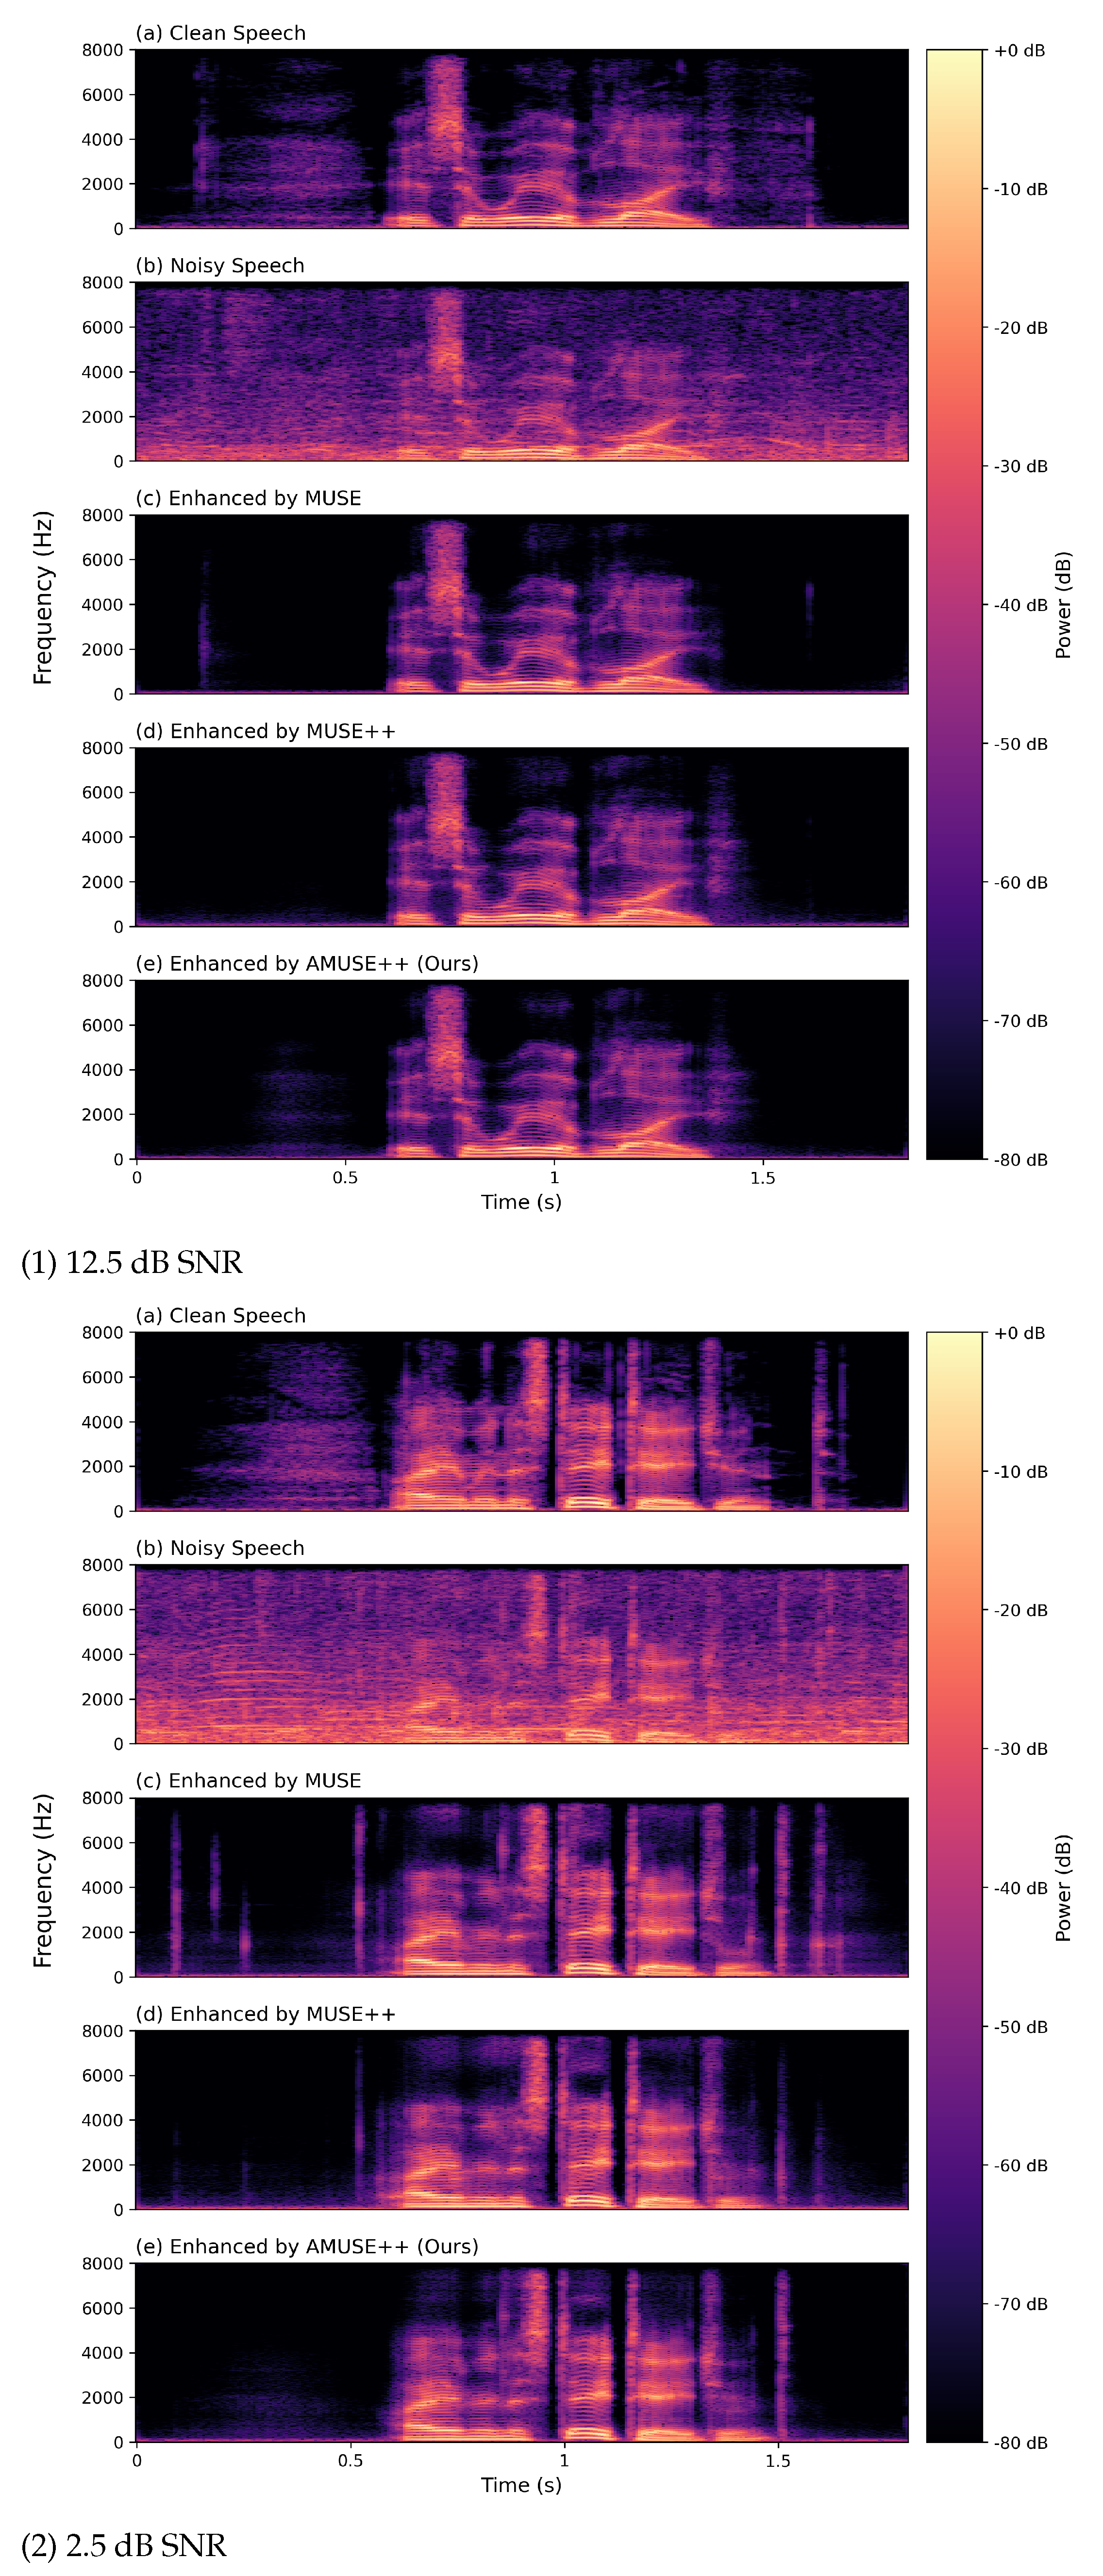
This study presents AMUSE++, an advanced speech enhancement framework that extends the MUSE++ model by redesigning its core Mamba module with two major improvements. First, the originally unidirectional one-dimensional (1D) Mamba is transformed into a bi-directional architecture to capture temporal dependencies more effectively. Second, this module is extended to a two-dimensional (2D) structure that jointly models both time and frequency dimensions, capturing richer speech features essential for enhancement tasks. In addition to these structural changes, we propose a Preliminary Denoising Module (PDM) as an advanced front-end, which is composed of multiple cascaded 2D bi-directional Mamba Blocks designed to preprocess and denoise input speech features before the main enhancement stage. Extensive experiments on the VoiceBank+DEMAND dataset demonstrate that AMUSE++ significantly outperforms both the backbone MUSE++ across a variety of objective speech enhancement metrics, including improvements in perceptual quality and intelligibility. These results confirm that the combination of bi-directionality, two-dimensional modeling, and an enhanced denoising frontend provides a powerful approach for tackling challenging noisy speech scenarios. AMUSE++ thus represents a notable advancement in neural speech enhancement architectures, paving the way for more effective and robust speech enhancement systems in real-world applications.
Keywords: speech enhancement; mamba state-space models; time–frequency modeling; bi-directional 2D mamba; lightweight neural networks speech enhancement; mamba state-space models; time–frequency modeling; bi-directional 2D mamba; lightweight neural networks