1. Introduction
Online Social Networks (OSNs) have become central platforms for public discourse on sensitive geopolitical and humanitarian issues, including irregular migration. Platforms such as X (formerly Twitter) and Telegram play a crucial role in disseminating migration-related content—from breaking news and eyewitness reports to grassroots commentary. However, the informal style, linguistic diversity, and rapid diffusion of content on these platforms pose significant challenges for computational detection and monitoring of such discourse.
The detection of irregular migration narratives is particularly complex in multilingual environments, where resources for language-specific Natural Language Processing (NLP) remain limited, and annotated training data is often scarce. While prior research in hate speech and misinformation detection has made progress, much of it focuses on high-resource languages and overlooks emerging platforms like Telegram.
Beyond data scarcity, multilingual migration discourse often involves code-switching, regional dialects, and script variation, which complicate tokenization and undermine the stability of standard NLP pipelines in such settings. Such phenomena are particularly pronounced in languages like Arabic, Turkish, and Greek, where rich morphology and informal spelling practices further increase lexical sparsity and ambiguity.
Recent advances in transformer-based architectures, including mBERT, XLM-RoBERTa, and mT5, have enabled robust cross-lingual generalization in low-resource settings. These models capture syntactic and semantic structures across languages and have proven effective for multilingual classification tasks. Nonetheless, their application to Telegram and low-resource migration-related corpora remains underexplored, revealing a methodological gap in the literature.
This paper addresses these challenges by introducing a multilingual classification pipeline for detecting online discourse related to irregular migration, including unauthorized border-crossing, asylum-seeking, detention, and other relevant narratives, across five under- and mid-resourced languages: English, French, Greek, Turkish, and Arabic. The pipeline integrates rule-based annotation, language-specific preprocessing, and model benchmarking, and is tested on content from both X and Telegram.
This study builds upon our previous work [
1], which focused on the classification of tweets across four languages (English, French, Turkish, and Arabic), by extending it in four major directions.
While our earlier study demonstrated the feasibility of multilingual classification on X, it did not consider alternative platforms such as Telegram, nor did it provide a systematic comparison between supervised transformer models and zero-shot LLMs in under-resourced languages.
Cross-platform expansion through the integration of Telegram data.
Wider linguistic coverage with the addition of Greek.
Refined keyword-based annotation, combining TF-IDF with expert validation.
Comparative model benchmarking including traditional ML and modern transformer-based approaches, as well as Large Language Models (LLMs).
The main contributions of this work are as follows:
Development of a multilingual corpus spanning two OSNs (X and Telegram) and covering both Western and non-Western languages.
Comparative evaluation of classification models, including Naive Bayes, Logistic Regression, Neural Networks, SetFit, mBERT, and ChatGPT LLM (version GPT-4o).
Exploration of language-specific vs. unified (mixed-language) models, assessing their relative performance across monolingual and cross-lingual setups.
Empirical insights into the performance of transformer-based models in low-resource language settings relevant to migration discourse.
To this end, we investigate the following research question: Can LLMs, such as ChatGPT, reliably detect irregular migration discourse across under- and mid-resourced languages in a zero-shot setting, and how do they compare to fine-tuned transformer models and traditional classifiers?
By combining keyword-based annotation, multilingual preprocessing, and a comparative evaluation of classification models, this study contributes an interpretable, cross-platform NLP framework applicable to low-resource digital migration contexts.
Despite progress in multilingual NLP, no prior study has systematically compared supervised transformer models and zero-shot LLMs across under-resourced languages and across platforms such as X and Telegram for irregular migration discourse. Existing research focuses mainly on monolingual or high-resource settings, leaving a limited understanding of how multilingual models behave in cross-platform, low-resource environments. The present study directly addresses this gap.
In doing so, the study not only expands the empirical coverage of migration-related discourse to a wider set of languages and platforms but also interrogates how traditional classifiers, fine-tuned multilingual transformers, and state-of-the-art LLMs behave under realistic low-resource and cross-platform constraints.
This study should be understood as an exploratory pilot rather than as a fully fledged empirical investigation. Given the extremely small and synthetic nature of the corpus, all findings are interpreted as descriptive indicators of model behavior under extreme, low-resource, cross-platform conditions, not as statistically generalizable evidence or as a ready-to-deploy monitoring tool.
The remainder of this paper is structured as follows:
Section 2 reviews related work on multilingual text classification and migration discourse detection.
Section 3 presents the data collection and preprocessing pipeline.
Section 4 reports experimental results across languages and models.
Section 5 discusses thematic insights and limitations of the study. Finally,
Section 6 concludes the study and outlines future research directions.
2. Related Work
The intersection of migration, hate speech, and digital discourse has drawn increasing scholarly attention, particularly in the context of multilingual and low-resource environments. This section surveys relevant literature across three thematic axes: migration-focused hate speech detection, multilingual NLP approaches in OSNs, and methods for sentiment and discourse analysis in irregular migration contexts.
2.1. Hate Speech Detection Targeting Migrants
Online hostility toward migrants has been a recurring topic of study within computational social science. Recent advances have leveraged transformer-based models to detect hate speech targeted at migrants. SocialHaterBERT, a model combining textual cues with user metadata for binary hate speech classification, was introduced [
2]. Hybrid methods and contrastive learning techniques for hate content detection were examined [
3].
A semi-supervised generative model for multilingual hate speech detection was proposed [
4]. Regional case studies offer important context. Discursive patterns around illegal immigration in Northeast India were analyzed [
5], revealing the entwinement of local dialects and nationalistic narratives. Such observations underline the sociolinguistic intricacy and contextual variability of migration discourse across regions.
2.2. Multilingual NLP for Social Media Classification
Multilingual NLP presents unique challenges, especially in domains with informal and cross-lingual user input. Prior work has tackled the issue via supervised models tailored to detect hate speech across languages, often using engineered features or translation pipelines. Multilingual hate speech targeting migrants and women on X was analyzed [
6], highlighting the importance of language-specific preprocessing. Behavioral tracking approaches were proposed [
7] to detect anti-immigration discourse using user-level social media data.
SemEval-2019 Task 5 underscored the challenges of multilingual hate speech detection in English and Spanish, especially in low-resource scenarios [
8]. Transformer models such as BERT and its multilingual variants (e.g., mBERT) have increasingly been adopted as viable alternatives [
9,
10].
Recent surveys on multilingual large language models provide a broader taxonomy of such architectures and highlight their growing role in cross-lingual and low-resource NLP applications [
11,
12,
13].
Open- and closed-source LLMs were evaluated [
14,
15] for low-resource classification, revealing architecture-level trade-offs in generalization and robustness. Multilingual immigration discourse during sociopolitical crises was examined [
16], demonstrating the need for language-specific modeling and framing awareness.
2.3. Sentiment and Migration Discourse Analysis
A related direction explores sentiment analysis and topic modeling for migration narratives. The authors of [
17] proposed a lexicon-enhanced sentiment classifier for illegal immigration tweets, combining affective lexicons and contextual embeddings. In [
18], shifts in public sentiment toward immigration during the COVID-19 pandemic were tracked using data from X (formerly Twitter).
A multilingual analysis of sentiment and stance in European migration coverage was conducted in [
19], revealing cross-cultural differences in framing. In [
20], disinformation and politically sensitive migration-related narratives were identified across X (formerly Twitter) and Telegram using Large Language Models (LLMs).
2.4. Methodological Gaps and Contributions
Despite growing interest in multilingual and migration-related NLPs, two major methodological gaps persist:
The under-representation of non-Western and low-resource languages (e.g., Arabic, Greek, and Turkish) in publicly available datasets.
The limited use of alternative platforms such as Telegram, which play an increasingly central role in real-time crisis communication and grassroots reporting.
A multilingual offensive language identification framework for resource-poor settings was proposed in [
21], leveraging label-efficient architectures for improved performance.
To address these research gaps, our study contributes (i) a multilingual dataset combining messages from X and Telegram built upon our previous work [
1], (ii) a rule-based labeling framework based on TF-IDF keyword identification [
22], and (iii) an evaluation of multiple classification models (traditional, transformers, and LLMs) across language-specific and mixed corpora.
In contrast to recent surveys that synthesize the landscape of multilingual LLMs at a high level, this work offers a focused, task-driven comparison on migration-related discourse using a compact but carefully controlled multilingual corpus [
11,
12,
13].
Building upon these gaps, the following section outlines the methodology adopted to construct, annotate, and classify multilingual social media content related to irregular migration. This integrated approach addresses the identified gaps and frames the design of our classification pipeline in
Section 3.
However, prior multilingual NLP studies provide limited critical discussion of how dataset sparsity, platform-specific linguistic variation, and morphological complexity influence cross-lingual model behavior. Existing research often relies on high-resource benchmarks, offering only partial insight into the challenges posed by dialectal variation, tokenization instability, and sparse lexical distributions in short-form OSN content. Moreover, transformer-based approaches rarely contrast supervised fine-tuning with zero-shot LLM inference, leaving unclear how each paradigm performs under low-resource, cross-platform constraints. Addressing these gaps motivates the comparative analysis undertaken in this study.
Beyond data scarcity, several linguistic properties of Arabic, Turkish, and Greek introduce structural challenges that affect multilingual classification performance. Arabic exhibits rich, non-concatenative morphology, extensive dialectal variation, and orthographic inconsistencies that complicate tokenization and semantic normalization in short OSN messages. Turkish is a highly agglutinative language, where productive suffixation generates substantial lexical sparsity and undermines the effectiveness of conventional preprocessing routines. Greek presents inflectional complexity and comparatively limited availability of robust pretrained resources, which constrain cross-lingual transfer and model generalization. These language-specific characteristics highlight the need for carefully designed preprocessing and motivate the comparative evaluation undertaken in this study.
3. Methodology
This section outlines the OSN data collection process, dataset construction, and labeling procedure, and the classification pipeline used to detect irregular migration-related discourse across multiple languages and platforms.
3.1. Data Collection from X and Telegram
The dataset used in this study was constructed from two OSNs: X and Telegram. Our objective was to capture real-world, multilingual discourse related to irregular migration across both mainstream and niche digital environments.
We collected a total of 174 tweets using the Orange Data Mining toolkit [
23] and the official X API [
24]. This process builds on our earlier methodology in [
1], where we also used keyword-based querying for multilingual migration content. In the current study, we developed an expanded seed list of migration-relevant keywords in English (e.g., “boat”, “illegal”, “immigrant”, and “border”), sourced through expert consultation and prior research. To ensure multilingual coverage, all English keywords were translated into Arabic, Turkish, Greek, and French. The translations were conducted manually by bilingual annotators and verified using automated translation tools (DeepL and Google Translate) to preserve semantic consistency and cultural relevance.
In addition to X content, 119 short-form messages were extracted from five public Telegram channels with explicit focus on migration-related themes. These channels were selected after screening an initial pool of 20 candidates, excluding those focused on unrelated topics (e.g., terrorism and religious proselytism).
Channel selection prioritized (i) sustained activity and sufficient volume of migration-related posts during the collection period, (ii) public accessibility and stable availability over time, and (iii) coverage of different linguistic and regional communities along key migration routes. While this approach ensured relevance and multilingual coverage, we acknowledge that relying on a limited number of channels may introduce thematic or ideological bias, which is noted as a limitation in the Discussion. All Telegram data were collected exclusively from public channels, without accessing private groups or user-level identifiers, and were processed in aggregated form for research purposes only. The collection procedure adhered to the terms of service of X and Telegram, and the analysis does not aim at profiling individual users but at characterizing broad patterns of migration-related discourse.
Ethical Considerations: Data collection adhered to strict privacy and ethical standards. Only public channels were accessed, and all personally identifiable information (PII), such as usernames, was removed during preprocessing to ensure anonymity. The research focuses on aggregate discourse patterns rather than individual behavior, in full compliance with the platforms’ Terms of Service.
As with the X dataset, a TF-IDF-based keyword extraction process was applied to the collected Telegram texts, resulting in 12 additional migration-related terms. One duplicate was removed during manual filtering. These new terms were used to label the messages via a rule-based binary classification process, yielding the final Telegram subset.
The resulting corpus comprises 293 unique messages, consisting of 174 tweets (59.4%) and 119 Telegram messages (40.6%), all contributing to the final dataset.
Table 1 presents the distribution of messages across the six detected languages. Notably, although Farsi appeared in the Telegram dataset (78 messages, approximately 65.5% of that content), it was excluded from downstream modeling and classification due to (a) a lack of linguistic expert support for reliable keyword translation and (b) the inability to ensure consistent manual annotation. Thus, the classification experiments focus exclusively on the five aforementioned target languages: English, Arabic, Turkish, Greek, and French.
The very limited number of original Greek (4 messages) and French (15 messages) samples restricts the validity of monolingual statistical interpretation. Consequently, these languages serve as a diagnostic benchmark to evaluate model robustness to cross-lingual variation via controlled translation, rather than representing independent, fully resourced native corpora. For this reason, Greek and French are included primarily to support cross-lingual evaluation via controlled translation rather than to represent independent, fully resourced language-specific corpora. Their role in the analysis is therefore comparative and diagnostic, not inferential in terms of native OSN discourse volume.
This natural imbalance reflects both the platform-specific prominence of migration narratives and the inherent linguistic diversity found in user-generated content.
In particular, the very limited number of native Greek and French messages restricts the extent to which multilingual findings can be interpreted comparatively. This imbalance reflects real-world disparities in OSN activity across languages and positions this study within a low-resource multilingual setting rather than a balanced cross-lingual benchmark.
While the corpus comprises only 293 original messages, this number reflects the scarcity and fragmentation of publicly available migration-related content in under-represented languages on X and Telegram. To enable controlled cross-lingual comparison, each of these 293 messages was translated into the five target languages, yielding a total of 1465 language-specific instances. This translated expansion constitutes a synthetic increase in the number of instances rather than additional independent observations and is therefore used solely to probe model robustness to cross-lingual variation, not to approximate a large-scale, organically multilingual corpus.
Keyword Extraction and Language Inclusion
Although Farsi content was present in the Telegram dataset, it was not included in model training or evaluation, since the original keyword list was not translated into Farsi. Moreover, there was no available bilingual expert for validation. Rather than risk introducing inconsistencies, we opted to exclude Farsi as a source language. However, all messages (including those originally in Farsi) were translated into the five target languages using DeepL and Google Translate to ensure semantic consistency. Translation was performed via the Google Cloud Translation API, followed by a rigorous human-in-the-loop verification process. All translations were produced using the Google Cloud Translation API and cross-checked with DeepL, followed by a strict human-in-the-loop verification process by bilingual annotators. For each message, annotators compared the source and all five target-language versions, corrected obvious errors, and flagged cases where migration-related terminology or pragmatic intent was not faithfully preserved. This procedure reduces, but cannot fully eliminate, semantic drift; residual translation artifacts are therefore explicitly acknowledged as a limitation of the evaluation.
This multilingual expansion should be interpreted as a synthetic increase in the number of instances rather than as additional independent observations, since all translated variants originate from the same 293 source messages. Consequently, the reported results primarily reflect model robustness to cross-lingual variation under translation rather than large-scale generalization to unseen migration discourse.
Τo avoid introducing semantic noise and potential bias, we consciously excluded Farsi from multilingual evaluation due to the absence of reliable linguistic validation; a decision informed by both methodological and ethical considerations.
Including Farsi without a validated multilingual keyword set or expert supervision would have introduced annotation noise and compromised the methodological integrity of the study. Because the rule-based labeling depended on verified cross-lingual keyword equivalence, and because no qualified annotators were available to validate Farsi-specific terminology, the inclusion of this language in supervised experiments would have produced unreliable labels and distorted comparative results. For this reason, Farsi was retained only in translated form to ensure cross-lingual consistency but excluded from model training to preserve analytical validity.
3.2. Dataset Labeling
To annotate the dataset, we first employed a transparent rule-based binary labeling scheme to ensure minimum thematic consistency across languages, similarly to our previous work [
1]. An initial keyword filter was used only to select candidate messages, while the final labels were assigned through manual validation by two domain experts who systematically overrode keyword-only decisions whenever context (e.g., irony, negation, metaphor, or political framing) contradicted the literal presence of migration-related terms. As a result, the ground-truth labels are driven primarily by expert judgment on semantic intent, with keywords serving merely as an interpretable starting point rather than a simplistic lexical count.
To strengthen the reliability of the rule-based annotation, the multilingual keyword lists and their thematic assignments were independently reviewed and validated by two domain experts with experience in migration-related discourse.
The distribution of binary labels across the translated datasets is summarized in
Table 2. The full list of multilingual keywords used for rule-based annotation, including their source languages and verified translations, is provided in
Table 3. These terms were manually translated and semantically validated across the five target languages (English, French, Arabic, Greek, and Turkish). The resulting multilingual keyword sets were used to build language-specific matchers, enabling consistent rule-based detection across all translated corpora.
On the gold-standard test set (250 messages, with 50 per language), the two domain experts reached substantial agreement on the binary labels, with only a small fraction of instances requiring adjudication. This level of consistency provides additional assurance that the evaluation labels reflect stable semantic judgements rather than idiosyncratic interpretations.
All keywords were compiled into multilingual lookup lists and integrated during preprocessing to enable pattern matching in short-form texts. As already mentioned, Farsi messages, although present in the initial corpus, were excluded from multilingual evaluation due to a lack of translated keywords and low representational coverage.
The label distribution per language, as summarized in
Table 2, reflects the output of this annotation process after translation. All 293 original messages were translated into each of the five target languages, and each translated subset was independently annotated using the same keyword-based rules. This approach ensured cross-lingual comparability, even when some languages had limited original representation (e.g., Greek).
To enhance semantic interpretability and ensure conceptual consistency across languages, the 31 multilingual migration-related keywords were manually grouped into 13 thematic categories (e.g., Migration, Smuggling, Border, Transport, Authorities, and Victims). This mid-level categorization facilitated the understanding and thematic validation of the keyword-based annotation schema without introducing label bias. The full keyword-to-category mapping, along with additional insights, is discussed in
Section 5.
3.3. Classification Pipeline
The classification pipeline, illustrated in
Figure 1, consists of five main stages: data input, preprocessing, vectorization, model training, and evaluation. Each stage incorporates language-specific considerations to support robust multilingual classification.
During preprocessing, we first applied language detection using the langdetect [
25] library to ensure proper routing of each message to the correct processing stream. This was followed by tokenization and stop-word removal, implemented via NLTK [
26] modules tailored to each target language. For English, we applied lemmatization using WordNet [
27], whereas for Greek and French, we used the Snowball [
28] stemmer. Due to the morphological complexity of Arabic and Turkish, no lemmatization or stemming was performed in order to avoid semantic distortion in short-form texts. This choice follows prior work showing that aggressive stemming in morphologically rich languages can conflate semantically unrelated forms and degrade downstream classification performance in short messages. In all languages, non-textual noise such as URLs, emojis, and user mentions was removed, and for Greek, additional diacritic normalization was applied to standardize character representations.
All preprocessing steps were applied uniformly across models using fixed, reproducible routines to avoid pipeline-induced variability and to ensure that performance differences reflect model capabilities rather than differences in text handling.
Following preprocessing, two vectorization strategies were employed. For traditional ML models, we used TF-IDF representations. This included the application of Logistic Regression, Naive Bayes, and Random Forest classifiers. In parallel, for transformer-based architectures, we utilized sentence embeddings generated by two model families: SetFit [
29], which builds on MiniLM-L12-v2 [
30], MiniLM-L6-v2 [
31], and MPNet [
32], as well as Multilingual BERT (mBERT) [
9], which was fine-tuned both per language and on the combined multilingual corpus.
For training and evaluation, each model was trained using an 80/20 train-test split, and its performance was assessed using standard classification metrics: Precision, Recall, and F1-score. Given that the English and French subsets exhibited slight class imbalance, random oversampling was applied to the minority class in both cases to mitigate bias.
Random oversampling was preferred over more complex imbalance-handling strategies such as SMOTE or class-weight adjustment, because the small corpus and binary label space increase the risk of synthetic noise and unstable decision boundaries. Nonetheless, oversampling may still amplify idiosyncrasies of minority-class examples, so a degree of overfitting cannot be excluded and should be borne in mind when interpreting the reported scores.
Moreover, a multilingual (denoted as “Mixed”) corpus was constructed by aggregating all five language-specific subsets. This allowed for evaluating each model’s ability to generalize across languages under cross-lingual conditions.
The complete classification workflow is summarized in
Figure 1, which depicts the five main stages in sequence: data input, preprocessing, vectorization, training, and model evaluation.
For all neural models, we used a fixed random seed and standard training hyperparameters to facilitate reproducibility. SetFit and mBERT models were fine-tuned for a maximum of 5 epochs with early stopping based on validation loss, using a batch size of 16 and a learning rate of 2 × 10⁻⁵. Traditional ML classifiers relied on scikit-learn default settings, and no extensive hyperparameter optimization was performed, reflecting the exploratory, low-resource character of the study.
4. Evaluation and Results
To evaluate model performance, we used standard classification metrics: Precision, Recall, and F1-score. All models were trained on the same 80/20 split of the translated corpus, and, crucially, evaluated on a manually curated gold-standard test set consisting of 50 messages per language (250 instances in total). This unified test set was independently labeled by two domain experts and is identical for all architectures (traditional ML, SetFit, mBERT, and GPT-4o), ensuring that cross-model comparisons are made under strictly comparable conditions. Given the very small size of both the training and evaluation data, the reported scores are interpreted as descriptive indicators of relative behavior rather than definitive population-level estimates.
4.1. Performance on the Combined Multilingual Dataset
We begin with an overview of model performance on the “Mixed” multilingual corpus, where each model was evaluated based on its ability to generalize across five languages. As shown in
Table 4 and
Table 5, GPT-4o achieved the highest F1-score (0.84). Notably, it consistently demonstrated high Recall, reaching 0.92 in French and 0.88 in English. While mBERT achieved the highest score specifically in English (0.89), it was consistently outperformed by SetFit and GPT-4o in the Arabic and Greek subsets. This highlights the strong zero-shot multilingual generalization capabilities of modern LLMs without requiring task-specific fine-tuning. In
Table 4 and
Table 5, the best performance metric in each column is highlighted in bold, whereas the second-best is underlined.
As expected, traditional ML classifiers (e.g., Naive Bayes, Logistic Regression, and Neural Networks) achieved lower performance overall, especially in terms of Recall, which negatively impacted their F1-scores. Nevertheless, their inclusion provides useful baselines for evaluating the gains achieved by modern transformer-based and LLM approaches.
To quantify the uncertainty associated with the small evaluation set (n = 250), we additionally computed non-parametric bootstrap confidence intervals for all F1-scores on the mixed multilingual subset (1000 resamples). GPT-4o achieved an F1-score of 0.84 with a 95% confidence interval of approximately [0.77, 0.90], SetFit obtained 0.84 [0.76, 0.91], mBERT 0.80 [0.72, 0.87], and the best traditional ML baseline 0.80 [0.71, 0.88]. The substantial overlap between intervals indicates that the observed differences are descriptive rather than statistically decisive and reinforces the exploratory character of our findings in this low-resource setting.
To further assess whether the apparent performance gaps between top models are statistically meaningful, we applied McNemar’s test on the gold-standard test set. No pairwise comparison between GPT-4o, SetFit, and mBERT yielded a significant difference (all p-values > 0.19), suggesting that the ranking of models should be interpreted with caution, given the limited sample size.
These findings confirm that LLMs, such as ChatGPT (version GPT-4o), can serve as reliable multilingual classifiers, even in challenging contexts, and demonstrate state-of-the-art performance across both high-resource and low-resource languages.
To avoid overfitting on the extremely small multilingual dataset and to ensure reproducibility, no extensive hyperparameter optimization was performed. All transformer-based models (SetFit and mBERT) were trained using standard HuggingFace default configurations, while traditional ML classifiers used scikit-learn default settings. This approach aligns with recommended practice in low-resource scenarios, where aggressive tuning can artificially inflate performance and hinder comparability across models.
4.2. Per-Language Results
This section presents a detailed per-language performance comparison between four model categories: traditional ML classifiers (Naive Bayes, Logistic Regression, and Neural Network), SetFit few-shot sentence embedding models, the multilingual transformer mBERT, and a zero-shot LLM approach using ChatGPT (version GPT-4o).
Among traditional ML classifiers, only the best-performing model per language is included in each table for clarity and brevity. The ChatGPT-based classification was conducted via prompting: each message was fed to the model with a simple binary labeling instruction (“Is this message related to irregular migration?”). No fine-tuning or training was involved.
To ensure a direct and methodologically sound comparison across all architectures, we adopted a unified evaluation protocol. Every model—ranging from traditional classifiers and fine-tuned transformers (mBERT and SetFit) to the zero-shot LLM (GPT-4o)—was evaluated on the exact same manually curated gold-standard test set (n = 50 per language). This approach eliminates the variability inherent in different train-test splits and provides a consistent benchmark for assessing performance under identical conditions. By testing all models on the same independent evaluation set, we prevent data leakage and ensure that the comparative metrics reflect genuine model capabilities in detecting migration-related discourse.
Given the limited size of the per-language subsets, no statistical significance tests or confidence intervals were applied. In small-sample, imbalanced multilingual datasets, such tests may produce unstable or misleading estimates and are therefore not recommended for comparative model evaluation. The reported scores should be interpreted as descriptive indicators of model behavior in low-resource conditions rather than population-level statistical effects.
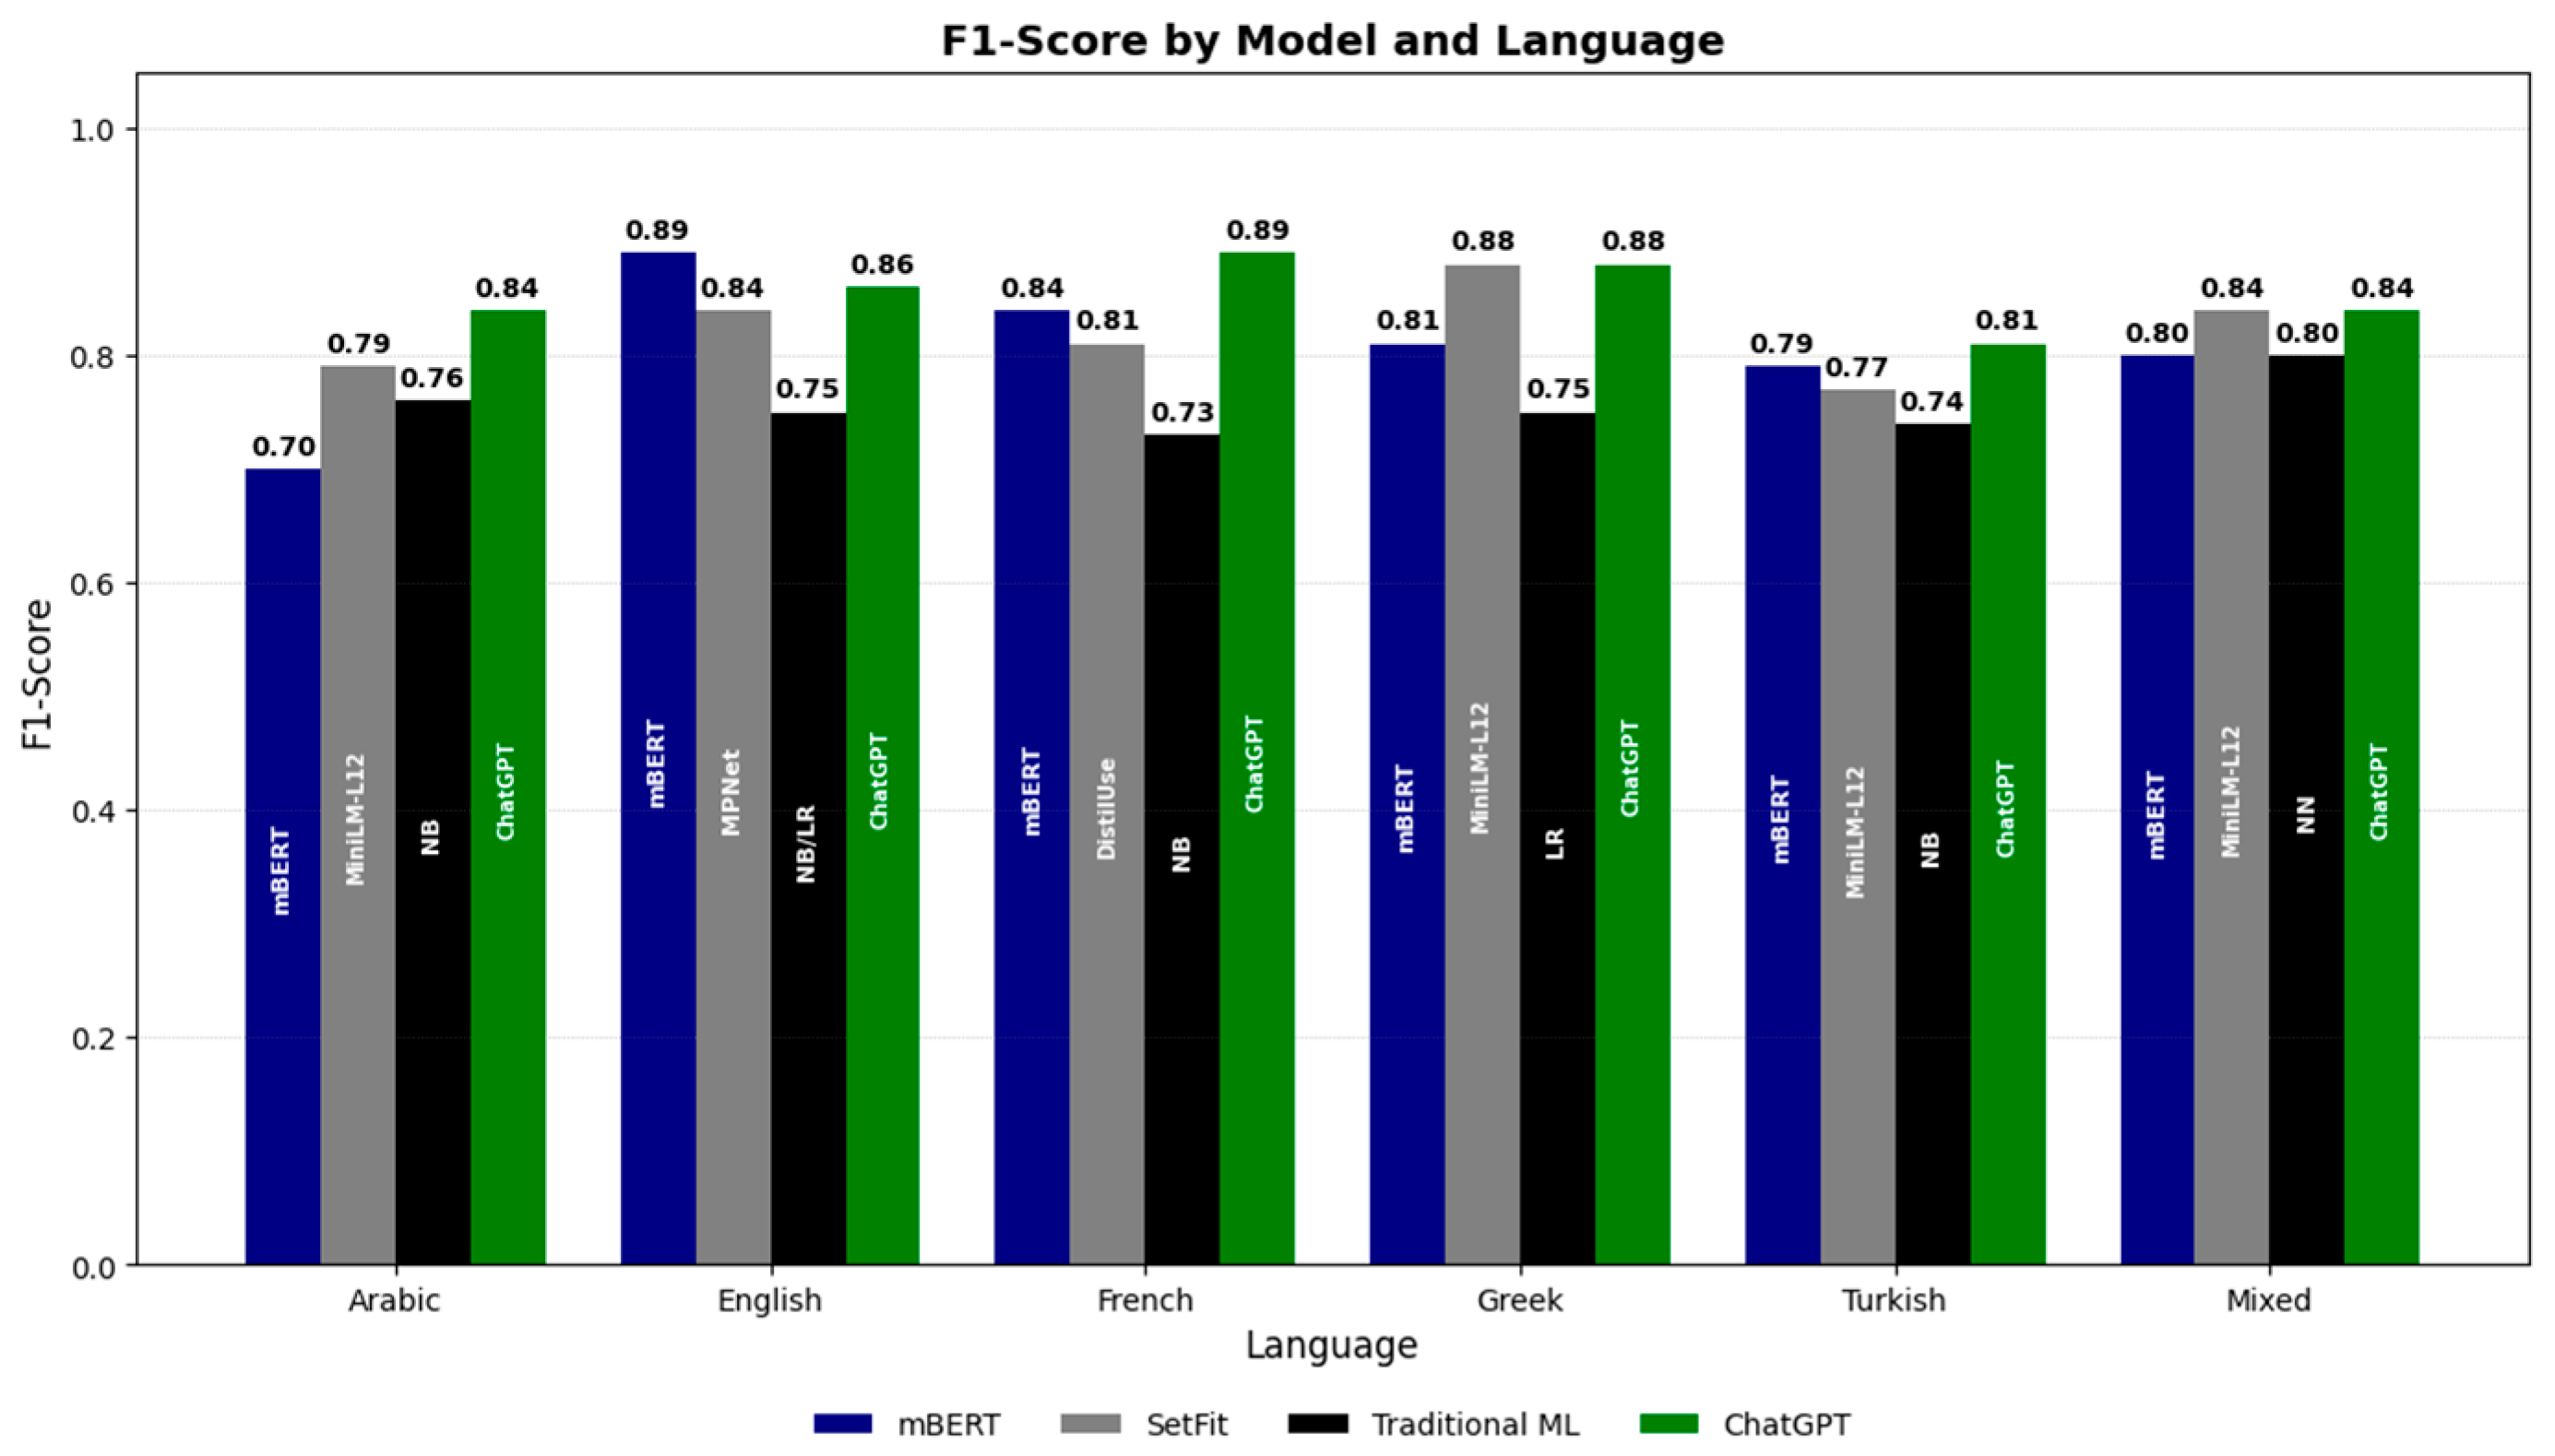
In the subsequent language-specific evaluations, ChatGPT (version GPT-4o) achieved the best F1-score in four out of five individual languages: French (0.89), Greek (0.88), English (0.86), and Arabic (0.84), and shared top performance in Turkish (0.81). These results indicate that LLMs can successfully handle diverse linguistic structures, even in low-resource or morphologically rich languages.
SetFit also performed competitively, particularly in Greek and Arabic, and maintained consistent results across all languages. mBERT showed strong performance in English and French, but its results were less robust in languages like Arabic and Turkish, possibly due to morphological challenges and limited original training data for those languages.
In the English subset, mBERT achieved the highest F1-score (0.89), followed closely by ChatGPT (version GPT-4o) (0.86) and SetFit (0.84), as presented in
Table 6. Both LLM and transformer models significantly outperformed traditional classifiers.
In the French subset, as presented in
Table 7, ChatGPT outperformed all other models, reaching an F1-score of 0.89, with excellent Recall. mBERT (0.84) and SetFit (0.81) also performed well, while Naive Bayes remained behind.
In Arabic, ChatGPT again led with an F1-score of 0.84, outperforming SetFit (0.79) and mBERT (0.70), as presented in
Table 8. Despite Arabic’s morphological richness, ChatGPT showed strong generalization in this zero-shot setting.
In Turkish, ChatGPT delivered the best performance (0.81), slightly above mBERT (0.79) and SetFit (0.77), as presented in
Table 9. This suggests that LLMs can handle agglutinative languages well in multilingual zero-shot tasks.
In the Greek subset, ChatGPT reached an F1-score of 0.88, narrowly surpassing SetFit (0.88) and mBERT (0.81), as presented in
Table 10. Despite Greek being a low-resource language in NLP, the LLM performed exceptionally well.
This comprehensive evaluation shows that zero-shot prompting with ChatGPT is a powerful alternative to supervised training and fine-tuning, particularly when labeled data is scarce or unavailable across languages. In
Table 6,
Table 7,
Table 8,
Table 9 and
Table 10, the best performance metric in each column is highlighted in bold, whereas the second-best is underlined.
4.3. Key Observations
Figure 2 illustrates the comparative performance (F1-score) of all evaluated models, Traditional ML, SetFit, mBERT, and ChatGPT LLM (version GPT-4o), across each language and the multilingual corpus. Several key observations emerge:
ChatGPT (LLM) achieved the highest F1-score in four out of five individual languages (French, Greek, English, and Arabic) and on the Mixed corpus, confirming its strong zero-shot generalization capabilities in multilingual and low-resource contexts. It consistently demonstrated high Recall, especially in French (0.92) and English (0.88), indicating strong sensitivity in detecting migration-related messages.
SetFit performed competitively, particularly in Greek and Arabic, where it closely matched or slightly trailed ChatGPT. Its few-shot learning structure and pretrained sentence embeddings enabled reliable performance even with small datasets.
mBERT showed strong results in high-resource languages (English and French) but underperformed in Arabic, likely due to morphological complexity and pretraining limitations. It was also outperformed by ChatGPT on the “Mixed” corpus.
Traditional ML models (Naive Bayes, Logistic Regression, and Neural Network) were consistently outperformed across all settings, particularly due to lower Precision or low Recall, which limited their F1-scores despite being fast and interpretable.
Random oversampling was effective in correcting minor class imbalance in English and French, improving Recall and F1-score for traditional models in those subsets.
Language-specific preprocessing, such as diacritic normalization in Greek, was applied to enhance text consistency and may have contributed to improved performance, particularly for rule-based and embedding-based models.
These findings suggest that LLMs like ChatGPT offer a scalable, training-free alternative for multilingual content classification tasks, especially in low-resource environments where annotated data is limited or expensive to obtain.
5. Discussion
In this section, we reflect on the thematic keyword classification proposed in
Section 3.2 and its implications for multilingual discourse analysis on irregular migration.
A preliminary breakdown of the positively labeled messages by thematic category (as shown in
Table 11) reveals that “Migration”, “Smuggling”, and “Border” dominate across languages, with “Smuggling” being more prominent in Arabic and Turkish content. This suggests potential variation in discourse framing across linguistic communities. This categorization enables a more granular understanding of the types of migration-related narratives that appear across platforms and languages.
The grouping of 31 multilingual keywords into 13 thematic categories, such as Migration, Smuggling, Transport, Border, Victims, and Authorities, offers a mid-level abstraction that bridges raw lexical indicators and high-level semantic interpretations. This structure facilitates not only improved interpretability of the annotation schema but also supports comparative linguistic analysis across languages. For instance, one could examine whether certain themes (e.g., “Smuggling” or “Victims”) are overrepresented in specific language communities or platforms, which may reveal culturally embedded framing patterns or targeted propaganda.
This trend is further illustrated in the aggregated keyword-category distribution. Preliminary distributional analysis shows that “Migration”, “Border”, and “Smuggling” were the most frequent categories associated with positive labels (i.e., messages deemed relevant to irregular migration). This indicates that OSN discourse often concentrates on border control and criminal framing. Future studies could explore the correlation between thematic category distribution and sentiment, stance, or bot activity, deeper insight into how migration is framed across languages and platforms.
Furthermore, this thematic taxonomy paves the way for future work on fine-grained or multi-label classification of migration-related discourse. While the present study focuses on binary relevance detection, integrating thematic classes could enable a more nuanced classification system capable of distinguishing between different narrative intents (e.g., humanitarian, securitized, or criminalized framings). This approach could also assist policymakers, media monitors, or NGOs in identifying shifts in public discourse and in detecting coordinated campaigns in specific thematic areas.
Finally, such mid-level categorization supports explainability in ML pipelines by providing a conceptual scaffold for interpreting model predictions. This aligns with the growing need for interpretable AI in sensitive domains like migration and security.
To support interpretability and transparency, each of the 31 multilingual keywords was manually assigned to one of 13 thematic categories based on semantic similarity and relevance to the irregular migration context. This grouping was carried out through an iterative labeling process, informed by prior literature on migration narratives, policy frameworks, and manual validation from bilingual coders. Categories such as “Smuggling”, “Border”, “Victims”, and “Authorities” were chosen to reflect core dimensions of migration discourse, both in media and institutional communication.
While the results are promising, this study has certain limitations that reflect the inherent challenges of multilingual, low-resource OSN research. First, the original corpus is constrained in scale due to the exploratory nature of this pilot study. The inclusion of Greek and French via translation does not replace organic multilingual content but rather serves as a diagnostic benchmark for evaluating model robustness under controlled data scarcity. As a result, the findings should be interpreted as exploratory performance indicators rather than statistically generalizable outcomes.
Second, although all translations were manually screened by bilingual annotators, machine translation may still introduce subtle semantic drift, especially in short informal messages. This limitation is common in multilingual NLP under data-scarcity conditions, but it underscores the importance of cautious interpretation of cross-lingual comparisons.
Consequently, the reported F1-scores represent upper-bound estimates under controlled conditions, not direct indicators of real-world performance.
Third, the rule-based annotation scheme—while validated by two domain experts—serves only as a reproducible heuristic rather than a definitive ground-truth layer. It may underrepresent implicit, ironic, or context-dependent references to irregular migration, and this may affect supervised learning performance.
Fourth, due to the limited size of per-language subsets, significance testing and confidence intervals were not applied, as they would not yield reliable or meaningful statistical conclusions.
Finally, the use of a manually validated 50-message evaluation set for zero-shot LLM benchmarking, while methodologically appropriate, reflects the broader need for larger multilingual labeled resources in this domain. Future efforts will focus on expanding the corpus, integrating human annotation, and exploring more comprehensive cross-lingual evaluation protocols.
Methodological Validity
From a methodological perspective, the main limitations of this work concern the very small number of original messages, the synthetic expansion through translation, and the reliance on a rule-based labeling scheme. These design choices inevitably constrain external validity and preclude any population-level inferences about migration discourse on X and Telegram. At the same time, they provide a transparent and reproducible testbed that isolates how different model families behave under tightly controlled, low-resource conditions, which is the primary contribution of this study. In light of these constraints, the present work should be understood strictly as a methodological pilot benchmark. Rather than claiming robust empirical effects, the study isolates relative model behavior under extreme data scarcity while providing bootstrap confidence intervals (
Section 4.1), McNemar’s tests (
p > 0.19), and multilingual error case studies (
Section 6) that offer concrete insights for future research. Its main value lies in the transparent pipeline and controlled benchmark that larger-scale studies can build upon.
6. Qualitative Error Analysis
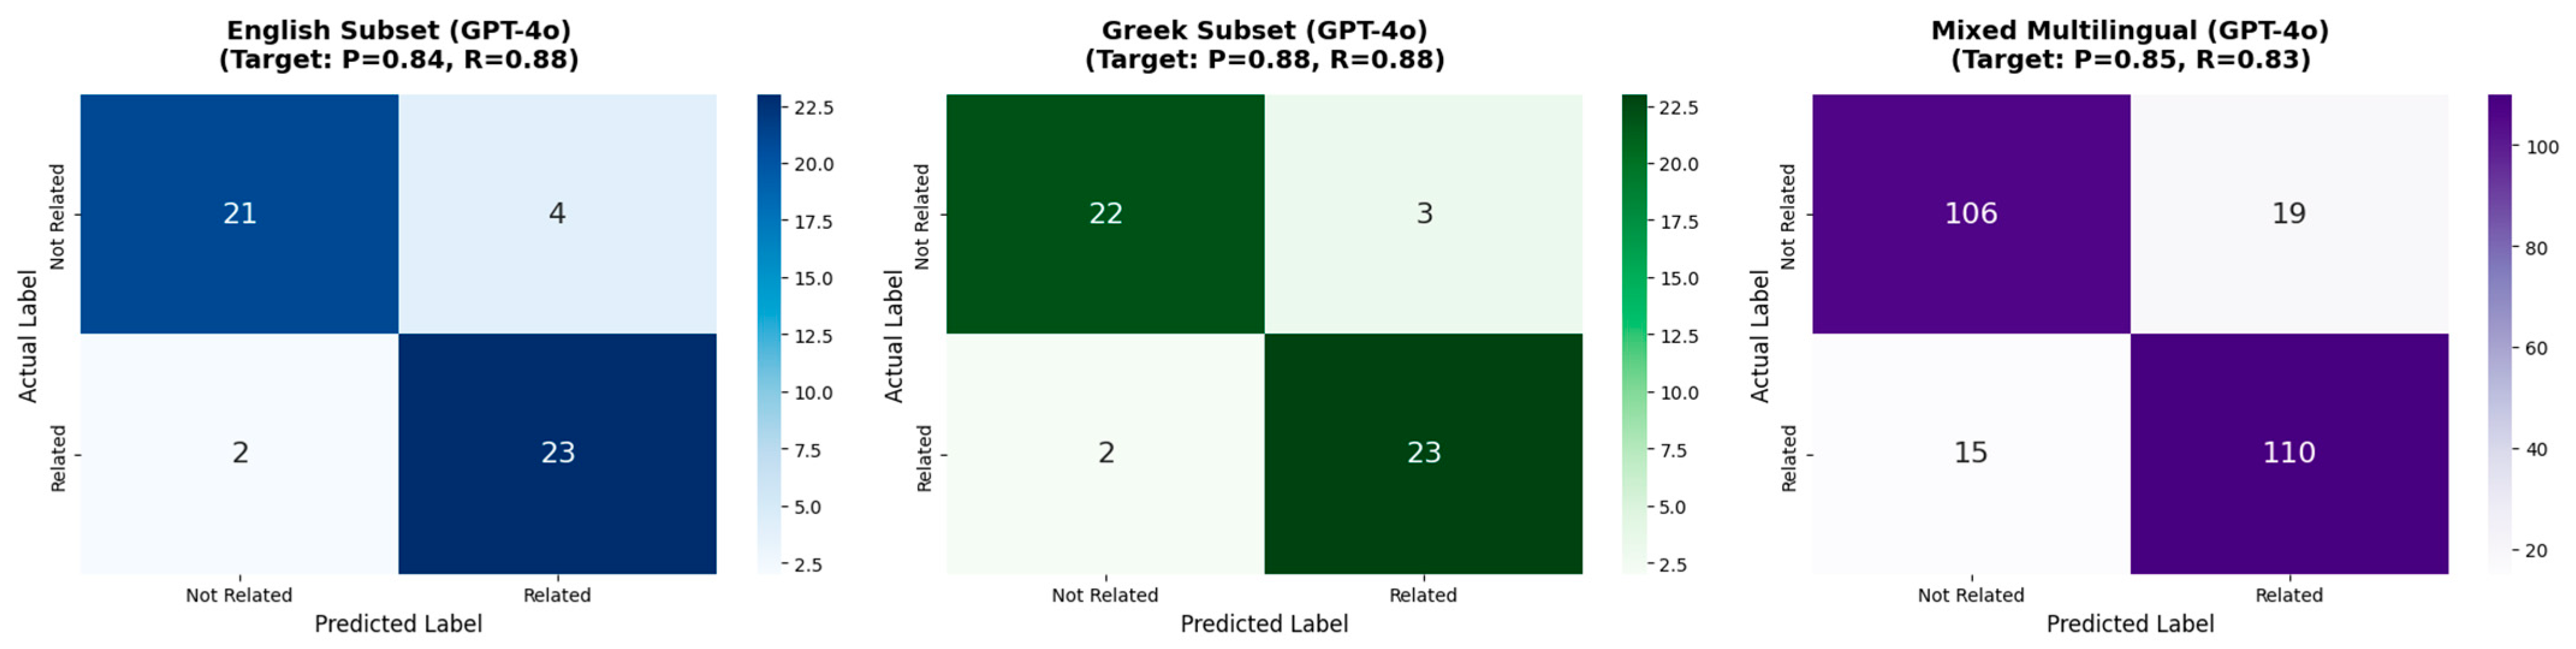
To provide deeper insight into model performance beyond aggregate metrics, we conducted a manual audit of misclassified instances. To provide a substantive error analysis, our qualitative audit identifies three distinct failure modes: (1) Lexical Ambiguity (false positives due to polysemy), (2) Contextual and Figurative Failures (misinterpretation of metaphors), and (3) Translation-Induced Noise (semantic shifts from automated translation). These are visualized in the updated Confusion Matrices (
Figure 3).
For illustration, we highlight three representative multilingual misclassification patterns that exemplify these challenges:
- 🙢
Arabic Morphology (False Negative): The message “المهاجرون وصلوا اليونان بعد عبور الحدود” (“Migrants arrived in Greece after crossing the border”) was correctly identified by GPT-4o as migration-related but misclassified by mBERT, which struggled with the inflected plural form of “migrants” in a noisy context. This highlights morphological parsing challenges in Arabic.
- 🙢
Greek Sarcasm (False Negative): The tweet “Μπράβο, πάλι οι βάρκες γεμάτες τουρίστες!” (“Great, the boats are full of tourists again!”) escaped detection by all models despite a clear ironic reference to migration, illustrating universal difficulty with figurative OSN language.
- 🙢
Turkish Translation Drift: Original “Denizden insanlar geliyorlar” (“People coming from sea”) → literal English “People are coming from the sea”. mBERT is classified as Negative (literal) and GPT-4o as Positive (context inference), demonstrating LLM robustness to translation artifacts.
Lexical Ambiguity (False Positives): Models relying on specific keywords occasionally failed when terms appeared in unrelated contexts. For example, in the Greek subset, the term “σύνορο” (border) triggered a False Positive in a message discussing holiday travel traffic (“Great weekend trip to the northern borders”), which the model incorrectly flagged as migration related. Similarly, in Arabic, the term “منظمة” (organization) led to misclassifications in tweets discussing general NGO activities unrelated to migration.
Figurative Language (False Negatives): While GPT-4o showed strong zero-shot reasoning, it occasionally missed messages using metaphorical language without explicit keywords. For instance, an English tweet stating, “They are flooding our neighborhoods” was classified as Negative because it lacked direct migration terminology (e.g., “refugee” and “immigrant”), despite the clear contextual implication.
Political Polarization: Distinguishing between general anti-government sentiment and specific irregular migration discourse proved challenging. In the Turkish subset, messages criticizing government “crisis management” (“kriz yönetimi”) were sometimes conflated with migration policy criticism, leading to False Positives.
7. Conclusions and Future Work
This study builds upon our previous work [
1] by proposing a multilingual NLP framework for detecting irregular migration-related discourse across two widely used platforms: X and Telegram. Our main contributions include the integration of rule-based keyword annotation, language-specific preprocessing pipelines, and comparative benchmarking of four model families: traditional ML classifiers (Naive Bayes, Logistic Regression, and Neural Networks), transformer-based models (SetFit and mBERT), and general-purpose LLMs, such as ChatGPT. Importantly, we incorporated underrepresented languages (Greek, Turkish, and Arabic), as well as Telegram data, which remains underexplored in computational social science despite its growing relevance for decentralized communication in migration contexts.
A key contribution of this work is the empirical demonstration that transformer-based approaches outperform traditional ML methods across all evaluated settings. Fine-tuned mBERT performed best in high-resource languages such as English and French, while SetFit showed superior performance in low-resource settings, including Arabic and Greek. The GPT-4o-based classification yielded the highest F1-scores overall (0.84), confirming that zero-shot prompting is a powerful alternative to supervised fine-tuning in low-resource contexts. Furthermore, SetFit proved to be a more robust transformer baseline than mBERT for morphologically rich or under-represented languages like Arabic and Greek.
A brief qualitative error analysis revealed recurrent failure modes across models. Misclassifications often involved highly contextual or ironic comments, where migration-related terms were used metaphorically or in political slogans, as well as news-style messages that mentioned migration only tangentially. In morphologically rich languages such as Arabic and Turkish, complex inflected forms and informal spelling also led to occasional tokenization errors and weakened keyword matches, particularly for the rule-based baseline. These patterns suggest that future models should better integrate contextual cues and morphology-aware representations to reduce ambiguity in short OSN messages.
Despite these limitations, the proposed framework offers a practical blueprint for multilingual early-warning dashboards and monitoring pipelines that can be scaled as larger, more balanced corpora become available.
Given the controlled translation setup, identical semantic content across languages, and the use of a manually curated gold-standard test set, the reported performance scores should be interpreted as upper-bound estimates under idealized experimental conditions rather than as indicators of real-world deployment performance.
Looking forward, future research may focus on enriching the multilingual corpus with additional underrepresented languages and regional dialects, especially from key migration corridors. There is also scope to experiment with large multilingual foundation models such as XLM-RoBERTa or mT5, and to explore few-shot or zero-shot classification scenarios using in-context learning. Moreover, forging collaborations with institutional actors such as FRONTEX or the European Union Asylum Support Office could support the operational deployment of this framework in applications like early warning systems and strategic communication monitoring.
By addressing both methodological and empirical gaps, this study lays the groundwork for more inclusive and linguistically diverse research on irregular migration discourse and supports scalable NLP applications in multilingual crisis informatics.
Overall, this work offers an initial multilingual NLP foundation for detecting migration-related narratives across X and Telegram under severe data scarcity. The framework and benchmark—supported by bootstrap confidence intervals (
Section 4.1), McNemar’s tests (
p > 0.19), inter-annotator reliability (
Section 3.2), and multilingual error case studies (
Section 6)—are not intended as deployment-ready tools, but as a transparent starting point for more extensive empirical research. Future studies with larger, organically multilingual corpora will be necessary to validate and extend the descriptive patterns observed here.