


Abstract
Fall from height (FFH) remains the predominant cause of fatalities and injuries in construction and industrial safety worldwide. Traditional accident cause analysis approaches often focus on single-factor identification or static statistical analysis, ignoring the hierarchical coupling and correlational relationship of multiple factors. To address this research gap, this study proposes a novel method based on an overlay network chain in quotient space to identify overlapping causal factor clusters in FFH accidents. First, a causal factor interaction network is constructed based on the similarity of causes. On this basis, an overlay network chain in quotient space is established to identify overlapping causal factor clusters. The proposed method is validated using real FFH accident data. Results demonstrate that this approach effectively identifies hidden high-risk overlapping clusters that are undetectable by traditional methods. Notably, Cluster C5—comprising PPE non-compliance, inadequate supervision, unverified qualifications, and insufficient training—exhibits the highest occurrence rate (0.072) and structural vulnerability (CVI = 9.5), identifying it as the most critical risk pattern. The identified clusters are highly consistent with practical engineering experience. This study provides a systematic, data-driven tool for FFH accident causation analysis, supporting targeted safety prevention and control strategies.
1. Introduction
Falls from height accidents are among the most harmful accidents in occupational safety [1,2]. Among various construction safety hazards, fall-from-height (FFH) accidents consistently rank first in terms of occurrence frequency and casualty rate, occupying a dominant proportion of construction fatal and injury accidents [3,4]. Studies report that up to 51% of fall-related accidents occur in the construction industry [5], across all project stages from site preparation and structural framing to façade installation and interior finishing [6]. According to Hamid et al. [7], construction-related fatalities occur at a rate over three times higher than in alternative sectors, emphasizing the imperative for enhanced and effective safety interventions.
Haslam et al. [8] noted that ineffective safety implementation persists as a ubiquitous challenge within the global construction sector. They identified a multifaceted array of contributing factors, encompassing deficiencies in safety system design, substandard maintenance routines, defective machinery, insufficient supervision, and inadequate workforce training. Furthermore, their statistical analysis revealed that fall-from-height (FFH) incidents, pedestrian slips on access walkways, and impacts from falling objects constitute the most frequent categories of on-site accidents. Wong et al. [9] identified that fall incidents in construction are predominantly driven by deficiencies in safety training, inadequate height-access equipment, unsafe operational behaviors among workers, and a lack of sufficient oversight. Their findings underscore the severity of the problem: falls account for nearly 50% of fatal construction accidents in Hong Kong, and Zaini et al. [10] reported that FFHs in Malaysia cause not only human suffering but also substantial project delays from accident investigations, worker replacement, retraining, and compensation.
Affected by human factors, equipment conditions, environmental conditions, and management defects, FFH accidents present typical characteristics of multi-factor coupling, complex interaction, and nonlinear evolution [11]. A single accident is not caused by an independent factor but by the joint action of multiple interrelated factors [11,12]. Therefore, clarifying the interactive relationship and community structure of FFH accident causal factors is crucial for revealing accident formation mechanisms and formulating targeted prevention measures.
In recent years, domestic and foreign scholars have carried out extensive research on the causal analysis of construction FFH accidents [13]. Common research methods include statistical analysis, random forest [14], fault tree analysis (FTA), event tree analysis (ETA), Bayesian network [15], and traditional complex network clustering algorithms [16,17]. These methods can effectively screen key accident factors and analyze the correlation between single factors and accidents to a certain extent.
Based on an examination of 621 fatal falls, Chi et al. [18] clustered the contributory elements into worker-centric, equipment-centric, and management-centric categories. Worker-related factors encompass excessive strain, irregular control, inadequate operations, and the removal of safety equipment; tool-related factors cover technical malfunctions, unsafe apparatus, and unstable ladders. In the management domain, the study highlighted severe lapses, including unshielded holes, violations of scaffolding regulations, illicit access to high-risk sectors, and occupational exposure to harmful environments. Zermane et al. [19] identified three root causes of fatal work-at-height accidents: failure to wear personal protective equipment (PPE), inadequate supervision and leadership, and missing or improperly followed work standards.
Abdelhamid and Everett [20] delineated three fundamental root causes of construction accidents: the pre-task failure to identify potential site hazards, the execution of work in the absence of adequate safety knowledge, and the intentional engagement in unsafe practices despite an awareness of the associated dangers. Their contribution has significantly advanced accident investigation frameworks by incorporating a human error analysis perspective.
According to Khanh et al. [2], among the various determinants of FFH, unstable scaffolding and ladders were ranked as the topmost critical hazard. These risks were subsequently categorized into five distinct domains, namely, hazards tied to structural and site conditions, workforce factors, environmental interactions and worker characteristics, organizational management and safety protocols, as well as worker competency and tool-related issues. However, this study was limited to a qualitative categorization of these factors and lacked a rigorous statistical screening process to identify the primary drivers. More importantly, the latent coupling relationships and synergistic interactions among these distinct risk domains were not systematically examined.
However, existing studies still have obvious limitations in mechanism exploration. Most traditional clustering and community detection methods follow the principle of exclusive attribution, that is, each causal factor can only be divided into a single independent community [21]. This rigid partition cannot reflect the actual situation of construction accidents, where one causal factor often has multiple attribute characteristics and participates in different accident evolution chains simultaneously. The ignorance of overlapping causal community structures leads to incomplete excavation of implicit factor coupling relationships, resulting in insufficient depth of accident mechanism analysis and limited practical guiding value for on-site safety management.
To overcome the above deficiencies, this study introduces quotient space theory into the causal analysis of FFH accidents and proposes an overlapping causal community mining method based on a quotient space covering network chain [21,22]. Different from traditional single-attribution analysis methods, this method realizes hierarchical granulation and structural mining of causal factor networks, which can effectively identify overlapping causal factor communities and accurately describe the multi-role and multi-path participation characteristics of accident factors [23]. Compared with conventional models, the proposed method better conforms to the complex and uncertain evolutionary laws of actual construction safety accidents.
The main contributions of this study are summarized as follows: (1) an interactive relationship network of FFH accident causal factors is constructed, which quantitatively visualizes the complex correlation and interaction topology of accident influencing factors. (2) An overlay network chain in quotient space is innovatively applied to mine overlapping causal factor clusters of FFH accidents, breaking through the single-attribution limitation of traditional clustering methods. (3) The effectiveness and superiority of the proposed method are verified based on real FFH accident data, which provides a new perspective for refined causal analysis and targeted risk prevention of construction FFH accidents.
2. Materials and Methods
This section elaborates the overall research framework and detailed implementation procedures adopted to explore the causal mechanisms of FFH accidents. The core research idea is to integrate complex network theory with quotient space theory to achieve overlapping causal factor cluster mining and reveal the multi-association characteristics of accident influencing factors. The detailed methodology is divided into three key parts: construction of the FFH accident causal factor interaction network, establishment of the quotient space overlay network chain model, and empirical verification design.
2.1. Extracting Accident Causal Factors
The accident investigation report contains a large number of actual records related to the accident, and the content is true and valid [24]. The accident investigation report describes in detail the time of the accident, the process of the accident, the overview of the unit in which the accident occurred, the casualties and the basic information of the injured and the property damage, etc., and analyzes the nature of the accident, the causes of the accident, and the division of responsibility for the accident [25]. Therefore, the potential causative factors of FFH accidents can be obtained from accident investigation reports.
According to the Classification and Coding of Dangerous and Hazardous Factors in Production Processes (GB/T 13861-2022) [26], the causes of fall from height accidents can be categorized into four aspects: people-related factors, facility-related factors, environment-related factors and management-related factors, each of which contains many sub-factors [1,15]. All the sub-factors constitute the data set of FFH causal factors. If the causes of an FFH accident include np people-related factors, nf facility-related factors, ne environmental-related factors, and nm management-related factors, the causes of the FFH accident ai can be expressed as the vector [P1, P2, …, Pnp, F1, F2, …, Fnf, E1, E2, …, Ene, M1, M2, …, Mnm]; an FFH accident has n = np + nf + ne + nm causal factors. The causal factors of m FFH accidents can be represented by the accident cause matrix Mac(m × n). Mac(i × j) = 1 if factor j(1 ≤ j ≤ n) is included in the causes of accident ai.
2.2. Constructing Causal Factor Interaction Network
FFH accidents are caused by a combination of many causes, including people-related factors, facility-related factors, environment-related factors and management-related factors [27,28]. According to FFH accident investigation reports, the same FFH accident contains several different types of accident causation, and the same accident causation may occur in different FFH accidents [11,29]. Accidents are not caused by a single cause; they are the result of a combination of causes [1,11]. These causes have potential correlations with each other, and if these clusters of causes with correlations can be found, the occurrence of fall from height accidents can be better prevented [27].
The FFH accidents causal factor interaction network is constructed using complex network theory. In the network, each node represents an independent causal factor, and each edge represents the interaction between two factors [30,31,32]. The Jaccard similarity is used to measure the interaction strength between accident causes; the interaction strength between cause ci and cj is defined as follows [33,34]:
where Mac(:,i) and Mac(:,j) denote column i and column j of the accident causation correlation matrix Mac(m × n), respectively. |Mac(:, i) ∩ Mac(:, j)| is the number of fall from height accidents where causes ci and cj occur together. |Mac(:, i) ∪ Mac(:, j)| is the number of fall from height accidents where accident causes included causes ci and cj. Accident investigation report data have false positives and false negatives because of human influence in the accident investigation report records, so we consider the interaction strength between cause ci and cj to be credible only if the interaction strength between cause ci and cj is greater than a certain threshold JacTh [35,36].
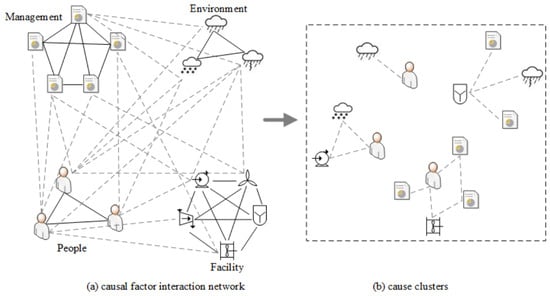
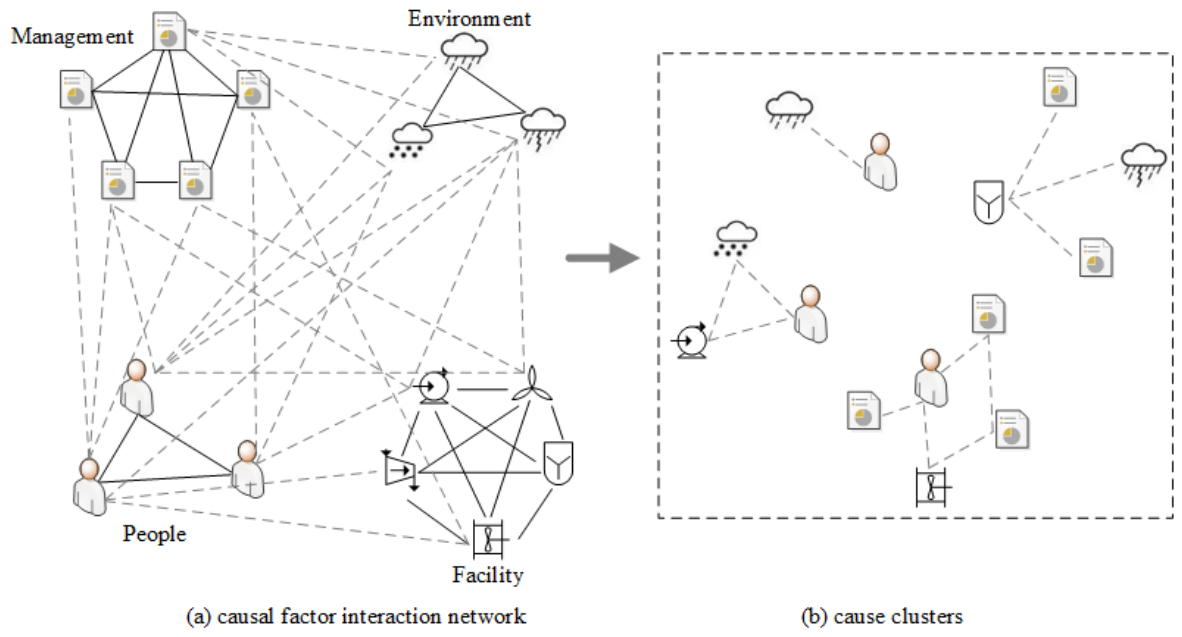
An example is shown to explain the causal factor interaction network. Figure 1a shows the schematic diagram of causal factor interaction network, where each node represents a cause and two nodes are connected by an edge if the interaction strength between the two causes is greater than the threshold JacTh. If the value of interaction strength is less than JacTh, it is considered that there is no interaction between the two factors, and the edge between the corresponding nodes is not established in the network. The causal factor interaction network is represented by an adjacency matrix Madj(n × n).
Figure 1.
Schematic diagram of causal factor interaction network and causal factor clusters.
2.3. Construction of Quotient Space Overlay Network Chain
After the causal factor interaction network is constructed, the quotient space overlay network chain can be applied to mine the causal factor clusters, as shown in Figure 1b.
2.3.1. Quotient Space Theory
Quotient space theory provides a formal framework for hierarchical abstraction. A problem space is represented as a triple (X,F,T), where X is the domain, F is the set of attributes, and T is the structure [37]. By defining a relation on X—either an equivalence relation or a compatibility relation—the original space can be coarsened into a quotient space ([X],[F],[T]). The granularity coefficient gc controls how aggressively this coarsening is applied. In the present study, the domain X corresponds to the nodes of the causal factor interaction network [38].
2.3.2. Quotient Space Overlay Network Chain
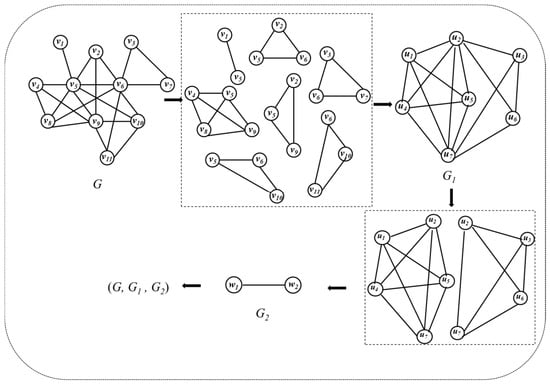
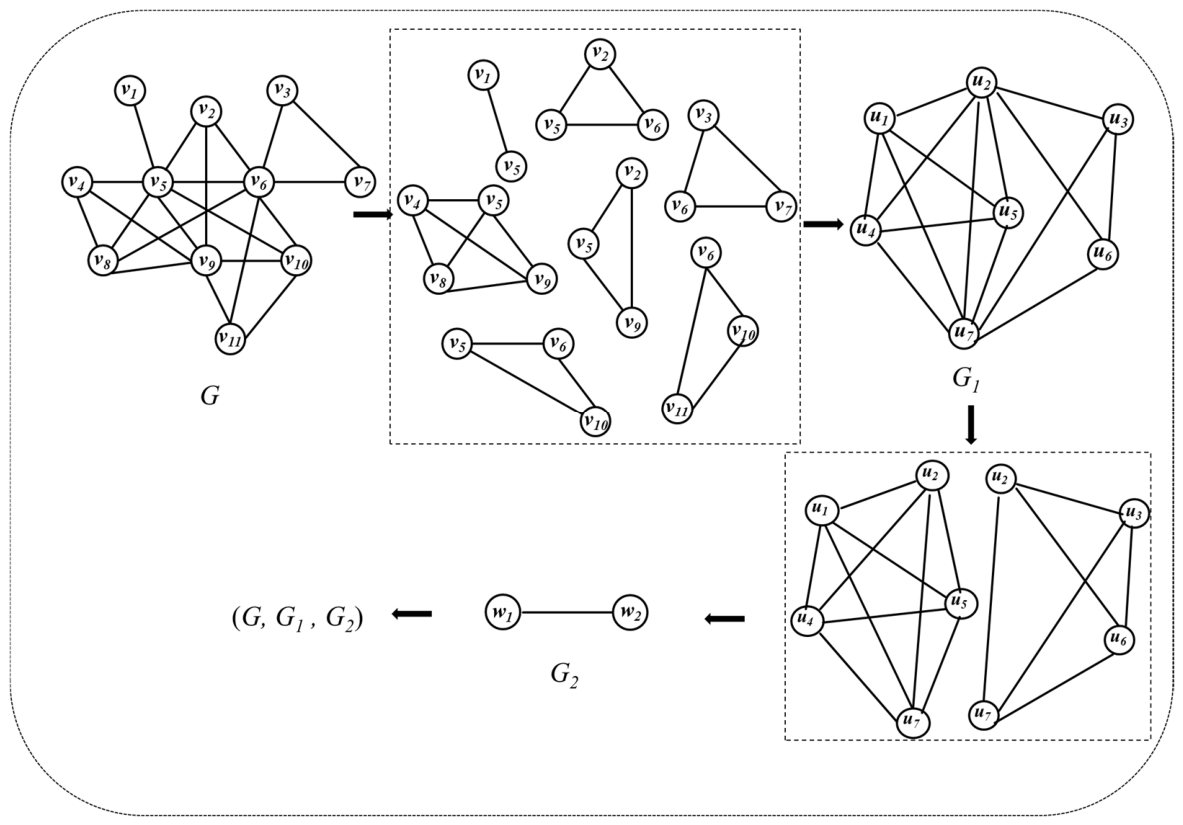
For the causal factor interaction network, each maximal complete subgraph is treated as one cover under the compatibility relation [39]. A maximum complete subgraph, also known as a maximum clique, is a vertex subset in an undirected graph such that every two distinct vertices are adjacent, and it contains the largest possible number of vertices among all complete subgraphs of the graph. Once all maximal cliques are identified, each clique becomes a node in a new network. Two such nodes are connected whenever their cliques share at least one factor; the resulting network is the quotient-space overlay network of that granularity level. Figure 2 illustrates how the overlay networks are chained across levels.
Figure 2.
Construction of quotient space overlay network chain.
Assuming that Gi is the ith level quotient space overlay network of G, and Gi+1 is the 1st level quotient space overlay network of Gi; therefore, Gi+1 is the (i + 1)th level quotient space coverage network of G. (G, G1, G2, …, Gi) is called a quotient space coverage network chain. In the quotient space overlay network, each node represents a maximum complete subgraph. There are repeated points and edges between maximal complete subgraphs. So overlapping causal factor clusters can be found by using the quotient space covering network [38].
The causal factor interaction network is usually described as an undirected graph G(V, E). In quotient space overlay network theory, Formula (3) is used to measure the similarity of two maximal complete subgraphs mcsi and mscj.
where |mcsi ∩ mcsj| is the number of the common nodes of mcsi and mscj, |mcsi ∪ mcsj| is the sum of the nodes of mcsi and mscj. Only when sim(mcsi, mcsj) is greater than the granularity coefficient gc, two corresponding nodes are defined to be connected in the next generation quotient space overlay network. In ith level quotient space overlay network, if there is no maximal complete subgraph satisfying the similarity condition, the quotient space overlay network chain (G, G1, G2, …, Gi) can be obtained. At this point, each node in Gi represents a causal factor cluster.
3. Results
To verify the scientificity, effectiveness, and practical applicability of the proposed method, real FFH accident data is selected to ensure the authenticity and representativeness of the verification results and to conduct a comprehensive comparison and evaluation of the results.
3.1. Data Preparation
3.1.1. Data Source
To ensure the authenticity and representativeness of the experimental data, this study collects real FFH accident data from 2018 to 2025 from three sources:
- (1)
- Official accident investigation reports released by the Ministry of Housing and Urban-Rural Development of China and the Emergency Management Bureau, which provide detailed information on accident causes, occurrence processes, and casualties.
- (2)
- The safety accident records of the government’s other departments including on-site investigation records, hidden danger inspection records, and accident handling reports.
- (3)
- Records of safety accidents disclosed by large construction enterprises in China.
A total of 563 accident reports of fall from height accidents were obtained, and after data cleaning, excluding cases with incomplete information, unclear causes, or obvious data errors, 526 valid accident reports were obtained. The cases cover different regions, different construction types, and different accident severity levels, ensuring the comprehensiveness and representativeness of the data [40,41].
3.1.2. Causal Factor Extraction and Coding
Based on the collected FFH accident investigation reports, the BoW (Bag-of-Words) method, combined with manual analysis, was used to identify the causal factors of fall-from-height accidents in construction [42]. BoW is a widely used text representation method that encodes a document as a frequency vector over a predefined vocabulary. In this approach, word order and syntactic structure are ignored, and the importance of each word is determined by its occurrence frequency in the document. From the preprocessed text, a vocabulary is first generated in which each unique word is assigned a distinct integer index, for example, {“PPE”: 1, “training”: 2, “subcontracting”: 3, …}. For each document, a vector of length equal to the vocabulary size is then constructed: each dimension corresponds to one vocabulary entry, and the value in that dimension indicates how many times the corresponding word appears in the current document.
The specific procedure is as follows:
- (1)
- Data preprocessing. Text cleaning was performed on the 526 selected accident reports, including the removal of irrelevant information, punctuation marks, and numbers.
- (2)
- Text vectorization. Text vectorization methods such as BoW were applied to convert the cleaned text into numerical representations.
- (3)
- Key factor extraction. Feature selection was performed on the BoW vectors to integrate identical or similar terms, and the 32 most frequent keywords or phrases were selected as the primary causal factors. These factors were further refined through manual screening and analysis based on domain expertise and relevant literature.
Finally, 32 key causal factors are identified according to the Classification and Code of Dangerous and Hazardous Factors in the Production Process (GB/T 13861-2022) and expert consultation, which are divided into 4 categories: 7 factors related to people, 5 factors related to facilities, 3 factors related to the environment, and 17 factors related to management. The specific contents of each factor and its number are shown in Table 1.
Table 1.
The data set of FFH causation factors.
The accident cause matrix contains 526 rows and 32 columns, each row represents an FFH accident, and each column represents an accident causation factor. If the accidental cause of a fall from height accident i includes the causation factor j, the accident cause matrix Mac(i × j) = 1.
3.2. Experimental
3.2.1. Hardware and Software Environment
To ensure the smooth progress of the experiment, the following hardware and software environments are used:
- (1)
- Hardware: CPU (Intel Core i7-8700, 3.2 GHz), RAM (16 G), hard disk (1 TB), which can meet the requirements of data processing and complex network calculations.
- (2)
- Software: Operating system (Windows 11 Professional), programming language (Matlab R2019a), visualization tools (Cytoscape 3.7.2).
3.2.2. Model Parameters Setting
The proposed model has two key parameters: interaction strength threshold JacTh and granularity coefficient gc [38].
- (1)
- Interaction strength threshold JacTh
In the causal factor interaction network, two nodes are connected by an edge if the interaction strength between the two causes is greater than the threshold JacTh. If JacTh is set too low, many weakly supported co-occurrence pairs are retained as edges, which inflates the network and dilutes the core couplings. If it is set too high, weakly but genuinely associated pairs are removed, producing isolated factors and incomplete clusters.
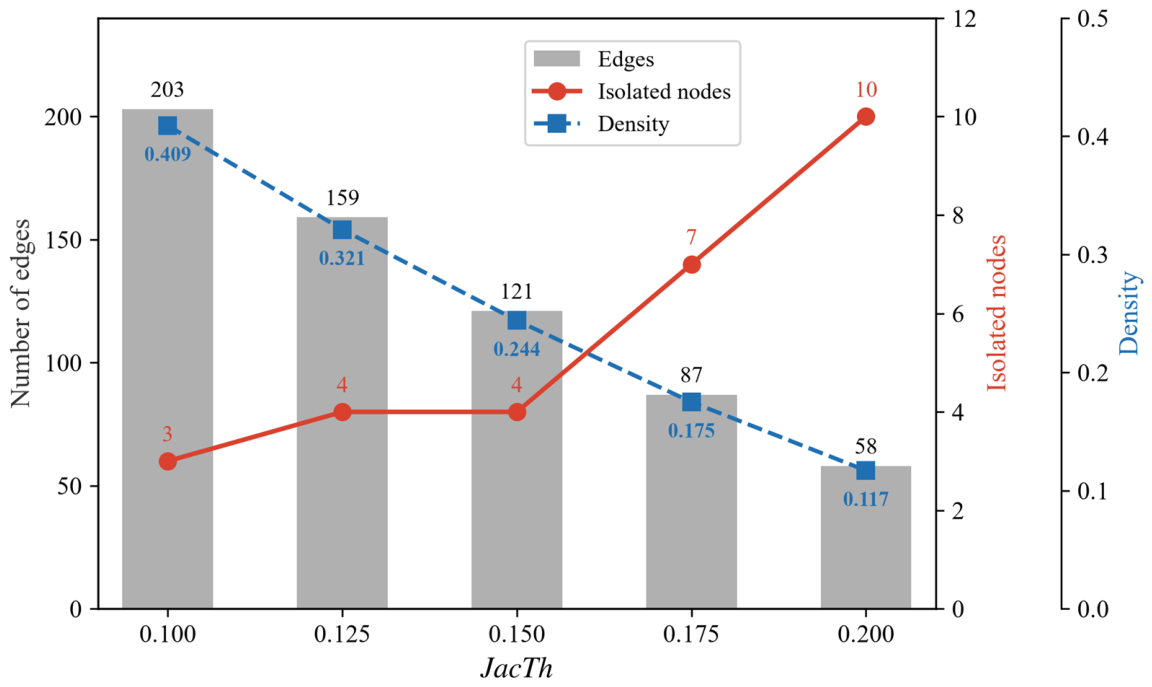
Since the overlapping causal clusters detection builds on the causal factor interaction network, the stability of the network directly governs the extracted causal clusters. Figure 3 reports how structural indicators of the network vary with the threshold JacTh. As JacTh rises from 0.10 to 0.20, the number of retained edges decreases from 203 to 58, and the network density drops from 0.409 to 0.117. At the lower end (JacTh = 0.10), the high density (0.409) indicates that many weakly supported co-occurrences are retained, which dilutes the core couplings and weakens the network’s discriminative power. At the upper end (JacTh = 0.20), the density falls to 0.117 and ten factors become isolated, so that the detected clusters omit a substantial part of the system. In contrast, at JacTh = 0.15 the network retains 121 edges with a density of 0.244, keeping 28 of the 32 factors in the giant component while only four low-frequency factors remain isolated. JacTh = 0.15, therefore maintaining a reasonable balance between network coverage (28 active factors) and structural density (0.244), and is adopted as the working threshold in the subsequent analysis.
Figure 3.
Causal factor interaction network structure vs. interaction strength threshold JacTh: number of retained edges (gray bars), number of isolated nodes (red solid line), and network density (blue dashed line).
- (2)
- Granularity coefficient gc
In the overlay network, two cliques are merged into a node at the next level whenever their similarity exceeds gc. If gc is too small, the cliques are over-connected and the model inflates; if gc is too large, meaningful clusters are split and accuracy drops. Selecting a suitable gc is therefore essential. Based on the experience and the available references, the granularity coefficient gc is set to 0.4.
3.2.3. Experimental Procedures
The specific experimental procedures are carried out in accordance with the following steps, ensuring the repeatability and rigor of the experiment:
Step 1: Data processing. Sort out the collected 526 FFH accident reports, extract 32 causal factors, and code them according to Table 1. Clean the data to remove duplicate and invalid information, and establish the accident cause matrix.
Step 2: Construction of causal factor interaction network. Based on the accident cause matrix, quantify the interaction strength between each pair of factors by Formula (1). Nodes in the network represent causal factors; two nodes are connected by an edge if the interaction strength between the two causes is greater than the threshold JacTh.
Step 3: Construction of the quotient space overlay network chain on the causal factor interaction network according to Section 2.3.2.
Step 4: Mining overlapping causal factor clusters. In the final level of the quotient space overlay network, each node represents a causal factor cluster.
Step 5: Result analysis and verification.
3.3. Experimental Results
3.3.1. Construction of Causal Factor Interaction Network
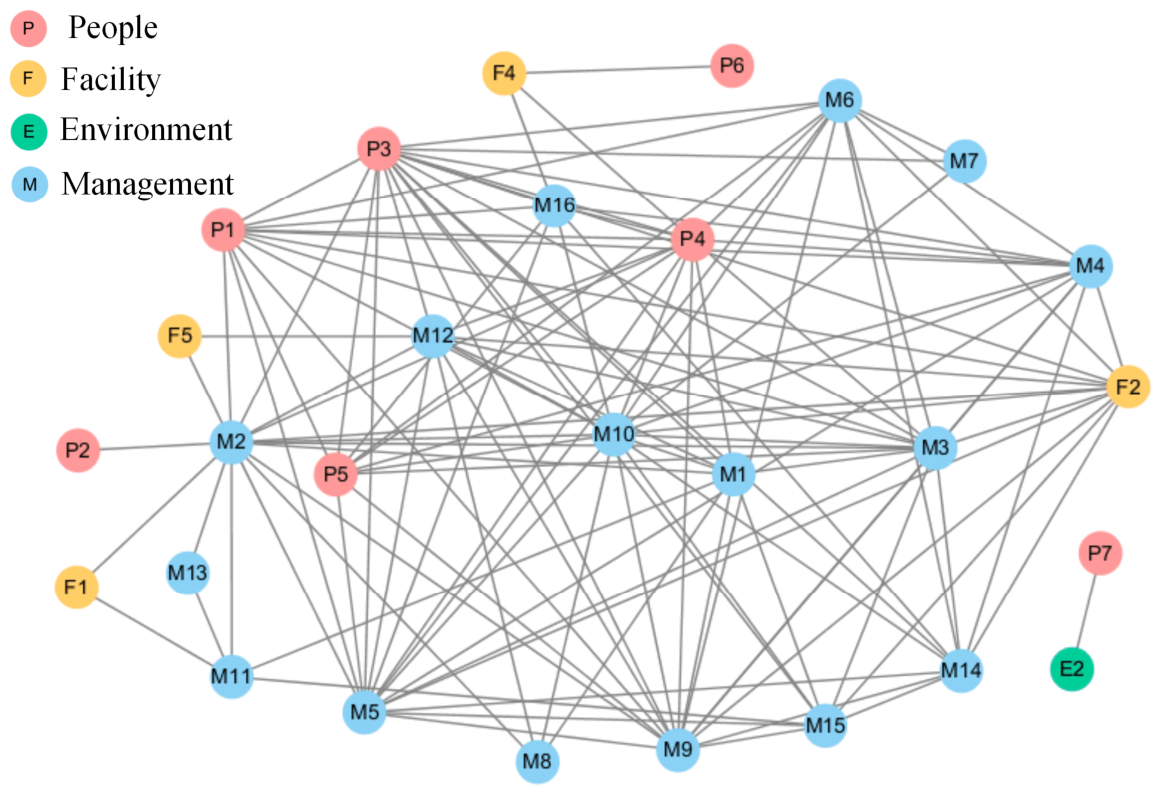
The interaction strength between causes ci and cj is calculated using Formula (1); the causal factor interaction network is represented by an adjacency matrix Madj(32 × 32); the adjacency is determined according to Formula (2). After removing the isolated nodes, the final causal factor interaction network contains 28 nodes and 121 edges. The causal factor interaction network is shown in Figure 4.
Figure 4.
Causal factor interaction network.
3.3.2. Causal Factor Clusters
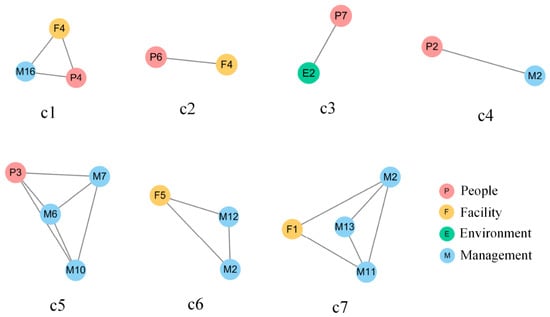
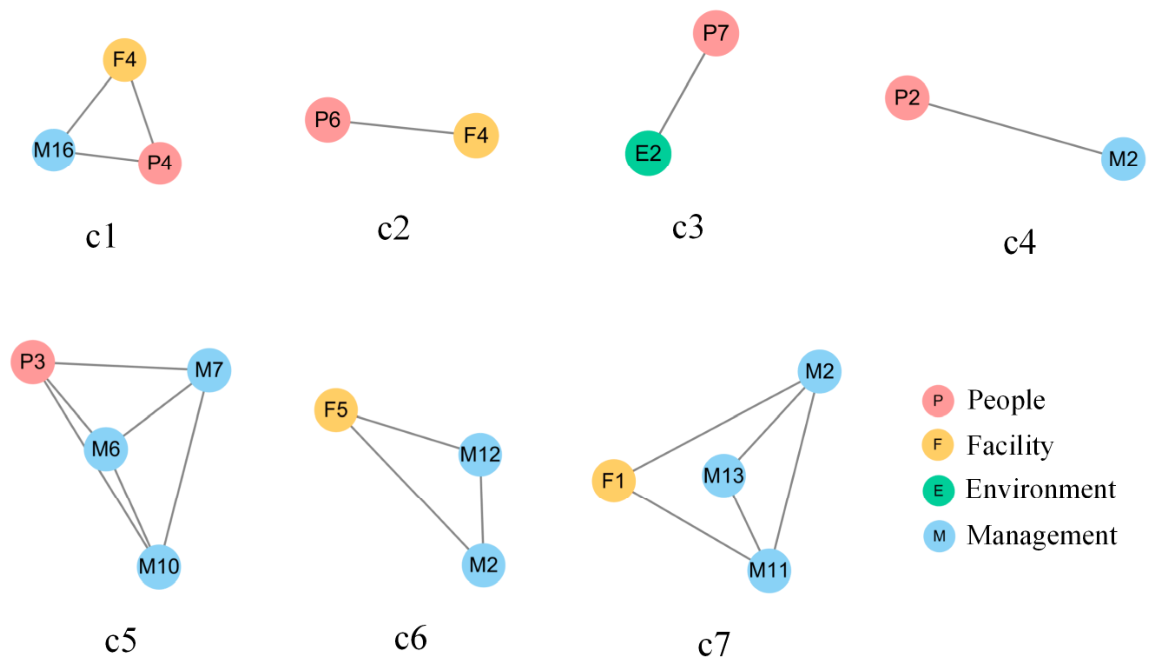
Applying the quotient space overlay network chain model to the causal factor interaction network, seven FFH causal factor clusters are obtained as shown in Table 2.
Table 2.
Seven FFH Causal factor clusters.
To visually demonstrate the coupling relationship among factors, the results were visualized. The visualization effect is shown in Figure 5.
Figure 5.
Accident causal factor clusters.
As presented in Table 2 and Figure 5, the proposed method successfully mines seven overlapping causal factor clusters (C1–C7). A considerable number of factors appear in multiple clusters, directly verifying the significant overlapping and coupling characteristics of FFH accidents.
Cluster C1 is characterized by unlicensed working (P4), substandard tools (F4), and inadequate fulfillment of management responsibilities (M16). This cluster represents a typical coupling of illegal operation and weak on-site management.
Cluster C2 highlights the joint effect of unsafe equipment (P6) and non-compliant tools (F4), reflecting facility-induced risks.
Cluster C3 connects poor personal health conditions (P7) and severe weather (E2), revealing the combined impact of individual and environmental conditions.
Cluster C4 couples insufficient risk judgment (P2) with irregular contracting (M2), indicating risks caused by qualification and awareness defects.
Cluster C5 is dominated by PPE misuse (P3), inadequate on-site supervision (M6), lack of qualification verification (M7), and insufficient safety training (M10).
Cluster C6 links defective equipment (F5), irregular contracting (M2), and unapproved construction schemes (M12), showing chain failure of equipment and management.
Cluster C7 involves sign marking defects (F1), irregular contracting (M2), missing construction permit (M11), and absent safety agreements (M13), representing procedural management failure.
Overall, the extracted clusters clearly reveal the multi-group, overlapping, and coupled formation mechanism of FFH accidents, which is highly consistent with real accident evolution laws.
4. Discussion
4.1. Distribution of Causal Factors
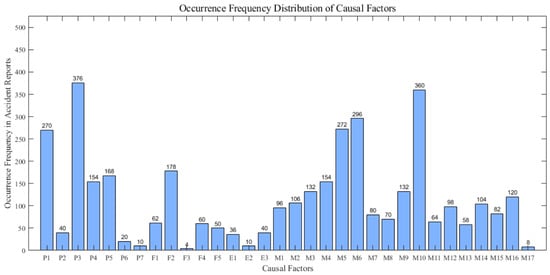
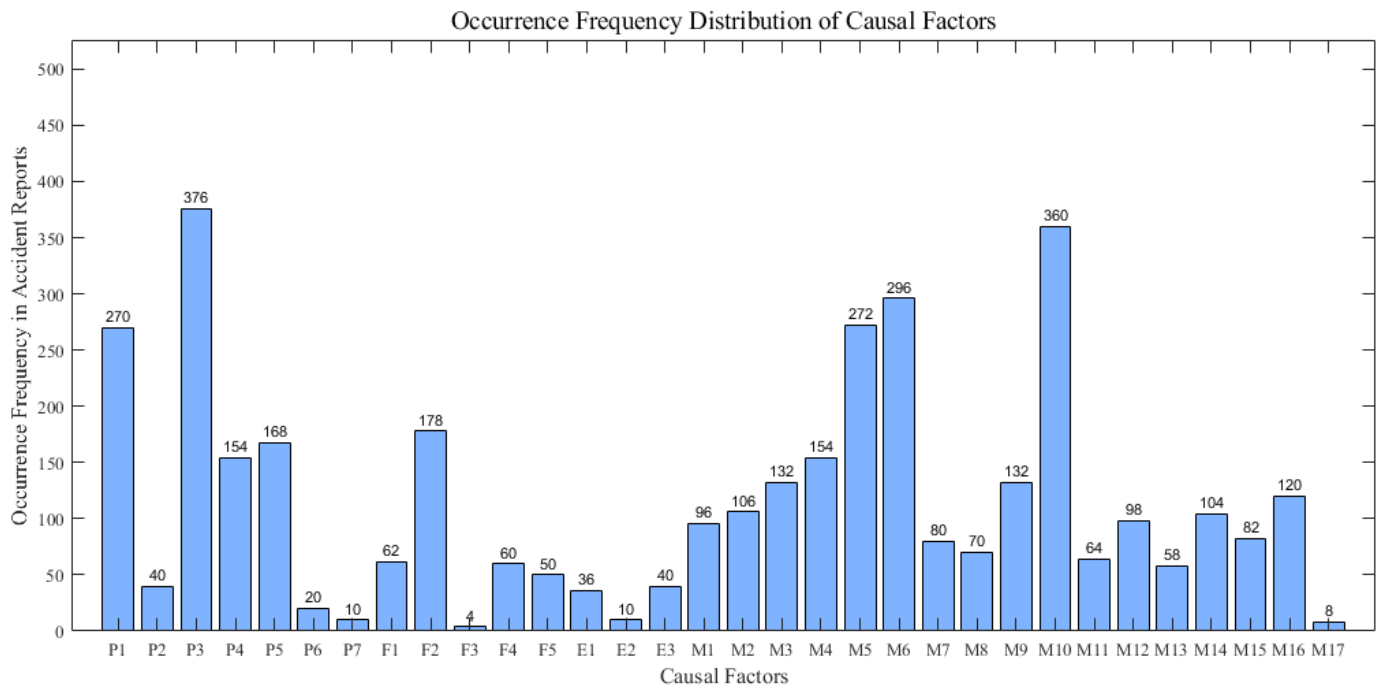
Figure 6 visually displays the occurrence frequency of all screened causal factors derived from accident records, serving to identify dominant hazard sources and differentiate contribution degrees of various factor categories.
Figure 6.
Occurrence frequency distribution of causal factors.
The frequency distribution of causal factors presents an obvious uneven characteristic. Management-related factors show the highest occurrence frequency in accident reports, followed by human factors and equipment factors. In contrast, environmental factors exhibit relatively low occurrence frequency. P3, M10, and M6 are the key causal factors with the highest frequency.
This degree distribution shows an uneven pattern. Management factors have the highest degrees and dominate the network, followed by human factors, while equipment and environmental factors have relatively low degrees. P3 (Failure to wear correct personal protective equipment (PPE)), M10 (Failure to conduct safety education and training), and M6 (Inadequate on-site safety supervision and management) are the core nodes with the highest degrees.
4.2. Occurrence Rate of Causal Factor Clusters
The occurrence rate of causal factor clusters was calculated to determine how frequently each identified cluster appeared in the actual accident report, thereby reflecting their practical significance in systemic risk propagation. The occurrence rate of causal factor clusters is formally defined as follows. For a given causal factor cluster Ci, its occurrence rate OR(Ci) is calculated as the ratio of the number of accident cases in which Ci is observed to the total number of accident cases.
where Nobs(Ci) denotes the frequency of accidents containing causal factor cluster Ci, and Ntotal is the total number of accident cases analyzed.
Table 3 presents the occurrence rates of the seven identified causal factor clusters, ranked in descending order. As shown, the occurrence rates vary considerably across clusters, ranging from 0.072 for Cluster C5 to 0.008 for Clusters C3 and C7.
Table 3.
Occurrence rates of causal factor clusters ranked in descending order (Ntotal = 526).
Cluster C5 (P3, M6, M7, M10) exhibits the highest occurrence rate (0.072), substantially surpassing all other clusters. This indicates that C5 is the most empirically prevalent factor combination in the accident dataset, suggesting that the causal mechanisms represented by this cluster are activated more frequently than any other identified pattern. This finding is further corroborated by the individual factor frequency distribution: P3 (failure to wear correct PPE), M10 (failure to conduct safety education and training), and M6 (inadequate on-site safety supervision) are among the most frequently occurring single factors in the dataset—and all three are integral components of Cluster C5. The alignment between cluster-level and factor-level evidence reinforces the conclusion that C5 represents the most dominant risk pattern, and that its high prevalence is not an artifact of clustering logic but a reflection of the empirical prominence of its constituent factors.
Clusters C3 (P7, E2) and C7 (F1, M2, M11, M13) show the lowest occurrence rates (0.008 each), indicating that these two factor combinations are comparatively rare in real-world accident scenarios. However, it is important to note that a low occurrence rate does not necessarily equate to low risk; rare clusters may still be associated with severe consequences when they do occur, as their activation may depend on highly specific conditions or represent extreme but high-impact failure modes.
Thus, while occurrence frequency provides a valuable basis for prioritization, it should ideally be complemented by vulnerability assessments to inform more balanced safety decisions.
4.3. Cluster Vulnerability Index of Causal Factor Clusters
While occurrence rates reflect the empirical prevalence of each cluster, they do not capture the structural fragility of these clusters once formed. To address this gap, we introduced the Cluster Vulnerability Index (CVI) to quantify the structural vulnerability of each cluster.
We propose the Cluster Vulnerability Index (CVI) to quantify the structural fragility of causal factor clusters. For a given cluster C, the CVI(C) is defined as the ratio of its external edge connections to its internal edge density, formally expressed as:
where |V| is the number of nodes (causal factors) within the cluster C, Ein is the number of internal edges connecting factors inside the cluster, and Eout is the number of external edges connecting factors inside the cluster to factors outside it. dout represents the average number of external connections per node, capturing the intensity of external pull on the cluster. din is the internal edge density, reflecting how tightly the cluster is bound internally. Consequently, a higher CVI indicates that external influences outweigh internal cohesion, rendering the cluster structurally vulnerable and more prone to disintegration or state transition under exogenous disturbances.
Table 4 presents the CVI values for the seven causal factor clusters, ranked in descending order of structural vulnerability. The results reveal a substantial variation in vulnerability across clusters, ranging from 9.50 for Cluster C5 to 0.00 for Cluster C3.
Table 4.
Cluster Vulnerability Index (CVI) values for the identified causal factor clusters, ranked in descending order.
Table 4 ranks the seven clusters by their CVI values. Cluster C5 exhibits the highest vulnerability (9.50), consistent with its dominant occurrence rate, while Cluster C3 shows zero vulnerability (0.00), reflecting its complete isolation from external connections. Cluster C5 exhibits the highest CVI (9.50), indicating that it is not only the most frequently occurring cluster (as shown in Table 3) but also the most structurally vulnerable. This dual predominance—highest occurrence rate and highest vulnerability—reinforces the critical importance of Cluster C5 as the primary target for safety interventions. Its structural fragility, characterized by a high ratio of external to internal connections, suggests that C5 is highly susceptible to external disturbances, which may facilitate its activation or transformation in accident scenarios.
A noteworthy finding is the divergence between occurrence frequency and structural vulnerability. Cluster C6 ranks second in CVI (7.67) despite its low occurrence rate (0.015), whereas Cluster C2 ranks third in occurrence frequency but exhibits near-minimal CVI (1.00). This indicates that frequency and vulnerability capture distinct risk dimensions: a cluster may be structurally fragile but rarely activated, or frequently activated but structurally robust.
The combined perspective suggests that intervention strategies should prioritize C5 and C4 (high frequency and high vulnerability), while C6, C1, and C7 warrant further severity assessment despite their lower frequencies. Clusters C2 and C3, with low vulnerability, represent comparatively lower structural concerns.
4.4. Four-Quadrant Risk Analysis of Causal Factor Clusters
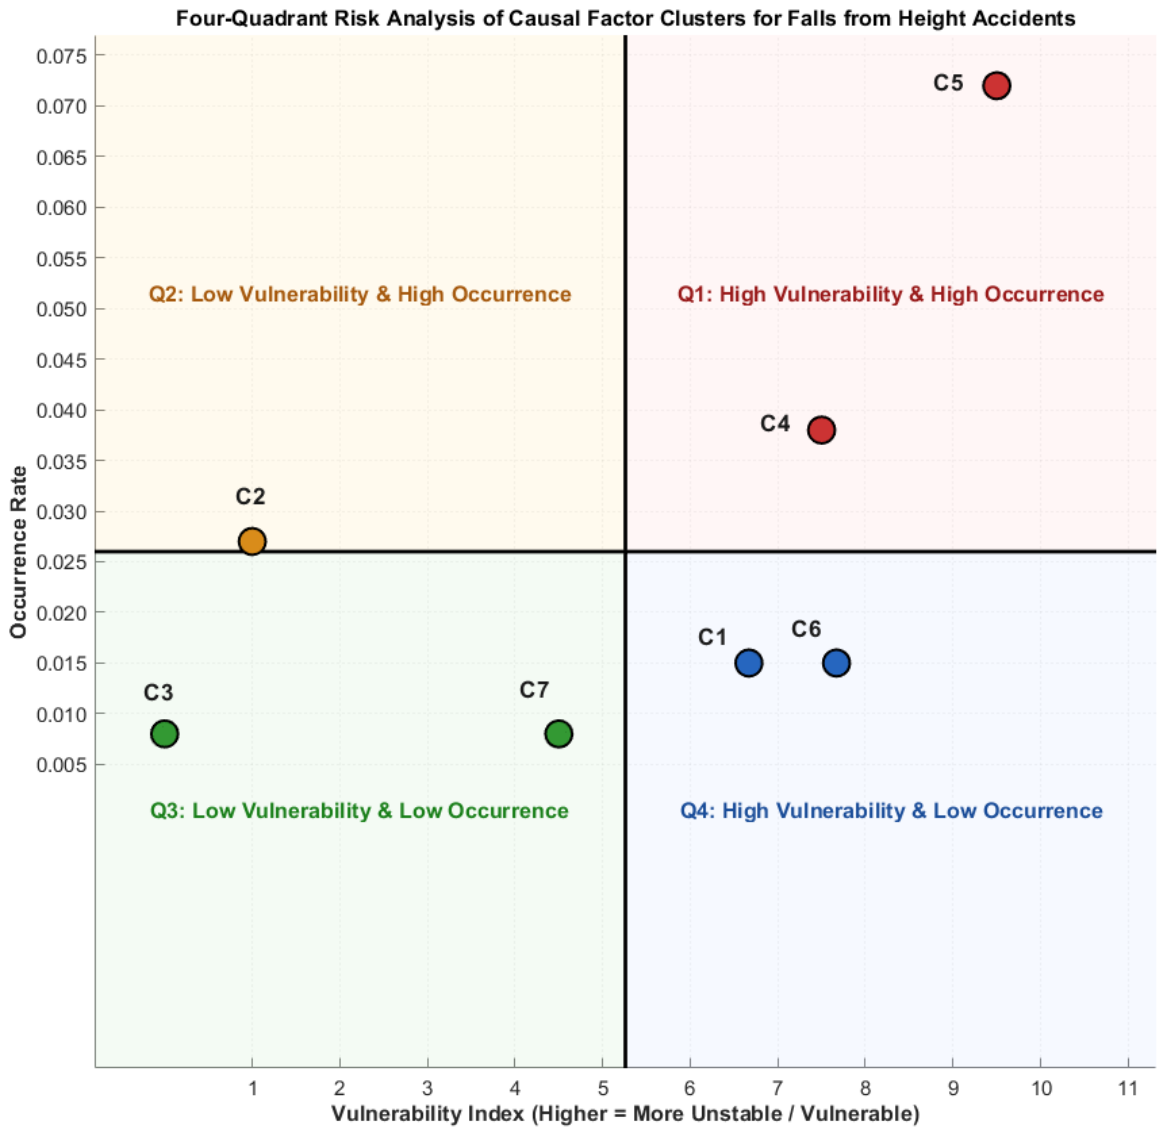
The preceding two subsections examined the seven clusters from two distinct perspectives: empirical prevalence (occurrence rate) and structural fragility (CVI). However, neither dimension alone provides a sufficient basis for risk prioritization—a cluster that is frequently observed may be structurally robust, while a rarely observed cluster may be highly vulnerable to external perturbations. To address this gap, this subsection integrates both dimensions into a four-quadrant risk classification framework, enabling a more balanced and actionable assessment of intervention priorities. The resulting classification is illustrated in Figure 7.
Figure 7.
Four-quadrant risk analysis of causal factor clusters for falls from height accidents based on vulnerability index (x-axis) and occurrence rate (y-axis). The origin is set at (5.26, 0.026) for balanced distribution. Quadrants: Q1 (red): high vulnerability & high occurrence; Q2 (orange): low vulnerability & high occurrence; Q3 (green): low vulnerability & low occurrence; Q4 (blue): high vulnerability & low occurrence. Point distribution: Q1 = 2 (C4, C5), Q2 = 1 (C2), Q3 = 2 (C3, C7), Q4 = 2 (C1, C6).
The resulting classification is presented in Figure 7, where the seven causal factor clusters are mapped onto a two-dimensional matrix defined by CVI (x-axis) and occurrence rate (y-axis). The origin is set at the sample mean of the seven clusters on each axis ( = 5.26, ȳ = 0.026), so that the four quadrants objectively distinguish clusters above versus below the average structural vulnerability and empirical prevalence. The horizontal axis represents increasing CVI and the vertical axis represents increasing occurrence rate.
The four quadrants are defined as follows: Q1 (red)—high vulnerability and high occurrence; Q2 (orange)—low vulnerability and high occurrence; Q3 (green)—low vulnerability and low occurrence; and Q4 (blue)—high vulnerability and low occurrence. As shown in Figure 7, the seven clusters are distributed as follows: Q1 contains two clusters (C4, C5), Q2 contains one cluster (C2), Q3 contains two clusters (C3, C7), and Q4 contains two clusters (C1, C6). This relatively balanced distribution across the four quadrants suggests that FFH accidents involve a diverse range of causal patterns that require differentiated intervention strategies.
From a safety management perspective, the four quadrants correspond to distinct causal roles within the FFH accident network. Q1 (root causes)—high vulnerability and high occurrence—represents the most critical factor combinations that consistently drive accident occurrence and exhibit structural fragility. Q2 (triggering factors)—high occurrence but low vulnerability—represents frequently observed but structurally stable configurations that serve as immediate accident triggers. Q3 (minor factors)—low occurrence and low vulnerability—represents peripheral factor combinations with limited influence on the accident network. Q4 (latent root causes)—low occurrence but high vulnerability—represents hidden systemic vulnerabilities that lie dormant but become fragile once activated.
Q1 (Root Causes): Clusters C4 and C5. Clusters C4 and C5 exhibit both high empirical prevalence and high structural vulnerability, making them the primary drivers of FFH accidents. Cluster C5 (CVI = 9.5, Rate = 0.072) comprises P3 (PPE non-compliance), M6 (inadequate supervision), M7 (unverified qualifications), and M10 (insufficient training)—a systemic pattern spanning individual behavior and organizational oversight. Cluster C4 (CVI = 7.5, Rate = 0.038) links P2 (inadequate risk judgment) with M2 (irregular contracting), reflecting a persistent vulnerability in contractor management. As root causes, these clusters demand immediate, multi-layered, systemic interventions addressing both behavioral and organizational dimensions.
Q2 (Triggering Factors): Cluster C2. Cluster C2 (CVI = 1, Rate = 0.027) comprises P6 (unsafe equipment) and F4 (substandard tools)—a straightforward equipment-related failure mode. Its low CVI indicates structural stability, meaning it serves as a proximal trigger that directly precipitates FFH accidents without embedding deeper systemic fragilities. The appropriate strategy is routine monitoring and targeted prevention through equipment maintenance and inspection protocols.
Q3 (Minor Factors): Clusters C3 and C7. Cluster C3 (CVI = 0, Rate = 0.008) consists of P7 (self-health reasons) and E2 (severe weather)—external factors with limited interaction with organizational safety systems and thus deprioritized. Cluster C7 (CVI = 4.5, Rate = 0.008), while also low-frequency, involves F1 (sign marking defects), M2 (irregular contracting), M11 (no construction permit), and M13 (no safety agreement)—four procedural violations whose complexity suggests caution despite its low occurrence. Routine observation with periodic review is recommended for C7.
Q4 (Latent Root Causes): Clusters C1 and C6. Clusters C1 and C6 are rarely observed but highly fragile. Cluster C6 (CVI = 7.67, Rate = 0.015) combines F5 (defective equipment), M2 (irregular contracting), and M12 (unapproved construction program). Cluster C1 (CVI = 6.67, Rate = 0.015) combines P4 (unlicensed work), F4 (substandard tools), and M16 (managerial neglect). These clusters represent dormant systemic vulnerabilities that may remain hidden until specific conditions allow them to coalesce. The appropriate strategy is proactive identification and mitigation through regular safety audits targeting equipment certification, contracting procedures, and management oversight, supplemented by scenario-based risk simulations to assess potential escalation pathways.
Cross-quadrant insights reveal that management factors (M-type) are present in all high-vulnerability clusters (Q1 and Q4), suggesting that management system reforms should be the cornerstone of FFH accident prevention. The balanced distribution of clusters across quadrants further indicates that FFH accidents stem from heterogeneous causal patterns requiring differentiated strategies rather than uniform safety programs.
In summary, the four-quadrant framework provides a structured, evidence-based approach to prioritizing safety interventions in FFH accidents. By distinguishing between root causes, triggering factors, minor factors, and latent root causes, it offers a practical taxonomy that enables safety managers to allocate resources efficiently.
4.5. Parameter Sensitivity Analysis (JacTh and gc)
The proposed method uses two thresholds: JacTh, the Jaccard similarity above which two causes are connected in the interaction network, and the granularity coefficient gc. Both directly affect the extracted clusters, so we tested a 5 × 5 grid: JacTh ∈ {0.10, 0.125, 0.15, 0.175, 0.20} and gc ∈ {0.30, 0.35, 0.40, 0.45, 0.50}, giving 25 combinations. The identified overlapping causal factor clusters are shown in Table 5.
Table 5.
Overlapping causal factor clusters identified under each combination of JacTh and gc.
- (1)
- Effect of JacTh. Figure 3 shows how the network structure varies with JacTh. As JacTh increases from 0.10 to 0.20, the number of edges drops from 203 to 58, the network density falls from 0.409 to 0.117, and the number of isolated nodes increases rapidly. As shown in Table 5, at JacTh = 0.10 and 0.125, many weak co-occurrence pairs are retained, and the detected clusters are few, largely independent, and show little overlap. At JacTh = 0.20, the number of isolated factors rises sharply, and the remaining edges mostly form small two-node pairs with limited discriminative power, so the detected clusters exhibit excessive overlap. At JacTh = 0.15, the network retains enough structure to identify overlapping clusters while still preserving the stronger couplings; JacTh = 0.15 is adopted as a reasonable working threshold.
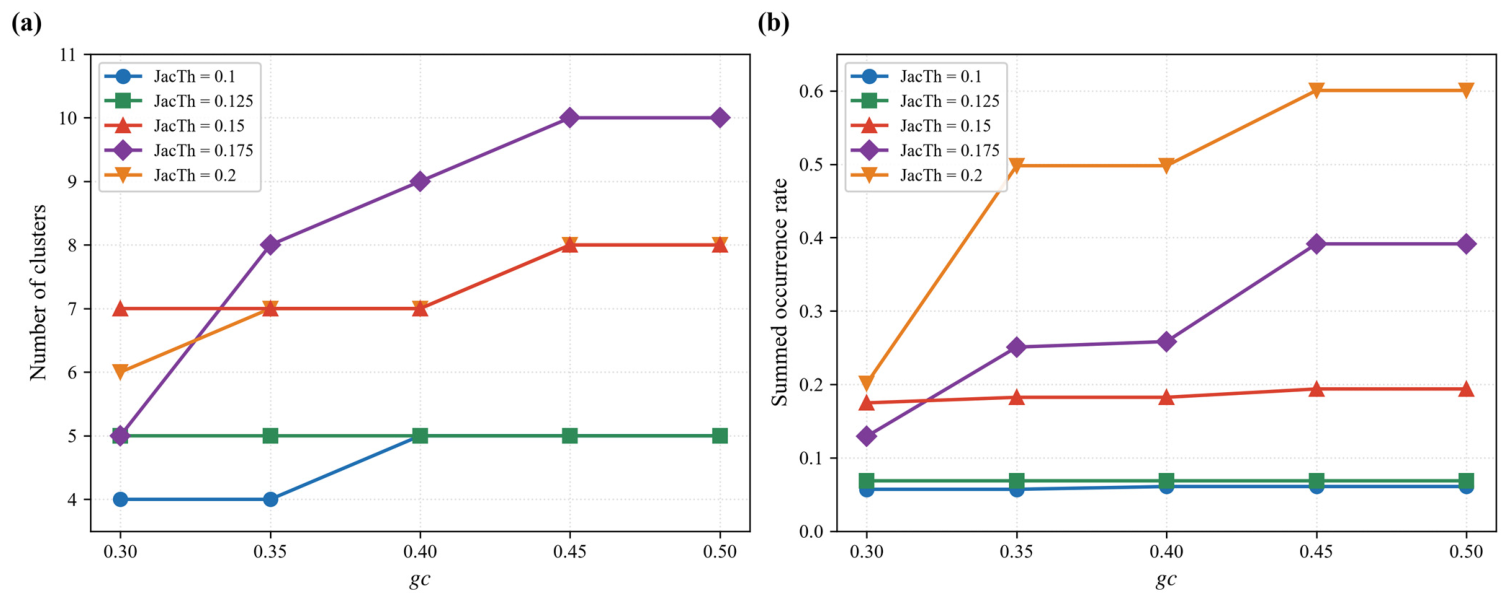
Figure 8 summarizes the sensitivity analysis. In Figure 8a, when JacTh = 0.15, the cluster count stays between 7 and 8 no matter how gc changes. But when JacTh ≥ 0.175, the count swings from 5 to 10. Figure 8b shows the same picture: the total occurrence rate stays at 0.17–0.19 at JacTh = 0.15, but jumps to 0.39–0.60 when JacTh ≥ 0.175. This shows that JacTh = 0.15 gives stable results and is not sensitive to the value of gc, so we use JacTh = 0.15 as the working threshold.
Figure 8.
Sensitivity of the detected overlapping clusters to JacTh and gc. (a) Number of clusters; (b) summed occurrence rate of all clusters. At JacTh = 0.15 (red line), both indicators remain nearly stable across the full gc range; at JacTh ≤ 0.125 the cluster count and summed rate are low, while at JacTh ≥ 0.175 both increase sharply as the network fragments into small pairs.
- (2)
- Effect of gc. As shown in Figure 8, at JacTh = 0.15 the summed occurrence rate remains nearly flat (0.17–0.19) across the entire gc range, indicating that gc has little quantitative influence on the detected clusters. Nevertheless, we adopt gc = 0.40 based on cluster interpretability. At gc = 0.30, cluster C6 is over-merged as {F5, M1, M2, M8, M10, M12}, mixing an equipment defect (F5) with four management factors that belong to different risk themes. At gc ≥ 0.45, a weakly supported extra cluster {M1, M2, M8, M10, M12} splits off, which occurs in only 1.1% of the accidents and has no clear engineering interpretation. At gc = 0.40, C6 is cleanly identified as {F5, M2, M12}, and no such spurious cluster appears. We therefore choose gc = 0.40 as a middle ground that avoids both over-merging and over-splitting.
- (3)
- Core couplings stay stable. Two couplings that matter in practice hold up across the sensitivity test: {P4, M16, F4} (unlicensed work, poor tools, weak management) is preserved at every grid point with JacTh <= 0.15, and {P7, E2} (self-health reasons, severe weather) is preserved at all 25 grid points.
- (4)
- Total occurrence rate does not inflate. We summed the occurrence rates of all clusters in each grid cell. At JacTh = 0.15 the summed rate stays between 0.17 and 0.19 for all gc values. At JacTh >= 0.175 it jumps to 0.39–0.60, which means the clusters are breaking into small pairs rather than revealing more system-level couplings.
We therefore adopt JacTh = 0.15 and gc = 0.40. This is not the best point by any single metric; it is the setting where the network keeps enough factors (28/32), the results are not sensitive to small changes in gc, the key practical couplings are preserved, and the occurrence rate does not inflate from fragmentation.
4.6. Comparison with Existing Overlapping Community Detection Methods
To further validate the proposed method, we ran the Clique Percolation Method [43] on the same network (JacTh = 0.15, 121 edges, density 0.244). CPM is a widely used overlapping-community method that, like ours, detects overlap from shared local structure. We tested four clique sizes (k = 3, 4, 5, 6). In all four runs, CPM merged the whole network into one community and produced no overlapping nodes. This is because the network is too dense: the cliques from different regions touch too much and fuse together. Our method, by contrast, splits the same network into seven interpretable clusters, with two nodes (F4 and M2) shared across clusters as bridges between categories. These results show that the proposed method is better suited to moderately dense accident co-occurrence networks than CPM, which is the most widely used overlapping-community baseline. Table 6 summarizes the comparison.
Table 6.
Quantitative comparison between the proposed method and CPM.
4.7. Practical Implications for Falls from Height Safety Management
The quadrant-based causal taxonomy offers several practical implications for safety management in FFH accident prevention.
First, the classification of Q1 clusters (C4, C5) as root causes suggests that safety managers should allocate disproportionate resources to addressing the synergy between individual-level behaviors and organizational-level failures. This includes strengthening PPE enforcement, enhancing on-site supervision, implementing rigorous qualification verification, conducting mandatory safety training, and tightening contractor qualification screening. These interventions should be implemented in an integrated manner, as root causes are inherently systemic and addressing individual factors in isolation will not disrupt the core failure pathways.
Second, the identification of Q4 clusters (C1, C6) as latent root causes highlights the importance of proactive identification of hidden vulnerabilities. Safety management systems should incorporate regular audits targeting the constituent factors of Q4 clusters—particularly equipment certification, contracting procedures, construction program approvals, and management oversight. Leading indicators should be developed to detect early warning signs of Q4 cluster activation, enabling intervention before the full constellation of latent factors coalesces. The low frequency of Q4 clusters should not be interpreted as a sign of safety, but rather as a reminder that rare events can have severe consequences when they occur.
Third, the classification of Q2 cluster (C2) as a triggering factor suggests that equipment-only failure modes may be effectively managed through established maintenance and inspection protocols. Routine equipment safety programs are likely adequate for preventing this type of cluster, and they do not require the systemic reforms needed for Q1 and Q4 clusters.
Fourth, the Q3 clusters (C3 and C7) remind safety managers that low frequency and low vulnerability do not automatically justify complete deprioritization. While C3 can be safely deprioritized due to its external nature (health and weather), C7’s multi-layered procedural failure composition suggests that it may represent an extreme but potentially severe accident scenario. Safety managers should periodically review C7-related incidents to ensure that its rarity is not masking a hidden high-impact risk.
Fifth, the overarching finding that management factors (M-type) are present in all high-vulnerability clusters (Q1 and Q4) suggests that management system reforms should be the cornerstone of FFH accident prevention. Strengthening management oversight, clarifying safety responsibilities, and ensuring procedural compliance are likely to yield broader reductions in both frequency and vulnerability than interventions targeting individual behaviors or equipment factors alone.
5. Conclusions
This study investigated the causal mechanisms of falls from height accidents by constructing a causal factor interaction network and applying the quotient space overlay network chain approach. Through this methodology, seven distinct causal factor clusters were identified. Cluster C5 exhibited both the highest occurrence rate (0.072) and structural vulnerability (CVI = 9.5), identifying it as the most critical risk pattern. The proposed Cluster Vulnerability Index provides a complementary metric to occurrence frequency for assessing cluster fragility.
The four-quadrant framework distinguishes root causes, triggering factors, minor factors, and latent root causes. Management-related factors drive structural vulnerability across all high-risk clusters, indicating that management system reforms should be the cornerstone of prevention efforts. This framework offers a practical tool for safety resource allocation adaptable to other construction contexts.
Limitations include reliance on a single dataset; future research should incorporate consequence severity and examine temporal cluster evolution.
Author Contributions
J.Z. conceptualized the study; X.D. collected and analyzed the FFH accident data; J.Z. designed the model and wrote the original draft. S.X. and H.S. read and revised the paper critically. All authors have read and agreed to the published version of the manuscript.
Funding
This work was financially supported by the National Natural Science Foundation of China (72604051), China Postdoctoral Science Foundation (2021M700532, GZB20260177), and Natural Science Basic Research Program of Shaanxi (2022JQ-657).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The MATLAB implementation code and data of the algorithm are available from the corresponding author upon reasonable request (email: zhaojie2012@chd.edu.cn).
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| FFH | Fall from height |
| CVI | Cluster vulnerability index |
References
- Peng, J.L.; Liu, X.; Peng, C.; Shao, Y. Comprehensive factor analysis and risk quantification study of fall from height accidents. Heliyon 2023, 9, e22167. [Google Scholar] [CrossRef] [Scilit]
- Khanh, H.D. Factors contributing to fall accidents in Vietnamese building projects: A cluster-based approach. Saf. Sci. 2026, 194, 107058. [Google Scholar] [CrossRef] [Scilit]
- Oliveira, S.S.; de Albuquerque Soares, W.; Vasconcelos, B.M. Fatal fall-from-height accidents: Statistical treatment using the Human Factors Analysis and Classification System–HFACS. J. Saf. Res. 2023, 86, 118–126. [Google Scholar] [CrossRef] [Scilit]
- Pereira, F.; González García, M.d.l.N.; Poças Martins, J. BIM for safety: Applying real-time monitoring technologies to prevent falls from height in construction. Appl. Sci. 2025, 15, 2218. [Google Scholar] [CrossRef] [Scilit]
- Anantharaman, V.; Zuhary, T.M.; Ying, H.; Krishnamurthy, N. Characteristics of injuries resulting from falls from height in the construction industry. Singap. Med. J. 2022, 64, 237–243. [Google Scholar] [CrossRef] [Scilit]
- Huang, X.; Hinze, J. Analysis of construction worker fall accidents. J. Constr. Eng. Manag. 2003, 129, 262–271. [Google Scholar] [CrossRef] [Scilit]
- Hamid, A.R.A.; Majid, M.Z.A. Causes of accidents at construction sites. Malays. J. Civ. Eng. 2008, 20, 242–259. [Google Scholar]
- Haslam, R.A.; Hide, S.A.; Gibb, A.G.; Gyi, D.E.; Pavitt, T.; Atkinson, S.; Duff, A.R. Contributing factors in construction accidents. Appl. Ergon. 2005, 36, 401–415. [Google Scholar] [CrossRef] [Scilit]
- Wong, L.; Wang, Y.; Law, T.; Lo, C.T. Association of root causes in fatal fall-from-height construction accidents in Hong Kong. J. Constr. Eng. Manag. 2016, 142, 04016018. [Google Scholar] [CrossRef] [Scilit]
- Zaini, N.Z.M.; Salleh, M.A.M.; Hasmori, M.F.; Abas, N.H. Effect of accident due to fall from height at construction sites in Malaysia. In Proceedings of the IOP Conference Series: Earth and Environmental Science; IOP Publishing: Bristol, UK, 2020. [Google Scholar]
- Niu, H.; Yang, X.; Zhang, J.; Guo, S. Risk coupling analysis of causal factors in construction fall-from-height accidents. Eng. Constr. Archit. Manag. 2025, 32, 6045–6067. [Google Scholar] [CrossRef] [Scilit]
- Zheng, Y.; Guo, J.; Chen, J.; Wang, X. Mechanism Analysis of Fall Accidents Based on Rheological-Catastrophic Theory. In Proceedings of the 2025 International Conference on Engineering Management and Safety Engineering (EMSE 2025); Atlantis Press: Dordrecht, The Netherlands, 2025; p. 133. [Google Scholar]
- Li, J.; Wang, T. Data-driven Bayesian networks for risk scenario mapping of Falls from height accidents. PLoS ONE 2025, 20, e0334611. [Google Scholar] [CrossRef] [Scilit]
- Zermane, A.; Tohir, M.Z.M.; Zermane, H.; Baharudin, M.R.; Yusoff, H.M. Predicting fatal fall from heights accidents using random forest classification machine learning model. Saf. Sci. 2023, 159, 106023. [Google Scholar] [CrossRef] [Scilit]
- Xia, Q.; Yu, M.; Tan, Y.; Cheng, G.; Zhang, Y.; Wang, H.; Tian, L. A Novel Framework for Roof Accident Causation Analysis Based on Causation Matrix and Bayesian Network Modeling Methods. Appl. Sci. 2025, 15, 11521. [Google Scholar] [CrossRef] [Scilit]
- Kumi, L.; Jeong, J.; Jeong, J.; Son, J.; Mun, H. Network-based safety risk analysis and interactive dashboard for root cause identification in construction accident management. Reliab. Eng. Syst. Saf. 2025, 256, 110814. [Google Scholar] [CrossRef] [Scilit]
- Liu, S.; Yan, W.; Ma, J.; Liu, G.; Zhang, R. Modularity-Driven Keyword Co-Occurrence Network for Mining Statistical Associations in Construction Safety Accidents. Buildings 2026, 16, 1461. [Google Scholar] [CrossRef] [Scilit]
- Chi, C.-F.; Chang, T.-C.; Ting, H.-I. Accident patterns and prevention measures for fatal occupational falls in the construction industry. Appl. Ergon. 2005, 36, 391–400. [Google Scholar] [CrossRef] [Scilit]
- Zermane, A.; Tohir, M.Z.M.; Baharudin, M.R.; Yusoff, H.M. Risk assessment of fatal accidents due to work at heights activities using fault tree analysis: Case study in Malaysia. Saf. Sci. 2022, 151, 105724. [Google Scholar] [CrossRef] [Scilit]
- Abdelhamid, T.S.; Everett, J.G. Identifying root causes of construction accidents. J. Constr. Eng. Manag. 2000, 126, 52–60. [Google Scholar] [CrossRef] [Scilit]
- Ren, C.; Li, X.; Xie, F. Key factors coupling in hazardous materials road transport accidents integrating higher-order network and functional resonance analysis method. J. Highw. Transp. Res. Dev. 2025, 42, 24–36. [Google Scholar]
- Zhang, L.; Zhang, B. Quotient Space Based Problem Solving: A Theoretical Foundation of Granular Computing; Newnes: London, UK, 2014. [Google Scholar]
- Zhao, J.; Lei, X. Mining overlapping protein complexes in PPI network based on granular computation in quotient space. In Proceedings of the International Conference on Intelligent Computing; Springer: Berlin/Heidelberg, Germany, 2018; pp. 691–696. [Google Scholar]
- Mao, Y.; Ming, Z.; Yu, X.; Li, J. Construction Accident Narrative Classification and Risk Theme Mining Using Pretrained Language Models. Reliab. Eng. Syst. Saf. 2026, 277, 112992. [Google Scholar] [CrossRef] [Scilit]
- Luo, X.; Zhang, L.; Guo, B.H.; Ma, Y.; Du, Q.; Bai, L. A domain-adaptive multilevel framework for learning accident narratives to support proactive construction safety management. Saf. Sci. 2026, 202, 107295. [Google Scholar] [CrossRef] [Scilit]
- GB/T 13861-2022; Classification and Code for the Hazardous and Harmful Factors in Process. Standards Press of China: Beijing, China, 2022.
- Guo, H.; Mo, Y.; Guo, F.; Kang, R.; Tang, K.; Ma, Q. Association analysis of causative factors of fall from height accidents. J. Saf. Sci. Resil. 2025, 6, 100221. [Google Scholar] [CrossRef] [Scilit]
- Yoon, Y. A Study on Causes of Fatal Accidents in the Construction Industry Using 4M-based Frequency Ratio Analysis. J. Converg. Cult. Technol. 2025, 11, 787–796. [Google Scholar]
- Qi, H.; Zhou, Z.; Irizarry, J.; Lin, D.; Zhang, H.; Li, N.; Cui, J. Automatic identification of causal factors from fall-related accident investigation reports using machine learning and ensemble learning approaches. J. Manag. Eng. 2024, 40, 04023050. [Google Scholar] [CrossRef] [Scilit]
- Huang, S.; Jin, C.; Chen, T.; Wang, Z.; Wang, J. Analysis of major road traffic accident causes using a combined method of association rule and complex network. J. Adv. Transp. 2025, 2025, 8714444. [Google Scholar] [CrossRef] [Scilit]
- Wang, W.; Lai, X.; Sun, Y. Explore human-factor impacts on the occurrence of general aviation accidents. Reliab. Eng. Syst. Saf. 2025, 267, 111900. [Google Scholar] [CrossRef] [Scilit]
- Yang, L.; Liu, J.; Liu, Z.; Zhou, Q.; Liu, Y.; Wang, Y.; Wu, W. From text to network: A framework for identifying causal factors and risk propagation paths in maritime accidents. Reliab. Eng. Syst. Saf. 2026, 271, 112282. [Google Scholar] [CrossRef] [Scilit]
- Huo, X.; Du, S.; Jiao, L. Critical causal path analysis of subway construction safety accidents based on text mining. ASCE-ASME J. Risk Uncertain. Eng. Syst. Part A Civ. Eng. 2025, 11, 04024075. [Google Scholar] [CrossRef] [Scilit]
- Zhao, C.; Mi, C.; Zhou, Z.; Fang, J. Key cause chains selection of electric personal accidents based on combinatorial association analysis model. China Saf. Sci. J. (CSSJ) 2022, 32, 99–106. [Google Scholar]
- Hasan, Z.F.; Nawaf, H.N. Community Detection Based on the LO-WT Algorithm. Eng. Technol. Appl. Sci. Res. 2025, 15, 26540–26548. [Google Scholar] [CrossRef] [Scilit]
- Zhao, J.; Lei, X.; Wu, F.-X. Predicting protein complexes in weighted dynamic PPI networks based on ICSC. Complexity 2017, 2017, 4120506. [Google Scholar] [CrossRef] [Scilit]
- Zhang, L.; Zhang, B. Quotient space based multi-granular computing. In Proceedings of the 2005 IEEE International Conference on Granular Computing; IEEE: Piscataway, NJ, USA, 2005; Volume 91, p. 98. [Google Scholar]
- Zhao, J.; Lei, X. Detecting overlapping protein complexes in weighted PPI network based on overlay network chain in quotient space. BMC Bioinform. 2019, 20, 682. [Google Scholar] [CrossRef] [Scilit]
- Zhang, L.; He, F.-G.; Zhang, Y.-P.; Zhao, S. A new algorithm for optimal path finding in complex networks based on the quotient space. Fundam. Informaticae 2009, 93, 459–469. [Google Scholar] [CrossRef] [Scilit]
- Li, Z.; Zhang, Y. High-Altitude Fall Accidents in Construction: A Text Mining Analysis of Causal Factors and COVID-19 Impact. Modelling 2025, 6, 124. [Google Scholar] [CrossRef] [Scilit]
- Zhang, J.; Jiang, S. Identification of unsafe behaviors and coupling relationship based on enhanced text preprocessing and association analysis. Eng. Constr. Archit. Manag. 2026, 33, 7526–7550. [Google Scholar] [CrossRef] [Scilit]
- Benderouach, K.; Bennis, I.; Mansouri, K.; Siadat, A. Predicting industrial accident causes from text descriptions: A Machine Learning-Based approach. In Proceedings of the 2025 11th International Conference on Optimization and Applications (ICOA); IEEE: Piscataway, NJ, USA, 2025; pp. 1–5. [Google Scholar]
- Palla, G.; Derényi, I.; Farkas, I.; Vicsek, T. Uncovering the overlapping community structure of complex networks in nature and society. Nature 2005, 435, 814–818. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.