


Abstract
Many real-world datasets are given as a stream of user–interest pairs, where a user–interest pair represents a link from a user (e.g., a network host) to an interest (e.g., a website), and may appear more than once in the stream. Monitoring and mining statistics, including cardinality, intersection cardinality, and Jaccard similarity of users’ interest sets on high-speed streams, are widely employed by applications such as network anomaly detection. Although estimating set cardinality, set intersection cardinality, and set Jaccard similarity, respectively, is well studied, there is no effective method that provides a one-shot solution for estimating all these three statistics. To solve the above challenge, we develop a novel framework, SimCar. SimCar online builds an order-hashing (OH) sketch for each user occurring in the data stream of interest. At any time of interest, one can query the cardinalities, intersection cardinalities, and Jaccard similarities of users’ interest sets. Specially, using OH sketches, we develop maximum likelihood estimation (MLE) methods to estimate cardinalities and intersection cardinalities of users’ interest sets. In addition, we use OH sketches to estimate Jaccard similarities of users’ interest sets and build locality-sensitive hashing tables to search for users with similar interests with sub-linear time. We evaluate the performance of our methods on real-world datasets. The experimental results demonstrate the superiority of our methods.
1. Introduction
Many real-world networks (e.g., computer networks, phone networks, and financial networks) generate data (e.g., packets, calling records, and transactions) in a stream fashion, where an element (e.g., a packet) records a link from a user (e.g., a source IP address) to an interest (e.g., a destination IP address). The data can be modeled as a data stream of user–interest pairs, including duplicates, because multiple data records (e.g., packets from a source IP address to a destination IP address) may relate to the same user–interest pair. Due to the large size and high-speed nature of these data streams, it is prohibitive to collect all the data, especially when the computation and memory resources of data-collection devices (e.g., network routers) are limited. To solve this challenge, considerable attention has been paid to designing fast and memory-efficient data streaming algorithms for monitoring and mining user behaviors. For example, Count-Min sketch [1] and its variants have been successfully used to detect heavy hitters (e.g., user–interest pairs frequently occurred).
In addition to statistics using the frequency of duplicates, significant effort has also been made to mine users’ interest sets, such as:
- User cardinality. A user’s cardinality is defined to be the number of distinct interests that the user links to, i.e., the cardinality of the user’s interest set. Monitoring user cardinalities in computer networks is fundamental for applications such as network anomaly detection [2]. One can use a variety of sketch methods, such as LPC [3], LogLog [4], HyperLogLog [5], MinCount [6], RoughEstimator [7], and their variants [2,8,9,10,11,12,13] to generate a compact data summary (or sketch) for each user’s interest set, and then infer user cardinalities from the generated sketches.
- Common-interest count. Two users’ common-interest count is defined as the number of interests that they both link to, i.e., the cardinality of the intersection of two users’ interest sets. It is popularly used for applications such as friend recommendation [14] and network anomaly detection [15]. One can use sketch and sampling methods in [13,14,15] to estimate users’ common-interest counts.
- User Jaccard similarity. The Jaccard similarity is a popular similarity measure. Two users’ similarity can be evaluated as the Jaccard similarity of their interest sets, which is defined as their common-interest count divided by the number of distinct interests at least one of them links to. One can use sketch methods such as MinHash [16], OPH [17], and their variants [18,19,20,21,22] to estimate users’ Jaccard similarities. Some of these sketch methods, such as Minhash, can be used for locality-sensitive hashing (LSH) indexing [16,23,24,25,26], which is capable of searching a query user’s similar users with sub-linear time.
The above three duplicate-irrelevant statistics may all be desired for applications such as network anomaly detection. For example, given a detected abnormal user (e.g., the IP address of an attacker captured by Honeynet systems), network administers may want to quickly search for similar users among all network users, which may also be abnormal users, and then estimate their cardinalities, Jaccard similarities, and common-interest counts for further inspection. Although many cardinality estimation methods can be easily extended to estimate the above three statistics because they generate mergeable sketches (mergeable cardinality estimation sketches of two sets and can be used to generate a sketch of , which is used to estimate the cardinality of .), Cohen et al. [15] observed that their extensions exhibit large errors for estimating common-interest counts and Jaccard similarities. Even worse, the sketches generated by these cardinality methods cannot be used for LSH indexing, which results in a high computational cost for searching users with similar interests. One can combine multiple existing methods to generate different sketches for estimating user cardinalities, common-interest counts, and Jaccard similarities, respectively. This straightforward method increases the required memory and computational resources, which limits its usage for high-speed data streams.
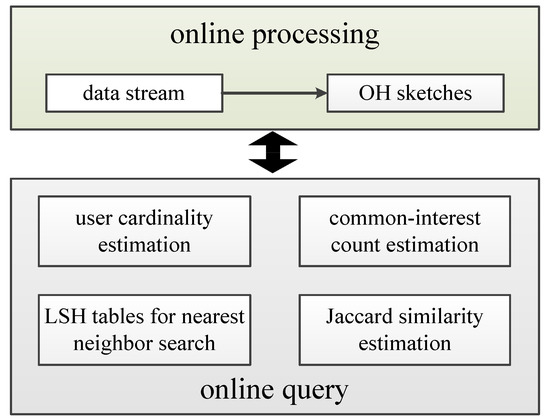
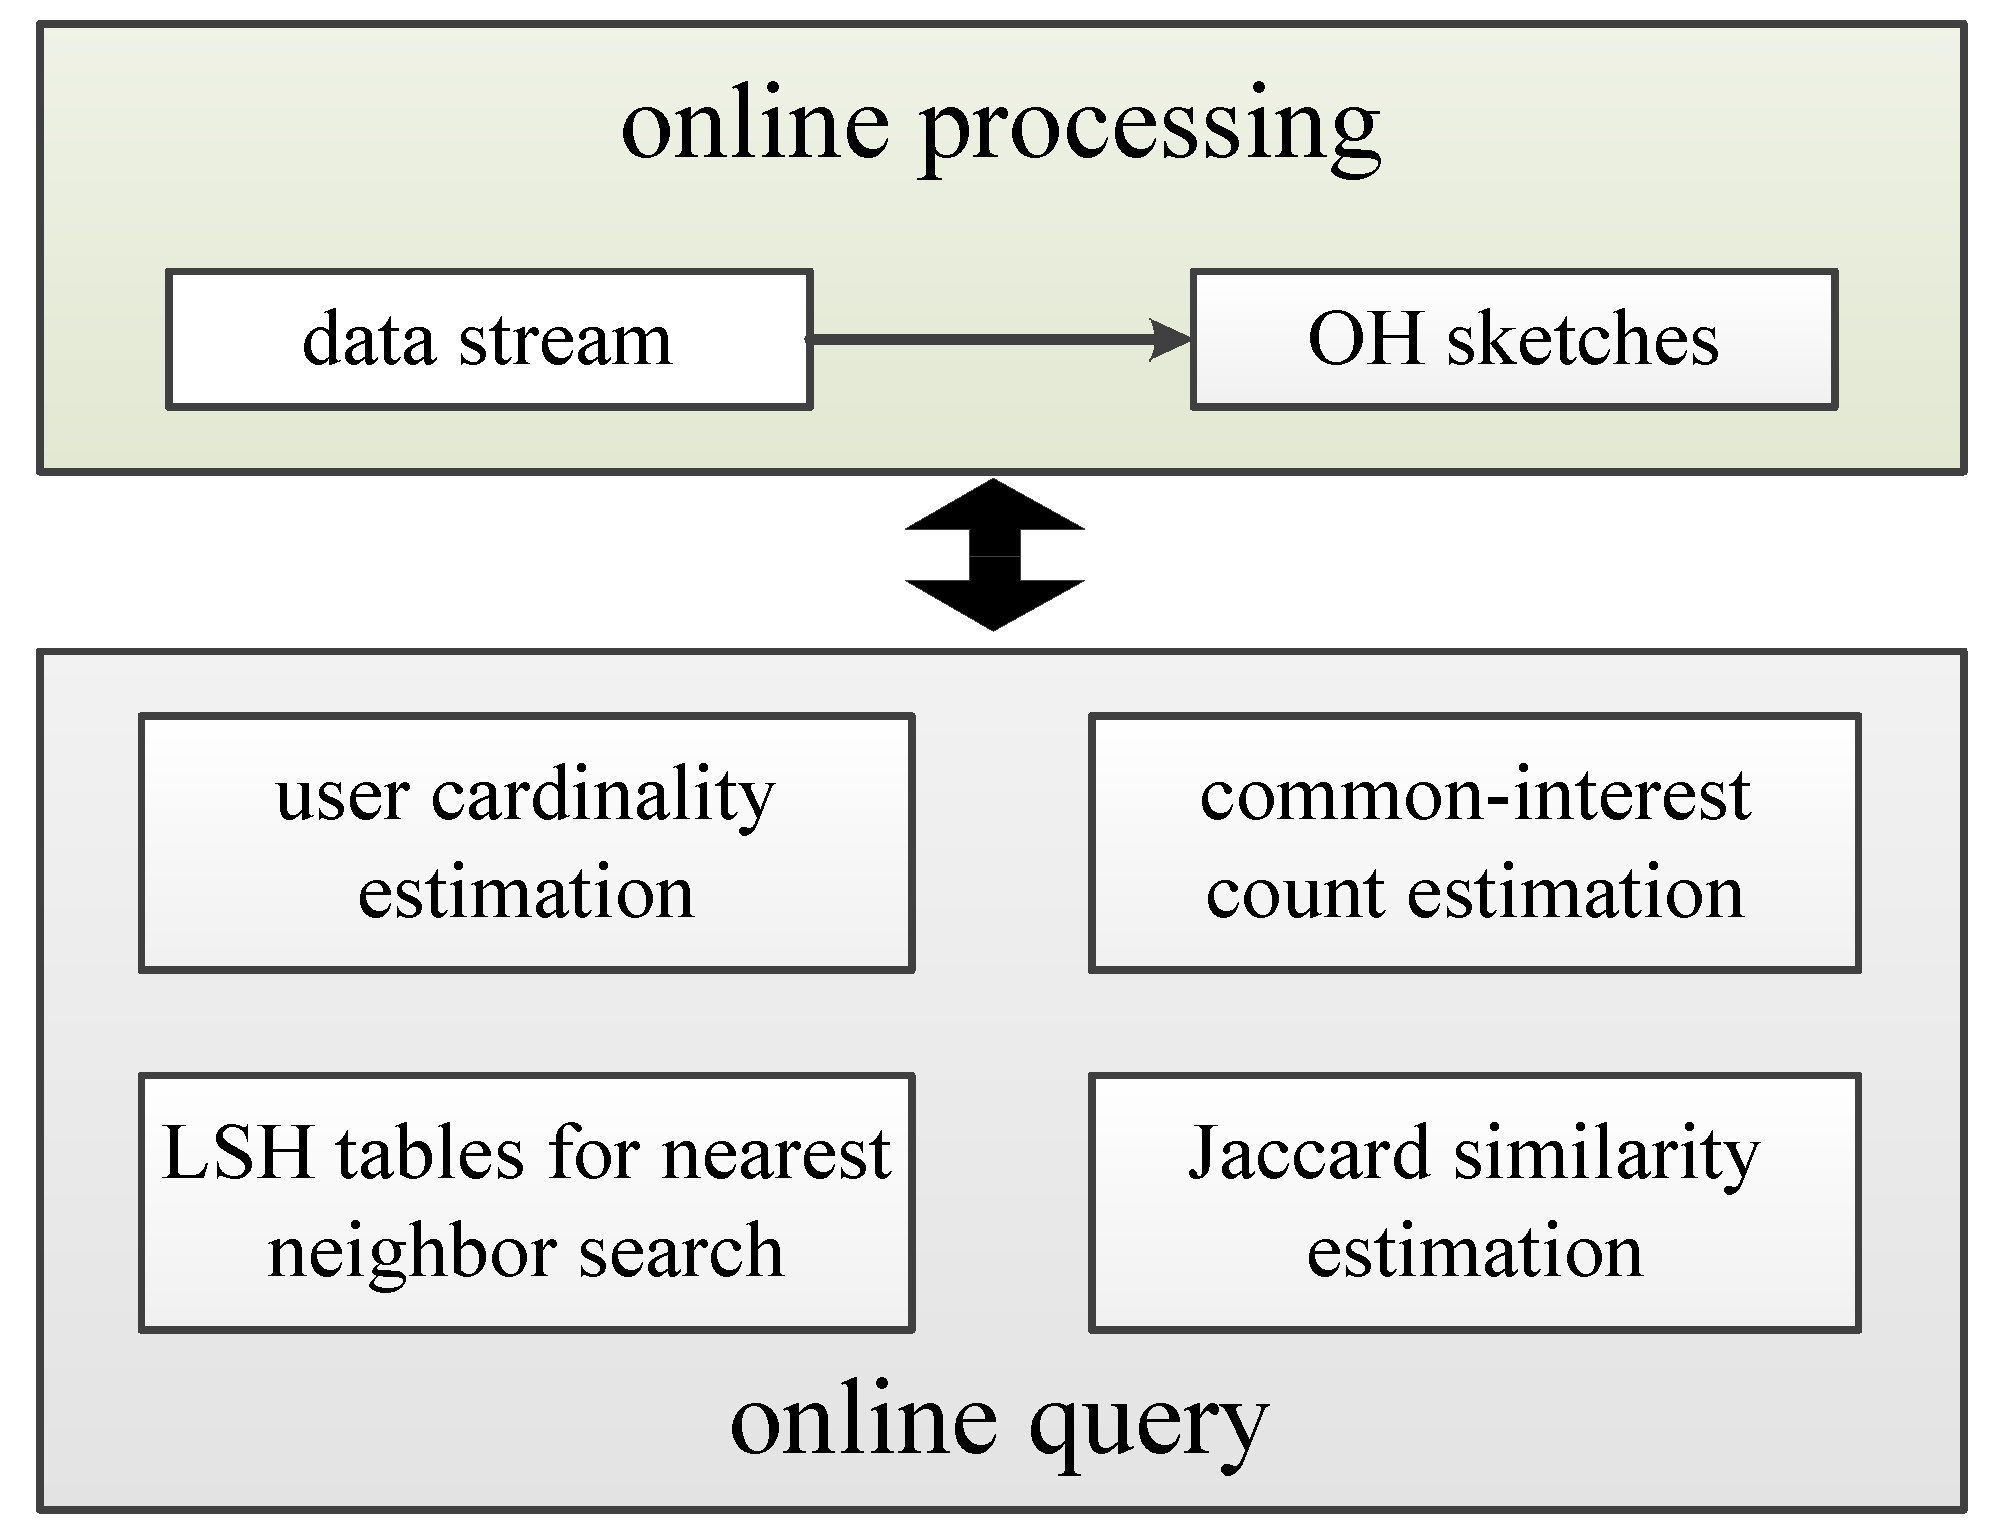
To address the above challenges, we develop a novel framework, SimCar, which is shown in Figure 1. The framework consists of two modules: (1) the online processing module, which uses Giroire’s algorithm [6] to build an order-hashing (OH) sketch of the interest set of each user occurring in the stream; (2) the online query module, which provides functions for estimating the cardinalities, intersection cardinalities, and Jaccard similarities of users’ interest sets at any time of interest. Specially, using OH sketches, we develop maximum likelihood estimation (MLE) methods for estimating cardinalities and intersection cardinalities of users’ interest sets. In addition, we use the technique optimal densification [22] to generate densification OH (DOH) sketches and then use DOH sketches to estimate Jaccard similarities of users’ interest sets and build locality-sensitive hashing tables to search for users with similar interests with sub-linear time. Our main contributions are summarized as follows:
Figure 1.
Framework of our framework SimCar.
- For sets given in a stream fashion, our method, SimCar, builds only one type of sketches (i.e., OH sketch) to effectively mine a variety of their statistics, including cardinality, intersection cardinality, and Jaccard similarity, as well as fast search similar sets. It outperforms the straightforward method of combining existing sketch-based cardinality estimation methods and Jaccard similarity estimation methods.
- We develop maximum likelihood estimation (MLE) methods to estimate set cardinalities and intersection cardinalities, which are more accurate than the original OH-sketch-based cardinality estimation method [6].
- Compared with state-of-the-art methods, experimental results on real-world datasets demonstrate that our method, SimCar, is up to 1000 times faster for online data streams processing, and reduces the memory usage by 13.5–23.8% to achieve the same performance accuracy.
The rest of this paper is organized as follows. The problem formulation is presented in Section 3. Section 4 introduces the preliminaries. Section 5 presents our framework, SimCar. The performance evaluation is presented in Section 6. Section 2 summarizes related work. Concluding remarks then follow.
2. Related Work
LSH for similarity estimation. LSH maps similar objects (e.g., sets and vectors) to the same hash value with higher probability than dissimilar ones [23], and has been widely used for applications such as similarity estimation and nearest neighbor search. MinHash [16] is a popular LSH technique for estimating the Jaccard similarity coefficient of sets. Recently, considerable attention has been paid to improving the performance of MinHash. For example, b-bit minwise hashing [18], odd sketch [19], and MaxLogHash [27] use probabilistic techniques such as sampling and sketching to further reduce the amount of memory used by MinHash. However, all these methods update each element with a high complexity of . To solve this problem, OPH [17] and its variants [20,21,22,28] were developed to accelerate the speed of processing each element in sets by orders of magnitude. Very recently, Raul et al. [29] used HyperLogLog [5] and OPH [17] sketches to estimate the Jaccard similarity, as well as the containment. In addition to sets (i.e., binary vectors), a variety of sketch methods have also been developed to estimate similarity between real-value weighted vectors. For example, Charikar [25] developed a method, SimHash, for approximating angle similarity (i.e., cosine similarity) between weighted vectors. Datar et al. [26] used p-stable distributions to estimate distance between weighted vectors, where . Refs. [30,31,32,33,34,35,36,37,38] were developed to approximate the weighted Jaccard similarity of weighted vectors. Ryan et al. [39] proposed a Gumbel-Max-Trick-based sketching method, -MinHash, to estimate another novel Jaccard similarity metric, probability Jaccard similarity. They also demonstrated that the probability Jaccard similarity is scale invariant and more sensitive to changes in vectors. Qi et al. [40] proposed FastGM to further reduce the time complexity of -MinHash by generating the hash values in order.
LSH for nearest neighbor search. To perform a nearest neighbor search, refs. [23,26] first, objects are hashed into a hash table. To perform a similarity search, a query object is hashed into a bucket of the hash table, and then the objects in the bucket are used as candidate objects, which need to be further verified. However, nearest neighbors may not appear as candidate objects because close objects may be hashed into different buckets. To solve this problem, refs. [41,42,43] proposed methods that look up more than one bucket of the hash table for a query, which significantly reduces the amount of storage. To further improve the performance, many techniques, such as C2LSH [44], SK-LSH [45] and LSB-Frest [46], were developed to reduce memory usage and query cost. After gathering the candidate objects, but before verifying them, Satuluri et al. [47] developed a method BayesLSH that performs similarity estimation and candidate pruning using LSH sketches to accelerate the procedure of verifying candidate objects. Real-world datasets are usually not distributed uniformly over the space, which results in unbalanced LSH buckets and degrades the performance of LSH for nearest neighbor search. To solve this problem, Gao et al. [48] developed a method DSH leveraging data distributions to hash nearest neighbors together with a larger probability. Wang et al. [49] developed a system, FLASH, using OPH and reservoir sampling to overcome the computational and parallelization hurdles. Recently, several LSH-based methods [50,51,52] and transformation-based methods [53,54,55] were developed to solve the maximum inner product search (MIPS) problem, i.e., search vectors having maximum inner products with a given query vector.
Cardinality estimation. To estimate a large data set’s cardinality, Whang et al. [3] developed the first fast sketch method LPC. Additionally, refs. [2,12] used different sampling methods to enlarge the estimation range of LPC. Flajolet and Martin [56] developed a sketch method, FM, which uses a register initialized to zero for cardinality estimation. To further improve the performance of FM, sketch methods LogLog [4], HyperLogLog [5], RoughEstimator [7], and HLL-TailCut+ [57] were developed to use a list of m registers and compress the register size from 32 bits to 5 or 4 bits. Giroire [6] developed a sketch method, MinCount, (also known as bottom-k sketch [58]) which stores the k minimum hash values of elements in the stream to estimate the stream cardinality. Lumbroso [59] developed another order-statistics-based cardinality estimation method which hashes the data stream’s elements into k registers at random, and each register stores the minimum hash value of elements hashed into it. Ting [53] developed a martingale-based estimator to further improve the accuracy of the above sketch methods, such as LPC, HyperLogLog, and MinCount. Chen et al. [60] extended HyperLogLog to sliding windows. In addition to sketch methods, two sampling methods [61,62] were also developed for cardinality estimation. Recently, considerable attention [8,9,10,11] has been given to developing fast sketch methods to monitor the cardinalities of network hosts over high-speed links. Ting [13] developed methods to estimate the cardinality of set unions and intersections from MinCount sketches. Cohen et al. [15] developed a method combining MinHash and HyperLogLog to estimate set intersection cardinalities. These two methods fail to solve the problem studied in this paper, because MinCount does not belong to the LSH family, and cannot be used for sub-linear time similarity search, and MinHash fails to deal with high-speed data streams due to its high time complexity.
LSH for clustering and feature tracking. LSH can also support other analytical tasks, such as clustering and feature tracking. Mao et al. [63] proposed the MR-PGDLSH algorithm to reduce the overhead of frequent communication between nodes through LSH, so as to solve the problem of excessive communication overhead faced by the partition-based K-means clustering algorithm in the big data environment. Corizzo et al. [64,65] proposed the DENCAST algorithm to process large-scale high-dimensional data using LSH, which is more efficient than the most advanced distributed clustering algorithm. Cao et al. [66] used LSH-based k-nearest neighbor matching to generate feature correspondence, and then used a ratio test method to remove outliers from the previous matching set, and finally achieved better results. Ding et al. [67] proposed a perceptual hash algorithm based on deep learning and LSH to generate edge feature samples to improve the robustness of HRRS image authentication.
3. Problem Formulation
Let denote the stream of interest, where is the element of stream , which represents a link from a user to an interest . Note that a pair may appear more than once in stream . Denote by U the set of occurring users, and W the set of occurring interests. Let be the interest set of user u, i.e., the set of interests that user u links to. User u’s cardinality is defined as the number of its distinct interests, i.e., . For two users u and v, we define their common-interest count as , and their Jaccard similarity as . In this paper, we aim to design a fast method to build a compact data summary (or, sketch) for each user in a single-pass stream . For any specific query user u, generated sketches are effective for rapidly searching for nearest neighbors of user u (i.e., users with large Jaccard similarity ) without enumerating each user in U. More importantly, they are also accurate for estimating the cardinality of any user v, Jaccard similarity , as well as the common-interest count of any two users u and v. For ease of reference, we list the notation used throughout the paper in Table 1.
Table 1.
Table of notation.
4. Preliminaries
In this section, we present Giroire’s algorithm [6] for cardinality estimation, and the OPH method [17] as well as the optimal densification [22] for Jaccard similarity estimation, which are closely related with our framework, SimCar.
4.1. Giroire’s Algorithm
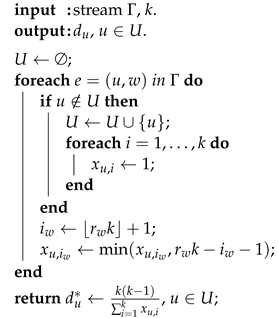
Giroire [6] developed a fast method, CORE, for estimating a stream’s cardinality, i.e., the number of distinct elements occurring in the stream. The basic idea behind CORE is that one can assign each element in the stream a rank that is randomly and uniformly selected from the range (0,1), and to some extent, the minimum of occurring elements’ ranks reflects the number of distinct occurring elements (i.e., the stream’s cardinality). To accelerate the performance, CORE splits elements in the stream into k subsets, and keeps track of the minimum rank for each subset, which is finally used to infer the stream’s cardinality. In detail, CORE uses k registers , …, to generate a sketch of the stream, where , …, are initialized to 1. Let be the rank of an element e that is uniformly selected from range (0, 1) at random; that is, . For an element e arriving on the stream, CORE computes and then updates the register as
At the end of the stream, the stream’s cardinality is estimated as . Since is severely biased for small cardinalities, CORE treats the list of registers as an LPC sketch (i.e., a bitmap of k bits) [3]. Let be the number of registers among that equal 1 at the end of the stream. When , CORE estimates the stream’s cardinality as .
4.2. OPH
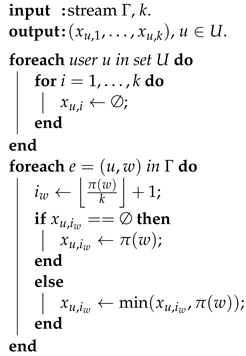
OPH [17] can be viewed as a sampling method, which samples (at most) k distinct elements from each set of interest without replacement and then estimates the Jaccard similarity of two sets based on their sampled elements. Compared with the well-known sketch method MinHash [16], which is used to estimate set Jaccard similarity, OPH reduces the time complexity of processing each element in set from to . In detail, to build a sketch of set , OPH [17] uses a single permutation function to process each element in a set . Specifically, it evenly divides into k bins: , . The OPH sketch of set is a vector , where each element , , is computed as
Given that at least one of and does not equal ∅ Li et al. [17] observed that occurs with probability , and proposed estimating based on this observation. Let be the indicator function that equals one when the predicate is true, and zero otherwise. Formally, OPH estimates the Jaccard similarity of two sets and based on their OPH sketches and as
As shown in Algorithm 1, one can apply the above OPH algorithm online to stream and compute the OPH sketch of each user’s interest set , .
| Algorithm 1: Online update procedure of OPH [17]. |
 |
4.3. Optimal Densification
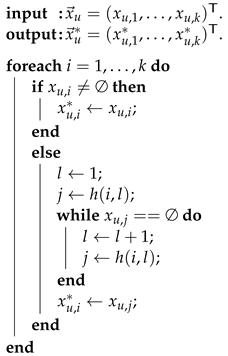
Clearly, the OPH method generates sketches (i.e., vectors) that may have empty elements (i.e., elements equal ∅), which hinders its application for LSH-based similarity search with sub-linear time, and also results in a large error in the Jaccard similarity estimation. To solve this problem, refs. [20,21,22] proposed several densification techniques, which reassign empty elements using the values of non-empty elements. The state-of-the-art densification technique, optimal densification [22], is shown in Algorithm 2. Specifically, when the element of OPH sketch is empty (i.e., ), optimal densification iteratively uses a hash function , to find a non-empty element (i.e., ). Function takes two arguments: (1) i, the current empty element that needs to be reassigned; (2) l, the number of failed attempts made so far to reach a non-empty element, which is initialized to 1. Let denote the optimal densification of OPH sketch . For any sets and , their Jaccard similarity is estimated as
Shrivastava [22] proves that is an unbiased estimator of and is more accurate than the original OPH method, as well as other densificiation techniques in [20,21].
| Algorithm 2: Optimal densification [22]. |
 |
5. Our Framework SimCar
In this section, we use Giroire’s algorithm [6] (Algorithm 3) to build an OH sketch for each occurring user. Based on generated OH sketches, we first present our methods for estimating the Jaccard similarity of users’ interest sets and quickly searching users with similar interests. Then, we propose methods for estimating the cardinalities and common-interest counts of users’ interest sets.
| Algorithm 3: The CORE algorithm [59]. |
 |
5.1. Jaccard Similarity Estimation and Nearest Neighbor Search
Jaccard Similarity Estimation. Let be the DOH sketch of OH sketch , , which is computed using the optimal densification technique introduced in Section 4. Similar to optimal densification [22], we find that for any . Then, we estimate the Jaccard similarity of as
Following the error analysis in [22], we find that is an unbiased estimate of and has the same accurate performance as the optimal densification of OPH.
Nearest Neighbor Search. A variety of LSH methods [16,23,24,25,26] have been developed to solve the task of nearest neighbor search with sub-linear time. The basic idea behind these LSH methods is to place similar users into the same bucket of a hash table with high probability. Following the principle of LSH, our nearest neighbor search method consists of two basic phases:
- Pre-processing phase. We first construct b hash tables for all users in U. Let , where c is an integer parameter used to determine the performance of LSH. Let , , denote the vector consisting of the to elements of DOH sketch , i.e., . Then, we insert each user u and its densification sketch into hash tables as
- Retrieving phase. Given a specific user u, we search for its similar users. Instead of scanning all users in set U, we only probe b different buckets from b hash tables, respectively, and report the users in any of these buckets as the potential candidates. Last, nearest neighbors of user u are detected by enumerating all users in set , and computing and sorting their Jaccard similarity estimations.
5.2. User Cardinality Estimation
In this section, we estimate the cardinality of any queried user. Specially, we first build a probabilistic model according to the state of the OH sketch, and then solve it using MLE methods.
Exact probabilistic model. For any user , let denote the set of its interests whose hash values equal i with respect to hash function f; that is,
At any time of stream , from Equation (1), we have
Define . Let denote the probability density function (PDF) of random variable at x given . Then, we have
Our algorithm randomly splits users in set into k subsets , …, . Using the classical balls-in-urns model, we derive the probability distribution of vector as
where . Therefore, the PDF of given is computed as
Poisson approximation model. Clearly, are not independent, which hinders us when it comes to obtaining the MLE of . Similar to [5], we use the Poisson approximation technique to remove the dependence of . Specifically, we assume that the value of is distributed according to a Poisson distribution with parameter , i.e., . Then, the PDF of given is
Given , the above equation indicates that the values of are independent and identically distributed. In addition, the values of are independent and identically distributed according to a Poisson distribution . Formally, we have
For an estimator of (e.g., Equation (5), derived later), we let and denote the expectation and the variance of under the exact probabilistic model (i.e., ), and let and denote the expectation and the variance of under the Poisson approximation model (i.e., ). The authors of [5,68,69] reveal that statistical properties of and are well approximated by and when setting , which is the depoissonization step.
Estimator of . Next, we elaborate our method to derive the MLE of under the Poisson approximation model. For any , the following equation holds
where the last equation holds because of the Taylor series of at . Then, we compute the PDF of at x given as
The last equation holds because we have when , which occurs with probability . Let denote the set of elements in vector that are smaller than 1, i.e.,
Denoted by is the number of elements in vector that equal 1. Then, the likelihood function of given by k independent observed variables is computed as
Let denote the MLE of . We compute the derivative of as
Let . Then, we obtain the MLE of as
To analyze the estimation error of , we first compute the Fisher information of as
The last equation is obtained because , which is easily derived from Equation (4). From [70], we find that the MLE is an asymptotically efficient unbiased estimator of , and its mean square error (MSE) asymptotically approaches the Cramér–Rao lower bound (CRLB) of , which is defined as . Formally, we have and . Lastly, at the depoissonization step, we use to approximate . In our experiments, we will show that the above MLE estimator is more accurate than the Giroire’s algorithm (Section 4.1), especially for small cardinalities.
5.3. Common-Interest Count Estimation
Similarly, we use the MLE and Poisson approximation techniques to estimate the common-interest count of any two users . Specifically, we assume
Define and . Let and . We also assume
where and . Similar to , we define
Let , , and . Similar to Equation (2), we find that , …, , , …, , , …, are independent, and they are distributed according to the following Poisson distributions
Define , , and . Then, we find that
Let denote the PDF of the random variable pair at , given , , and . In what follows, we omit the conditions , , and for simplicity when no confusion is raised. We derive for all possible relations between and as follows:
Case 1:. This case indicates . Therefore, we have
Case 2:.This case indicates and . Similar to Equation (4), we have . Then, we have
Case 3:. Similar to Case 2, we have
Case 4:. This case indicates that and . Similar to Equation (4), we obtain , , and . Therefore, we have
Case 5:. This case indicates that and . We find that , and . Therefore, we have
Case 6:. Similar to Case 5, we have
Let denote the set of integers , such that the relation between and is Case j, . Define . Then, we have , , , and . Now, we obtain the likelihood function of given by k independent observed variable pairs as
We use the Newton–Raphson method [71] to compute the MLE of , i.e., . The Newton–Raphson method starts from an initial estimation, , and then repeats the following procedure
until a sufficiently accurate root of function is reached, where and are the gradient and the Hessian matrix of at is defined as
The closed formulas of and are given in Appendix A. To set , we initialize and using the estimates of and given in Section 5.2 (i.e., and ) and initialize , where is an estimate of Jaccard similarity , which is introduced in Section 5.1.
Next, we analyze the error of obtained MLE . The Fisher information matrix of is defined as
The closed formula of is given in Appendix A. Let be the element of the inverse of matrix . From [70], we find that the MLE is an asymptotically efficient unbiased estimator of , and its MSE asymptotically approaches the CRLB of , i.e., . Lastly, we use to approximate .
5.4. Space and Time Complexities
Complexities of online generating OH sketches. We use k registers for each occurring user in stream , and the time complexity of processing each element of stream is .
Complexities of densification. No extra memory space is required for densification. From [22], we find that computing a user u’s DOH sketch from its OH sketch requires time complexity .
Complexities of user cardinality estimation. No extra memory space is required for user cardinality estimation. The time complexity of estimating a user’s cardinality is .
Complexities of common-interest count estimation. No extra memory space is required for common-interest count estimation. We find that our method only requires several Newton–Raphson iterations to converge, where each iteration has a negligible computational cost. Therefore, the time complexity of estimating two users’ common-interest counts is .
Complexities of Jaccard similarity estimation. No extra memory space is required for common-interest count estimation. Based on two users’ DOH sketches, time is required when estimating two users’ Jaccard similarity.
Complexities of nearest neighbor search. Given DOH sketches of users in U, space and time are required for building LSH tables, and searching a query user’s nearest neighbors requires time .
6. Evaluation
In this section, we evaluate the runtime and accuracy of our framework, SimCar, compared to the state of the art. All experiments were run on the same machine with an Intel Xeon CPU E5-2620 v3 with 2.4 GHz, and all algorithms were implemented in Python.
6.1. Datasets
We performed our experiments on six real-world datasets from different areas. The dataset Flickr [72] is a bipartite network of Flickr users and their group memberships. The dataset Movie [73] is a bipartite network consisting of one million movie ratings from MovieLens (http://movielens.umn.edu/, accessed on 10 March 2022).
The dataset Wikipedia [74] is a bipartite network of excellent articles in the English Wikipedia (http://en.wikipedia.org/wiki/Wikipedia, accessed on 10 March 2022) which meet a core set of editorial standards, and the words they contain. The dataset Reuters [75] is a bipartite network of article-word inclusions in documents that appeared on Reuters newswire in 1987. The dataset Tropes [76] is a bipartite network of TV tropes (http://tvtropes.org, accessed on 10 March 2022), characterizing artistic works by their tropes. The dataset TREC [77] is a bipartite network of 1.7 million text documents from the Text Retrieval Conference’s (TREC) (http://trec.nist.gov/data/docs_eng.html, accessed on 10 March 2022), containing 556,000 words of different languages. The detailed statistics of these real-world datasets are summarized in Table 2.
Table 2.
Real-world datasets used in our experiments, where “size” refers to the number of elements in the stream.
6.2. Baselines
We compared our framework with the following state-of-the-art methods on all four tasks: user cardinality estimation, common-interest count estimation, Jaccard similarity estimation, and nearest neighbor search.
- MinHash and HLL. For common-interest count estimation, the baseline is the method [15], which estimates common-interest counts by generating both MinHash [16] and HyperLogLog [5] (short for HLL in the following paper) sketches for each user’s interest set. Clearly, one can use generated HLL sketches to estimate user cardinalities, and use generated Minhash sketches to estimate Jaccard similarities and build LSH tables for a nearest neighbor search.
- OPH+HLL. One can also solve all four tasks by combining OPH [17] and HLL, where OPH [17] is much faster than MinHash and exhibits comparable accuracy for applications such as Jaccard similarity estimation and nearest neighbor search [20,21,22]. In detail, HLL sketches were used to estimate user cardinalities, and optimal densified OPH sketches were used to estimate Jaccard similarity and build LSH tables for a rapid nearest neighbor search. To estimate the common-interest count of any two users u and v, we first easily obtained (1) estimations , , and of , , and from HLL sketches and our OH sketches; (2) estimation of Jaccard similarity from optimal densified OPH sketches and DOH sketches. As shown in [15], the common-interest count can be estimated by each of the following schemes: (scheme 1) ; (scheme 2) ; (scheme 3) . Similar to MinHash and HLL method [15], we initialize the parameter for our common-interest count estimation method in Section 5.3 and then run only a single Newton–Raphson iteration to obtain a more accurate estimation of . In our experiments, common-interest count estimations given by OPH and HLL are computed by the above schemes 1, 2, and 3 in a direct manner.
In our experiments, by default, we let MinHash, OPH, and our sketch method OH use the same k, i.e., the number of registers used to generate one MinHash/OPH/OH sketch. We let denote the number of registers used for an HLL sketch. Therefore, our method, SimCar, uses fewer registers than baselines MinHash and HLL and OPH and HLL. Compared with MinHash, OPH, and OH using 32-bit registers, HLL uses 5-bit registers [5]; thus, our method, SimCar, reduces the memory usage by 13.5% and 23.8% when and , respectively.
6.3. Metric
We evaluated both the efficiency and effectiveness of our method, SimCar, in comparison with the above two baseline methods. For efficiency, we evaluated the running time of all methods. Specially, we used the online sketching time to measure the time of online processing stream . For user cardinality estimation, common-interest count estimation, and Jaccard similarity estimation, we evaluated the error of estimation with respect to its true value using the normalized root mean square error (NRMSE), which is defined as , where . For the nearest neighbor search, given a query user, we report the average size of the retrieved user set, as well as the recall of the top 10 most similar users among that set. In our experiments, we computed the above metrics over 100 independent runs.
6.4. Runtime
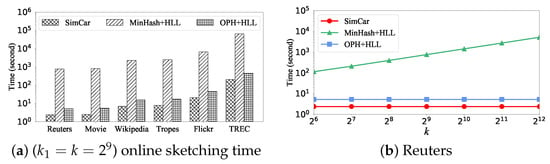
As shown in Figure 2a, where we set , our framework, SimCar, significantly outperforms MinHash and HLL and OPH and HLL on all datasets in Table 2. For example, for Reuters, the online sketching time of SimCar is about 2 seconds, while MinHash and HLL and OPH and HLL need about 764 and seconds, respectively. On average, SimCar is about 400 and times faster than MinHash and HLL and OPH and HLL, respectively. Figure 2b shows the online sketching time for different k. We can see that the online sketching time of SimCar and OPH+HLL is almost constant, while the online sketching time of MinHash and HLL increases linearly to k, because Minhash needs to update each of its k registers when updating each element that occurs in stream .
Figure 2.
Online sketching time of our framework, SimCar, in comparison with MinHash and HLL and OPH and HLL. (a) Sketching time on different datasets with . (b) Sketching time on dataset Reuters with different k.
6.5. Accuracy
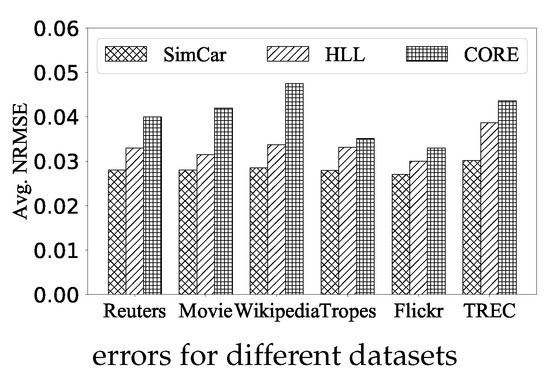
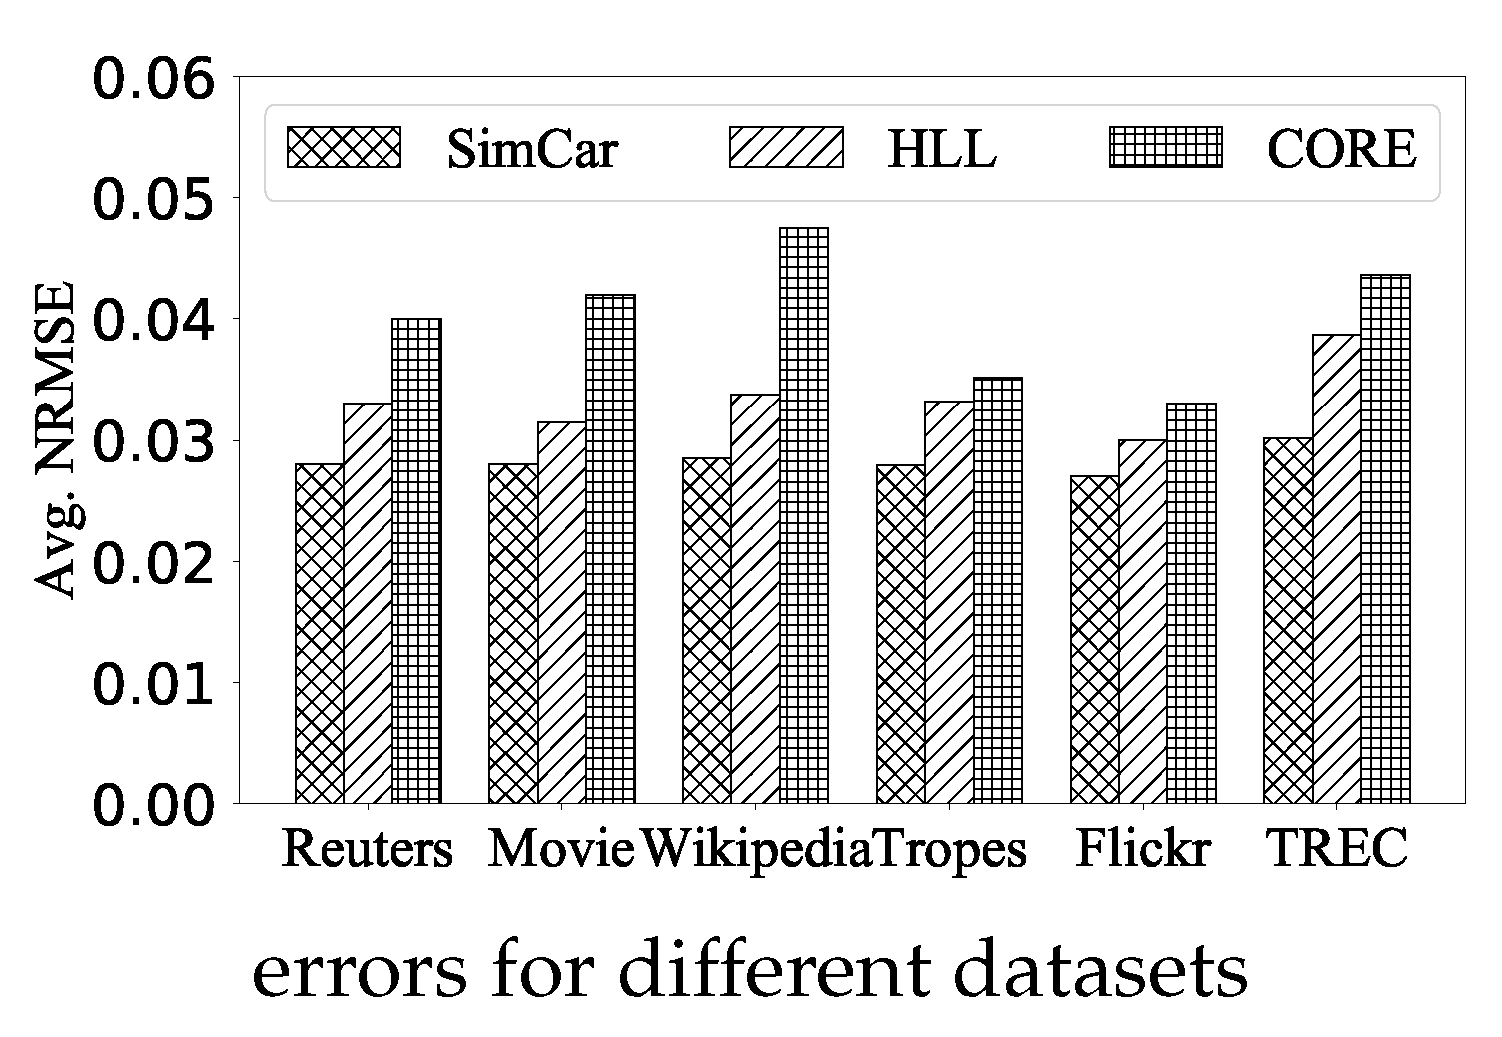
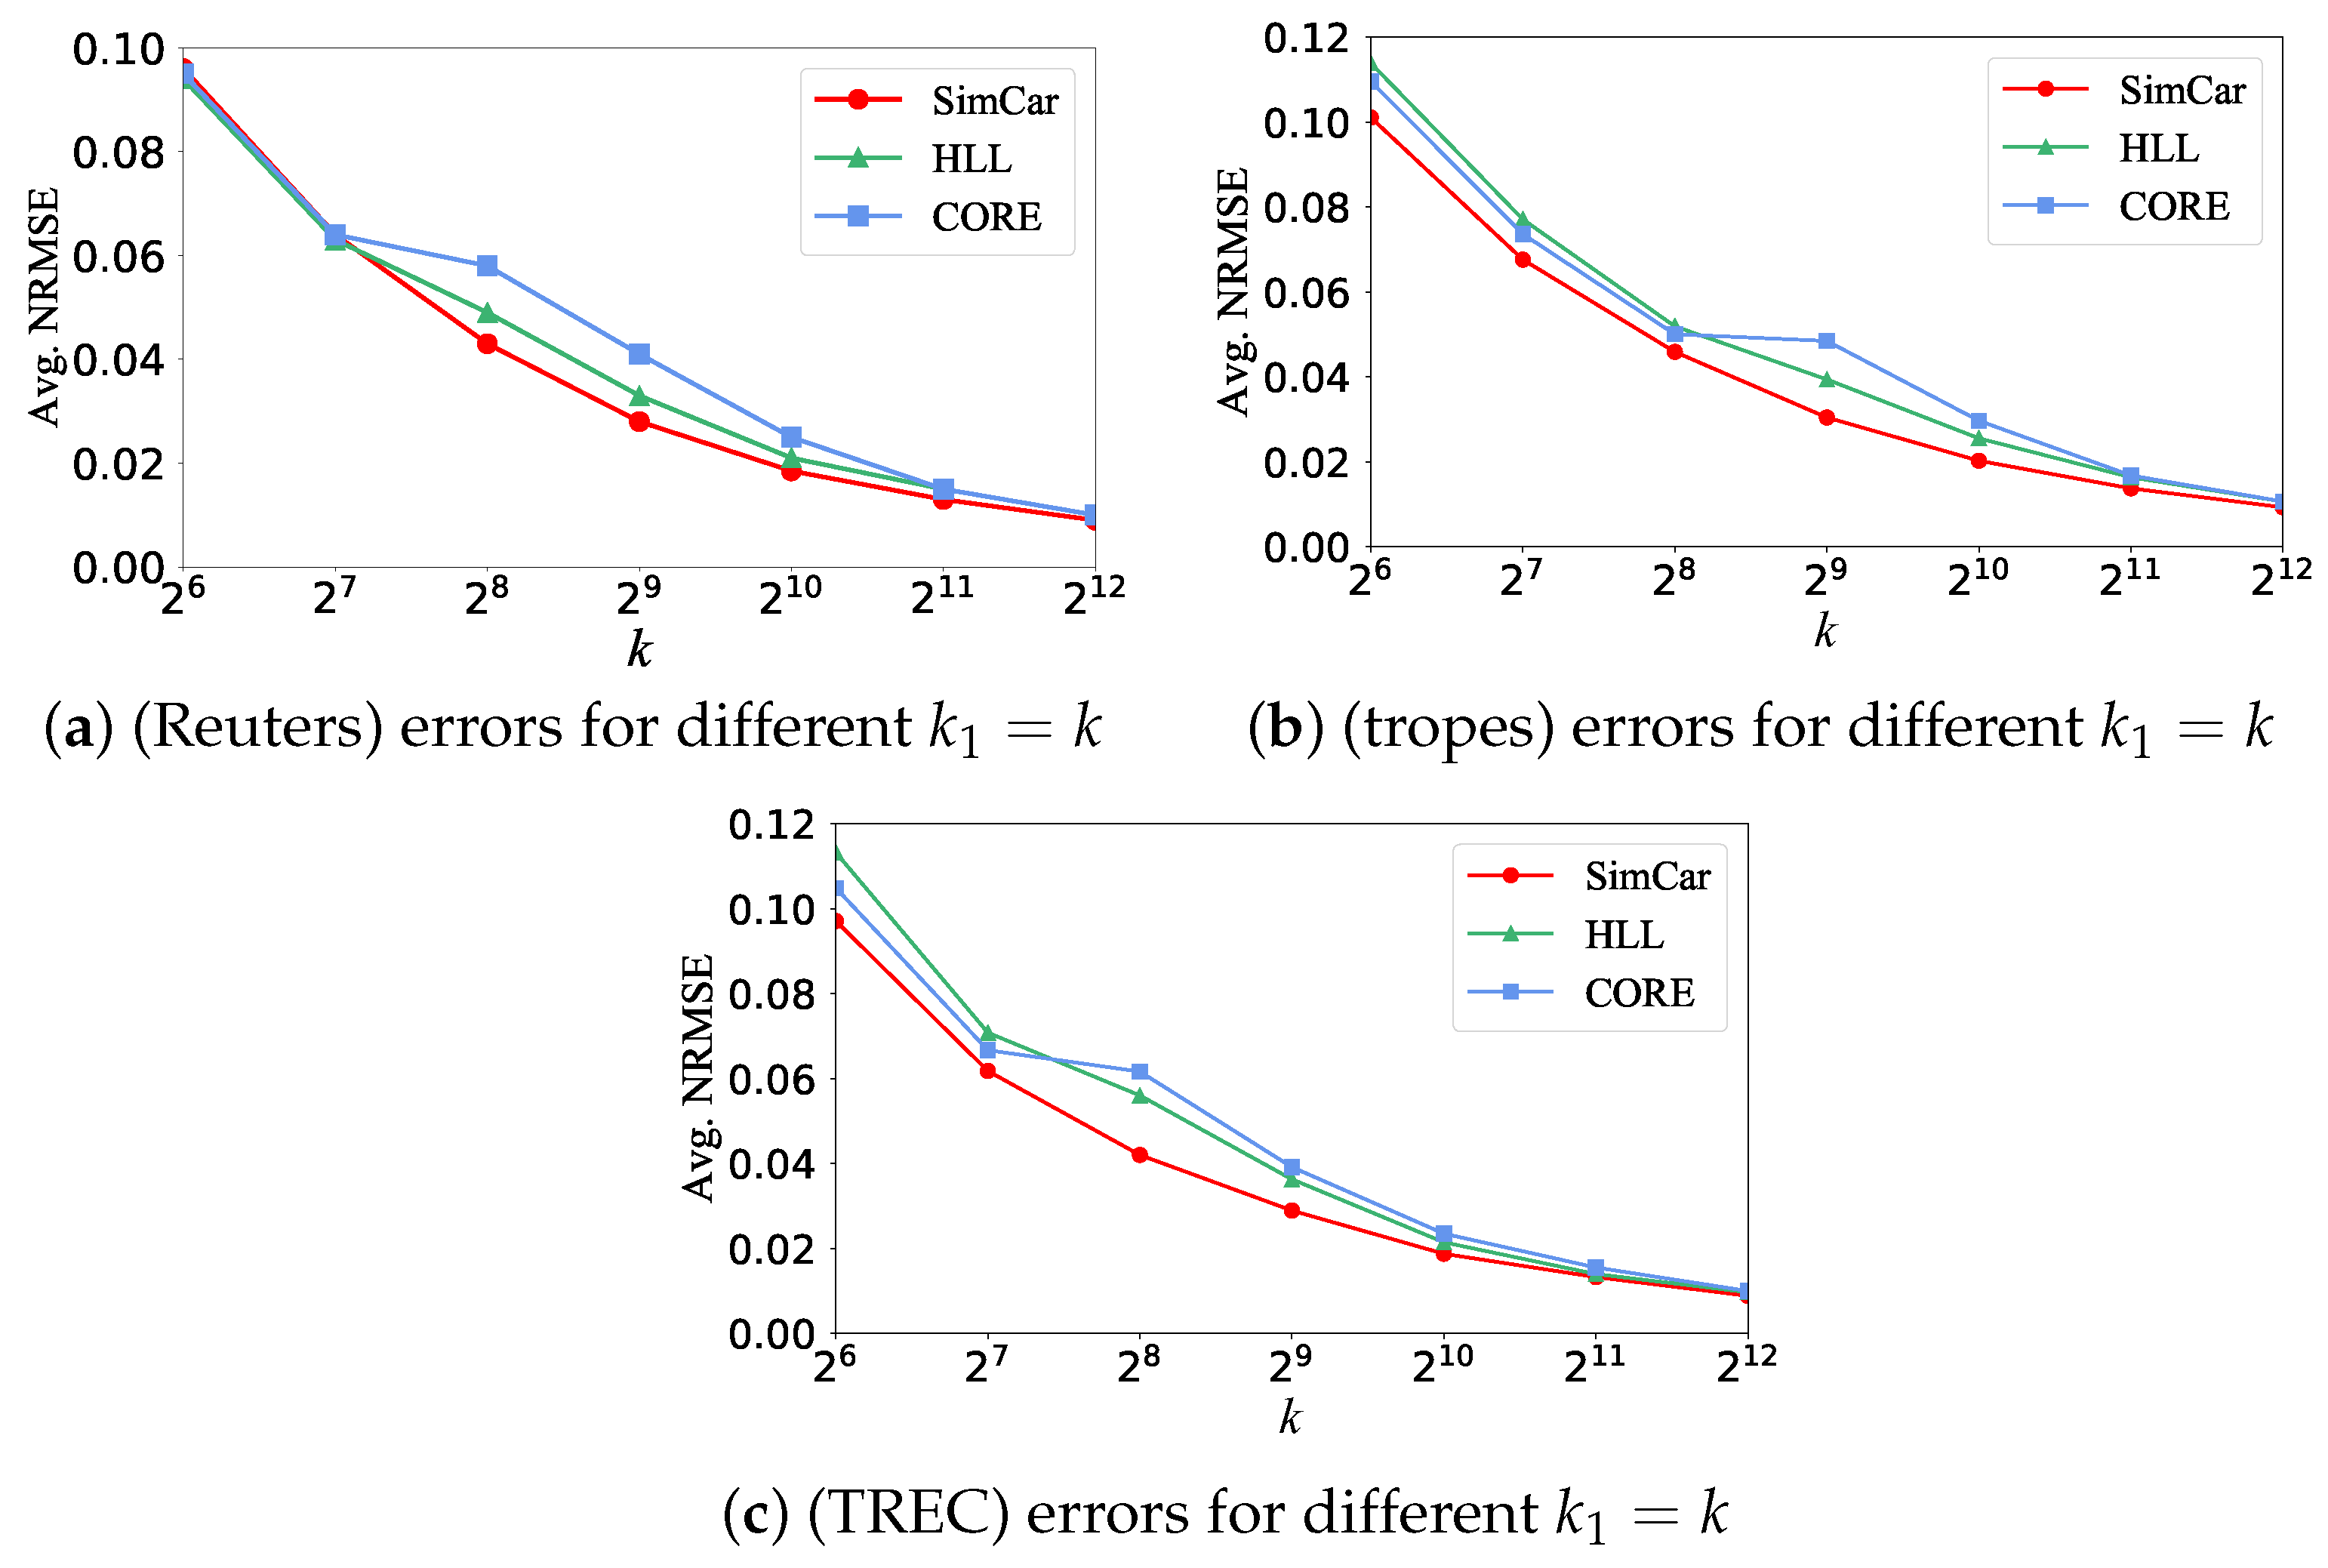
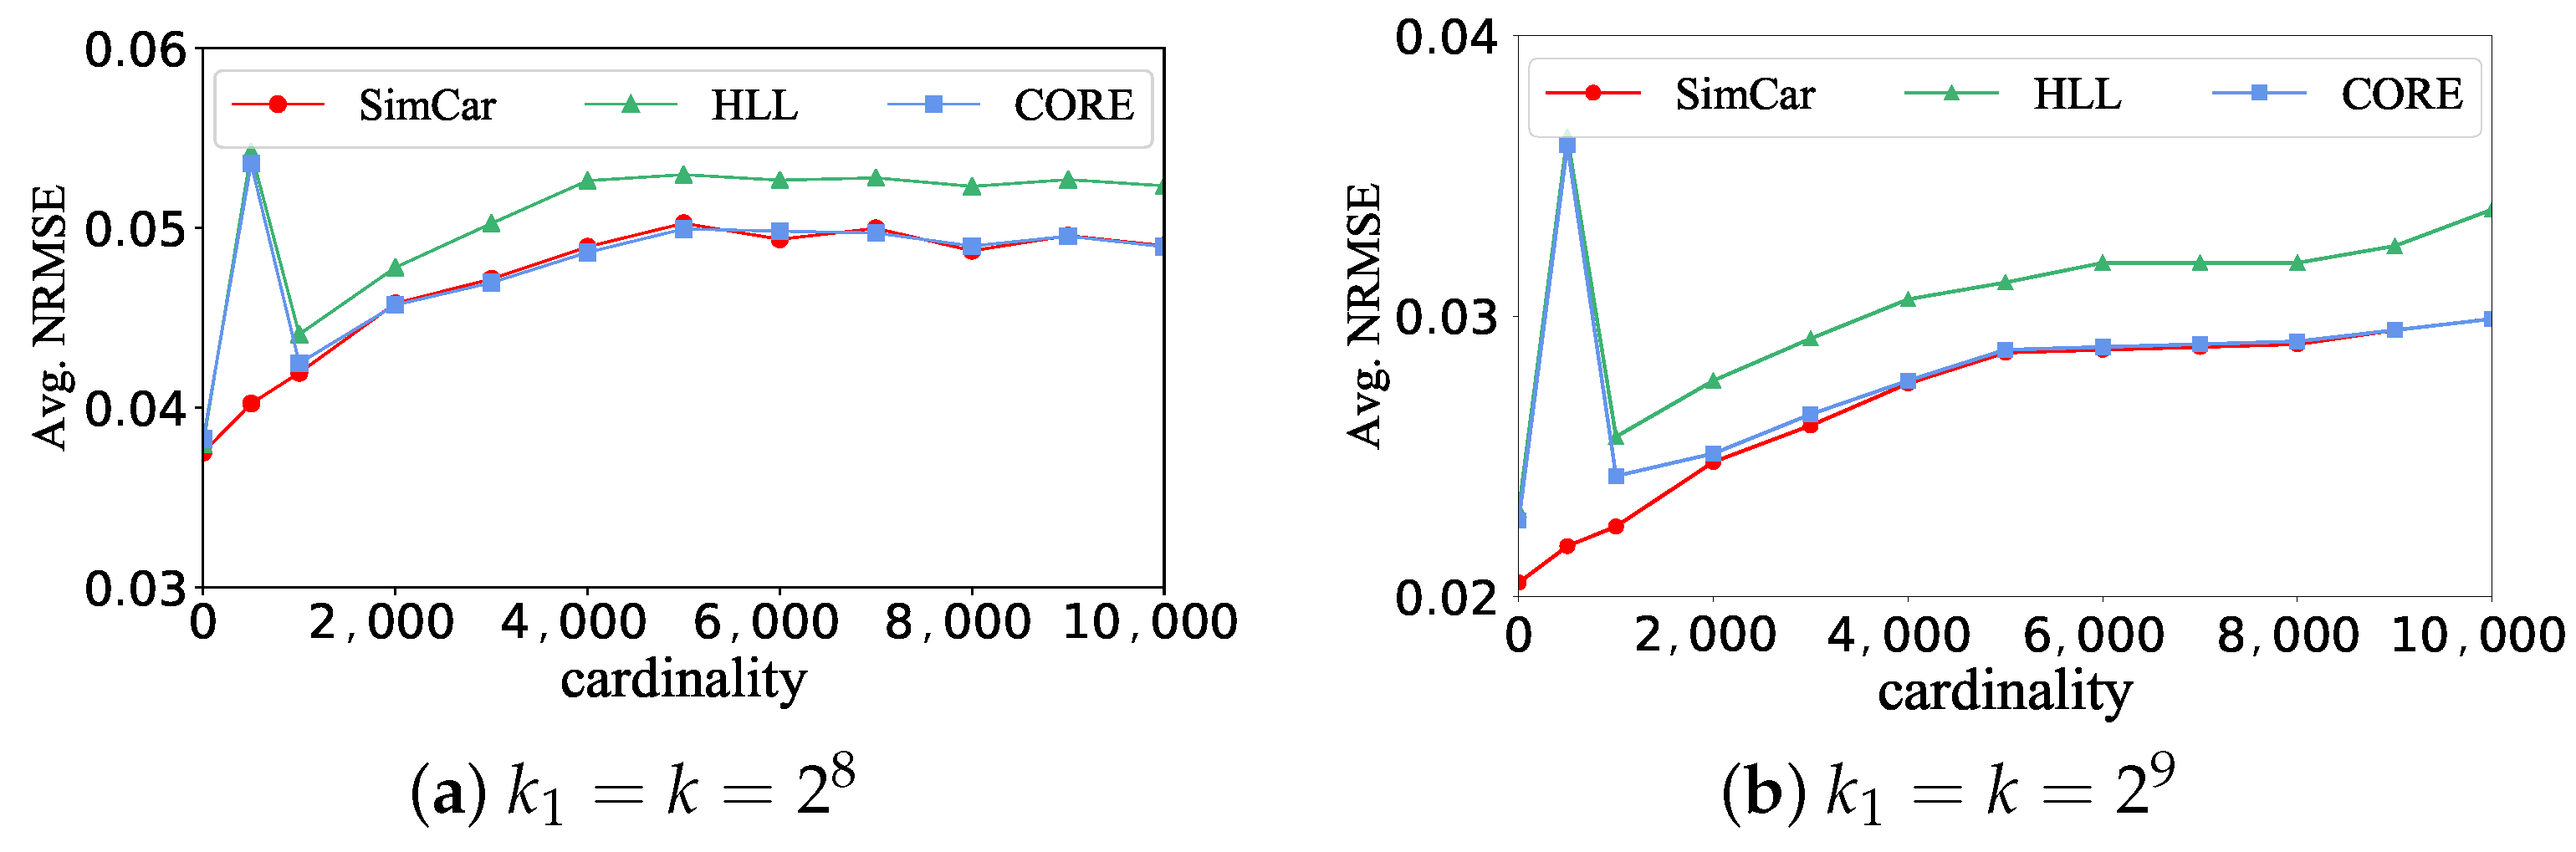
Results of cardinality estimation. We compared our method, SimCar, with HyperLogLog used by MinHash and HLL and OPH and HLL, as well as the CORE algorithm [59], which is introduced in Algorithm 3 in Section 5. In this experiment, all three sketch methods—HLL, CORE, and SimCar—use the same number of registers, i.e., . As shown in Figure 3, our method, SimCar, is significantly more accurate than HLL and CORE on these real-world datasets. To be more specific, SimCar gives a gain of ∼ (resp. ∼) improvement to CORE (resp. HLL). For example, on Wikipedia, the average NRMSE of SimCar is , while those of HLL and CORE are and , respectively. Figure 4 further shows the average NRMSEs for different k. We can see that the average NRMSEs of all methods decrease as k increases, and our method is consistently more accurate than HLL and CORE. In addition, we compute the fine-grained NRMSEs with respect to the user cardinality ranging from 1 to with and . As shown in Figure 5, both HLL and CORE exhibit large estimation errors when user cardinality is small because they both use two different estimators for cardinalities within two different ranges, respectively. However, our method, SimCar, just uses one estimator, and we find that SimCar decreases the NRMSEs of HLL and CORE by for different user cardinalities.
Figure 3.
User cardinality estimation errors of our framework, SimCar, compared with HLL and CORE, by default.
Figure 4.
User cardinality estimation errors of our framework, SimCar, compared with HLL and CORE, by default.
Figure 5.
User cardinality estimation errors of our framework, SimCar, compared with HLL and CORE.
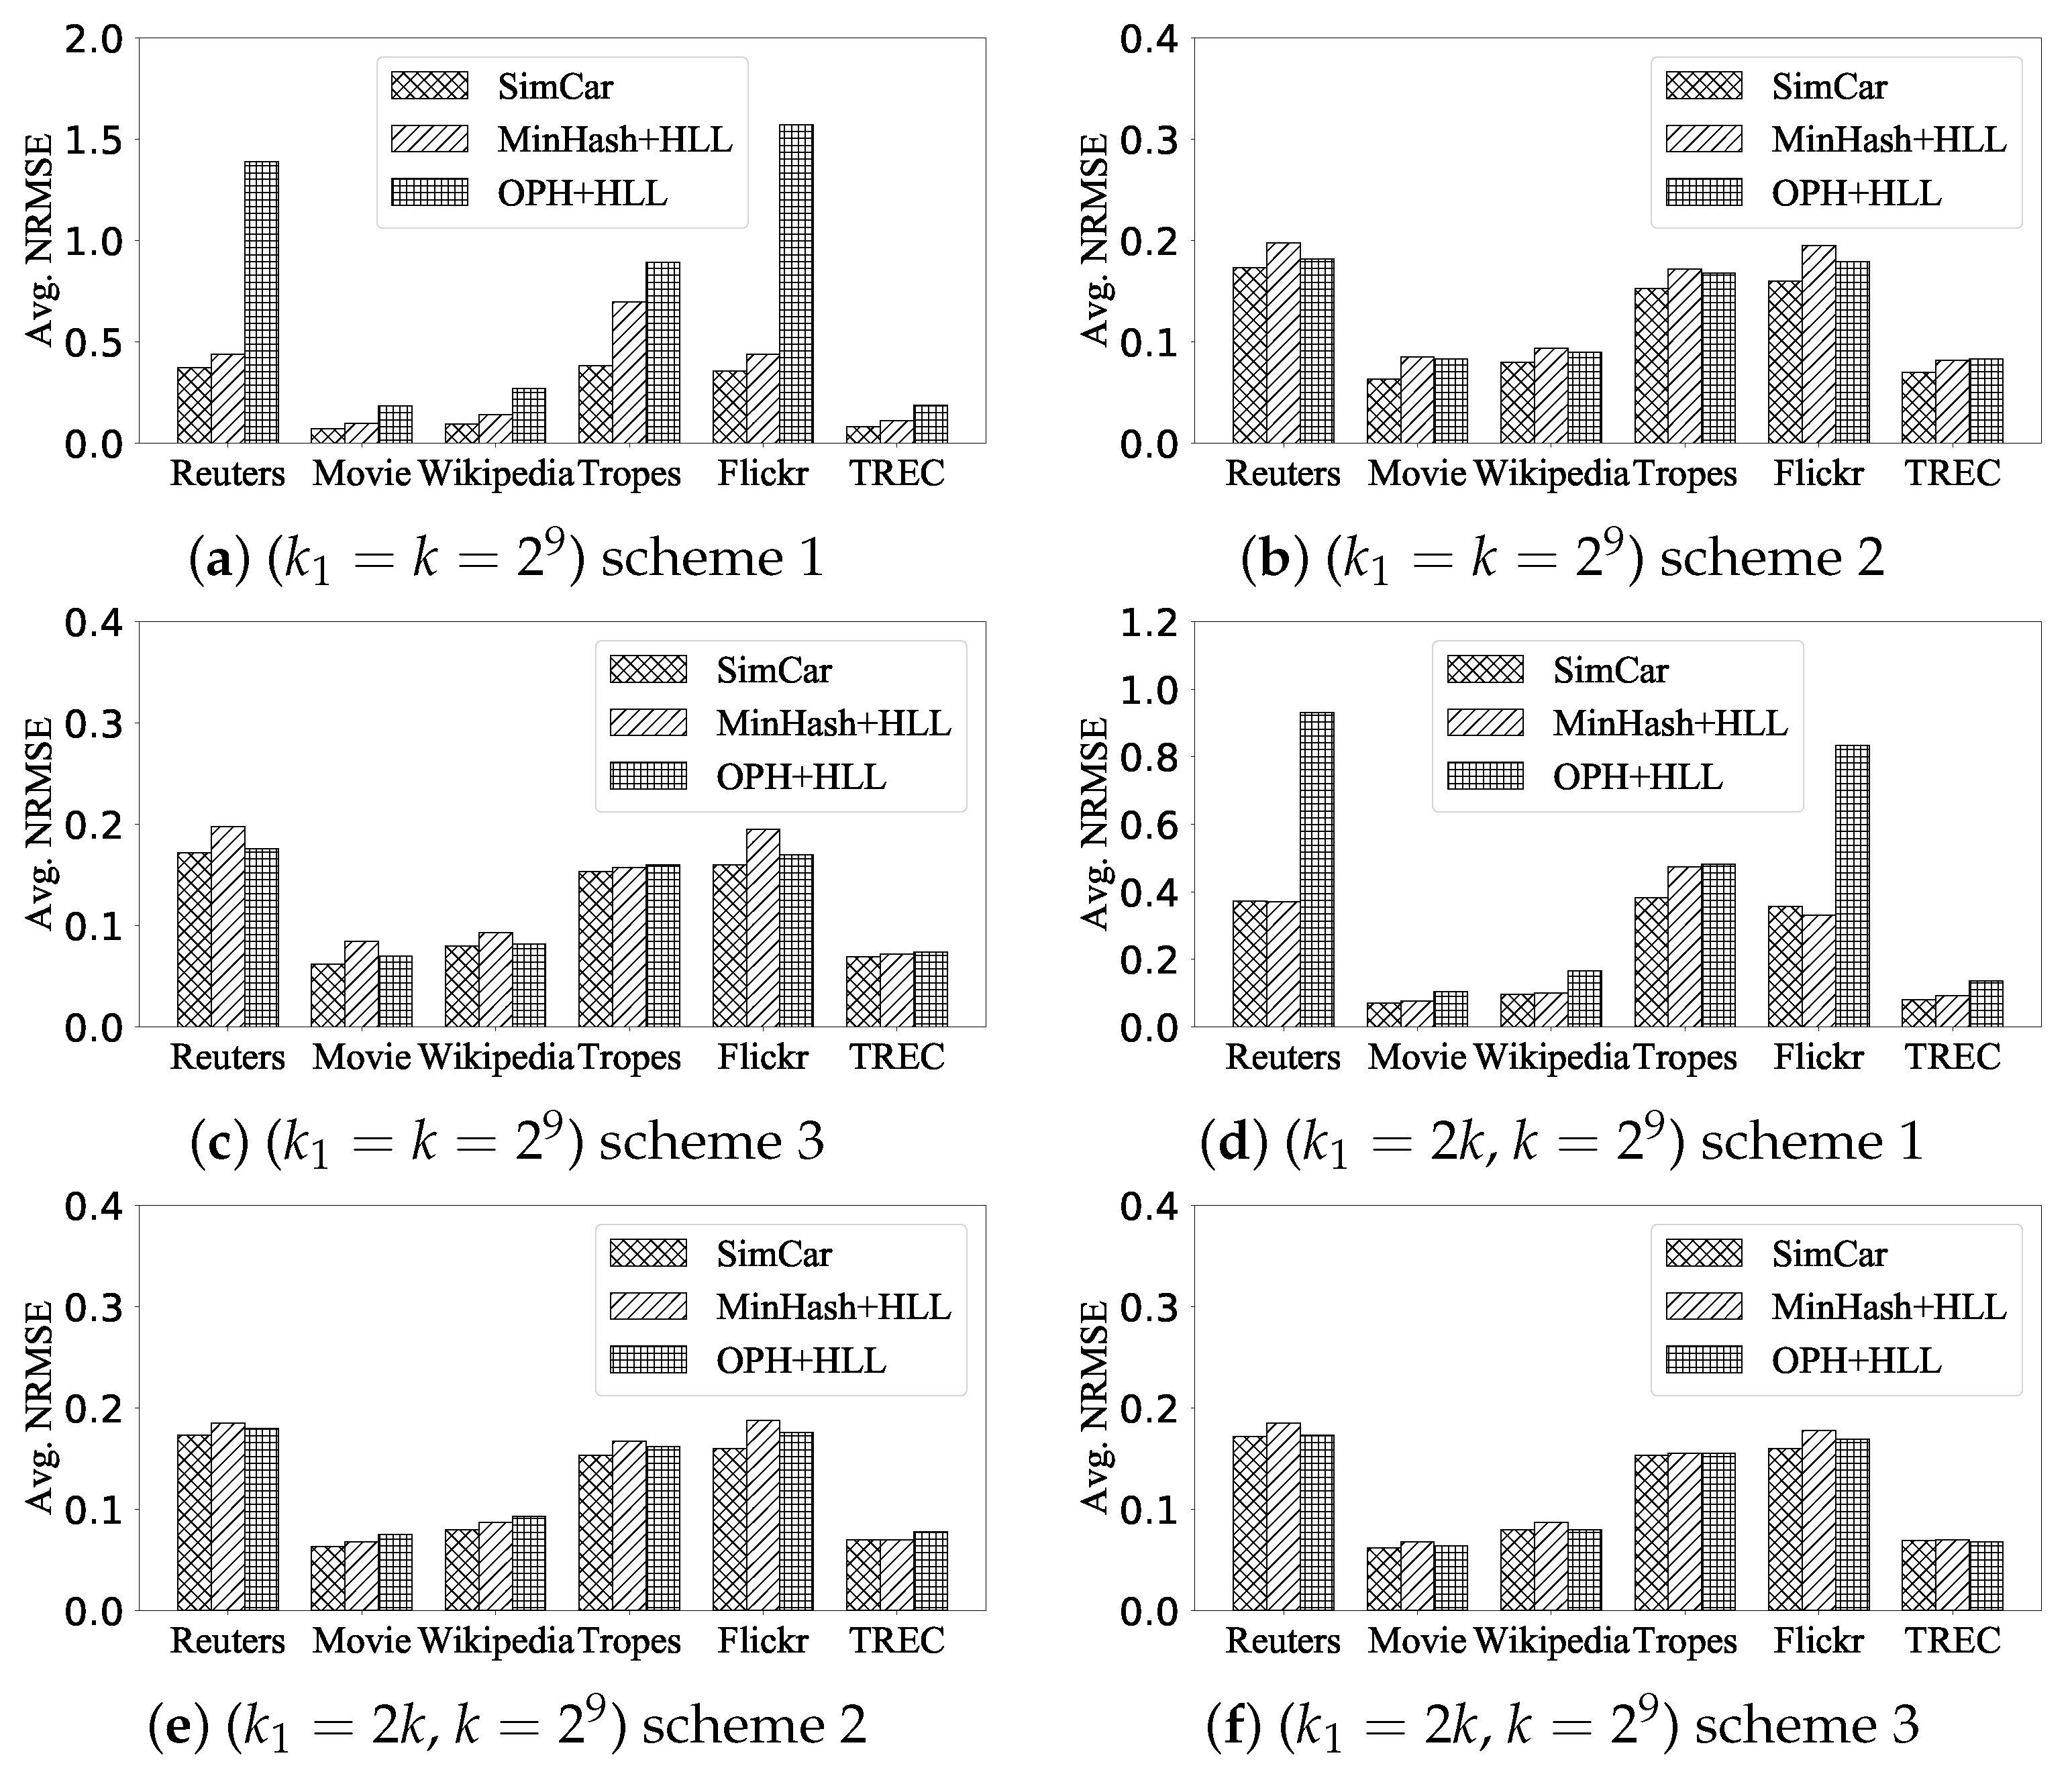
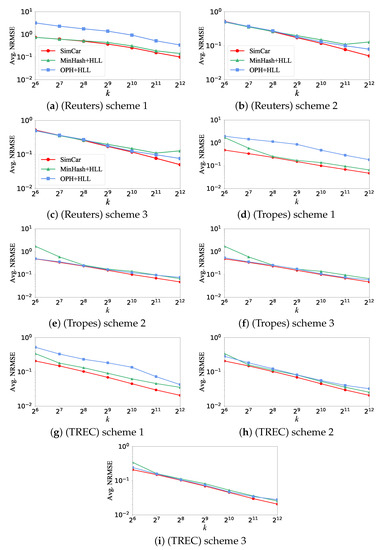
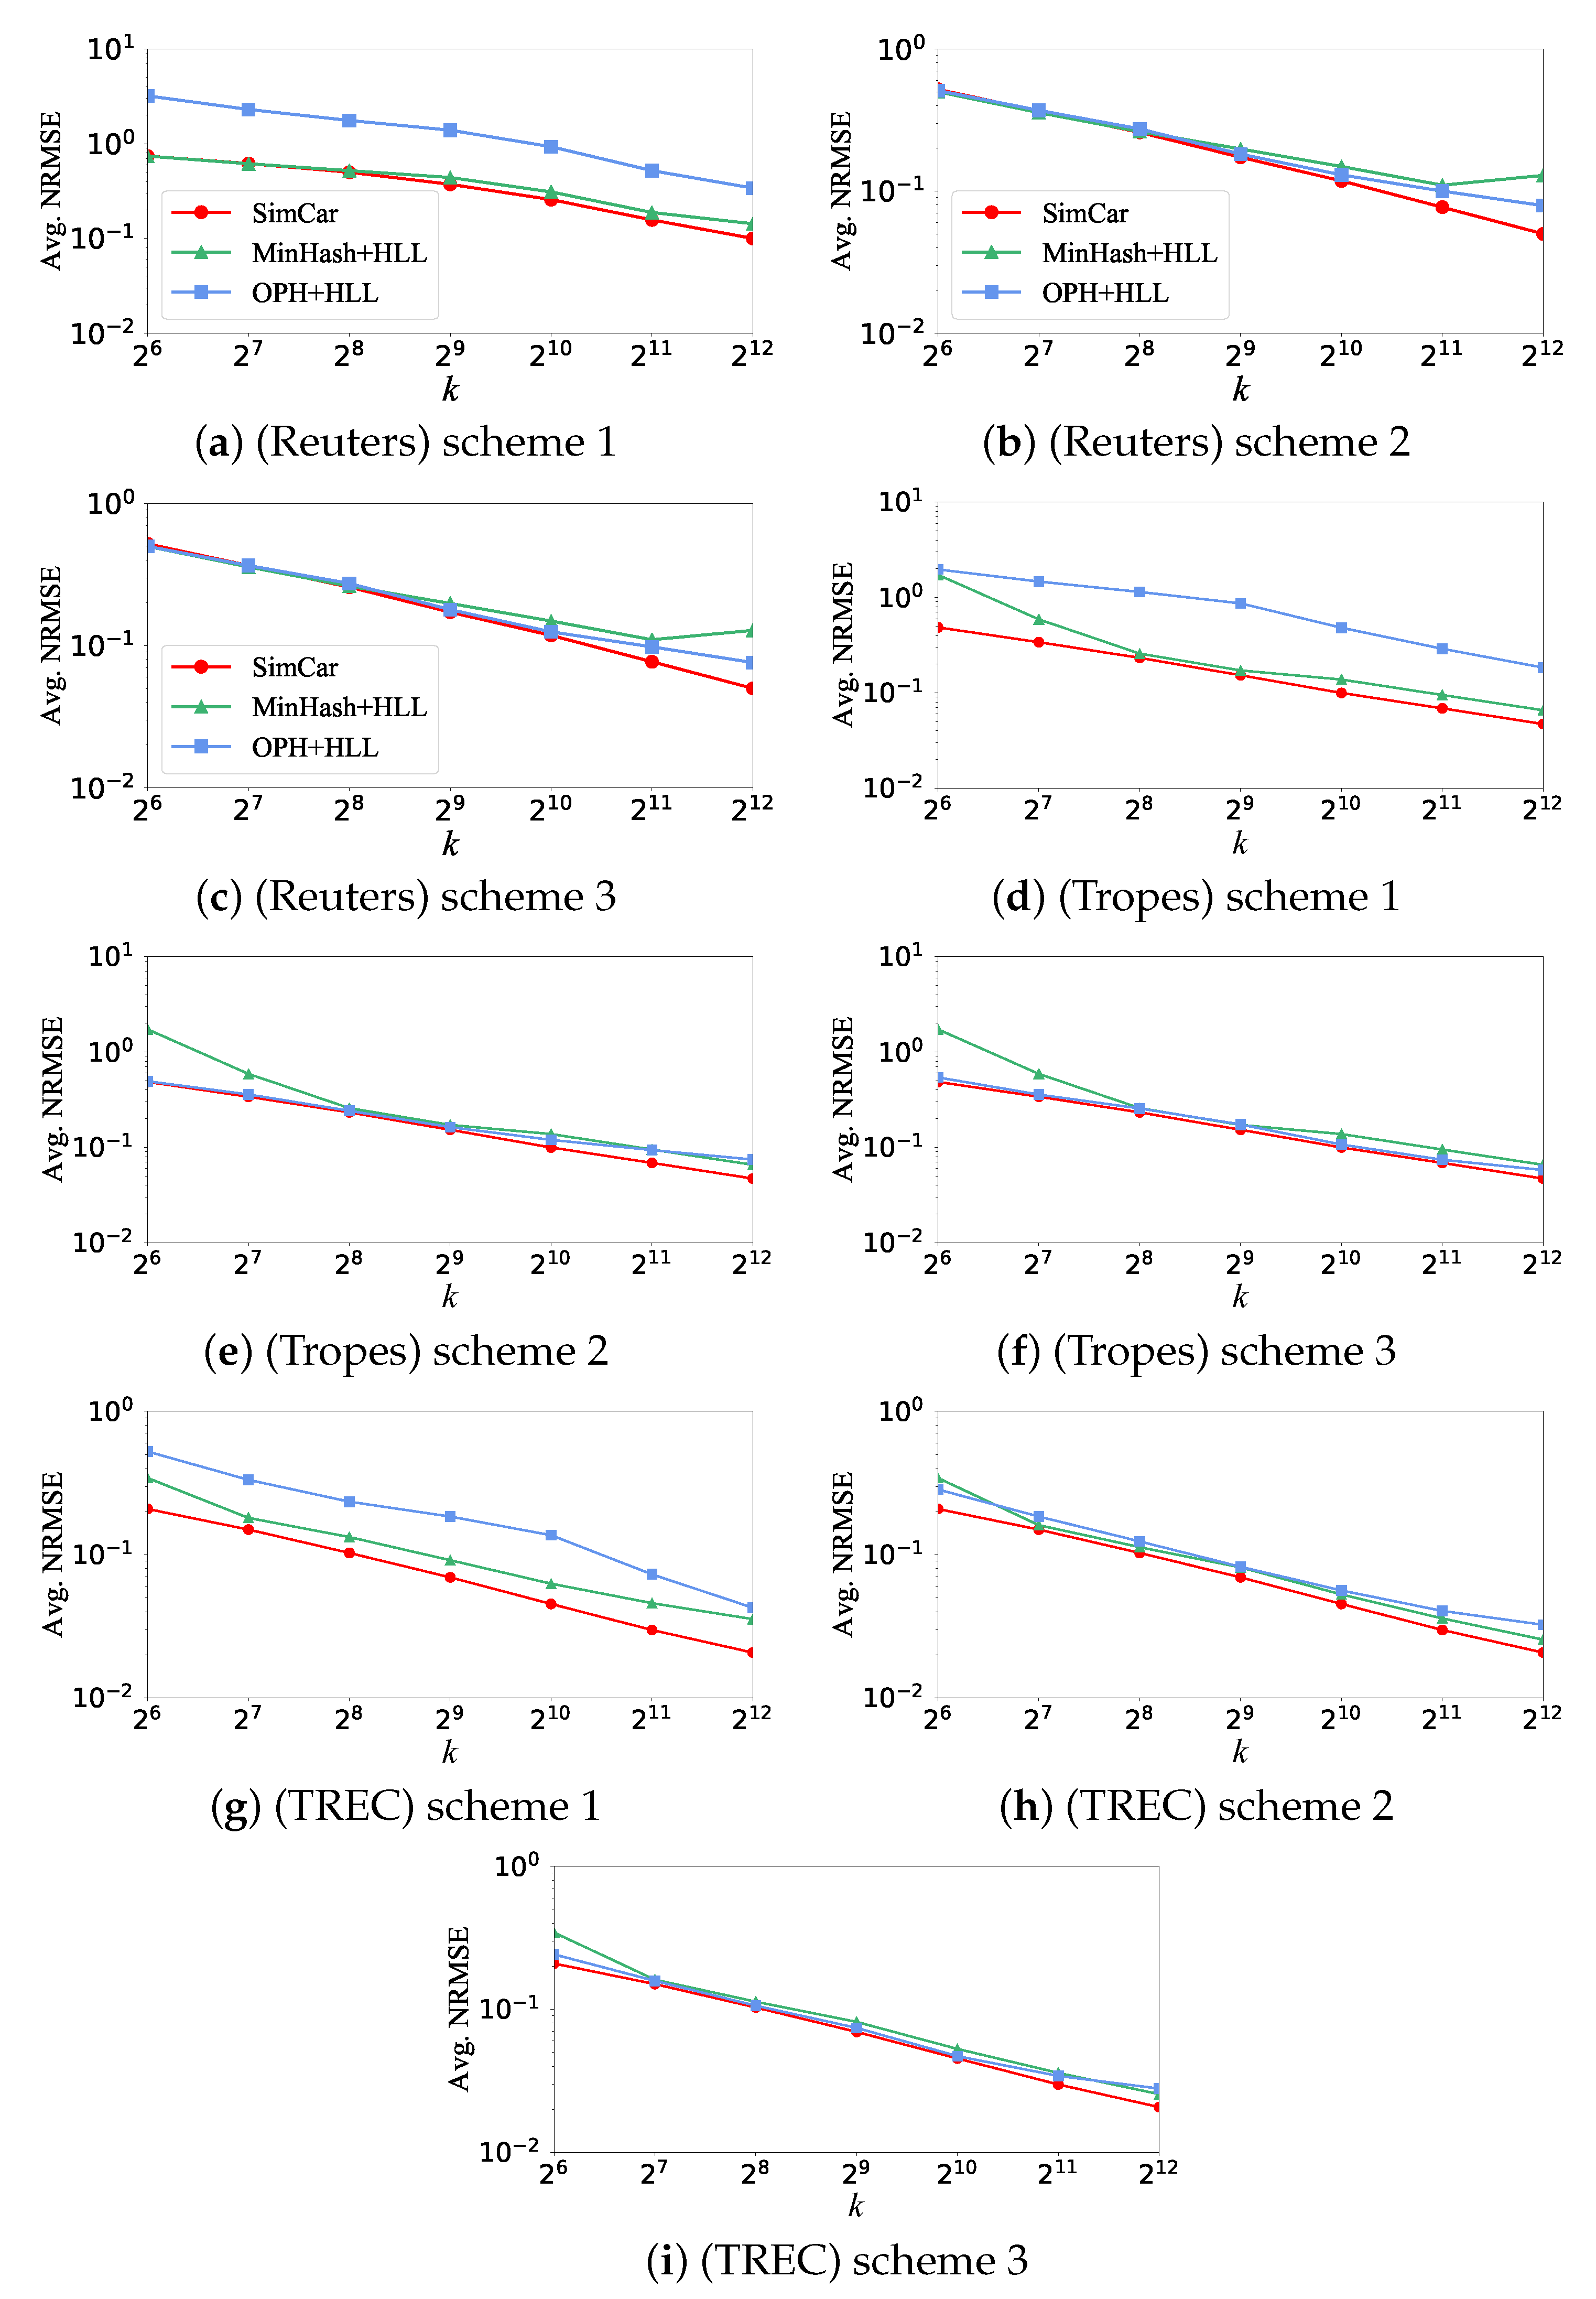
Results of common-interest count estimation. As shown in Figure 6a–c, where we set , we can see that our method, SimCar, is more accurate than the other two methods for all three schemes introduced in Section 6.2, and scheme 1 performs the worst among the three schemes, whose average NRMSEs are up to those of the other two schemes. We raised to , and the results are shown in Figure 6d–f. We can see that SimCar still outperforms MinHash and HLL and OPH and HLL for most of the datasets. Figure 7 show the average NRMSEs for different k on datasets Reuters, Tropes, and TREC, where we set . We can see that the average NRMSEs of all methods decrease as k increases. For scheme 1, our method, SimCar, is up to four and three times more accurate than MinHash and HLL and OPH and HLL, respectively. For schemes 2 and 3, we find that OPH and HLL gives results comparable to SimCar when k is medium. However, our method, SimCar, still outperforms OPH and HLL when .
Figure 6.
Average NRMSEs of SimCar compared with MinHash and HLL and OPH and HLL for estimating common-interest counts.
Figure 7.
Average NRMSEs of SimCar compared with MinHash and HLL and OPH and HLL for estimating common-interest counts.
Results of Jaccard similarity estimation and nearest neighbor search. We compared our method to the MinHash sketch and densified OPH sketch for Jaccard similarity estimation and nearest neighbor search. We used the technique discussed in Section 5.1 to build LSH for all three methods. The experimental results in Table 3 demonstrate that our method, SimCar, is comparable to MinHash and densified OPH on all the datasets.
Table 3.
Performance of our framework, SimCar, compared with MinHash and OPH for Jaccard similarity estimation and nearest neighbor search with , .
7. Conclusions and Future Work
In this paper, a framework—SimCar—was developed for mining users’ interest sets. We built an OH sketch for each user that occurred in the data stream of interest, and one can query several mining results of users’ interest sets at any time of the data stream. Specially, we developed accurate methods for estimating cardinalities, common-interest counts, and Jaccard similarities of users’ interest sets. In addition, we used OH sketches to build LSH tables to quickly search for users with similar interests with sub-linear time. We evaluated the performance of our methods on real-world datasets. The experimental results demonstrated the effectiveness and efficacy of our methods. In future, we plan to use techniques such as register sharing (i.e., compress the OH sketches of all users into a large register array) to further reduce the memory usage.
Author Contributions
Conceptualization, K.Y. and Y.Q.; methodology, K.Y. and Y.Q.; software, K.Y. and Y.Q.; validation, K.Y.; formal analysis, K.Y. and Y.Q.; investigation, K.Y. and Y.Q.; resources, K.Y. and P.J.; data curation, Y.Q.; writing—original draft preparation, K.Y.; writing—review and editing, W.G., Y.Q., P.W. and P.J.; visualization, K.Y.; supervision, W.G., P.W. and P.J.; project administration, W.G.; funding acquisition, W.G. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by National Key R&D Program of China (2021YFB1715600).
Data Availability Statement
Publicly available datasets were analyzed in this study. This data can be found here: [http://movielens.umn.edu/; http://en.wikipedia.org/wiki/Wikipedia; http://tvtropes.org; http://trec.nist.gov/data/docseng.html].
Conflicts of Interest
The authors declare that they have no conflict of interest.
Appendix A
(1) Formula of the gradient . Each element of is computed as
(2) Formula of Hessian matrix . Each element of is computed as
Based the above equations and the formula of , we easily obtain the formula of each entry of matrix .
References
- Cormode, G.; Muthukrishnan, S. An Improved Data Stream Summary: The Count-min Sketch and Its Applications. J. Algorithms 2005, 55, 58–75. [Google Scholar] [CrossRef] [Scilit]
- Estan, C.; Varghese, G.; Fisk, M. Bitmap algorithms for counting active flows on high speed links. In Proceedings of the SIGCOMM, Karlsruhe, Germany, 25–29 August 2003; pp. 182–209. [Google Scholar]
- Whang, K.; Vander-zanden, B.T.; Taylor, H.M. A linear-time probabilistic counting algorithm for database applications. IEEE Trans. Database Syst. 1990, 15, 208–229. [Google Scholar] [CrossRef] [Scilit]
- Durand, M.; Flajolet, P. Loglog Counting of Large Cardinalities; Springer: Berlin/Heidelberg, Germany, 2003; pp. 605–617. [Google Scholar]
- Flajolet, P.; Fusy, E.; Gandouet, O.; Meunier, F. Hyperloglog: The analysis of a near-optimal cardinality estimation algorithm. In Proceedings of the AOFA, Nice, France, 17–22 June 2007. [Google Scholar]
- Giroire, F. Order statistics and estimating cardinalities of massive data sets. Discret. Appl. Math. 2009, 157, 406–427. [Google Scholar] [CrossRef] [Scilit]
- Kane, D.M.; Nelson, J.; Woodruff, D.P. An Optimal Algorithm for the Distinct Elements Problem. In Proceedings of the PODS, Indianapolis, IN, USA, 6–11 June 2010; pp. 41–52. [Google Scholar]
- Zhao, Q.; Kumar, A.; Xu, J. Joint data streaming and sampling techniques for detection of super sources and destinations. In Proceedings of the ACM SIGCOMM IMC 2005, Berkeley, CA, USA, 19–21 October 2005; pp. 77–90. [Google Scholar]
- Yoon, M.; Li, T.; Chen, S.; Peir, J.K. Fit a spread estimator in small memory. In Proceedings of the IEEE INFOCOM 2009, Rio de Janeiro, Brazil, 19–25 April 2009; pp. 504–512. [Google Scholar]
- Wang, P.; Guan, X.; Qin, T.; Huang, Q. A Data Streaming Method for Monitoring Host Connection Degrees of High-Speed Links. IEEE Trans. Inf. Forensics Secur. 2011, 6, 1086–1098. [Google Scholar] [CrossRef] [Scilit]
- Xiao, Q.; Chen, S.; Chen, M.; Ling, Y. Hyper-Compact Virtual Estimators for Big Network Data Based on Register Sharing. In Proceedings of the SIGMETRICS, Portland, OR, USA, 15–19 June 2015; pp. 417–428. [Google Scholar]
- Chen, A.; Cao, J.; Shepp, L.; Nguyen, T. Distinct counting with a self-learning bitmap. J. Am. Stat. Assoc. 2011, 106, 879–890. [Google Scholar] [CrossRef] [Scilit]
- Ting, D. Towards Optimal Cardinality Estimation of Unions and Intersections with Sketches. In Proceedings of the SIGKDD, San Francisco, CA, USA, 13–17 August 2016. [Google Scholar]
- Zhao, P.; Aggarwal, C.C.; He, G. Link prediction in graph streams. In Proceedings of the 32nd IEEE International Conference on Data Engineering, (ICDE 2016), Helsinki, Finland, 16–20 May 2016; pp. 553–564. [Google Scholar]
- Cohen, R.; Katzir, L.; Yehezkel, A. A Minimal Variance Estimator for the Cardinality of Big Data Set Intersection. In Proceedings of the SIGKDD, Halifax, NS, Canada, 13–17 August 2017. [Google Scholar]
- Broder, A.Z.; Charikar, M.; Frieze, A.M.; Mitzenmacher, M. Min-Wise Independent Permutations. J. Comput. Syst. Sci. 2000, 60, 630–659. [Google Scholar] [CrossRef] [Scilit]
- Li, P.; Owen, A.B.; Zhang, C. One Permutation Hashing. In Proceedings of the NIPS, Lake Tahoe, NV, USA, 3–6 December 2012; pp. 3122–3130. [Google Scholar]
- Li, P.; König, A.C. b-Bit minwise hashing. In Proceedings of the WWW, Raleigh, NC, USA, 26–30 April 2010; pp. 671–680. [Google Scholar]
- Mitzenmacher, M.; Pagh, R.; Pham, N. Efficient estimation for high similarities using odd sketches. In Proceedings of the WWW, Doha, Qatar, 7–11 April 2014; pp. 109–118. [Google Scholar]
- Shrivastava, A.; Li, P. Improved Densification of One Permutation Hashing. In Proceedings of the UAI, Quebec City, QC, Canada, 23–27 July 2014; pp. 732–741. [Google Scholar]
- Shrivastava, A.; Li, P. Densifying One Permutation Hashing via Rotation for Fast Near Neighbor Search. In Proceedings of the ICML, Beijing, China, 21–26 June 2014; pp. 557–565. [Google Scholar]
- Shrivastava, A. Optimal Densification for Fast and Accurate Minwise Hashing. In Proceedings of the ICML, Sydney, Australia, 6–11 August 2017; pp. 3154–3163. [Google Scholar]
- Indyk, P.; Motwani, R. Approximate Nearest Neighbors: Towards Removing the Curse of Dimensionality. In Proceedings of the STOC, Dallas, TX, USA, 23–26 May 1998; pp. 604–613. [Google Scholar]
- Gionis, A.; Indyk, P.; Motwani, R. Similarity Search in High Dimensions via Hashing. In Proceedings of the PVLDB, Edinburgh, UK, 7–10 September 1999; pp. 518–529. [Google Scholar]
- Charikar, M. Similarity estimation techniques from rounding algorithms. In Proceedings of the STOC, Montreal, QC, Canada, 19–21 May 2002; pp. 380–388. [Google Scholar]
- Datar, M.; Immorlica, N.; Indyk, P.; Mirrokni, V.S. Locality-sensitive hashing scheme based on p-stable distributions. In Proceedings of the SOCG, Brooklyn, NY, USA, 8–11 June 2004; pp. 253–262. [Google Scholar]
- Wang, P.; Qi, Y.; Zhang, Y.; Zhai, Q.; Wang, C.; Lui, J.C.S.; Guan, X. A Memory-Efficient Sketch Method for Estimating High Similarities in Streaming Sets. In Proceedings of the KDD, Anchorage, AK, USA, 4–8 August 2019; pp. 25–33. [Google Scholar]
- Li, X.; Li, P. C-OPH: Improving the Accuracy of One Permutation Hashing (OPH) with Circulant Permutations. arXiv 2021, arXiv:2111.09544. [Google Scholar]
- Fernandez, R.C.; Min, J.; Nava, D.; Madden, S. Lazo: A Cardinality-Based Method for Coupled Estimation of Jaccard Similarity and Containment. In Proceedings of the 2019 IEEE 35th International Conference on Data Engineering (ICDE), Macao, China, 8–11 April 2019; IEEE: Piscataway, NJ, USA, 2019; pp. 1190–1201. [Google Scholar]
- Manasse, M.; McSherry, F.; Talwar, K. Consistent Weighted Sampling; Technical Report; John Cappelen: Copenhagen, Denmark, 2010. [Google Scholar]
- Haeupler, B.; Manasse, M.S.; Talwar, K. ling Made Fast, Small, and Easy. CoRR 2014. abs/1410.4266. [Google Scholar]
- Ioffe, S. Improved Consistent Sampling, Weighted Minhash and L1 Sketching. In Proceedings of the ICDM, Sydney, Australia, 13–17 December 2010; pp. 246–255. [Google Scholar]
- Li, P. 0-Bit Consistent Weighted Sampling. In Proceedings of the KDD, Sydney, Australia, 10–13 August 2015; pp. 665–674. [Google Scholar]
- Wu, W.; Li, B.; Chen, L.; Zhang, C. Canonical Consistent Weighted Sampling for Real-Value Weighted Min-Hash. In Proceedings of the ICDM, Barcelona, Spain, 12–15 December 2016; pp. 1287–1292. [Google Scholar]
- Shrivastava, A. Simple and Efficient Weighted Minwise Hashing. In Proceedings of the NIPS, Barcelona, Spain, 5–10 December 2016; pp. 1498–1506. [Google Scholar]
- Wu, W.; Li, B.; Chen, L.; Zhang, C. Consistent Weighted Sampling Made More Practical. In Proceedings of the WWW, Seville, Spain, 16–18 November 2017; pp. 1035–1043. [Google Scholar]
- Ertl, O. BagMinHash-Minwise Hashing Algorithm for Weighted Sets. CoRR 2018. abs/1802.03914. [Google Scholar]
- Li, P.; Li, X.; Samorodnitsky, G.; Zhao, W. Consistent Sampling Through Extremal Process. In Proceedings of the Web Conference 2021, Ljubljana, Slovenia, 19–23 April 2021; pp. 1317–1327. [Google Scholar]
- Moulton, R.; Jiang, Y. Maximally Consistent Sampling and the Jaccard Index of Probability Distributions. arXiv 2018, arXiv:1809.04052. [Google Scholar]
- Qi, Y.; Wang, P.; Zhang, Y.; Zhao, J.; Tian, G.; Guan, X. Fast Generating A Large Number of Gumbel-Max Variables. In Proceedings of the WWW, Taipei, Taiwan, 20–24 April 2020; pp. 796–807. [Google Scholar]
- Panigrahy, R. Entropy based nearest neighbor search in high dimensions. In Proceedings of the SODA, Miami, FL, USA, 22–26 January 2006; pp. 1186–1195. [Google Scholar]
- Lv, Q.; Josephson, W.; Wang, Z.; Charikar, M.; Li, K. Multi-probe LSH: Efficient indexing for high-dimensional similarity search. In Proceedings of the VLDB, Vienna, Austria, 23–27 September 2007; pp. 950–961. [Google Scholar]
- Huang, Q.; Feng, J.; Zhang, Y.; Fang, Q.; Ng, W. Query-aware locality-sensitive hashing for approximate nearest neighbor search. PVLDB 2015, 9, 1–12. [Google Scholar] [CrossRef] [Scilit]
- Gan, J.; Feng, J.; Fang, Q.; Ng, W. Locality-sensitive hashing scheme based on dynamic collision counting. In Proceedings of the SIGMOD, Scottsdale, AZ, USA, 20 May 2012; pp. 541–552. [Google Scholar]
- Liu, Y.; Cui, J.; Huang, Z.; Li, H.; Shen, H.T. SK-LSH: An efficient index structure for approximate nearest neighbor search. PVLDB 2014, 7, 745–756. [Google Scholar] [CrossRef] [Scilit]
- Tao, Y.; Yi, K.; Sheng, C.; Kalnis, P. Quality and efficiency in high dimensional nearest neighbor search. In Proceedings of the SIGMOD, Providence, RI, USA, 29 June–2 July 2009; pp. 563–576. [Google Scholar]
- Satuluri, V.; Parthasarathy, S. Bayesian locality sensitive hashing for fast similarity search. PVLDB 2012, 5, 430–441. [Google Scholar] [CrossRef] [Scilit]
- Gao, J.; Visvesvaraya Jagadish, H.; Lu, W.; Chin Ooi, B. DSH: Data Sensitive Hashing for high-dimensional k-NN search. In Proceedings of the SIGMOD, Snowbird, UT, USA, 22–27 June 2014. [Google Scholar]
- Wang, Y.; Shrivastava, A.; Ryu, J. Randomized Algorithms Accelerated over CPU-GPU for Ultra-High Dimensional Similarity Search. In Proceedings of the SIGMOD, Houston, TX, USA, 10–15 June 2018. [Google Scholar]
- Ahle, T.D.; Pagh, R.; Razenshteyn, I.; Silvestri, F. On the complexity of inner product similarity join. In Proceedings of the 35th ACM SIGMOD-SIGACT-SIGAI Symposium on Principles of Database Systems, San Francisco, CA, USA, 26 June–1 July 2016; pp. 151–164. [Google Scholar]
- Neyshabur, B.; Srebro, N. On Symmetric and Asymmetric LSHs for Inner Product Search. In Proceedings of the International Conference on Machine Learning, Lille, France, 6 July–11 July 2015; pp. 1926–1934. [Google Scholar]
- Shrivastava, A.; Li, P. Asymmetric LSH (ALSH) for sublinear time maximum inner product search (MIPS). In Proceedings of the Advances in Neural Information Processing Systems, Montreal, QC, Canafa, 8–13 December 2014; pp. 2321–2329. [Google Scholar]
- Ting, D. Streamed Approximate Counting of Distinct Elements: Beating Optimal Batch Methods. In Proceedings of the SIGKDD, New York, NY, USA, 24–27 August 2014; pp. 442–451. [Google Scholar]
- Bachrach, Y.; Finkelstein, Y.; Gilad-Bachrach, R.; Katzir, L.; Koenigstein, N.; Nice, N.; Paquet, U. Speeding up the xbox recommender system using a euclidean transformation for inner-product spaces. In Proceedings of the 8th ACM Conference on Recommender Systems, Silicon Valley, CA, USA, 6 October 2014; pp. 257–264. [Google Scholar]
- Ballard, G.; Kolda, T.G.; Pinar, A.; Seshadhri, C. Diamond sampling for approximate maximum all-pairs dot-product (MAD) search. In Proceedings of the ICDM, Atlantic City, NJ, USA, 14–17 November 2015; pp. 11–20. [Google Scholar]
- Flajolet, P.; Martin, G.N. Probabilistic counting algorithms for data base applications. J. Comput. Syst. Sci. 1985, 31, 182–209. [Google Scholar] [CrossRef] [Scilit]
- Xiao, Q.; Zhou, Y.; Chen, S. Better with fewer bits: Improving the performance of cardinality estimation of large data streams. In Proceedings of the INFOCOM, Atlanta, GA, USA, 1–4 May 2017; pp. 1–9. [Google Scholar]
- Cohen, E.; Kaplan, H. Summarizing Data Using Bottom-k Sketches. In Proceedings of the PODC, Portland, OR, USA, 12–15 August 2007; pp. 225–234. [Google Scholar]
- Lumbroso, J. An optimal cardinality estimation algorithm based on order statistics and its full analysis. In Proceedings of the AofA, Vienna, Austria, 28 June–2 July 2010; pp. 489–504. [Google Scholar]
- Chen, W.; Liu, Y.; Guan, Y. Cardinality change-based early detection of large-scale cyber-attacks. In Proceedings of the INFOCOM, Turin, Italy, 14–19 April 2013; IEEE: Piscataway, NJ, USA, 2013; pp. 1788–1796. [Google Scholar]
- Flajolet, P. On Adaptive Sampling. Computing 1990, 43, 391–400. [Google Scholar] [CrossRef] [Scilit]
- Gibbons, P.B. Distinct Sampling for Highly-Accurate Answers to Distinct Values Queries and Event Reports. In Proceedings of the PVLDB, Roma, Italy, 11–14 September 2001; pp. 541–550. [Google Scholar]
- Mao, Y.; Gan, D.; Mwakapesa, D.S.; Nanehkaran, Y.A.; Tao, T.; Huang, X. A MapReduce-based K-means clustering algorithm. J. Supercomput. 2022, 78, 5181–5202. [Google Scholar] [CrossRef] [Scilit]
- Corizzo, R.; Pio, G.; Ceci, M.; Malerba, D. DENCAST: Distributed density-based clustering for multi-target regression. J. Big Data 2019, 6, 1–27. [Google Scholar] [CrossRef] [Scilit]
- Corizzo, R.; Dauphin, Y.; Bellinger, C.; Zdravevski, E.; Japkowicz, N. Explainable image analysis for decision support in medical healthcare. In Proceedings of the 2021 IEEE International Conference on Big Data (Big Data), Orlando, FL, USA, 15–18 December 2021; IEEE: Piscataway, NJ, USA, 2021; pp. 4667–4674. [Google Scholar]
- Cao, M.; Jia, W.; Lv, Z.; Zheng, L.; Liu, X. Superpixel-Based Feature Tracking for Structure from Motion. Appl. Sci. 2019, 9, 2961. [Google Scholar] [CrossRef] [Scilit]
- Ding, K.; Yang, Z.; Wang, Y.; Liu, Y. An improved perceptual hash algorithm based on u-net for the authentication of high-resolution remote sensing image. Appl. Sci. 2019, 9, 2972. [Google Scholar] [CrossRef] [Scilit]
- Jacquet, P.; Szpankowski, W. Analytical Depoissonization and its Applications. Theor. Comput. Sci. 1998, 201, 1–62. [Google Scholar] [CrossRef] [Scilit]
- Mitzenmacher, M.; Upfal, E. Probability and Computing—Randomized Algorithms and Probabilistic Analysis; Cambridge University Press: Cambridge, UK, 2005. [Google Scholar]
- Bickel, P.J.; Doksum, K.A. Mathematical Statistics: Basic Ideas and Selected Topics, 2nd ed.; Prentice-Hall: Hoboken, NJ, USA, 2001; Volume 1. [Google Scholar]
- Ypma, T.J. Historical Development of the Newton-Raphson Method. SIAM Rev. 1995, 37, 531–551. [Google Scholar] [CrossRef] [Scilit]
- Mislove, A.; Marcon, M.; Gummadi, K.P.; Druschel, P.; Bhattacharjee, B. Measurement and analysis of online social networks. In Proceedings of the SIGCOMM, Kyoto, Japan, 27–31 August 2007; pp. 29–42. [Google Scholar]
- GroupLens Research. MovieLens Data Sets. 2006. Available online: http://www.grouplens.org/node/73 (accessed on 1 March 2022).
- Wikimedia Foundation. Wikimedia Downloads. 2010. Available online: http://dumps.wikimedia.org/ (accessed on 13 June 2021).
- Lewis, D.D.; Yang, Y.; Rose, T.G.; Li, F. RCV1: A New Benchmark Collection for Text Categorization Research. J. Mach. Learn. Res. 2004, 5, 361–397. [Google Scholar]
- Kunegis, J. KONECT: The Koblenz Network Collection. In Proceedings of the 22nd International Conference on World Wide Web, Rio de Janeiro, Brazil, 13–17 May 2013; pp. 1343–1350. [Google Scholar]
- National Institute of Standards and Technology. Text REtrieval Conference (TREC) English Documents. 2010; Volume 4–5. Available online: http://trec.nist.gov/data/docs_eng.html (accessed on 11 June 2021).
Publisher’s Note: MDPI stays neutral with regard to jurisdictional claims in published maps and institutional affiliations. |
© 2022 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).