


Abstract
Poorly governed geoscience databases introduce subtle but systematic biases that propagate through mineral resource estimation workflows, distorting grade continuity and resource classification. While the importance of data quality in mining is widely acknowledged, quantitative demonstrations of how specific data management decisions translate into downstream technical and economic impacts remain limited. This study addresses that gap through three case studies derived from real-world industry examples. The first case study quantifies operator-dependent data extraction bias by comparing two independently generated datasets sourced from the same database on the same day. Despite nominal equivalence, the datasets differed materially in record counts and grade distributions, producing only negligible global volumetric differences (~0.1%) but up to ~5% local geometric variability and a 19.5% difference in estimated copper grade, resulting in a ~36% divergence in projected revenue. The second case study evaluates analytical uncertainty near detection limits using duplicate assay pairs, demonstrating that relative error increases markedly at low concentrations and that this behavior reflects inherent analytical limitations rather than laboratory non-compliance. The third case study examines the common practice of assigning detection limit placeholder values to unassayed intervals, showing that such substitutions can artificially generate ore in barren domains, whereas retaining null values and applying assignments during post-processing yields geologically and statistically coherent results. Collectively, these case studies demonstrate that hidden data biases can exert a stronger influence on resource outcomes than estimation methodology alone. The results highlight the need for standardized extraction workflows, explicit treatment of low-grade uncertainty, and validation practices that extend beyond global reconciliation metrics. Robust data governance and transparent, reproducible workflows are essential to reducing compounding uncertainty and improving confidence in mineral resource models. All datasets have been anonymized, scaled, or modified to prevent identification of any specific project, company, or operation. No confidential or proprietary datasets are disclosed.
1. Introduction
Effective data management has never been as critical as it is in modern mining operations. Data underpins the entire mining value chain from exploration to closure, and vulnerabilities in its quality or integrity can compromise this entire system. For industries that rely heavily on data, such as mining, treating data as a core asset is essential. Not only is it important, but with the increasing scale of mining operations and the growing complexity of geology within ore deposits, more data is generated and required every day. Billion-dollar decisions depend on such databases, and even subtle biases or inconsistencies within the data can propagate through modeling workflows, forecasts, and strategies. These effects extend beyond technical metrics and can ultimately will determine project viability and profitability. Furthermore, the implications are not confined to statistical analysis. Beyond technical impacts, flawed data introduces uncertainty [1] with broader consequences noted in the literature, including operational risk and occupational health [2]. Therefore, standard protocol and software are necessary to effectively manage such an important component of the mining operation [3]. Despite its critical role, data is often collected under inconsistent protocols, stored with minimal governance, and manipulated by assumptions rather than standards. The cumulative effect is the emergence of undetected errors that undermine confidence, increase risk, and influence outcomes across all stages of the mining process.
These undetected errors are rarely abstract. In practice, mineral resource databases accumulate a range of concrete and frequently legacy-driven inconsistencies that are easily overlooked. These include collar georeferencing errors and drilling campaigns surveyed in different coordinate systems; assays generated under different analytical methods and detection limits; mixed samples or composite lengths; logging criteria that vary over time or between geologists; the assignment of placeholder grades to barren intervals; and differences in extraction procedures between operators. Many of these issues are inherited from the historical evolution of an operation and persist quietly through successive model updates. Critically, a large portion of them escape conventional QA/QC procedures. Such procedures are typically designed to detect overlapping intervals, missing assays, or invalid values; they are not designed to detect the more subtle systematic biases introduced by how data are logged, coded, extracted, and interpreted.
The significance of these inconsistencies lies in where they ultimately surface. In mining, mineral resource estimation is a cornerstone of project evaluation and overall feasibility, and it is here that upstream database defects exact their greatest cost. A robust and well-constructed resource model depends on strong data integrity. Poorly governed databases can distort geological interpretations and lead to flawed conclusions, ultimately impacting project economics and decision making.
Effective database management requires a combination of automated quality control checks and validation by a qualified person to ensure data integrity before integration into the resource model. These validations typically include basic quality controls, such as ensuring there are no overlapping intervals, missing assays or geological data, excessive drillhole deviation, collar positions outside topography, or invalid assay values (e.g., zero or negative).
In large or complex operations, additional errors often arise when governance controls, extraction logic, and unit consistency are not clearly defined or enforced. This situation underscores the need for rigorous data management practices to safeguard the reliability and reproducibility of resource estimates.
Ultimately, resource estimation is potentially less influenced by the choice of estimation methods than by systematic, poorly documented database issues that introduce bias, instability, and irreproducibility. These problems are common, frequently legacy-driven, and often remain undetected until the reporting stage. Ref. [4] proposes a reflective exercise, encouraging practitioners to evaluate their database quality by answering five key questions:
- How much data do you have?
- What is the cost of replacing each data point?
- What is the collective value of the data?
- How much data remains unused?
- How much data is unfit for use?
This simple exercise provides a framework for assessing data quality and determining the cost implications of poor data integrity. It also helps to target improvement initiatives and efficient allocation of resources.
In addition to these retrospective questions, a few forward-looking considerations can further strengthen long-term data governance:
- In what ways can current data collection practices influence information interpretation, relevance, and utility in 5, 10 and 20 years?
- To what extent might future practitioners identify gaps in data that is or is not collected, stored, and verified today?
- What is the scope and effectiveness of the current data acquisition process and its oversight?
These forward-looking questions, taken together, reframe data quality assurance as a proactive responsibility rather than a retrospective exercise: decisions today made about storage, validation, and sampling determine whether data remains comparable, interpretable, and useable as economic and technical contexts evolve.
This standpoint aligns with [1], who discusses how the perception of data management must inevitably change within the mining industry. With the advances made in technology, companies are collecting and have the potential to collect even more data in real time. Fast and reliable data analysis will be pivotal and can potentially change the whole operation landscape.
Rather than reiterating general principles of data quality, this study provides quantitative, end-to-end evidence of how specific, routinely applied data management decisions alter geological models, estimation behavior, and economic outcomes. From the broad class of hidden database biases outlined above, three were selected as representative and commonly encountered: operator-dependent data extraction from a shared source database, analytical behaviour near detection limits, and the treatment of unassayed intervals. Using three industry-based case studies, the paper isolates each mechanism and demonstrates how it propagates through the workflow to influence the reliability of model outputs. The results show that seemingly minor upstream database choices can locally produce significant geometric changes, order-of-magnitude differences in grade uncertainty, and economically material divergences in resource outcomes, even when global reconciliation metrics appear stable.
2. Materials and Methods
This study adopts a case study-based approach to examine how different sources of hidden bias arise and propagate within mineral resource databases and downstream modelling workflows. A case-study framework was selected because it allows end-to-end evaluation of operational decisions, capturing interactions between data management, geological interpretation, geostatistical analysis, and economic outcomes that are difficult to isolate in synthetic examples. The three case studies were intentionally selected to represent distinct, commonly encountered bias mechanisms: (1) operator-dependent data extraction from a shared source database, (2) analytical uncertainty associated with assays near detection limits, and (3) the treatment of unassayed or geologically barren intervals through assigned placeholder values versus null handling. Together, these cases span database construction, analytical measurement, and estimation workflow decisions. Across the studies, standard industry tools and methods are applied consistently to reflect realistic practice. Geological interpretations are developed using Leapfrog Geo® software version 2023.3 (Seequent Ltd., Christchurch, New Zealand). Statistical and distributional analyses included descriptive statistics, histograms, cumulative probability plots, and Bland–Altman analysis for paired assay comparisons. Resource estimation sensitivity was evaluated using inverse distance cubed (ID3) interpolation and, where appropriate, ordinary kriging to assess the geostatistical implications of dataset differences.
2.1. Case Study 1
This case study examines what happens when the same corporate database is extracted twice, under the same criteria stated by two different teams. The two extractions returned materially different datasets, and those differences carry through into the geologic interpretation and resource estimate. The intent is not to decide which extraction is “correct”; both are shaped by different default assumptions, filters or post-processing. The comparison isolates the effect of operator-dependent extraction bias on the downstream outputs, with the deposit, company, and extraction criteria all held constant. Framed this way, the comparison gives a sense of reproducibility risk that shows up when standardized extraction profiles exist but are not consistently applied.
Consider a database for a skarn deposit. In the early stages of the resource reporting process, the assay database is validated by the geologist, which is the primary input for estimating tonnage, grade, and contained metal in the resource model. These outputs form the basis for investment decisions, mine planning, and life-of-mine assessments. Because these decisions depend directly on the data analysis results, maintaining rigorous data integrity is critical.
To exemplify, consider a common issue observed across industry databases. Independent data extractions provided to the resource team can differ depending on the methods and assumptions applied. Initial review often shows that different extraction approaches result in significantly distinct versions of the same database, as shown in Table 1.
Table 1.
Global drillhole summary comparison between main metrics of Dataset 1 and 2.
In this case, extractions were requested with the same criteria from two teams working on the same deposit with the expectation that they would return comparable datasets. In principle, standardized extraction profiles exist to enforce this consistency by fixing the fields, filters and rules applied. In practice, however, the use of these profiles is not guaranteed. An extraction may apply different default assumptions or omit steps defined in the profile, or post-processing procedures can occur. As a result, the same request can still yield materially different versions of the database, as shown in Table 1. This highlights that reproducibility depends not only on the existence of extraction profiles but on their consistent application.
From Table 1, the discrepancies between the datasets are clear. Dataset 1 contains 8% more drillholes than Dataset 2. The number of 10 ft composites varies widely. Most concerning, however, is the variation in average copper grade, in which Dataset 1 presents a 9% lower average grade than Dataset 2. While the data pertains to the same deposit and same company, without standardized extraction procedures and thorough database vetting, downstream users are likely to model entirely different interpretations of the same deposit.
Moreover, the database also presents differences in sample grade values. The single interval example presented in Table 2 is the same drillhole ID, the same interval, and has a different sample type, priority and grade. The data obtained also presents mismatches on the lithology log interpretation column. While Dataset 1 has all intervals with assigned lithology, Dataset 2 has null values. This is another factor that can impact the understanding of the subsurface. Table 3 presents the differences in the different lithology extracted with the same drill hole ID. This may be due to priorities defined during the extraction process, leading to different outputs from the database.
Table 2.
Single sample differences detected between Dataset 1 and 2 related to copper grade, sample type and priority.
Table 3.
Comparison between Dataset 1 and 2 of extracted LITH column data.
Although both data extractions were performed with the same stated objective, from the same underlying database, the results reveal a clear operator-dependent extraction bias. Despite identical intent, differences in how extraction rules were interpreted and implemented result in non-equivalent datasets. The observed discrepancies are therefore systematic rather than random and cannot be attributed to geological interpretation, sampling density, or estimation methodology.
2.1.1. Geologic Model Differences Arising from Operator-Dependent Extraction Bias
Table 3 demonstrates significant discrepancies between Lith Dataset 1 and Lith Dataset 2. This mismatch is unexpected, particularly because the drillholes in question are older, and therefore their geological information should already exist in the database, the extraction dates were the same for both datasets. The failure to correctly extract lithological data has substantial implications for downstream geological and resource-modelling workflows. In Seequent’s Leapfrog® software, lithological intervals form the basis for automatically generated geological models; any errors in the lithology column, or in derived interpreted fields, directly propagate into the modelling process. Automated geological modeling is not intended to replace geological interpretation. In a mineral resource context, the geological model is reviewed and validated by a geologist before it informs estimation, and a human check remains best practice. However, the same is not always true of operational and production models, which are regenerated frequently to keep pace with new drilling and grade control. In these workflows, the modeling code, wireframe triggers, and column settings are held fixed so that outputs are consistent and repeatable and only the input data change between runs. It is precisely this design that allows a data extraction error to pass unnoticed. The workflow, parameters and resulting solids appear unchanged and, as the volumetric reconciliation below demonstrates, the district-scale geometry reconciles within ~0.1%. Consequently, the model would likely pass routine visual and volumetric review. The discrepancy does not present as a geometric or modeling error; it presents as a change in the underlying data classification, which a standard geologic review of the solids is not designed to detect.
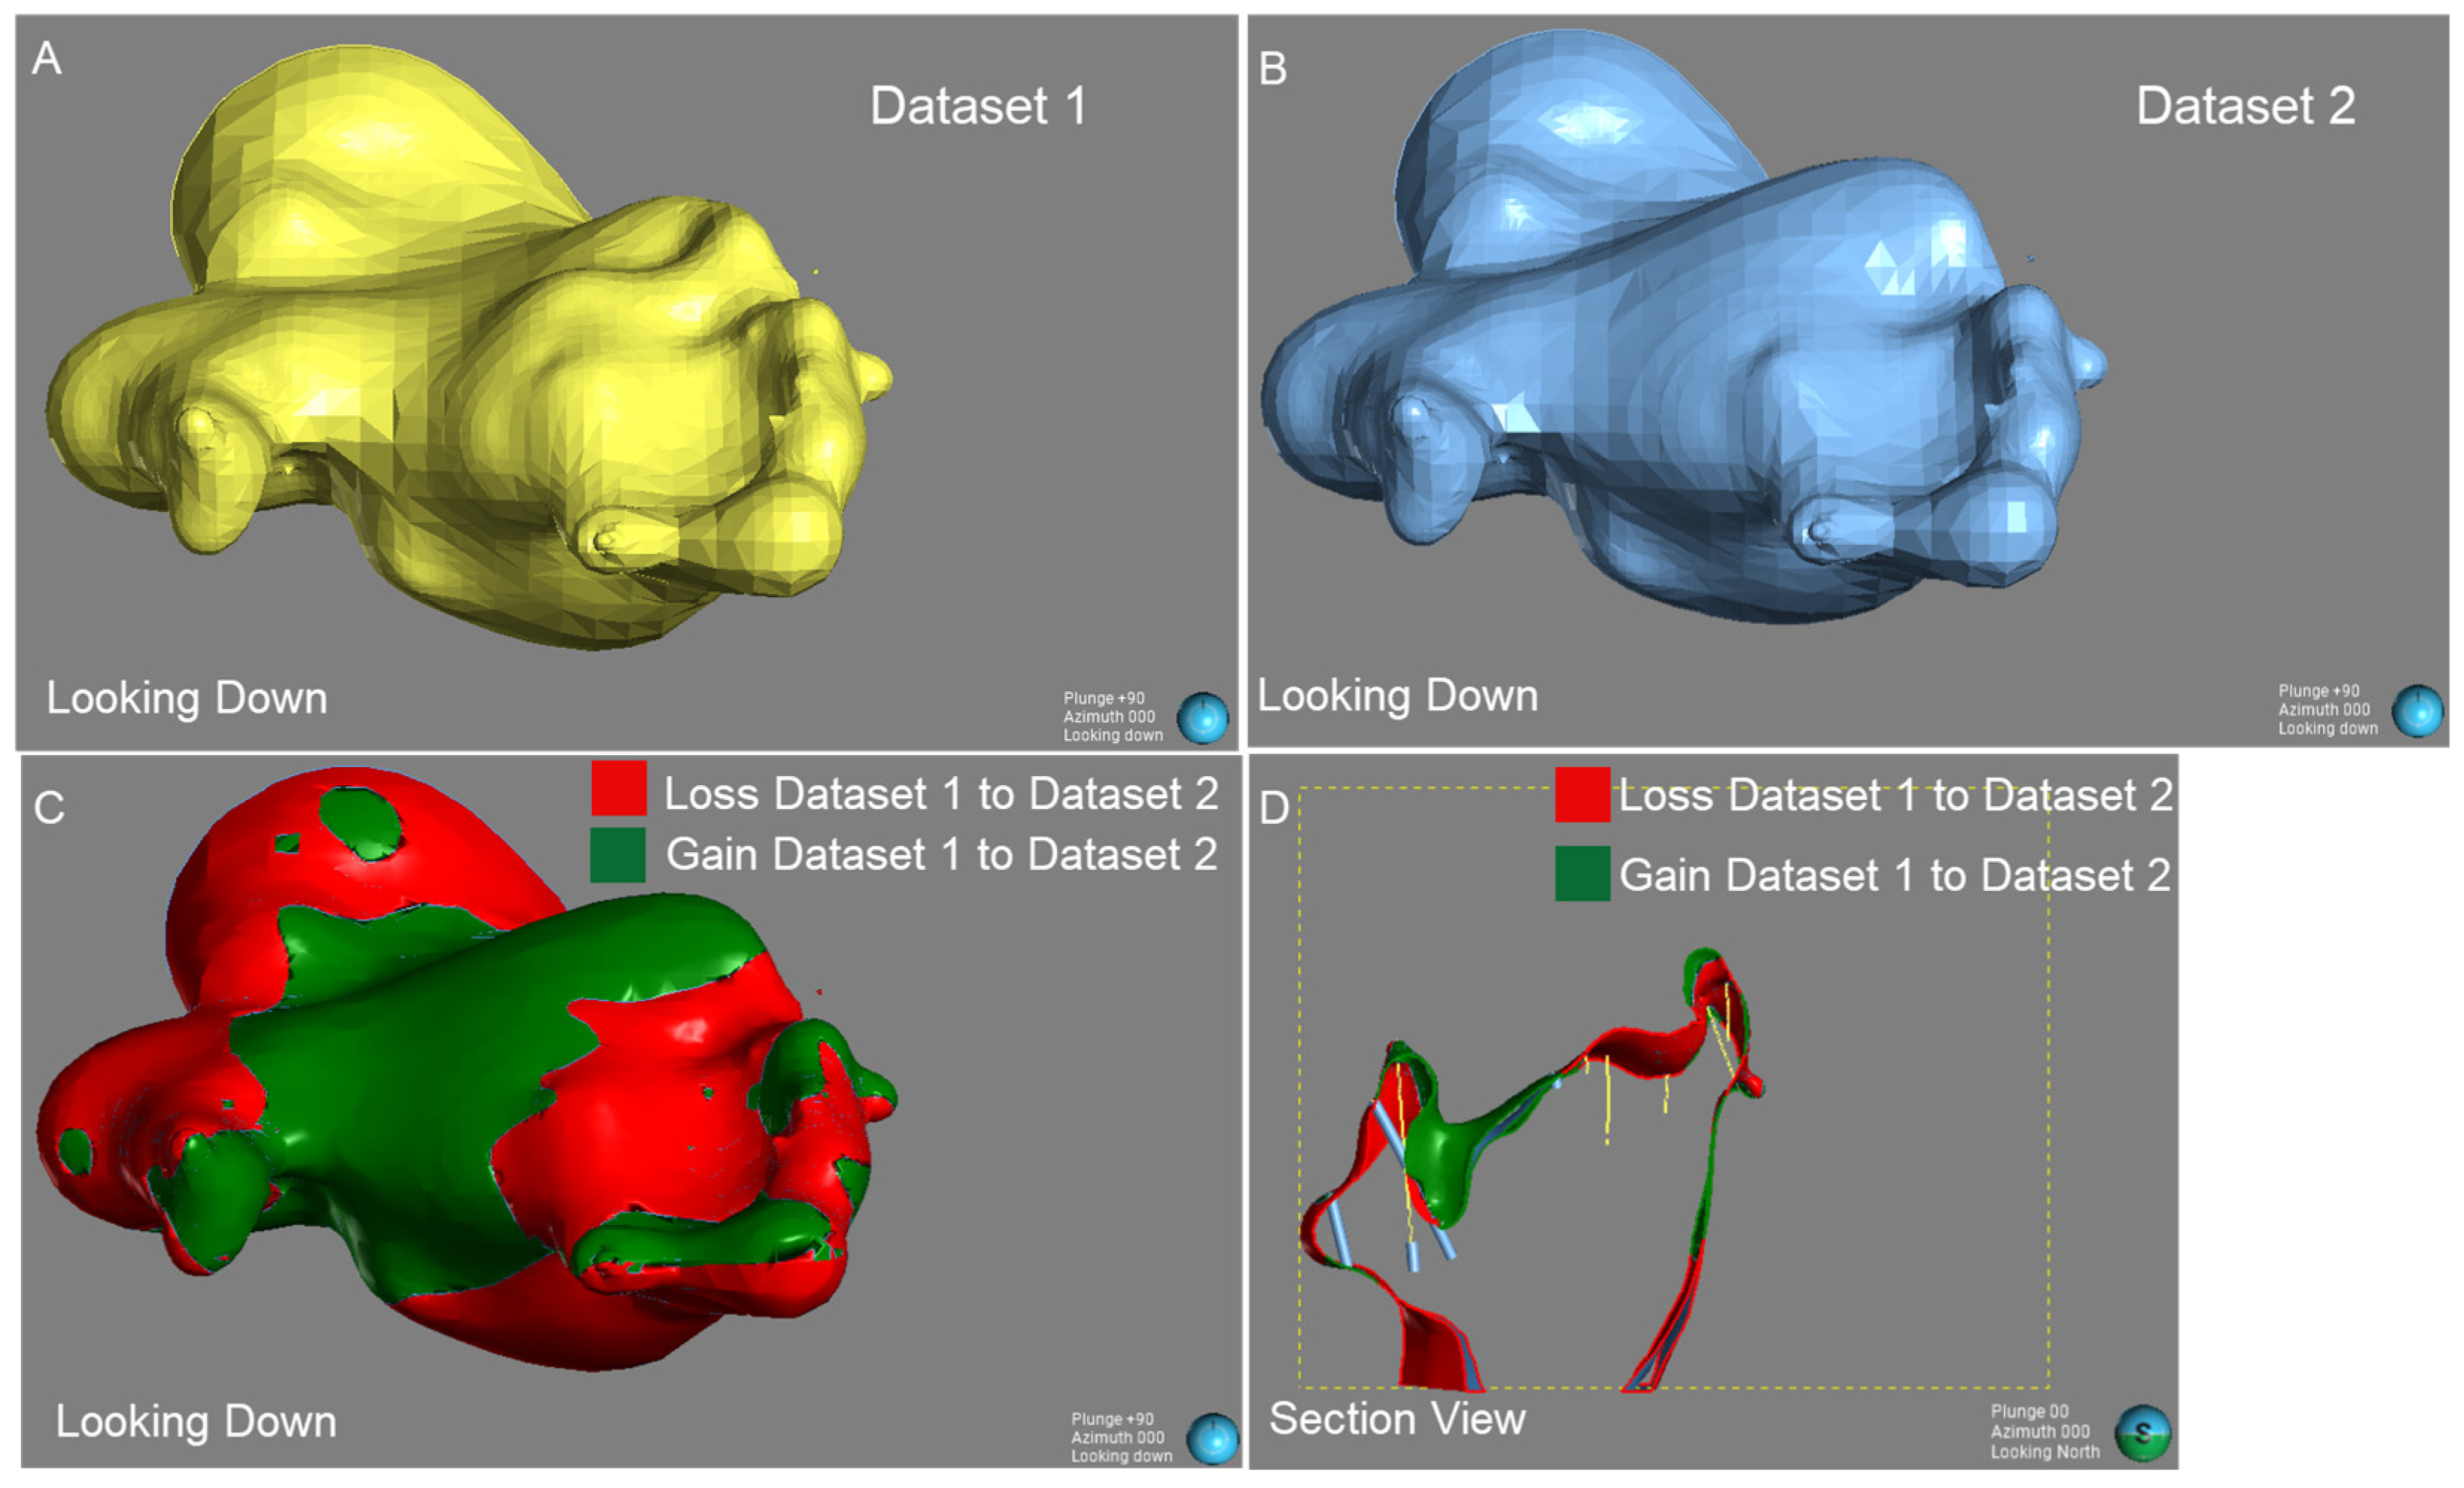
Leapfrog models were constructed using identical workflows (i.e., the same modeling code and column settings). Geologic interpretations for Datasets 1 and 2 were generated with the Geologic Model function and explicitly incorporate the intrusion depicted in Figure 1.
Figure 1.
Comparison of geological solids generated using identical Leapfrog modelling workflows. (A) Geological solid generated from Dataset 1. (B) Geological solid generated from Dataset 2. (C) Volumetric difference between the two solids, where green represents material present in the Dataset 2 solid but absent from the Dataset 1 solid, and red represents material present in the Dataset 1 solid but absent from the Dataset 2 solid. (D) Section view illustrating local geometric discrepancies between the two models despite a negligible net volumetric difference (~0.1%).
2.1.2. Results Case Study 1
At the district/structural scale, the resulting geometries are broadly concordant; however, systematic discrepancies emerge at the local scale. Volumetric reconciliation seen in Table 4 indicates a 5.4% gain and a 5.3% loss when comparing the two surfaces, yielding a negligible net volumetric change of ~0.1%, which reflects minor differences in Leapfrog interpolation responding to slightly different lithologic inputs rather than any genuine change in geologic interpretation.
Table 4.
Volume comparison of geologic unit created by Dataset 1 and Dataset 2.
The near-zero net volume change suggests that global inventory is stable; however, the paired 5.4%/5.3% bidirectional differences seen in Table 5 reflect minor local variability. These localized gains and losses are consistent with normal interpolation behaviour at lithologic contacts (particularly along the intrusion–host rock boundary), scale-dependent smoothing, and sensitivity to sparse or clustered data sample support in structurally complex zones [5] and are not attributable to the extraction discrepancy itself. Notably, the mismatched lithological intervals are concentrated in the interior of the modelled unit rather than along its margins. Because the wireframe surface is controlled by boundary intervals, these interior errors do not shift the geometry, which explains both the negligible ~0.1% net volume change and the absence of any visible modeling anomaly. Their effect is not geometric but statistical; they alter the sample population contained within the domain.
Table 5.
Gains and losses from the Dataset 1 geologic model to the Dataset 2 model.
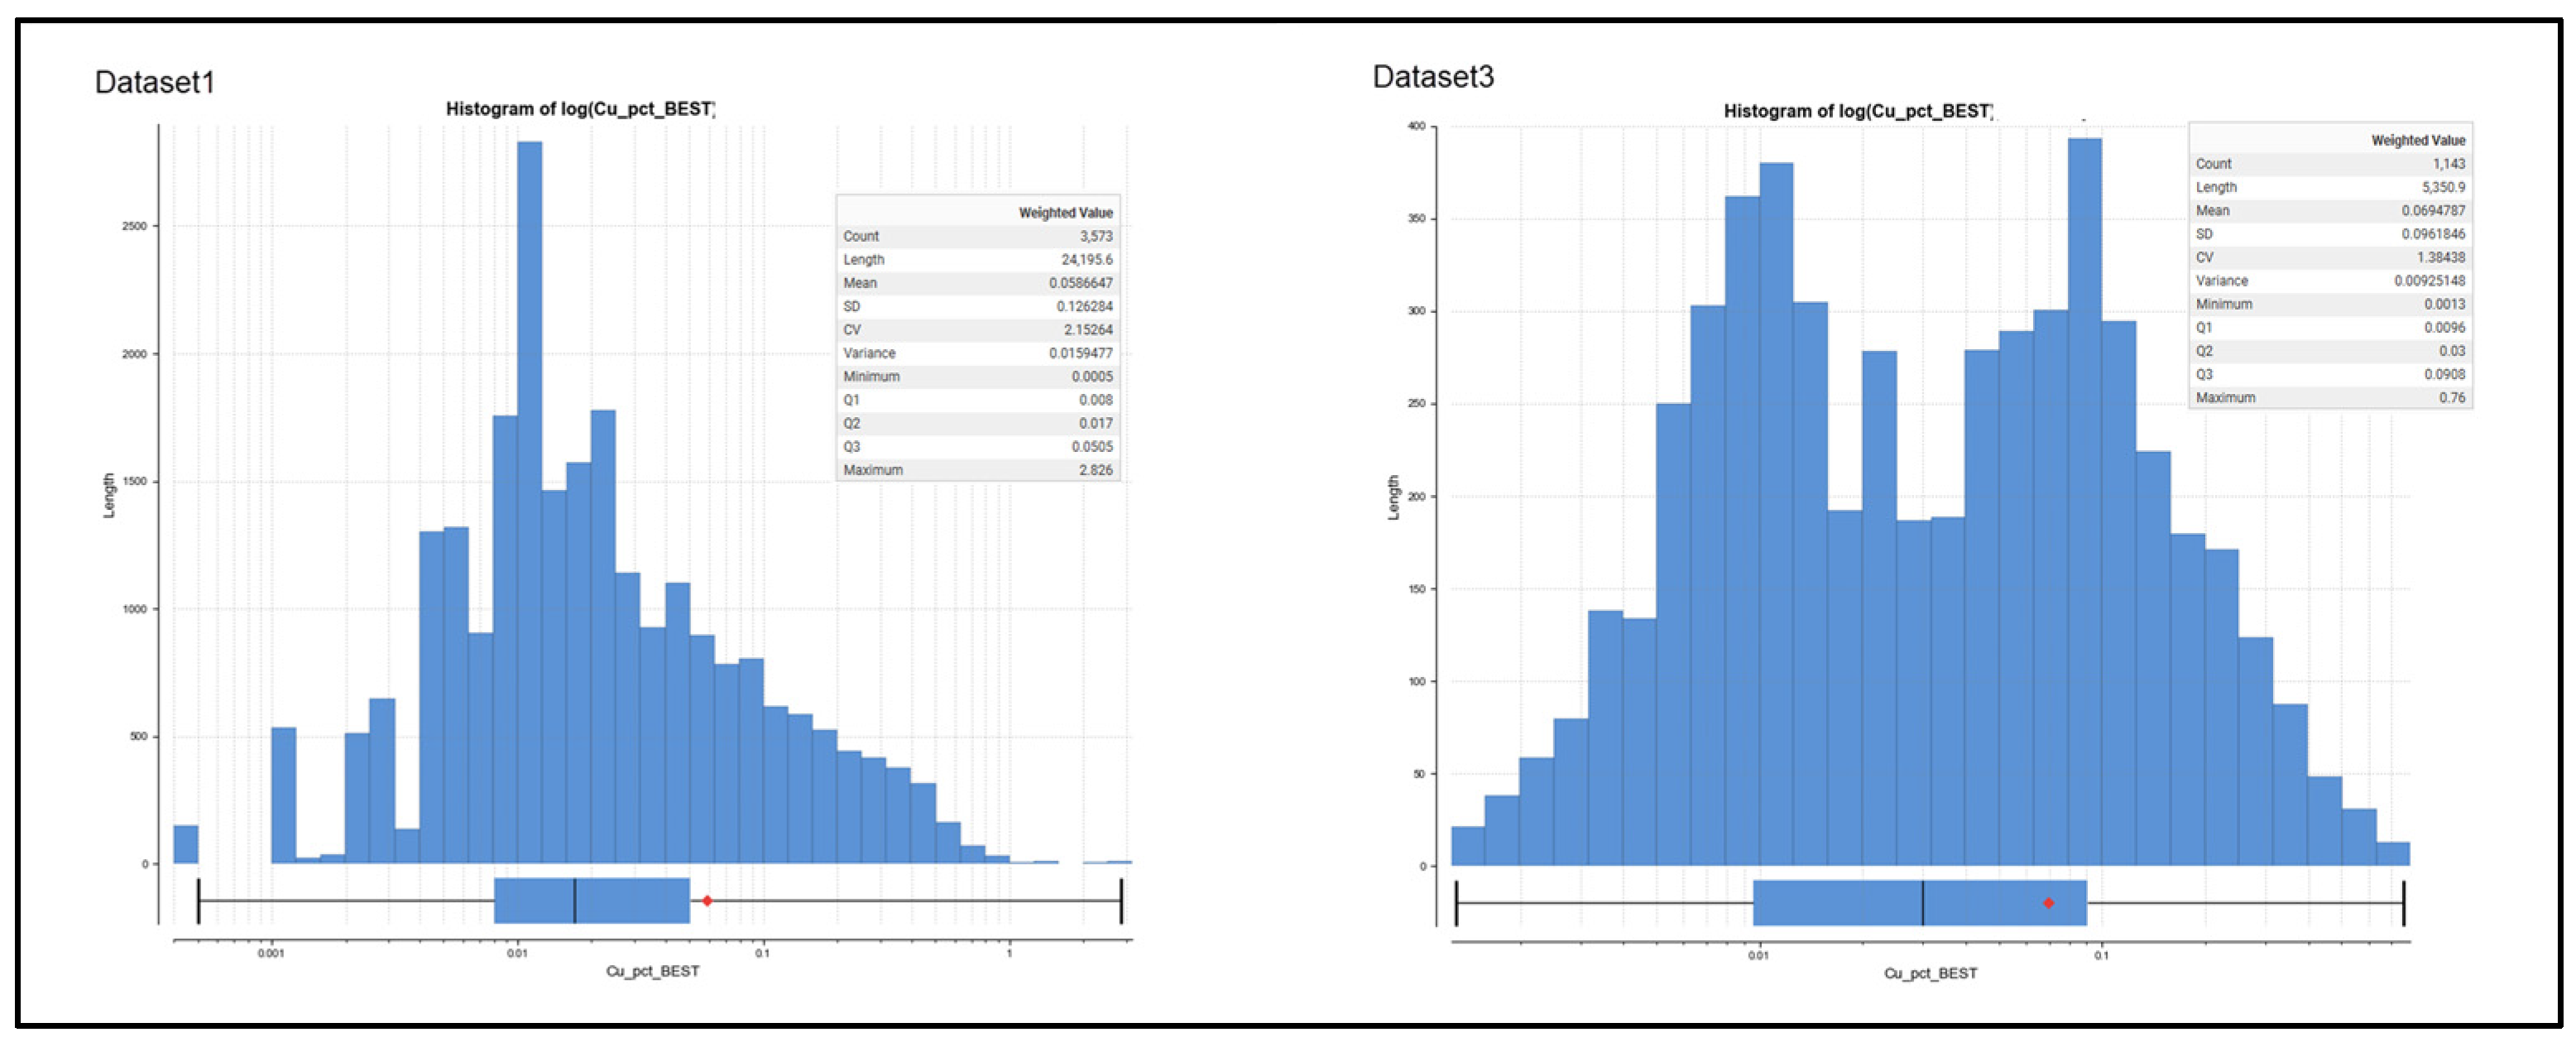
The significant impact lies not in the geometry of the solids but in the classification of the data used to build and populate them. Although the wireframes are nearly identical, the lithologic flags assigned to drillhole intervals differ substantially between the two datasets. This changes which samples are assigned to each domain and therefore the sample populations available for estimation. The resulting statistical summaries and histogram analyses of the raw assays in the modelled geologic units from Dataset 1 and Dataset 2 are examined (Figure 2 and Table 6).
Figure 2.
Histograms of log-transformed Cu (%) statistics of each dataset within their respective geologic models.
Table 6.
Comparison statistics of raw Cu (%) grade within the interpreted geologic models.
Despite the nearlyconstant total modelled volume, the statistical comparison reveals substantial divergence in the underlying sample populations. The number of assays assigned to the modelled unit decreases by 68% from Dataset 1 to Dataset 2, while the mean grade increases by 18%, and the coefficient of variation (CV) decreases by 36%. These pronounced differences indicate that the two datasets do not represent equivalent populations, highlighting inconsistency in extraction and underscoring the practical consequences of applying unclear or non-standardized rules.
The divergence is further reflected in the distributional form. Dataset 1 exhibits a pronounced right-skewed distribution with a CV exceeding 2, indicating a highly variable distribution and potential violation of the stationarity assumption required for ordinary kriging, and therefore its use is compromised. This can lead to increased smoothing of estimated and reduced local accuracy [6,7]. Dataset 2 displays a multimodal distribution in Cu, suggesting that the domain may be aggregating multiple geological populations, warranting further discussion with the geologist regarding the need for re-domaining or sub-domaining to restore stationarity.
In contrast, Dataset 1 displays a right-skewed but unimodal distribution with a comparatively lower CV. Its single-population form and lower variability make it more amenable to ordinary kriging, in the sense that a stationary domain mean and an interpretable variogram can be more readily supported, provided appropriate variogram modelling and top-cut strategies are applied. Relative to Dataset 2, Dataset 1 is more consistent with the stationarity assumptions underlying conventional geostatistical estimation, though the ultimate suitability of the estimate depends on the modelling objective and should be confirmed through cross-validation and other performance checks [8].
The observed changes in CV and tail behavior imply materially different stationarity and variogram characteristics [8], which directly influence kriging performance, local selectivity, and grade smoothing.
Consequently, even though the global volumetric balance is stable, the distributional shifts are material at the local scale, particularly at the stope or drift level. These results demonstrate that volumetric reconciliation alone is insufficient for model validation and that statistical and distributional diagnostics are essential for assessing the geological and geostatistical validity of alternative interpretations.
2.1.3. Estimation Differences
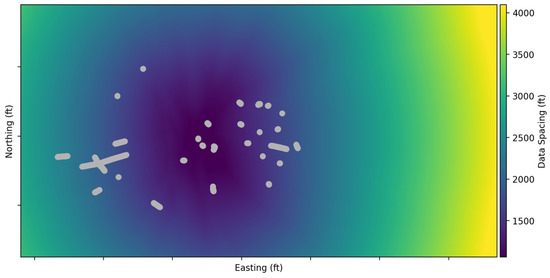
To further assess the potential downstream impact of uncertainty associated with the extraction methodology, an inverse distance cubed (ID3) estimate was completed as a comparative exercise. This estimation is intended to solely illustrate the relative differences between the two datasets and is not suitable for economic evaluation or resource-level reporting. Variogram analysis was attempted; however, a stable and interpretable variogram model could not be developed. As a result, an omnidirectional experimental variogram was generated and used solely to inform the selection of an appropriate search distance. It is acknowledged that post-processing techniques could be applied to mitigate some of the smoothing and support-related effects inherent to this estimate; however, such refinements fall outside the scope of the present comparison. On this basis, the ID3 estimation employed a large isotropic search radius of 1300 ft consistent with the average drillhole spacing of ~2300 ft within the domain (Figure 3). This resulted in a minimum and maximum of 4 and 18 informing samples, respectively, and a restriction of no more than 3 samples per drillhole.
Figure 3.
Average data spacing in the estimation domain of Dataset 1 in 2D in the plan section. Gray markers indicate drillhole/sample locations used in the data spacing calculation.
Both datasets were evaluated above a cutoff grade of 0% Cu to retain all estimated material and enable a direct comparison rather than to define potentially economic material. A generic bulk density, provided by the site team, was applied consistently to both datasets to ensure comparable and reasonably accurate tonnage estimates. The estimation results are summarized in Table 7.
Table 7.
Estimation results using Dataset 1 vs. Dataset 2.
A clarification of the reported grades is warranted, as the values in Table 6 and Table 7 are stated at a different support and scale than those presented earlier. They are not directly comparable to the whole-database composite averages in Table 1, nor to the single-interval values in Table 2, with the latter being individual sample records used only to illustrate the extraction mismatch and not to represent dataset averages. Table 6 and Table 7 refer to a single, comparatively low-grade modelled unit rather than the deposit as a whole. The further reduction from the raw domain mean (~0.06% Cu) to the estimated mean (~0.03% Cu) is a function of the estimation itself and not the extraction. It reflects block support and volume variance smoothing, declustering of spatially clustered high-grade samples into a regular grid, and the retention of all blocks above a 0% Cu cutoff, which carries a large low-grade waste volume that dilutes the mean. These are support- and methodology-related effects independent of the database extraction process.
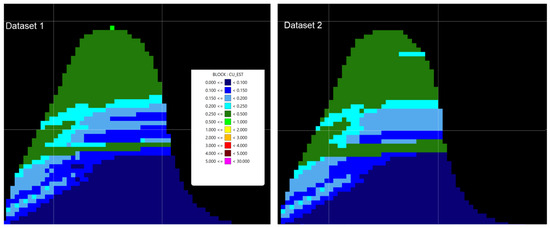
The comparison highlights meaningful differences between the two datasets. Dataset 2 reports a 19.5% higher copper grade relative to Dataset 1, while total tonnage is 12.0% lower. Despite the reduction in tonnage, the higher grade in Dataset 2 results in an overall 5.1% increase in contained copper metal. These results illustrate that grade variability exerts a stronger influence on contained metal than tonnage alone and underscores the sensitivity of resource outcomes to input data selection. Also, it is important to highlight that density variability potentially amplifies this result.
Visual differences between the two estimates, including the spatial distribution of grade, are illustrated in Figure 4.
Figure 4.
Differences in estimate between Dataset 1 and Dataset 2.
2.2. Case Study 2
The objective of this case study is not to assess whether the laboratory performed adequately; the analysis that follows demonstrates that it did. Rather, the aim is to illustrate a subtler, structurally embedded bias in which historical low-grade gold data were generated, sampled, and subjected to QA/QC under an economic regime where such grades were treated as waste yet are now relied upon to support decisions that the original protocols were never designed to inform. The relevant question is therefore not whether the data are biased but whether data considered fit for purpose under one set of economic conditions remain fit for purpose when those conditions change. The precision analysis presented below deliberately establishes that the assays themselves are sound, so that the residual uncertainty can be correctly attributed to the interaction between the detection limit regime and modern low-grade cutoffs, rather than analytical failure.
2.2.1. Historical Context
For many years, persistently low metal prices meant that grades near analytical detection limits were of little economic relevance within many operations and projects. Assays near the detection limit were rarely used in key technical or economic decisions and were often treated as dilution, effectively classified as “waste”. In many cases, these low-grade values were commonly ignored, censored, or not sampled at all. Where material was logged as “waste”, samples were not submitted for analysis to conserve time, budget, and other resources.
Within the economic context of the time, these practices were considered reasonable. The implicit assumption was that analytical performance at very low concentrations was inconsequential, since such grades were not anticipated to contribute meaningfully to mine planning, reconciliation, or value determination.
2.2.2. Shift in Economic Relevance
As commodity prices increased, many mines and projects began operating and conducting technical studies within grade ranges that were never intended for detailed evaluation. Material once dismissed as “background noise” has become potential ore under today’s economic assumptions. Data fit for waste classification decisions is being reused for ore/waste selection decisions.
This shift exposed a previously hidden bias in the resource database. Analytical precision at low concentrations was far poorer than assumed by the company or operational side, and historical low-grade values no longer supported the accuracy required for modern mine planning and reconciliation. While laboratories have long documented that analytical precision degrades as concentrations approach the detection limits, which is an expected and well-understood phenomenon, the bias arose because these low-grade ranges were historically irrelevant. As a result, laboratory performance near detection limits was rarely scrutinized, particularly in production sampling.
Consequently, internal mental models, workflows and databases inherited decades of low-grade data that had effectively been neglected yet was later expected to support materially different decisions.
2.2.3. Commodity-Driven Misalignment
An example of where this situation could occur is where copper was the main contributor to project economics, with gold a secondary by-product. Consequently, the testing programs, technical studies, and underlying assumptions were designed primarily around copper. As the commodity price increased for gold, the cutoff for gold grade dropped to now include the old and new detection limit assays with the rest of the ore.
Best-practice sampling theory generally recommends that sampling protocols, sample preparation procedures, and QA/QC programs be designed around the most heterogeneous material and the level of precision required for all elements of economic or environmental significance, rather than solely the primary commodity. Failure to do so can result in analytical performance that is appropriate for the principal revenue-generating element but insufficient for by-products, deleterious elements, contaminants, or elements that may become economically important in the future. In hindsight, this is particularly relevant for legacy datasets where sampling, analytical methods, and reporting limits were established under economic conditions that differed substantially from those prevailing today.
The issue highlighted in this case study should therefore not be interpreted as a criticism of historical industry practice. Rather, it illustrates how evolving economic conditions can expose limitations in legacy sampling and analytical protocols that were originally considered fit for purpose. As commodity prices change and lower-grade material becomes economically relevant, analytical performance requirements may also change, creating a mismatch between the quality of historical data and the precision required by modern resource estimation, mine planning, reconciliation, and value determination activities.
In recognition of these challenges, some operations and projects apply practical lower-grade thresholds, reporting cutoffs, or minimum selectivity criteria above analytical detection limits when making resource, planning, or operational decisions. These thresholds do not eliminate uncertainty but can reduce the influence of grade ranges where relative analytical variability becomes large compared with the magnitude of the reported value. The appropriate threshold remains site-specific and depends on the commodity, analytical method, economic drivers, and intended use of the data.
2.2.4. Dataset Description
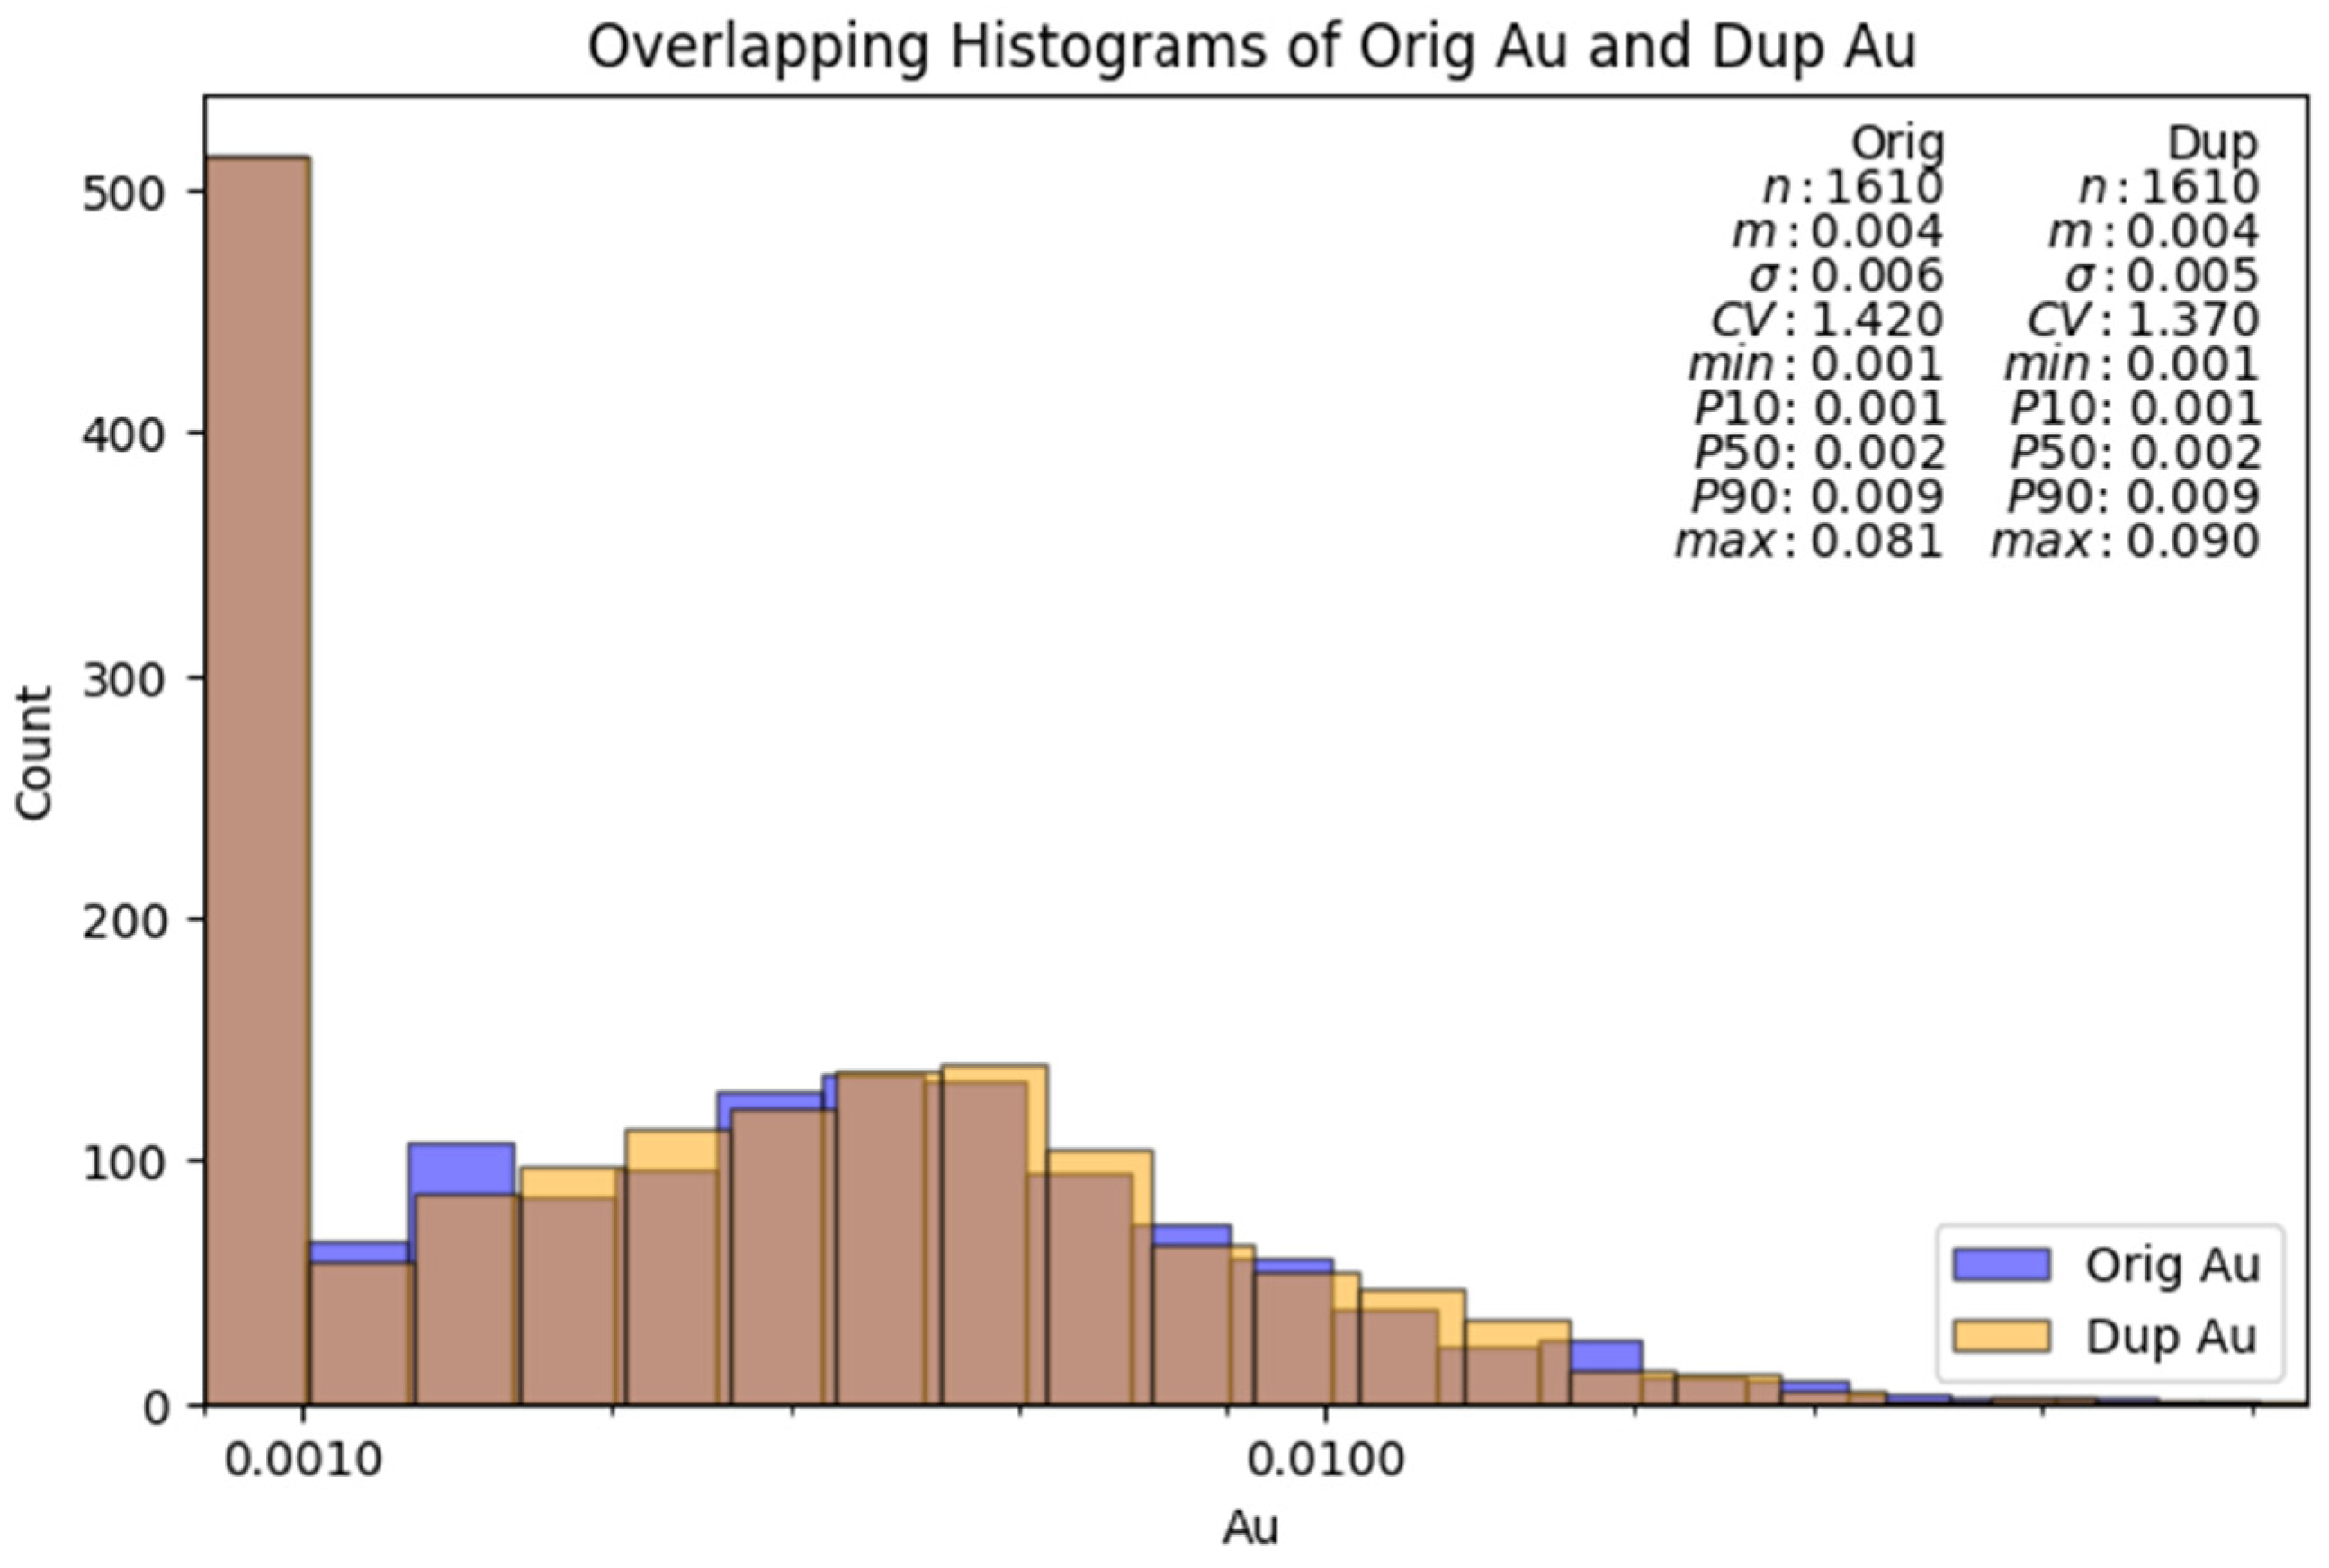
This case study is analyzing assay data from a deposit with low-grade gold. A blasthole dataset from riffle splitter sampling method was used and included primary and duplicate assays. A total of 1610 duplicate assay pairs for gold grade were available for this analysis and presented in Figure 5, providing a robust basis for evaluating analytical precision at concentrations near detection limit.
Figure 5.
Overlapping histogram plot for Original and Duplicates.
It is seen in Figure 5 that the distributions seem rather similar in shape and scale, with the Duplicates (Dup) having a slightly higher maximum value for Au than the Original (Orig) and the Original (Orig) having a slightly higher standard deviation than the Duplicates (Dup).
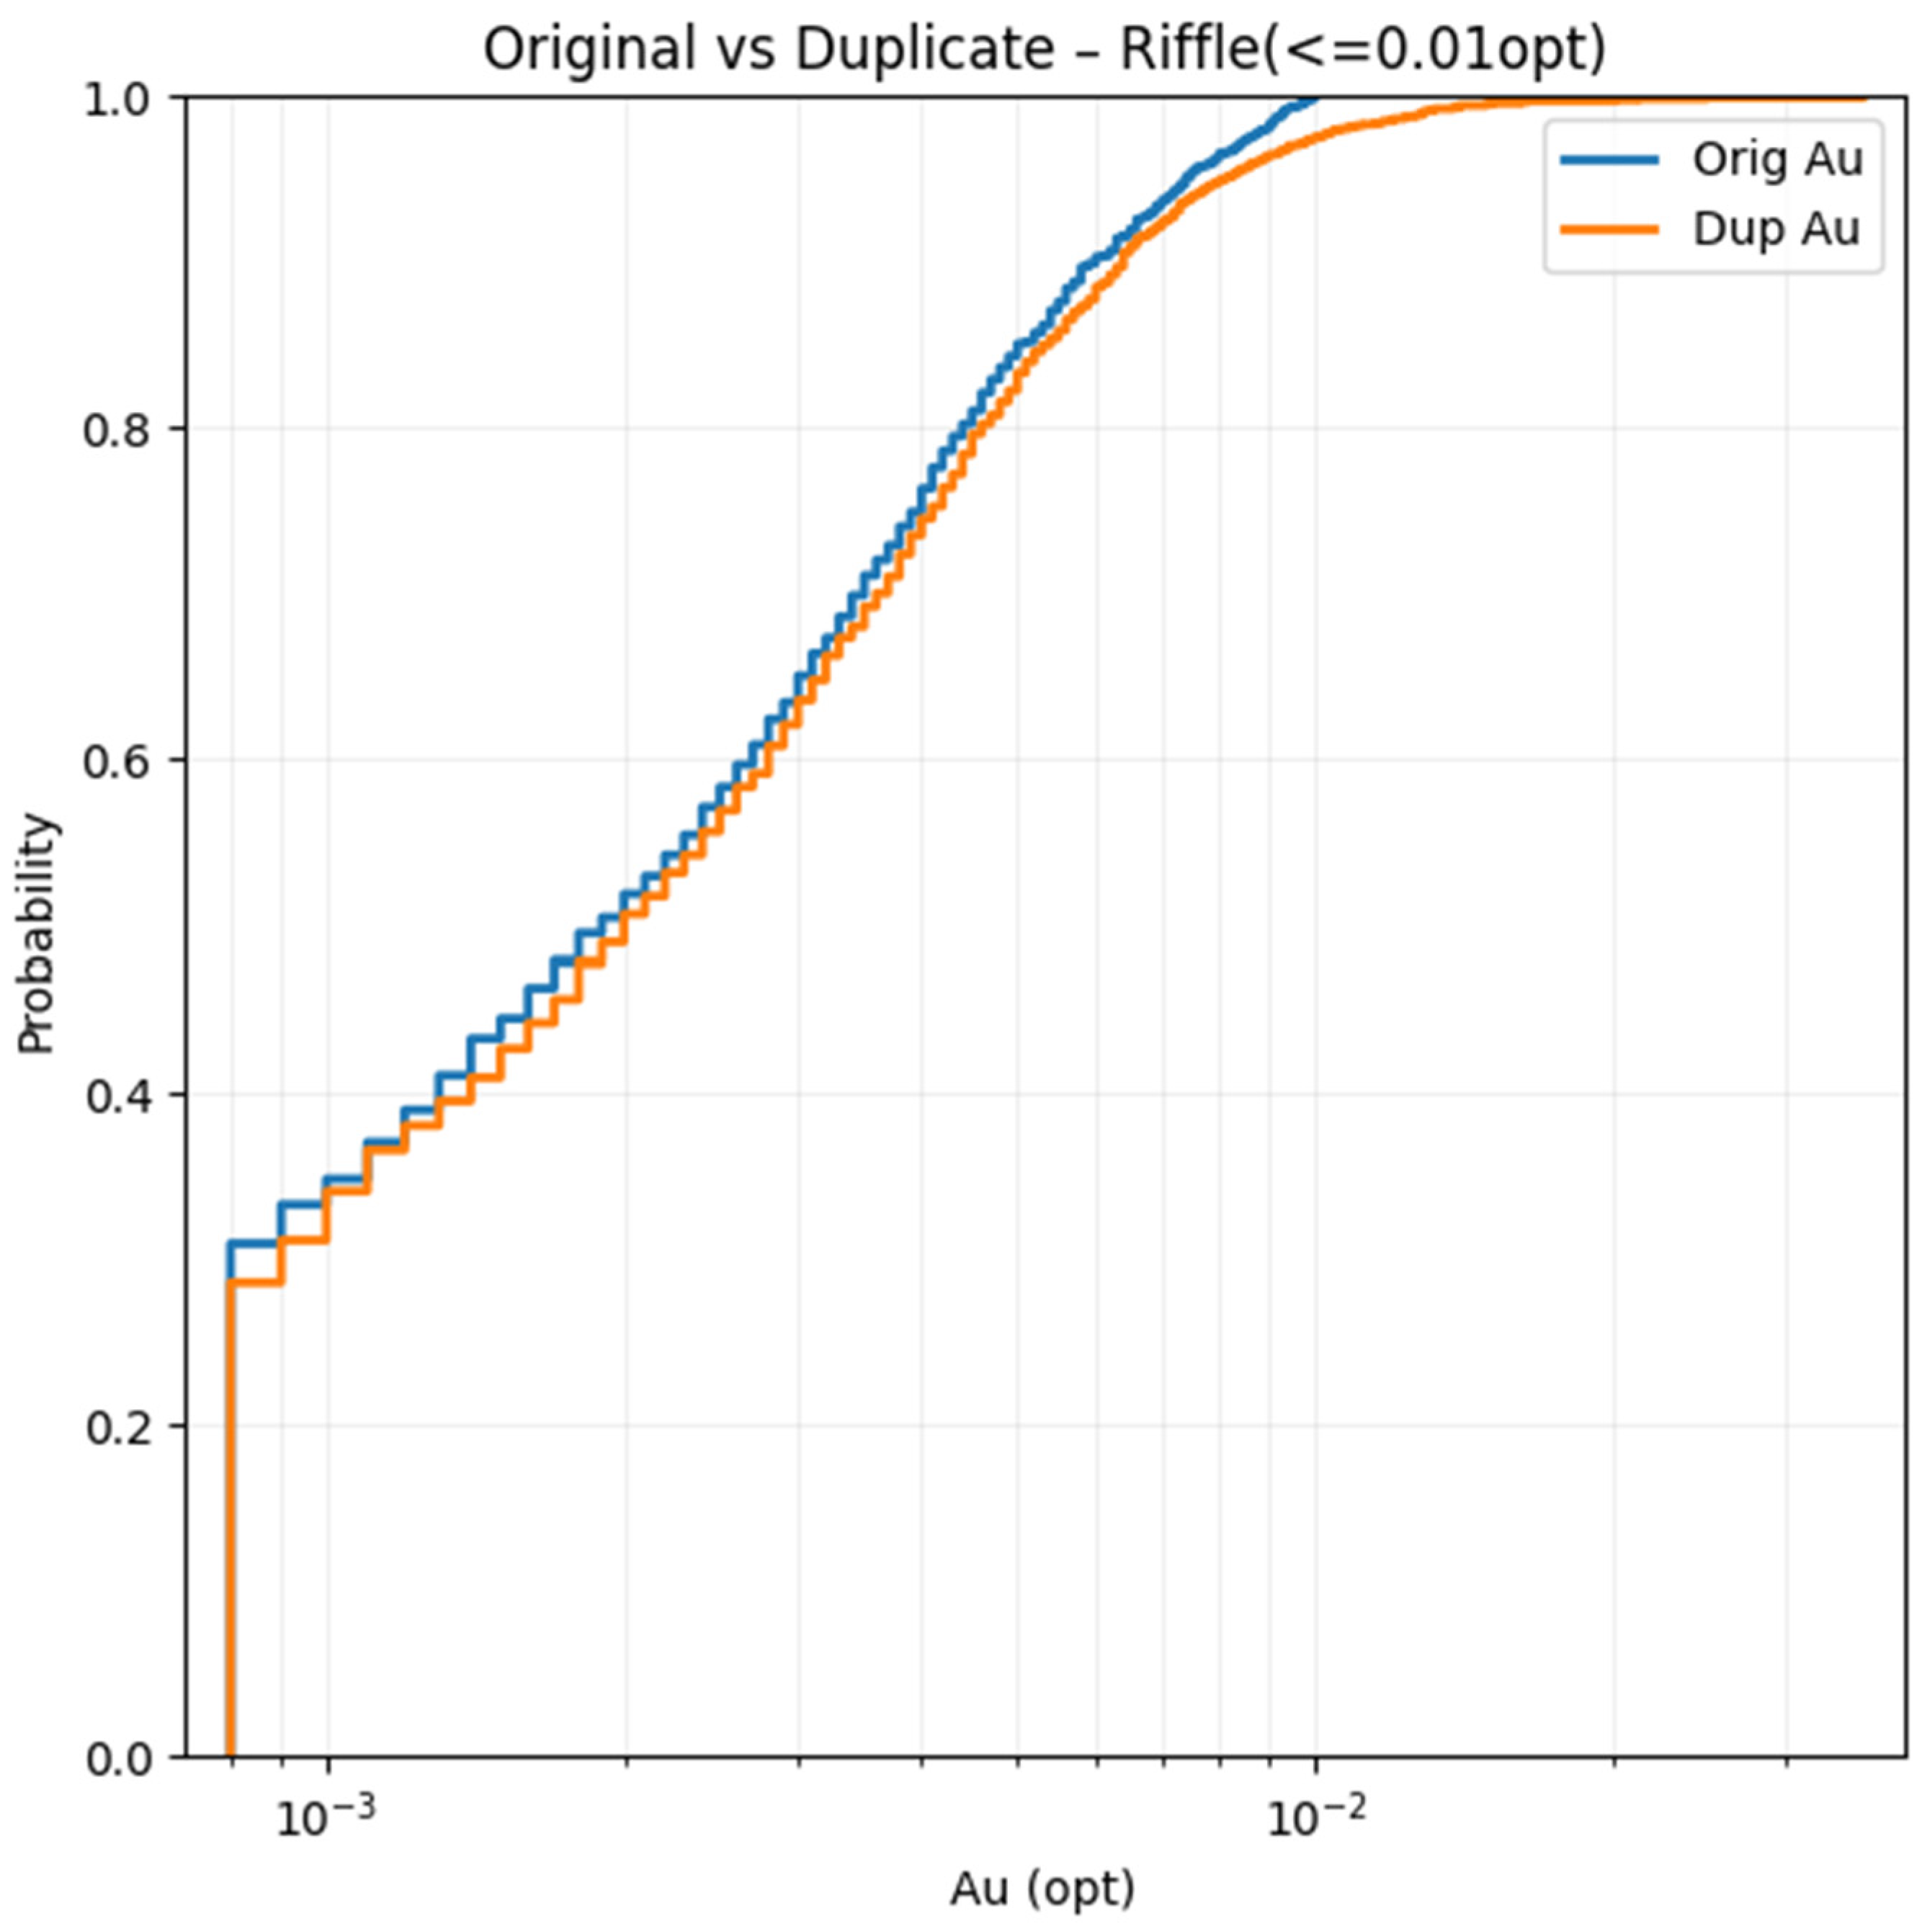
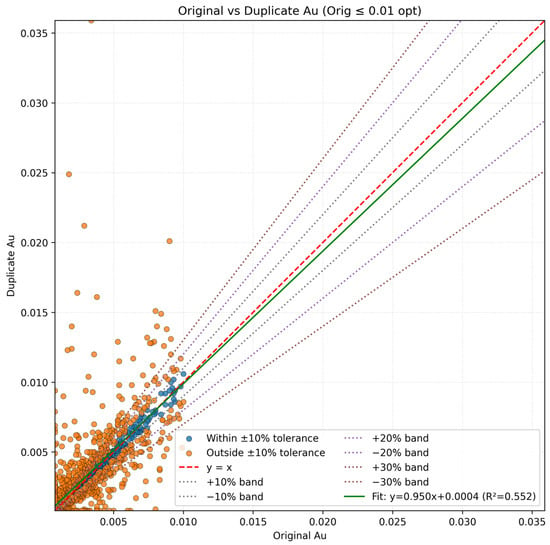
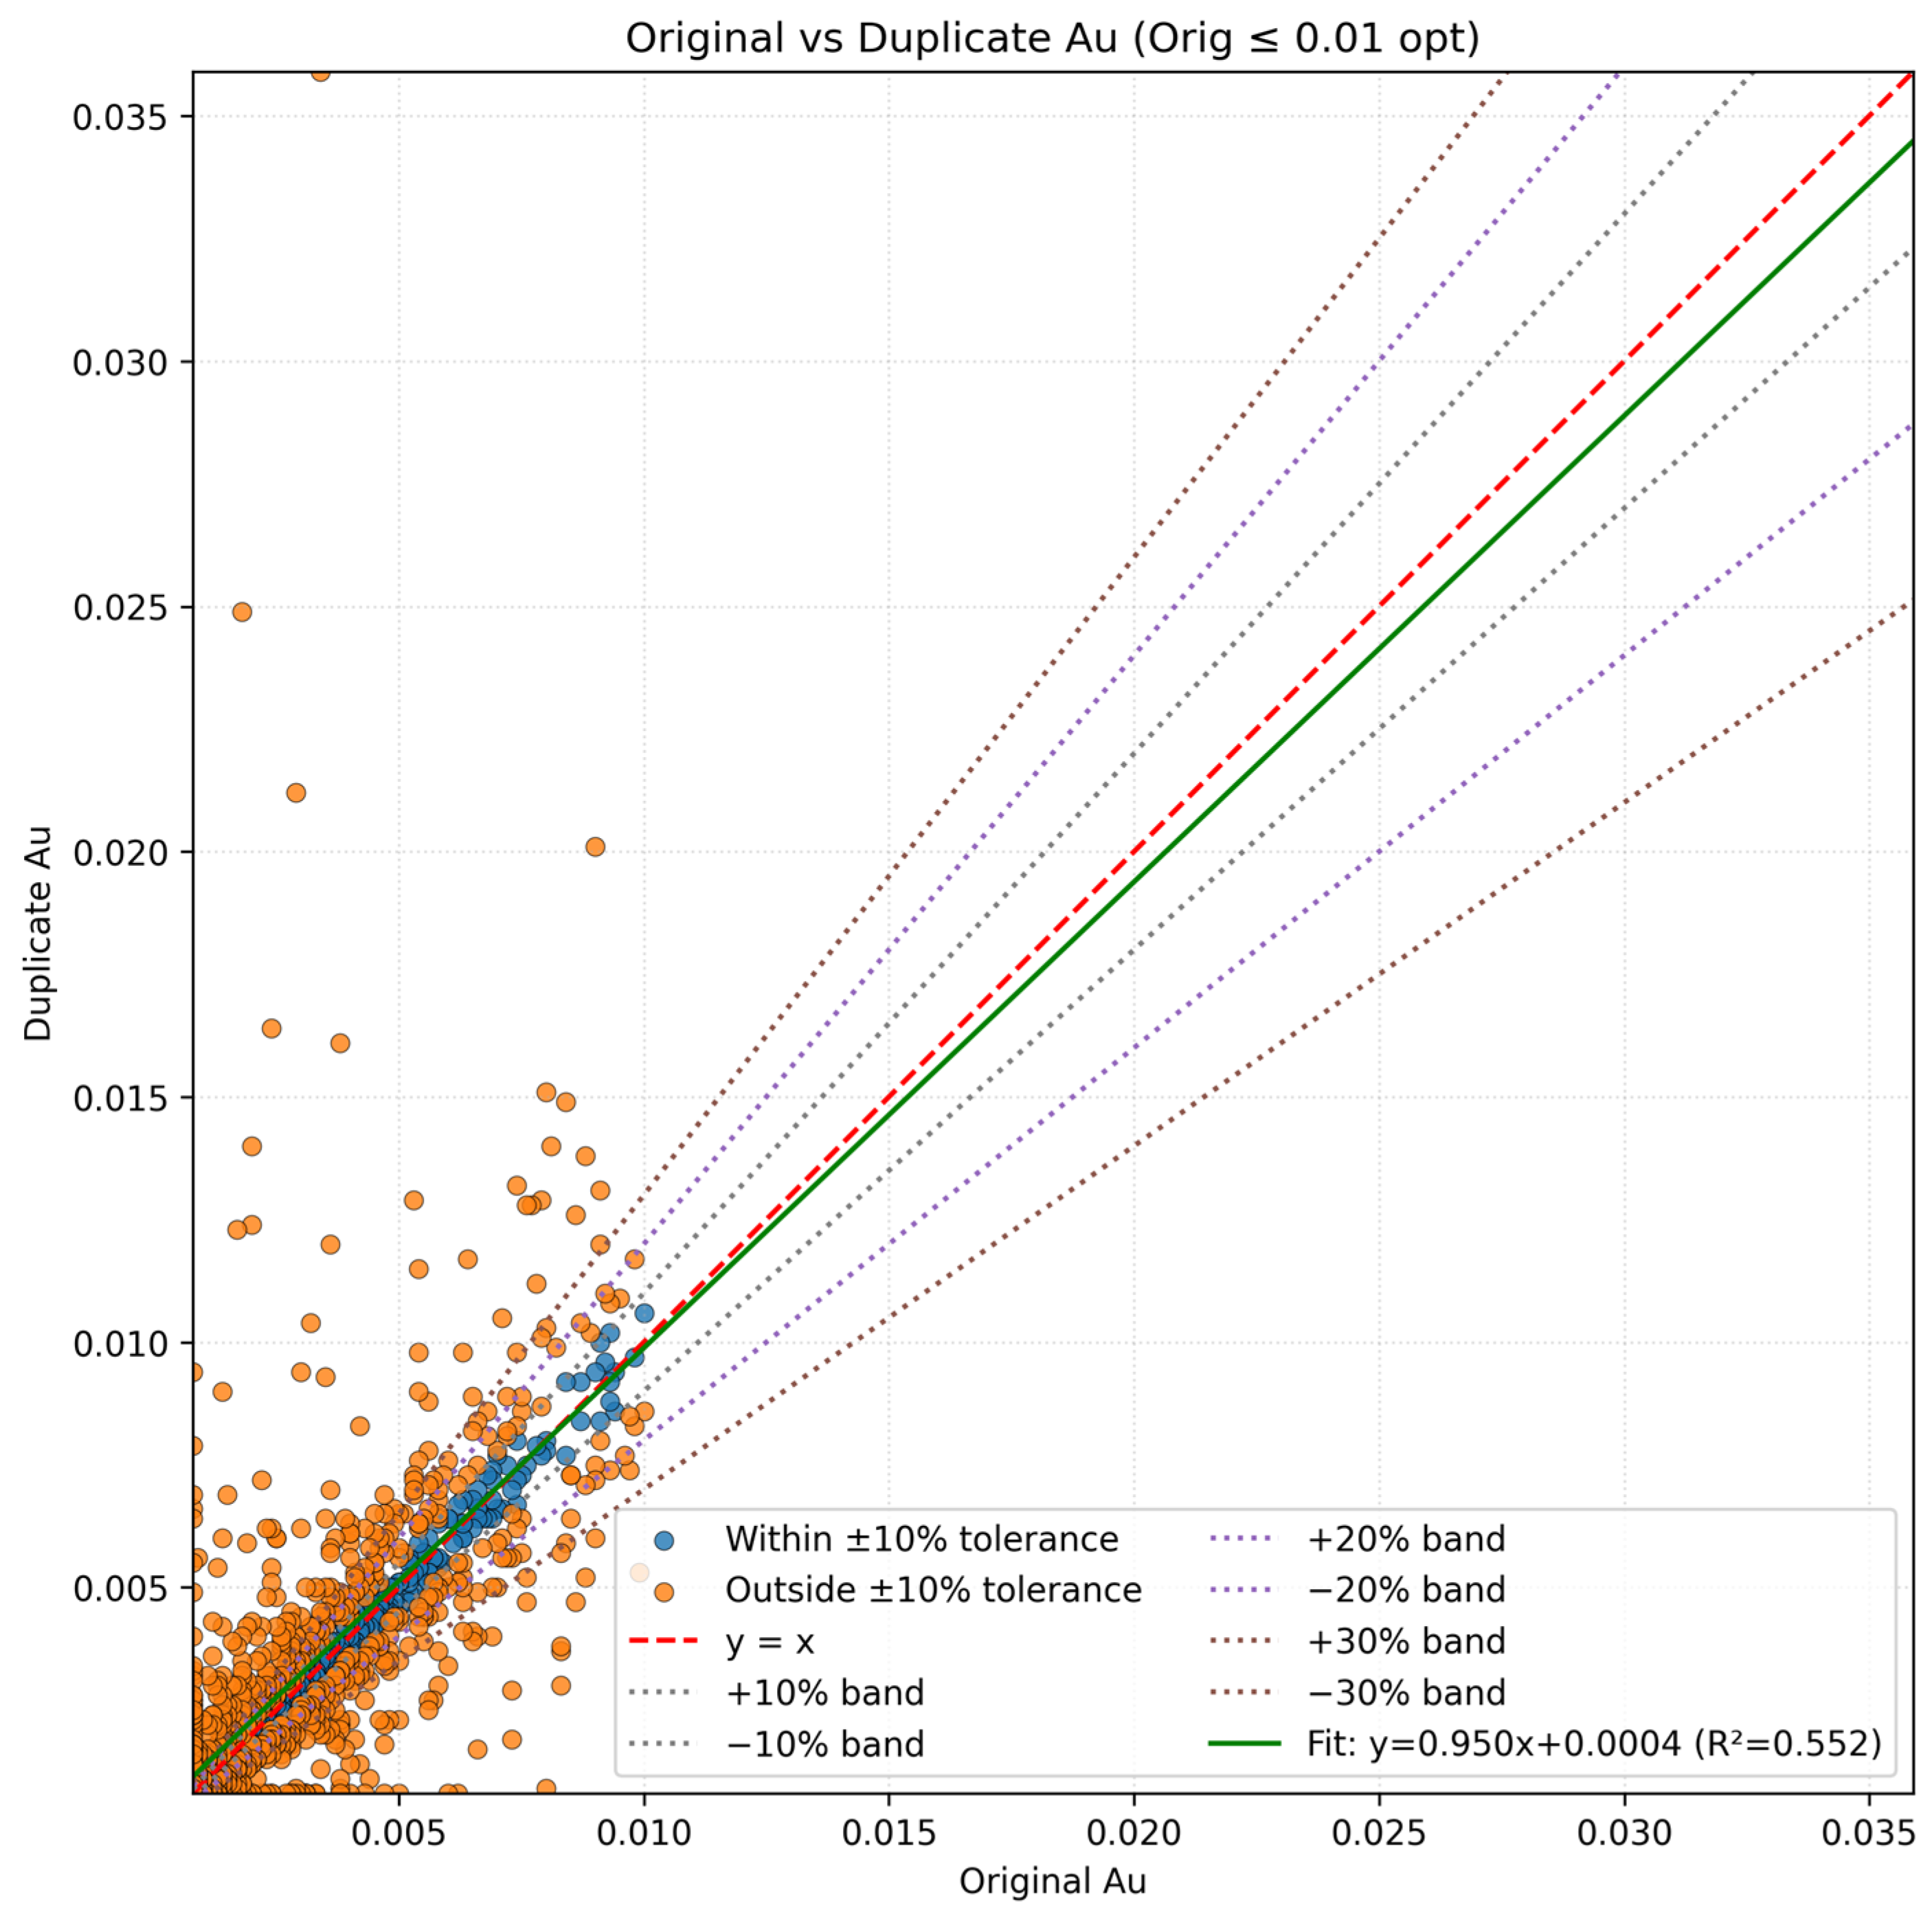
The lower portion of the distribution is the focal point of this study. In Figure 6, it is noted that for gold grades less than 0.01 ounces per short ton (opt), there is negligible bias between Original and Duplicate, where the Original is always slightly lower than the Duplicate and has good reproducibility. The paired scatter fit (Dup = 0.95 Orig + 0.0004) presented in Figure 7 crosses the 1:1 line at around 0.008 opt; Duplicates trend slightly higher than Originals below this grade and slightly lower above it. Most pairs fall within ±20%–30%, which is consistent with expected low-grade variability.
Figure 6.
Cumulative probability plot of Original vs. riffle Duplicate Au grades.
Figure 7.
Paired scatterplot of Original vs. riffle Duplicate Au grades.
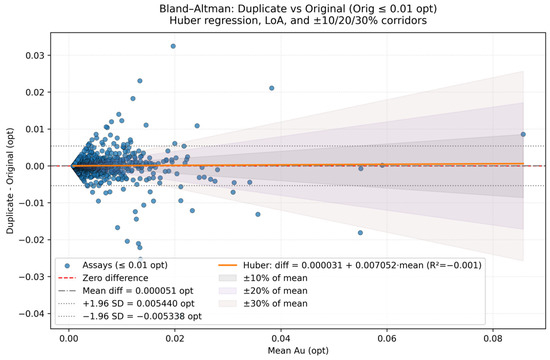
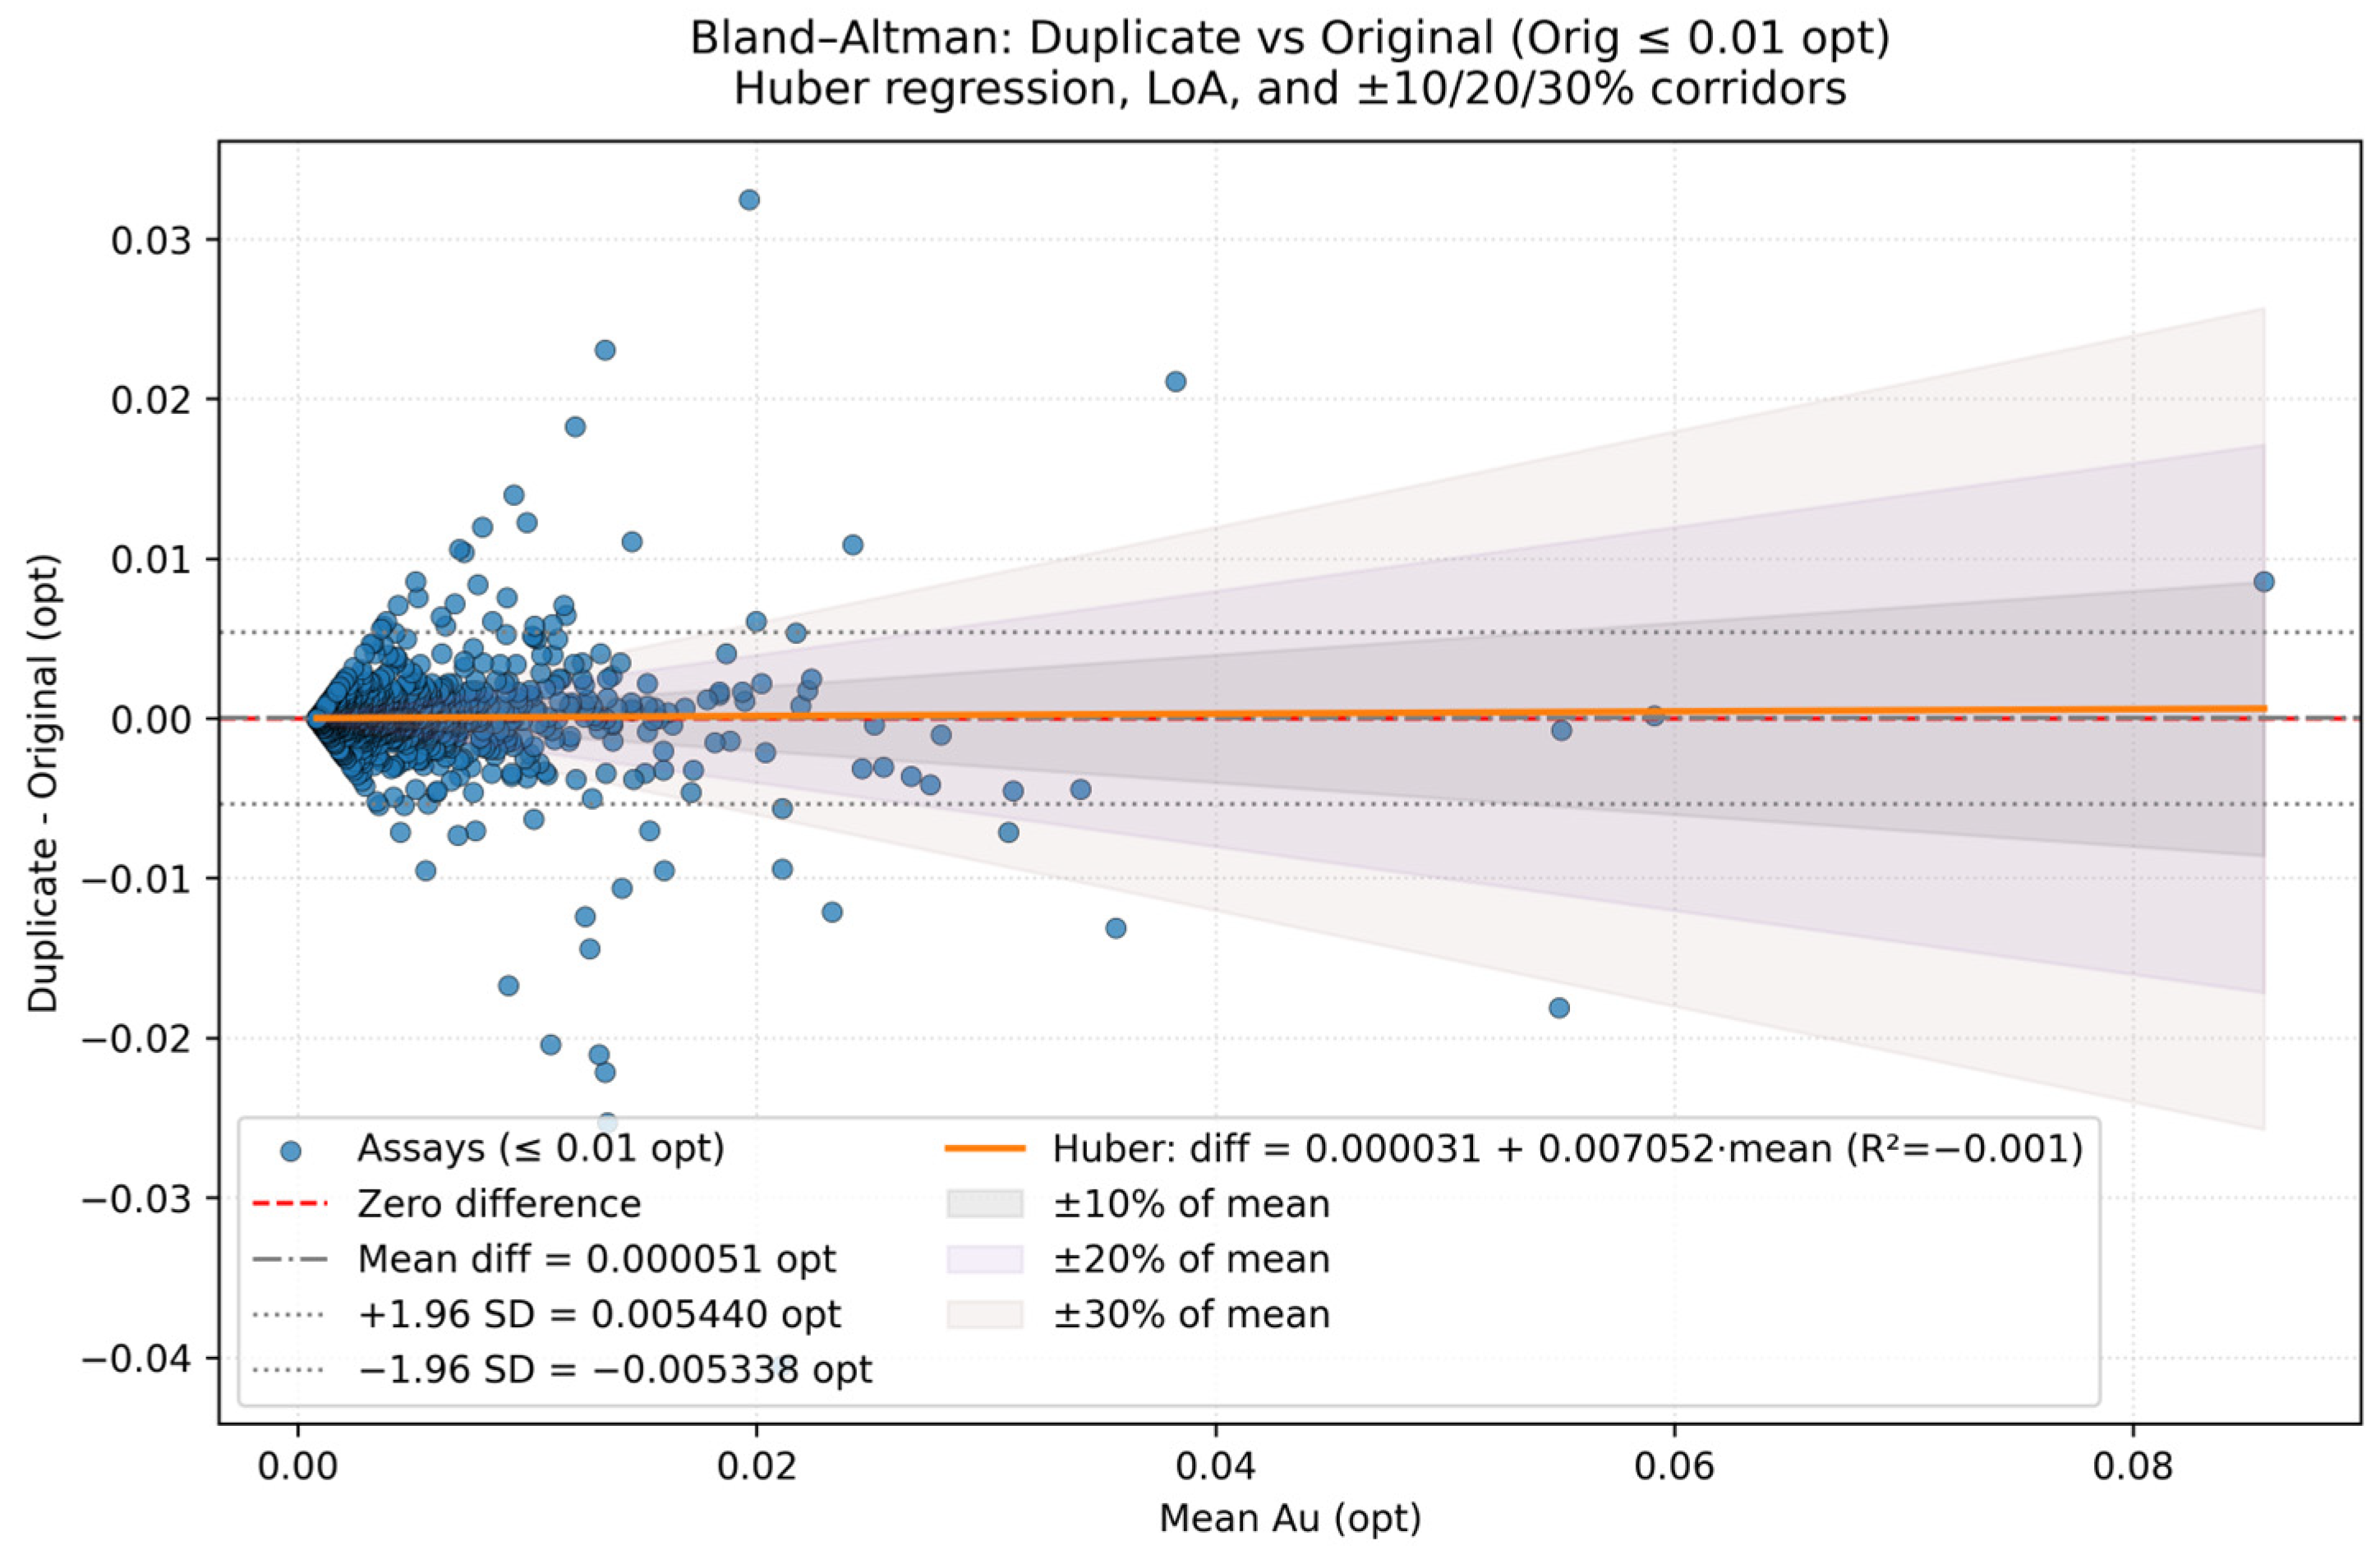
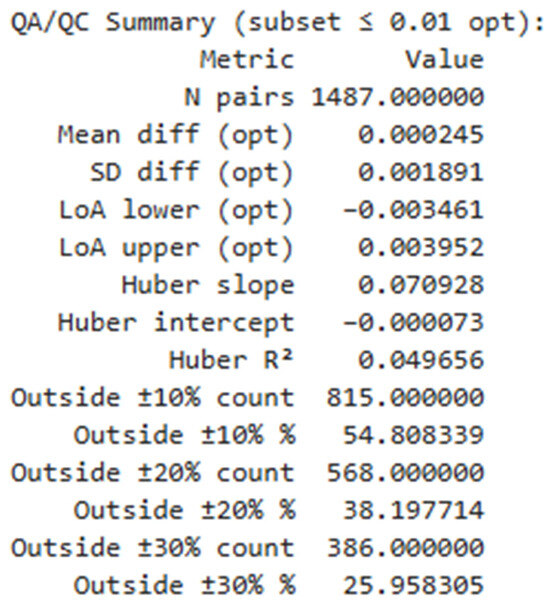
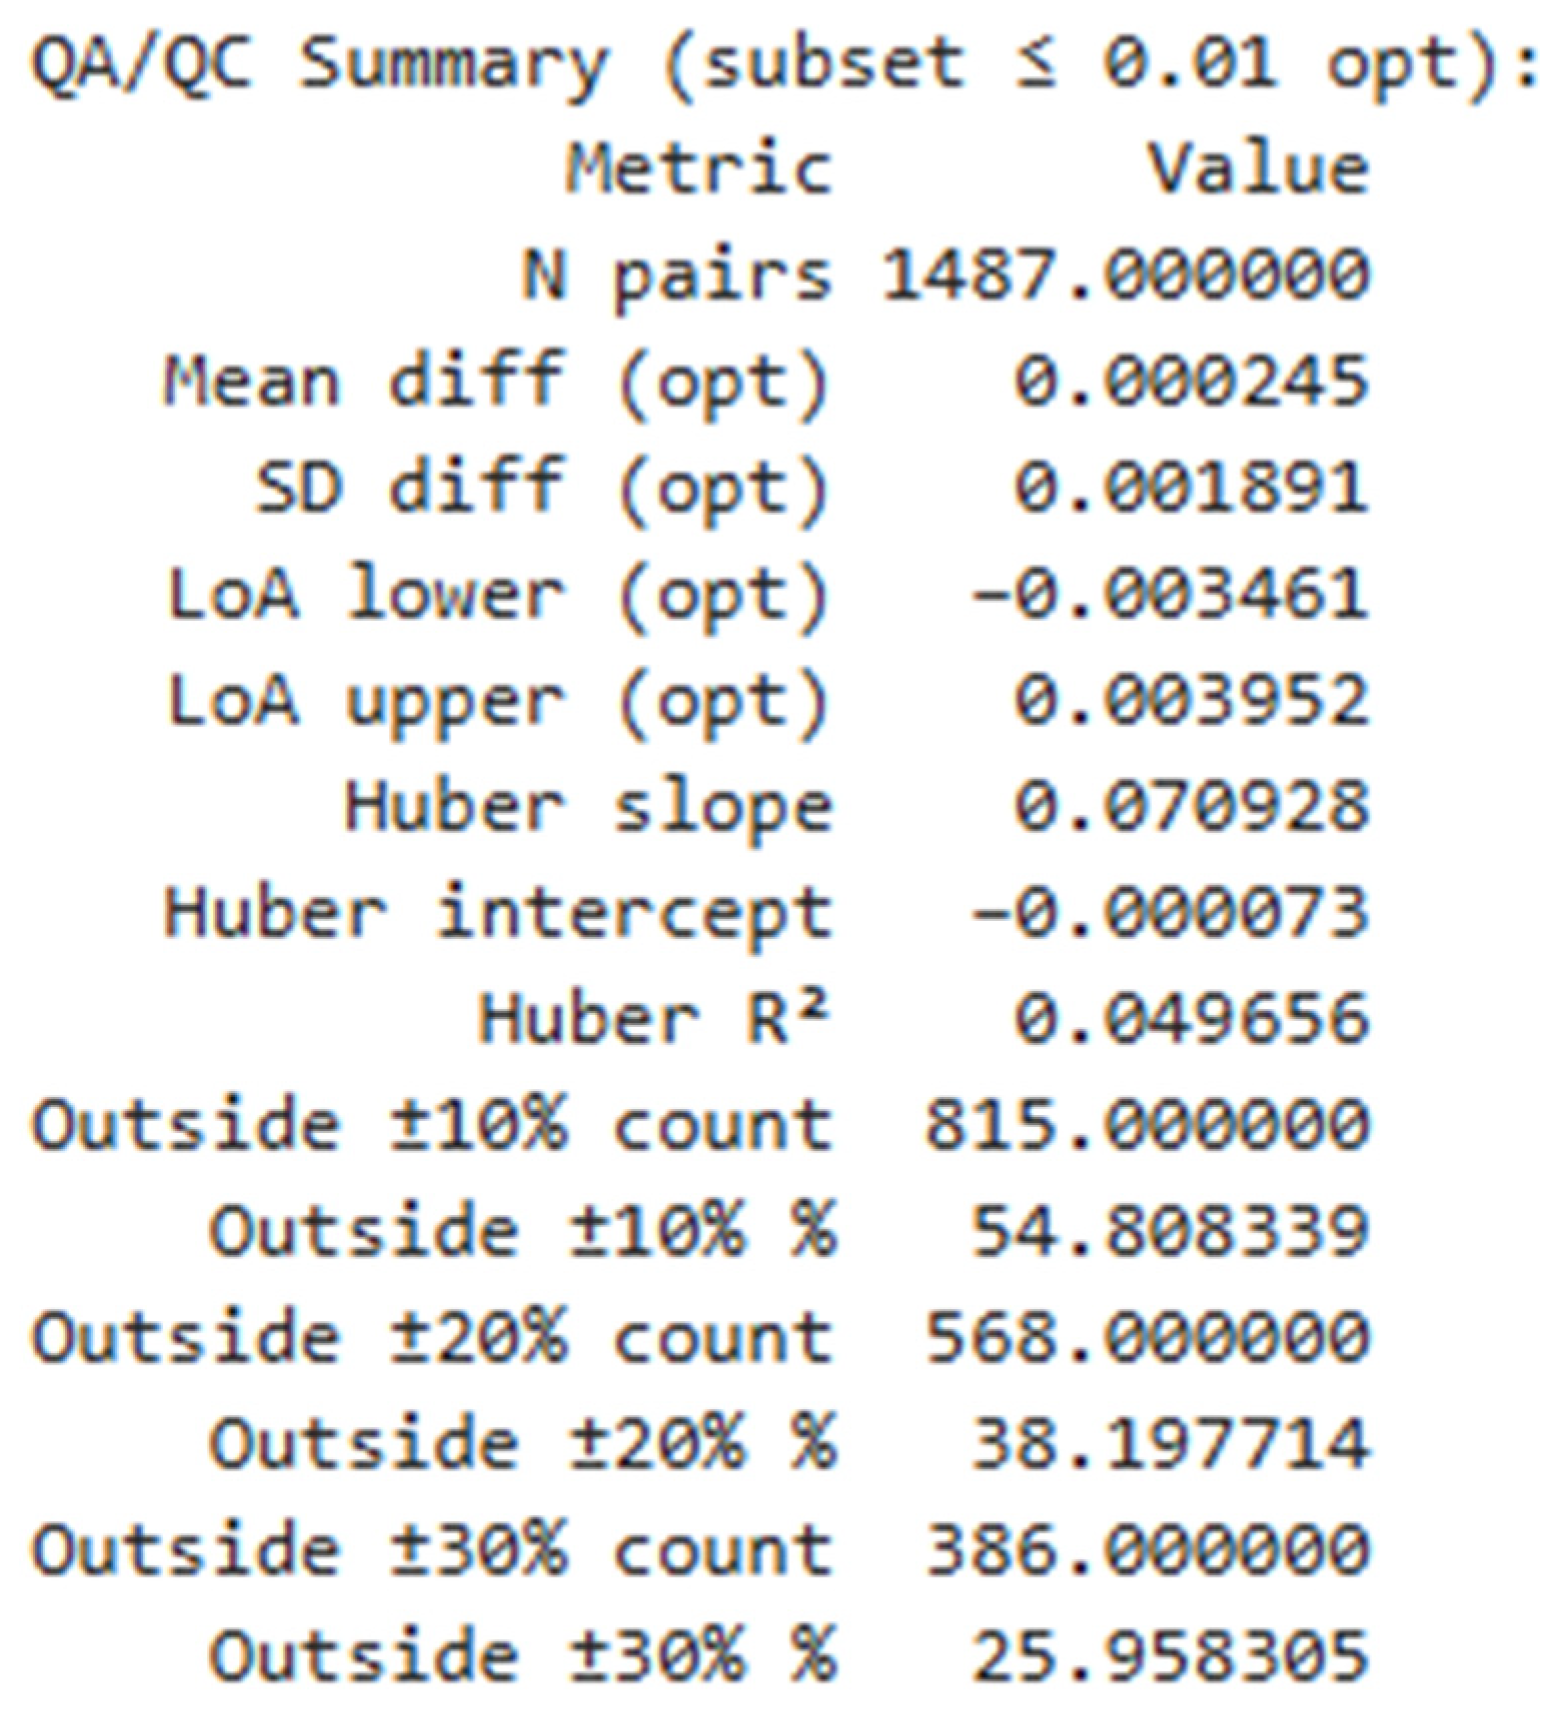
Bland–Altman analysis is used to evaluate agreement between original and riffle duplicate gold assays, focusing on differences rather than on correlation. For samples defined by the Original Au ≤ 0.01 opt, the mean difference is near zero, as seen in Figure 8 and Figure 9, indicating negligible average bias, with 95% limits of agreement of approximately ±0.0054 opt reflecting expected low-grade analytical variability. A robust Huber regression of difference versus mean shows only a weak non-explanatory trend (slope ≈ 0.007, ). In percentage terms, ~45% of the pairs lie within ±10% of the mean, ~62% within ±20%, and ~74% within ±30%, consistent with the fact that relative error inflates at very low grades even when absolute difference remains small. Overall, no material systematic bias is evident in the low-grade tail, and precision is fit for purpose.
Figure 8.
Bland–Altman: duplicate vs. original (orig ≤ 0.01 opt).
Figure 9.
QA/QC summary: Duplicate vs. Original (orig ≤ 0.01 opt).
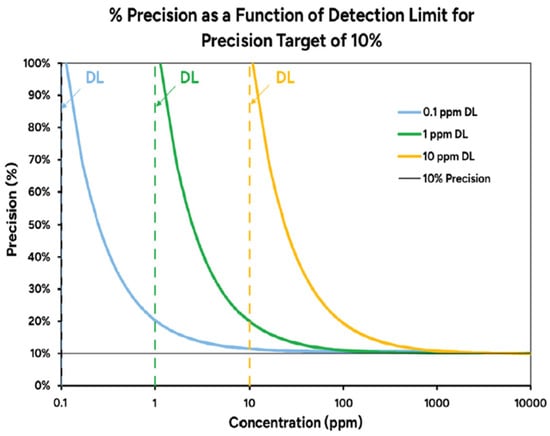
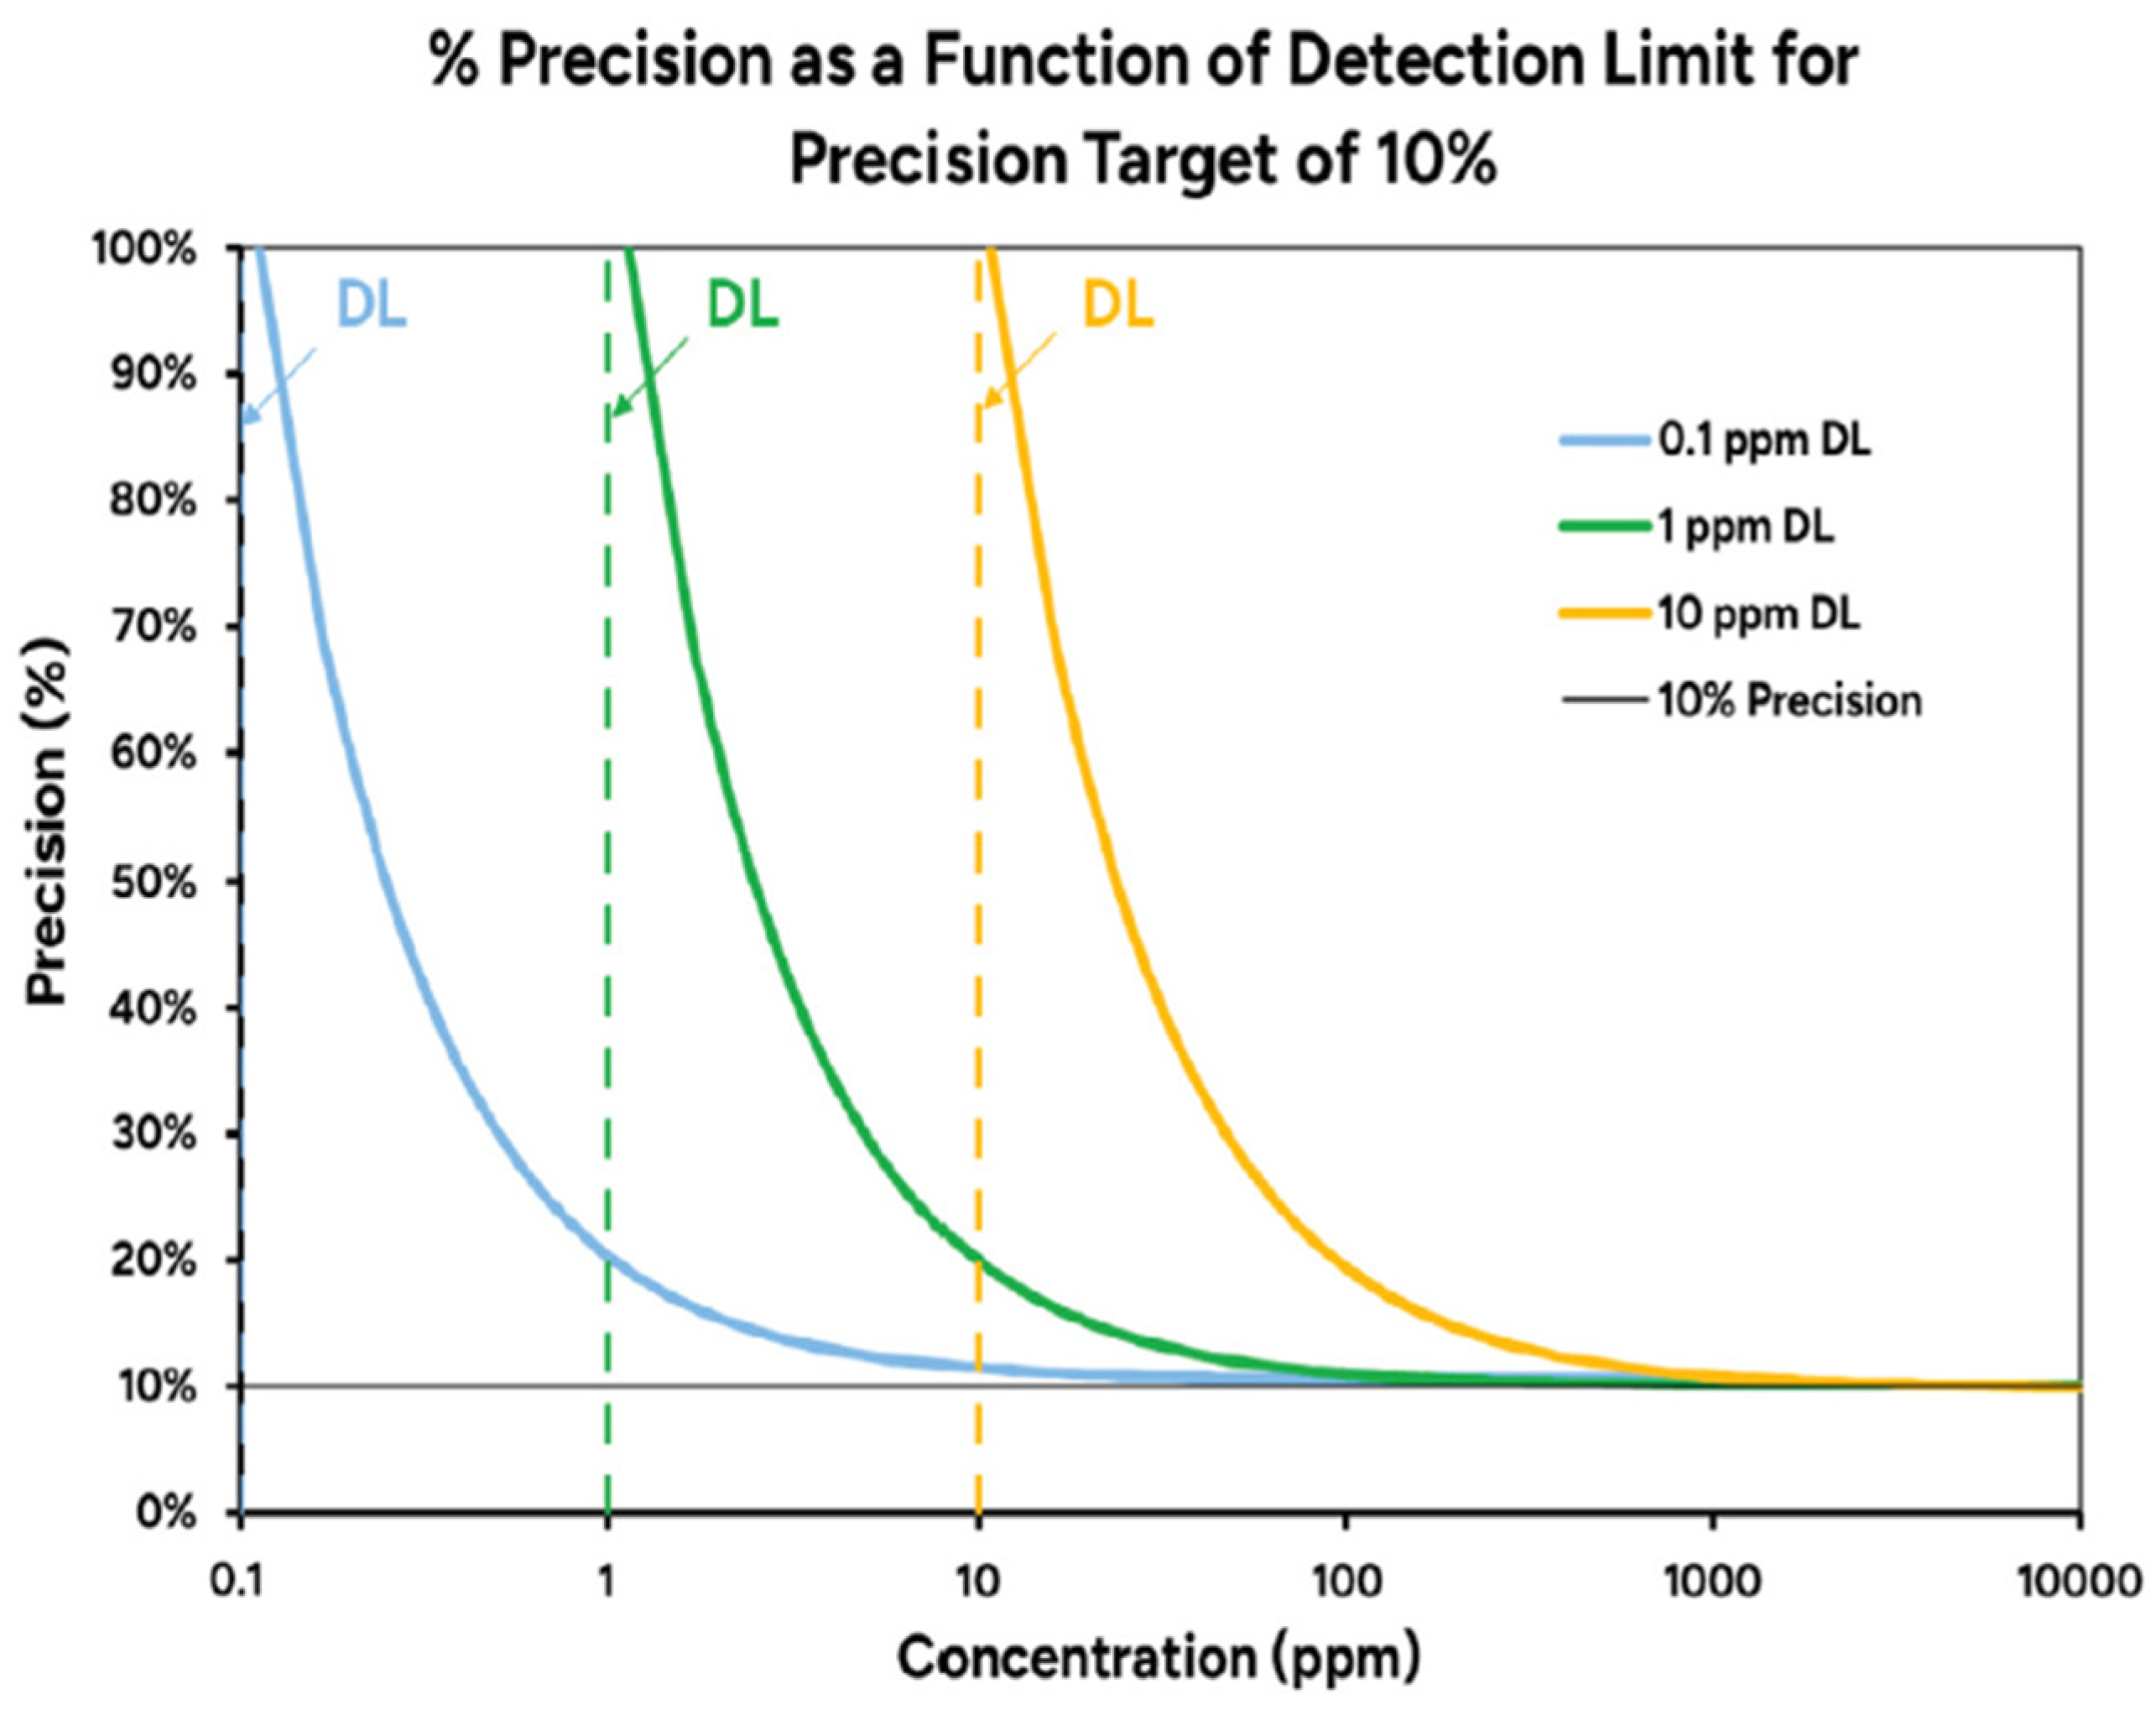
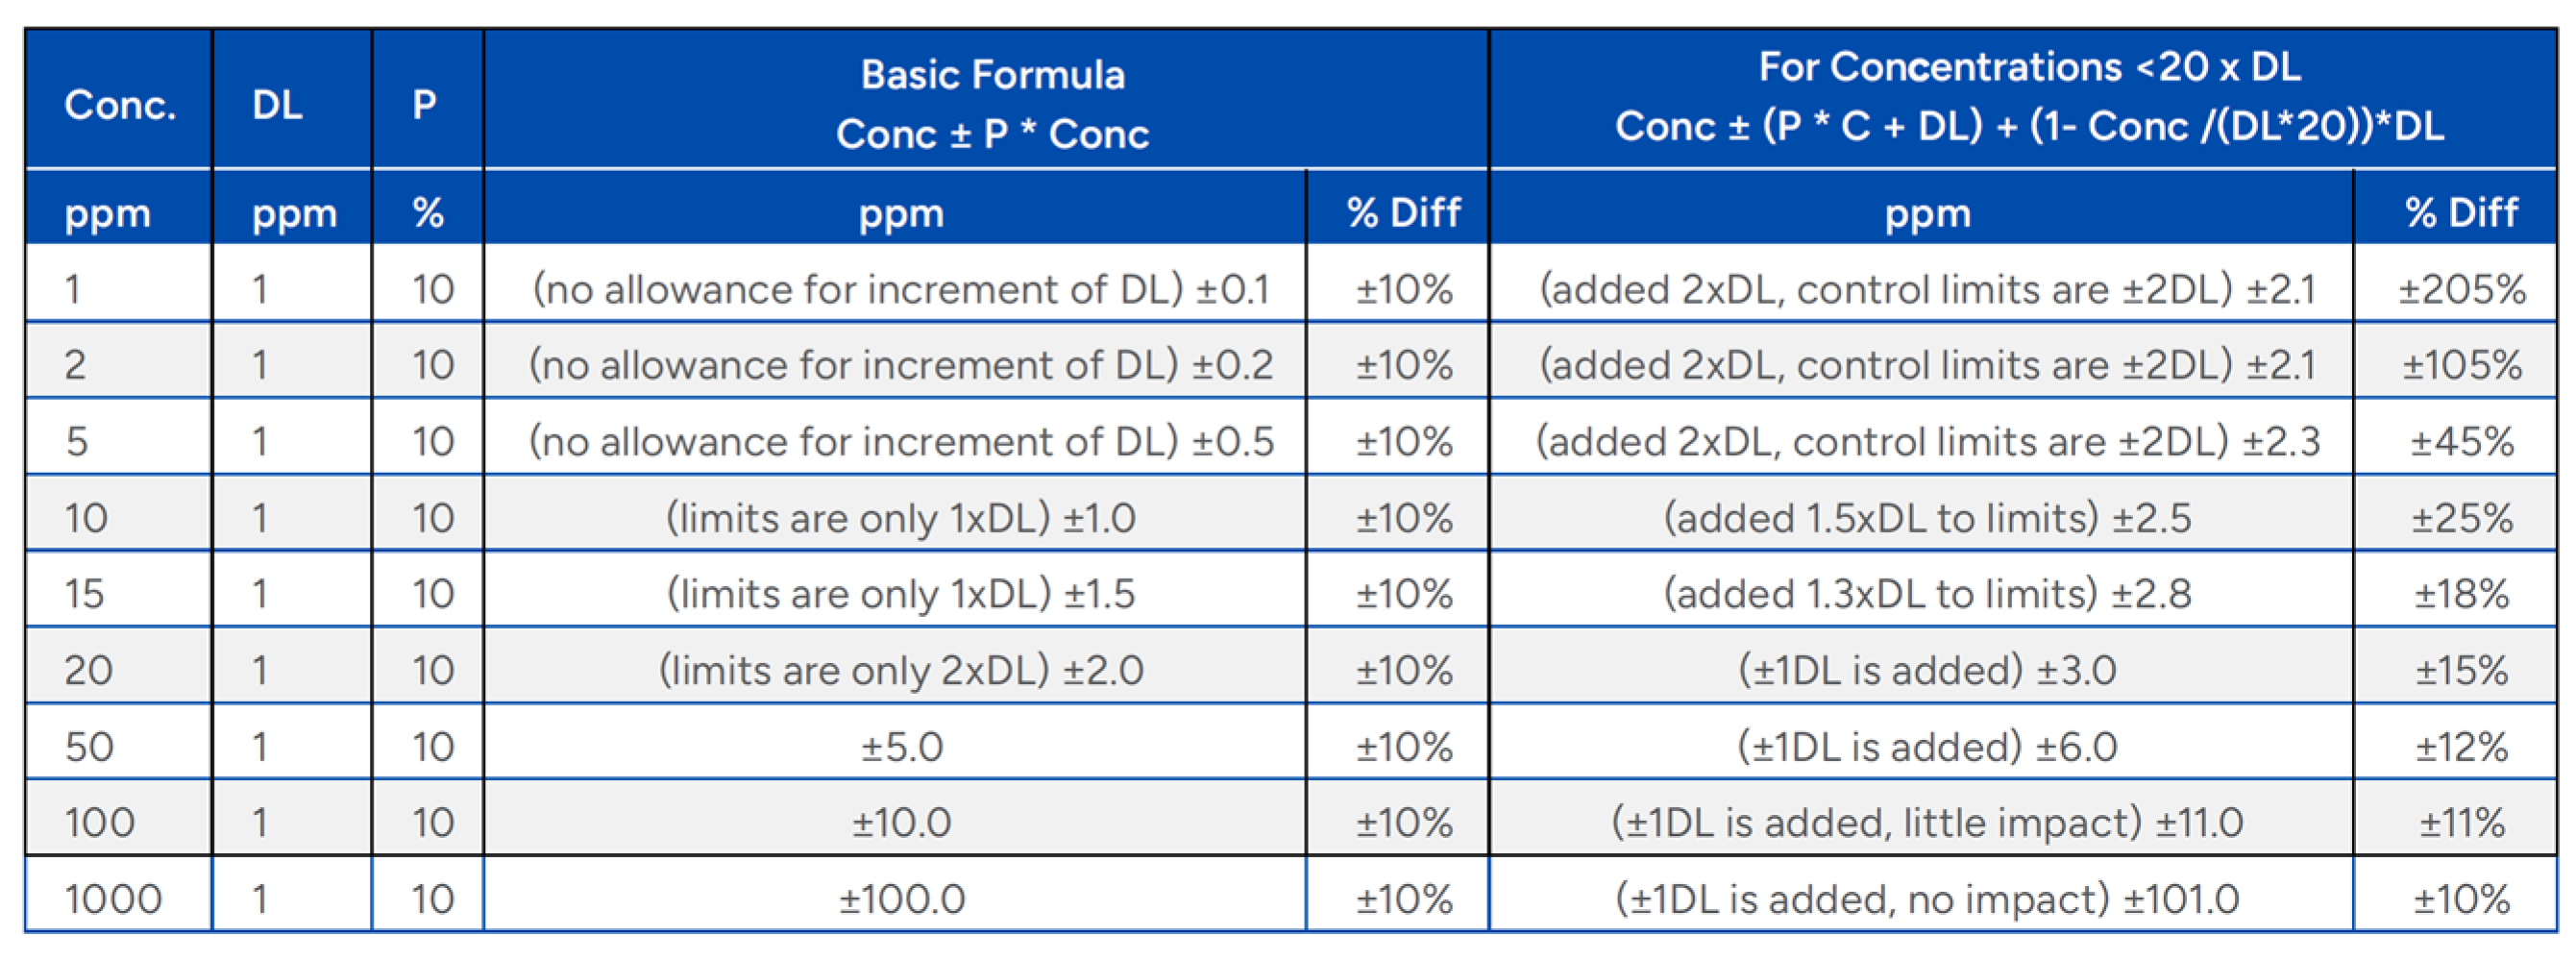
The cumulative probability plot, paired scatter analysis, and Bland–Altman analyses demonstrate negligible average bias between Original and riffle Duplicate assays and show scatter consistent with expectations at low grades, with relative error inflating as grades approach the detection limit. These analyses, however, do not explicitly describe how laboratory control limits are constructed near the detection limit nor how this construction can cause an otherwise symmetric error structure to appear biased when expressed in percentage terms. This behavior is often informally attributed to geological nugget effects; however, ALS Global’s QC limits fact sheet “QC Limits Fact Sheet_Rev2.0.pdf”, here taken as an illustrative of a broader analytical principal, makes it clear that it is also an inherent consequence of method precision, detection limits, and reporting increments. ALS explicitly accounts for degraded precision near the detection limit by expanding acceptable control limits through the inclusion of detection limit-based terms, formalizing the inflation of relative error at very low concentrations, as seen in Figure 10.
Figure 10.
Percentage precision as a function of detection limit [9].
As stated in the ALS QC Limits Fact Sheet, the basic formula for target performance control limits for analytical reference material is Conc ± P * Conc, where Conc is the concentration of the reference material and P is the precision expectation of the method, and this formula does not accommodate reporting in increments of the detection limit. The calculated limits may be smaller than what is reported analytically. To address this, an adjusted formula is applied to concentrations below 20 times the method’s detection limit, providing an additional margin:
where Conc is the concentration of the reference material, DL is the detection limit of the method, and P is the precision of the method.
Based on Figure 11, it is evident that as gold concentrations approach the analytical detection limit, the calculated percent difference increases substantially when using the <20× detection limit formulation compared to the basic percent difference formula. The basic formula applies to a constant proportional error, resulting in a uniform ±10% difference across all concentrations. In contrast, the <20× DL formulation explicitly incorporates the detection limit into the calculation, leading to progressively larger relative differences at low concentrations.
Figure 11.
Comparison of values calculated from both formulas.
For this study, historical gold concentrations are commonly near legacy detection limits. As a result, uncertainty associated with low-grade assays is expected to be elevated, with potential relative differences ranging from approximately ±10% at higher concentrations to greater than ±200% at or near detection limit. These elevated differences reflect the conservative behavior of the <20× DL formulation rather than true analytical precision and are intended to appropriately represent uncertainty in low-level gold data.
2.2.5. Demonstration of Downstream Impact
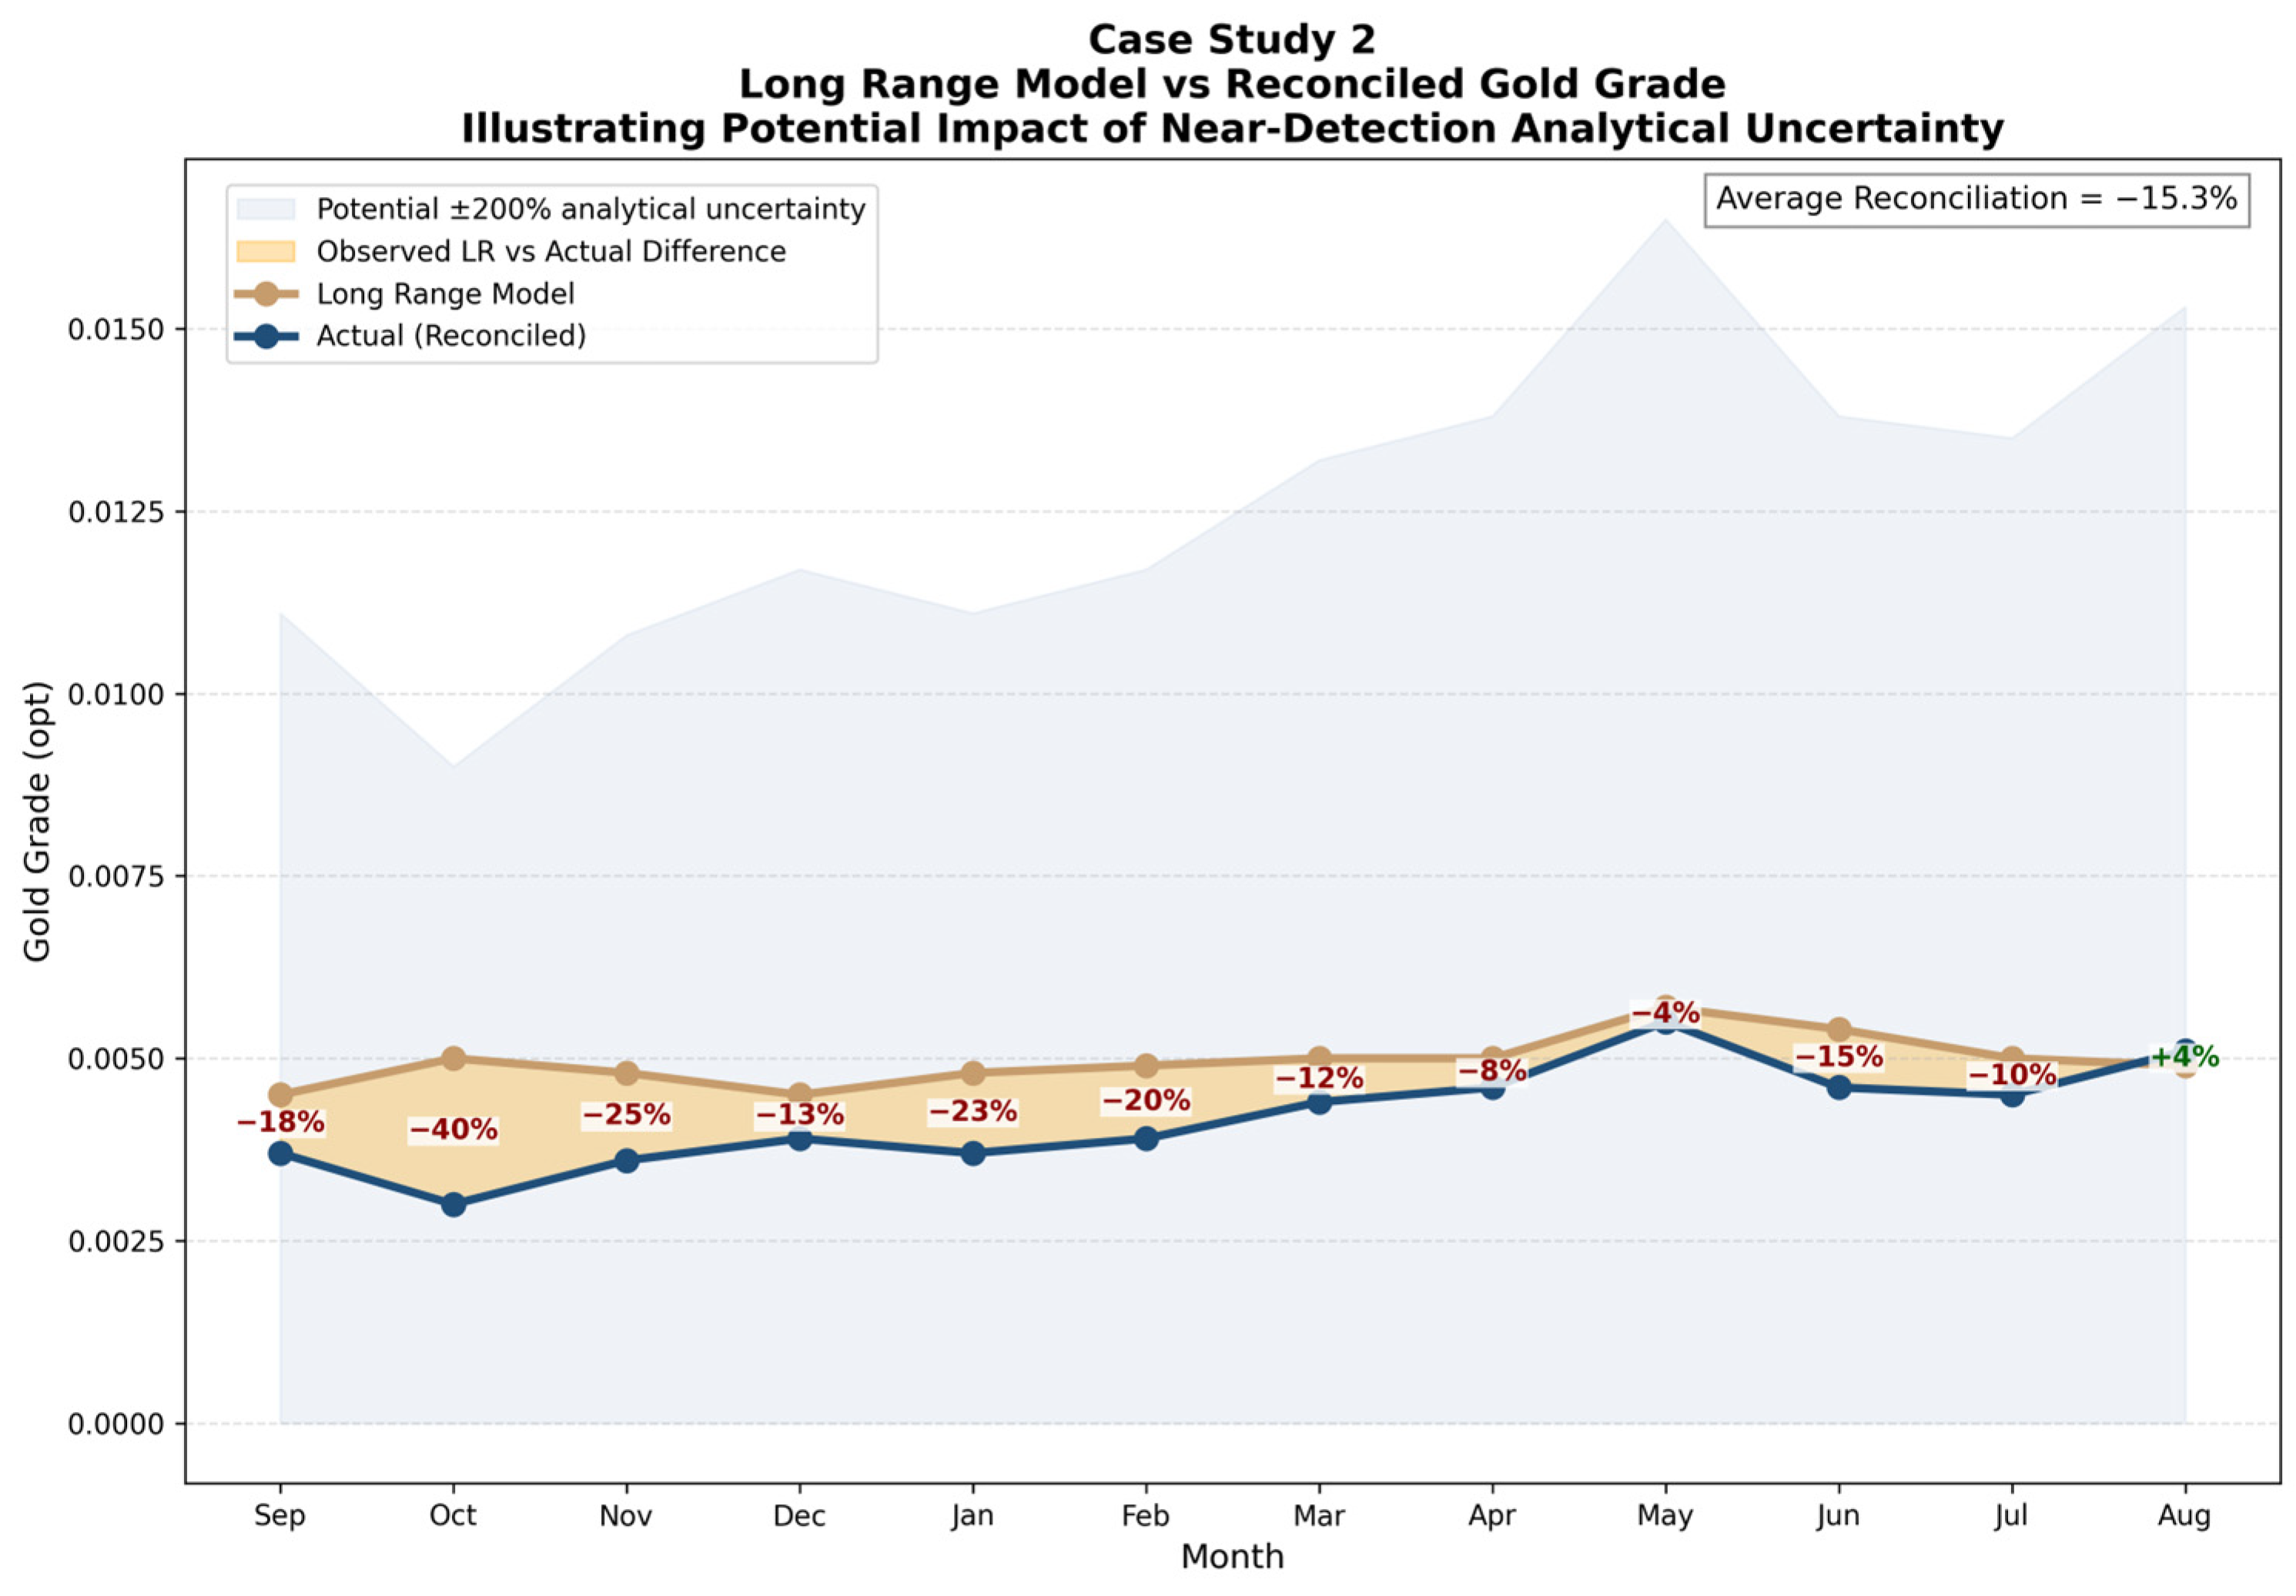
While Figure 10 and Figure 11 above demonstrate how relative uncertainty can increase substantially as concentrations approach the analytical detection limit, the operational significance of this uncertainty is often less apparent. To illustrate a potential downstream consequence, Figure 12 compares long-range model gold grades with reconciled production grades over a twelve-month period.
Figure 12.
Long-range model versus reconciled gold grade, with analytical uncertainty envelope for grades near the detection limit.
As shown in Figure 12, reconciled gold grades were generally lower than long-range model predictions throughout most of the study period, with an average reconciliation of approximately −15.3%. The blue shaded uncertainty envelope represents the analytical uncertainty range reported by ALS for values approaching the detection limit based on the adjusted formula.
The figure highlights an important concept. While analytical uncertainty near the detection limit may appear to have an insignificant effect on an individual-sample basis, the cumulative effect of uncertainty within large populations of low-grade samples can become economically meaningful when these materials are incorporated into resource models, mine plans, stockpiles and processing streams. Analytical uncertainty should therefore be considered one potential contributor among many sources of reconciliation variance.
2.2.6. Discussion
This case study demonstrates that low-grade gold assays near the detection limit can exhibit acceptable precision and negligible systematic bias when evaluated using detection limit-appropriate QA/QC frameworks. Apparent inflation of relative error at very low concentrations is shown to be a predictable consequence of analytical method behavior rather than analytical failure, and therefore the uncertainty must be carried explicitly into low-grade decisions. These effects reflect legacy misalignment between historical data collection practices and modern economic requirements.
2.2.7. Implications for Reconciliation and Low-Grade Material Handling
When analytical precision near the detection limit is not the primary driver of reconciliation performance, it represents a subtle but systematic source of uncertainty that can contribute to observed reconciliation differences when low-grade material becomes economically relevant. As demonstrated in this case study, relative error in gold assays inflates at concentrations near the detection limit due to method precision, reporting increments, and detection limit-based control limits, even when absolute differences remain small and unbiased.
In historical operating contexts, these low-grade gold values were rarely relied upon for material classification or value determination and therefore did not materially influence reconciliation outcomes. Under current economic conditions, the inclusion of low-grade material near detection limits or even historical detection limits in ore classifications, stockpiles, and processing streams introduces a component of variability that was not previously considered. When aggregated over large tonnages, this low-grade analytical variability can manifest as small but persistent differences between model predictions and downstream reconciliations.
A number of statistical and geostatistical methods have been developed to address censored observations and data affected by detection limits, including maximum likelihood approaches, censored-data geostatistical models, and related estimation frameworks designed specifically for observations that are only partially quantified. Ordoñez et al. (2017), for example, describe a geostatistical framework for estimation and prediction using censored responses rather than relying on arbitrary substitution values [10]. However, despite the existence of these methods, they are not routinely incorporated into standard mineral resource estimation workflows. In practice, most resource estimation datasets contain relatively few below-detection observations, analytical results are frequently reported as numerical values rather than explicit non-detects, and assay values are commonly treated as fixed inputs following validation and compositing. Furthermore, the issue considered in this study differs from classical censored-data problems because the majority of gold assays were reported as quantifiable values near the detection limit rather than as censored observations below detection limit. Consequently, uncertainty associated with near-detection-limit analytical performance is rarely modelled explicitly during resource estimation, classification, mine planning, or reconciliation studies. When performing simulation workflows, uncertainty associated with geological variability is commonly represented; however, uncertainty related specifically to low-grade analytical measurements near the detection limit is rarely quantified separately. As a result, its contribution to reconciliation differences can be difficult to isolate or diagnose.
Historically, these low-grade ranges were often excluded from economic consideration and, therefore, had limited influence on resource classification decisions. As economic cutoffs decline and lower-grade material becomes part of production and reporting streams, the confidence assigned to these areas may warrant reassessment to ensure that classification reflects not only geological uncertainty but also the limitations of the underlying analytical data. While this study does not propose a specific classification methodology, it highlights that analytical uncertainty near the detection limit represents an additional source of uncertainty that may not be fully captured by traditional classification criteria focused on drill spacing, geological continuity, estimation quality, and data quantity to name a few.
This does not imply that reconciliation issues can be solely attributed to analytical performance, but it highlights that detection-limit effects represent one of several interacting contributors that collectively influence reconciliation outcomes. Recognizing and contextualizing this effect helps prevent misinterpretation of reconciliation discrepancies and supports more realistic expectations for low-grade material performance.
As progressively lower-grade material is incorporated into mine plans and processing methods advance to enable recovery from these lower-grade materials with analytical uncertainty near the detection limit, increased attention should be given to understanding and managing analytical uncertainty associated with grades near the detection limit. This does not imply that low-grade data should be arbitrarily adjusted or replaced with detection-limit values or other values, but it highlights the need for explicit acknowledgement of uncertainty in the lower tail, whether through conservative reconciliation expectations, sensitivity analysis, domain-specific treatment, modifying factors, adjusting the resource classification in these areas, or transparent communication of the limitations. This will help prevent low-grade material from being over-interpreted or unfairly penalized.
2.3. Case Study 3
As stated previously in Case Study 2, there are instances where unmineralized composites are ignored, censored, or not sampled at all. When intervals are logged as unmineralized, these samples are withheld from laboratory analysis to conserve time, budget, and other resources. However, this creates gaps in the database where no values are measured for certain intervals. In cases where site geologists are confident that the interval belongs to a barren unit, it is common for these intervals to have values at or near the detection limit assigned in the database, as there is enough geological confidence that the assigned low values will control and avoid biasing grade upward in locations where there should not be ore. This maintains spatial continuity for the estimation step and honors the geological interpretation. Hence, these values are carried forward into resource estimation and classification. Although intended to represent barren intervals, this practice introduces significant technical and compliance risks [11]. The resource model exemplified herein is subdivided into geological domains estimated independently. The data issue discussed here is specific to a single domain, i.e., the barren (waste) domain, and all data presented in this section belongs to that domain only. In the mineralized domains, the question does not arise; intervals logged within those lithologies are routinely submitted for assay, so every sample carries a measured grade, and no value assignment is required. The need for data-handling decisions is therefore unique to the barren domain, where intervals logged as waste are not systematically assayed. A subset of intervals within the barren domain have been assayed and return anomalous copper grades. These are interpreted as thin sills or lenses of mineralized lithology hosted within the barren material, with an almost random spatial distribution at the current drill spacing. Ideally, these intervals would be captured as separate domains; however, this has not yet been implemented in the geological model, and the available data are currently too sparse to define robust domain boundaries. The barren domain therefore contains a small population of intermingled mineralized samples that cannot yet be isolated geologically.
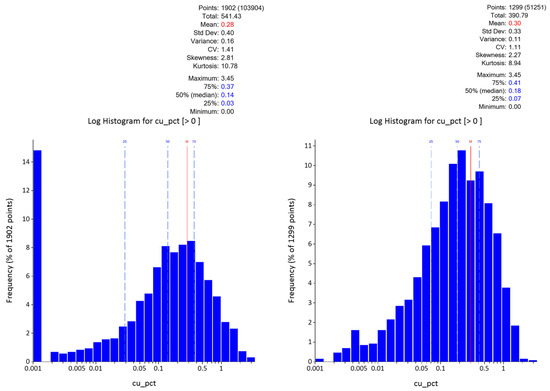
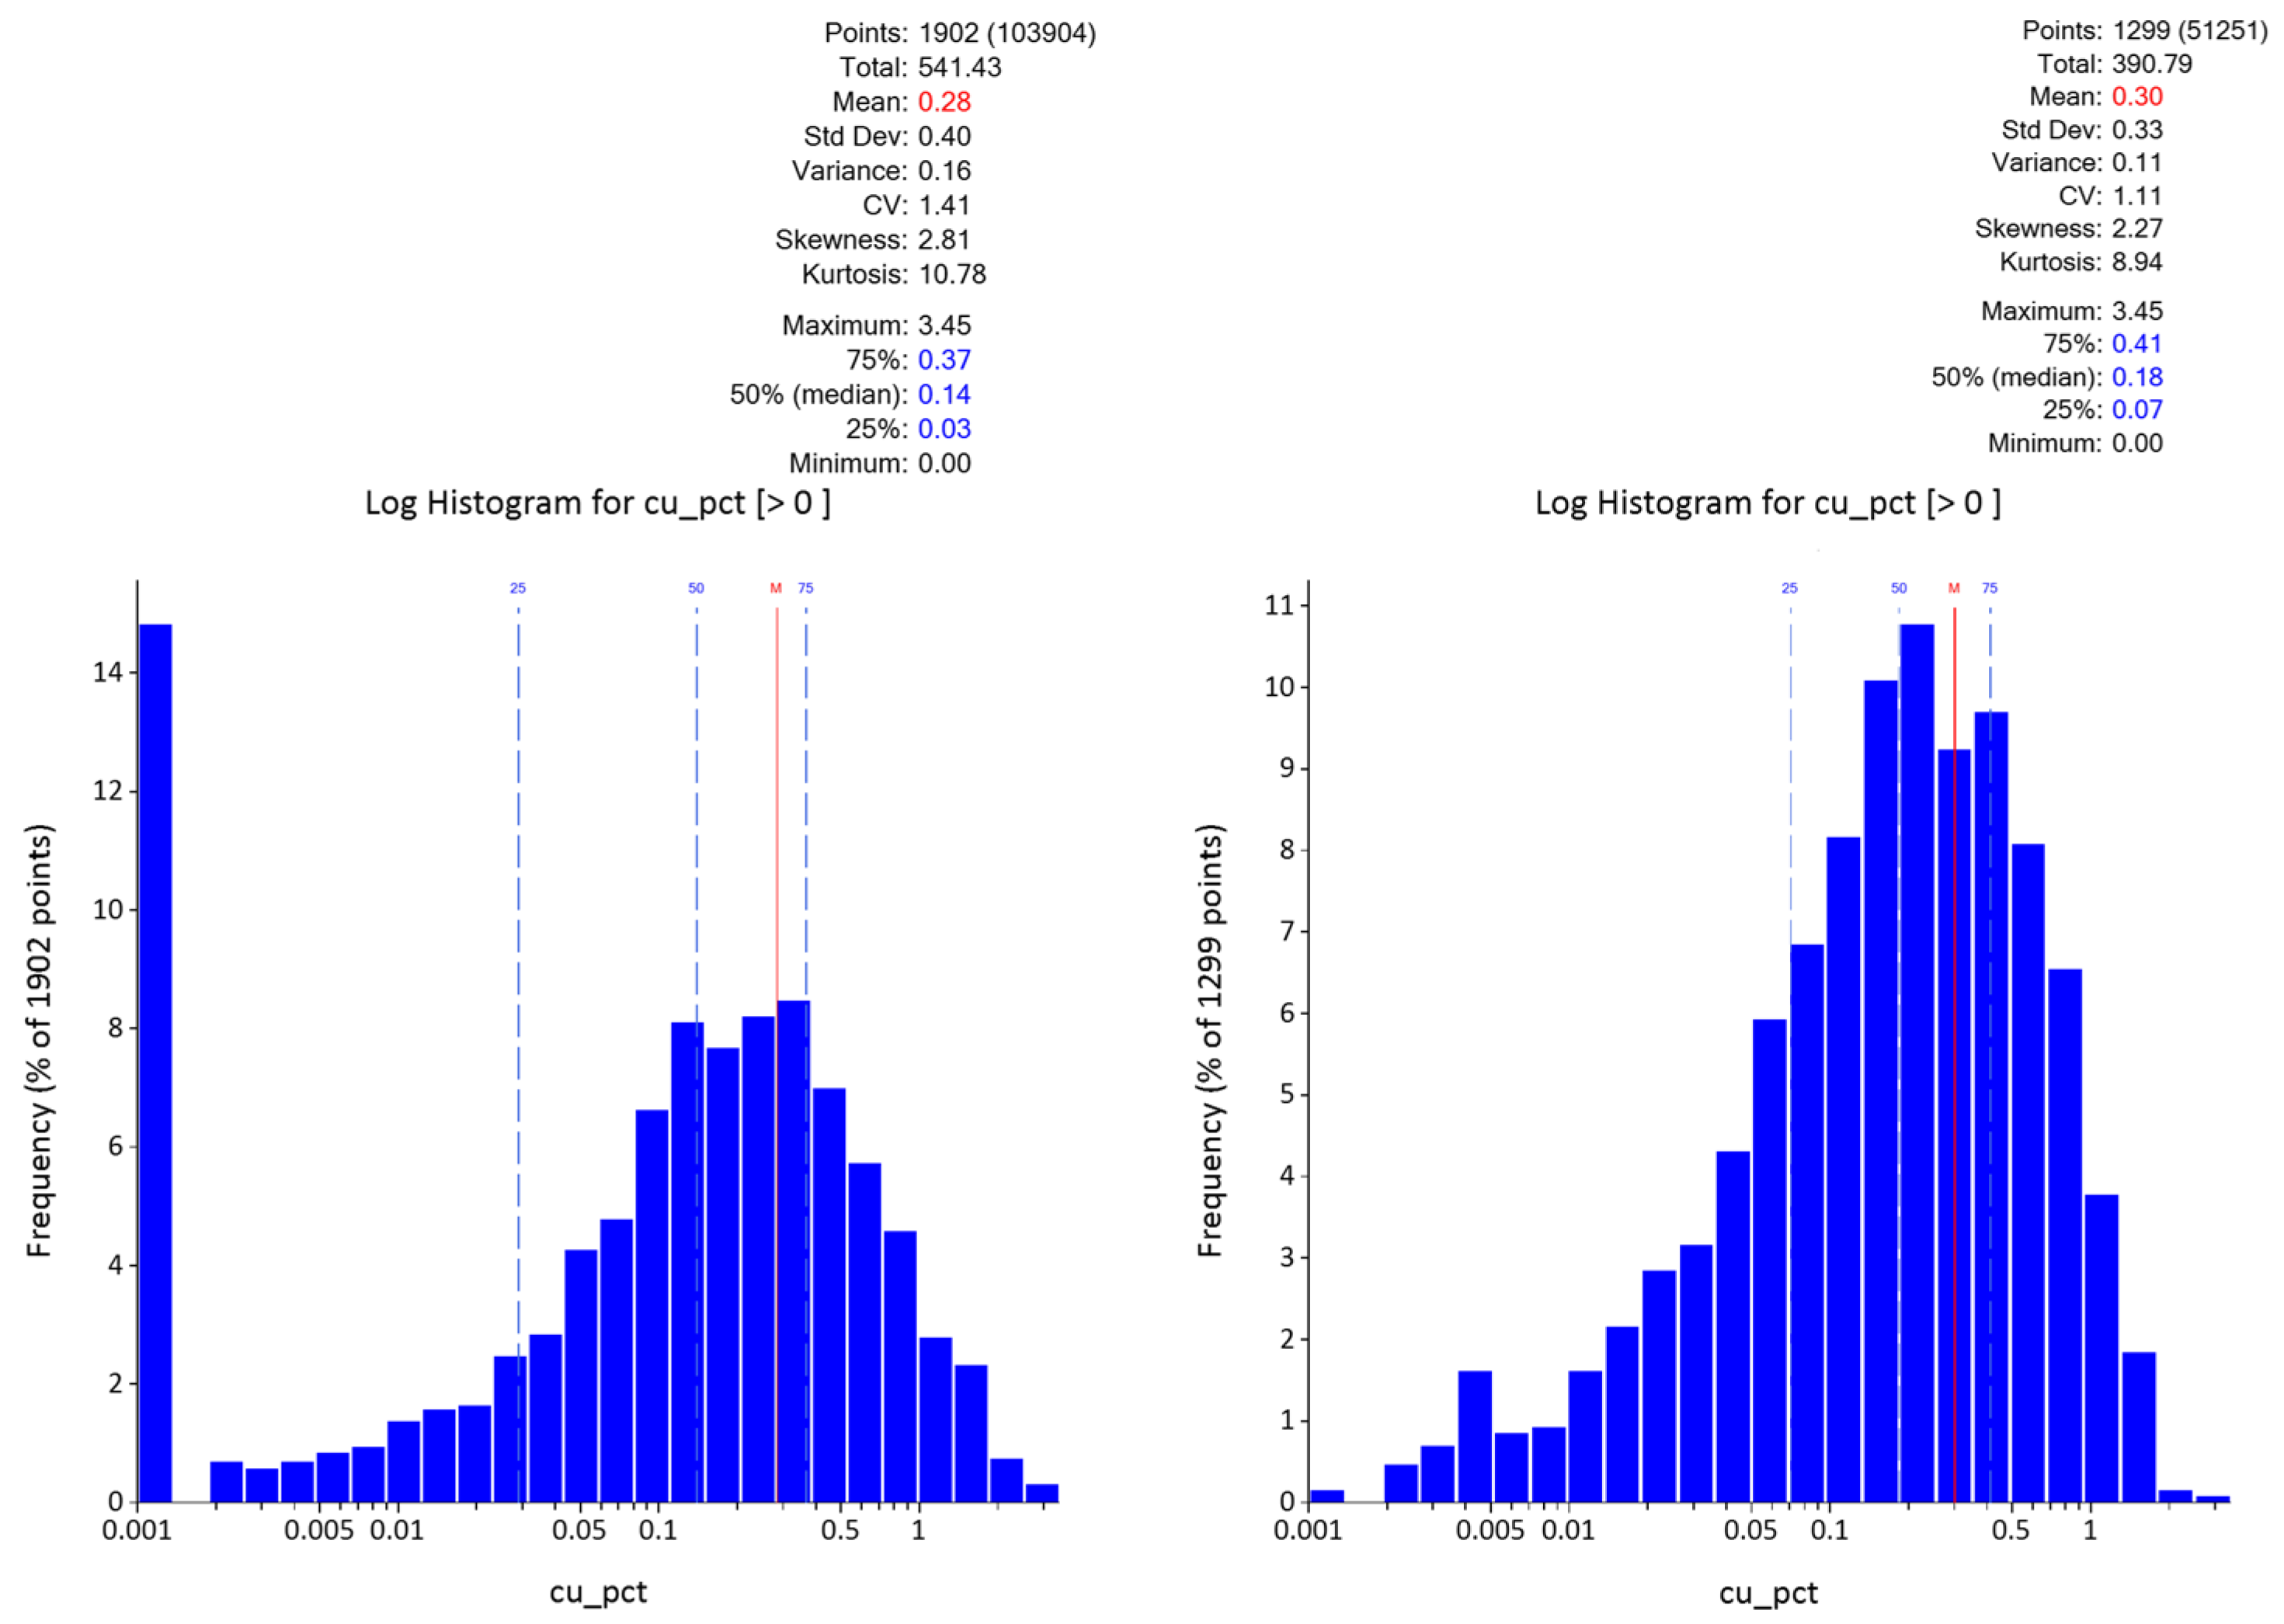
In Figure 13, the impact of data-handling decisions on the statistical distribution of the database can be clearly seen. Core intervals logged as barren lithology were not submitted for assay, reflecting a sampling decision by the geologist that these intervals were waste. On the left-hand histogram, these unassayed intervals are retained and assigned a nominal low grade of 0.001% Cu, consistent with their logged barren character. On the right-hand histogram, the same intervals are excluded from the analysis. Assigning a low value reintroduces these intervals as measured-equivalent data, producing a pronounced spike at the lower tail and shifting the summary statistics relative to the population of assayed samples. On the other hand, excluding the non-assayed intervals preserves the natural distribution of assayed grades. This simple comparison demonstrates how the use of background values, even in uneconomical lithologies, can introduce bias that propagated to subsequent geostatistical modeling and resource estimation. A more rigorous treatment would separate the mineralized sills from the barren host through additional domaining or model the proportion of mineralized material using an indicator approach. Nonetheless, both methods require denser sampling than what is currently available; consequently, the present analysis retains the barren domains as a single population, and the data-handling sensitivity shown in Figure 13 should be read as a characterization of that limitation rather than its resolution.
Figure 13.
Log-normal histograms of data with and without assigned grades in non-sampled intervals inside barren domain.
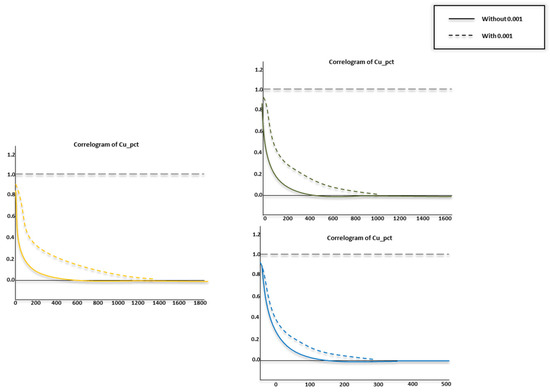
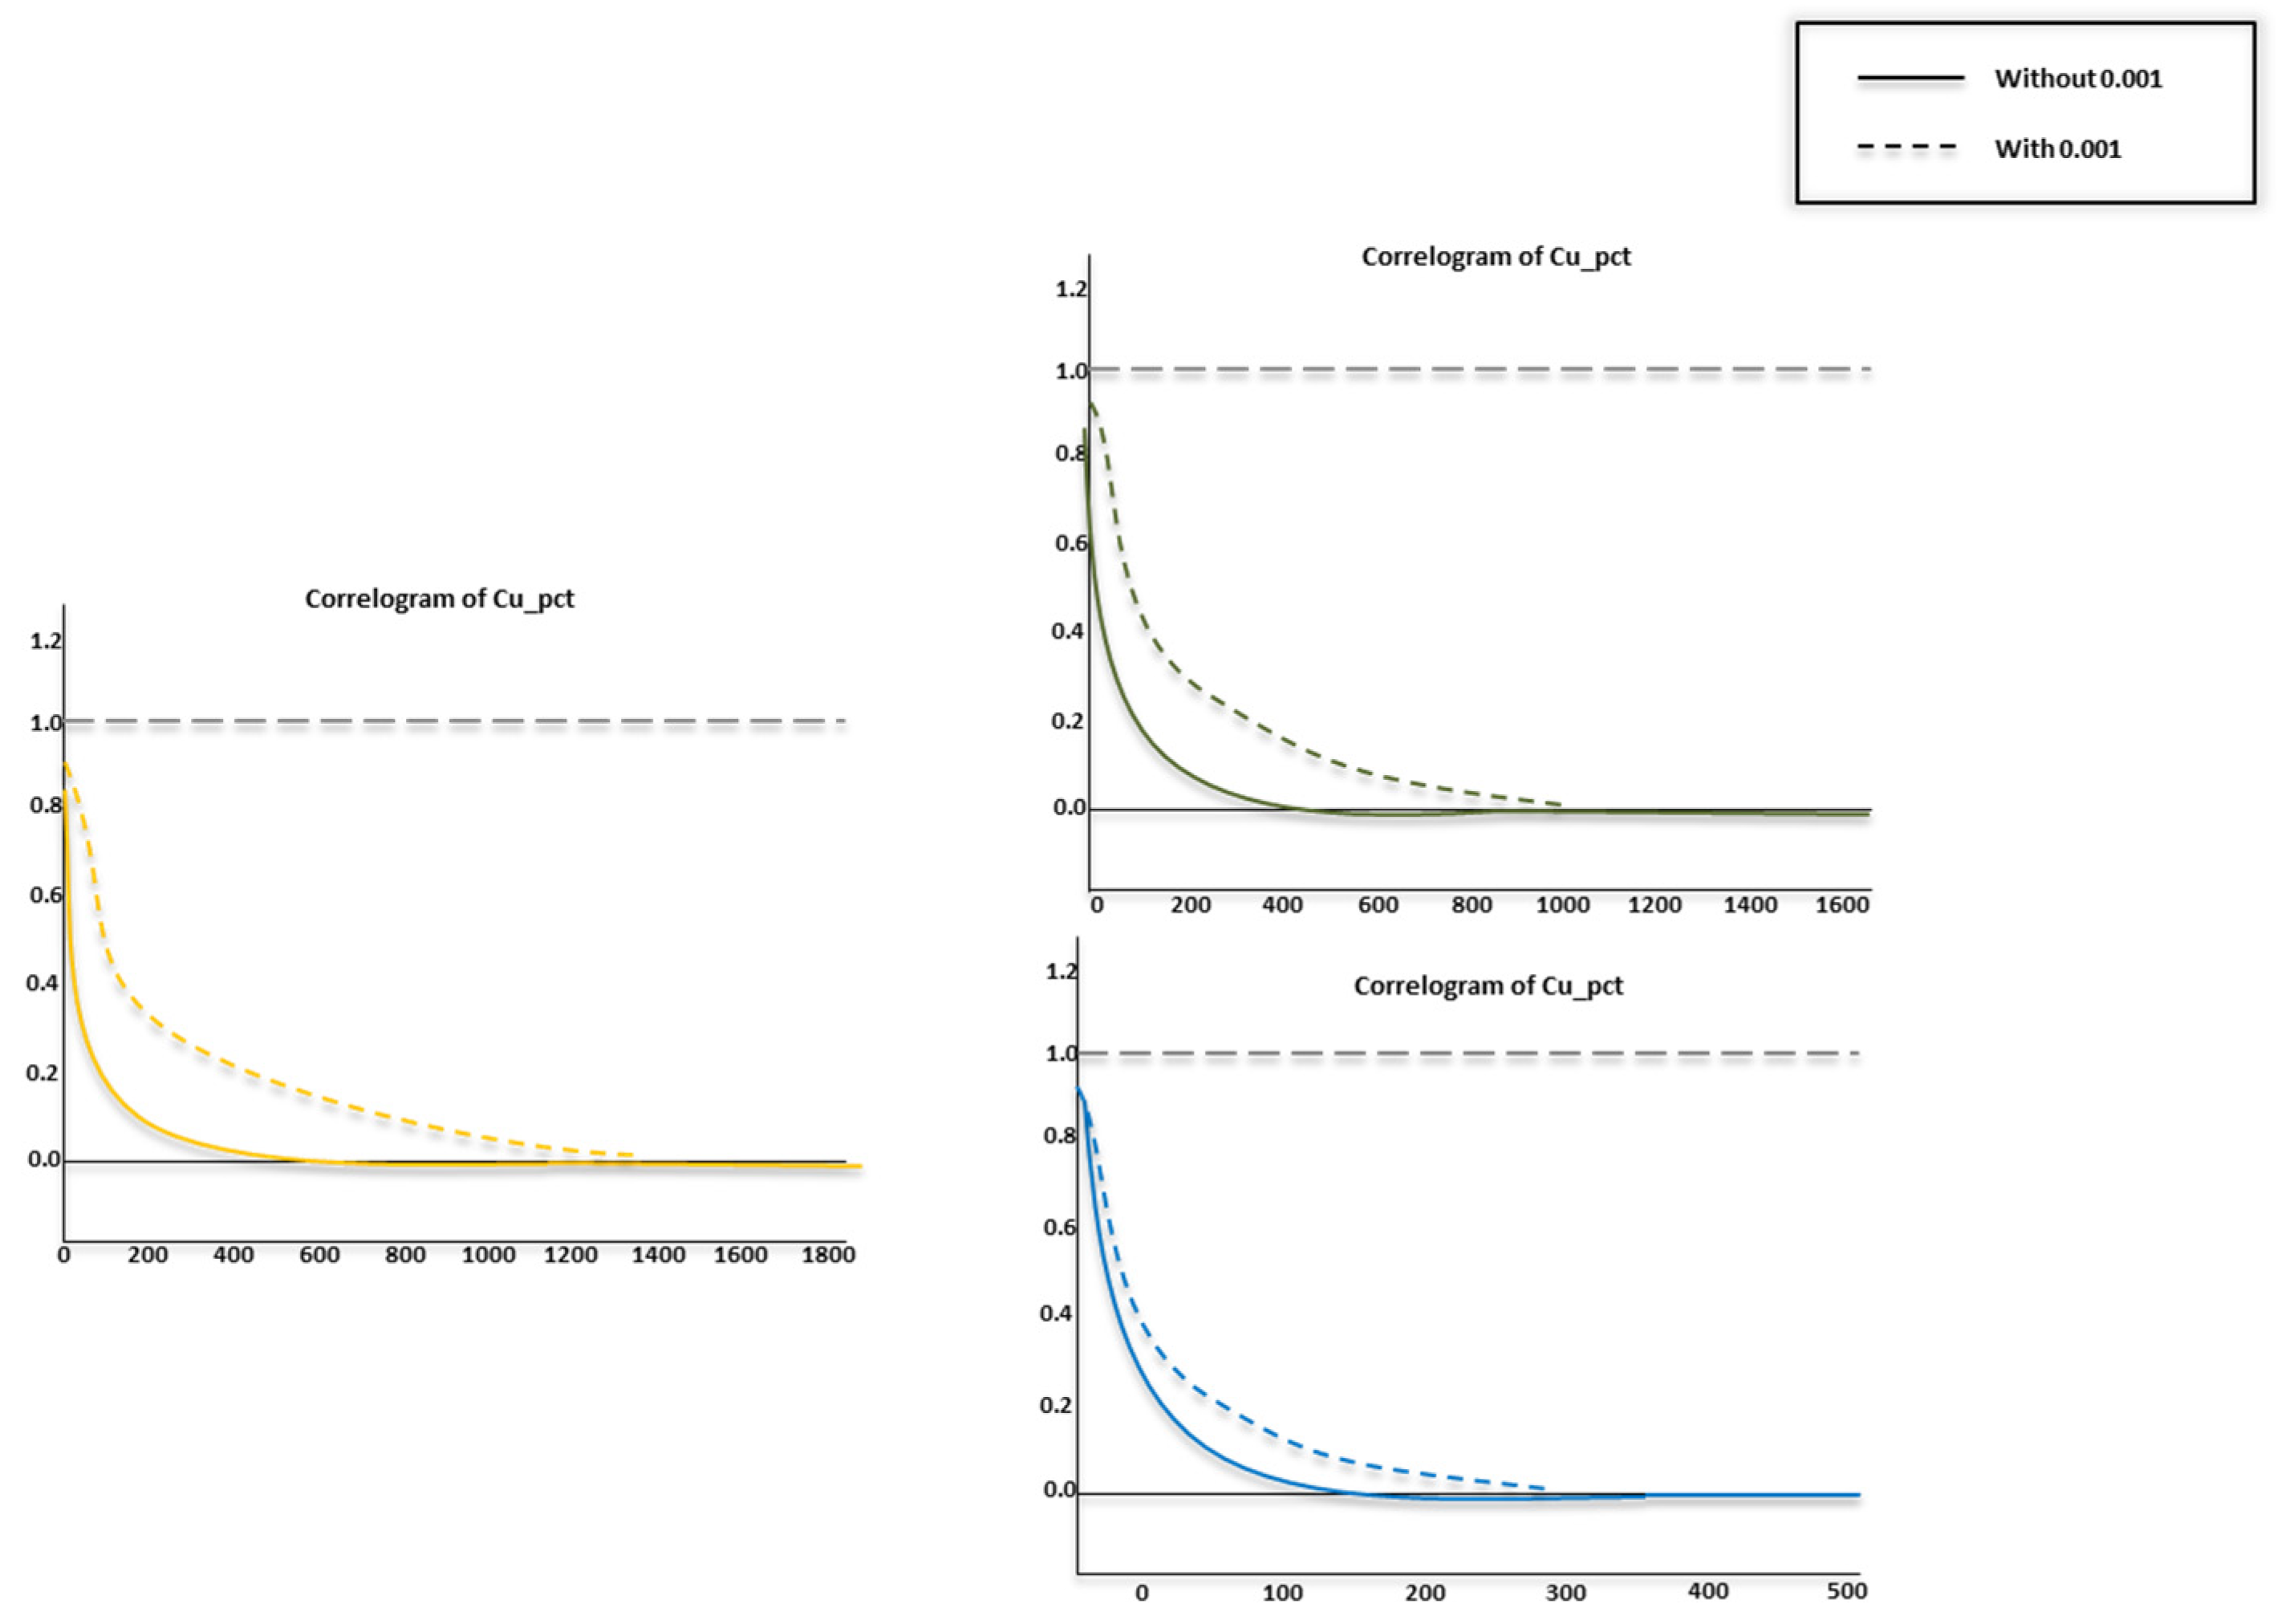
The inclusion of the low-grade values in the database creates an artificial continuity for the grades, as shown in Figure 14.
Figure 14.
Directional correlograms with and without assigned values in non-assayed intervals. Solid lines represent correlograms generated without assigning a value of 0.001 to unassayed intervals, while dashed lines represent correlograms generated with the assigned value. The horizontal gray dashed line at a correlation value of 1.0 indicates the normalized sill.
Figure 14 compares directional correlograms (three directions) generated from the same drillhole dataset using two alternative treatments for non-assayed intervals. It clearly shows the effect of assigning background values on spatial continuity. The correlograms show that the inclusion of these values consistently results in higher continuity, expressed by a lower decay of the correlation relative to the lag. This behavior smooths the estimates artificially, where low-grade values infill gaps and reduce local variability, effectively masking the natural heterogeneity of the deposit. Consequently, what appears to be improved continuity is not a true geological feature but a by-product of imposed assumptions on unmeasured data.
For further analysis, the two sets of copper grade (Cu) are used for estimation using ordinary kriging, with the corresponding variogram model specific to each dataset. In this context, the kriging parameters are not standardized across databases. Low-grade values are manually assigned to intervals interpreted as barren, serving both to reflect expected geological conditions and to constrain the emergence of unrealistically high-grade estimates in areas where mineralization is not anticipated.
The underlying question is therefore whether the explicit assignment of low-grade values to these intervals is the most appropriate approach for controlling grade behavior, or whether a more restrictive kriging strategy, applied to a database from which such intervals are excluded, would achieve the same objective. Table 8 shows the kriging strategy for both cases, labeled as Case 1 (data with assigned low-grade values) and Case 2 (data which exclude non-assayed intervals).
Table 8.
Estimation strategy used on each case considered. Cases consider different strategies due to decisions taken based on the sample database.
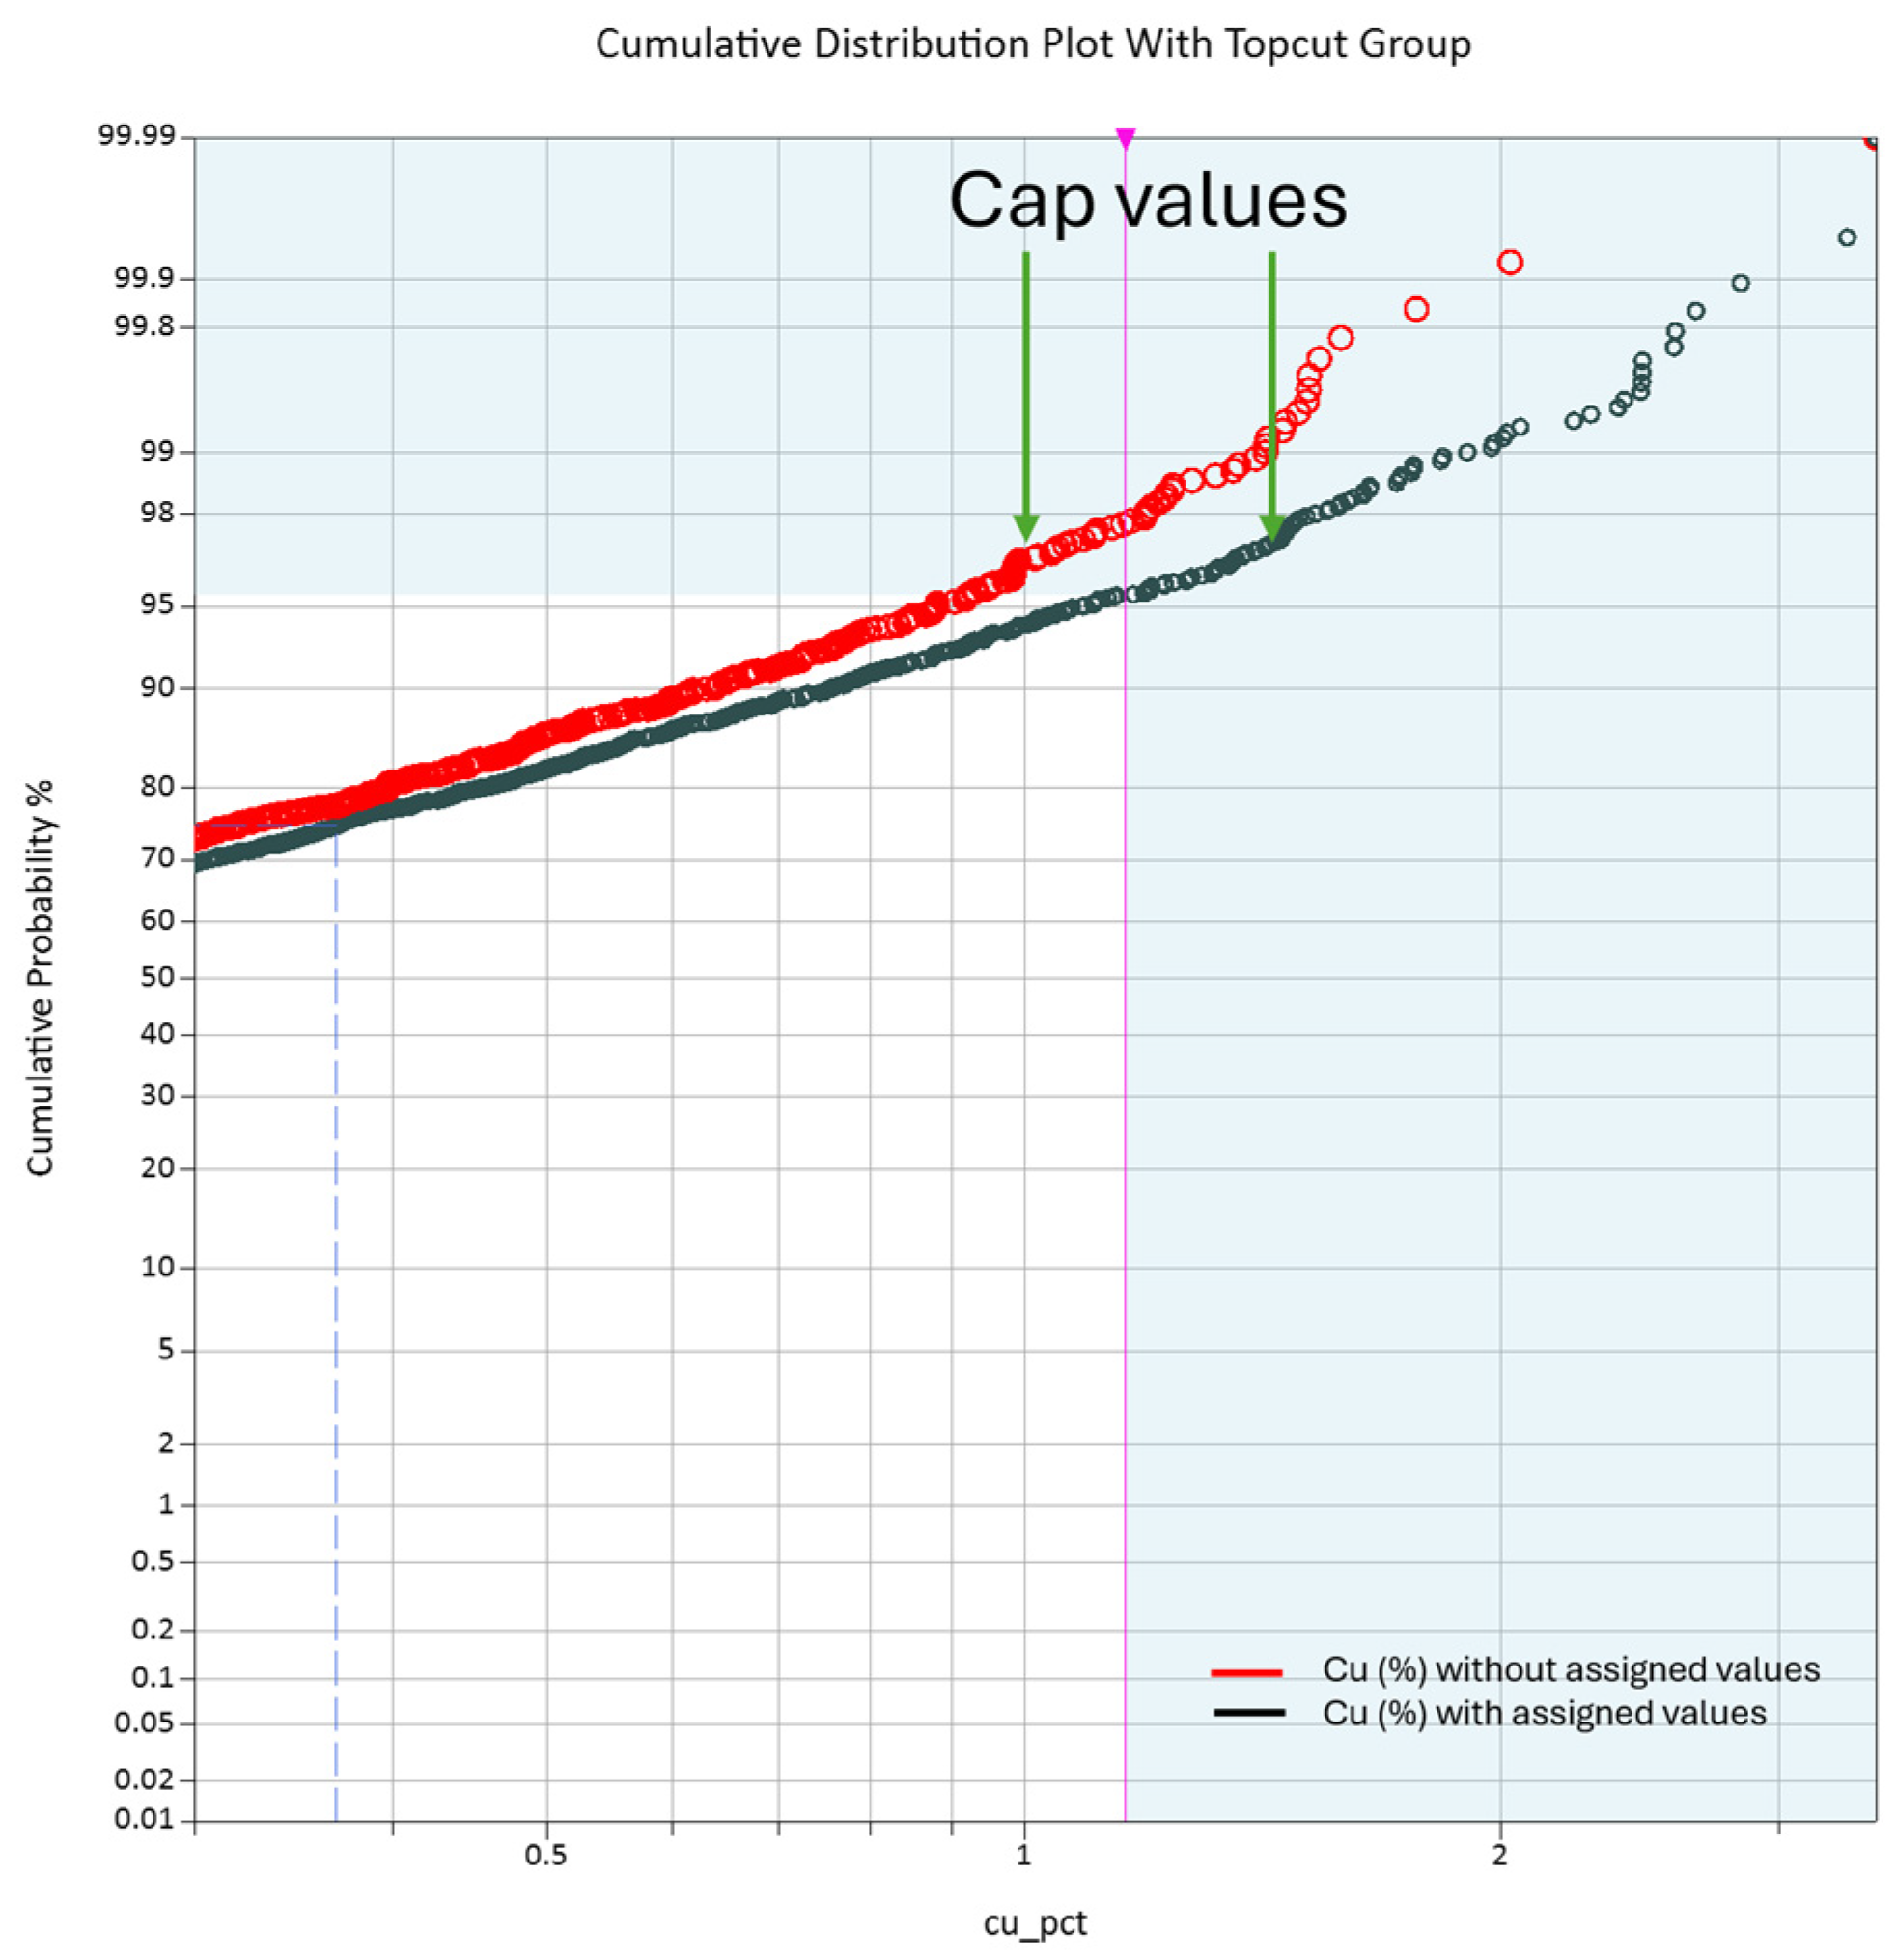
The kriging strategy was chosen based on optimized estimation parameters for each case. For Case 1, we used a capping threshold of 1.55% Cu, consistent with the region identified by the red arrow on the red curve (Figure 15). The strategy adopted in Case 2 was to choose an aggressive cap value to restrict the grade inside the domain, preventing inflating estimates.
Figure 15.
Log-normal probability plots for Case 1 (black curve) and Case 2 (red curve) and chosen cap values in each case.
Therefore, the cap value chosen was 1% Cu, as indicated by the black arrow on the black curve. Combined with the cap, a high yield (HY) search was also applied for samples of 0.8% Cu, allowing one block of influence for those.
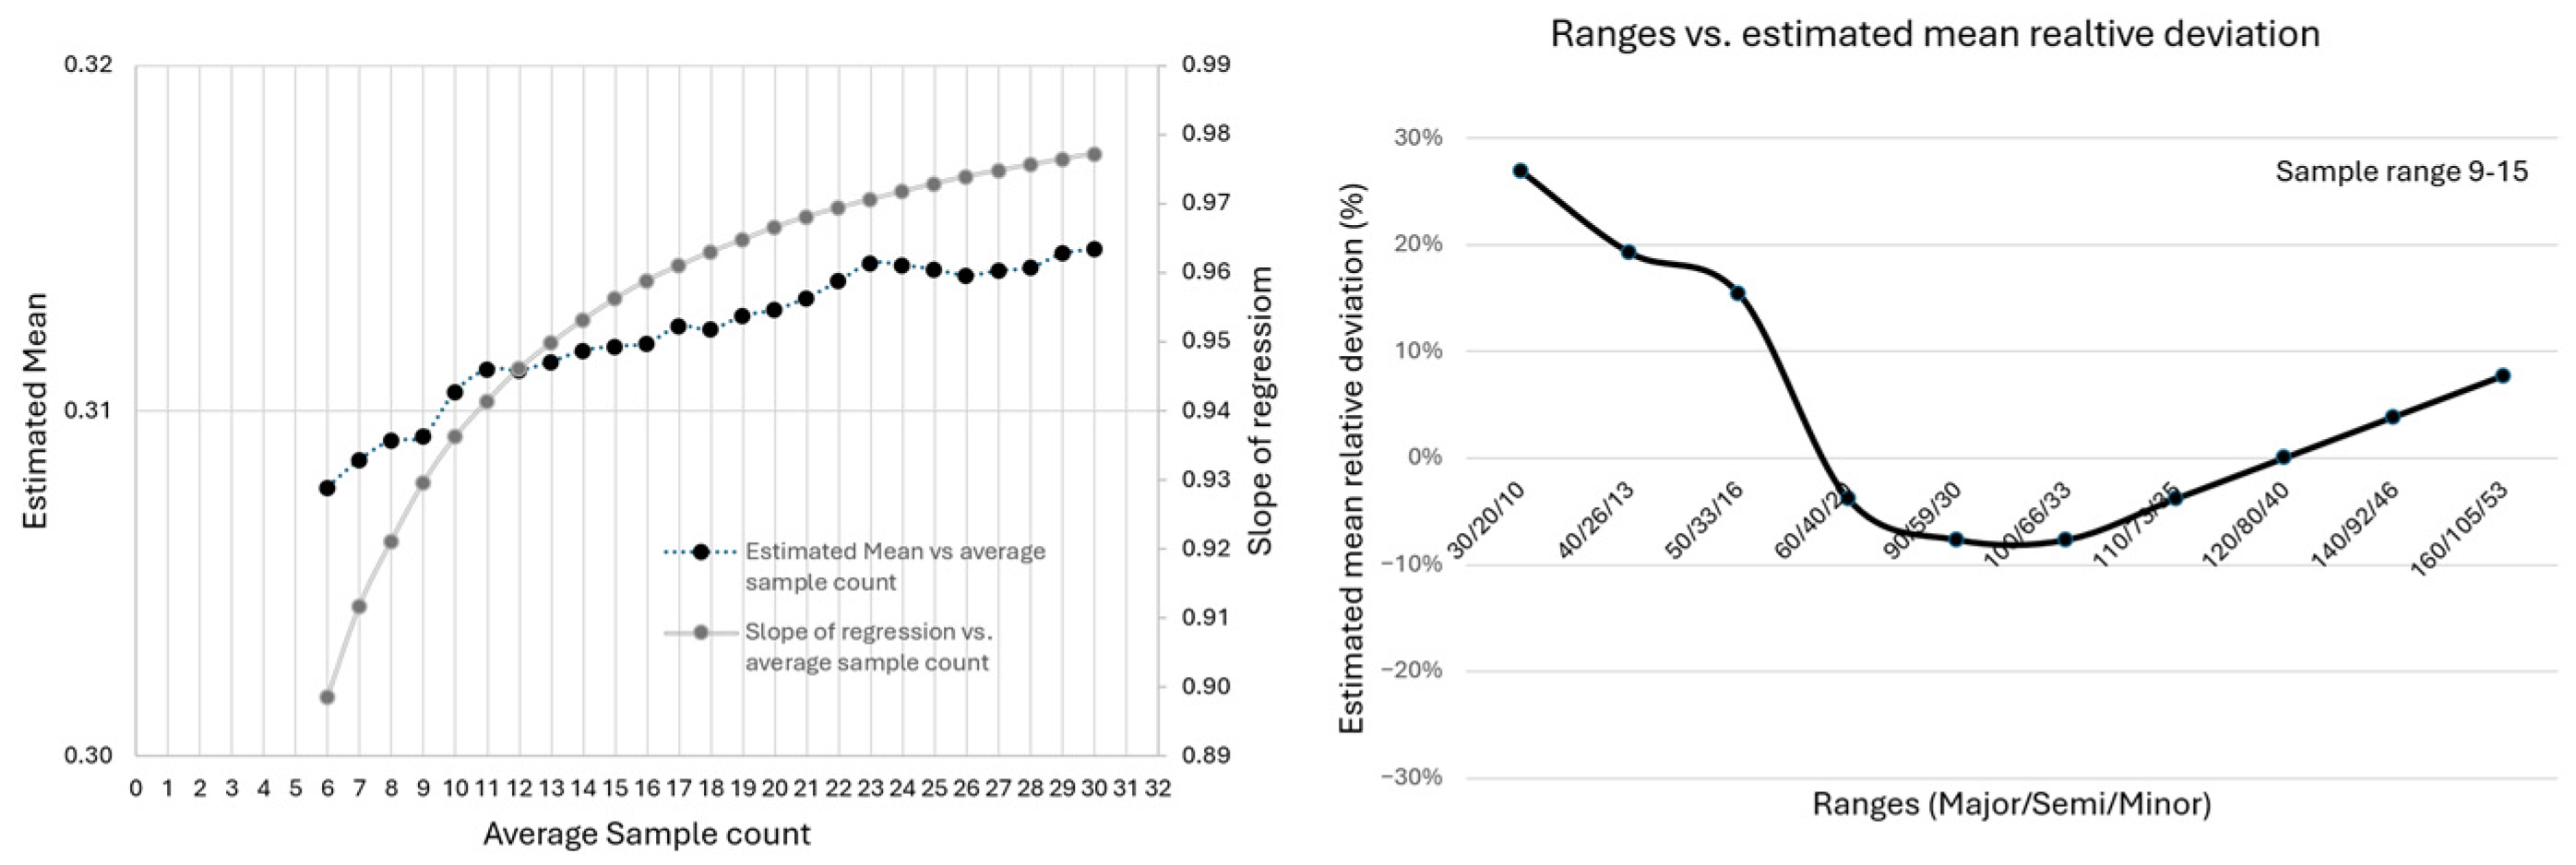
The search neighborhood of a minimum of 9 and maximum of 15 samples was selected through the KNA presented above, following the QKNA framework in [12]. Two sensitivity analyses were performed. First, the number of informing samples varied while monitoring the slope of regression and the reproduction of the mean (Figure 16—left). The slope of regression improved rapidly up to approximately 9–12 samples and then flattened (~0.95–0.97), while the estimated mean stabilized by roughly 12–15 samples. A minimum of 9 samples was therefore chosen to keep the estimate off the high conditional bias portion of the curve, while the maximum of 15 samples was set at the point of diminishing returns, that is, the point beyond which additional samples produce over-smoothing and inflate the global mean without any meaningful reduction in conditional bias. Second, with the sample count fixed at 9–15 samples, the search ranges were varied and the relative deviation from the mean assessed (Figure 16—right). Overly restrictive ranges overstated the mean by +27%, while excessive large ranges reintroduced bias (+8%); with the set sample count of 9–15, the global mean was reproduced at acceptable tolerance across the range of ~60 m/40 m/20 m to ~120 m/80 m/40 m. It should be noted that this analysis optimized the search strategy for Case 2 only. Case 1 was not derived from this KNA sensitivity workflow; rather, it reflects the strategy adopted by the site team and is retained here to represent the approach currently applied in practice. The two cases are therefore presented to illustrate how different data-handling decisions can propagate into the estimation process and outcome.
Figure 16.
KNA optimization. Left—estimated mean and slope of regression versus the average sample count. Right—estimated mean relative deviation obtained over different search ranges with a fixed sample count.
It is acknowledged that the two estimation scenarios evaluated in this case study differ not only in the treatment of unassayed intervals (assigned placeholder values versus retained nulls) but also in associated estimation parameters such as capping strategy, search geometry, and high-yield restrictions. This coupling is intentional and reflects realistic industry practice rather than an isolated variable test. In operational workflows, the removal of placeholder values fundamentally alters the statistical population and support of the dataset, necessitating corresponding adjustments to estimation controls to maintain geostatistical validity. Treating placeholder removal as a standalone change while holding all other parameters constant would misrepresent how practitioners adapt workflows in response to altered data characteristics. Accordingly, the comparison presented here should be interpreted as a workflow-level evaluation, demonstrating how alternative data-handling philosophies propagate through estimation design, model behavior, and resource outcomes under practical conditions.
Added to the different kriging strategy, Case 2 uses post-processing of the unestimated blocks, assigning to blocks the low-grade value of 0.001% Cu. The databases’ declustered means are 0.28% for Case 1 and 0.27% for Case 2. The estimates obtained are 0.21% and 0.23% average grades, respectively. The relative deviation in Case 1 is −25% from the global declustered mean. In Case 2, the relative deviation is −14% from the global declustered mean.
To evaluate the impact that different choices have on how we manage unassayed samples, classification is run for both cases. The classification scheme is kept the same for both variables, given that there is not a necessity for the drill hole to be assayed, so it can be considered in the classification scheme if there is enough confidence in the geology of the drill hole. It should be noted that classification based solely on drillhole spacing or drillhole density is not considered current best practice and is used here only as a simplified analytical framework. Modern resource classification typically incorporates multiple lines of evidence, including but not limited to geological continuity, estimation quality, data quality, sampling confidence, reconciliation, and the reliability of the underlying geological and grade models. Accordingly, the classification results presented in this case study should be interpreted as a comparative measure between the two scenarios rather than as an example of a recommended classification methodology.
For this case study, measured is defined if the average distance between three drill holes is equal or less than 50 m; indicated is defined if the average distance to three drill holes is greater than 50 m and less than 150 m; finally, inferred is defined if the average distance between two holes is less than or equal to 150 m. Computing resources within the area considered has led to the following.
It is acknowledged that the differences shown in Table 9 are not attributable solely to the assignment of low-grade values in non-assayed intervals. Therefore, to isolate the individual contributions of the two decisions, the analysis was restructured into a two-step factorial in which the treatment of unassayed intervals (Case 1, assigned low-grade placeholders; Case 2, intervals retained as null) and the estimation plan (Strategy 1, the site-team approach—1.55% cap, 180 m isotropic search, no high-yield restriction; Strategy 2, the KNA-derived plan—1.0% cap, 0.8% high-yield restriction, and a 60 m/40 m/20 m anisotropic search) were varied independently. The Case 1–Strategy 1 combination, which reflects the strategy currently adopted in practice rather than one derived from the KNA sensitivity workflow, is retained as the baseline against which all deltas are measured. In Step 1, the effect of data handling under a fixed estimation plan is captured by the Case 1 to Case 2 comparison under Strategy 1, which alone reduces Class 1 (higher confidence) contained copper by approximately 71% and Class 2 by approximately 97%. In Step 2, the effect of the estimation plan under fixed data is captured by the Strategy 1 to Strategy 2 comparison, which reduces Class 1 contained copper by approximately 88% and effectively eliminates Class 2 (−100%). Both decisions therefore act as first-order controls on the reported estimate, and the estimation plan emerges as the stronger single driver of the Class 1 reduction, consistent with the aggressive cap and high-yield restriction constraining the outliers that had inflated the placeholder-data model. Crucially, the two effects are not additive. When both changes are applied together (Case 2/Strategy 2), the Class 1 reduction is only ~44%, a smaller loss than either factor produces in isolation, which reveals a strong antagonistic interaction between data treatment and estimation parameters. This interaction demonstrates that the two decisions cannot be decoupled into independent, summable contributions; the estimation parameters are not selected independently of the data treatment but are the practical response to it, and their combined effect is governed by how outlier management, capping, search geometry, and high-yield restrictions interact with the presence or absence of placeholder intervals.
Table 9.
Results of Case 1 and Case 2 estimation comparison, treating the approach applied in practice (Case 1) as the base case.
In this context, the case study should be interpreted as a workflow-level comparison rather than a controlled sensitivity test of imputation alone. The assignment of low-grade values was intended to constrain grade estimates in areas interpreted as barren, but it did not eliminate the influence of isolated high-grade assays. Instead, it created an apparent impression of conservatism while retaining uncertainty about the true grade distribution in unassayed intervals.
This creates an important asymmetry in the data. High-grade values are only observed where assays were collected, whereas intervals interpreted as barren may remain untested. Therefore, the absence of assays cannot be treated as equivalent to the absence of grade. Where reconciliation later identifies grade in material previously interpreted as waste, this suggests that the geological or sampling assumption may not fully represent the mined reality. Under these conditions, assigning detection-limit values may create artificial continuity and apparent confidence without resolving the underlying uncertainty.
Therefore, where database contains unassayed intervals interpreted as barren, the following practices are recommended to avoid the biases illustrated above: (1) Unassayed intervals should not be treated as equivalent to detection limit values. Intervals are retained and treated as null, while the decision is made explicit and auditable, rather than embedding the barrenness assumption into the model. (2) The data-handling and estimation decisions should be isolated before drawing conclusions. Isolating the effects of each assumption, as demonstrated by the two-step exercise presented herein, allows each impact to be quantified independently so that outcomes are not attributed to the wrong cause. (3) Resolving the intermingled ore within the barren lithology through indicator approaches is more robust than assigning low-grade to unassayed intervals, as it represents the true grade distribution more adequately. (4) Dinally, all assumptions should be validated against reconciliation data, and the geological and sampling assumptions should be revisited when production identifies conflicting outcomes.
The main conclusion is therefore not that assigned low-grade values alone caused the observed outcome but that using assigned values as a control for unassayed intervals can propagate through variography, outlier management, estimation strategy, and classification. If not explicitly tested and communicated, this workflow can create a misleading perception of conservatism and confidence in domains where the true grade behavior remains uncertain.
3. Conclusions
This study demonstrates that bias in mineral resource databases is rarely introduced at a single point and is seldom detectable through conventional validation metrics alone. Instead, bias commonly emerges from a sequence of technically reasonable decisions that interact across data extraction, geological interpretation, statistical treatment, and estimation workflows, allowing uncertainty to propagate in non-linear and often obscured ways.
The first case study shows that operator-dependent data extraction can generate materially different geological models and statistical populations, even when global volumetric reconciliation suggests negligible change. Local-scale lithological inconsistencies, introduced during extraction, are shown to destabilize domains and violate geostatistical assumptions, leading to significant differences in grade, tonnage, and contained metal. These results confirm that volumetric agreement alone is insufficient to validate model equivalence and that local statistical and spatial diagnostics are essential.
The second case study highlights how legacy data practices can become a hidden source of uncertainty as economic conditions evolve. Analytical behavior near detection limits was shown to be consistent with expected laboratory performance rather than systematic bias. The primary risk arises from misinterpretation: when low-grade material becomes economically relevant, relative error near detection limits may be misconstrued as poor data quality or reconciliation failure. Explicit recognition and communication of low-grade analytical uncertainty are therefore critical to avoiding over-interpretation of model outputs.
The third case study demonstrates that assigning values at or near detection limits to unassayed or barren intervals can distort grade distributions, impose unrealistic continuity, and bias estimation results. Contrary to common assumptions, such substitutions do not reduce risk but instead generate spurious mineralization in geologically barren areas. Retaining null values and applying restrictive geologically informed estimation controls produce outcomes consistent with geological expectations. The treatment of null values should be deliberate, documented, and clearly communicated throughout the value chain.
Collectively, these case studies reveal a unifying theme: upstream data-handling decisions exert a disproportionate influence on downstream estimation outcomes. Once embedded within geological and statistical frameworks, biases are difficult to detect and correct. Robust data governance, transparent and reproducible extraction workflows, and integrated geological, statistical, and estimation validation are therefore essential to maintain confidence in mineral resource models and the decisions they support.
Author Contributions
K.C. led the analysis and interpretation of Case Study 1. C.W. led the analysis and interpretation of Case Study 2. C.d.S. led the analysis and interpretation of Case Study 3. All authors contributed to study concept and design, methodology development, interpretation of results, manuscript preparation, review, and editing. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The datasets used in the current study are derived from proprietary operational data and are not publicly available due to commercial confidentiality restrictions.
Conflicts of Interest
The authors declare that the research was conducted in the absence of any commercial or financial relationship that could be constructed as a potential conflict of interest. The views expressed are those of the authors and do not necessarily reflect those of their employer(s) or client(s). This paper is intended solely for research and educational purposes and should not be relied upon for investment, valuation, or operational decisions. All datasets have been anonymized, scaled, or modified to prevent identification of any specific project, company, or operation. No confidential or propriety datasets are disclosed. This document does not constitute a Mineral Resource or Mineral Reserve disclosure as defined by NI 43-101, JORC, or other CRIRSCO-aligned reporting standards. All estimates are illustrative and prepared solely for methodological comparison.
References
- Bovim, A.B.; Morton, K.L. Advanced monitoring of tailings storage facilities and dams to prevent failure: Illustrated with case studies from UK, Africa and South America. In Proceedings of the IMWA 2023—Y Dyfodol|The Future: Proceedings of the International Mine Water Association Conference, Newport, UK, 17–21 July 2023; Stanley, P., Wolkersdorfer, C., Wolkersdorfer, K., Eds.; International Mine Water Association: Wendelstein, Germany, 2023; pp. 69–76. [Google Scholar]
- Matamala Pizarro, J.; Aguayo Fuenzalida, F. Mental health in mine workers: A literature review. Ind. Health 2021, 59, 343–370. [Google Scholar] [CrossRef] [Scilit]
- Qi, J.; Wang, P.; Feng, X.; Ma, C.; Su, X. Data standards–based mine-side data integration governance platform: Research and applications. EAI Endorsed Trans. Scalable Inf. Syst. 2024, 11, 1–11. [Google Scholar] [CrossRef] [Scilit]
- Yacopetti, M.; Mundell, S. Improving the quality of geoscientific information. In Proceedings of the Bowen Basin Symposium 2010—“Back in the Black”; Geological Society of Australia, Coal Geology Group and Bowen Basin Geologists Group: Mackay, Australia, 2010; pp. 97–100. [Google Scholar]
- Ortiz, J.M.; Emery, X. Geostatistical estimation of mineral resources with soft geological boundaries: A comparative study. J. S. Afr. Inst. Min. Metall. 2006, 106, 577–584. [Google Scholar]
- Tolmay, L. On the reduction of algorithmic smoothing of kriged estimates. J. S. Afr. Inst. Min. Metall. 2014, 114, 667–673. [Google Scholar]
- Isaaks, E.H.; Srivastava, R.M. An Introduction to Applied Geostatistics; Oxford University Press: Oxford, UK, 1989. [Google Scholar]
- Myers, D.E. To be or not to be … stationary? Math. Geol. 1989, 21, 347–362. [Google Scholar] [CrossRef] [Scilit]
- ALS Global. Quality Control (QC) Limits Fact Sheet (Rev. 2.0); Unpublished technical document; ALS Global: Brisbane, Australia, 2025. [Google Scholar]
- Ordoñez, J.A.; Bandyopadhyay, D.; Lachos, V.H.; Cabral, C.R.B. Geostatistical estimation and prediction for censored responses. Spat. Stat. 2017, 23, 109–123. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Helsel, D.R. Fabricating data: How substituting values for nondetects can ruin results, and what can be done about it. Chemosphere 2006, 65, 2434–2439. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Vann, J.; Jackson, S.; Bertoli, O. Quantitative Kriging Neighbourhood Analysis for the Mining Geologist—A Description of the method with worked case examples. In Proceedings of the 5th International Mining Geology Conference, The Australian Institute of Mining and Metallurgy, Bendigo, Australia, 17–19 November 2003; The Australasian Institute of Mining and Metallurgy: Carlton, Australia, 2003. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.