


Abstract
Integrating heterogeneous and multilingual geoscience texts into coherent knowledge graphs is challenged by semantic inconsistencies from terminology variations, diverse expressions, and data heterogeneity, hindering the construction of reliable mineral exploration knowledge systems. We propose a semantic-aware fusion framework that enables consistent and sustainable integration of mineral exploration knowledge. Built on a standardized geological knowledge schema defining core entities and their interrelations, the framework incorporates an incremental update paradigm via a schema-guided fusion mechanism that detects and resolves semantic conflicts while preserving provenance for traceable evolution. Evaluated on textual sources, the framework achieves an overall triple extraction F1-score of 0.82. Notably, for the critical task of entity extraction, it attains an F1-score of 0.88, outperforming BERT-BiLSTM and BERT-BiLSTM-CRF baselines by up to 11 points. Precision for key metallogenic elements exceeds 0.90. It identifies 1432 conflicts during fusion and generates a refined knowledge graph of 18,204 high-quality de-duplicated triples, retaining 87.3% of inputs. The resulting graph supports downstream applications, including case analysis, visualization, question answering, and mineral prospectivity prediction. Unlike conventional aggregation approaches, this work treats knowledge fusion as a semantically guided dynamic process, enhancing consistency, transparency, and adaptability. It provides a practical pathway toward intelligent and sustainable geoscience knowledge infrastructures.
1. Introduction
The ongoing transition of the global energy structure is profoundly reshaping the global resource supply–demand landscape, with critical minerals such as copper, lithium, cobalt, and rare earth elements becoming strategic resources underpinning low-carbon energy technologies and advanced manufacturing [1,2]. Coping with increasingly deep-seated and concealed exploration targets, as well as complex and dynamic geological environments, traditional experience-driven mineral exploration paradigms are rapidly shifting toward data- and knowledge-driven intelligent approaches [3,4,5]. In this context, systematic organization and intelligent reasoning of geoscience knowledge have become central to enhancing the accuracy of mineral prospectivity prediction and the efficiency of resource assessment.
As a key enabler for knowledge organization and reasoning, geological knowledge graphs have demonstrated significant potential in domains including mineral prediction, geological entity recognition, and mineral system modeling [6,7,8,9]. Their core strength lies in the ability to integrate disparate data sources and perform relational reasoning, an approach that is proving critical for understanding complex systems across the geosciences [10,11]. However, existing studies predominantly rely on static construction paradigms and are heavily dependent on structured databases and English-language corpora, making them ill-suited for the dynamic integration of heterogeneous, multi-source, and continuously evolving exploration data [12,13]. Particularly when processing unstructured texts (e.g., exploration reports, regional geological memoirs) and cross-lingual literature, challenges such as semantic ambiguity, terminological inconsistency, and insufficient accuracy in automated information extraction severely constrain the scalability and practical applicability of knowledge systems [14,15].
A central challenge in current construction approaches lies in balancing semantic accuracy and computational efficiency [16,17]. This challenge stems from a fundamental trade-off: manual annotation delivers high semantic fidelity but suffers from high costs and poor scalability, whereas automated extraction offers high throughput yet is prone to errors induced by contextual complexity, leading to frequent knowledge noise and logical conflicts. Therefore, achieving efficient knowledge fusion while preserving semantic consistency—that is, ensuring all integrated facts remain logically coherent—has become a critical bottleneck in building dynamic geological knowledge infrastructures. Furthermore, a large volume of regionally produced exploration literature rich in critical mineralization information remains isolated from the global knowledge ecosystem due to linguistic and representational disparities. This leads to fragmented knowledge and underutilized local expertise, highlighting the urgent need for cross-lingual knowledge integration.
To address these challenges, this study proposes a novel Semantic-Aware Fusion Framework designed to enable dynamic integration of multi-source and multilingual mineral exploration knowledge while preserving semantic consistency. The framework is built upon a standardized geological knowledge schema that defines key entity types and semantic relations in petrogenetic and metallogenic processes, providing structured guidance for corpus construction and knowledge extraction. A core innovation of our approach lies in the synergistic integration of context-aware language modeling, cross-lingual terminology alignment, and knowledge conflict detection mechanisms. This integration supports the construction of high-quality, evolving geological knowledge graphs from unstructured texts and, more importantly, empowers mineralization association reasoning and intelligent target identification. Consequently, this work presents a novel methodological pathway for overcoming knowledge fragmentation and linguistic barriers in geoscience, paving the way for more intelligent and integrative mineral systems analysis.
2. Data and Methods
2.1. Data Sources and Knowledge Stream Collection
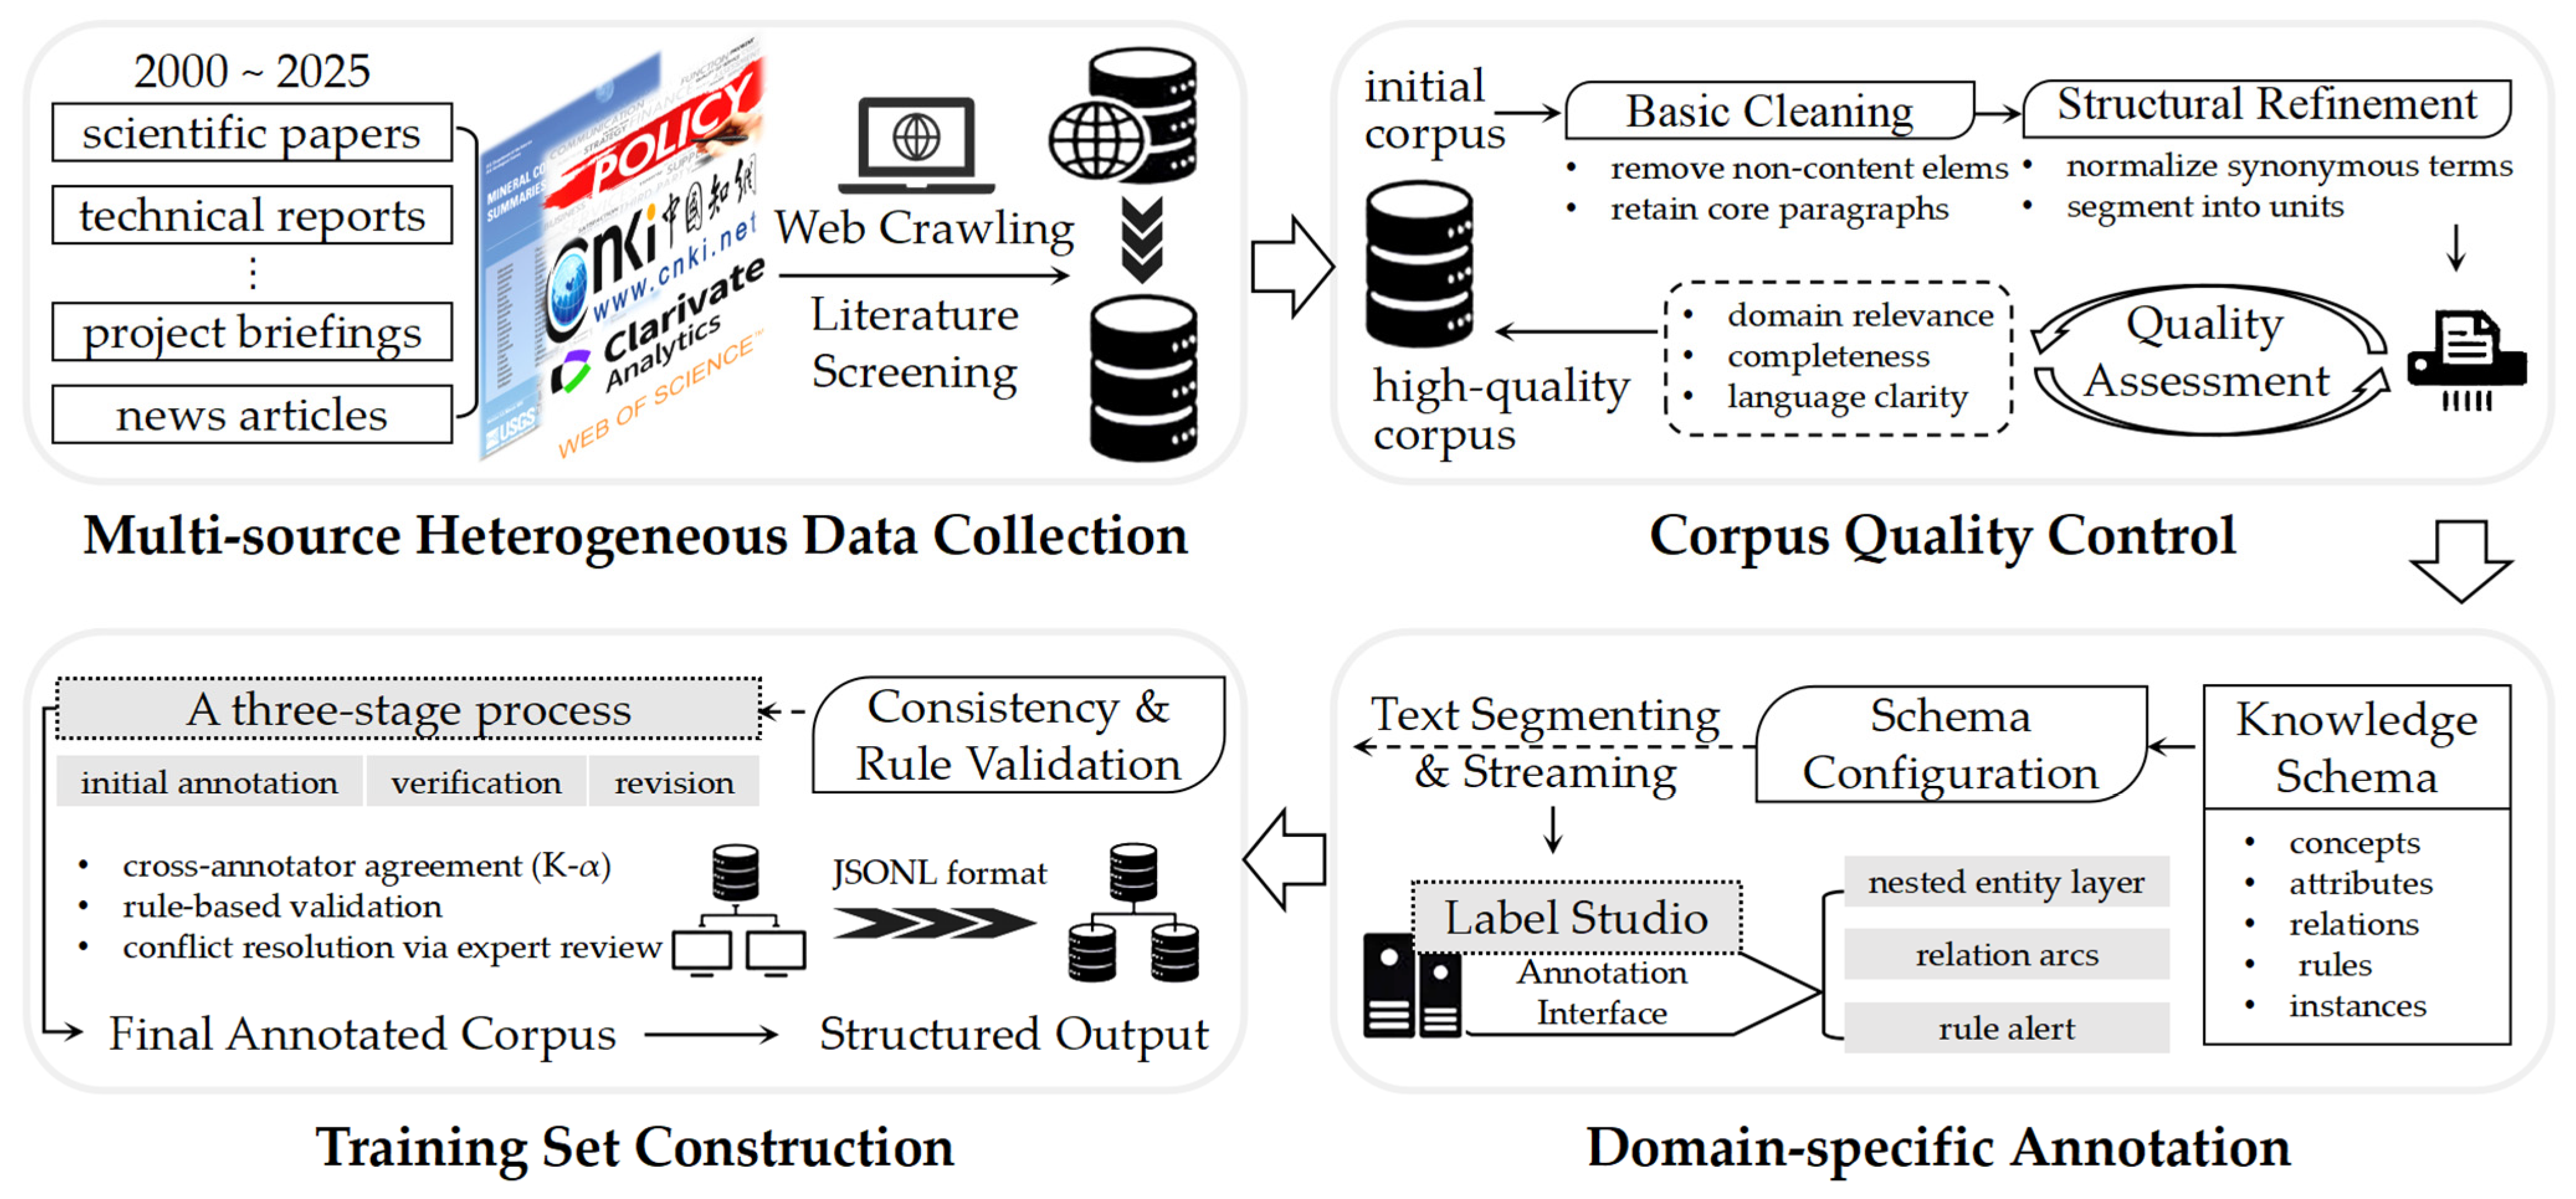
This section outlines the construction of a structured, annotated training dataset tailored for the mineral exploration domain. The process was designed to transform raw, multi-source, and often unstructured geological data into a high-quality, machine-readable corpus suitable for training downstream knowledge extraction models. It encompasses four key stages: data collection, corpus quality control, domain-specific annotation, and training set construction. The overall workflow is illustrated in Figure 1.
Figure 1.
The data-to-knowledge transformation workflow in mineral exploration.
2.1.1. Multi-Source Heterogeneous Data Collection and Corpus Quality Control
Geological knowledge in mineral exploration practice is widely distributed across unstructured texts such as scientific papers, technical reports, industry policies, project briefings, and news articles, exhibiting high dispersion and continuous evolution. This study focuses on openly accessible or authorized multi-source textual resources, systematically collecting Chinese and English literature and industry updates published between 2000 and 2025 to construct an initial corpus of approximately 1.8 million characters, providing data support for geological knowledge extraction and integration.
The raw texts contain substantial non-content elements (e.g., headers, footers, figure captions, references), along with challenges such as terminological variation and broad descriptive scope. To enhance semantic consistency and processing efficiency, basic cleaning and structural refinement were performed: irrelevant segments were removed, retaining only core paragraphs containing descriptions of geological entities; synonymous terms (e.g., “porphyry Cu-Mo deposit” and “Cu-Mo porphyry deposit”) were manually normalized; and long reports were segmented into semantically independent text fragments based on geological units (e.g., deposits, intrusive bodies, stratigraphic layers) to ensure each fragment focuses on a single thematic unit.
After processing, the original 1.8 million-character text was compressed into a high-quality corpus of approximately 1.2 million. This refined dataset exhibits strong semantic coherence and clear thematic focus and was used in subsequent knowledge annotation and extraction tasks.
2.1.2. Domain-Specific Annotation and Training Set Construction
To enable structured geological knowledge extraction, this study integrates metallogenic theory and textual expression patterns in mineral exploration to design a domain-specific knowledge schema incorporating geological entities and semantic relations. Formally, the schema is defined as a structured type with five components [18]:
where C, A, R, and I denote the sets of geological concept types (e.g., Mineral Deposit, Intrusive Body, Alteration Type), attribute types (e.g., Metallogenic Age, Ore Grade, Geotectonic Location), relation types (e.g., Located in, Genetically related to, Coexists with), and instance identifiers, respectively; P(∙) represents the power set (i.e., a collection of sets); the attribute mapping C→P(A) specifies which attributes are defined for each concept; Φ is a set of first-order logical rules that formalize domain constraints derived from metallogenic theory and expert guidelines (e.g., “an Orebody must be hosted within a specific Geological Unit”); and instances are concrete realizations of concepts grounded in text.
This schema guides the annotation practice and supports the construction of a labeled corpus for model training and evaluation. The classification framework of this knowledge schema is detailed in Table 1. Appendix A provides the complete entries of the schema, including term definitions, value types, and representative examples, and its classification system and semantic structure are designed to systematically capture the implicit geological reasoning logic embedded in the text.
Table 1.
Core components of the geological knowledge schema.
Annotation was implemented on the Label Studio platform, with nested entity tags and relation arcs configured to enable joint annotation of multiple entities and relations within complex sentence structures. Based on the quality-controlled corpus, semantic fragments were annotated sentence-by-sentence. A three-stage process (initial annotation, verification, and revision) was employed, combined with cross-validation to resolve annotation conflicts and ensure semantic consistency and process reproducibility. Finally, the annotated data were exported in a structured format (e.g., JSONL) and served as the data foundation for model training and evaluation.
2.2. Schema-Guided Knowledge Extraction
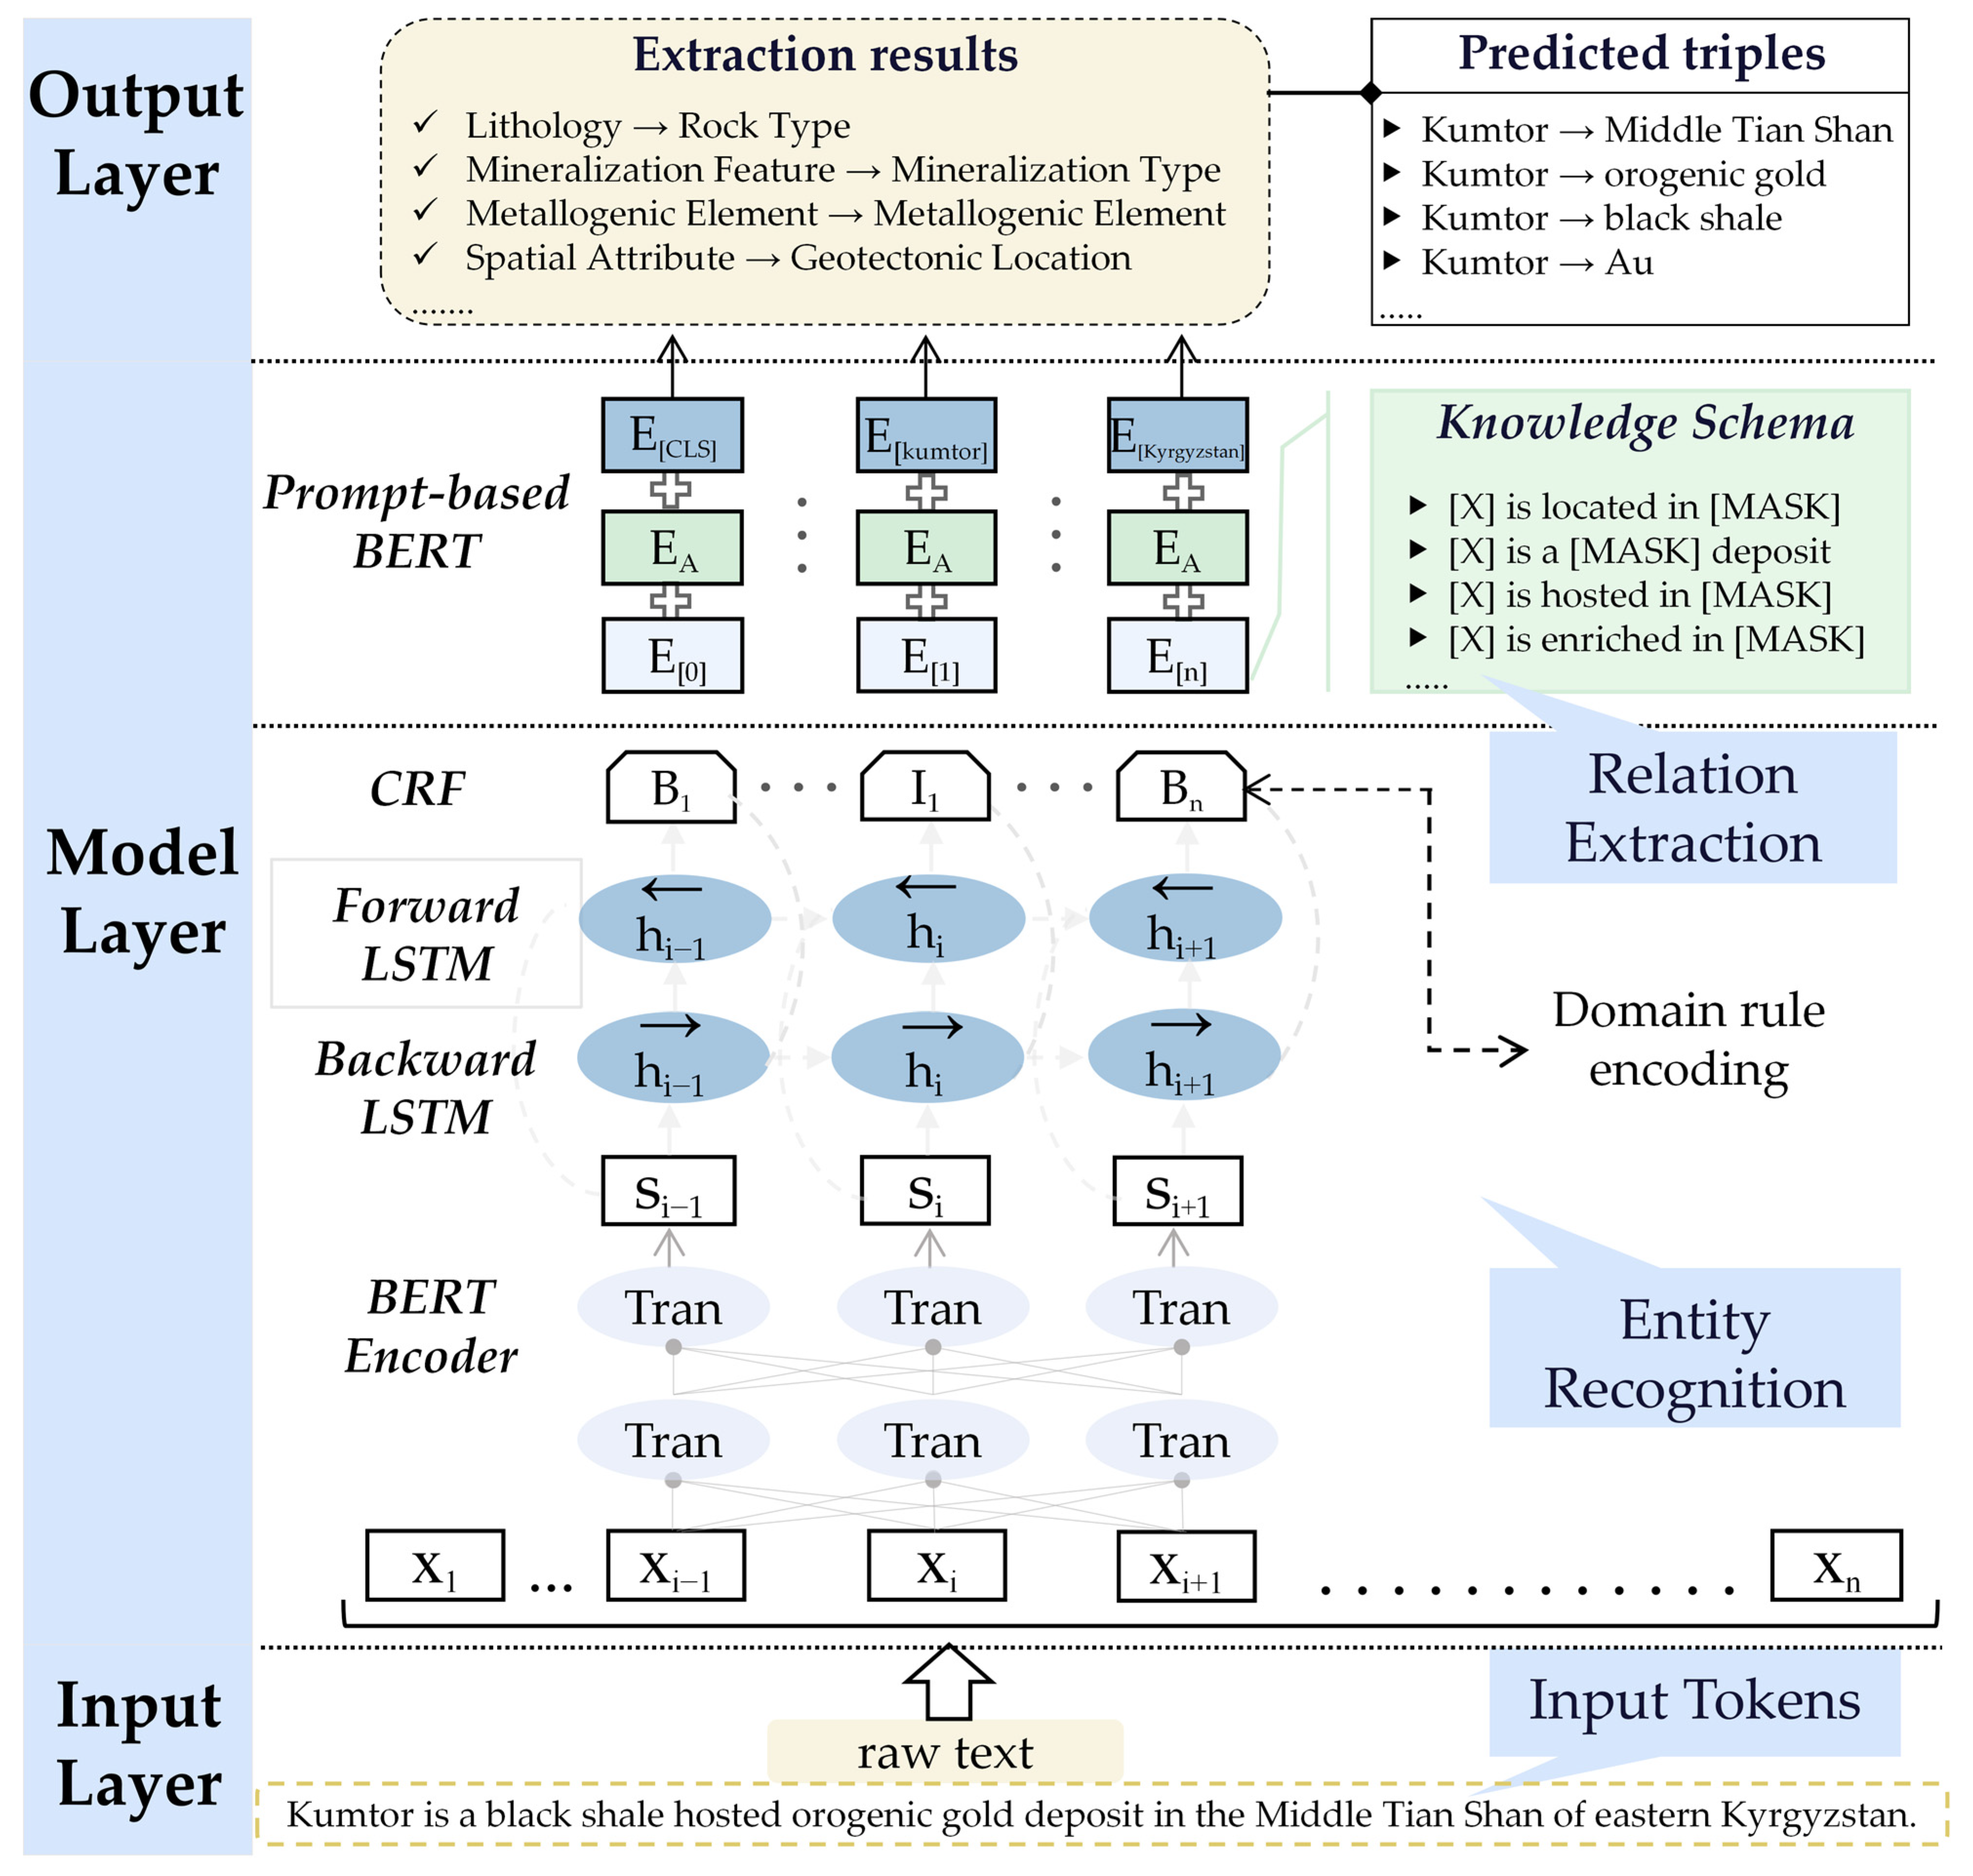
To automatically extract structured knowledge from annotated geological texts, we adopt a two-stage framework under the GeoKE (Schema-guided Geological Knowledge-aware Extraction) paradigm. This paradigm emphasizes the integration of domain knowledge from the geological schema S into the extraction process, ensuring that the output adheres to predefined semantic and structural constraints.
In the first stage, named entity recognition is performed using a sequence labeling approach based on contextualized representations. Specifically, BERT is employed to encode input tokens into contextual embeddings, which are then processed by a BiLSTM layer to model long-range dependencies in the text [19,20,21,22]. Finally, a CRF layer decodes the optimal label sequence [23,24]. To align the predictions with domain knowledge, we enhance the CRF layer with transition constraints derived from S. These constraints restrict invalid label transitions by penalizing sequences that violate the type compatibility and sequential rules defined in the schema. The constrained CRF variant is used in all main experiments, while the standard CRF (without schema-based constraints) serves as the baseline for ablation analysis.
In the second stage, relation and attribute extraction is performed using a prompt-based BERT model. Predefined relation and attribute types in S are mapped to semantically aligned prompt templates, for example, “[X] is located in [MASK]”, “[X] exhibits [MASK] alteration”, or “[X] is a [MASK]-type deposit”. A representative subset of these templates is provided in Table 2. During inference, the model predicts the most likely token for the [MASK] position, with the candidate space constrained to valid values specified in S (see Table A1). This design ensures that extracted assertions are not only contextually grounded but also conform to domain-specific semantic constraints.
Table 2.
Representative prompt templates and schema-based constraints.
The overall extraction framework is illustrated in Figure 2. It outputs confidence-scored knowledge triples in the form of (e1, r, e2) or (e, a, v), where e1 and e2 denote entities, r a binary relation, and (e, a, v) an attribute value assignment. All extracted elements are formally typed according to S, enabling seamless integration into downstream modules such as the semantic-aware fusion component.
Figure 2.
The GeoKE framework for schema-guided knowledge extraction from geological texts.
By anchoring both entity recognition and relational prediction to a theory-informed schema, the GeoKE framework transcends surface-level text mining: it operationalizes established metallogenic principles as executable constraints, thereby aligning automated extraction with expert geological reasoning.
2.3. Dynamic Semantic-Aware Fusion of Heterogeneous Knowledge Sources
To integrate knowledge from diverse sources, including scientific literature, technical reports, and regional surveys, we design a semantic-aware fusion mechanism that leverages the geological knowledge schema S as a unified semantic backbone. This ensures that the fused knowledge graph remains both comprehensive and semantically coherent. The process involves two key phases:
- (1)
- Translating heterogeneous knowledge into S-aligned triples.
- (2)
- Dynamically detecting and resolving conflicts based on semantic consistency.
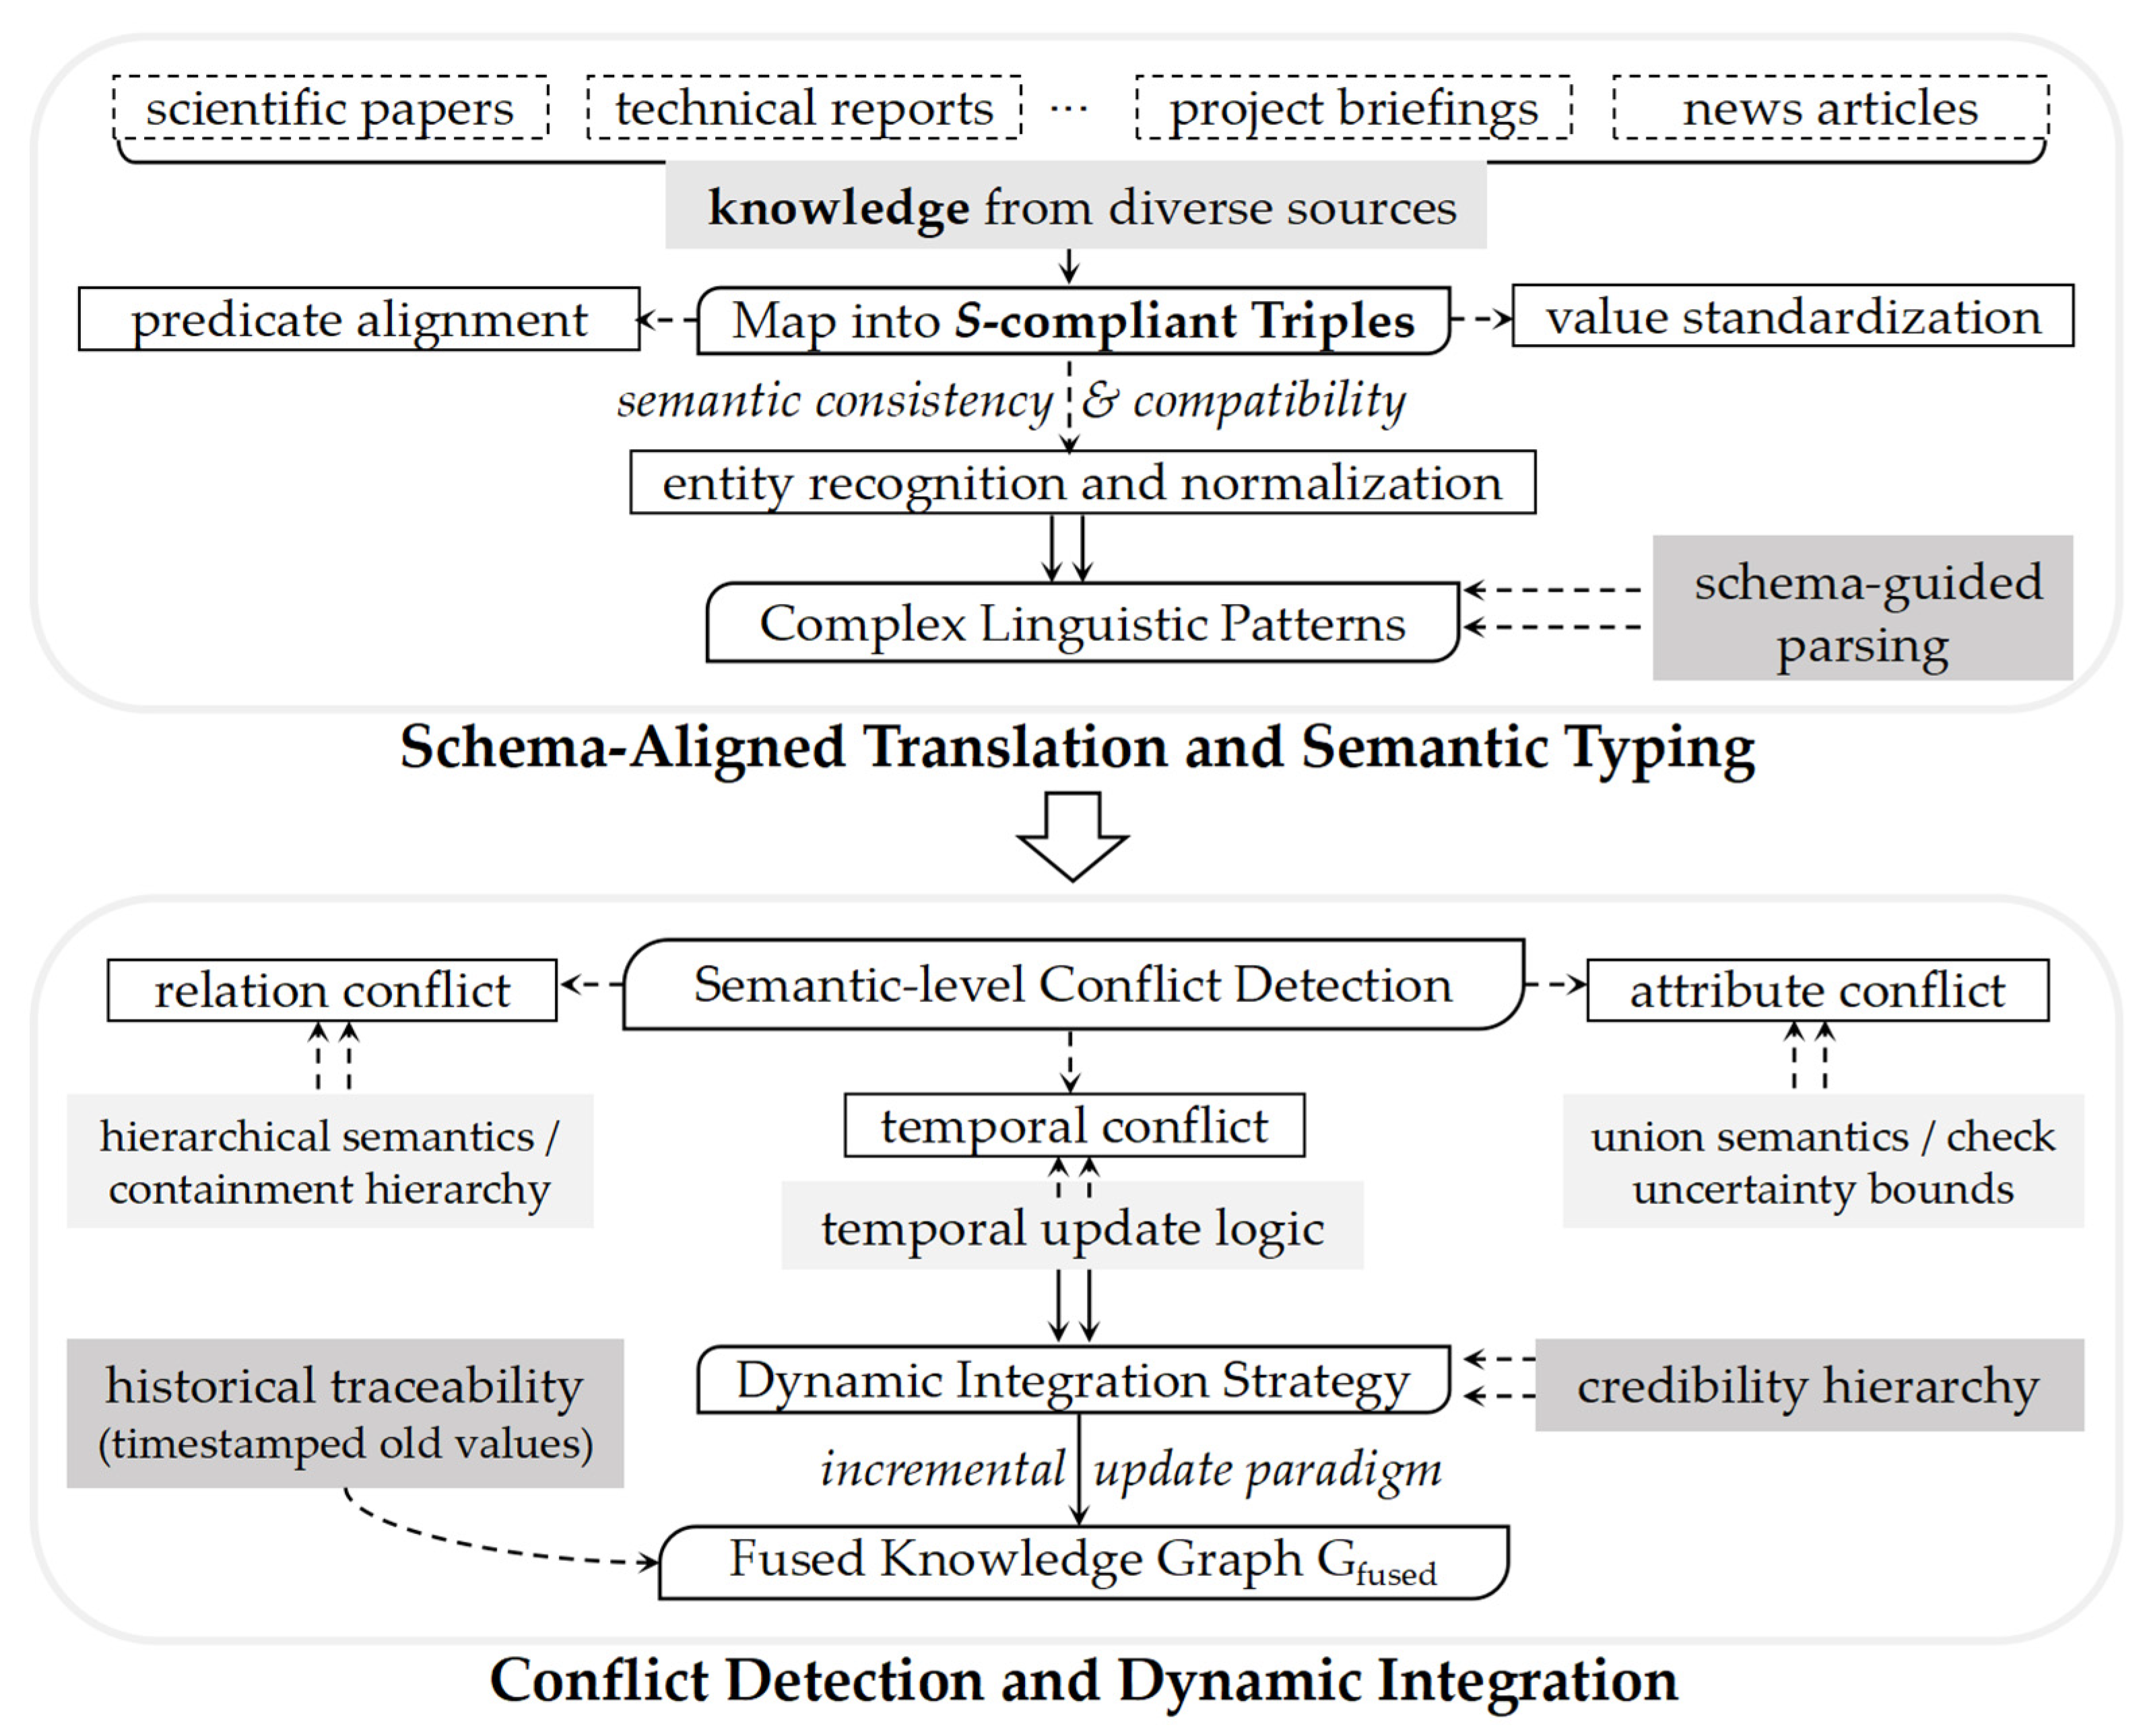
Figure 3 illustrates the overall workflow of this fusion mechanism, highlighting the two-phase process and the role of S in maintaining semantic consistency across heterogeneous inputs. The fusion process is designed to be dynamic: new knowledge can be incrementally integrated without reprocessing existing data, enabling continuous evolution of the knowledge graph.
Figure 3.
Overview of the semantic-aware fusion mechanism.
2.3.1. Schema-Aligned Translation and Semantic Typing
The translation phase systematically maps knowledge from diverse sources into S-compliant triples, ensuring that all extracted information conforms to the formal semantic types defined in the geological knowledge schema. This process involves three critical steps: entity recognition and normalization, predicate alignment, and value standardization.
Entity recognition identifies geological entities (e.g., deposits, rocks, regions) from unstructured text and normalizes them into canonical forms defined in S. For example, “Central Uzbekistan” and “Uzbekistan, central region” are unified into a single geographic entity, while “quartz monzonite” and “adamellite” are recognized as equivalent rock types under the Rock Type category. This normalization ensures consistent representation of semantically identical entities across all sources.
Predicate alignment maps natural language expressions to formal relation and attribute types in S, constraining outputs to the predefined set of relations (R1–R5) and attributes (A1–A16). For instance, phrases such as “is located in,” “occurs in,” and “situated within” are uniformly mapped to the “Located in” relation (R1), while “hosted in,” “developed within,” and “found in” align with the “Developed in” relation (R2). Similarly, “genetically linked to” or “related to” an intrusion maps to “Genetically related to” relation (R3). This schema-guided approach ensures semantic consistency and compatibility with downstream fusion tasks.
Value standardization enforces consistency by validating and normalizing attribute values against the predefined value spaces in S. For quantitative attributes, unit conversion and range validation are applied (e.g., converting “10 Moz” to a standardized numeric value with unit “Moz”); for categorical attributes, values are constrained to the schema’s controlled vocabulary (e.g., Primary Host Rock accepts only standard lithological terms such as “granite” or “sedimentary rock”). This step prevents the introduction of inconsistent or invalid data.
Complex linguistic patterns are resolved through schema-guided parsing. For example, the sentence:
“The Zarmitan gold deposit is located in central Uzbekistan and resources exceed 10 Moz of gold, mainly distributed in narrow, high-grade quartz veins in granites and partially in sedimentary rocks intruded by the granites.”
It is decomposed into the following S-compliant atomic triples (entities without quotes, attribute values in double quotes):
- (Zarmitan, Located in, Central Uzbekistan);
- (Zarmitan, Resource Estimate, “10 Moz Au”);
- (Zarmitan, Metallogenic Element, “Au”);
- (Zarmitan, Primary Host Rock, “granite”);
- (Zarmitan, Associated Host Rock, “sedimentary rock”);
- (Zarmitan, Mineralization Type, “quartz vein”);
- (Zarmitan, Developed in, Granite).
This systematic decomposition ensures that rich geological descriptions are transformed into structured, machine-readable knowledge without loss of critical semantic content while fully adhering to the constraints of S.
2.3.2. Conflict Detection and Dynamic Integration
For experimental evaluation, we simulated dynamic knowledge graph evolution by integrating source triples in sequential temporal batches rather than as a single aggregate. This setup allows us to assess how the system handles incoming information over time. After schema-aligned knowledge translation, triples from heterogeneous geological sources often introduce semantic inconsistencies or redundancies—particularly when new batches contain assertions that contradict or duplicate existing knowledge. To address this, the dynamic integration phase incrementally detects and resolves such conflicts as each batch arrives, ensuring the coherence and credibility of the evolving graph. Unlike traditional fusion methods that operate at the surface level, our approach performs conflict resolution at the semantic level, guided by the formal structure and hierarchical semantics of S.
Semantic-level conflict detection operates by evaluating the consistency of S-compliant triples. For a given entity e, let R(e) denote the set of relations associated with e, and A(e) the set of its attributes. A relational conflict is detected when:
where Ti and Tj are triple sets from different sources, and v1 ≠ v2 indicates semantic non-equivalence. For example, if one source states (Kumtor, Located in, Tien Shan) and another states (Kumtor, Located in, Kyrgyz Range), a location conflict is flagged—unless these terms are semantically related.
∃r ∈ R(e), such that (e, r, v1) ∈ Ti, (e, r, v2) ∈ Tj, v1 ≠ v2
Crucially, the hierarchical structure in S enables semantic reconciliation. Geographic entities are organized as a containment hierarchy:
When one source specifies “Tian Shan” and another “Middle Tian Shan” for the same deposit, no conflict exists—instead, the latter refines the former. This hierarchical reasoning prevents false positives and supports nuanced integration of spatial knowledge.
For attribute conflicts, S defines domain-specific semantic operations. Metallogenic composition follows union semantics: if one source reports (Kumtor, has Metallogenic Element, Au) and another (Kumtor, has Metallogenic Element, Au + Cu), the system merges them into Au + Cu, representing the complete mineralization as:
where S(e) is the set of sources describing entity e. Similarly, quantitative attributes (e.g., grade, resource estimate) are considered consistent if their values fall within overlapping uncertainty bounds or represent temporal updates.
Composition(e) = {Comps(e) | s ∈ S(e)}union
The dynamic integration strategy resolves conflicts based on source type and temporal context. Sources are classified into a predefined credibility hierarchy:
- Peer-reviewed literature (highest priority);
- Technical reports and exploration summaries;
- Regional geological surveys and open databases (lowest priority).
In cases of semantic conflict, triples from higher-priority sources are retained. For instance, if a journal publication asserts (Kumtor, Resource Estimate, “10 Moz Au”), while a regional survey reports (Kumtor, Resource Estimate, “5 Moz Au”), the value from the peer-reviewed source is preserved in the fused graph Gfused.
In cases of temporal conflicts, such as updated resource estimates or revised tectonic classifications, the most recent information takes precedence, provided it originates from a source of equal or higher credibility. This supports an incremental update paradigm: the knowledge graph is not rebuilt from scratch but selectively refined as new evidence arrives. To maintain historical traceability, older values are retained in the graph with explicit timestamps, enabling the evolution of geological understanding to be tracked over time. For experimental evaluation, we instantiated this paradigm by integrating source triples in sequential temporal batches rather than as a single aggregate.
2.4. Knowledge Graph Export and Validation
To enable efficient access and analysis of the integrated geological knowledge, a graph database is employed as the primary storage and query platform. Among available systems such as Neo4j, JanusGraph, HugeGraph, and Dgraph, Neo4j is selected for its native graph processing capabilities, support for expressive pattern matching via Cypher, and proven scalability in managing highly connected data [25,26]. These features are particularly advantageous for mineral system modeling, where entities exhibit dense interrelations and analytical workflows often involve multi-hop traversals or complex subgraph queries.
The knowledge graph schema is implemented using the property graph model. In this structure:
- Nodes represent domain-specific geological entities defined in the ontology (see Appendix A), such as Mineral Deposit and Ore Block;
- Relationships capture semantic associations between entities, including Located in and Developed in, as formally specified in the schema;
- Properties store quantitative and qualitative attributes associated with nodes or relationships, such as Geotectonic Location and Morphology.
This design ensures a direct and consistent mapping from the fused knowledge triples to the graph database, preserving both semantic fidelity and structural expressiveness.
Data is ingested into Neo4j through batch loading using the official Python 3.11 driver. To maintain entity consistency, a deduplication strategy based on composite keys (e.g., name + geographic coordinates) is applied during insertion. The Cypher MERGE clause, combined with uniqueness constraints on key identifiers, prevents redundant node creation. Indexes are created on frequently queried fields (e.g., deposit type, mineral name), and composite indexes are utilized to accelerate queries involving multiple filtering criteria.
For long-term sustainability, a dynamic update mechanism is implemented. Periodic execution of predefined Cypher scripts allows new knowledge to be incrementally incorporated, supporting continuous evolution of the knowledge base without full reprocessing.
Validation of the final graph follows a dual approach. Automated checks verify structural integrity, including schema adherence and referential consistency. For factual reliability, a stratified sample of relationships, encompassing co-occurrence patterns and host rock associations, is cross-referenced against authoritative sources such as Mindat.org, the USGS MRDS database, and peer-reviewed syntheses.
3. Results
3.1. Corpus Statistics and Domain Coverage
The raw corpus was compiled from geological technical reports, policy documents, and academic publications, totaling approximately 1.8 million characters. After preprocessing, which involved removing references, figures, low-quality content, and duplicates, a clean corpus of 4327 sentences (1.2 million characters) was obtained.
To support the GeoKE framework (Section 2.2), a subset of 650 sentences was manually annotated for geological entities based on the geological schema S (Appendix A). Annotations included only entity spans and types, covering four categories: Exploration Unit, Rock and Structural Unit, Lithology and Mineralization Feature, and Metallogenic Element. This annotated set was used to develop and calibrate the schema-guided entity recognition component of GeoKE, as well as to design prompt templates for attribute and relation extraction.
The full corpus was processed using the two-stage GeoKE framework, extracting entities, attributes, and semantic relations. All outputs were transformed into S-compliant triples, forming a structured knowledge base. Performance is evaluated in Section 3.2.
3.2. Performance of GeoKE Framework
The performance of the two-stage GeoKE framework was evaluated on a standard test set of 156 sentences, independently annotated for Geological Entities, Attribute Features, and Semantic Relations. The test set was held out from both model training and prompt design to ensure unbiased assessment.
Evaluation was conducted at the instance level using exact match criteria. An extraction was considered correct only if both the type and argument spans (e.g., entity span, attribute value span, or subject–predicate–object triple) were fully and precisely matched. The results are summarized in Table 3.
Table 3.
Performance of the GeoKE Framework on the Test Set.
In the first stage, schema-guided entity recognition achieved an F1-score of 0.87. The highest performance was observed on Metallogenic Element (F1 = 0.91), which benefits from standardized expressions (e.g., “Au”, “Cu-Zn”). This strong result is primarily driven by frequently occurring elements with consistent notation; for instance, Au and Cu achieved precisions of 0.92 and 0.91, respectively. Performance on Rock and Structural Unit was slightly lower due to challenges in boundary disambiguation of complex noun phrases.
In the second stage, schema-constrained prompt extraction achieved F1 scores of 0.78 for attributes and 0.79 for relations. The schema S was used to constrain the [MASK] prediction space to geologically valid values (e.g., temporal attributes restricted to 0–4500 Ma, spatial angles to 0–90°), which eliminated semantically invalid outputs such as “dip angle = 110°” or “formation age = 5000 Ma”. Spatial Attribute and Spatial Relation performed best (F1 = 0.78 and 0.82), as they are often expressed with explicit linguistic cues (e.g., “at 500 m depth”, “located in”). In contrast, Genetic Relation and Compositional Attribute showed lower performance due to implicit and context-dependent expressions.
These results demonstrate that the schema-guided design of GeoKE improves accuracy and ensures domain compliance in automated knowledge generation through the integration of formal semantics in both entity recognition and structured extraction.
3.3. Outcomes of Knowledge Fusion and Conflict Resolution
The structured knowledge extracted from the full corpus consists of 20,840 triples, including entities, their attributes, and semantic relations. Due to the integration of heterogeneous sources, the data fusion process revealed numerous redundant and conflicting assertions, attributable to differences in terminology, temporal updates, and interpretation.
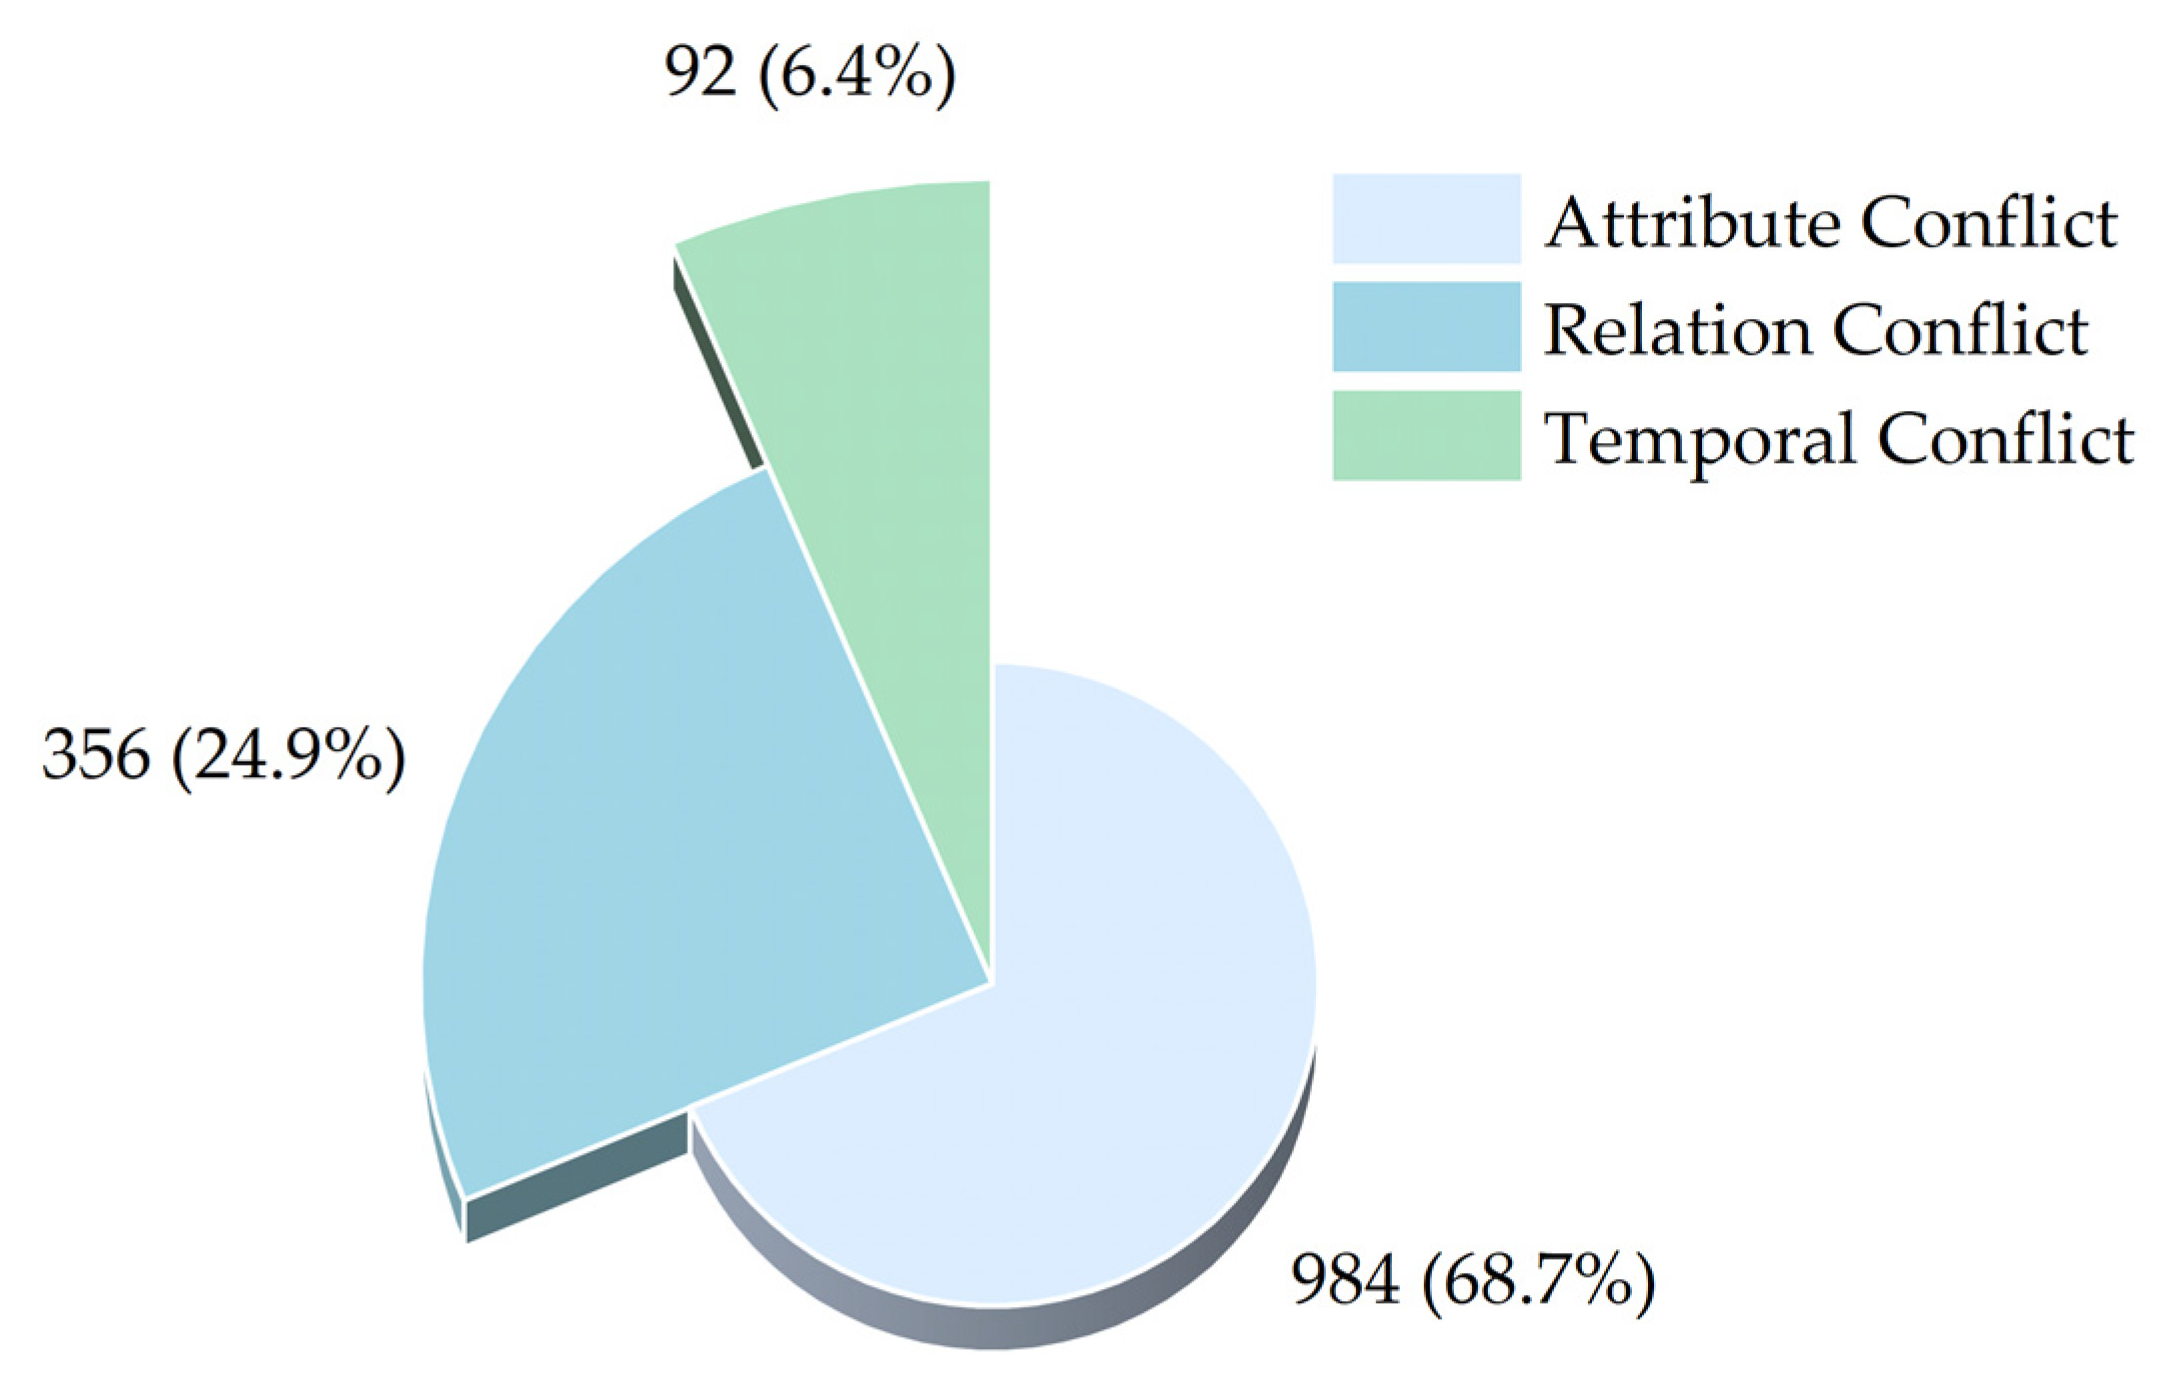
A conflict detection module identified 1432 conflicting assertions involving 896 unique entities. Conflicts were classified into three categories: attribute, relation, and temporal (Figure 4). The most common were attribute conflicts (984 instances), primarily concerning resource estimates and mineral grades reported with variations across sources.
Figure 4.
Statistics of detected conflicts.
After applying schema-guided conflict resolution strategies, the system generated a clean and consistent knowledge graph containing 18,204 unique triples. This represents a net retention rate of 87.3% of the original input, with 1636 triples removed due to redundancy or unresolvable conflicts.
Crucially, the framework is designed to retain conflicting and historical assertions as traceable variants, annotated with available source information (e.g., document title, year). This ensures transparency in knowledge evolution and supports expert-driven validation and updates.
3.4. Structural Overview of the Integrated Knowledge Graph
The integrated geological knowledge graph constructed through the two-stage extraction and fusion pipeline contains 18,204 unique triples, forming a structured representation of mineral systems, exploration units, and their interrelations. This section presents a structural analysis of the graph, including entity and relation distributions, topological properties, and comparisons with existing resources. Its fundamental composition is summarized in Table 4.
Table 4.
Basic statistics of the integrated knowledge graph.
In the knowledge graph, only Geological Entities are represented as nodes, while Attribute Features are encoded as literal values (e.g., “5.2 Mt”, “250 Ma”) connected via property edges, and Semantic Relations serve as typed edges between entities.
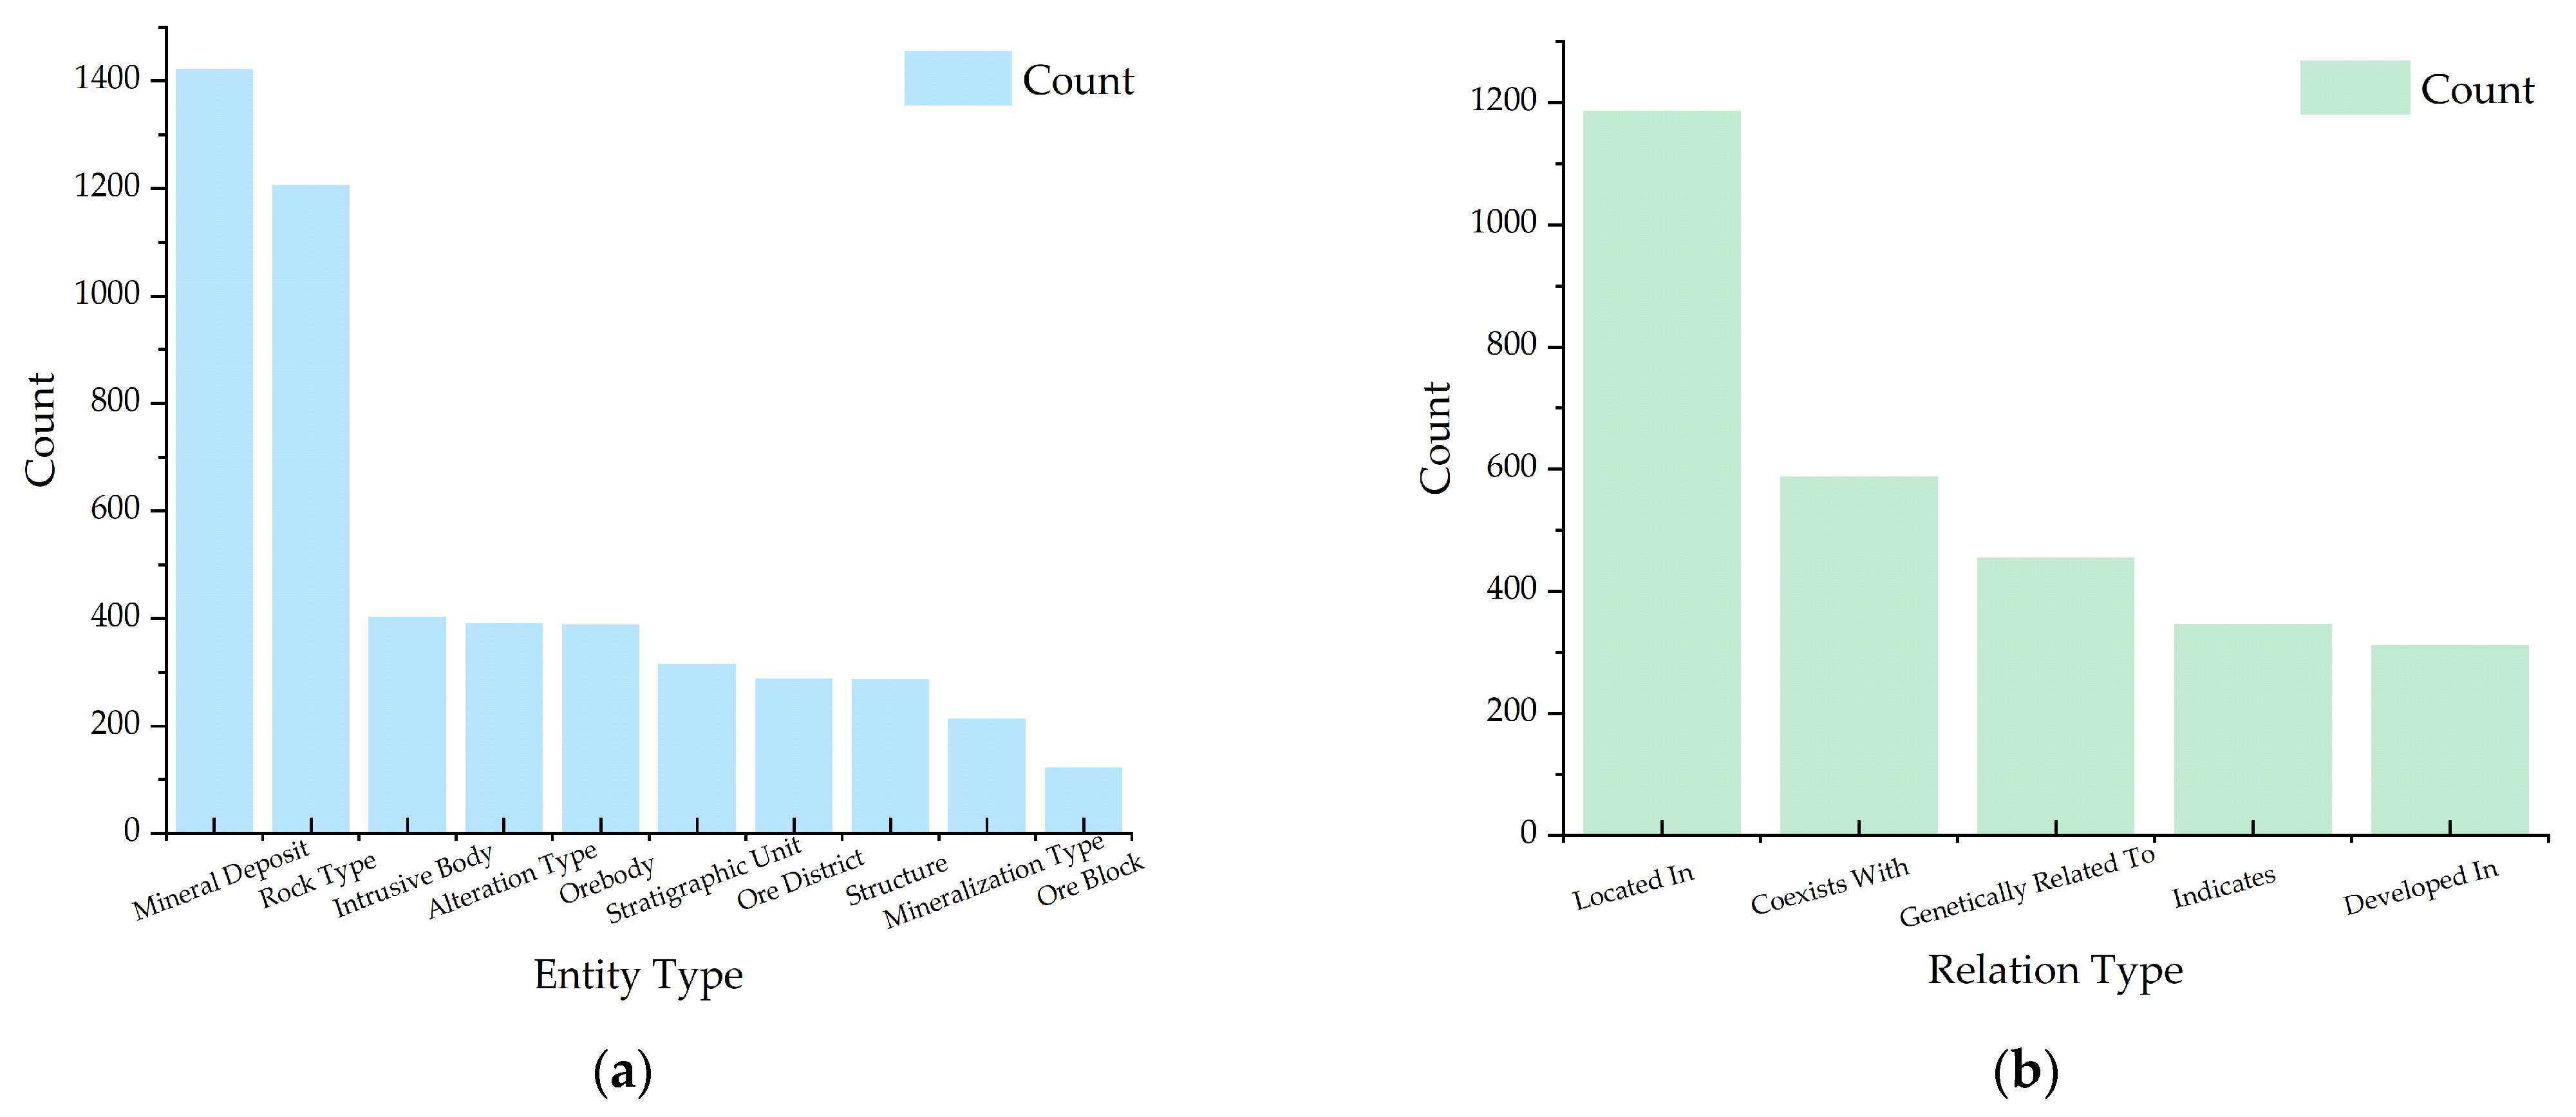
As shown in Figure 5a, the most prevalent entity types are Mineral Deposit (1423) and Rock Type (1207), accounting for 26.7% and 22.6% of all entities, respectively. This distribution reflects the emphasis of the source corpus on mineral system characterization and lithological description. Other notable types include Orebody (389), Alteration Type (392), and Intrusive Body (403), which are critical for understanding ore genesis and exploration criteria. As shown in Figure 5b, the most frequent semantic relation is located_in (1187 instances, 24.3%), followed by coexists_with (589, 12.1%) and genetically_related_to (456, 9.3%). These distributions reflect dominant spatial containment and paragenetic associations in the mineral systems described in the corpus. In addition to these semantic relations, the graph contains numerous attribute-level assertions (e.g., has_grade, has_resource_estimate) and implementation-specific predicates (e.g., contains_mineral, formed_by).
Figure 5.
Distribution of entities and semantic relations in the integrated geological knowledge graph: (a) entity type distribution; (b) semantic relation type distribution.
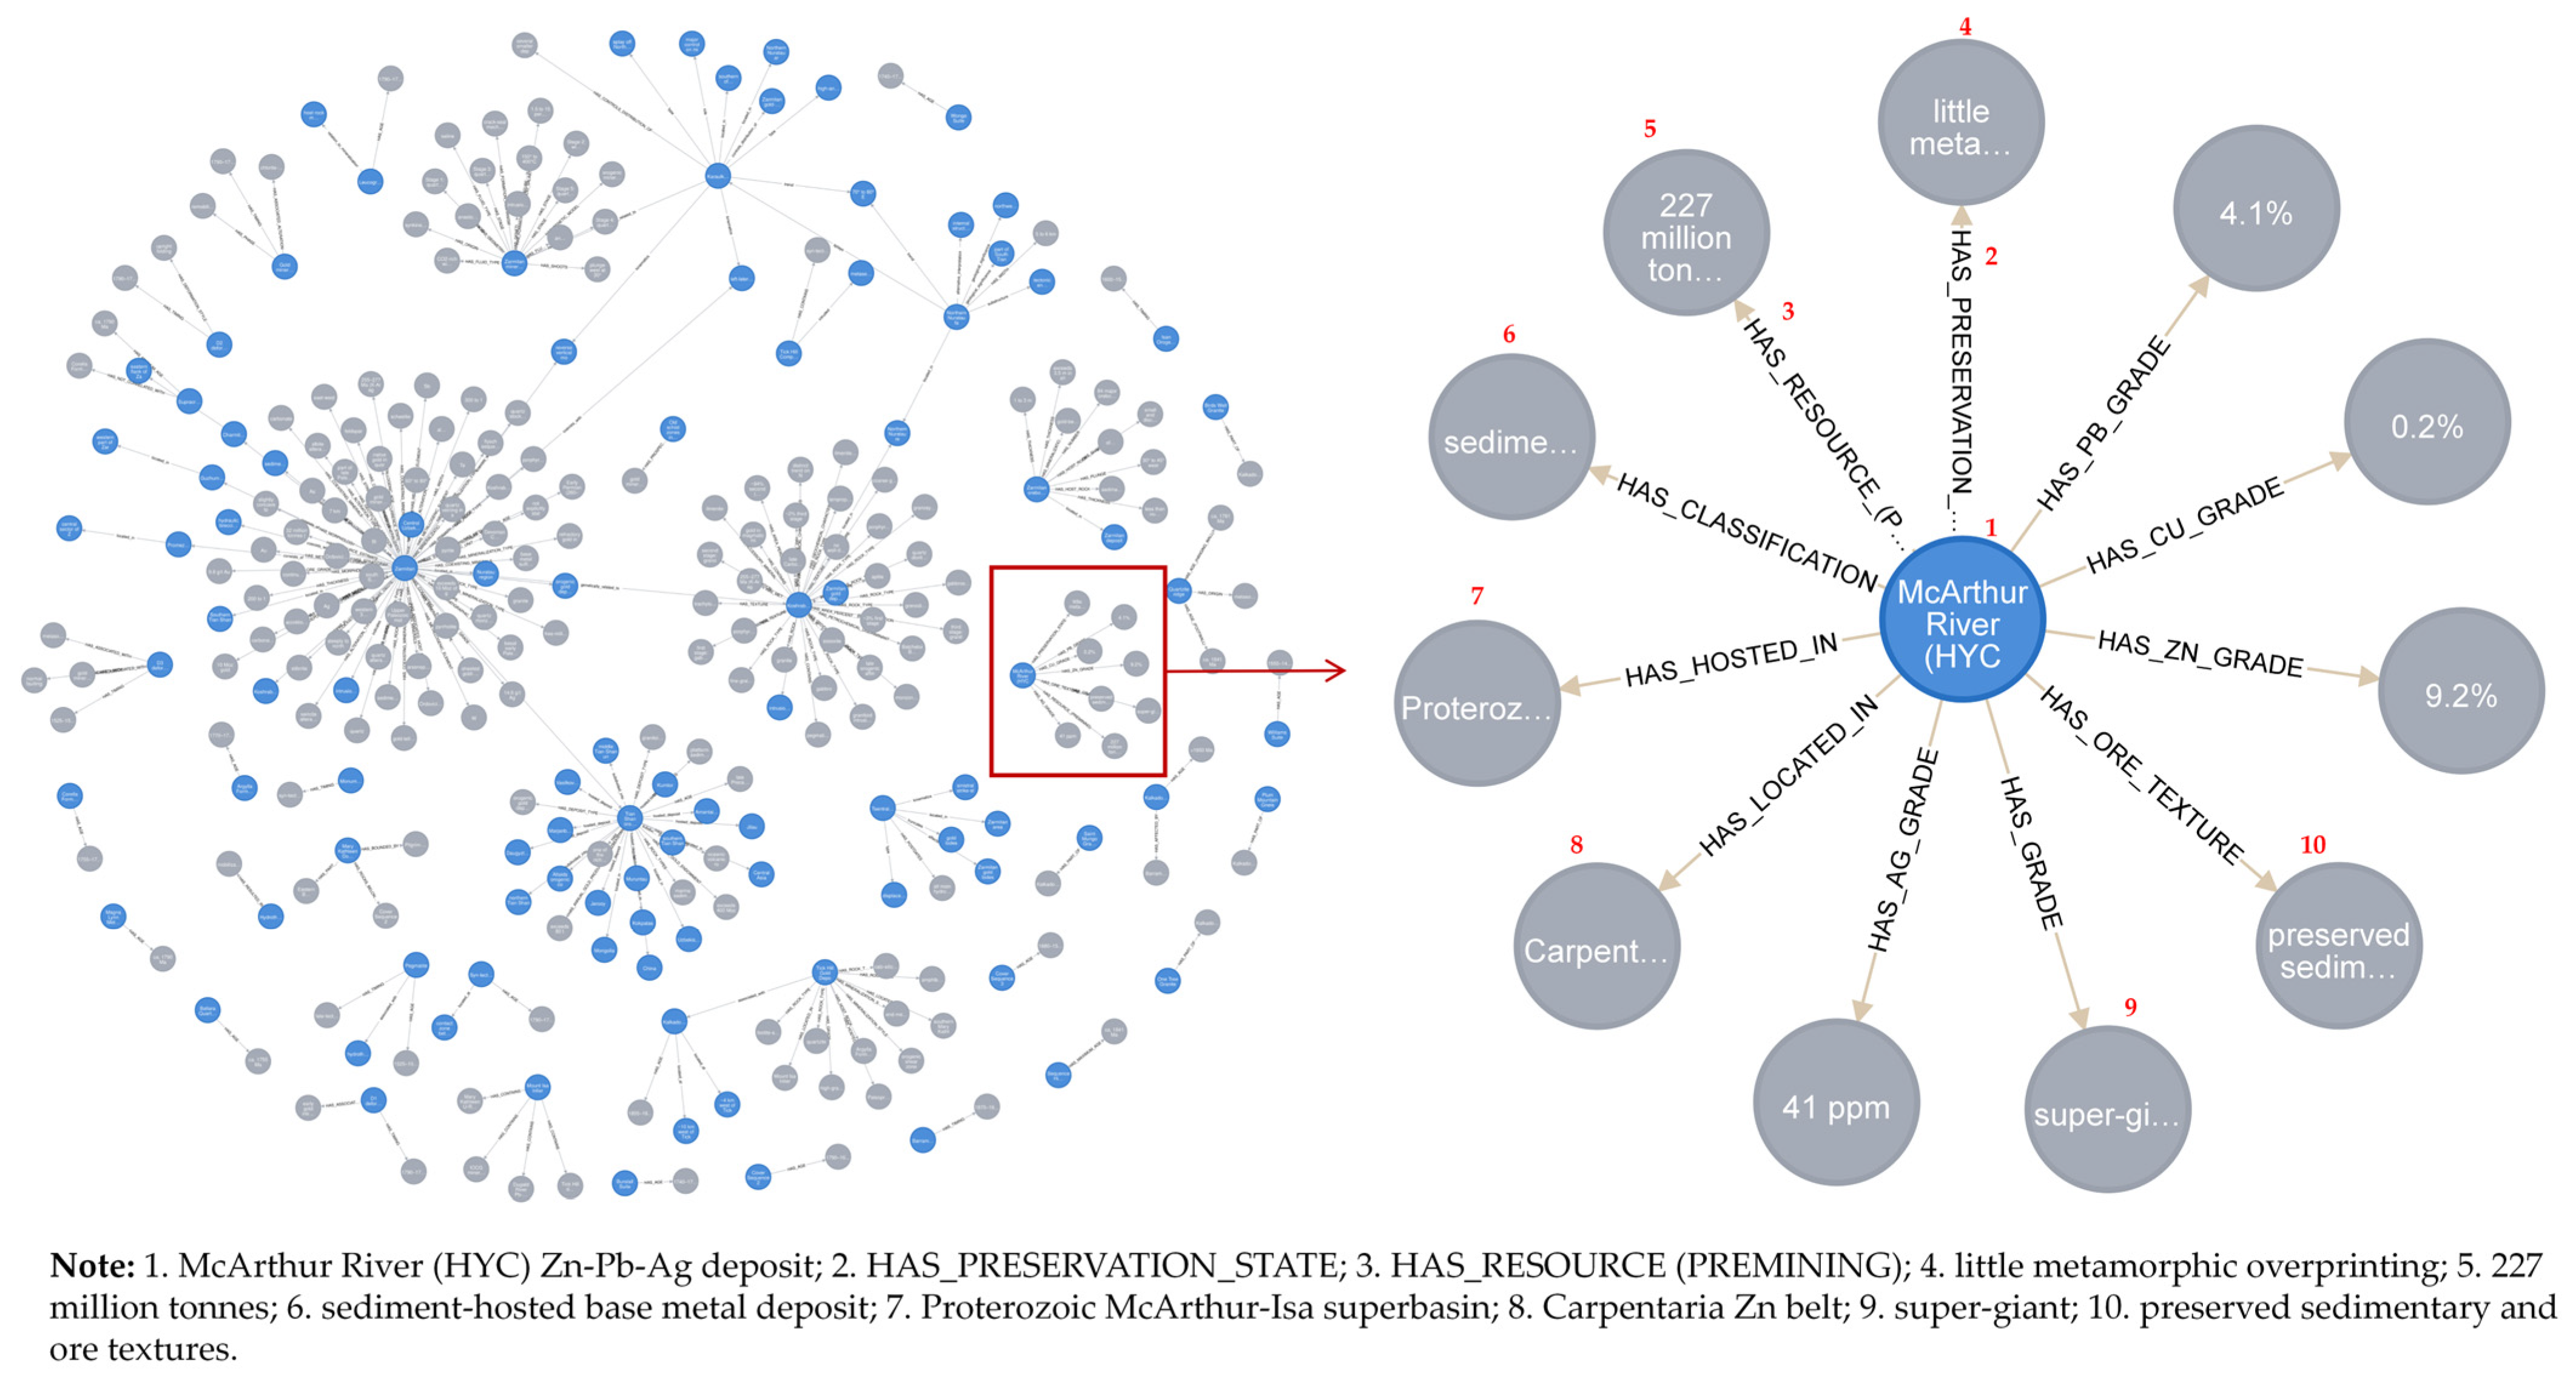
The integrated geological knowledge graph, with its heterogeneous entities and semantic relations, is visualized in Figure 6. To assess the connectivity and coherence of the graph, basic network metrics were computed. On average, each entity participates in 3.42 assertions (i.e., appears in 3.42 triples), indicating moderate connectivity. The largest connected component (LCC) contains 4612 nodes (86.6% of all entities), suggesting that the majority of geological concepts are interlinked through spatial, genetic, or compositional paths. The graph density is approximately 0.0018, which is typical for domain-specific knowledge graphs with hierarchical and sparse structures.
Figure 6.
Visualization of the integrated geological knowledge graph (part data).
A preliminary comparison was conducted between a subset of data from Mindat.org and extracted records from MRDS. While Mindat contains more mineral-specimen entries, our knowledge graph provides richer genetic and spatial relationships, as well as more structured attribute values (e.g., resource estimates with units). Compared to MRDS, our graph features finer-grained entity typing and explicit semantic relations, significantly enhancing queryability and reasoning capabilities. Furthermore, the graph systematically captures co-occurring and associated mineral relationships, offering critical support for analyzing mineralization patterns and predicting ore deposits.
These structural characteristics demonstrate that the integrated knowledge graph is semantically rich, well-connected, and tailored for downstream geological applications such as exploration targeting and resource assessment.
4. Discussion
4.1. Accuracy Evaluation of Knowledge Extraction: A Quantitative Comparative Analysis
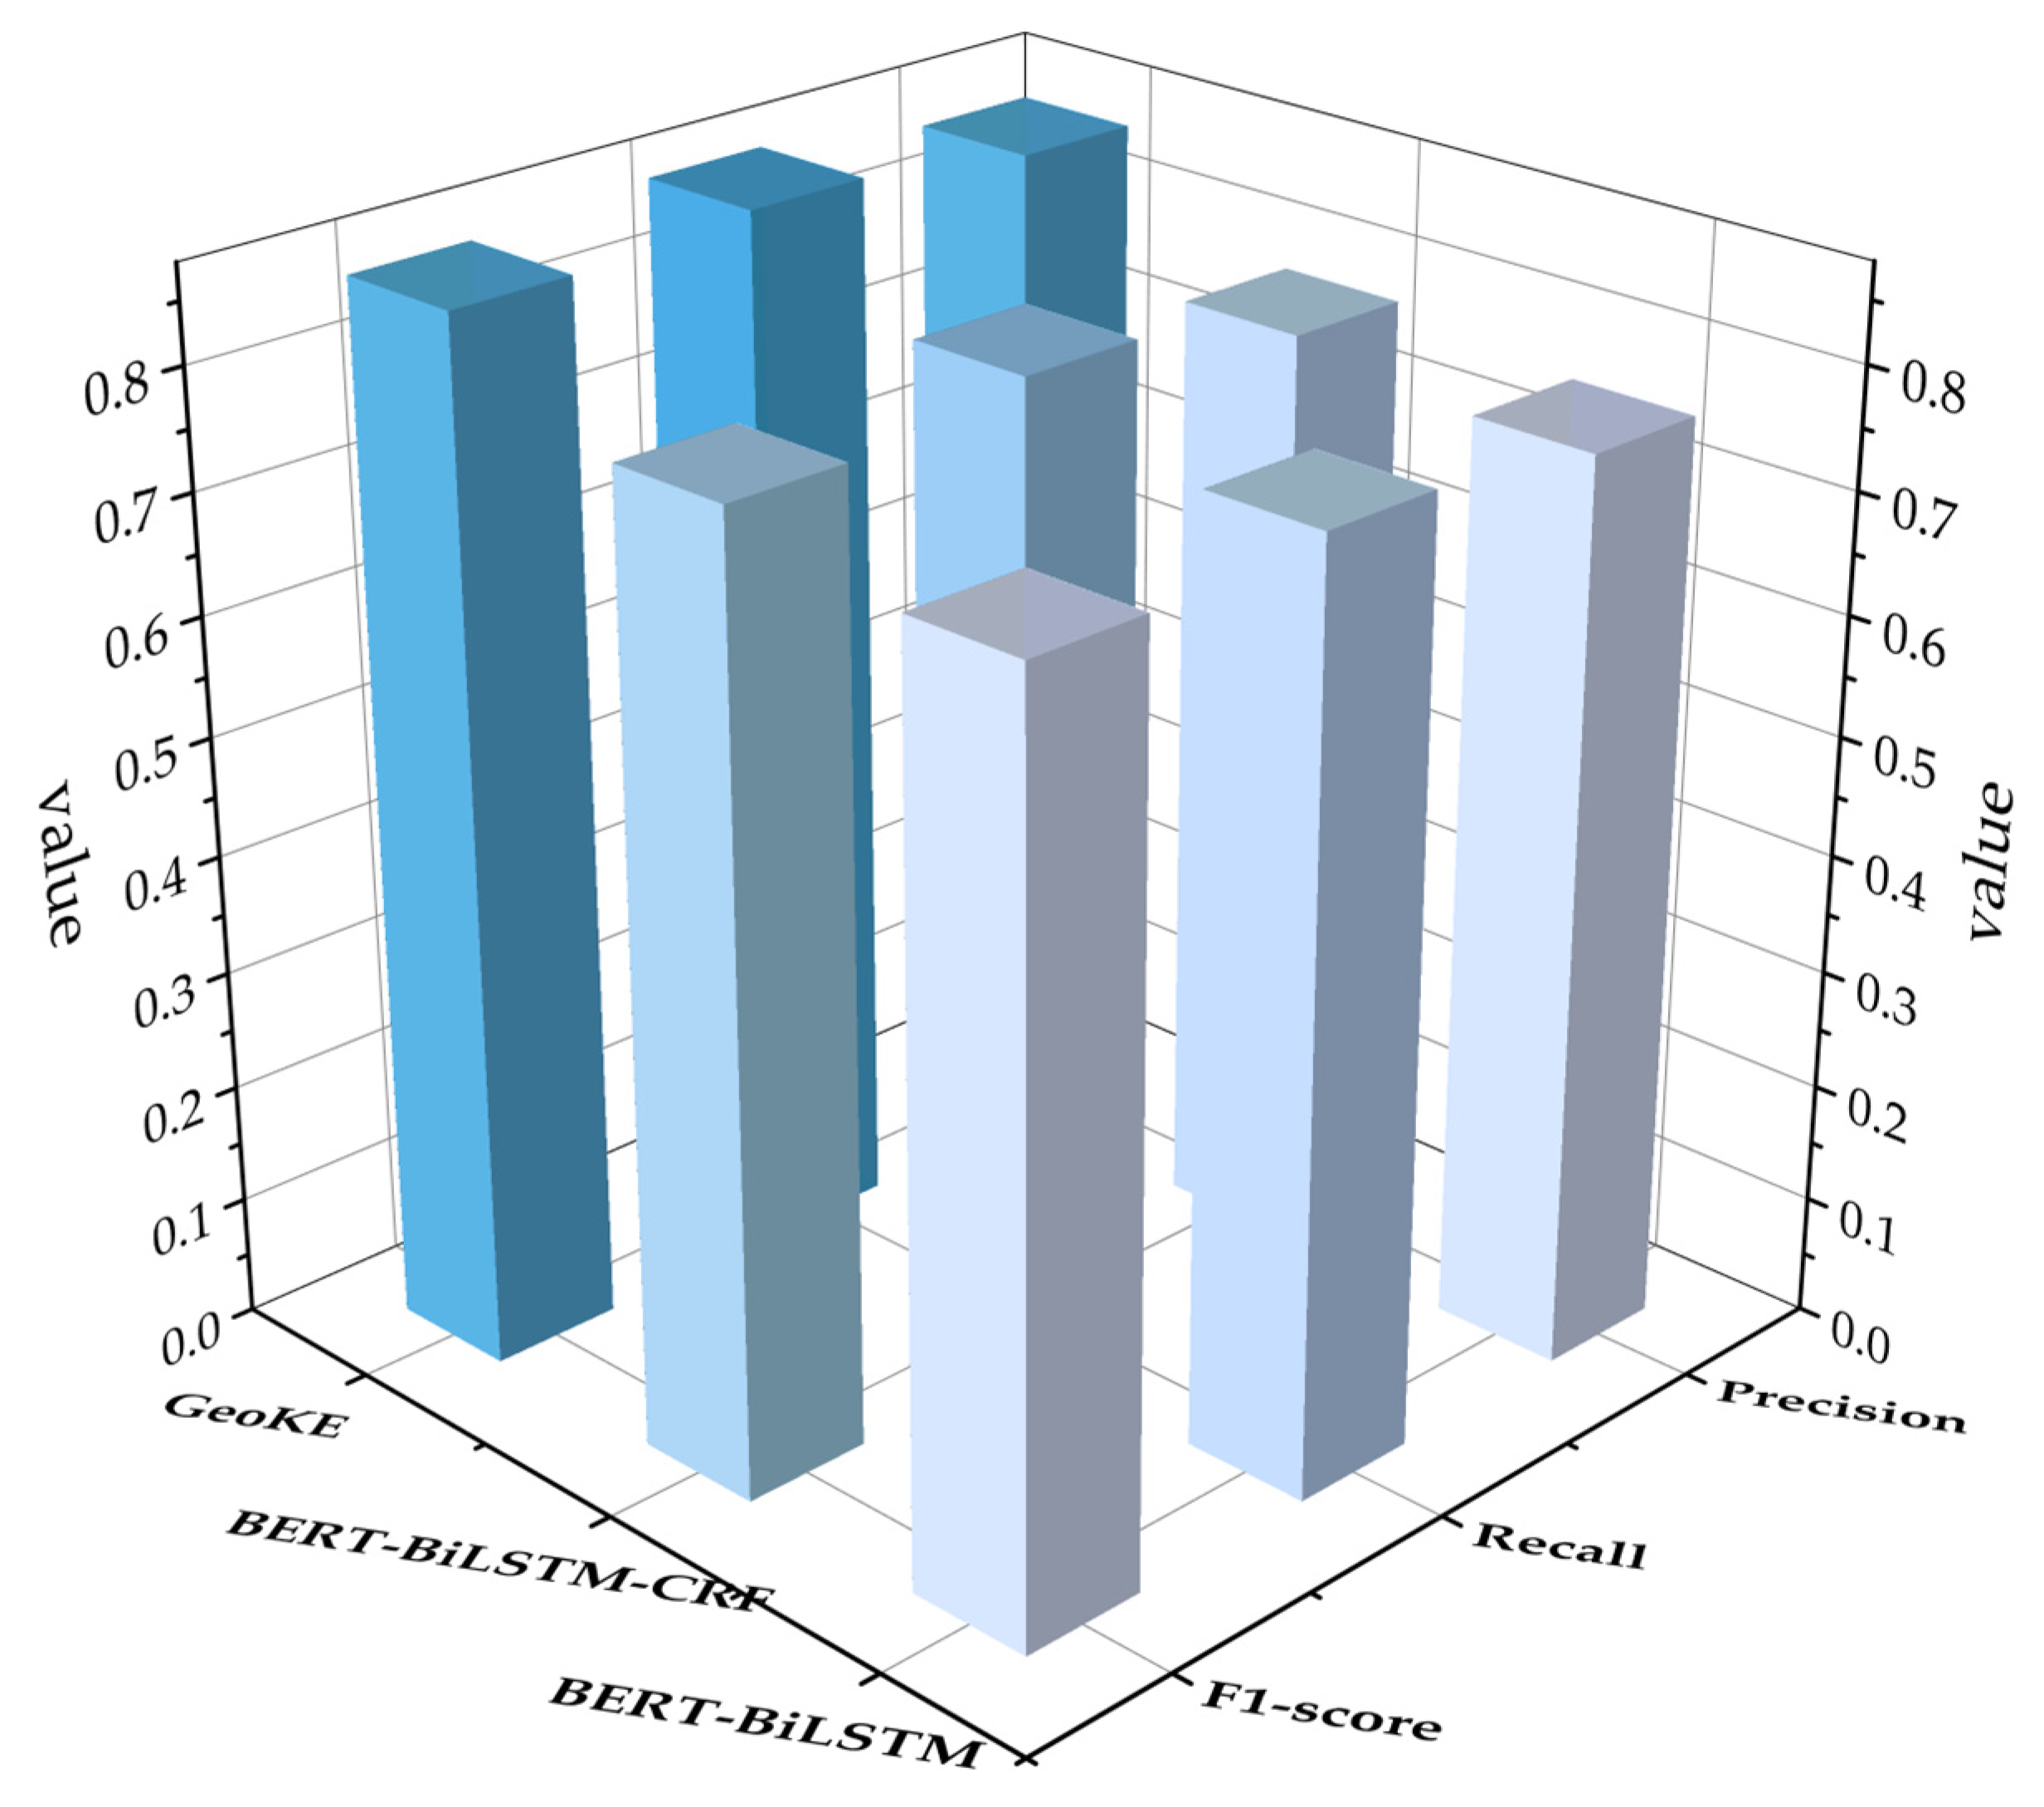
To evaluate the effectiveness of GeoKE in geological knowledge extraction, we compared its performance against two strong baselines, BERT-BiLSTM and BERT-BiLSTM-CRF, on a manually annotated test set. As shown in Figure 7, GeoKE achieves an F1-score of 0.88 for entity recognition, outperforming BERT-BiLSTM by 11 points and BERT-BiLSTM-CRF by 8 points. It also achieves higher precision (0.87) and recall (0.89), demonstrating well-balanced performance. These results highlight the effectiveness of domain-specific semantic constraints and hierarchical modeling in GeoKE for capturing complex geological entities.
Figure 7.
Performance comparison of GeoKE and baseline models in geological entity recognition.
4.2. Semantic-Aware Knowledge Fusion Strategies: Transforming Data into Interpretable Knowledge
The true value of a geological knowledge graph lies not only in high-precision information extraction but also in its ability to integrate heterogeneous and conflicting data into a coherent, semantically meaningful representation. Traditional fusion approaches that rely on syntactic matching or rigid schema alignment often result in semantic fragmentation: equivalent terms across languages or varying nomenclatures may be treated as distinct entities, and contradictory lithological descriptions from different sources may remain unresolved.
To address these limitations, our semantic-aware fusion framework leverages domain ontologies, contextual similarity, and logical constraints. Knowledge-guided normalization aligns synonymous expressions, including cross-lingual variants such as “quartz-vein type gold deposit” and their counterparts in non-English literature, into standardized concepts. This enables seamless integration across multilingual and multi-source datasets without privileging any single linguistic or regional convention.
Context-aware conflict resolution evaluates inconsistent assertions by analyzing co-occurring geological features. For example, when faced with conflicting labels such as “granodiorite” and “monzogranite”, the system favors interpretations most consistent with established geological contexts. Similarly, semantic role labeling preserves not only factual content but also relational semantics, distinguishing between “alteration associated with mineralization” and “alteration post-dating ore formation”. This supports fine-grained temporal and causal reasoning within the knowledge graph.
As demonstrated in Section 3.3, this approach resolved 1432 conflicts involving 896 unique entities. The final knowledge graph contains 18,204 unique triples, representing an 87.3% retention rate of the original input. Crucially, unresolvable variants are preserved as traceable, source-annotated alternatives, ensuring transparency in knowledge evolution and supporting expert validation.
To illustrate the geological plausibility of resolved conflicts, consider the case of the Kumtor deposit. First, sources disagreed on host rock classification (“granodiorite” vs. “quartz monzonite”). Our system merged these based on petrological hierarchy and source credibility, retaining “granodiorite,” a resolution consistent with regional porphyry-related metallogenic models. Second, one source reported its metallogenic elements as “Au,” while another listed “Au + Cu.” Following union semantics defined in our ontology, the system merged these into “Au + Cu,” reflecting the complete mineralization signature. This outcome aligns with published studies confirming minor Cu mineralization at Kumtor and is consistent with characteristics of intrusion-related gold systems in Central Asia. Such cases were spot-checked by co-authors with domain expertise in Central Asian metallogeny and found consistent with established interpretations.
Nevertheless, certain error patterns and unresolved conflicts reveal inherent challenges in fully automating geological knowledge fusion. First, lexical similarity between geologically distinct terms, such as “quartz vein” and “quartzite”, can lead to entity misclassification during extraction, particularly in low-context sentences that lack mineralogical or structural descriptors. Second, temporal assertions frequently employ heterogeneous formats, such as “Late Cretaceous” versus “85 Ma”, requiring alignment to a unified chronostratigraphic scale, a capability not yet embedded in our pipeline. Third, spatial scope mismatches, such as “region-wide potassic alteration” versus “local propylitic halo”, pose difficulties for relation fusion because the current schema S lacks explicit qualifiers to represent scale-modified spatial predicates. In these cases, the system conservatively retains both assertions with full source provenance and flags them for potential expert review. Future work will enrich S with temporal normalization rules and spatial granularity layers to better capture such nuances.
The high retention rate indicates strong consensus across most sources, reinforcing confidence in commonly reported geological patterns. At the same time, the explicit identification of conflicts, especially those related to resource estimates and mineral grades, reveals domains of uncertainty and interpretive variability that warrant expert scrutiny.
By transforming isolated triples into a semantically rich and logically structured representation, the fused knowledge graph transcends passive data storage. It enables advanced reasoning about spatial, genetic, and temporal relationships in geological systems. This establishes a trustworthy, auditable foundation for intelligent applications such as mineral prospectivity mapping, automated report synthesis, and collaborative knowledge discovery, where explainability and reliability are paramount.
4.3. Enabling Geological Intelligence Through Structured Knowledge Graphs
- (1)
- Illustrative Example: The Tian Shan Orogenic Belt
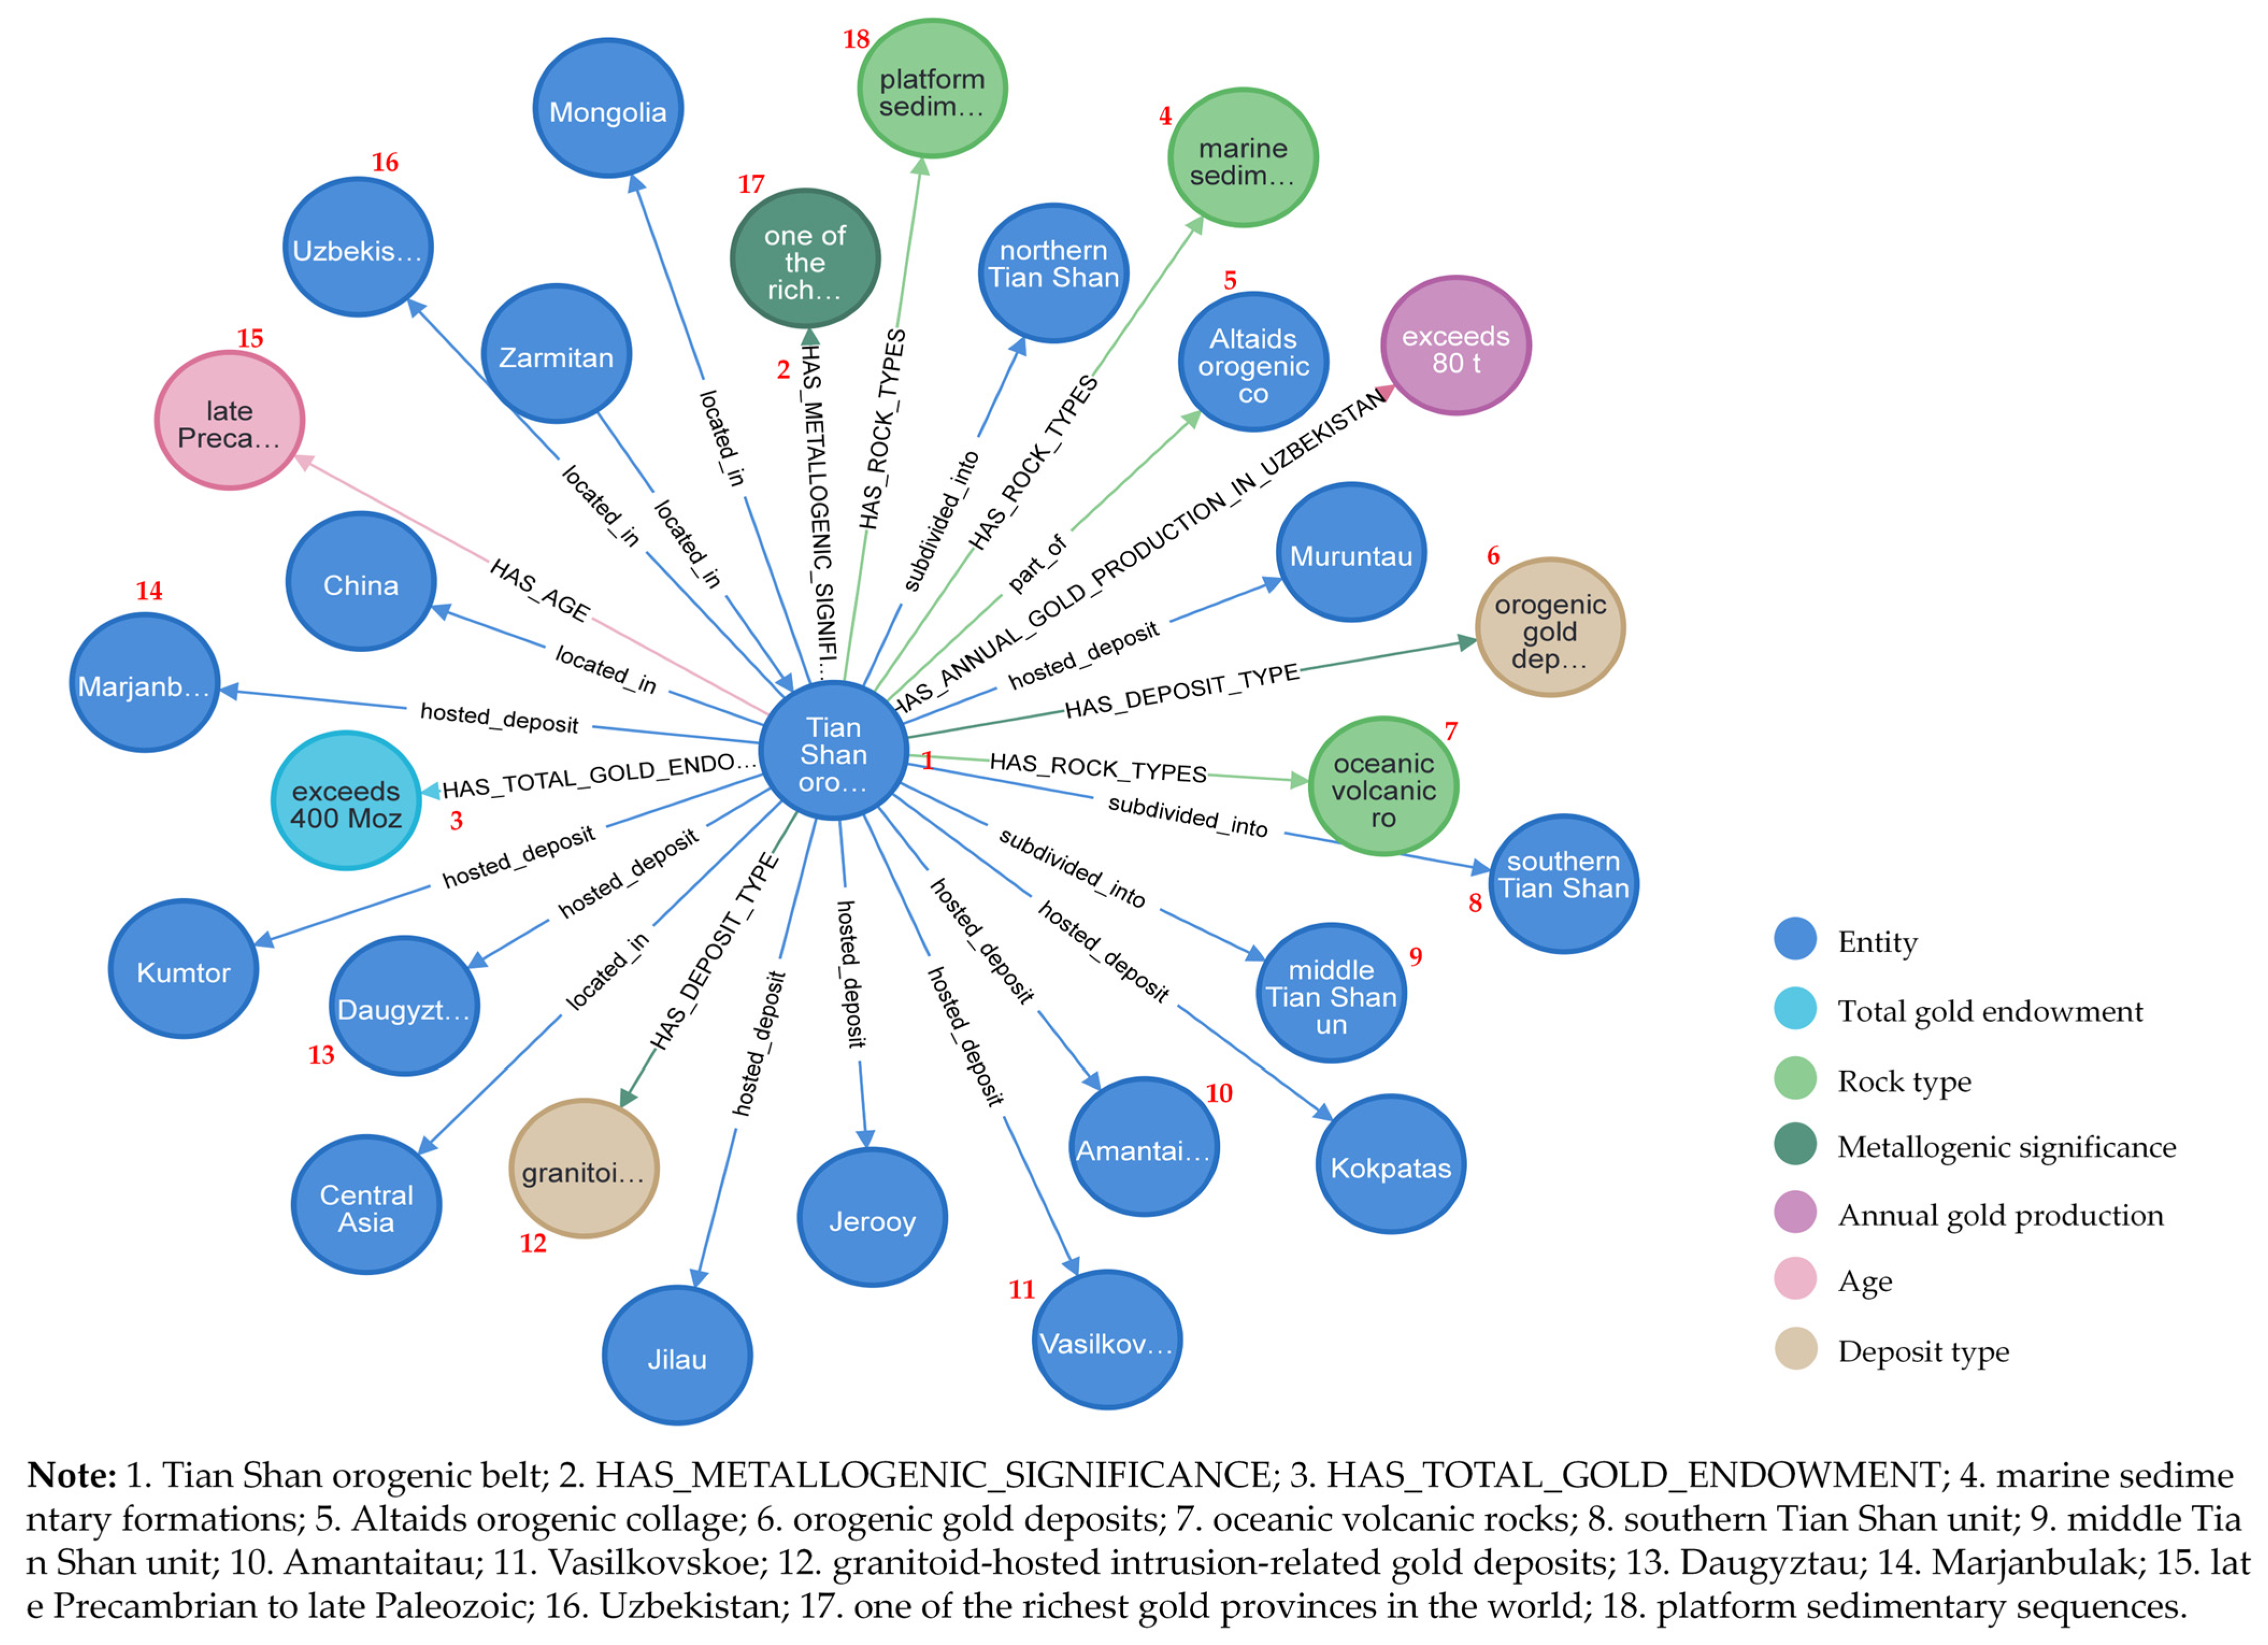
This case demonstrates how a knowledge graph integrates diverse geological data for the Tian Shan orogenic belt. As shown in Figure 8, the graph centers on the “Tian Shan orogenic belt” node, with colors indicating entity types (e.g., locations, deposits, attributes). It establishes spatial context—spanning China, Uzbekistan, and Mongolia—and structural subdivision into northern, middle, and southern units. Critically, it links the orogen to world-class gold deposits (e.g., Muruntau, Kumtor), enriched with resource and production data, highlighting its metallogenic significance. This structured representation transforms fragmented reports into a coherent, queryable knowledge base.
Figure 8.
Knowledge graph representation of the Tian Shan orogenic belt.
- (2)
- Intelligent Question Answering
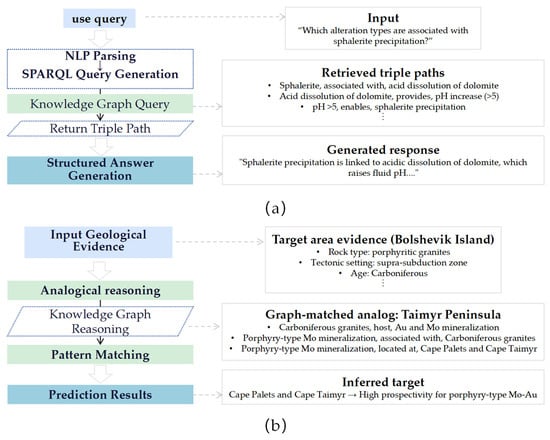
An intelligent question answering system enables users to pose complex geological queries in natural language, such as “Which alteration types are associated with sphalerite precipitation?” The system first parses the input using NLP techniques, identifying geological entities and semantic relationships. It then translates the query into a structured format compatible with the knowledge graph and executes it to retrieve relevant triple paths, such as chains linking alteration types to mineral assemblages and geological settings. Based on these results, the system synthesizes the information and generates a structured natural language response that clearly presents the logical connections among geological concepts. As concretely demonstrated in Figure 9a, this workflow retrieves paths like “sphalerite → associated with → acid dissolution of dolomite” and produces interpretable answers such as “Sphalerite precipitation is linked to acidic dissolution of dolomite, which raises fluid pH…”, forming a complete pipeline from natural language input to graph-based reasoning and answer generation.
Figure 9.
A framework for intelligent geological applications enabled by the knowledge graph: (a) intelligent question answering; (b) mineral prospectivity prediction.
- (3)
- Mineral Prospectivity Prediction
The mineral prospectivity prediction system identifies potential mineralized zones by analogical reasoning based on known mineralization patterns encoded in the knowledge graph. Given geological evidence from a target area, such as rock type, tectonic setting, and alteration characteristics, the system searches the graph for documented mineral systems with similar features. By matching the ore-forming conditions and spatial configurations of these known analogs, the system infers areas with high mineralization potential and generates predictive outputs. This process achieves knowledge transfer from “known” to “unknown,” enhancing the geological plausibility and interpretability of predictions. As illustrated in Figure 9b, the system matches geological evidence from a target area to analogous mineral systems in the knowledge graph and identifies high-prospectivity zones accordingly.
5. Conclusions
The Semantic-Aware Fusion Framework proposed in this study addresses semantic inconsistencies in integrating multi-source and multilingual geoscience knowledge by introducing a unified approach that combines structured extraction with dynamic fusion. Unlike conventional pipelines, where knowledge integration is often treated as simple aggregation, our framework embeds semantic constraints throughout the entire workflow via a standardized geological knowledge schema that defines core entities such as rock units, mineralization features, and metallogenic events and their spatial, genetic, and associative relations.
The system achieves robust knowledge extraction with an overall F1 score of 0.82, exceeding 0.90 for critical entity types. Compared to BERT-BiLSTM and BERT-BiLSTM-CRF baselines, GeoKE improves F1-score by up to 11 points (achieving a peak of 0.88 on specific subsets), demonstrating the effectiveness of domain-specific modeling in capturing complex geological entities. During fusion, 1432 conflicts were identified, including attribute, relation, and temporal inconsistencies. After schema-guided resolution, a coherent knowledge graph of 18,204 high-quality triples was generated, retaining 87.3% of the input and significantly improving semantic coherence.
The key distinction of this framework lies in treating knowledge fusion as a traceable, evolutionary process: conflicting assertions are preserved with provenance and versioning, enabling expert review and incremental updates. The resulting graph supports case studies, visualization, question answering, and mineral prospectivity prediction, demonstrating a shift from static repositories toward dynamic, intelligent systems. This work offers a new pathway for building sustainable and evolving geoscience knowledge infrastructures.
The current knowledge graph has limited relation types and relies mainly on text, missing detailed genetic processes and spatial or geochemical data. Future work will enhance it by adding fine-grained relations, integrating maps and assay data, and developing models for predictive inference.
Author Contributions
Conceptualization, Y.Q. (Ying Qin) and H.Y.; methodology, Y.Q. (Ying Qin); software, Y.Q. (Ying Qin), H.Y. and G.F.; validation, Y.Q. (Ying Qin), H.Y., Y.Z. and L.C.; formal analysis, Y.Q. (Ying Qin) and L.C.; investigation, Y.Q. (Ying Qin) and Y.Q. (Yina Qiao); resources, Y.Q. (Ying Qin) and H.Y.; data curation, Y.Q. (Ying Qin), Y.Y., Y.Q. (Yina Qiao) and Y.Z.; writing—original draft preparation, Y.Q. (Ying Qin); writing—review and editing, Y.Q. (Ying Qin) and H.Y.; visualization, Y.Q. (Ying Qin), G.F. and L.C.; supervision, H.Y.; project administration, Y.Q. (Ying Qin) and H.Y.; funding acquisition, H.Y. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by National Natural Science Foundation of China, grant number 42571545; National Natural Science Foundation of China, grant number 52478011; the Third Xinjiang Scientific Expedition Program, grant number 2022xjkk1006; the Xinjiang Uygur Autonomous Region Key Research and Development Program, grant number 2022B01012-1; the Science and Technology Innovation Project of Jiangsu Provincial Department of Natural Resources, grant number 2023018; the Fundamental Research Funds for the Central Universities, grant number 2024ZDPYCH1002; Jiangsu Provincial Science and Technology Think Tank Program, grant number JSKX0225042 and the APC was funded by Correspondence Prof. Dr. Yang.
Data Availability Statement
The data presented in this study are available on request from the corresponding author. The data are not publicly available due to privacy concerns.
Acknowledgments
We sincerely acknowledge the School of Resources and Geosciences and the Key Laboratory of Coalbed Methane Resources and Reservoir Formation Process, Ministry of Education, at the China University of Mining and Technology for their experimental facility and resource support.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| GeoKE | Schema-guided Geological Knowledge-aware Extraction |
| BERT | Bidirectional Encoder Representations from Transformers |
| Bi-LSTM | Bidirectional Long Short-Term Memory |
| CRF | Conditional Random Field |
| S | Schema |
| P | Precision |
| R | Recall |
| F1 | F1 Score |
| Gfused | Fused Knowledge Graph |
| Mindat | Mindat.org |
| MRDS | Mineral Resources Data System |
| LCC | Largest Connected Component |
| NLP | Natural Language Processing |
| SPARQL | SPARQL Protocol and RDF Query Language |
Appendix A
Table A1.
Complete Specification of the Mineral Exploration Knowledge Schema.
References
- Balaram, V. Potential Future Alternative Resources for Rare Earth Elements: Opportunities and Challenges. Minerals 2023, 13, 425. [Google Scholar] [CrossRef] [Scilit]
- Owen, J.R.; Kemp, D.; Lechner, A.M.; Harris, J.; Zhang, R.; Lèbre, É. Energy transition minerals and their intersection with land-connected peoples. Nat. Sustain. 2023, 6, 203–211. [Google Scholar] [CrossRef] [Scilit]
- Yang, F.F.; Zuo, R.G.; Kreuzer, O.P. Artificial intelligence for mineral exploration: A review and perspectives on future directions from data science. Earth-Sci. Rev. 2024, 258, 104941. [Google Scholar] [CrossRef] [Scilit]
- Zuo, R.G.; Carranza, E.J.M. Machine Learning-Based Mapping for Mineral Exploration. Math. Geosci. 2023, 55, 891–895. [Google Scholar] [CrossRef] [Scilit]
- Yu, X.T.; Yu, P.P.; Wang, K.Y.; Cao, W.; Zhou, Y.Z. Data-Driven Mineral Prospectivity Mapping Based on Known Deposits Using Association Rules. Nat. Resour. Res. 2024, 33, 1025–1048. [Google Scholar] [CrossRef] [Scilit]
- Han, F.; Deng, Y.R.; Liu, Q.Y.; Zhou, Y.Z.; Wang, J.; Huang, Y.J.; Zhang, Q.L.; Bian, J. Construction and application of the knowledge graph method in management of soil pollution in contaminated sites: A case study in South China. J. Environ. Manag. 2022, 319, 115685. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.Y.; Huang, Y.; Zhang, C.J.; Ye, P. Geoscience Knowledge Graph (GeoKG): Development, construction and challenges. Trans. GIS 2022, 26, 2480–2494. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Zhang, X.Y.; Ye, P.; Du, M.; Lu, Y.X.; Xue, H.N. Geographic Knowledge Graph (GeoKG): A Formalized Geographic Knowledge Representation. ISPRS Int. J. Geo-Inf. 2019, 8, 184. [Google Scholar] [CrossRef] [Scilit]
- Hou, Z.-W.; Liu, X.; Zhou, S.; Jing, W.; Yang, J. Bibliometric Analysis on the Research of Geoscience Knowledge Graph (GeoKG) from 2012 to 2023. ISPRS Int. J. Geo-Inf. 2024, 13, 255. [Google Scholar] [CrossRef] [Scilit]
- Shbita, B.; Sharma, N.; Vu, B.; Lin, F.; Knoblock, C.A. Constructing a Knowledge Graph of Historical Mining Data. In Proceedings of the 6th International Workshop on Geospatial Linked Data (GeoLD 2024), Co-Located with the 21st Extended Semantic Web Conference (ESWC 2024), Hersonissos, Greece, 26 May 2024; CEUR Workshop Proceedings. Volume 3743, pp. 1–14. Available online: https://ceur-ws.org/Vol-3743/paper1.pdf (accessed on 23 November 2025).
- Cole, D.L.; Ruiz-Mercado, G.J.; Zavala, V.M. A graph-based modeling framework for tracing hydrological pollutant transport in surface waters. Comput. Chem. Eng. 2023, 179, 108457. [Google Scholar] [CrossRef] [Scilit]
- Enkhsaikhan, M.; Holden, E.-J.; Duuring, P.; Liu, W. Understanding ore-forming conditions using machine reading of text. Ore Geol. Rev. 2021, 135, 104200. [Google Scholar] [CrossRef] [Scilit]
- Qiu, Q.J.; Tian, M.; Tao, L.F.; Xie, Z.; Ma, K. Semantic information extraction and search of mineral exploration data using text mining and deep learning methods. Ore Geol. Rev. 2024, 165, 105863. [Google Scholar] [CrossRef] [Scilit]
- Liu, C.J.; Ji, X.H.; Dong, Y.H.; He, M.Y.; Yang, M.; Wang, Y.Z. Chinese mineral question and answering system based on knowledge graph. Expert Syst. Appl. 2023, 231, 120841. [Google Scholar] [CrossRef] [Scilit]
- Qiu, Q.; Xie, Z.; Wu, L.; Tao, L. Automatic spatiotemporal and semantic information extraction from unstructured geoscience reports using text mining techniques. Earth Sci. Inform. 2020, 13, 1393–1410. [Google Scholar] [CrossRef] [Scilit]
- He, H.; Ma, C.; Ye, S.; Tang, W.; Zhou, Y.; Yu, Z.; Yi, J.; Hou, L.; Hou, M. Low Resource Chinese Geological Text Named Entity Recognition Based on Prompt Learning. J. Earth Sci. 2024, 35, 1035–1043. [Google Scholar] [CrossRef] [Scilit]
- Peng, C.; Xia, F.; Naseriparsa, M.; Osborne, F. Knowledge Graphs: Opportunities and Challenges. Artif. Intell. Rev. 2023, 56, 13071–13102. [Google Scholar] [CrossRef] [Scilit]
- Noy, N.F.; McGuinness, D.L. Ontology Development 101: A Guide to Creating Your First Ontology; KSL-01-05; Knowldege Systems Laboratory, Stanford University: Palo, CA, USA, 2001. [Google Scholar]
- Qiu, Q.; Xie, Z.; Wu, L.; Tao, L.; Li, W. BiLSTM-CRF for geological named entity recognition from the geoscience literature. Earth Sci. Inform. 2019, 12, 565–579. [Google Scholar] [CrossRef] [Scilit]
- Meng, F.; Yang, S.; Wang, J.; Xia, L.; Liu, H. Creating Knowledge Graph of Electric Power Equipment Faults Based on BERT–BiLSTM–CRF Model. J. Electr. Eng. Technol. 2022, 17, 2507–2516. [Google Scholar] [CrossRef] [Scilit]
- Cui, Y.M.; Che, W.X.; Liu, T.; Qin, B.; Yang, Z.Q. Pre-Training with Whole Word Masking for Chinese BERT. In Proceedings of the IEEE/ACM Transactions on Audio, Speech, and Language Processing, Maynooth, Ireland, 28 July–1 August 2015; IEEE: Piscataway, NJ, USA, 2021; Volume 29, pp. 3504–3514. [Google Scholar] [CrossRef] [Scilit]
- Li, D.Y.; Yan, L.; Yang, J.Z.; Ma, Z.M. Dependency syntax guided BERT-BiLSTM-GAM-CRF for Chinese NER. Expert Syst. Appl. 2022, 196, 116682. [Google Scholar] [CrossRef] [Scilit]
- Chen, T.; Xu, R.F.; He, Y.L.; Wang, X. Improving sentiment analysis via sentence type classification using BiLSTM-CRF and CNN. Expert Syst. Appl. 2017, 72, 221–230. [Google Scholar] [CrossRef] [Scilit]
- Arslan, S. Application of BiLSTM-CRF model with different embeddings for product name extraction in unstructured Turkish text. Neural Comput. Appl. 2024, 36, 8371–8382. [Google Scholar] [CrossRef] [Scilit]
- Francis, N.; Green, A.; Guagliardo, P.; Libkin, L.; Lindaaker, T.; Marsault, V.; Plantikow, S.; Rydberg, M.; Selmer, P.; Taylor, A. Cypher: An Evolving Query Language for Property Graphs. In Proceedings of the 2018 International Conference on Management of Data, Houston, TX, USA, 10–15 June 2018; pp. 1433–1445. [Google Scholar] [CrossRef] [Scilit]
- Monteiro, J.; Sá, F.; Bernardino, J. Experimental Evaluation of Graph Databases: JanusGraph, Nebula Graph, Neo4j, and TigerGraph. Appl. Sci. 2023, 13, 5770. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).