


Highlights
What are the main findings?
- A latent-space guided transfer learning framework (LGT-SAR) is introduced to explicitly bridge 2D single-look despeckling and 3D spatio-temporal modeling via latent-space regularization, enabling effective knowledge transfer for multi-temporal SAR despeckling.
- The proposed method achieves stronger detail and edge preservation while despeckling.
What are the implications of the main findings?
- The approach provides a practical way to train robust multi-temporal despeckling models under limited multi-temporal samples by reusing mature single-image priors, mitigating over-smoothing and structural distortion.
- The fully convolutional design supports variable-length temporal inputs, improving adaptability to different acquisition/sampling conditions and facilitating deployment across diverse SAR time-series scenarios.
Abstract
Synthetic Aperture Radar (SAR) images are affected by speckle noise, which limits their application in fine object interpretation and quantitative analysis. Recent deep learning-based single-image SAR despeckling methods have made significant progress in spatial structure modeling but struggle to exploit temporal redundancy in multi-temporal data. Existing multi-temporal despeckling methods usually rely on complex spatiotemporal network structures, which are prone to overfitting or excessive smoothing of details when training samples are limited. To address these challenges, this paper proposes a latent-space-guided multi-temporal SAR despeckling method from the perspective of transfer learning and representation alignment, achieving effective knowledge transfer from single-image SAR despeckling to multi-temporal despeckling tasks. The method treats the single-image SAR despeckling task as a knowledge source domain, using stable latent space representations learned from the pre-trained single-image despeckling model as prior constraints. A latent space regularization mechanism is introduced during the training of the multi-temporal despeckling model, thereby establishing an explicit representation bridge between the 2D spatial model and the 3D spatiotemporal model. With this strategy, the multi-temporal model inherits the structural perception capability of the single-image model under limited training samples, improving speckle suppression while effectively maintaining image detail and structural consistency. Additionally, a pure convolutional network architecture is employed to support variable-length multi-temporal sequence input, enhancing the method’s adaptability under different temporal sampling conditions.
1. Introduction
Synthetic Aperture Radar (SAR) images are inevitably affected by speckle noise due to their coherent imaging mechanism, which severely limits their application in fine object interpretation and quantitative analysis. Over the years, single-image (single-temporal) SAR despeckling has been a fundamental issue in SAR image preprocessing, and has been extensively researched in areas such as statistical modeling, non-local filtering, and deep learning. These methods have gradually formed a set of stable single-image despeckling models with strong performance in spatial structure modeling. However, with the enhancement of multi-temporal SAR data acquisition capabilities, a key challenge now is how to effectively transfer the mature models and knowledge accumulated in single-image to multi-temporal SAR despeckling scenarios. Unlike merely redesigning multi-temporal network structures, this problem essentially involves cross-task and cross-dimensional representation transfer and a paradigm shift in modeling—specifically, how to achieve an effective transition from 2D spatial modeling to 3D spatio-temporal joint modeling.
Traditional single-image despeckling methods primarily utilize spatial neighborhood or statistical characteristics for filtering. Such methods often struggle to balance speckle suppression and detail preservation in complex textured regions [1,2]. Conventional single-image despeckling methods [3,4], including those based on statistical modeling, filter design, and non-local methods, can reduce speckle to some extent, but often result in detail loss or over-smoothing in areas with complex textures. With the improvement in remote sensing data acquisition capabilities, the acquisition of multi-temporal SAR image sequences has gradually become feasible, providing a new source of information for speckle suppression. Multi-temporal despeckling methods enhance speckle suppression by fusing images of the same scene taken at different times, leveraging temporal redundancy, while minimizing the loss of structural information. For example, the Ratio-Based multi-temporal despeckling method [5] constructs ratio images from time-averaged images, enabling single-image despeckling methods to operate more effectively in multi-temporal environments. The multi-temporal SAR despeckling algorithm MSAR-BM3D [6], an extension of single-image SAR-BM3D [7], performs block matching and collaborative filtering in both the spatial and temporal domains, achieving superior speckle suppression in multi-temporal data. MSAR-BM3D [6] utilizes the self-similarity of images, matching repeated structures spatially while integrating redundant information across time sequences, thereby achieving better speckle noise removal performance and detail preservation than traditional methods.
In recent years, deep learning methods have shown significant advantages in image despeckling tasks and have gradually been extended to SAR despeckling. Single-image despeckling methods based on Convolutional Neural Networks (CNNs) [8,9,10,11], which learn nonlinear mappings from noisy observations to clean targets, have achieved excellent results in single-image despeckling. However, these methods overlook the temporal redundancy information, limiting the full utilization of multi-temporal data. To address this limitation, recent studies have begun to incorporate temporal information into deep SAR despeckling frameworks [12,13,14]. For instance, ISSMSAR [15] integrates multi-temporal information for joint speckle reduction and super-resolution, showing the potential of deep networks in exploiting temporal redundancy. To further improve multi-temporal despeckling performance, recent studies have attempted to extend deep networks to spatio-temporal modeling by introducing temporal feature interaction, cross-temporal fusion modules, and dedicated spatio-temporal learning strategies to capture temporal consistency and spatial structural information [16,17]. These efforts aim to more effectively exploit time correlations in multi-temporal stacks, thereby improving noise suppression and detail preservation.
Although multi-temporal despeckling methods have made progress, many challenges remain. On the one hand, multi-temporal image sequences are limited by acquisition costs, satellite orbital cycles, and other factors, leading to a scarcity of data and making it difficult to adequately train spatio-temporal models. On the other hand, maintaining image structural details while suppressing speckle, and avoiding excessive smoothing, continues to be a research challenge. Therefore, introducing effective prior knowledge into multi-temporal SAR despeckling has become an important research direction [2,18]. Some studies have improved multi-temporal despeckling performance by combining time-averaged information with deep networks, such as enhancing noise reduction by combining ratio images with deep networks [19]. Additionally, self-supervised learning frameworks have been proposed to alleviate the problem of the lack of noise-labeled data in real SAR images [20,21], but these methods still rely on a large amount of multi-temporal data characteristics for training.
To address these challenges, this paper proposes a latent-space guided multi-temporal SAR despeckling method from the perspective of transfer learning and representation alignment. The latent space refers to the intermediate features extracted by the encoder when processing input data, capturing key information that guides the decoder to generate output images. Unlike existing methods that primarily rely on complex spatio-temporal network structures to mine multi-temporal information, we believe that the core challenge in multi-temporal SAR despeckling lies in effectively utilizing the stable spatial representations learned in single-image SAR despeckling models and transferring them to spatio-temporal modeling tasks. To achieve this, we treat the single-image SAR despeckling task as the source domain and use the stable latent representations learned by the pre-trained single-image SAR despeckling model to provide supervision and prior constraints in the multi-temporal despeckling model’s training process. We introduce a latent-space regularization mechanism, establishing an explicit representation bridge and knowledge transfer between the 2D spatial model and the 3D spatio-temporal model. This strategy not only improves model training stability and generalization under the condition of limited multi-temporal training samples but also effectively mitigates the over-smoothing and structural distortion issues in traditional multi-temporal methods. Moreover, this paper adopts a purely convolutional neural network architecture, which supports variable-length multi-temporal sequence input, enhancing the method’s adaptability and practicality under different temporal sampling conditions.
The main contributions of this work can be summarized as follows:
- We propose a latent-space-guided transfer learning framework for multi-temporal SAR despeckling, which establishes an explicit bridge from single-image SAR despeckling to 3D spatio-temporal modeling.
- We design an encoder–decoder latent-space regularization mechanism, through which the trainable 3D multi-temporal model is constrained by the stable priors learned from a pretrained 2D single-image model.
- We develop a pure convolutional multi-temporal despeckling network with transferable initialization, which supports variable-length temporal input and improves training stability under limited multi-temporal training samples.
2. Materials and Methods
This section presents the methodological and experimental foundations of the proposed LGT-SAR framework. We first introduce the basic idea of latent-space-guided transfer learning and the associated regularization design. We then describe the network structure, workflow, and loss functions, followed by the construction of the training dataset, the experimental data used in this study, and the training strategy adopted for model optimization.
2.1. Basic Idea
The core idea of the proposed method, Latent-Space Guided Multi-Temporal SAR Despeckling (LGT-SAR), is not to rely solely on the temporal modeling capability of the multi-temporal network itself. Instead, from the perspective of transfer learning, it introduces the well-trained latent representations learned from the single-image SAR despeckling task into the training process of the multi-temporal despeckling model. In this paper, the latent space refers to the intermediate feature representation produced by the encoder before decoding. By explicitly introducing latent-space alignment constraints, the multi-temporal model can inherit the spatial structure perception capability of the single-image model under limited training data, thereby enabling an effective transition from single-image SAR despeckling to multi-temporal SAR despeckling.
2.1.1. Transfer Strategy Based on Single-Image Priors
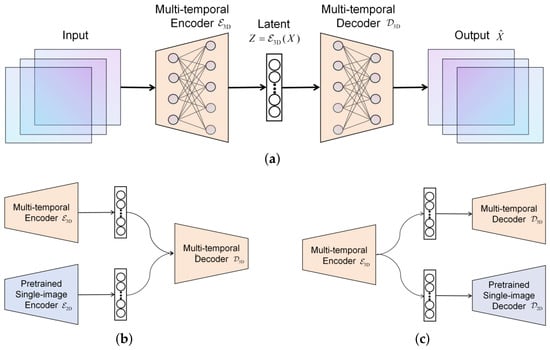
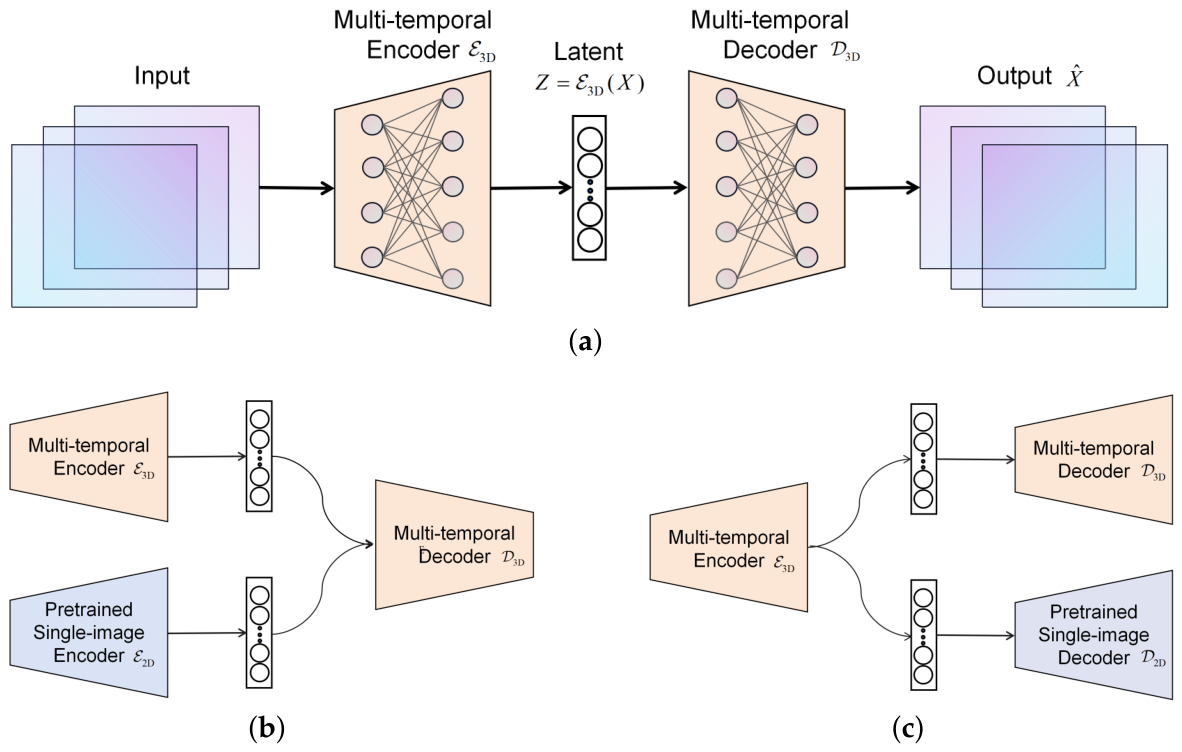
As illustrated in Figure 1, the proposed framework follows a transfer-learning paradigm from a pretrained 2D single-image SAR despeckling model to a trainable 3D multi-temporal despeckling model. The main idea is to use the pretrained 2D model as a prior knowledge source and introduce its stable spatial representations into the 3D spatio-temporal modeling process. Specifically, a 2D convolutional despeckling network is first trained on single-image SAR data to learn discriminative spatial structural features. Then, a 3D multi-temporal model is constructed by extending the 2D convolution kernels along the temporal dimension, which are further used to initialize the parameters of the 3D network. On this basis, latent-space alignment regularization is introduced so that the 3D multi-temporal model can inherit and utilize the prior representations learned by the 2D single-image model during training.
Figure 1.
Overview of the proposed LGT-SAR framework. (a) Main multi-temporal inference path, where the co-registered input sequence is encoded by the 3D encoder and reconstructed by the 3D decoder to produce the despeckled multi-temporal output . (b) Schematic illustration of the encoder-side latent-space regularization branch. (c) Schematic illustration of the decoder-side latent-space regularization branch.
2.1.2. Encoder–Decoder Latent-Space Regularization Design
During training, latent-space regularization constraints are introduced at both the encoder and decoder sides to achieve cross-model alignment. On the encoder side, we aim to ensure that the latent representations learned by the 3D multi-temporal model remain compatible with those extracted by the pretrained 2D single-image encoder. On the decoder side, we further require that the latent representation generated by the 3D encoder can still be meaningfully interpreted by the pretrained 2D single-image decoder. In this way, explicit cross-model supervision is established between the pretrained 2D model and the trainable 3D model, which constrains the 3D spatio-temporal representation space to remain close to the prior distribution learned from the single-image task.
It should be noted that Figure 1 provides only a high-level conceptual illustration of the proposed framework. The detailed interactions among the main reconstruction branch, the encoder-side regularization branch, and the decoder-side regularization branch are presented more explicitly in the following subsections.
2.2. Network Structure
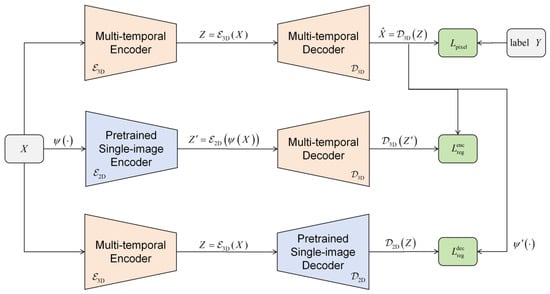
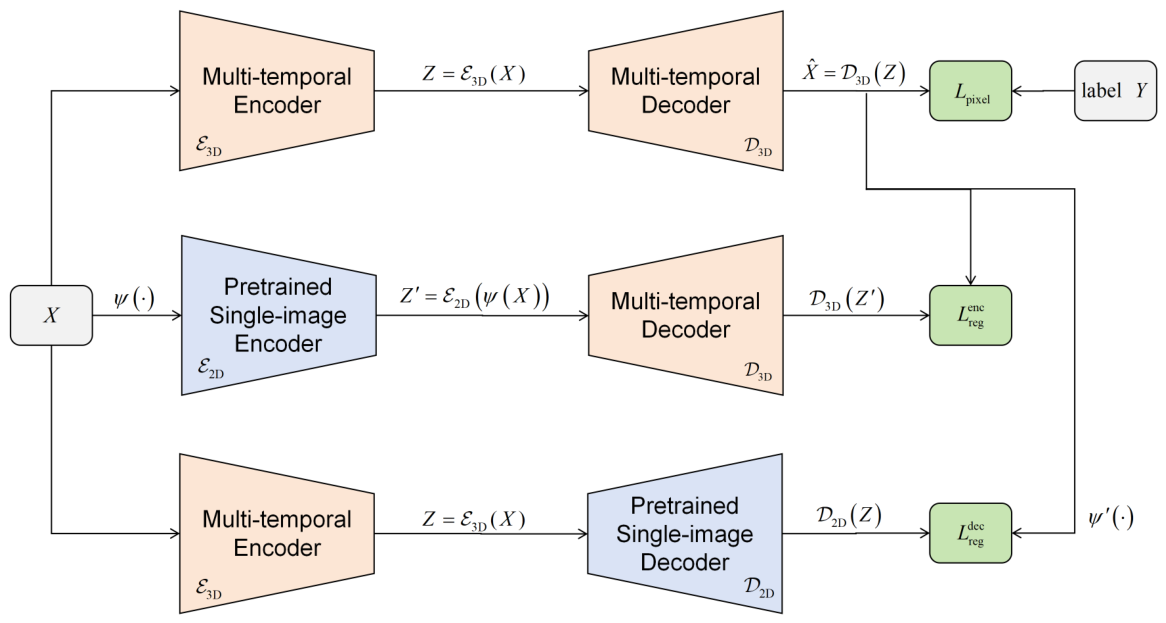
The proposed method is based on transfer learning and aims to guide the training of the multi-temporal SAR despeckling model by utilizing the spatial structure priors learned from a single-image SAR despeckling model. Based on this idea, we construct an end-to-end multi-temporal autoencoder network, as illustrated in Figure 2. This network consists of one main reconstruction branch and two auxiliary cross-model regularization branches. The main branch is formed by a trainable 3D multi-temporal encoder–decoder pair, while the auxiliary branches involve a pretrained 2D single-image encoder–decoder pair.
Figure 2.
Framework of the proposed LGT-SAR method. The top branch is the main multi-temporal reconstruction pathway, the middle branch shows the encoder-side regularization, and the bottom branch shows the decoder-side regularization.
The input multi-temporal sequence is denoted as , where T represents the number of temporal frames and denotes the spatial dimensions of each frame. The output, , is the despeckled multi-temporal sequence. The multi-temporal encoder adopts a 3D convolutional structure to extract spatio-temporal features layer by layer and generate the latent representation
The corresponding multi-temporal decoder progressively upsamples and fuses these features to reconstruct the final output
The pretrained single-image model is represented by and , which have been trained on single-image SAR despeckling data to suppress speckle while preserving spatial structures.
Under this architecture, the model performs spatial modeling through the pretrained 2D prior branch and spatio-temporal modeling through the trainable 3D branch. Compared with a conventional 2D single-image despeckling network, the proposed method extends part of the convolutional layers into 3D convolutions, allowing the network to capture both spatial structures and temporal correlations in multi-temporal SAR image stacks.
The adopted architecture is entirely convolutional, which offers several advantages. First, 3D convolution kernels share weights across both spatial and temporal dimensions, enabling efficient extraction of local spatio-temporal features while reducing the number of parameters and the risk of overfitting under limited training data. Second, compared with models involving complex gating or attention mechanisms, a fully convolutional network is easier to optimize and tends to yield more stable training. Third, the convolutional structure naturally facilitates transfer learning: the pretrained 2D convolution kernels from the single-image model can be directly extended and reused in the 3D multi-temporal network, which accelerates convergence and improves the effectiveness of spatio-temporal feature initialization.
2.3. Network Workflow
As shown in Figure 2, the proposed framework contains one main multi-temporal reconstruction branch and two auxiliary cross-model regularization branches. The top branch is the main reconstruction pathway and is the only branch used during inference. Given the input sequence X, the trainable 3D encoder first extracts the latent representation Z, and the trainable 3D decoder then reconstructs the despeckled multi-temporal output .
To further enhance the despeckling performance of the multi-temporal model, two auxiliary cross-model supervision branches are introduced during training. These branches use the pretrained 2D single-image model as a latent-space teacher and regularize both the encoder and decoder of the 3D network.
In the encoder-side regularization branch, the mapped single-image input is first processed by the pretrained 2D encoder to obtain 2D-compatible latent features, which are then decoded by the 3D decoder . This branch encourages the 3D decoder to correctly interpret latent features originating from the pretrained 2D encoder.
In the decoder-side regularization branch, the latent representation generated by the 3D encoder is further decoded by the pretrained 2D decoder . This branch constrains the 3D encoder to produce latent features that remain compatible with the feature space of the pretrained 2D model.
Here, denotes a temporal-to-single mapping operator that converts the multi-temporal input sequence into a single-image representation suitable for the pretrained single-image encoder . In this work, is implemented as a temporal averaging operation, where the averaging range is matched to the temporal compression behavior of the multi-temporal encoder.
Similarly, denotes the output-side mapping operator used to project the reconstructed multi-temporal output into the single-image domain, so that it can be directly compared with the output of the pretrained single-image decoder . For consistency, follows the same temporal averaging principle as .
Therefore, during training, the framework contains one main 3D reconstruction path and two auxiliary regularization paths. The main path produces the final despeckling output, while the two auxiliary paths are used only to construct latent-space alignment losses. During inference, the final despeckled result is generated solely by the main 3D encoder–decoder branch.
2.4. Training Loss Function Design
In multi-temporal SAR despeckling tasks, directly training a 3D spatio-temporal model may lead to unstable or shifted latent-space representations, especially when training data are limited. To address this issue, the proposed method does not merely use the single-image model as an initialization tool, but instead employs it as a prior constraint source. By introducing latent-space regularization, the training of the multi-temporal model is continuously guided toward a representation space compatible with the pretrained 2D model.
To effectively incorporate the prior knowledge from the pretrained single-image model into the training of the multi-temporal model, we introduce encoder-side and decoder-side regularization strategies [22] in addition to the conventional pixel-domain speckle suppression loss. Two regularization terms are designed to align the latent spaces of the 2D and 3D models.
2.4.1. Encoder Latent-Space Alignment
The encoder-side regularization aims to enforce consistency between the latent representations learned from the pretrained single-image encoder and those learned from the trainable multi-temporal encoder. Given the input multi-temporal sequence X, the main reconstruction branch first produces
Meanwhile, the mapped single-image representation is fed into the pretrained single-image encoder to obtain
This latent representation is then decoded by the multi-temporal decoder:
The encoder-side regularization loss is defined as
This loss encourages the multi-temporal decoder to correctly interpret the latent features provided by the pretrained single-image encoder, thereby improving the compatibility between the 2D and 3D feature spaces.
2.4.2. Decoder Output Alignment
The decoder-side regularization aims to constrain the latent representation generated by the multi-temporal encoder so that it remains compatible with the pretrained single-image decoder. Given the latent feature
the pretrained single-image decoder produces
Since operates in the single-image domain, the reconstructed multi-temporal output is projected to the corresponding single-image representation through :
The decoder-side regularization loss is defined as
This regularization ensures that the latent representation learned by the multi-temporal encoder stays close to the representation space that can be correctly decoded by the pretrained single-image decoder.
2.5. Total Loss Function
The total loss function consists of the basic pixel-domain speckle suppression loss, the encoder latent-space alignment loss, and the decoder output alignment loss.
Define the pixel-domain speckle suppression loss as the error between the model output and the reference label Y:
Finally, the optimization objective of the model is the weighted sum of all the losses:
where and are hyperparameters that balance the importance of the encoder and decoder alignment losses, which are introduced in Section 2.4.1 and Section 2.4.2, respectively.
By introducing the above regularization terms, knowledge from the pretrained single-image model is incorporated into the training of the multi-temporal model. ensures that the multi-temporal decoder can correctly utilize latent features coming from the pretrained 2D encoder, maintaining the ability to reconstruct spatial details. guides the multi-temporal encoder to extract features that do not deviate from the pretrained single-image feature distribution, thereby enhancing the reliability of spatio-temporal feature extraction. Together, these terms establish a latent-space consistency constraint between the multi-temporal model and the single-image model, which improves despeckling performance under limited multi-temporal data and also enhances training stability and convergence speed.
2.6. Training Dataset Construction
In SAR despeckling, fully speckle-free references are generally unavailable. To construct paired training samples, we adopt a physics-inspired, scatterer-based echo simulation coupled with a band-limited SAR image formation model. This simulation follows the data-generation framework previously presented in our SAR-SPD work [8].
We begin from a reflectivity proxy extracted from real SAR patches and construct an over-sampled scatterer map on a fine grid (with spacing ). Specifically, for each output-resolution pixel, the corresponding resolution cell contains sub-scatterers; in this work we use (i.e., a sampling on the finest grid). The sub-pixel locations of these scatterers are represented by the over-sampled grid points within each output pixel support, so that each output pixel is formed by the coherent superposition of multiple sub-scatterers rather than a single point target.
For the multi-temporal setting, each acquisition indexed by t is simulated independently using the corresponding original SAR amplitude patch at time t. Importantly, the amplitude parameter in our simulator is not generated by an autoregressive or random evolution model; instead, it is directly taken from the original data. Concretely, for the i-th sub-scatterer at time t, we assign a complex coefficient
where is obtained from the original SAR amplitude and used as the scattering/reflectivity proxy mapped onto the over-sampled grid, and accounts for the deterministic propagation phase relative to a reference slant range . Denoting the slant-range coordinate of the i-th sub-scatterer by , the simulator applies
where is the radar wavelength.
Given the complex scatterer field at each acquisition, the SAR image formation effect is modeled via a separable two-dimensional band-limited impulse response constructed from sinc functions in azimuth and range. Let and denote the azimuth-time and range-time sampling grids determined by the simulator parameters. The azimuth and range kernels are defined as
where is the Doppler bandwidth determined by the platform/antenna setting and target azimuth resolution, and is the chirp bandwidth determined by the target range resolution. The 2-D impulse response is then
and the focused complex image on the over-sampled grid is obtained by a 2-D convolution with amplitude normalization
where v is the platform velocity and C is the speed of light. Finally, is downsampled by factors to match the desired output resolutions , producing the simulated complex SAR image. Here, is a normalization coefficient that reflects the scaling effect of the system bandwidth and acquisition geometry on the focused SAR response; denotes the sampling spacing of the over-sampled simulation grid; and and denote the downsampling factors in the azimuth and range directions, respectively, which are used to convert the over-sampled simulated image to the target output resolution.
Through coherent superposition followed by band-limited imaging, the simulated observations naturally exhibit speckle-like fluctuations while preserving the structural content inherited from the original amplitude proxy. Since the real multi-temporal data stacks used in this work are pre-coregistered, the simulated inputs and the corresponding reference patches can be paired in a pixel-wise manner without introducing additional registration steps in the dataset construction. Finally, the simulated multi-temporal speckled sequence serves as the network input, while the corresponding original SAR patches serve as the reference label for supervised learning, yielding training pairs with realistic speckle appearance and consistent scene structure. The simulation pipeline is used only for offline training-data construction and is not part of the inference workflow of LGT-SAR.
2.7. Experimental Data Description
All experiments are conducted on real spaceborne SAR data acquired by the TanDEM-X (TDX-1) mission. We use Level 1B SSC products. This product type preserves the in-phase/quadrature samples, enabling the formation of amplitude representations used for network training. Table 1 summarizes key parameters reported in the metadata.
Table 1.
Key parameters of the TanDEM-X (TDX-1) Spotlight SSC (Level 1B) product used in this work.
We consider a multi-temporal despeckling setting, where multiple SSC acquisitions over the same area are organized into a temporal stack. Specifically, each training sample in this work is composed of a sequence of co-registered acquisitions. For each acquisition, the complex image is converted to amplitude as
where S denotes the complex SSC sample.
To enable pixel-wise temporal learning, all temporal images are co-registered to a chosen reference acquisition to achieve accurate alignment. Training samples are generated by cropping fixed-size patches of size from the aligned amplitude stacks. Therefore, each sample can be written as
where denotes the co-registered amplitude patch at time index t.
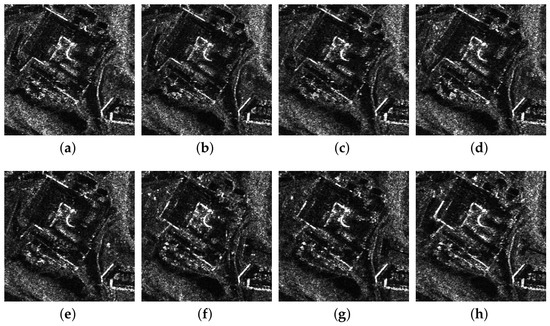
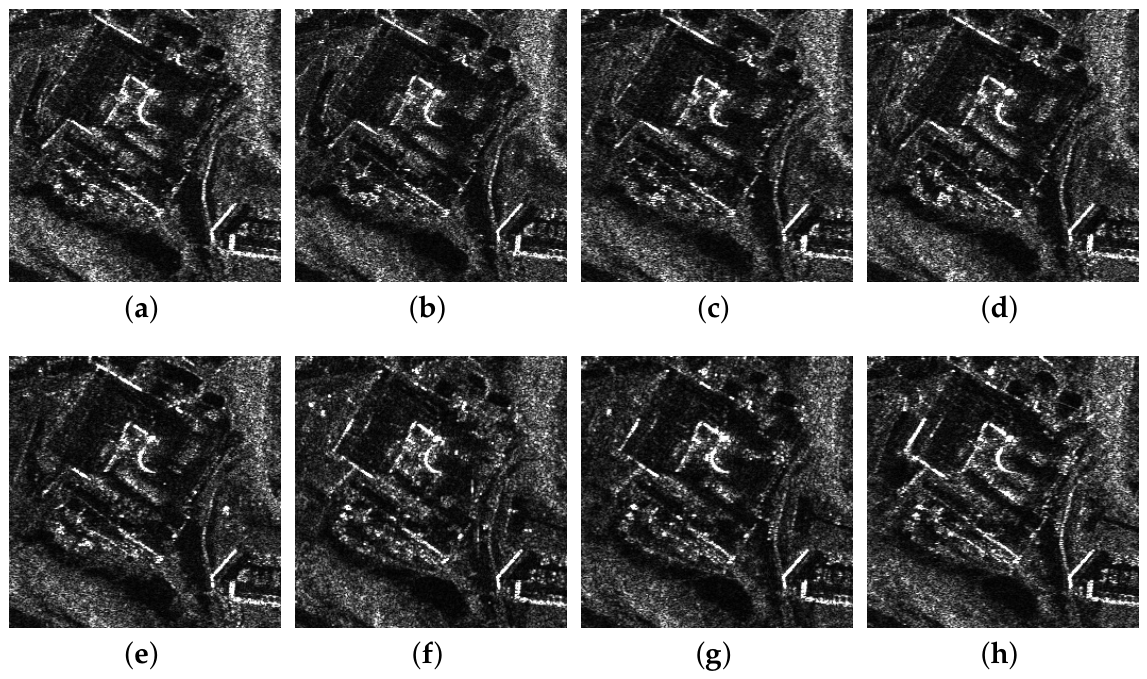
Figure 3 presents representative examples of the constructed multi-temporal amplitude patches. Each example corresponds to the same spatial region observed at time instants, illustrating both the strong temporal consistency of underlying backscatter structures and the apparent multiplicative speckle fluctuations across acquisitions. These examples motivate the use of temporal redundancy to improve despeckling performance.
Figure 3.
SAR data examples. (a–h) Co-registered SAR amplitude patches cropped at the same spatial location, corresponding to the first to eighth temporal acquisitions, respectively.
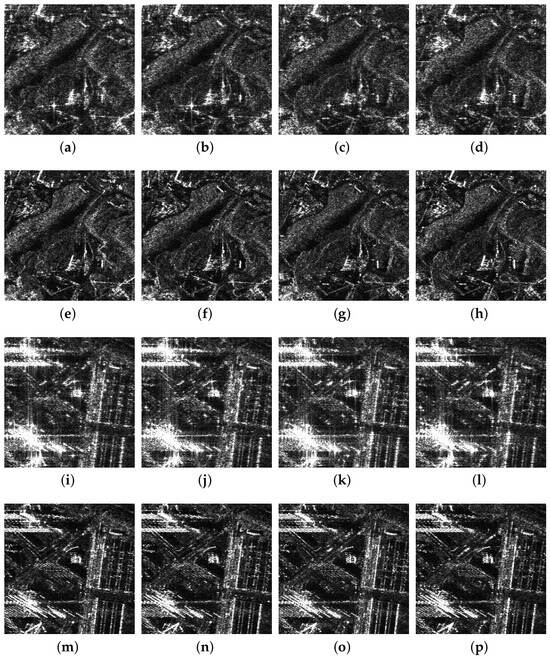
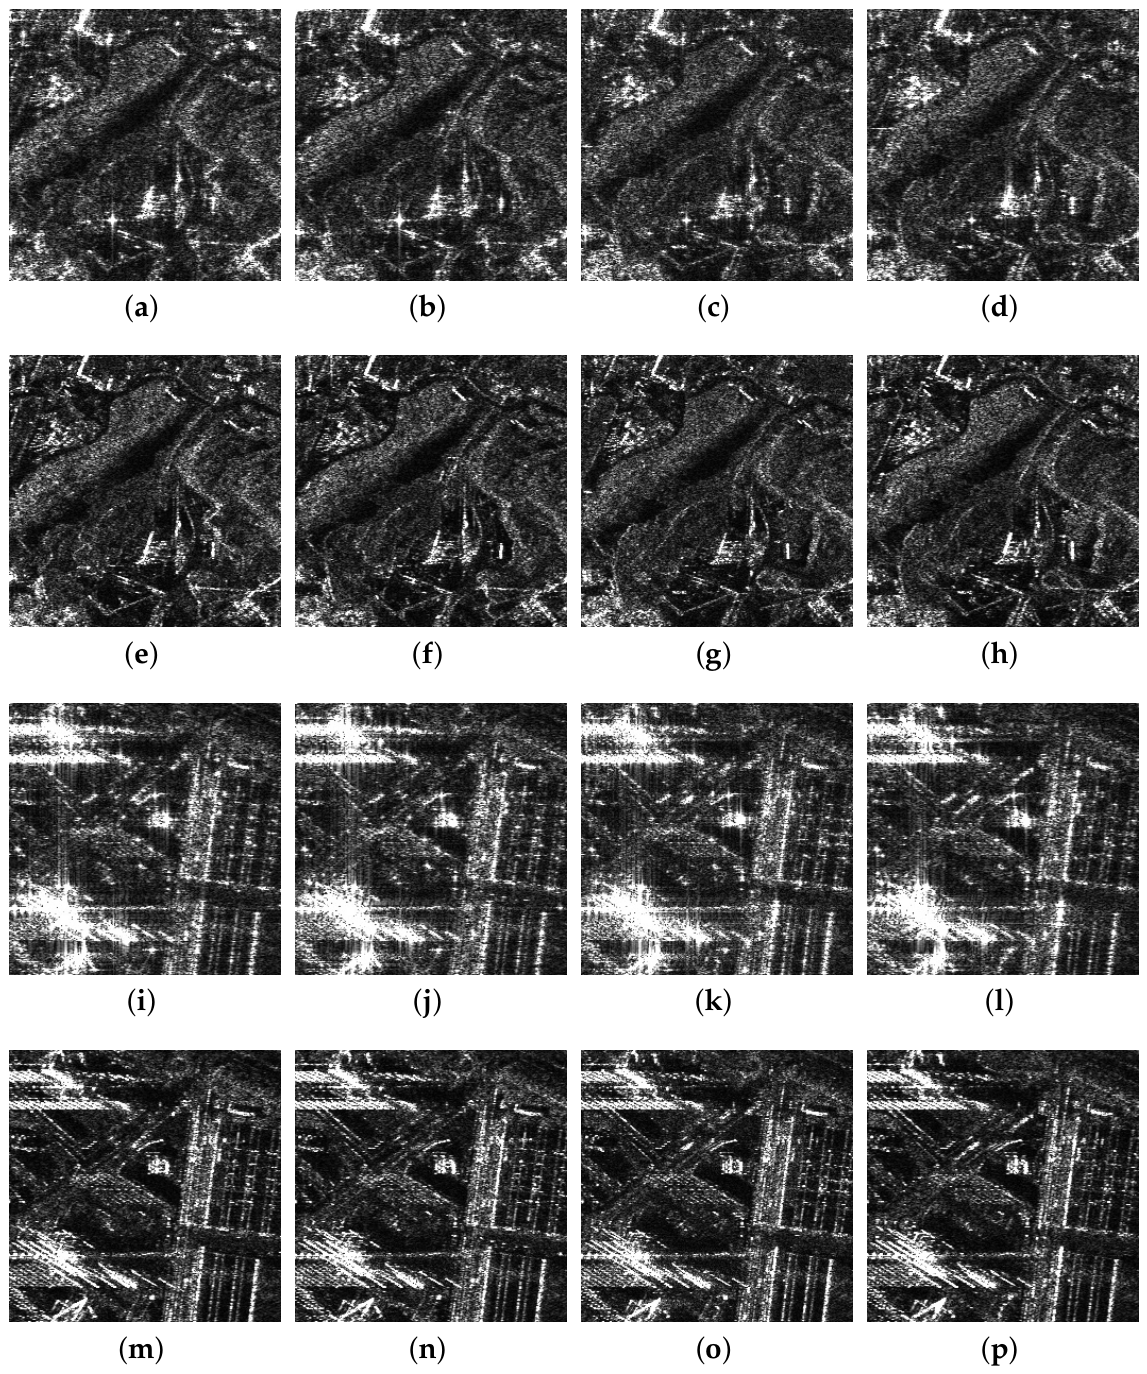
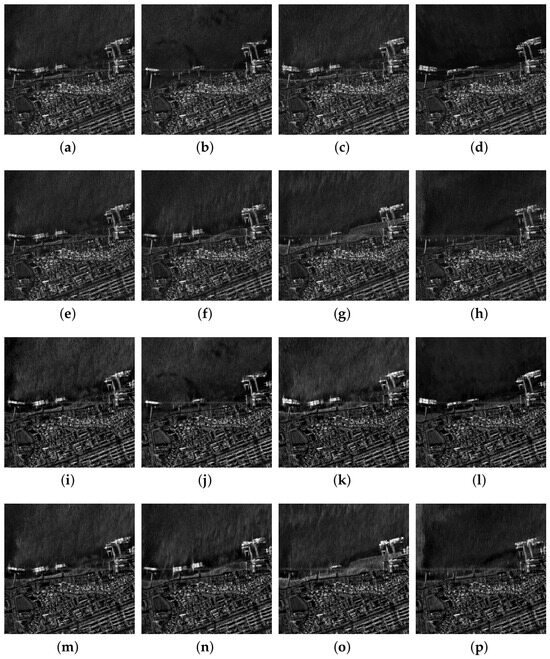
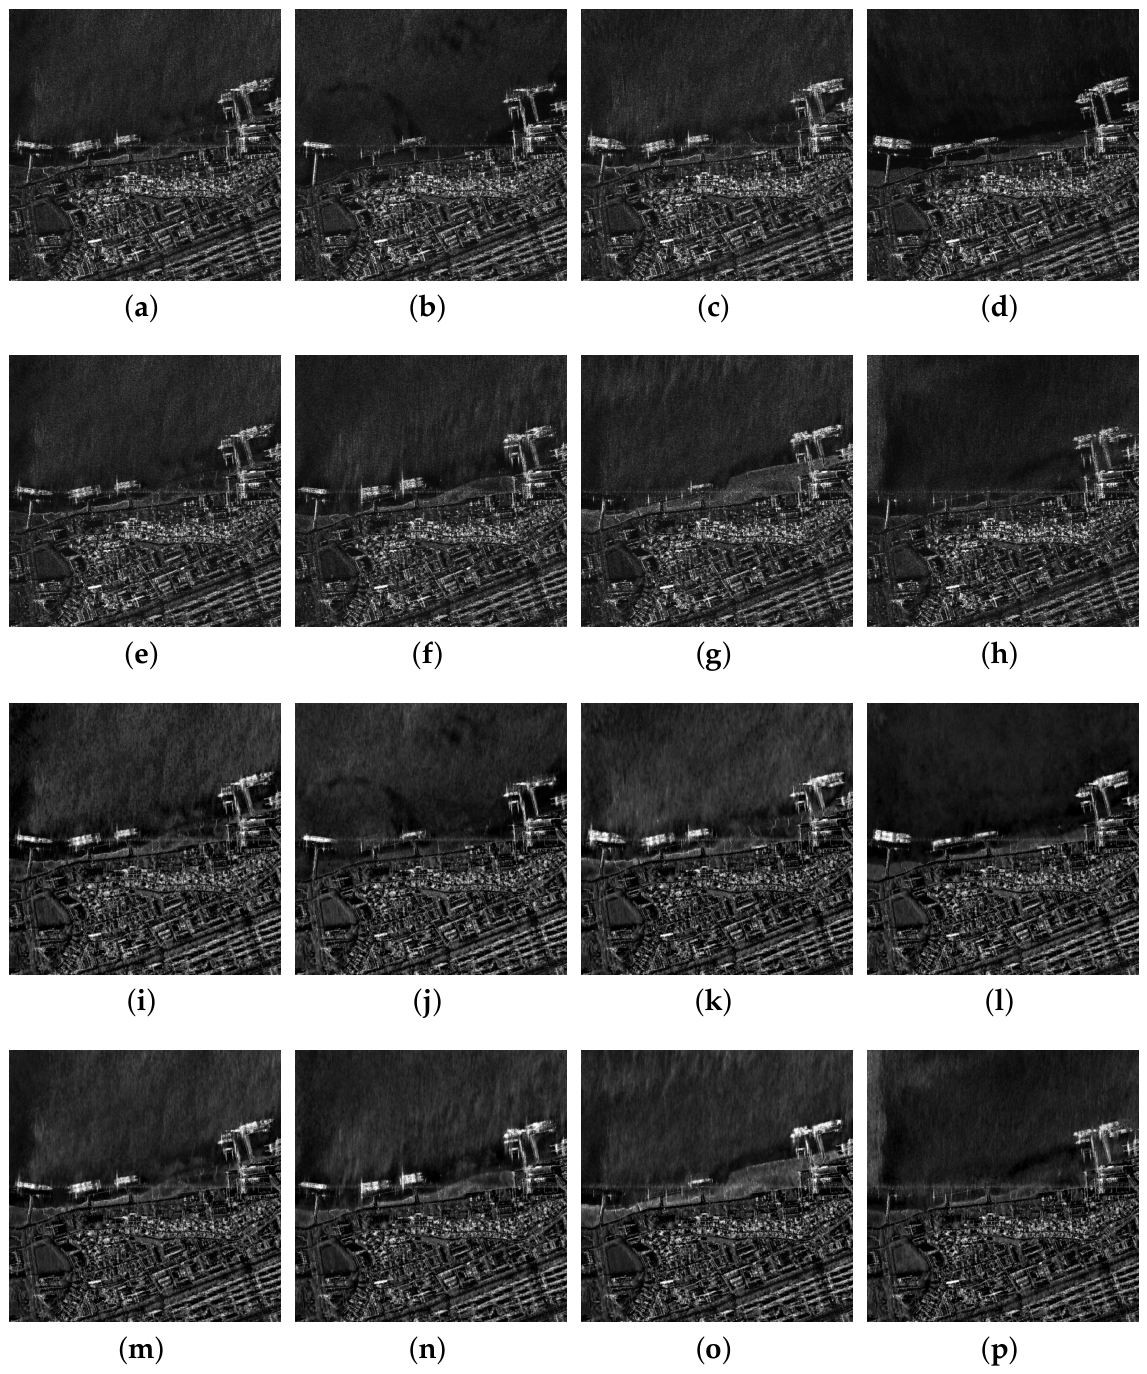
Figure 4 presents representative examples of the training data constructed from the original multi-temporal SAR dataset using the simulation pipeline described in Section 2.6. Unlike Figure 3, which only shows the original temporal SAR stack, Figure 4 includes both the simulated noisy inputs and the corresponding original SAR labels. Specifically, Figure 4 shows two different scenes, and for each scene, four temporal acquisitions are displayed for clarity. The first and third rows show the simulated speckled inputs, while the second and fourth rows show the corresponding original SAR amplitude patches used as labels.
Figure 4.
Examples of the constructed training dataset. (a–d) Simulated speckled inputs of Scene 1 at four selected temporal acquisitions; (e–h) corresponding original SAR amplitude labels of Scene 1; (i–l) simulated speckled inputs of Scene 2 at four selected temporal acquisitions; (m–p) corresponding original SAR amplitude labels of Scene 2.
Figure 4a–d,i–l show the simulated speckled observations used as network inputs, where the coherent superposition of sub-scatterers and the subsequent band-limited imaging naturally produce realistic speckle fluctuations while preserving the main scene structures. Figure 4e–h,m–p show the corresponding labels, whose amplitude is directly taken from the original SAR data at acquisition t and thus retains the underlying reflectivity patterns. For clarity, four acquisitions are displayed from a multi-temporal stack with .
2.8. Training Strategy
To ensure continuity and stability during the knowledge transfer from the single-image model to the multi-temporal model, we adopt a weight-transfer initialization strategy based on a pretrained single-image network.
Specifically, to effectively leverage the pretrained 2D single-image despeckling model, we initialize the 3D multi-temporal network by transferring the 2D weights via kernel inflation. For some convolutional layers, the pretrained spatial kernel is embedded into the corresponding spatiotemporal kernel by copying the 2D weights to the 3D kernel, while setting the newly introduced parameters along the temporal dimension to zero at initialization. With this design, the temporal convolution in each 3D layer is effectively inactive at the beginning of training, which guarantees that, when a single-image is provided as input, the output of the 3D multi-temporal network remains consistent with that of the original pretrained 2D network.
This initialization strategy not only accelerates the convergence of the multi-temporal network, it also prevents degradation of despeckling performance on single images. Overall, the proposed encoder–decoder architecture models temporal correlations through 3D convolutions, while fully inheriting the mature spatial feature extraction capability of the pretrained 2D single-image model.
3. Results
This section reports the experimental results of the proposed LGT-SAR method on real multi-temporal SAR data. We first compare LGT-SAR with representative baseline methods, then present its temporal despeckling behavior, and finally examine its qualitative robustness across diverse land-cover scenes.
3.1. Real SAR Image Comparison Experiment
To verify the effectiveness and robustness of the proposed multi-temporal despeckling method based on latent space-guided transfer learning in real-world scenarios, comparative experiments were conducted on real SAR images.
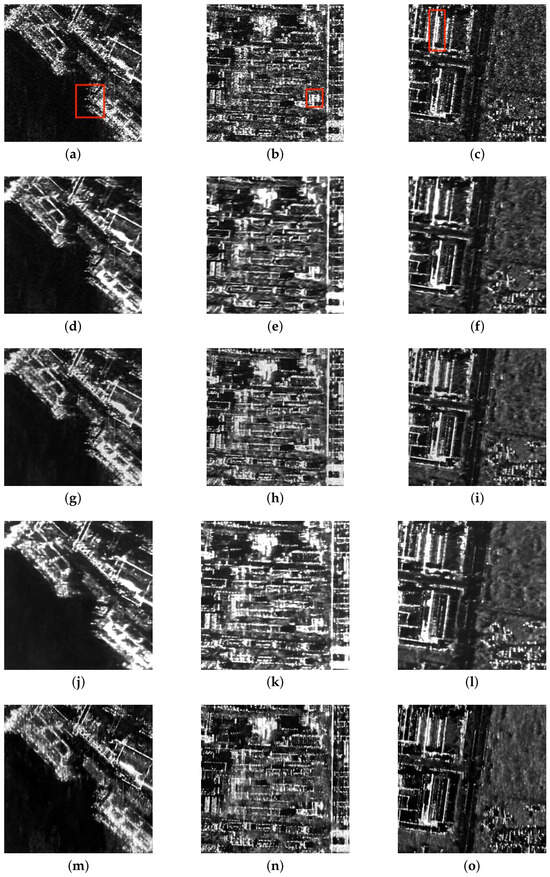
In this study, we performed comparison experiments evaluating the performance of the SDUDNet [23], MSAR-BM3D algorithm [6], multitemporal MERLIN algorithm [16], and the proposed method LGT-SAR in this section. Figure 5 shows the visual comparison of typical experimental examples.
Figure 5.
Comparison of despeckling effects of different despeckling methods on real SAR images. (a–c) Original SAR images of three representative scenes; (d–f) SDUDNet results; (g–i) MSAR-BM3D results; (j–l) multitemporal MERLIN results; (m–o) proposed LGT-SAR results. The three columns correspond to different experimental scenes.
As shown in Figure 5, the original SAR image contains significant speckle, resulting in blurred texture details. After processing with the multi-temporal speckle suppression algorithm, the image quality improves to varying degrees. Observing the red box region of the scene in the first column of Figure 5, which contains numerous strong scatterers, the proposed method preserves the strong scatterer details the best, while the others result in more blurred details of the strong scatterers. Observing the red box regions in the second and third columns of Figure 5, the proposed method best restores rich texture details and structural edges. This advantage stems not only from the 3D convolution’s joint modeling of temporal sequence correlations but also from the latent space alignment constraint guiding the model’s representational space, allowing the multi-temporal model to inherit the single-image model’s perceptual ability for structure and texture during the despeckling process.
Table 2 presents the comparison results of quantitative evaluation metrics. EPI (Edge Preservation Index) measures how much edge information is preserved while suppressing noise in the image. A higher EPI value indicates better preservation of edges and details. The proposed method achieves the best EPI performance, indicating a significant advantage in preserving image structure and details. STD (Standard Deviation) quantifies the noise fluctuation in the image, where a lower value signifies better noise suppression. The proposed method outperforms other methods in terms of STD, demonstrating its ability to better utilize temporal information and eliminate random noise fluctuations in multi-temporal image processing, thus achieving better noise suppression. ENL (Equivalent Number of Looks) measures the overall smoothness of the SAR image. In Table 2, the proposed method shows a higher ENL value compared to SDUDNet and MSAR-BM3D, but slightly lower than multitemporal MERLIN. It should be noted that multitemporal MERLIN achieves a higher ENL through stronger temporal smoothing, which, however, results in significant detail loss. In contrast, the proposed method achieves a more balanced performance in terms of ENL, EPI, and STD.
Table 2.
Quantitative assessment results.
This result further confirms that, through the latent space-guided transfer learning mechanism, the proposed multi-temporal model LGT-SAR can maintain temporal consistency while avoiding excessive smoothing, thereby stably inheriting the structural priors already learned from the single-image model.
3.2. Multi-Temporal Processing Results Display
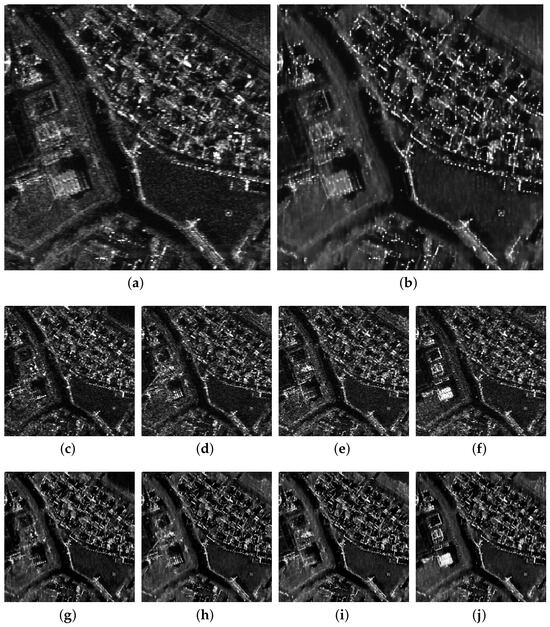
To display the performance of the proposed algorithm in temporal image despeckling, Figure 6 shows the mean changes before and after despeckling in 8-temporal images, along with specific details of the images. By comparing the mean images before and after despeckling in Figure 6a,b, we can visually observe the improvement in overall image quality during the despeckling process. Additionally, to further analyze the despeckling effect of the algorithm, the 1st, 3rd, 5th, and 7th temporal images are selected to show the processing results before and after despeckling at these specific time points. The experimental results show that the proposed algorithm not only effectively reduces the impact of speckle but also significantly improves the image clarity while preserving image details and structure.
Figure 6.
Detailed display of the proposed algorithm’s speckle noise suppression effect on temporal images. (a) Mean image of the 8-temporal SAR image. (b) Mean image after processing with the proposed LGT-SAR method. (c–f) represent the SAR images at the 1st, 3rd, 5th, and 7th time points. (g–j) show the speckle noise suppression results of the proposed algorithm for (c–f).
By fully utilizing the redundant information in the SAR image sequence of the same scene at different time points, the proposed method can effectively reduce the randomness of noise and better preserve the structural features in the image. To further validate the effectiveness of the algorithm, Figure 7 demonstrates the processing results of the proposed method on SAR images of the same scene at different time points. The experimental results show that the proposed algorithm can effectively handle temporally varying targets and suppress speckle noise in the current temporal sequence.
Figure 7.
The speckle noise suppression effect of the proposed algorithm on scenes containing moving ship targets. (a–h) represent the SAR image scenes at different time points. (i–p) show the despeckling results of LGT-SAR for (a–h).
3.3. Diverse Land-Cover Scene Validation
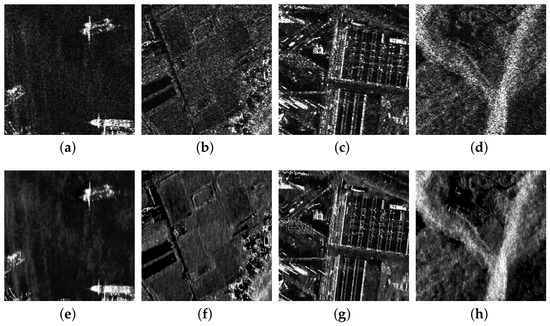
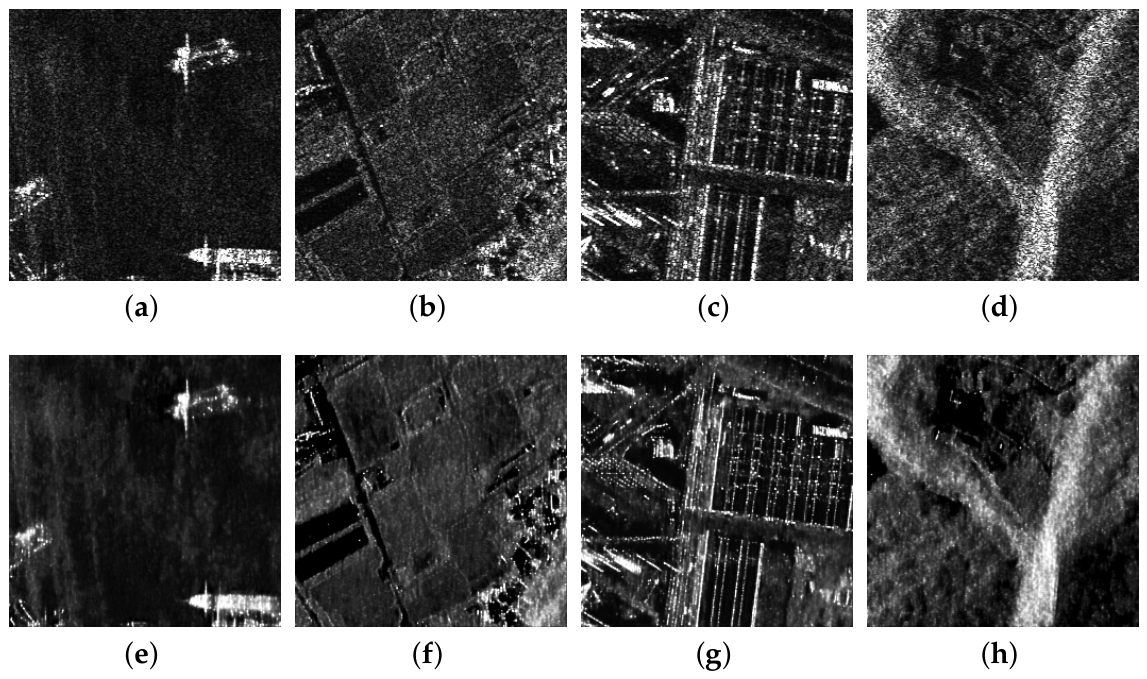
To further examine the robustness of the proposed method under different scene characteristics, we provide additional qualitative results on four representative land-cover categories, as shown in Figure 8. From left to right, the examples correspond to sea area, plains area, dense urban built-up region, and hilly area. These scenes cover substantially different backscatter patterns and structural characteristics, including relatively homogeneous background regions, weak-texture open areas, dense man-made scattering structures, and terrain-induced intensity variations.
Figure 8.
Despeckling results of the proposed method in diverse land-cover scenes. (a–d) Original SAR images of a sea area, plains area, dense urban built-up region, and hilly area, respectively; (e–h) corresponding despeckling results.
As shown in Figure 8, the proposed LGT-SAR method consistently suppresses speckle across all four scene types while preserving the dominant structural information of each scene. In the sea area example, the method effectively reduces random speckle fluctuations in the relatively homogeneous background while maintaining the salient bright targets. In the plains-area example, it suppresses speckle without introducing obvious structural distortion in the weak-texture region. In the dense urban built-up scene, the method better preserves strong scatterers, linear structures, and building-related edges. In the hilly area example, it remains capable of reducing speckle while maintaining the main terrain-related intensity transitions and structural contours.
These additional visual results further indicate that the proposed latent-space-guided transfer learning framework is not limited to a single scene type, but exhibits stable despeckling behavior across diverse land-cover conditions.
4. Discussion
4.1. Interpretation of Comparative Results
The experimental results show that the proposed LGT-SAR framework achieves a favorable balance between speckle suppression and structural preservation in multi-temporal SAR despeckling. Compared with SDUDNet, MSAR-BM3D, and multitemporal MERLIN, the proposed method produces cleaner despeckled outputs while better maintaining strong scatterers, edge structures, and local textures. This tendency is reflected not only in the visual comparisons, but also in the quantitative metrics. In particular, the proposed method exhibits a more balanced performance among ENL, EPI, and STD, indicating that it improves despeckling quality in a structurally meaningful manner rather than merely increasing smoothness.
These observations suggest that performance improvement in multi-temporal SAR despeckling should not be understood only as a matter of stronger temporal smoothing or more complex spatio-temporal modeling. Some competing methods can achieve higher smoothness-related metrics, but this may come at the cost of attenuating fine structures or weakening strong scatterers. By contrast, the proposed method introduces stable spatial priors from a pretrained single-image SAR despeckling model into the training of the 3D multi-temporal network through latent-space regularization. As a result, the 3D model is encouraged not only to exploit temporal redundancy, but also to preserve compatibility with the structural feature space already learned in the mature 2D single-image domain.
The qualitative validation on diverse land-cover scenes further supports the robustness of this framework. The results on sea area, plains area, dense urban built-up region, and hilly area indicate that the proposed method is not limited to a single class of SAR scenes. In relatively homogeneous backgrounds, it effectively suppresses random speckle fluctuations while preserving salient bright targets. In weak-texture and structurally complex scenes, it remains capable of reducing speckle without introducing obvious structural distortion. This suggests that the proposed latent-space-guided transfer mechanism provides stable structural constraints across scene types with substantially different backscatter characteristics.
4.2. Ablation Analysis of the Proposed Framework
To further clarify the source of the performance gain of the proposed LGT-SAR framework, we analyze the ablation results from the perspectives of single-image prior transfer, temporal modeling capability, and latent-space alignment. The goal of this analysis is not only to compare different architectural variants, but also to determine whether the improvement of LGT-SAR mainly arises from the introduction of a temporal dimension or from the proposed latent-space-guided transfer mechanism.
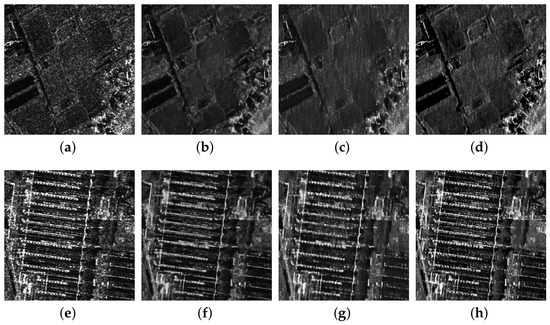
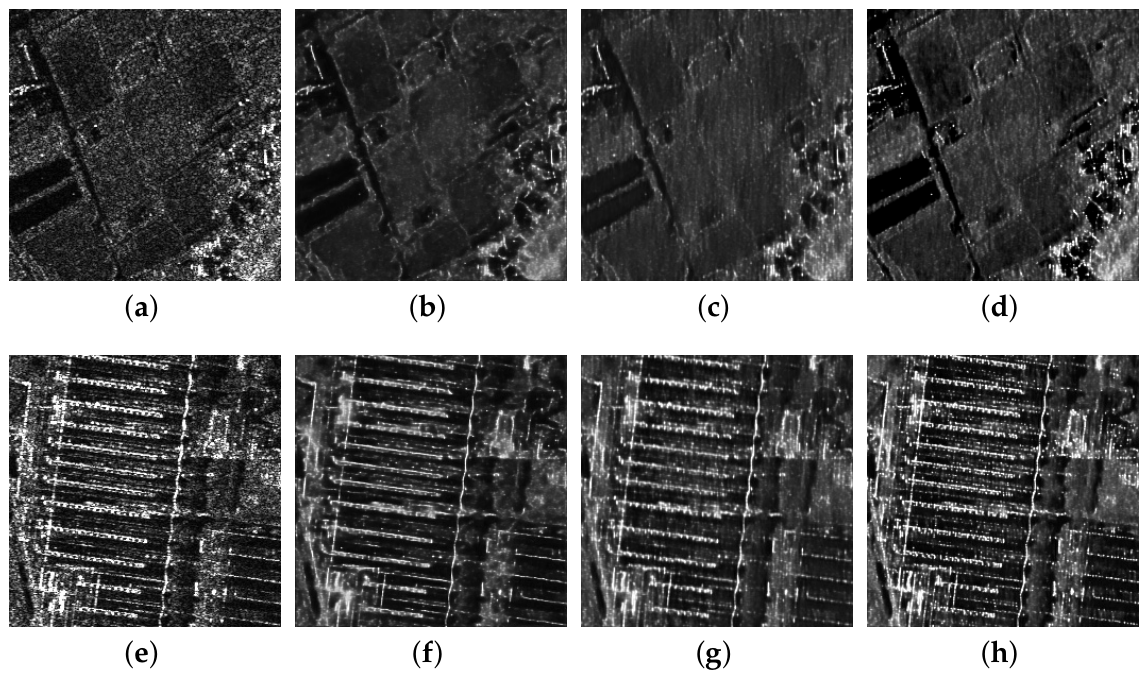
Using the original SAR image as the baseline, Figure 9a,e presents the unprocessed input images, where strong speckle interference can be clearly observed. Figure 9b,f shows the results produced by the 2D single-image despeckling model. This model provides a useful spatial baseline and can suppress speckle to some extent. However, because it operates only in the spatial domain and does not exploit temporal redundancy, it still tends to over-smooth structural details during despeckling, as reflected by the thinning of building edges and the blurring of point-like targets.
Figure 9.
Ablation experiment results. (a,e) represent the original SAR images. (b,f) show the results of the 2D single-image network. (c,g) are the results of the 3D multi-temporal network with a temporal convolution kernel size of 1. (d,h) display the results of the proposed multi-temporal network LGT-SAR.
Figure 9c,g show the results obtained by a 3D multi-temporal convolutional network with the temporal convolution kernel size set to 1. Although this configuration introduces a temporal dimension into the network structure, it does not perform effective temporal information fusion. In essence, the model only shares parameters across temporal positions and cannot fully exploit temporal correlations among acquisitions. Compared with the 2D single-image model, this variant shows some improvement in speckle suppression, but the overall results still exhibit noticeable blurring. This suggests that merely extending the network to a nominal 3D form is insufficient to fully utilize the advantages of multi-temporal SAR data.
By contrast, Figure 9d,h presents the results of the complete LGT-SAR framework. Based on genuine 3D spatio-temporal convolutional modeling, the proposed method further introduces encoder–decoder latent-space alignment regularization, through which the pretrained single-image model continuously constrains the representation space of the multi-temporal branch. As a result, LGT-SAR achieves more effective transfer from the single-image despeckling domain to the multi-temporal despeckling task. Visually, the proposed method not only suppresses speckle more effectively, but also better preserves structural edges, strong scatterers, and local texture details, thereby providing the most balanced overall despeckling result.
Table 3 summarizes the quantitative evaluation metrics of the ablation study. The results show that LGT-SAR significantly outperforms both the conventional single-image network and the simplified multi-temporal network with a temporal kernel size of 1, which is consistent with the visual observations.
Table 3.
Quantitative evaluation of ablation experiment.
Taken together, these ablation results indicate that the improvement of the proposed method cannot be attributed solely to the use of a 3D network structure. More importantly, it arises from the combination of effective spatio-temporal modeling and latent-space-guided transfer learning. The encoder–decoder latent-space alignment enables the 3D branch to inherit stable structural priors from the pretrained 2D single-image model, which helps reduce representation drift and mitigate over-smoothing under limited multi-temporal training data. Therefore, the ablation analysis strongly supports the central claim of this work: the effectiveness of LGT-SAR relies not only on introducing temporal modeling capability, but also on explicitly transferring mature spatial knowledge from the single-image domain to guide multi-temporal SAR despeckling.
4.3. Limitations and Future Perspectives
Several limitations should also be noted. First, the current framework relies on accurately co-registered multi-temporal SAR data. Although this assumption is reasonable in the present experimental setting, registration errors may weaken temporal consistency and reduce the effectiveness of latent-space-guided transfer. Second, while the current experiments cover representative scenes and show consistent trends, the diversity of sensors, acquisition geometries, and practical application conditions remains limited. Third, although the simulation-based training data construction adopted in this work is physically motivated and effective in practice, its generality could be further strengthened through broader cross-scene and cross-sensor validation.
Overall, the present results suggest that latent-space-guided transfer learning is a promising direction for multi-temporal SAR image restoration. Instead of treating single-image despeckling and multi-temporal despeckling as completely separate problems, the proposed framework shows that stable knowledge learned in the single-image domain can be explicitly transferred to guide spatio-temporal modeling. This idea may also be valuable for other SAR time-series restoration tasks.
5. Conclusions
In this paper, we proposed LGT-SAR, a latent-space-guided transfer learning framework for multi-temporal SAR despeckling. By introducing stable spatial priors from a pretrained single-image SAR despeckling model into a 3D multi-temporal network through encoder–decoder latent-space regularization, the proposed method establishes an explicit bridge between 2D spatial modeling and 3D spatio-temporal modeling.
Experimental results on real multi-temporal SAR data demonstrate that LGT-SAR achieves effective despeckling while better preserving structural details and local textures. The results indicate that the proposed framework provides a practical solution for multi-temporal SAR despeckling under limited training data and offers a feasible way to transfer mature single-image despeckling knowledge to more complex temporal scenarios.
Future work will focus on improving robustness under imperfect registration, extending the validation to more diverse sensors and scenes, and further exploring more general transfer-learning strategies for SAR time-series restoration tasks.
Author Contributions
Conceptualization, B.P., Z.Y. and X.Y.; methodology, B.P.; software, B.P.; validation, B.P.; formal analysis, B.P., Z.Y. and Z.T.; investigation, B.P. and X.Y.; resources, Z.Y.; data curation, B.P.; writing—original draft preparation, B.P.; writing—review and editing, Z.Y. and X.Y.; visualization, B.P. and Z.T.; supervision, Z.Y., X.Y., Z.T. and W.R.; project administration, Z.Y. and X.Y.; funding acquisition, Z.Y. All authors have read and agreed to the published version of the manuscript.
Funding
Project supported by the National Natural Science Foundation of China (Grant No. 62271031).
Data Availability Statement
The data presented in this study are available on request from the corresponding author. The data are not publicly available due to restrictions on the TanDEM-X data license.
Conflicts of Interest
Author Wei Ren was employed by the company Byudata (Shanghai) Co., Ltd. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
References
- Lattari, F.; Gonzalez Leon, B.; Asaro, F.; Rucci, A.; Prati, C.; Matteucci, M. Deep Learning for SAR Image Despeckling. Remote Sens. 2019, 11, 1532. [Google Scholar] [CrossRef] [Scilit]
- Fang, Y.; Liu, R.; Peng, Y.; Guan, J.; Li, D.; Tian, X. Contrastive learning for real SAR image despeckling. ISPRS J. Photogramm. Remote Sens. 2024, 218, 376–391. [Google Scholar] [CrossRef] [Scilit]
- Aghababaei, H.; Ferraioli, G.; Vitale, S.; Zamani, R.; Schirinzi, G.; Pascazio, V. Nonlocal Model-Free Denoising Algorithm for Single- and Multichannel SAR Data. IEEE Trans. Geosci. Remote Sens. 2022, 60, 5217315. [Google Scholar] [CrossRef] [Scilit]
- Deledalle, C.A.; Denis, L.; Tupin, F. Iterative weighted maximum likelihood denoising with probabilistic patch-based weights. IEEE Trans. Image Process. 2009, 18, 2661–2672. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhao, W.; Deledalle, C.A.; Denis, L.; Maître, H.; Nicolas, J.M.; Tupin, F. Ratio-Based Multitemporal SAR Images Denoising: RABASAR. IEEE Trans. Geosci. Remote Sens. 2019, 57, 3552–3565. [Google Scholar] [CrossRef] [Scilit]
- Chierchia, G.; El Gheche, M.; Scarpa, G.; Verdoliva, L. Multitemporal SAR Image Despeckling Based on Block-Matching and Collaborative Filtering. IEEE Trans. Geosci. Remote Sens. 2017, 55, 5467–5480. [Google Scholar] [CrossRef] [Scilit]
- Parrilli, S.; Poderico, M.; Angelino, C.V.; Verdoliva, L. A Nonlocal SAR Image Denoising Algorithm Based on LLMMSE Wavelet Shrinkage. IEEE Trans. Geosci. Remote Sens. 2012, 50, 606–616. [Google Scholar] [CrossRef] [Scilit]
- Yu, J.; Pan, B.; Yu, Z.; Li, C.; Wu, X. Collaborative optimization for SAR image despeckling with structure preservation. IEEE Trans. Geosci. Remote Sens. 2024, 63, 5201712. [Google Scholar] [CrossRef] [Scilit]
- Chierchia, G.; Cozzolino, D.; Poggi, G.; Verdoliva, L. SAR image despeckling through convolutional neural networks. In Proceedings of the 2017 IEEE International Geoscience and Remote Sensing Symposium (IGARSS), Fort Worth, TX, USA, 23–28 July 2017; pp. 5438–5441. [Google Scholar] [CrossRef] [Scilit]
- Lin, N.; Chen, G.; Zhou, Q.; Liu, C. Dilated Residual Shrinkage Network for SAR Image Despeckling. In Proceedings of the 2021 IEEE 6th International Conference on Signal and Image Processing (ICSIP), Nanjing, China, 22–24 October 2021; pp. 503–507. [Google Scholar] [CrossRef] [Scilit]
- Vitale, S.; Ferraioli, G.; Pascazio, V. Multi-Objective CNN-Based Algorithm for SAR Despeckling. IEEE Trans. Geosci. Remote Sens. 2021, 59, 9336–9349. [Google Scholar] [CrossRef] [Scilit]
- Bu, L.; Zhang, J.; Zhang, Z.; Yang, Y.; Deng, M. Enhancing RABASAR for Multi-Temporal SAR Image Despeckling through Directional Filtering and Wavelet Transform. Sensors 2023, 23, 8916. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Abramov, S.; Shelestov, A.; Lavreniuk, M.; Meretsky, M. Despeckling of multitemporal sentinel SAR images and its impact on agricultural area classification. In Recent Advances and Applications in Remote Sensing; BoD—Books on Demand: Hamburg, Germany, 2018; p. 21. [Google Scholar]
- Liang, Y.; Yang, X.; Tan, W.; Wang, Z.; Huang, P.; Yang, J. Ratio-based multitemporal SAR image despeckling with low-rank approximation. IEEE Geosci. Remote Sens. Lett. 2023, 21, 4000105. [Google Scholar] [CrossRef] [Scilit]
- Bu, L.; Zhang, J.; Zhang, Z.; Yang, Y.; Deng, M. Deep learning for integrated speckle reduction and super-resolution in multi-temporal SAR. Remote Sens. 2023, 16, 18. [Google Scholar] [CrossRef] [Scilit]
- Meraoumia, I.; Dalsasso, E.; Denis, L.; Abergel, R.; Tupin, F. Multitemporal speckle reduction with self-supervised deep neural networks. IEEE Trans. Geosci. Remote Sens. 2023, 61, 5201914. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; Shi, S.; Lin, L.; Yuan, Q.; Shen, H.; Zhang, L. A multi-task learning framework for dual-polarization SAR imagery despeckling in temporal change detection scenarios. ISPRS J. Photogramm. Remote Sens. 2025, 221, 155–178. [Google Scholar] [CrossRef] [Scilit]
- Fracastoro, G.; Magli, E.; Poggi, G.; Scarpa, G.; Valsesia, D.; Verdoliva, L. Deep Learning Methods For Synthetic Aperture Radar Image Despeckling: An Overview Of Trends And Perspectives. IEEE Geosci. Remote Sens. Mag. 2021, 9, 29–51. [Google Scholar] [CrossRef] [Scilit]
- Dalsasso, E.; Meraoumia, I.; Denis, L.; Tupin, F. Exploiting Multi-Temporal Information for Improved Speckle Reduction of Sentinel-1 SAR Images by Deep Learning. In Proceedings of the 2021 IEEE International Geoscience and Remote Sensing Symposium IGARSS, Brussels, Belgium, 11–16 July 2021; pp. 1081–1084. [Google Scholar] [CrossRef] [Scilit]
- Molini, A.B.; Valsesia, D.; Fracastoro, G.; Magli, E. Speckle2Void: Deep Self-Supervised SAR Despeckling with Blind-Spot Convolutional Neural Networks. IEEE Trans. Geosci. Remote Sens. 2021, 60, 5204017. [Google Scholar] [CrossRef] [Scilit]
- Dalsasso, E.; Denis, L.; Tupin, F. SAR2SAR: A Semi-Supervised Despeckling Algorithm for SAR Images. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2021, 14, 4321–4329. [Google Scholar] [CrossRef] [Scilit]
- Zhao, S.; Zhang, Y.; Cun, X.; Yang, S.; Niu, M.; Li, X.; Hu, W.; Shan, Y. Cv-vae: A compatible video vae for latent generative video models. Adv. Neural Inf. Process. Syst. 2024, 37, 12847–12871. [Google Scholar]
- Bo, F.; Ma, X.; Hu, S.; An, G.; Li, Y.; Cen, Y. Speckle-Driven Unsupervised Despeckling for SAR Images. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2025, 18, 13023–13034. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.