1. Introduction
As an important way of energy conversion, coal gasification plays an increasingly significant role in the field of modern industry. With the global pursuit of environmental protection and sustainable development, coal gasification technology has been continuously optimized and improved, and its application scope has gradually expanded. Coal water slurry preparation technology is a new technology to convert coal into clean energy. The renewable resources such as biomass and waste added in coal water slurry can increase the content of clean energy, so as to realize the sustainable development of energy. Coal water slurry preparation technology has been widely used in electric power, metallurgy, chemical industry, and other fields. It plays an important role in reducing pollution emissions, improving coal utilization, and achieving sustainable energy development. With the improvement of environmental awareness, the future application prospects in the field of clean energy are very broad.
Coal slurry preparation system is an important part of coal gasification system. Continuous and stable preparation, transportation, and storage of high-concentration coal water slurry is one of the necessary conditions for safe, stable, and long-term operation of gasifier. However, the coal slurry preparation system often encounters a series of problems, such as coal plugging, insufficient water supply, and poor conveying capacity of the mill discharge tank pump during operation, which limit production, increase energy consumption, and increase safety risks. Therefore, it is very important to dynamically monitor and evaluate the status of the coal slurry preparation system during operation to ensure that the production and operation of the enterprise are not affected by equipment failure and downtime. Through the dynamic risk assessment of the system, enterprises can find potential problems in time and take appropriate measures to reduce risks, thereby enhancing the sustainability of enterprise production [
1,
2,
3,
4].
Bayesian networks (BNs) have been widely used in risk assessments in the coal chemical industry. For example, Liu et al. [
5] focused on the problem of zero-fault data and dynamic faults in gasification systems. They proposed a method based on dynamic Bayesian networks (DBNs) and combined it with Monte Carlo simulation to conduct reliability analyses. Through structure and parameter learning, the problem of zero-fault data was effectively solved, and prediction and inference accuracy were improved. Liu et al. [
6] focused on coal gasification furnaces and proposed a method integrating Bayesian networks and the trapezoidal intuitionistic fuzzy number similarity aggregation method (TpIFN-SAM). By constructing Bayesian networks, collecting and aggregating expert opinions, deblurring, calculating system failure probabilities, and diagnosing key nodes, they completed the risk assessment of gasification furnace failures. To cope with the domino effect in the coal gasification process and evaluate its impact, Zhao et al. [
7] combined the fuzzy analytic hierarchy process (FAHP) with BNs, providing a basis for the development of safety protection measures in the chemical industry. Liu Ming et al. [
8] conducted a risk analysis of the gasifier feeding system using BNs, providing support for identifying weak links in the system and improving operational safety. Finally, Gao Han et al. [
9] conducted an in-depth dynamic risk analysis of gasifier overheating based on the DBT-DBN model, further improving the risk assessment system under high-temperature conditions.
At the same time, with the development and popularization of artificial intelligence, neural networks also began to be used in various fields, mainly for prediction, fault diagnosis, optimization, etc. Yuan Chenbo et al. [
10] proposed a numerical simulation method based on the BP neural network to study the processes present in coal gasification furnaces. Wei Tao et al. [
11] proposed the idea of applying the BP neural network to coal mine gas safety management and studied the prediction and application of coal mine gas safety accidents. Rui Xue et al. [
12] proposed a fault diagnosis model based on the LM-BP neural network and conducted diagnostic research on hydraulic system faults in coal mining machines. Fu Yao et al. [
13] proposed an evaluation model combining principal component analysis and the BP neural network to study the quality of imported coal. Jiang Li et al. [
14] proposed a detection system construction scheme based on the BP neural network and studied the development and application of a detection system locating fault points in petrochemical equipment. The application value of BP neural networks has been explored in fields such as chemical engineering, coal mine safety, mining equipment, coal quality evaluation, and petrochemical equipment testing, providing technical references for process optimization, risk prevention, and equipment management in related industries.
Recurrent neural networks (RNNs) have demonstrated strong application value in multiple fields. In mechanical manufacturing, Cheng Yinghao et al. [
15] used RNNs for sensorless monitoring of cutting forces. In fault diagnosis, Liao et al. [
16] designed a multi-scale residual neural network with enhanced gated recurrent units to diagnose rolling bearing faults. In transportation, RNNs can be used for traffic volume prediction [
17,
18,
19], while in the field of energy, they can be used for wind power generation and short-term wind speed prediction [
20,
21]. RNNs have also been applied in the fields of finance, hydrology, meteorology, and electricity [
22,
23,
24,
25,
26].
As an improved version of the RNN, a long short-term memory recurrent neural network (LSTM-RNN) solves the problem of vanishing or exploding gradients present in RNNs, further expanding their application scenarios. In the field of communication, Rohini et al. [
27] used an LSTM-RNN to autonomously predict traffic volume in cellular networks. In power systems, Zhang Xueyou et al. [
28] applied an LSTM-RNN to detect relay protection faults in ultra-high-voltage direct current transmission systems. In new energy vehicles, Li Hao et al. [
29] constructed an LSTM-RNN temperature prediction model for use in power batteries of hydrogen fuel heavy-duty trucks. In metallurgy, Li Fujin et al. [
30] used an LSTM-RNN to predict slag discharge during continuous casting. In the field of coal mine safety, Sun Zhuoyue et al. [
31] used an LSTM-RNN to dynamically predict the gas concentration in the mining face. In the petroleum industry, Chu Haoyuan et al. [
32] used an LSTM-RNN to provide intelligent warnings for pump well faults. X. Ruan et al. [
33] combined an LSTM-RNN with physical information to predict the failure process of prefabricated bridge deck joints. In the field of energy equipment maintenance, L. Brahmi et al. [
34] used an LSTM-RNN to assist in the predictive maintenance of gas turbines. LSTM-RNNs have also been employed in other industrial fields [
35,
36,
37]. They effectively address the limitations of RNNs in long sequence dependency problems and improve prediction and diagnostic performance in complex scenarios. However, there is still a lack of research on using neural networks for dynamic risk assessment of key coal gasification equipment. Based on this, this study is mainly based on the research on “BP neural network optimization of dynamic Bayesian network (DBN) parameters” proposed by Liu et al. [
5], and further expanding research ideas: given that long short-term memory (LSTM) neural networks have better ability to process time-series data and extract features than BP neural networks, and can more accurately capture dynamic correlation information of data, BP neural network and LSTM are used to optimize dynamic Bayesian network parameter learning and compare their effects. At the same time, gated recurrent unit (GRU) is introduced to participate in the analysis. By comparing the performance indicators of the three, a better model is determined to achieve accurate dynamic risk assessment of the coal slurry preparation system and extend its service life.
2. Deep Learning Predictive Model
Due to the reliance of traditional methods on expert knowledge to determine the prior parameters of DBN, the subjective limitations of expert experience, and significant differences in parameter assignments among different experts, the obtained parameters have strong subjectivity and are difficult to ensure their accuracy.
Here, a long short-term memory (LSTM) data-driven optimization method that relies on time-series data related to the system’s operational status to construct a model is proposed. By independently mining deep features of data to complete parameter iteration optimization, there is no need to rely on subjective assignment based on expert experience, which fundamentally avoids subjective bias caused by human factors. This enables the optimized parameters to more accurately match the actual operating conditions of the system, improving the engineering applicability and predictive reliability of the model.
The core of adapting neural network models for dynamic estimation of failure rates lies in their highly compatible design with the physical essence and statistical characteristics of fault timing. The evolution of fault occurrence is cumulative and correlated, and the preceding damage state will continue to affect the current and future failure rates. RNN can transmit preceding information and naturally adapt to this temporal dependence. In response to the statistical characteristics of long-range positive correlation and non-stationarity in fault time series, LSTM breaks through the gradient defects of traditional RNNs with its unique design of gate control and unit state. It can accurately capture long-range dependencies and dynamic mutation features in the fault evolution process, while adapting to the non-stationary properties of the sequence. The sliding window configuration of the LSTM model does not require preset fixed parameters. Its core function is to convert time-series data into an input format that the model can process, thereby matching the continuous evolution characteristics of fault sequences; the number of LSTM units is set based on the complexity of the fault characteristics, and parameter optimization is achieved through grid search method to ensure the quantitative response ability of the model to the multidimensional characteristics of fault evolution. The BP network uses nonlinear mapping and gradient descent optimization to extract key statistical features, filter noise, and provide clean input for estimation. All three, individually or in combination, can meet the requirements of fault rate estimation.
2.1. Back Propagation Neural Network
Considering that the BP neural network can fully handle various data types, does not rely on prior knowledge, and has a strong nonlinear mapping and generalization ability, a method based on the BP neural network is proposed to obtain a more accurate dynamic Bayesian network and optimize its prior parameters [
5].
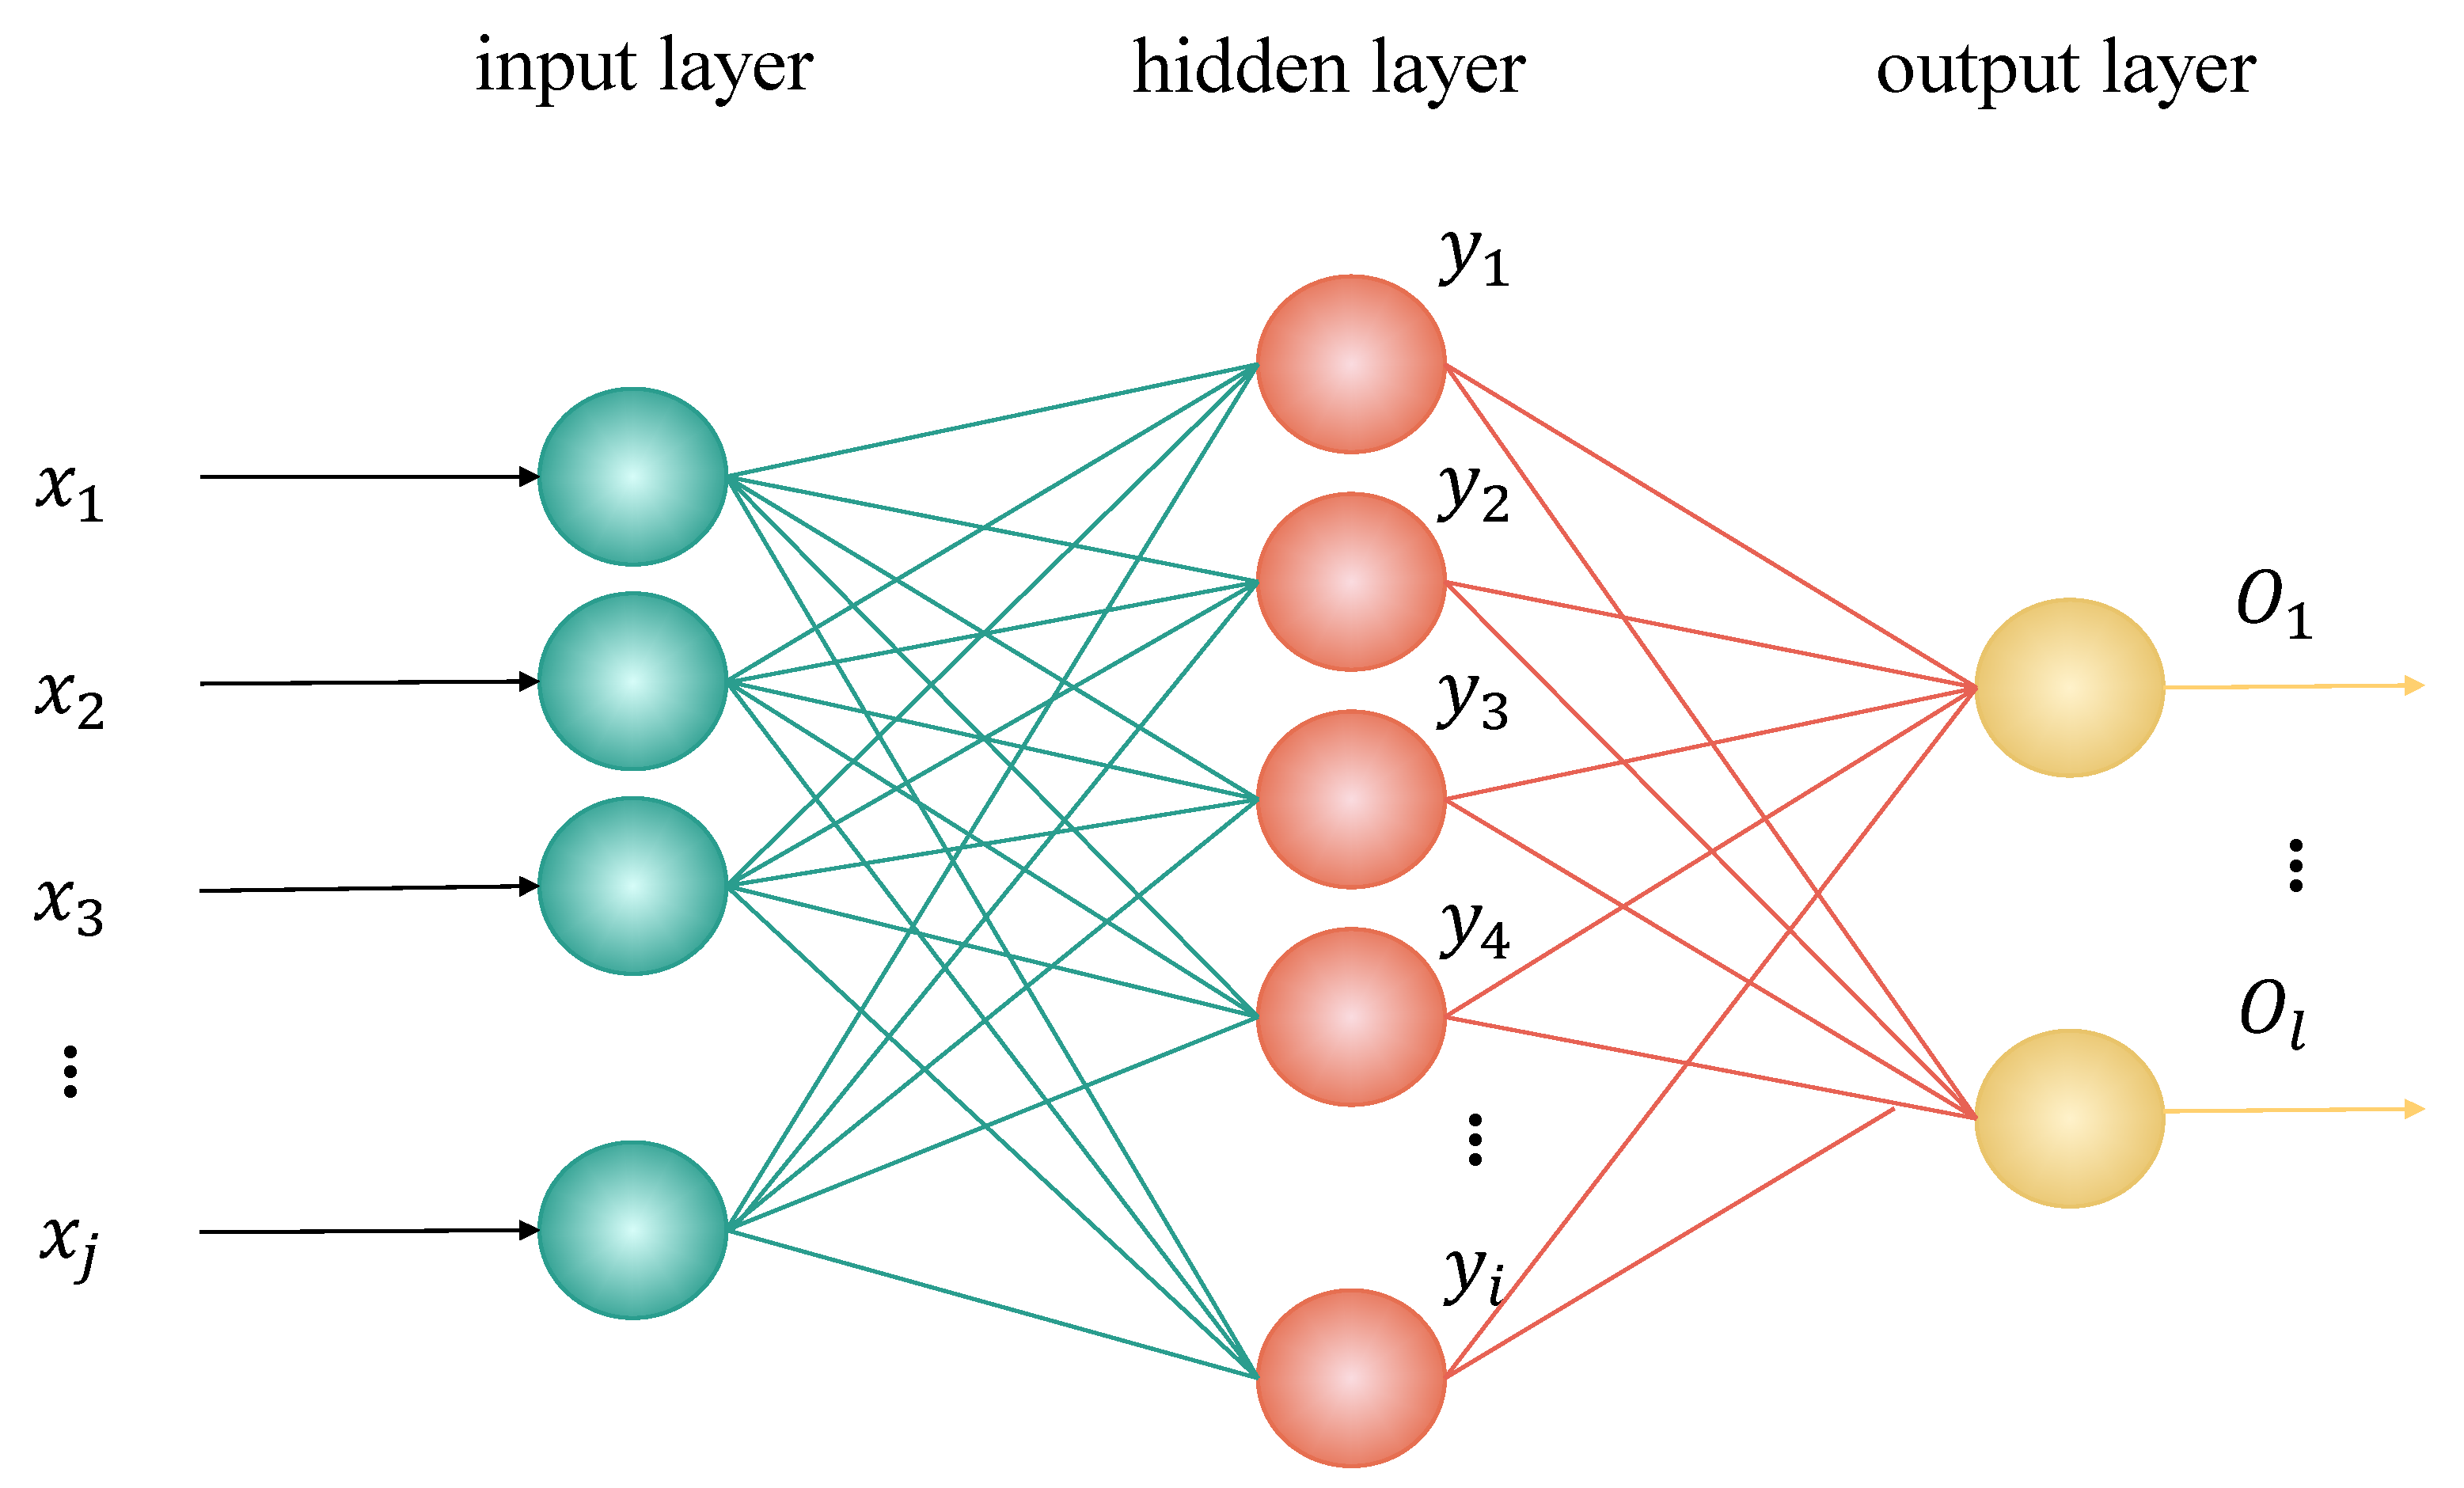
A BP neural network is a multi-layer feedforward neural network. It is a hierarchical neural network composed of an input layer, a hidden layer, and an output layer, as shown in
Figure 1: Topological structure of back propagation neural network. In
Figure 1,
is the input of the input node;
is the input of the hidden node; and
is the output of the output node.
is the external raw feature data received by the input layer, whose value range is normalized and falls within the range of . is the result of weighted summation plus the deviation from the input layer to the hidden layer, with no fixed range of values, and the value fluctuates with the weight, input, and deviation. is the final output of the network, and its value range is determined by the activation function of the output layer. For example, the Sigmoid function corresponds to , the Softmax function corresponds to with a sum of 1, and ReLU or linear functions have no fixed range.
The algorithm stems from the forward propagation of information and backward propagation of errors. By adjusting the network weights and threshold , the error function decreases along the gradient direction. Training can be completed when the sum of squared errors in the network output layer is less than the specified convergence error.
The empirical formula for the number of hidden-layer neurons is
where
is the amount of input layer units,
is the amount of output layer units,
is the amount of neurons in the hidden layer, and
is the adjustment constant defined within [
1,
10].
The BP neural network model can be represented as the input of hidden nodes, the output of output nodes, and the error of output nodes:
where
and
are the network weights between the input node and the hidden node and those between the hidden node and the output node, respectively,
and
are the thresholds between the input node and the hidden node and those between the hidden node and the output node, respectively,
is the expected output of the output node,
is the network between the input layer and the hidden layer, and
is also the network between the hidden layer and the output layer.
2.2. Recurrent Neural Network Model
An RNN is a neural network architecture suitable for dealing with sequential data. By using neurons with self-feedback, it can process time-series data of any length.
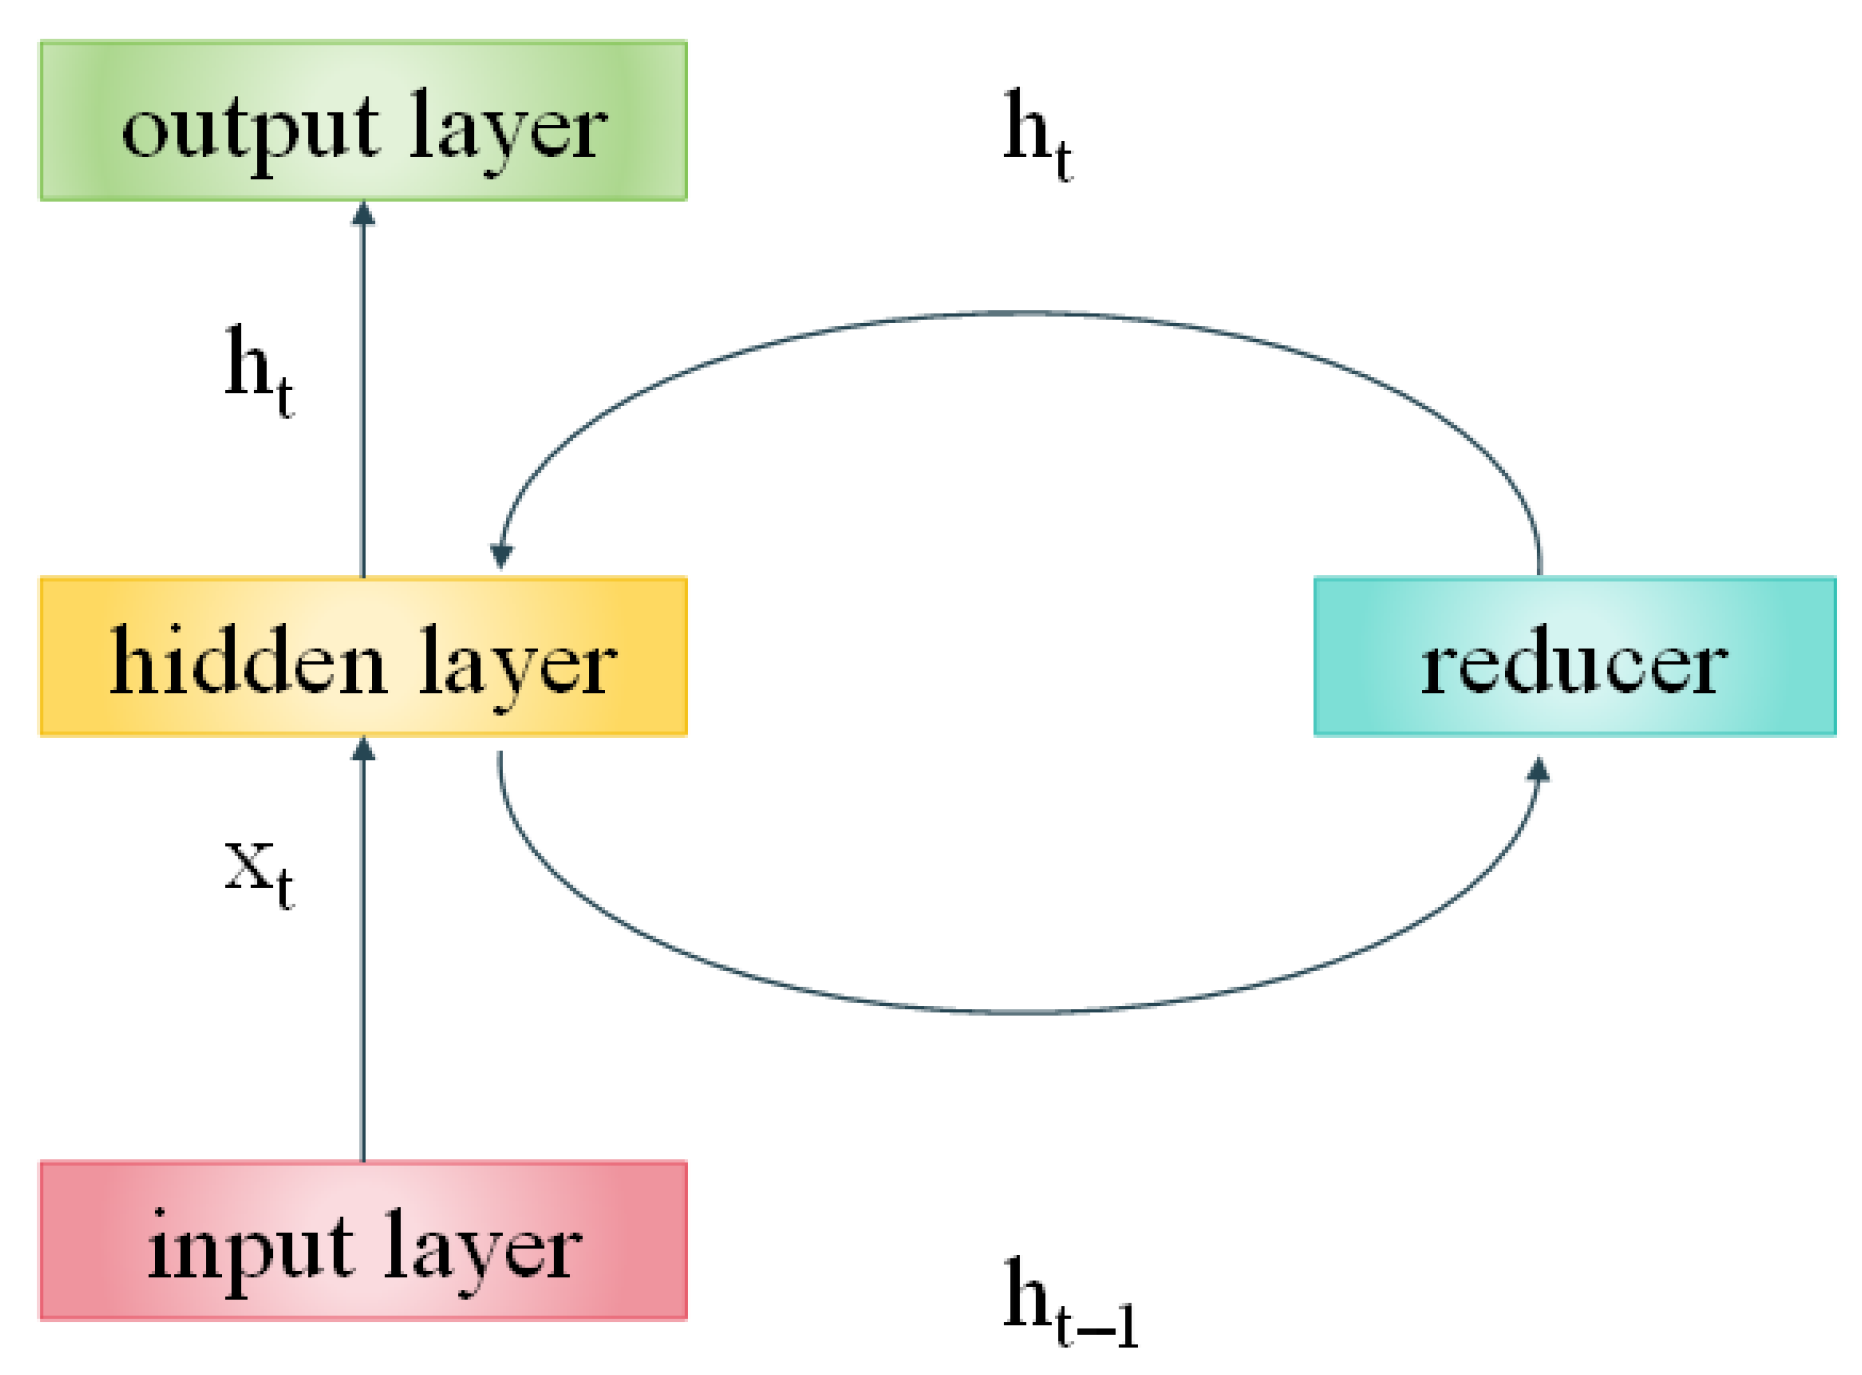
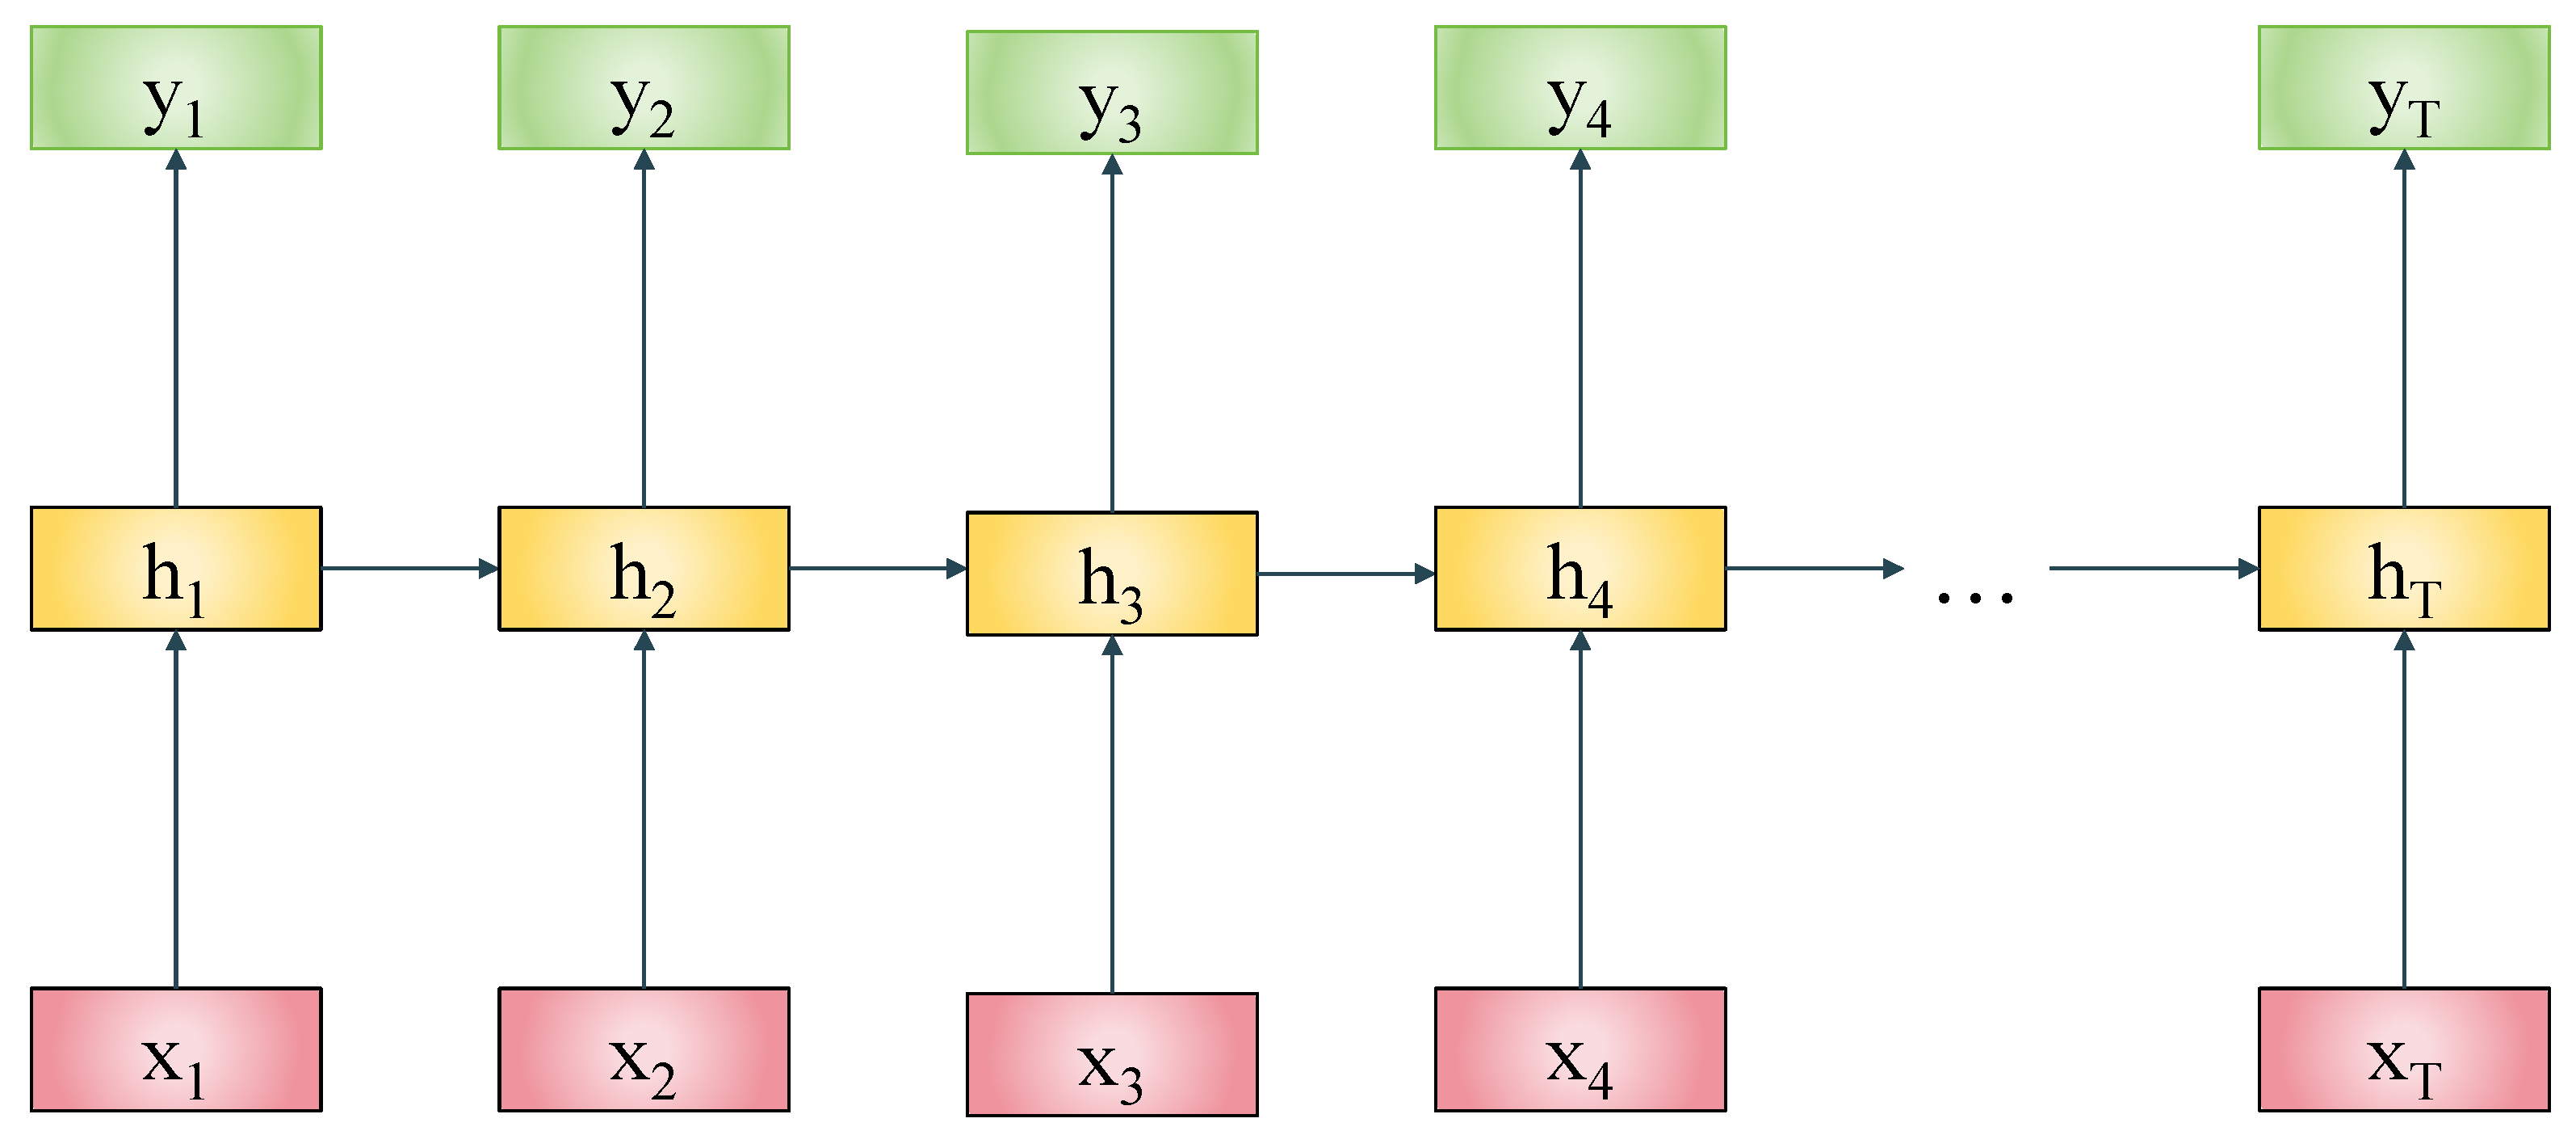
The basic structure of an RNN comprises an input layer, a hidden layer (loop layer), and an output layer. There are cyclic connections between neurons in the hidden layer, allowing information to be transmitted between time steps. The hidden layer in an RNN receives the current input and the output of the previous time step as inputs at each time step, which gives the network a memory capability.
represents the input data,
represents the output data, and
represents a hidden state. In RNNs, hidden state
is an internal state of the network used to store information from previous time steps. The hidden state of each time step will be updated based on the current input and the previous hidden state, i.e.,
, where
is a nonlinear function and
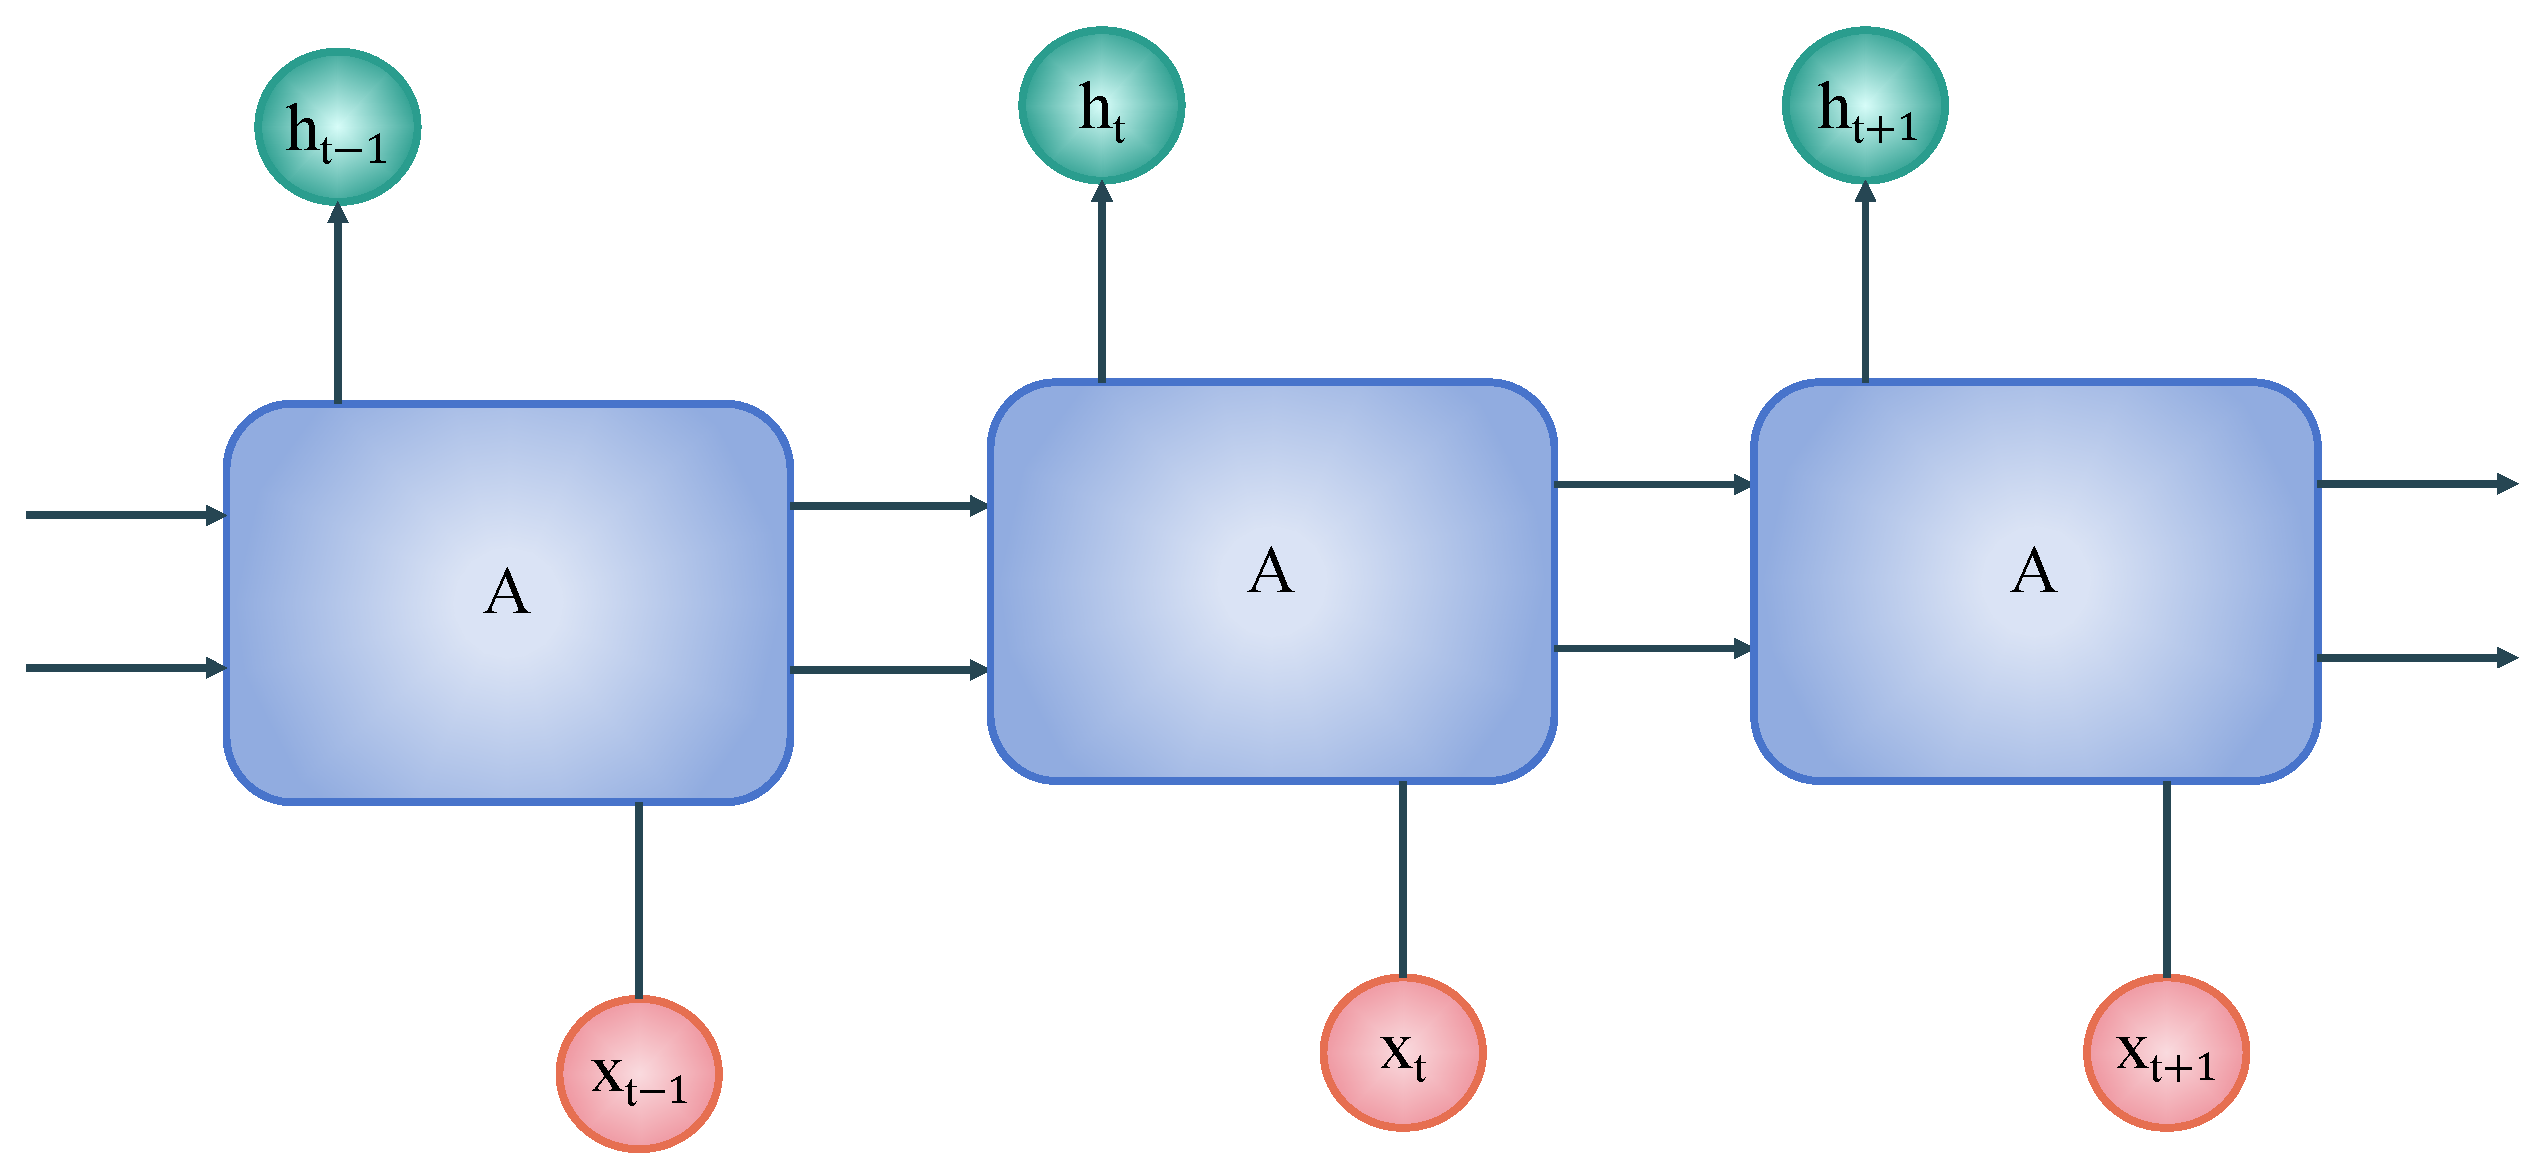
is the hidden state of the previous time step. The RNN structure is shown in
Figure 2, and
Figure 3 shows the RNN structure unfolded over time.
The basic architecture of an RNN can be represented as
where
is the output at the current time,
is the input at the current time, and
is the hidden state at the previous time.
The model combines two parts, one of which is a cyclic structure used to calculate the hidden state
at the current time:
where
represents the nonlinear activation layer,
and
represent the weight matrices related to hidden states and inputs, and
is used on behalf of the bias vector.
The other part of the model is a non-cyclic structure responsible for transforming the hidden state at the current time into the output at the current time:
where
represents the output layer containing nonlinear activation functions or only linear transformations.
2.3. Long Short-Term Memory Model
Long short-term memory (LSTM) is an improved version of the RNN designed to solve long sequence dependency problems. It precisely controls the storage and forgetting of information through gating mechanisms and is widely used in tasks such as machine translation and temporal prediction. Its core principle is to introduce the “Cell State” as a “conveyor belt” for information transmission and regulate the flow of information through three gating units.
Firstly, there is the forget gate, which determines how much of the historical cell state to retain, and is represented by the following equation:
where
is the output value of the forget gate and varies between
, the complete retention, and
represents complete forgetting,
is the weight matrix of the forget gate,
is the bias term of the forget gate, and
represents concatenating the hidden state of the previous moment with the current input.
Next is the input gate, which controls new information entering the cellular state, and is represented by the following equation:
The candidate cell state (new information) is
where
is the output value of the input gate
,
is the candidate cell state calculated at the current time,
and
are the weight matrices of the corresponding parts,
and
are the bias terms of the corresponding parts, and
is the hyperbolic tangent activation function (output range −1 to 1);
Then, there is the update of the cell state, which integrates historical and new information, and is represented by the following equation:
where
is the current cell state,
is the previous cell state, and
is the element-level multiplication (Hadamard product), representing the multiplication of corresponding position elements.
Finally, the output gate determining the output content is expressed in the following equation:
where
is the output value of the output gate and varies within
,
is the weight matrix of the output gate, and
is the bias term of the output gate.
The hidden state is expressed in the following equation:
where
is the hidden state at the current time.
LSTM dynamically adjusts the information retention time through a gating mechanism, effectively alleviating the gradient problem of the RNN and capturing long-distance temporal dependencies.
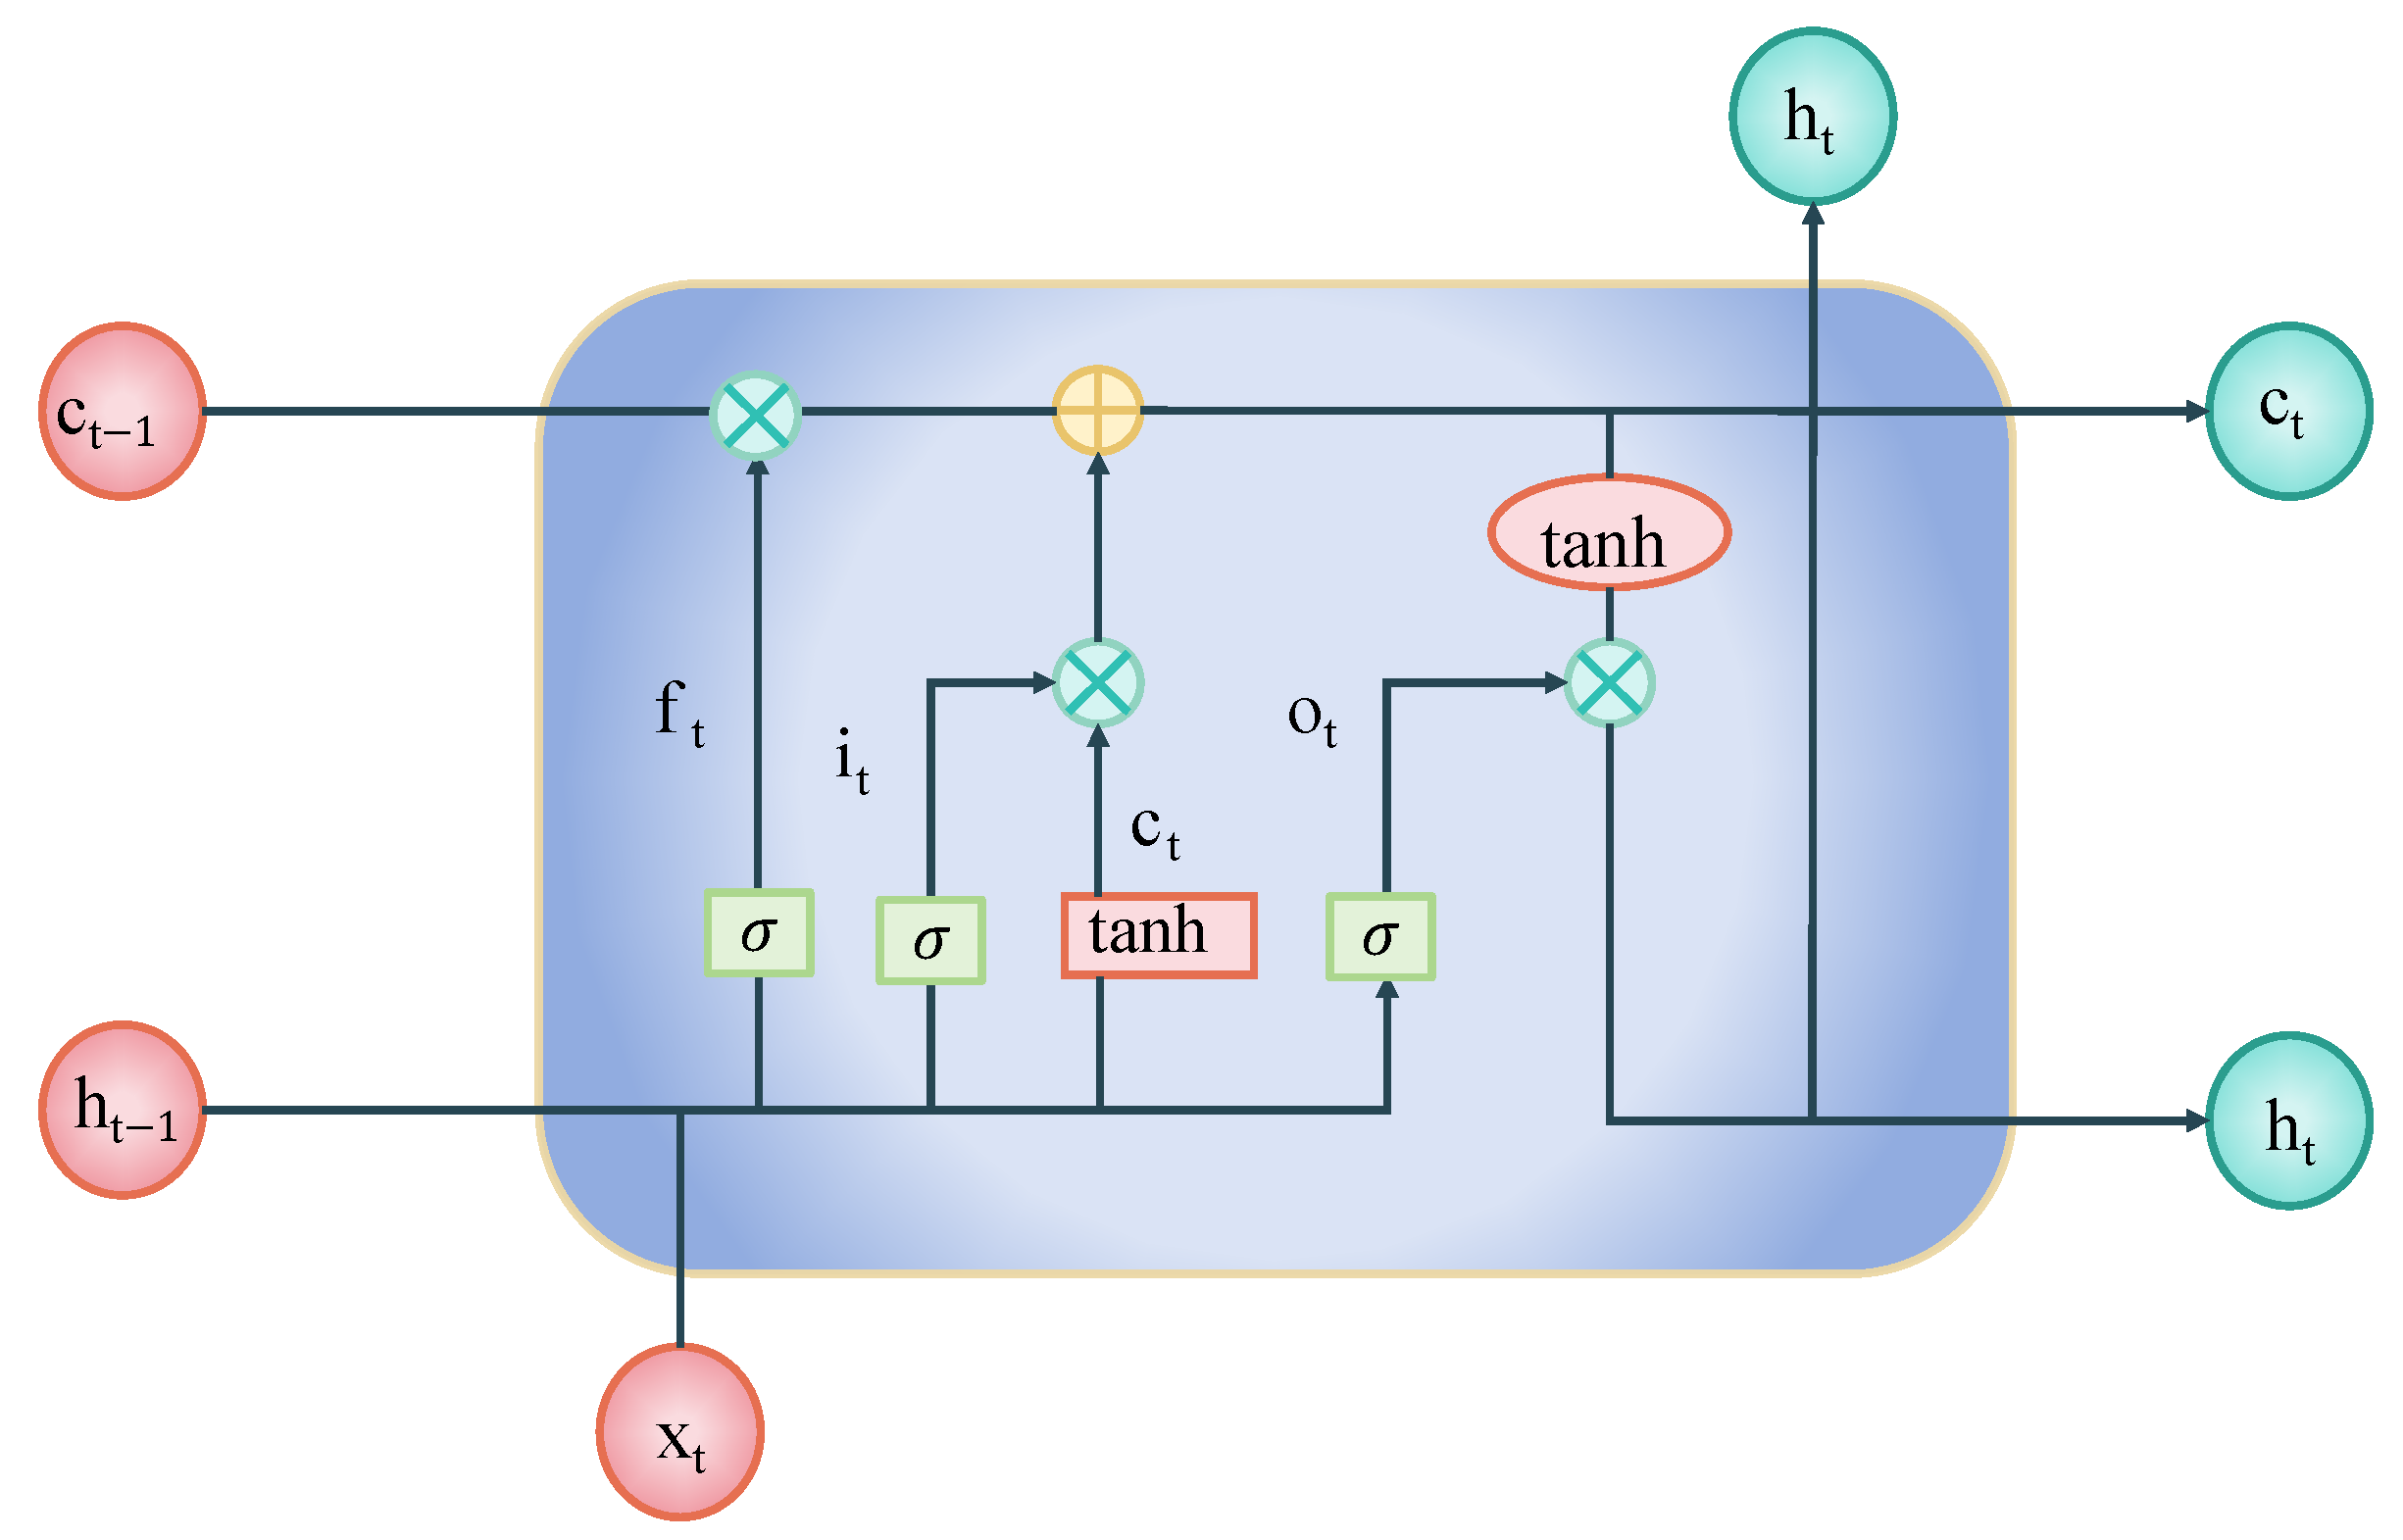
The overall framework of LSTM has been simplified, as shown in
Figure 4. And
Figure 5 shows in detail the internal gating mechanism of LSTM. In
Figure 5, the symbol with a “
” in yellow and green represents the element level operation module: the green module represents element level dot multiplication (such as the forgetting gate for filtering the previous cell state), and the yellow module represents element level addition (used to fuse old states with new information to update the cell state), which are the core operations of LSTM for dynamically updating memory.
In summary, the core structure, key parameters, and basic formulas of BP, RNN, and LSTM models were elucidated, and the mechanism of capturing data dependencies in temporal models was clarified. The following text will focus on the characteristics of coal slurry preparation systems and carry out the construction of DBN models and determination of prior parameters.
4. Optimization of DBN Prior Parameters for Coal Slurry Preparation System
This section aims to combine the
Section 2 model with the
Section 3 DBN model, utilizing the temporal data processing advantages of neural network models to optimize the prior parameters of DBN. Specifically, using the logic of
Section 2 model as the support and the DBN model and parameters of
Section 3 as the carrier, the optimization objectives and constraints are clearly defined. Through data preprocessing, model training, parameter iteration optimization, and verification, the LSTM model with the best optimization effect is selected to improve the prediction accuracy of DBN.
4.1. Back Propagation Model Optimization
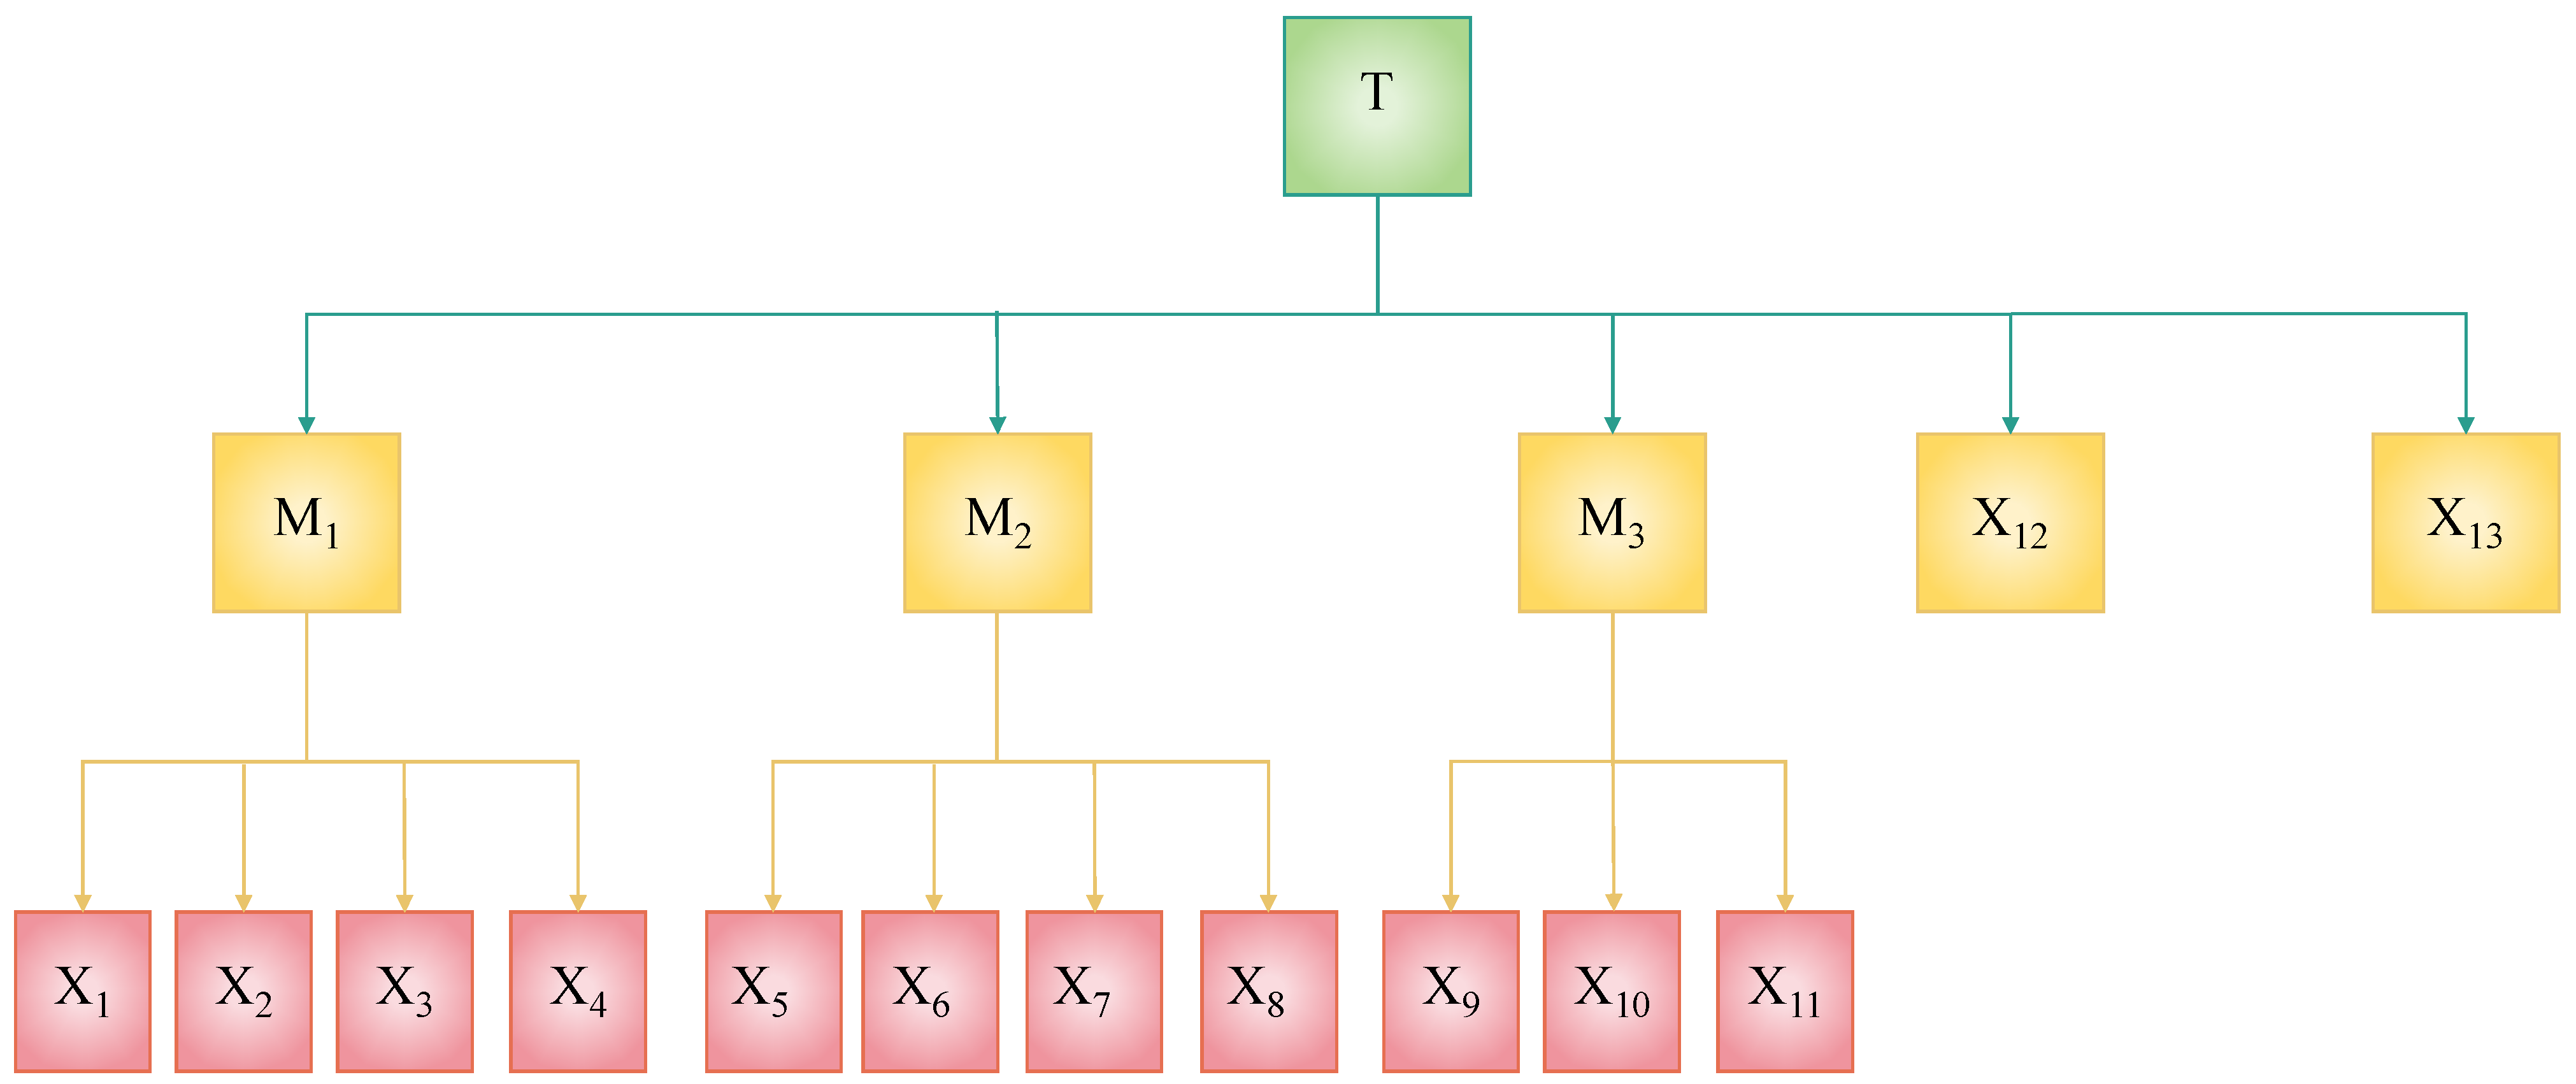
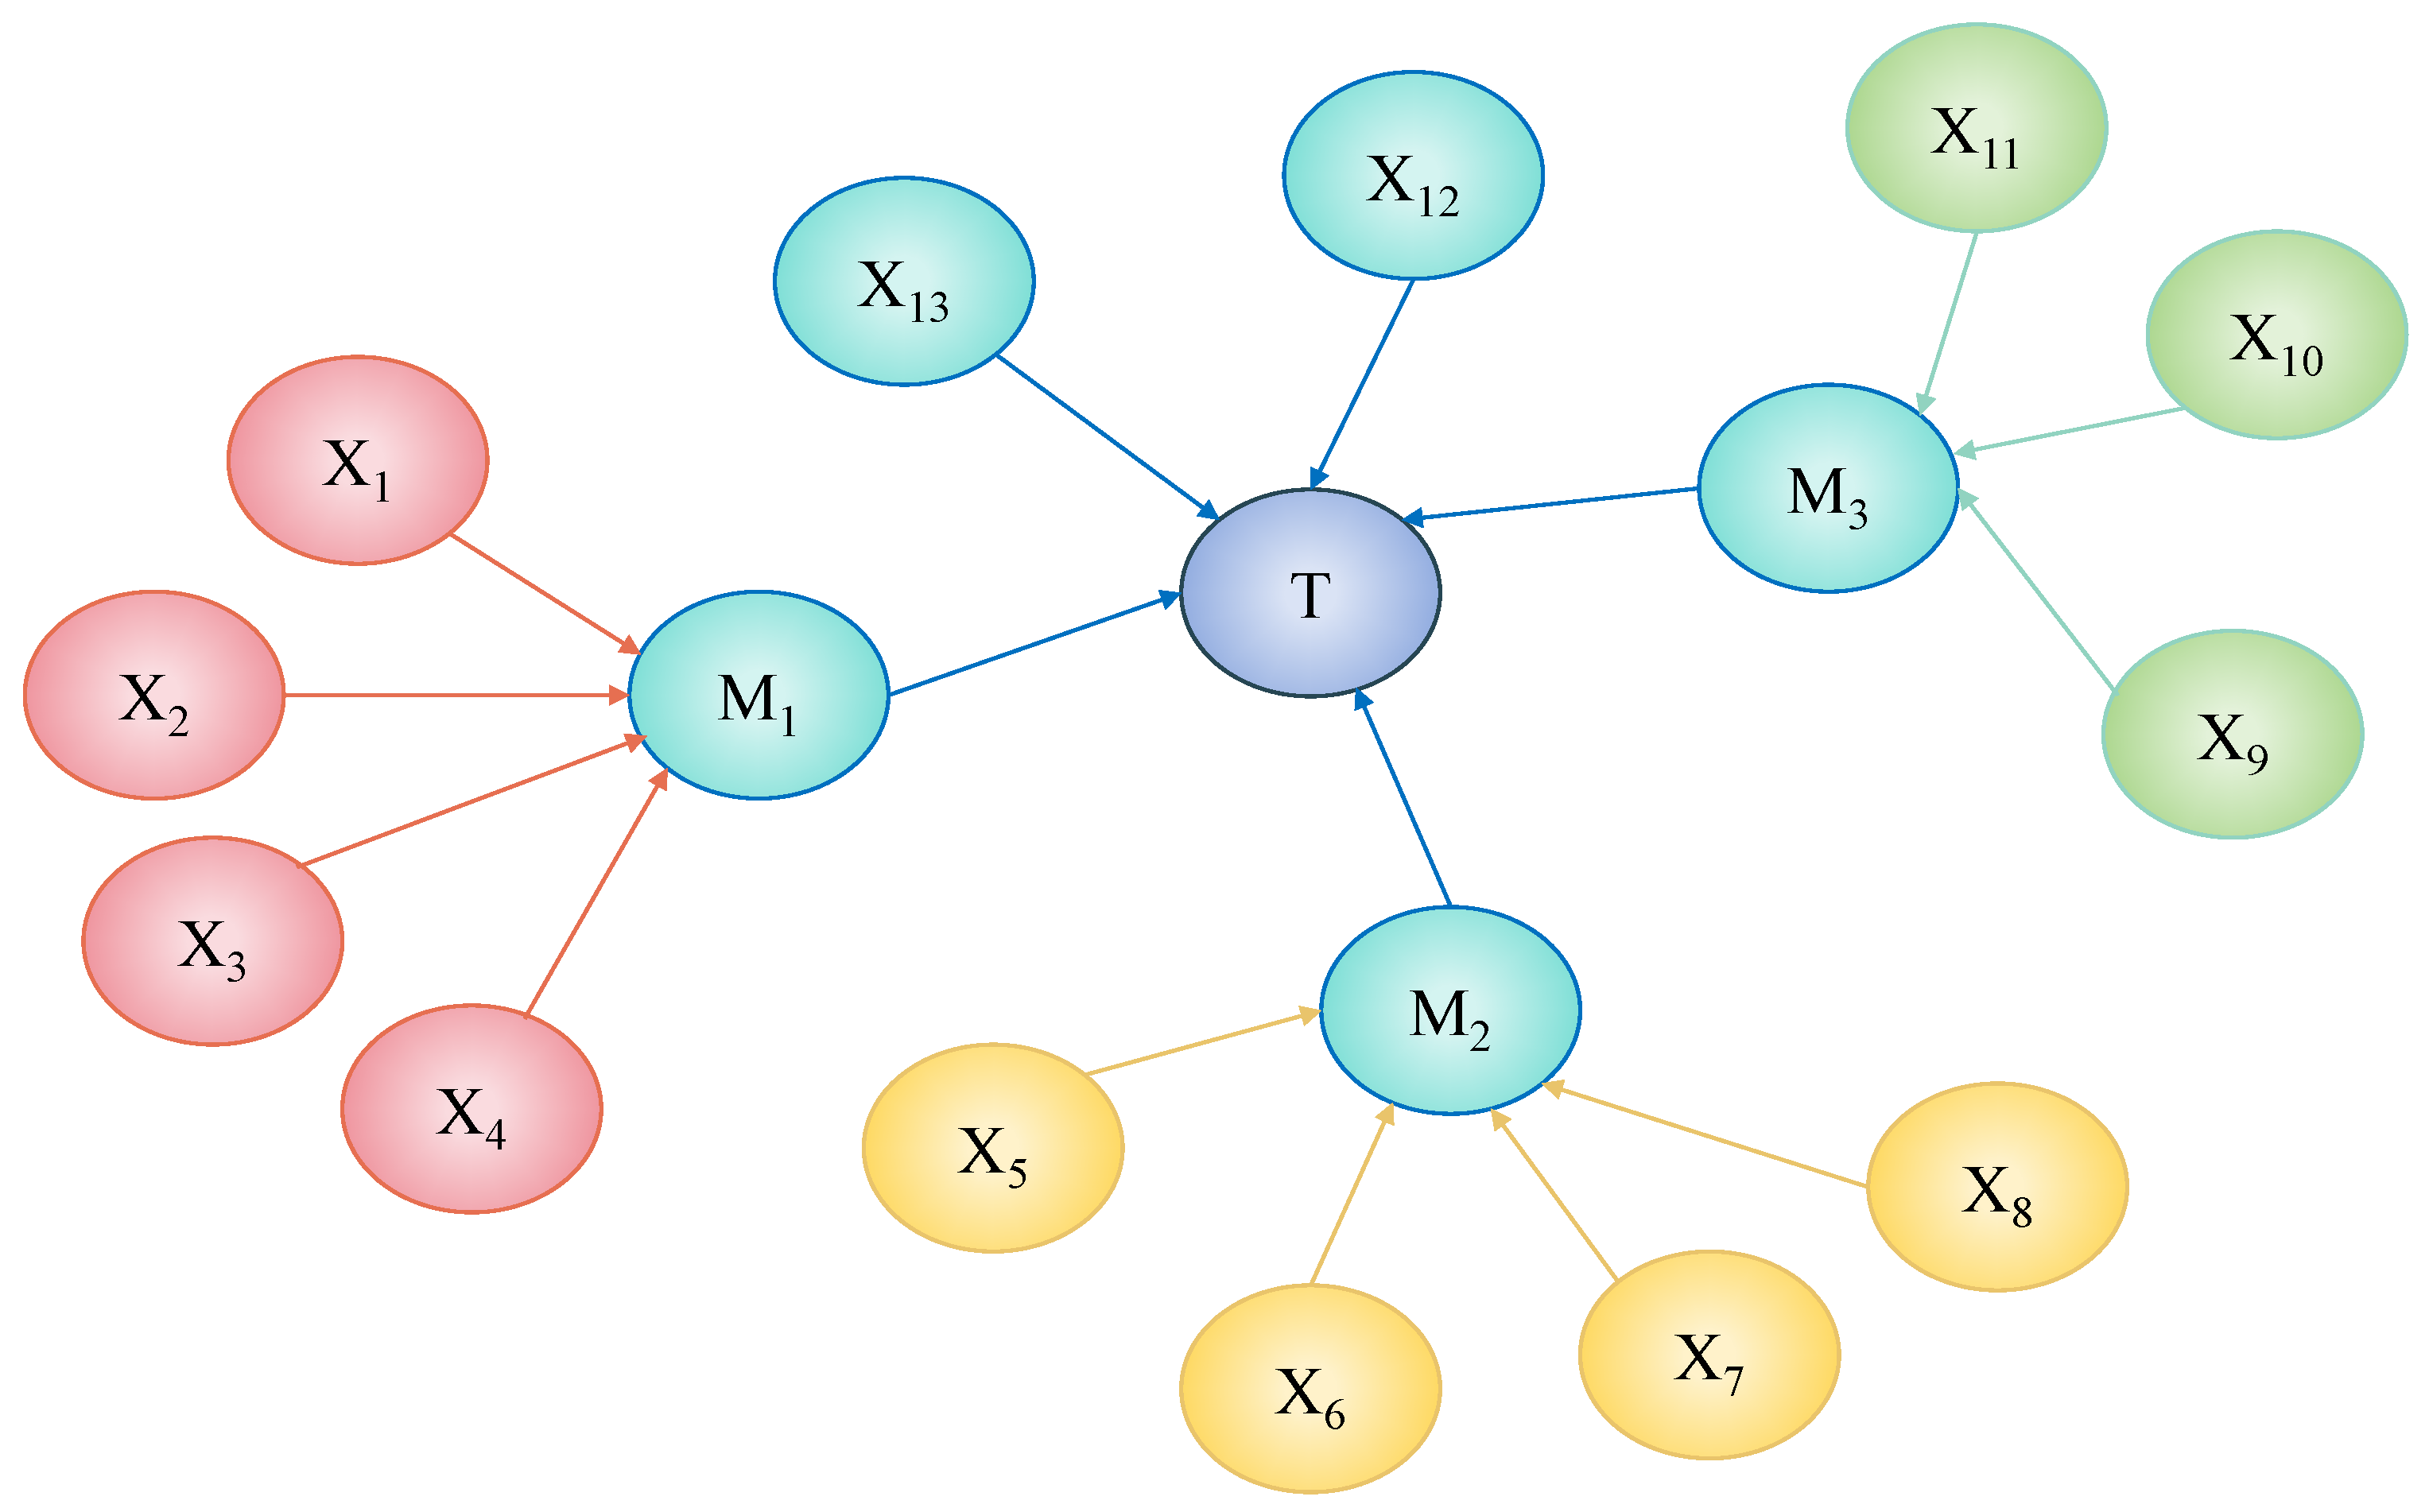
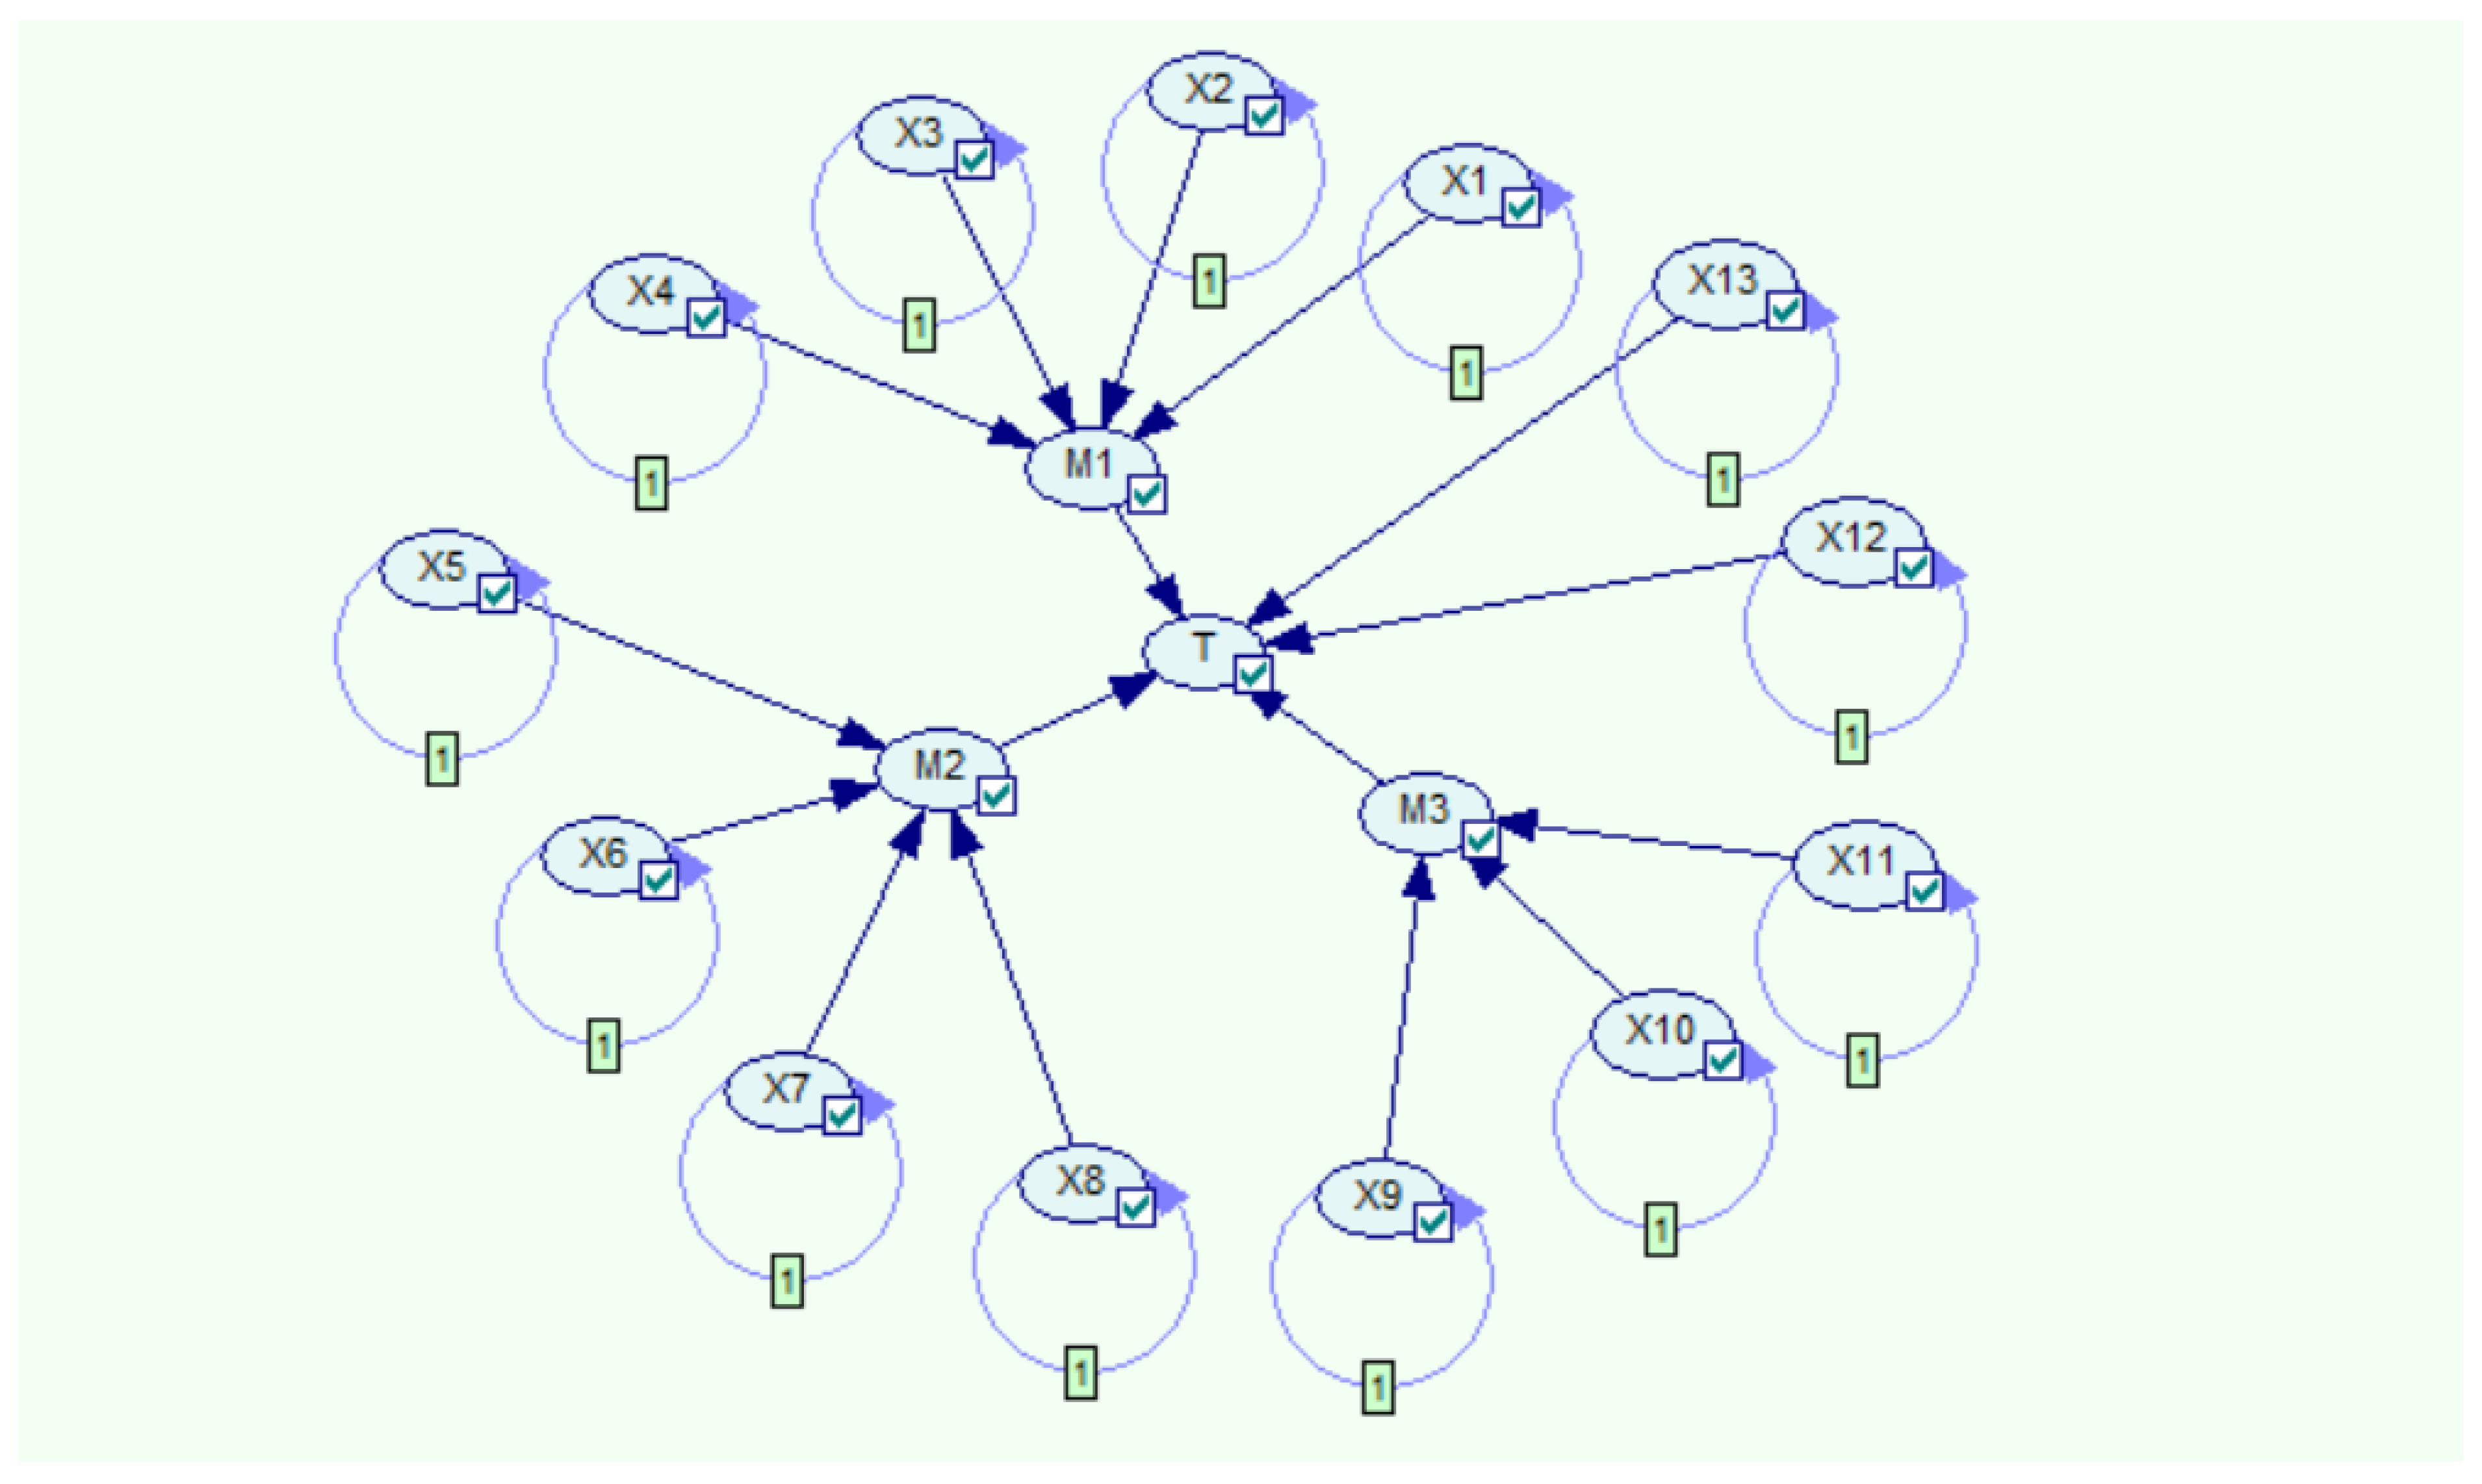
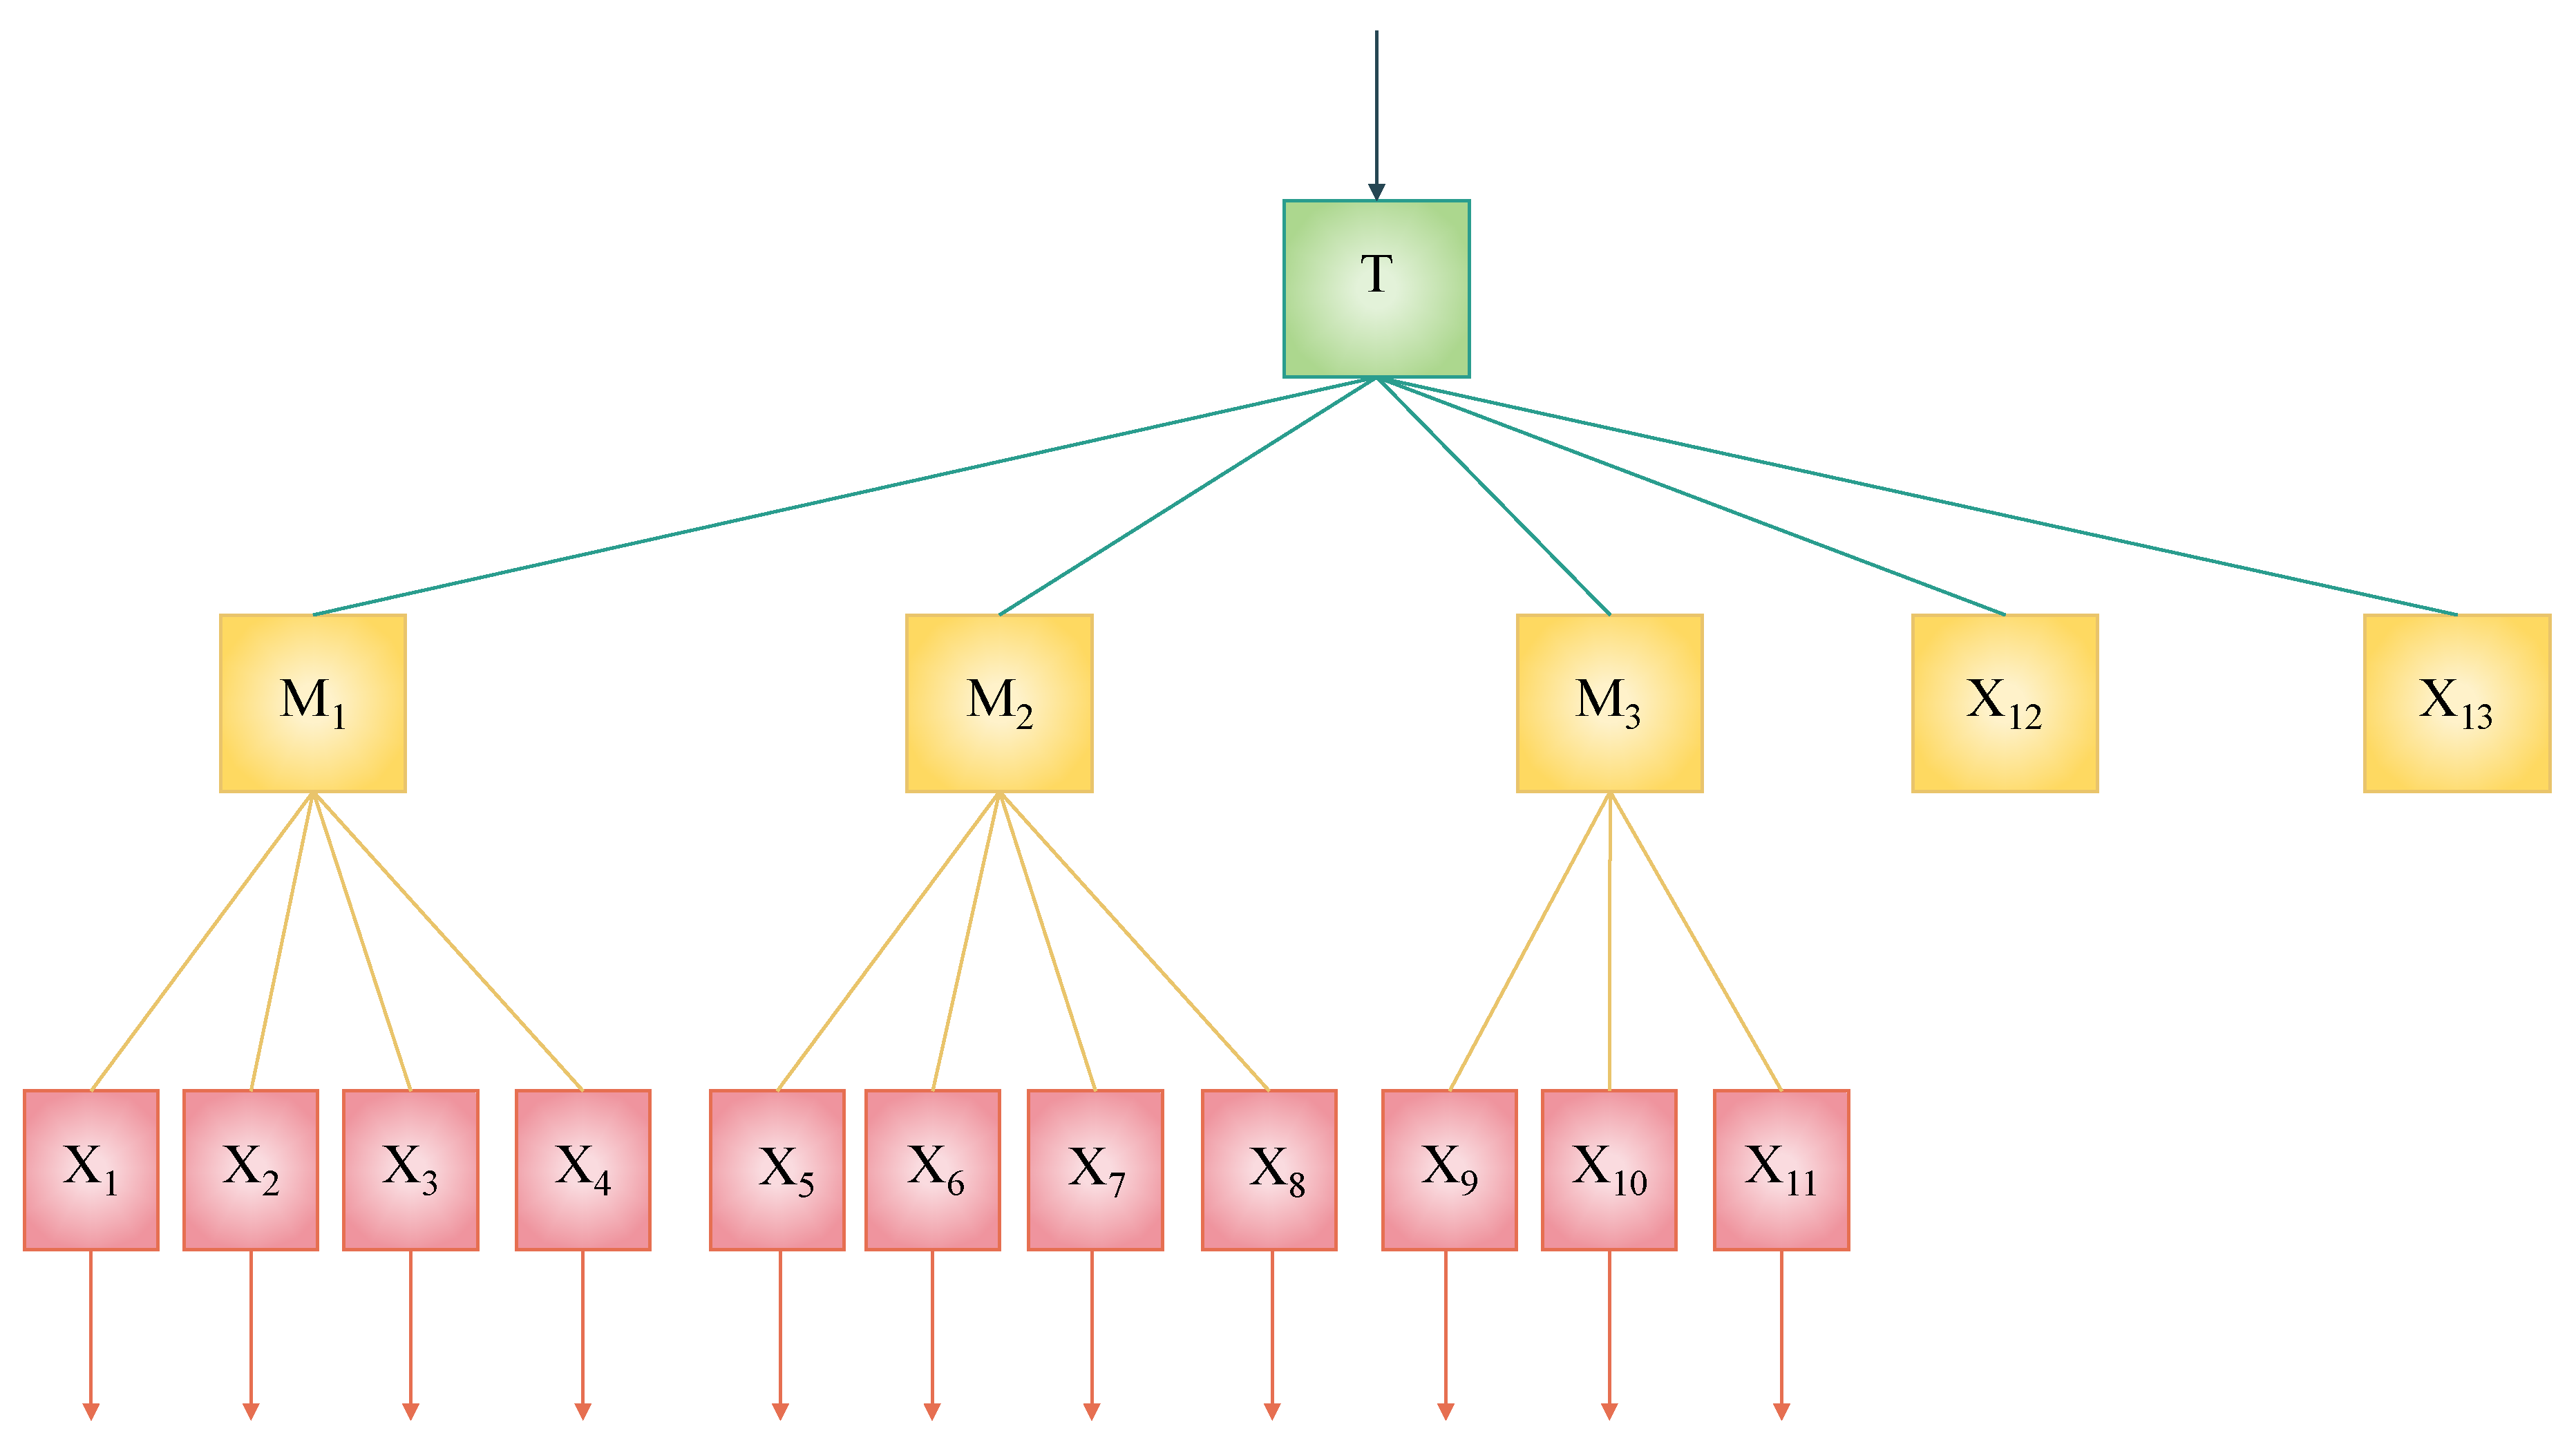
The core of transforming DBN into BP neural network is the dual adaptation of structure and parameters, and its underlying logic originates from the triple adaptation of structure, variable relationships, and optimization objectives. DBN is composed of multiple layers of constrained Boltzmann machines stacked together, and the fully connected architecture between layers presents a hierarchical structure of “leaf nodes–intermediate associated nodes–root nodes”, which naturally fits the feedforward architecture of BP network “input layer–hidden layer–output layer”. Leaf nodes (such as T) have no prior dependencies, corresponding to the input layer of BP network; the root node is the final derivation result, corresponding to the output layer of the BP network; the intermediate associated nodes (such as M
1, M
2, M
3, etc.) assume the role of probability transmission, which is consistent with the feature extraction and signal conversion functions of the BP network’s hidden layer. This mapping method is based on the adaptive design of fault causal semantics and BP neural network feature learning and is not arbitrarily constructed. This node mapping method enables the BP network to accurately learn the causal dependencies and probability propagation logic of “basic variables → intermediate events → target results” in DBN, and the pretrained weights and bias parameters of DBN can be directly mapped to the BP network. Combined with the empirical formula of the number of hidden-layer neurons in the BP network to match the feature dimension with the prediction requirements, it can effectively solve the problem of strong subjectivity in the prior data of DBN. When converting, first establish the corresponding relationship between the above nodes, construct an adaptive structure based on empirical formulas, normalize the prior parameters of DBN, and input them into the BP network. Through training, optimize and reverse modify the parameters. After fitting the optimized prior parameters of each node of DBN, the conversion can be completed [
5], achieving complementary structural and functional advantages of the two.
The DBN was converted into a BP neural network based on the empirical formula for the number of hidden-layer neurons in the BP neural network. The prior distribution of DBN leaf nodes corresponds to the input function, and that of the DBN root node to the output function. The performance of the transformed network was trained, and the trained data was fitted into the prior parameters of each node in the DBN to obtain the optimized prior data of the DBN.
The prior distribution parameters of leaf node T in the coal slurry preparation system DBN were used as input parameters for the BP neural network, and the prior distribution parameters of its root nodes X
1, X
2, X
3, X
4, X
5, X
6, X
7, X
8, X
9, X
10, and X
11 were used as output parameters for the BP neural network. M
1, M
2, M
3, X
12, and X
13 were used as hidden nodes for the coal slurry preparation system BP neural network. Finally, the DBN model was converted into a BP neural network, BP model of coal slurry preparation system as shown in
Figure 14.
Based on Bayesian estimation and Monte Carlo simulation, the initial failure rates of 11 basic nodes in the coal slurry preparation system were obtained. Combining the system’s average failure time of 8000 h, 8000 time points were taken at equal intervals within 0–8000 h to generate a “time failure probability” time-series dataset with 11 output dimensions.
A BP neural network with 1 input layer, 5 hidden layers, and 11 output layers was built, and the input and output were normalized to [0, 1]. The dataset is first divided into a training validation set (accounting for 60% of the total data) and a testing set (accounting for 40% of the total data) in chronological order according to a ratio of 6:4. Then, the training validation set is further divided in chronological order at an 8:2 ratio, resulting in a training set accounting for 48% of the total data and a validation set accounting for 12% of the total data. The entire partitioning process maintains the temporal continuity of the data, which meets the core requirements of time series modeling. A 40% test set proportion can ensure sufficient sample size, fully restore the statistical distribution characteristics of the original data, avoid generalization ability evaluation bias caused by insufficient test set size, and effectively verify model performance. A 60% of the training validation set can provide sufficient sample support for model learning, which is further divided into 48% formal training set and 12% validation set in an 8:2 ratio. The validation set is used for hyperparameter adjustment to achieve a balance between training accuracy and computational efficiency. Given the large sample size advantage of this study with 50,000 samples, a 6:4 data partition ratio is more reasonable compared to the traditional 7:3 ratio. This proportion can further reduce random bias during sampling and ensure the robustness of model training and performance evaluation results.
The BP network uses a normalized f-sequence as input, logsig activation function for the hidden layer, and purelin function for the output layer. Assuming a maximum training round of 1000, a target error of 0.0001, and a learning rate of 0.005, the learning function traingd was selected, and an early shutdown mechanism was added to prevent overfitting.
After adding 0.06 noise to the test set to simulate interference, the average
, RMSE, and MAE of the 11 nodes showed excellent performance, and the BP network had good fitting and prediction effects. The optimized failure rate was more in line with the actual data patterns and avoided the influence of subjective prior assumptions. The failure rate of the optimized nodes is shown in
Table 5.
4.2. Gated Recurrent Unit Model Optimization
In response to the limitations of dynamic Bayesian network (DBN) parameter learning relying on subjective prior assumptions, this study adopts a gated recurrent unit (GRU) network to optimize DBN parameters in a data-driven manner. Based on Bayesian estimation combined with Monte Carlo simulation, obtain the initial failure rate of the basic nodes in the coal slurry preparation system; based on the average failure time of 8000 h in the system, select 50,000 equidistant time points within 0–8000 h to construct a “time failure efficiency” time-series dataset.
After sliding window conversion and normalization of the [0, 1] interval. The dataset is first divided into a training validation set (accounting for 60% of the total data) and a testing set (accounting for 40% of the total data) in chronological order according to a ratio of 6:4. Then, the training validation set is further divided in chronological order at an 8:2 ratio, resulting in a training set accounting for 48% of the total data and a validation set accounting for 12% of the total data. The entire partitioning process maintains the temporal continuity of the data, which meets the core requirements of time series modeling. The constructed GRU model consists of two stacked tanh-activated GRU layers, Dropout regularization layer, and ReLU activated fully connected layer. It is trained using Adam optimizer (learning rate 0.001), introduces early stop strategy, and optimizes hyperparameters through grid search.
After adding 0.0012 noise simulation interference to the test set, the average,
RMSE, and MAE performance of 13 nodes were excellent, verifying the fitting and prediction ability of the GRU network. The optimized failure rate conforms to the actual data distribution and avoids the influence of subjective prior assumptions (see
Table 6 for details).
4.3. Long Short-Term Memory Model Optimization
In response to the limitations of relying on subjective prior distribution assumptions in dynamic Bayesian network (DBN) parameter learning, this study adopts an improved recurrent neural network (RNN) method (specifically implemented as a long short-term memory network (LSTM), which is an extended form of the RNN), optimizes DBN parameters through a data-driven approach, and improves model objectivity.
The initial failure rate data of each basic node in the coal slurry preparation system were calculated based on Bayesian estimation combined with Monte Carlo simulation, as shown in
Table 2. Given that the average failure time of the system is 8000 h, 50,000 time points were collected at equal intervals within the 0–8000 h time range, and the failure rate corresponding to each time point was calculated to form a time-series dataset of “time failure efficiency”.
To adapt to the input requirements of the model, the data was preprocessed by sliding window conversion and normalization to [0, 1]. The dataset is first divided into a training validation set (accounting for 60% of the total data) and a testing set (accounting for 40% of the total data) in chronological order according to a ratio of 6:4. Then, the training validation set is further divided in chronological order at an 8:2 ratio, resulting in a training set accounting for 48% of the total data and a validation set accounting for 12% of the total data. The entire partitioning process maintains the temporal continuity of the data, which meets the core requirements of time series modeling. These sets were input into the LSTM model and used for model training, hyperparameter validation, and generalization ability evaluation.
Adopting the LSTM network as a specific implementation of the RNN (as it is more suitable for capturing long sequence dependencies), its model structure is as follows: the input layer receives normalized sequence data; the hidden layer uses the ReLU activation function (to alleviate the gradient vanishing problem) and sets multiple LSTM units and the Dropout layer (to prevent overfitting); and the output layer uses the linear activation function to directly output the predicted failure rate. In terms of the training configuration, the Adam algorithm is selected as the optimizer, and the early stopping method is introduced to stop training when the validation set loss does not significantly decrease for multiple consecutive rounds to ensure the model’s generalization ability. Parameter tuning involves optimizing key hyperparameters through grid search, including sliding window size, LSTM cell count, Dropout rate, batch size, etc., to minimize prediction errors.
After adding 0.0015 noise simulation interference to the test set, taking node X
11 as an example, after model training and validation, its prediction accuracy is manifested as the loss of the test set (MSE), an RMSE not exceeding 0.006, and a coefficient of determination (
) greater than 0.9, all of which indicates that the model has an excellent fitting effect on the time series of failure rates and can predict them accurately [
5]. The model’s predicted failure rate data are fitted into a distribution function that each node follows, and the optimized failure rate of X
11 nodes is thus obtained. This parameter is more in line with the actual data rules compared to the initial value and avoids the influence of subjective prior assumptions.
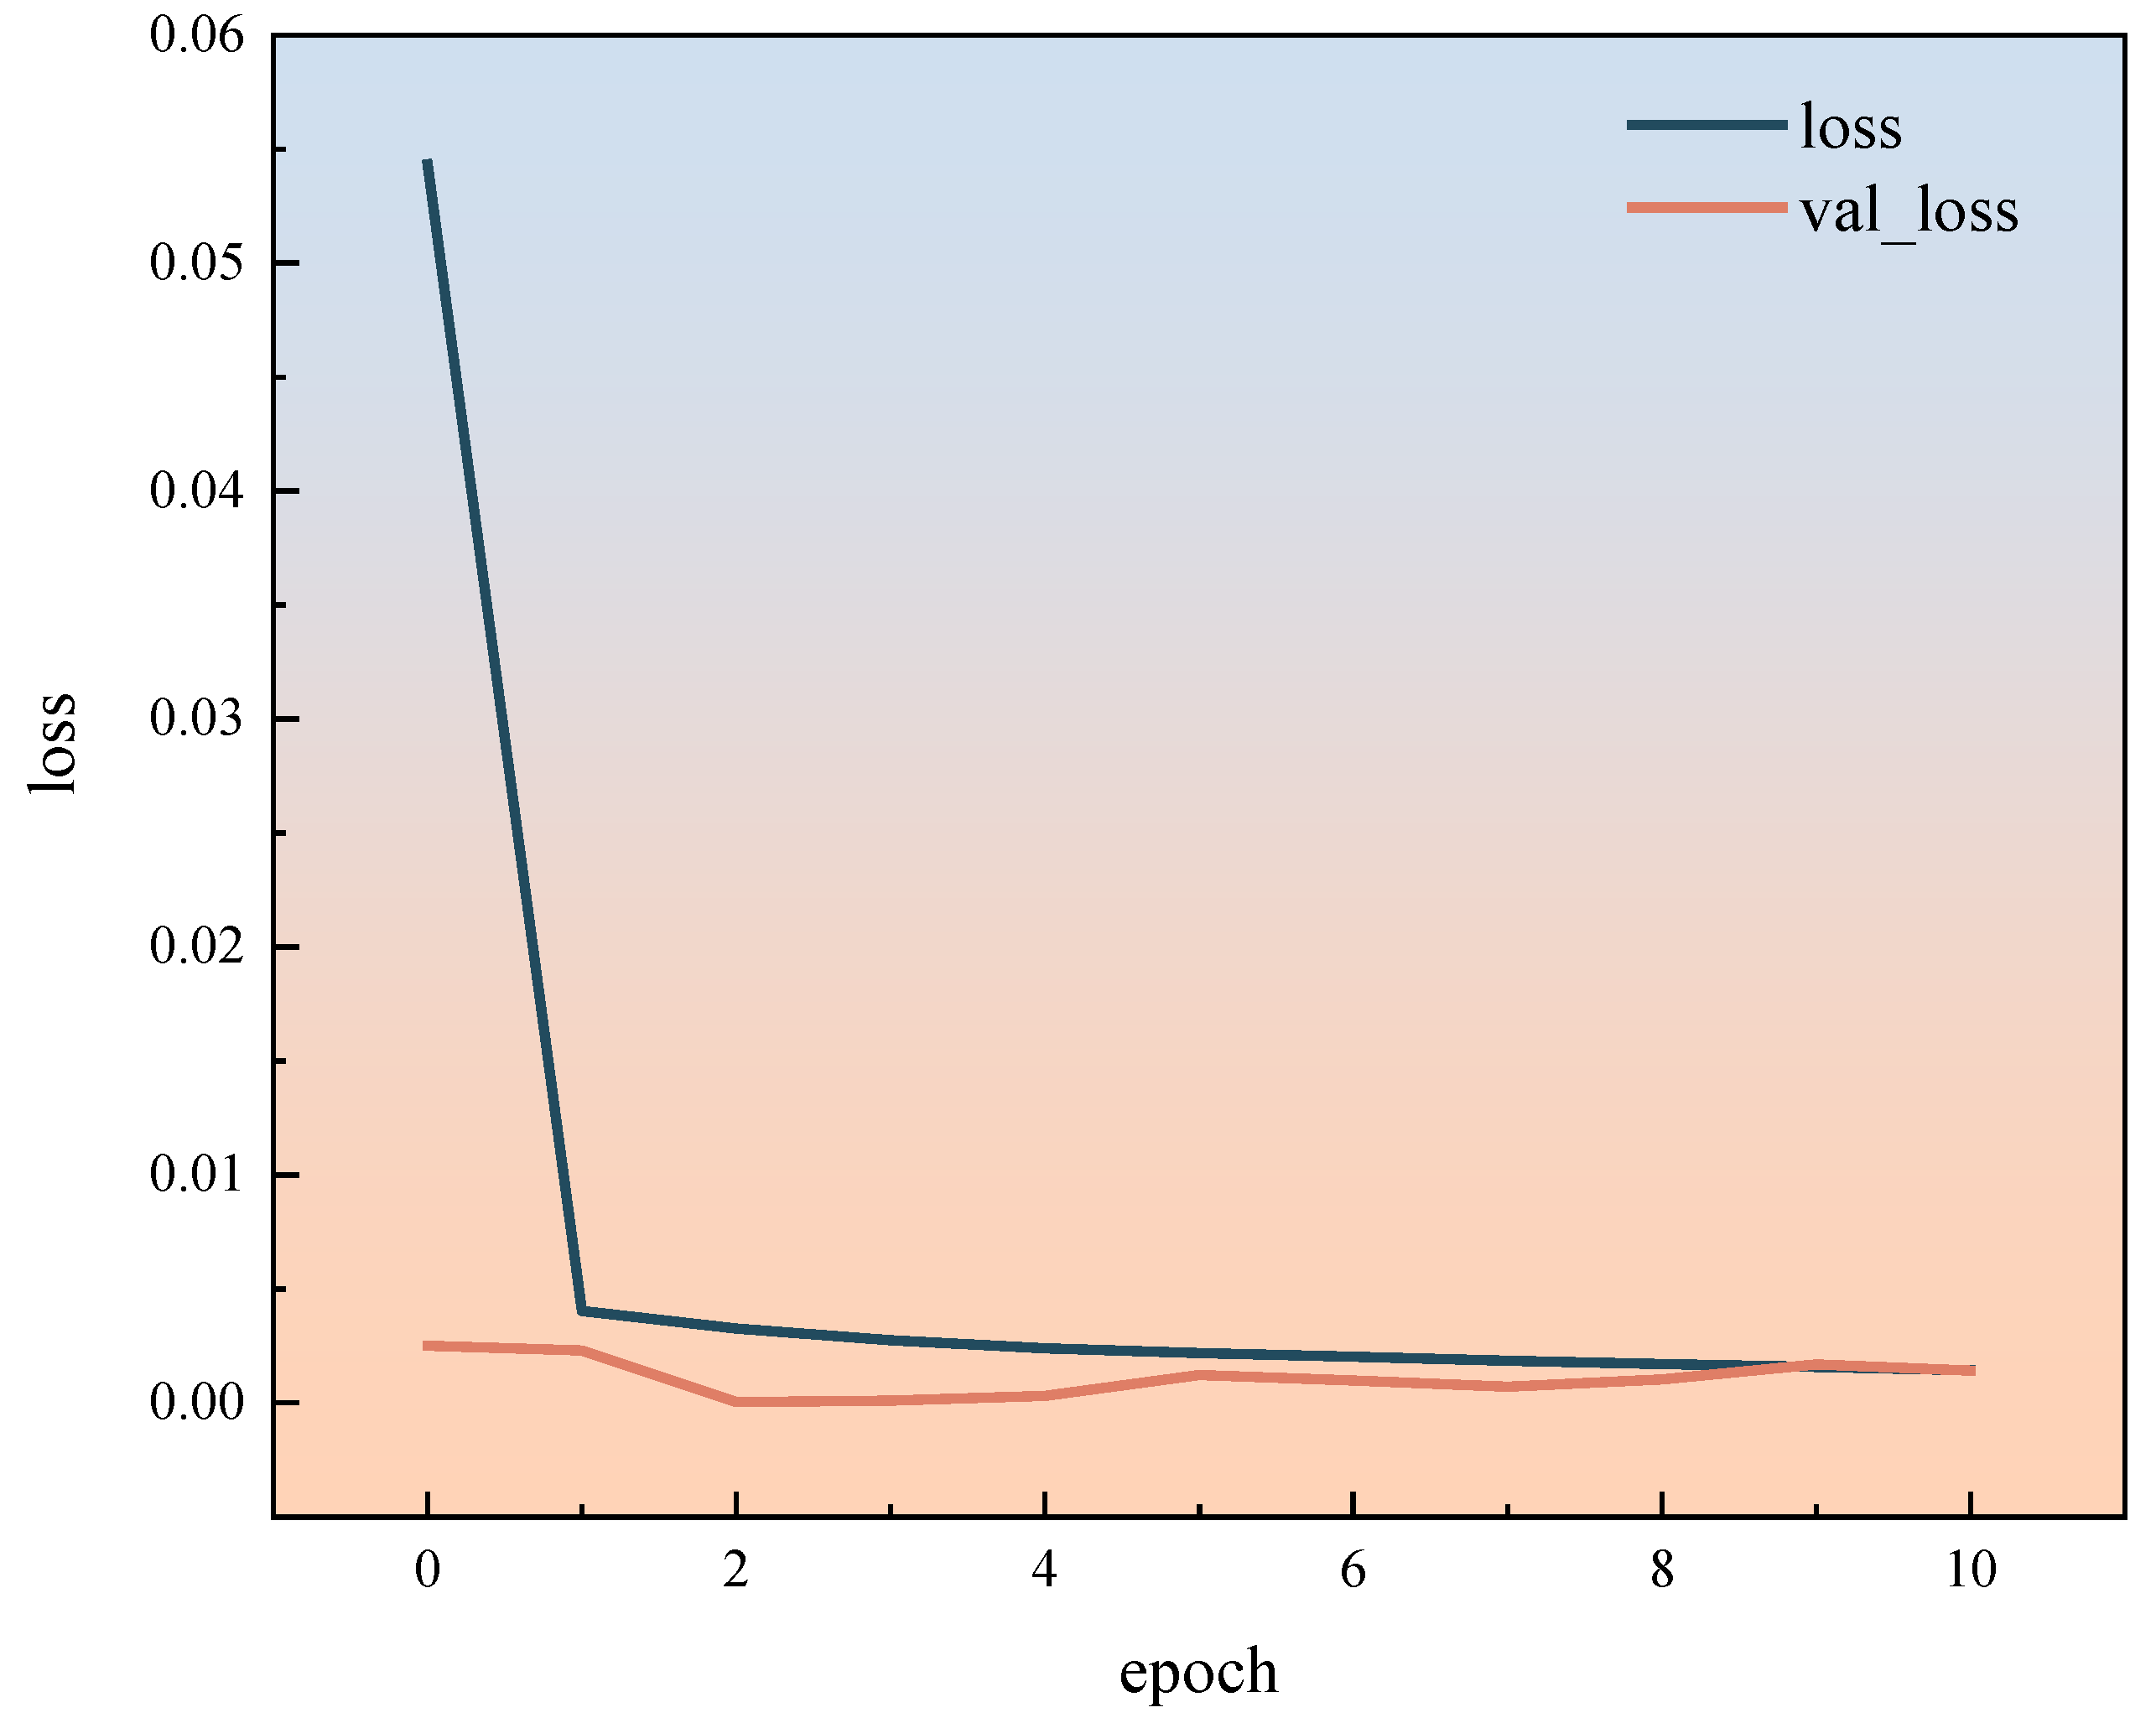
As shown in
Figure 15, the loss function curve of node X
1 is presented, and the performance of the model is excellent: the training loss rapidly decreases in the initial iteration stage, and then tends to be stable at a low loss level, fully demonstrating the efficient learning ability of the model based on the training data; the validation loss is maintained in an extremely low range throughout the process, and is highly fitted to the training loss with minimal fluctuations. There is no learning deficiency caused by underfitting (high loss values are difficult to lower), nor is there a generalization performance defect caused by overfitting (validation loss is significantly higher than training loss). This result indicates that the model not only accurately fits the distribution characteristics of training data but also has stable and reliable prediction ability on unseen test data, making it a high-quality model with good training status.
Similarly, the optimized failure rates of other nodes can be obtained. The node maintenance rate can be determined based on the system’s maintenance methods, maintenance cycles, and past maintenance failure records. The failure rate and maintenance rate of the optimized DBN system are shown in
Table 7 and
Table 8.
4.4. Comparison Between BP, GRU, and LSTM Models
In order to better evaluate the generalization performance of the prediction model and compare the predictive ability of the three prediction models, their prediction error results for three samples are summarized in
Table 9.
According to the data in the table, there is a significant difference in the performance of the three models in predicting node failure rates in coal slurry preparation systems, with LSTM and GRU models performing better overall than BP neural networks. Specifically, the LSTM model achieves full node (including X12 and X13 nodes that are not covered by BP, X12 and X13 are not root nodes, and as child nodes directly associated with the parent node, they can directly act on the parent node, which is different from the mechanism of the root node that needs to indirectly act on the parent node through an intermediate node. Therefore, they are not included in the prediction range of the BP model) prediction coverage, with a coefficient of determination () consistently above 0.9 in most nodes. This not only effectively compensates for the fitting deficiency of the BP model at node X5 (LSTM: 0.9073, BP: 0.5330), but also maintains a high fitting level of around 0.9 for the newly added X12 and X13 nodes; although the GRU model also achieves full node coverage and exhibits extremely low error characteristics in some nodes, the overall mean is slightly lower than that of LSTM, and there are also cases where the fitting effect of some nodes (such as X4) is close to that of the BP model. The BP model not only has gaps in node coverage (X12, X13 not predicted) but also has a fitting weakness such as X5 in existing predicted nodes. Although its root mean square error (RMSE) and mean absolute error (MAE) are stable, the overall level is significantly high, and the comprehensive prediction performance is the worst.
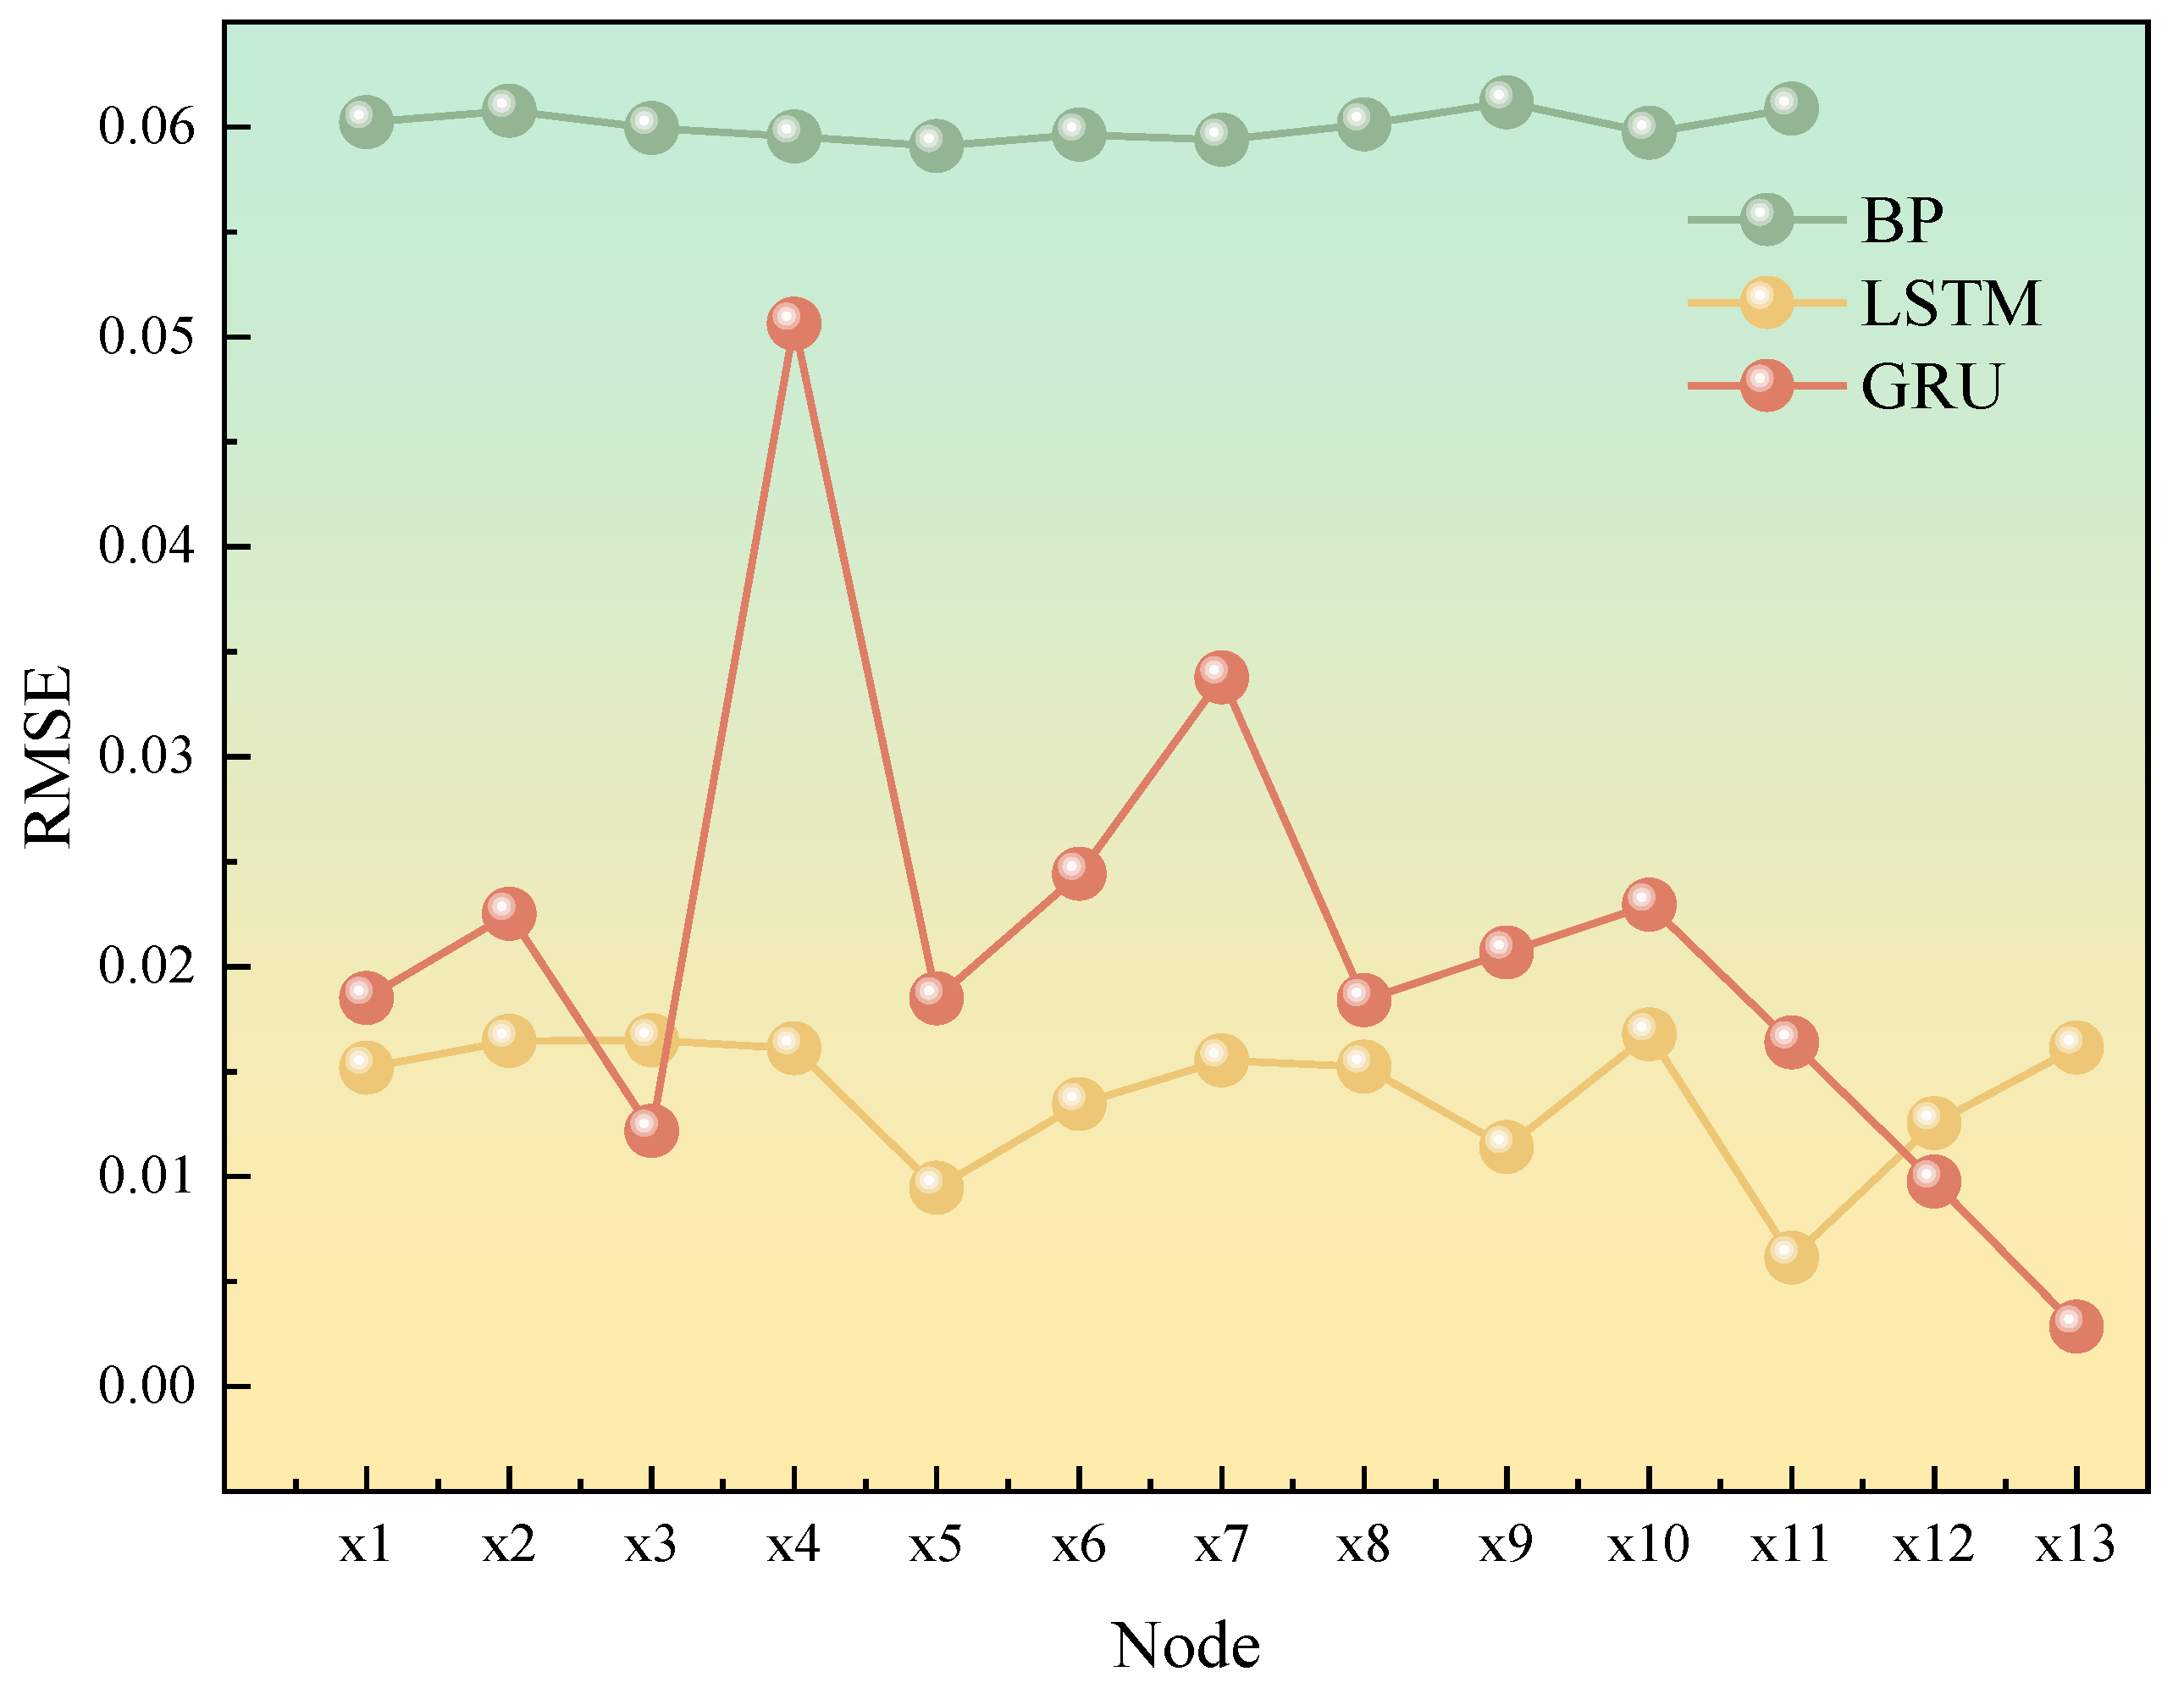
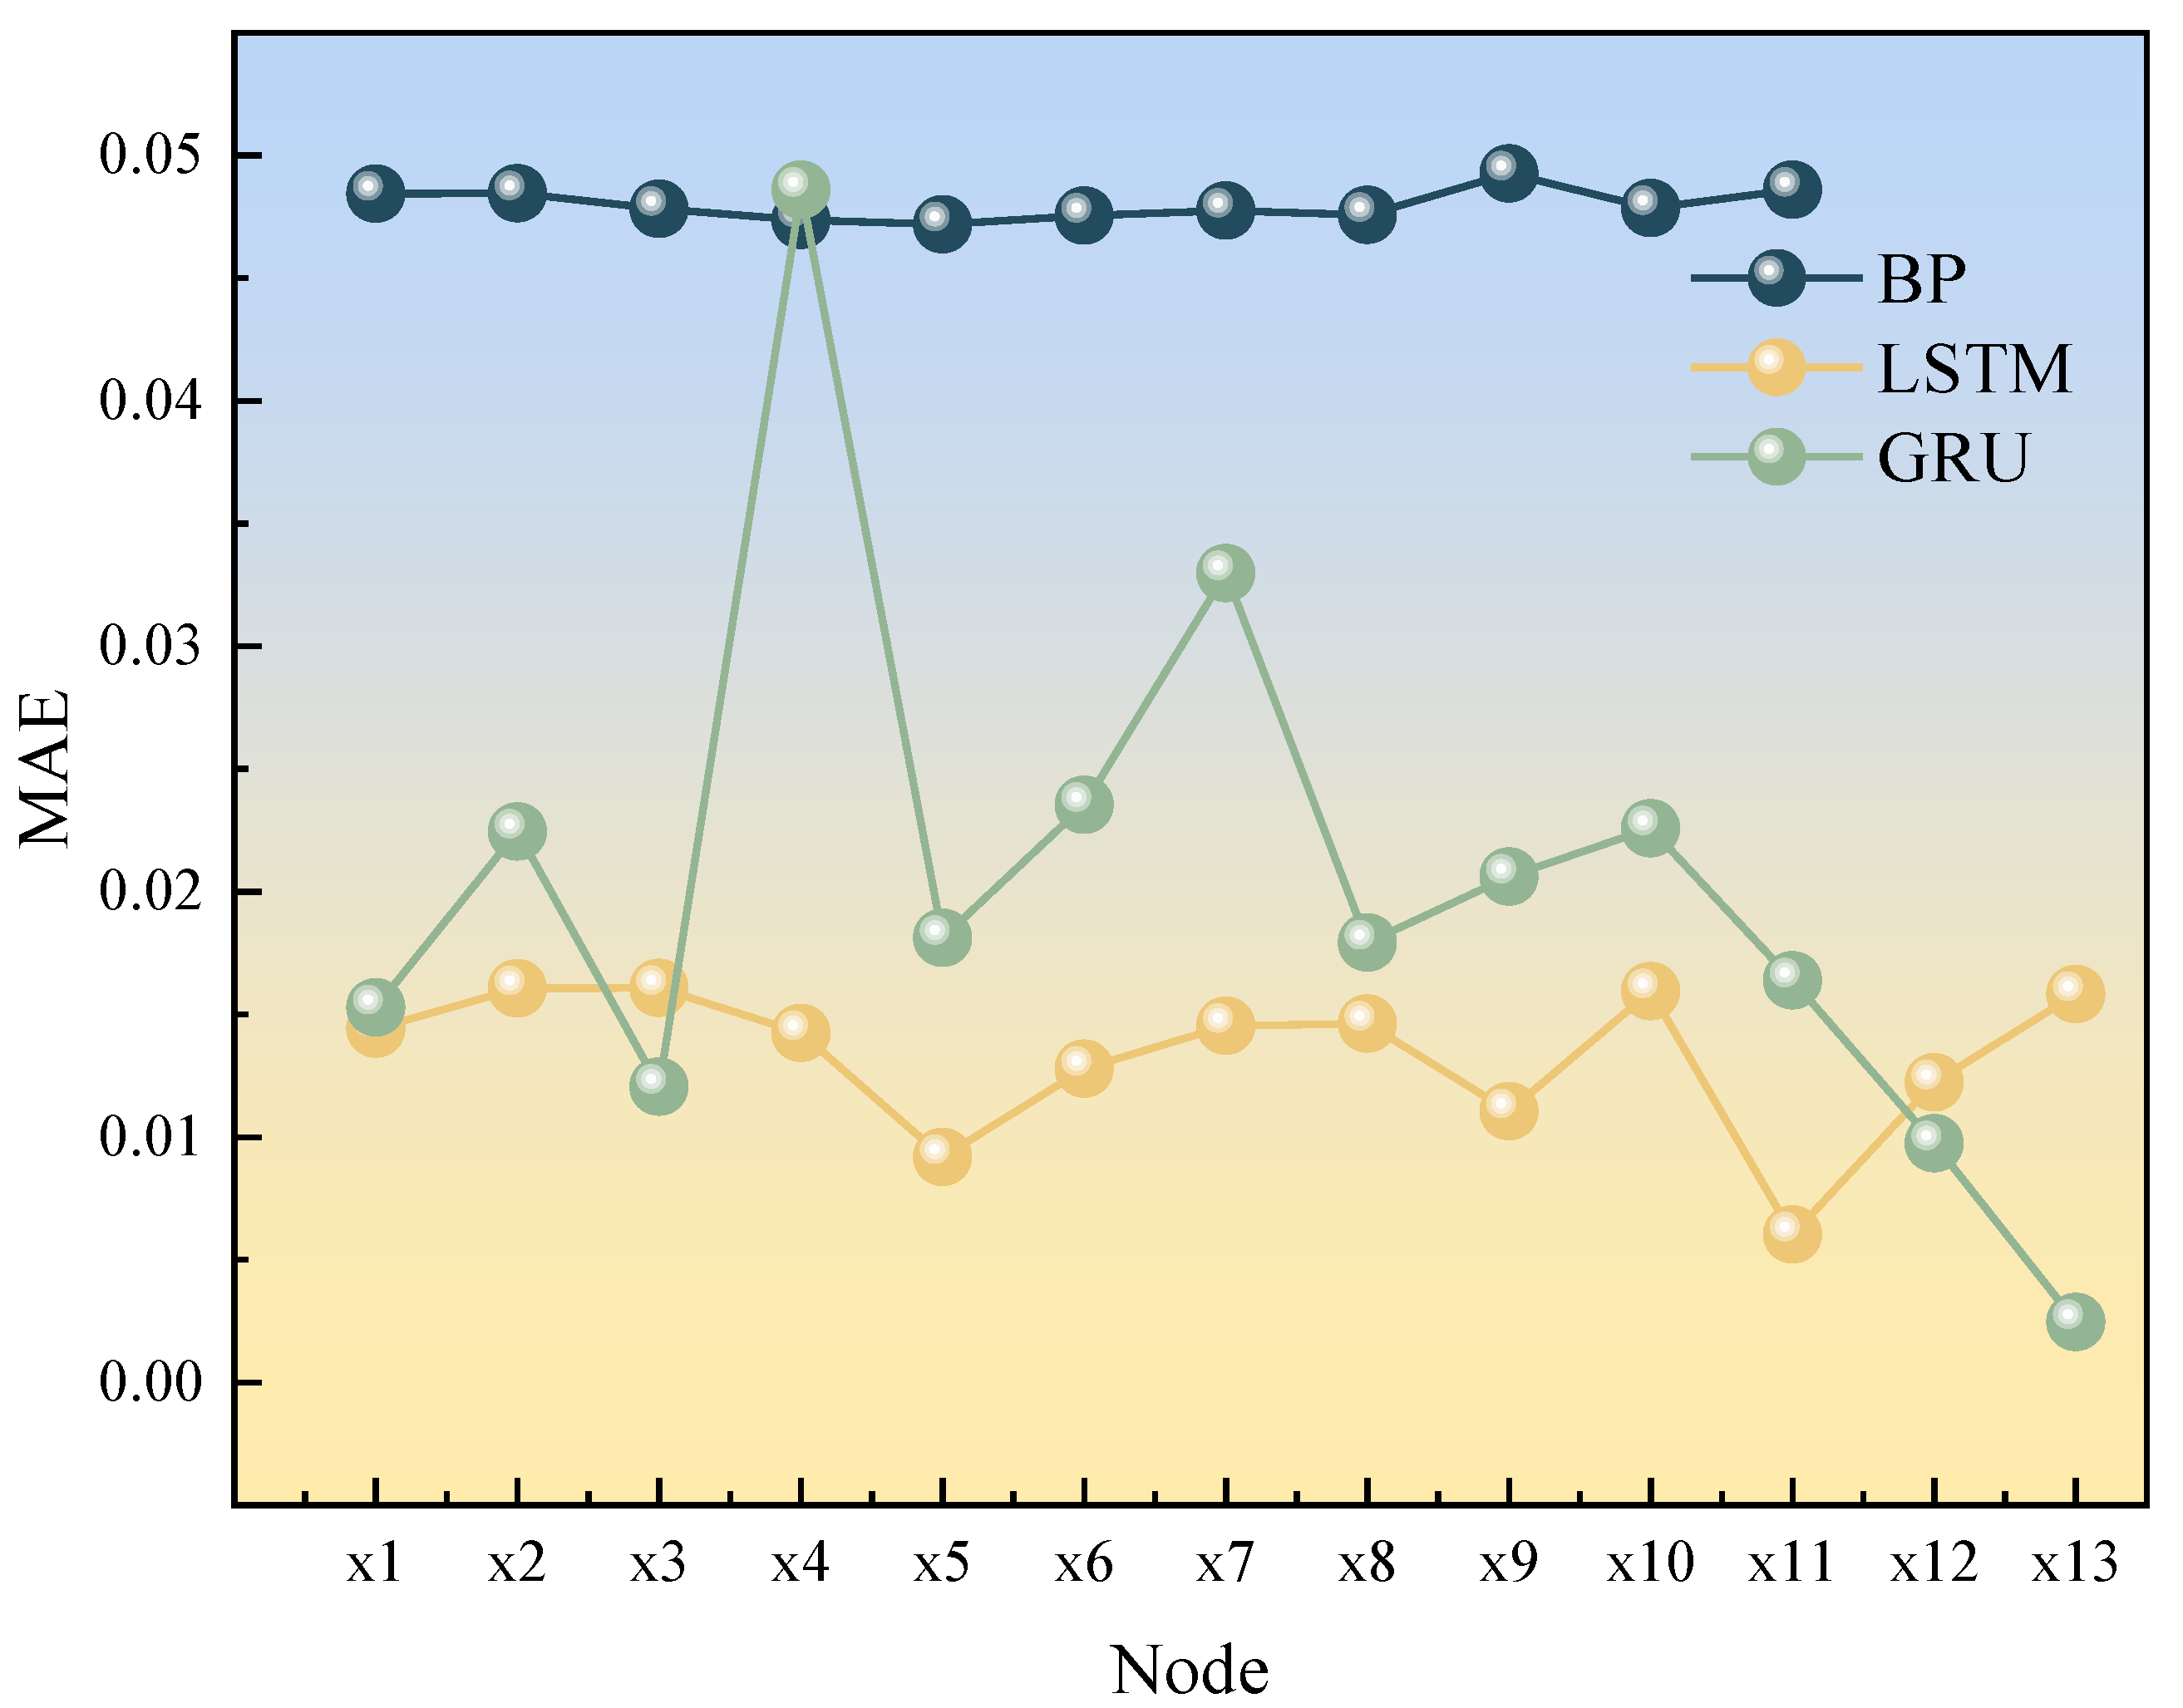
Using nodes as the horizontal axis and the error value of predicting failure probability as the vertical axis, the error curve was visualized, and the prediction error of the neural network model was compared. The prediction errors RMSE and MAE of the three models are shown in
Figure 16 and
Figure 17, respectively.
The error visualization results of
Figure 16 (RMSE comparison) and
Figure 17 (MAE comparison) further validate the performance differences mentioned above. From the perspective of error distribution characteristics, the error index of the BP model shows a “stable but high” feature, with its RMSE consistently maintained at around 0.06 and MAE stable around 0.048. Although the fluctuation amplitude is minimal, it is overall in the high error range; the RMSE and MAE of the LSTM model are both concentrated in the low error range below 0.02, with uniform error distribution and optimal overall level, demonstrating excellent error control capability; the error curve of the GRU model exhibits significant volatility. On the one hand, the lowest error value of the entire model appears at nodes such as X
13 (such as RMSE of only 0.002), demonstrating local prediction advantages. On the other hand, at nodes such as X
4, the error value suddenly rises to a level close to that of the BP model, and its stability is significantly worse than that of LSTM. The above visualization results are consistent with the table data, fully indicating that the LSTM model has comprehensive advantages in error control, while the GRU model has the characteristics of local advantages and insufficient stability, and the BP model is difficult to meet the accurate prediction requirements of this scenario due to its high error characteristics.
Overall, LSTM model outperforms the BP model and GRU model in failure rate prediction in terms of fitting degree (), error control (MAE, RMSE), and node coverage and generalization ability. The LSTM exhibits significant advantages, especially in low-fitting weak nodes (such as X5) and newly added nodes (X12, X13). In these areas, its strengths are more prominent and more suitable for the accurate prediction of failure rates at various nodes in coal slurry preparation systems.
7. Future Development
The LSTM model constructed in this study optimized the parameters of the DBN model, achieving quantitative assessment and early warning of dynamic risks in coal slurry preparation systems, providing quantitative support for predictive maintenance. Subsequent research will deepen from the data layer, method layer, and application layer: the data layer will introduce industrial measured fault data to solve the problem of insufficient generalization ability of simulated data; at the method level, this research method will be compared and integrated with frameworks such as hybrid Bayesian networks and evidence-based hazard modeling to clarify technical advantages and boundaries; the application layer improves the all factor operation and maintenance modeling, embeds physical constraint modules, optimizes the adaptability to non-steady state operating conditions, and develops real-time monitoring modules to promote the transition of technology from offline analysis to online warning. Meanwhile, future research will focus on sensor accuracy and error distribution, constructing a noise quantification model for dynamic risk assessment of coal slurry systems, and calibrating parameters with long-term on-site data. It will integrate the temporal characteristics of multidimensional monitoring data, optimize the noise strategies of BP, LSTM, and GRU models, and improve the accuracy and reliability of risk assessment. In addition, the team will collaborate with enterprises in data sharing and engineering applications, integrate full process industrial datasets, validate the out of sample predictive performance of the model, and analyze the impact of optimization priors on system reliability and diagnostic accuracy. In summary, this study provides a feasible solution for risk assessment in process industries. Future work will extend its application to complex systems, facilitate the implementation of methods, and provide quantitative decision support for predictive maintenance.