


Abstract
Landslide susceptibility assessment is important for disaster prevention and sustainable land-use planning in mountainous regions. However, conventional discretization methods often overlook threshold effects in conditioning factors, and many machine learning models still have limited interpretability. This study develops an integrated framework that combines ChiMerge discretization, Weight of Evidence (WOE) transformation, and tree-based ensemble learning to map landslide susceptibility in Jiuzhaigou County, Sichuan Province, China. A landslide inventory of 164 points was compiled from field investigations and hazard records, and fourteen topographic, geological, and environmental conditioning factors were derived from multi-source spatial datasets. Continuous factors were discretized using ChiMerge, a supervised chi-square-based discretization method that identifies statistically meaningful thresholds according to the distributions of landslide and non-landslide samples. WOE values were then calculated to quantify the association between each factor class and landslide occurrence. Three WOE-based ensemble models, WOE-CatBoost, WOE-LightGBM, and WOE-RF, were constructed and compared. All models showed high predictive performance (AUC > 0.90), with WOE-CatBoost performing best (AUC = 0.9432). Its high and very high susceptibility zones covered 28.59% of the study area but contained 85.96% of observed landslides. High-risk areas were mainly concentrated in steep valleys, fractured lithological zones, erosion belts, and areas affected by engineering activities, such as road construction, slope cutting, tourism infrastructure development, and settlement expansion. The proposed framework improves prediction accuracy and interpretability and provides spatial support for landslide prevention and sustainable land-use management.
1. Introduction
Landslides are among the most destructive geological hazards in mountainous regions, posing serious risks to human lives, infrastructure, land resources, and ecological security [1]. Landslides can occur in various forms, including rock slides, debris slides, shallow landslides, rockfalls, and debris flows, depending on material type, movement mechanism, slope structure, and triggering conditions [2,3]. Under the combined effects of climate variability, extreme rainfall, and intensified engineering activities, landslide occurrence has become more spatially complex, creating challenges for disaster risk reduction and sustainable land-use planning. Therefore, accurate regional-scale landslide susceptibility assessment is needed to identify landslide-prone areas and support infrastructure planning, early warning, and mitigation strategies.
Traditional landslide susceptibility assessment methods include Frequency Ratio (FR), Information Value (IV), Logistic Regression (LR), and WOE models [4,5,6]. These methods are widely used because they are relatively easy to implement and provide clear statistical interpretations. FR and IV models quantify the relationship between landslide occurrence and conditioning factor classes [7,8] while LR is commonly used to model the relationship between landslide occurrence and multiple conditioning factors [9]. The WOE method assigns interpretable statistical weights to environmental factor categories and has been effectively applied in landslide susceptibility mapping [10,11,12,13]. However, these methods generally rely on predefined factor classifications and have limited ability to represent complex nonlinear interactions among conditioning factors. For example, in FR, IV, and WOE models, continuous factors such as slope, elevation, rainfall, and distance to faults are usually divided into predefined intervals, such as equal intervals, natural breaks, or expert-defined classes, before statistical weights are calculated [14,15]. Such fixed classes may overlook the actual threshold response of landslide occurrence. Moreover, landslide susceptibility is often controlled by coupled effects among multiple factors, such as steep slopes, weak lithology, fault proximity, sparse vegetation, and high rainfall, which are difficult to fully represent using traditional statistical models [2,16,17].
In classification-based landslide susceptibility assessment, continuous conditioning factors, such as elevation, slope, curvature, precipitation, and distance to faults, are often discretized into intervals before calculating occurrence probabilities or statistical weights for different factor classes [15]. Common discretization methods include equal interval, natural breaks, quantile, and geometric interval classification [14,18]. The choice of discretization method usually depends on the data distribution, research purpose, and availability of landslide/non-landslide labels. Equal interval classification divides the value range into intervals of the same width, whereas natural breaks classification identifies inherent groupings in the data distribution. Quantile classification assigns a similar number of samples to each class, and geometric interval classification creates class breaks based on a geometric series and is often used for continuous variables with uneven value ranges. In landslide susceptibility mapping, different classification schemes may lead to different susceptibility modelling results [14]. However, these methods are generally unsupervised and mainly depend on the distribution of factor values rather than the relationship between conditioning factors and landslide occurrence. In contrast, ChiMerge is a supervised discretization method that uses landslide and non-landslide samples to identify statistically meaningful thresholds [19]. Therefore, ChiMerge was prioritized in this study because the aim was not only to classify continuous factors, but also to identify threshold intervals more closely related to landslide occurrence.
Machine learning algorithms have been increasingly used for landslide susceptibility mapping because of their ability to model nonlinear relationships among multiple conditioning factors [2,17,20]. Ensemble tree-based models, including RF, GBDT, LightGBM, CatBoost, and XGBoost, have shown strong predictive performance in susceptibility assessment [21,22,23,24]. Other algorithms, such as Support Vector Machines and Neural Networks, have also been applied in this field [25,26,27]. However, although these models can improve prediction accuracy, their interpretability and spatial generalization ability still require further improvement. For practical applications in disaster prevention and land-use management, model outputs should provide not only accurate predictions but also understandable information on the contribution of conditioning factors [28,29,30,31]. Interpretable susceptibility results are also useful for practical mitigation. High-susceptibility zones can be prioritized for field investigation, slope deformation monitoring, early warning, and engineering treatment. In these areas, mitigation measures may include restricting inappropriate construction, optimizing road and settlement planning, improving surface and subsurface drainage systems, reinforcing unstable slopes, and reducing excessive slope cutting or other engineering disturbances. To address these limitations, ChiMerge discretization provides a supervised approach for determining statistically meaningful intervals of continuous conditioning factors. Based on the chi-square test, ChiMerge iteratively merges adjacent intervals with similar class distributions and can identify thresholds that are closely related to landslide occurrence [19]. This method has been applied in different fields and has shown the ability to produce structured and interpretable features [3,32,33,34]. After discretization, WOE encoding can quantify the association between each factor category and landslide occurrence, producing interpretable numerical inputs for machine learning models. Combining ChiMerge discretization, WOE encoding, and ensemble learning therefore offers a way to integrate threshold-sensitive feature processing, statistical interpretability, and nonlinear predictive modeling.
The specific objectives of this study were to: (1) construct a landslide conditioning factor system based on topography, geological structure, hydrometeorological conditions, vegetation, and land use; (2) identify statistically meaningful threshold intervals of continuous factors using ChiMerge discretization; (3) quantify the contribution of factor categories to landslide occurrence through WOE encoding; (4) compare the predictive performance and spatial consistency of WOE-CatBoost, WOE-LightGBM, and WOE-RF models; and (5) discuss the implications of landslide susceptibility mapping for disaster risk reduction, infrastructure safety, and sustainable land-use planning in mountainous regions.
2. Materials
2.1. Study Area Overview
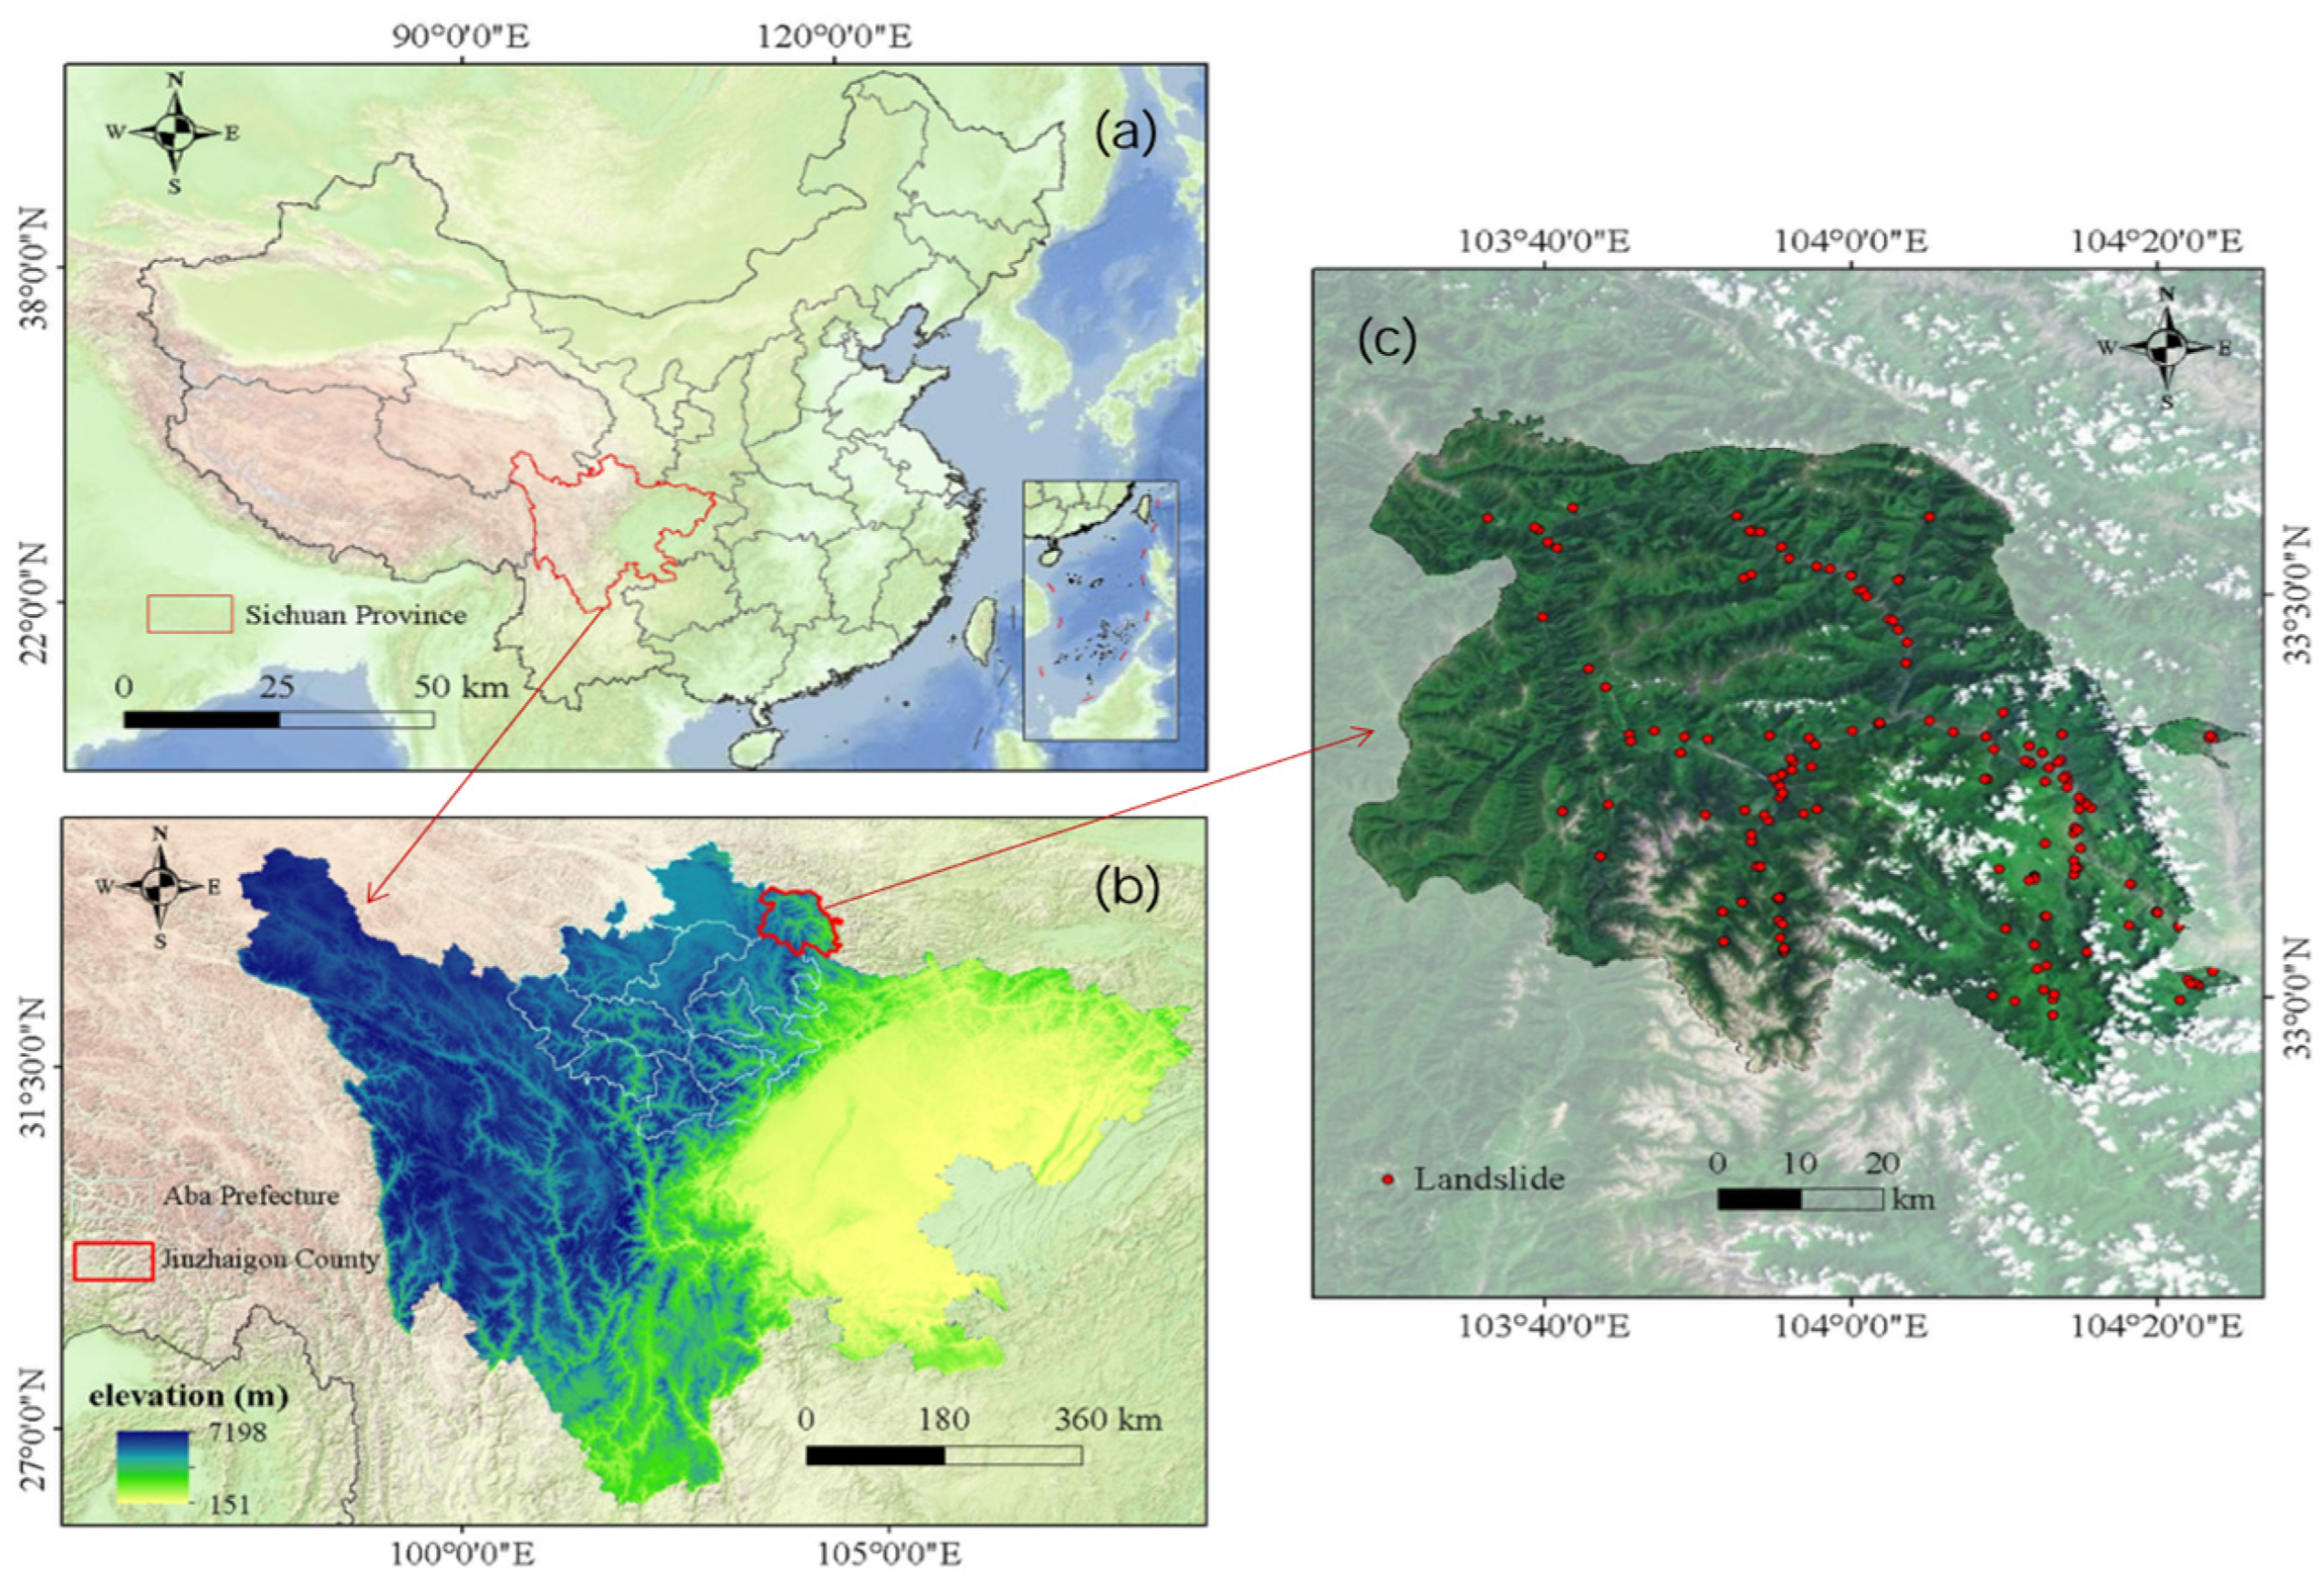
Jiuzhaigou County is located in northeastern Sichuan Province, China, at the southern end of the Min Mountains and in the transition zone between the Qinghai–Tibet Plateau and the Sichuan Basin. Its geographic extent ranges from approximately 103°27′ to 104°26′ E and from 32°53′ to 33°43′ N (Figure 1). The county covers approximately 5288 km2, with an average elevation of about 2800 m and a maximum relative elevation difference of 3428 m. The terrain is dominated by high mountains and deeply incised valleys. The region has a humid climate, with an average annual temperature of about 7.8 °C. Rainfall is concentrated from May to October.
Figure 1.
Overview of the study area: (a) geographical location of Sichuan Province in China; (b) location of Jiuzhaigou County within Aba Prefecture, Sichuan Province, with elevation background; (c) spatial distribution of landslide points in Jiuzhaigou County.
Geologically, Jiuzhaigou County lies in the northern segment of the Longmenshan Fault Zone and is affected by neotectonic activity and major faults, including the Huya Fault and Minjiang Fault. Based on field investigations and existing hazard records, landslides in the study area are mainly distributed along fault zones, river valleys, and terraces. The combination of steep terrain, fractured rock masses, river incision, and seasonal rainfall provides favorable conditions for landslide development. Landslide susceptibility assessment in this region can support disaster prevention, infrastructure safety, settlement risk management, and sustainable land-use planning.
2.2. Data Sources and Landslide Inventory
The datasets used in this study consisted of a landslide inventory and a set of candidate landslide conditioning factors, all processed at a spatial resolution of 30 m (Table 1). Based on landslide formation mechanisms and previous susceptibility studies, an initial conditioning factor system was established from six aspects: topography, geological structure, hydrometeorological conditions, vegetation and ecological characteristics, land use, and ecosystem conditions [35,36]. In total, 164 landslide inventory points were compiled from field investigations, existing geological hazard records, and relevant reports. The candidate conditioning factors were obtained from multiple spatial datasets, including topographic, geological, hydrometeorological, vegetation, land-use, and ecosystem-related data. To facilitate mapping and analysis, the candidate factors were labeled with alphabetical identifiers (a–p), consistent with the labels used in the following figures.
Table 1.
Candidate landslide conditioning factors and data sources used in this study.
2.3. Data Processing and Conditioning Factor Construction
2.3.1. Data Preprocessing
All spatial datasets were preprocessed in ArcMap 10.8 through clipping, projection, resampling, and raster alignment. To ensure spatial consistency among data layers, all candidate conditioning factors listed in Table 1 (factors a–p) were converted to the same projected coordinate system and resampled to a spatial resolution of 30 m. After raster alignment and masking, the study area contained 5,826,262 valid 30 m × 30 m grid cells. The value of each conditioning factor was then extracted for every valid grid cell to establish a spatial attribute database [3]. Based on the landslide inventory, grid cells containing landslide points were labeled as 1 and treated as positive samples. Grid cells without recorded landslides were not regarded as absolutely landslide-free areas, but were used as candidate non-landslide samples for subsequent negative sample selection and model construction [37].
2.3.2. Optimization and Selection of Candidate Conditioning Factors
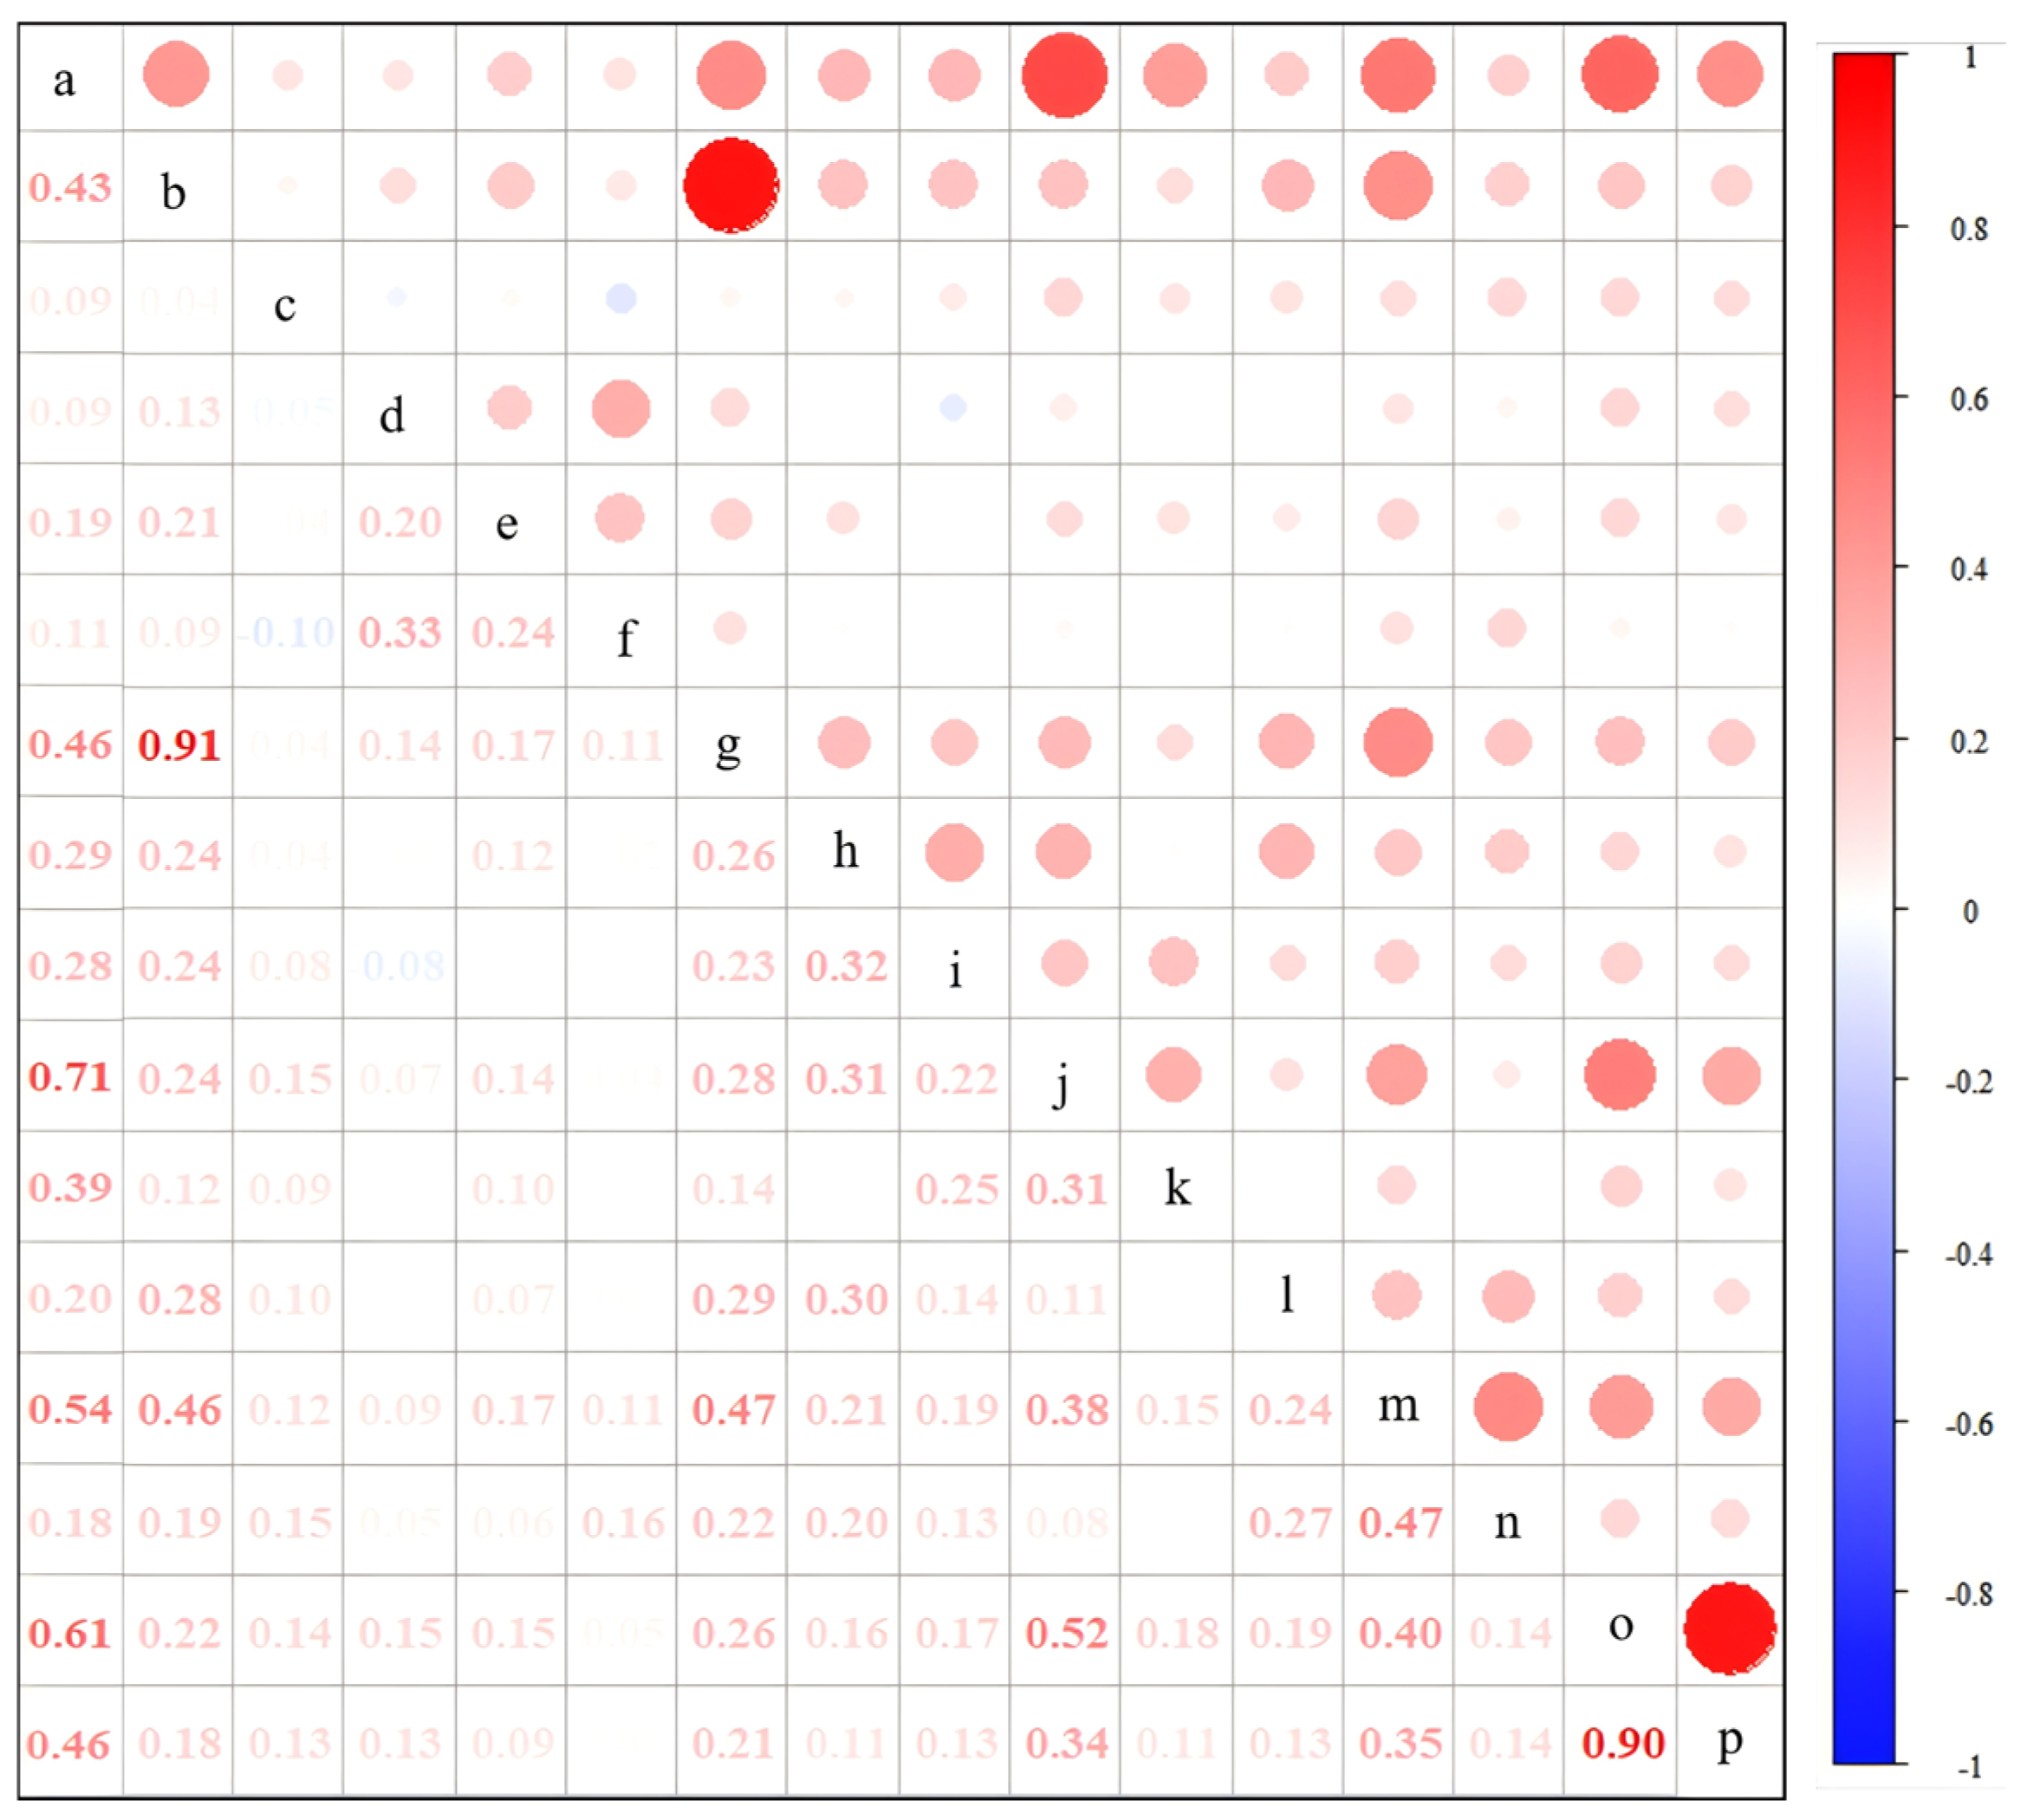
Multicollinearity among conditioning factors can affect model stability and reduce the reliability of landslide susceptibility assessment results [38]. Therefore, Pearson correlation analysis and mutual information (MI) screening were used to reduce redundancy among the candidate factors. In this study, Pearson correlation analysis was used mainly to identify strong linear collinearity between conditioning factors, rather than to evaluate the overall importance of each factor to landslide occurrence. This distinction is important because landslide occurrence may have nonlinear, threshold-type, or non-monotonic relationships with environmental variables, and these complex associations cannot be fully captured by Pearson correlation alone.
Pearson correlation coefficients were calculated for all candidate factor pairs (Figure 2). In Figure 2, red circles indicate positive correlations, blue circles indicate negative correlations, and the size and color intensity of each circle correspond to the magnitude of the correlation coefficient. Numeric values of R are also shown for clarity. A factor pair with was considered to have strong collinearity [39,40]. The results showed strong correlations between slope and topographic roughness () and between land-use type and ecosystem type (), indicating substantial information overlap between these factor pairs.
Figure 2.
Pearson correlation matrix of candidate landslide conditioning factors.
MI was then used as a complementary criterion to measure the statistical dependence between each conditioning factor and landslide occurrence. Unlike Pearson correlation, MI does not require a strictly linear relationship and can therefore provide additional information for factors that may have nonlinear associations with landslide occurrence. For each strongly correlated factor pair, the factor with a higher MI value was retained. Based on the MI results, slope (MI = 0.43) and land-use type (MI = 0.38) were retained because they showed higher associations with landslide occurrence, whereas topographic roughness, an index representing local terrain surface variability, and ecosystem type were excluded. After this screening, 14 conditioning factors were retained for subsequent discretization, WOE transformation, and ensemble model construction.
To further examine whether the selected Pearson correlation threshold influenced the factor-screening results and model performance, a sensitivity analysis was conducted using three threshold settings: |R| ≥ 0.7, |R| ≥ 0.8, and |R| ≥ 0.9. The |R| ≥ 0.88 threshold was retained as the main screening criterion, while the other thresholds were used only to test the robustness of the results to changes in the linear-collinearity threshold. Under each threshold, strongly correlated factor pairs were identified, redundant factors were removed based on the MI-based comparison, and the WOE-CatBoost model was rebuilt using the same 30 repeated stratified random validation procedure.
As shown in Table 2, the WOE-CatBoost model maintained stable predictive performance under different Pearson correlation threshold settings. When the stricter threshold of |R| ≥ 0.7 was used, three strongly correlated factor pairs were identified, including elevation–lithology, slope–topographic roughness, and land-use type–ecosystem type. After MI-based comparison, lithology, topographic roughness, and ecosystem type were removed, and 13 conditioning factors were retained. The model achieved an AUC of 0.9420 ± 0.0220 and an accuracy of 0.8788 ± 0.0292 under this scenario. Under the |R| ≥ 0.8 and |R| ≥ 0.99 thresholds, 14 conditioning factors were retained, and the corresponding AUC and accuracy were 0.9432 ± 0.0196 and 0.8825 ± 0.0284, respectively. These results suggest that the susceptibility modeling results were not highly sensitive to the selected Pearson correlation threshold.
Table 2.
Sensitivity analysis of Pearson correlation threshold settings for factor screening and WOE-CatBoost performance.
The retained conditioning factors were further used as inputs for tree-based ensemble models, including CatBoost, LightGBM, and RF, which are capable of modeling nonlinear relationships among environmental variables and landslide occurrence.
2.3.3. Discretization and Reclassification of Retained Conditioning Factors
For the 10 retained continuous conditioning factors, including elevation, slope, curvature, mean annual precipitation, and distance to faults, the ChiMerge algorithm was used for discretization [19]. This supervised method divides continuous variables into statistically meaningful intervals according to the differences between landslide and non-landslide sample distributions. Based on the discretization results, the continuous factors were reclassified into several interval categories. The retained discrete factors, including lithology, landform type, vegetation cover type, and land-use type, were preserved according to their original thematic classes.
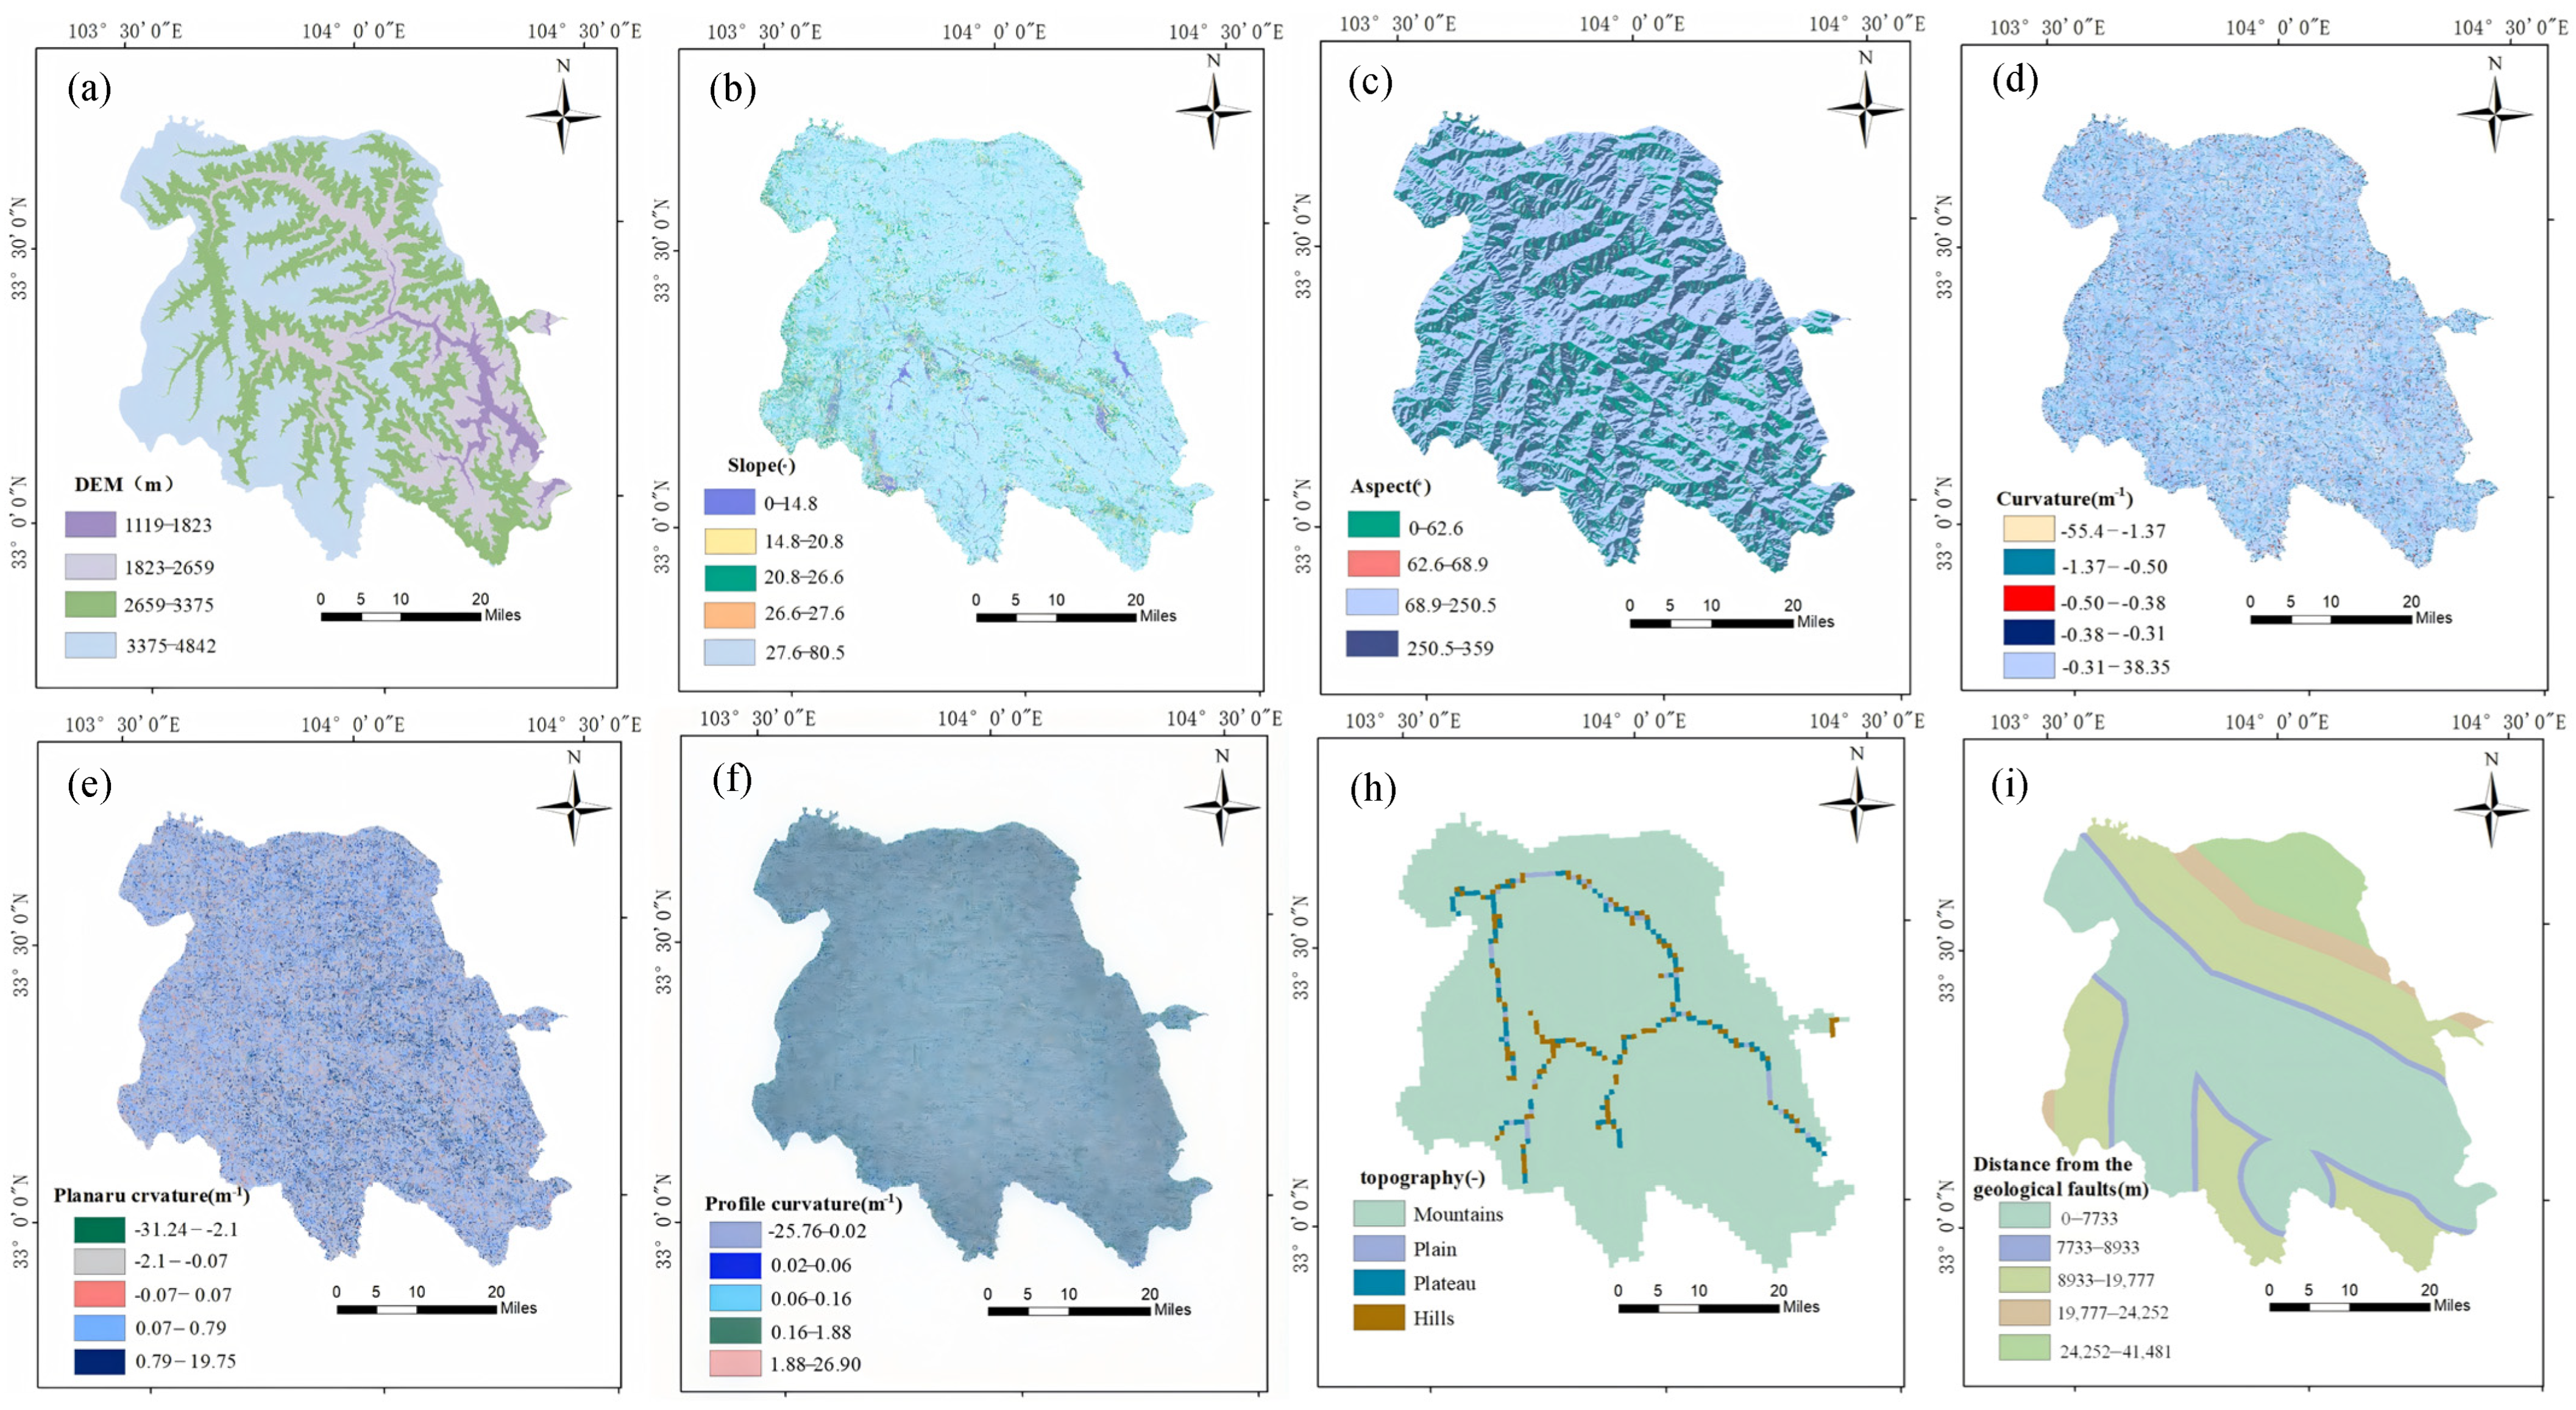
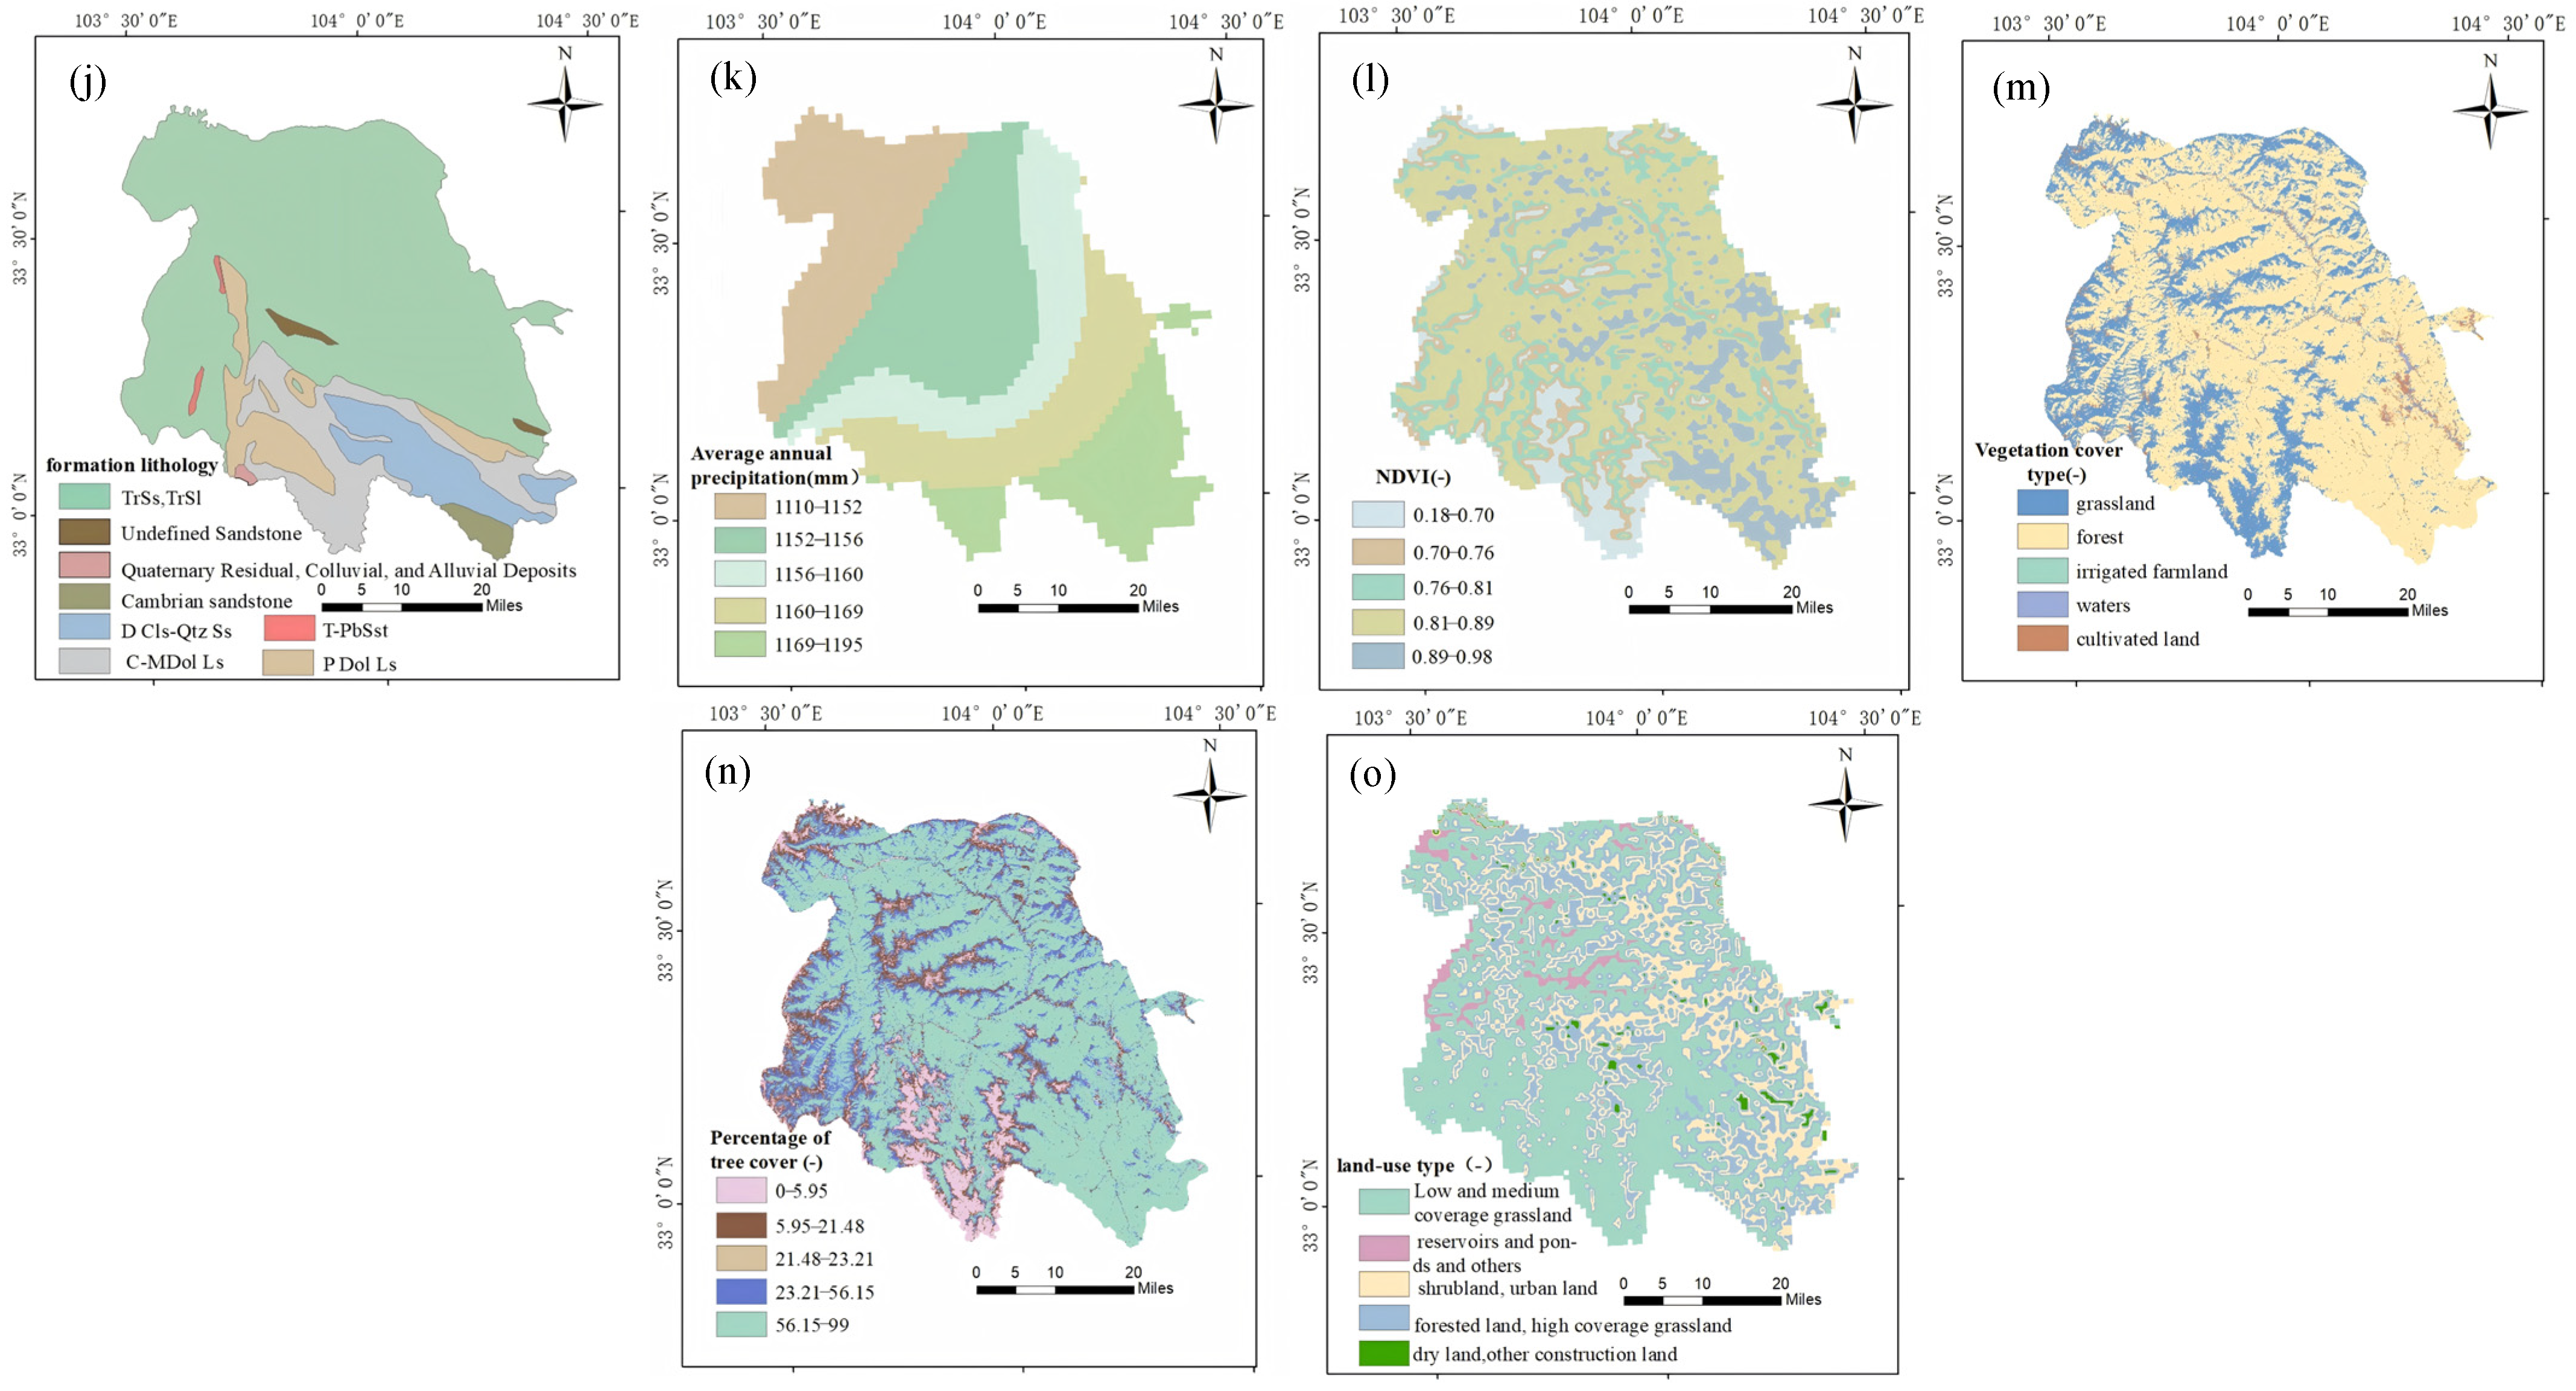
Figure 3 shows the spatial distribution and reclassified categories of the retained conditioning factors. Numerical codes were assigned to each category for raster reclassification and spatial modeling purposes. These codes were used only for reclassification and data management; the final model inputs were generated through WOE transformation. Detailed discretization intervals and WOE values for all retained factors are presented later in the Results section.
Figure 3.
Spatial distribution of the 14 retained landslide conditioning factors: (a) DEM; (b) slope; (c) aspect; (d) curvature; (e) plane curvature; (f) profile curvature; (h) landform type; (i) distance to faults; (j) lithology; (k) mean annual precipitation; (l) NDVI; (m) vegetation cover type; (n) tree cover percentage; and (o) land-use type.
3. Methods
3.1. Landslide Susceptibility Model Construction
Based on the preprocessed landslide inventory and retained conditioning factor layers, a ChiMerge–WOE ensemble learning framework was constructed for landslide susceptibility assessment. The landslide inventory used in this study was point-based, and each recorded landslide was represented by one verified point sample [41]. The landslide points were overlaid with the 30 m × 30 m grid cells, and grid cells containing landslide points were extracted as positive samples (PS).
Negative samples (NS) were selected using a spatially constrained random sampling strategy. A 500 m buffer was first generated around all positive landslide points, and candidate non-landslide grid cells within this buffer were excluded. Negative samples were then randomly drawn from the remaining non-landslide grid cells, with each sample required to be at least 500 m from any positive landslide point and at least 500 m from another negative sample. This distance constraint was used to limit the selection of samples from areas with similar local instability conditions and to reduce spatial clustering. The number of negative samples was kept the same as that of positive samples, resulting in a PS:NS ratio of 1:1 [37]. Positive and negative samples were combined to construct the modeling dataset, with labels of 1 and 0, respectively. The 500 m buffer also helped reduce potential spatial dependence between positive and negative samples while retaining enough candidate non-landslide grid cells for balanced model training. After sample construction and factor screening, the retained continuous factors were discretized using the ChiMerge algorithm, while the retained discrete factors were kept according to their original thematic classes. WOE values were then calculated for each factor class to quantify its statistical association with landslide occurrence. Based on the calculated WOE values, the original conditioning factor raster layers were reclassified into WOE-transformed raster layers.
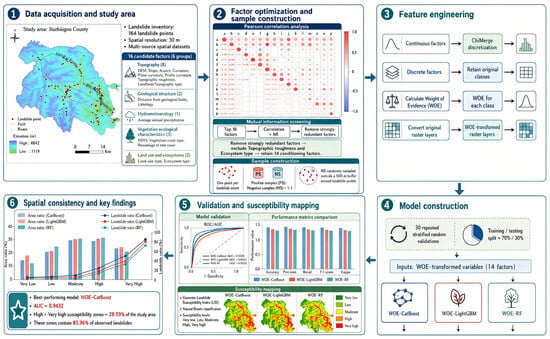
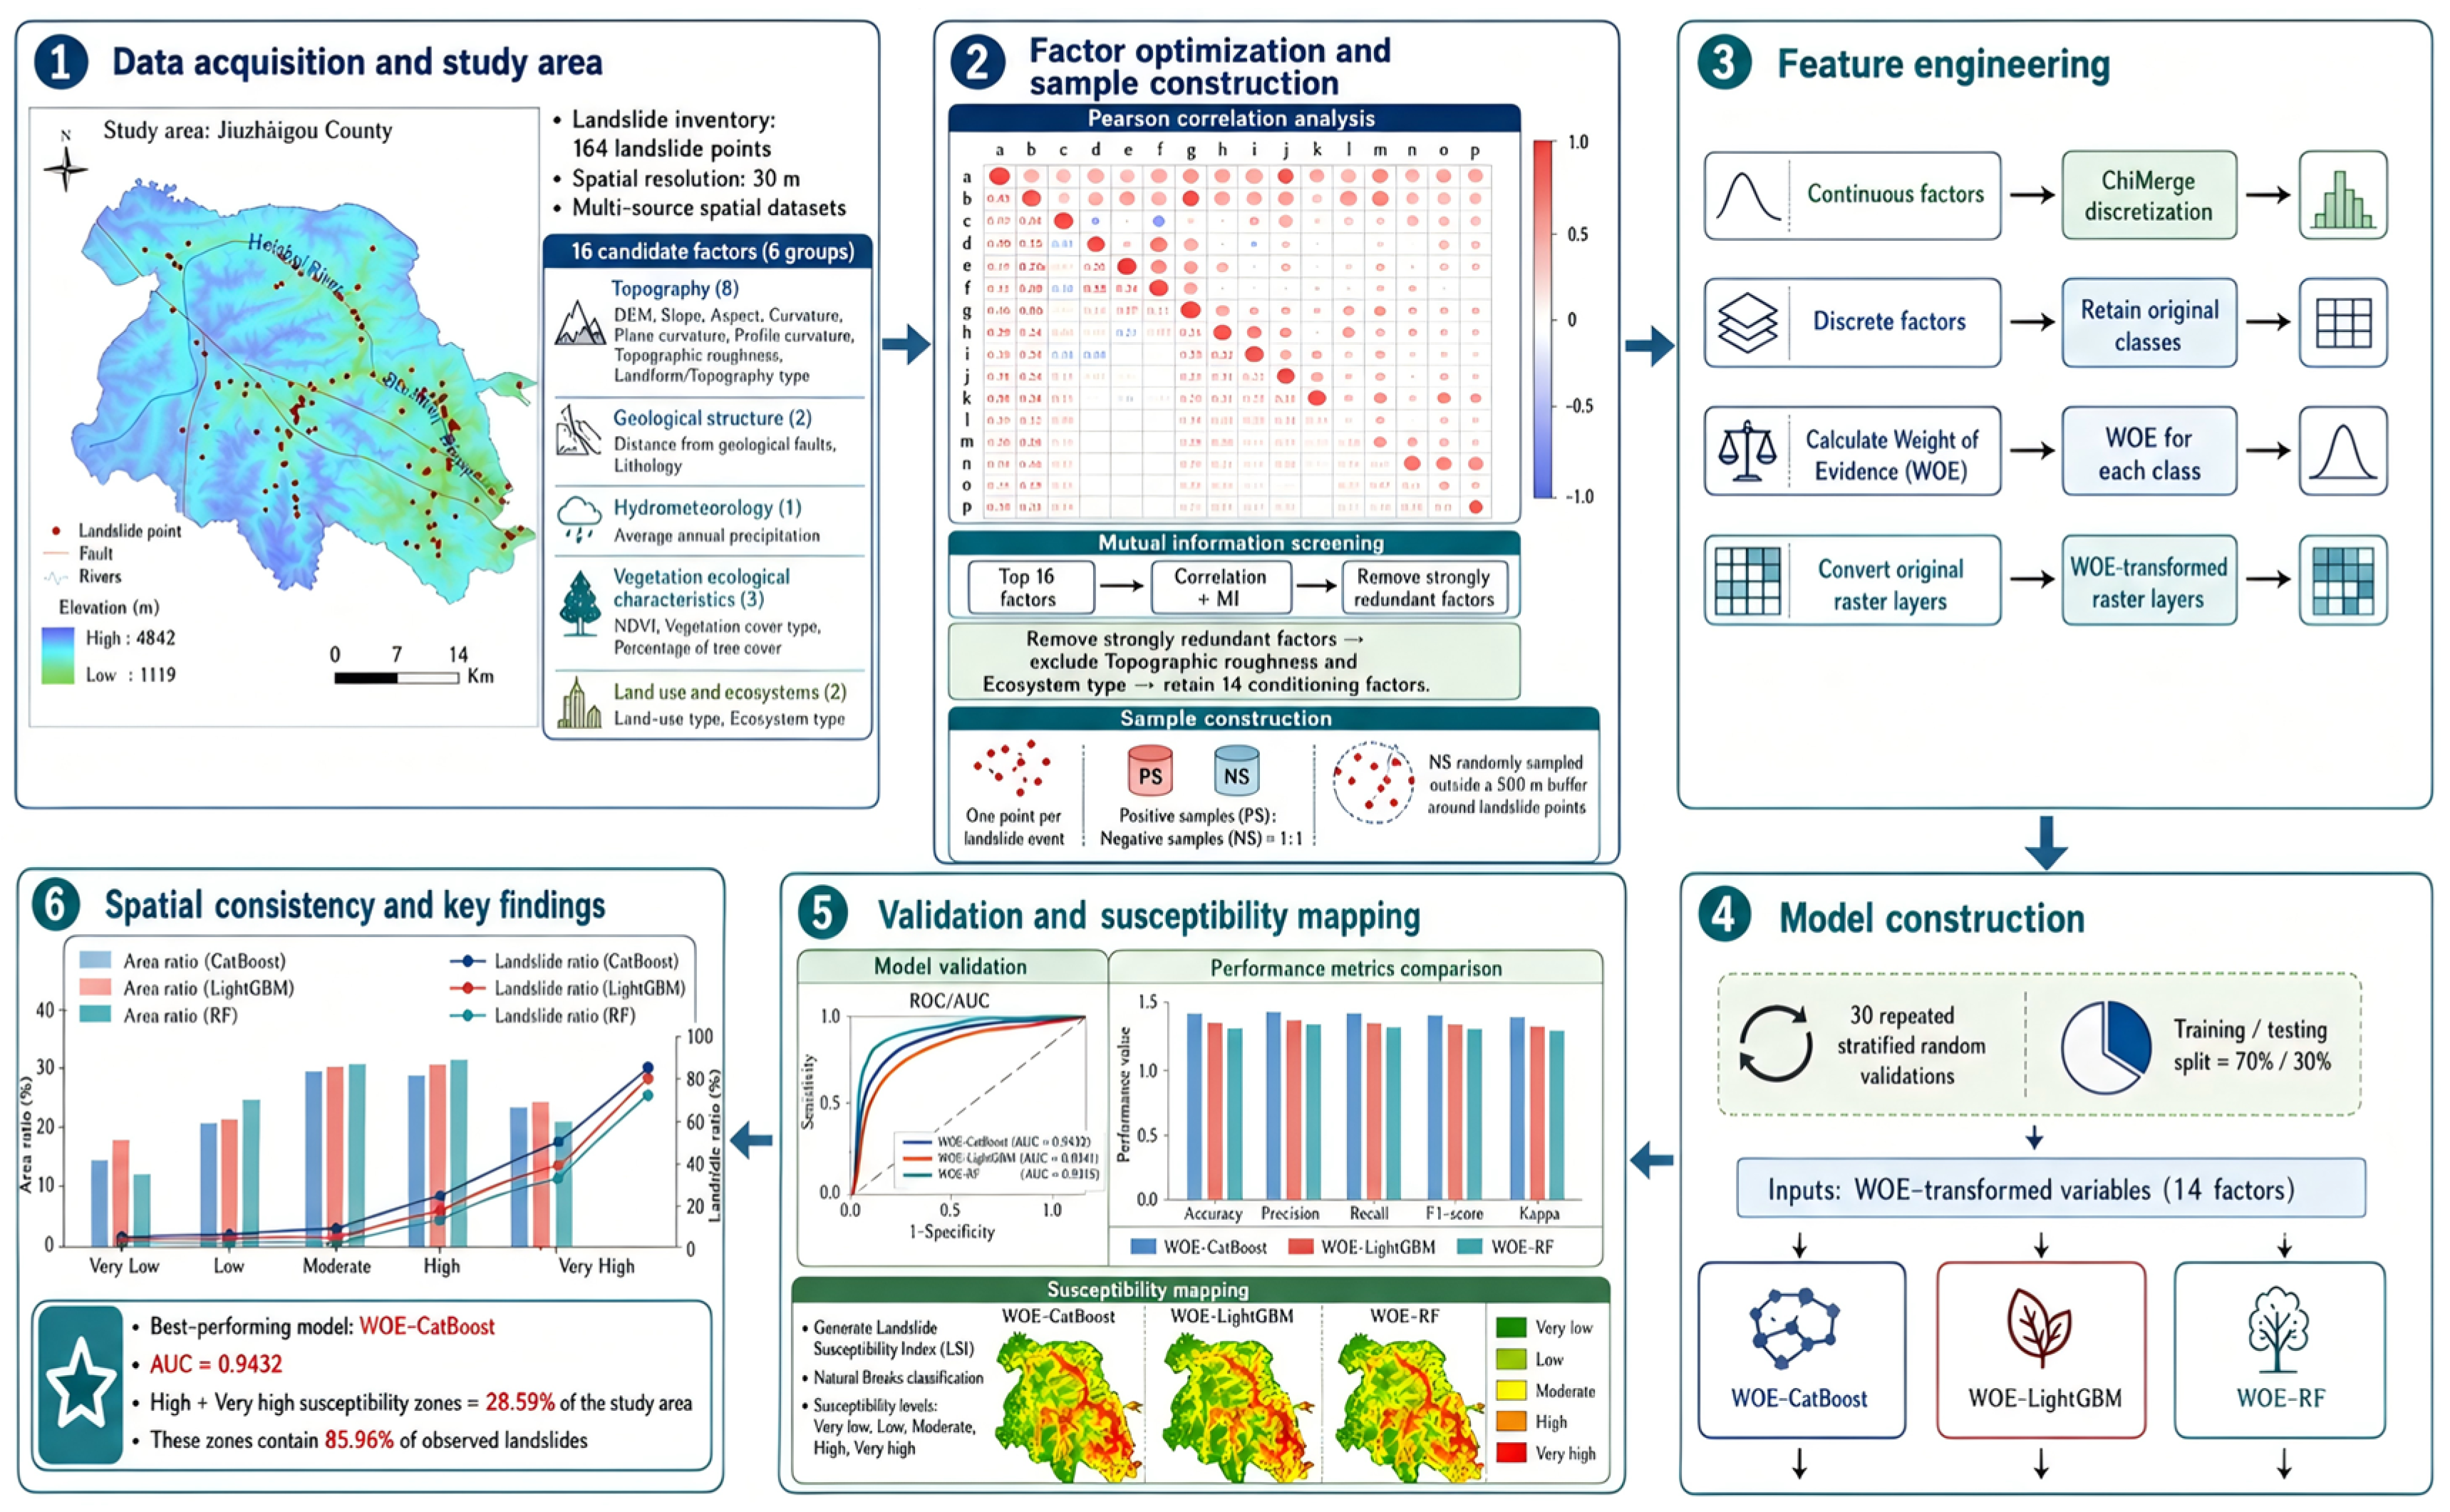
The WOE-transformed variables derived from the retained 14 conditioning factors were used as input features for three ensemble learning models: WOE-CatBoost, WOE-LightGBM, and WOE-RF. Model training and validation were performed using 30 repeated stratified random splits. In each repetition, 70% of the samples were used for training and 30% for testing. The trained models were then applied to the WOE-transformed raster layers to calculate the landslide susceptibility index (LSI) for each 30 m grid cell. The landslide susceptibility maps generated in this study should be interpreted as static regional susceptibility patterns rather than time-varying landslide occurrence probabilities or short-term hazard predictions. The overall workflow is shown in Figure 4.
Figure 4.
Workflow of the proposed ChiMerge–WOE ensemble learning framework for landslide susceptibility assessment.
3.2. Feature Transformation and Ensemble Learning Algorithms
3.2.1. ChiMerge Discretization
ChiMerge is a supervised discretization method based on Pearson’s chi-square test [19]. It iteratively merges adjacent intervals of continuous factors according to the similarity of landslide and non-landslide sample distributions:
where and are the observed and expected counts in interval and class , respectively; is the total number of samples in interval ; is the total number of samples in class ; is the total sample size; is the number of intervals being compared; and is the number of classes. In this study, , corresponding to landslide and non-landslide samples.
Each retained continuous factor was first divided into 20 initial intervals. Adjacent intervals with similar landslide/non-landslide distributions were iteratively merged using a significance level of α = 0.05. The final number of bins was controlled at four to five for each continuous factor to balance statistical discrimination and interpretability. The resulting bins were then used for subsequent WOE encoding.
3.2.2. Weight of Evidence Encoding
The WOE method is a Bayesian statistical approach used to quantify the association between conditioning factor classes and landslide occurrence [11]. In this study, WOE was used to transform each discretized or thematic factor class into a numerical weight before model training. The positive and negative WOE values for factor class i were calculated as follows:
where is the number of landslide grid cells within factor class ; is the number of landslide grid cells outside factor class ; is the number of non-landslide grid cells within factor class ; and is the number of non-landslide grid cells outside factor class . and represent the positive and negative weights of factor class , respectively. The contrast value was used as the final WOE value for each factor class. A positive indicates that the factor class is positively associated with landslide occurrence, whereas a negative value indicates a negative association. A value close to zero suggests a weak or negligible association. The original factor layers were then reclassified using the corresponding values to generate WOE-transformed raster layers.
3.2.3. CatBoost
CatBoost is an ensemble learning algorithm based on gradient boosting decision trees and is designed to improve prediction stability through ordered boosting and symmetric tree structures [42]. In this study, CatBoost was applied to the WOE-transformed variables to model nonlinear relationships between conditioning factors and landslide occurrence. CatBoost uses symmetric tree structures, in which nodes at the same level share the same splitting rule, thereby improving computational efficiency and model stability. Its ordered boosting strategy helps reduce prediction bias caused by target leakage during iterative training. The model prediction is updated iteratively as follows:
where is the prediction function at iteration , is the prediction function from the previous iteration, is the learning rate, and is the symmetric regression tree fitted at iteration .
3.2.4. LightGBM
LightGBM is an efficient gradient boosting decision tree framework that uses histogram-based learning and leaf-wise tree growth to improve computational efficiency and predictive performance [43]. In this study, LightGBM was applied to the WOE-transformed variables to model nonlinear relationships between conditioning factors and landslide occurrence. Its core idea is to build decision trees sequentially, with each new tree fitted to the residual information of the current model, and to improve prediction through additive boosting. The objective function can be expressed as:
where is the loss function measuring the difference between the observed label and the predicted value , and is the regularization term used to control model complexity and reduce overfitting. The model is updated iteratively as follows:
where is the prediction function at iteration , is the decision tree fitted at iteration , and is the learning rate.
3.2.5. Random Forest
Random Forest (RF) is an ensemble learning method based on multiple decision trees. It constructs decision trees through bootstrap sampling and random feature subset selection, which helps improve model generalization and reduce overfitting [11]. In this study, RF was applied to the WOE-transformed variables as a comparative ensemble model for landslide susceptibility assessment. Each tree was trained on a bootstrap sample drawn from the original dataset, and a random subset of features was selected at each split node. The final classification result was determined by majority voting across all decision trees. This structure makes RF relatively robust to noise and suitable for modeling nonlinear relationships between landslide occurrence and conditioning factors.
3.3. Model Validation and Performance Evaluation
Model performance was evaluated using a repeated stratified random holdout validation strategy. In each repetition, the sample dataset was randomly divided into training and testing subsets at a ratio of 7:3 using stratified sampling, which maintained the same proportion of landslide and non-landslide samples in both subsets. ChiMerge discretization thresholds and WOE values were derived from the training subset and then applied to the corresponding testing subset. To reduce the uncertainty associated with a single random split, the validation procedure was repeated 30 times using different random seeds.
In each repetition, WOE-CatBoost, WOE-LightGBM, and WOE-RF were trained and tested using the same training and testing subsets, ensuring a fair comparison among the three models. The WOE-transformed conditioning factors were used as input variables, and the landslide/non-landslide label was used as the response variable.
Model performance was assessed using the area under the receiver operating characteristic curve (AUC), accuracy, precision, recall, F1-score, and Kappa coefficient. These metrics were used to evaluate discrimination ability, overall classification accuracy, landslide identification capability, and classification agreement beyond chance. The final results were summarized as the mean ± standard deviation of each metric over the 30 repetitions. After repeated validation, the final susceptibility maps were generated using models refitted on the full modeling dataset with the fixed hyperparameter settings.
3.4. Model Parameter Configuration
Hyperparameter settings influence the predictive performance and generalization ability of machine learning models [44]. The main hyperparameters used for WOE-CatBoost, WOE-LightGBM, and WOE-RF are summarized in Table 3. The hyperparameters were determined through preliminary tuning and were then fixed during the repeated validation process.
Table 3.
Hyperparameter settings of the three WOE-based ensemble models.
To ensure comparability across repeated validations, the hyperparameter configuration of each model was kept constant. Only the random seed was changed in each repetition to generate different training and testing partitions, allowing the influence of data partitioning randomness to be assessed under consistent model settings.
4. Results
4.1. ChiMerge Discretization and WOE Results
ChiMerge was used to divide continuous conditioning factors into statistically meaningful intervals, and WOE values were calculated for each factor class. Table 4 presents the final discretization results and corresponding WOE values. The original factor raster layers were then reclassified into WOE-transformed raster layers and used as model inputs.
Table 4.
ChiMerge discretization intervals and WOE values of landslide conditioning factors.
Topographic factors are closely related to the initiation and spatial distribution of landslides [16]. In the WOE analysis, Wfi represents the final Weight of Evidence value for each factor class, with positive values indicating a stronger statistical association with mapped landslide occurrence and negative values indicating a weaker association. In this study, the slope interval of 0–14.8° had the highest positive Wfi value. This result does not mean that gentle slopes are mechanically more susceptible to landslides. Rather, it is likely related to the way the point-based landslide inventory and 30 m DEM data represent landslide locations. Many mapped landslide points are located near valley bottoms, terrace margins, road corridors, or depositional zones, where the slope values extracted from DEM grids are relatively moderate. In addition, point-based inventories may record the central or depositional parts of landslides instead of the steepest source areas. Therefore, the high Wfi value in the 0–14.8° interval should be interpreted as a statistical outcome affected by inventory position, DEM resolution, and local terrain conditions, rather than as evidence that lower slopes are more prone to failure. Steeper slopes remain important for landslide initiation, but their Wfi values depend on how many mapped landslide points fall within each slope class. For aspect, the interval of 62.6–68.9° showed the highest Wfi value, which may be related to differences in rock layer orientation, joints, and fractures [38]. Slope aspect can also affect solar radiation, soil moisture, vegetation growth, freeze–thaw processes, and exposure to rainfall or moisture-bearing airflow, all of which may influence weathering intensity and slope stability. The possible effect of prevailing winds and moisture airflow is therefore considered as a potential contributing mechanism, although further data on wind direction and slope-scale moisture conditions would be needed for verification. Curvature also showed spatial variation in WOE values. The plane curvature interval of −0.07 to 0.07 and the profile curvature interval of 0.02–0.06 were more closely associated with landslide occurrence [45]. Elevations between 1119 m and 2659 m had positive WOE values, whereas higher elevation intervals showed negative values. In addition, hills and plateaus showed relatively stronger associations with landslide occurrence among the landform types [46,47].
Precipitation is an important external factor related to landslide development [48]. In this study, the annual precipitation interval of 1160–1169 mm showed the highest Wfi value, suggesting that mapped landslides were relatively more concentrated within this rainfall range. Rainfall can reduce slope stability by increasing pore water pressure, weakening soil shear strength, and enhancing surface erosion [39,49]. However, the precipitation–landslide relationship was not strictly monotonic. Areas with the highest annual precipitation did not necessarily contain the highest concentration of landslide points. This suggests that landslide occurrence was affected not only by rainfall, but also by terrain, lithology, vegetation, drainage conditions, and engineering disturbance. Therefore, the 1160–1169 mm interval should be understood as a rainfall range that overlaps with other landslide-favorable conditions, rather than as evidence that higher annual precipitation always leads to higher susceptibility.
Geological factors also showed clear differences in WOE values. For distance to faults, the Wfi values varied among discrete distance intervals rather than showing a strictly linear trend. The intervals of 0–7733 m and 7733–8933 m had positive Wfi values, indicating that mapped landslide points were relatively concentrated near fault zones. This may be related to fractured rock masses, weakened structural planes, enhanced permeability, and stronger weathering around faults, which can reduce slope stability [50]. However, the Wfi values did not decrease monotonically with increasing distance; for example, the 8933–19,777 m interval had a negative Wfi value, whereas the 19,777–24,252 m interval had a positive value. These fluctuations indicate that fault distance alone cannot fully explain landslide distribution and should be considered together with lithology, slope conditions, drainage, precipitation, and engineering disturbance. Lithology controls the engineering properties of rock and soil, including strength, permeability, and weathering resistance [51]. Among the lithological units, Quaternary residual, colluvial, and alluvial deposits showed the strongest positive association with landslide occurrence. This is generally consistent with the relatively weak mechanical properties of loose deposits compared with more stable hard rock units [16].
Vegetation and land-use factors reflected the influence of surface cover conditions. NDVI intervals of 0.70–0.76 and 0.76–0.81 showed stronger associations with landslide occurrence [52,53]. For canopy cover, the interval of 5.95–21.48% had the highest Wfi value, indicating that landslide occurrence was more concentrated within this range [54]. In terms of vegetation cover and land-use type, cultivated land, irrigated farmland, shrubland or urban land, and dry land or other construction land showed positive WOE values. These results suggest that both vegetation conditions and human land-use disturbance should be considered when interpreting landslide susceptibility and formulating sustainable land-use planning strategies.
4.2. Model Performance Under Repeated Validation
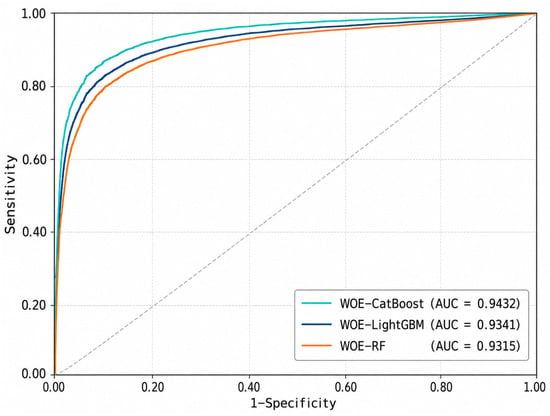
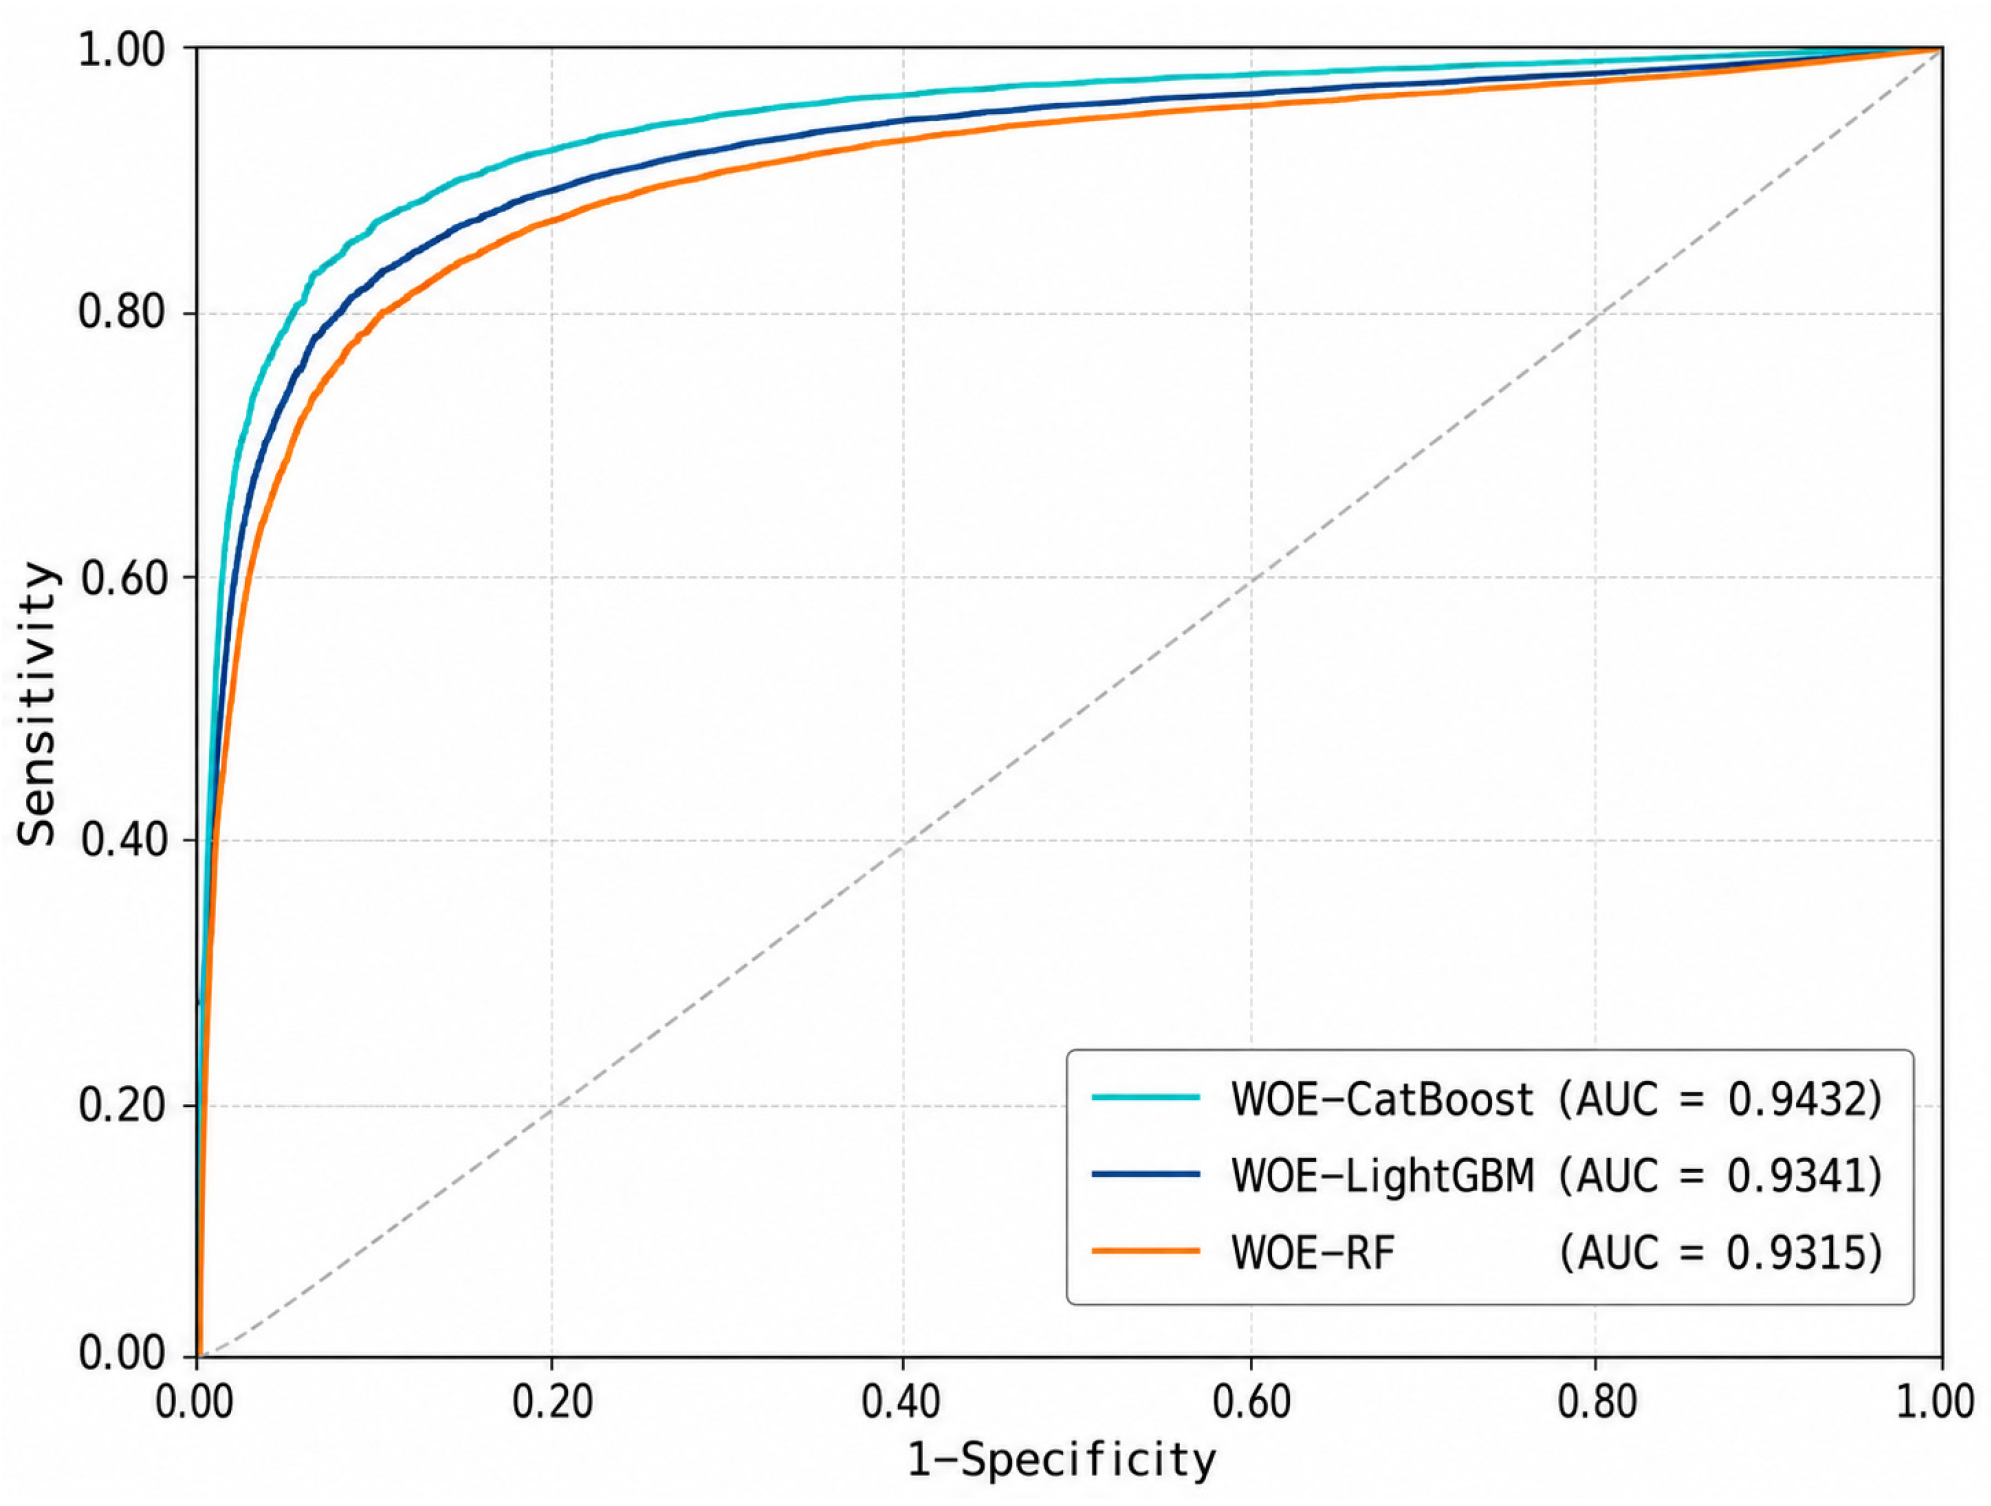
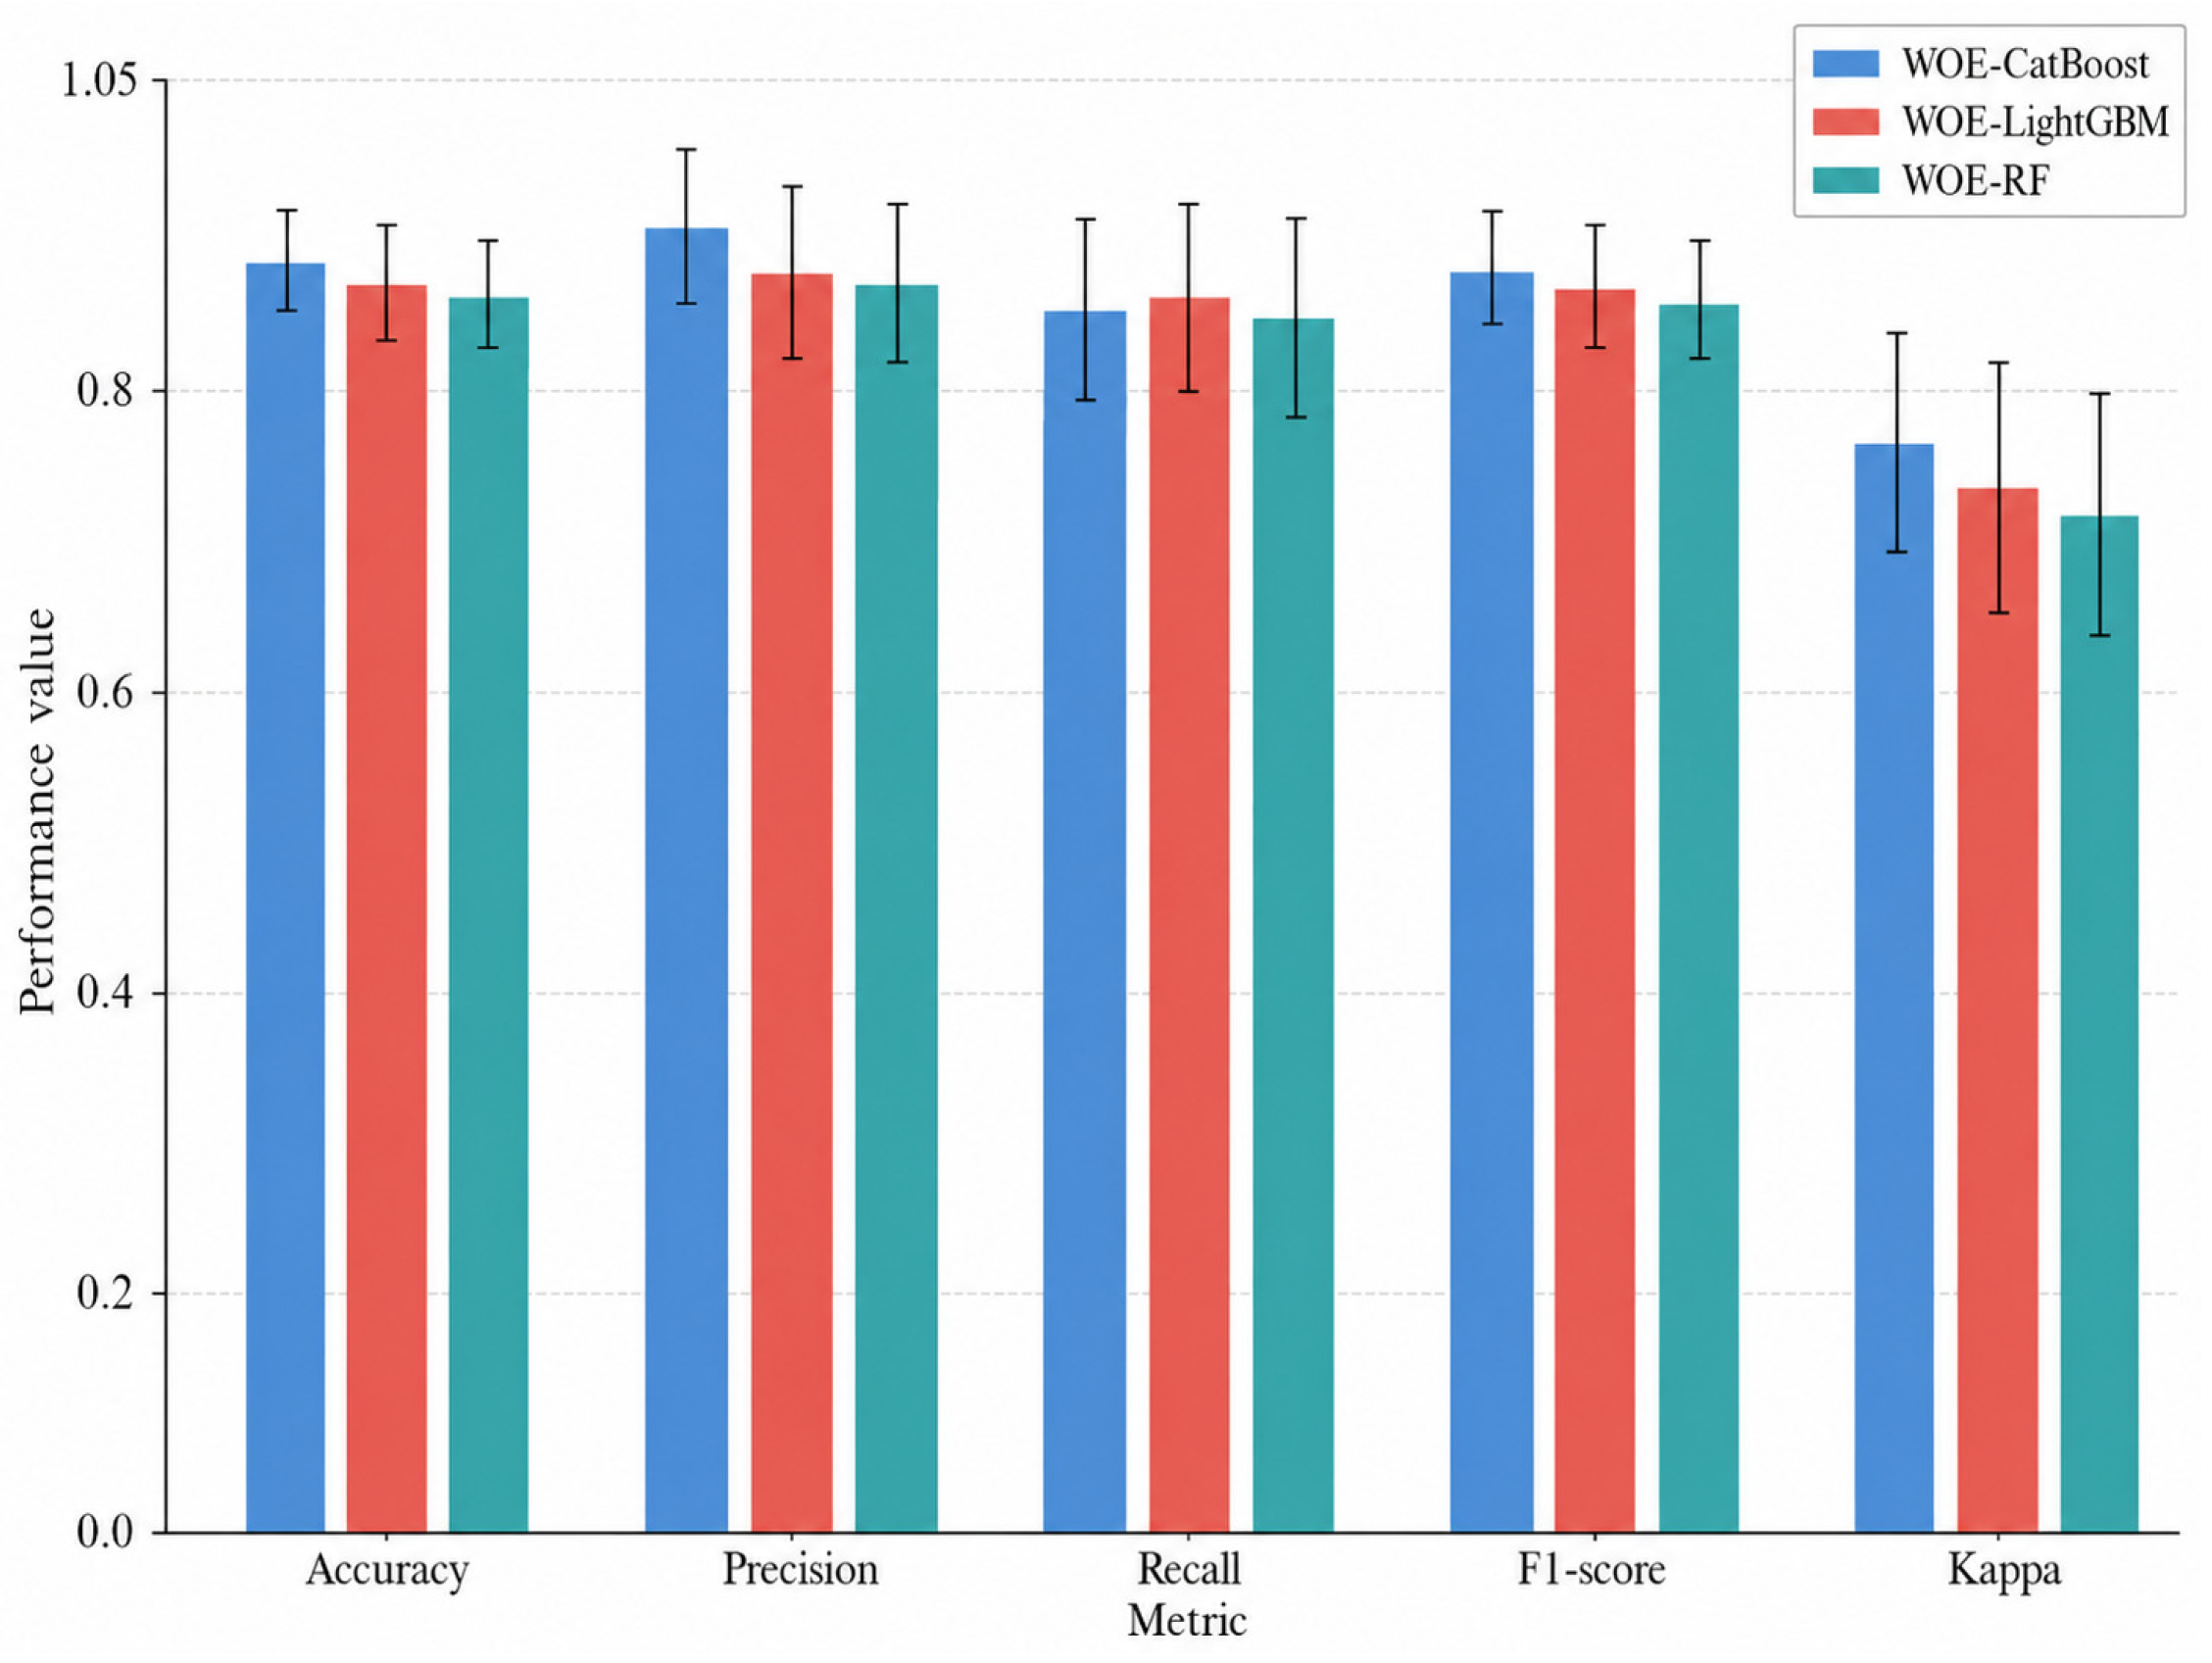
The predictive performance of the three WOE-based landslide susceptibility models was evaluated using 30 repeated stratified random validation runs. For each model, the ROC curves obtained from the 30 repetitions were averaged to generate the mean ROC curves shown in Figure 5. The corresponding performance metrics are presented in Figure 6.
Figure 5.
ROC curves of the three WOE-based models.
Figure 6.
Performance comparison of the three WOE-based models.
The ROC curve was used to evaluate the discrimination ability of each model by plotting sensitivity against 1-specificity [55]. As shown in Figure 5, all three models achieved mean AUC values greater than 0.90, indicating good discrimination between landslide and non-landslide samples. Among the three models, WOE-CatBoost achieved the highest mean AUC value of 0.9432 ± 0.0233, followed by WOE-LightGBM with 0.9341 ± 0.0213 and WOE-RF with 0.9315 ± 0.0213.
The comparison of classification metrics further confirmed the stable performance of the three models. As shown in Figure 6, WOE-CatBoost achieved the highest accuracy, precision, F1-score, and Kappa coefficient, with values of 0.8825 ± 0.0284, 0.9087 ± 0.0439, 0.8790 ± 0.0299, and 0.7649 ± 0.0568, respectively. WOE-LightGBM obtained the highest recall value of 0.8596 ± 0.0522, suggesting a slightly stronger ability to identify landslide samples. Considering the overall performance across all evaluation metrics, WOE-CatBoost showed the best overall predictive performance among the three models.
4.3. Spatial Distribution of Landslide Susceptibility
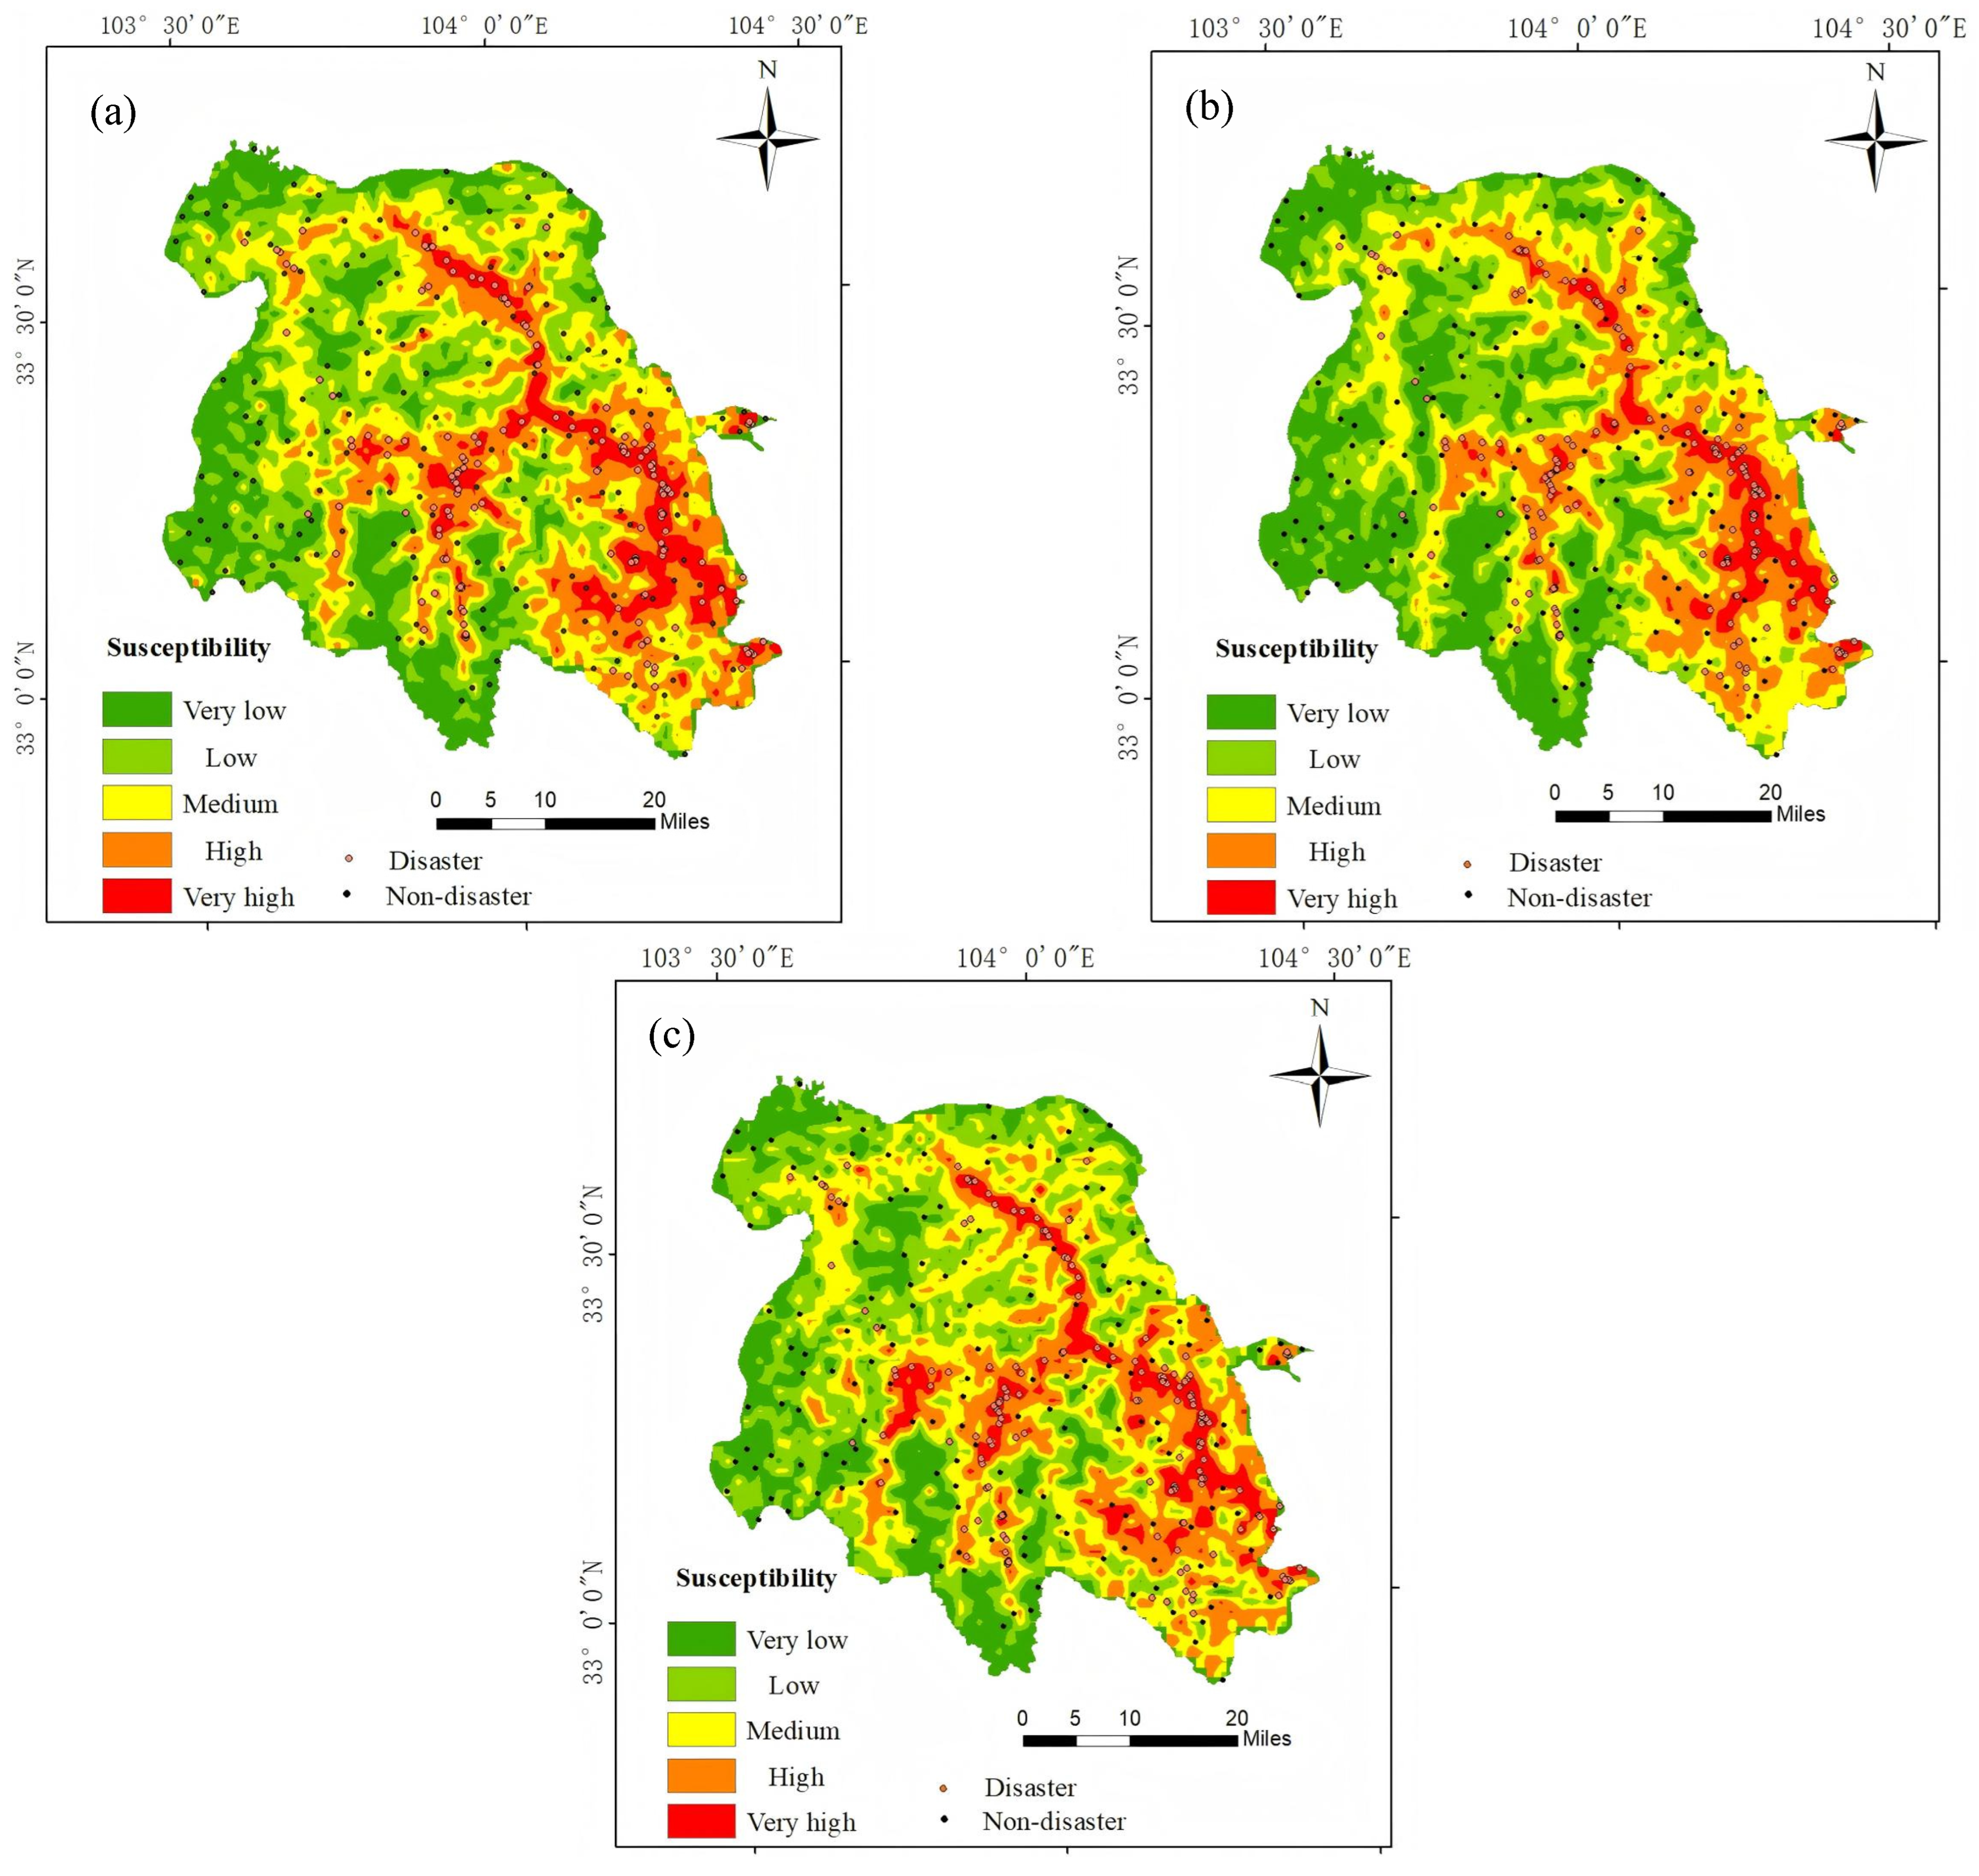
The trained WOE-CatBoost, WOE-LightGBM, and WOE-RF models were applied to the WOE-transformed raster layers to calculate the LSI for each 30 m grid cell. The LSI values were classified into five susceptibility levels using the Natural Breaks method: very low, low, moderate, high, and very high. The resulting susceptibility maps are shown in Figure 7.
Figure 7.
Landslide susceptibility maps predicted by the three WOE-based models: (a) WOE-CatBoost, (b) WOE-LightGBM, and (c) WOE-RF.
As shown in Figure 7, the three models produced generally similar spatial patterns. High and very high susceptibility areas were mainly distributed along steep valley systems, deeply incised drainage corridors, erosion-prone slopes, and areas affected by intensive engineering activities. These locations are often associated with steep terrain, well-developed drainage networks, fragmented landforms, and strong human disturbance. By contrast, low and very low susceptibility areas were mostly found in gentler terrain, where structural disturbance and human activity were relatively limited. Moderate susceptibility areas were mainly located around the margins of high-susceptibility zones, whereas low and very low susceptibility areas were concentrated in the relatively flat northern and western parts of the study area. Most observed landslide points were located within the high and very high susceptibility zones, indicating that the three models captured the main spatial pattern of landslide occurrence. Among them, WOE-CatBoost showed a clearer concentration of high-susceptibility areas, which was consistent with its better validation performance.
4.4. Spatial Consistency Between Susceptibility Zoning and Landslide Occurrence
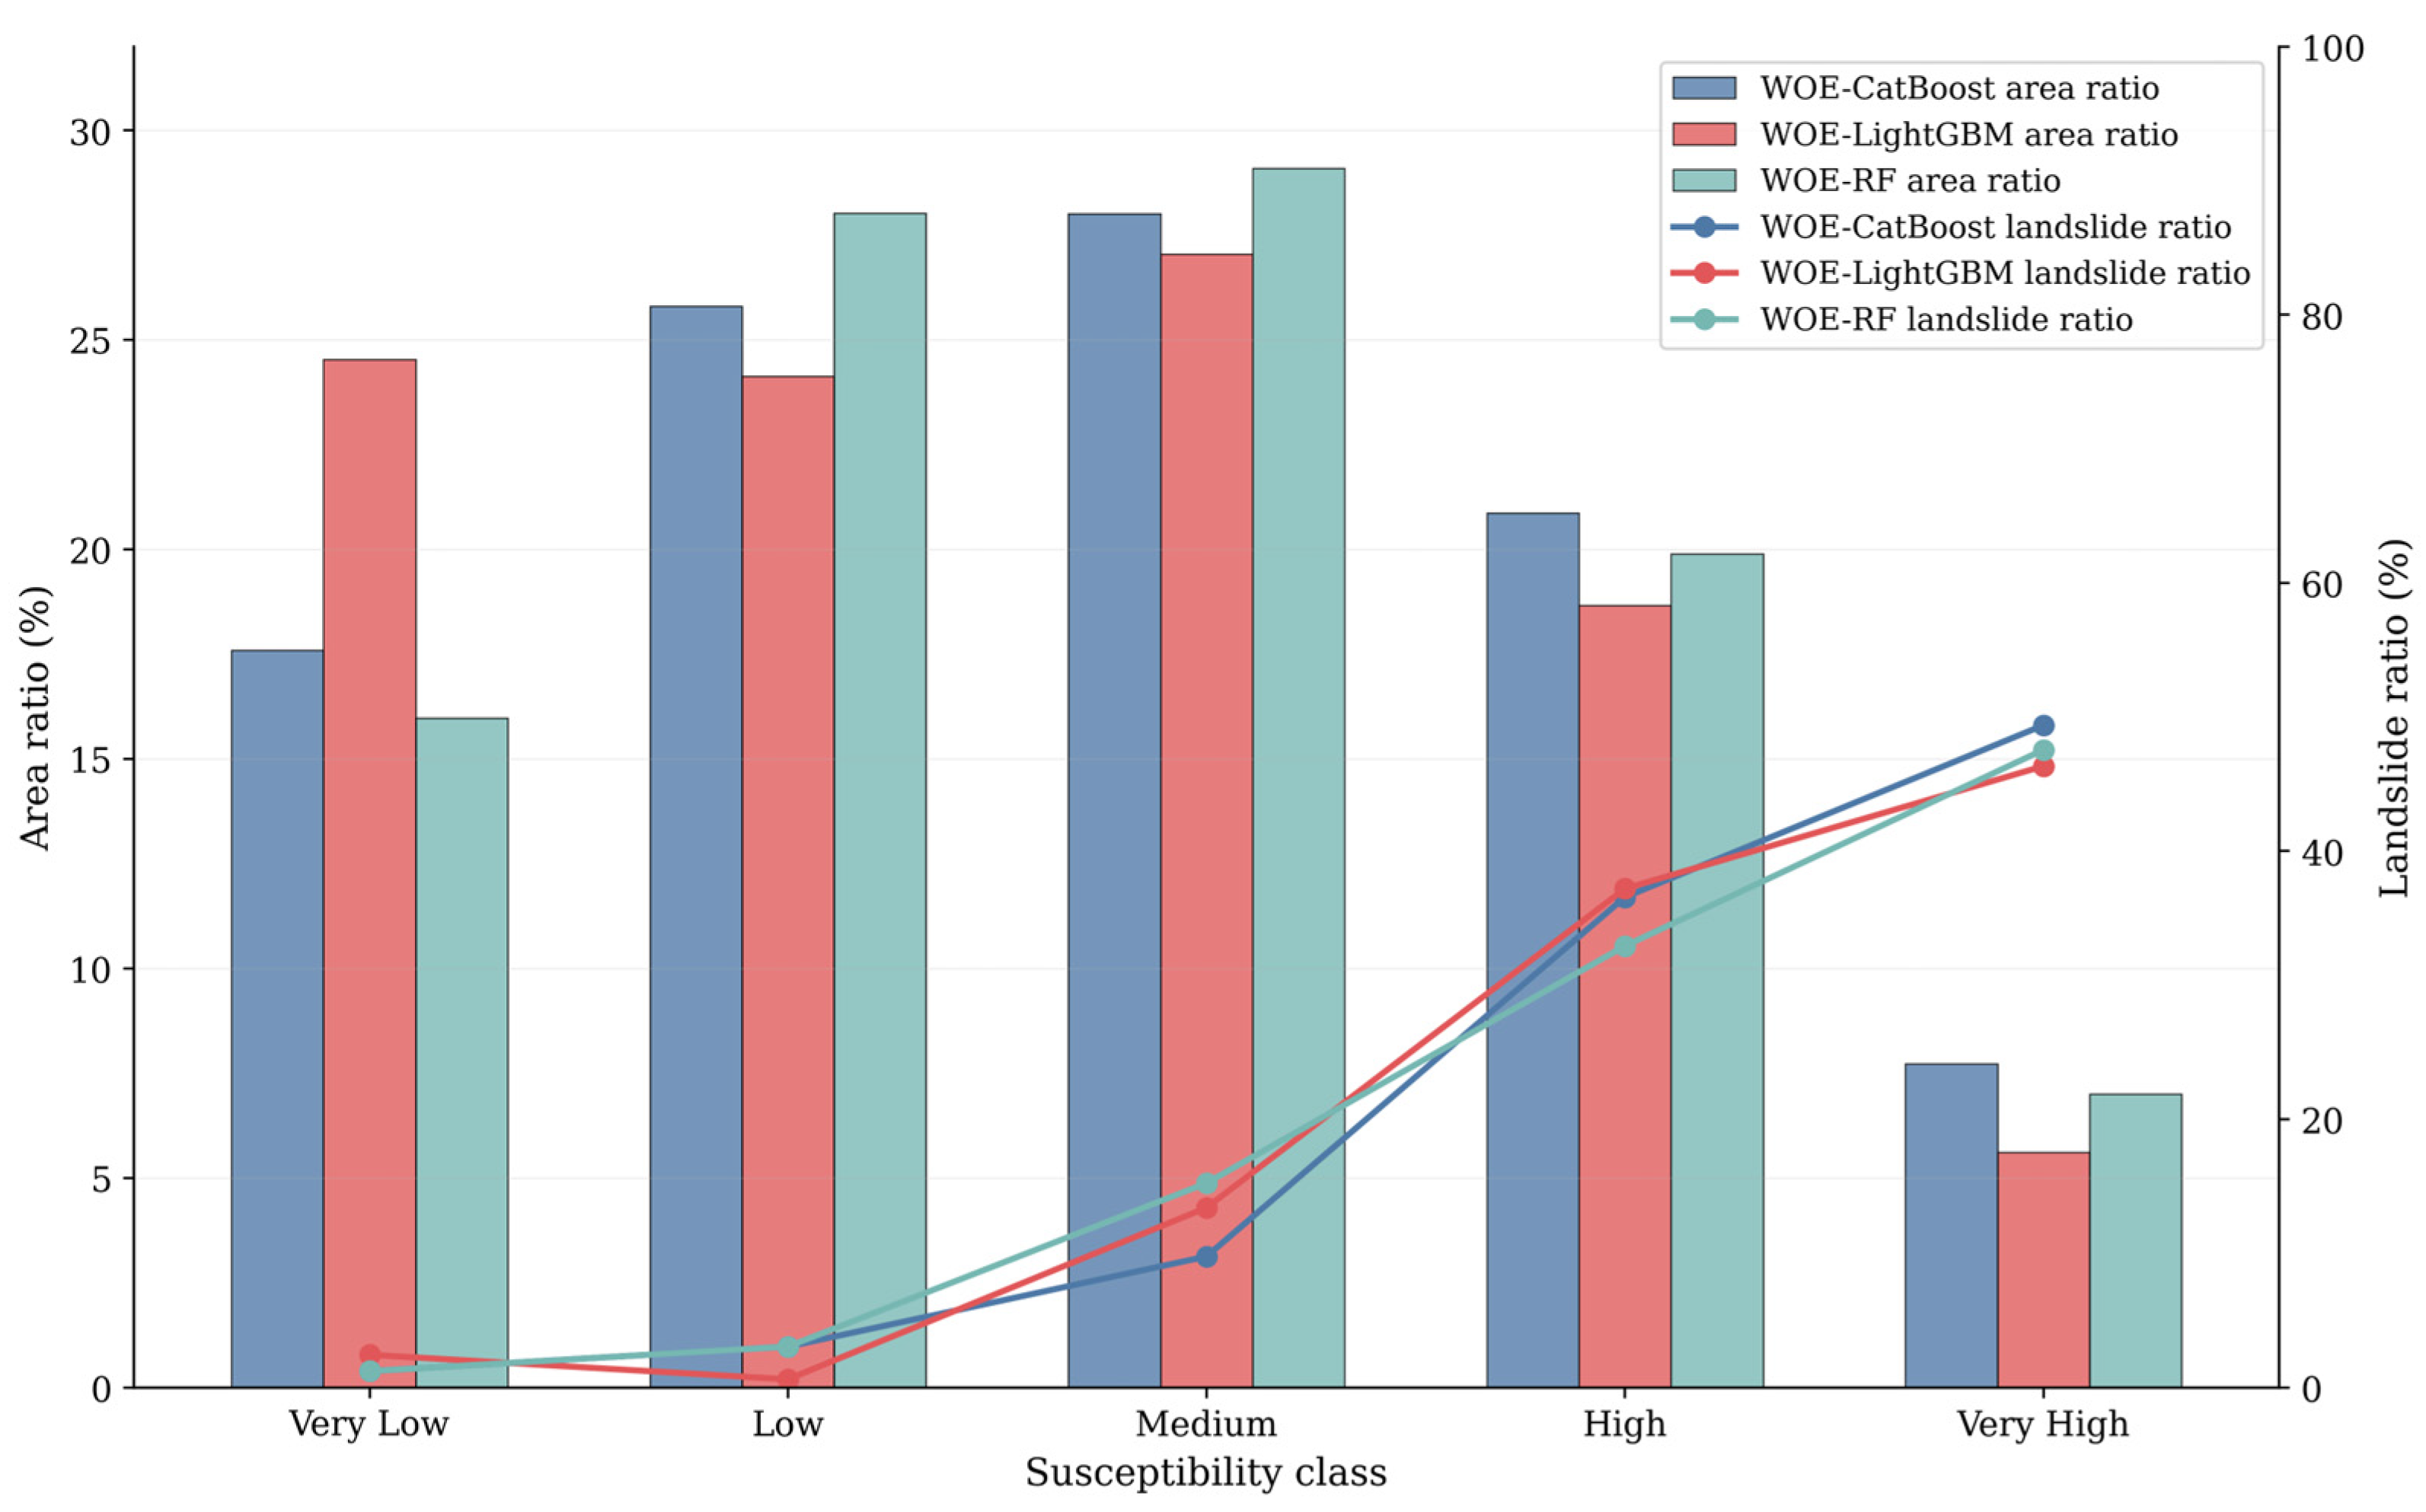
The spatial consistency of the susceptibility maps was evaluated by comparing the area ratio and observed landslide ratio within each susceptibility class. The detailed results are presented in Table 5 and Figure 8.
Table 5.
Area and landslide ratios in different susceptibility classes.
Figure 8.
Area ratios and observed landslide ratios across susceptibility classes for the three WOE-based models.
For WOE-CatBoost, the high and very high susceptibility zones accounted for 28.59% of the study area and contained 85.96% of the observed landslides. In contrast, the very low and low susceptibility zones covered 43.40% of the total area but included only 4.27% of the landslide inventory. This distribution indicates that landslide occurrences were highly concentrated in areas classified as high or very high susceptibility.
A similar spatial pattern was observed for WOE-LightGBM and WOE-RF. Their high and very high susceptibility zones contained 83.54% and 80.49% of the observed landslides, respectively. As shown in Figure 8, landslide ratios were substantially higher in the high and very high susceptibility classes than in the lower classes across all three models, confirming that the predicted susceptibility zoning was broadly consistent with the spatial distribution of recorded landslides.
Among the three models, WOE-CatBoost showed the strongest concentration of landslides within the high and very high susceptibility zones. Taken together, these results demonstrate that the WOE-based ensemble models provided reliable spatial discrimination of landslide-prone areas, with WOE-CatBoost exhibiting the highest spatial consistency with the landslide inventory.
5. Discussion
The results demonstrate that integrating ChiMerge discretization, WOE transformation, and ensemble machine learning is an effective strategy for landslide susceptibility assessment in Jiuzhaigou County. Compared with conventional discretization approaches based mainly on empirical rules or data distribution, ChiMerge identifies factor intervals according to differences between landslide and non-landslide samples, thereby reducing the subjectivity of threshold selection. WOE transformation further converts heterogeneous factor classes into comparable numerical weights that reflect their statistical associations with landslide occurrence. This feature-processing procedure provides interpretable inputs for ensemble learning models and helps connect statistical susceptibility analysis with nonlinear machine learning prediction.
The three WOE-based ensemble models all achieved strong predictive performance under repeated validation, indicating that the transformed conditioning factors captured the main spatial characteristics of landslide occurrence. Among them, WOE-CatBoost showed the best overall performance in terms of AUC, accuracy, precision, F1-score, and Kappa coefficient, while WOE-LightGBM obtained a slightly higher recall. This suggests that WOE-CatBoost achieved a more balanced classification performance, whereas WOE-LightGBM was marginally more sensitive to landslide samples. The stronger overall performance of WOE-CatBoost may be related to its ordered boosting strategy and stable iterative learning process, which can reduce prediction bias and improve generalization during model training. However, the differences among the three models were not large, indicating that the ChiMerge–WOE feature transformation itself played an important role in improving the stability of the susceptibility assessment framework.
The spatial distribution of susceptibility also supports the reliability of the proposed framework. High and very high susceptibility zones were mainly concentrated in steep valleys, erosion belts, structurally disturbed areas, and locations affected by intensive engineering activities. These areas are characterized by complex terrain, strong river incision, fragmented landforms, and relatively high levels of human disturbance, which jointly create favorable conditions for slope instability. The spatial consistency analysis further showed that the high and very high susceptibility zones identified by WOE-CatBoost covered only 28.59% of the study area but contained 85.96% of the observed landslides. This pattern indicates that the model not only achieved good statistical performance but also produced susceptibility zoning with practical spatial relevance. For mountainous counties such as Jiuzhaigou, these results can support landslide-prone area identification, settlement risk screening, infrastructure site selection, and sustainable land-use management.
Several limitations should be acknowledged. This study mainly considered static conditioning factors and did not explicitly include dynamic triggers such as short-duration extreme rainfall, earthquake disturbance, or recent land-use changes. Therefore, the susceptibility maps should be interpreted as relative spatial patterns of landslide susceptibility, rather than as short-term triggering probabilities or time-varying hazard maps. Future work could incorporate event-based rainfall records, earthquake-related disturbance information, and InSAR-derived deformation data to better capture seasonal or post-seismic changes in landslide activity.
Uncertainty may also arise from the 30 m spatial resolution of the input datasets and the use of a point-based landslide inventory. Although this resolution is suitable for regional-scale susceptibility assessment, small and medium-sized landslides may occupy only part of a grid cell or extend across several grid cells. As a result, the extracted conditioning-factor values may not fully represent the actual source areas or the internal spatial variability of individual landslides. Since complete landslide polygon boundaries and detailed landslide-size information were not available for all records, this uncertainty could not be quantified in the present study. Future studies based on landslide polygon inventories, landslide-size statistics, higher-resolution spatial datasets, and multi-resolution comparisons would help assess this effect more clearly.
The negative sampling strategy is another source of uncertainty. Although the spatially constrained sampling approach reduced the likelihood of false-negative selection and sample clustering, the negative samples were not further stratified by geomorphic units such as river valleys, steep slopes, or terraces. If negative samples are unevenly distributed across different environmental settings, this may affect model training and evaluation. Future work could compare buffer-based spatially constrained sampling with cluster-based and environmental stratified sampling to examine how different sampling strategies influence model robustness, regional generalization, and AUC.
In addition, the factor-screening and mapping procedures could be further refined in future work. The Pearson-threshold sensitivity analysis showed that model performance remained stable under different linear-correlation threshold settings, suggesting that the selected threshold did not strongly affect the susceptibility results. Nevertheless, nonlinear dependence measures, such as distance correlation, and tree-model-based feature importance could be further used to examine factor redundancy, nonlinear contributions, and model sensitivity from additional perspectives. Alternative susceptibility classification schemes could also be compared to assess classification uncertainty. Applying the proposed framework to other mountainous regions with different geological, climatic, and geomorphic conditions would further help evaluate its broader applicability.
6. Conclusions
This study developed a landslide susceptibility assessment framework for Jiuzhaigou County by integrating ChiMerge discretization, Weight of Evidence transformation, and ensemble machine learning. The main conclusions are as follows.
First, the ChiMerge–WOE feature-processing strategy provided a statistically grounded and interpretable representation of landslide conditioning factors. ChiMerge identified meaningful intervals for continuous variables based on landslide and non-landslide sample distributions, while WOE quantified the association between each factor class and landslide occurrence.
Second, all three WOE-based ensemble models achieved strong predictive performance under 30 repeated validations. Among them, WOE-CatBoost showed the best overall performance, with the highest mean AUC, accuracy, precision, F1-score, and Kappa coefficient, indicating stronger discrimination ability and more balanced classification performance than WOE-LightGBM and WOE-RF.
Third, the susceptibility maps showed good spatial consistency with the observed landslide inventory. For WOE-CatBoost, the high and very high susceptibility zones covered 28.59% of the study area but contained 85.96% of the recorded landslides. High-susceptibility areas were mainly concentrated in steep valleys, erosion belts, structurally disturbed zones, and areas affected by engineering activities.
Overall, the proposed framework improves both the interpretability and predictive reliability of regional landslide susceptibility assessment. It provides useful spatial information for landslide-prone area identification, disaster prevention, infrastructure planning, and sustainable land-use management in Jiuzhaigou County and other mountainous regions with similar environmental settings.
Author Contributions
Conceptualization, L.Z. and Y.L.; methodology, Y.L.; software, Y.L.; validation, Y.L., Y.Z. and Y.Y.; formal analysis, Y.L.; investigation, Y.L. and Z.B.; resources, L.Z.; data curation, Y.L.; writing—original draft preparation, Y.L.; writing—review and editing, L.Z., Y.Z., Y.Y. and Z.B.; visualization, Y.L.; supervision, L.Z.; project administration, L.Z.; funding acquisition, L.Z. and Y.Y. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by Science and Technology Innovation Program for Postgraduate students in IDP subsidized by Fundamental Research Funds for the Central Universities (ZY20260328), the National Natural Science Foundation of China (41702264 and 42174177), Hebei Key Laboratory of Resource and Environmental Disaster Mechanism and Risk Monitoring (FZ248107), The Science and Technology Project of the Hebei Education Department of China (QN2024093).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data supporting this study’s findings are available from the corresponding author upon reasonable request.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Kumar, P.; Priyanka, P.; Uday, K.V.; Dutt, V. Addressing class imbalance in soil movement predictions. Nat. Hazards Earth Syst. Sci. 2024, 24, 1913–1928. [Google Scholar] [CrossRef] [Scilit]
- Zhongyu, W.; Sumin, L.; Liwei, Y.; Weipeng, L. Landslide susceptibility evaluation considering the importance selection of influencing factors and soil moisture content. Hydrogeol. Eng. Geol. 2025, 52, 211–221. [Google Scholar] [CrossRef]
- Wang, J.; Tie, Y.; Bai, Y.; Gao, Y.; Wang, D.; Zhang, M. Application and prospects of machine learning for rockfalls, landslides and debris flows. Hydrogeol. Eng. Geol. 2025, 52, 228–244. [Google Scholar]
- Chen, H.; Liu, H.; Wang, T.; Sun, Y. Landslide susceptibility evaluation based on FR-DNN coupling model: A case study on Yanyuan County. Hydrogeol. Eng. Geol. 2024, 51, 161–171. [Google Scholar]
- Chowdhury, M.S.; Rahman, M.N.; Sheikh, M.S.; Sayeid, M.A.; Mahmud, K.H.; Hafsa, B. GIS-based landslide susceptibility mapping using logistic regression, random forest and decision and regression tree models in Chattogram District, Bangladesh. Heliyon 2024, 10, e23424. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Tang, R.-X.; Yan, E.-C.; Wen, T.; Yin, X.-M.; Tang, W. Comparison of logistic regression, information value, and comprehensive evaluating model for landslide susceptibility mapping. Sustainability 2021, 13, 3803. [Google Scholar] [CrossRef] [Scilit]
- Bhandari, B.P.; Dhakal, S.; Tsou, C.-Y. Assessing the prediction accuracy of frequency ratio, weight of evidence, Shannon entropy, and information value methods for landslide susceptibility in the Siwalik Hills of Nepal. Sustainability 2024, 16, 2092. [Google Scholar] [CrossRef] [Scilit]
- Wubalem, A.; Meten, M. Landslide susceptibility mapping using information value and logistic regression models in Goncha Siso Eneses area, northwestern Ethiopia. SN Appl. Sci. 2020, 2, 807. [Google Scholar] [CrossRef] [Scilit]
- Akbari, A.; Yahaya, F.B.M.; Azamirad, M.; Fanodi, M. Landslide susceptibility mapping using logistic regression analysis and GIS tools. Electron. J. Geotech. Eng. 2014, 19, 1687–1696. [Google Scholar]
- Cao, Y.; Wei, X.; Fan, W.; Nan, Y.; Xiong, W.; Zhang, S. Landslide susceptibility assessment using the Weight of Evidence method: A case study in Xunyang area, China. PLoS ONE 2021, 16, e0245668. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Getachew, N.; Meten, M. Weights of evidence modeling for landslide susceptibility mapping of Kabi-Gebro locality, Gundomeskel area, Central Ethiopia. Geoenviron. Disasters 2021, 8, 6. [Google Scholar] [CrossRef] [Scilit]
- Li, W.; Fan, X.; Huang, F.; Chen, W.; Hong, H.; Huang, J.; Guo, Z. Uncertainties analysis of collapse susceptibility prediction based on remote sensing and GIS: Influences of different data-based models and connections between collapses and environmental factors. Remote Sens. 2020, 12, 4134. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Z.; Qian, Z.; Wei, Y.; Zhu, X.; Wang, L. Evaluation of geological disaster sensitivity in Shuicheng District based on the WOE-RF model. Sustainability 2022, 14, 16247. [Google Scholar] [CrossRef] [Scilit]
- Akinci, H.; Ozalp, A.Y. Investigating the effects of different data classification methods on landslide susceptibility mapping. Adv. Space Res. 2025, 75, 3427–3450. [Google Scholar] [CrossRef] [Scilit]
- Ding, Q.; Chen, W.; Hong, H. Application of frequency ratio, weights of evidence and evidential belief function models in landslide susceptibility mapping. Geocarto Int. 2017, 32, 619–639. [Google Scholar] [CrossRef] [Scilit]
- Huang, F.; Chen, J.; Yang, Y.; Chen, Q.; Zhou, C.; Jiang, B.; Guo, F. Review and prospects of studies on disaster-causing environmental factors related to landslide susceptibility. Bull. Geol. Sci. Technol. 2025, 44, 14–37. [Google Scholar] [CrossRef]
- Zhao, J.; Zhang, Q.; Wang, D.; Wu, W.; Yuan, R. Machine learning-based evaluation of susceptibility to geological hazards in the Hengduan mountains region, China. Int. J. Disaster Risk Sci. 2022, 13, 305–316. [Google Scholar] [CrossRef] [Scilit]
- Nojavan, F.; Qian, S.S.; Stow, C.A. Comparative analysis of discretization methods in Bayesian networks. Environ. Model. Softw. 2017, 87, 64–71. [Google Scholar] [CrossRef] [Scilit]
- Kass, G.V. An exploratory technique for investigating large quantities of categorical data. J. R. Stat. Soc. Ser. C 1980, 29, 119–127. [Google Scholar] [CrossRef] [Scilit]
- Zhang, R.; Zhang, D.; Shu, B.; Chen, Y. Predicting the spatial distribution of geological hazards in southern Sichuan, China, using machine learning and ArcGIS. Land 2025, 14, 577. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.-C.; Lee, S.; Jung, H.-S.; Lee, S. Landslide susceptibility mapping using random forest and boosted tree models in Pyeong-Chang, Korea. Geocarto Int. 2018, 33, 1000–1015. [Google Scholar] [CrossRef] [Scilit]
- Yavuz Ozalp, A.; Akinci, H.; Zeybek, M. Comparative analysis of tree-based ensemble learning algorithms for landslide susceptibility mapping: A case study in Rize, Turkey. Water 2023, 15, 2661. [Google Scholar] [CrossRef] [Scilit]
- Sun, D.; Wen, H.; Wang, D.; Xu, J. A random forest model of landslide susceptibility mapping based on hyperparameter optimization using Bayes algorithm. Geomorphology 2020, 362, 107201. [Google Scholar] [CrossRef] [Scilit]
- Usta, Z.; Akıncı, H.; Akın, A.T. Comparison of tree-based ensemble learning algorithms for landslide susceptibility mapping in Murgul (Artvin), Turkey. Earth Sci. Inform. 2024, 17, 1459–1481. [Google Scholar] [CrossRef] [Scilit]
- Tien Bui, D.; Shahabi, H.; Shirzadi, A.; Chapi, K.; Alizadeh, M.; Chen, W.; Mohammadi, A.; Ahmad, B.B.; Panahi, M.; Hong, H. Landslide detection and susceptibility mapping by airsar data using support vector machine and index of entropy models in cameron highlands, malaysia. Remote Sens. 2018, 10, 1527. [Google Scholar] [CrossRef] [Scilit]
- Pradhan, B.; Lee, S. Regional landslide susceptibility analysis using back-propagation neural network model at Cameron Highland, Malaysia. Landslides 2010, 7, 13–30. [Google Scholar] [CrossRef] [Scilit]
- Xie, W.; Nie, W.; Saffari, P.; Robledo, L.F.; Descote, P.-Y.; Jian, W. Landslide hazard assessment based on Bayesian optimization–support vector machine in Nanping City, China. Nat. Hazards 2021, 109, 931–948. [Google Scholar] [CrossRef] [Scilit]
- Halder, K.; Srivastava, A.K.; Ghosh, A.; Das, S.; Banerjee, S.; Pal, S.C.; Chatterjee, U.; Bisai, D.; Ewert, F.; Gaiser, T. Improving landslide susceptibility prediction through ensemble recursive feature elimination and meta-learning framework. Sci. Rep. 2025, 15, 5170. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kumar, C.; Walton, G.; Santi, P.; Luza, C. An ensemble approach of feature selection and machine learning models for regional landslide susceptibility mapping in the arid mountainous terrain of Southern Peru. Remote Sens. 2023, 15, 1376. [Google Scholar] [CrossRef] [Scilit]
- Sharma, N.; Saharia, M.; Ramana, G. High resolution landslide susceptibility mapping using ensemble machine learning and geospatial big data. Catena 2024, 235, 107653. [Google Scholar] [CrossRef] [Scilit]
- Zhang, H.; Song, Y.; Xu, S.; He, Y.; Li, Z.; Yu, X.; Liang, Y.; Wu, W.; Wang, Y. Combining a class-weighted algorithm and machine learning models in landslide susceptibility mapping: A case study of Wanzhou section of the Three Gorges Reservoir, China. Comput. Geosci. 2022, 158, 104966. [Google Scholar] [CrossRef] [Scilit]
- Chen, C.; Wang, N.; Yu, H.; Chen, M. Evaluation model of converter operation process based on chi-square boxing method and logistic regression algorithm. J. Mater. Metall. 2019, 18, 87–91. [Google Scholar]
- Rana, R.; Singhal, R. Chi-square test and its application in hypothesis testing. J. Pract. Cardiovasc. Sci. 2015, 1, 69–71. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Yang, W.; Li, Z. Towards fake news refuter identification: Mixture of Chi-Merge grounded CNN approach. Expert Syst. Appl. 2023, 231, 120712. [Google Scholar] [CrossRef] [Scilit]
- Nath, S.K.; Sengupta, A.; Srivastava, A. Remote sensing GIS-based landslide susceptibility & risk modeling in Darjeeling–Sikkim Himalaya together with FEM-based slope stability analysis of the terrain. Nat. Hazards 2021, 108, 3271–3304. [Google Scholar] [CrossRef] [Scilit]
- Tan, F.; Yu, J.; Jiao, Y.-Y.; Lin, D.; Lv, J.; Cheng, Y. Rapid assessment of landslide risk level based on deep learning. Arab. J. Geosci. 2021, 14, 220. [Google Scholar] [CrossRef] [Scilit]
- Bian, Y.; Chen, H.; Liu, Z.; Chen, L.; Guo, Y.; Yang, Y. Geological Disaster Susceptibility Evaluation Using Machine Learning: A Case Study of the Atal Tunnel in Tibetan Plateau. Sustainability 2024, 16, 4604. [Google Scholar] [CrossRef] [Scilit]
- Su, Y.; Rong, G.; Ma, Y.; Chi, J.; Liu, X.; Zhang, J.; Li, T. Hazard assessment of earthquake disaster chains based on deep learning—A case study of Mao County, Sichuan province. Front. Earth Sci. 2022, 9, 683903. [Google Scholar] [CrossRef] [Scilit]
- Chen, J.; Li, Q.; Huang, C.; Hu, X.; Shen, Z. Landslide susceptibility assessment in the Central Yunnan Plateau by assembling optimized statistical and machine learning models. Geoenviron. Disasters 2026, 13, 28. [Google Scholar] [CrossRef] [Scilit]
- Yin, S.; Dai, Z.; Zeng, Y. Optimized landslide susceptibility prediction based on SBAS-InSAR: Case study of the Jiuzhaigou Ms7. 0 earthquake. Geomat. Nat. Hazards Risk 2024, 15, 2366362. [Google Scholar] [CrossRef] [Scilit]
- Kalantar, B.; Ueda, N.; Saeidi, V.; Ahmadi, K.; Halin, A.A.; Shabani, F. Landslide susceptibility mapping: Machine and ensemble learning based on remote sensing big data. Remote Sens. 2020, 12, 1737. [Google Scholar] [CrossRef] [Scilit]
- Ye, P.; Yu, B.; Chen, W.; Feng, Y.; Zhou, H.; Luo, X.; Li, Y. Risk assessment of landslide and rockfall hazards in hilly region of southwestern China: A case study of Qijiang, Wuxi and Chishui. Environ. Earth Sci. 2024, 83, 398. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Ling, Y.; Chan, T.O.; Awange, J. High-resolution earthquake-induced landslide hazard assessment in Southwest China through frequency ratio analysis and LightGBM. Int. J. Appl. Earth Obs. Geoinf. 2024, 131, 103947. [Google Scholar] [CrossRef] [Scilit]
- Su, Y.; Fu, J.; Lai, X.; Lin, C.; Zhu, L.; Xie, X.; Jiang, J.; Chen, Y.; Huang, J.; Huang, W. Complex cross-regional landslide susceptibility mapping by multi-source domain transfer learning. Geosci. Front. 2025, 16, 102053. [Google Scholar] [CrossRef] [Scilit]
- Gao, Q. Analysis of geological disasters and micro terrain factors in Wangmo River Basin based on ArcGIS. For. Inventory Plan. 2024, 49, 171–174. [Google Scholar]
- Wu, F.; Liao, Z.; He, N.; Liu, C.; Wu, Q.; Mo, Y. Airborne LiDAR for geological hazard investigation in mountainous areas with dense vegetation on point cloud density optimization. Geomat. Inf. Sci. Wuhan Univ. 2023, 48, 1897–1913. [Google Scholar]
- Xi, Q.; Wei, Z.; Zhao, J.; Geng, S.; Shi, F.; Zou, J.; He, H. Geomorphological classification of active fault zones integrating spectral characteristics and topographic factors: A case study of the northern piedmont fault zone of Liulingshan Mountain. Quat. Sci. 2025, 45, 149–163. [Google Scholar]
- Li, J.; Wang, W.; Ran, M. Threshold analysis of rainfall-induced landslide hazards in hilly area: Case study of Enyang District, Bazhong City. J. Meteorol. Sci. 2022, 42, 279–284. [Google Scholar]
- Zhang, H.; Wang, X.; Luo, L.; Wang, Y.; Guo, Q.; Xue, C. Changing law of shear strength of typical gravel soil in Qinba Mountain area and its application in the analysis of landslide mechanism in accumulation layers. Chin. J. Geol. Hazard Control 2024, 35, 50–58. [Google Scholar]
- Zhang, B.; Qian, L.; Li, T.; Chen, J.; Xu, J.; Yao, Y. Geological disasters and surface ruptures of January 23, 2024 MS 7.1 Wushi earthquake, Xinjiang, China. Seismol. Geol. 2024, 46, 220–234. [Google Scholar]
- Wu, K.; Yi, X.; Fu, X.; Zhang, L.; Kang, J.; Yuan, Q.; Shao, J. Geohazard development rules and post disaster reconstruction strategies of Hailuogou scenic road in the epicenter of Luding earthquake. Chin. J. Rock Mech. Eng. 2024, 43, 1909–1922. [Google Scholar]
- Guo, J.; Wang, K.; Wang, T.; Bai, N.; Zhang, H.; Cao, Y.; Liu, H. Spatiotemporal variation of vegetation NDVI and its climatic driving forces in global land surface. Pol. J. Environ. Stud. 2022, 31, 3541–3549. [Google Scholar] [CrossRef] [Scilit]
- Yu, M.; Guo, Y.; Su, L. Quantitative evaluation of influencing factors of landslide, collapse, and debris flow disasters in the Nyingchi area, Tibet. J. Geol. Hazards Prev. China 2024, 35, 33–43. [Google Scholar]
- Li, T.; Jia, B.; Wang, C.; Qiu, E.; Li, X. Analysis of tree canopy cover and its regional differences in rural residential areas of Beijing. Acta Ecol. Sin. 2021, 41, 5598–5610. [Google Scholar]
- Alatorre, L.C.; Sánchez-Andrés, R.; Cirujano, S.; Beguería, S.; Sánchez-Carrillo, S. Identification of mangrove areas by remote sensing: The ROC curve technique applied to the northwestern Mexico coastal zone using Landsat imagery. Remote Sens. 2011, 3, 1568–1583. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.