


Abstract
The rapid expansion of renewable energy has raised the demand for accurate, long-term wind power forecasting. However, wind power series are strongly affected by meteorological factors and exhibit pronounced volatility, making long-term prediction challenging. To model these characteristics more comprehensively, we propose STFNet, a dual-branch neural architecture that integrates time-domain and frequency-domain modeling. STFNet contains two key modules: (1) an MLFE module, which explicitly captures lag effects and non-stationary transitions through parallel multi-scale convolutions and a difference-convolution branch and further enhances multivariate dependency learning via cross-variable interaction modeling, and (2) an FGFE module, which applies DCT to capture long-cycle trends and uses a learnable low-pass filter for noise suppression. Experiments on two real-world wind farm datasets (LY and HG) show that STFNet consistently outperforms strong baselines, achieving average MSE reductions of 15.9–26.6% while maintaining a high computational efficiency. Ablation studies further confirm the effectiveness of each module, indicating the strong practical potential of STFNet for wind farm operation and management.
1. Introduction
Wind power has become a core component of the global low-carbon transition, with cumulative installed capacity exceeding 1 terawatt (TW) in 2023 [1,2]. As wind penetration continues to increase, reliable long-term forecasting (24 h to 7 days ahead) is increasingly important for dispatch planning, reserve allocation, maintenance scheduling, and electricity market operation [3,4,5,6]. Beyond industrial applications, wind power forecasting provides significant value to the broader research community. The severe volatility and non-stationarity of wind data offer a rigorous testbed for developing robust time-series techniques, thereby bridging data-driven artificial intelligence with meteorological physics. Despite this practical and academic importance, accurate long-horizon prediction remains difficult because the model must simultaneously capture lag-sensitive local fluctuations in the time domain and long-cycle regularities in the frequency domain while also handling complex coupling between wind power and exogenous meteorological variables.
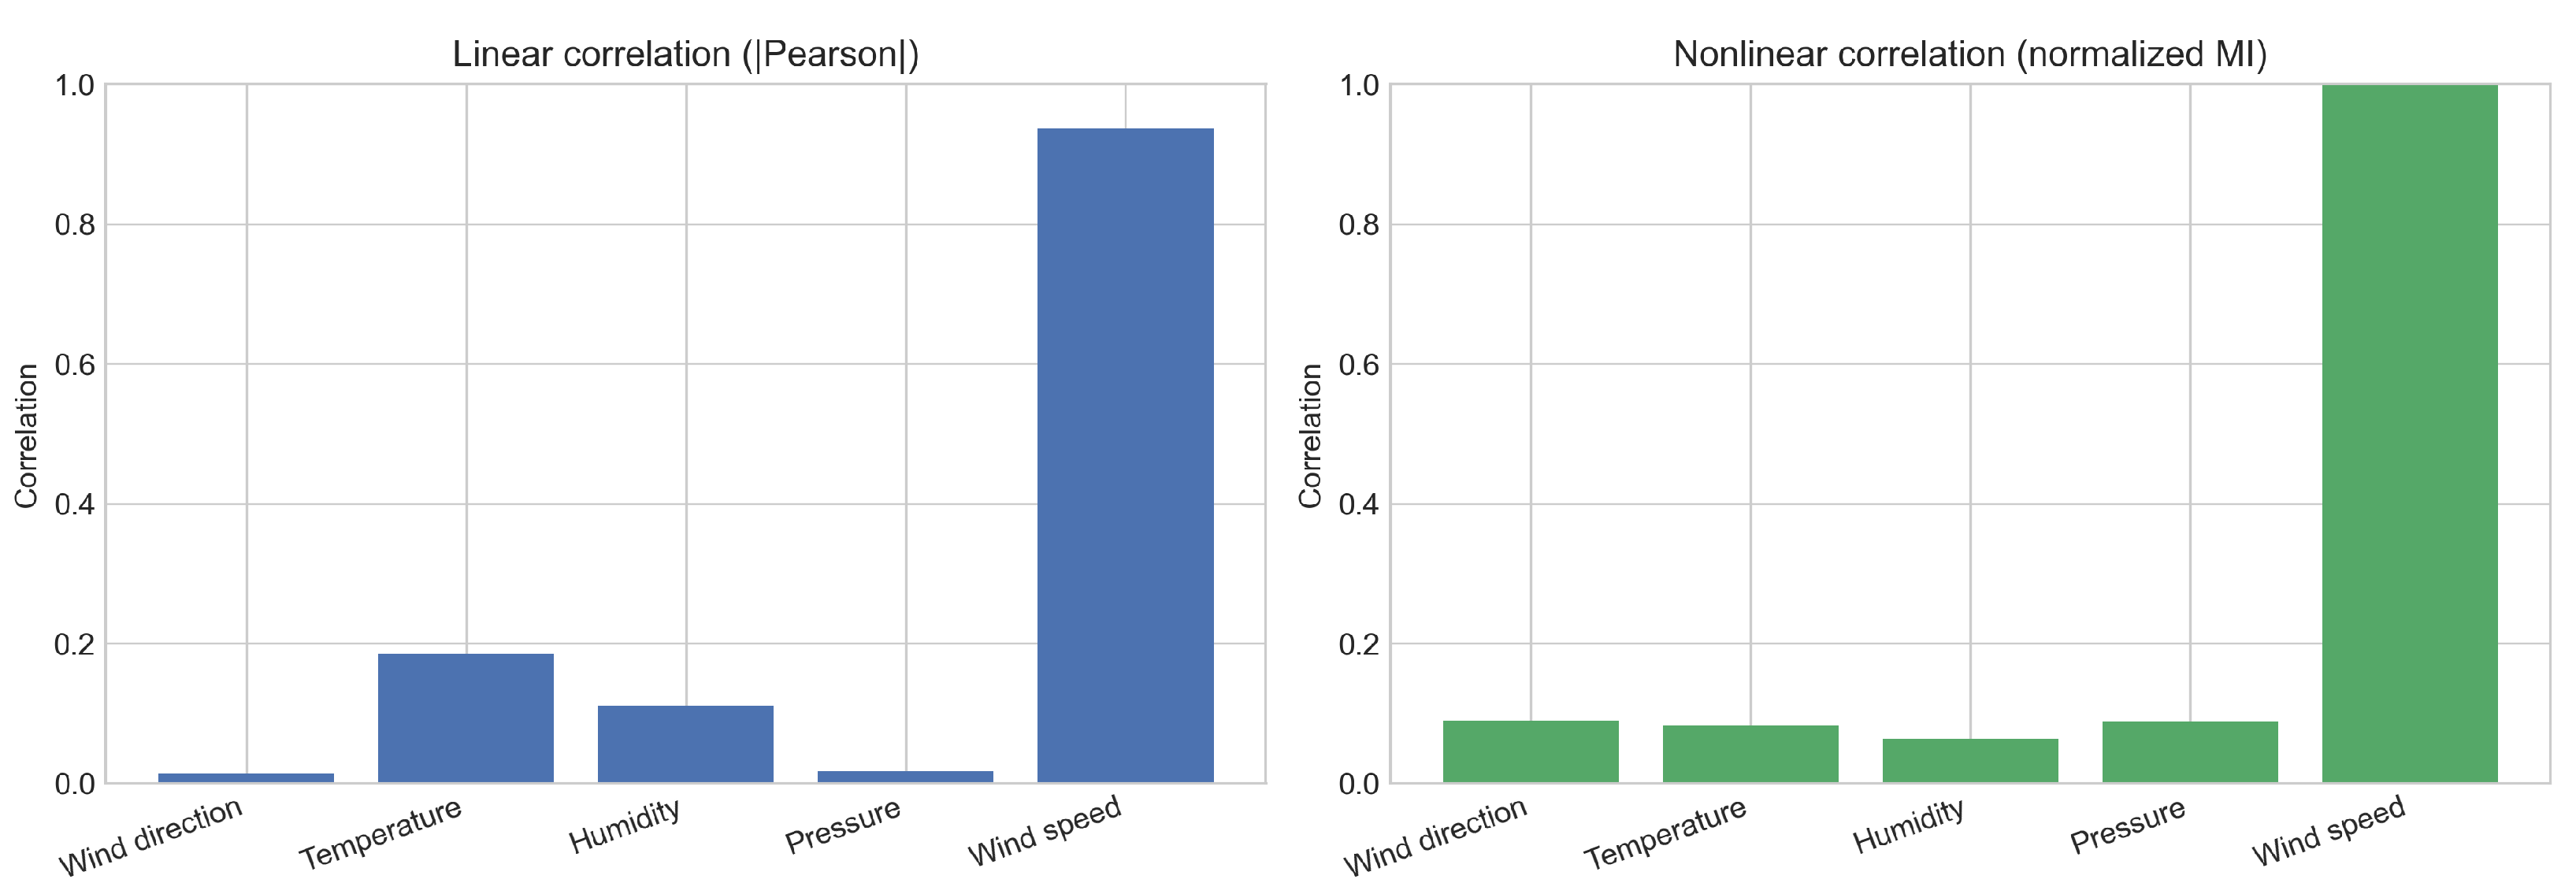
To provide an empirical view of such variable coupling, Figure 1 reports linear and nonlinear correlation analysis on the Longyuan (LY) dataset. Wind speed shows the strongest association with wind power under both criteria, while variables such as wind direction and pressure present a weak linear correlation but still non-negligible nonlinear dependence. These observations indicate that wind power is influenced by both dominant drivers and complementary nonlinear effects, rather than by a single simple dependency pattern.
Figure 1.
Linear and nonlinear correlations between wind power and major exogenous variables on the LY dataset. The left panel reports the absolute Pearson correlation (linear association), and the right panel reports the normalized mutual information (nonlinear association).
The existing forecasting methods only partially address these challenges. Physical models based on Numerical Weather Prediction (NWP) are meteorologically grounded, but they are computationally expensive and require dense observational support [7,8]. Classical statistical methods such as Autoregressive Moving Average (ARMA) and Autoregressive Integrated Moving Average (ARIMA) are efficient, yet their effectiveness is constrained by linear assumptions and strict stationarity requirements [9,10]. Deep learning methods have substantially improved nonlinear representation, including recurrent models (Long Short-Term Memory (LSTM), Gated Recurrent Unit (GRU)), Transformer-based long-horizon models (Informer, Autoformer, PatchTST), and convolutional models (TimesNet, Temporal Convolutional Network (TCN)) [11,12,13,14,15,16]. Nevertheless, many approaches remain effectively single-domain: they predominantly model either temporal evolution or the spectral structure and, thus, cannot fully exploit complementary information across both domains.
Time-frequency hybrid models are a promising direction to overcome this limitation. FEDformer integrates Fourier-based spectral operations into Transformer attention [17], FITS uses Fast Fourier Transform (FFT)-based filtering for noise suppression [18], StemGNN combines graph learning with spectral modeling [19], and N-BEATS introduces explicit seasonality-trend decomposition [20]. However, two practical issues remain. First, time-domain and frequency-domain signals are often mixed too early in a shared pipeline, which weakens branch-specific advantages. Second, similar operators are frequently applied to both domains, although local non-stationary ramps and long-cycle periodic components typically require different modeling treatments. Consequently, the existing hybrids may still face a trade-off between local accuracy and long-horizon global stability.
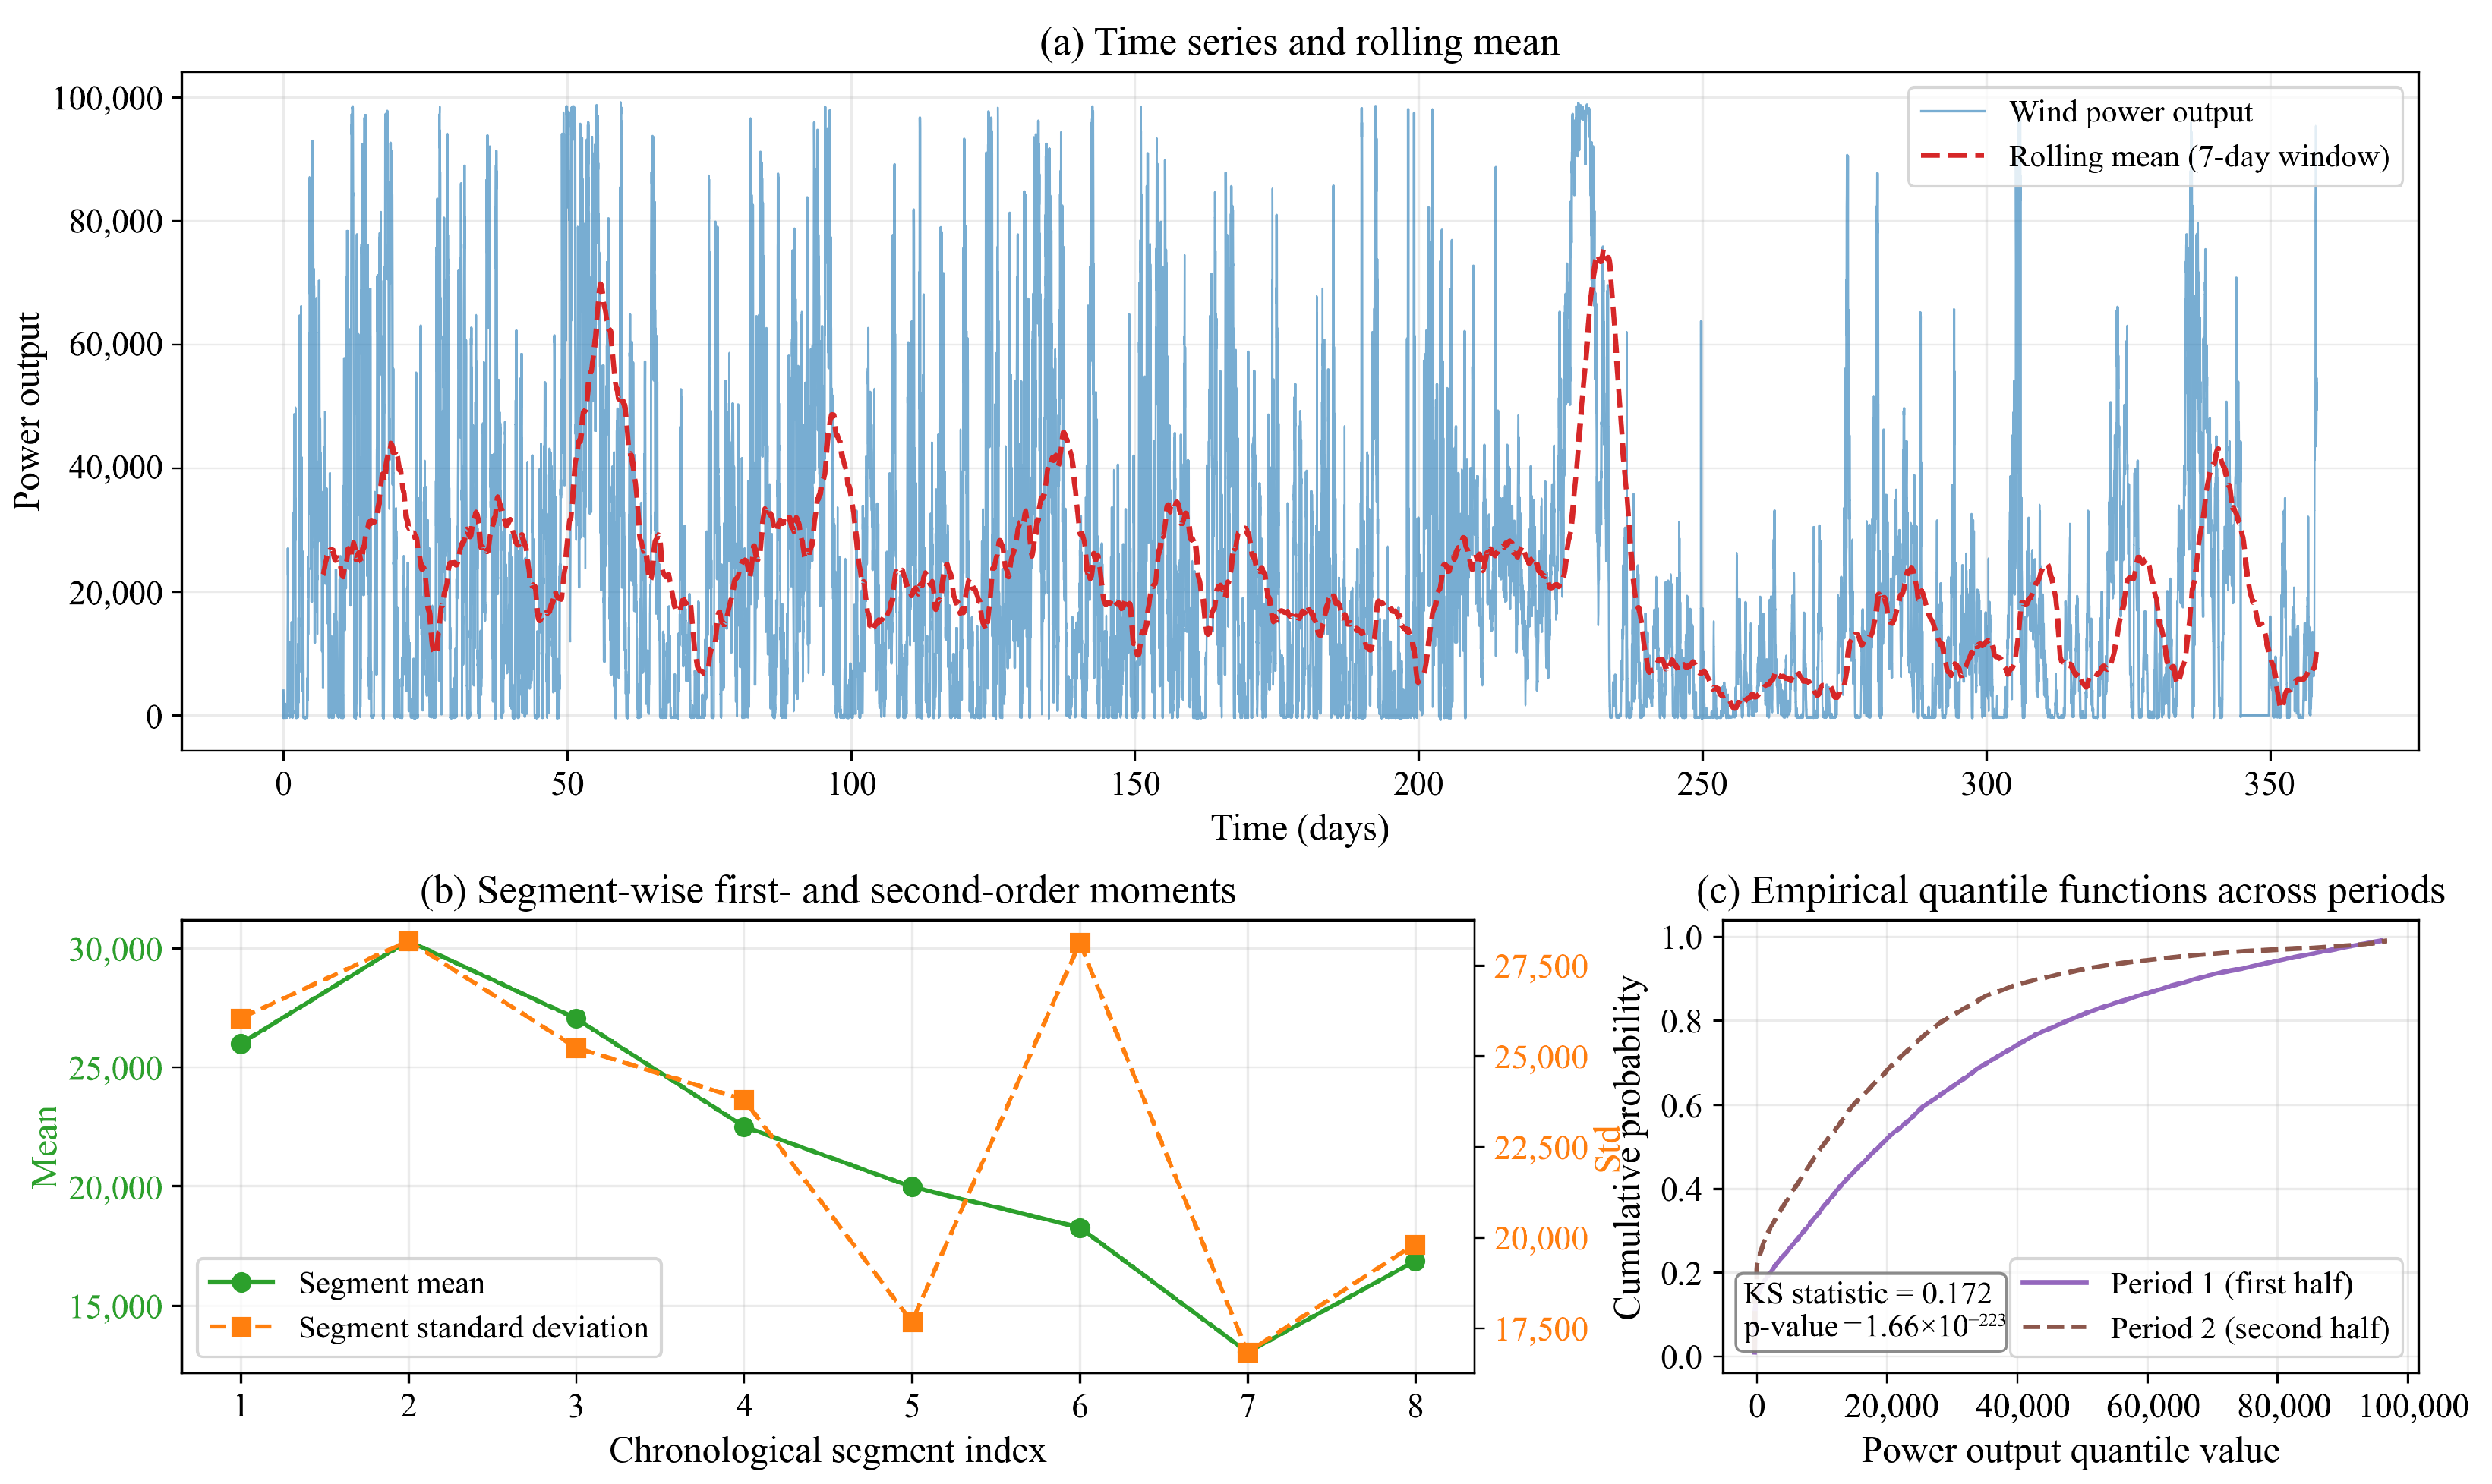
Non-stationarity in wind power data further increases this difficulty. As shown in Figure 2, the LY series has clear distribution shifts over time: the rolling mean changes notably, segment-wise first- and second-order moments vary, and the empirical distributions of two chronological periods are significantly different (Kolmogorov-Smirnov (KS) statistic , ). These results show that strict stationarity assumptions are often unrealistic and that effective models should capture both change-rate dynamics in time and long-cycle structure in frequency.
Figure 2.
Non-stationarity characteristics of the LY wind power series. (a) Time series with 7-day rolling mean, indicating variation in central tendency over time. (b) Segment-wise mean and standard deviation, showing temporal variation of first- and second-order moments. (c) Empirical quantile functions for two chronological periods, with a significant two-sample KS test result, indicating a distributional shift.
To address these limitations, we propose STFNet, a lightweight, specialized time-frequency network for long-term wind power forecasting. The core idea is straightforward: STFNet is specialized by assigning different modeling targets to two branches. The time-domain branch focuses on local lag-sensitive and non-stationary dynamics, while the frequency-domain branch focuses on global periodic structure and long-term trends. The main contributions are as follows:
- 1.
- Specialized dual-branch architecture: We design a time-frequency framework with explicit branch-specific roles. The time-domain branch and frequency-domain branch are complementary and non-overlapping, which avoids the information loss caused by early mixing and allows each branch to focus on what it models best.
- 2.
- Multi-Scale Local Feature Extraction (MLFE) module: MLFE uses parallel convolutions with four kernel sizes (1, 3, 5, 7) to capture lag-related local dynamics at different temporal scales. A first-order difference branch explicitly models change-rate information to improve robustness under non-stationary conditions. An adaptive fusion mechanism then adjusts the contribution of each scale according to changing weather conditions.
- 3.
- DCT-based Frequency-domain Global Feature Extraction (FGFE) module: FGFE uses the Discrete Cosine Transform (DCT) to obtain a compact real-valued spectral representation. Compared with FFT-based approaches, DCT can better reduce boundary ringing and spectral leakage in finite-length sequences. A learnable low-pass filter further suppresses high-frequency noise while preserving diurnal and seasonal low-frequency components that are important for long-term prediction.
Extensive experiments on two real-world wind power datasets (LY and Huaguang (HG)) show that STFNet achieves the lowest mean squared error (MSE) in all eight evaluated long-term settings. Relative to PatchTST at matched horizons, STFNet reduces MSE by 15.9–26.6% on HG and by up to 27.3% on LY while maintaining competitive computational efficiency. Ablation and intervention analyses further confirm that the two branches make complementary contributions.
The remainder of this paper is organized as follows. Section 2 reviews related work spanning wind power forecasting, time-domain methods, frequency-domain methods, and time-frequency hybrid approaches. Section 3 formalizes the forecasting problem and details the STFNet architecture. Section 4 presents comparative experiments, ablation studies, efficiency analysis, and discussion. Section 5 concludes the paper and outlines directions for future research.
2. Related Work
2.1. Wind Power Forecasting Studies
Compared with generic time-series forecasting, wind power forecasting achieves stronger meteorological coupling, more pronounced intermittency, and stricter operational requirements in grid dispatch and market scheduling [4,5]. The existing studies can be broadly grouped into physical, statistical, and hybrid data-driven paradigms [6,21].
Physical approaches based on NWP remain important for medium- and long-term forecasting because of meteorological consistency [7,8], while recent data-driven studies have expanded along three practical directions. First, extitspatial/regional coordination: hierarchical reconciliation and regional aggregation are used to enforce coherence across farms and zones [22,23,24]. Second, probabilistic and multivariate modeling: copula-based and uncertainty-aware frameworks explicitly model cross-farm dependence and forecast distributions, rather than only point values [25,26]. Third, feature-engineered deep learning: SCADA-driven models, decomposition-graph networks, interpretable residual architectures, and ramp-aware deep models improve nonlinear representation under changing wind regimes [27,28,29,30].
In parallel, market-oriented formulations such as regression-market learning with sparse regularization have highlighted the value of information sharing and feature pricing in forecasting ecosystems [31]. Statistical Hidden Markov Model (HMM)-style pipelines also remain competitive in specific short-term operating conditions [32]. Recent Energies studies further report that deep architectures are sensitive to feature-space design and hyperparameter optimization in wind forecasting tasks [33,34].
Importantly, as highlighted by recent literature, wind power forecasting is highly case-sensitive. The performance of forecasting models is strictly influenced by local terrain, climate characteristics, data sampling rates, and feature configurations. To provide a clear overview of this diversity, Table 1 summarizes representative wind power forecasting studies, detailing their locations, datasets, applied techniques, advantages, limitations, and evaluation metrics (e.g., mean squared error (MSE), root mean square error (RMSE), mean absolute error (MAE), and continuous ranked probability score (CRPS)). Because wind power dynamics are extremely localized, a direct comparison of absolute error metrics across different datasets is often misleading. This case-sensitivity also underscores the necessity of evaluating forecasting frameworks on multiple independent wind farms with distinct meteorological characteristics, a principle we strictly follow in our empirical studies.
Table 1.
Summary of closely related wind power forecasting literature and their case-specific settings.
Although these preceding studies significantly improve practical forecasting performance, most models emphasize either spatial uncertainty modeling or temporal pattern extraction, with a limited explicit separation between local lag-sensitive dynamics and global spectral structure. Therefore, a key open problem in long-term wind power forecasting is how to jointly model lag-dependent local fluctuations, non-stationary transitions, and long-cycle global regularities within a unified yet specialized architecture.
2.2. Time-Domain Forecasting Methods
Time-domain forecasting has evolved from classical linear models to deep neural architectures. Traditional methods such as ARMA/ARIMA remain computationally efficient but are limited by linear assumptions in nonlinear multivariate settings [9]. Deep learning models substantially improved representation learning for temporal data, including recurrent neural network (RNN) and convolutional neural network (CNN) backbones and Transformer-based long-term models [13,14,16,37].
Despite strong empirical performance, each family involves clear limitations. RNN variants (e.g., LSTM/GRU) are effective for sequential dependency modeling but can still suffer from optimization degradation on long horizons [11,12]. Transformer-based models capture long-range dependencies via self-attention, yet they often incur high time–memory complexity and may lose fine temporal inductive bias due to permutation-invariant attention mechanisms [15]. CNN-based models (e.g., TCN-style designs) provide strong local pattern extraction through dilated convolutions [38,39], but single-path temporal convolutions may be insufficient for jointly modeling lag effects across multiple scales and abrupt local transitions. In addition, methods such as MICN and DLinear reveal a recurring issue: either multi-scale features are fused too coarsely or decomposition patterns are overly fixed [40,41]. In power-system applications, operational wind-power studies are informative, but many methods are still tuned to short-horizon or task-specific scenarios [23,27,31].
Overall, time-domain methods are strong at local dynamics but often less effective at explicitly representing long-period global regularities.
2.3. Frequency-Domain Forecasting Methods
Frequency-domain methods map sequences into spectral representations to model periodicity and the global trend structure more directly. Representative works include StemGNN, which combines graph learning and Fourier-domain modeling [19], SFM, which introduces frequency-aware processing into recurrent modeling [42], and FITS, which uses FFT-based filtering to suppress high-frequency noise [18].
The key advantage of this line is the efficient extraction of long-cycle components. However, spectral modeling alone is typically less sensitive to localized non-stationary changes and short-term sharp transitions that are critical in wind power forecasting. Therefore, frequency-domain methods alone may not fully characterize the coupled local–global dynamics of long-term wind power series.
2.4. Time-Frequency Hybrid Methods
To bridge the above gap, time-frequency hybrid models have become an active research direction. Early hybrids relied on wavelet-based preprocessing [43], while later models incorporated explicit seasonality/trend bases into end-to-end forecasting [20]. More recent architectures integrate spectral operations more deeply, such as FEDformer [17], PathFormer [44], and ATFN-style frequency-enhanced designs [45].
A central diverging hypothesis in the current literature concerns architectural coupling: some methods favor unified processing pipelines for simplicity, whereas others advocate for domain-specialized branches to preserve complementary inductive biases. Unified pipelines are compact, but they may dilute domain-specific feature extraction; highly decoupled schemes improve specialization, but they require careful fusion design. This trade-off remains unresolved, especially for long-term wind power forecasting where lag effects, non-stationarity, and periodicity coexist.
2.5. Positioning of Our Work
Building on the above review, STFNet is designed as a specialized time-frequency hybrid framework. Unlike unified-processing approaches, STFNet uses explicit branch-specific specialization:
- Specialized time-domain branch: The MLFE module combines multi-scale convolutions and difference convolution to model lag-dependent local dynamics and non-stationary change cues.
- Specialized frequency-domain branch: The FGFE module uses DCT-based real-valued spectral modeling to extract global periodic structure and long-term trends with robust noise suppression.
This design directly targets the local–global representation gap identified above and provides a principled basis for combining temporal precision with spectral global awareness.
3. Methodology
3.1. Problem Formulation and Notation
Long-term wind power forecasting is formalized as a multivariate time series regression task. Given a historical multivariate time series, , where T denotes the number of historical time steps, and d is the input dimension (including wind power, wind speed, direction, temperature, humidity, pressure, etc.), the goal is to predict future wind power outputs over H time steps: .
Wind power sequences exhibit multi-scale complexity: short-term stochastic fluctuations coexist with long-term regularities, such as diurnal cycles and seasonality. This complexity renders single-domain methods inadequate for comprehensive feature capture.
3.2. Input Standardization
Before model training, each variable is transformed by z-score standardization. For variable j, let and denote its mean and standard deviation. For any sample at time step t, the standardized value is
For notation consistency, subsequent equations use X to denote standardized inputs unless otherwise specified. In this work, model training and default error reporting follow the standardized space unless otherwise specified.
3.3. Overall Architecture Design
3.3.1. Principle of Specialized Dual Branches
STFNet follows a domain-specialized design: the time domain is used to model local lag-sensitive dynamics, while the frequency domain is used to model long-cycle global regularities. Therefore, the model adopts two parallel branches and performs prediction after feature integration.
3.3.2. Architectural Components and Information Flow
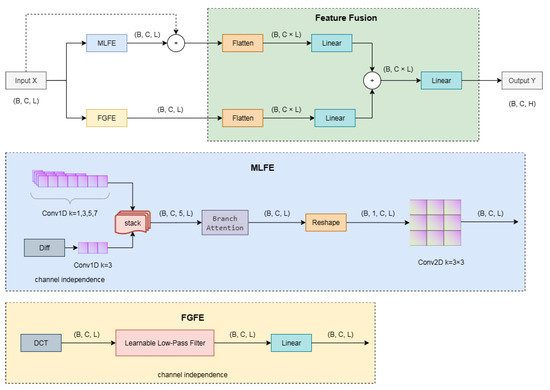
This subsection describes the architectural components of STFNet and the information flow between branches. As shown in Figure 3, the overall architecture consists of three modules:
Figure 3.
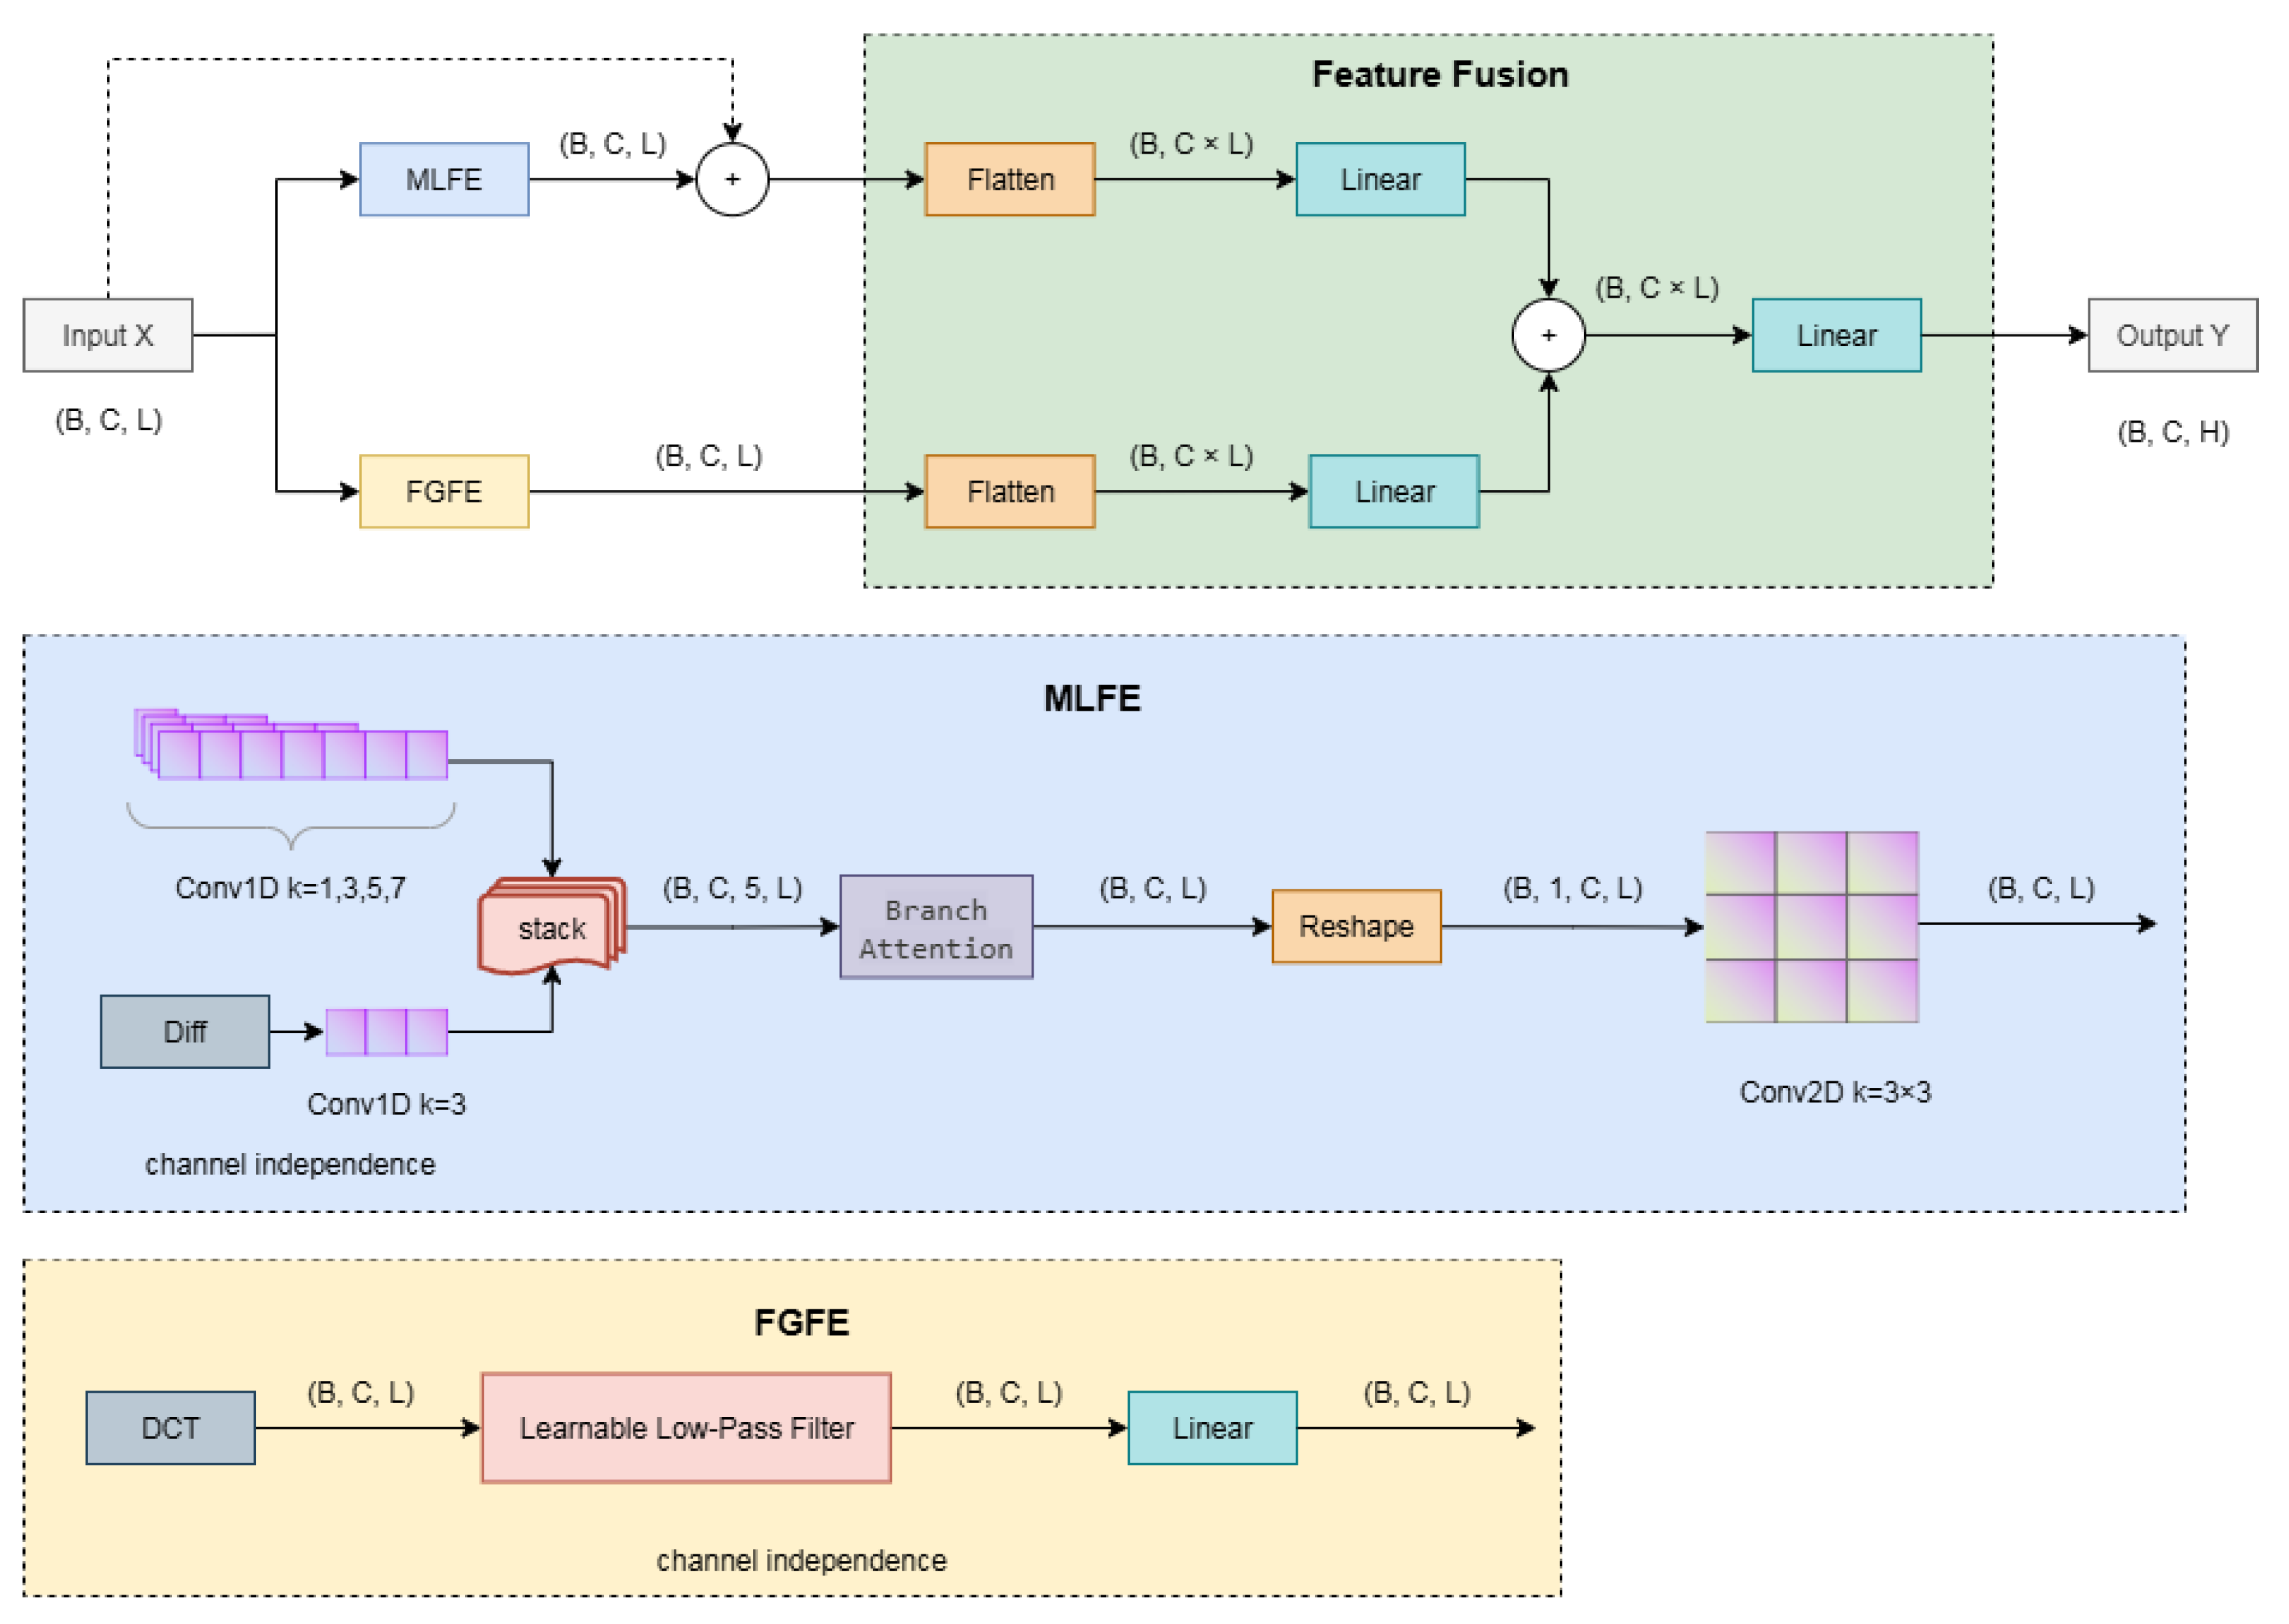
Overall architecture of STFNet. The model adopts a Channel Independence strategy for standardized inputs. The MLFE module performs time-domain local extraction across multiple temporal scales, using a Reshape operation to bridge branch attention and 2D convolution for cross-variable modeling. The FGFE module performs frequency-domain global extraction. Finally, the Feature Fusion module integrates the two complementary representations via element-wise addition (+) to directly output the final prediction. Tensor dimensions (e.g., ) are annotated to illustrate the data flow.
- 1.
- Multi-Scale Local Feature Extraction (MLFE): Processes time-domain information via parallel multi-kernel convolutions to capture local patterns across temporal scales.
- 2.
- Frequency-Domain Global Feature Extraction (FGFE): Processes frequency-domain information using DCT-based operations to extract global periodicity and long-term trends.
- 3.
- Feature Fusion Module: Integrates the complementary representations from MLFE and FGFE to yield the final forecast.
Input data are fed into the MLFE and FGFE branches in parallel, which avoids the error accumulation that may occur in serial processing. Each branch operates directly on the same raw input, enabling the full use of complementary local and global information before fusion and prediction. In the multivariate-to-univariate forecasting setup (MS), all variables are used as branch inputs, while training loss and evaluation metrics are computed on the wind power target channel.
3.4. Multi-Scale Local Feature Extraction Module (MLFE)
3.4.1. Multi-Scale Convolutional Branch Design
The core idea of MLFE is to use convolutional kernels of varying sizes to capture local wind power variations across multiple temporal scales. The module employs four parallel convolutional branches:
where denotes a 1D convolution with kernel size . This multi-scale parallel design simultaneously captures hierarchical features–from point-wise relationships to longer local trends.
For implementation, STFNet adopts a Channel Independence (CI) strategy. The input is rearranged to , where B is the batch size, C is the number of variables (or independent channels), and L is the lookback length. By processing each channel independently, CI mitigates distribution shifts across different sensor variables. Each 1D convolutional branch output maintains the independent shape , preserving sequence length through padding.
In implementation, these multi-scale convolutions are channel-independent (depthwise) operations, so each variable is first modeled within its own temporal stream before cross-variable interaction learning.
Different kernel sizes correspond to distinct temporal receptive fields, enabling the concurrent perception of wind power dynamics across scales. Smaller kernels focus on fine-grained short-term changes, while larger kernels capture extended local trends. This overcomes the limitations of single-scale feature extraction.
3.4.2. Difference Convolution Enhancement
To enhance sensitivity to the wind power rate of change, MLFE incorporates a difference convolution branch:
where denotes the first-order difference of the input sequence.
To keep the output length unchanged, the first difference element is computed with boundary padding: (equivalent to prepending the first value before differencing).
This branch highlights rate-of-change information and improves robustness under non-stationary operating conditions.
3.4.3. Adaptive Weight Fusion Mechanism
Feature importance varies with weather conditions: longer scales dominate during stable periods, while shorter scales prevail during rapid transitions. Thus, MLFE employs an adaptive fusion mechanism:
where is a learnable branch-weight matrix. Softmax is applied along the branch dimension, so each channel obtains five normalized branch weights.
This mechanism allows the model to adapt scale importance to changing meteorological regimes.
3.4.4. Cross-Variable Feature Interaction
Wind power depends on complex interactions among meteorological variables. Standard 1D convolutions cannot model cross-variable dependencies. MLFE addresses this via 2D convolution after reshaping:
where the Reshape operation constructs a 4D tensor, transforming the channel-independent representations into a standardized spatial format. This explicitly bridges from the Branch Attention mechanism to the subsequent 2D convolution.
The Conv2D layer then captures local inter-variable correlations (e.g., wind speed-direction synergy, temperature-pressure co-variation), which are critical for accurate wind power prediction.
3.4.5. Application of Discrete Cosine Transform
FGFE adopts the Discrete Cosine Transform (DCT) as its core spectral analysis tool:
with orthonormal scaling
DCT offers three practical advantages for wind power forecasting: real-valued computation, strong energy compaction in low-frequency coefficients, and mitigation of the Gibbs phenomenon in finite-length sequence analysis. Compared with FFT-based complex spectra, this representation is simpler for downstream learning.
DCT, therefore, provides a compact representation of diurnal and seasonal periodicity.
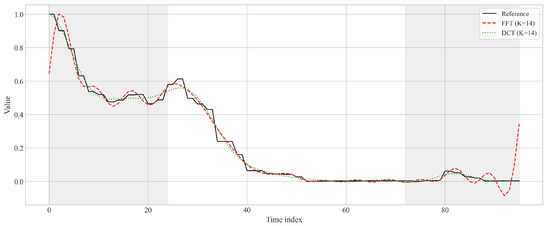
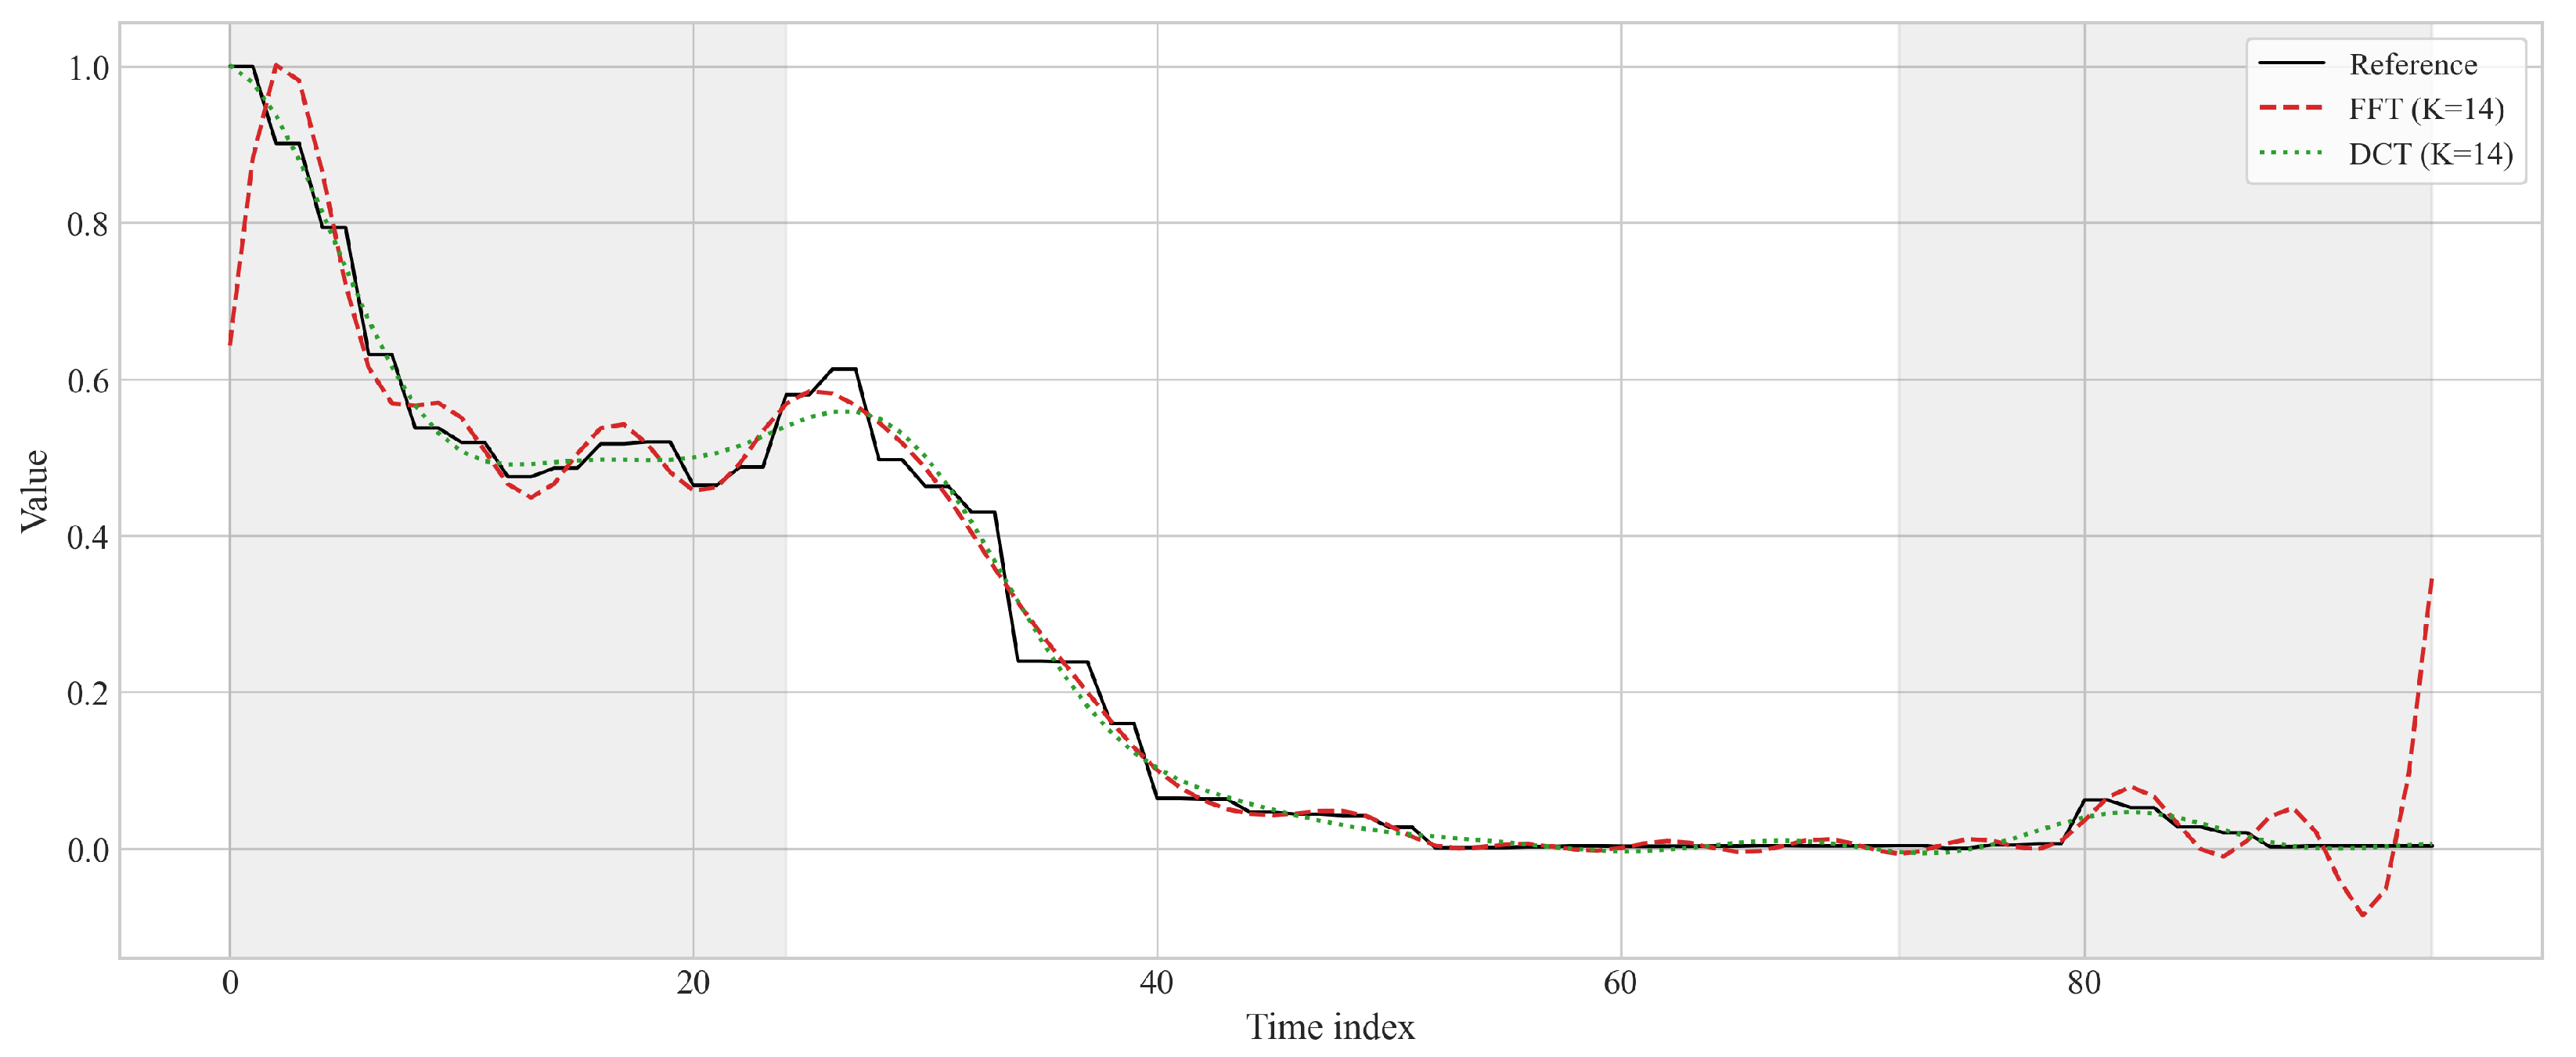
To provide empirical evidence on real wind power data, Figure 4 compares equal-budget low-frequency reconstructions using FFT and DCT on a finite LY segment. Under the same truncation order, FFT reconstruction exhibits pronounced boundary ringing due to periodic extension mismatch, whereas DCT reconstruction remains substantially smoother near both ends. This directly supports the use of DCT in FGFE for reducing Gibbs-related boundary distortion.
Figure 4.
Empirical comparison of DCT and FFT on a wind power segment from the LY dataset for Gibbs-phenomenon analysis. Under an equal low-frequency truncation budget, FFT reconstruction exhibits stronger boundary ringing, while DCT reconstruction remains smoother at both sequence ends. The gray-shaded regions indicate the boundary-sensitive zones.
3.4.6. Design of Adaptive Low-Pass Filter
Frequency-domain signals contain high-frequency noise detrimental to prediction. FGFE introduces a learnable adaptive low-pass filter:
where is a learnable frequency-wise filter shared across channels. The filter is initialized with a low-frequency-priority profile (larger weights in low frequencies and smaller weights in high frequencies) and then optimized jointly with the full network.
Unlike fixed-cutoff filters, this adaptive design learns data-dependent frequency retention and uses smooth transitions to reduce abrupt filtering artifacts.
3.4.7. Frequency Feature Extraction and Transformation
After low-pass filtering, frequency features are transformed in two linear stages consistent with implementation:
Here, the first transformation is applied channel-wise in the spectral axis, and the second transformation is applied after flattening to obtain branch-level frequency representations for fusion.
3.5. Feature Fusion and Forecast Generation
MLFE and FGFE produce complementary features that are first linearly transformed in each branch and then fused by element-wise addition:
where and are branch-specific linear projections. Additive fusion keeps the feature dimension unchanged, reduces parameters compared with concatenation, and preserves one-to-one alignment between branch channels. Built directly upon the fused representations, the final predictions are generated via a compact linear map:
This direct generation scheme seamlessly maps the fused features to the target horizon without requiring a separate, complex prediction component.
3.6. Training Objective
Given prediction and ground truth , STFNet is trained by minimizing the mean squared error:
Model parameters are optimized end-to-end with backpropagation. Detailed optimization hyperparameters are reported in Section 4.
3.7. Algorithmic Summary
The complete STFNet workflow can be summarized as follows:
- 1.
- Standardization and reshape: Given raw input , apply z-score standardization, and then permute to .
- 2.
- Time-domain branch: Apply four depthwise temporal convolutions () and one difference-convolution branch to each independent channel. Stack branch outputs and fuse them via Branch Attention with channel-wise softmax weights. Then, apply a Reshape operation and a 2D convolution to extract cross-variable correlations, obtaining .
- 3.
- Frequency-domain branch: Apply DCT channel-wise to , multiply by learnable frequency filter h, and project the filtered spectrum to obtain .
- 4.
- Branch projection: Vectorize branch features and apply branch-specific linear mappings: , .
- 5.
- Fusion and Delivery: Combine the two branches via element-wise addition, , and apply a final linear mapping to project it directly to the prediction length, reshaping to obtain the forecast .
This workflow yields a unified predictor that jointly models local temporal variation and global spectral structure in long-term wind power series.
4. Experiments
4.1. Datasets
We evaluate STFNet on two real-world wind power datasets: Longyuan (LY) and Huaguang (HG). The LY dataset is collected from the Longyuan Wind Farm, with 15 min sampling from 00:00 on 2 January 2021 to 23:45 on 30 September 2021, yielding 34,396 temporal samples. HG is collected from the Huaguang Wind Farm in Wuzhou, Guangxi, China, with 15 min sampling from 00:00 on 1 January 2023 to 16:15 on 31 December 2023, yielding 34,878 temporal samples.
Both datasets contain six aligned variables: instantaneous wind power output, wind speed, wind direction, temperature, pressure, and humidity. The missing values are imputed by polynomial interpolation, and the same preprocessing pipeline is applied to all compared methods.
For temporal fairness, we adopt chronological train/validation/test splitting with a fixed ratio of 0.7:0.1:0.2 to prevent information leakage from future observations. This corresponds to 24,077/3440/6879 samples for LY and 24,414/3489/6975 samples for HG. Statistical summaries are provided in Table 2.
Table 2.
Statistical summary of key features in LY and HG datasets.
4.2. Baselines and Metrics
To ensure a rigorous and balanced comparison, we benchmark STFNet against both naïve statistical methods and advanced deep learning models:
- Naïve and Conventional Methods: To identify the lower bound of predictability and check for lag-oversmoothing issues, we include Persistence (Naïve-Per.), which directly uses the last observed value of the input window, like all future predictions, and Historical Average (Naïve-HA), which uses the mean of the input window. We also include GRU [12] as a conventional recurrent sequential model and DLinear [41] as a lightweight linear decomposition baseline.
- Advanced Deep Learning Models: To evaluate against state-of-the-art architectures, we compare with FEDformer [17] (frequency-enhanced Transformer), PatchTST [15] and 2DXformer [35] (Transformer-style long-term models), TimesNet [16] (convolutional multi-period model), and DUET [36] (specialized clustering-enhanced reference model).
We report MSE and MAE. MSE is sensitive to large deviations and is informative for risk-aware operational scenarios, while MAE reflects the average error magnitude and improves the interpretability of point-forecast accuracy.
4.3. Experimental Settings
To support reproducibility, all models are implemented and evaluated on a unified computational platform utilizing an NVIDIA RTX 3090 GPU. The primary software environment is built upon Python 3.9 and PyTorch 2.0+. All experiments use Adam optimization and MSE loss under a unified training protocol: fixed random-seed initialization (Python/Torch/NumPy), maximum 10 epochs, early stopping with patience of 5 based on the validation loss, and epoch-wise learning-rate adjustment. The input length is fixed to 96, and the forecasting horizons are 96, 192, 336, and 720 time steps.
Table 3 reports the final hyperparameter settings. Parameter selection follows a validation-oriented strategy: for STFNet, the learning rate and batch size are selected by validation stability and the final validation error on LY and HG; for baseline models, we adopt commonly used settings from official implementations or original papers with minimal adaptation to the prediction horizon and input/output dimensions.
Table 3.
Model-specific effective hyperparameters used in experiments.
The main hyperparameters and their roles are as follows. The learning rate controls the optimization step size, and the batch size controls the gradient-estimation variance and update stability. Width parameters (e.g., hidden_size or d_model) determine the representation capacity. Depth parameters (e.g., num_layers or e_layers) control the model hierarchy. In Transformer-style baselines, n_heads sets the number of parallel attention subspaces, and d_ff controls the hidden width of feed-forward sublayers. For TimesNet, top_k determines the number of dominant periods retained in frequency-guided temporal modeling.
4.4. Long-Term Time Series Forecasting
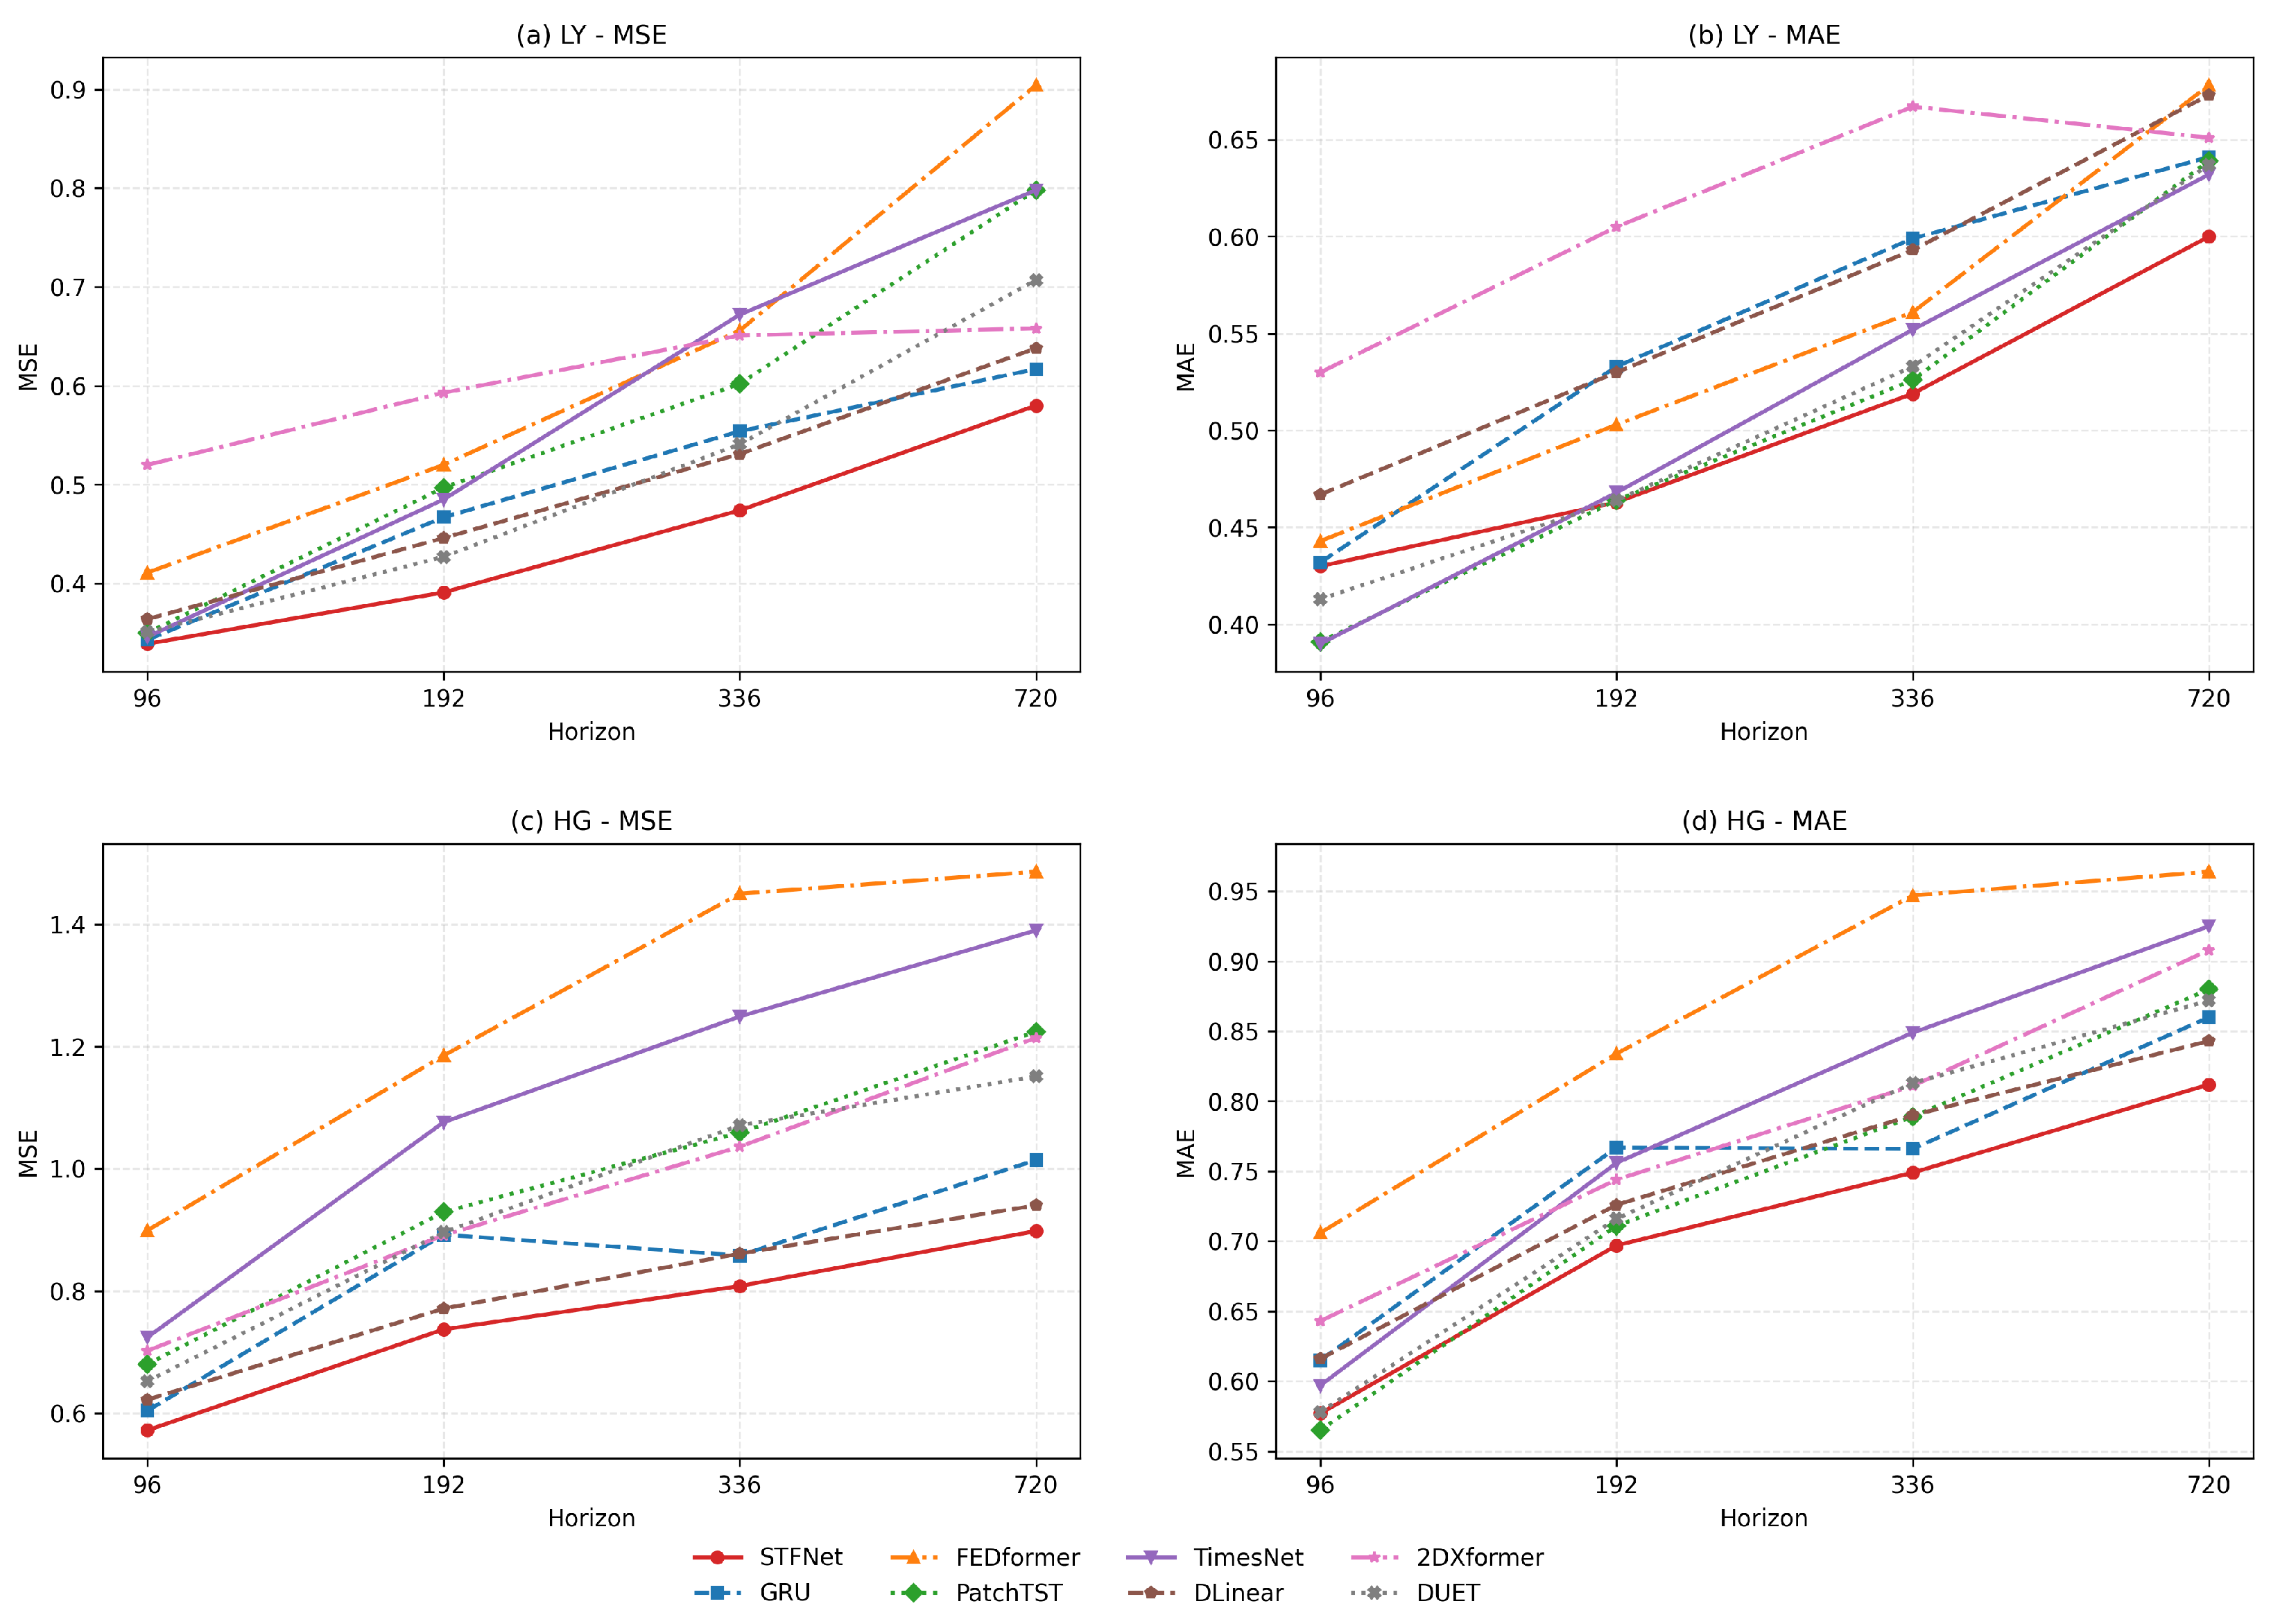
Table 4 reports long-term forecasting performance on LY and HG. For improved readability, the same metrics are also visualized in Figure 5. Across all horizons, STFNet achieves the lowest MSE among compared models on both datasets, indicating stable gains in long-term point forecasting. For MAE, STFNet attains 6 out of 8 best horizon-level results and remains close to the strongest competing methods in the remaining two settings. Improvements are more pronounced at 336 and 720 steps, consistent with the design objective of strengthening global periodic modeling while preserving local dynamics.
Table 4.
Metric-oriented comparison on LY and HG datasets. The method years are shown below the model names. For each row, the best value is shown in bold, and the second-best value is underlined.
Figure 5.
Line-chart presentation of the performance metrics in Table 4. Panels (a–d) show LY-MSE, LY-MAE, HG-MSE, and HG-MAE, respectively. The horizontal axis is the prediction horizon, and the vertical axis is the corresponding metric value. All the plotted values are directly mapped from Table 4.
Compared with PatchTST, STFNet reduces MSE on LY by 3.1%, 21.4%, 21.3%, and 27.3% at horizons 96/192/336/720, and on HG by 15.9%, 20.7%, 23.7%, and 26.6%, respectively. These patterns suggest that explicit time–frequency specialization is particularly beneficial when forecasting horizons increase. The time-domain branch contributes sensitivity to local ramps and lag-dependent variation, while the frequency-domain branch improves the extraction of periodic and trend components and reduces high-frequency disturbance. Their complementary interaction provides stronger robustness across both short-to-mid and long-term settings.
A rigorous comparison with naïve methods (Persistence and Historical Average) further highlights the necessity of advanced deep learning architectures for long-term wind power forecasting. While naïve statistical baselines exhibit marginally acceptable short-term pseudo-accuracies by relying heavily on the immediate preceding values or static statistics, their performance drops drastically as the forecasting horizon extends. For instance, on the LY dataset at horizon 720, the MSE of the Persistence method spikes to , whereas STFNet maintains a highly competitive metric of . This significant performance gap confirms that STFNet effectively captures genuine periodicity and non-stationary global dynamics, rather than superficially memorizing local historical noise.
4.5. Visualization of Forecasting Behavior
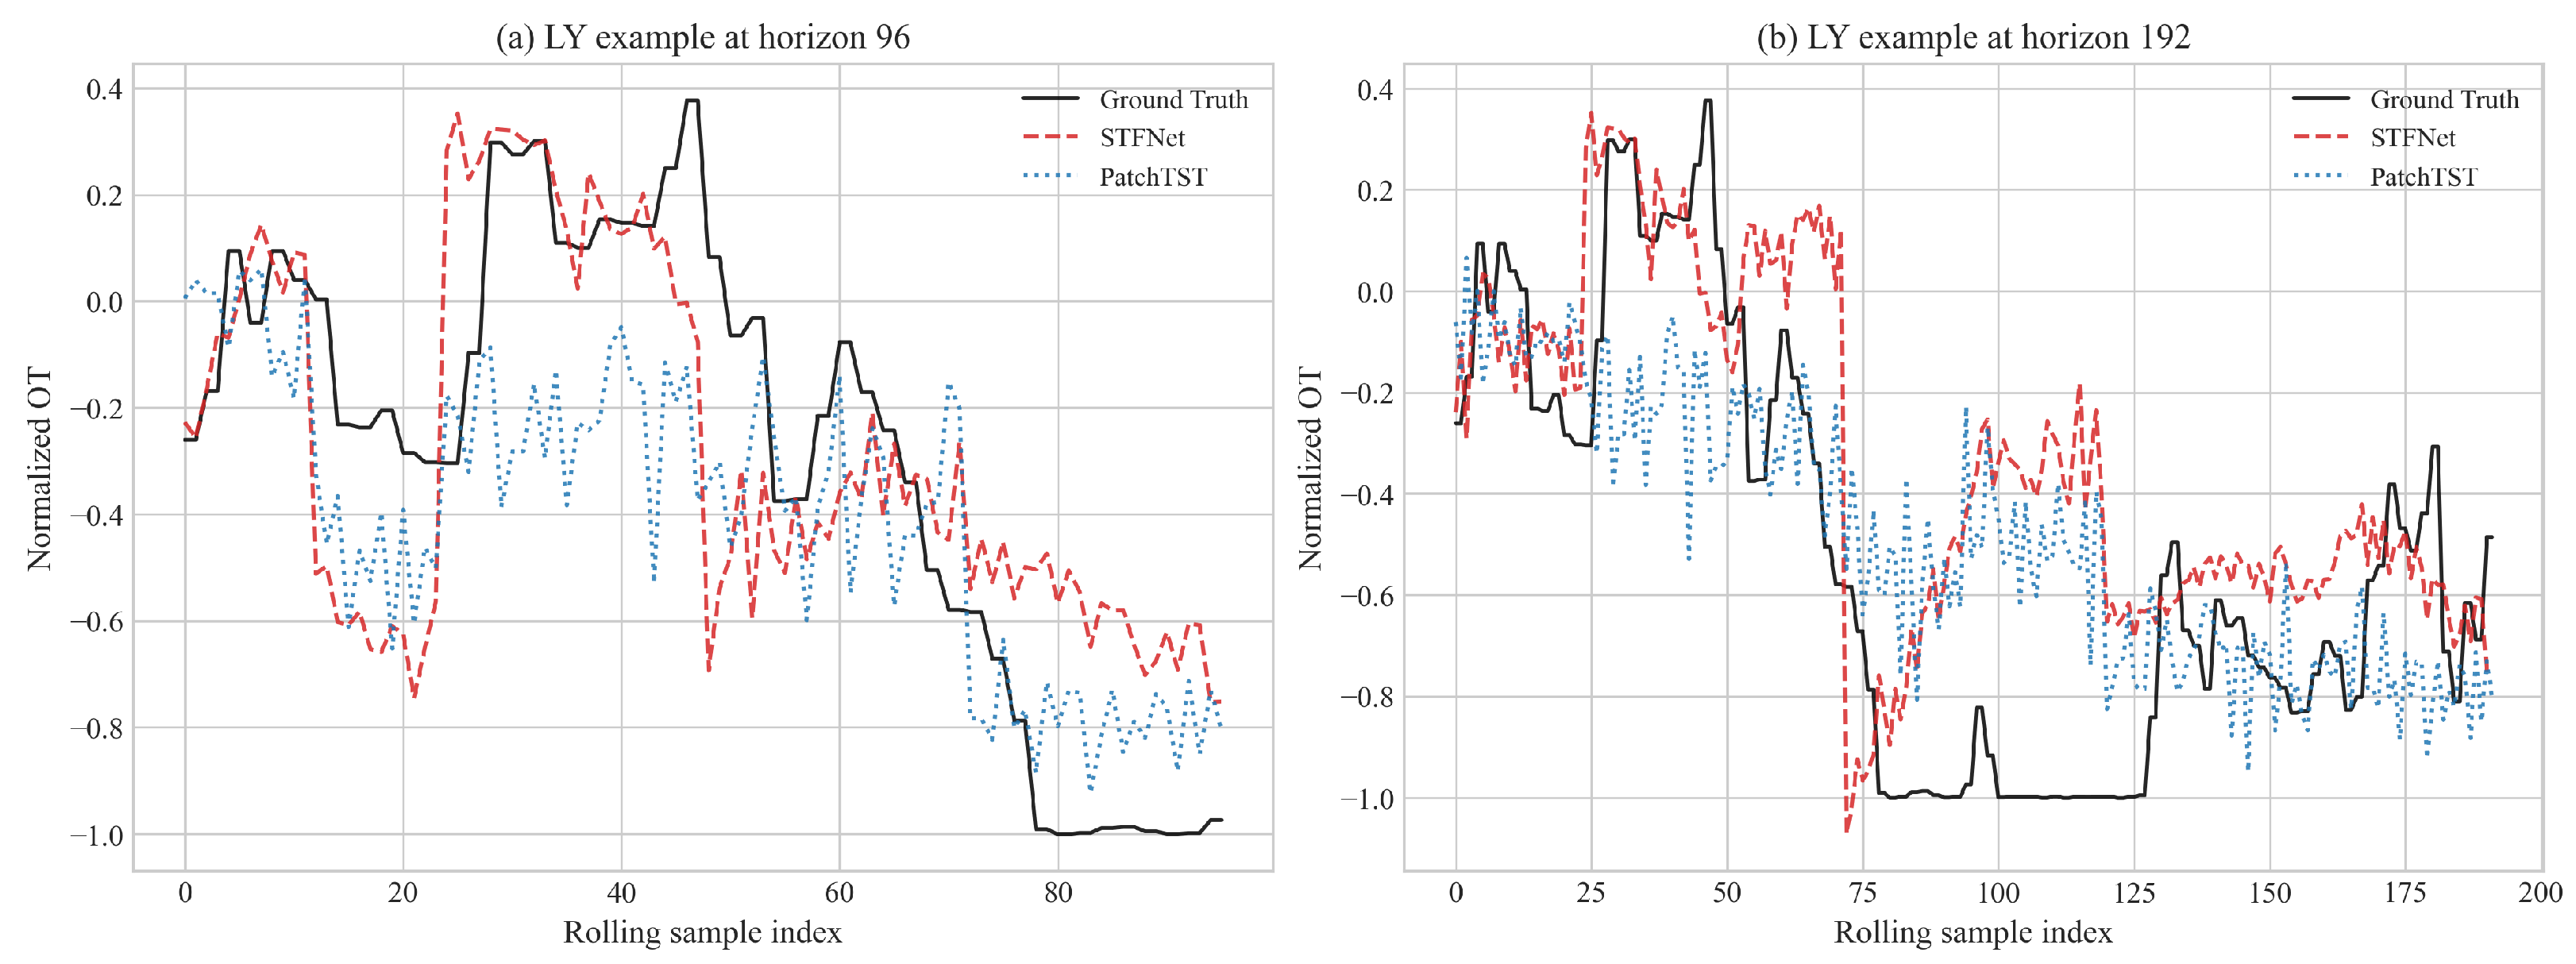
To complement aggregate metrics, we provide two visualization-based analyses on LY prediction outputs. Representative windows are selected from the test set by minimizing the discrepancy between the fluctuation levels of the historical input window and the corresponding ground-truth forecasting window, where the fluctuation level is quantified by the standard deviation of first-order differences. Figure 6 reports representative cases at horizons 96 and 192 for STFNet and PatchTST against the ground truth. Compared with PatchTST, STFNet exhibits closer trajectory alignment at local ramps and turning regions.
Figure 6.
Representative forecasting cases on LY. (a) Horizon 96. (b) Horizon 192. Test windows are selected according to historical–future fluctuation-level consistency in ground truth. Relative to PatchTST, STFNet provides closer local trajectory tracking around the ramp and turning segments.
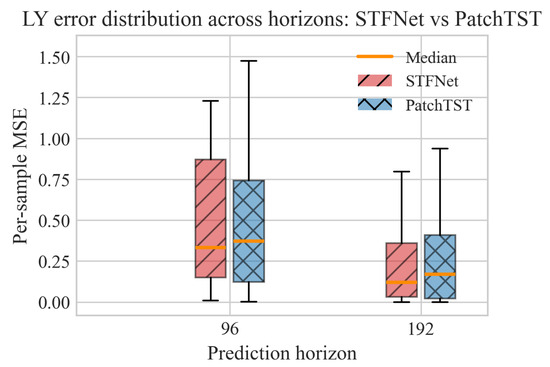
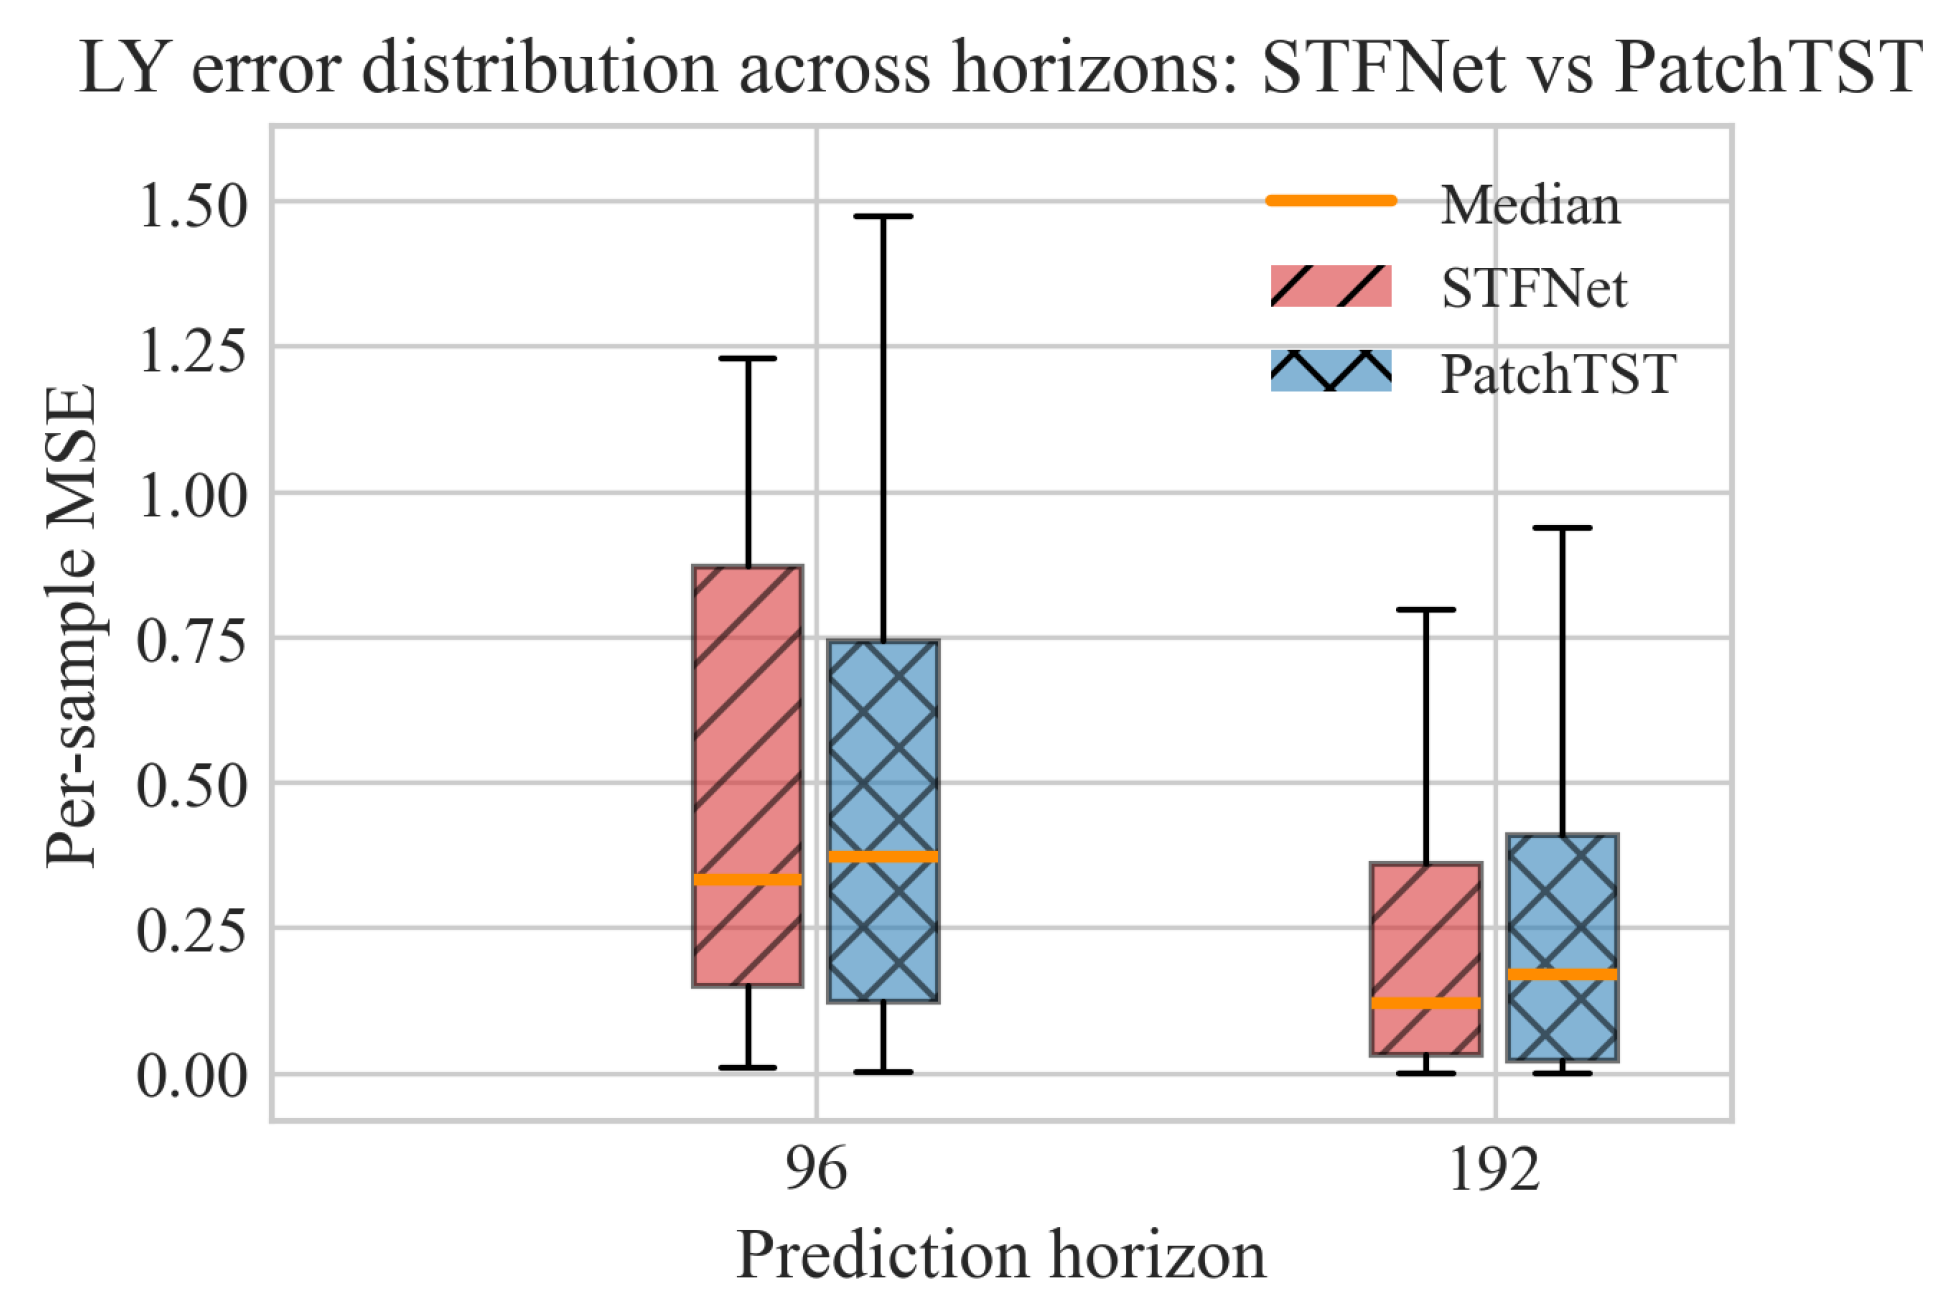
Figure 7 presents per-sample MSE distributions on LY for horizons 96 and 192. At both horizons, STFNet shows a lower median error and a narrower interquartile range than PatchTST, consistent with the ranking observed in aggregate evaluation metrics.
Figure 7.
Per-sample MSE distributions on LY at prediction horizons 96 and 192 (STFNet vs PatchTST). STFNet demonstrates a lower median error and reduced dispersion across both horizons.
4.6. Ablation Study
To assess the efficacy of each component in STFNet, we conduct full-horizon component ablations on LY by removing one module at a time while keeping all other settings unchanged. Table 5 reports MAE/MSE for prediction lengths of 96/192/336/720 and the relative change in MSE with respect to the baseline at each horizon.
Table 5.
Full ablation results on LY across multiple prediction lengths. The relative MSE is computed against the baseline at the same horizon.
The ablation sensitivity is horizon-dependent, but all three ablations consistently degrade forecasting performance relative to the baseline. At shorter horizons (96/192), removing MLFE causes larger degradation than removing FGFE, indicating the importance of local multi-scale temporal modeling for near-term forecasting. At longer horizons (336/720), removing FGFE causes the largest degradation (up to +8.50% MSE at 720). At the 336-step setting, the MSE degradation is +1.69% (w/o MLFE), +2.32% (w/o FGFE), and +1.05% (w/o Low-pass), showing that global frequency-domain modeling becomes increasingly critical as the prediction horizon grows.
4.7. Intervention-Based Validation of Specialization
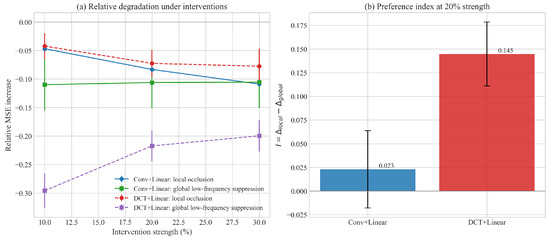
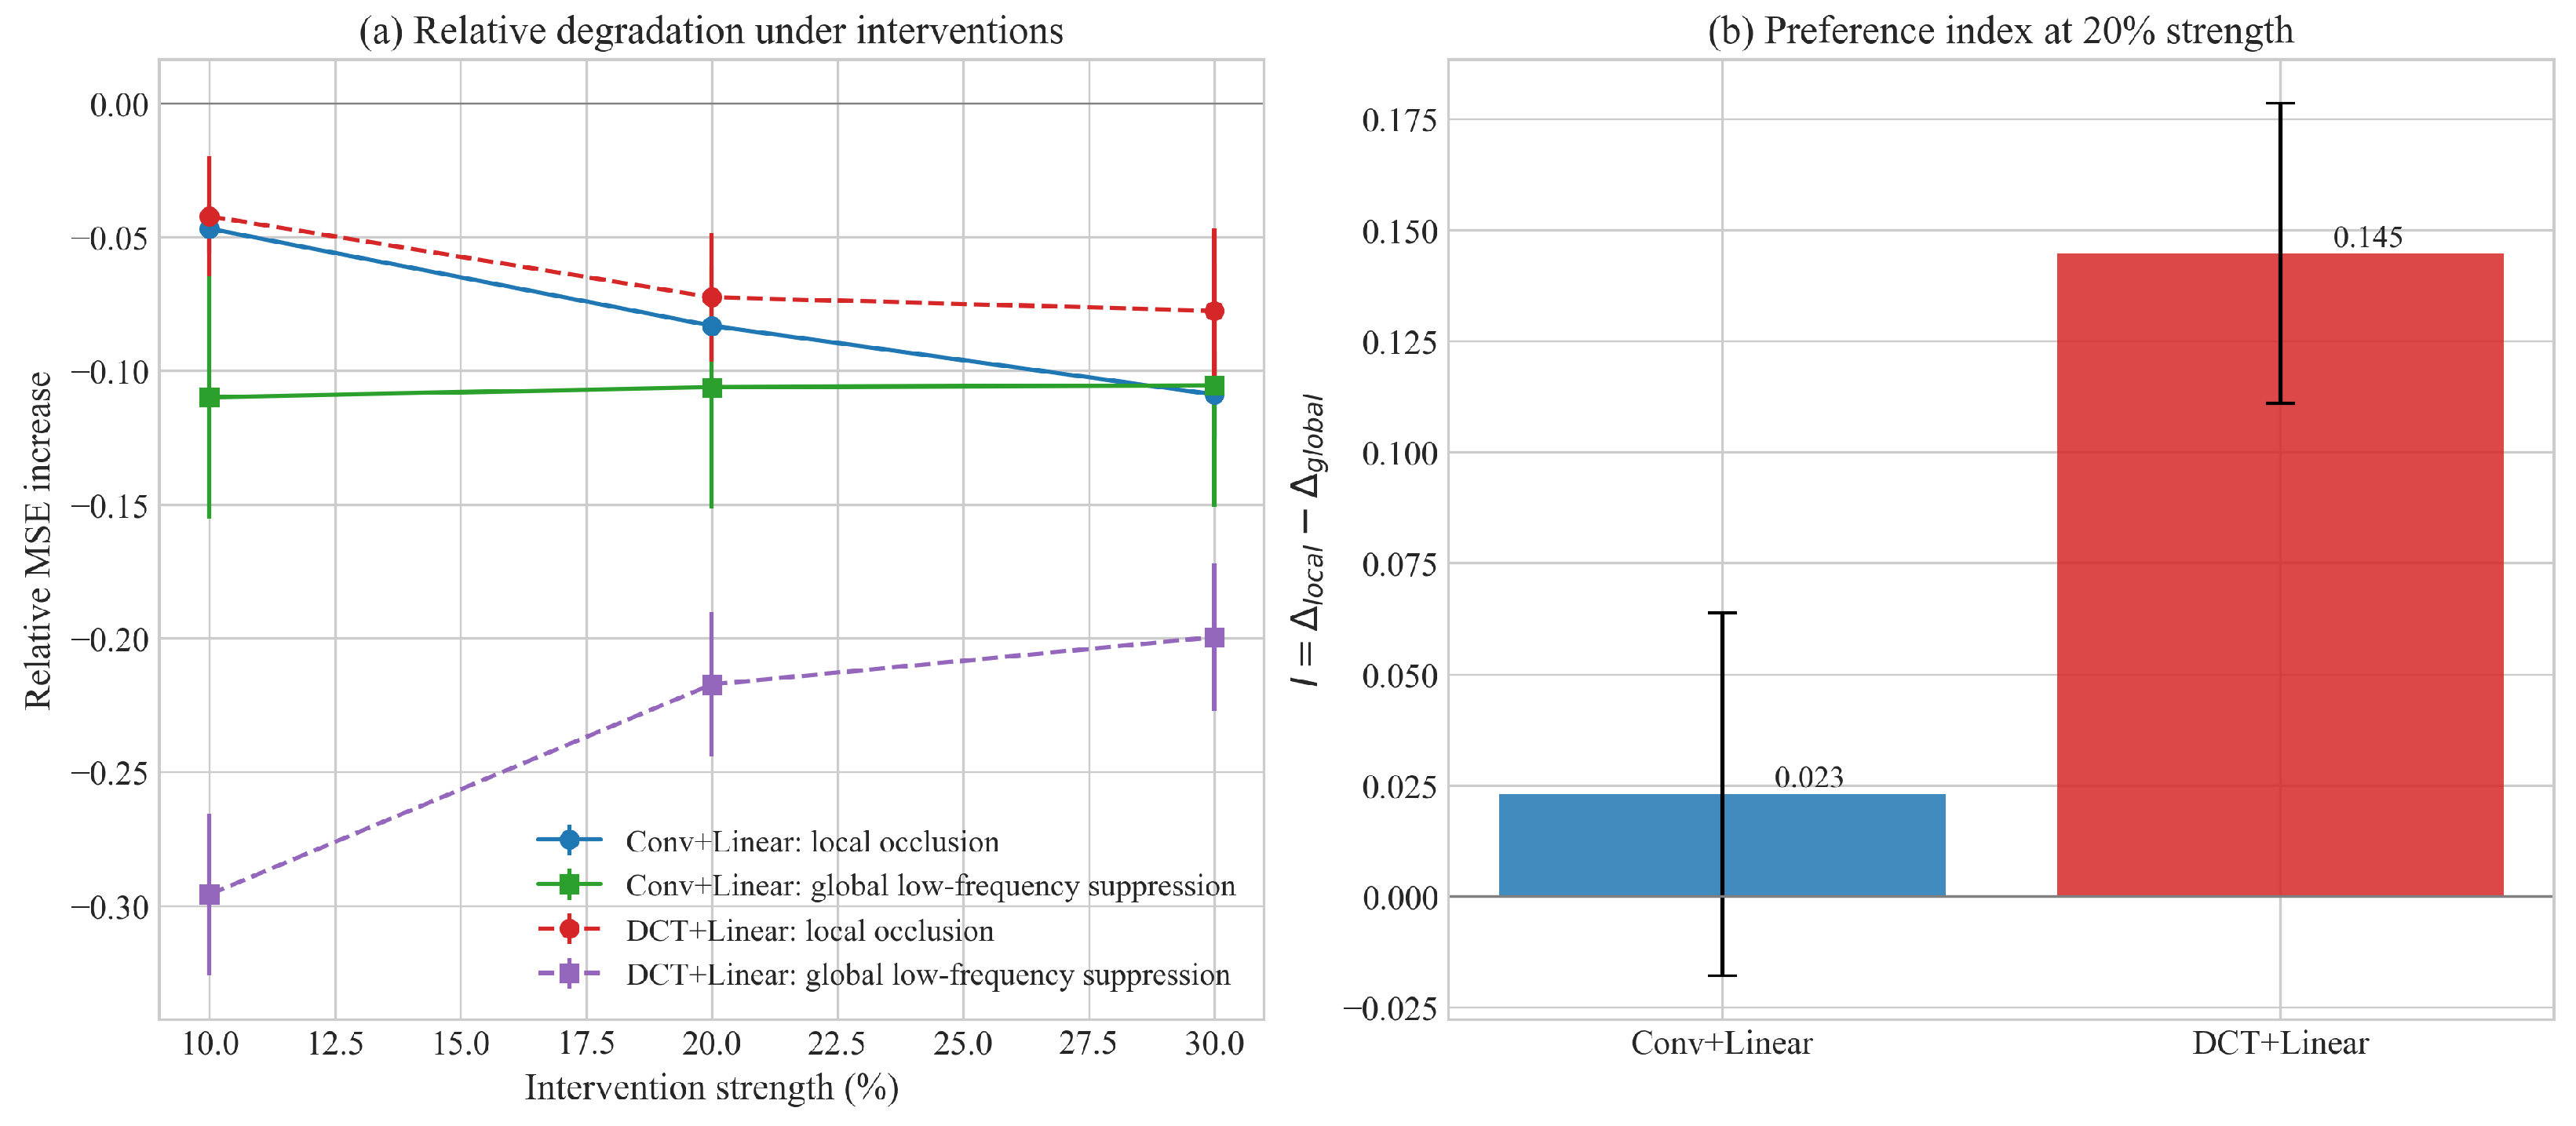
To provide intervention-based sensitivity evidence for local–global specialization, we conduct a perturbation analysis on the LY dataset. Two separately trained surrogate models (Conv+Linear and DCT+Linear) are tested under two controlled perturbations: local time-window occlusion and global low-frequency suppression. We measure the relative MSE degradation against the unperturbed baseline and define a preference index, . Under this unified metric, a larger positive I indicates a stronger local dependence, while a smaller (or negative) I indicates stronger global dependence.
Figure 8 shows that the Conv+Linear model is more sensitive to local occlusion, whereas the DCT+Linear model is more sensitive to global low-frequency suppression. To connect this evidence to the full STFNet model, we additionally use direct branch interventions in Table 5. Across all horizons, removing MLFE, FGFE, or adaptive low-pass filtering leads to performance degradation. The short-horizon degradation is more pronounced for w/o MLFE, while the long-horizon degradation is largest for w/o FGFE (up to +8.50% MSE at 720). This consistency supports the specialization design and confirms that both time-domain and frequency-domain components are beneficial.
Figure 8.
Intervention-based evidence on the LY dataset using two separately trained models (Conv+Linear and DCT+Linear). (a) Relative degradation curves under local occlusion and global low-frequency suppression with increasing intervention strength. (b) Preference index at 20% intervention strength, defined as . Positive values indicate stronger dependence on local information, while smaller values indicate stronger dependence on global information.
4.8. Model Analysis
To directly quantify and justify the complexity of the proposed method against the obtained accuracy, we benchmark STFNet against other baselines under a unified setting (LY dataset, input length 96, prediction length 336) on the same GPU. As reported in Table 6, we extend the conventional computational metrics with corresponding MSE and MAE values (mapped directly from Table 4) to evaluate the accuracy–complexity trade-off.
Table 6.
Computational efficiency comparison against forecasting accuracy under LY (96 → 336) setting. All models correspond to Table 4. The best values are shown in bold.
The results explicitly justify the architectural complexity introduced by STFNet’s dual-branch design. First, compared to extremely lightweight models like DLinear (0.391 M parameters) or GRU (0.411 M), STFNet requires moderately more parameters (2.502 M) and a slightly higher inference time (0.038 ms vs. 0.016 ms for DLinear). However, this operational overhead is completely justified by a substantial performance enhancement: STFNet reduces the long-term MSE by approximately 10.7% over DLinear (0.474 vs. 0.531) and 14.4% over GRU (0.474 vs. 0.554), demonstrating that handling non-stationary wind power dynamics inherently requires a certain level of model capacity.
Second, when compared to computationally heavy Transformer-based models, STFNet is highly efficient. For instance, PatchTST demands over three times the parameters (8.379 M) and requires nearly the inference latency (0.098 ms) to achieve an MSE of 0.602, falling far behind STFNet’s 0.474. Similarly, FEDformer exhibits massive training delays (1.657 min/epoch) without yielding competitive long-term accuracy (MSE: 0.656).
Overall, these quantified comparisons confirm that STFNet achieves an optimal Pareto frontier across parameter footprint, runtime latency, and predictive precision. The specific inclusion of both multi-scale convolutions and frequency adaptations provides a justified and efficient utilization of computational resources, converting acceptable structural complexity into state-of-the-art long-term accuracy.
4.9. Discussion and Practical Implications
The experimental results demonstrate that STFNet provides robust and superior long-term forecasting capabilities, particularly exhibiting substantial reductions in MSE at extended horizons (e.g., 336 and 720 steps). Beyond the quantitative gains, the performance of STFNet offers several fundamental insights into the nature of wind power time series forecasting.
Interpretation of the Dual-Branch Mechanism. Wind power generation is inherently driven by two distinct forces: the stable, long-cycle macroscopic meteorological periodicities (e.g., diurnal and seasonal variations) and the volatile, short-term microscopic turbulent fluctuations (e.g., wind gusts). The superiority of STFNet stems from its architectural alignment with these physical characteristics. While the existing end-to-end models often struggle to balance these conflicting patterns, STFNet’s explicit decoupling strategy provides a strong inductive bias. The Multi-Scale Local Feature Extraction (MLFE) module effectively acts as a time-domain feature tracker, capturing local ramp events and transient variations down to the step level. Meanwhile, the Frequency-domain Global Feature Extraction (FGFE) module leverages the energy-compaction property of the Discrete Cosine Transform (DCT) to filter out high-frequency noise, retaining only the dominant low-frequency harmonics that dictate the future global trend. Our ablation studies confirm that neither branch alone is sufficient for long-term forecasting; it is their synergistic fusion that prevents the model from either generating overly smoothed predictions (a common flaw of pure frequency-domain models) or overfitting to historical noise (a typical issue for pure time-domain models).
Contextualization with State-of-the-Art Baselines. The comparative results highlight the limitations of current dominant architectures when applied strictly to wind power. Lightweight linear models like DLinear process the sequence as a whole, which is highly efficient but fails to capture the complex, non-linear local interactions essential for detecting wind power ramps. On the other end of the spectrum, self-attention-based models like PatchTST and FEDformer exhibit high theoretical capacity but are prone to overfitting the high-frequency stochasticity inherent in wind data. Specifically, PatchTST’s patching mechanism, while successful in general multivariate forecasting, risks disrupting the continuous localized spectral properties of wind power. STFNet navigates this trade-off by achieving accuracy superior to heavy Transformer-based models while maintaining an inference efficiency comparable to lightweight linear models, placing it on the Pareto frontier of accuracy and computational cost.
Practical Implications for Grid Integration. From an industrial application perspective, accurate long-term wind power forecasting (e.g., 24 to 96 h ahead) is critical for day-ahead energy market bidding, reserve capacity allocation, and the reliable scheduling of power grids. STFNet’s proficiency in long-term horizons directly facilitates more proactive and reliable grid dispatching. Furthermore, as demonstrated in our model analysis, STFNet maintains a modest parameter count and low inference latency compared to large-scale architectures. This computational efficiency is particularly advantageous in real-world deployments where models must be frequently retrained to adapt to seasonal concept drifts or deployed directly on resource-constrained edge computing devices at individual wind farms.
Despite these advantages, the successful deployment of practically data-driven models is not without challenges. The model fundamentally relies on learning statistical mappings from historical data, which implies that performance may degrade when encountering unprecedented extreme weather events or when the input data represents persistent missing values. Future research should prioritize integrating physical meteorological priors (such as NWP data) and developing robust spatial–temporal imputation architectures to further enhance the model’s reliability in extreme industrial scenarios.
5. Conclusions
This paper introduces STFNet, a specialized time-frequency dual-branch neural network designed to address the intricate challenge of long-term wind power forecasting, where local high-frequency volatility and global low-frequency periodicity heavily intertwine. By explicitly decoupling the feature extraction process, STFNet utilizes the Multi-Scale Local Feature Extraction (MLFE) module to process lag-sensitive dynamics in the time domain, while employing the Frequency-Domain Global Feature Extraction (FGFE) module with Discrete Cosine Transform (DCT) to model long-cycle spectral regularities.
Extensive evaluations on two real-world wind farm datasets (LY and HG) demonstrate the superiority of the proposed architecture. STFNet consistently outperforms the existing state-of-the-art advanced deep learning models (such as PatchTST and DUET), as well as conventional and naïve baselines, particularly yielding substantial MSE reductions at extended forecasting horizons (e.g., 336 and 720 steps). These quantitative achievements highlight the model’s robust predictive stability and its capability to capture genuine periodic trends, rather than overfitting to local historical noise.
The performance gains are rooted in the explicit domain specialization mechanism validated by our ablation and intervention studies. In the time domain, the combination of parallel multi-scale convolutions and difference convolutions collectively perceives both fine-grained temporal local variations and critical rate-of-change information. Concurrently, the frequency domain’s adaptive low-pass filter effectively isolates predictive long-cycle components from high-frequency meteorological noise. Together, this unified framework offers a reliable point-forecasting tool for practical wind farm operation and grid dispatch.
Despite these encouraging results, this study involved several limitations that direct future research. First, because STFNet fundamentally extrapolates patterns from historical observational windows, it remains inherently restricted in accurately predicting unprecedented sudden meteorological mutations and extreme wind power ramps that lack precursor signals in the immediate past. Second, the model’s performance relies on relatively clean inputs; however, real-world wind power datasets inevitably contain a considerable proportion of missing values and anomalous readings, which can disrupt both time-domain convolutions and frequency-domain transformations. Therefore, our future work will primarily focus on two directions: (1) integrating Numerical Weather Prediction (NWP) data or physical meteorological priors to enhance the anticipatory capability for sudden mutations, and (2) developing robust, anomaly-resilient learning mechanisms and integrated data imputation strategies to improve the model’s tolerance to raw, low-quality industrial data. Furthermore, extending the current architecture to probabilistic forecasting to quantify the uncertainty of extreme events will also be a valuable pursuit.
Author Contributions
Conceptualization, T.D., Y.C. and X.H.; methodology, T.D.; software, T.D.; validation, T.D., X.H., Y.C., R.L., J.S., R.J. and Y.Q.; formal analysis, T.D., Y.C. and X.H.; investigation, T.D.; resources, Y.C., X.H. and Y.Q.; data curation, R.L., J.S. and R.J.; writing—original draft preparation, T.D.; writing—review and editing, T.D., X.H., Y.C., R.L., J.S., R.J. and Y.Q.; visualization, T.D.; supervision, Y.C. and X.H.; project administration, Y.C. and X.H.; funding acquisition, Y.C. and X.H. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the National Natural Science Foundation of China (No. 72461001), the Guangxi Scientific and Technological Achievements Transformation Plan–ZHIGUO Action (No. ZG2503980048), the Guangxi Natural Science Foundation (No. 2025GXNSFAA069957), and the Open Project Program of Guangxi Key Laboratory of Digital Infrastructure (No. GXDINBC202501).
Data Availability Statement
The LY dataset is publicly available at https://aistudio.baidu.com/datasetdetail/205286 (accessed on 25 October 2025) (file: 01.csv). The HG dataset is proprietary real-world wind farm data from Guangxi, China, and is available from the corresponding author upon reasonable request.
Acknowledgments
During the preparation of this work, the authors used ChatGPT (gpt-5-codex) in order to polish the English language and organize the reference list. After using this tool, the authors reviewed and edited the content as needed and take full responsibility for the content of the publication.
Conflicts of Interest
Author Yiming Qin was employed by the company Guangxi Power Grid. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| STFNet | Specialized Time-Frequency Network |
| MLFE | Multi-Scale Local Feature Extraction |
| FGFE | Frequency-Domain Global Feature Extraction |
| DCT | Discrete Cosine Transform |
| FFT | Fast Fourier Transform |
| NWP | Numerical Weather Prediction |
References
- GWEC. Global Wind Report 2024; Technical Report; Global Wind Energy Council: Brussels, Belgium, 2024. [Google Scholar]
- GWEC. Global Wind Energy Council Annual Report 2023; Technical Report; Global Wind Energy Council: Brussels, Belgium, 2023. [Google Scholar]
- Milan, P.; Wächter, M.; Peinke, J. Turbulent character of wind energy. Phys. Rev. Lett. 2013, 110, 138701. [Google Scholar] [CrossRef] [Scilit]
- Pinson, P. Wind energy: Forecasting challenges for its operational management. Stat. Sci. 2013, 28, 564–585. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; Zhou, J.; Chen, B. Review of wind power scenario generation methods for optimal operation of renewable energy systems. Appl. Energy 2020, 280, 115992. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Guo, H.; Zhang, Y.; Zuo, Z. A comprehensive review of wind power prediction based on machine learning: Models, applications, and challenges. Energies 2025, 18, 350. [Google Scholar] [CrossRef] [Scilit]
- Al-Yahyai, S.; Charabi, Y.; Gastli, A. Review of the use of Numerical Weather Prediction (NWP) Models for wind energy assessment. Renew. Sustain. Energy Rev. 2010, 14, 3192–3198. [Google Scholar] [CrossRef] [Scilit]
- Barque, M.; Martin, S.; Vianin, J.E.N.; Genoud, D.; Wannier, D. Improving wind power prediction with retraining machine learning algorithms. In Proceedings of the 2018 International Workshop on Big Data and Information Security (IWBIS); IEEE: Piscataway, NJ, USA, 2018; pp. 43–48. [Google Scholar]
- Box, G.E.; Jenkins, G.M.; Reinsel, G.C.; Ljung, G.M. Time Series Analysis: Forecasting and Control, 5th ed.; John Wiley & Sons: Hoboken, NJ, USA, 2015. [Google Scholar]
- Taylor, J.W. Short-term electricity demand forecasting using double seasonal exponential smoothing. J. Oper. Res. Soc. 2003, 54, 799–805. [Google Scholar] [CrossRef] [Scilit]
- Hochreiter, S.; Schmidhuber, J. Long short-term memory. Neural Comput. 1997, 9, 1735–1780. [Google Scholar] [CrossRef] [Scilit]
- Cho, K.; Van Merriënboer, B.; Bahdanau, D.; Bengio, Y. On the properties of neural machine translation: Encoder-decoder approaches. In Proceedings of the SSST-8 Workshop on Syntax, Semantics and Structure in Statistical Translation; ACL: Stroudsburg, PA, USA, 2014; pp. 103–111. [Google Scholar] [CrossRef] [Scilit]
- Zhou, H.; Zhang, S.; Peng, J.; Zhang, S.; Li, J.; Xiong, H.; Zhang, W. Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting. In Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), Virtually, 2–9 February 2021; pp. 11106–11115. [Google Scholar] [CrossRef] [Scilit]
- Wu, H.; Xu, J.; Wang, J.; Long, M. Autoformer: Decomposition transformers with auto-correlation for long-term series forecasting. Adv. Neural Inf. Process. Syst. (NeurIPS) 2021, 34, 22419–22430. [Google Scholar]
- Nie, Y.; Nguyen, N.H.; Sinthong, P.; Kalagnanam, J. A Time Series is Worth 64 Words: Long-term Forecasting with Transformers. In Proceedings of the International Conference on Learning Representations, Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Wu, H.; Xu, T.; Liu, H.; Long, G.; Dong, J.; Zhang, Y.; Zhu, Z. TimesNet: Temporal 2D-Variation Modeling for General Time Series Analysis. In Proceedings of the International Conference on Learning Representations, Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Zhou, T.; Ma, Z.; Wen, Q.; Wang, X.; Sun, L.; Jin, R. FEDformer: Frequency Enhanced Decomposed Transformer for Long-Term Series Forecasting. In Proceedings of the International Conference on Machine Learning (ICML), Baltimore, MD, USA, 17–23 July 2022; pp. 27268–27282. [Google Scholar]
- Yue, W.; Liu, Y.; Ying, X.; Xing, B.; Guo, R.; Shi, J. Freeformer: Frequency enhanced transformer for multivariate time series forecasting. arXiv 2025, arXiv:2501.13989. [Google Scholar] [CrossRef] [Scilit]
- Cao, D.; Lu, Y.; Wang, J.; Wang, J.; Tan, K.; Yang, Y. Spectral Temporal Graph Neural Network for Multivariate Time-Series Forecasting. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Virtual, 6–12 December 2020; pp. 19377–19388. [Google Scholar]
- Oreshkin, B.N.; Carpov, D.; Chapados, N.; Bengio, Y. N-BEATS: Neural Basis Expansion Analysis for Interpretable Time Series Forecasting. In Proceedings of the International Conference on Learning Representations (ICLR), Addis Ababa, Ethiopia, 30 April 2020. [Google Scholar]
- Lipu, M.S.H.; Miah, M.S.; Hannan, M.A.; Hussain, A.; Sarker, M.R.; Ayob, A.; Saad, M.H.M.; Mahmud, M.S. Artificial Intelligence Based Hybrid Forecasting Approaches for Wind Power Generation: Progress, Challenges and Prospects. IEEE Access 2021, 9, 102460–102489. [Google Scholar] [CrossRef] [Scilit]
- Bai, L.; Pinson, P. Distributed Reconciliation in Day-Ahead Wind Power Forecasting. Energies 2019, 12, 1112. [Google Scholar] [CrossRef] [Scilit]
- Konstantinou, T.; Hatziargyriou, N. Regional Wind Power Forecasting Based on Bayesian Feature Selection. IEEE Trans. Power Syst. 2025, 40, 113–124. [Google Scholar] [CrossRef] [Scilit]
- Cai, X.; Zhou, Y.; Wang, Z.; Lei, X.; Jia, Y. Regional wind power forecasting guided by physics-based wind field modeling and image fusion. Electr. Power Syst. Res. 2026, 253, 112527. [Google Scholar] [CrossRef] [Scilit]
- Arrieta-Prieto, M.; Schell, K.R. Spatio-temporal probabilistic forecasting of wind power for multiple farms: A copula-based hybrid model. Int. J. Forecast. 2022, 38, 300–320. [Google Scholar] [CrossRef] [Scilit]
- Dantas, G.; Browell, J. Seamless Short- to Mid-Term Probabilistic Wind Power Forecasting. Wind Energy 2025, 29, e70079. [Google Scholar] [CrossRef] [Scilit]
- Lin, Z.; Liu, X. Wind power forecasting of an offshore wind turbine based on high-frequency SCADA data and deep learning neural network. Energy 2020, 201, 117693. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y. TSG-Net: A Multiscale Decomposition and Spatio-Temporal Graph Neural Network Framework for High-Precision Wind Power Forecasting. Wind Energy 2026, 29, e70100. [Google Scholar] [CrossRef] [Scilit]
- Banik, R.; Biswas, A. Interpretable wind power forecasting with residual learning-based model. Electr. Power Syst. Res. 2025, 247, 111824. [Google Scholar] [CrossRef] [Scilit]
- Han, L.; Qiao, Y.; Li, M.; Shi, L. Wind Power Ramp Event Forecasting Based on Feature Extraction and Deep Learning. Energies 2020, 13, 6449. [Google Scholar] [CrossRef] [Scilit]
- Han, L.; Pinson, P.; Kazempour, J. Trading data for wind power forecasting: A regression market with lasso regularization. Electr. Power Syst. Res. 2022, 212, 108442. [Google Scholar] [CrossRef] [Scilit]
- Ghasvarian Jahromi, K.; Gharavian, D.; Mahdiani, H.R. Wind power prediction based on wind speed forecast using hidden Markov model. J. Forecast. 2023, 42, 101–123. [Google Scholar] [CrossRef] [Scilit]
- Manero, J.; Béjar, J.; Cortés, U. “Dust in the Wind…”, Deep Learning Application to Wind Energy Time Series Forecasting. Energies 2019, 12, 2385. [Google Scholar] [CrossRef] [Scilit]
- Hanifi, S.; Lotfian, S.; Zare-Behtash, H.; Cammarano, A. Offshore Wind Power Forecasting—A New Hyperparameter Optimisation Algorithm for Deep Learning Models. Energies 2022, 15, 6919. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Jiang, J.; Yan, Y.; Yang, L.; Zhang, P. 2DXformer: Dual Transformers for Wind Power Forecasting with Dual Exogenous Variables. arXiv 2025, arXiv:2505.01286. [Google Scholar] [CrossRef] [Scilit]
- Qiu, X.; Wu, X.; Lin, Y.; Guo, C.; Hu, J.; Yang, B. DUET: Dual Clustering Enhanced Multivariate Time Series Forecasting. In Proceedings of the SIGKDD, Toronto, ON, Canada, 3–7 August 2025; pp. 1185–1196. [Google Scholar]
- Li, S.; Jin, X.; Xuan, Y.; Zhou, X.; Chen, W.; Wang, Y.X.; Yan, X. Enhancing the Locality and Breaking the Memory Bottleneck of Transformer on Time Series Forecasting. In Proceedings of the Advances in Neural Information Processing Systems; ACM: New York, NY, USA, 2019; Volume 32, pp. 5005–5015. [Google Scholar]
- Bai, S.; Kolter, J.Z.; Koltun, V. An Empirical Evaluation of Generic Convolutional and Recurrent Networks for Sequence Modeling. arXiv 2018, arXiv:1803.01271. [Google Scholar] [CrossRef] [Scilit]
- van den Oord, A.; Dieleman, S.; Zen, H.; Simonyan, K.; Vinyals, O.; Graves, A.; Kalchbrenner, N.; Senior, A.W.; Kavukcuoglu, K. WaveNet: A Generative Model for Raw Audio. In Proceedings of the Speech Synthesis Workshop, Sunnyvale, CA, USA, 13–15 September 2016. [Google Scholar]
- Wang, H.; Peng, J.; Huang, F.; Wang, J.; Chen, J.; Xiao, Y. MICN: Multi-scale Local and Global Context Modeling for Long-term Series Forecasting. In Proceedings of the International Conference on Learning Representations, Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Zeng, A.; Chen, M.; Zhang, L.; Xu, Q. Are Transformers Effective for Time Series Forecasting? In Proceedings of the AAAI Conference on Artificial Intelligence, Washington, DC, USA, 7–14 February 2023; Volume 37, pp. 11121–11128. [Google Scholar] [CrossRef] [Scilit]
- Zhang, L.; Aggarwal, C.; Qi, G.J. Stock Price Prediction via Discovering Multi-Frequency Trading Patterns. In Proceedings of the 23rd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, KDD ’17, Halifax, NS, Canada, 13–17 August 2017; pp. 2141–2149. [Google Scholar] [CrossRef] [Scilit]
- Moosavi, V. A Wavelet-ANFIS Hybrid Model for Groundwater Level Forecasting for Different Prediction Periods. Water Resour. Manag. 2013, 27, 1301–1321. [Google Scholar] [CrossRef] [Scilit]
- Chen, P.; Zhang, Y.; Cheng, Y.; Shu, Y.; Wang, Y.; Wen, Q.; Yang, B.; Guo, C. Pathformer: Multi-scale Transformers with Adaptive Pathways for Time Series Forecasting. In Proceedings of the International Conference on Learning Representations (ICLR), Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Ye, H.; Chen, J.; Gong, S.; Jiang, F.; Zhang, T.; Chen, J.; Gao, X. Atfnet: Adaptive time-frequency ensembled network for long-term time series forecasting. arXiv 2024, arXiv:2404.05192. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.