


Abstract
This paper focuses on a neural adaptive sliding-mode control scheme for a class of uncertain nonlinear systems subject to external disturbances by the aid of adaptive dynamic programming (ADP). First, by combining the neural network (NN) approximation method with a nonlinear disturbance observer, an enhanced observer framework is developed for estimating the system uncertainties and observing the external disturbances simultaneously. Then, based on the reliable estimations provided by the enhanced observer, an adaptive sliding-mode controller is meticulously designed, which can effectively counteract the effects of the system uncertainties and the separated matched disturbances, even in the absence of prior knowledge regarding their upper bounds. While the remaining unmatched disturbances are attenuated by means of control performance on the sliding surface. Moreover, a single critic network-based ADP algorithm is employed to learn the cost function related to the Hamilton–Jacobi–Isaacs equation, and thus, the optimal control is obtained. An updated law for the critic NN is proposed not only to make the Nash equilibrium achieved, but also to stabilize the sliding-mode dynamics without the need for an initial stabilizing control. In addition, we analyze the uniform ultimate boundedness stability of the resultant closed-loop system via Lyapunov’s method. Finally, the effectiveness of the proposed scheme is verified through simulations of a single-link robot arm and a power system.
1. Introduction
Within the last few decades, multifarious robust control design theories and methods have been proposed for uncertain nonlinear systems [1]. As one of the most efficient and widely used control methods, sliding-mode control (SMC) has garnered significant attention by reason of its simplicity, order reduction and inherent robustness against the matched uncertainties [2]. The classical SMC approach is to exert a discontinuous control to drive the system states onto a prescribed sliding manifold or surface [3]. As long as the sliding surface is reached, the system will become immune from the matched uncertainties and input disturbances. To remove the reaching phase, an integral SMC was developed by using the integral sliding manifold, including an integral term, which can enable the system states to reach and remain on the sliding manifold from the beginning [4,5,6]. Although towards a wide variety of actual systems, the relevant uncertainties and disturbances can be assumed to be matched in the design of control systems, there are also many physical systems, such as permanent magnet synchronous motors [7], underactuated aerial vehicles and robotic systems [8] directly affected by unmatched disturbances. Lately, several new approaches involving the integral SMC have been proposed to stabilize various systems with unmatched disturbances [9,10,11,12,13]. Among these methods, it is worth noticing that in [12,13], the impact of the separated unmatched disturbances would not be amplified after choosing a suitable projection matrix in a sliding manifold and were attenuated by the combination of the integral SMC with control theories. This provides a feasible and effective way to handle the unmatched disturbances and helps explore the relationships between integral SMC and control in nonlinear system control design.
In many instances, we expect the control policy not just to make the closed-loop system stable, but to possess certain optimality by minimizing the user-defined cost. For nonlinear systems, the settlement of associated optimal control problems requires solving the Hamilton–Jacobi–Bellman (HJB) equation. While considering optimal control, based on the dissipativity theory, it can be formulated as an -gain control problem, which involves solving the Hamilton–Jacobi–Isaacs (HJI) equation [14]. However, the analytical solutions of both HJB and HJI equations are very hard or even impossible to obtain directly because of their inherent nonlinearities [15]. In recent years, a class of neural network (NN) and reinforcement learning (RL)-based intelligent optimization and control methods, referred to as adaptive dynamic programming (ADP), is becoming more and more striking and shows great application potential in solving various optimization problems, and effectively conquers the “curse of dimensionality” [15,16]. By now, many researchers have employed ADP to tackle a variety of optimal control problems for both discrete-time (DT) [17,18,19,20,21,22] and continuous-time (CT) systems [23,24,25,26,27,28]. Moreover, how to combine ADP with other robust methods to achieve better performance and stronger robustness for uncertain nonlinear systems is becoming a new research focus [29,30].
Recently, Modares et al. [31] proposed an online integral RL algorithm that incorporates a non-quadratic discounted cost function to address the constrained-input optimal tracking problem. Luo et al. [32] described an NN-based off-policy learning algorithm within the actor-critic framework to deal with the associated HJI equation, and this algorithm was later extended to find the near-optimal tracking control solution in [33]. Nevertheless, the influences of potential system or modeling uncertainties were not taken into account in the design. Wang et al. [34] introduced a robust neuro-optimal control approach for input-affine nonlinear systems with both matched and state-depended uncertainties. They achieved this by redesigning the cost function and selecting a suitable feedback gain, whereas the upper bound function of uncertainties is needed for redesigning the cost function to suppress these uncertainties. Mitra et al. [35] presented an optimal SMC scheme for the single-input cascade nonlinear systems with matched bounded disturbances. Fan et al. [36] investigated an adaptive actor–critic-based integral SMC strategy for CT nonlinear systems with unknown terms and input disturbances, where the initial stabilizing control requirement in the learning was quite stringent and limiting in practical applications. Qu et al. [37] developed an adaptive optimal SMC method in the presence of actuator faults and unmatched disturbances using the ADP algorithm, and further explored the optimal guaranteed cost SMC for constrained-input uncertain systems by formulating an auxiliary system and redefining the utility function [38]. Based on [37], combined with event-triggered mechanisms, Yang et al. [39] provided an event-triggered integral SMC design for nonlinear control-affine systems by leveraging the ADP technique. Note that these methods mentioned above rely on the availability of upper bounds for matched or unmatched disturbances, which may cause over-design and thus leads to an over-conservative control scheme. Additionally, in real-world scenarios, determining precise upper bounds of external disturbances is often a challenging task.
Inspired by the works mentioned earlier, we propose an adaptive neural SMC scheme for uncertain nonlinear systems subject to external disturbances using the ADP algorithm. Based on the enhanced observer system composed of the NN identifier and nonlinear disturbance observer (DO), an integral SMC is developed to counteract the impacts of the system uncertainties and the separated matched disturbances, as well as unknown approximation errors, without requiring prior knowledge of their upper bounds. While on the sliding manifold, the remaining unmatched disturbances are attenuated by optimal control solved by the single-network ADP algorithm. Moreover, the uniform ultimate boundedness stability of the resultant closed-loop system are guaranteed via the Lyapunov approach.
The principal contributions of this study can be enumerated as follows. First, unlike other existing schemes [34,35,36,37,38,39], based on the enhanced observer system, the proposed approach makes the designed sliding-mode controller independent from the relevant upper bounds of uncertainties and disturbances, which renders the implementation much easier and more practical and removes the assumption that the upper bounds need to be known in advance. Second, compared with the algorithms presented in [36,37], our approach can deal with both unknown nonlinear terms and unmatched external disturbances, where the single-network ADP is utilized to approximate an optimal control. Unlike typical actor–critic–disturbance network architectures, the single critic network structure may bring a simpler implementation, lower calculation amount, and avoid the numerical approximate errors arising from actor and disturbance networks. Third, we introduce an updated law for the critic NN, which not only achieves the Nash equilibrium, but also ensures the stability of the sliding-mode dynamics without the need for an initial stabilizing control in the learning.
The remainder of this paper is arranged as follows. Section 2 outlines the problem formulation and provides some necessary preliminaries. Section 3 describes the design of an integral SMC based on the enhanced observer system. Section 4 presents the application of the single-network ADP to obtain optimal control for the sliding-mode dynamics, along with stability analysis. Simulations of the robotic arm and a power system are given in Section 5, followed by a summary of this study in Section 6.
2. Problem Formulation
Consider the following uncertain perturbed nonlinear system as
where the state vector is measurable, is the control input, and are the known system drift and input dynamics, respectively; and denote uncertain nonlinear terms that refer to either the inherent characteristics of the system or modeling uncertainties, while represents the unknown external disturbances. Moreover, it is assumed that the system uncertainties and satisfy the matched condition, i.e., , then the system (1) is rewritten in the form of
with being the bounded lumped uncertain term. Let be a compact set, and suppose that is Lipschitz continuous over with . Besides, and its derivative is bounded such that with . To avoid any confusion, denotes the 2-norm of a vector or the Frobenius norm of a matrix hereafter, unless otherwise specified.
Assumption 1.
The input matrix has a full column rank and is norm bounded with , that is, for any x. Moreover, the resulting left pseudoinverse is given by , which is bounded by , where , are known positive constants.
Based on Assumption 1, d is then decomposed into the matched and unmatched components through the projection of d onto the input matrix as
where I denotes an identity matrix of appropriate dimensions, and is the left pseudoinverse of . It should be noted that Assumption 1 is somewhat restrictive, which may lessen the applicability scope of the proposed approach to some extent. However, many real-world physical systems, such as the satellite dynamics, the hypersonic flight vehicle and overhead crane systems, have such a property to make this assumption valid [15,20].
To deal with the uncertain nonlinear system (1) with external disturbances, an enhanced observer system is first constructed for estimating the uncertain terms and observing the unknown disturbances simultaneously. Then, based on the reliable estimations, an integral SMC is developed to counteract the impacts of the system uncertainties and the separated matched disturbances, as well as unknown approximation errors, without requiring prior knowledge of their upper bounds. Meanwhile, the remaining unmatched disturbances are attenuated by optimal control on the sliding surface. Moreover, the single-network ADP algorithm is employed to learn the cost function related to the Hamilton–Jacobi–Isaacs equation, and then, the optimal control is obtained. What is more, a weight updating law is formulated to ensure both the achievement of Nash equilibrium and the stabilization of sliding-mode dynamics during the learning process.
3. Integral SMC Design Based on the Enhanced Observer System
Recalling the NN universal approximation property, the uncertain term can be represented by a three-layered NN as
where and denote unknown ideal weight matrices between the output and hidden, and hidden and input layers, respectively; is the NN input, represents the activation function with hidden layer neurons, and stands for the NN reconstruction error. To simplify the learning process, only the weights of are adapted online, while is an initialized set with random values and then remains unchanged during the weight updating process [16].
The NN identifier is designed by
where A is a Hurwitz matrix, is the identifier state, is the estimate of , and the activation function with . Since the unknown disturbance term d is needed in (5), inspired by [11], a nonlinear DO is introduced for obtaining , namely, the estimated value of d.
Then, combining the NN identifier with a nonlinear DO, an enhanced observer system is constructed as
with , where is an auxiliary variable, and is a designed state-dependent function and brings out the gain function such that . Following (6), we have
where represents the NN weight estimation error. Let and be the state and disturbance estimation errors, respectively. Subtracting (5) from (2) and combining with (7), we obtain the coupled error dynamics of (6) as follows:
Before proceeding, we introduce a common assumption for stability analysis [15,16].
Assumption 2.
For the identifier NN, there are known positive constants , , and in the sense that , , and , respectively.
Lemma 1.
Considering the system (2) and the coupled error dynamics (8), let the identifier NN weight be updated by
where , are the positive updating ratios. Moreover, we select parameter matrices A, P and gain function to satisfy
with . Then all the estimation errors , , and are uniformly ultimately bounded (UUB).
Proof.
Consider the Lyapunov function candidate given by
where , , and is positive definite, which together with some matrix satisfies for the Hurwitz matrix A. By taking the time derivative of and substituting the coupled error dynamics (8), we can obtain
Based on Assumption 2, together with Young’s inequality, it follows:
Considering (10), (13) is rewritten as
where ensured by properly selecting positive definite matrix and its minimum eigenvalue .
Combining with (9), is derived as
With the inequality , (15) becomes
Note that the relationship for all , and the inequality , we can have
By combining (14) and (16) and taking their norms, one can derive an upper bound for as
Select and complete the square with respect to , then (17) becomes
where
Define
and , we can further derive
Therefore, we can conclude that only if satisfies
Furthermore, according to the Lyapunov extension theorem [16], when the inequality (10) holds by selecting proper matrices, we can infer that all the estimation errors , , and are UUB. □
Remark 1.
The gain function matrix is an important design parameter that can be chosen as linear or nonlinear functions. When the form of system function is simple, it can be easy to find the function that satisfies the inequality (10) by substituting appropriate functions into (10). However, if the form of system function is complex, the trial and error method is employed to select appropriate function that meets the inequality (10). Although there is no universal design procedure for designing , experience has shown that it is not difficult to find a suitable for specific applications [36,37].
To effectively handle both system uncertainties and external disturbances, we propose a compound optimal SMC scheme that combines the integral SMC with control theories. This compound controller is formulated as
where represents the discontinuous control designed to steer the system trajectories towards and maintain them on the sliding surface, thereby eliminating the effects of matched uncertainties and disturbances. denotes the continuous control derived to guarantee the system stability and achieve near-optimal performance under the remaining unmatched disturbances on sliding surfaces.
Accordingly, we define the integral sliding surface as follows:
where denotes the initial state, and . Moreover, it follows from Assumption 1 that a suitable matrix can be found such that the product is invertible.
Taking the time derivative of as
By incorporating the valid estimators and , is devised as
where , is the sign function, and is generated by
with . In particular, it is noted that is designed to tackle the unknown bounds of the approximation errors arisen from the estimated terms and .
Considering the specific implementation of and in (23), we define to represent the approximation errors. Based on the previous analysis and the boundedness of , is bounded as for an unknown positive constant . To estimate , we design as defined in (24), and the estimation error is calculated as .
Theorem 1.
Proof.
Choose the positive definite Lyapunov function candidate as
Along with the system (2), is derived as
Substituting (23) and (24) into (25), we can have
Using and the estimation error yields
Thus, it is shown from (26) that for any , where denotes the vector 1-norm. This means the asymptotic stability and convergence of sliding mode motion can be guaranteed. Moreover, according to (21), the sliding surface when , which implies that the system states start on the sliding surface, thus avoiding the need for a separate reaching phase. □
From Theorem 1, it is clear that the stable sliding motion exists from the initial time; that is, for all , and . Moreover, the equivalent control method is utilized to obtain the sliding-mode dynamics. Combining with (3) and (22), the equivalent control can be derived as
Then, substitute into (2), the sliding-mode dynamics without matched uncertain term and disturbance component is
where , is the unmatched component of the external disturbance in (3). In order to reduce the influence of multiplier matrix and minimize the unmatched disturbance , an optimal projection matrix within is provided in the following Lemma.
Lemma 2.
Considering nonlinear system (2) with Assumption 1, the optimal projection matrix is selected as , which not only minimizes the norm , but also makes the relation hold.
Proof.
The proof can refer to Theorem 1 in [12]. □
As a result, with the relation , we can express (28) as
which means that the discontinuous control in (23) can fully counteract the impacts of the matched uncertainties and disturbances.
Notice that in (20), aims not only to suppress the remaining unmatched disturbances on sliding surface, but also to achieve a near-optimal performance for sliding-mode dynamics (29). This formulation can be seen as a nonlinear optimal control problem, which is known to be challenging to solve directly. In the following, we will demonstrate how to find an approximate optimal control solution by using the single-network ADP algorithm.
4. H∞ Control Design for Sliding-Mode Dynamics
Considering (3) and (29), the sliding-mode dynamics is represented as
with . Since and are bounded, it follows that the function is also bounded by with .
For attenuating the remaining unmatched disturbances , the corresponding control problem of sliding-mode dynamics is established, which aims to seek a feedback control to stabilize the system and achieve -gain no larger than , that is,
where Q and R are positive definite matrices with appropriate dimensions, and refers to the level of the disturbance attenuation. Based on [32,33], by treating the disturbance d as the other system input, we can reframe the optimal control problem for system (30) as a two-player zero-sum game with the following infinite-horizon cost function:
Assuming that , the Hamiltonian function with the associated admissible control pair is defined as
with . From Bellman’s optimality principle, it follows that the optimal cost function satisfies the HJI equation
with . Moreover, according to the zero-sum game theory [16], we have the following Nash condition
which ensures the existence of saddle point of the HJI Equation (34). Then, applying the stationary condition, one can derive the optimal control and worst disturbance as
By substituting (36) and (37) into (33), the HJI equation associated with becomes
Due to the highly nonlinear nature of the relevant HJI equation, obtaining its analytical solution is extremely difficult, if not impossible. To overcome this challenge, we propose an online optimal algorithm that learns the solution of the HJI equation and achieves optimal control. This is accomplished through the use of single-network ADP, where only one critic network, implemented by NN, is adopted to approximate the cost function related to (38). Therefore, by using the critic NN with neurons, is represented over a set as follows:
with the ideal weight vector being unknown, the vector of activation functions and the reconstruction error . Meanwhile, we have the gradient vector
with and .
By combining (36), (37) and (40), it is easy to get
Substituting (41) and (42) into (33), the HJI equation becomes
where , and the approximate error is defined as due to the NN reconstruction error. Furthermore, taking into account and , we can infer that there exists a positive constant in the sense that .
Because in (39) is unknown, the critic NN with the estimated weights approximates the cost function in the form of
where denotes the estimated values of . In addition, we can obtain
By using (36), (37) and (45), the approximate forms of (41) and (42) are derived as
Then, incorporating (46) and (47) into (43), we have the approximate Hamiltonian as follows:
Subtracting (43) from (48), the corresponding Hamiltonian error is defined as
To effectively approximate the cost function, one needs to adjust the critic NN weight in a manner that minimizes the Hamiltonian error . To this end, it is common practice to train the critic NN by minimizing the squared residual error , where . The traditional weight updating laws of critic NN based on gradient descent method can only minimize the squared error, but cannot provide any guarantee for the stability of the resulting system during the learning phase.
However, in practice, the stability is one fundamental requirement of system, and a prerequisite for achieving other higher performance. Thus, not just for minimizing the residual error, but also to guarantee the system stability and eliminate the need for an initial stabilizing control, a weight updating law is developed for the critic NN as follows:
where and are the positive updating ratios, , , , and represent design parameter matrices with suitable dimensions, is a Lyapunov function candidate provided in Assumption 4, and the index operator is given by
with .
Remark 2.
Note that in (49), the first term is designed by the normalized gradient descent method for minimizing the residual error. The second term has a well-designed form for ensuring the system’s stability, which is derived from the Lyapunov stability analysis. The last term is an additional adjustment term that works or not depends on the index operator , which is selected based on the derivative of along the sliding-mode dynamics (30), namely, . Once the system dynamics may become unstable, this results in , then and the last term in (49) is activated. Moreover, based on the negative gradient direction of , i.e., , the last term is designed to reinforce the training process of the critic NN until the system dynamics become stable. This also eliminates the need for an initial stabilizing control, compared with [35,36,37,39], where the stabilizing control is required for initialization; however, in practical applications, finding an initial stabilizing control is quite challenging.
Remark 3.
Based on [14,15,16], it is necessary to satisfy the persistence of excitation (PE) requirement for updating the weights of critic NN, which enhances its ability to explore the state space and is indispensable for the weights to converge to their desired ones. To fulfill the PE requirement, a probing noise is injected into the control input [15], which may cause the instability problem during the online learning. As a result, it is important to design the last term in (49) for stabilizing the resulting system, especially when the probing signal is injected.
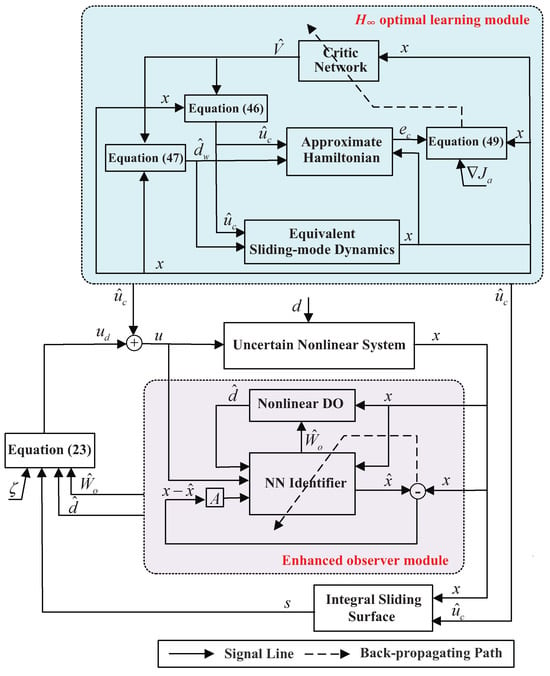
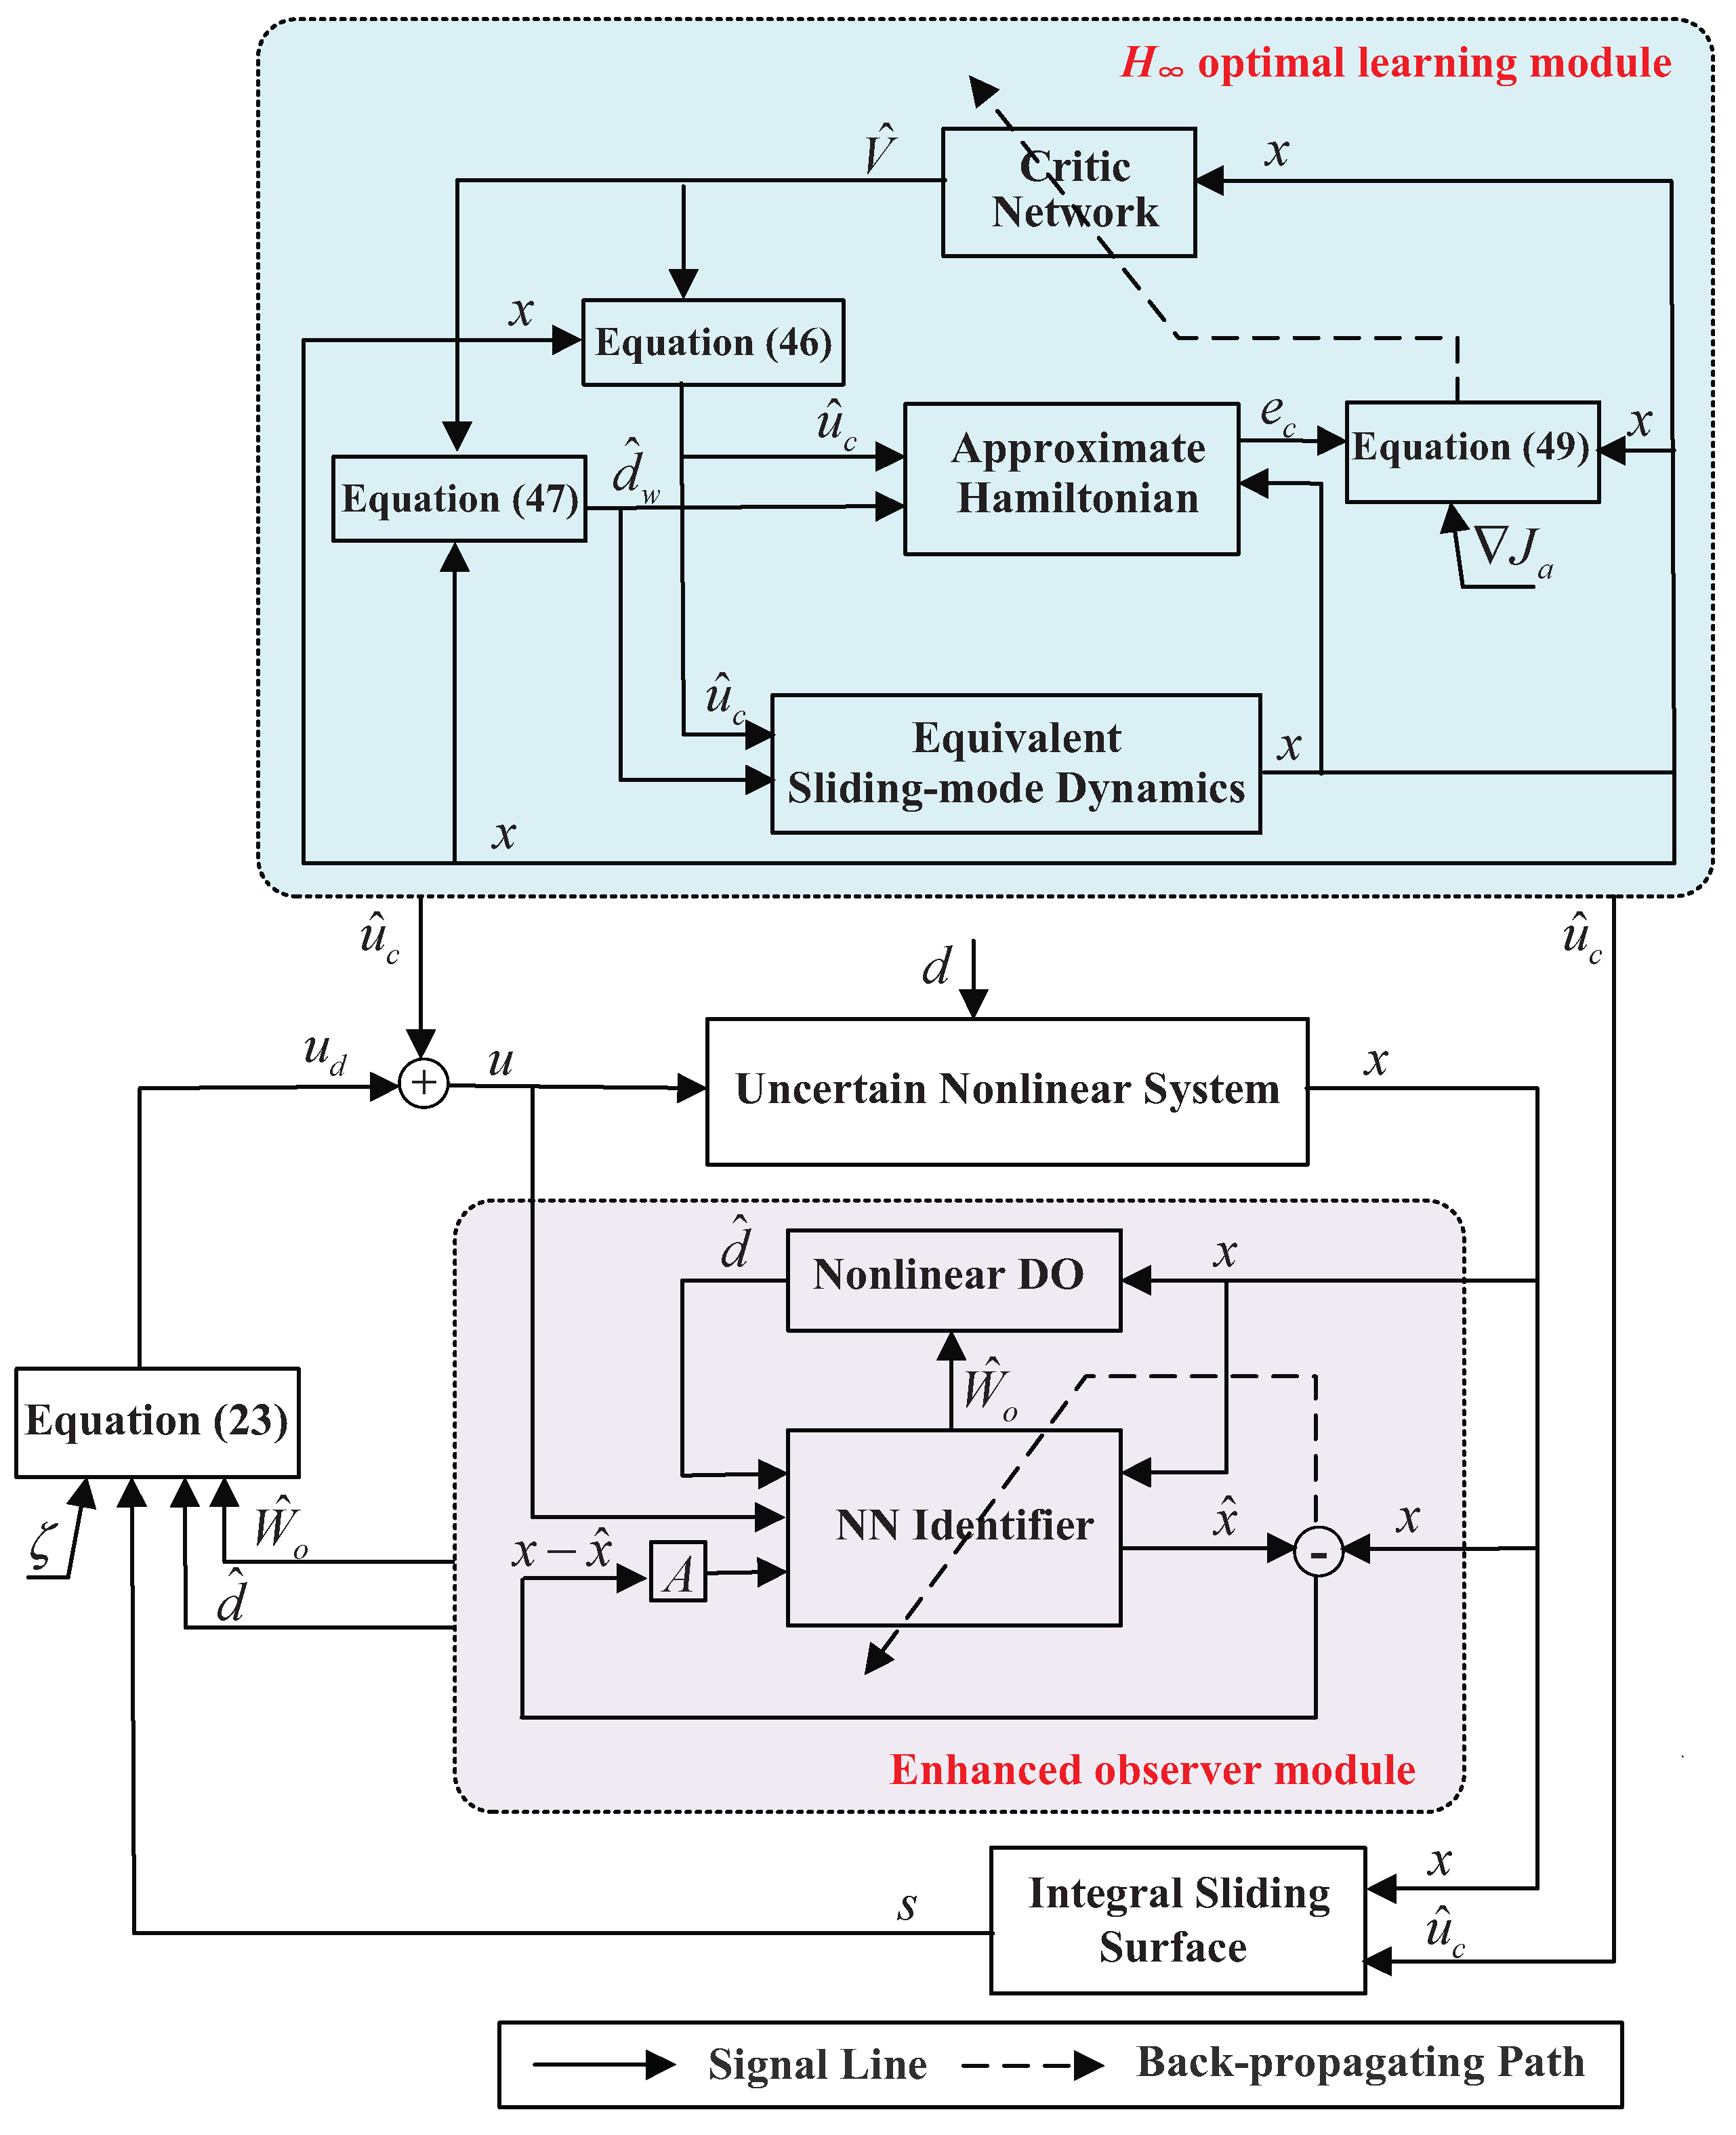
The schematic structure of the proposed SMC scheme is illustrated in Figure 1. As shown in Figure 1, this structure consists of two main modules: the optimal learning module and the enhanced observer module. It should be noted that, based on the deduced sliding-mode dynamics, the learning module can operate independently. However, the original system and the observer module rely on the compound control input u, which includes the approximate optimal control obtained from the learning module. Consequently, it is necessary to first run the learning module to obtain the approximate optimal control during the implementation process.
Figure 1.
The schematic of the adaptive SMC scheme.
Considering (43), together with , (48) is represented as
By means of the relation and incorporating (51) into (49), we obtain
Next, the main stability theorem is presented, but before that, one basic common assumption for the critic NN is introduced [16], and the other assumption for the sliding-mode dynamics is also needed, which has been used in [34,38].
Assumption 3.
For the critic NN, there exist known positive constants , , , and such that , , , and , respectively. Moreover, the approximation error is bounded above by , namely, .
Assumption 4.
Remark 4.
Note that the plausibility of Assumption 4 depends on the boundedness of optimal sliding-mode dynamics, which is usually assumed to be bounded by a function of system state x. For more details, refer to [34,38]. Furthermore, it is impossible to solve (53) directly for getting the form of . Based on [34], one can obtain by selecting an appropriate form, such as a quadratic polynomial.
Theorem 2.
Considering the sliding-mode dynamics (30) and its associated cost function (32), the control input and disturbance policy are designed by (46) and (47), respectively, along with the critic weight updating law as given by (49). Then, both the sliding-mode state x and the weight estimation error are ensured to be UUB. Furthermore, the obtained control input can be proven to converge to a neighborhood of the optimum control with a small adjustable bound.
Proof.
Consider the following Lyapunov function candidate
where . By calculating the time derivative of L along the sliding-mode dynamics (30), we have
Substituting (52) into (54) and making some adjustments, one can get
Using , the last two terms in (55) become
Defining , and substituting (55) into (56), it can be rewritten as
where
With Assumption 3 in mind, and recalling the boundedness of and D, in particular and , we can infer that there exists a positive constant in the sense that . For guaranteeing , the appropriate parameters and need to be selected in design. Then, one can upper bound as follows:
with being the minimum eigenvalue of M.
1: For , it follows from (50) that , i.e., , which, together with the PE condition, can ensure that there exists a positive constant such that . This implies that . Then, (58) becomes
Focus on (59), only if the following inequalities:
or
hold, then . Moreover, based on the relation with , we can derive
2: For , in light of (41) and (42), by adding and subtracting into (58), we can derive
Then, using (53) in Assumption 4, and recalling the boundedness of D and , (60) is upper bounded as
where , denotes the minimum eigenvalue of . Hence, provided the following inequalities:
or
hold, one has . Further, by the relation , we have
To sum up, for both 1 and 2, with proper parameters and satisfying , the inequality or holds, then, we have . From the Lyapunov extension theorem [16], it is found that and are bounded by and , respectively. Based on Assumption 4, the Lyapunov candidate is radially unbounded, which implies that the boundedness of leads to the boundedness of the system state . In particular, is bounded by , where and are determined by and , respectively. So far, we can conclude that both x and are guaranteed to be UUB.
Remark 5.
From the expression of and , it is seen that can be kept small with being larger enough. In view of (57), we can enlarge the value of by adjusting the corresponding design parameters and . Moreover, we can make the approximate error and its upper bound sufficiently small when the neuron number is large enough. Therefore, we can make the convergence errors in (62) as small as possible in the design.
5. Simulation Results
To validate the effectiveness of the proposed optimal SMC scheme, two simulation examples are provided. The first example focuses on a single-link robot arm, while the second example deals with a power system.
5.1. Single-Link Robot Arm
Considering a nonlinear single-link robot arm [23] and its dynamics given by
where is the joint rotation angle of robot arm in radians, u refers to the control torque applied to the joint in , and w denotes the lumped uncertain term. Select the system parameters as follows: the arm length , the payload mass , the local gravity acceleration . the rotational inertia and the viscous friction . With the system states defined as and , and considering the presence of exogenous disturbances, then the dynamics (63) in state-space form can be represented as
where d represents the unknown disturbances. Moreover, it is assumed that the initial state is set as , the lumped uncertainty term is , and the disturbance term is chosen as in the simulation.
The enhanced observer system, consisting of an NN identifier and a nonlinear DO, can be designed as shown in (6), where the identifier NN is selected as a three-layered feedforward NN with one hidden layer containing six neurons, and the hyperbolic activation function is utilized. The updating ratios are set as and , while the weights and are initialized with random values chosen from the interval . The initial observer state is set as . Moreover, based on Lemma 1, select the Hurwitz matrix , and to ensure that the inequality (10) holds. The integral sliding surface function is determined by (21), together with and . Accordingly, the discontinuous SMC is given by (23) and (24). For the propose of eliminating the chattering phenomenon, an arctangent function with a small positive scalar is employed to replace the sign function in (23).
By considering the SMC law , the sliding-mode dynamics can be obtained as
where . We choose the associated cost function as the form of (32), together with , and . For the critic NN, the activation function is chosen as , which results in . Select the updating ratios , , the design parameters , and as a quadratic polynomial. Furthermore, the weight vector is initialized to zero, which leads to the initial control input of zero. Noticing that the zero initial control cannot make the system (65) stable, it is thus clear that no initial stabilizing control strategy is necessary when implementing the proposed algorithm.
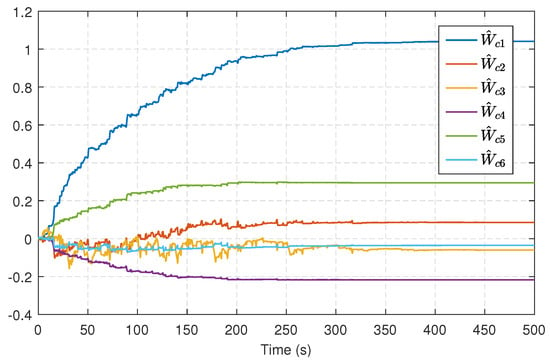
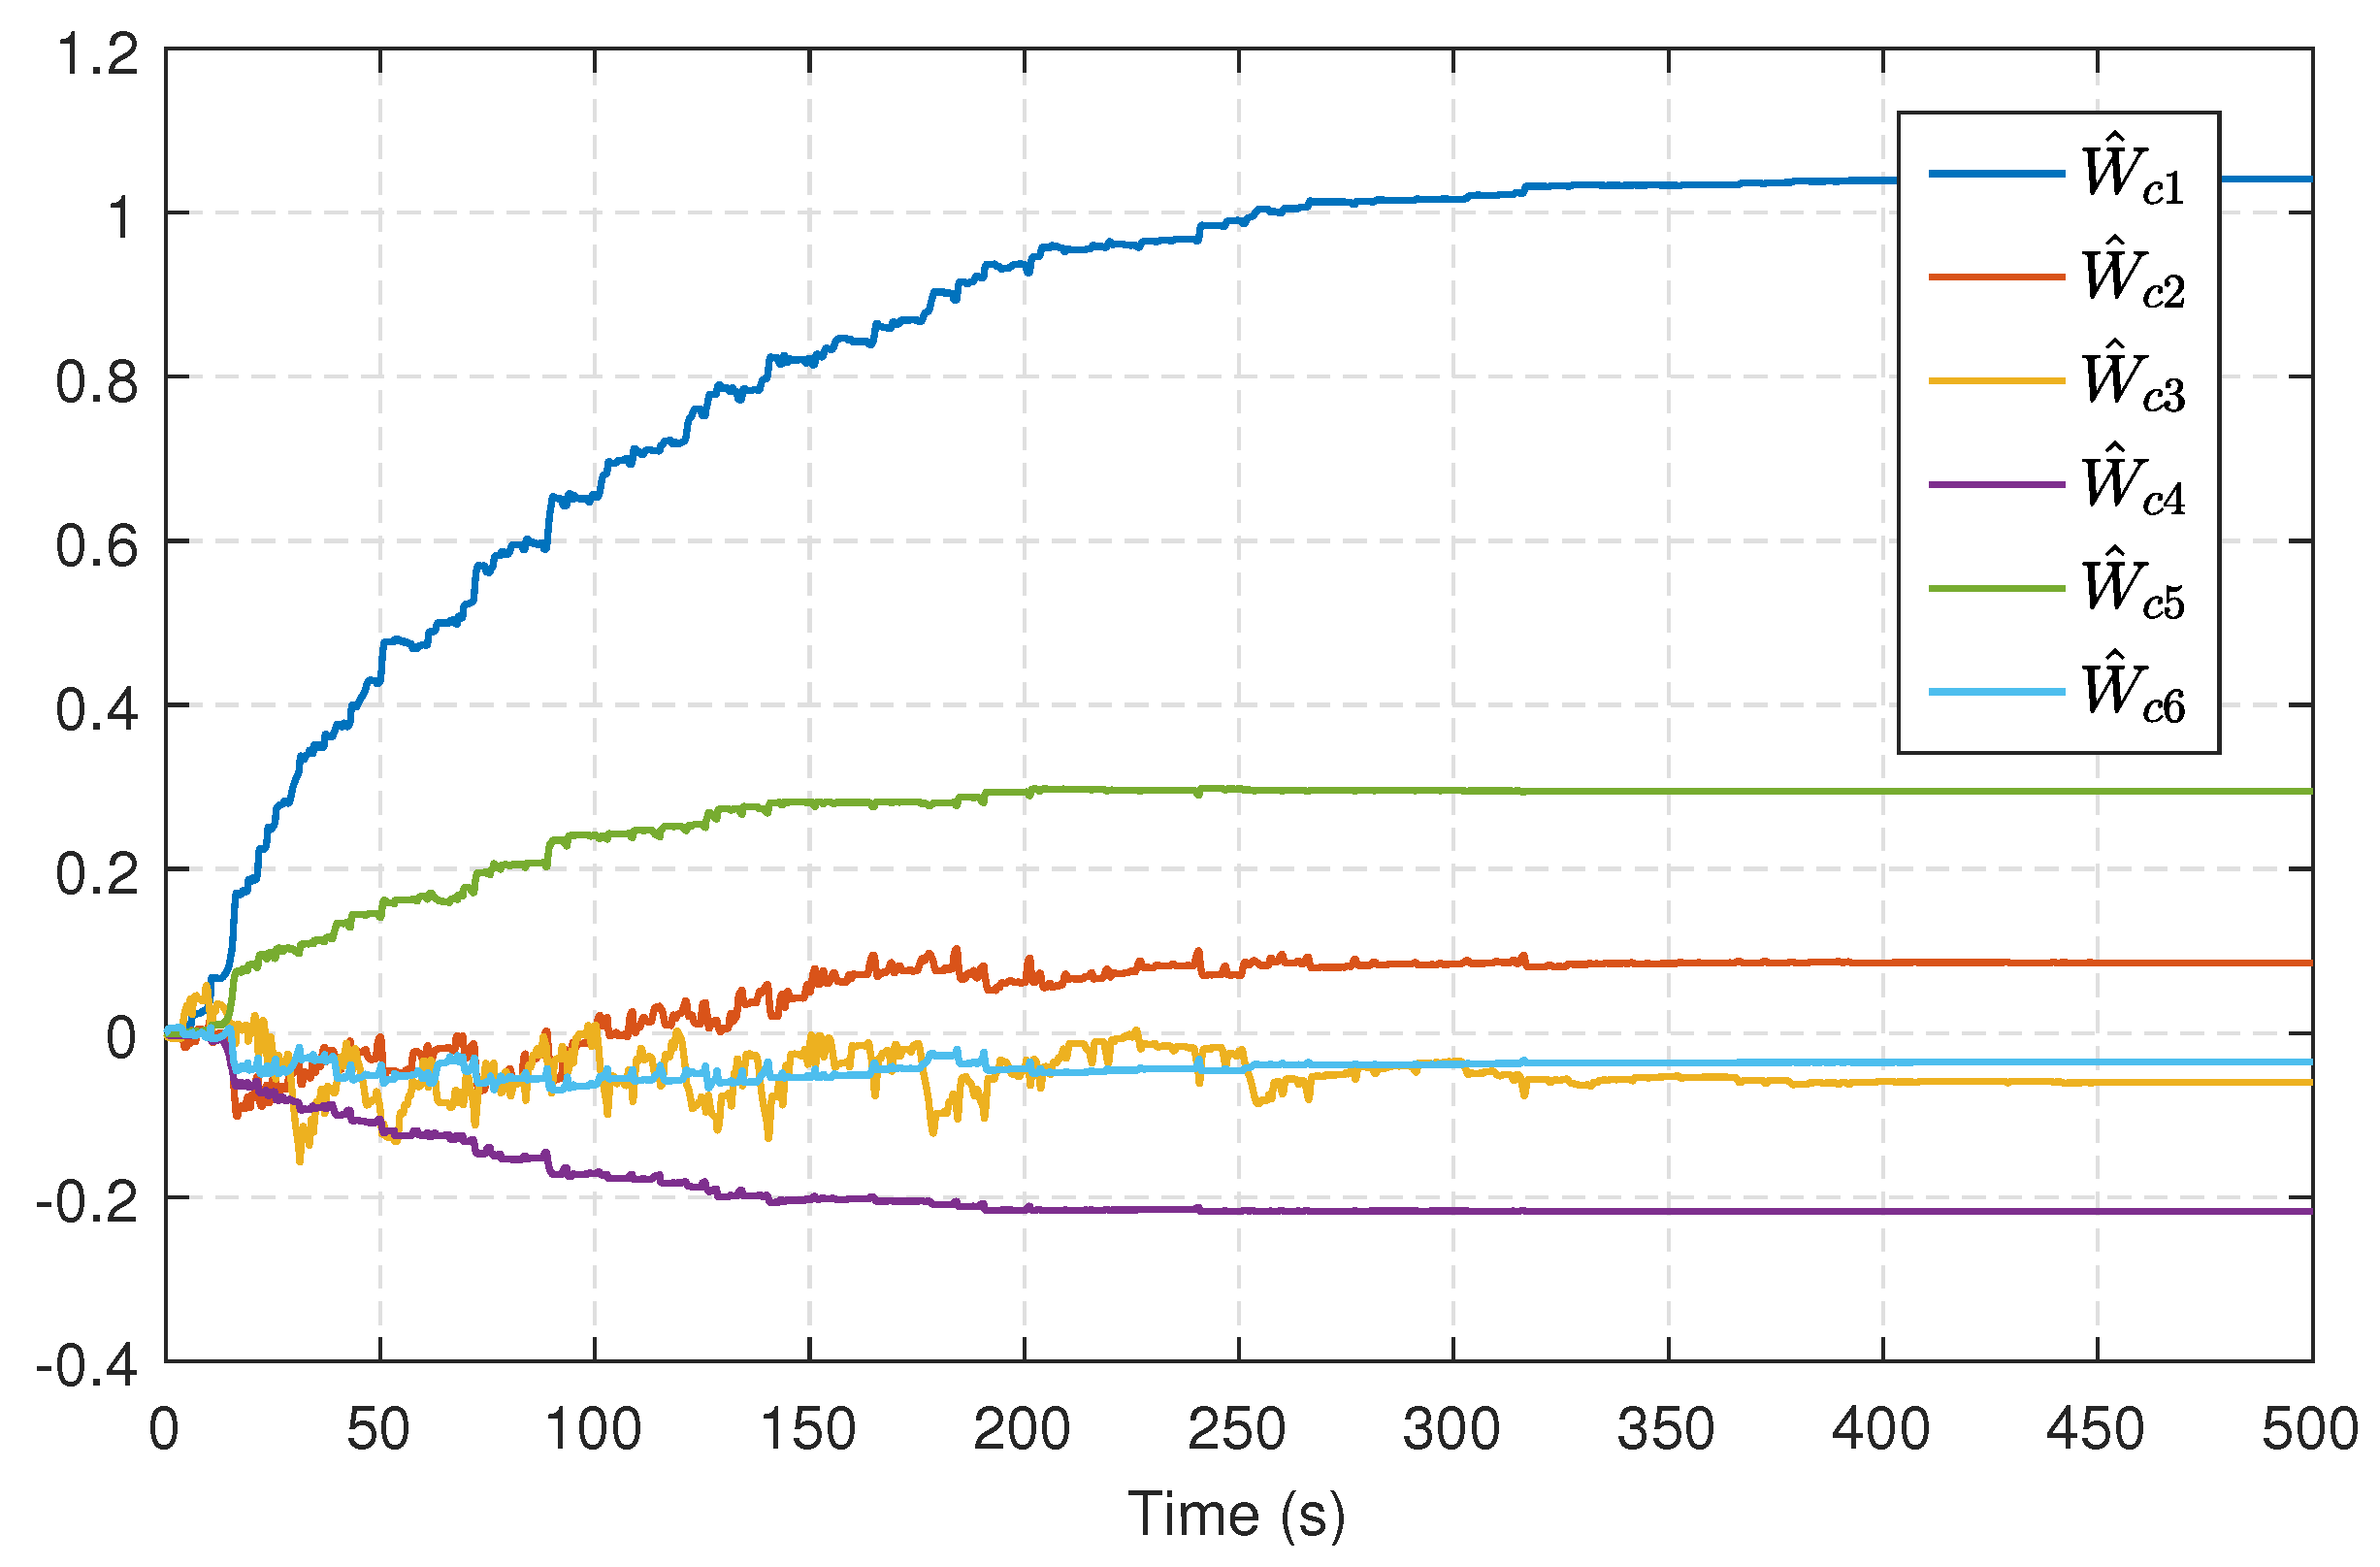
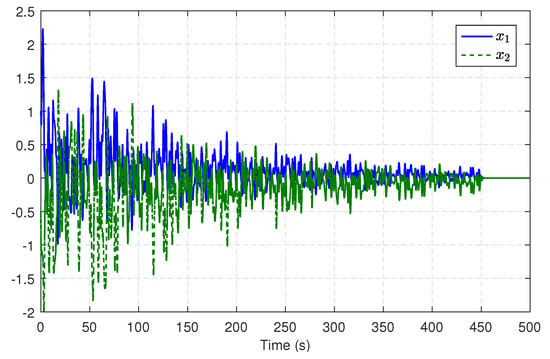
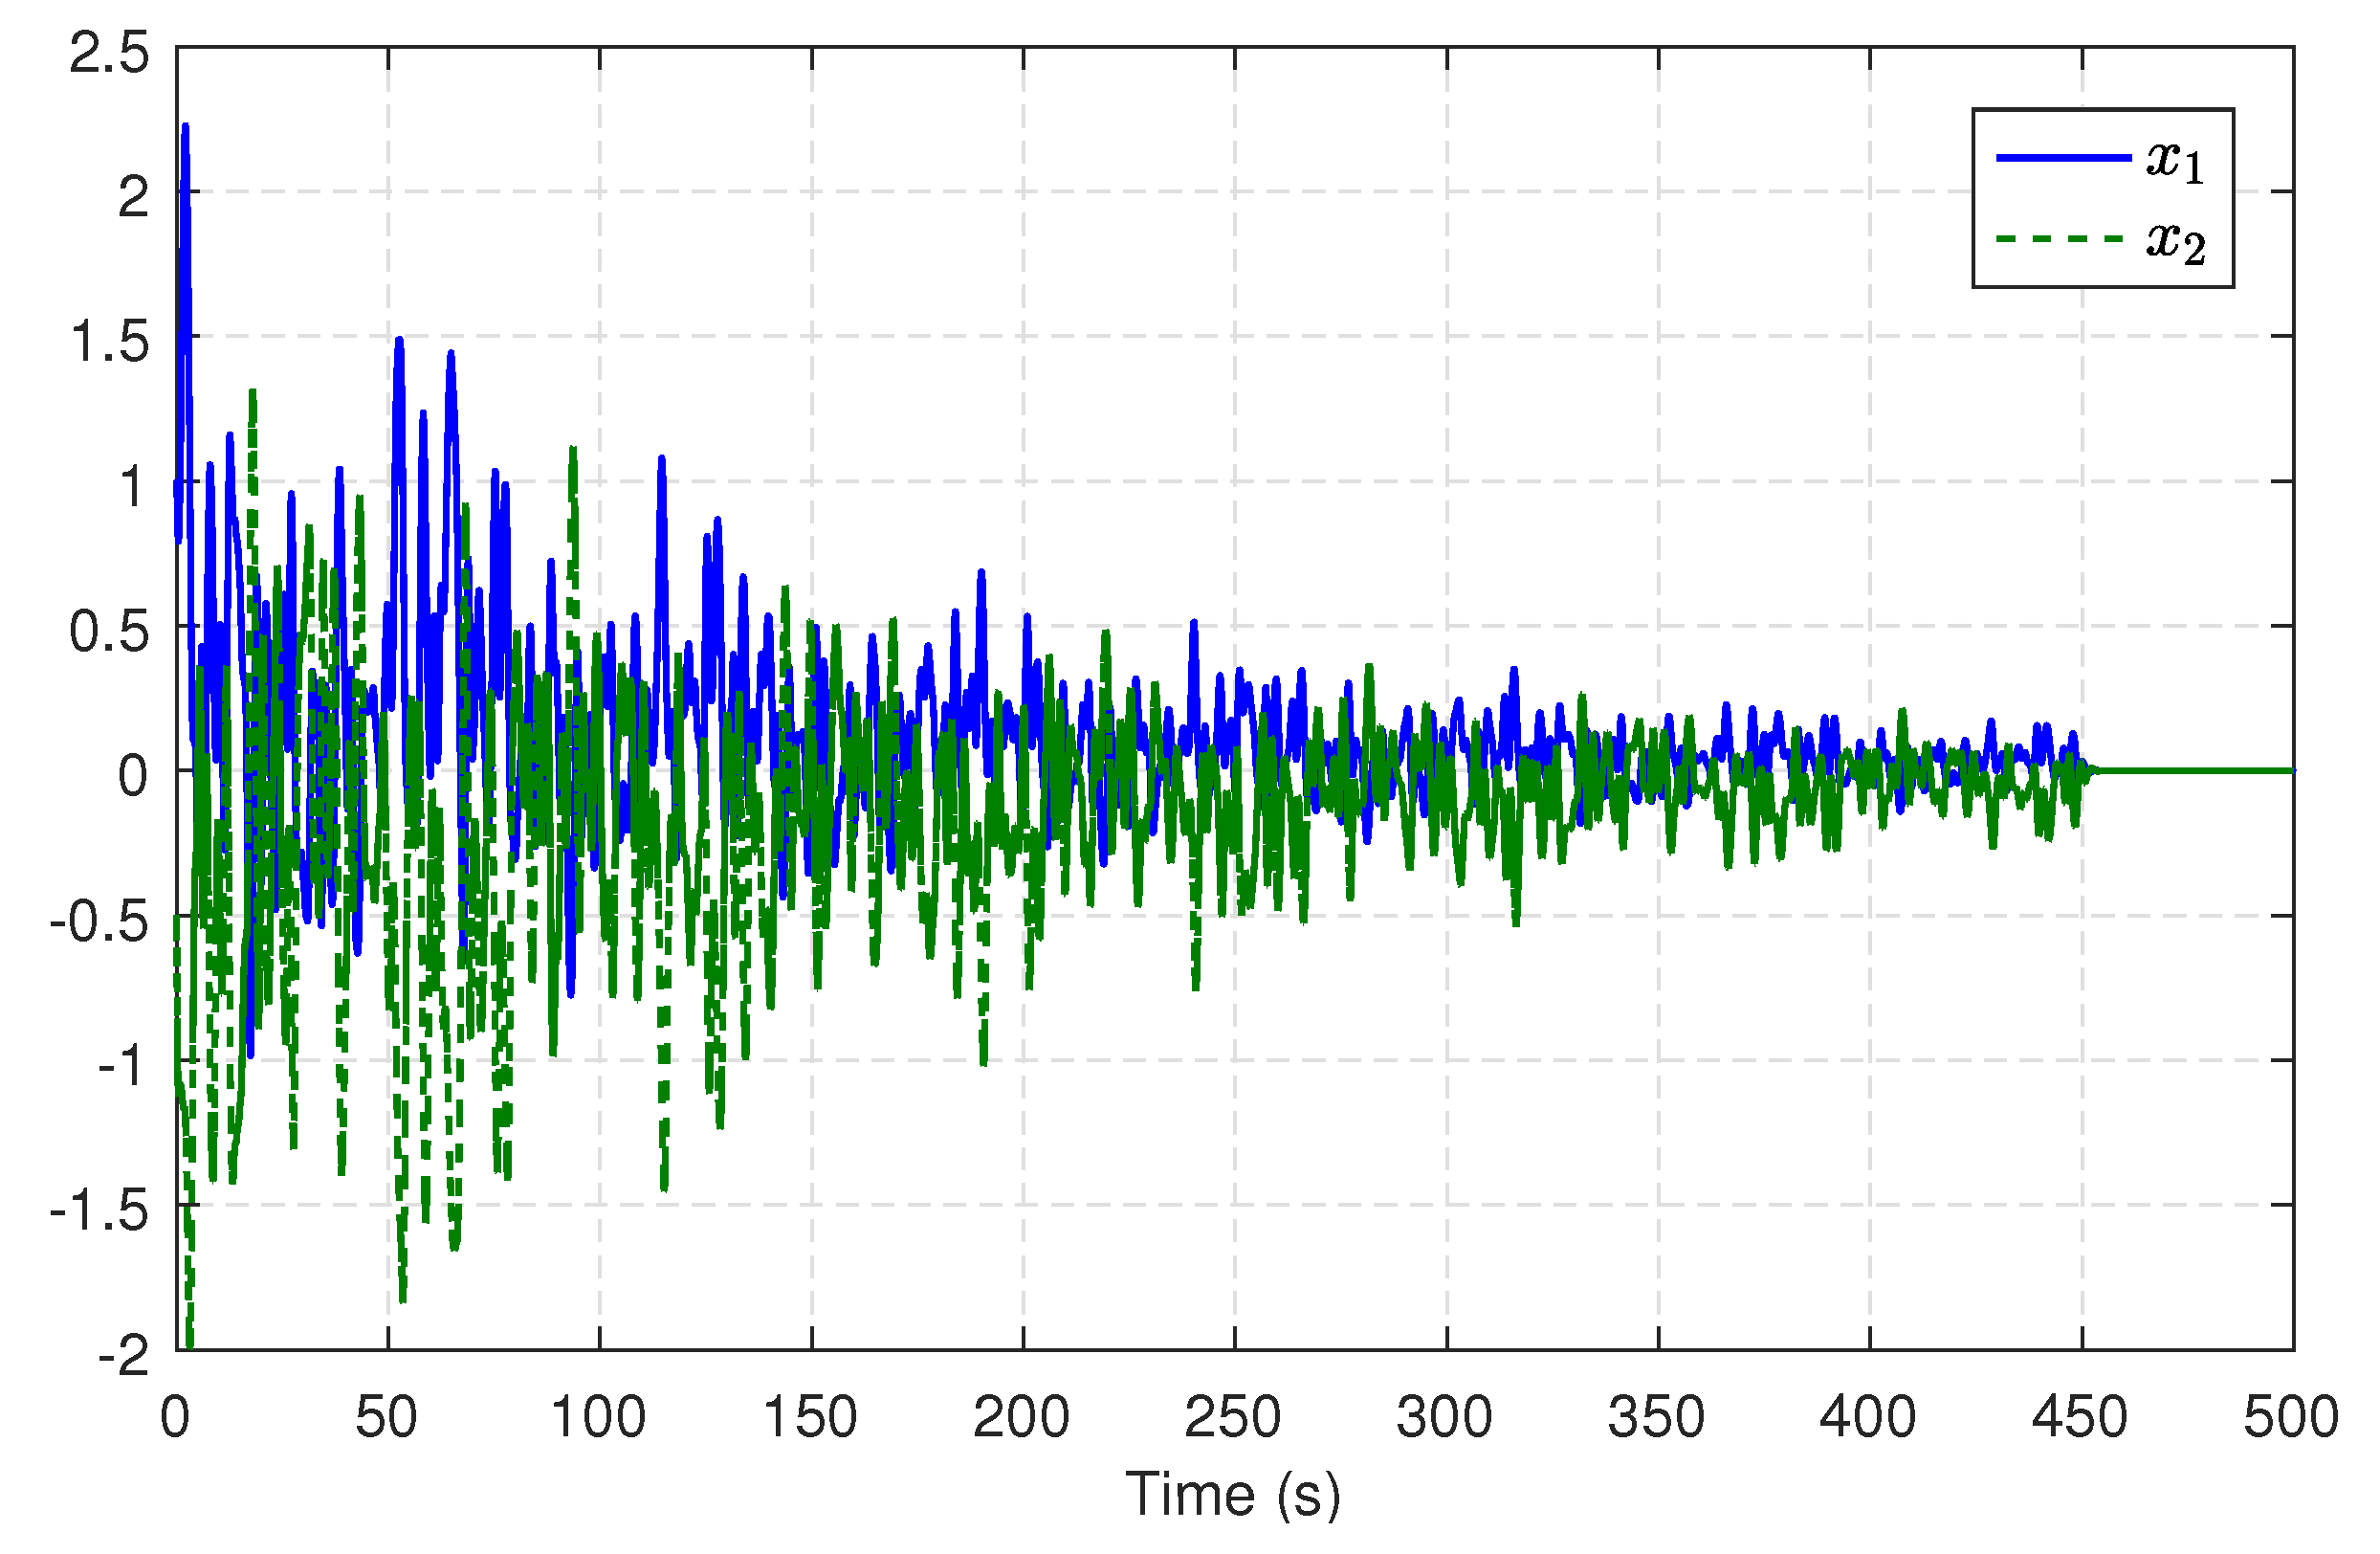
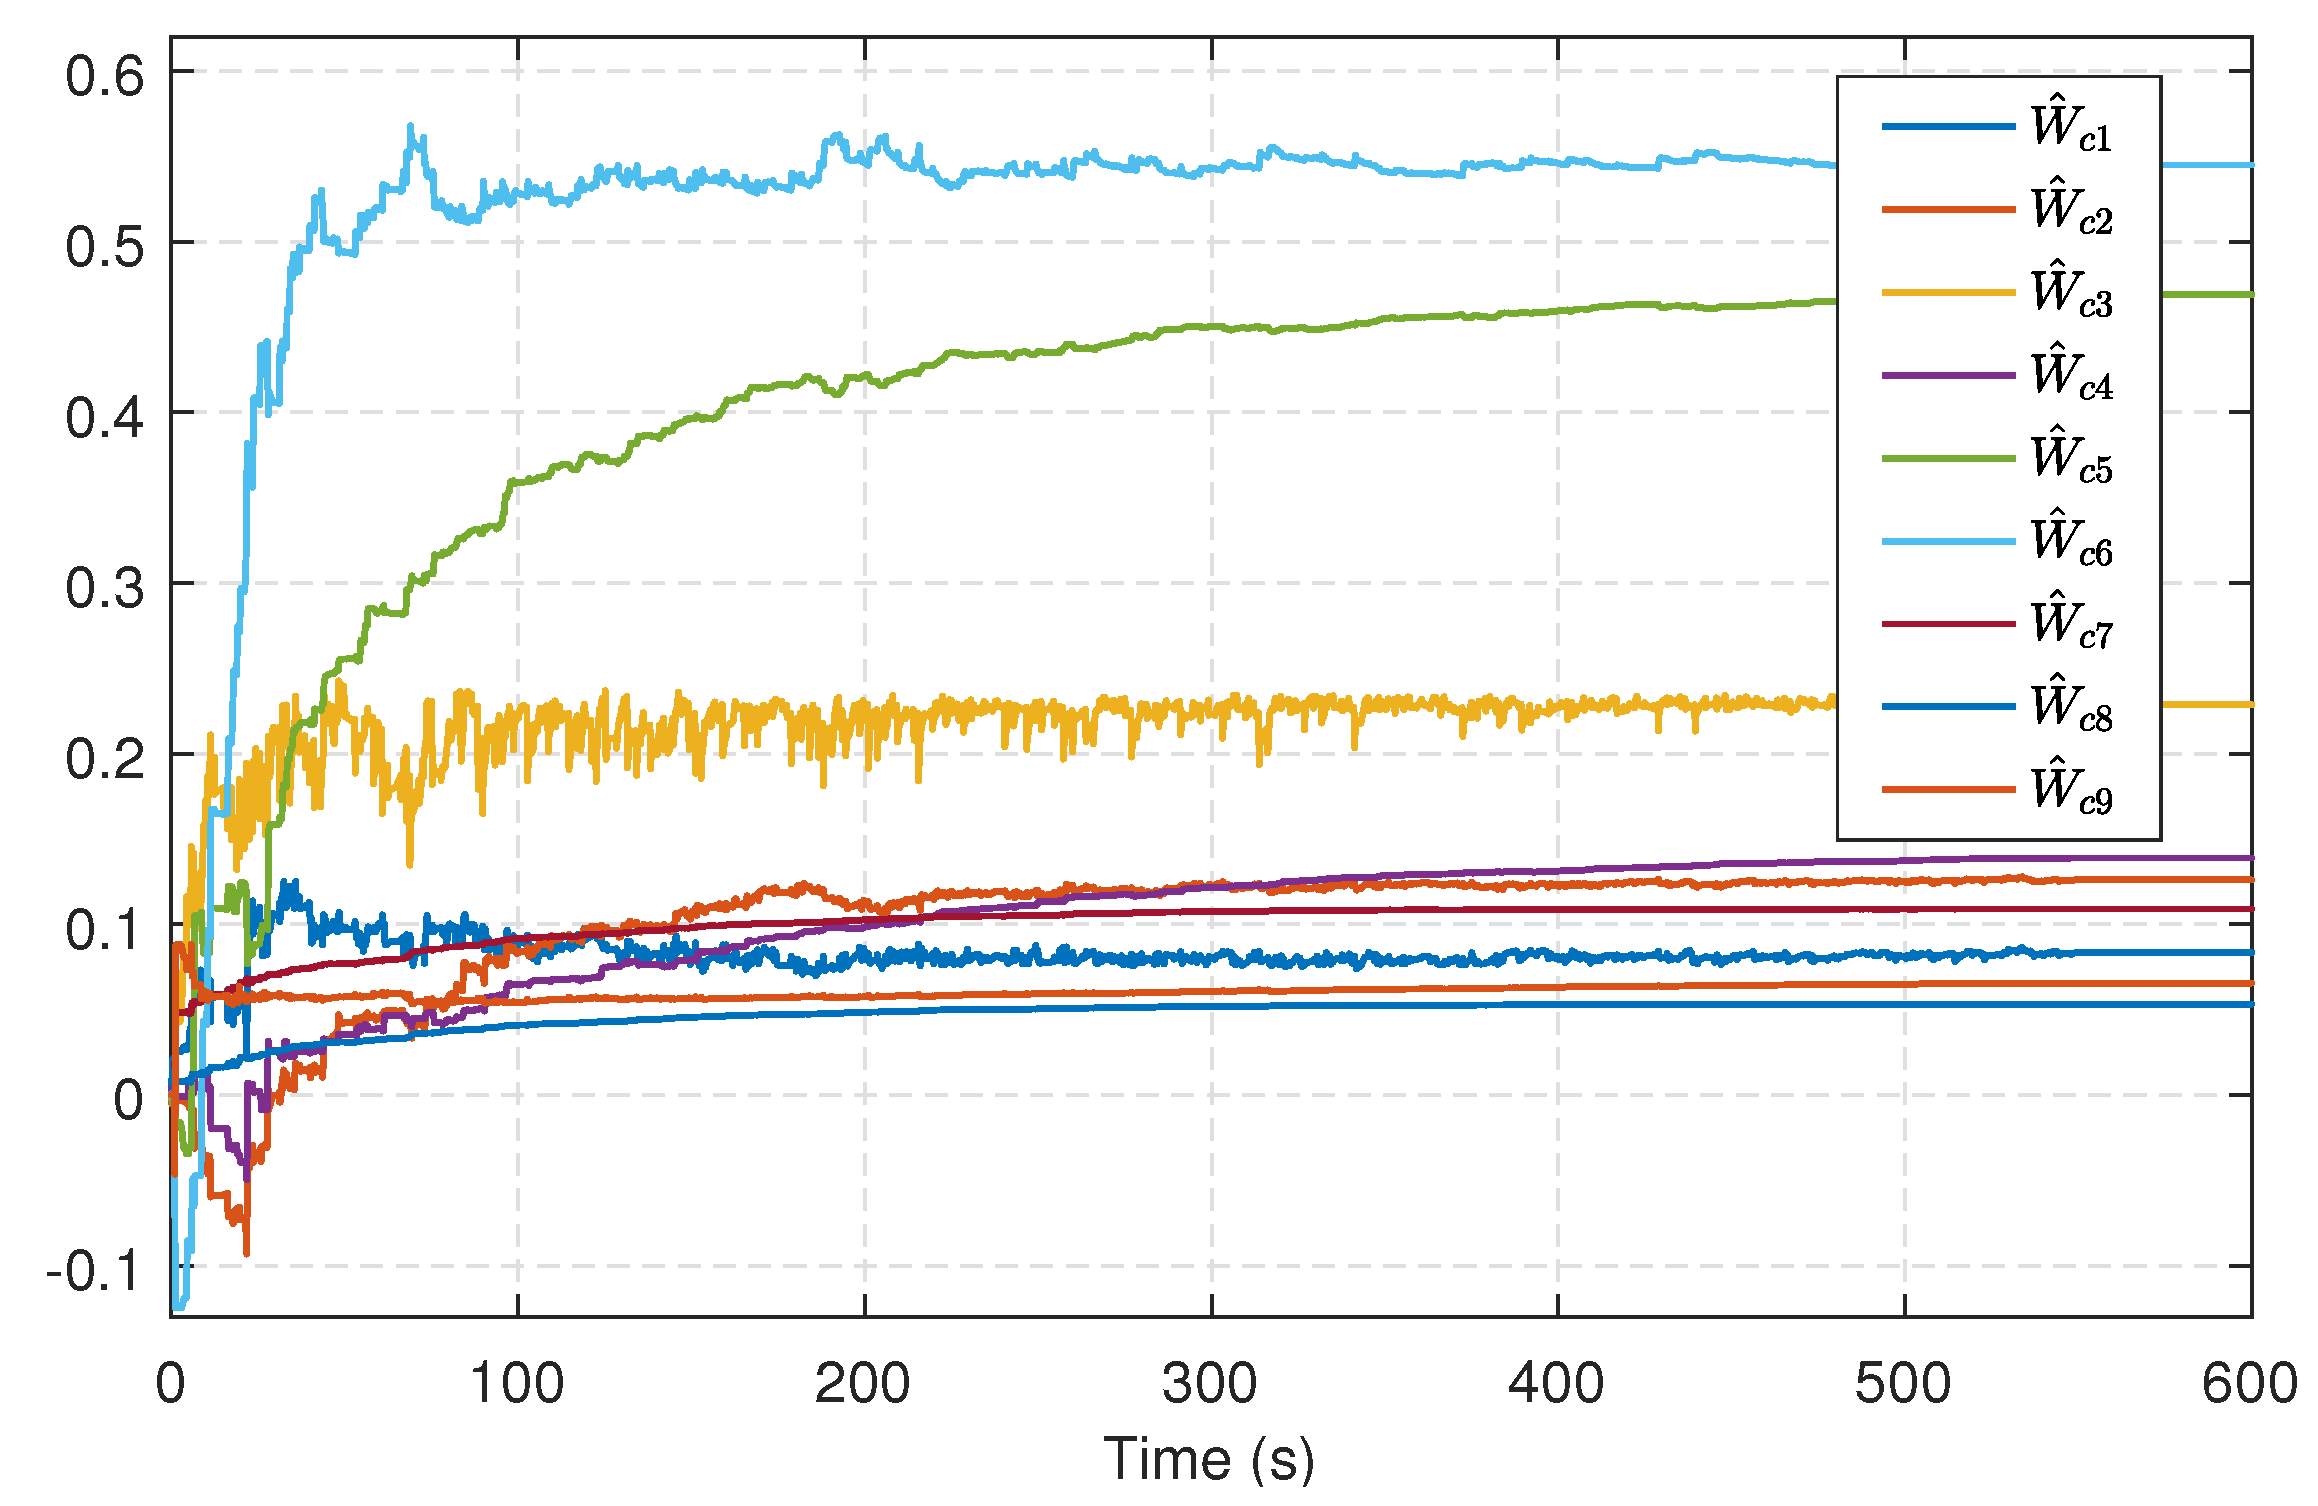
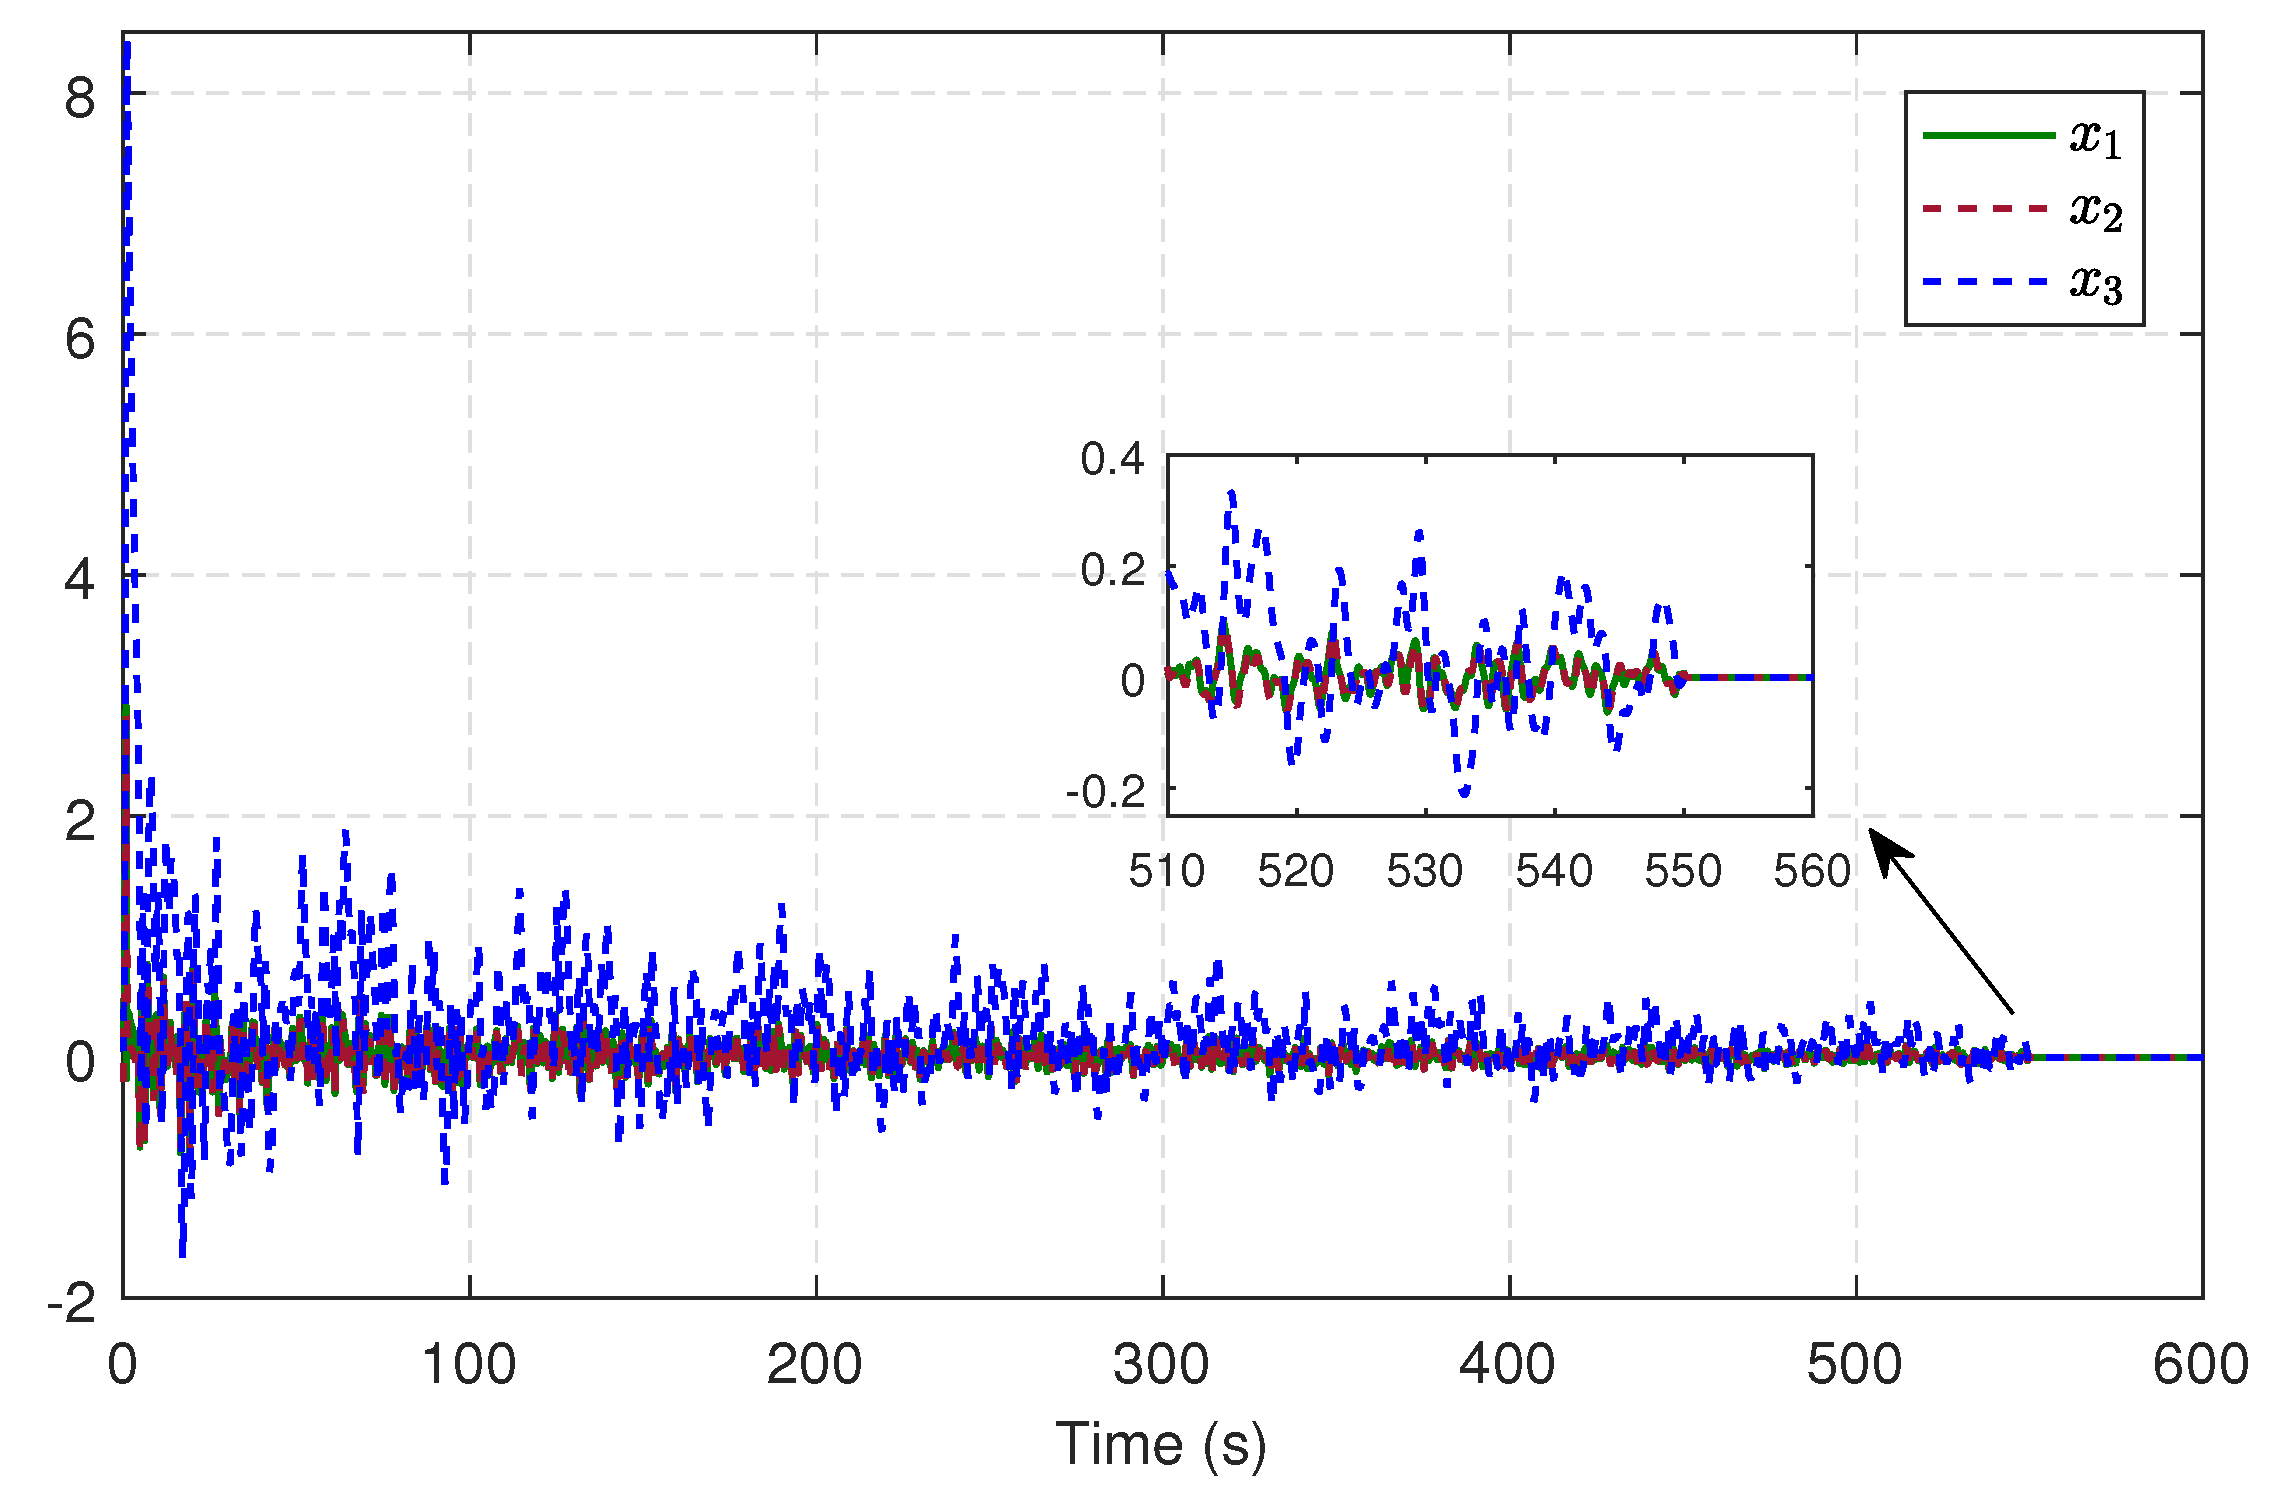
During the learning process, a damped decreasing probing noise is injected into the control input for satisfying PE condition. This noise comprises sinusoids of diverse frequencies and is applied for the first 450 s. Figure 2 shows the trajectories of the critic weights, which eventually converge to . Figure 3 describes the trajectories of system states in the learning. From Figure 3, one can see that without an initial stabilizing control, the system states stay at or near zero after the probing noise is removed, which indicates that generated by the learning module can effectively stabilize the system. With the converged weights, the approximate optimal control can be calculated by (46).
Figure 2.
Trajectories of the critic NN weights.
Figure 3.
Trajectories of system states in the learning.
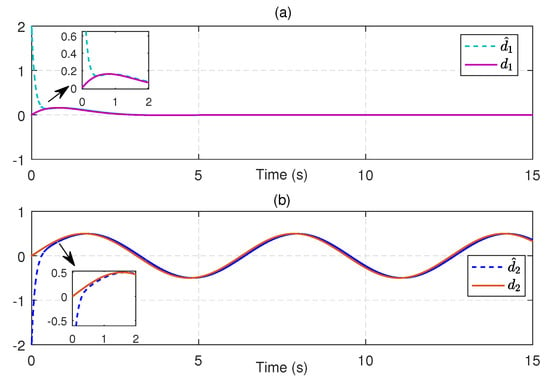
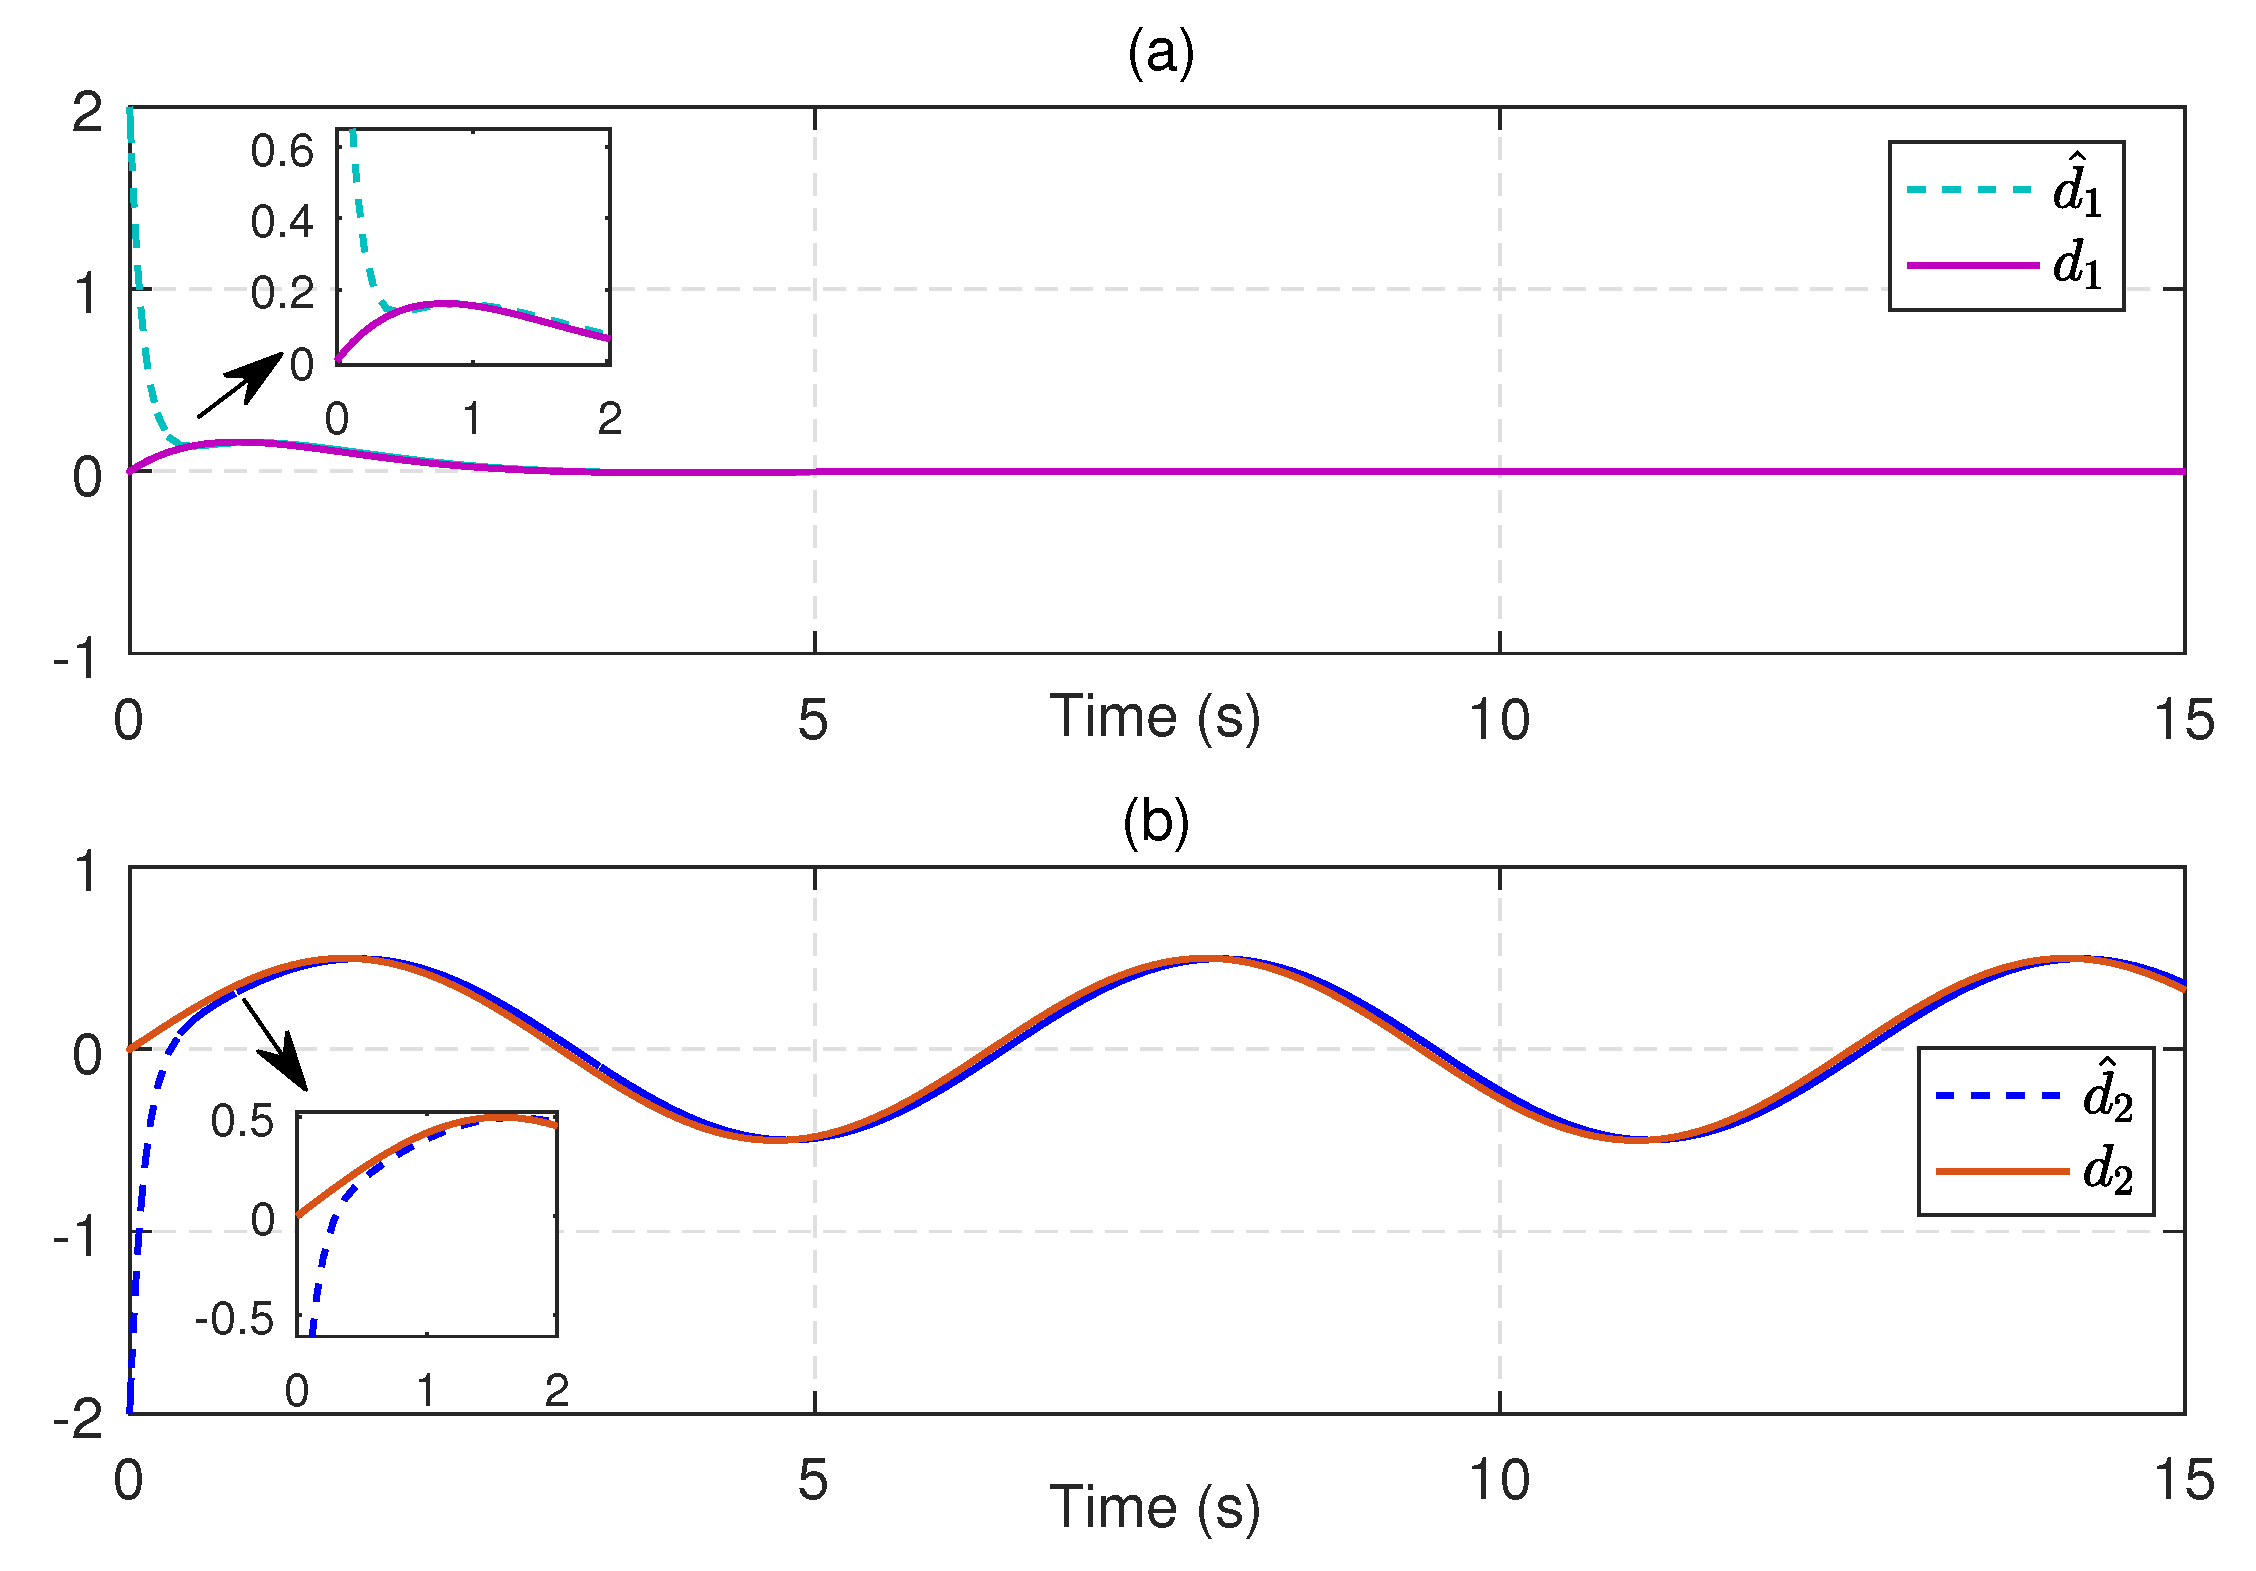
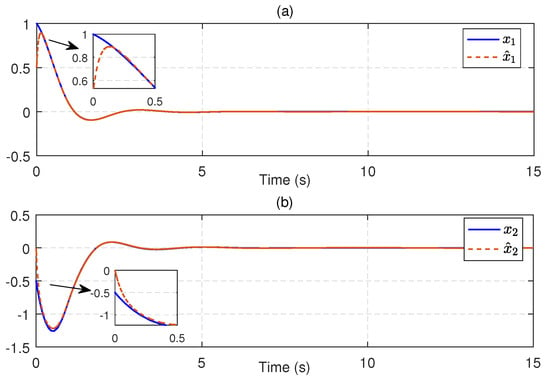
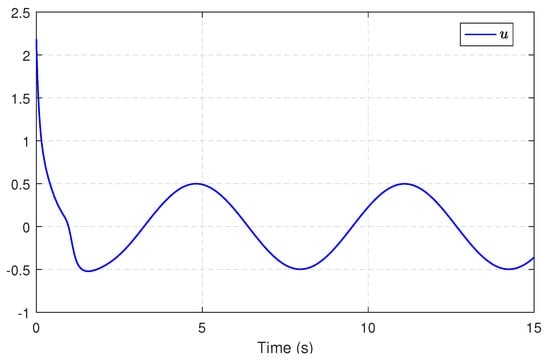
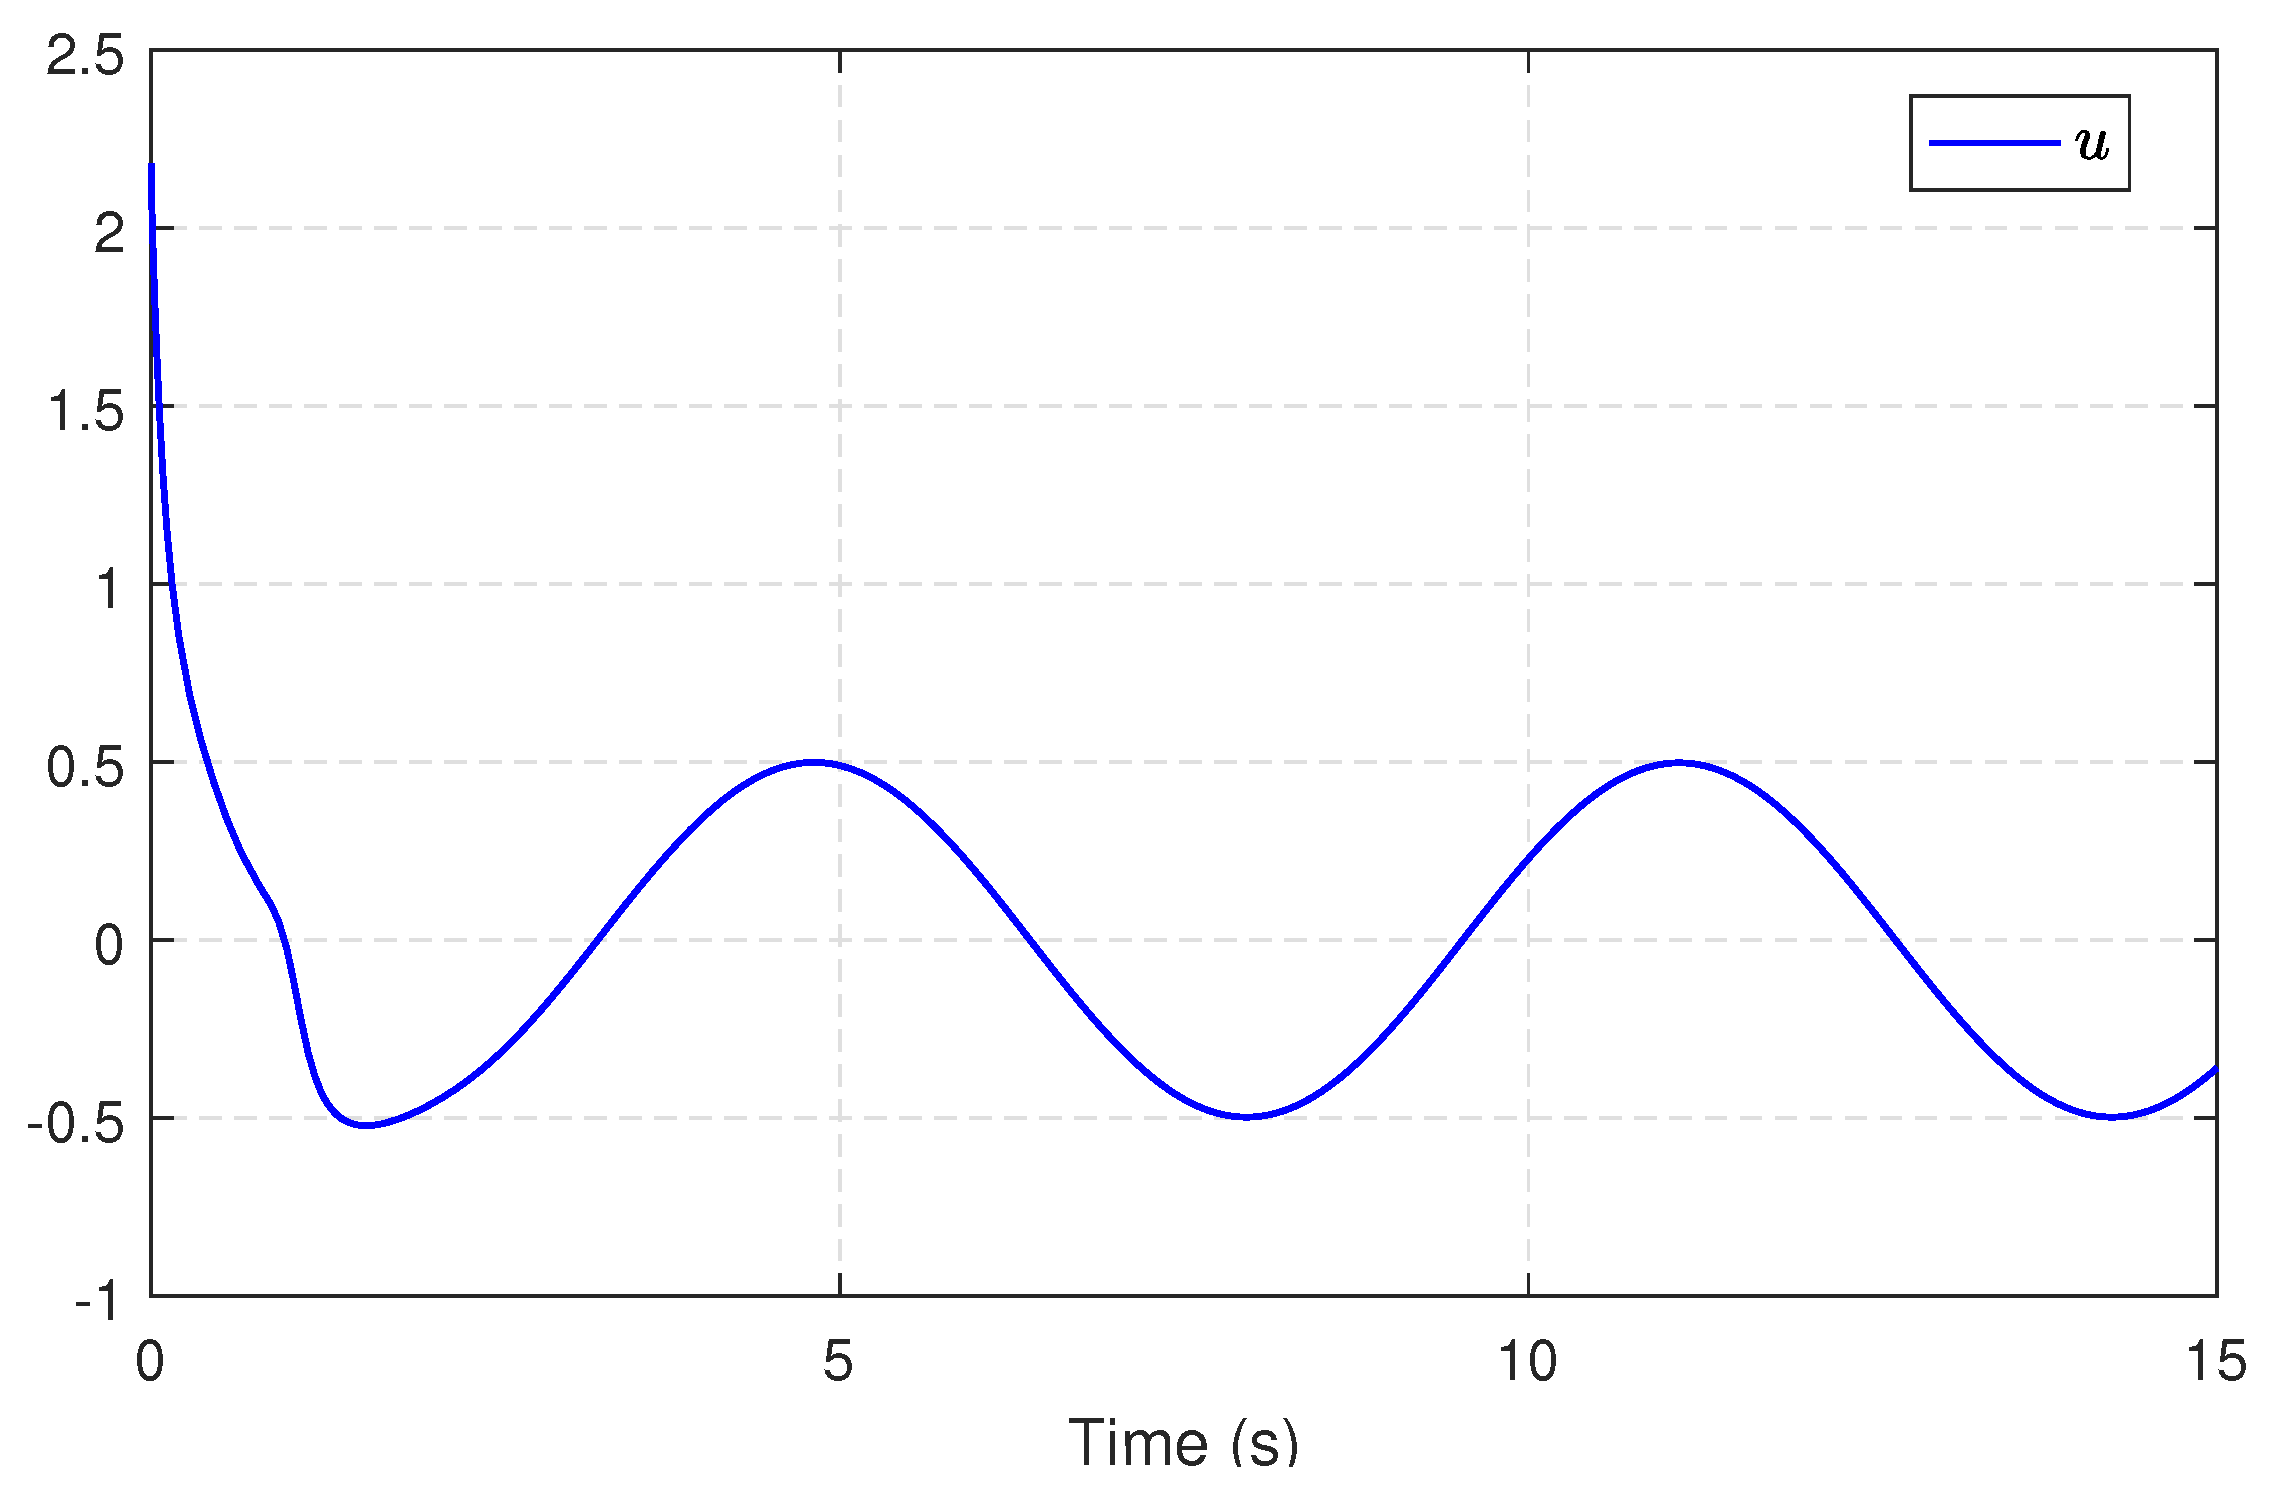
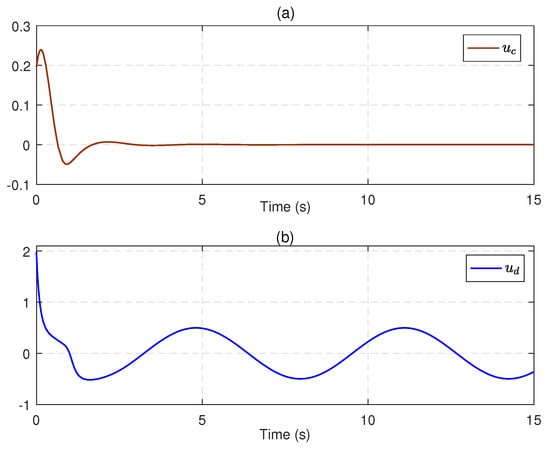
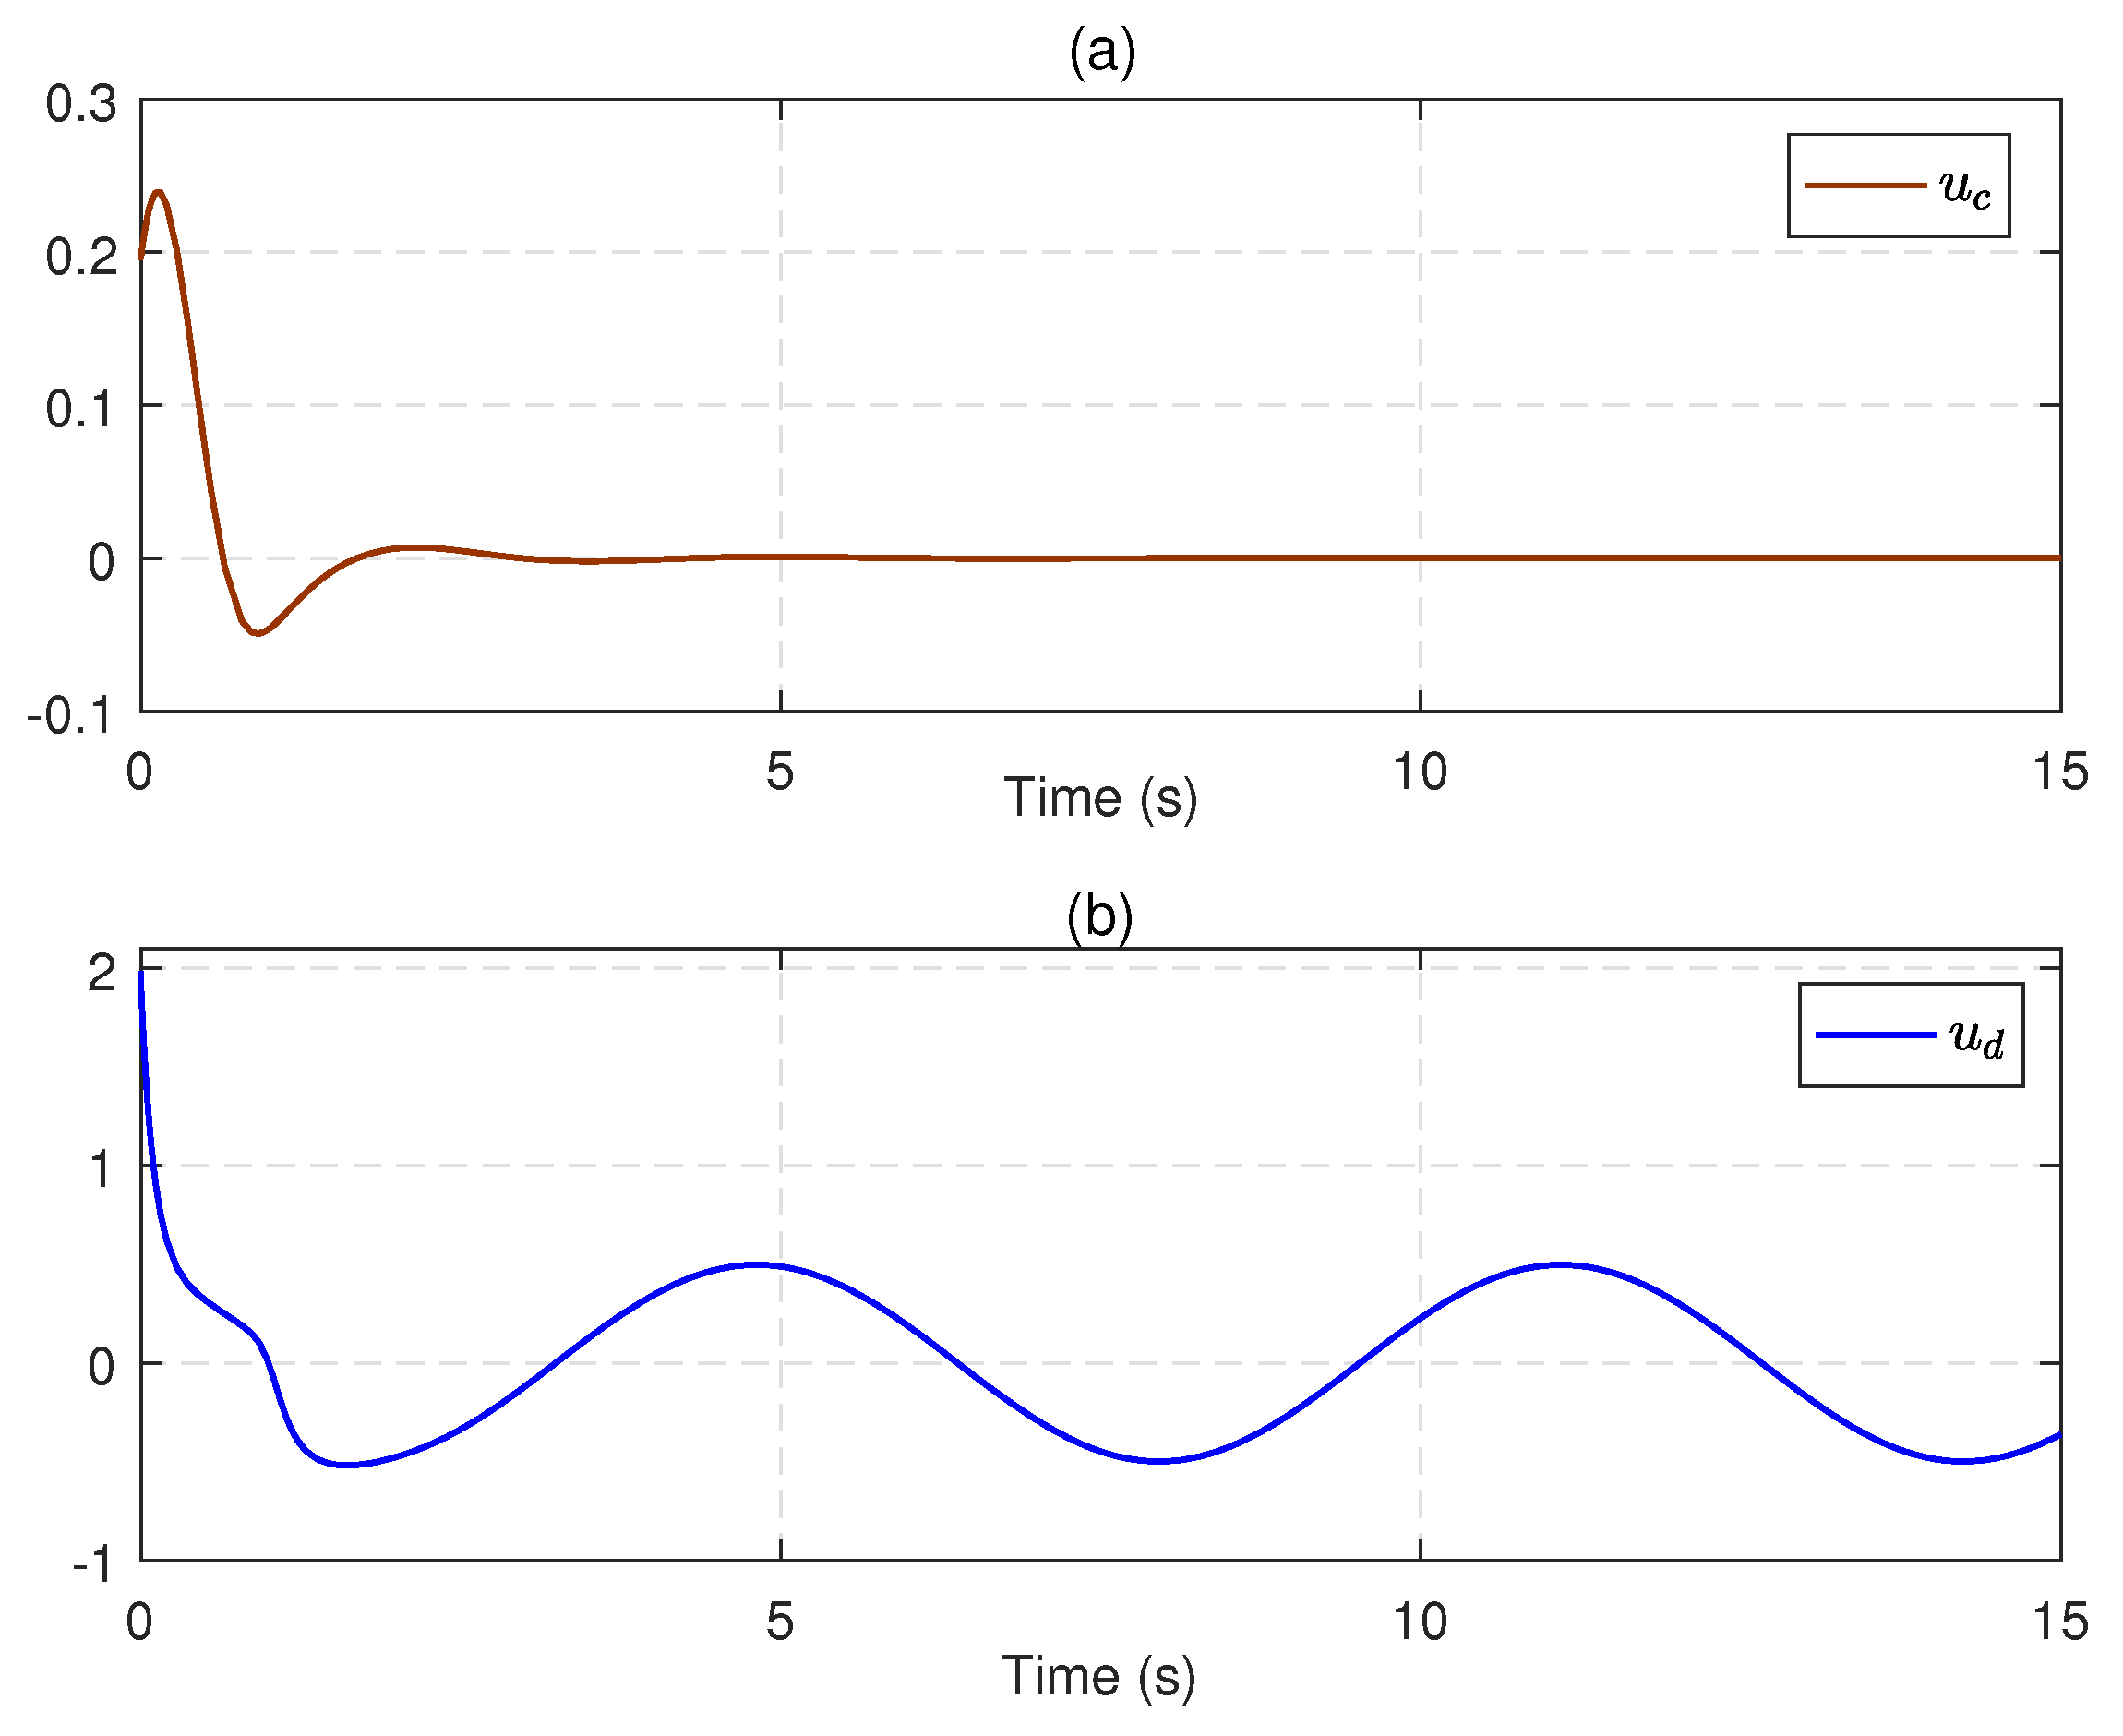
Next, we substitute into (21) to obtain an available sliding surface. Subsequently, integrating with the enhanced observer system, the SMC law is implemented by using (23) and (24) with the reliable estimations of uncertainties and disturbances. Figure 4 depicts the estimates of disturbances and , along with small estimation errors. Figure 5 presents the identifications of system states using the identifier NN. It can be observed that the identified states rapidly track the real states, illustrating the effectiveness and efficiency of the identifier NN. Note that the valid estimations and are used to design the SMC law , which helps to reduce the sliding-mode gain and alleviate the chattering phenomenon. Figure 6 displays the state trajectories of the robot arm under the compound sliding-mode control . Figure 7 depicts the compound control u, while the control and the SMC law are given in Figure 8. These results presented in Figure 6, Figure 7 and Figure 8 confirm that the compound control u successfully renders the robot arm system stable and exhibits satisfactory performance against both system uncertainties and external disturbances.
Figure 4.
(a) Real disturbance and its estimation , (b) Real disturbance and its estimation .
Figure 5.
(a) Real state and identified state , (b) Real state and identified state .
Figure 6.
State trajectories of the robotic arm.
Figure 7.
The compound control u.
Figure 8.
(a) The optimal control . (b) The SMC law .
5.2. Power Plant System
To further validate the effectivity of the proposed scheme, we consider an electric power system comprised of a gas turbine generator, a system load, and an automatic generation control [34]. To model this system, the incremental frequency deviation , the generator output power variation , and the valve position change of the governor are taken into consideration. The control input is represented by the speed change in position deviation. By defining the state vector , we can express the reduced power system model in state-space form as
where , represents the modeling uncertainty, and d stands for the exterior disturbances. Assume that the uncertain term is , and the disturbance term is defined as in the simulation. Let the regulation constant = 2.5 Hz/MW, the turbine gain constant = 1 s and the generator gain constant = 120 Hz/MW. Moreover, the corresponding time constants are set as = 0.08 s, = 0.1 s and = 20 s, respectively.
For estimating the unknown uncertainty and disturbance terms, the enhanced observer system is constructed as (6) with a three-layered feedforward NN containing eight hidden neurons and the Hurwitz matrix . The activation function, the initial weights, and the updating ratios are the same as in Section 5.1. Let , , and . Similarly, an arctangent function is used for designing the SMC law instead of the sign function .
Without the matched uncertainties and disturbances, we can derive the sliding-mode dynamics from (66), wherein , and the initial state . Let the associated cost function be of the form (32) along with , and . The critic NN is designed as (44) and its corresponding parameters are , , and . Similar to Section 5.1, , the initial weight vector is set to zero, and a similar probing noise is injected into the control input before 550 s. The evolving trajectories of the critic weights are shown in Figure 9, while the trajectories of system states in the learning are depicted in Figure 10. After 550 s, the critic weights converge to , then we can derive using (46) with the converged weights.
Figure 9.
Trajectories of the critic NN weights.
Figure 10.
Trajectories of system states in the learning.
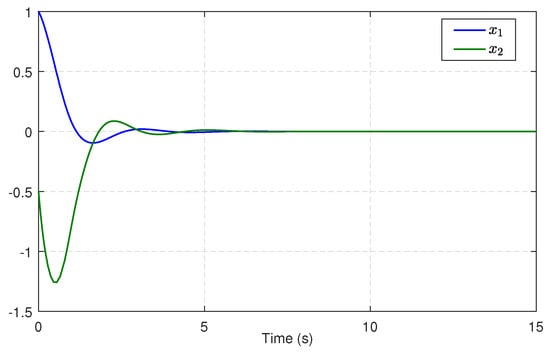
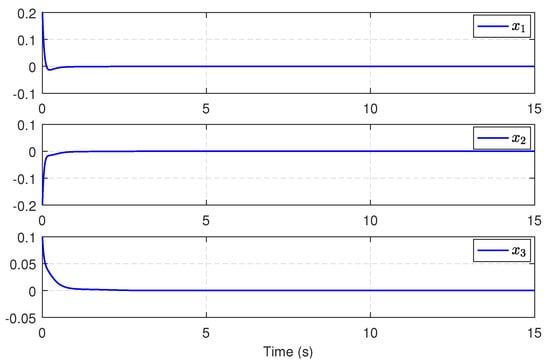
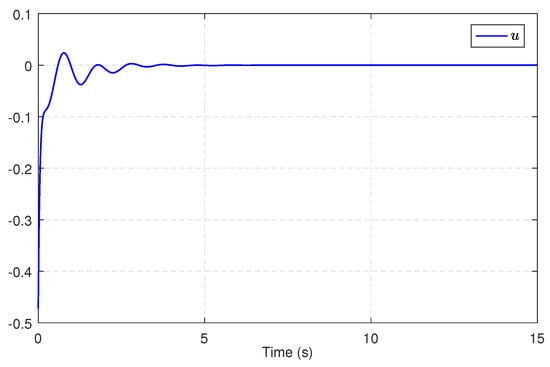
Then, we substitute into the integral sliding surface (21), and we design the SMC law by (23) and (24). Consequently, the compound control is constructed as . After simulation, Figure 11 shows the trajectories of the power system states under this compound control for 15 s. Figure 12 presents the compound control u. From Figure 11 and Figure 12, we can conclude that the compound control effectively stabilizes the system states to the equilibrium point, even in the presence of modeling uncertainties and exterior disturbances. These results undeniably demonstrate the viability and efficiency of the proposed approach.
Figure 11.
Trajectories of the electric power system.
Figure 12.
The compound optimal control.
6. Conclusions
In this paper, we develop a neural adaptive sliding-mode control scheme for uncertain nonlinear systems subject to external disturbances. Based on the enhanced observer system composed of the NN identifier and nonlinear DO, an integral SMC is designed for suppressing the influences of the uncertain term and the matched disturbance component, as well as unknown approximation errors, with no prior knowledge of their upper bounds. Meanwhile, on the sliding surface, the remaining unmatched disturbances are attenuated using the optimal control solved by the single critic network-based ADP algorithm. Furthermore, uniform ultimate boundedness stability of the resultant closed-loop system can be proven by Lyapunov’s method. In addition to the theoretical analysis, two simulation examples are provided to further validate the proposed approach. Recently, the growing interest in saving communication resources or reducing the calculation amount of networked control systems makes the event-triggering mechanism gain more and more attention and undergo rapid development. Hence, how to combine the optimal SMC strategy with the event-triggering mechanism for more complex physical systems, not just for control-affine systems, will be our future research topic.
Author Contributions
Y.H. contributed to the conception and design of this study, performed the experiment and the data analysis, and wrote the manuscript; Z.Z. contributed to the results discussion and the writing of the paper. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported in part by the Advanced Talents Incubation Program of Hebei University under Grant 521100221049, in part by Hebei Province Higher Education Science and Technology Research Project of China under Grant CXY2023009, in part by Hebei University Research and Innovation Team Project under Grant IT202306, and in part by Baoding Science and Technology Plan Project under Grant 2372P010.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The authors can confirm that all relevant data are included in the article.
Conflicts of Interest
The authors declare that they have no conflict of interest. All authors have approved the manuscript and agreed with submission to this journal.
References
- Ioannou, P.; Sun, J. Robust Adaptive Control; Prentice Hall: Upper Saddle River, NJ, USA, 1996. [Google Scholar]
- Utkin, V.; Guldner, J.; Shi, J. Sliding Mode Control in Electro-Mechanical Systems; CRC Press: Boca Raton, FL, USA, 2017. [Google Scholar]
- Yu, X.; Kaynak, O. Sliding-mode control with soft computing: A survey. IEEE Trans. Ind. Electron. 2009, 56, 3275–3285. [Google Scholar]
- Xu, J.; Guo, Z.; Tong, H. Design and implementation of integral sliding-mode control on an underactuated two-wheeled mobile robot. IEEE Trans. Ind. Electron. 2014, 61, 3671–3681. [Google Scholar] [CrossRef] [Scilit]
- Chen, L.; Edwards, C.; Alwi, H. Integral sliding mode fault-tolerant control allocation for a class of affine nonlinear system. Int. J. Robust Nonlinear 2019, 29, 565–582. [Google Scholar] [CrossRef] [Scilit]
- Pan, Y.; Yang, C.; Pan, L.; Yu, H. Integral sliding mode control: Performance, modification, and improvement. IEEE Trans. Ind. Inform. 2017, 14, 3087–3096. [Google Scholar] [CrossRef] [Scilit]
- Errouissi, R.; Ouhrouche, M.; Chen, W.; Trzynadlowski, A. Robust nonlinear predictive controller for permanent-magnet synchronous motors with an optimized cost function. IEEE Trans. Ind. Electron. 2012, 59, 2849–2858. [Google Scholar] [CrossRef] [Scilit]
- Huang, J.; Ri, S.; Fukuda, T.; Wang, Y. A disturbance observer based sliding mode control for a class of underactuated robotic system with mismatched uncertainties. IEEE Trans. Autom. Control 2019, 64, 2480–2487. [Google Scholar] [CrossRef] [Scilit]
- Cui, R.; Chen, L.; Yang, C.; Chen, M. Extended state observer-based integral sliding mode control for an underwater robot with unknown disturbances and uncertain nonlinearities. IEEE Trans. Ind. Electron. 2017, 64, 6785–6795. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Xie, X.; Chadli, M.; Xie, S.; Peng, Y. Sliding-mode control of fuzzy singularly perturbed descriptor systems. IEEE Trans. Fuzzy Syst. 2020, 29, 2349–2360. [Google Scholar] [CrossRef] [Scilit]
- Chen, M.; Chen, W. Sliding mode control for a class of uncertain nonlinear system based on disturbance observer. Int. J. Adapt. Control Signal Process 2010, 24, 51–64. [Google Scholar] [CrossRef] [Scilit]
- Rubagotti, M.; Estrada, A.; Castanos, F.; Ferrara, A. Integral sliding mode control for nonlinear systems with matched and unmatched perturbations. IEEE Trans. Autom. Control 2011, 56, 2699–2704. [Google Scholar] [CrossRef] [Scilit]
- Castanos, F.; Fridman, L. Analysis and design of integral sliding manifolds for systems with unmatched perturbations. IEEE Trans. Autom. Control 2006, 51, 853–858. [Google Scholar] [CrossRef] [Scilit]
- Kiumarsi, B.; Vamvoudakis, K.G.; Modares, H.; Lewis, F.L. Optimal and autonomous control using reinforcement learning: A survey. IEEE Trans. Neural Netw. Learn. Syst. 2018, 29, 2042–2062. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liu, D.; Wei, Q.; Wang, D.; Yang, X.; Li, H. Adaptive Dynamic Programming with Applications in Optimal Control; Springer: Cham, Switzerland, 2017. [Google Scholar]
- Lewis, F.L.; Liu, D. Reinforcement Learning and Approximate Dynamic Programming for Feedback Control; Wiley: Hoboken, NJ, USA, 2013. [Google Scholar]
- Ha, M.; Wang, D.; Liu, D. Discounted iterative adaptive critic designs with novel stability analysis for tracking control. IEEE/CAA J. Autom. Sin. 2022, 9, 1262–1272. [Google Scholar] [CrossRef] [Scilit]
- Wei, Q.; Lewis, F.L.; Liu, D.; Song, R.; Lin, H. Discrete-time local value iteration adaptive dynamic programming: Convergence analysis. IEEE Trans. Syst. Man Cybern. Syst. 2018, 48, 875–891. [Google Scholar] [CrossRef] [Scilit]
- Wei, Q.; Wang, L.; Lu, J.; Wang, F.Y. Discrete-Time Self-Learning Parallel Control. IEEE Trans. Syst. Man Cybern. Syst. 2022, 52, 192–204. [Google Scholar] [CrossRef] [Scilit]
- Heydari, A.; Balakrishnan, S. Finite-horizon control-constrained nonlinear optimal control using single network adaptive critics. IEEE Trans. Neural Netw. Learn. Syst. 2013, 24, 145–157. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Lu, J.; Wei, Q.; Wang, Z.; Zhou, T.; Wang, F. Event-triggered optimal control for discrete-time multi-player non-zero-sum games using parallel control. Inf. Sci. 2022, 584, 519–535. [Google Scholar] [CrossRef] [Scilit]
- Wang, D.; Ren, J.; Ha, M. Discounted linear Q-learning control with novel tracking cost and its stability. Inf. Sci. 2023, 626, 339–353. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.; Ni, Z.; He, H. A theoretical foundation of goal representation heuristic dynamic programming. IEEE Trans. Neural Netw. Learn. Syst. 2016, 27, 2513–2525. [Google Scholar] [CrossRef] [Scilit]
- Huang, Y.; Wang, D.; Liu, D. Bounded robust control design for uncertain nonlinear systems using single-network adaptive dynamic programming. Neurocomputing 2017, 266, 128–140. [Google Scholar] [CrossRef] [Scilit]
- Yang, X.; Wei, Q. Adaptive critic designs for optimal event-driven control of a CSTR system. IEEE Trans. Ind. Inform. 2021, 17, 484–493. [Google Scholar] [CrossRef] [Scilit]
- Yang, X.; He, H.; Zhong, X. Approximate dynamic programming for nonlinear-constrained optimizations. IEEE Trans. Cybern. 2021, 51, 2419–2432. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wen, G.; Niu, B. Optimized tracking control based on reinforcement learning for a class of high-order unknown nonlinear dynamic systems. Inf. Sci. 2022, 606, 368–379. [Google Scholar] [CrossRef] [Scilit]
- Wang, D.; Qiao, J.; Cheng, L. An approximate neuro-optimal solution of discounted guaranteed cost control design. IEEE Trans. Cybern. 2022, 52, 77–86. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liu, D.; Xue, S.; Zhao, B.; Luo, B.; Wei, Q. Adaptive dynamic programming for control: A survey and recent advances. IEEE Trans. Syst. Man Cybern. Syst. 2020, 51, 142–160. [Google Scholar] [CrossRef] [Scilit]
- Wang, D.; Ha, M.; Zhao, M. The intelligent critic framework for advanced optimal control. Artif. Intell. Rev. 2022, 55, 1–22. [Google Scholar] [CrossRef] [Scilit]
- Modares, H.; Lewis, F.L. Optimal tracking control of nonlinear partially-unknown constrained input systems using integral reinforcement learning. Automatica 2014, 50, 1780–1792. [Google Scholar] [CrossRef] [Scilit]
- Luo, B.; Wu, H.; Huang, T. Off-policy reinforcement learning for H∞ control design. IEEE Trans. Cybern. 2014, 45, 65–76. [Google Scholar] [CrossRef] [Scilit]
- Modares, H.; Lewis, F.L.; Jiang, Z. H∞ tracking control of completely unknown continuous-time systems via off-policy reinforcement learning. IEEE Trans. Neural Netw. Learn. Syst. 2015, 26, 2550–2562. [Google Scholar] [CrossRef] [Scilit]
- Wang, D.; He, H.; Liu, D. Adaptive critic nonlinear robust control: A survey. IEEE Trans. Cybern. 2017, 47, 3429–3451. [Google Scholar] [CrossRef] [Scilit]
- Mitra, A.; Behera, L. Continuous-time single network adaptive critic based optimal sliding mode control for nonlinear control affine systems. In Proceedings of the 34th Chinese Control Conference, HangZhou, China, 28–30 July 2015; pp. 3300–3306. [Google Scholar]
- Fan, Q.; Yang, G. Adaptive actor-critic design-based integral sliding-mode control for partially unknown nonlinear systems with input disturbances. IEEE Trans. Neural Netw. Learn. Syst. 2015, 27, 165–177. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Qu, Q.; Zhang, H.; Yu, R.; Liu, Y. Neural network-based H∞ sliding mode control for nonlinear systems with actuator faults and unmatched disturbances. Neurocomputing 2018, 275, 2009–2018. [Google Scholar] [CrossRef] [Scilit]
- Zhang, H.; Qu, Q.; Xiao, G.; Cui, Y. Optimal guaranteed cost sliding mode control for constrained-input nonlinear systems with matched and unmatched disturbances. IEEE Trans. Neural Netw. Learn. Syst. 2018, 29, 2112–2126. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yang, D.; Li, T.; Xie, X.; Zhang, H. Event-triggered integral sliding-mode control for nonlinear constrained-input systems with disturbances via adaptive dynamic programming. IEEE Trans. Syst. Man Cybern. Syst. 2019, 50, 4086–4096. [Google Scholar] [CrossRef] [Scilit]
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2023 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).