


Abstract
Tabletop role-playing game (TTRPG) research increasingly produces complex multimodal and multimedia evidence, including speech, audiovisual recordings, character sheets, maps, platform traces, session notes, game-state data, and retrospective documentation. However, the field lacks a stable methodological infrastructure for organizing, comparing, retrieving, and reusing these heterogeneous forms of play-derived evidence. This article presents a scoping review of 35 studies on computational, multimodal, multimedia, and knowledge-organization approaches to TTRPG-derived data. The findings show that this research is fragmented across publication venues, data types, analytical aims, and levels of formalization. Existing studies combine qualitative interpretation, discourse and conversation analysis, player-experience evaluation, structured datasets, natural language processing, semantic annotation, AI-assisted generation, and controlled vocabularies, but these approaches remain weakly coordinated across disciplinary vocabularies, data models, and formalization practices. To address this gap, the article proposes a Polyvocal Semantic Infrastructure for TTRPG research. Structured through a semantic atlas and scope ladder, this framework addresses persistent ambiguity in how objects and terms are defined across communities, systems, and disciplines while preserving interpretive plurality and supporting comparison, retrieval, provenance tracking, and future AI-assisted analysis of TTRPG-derived multimedia play data.
1. Introduction
Role-playing game (RPG) research increasingly produces complex multimedia and multimodal evidence, yet the field lacks stable infrastructures for organizing, comparing, retrieving, and reusing that evidence. A single game session may generate speech, gesture, character sheets, maps, rule references, dice outcomes, platform commands, audiovisual recordings, chat logs, digital assets, session notes, and retrospective narratives. These materials are not secondary traces of play. They participate in how play is produced, remembered, interpreted, and reused across sessions, campaigns, platforms, and research contexts. The central problem is that the richness of game-derived data has outpaced the field’s methodological infrastructure.
This article uses RPGs as an umbrella term for structured ludonarrative practices in which participants enact fictional roles through rules, narration, interaction, and shared interpretation. This broad category includes tabletop role-playing games (TTRPGs), live-action role-playing games (LARPs), actual play, virtual table-top (VTT) environments, computer role-playing games (CRPGs), massively multiplayer online role-playing games (MMORPGs), and hybrid role-playing practices that combine in-person and remote participation [1,2,3]. In the remainder of this article, these related but analytically distinct practices are referred to as adjacent RPG forms when they are discussed in relation to TTRPG-derived data. However, the primary object of this review is not RPGs in general. The review focuses on TTRPG-derived data, with particular attention to long-term campaigns, because these practices generate persistent, heterogeneous, and analytically demanding records of collaborative play.
TTRPGs are defined here as structured, collaborative role-playing practices in which participants generate fictional events through character action, rule interpretation, shared narration, and human adjudication. This definition distinguishes TTRPGs from adjacent forms while recognizing that their analytical problems often overlap. LARP emphasizes embodied performance and situated interaction within a shared diegetic frame [4]. CRPGs and MMORPGs implement role-playing conventions through computational systems. Actual play transforms play into mediated performance for external audiences. VTTs and hybrid formats introduce platform-mediated traces, including commands, chat logs, tokens, maps, and audiovisual records. These distinctions matter because each form produces different data types, yet methods and concepts often circulate across them without stable semantic alignment.
The need for this distinction is visible in work on controlled vocabularies and RPG classification. Smith [5] shows that existing vocabularies often fail to distinguish TTRPGs from board games, CRPGs, and works about RPGs. This problem is not merely bibliographic. When terms such as “role-playing game,” “campaign,” “scenario,” “world,” “mechanic,” or “player” shift across domains, researchers may lose clarity about what data are being analyzed, which methods are transferable, and what forms of infrastructure are required. Similar distinctions structure major field syntheses, including Role-Playing Game Studies: A Transmedia Approach [6] and The Routledge Handbook of Role-Playing Game Studies [7], where tabletop, live-action, digital, and transmedia forms are treated as related but analytically distinct.
This problem can be described as a double ontological problem. First, the same object of study may appear under several names. A researcher looking for “tabletop role-playing games” may encounter “role-playing games,” “tabletop roleplaying games,” “table-top role-playing games,” “Dungeons & Dragons,” “Dungeons and Dragons,” “analog role-playing games,” or other adjacent terms. Second, the same label may refer to different objects across cataloging systems, game communities, computational studies, educational research, therapeutic practice, and platform documentation. In practice, this means that a TTRPG source may become difficult to find not because it is absent, but because it has been classified through a different conceptual frame. A book about TTRPGs in an academic library may be indexed through categories closer to board games, recreational materials, or adjacent game taxonomies rather than as part of RPG studies. The problem is therefore not only terminological. It is ontological, infrastructural, and epistemic: what cannot be named consistently cannot be reliably retrieved, compared, or reused.
This article, therefore, treats terminology as a methodological problem. A vocabulary, taxonomy, ontology, or metadata scheme is not the phenomenon itself. It is a representational map that foregrounds some relations while obscuring others. Complex role-playing practices require attention to both component elements and larger systems [8,9]. RPGs make this problem especially acute because the same term may refer to a mechanic, artifact, genre, practice, social relation, digital object, or analytical category, depending on the level of observation. As Gary, Collins, Brata Winardy, and Septiana [10] suggest, role-playing is polysemic, and its structure varies according to the practice under examination.
Accordingly, this review uses TTRPG as the primary analytical category. LARP, Edu-LARP, actual play, VTTs, CRPGs, MMORPGs, therapeutic role-play (TRP), analog role-playing games (ARPG), and hybrid practices are included only when they contribute transferable data types, analytical procedures, methodological frameworks, or knowledge-organization practices relevant to TTRPG-derived data. The review does not attempt to describe every form of play-derived data in RPG studies. Instead, it asks how play-derived data in TTRPGs, especially long-term campaigns, are organized, analyzed, retrieved, and interpreted.
TTRPGs matter to multimedia research because they generate heterogeneous evidence across narrative, procedural, audiovisual, interactional, material, and platform-dependent layers. Contemporary studies examine TTRPGs as collaborative storytelling systems, pedagogical environments, therapeutic interventions, multimodal communication ecologies, computational narrative environments, and sites of identity negotiation [11]. Recent work on large language models, fantasy-domain named-entity recognition (NER), structured gameplay datasets, AI-supported Game Masters, knowledge-driven scenario generation, and controlled vocabularies has increased interest in TTRPGs as both cultural artifacts and computationally tractable systems [12]. These studies show that TTRPGs are not only objects of cultural analysis; they are also testbeds for studying how narrative, interaction, rules, media, and data structures interact.
Despite this growth, the field remains semantically and methodologically fragmented. Existing studies often examine isolated dimensions of play, such as narrative structure, player experience, computational assistance, therapeutic intervention, learning outcomes, digital mediation, or cataloging. Fewer studies provide a shared methodological infrastructure for connecting session data, player interaction, knowledge organization, computational analysis, and multimedia evidence. As a result, the same artifact may be interpreted as a ruleset, performance event, learning artifact, computational state, social interaction, audiovisual record, platform trace, or bibliographic object, depending on the research tradition. This instability complicates discoverability, metadata alignment, corpus comparison, computational analysis, and long-term preservation.
The problem is analogous to cataloging a TTRPG rulebook. The same object may be treated as a book, game, fantasy text, performance script, reference manual, teaching resource, collectible artifact, or special-collection item. None of these classifications is simply wrong, but each makes the object visible through a different system of retrieval and interpretation. TTRPG research faces the same problem: without a way to preserve multiple classifications and their provenance, the same play artifact becomes difficult to compare, retrieve, or reuse across studies.
The problem becomes more visible when computational methods are introduced, because computational analysis depends on stable representations of entities, actions, rules, scenes, and context. Grounded gameplay datasets suggest that narrative interpretation improves when systems can draw on structured contextual information. Fantasy-domain natural language processing (NLP) likewise shows that general-purpose models struggle with domain-specific entities unless they are supported by specialized annotation and semantic adaptation. Knowledge-driven generation systems depend on structured representations to maintain coherence across narrative and procedural layers. The same representational problem appears in multimodal educational research, where transcripts, journals, interviews, audiovisual recordings, gameplay logs, and observational data must be connected without reducing them to a single data type. Together, these studies indicate a common limitation: TTRPG research lacks interoperable semantic infrastructure capable of preserving both computational consistency and interpretive flexibility.
This study responds to that limitation through a scoping review of computational, multimodal, multimedia, and knowledge-organization approaches used to analyze TTRPG-derived data. The central research question is as follows: what methods, techniques, infrastructures, and semantic frameworks are currently used to organize, analyze, retrieve, and interpret play-derived data in TTRPG research? The review follows Preferred Reporting Items for Systematic Reviews and Meta-Analyses informed transparency practices, uses the Sample, Phenomenon of Interest, Design, Evaluation, Research type (SPIDER) to specify the phenomenon of interest, evidence type, design logic, and research scope, and synthesizes a final corpus of 35 sources through extraction, research-question alignment, corpus distribution analysis, and keyword co-occurrence mapping. The protocol was registered through the Open Science Framework (OSF) to support traceability and procedural transparency.
The contribution of this article is methodological and infrastructural. Rather than claiming that TTRPGs have not been studied, we argue that existing studies remain distributed across fields that do not yet share a common methodological vocabulary for Multimedia Play Data. We define Multimedia Play Data as the layered, situated, collaborative, and technically mediated evidence generated through role-playing activity. This operational definition includes speech, audiovisual media, rules artifacts, character materials, platform traces, structured game states, annotations, metadata, and retrospective documentation. The review shows that these data are increasingly analyzed through qualitative, computational, multimodal, and knowledge-organization methods, but that these methods remain weakly coordinated across vocabularies, data models, and formalization practices.
To address this gap, the paper proposes a Polyvocal Semantic Infrastructure (PSI). We define PSI as a provenance-aware knowledge-organization framework that coordinates multiple vocabularies, interpretive strata, and semantic mappings without reducing them to a single authoritative ontology. PSI is designed to preserve plurality while enabling retrieval, comparison, reuse, and AI-assisted analysis across heterogeneous forms of TTRPG-derived Multimedia Play Data (Supplemental Material PPT1).
The PSI is operationalized through a semantic atlas and a scope ladder. The semantic atlas coordinates heterogeneous vocabularies, interpretive strata, provenance records, and semantic mappings (Supplemental Material PPT2). The scope ladder organizes concepts by provenance, authority, and visibility across review-scoped vocabularies, group-scoped vocabularies, source-paper vocabularies, and external named vocabularies or authority systems. The purpose is not to impose a universal ontology of RPGs. Instead, the PSI preserves interpretive plurality while supporting comparison, retrieval, provenance tracking, reuse, and future AI-assisted analysis.
This contribution has three dimensions. Theoretically, the paper reframes TTRPG-derived data as Multimedia Play Data that connect narrative, interaction, material artifacts, platform traces, audiovisual evidence, and retrospective interpretation. Methodologically, it synthesizes how existing studies extract, classify, formalize, normalize, and interpret play-derived evidence. Practically, it identifies requirements for semantic infrastructures that can support future work in TTRPG studies, AI-assisted analysis, digital humanities, game studies, multimedia research, and knowledge organization.
To provide a high-level overview of the study’s analytical contribution, Figure 1 summarizes both the four analytical dimensions identified in the corpus and the overall architecture of the proposed PSI. On the left, the figure presents the fragmentation problem addressed in this review across publication ecosystems, data types, analytical purposes, and levels of formalization. In the center, it outlines the PSI as a coordinating infrastructure built around two complementary components—the semantic atlas and the scope ladder—designed to preserve analytical plurality while supporting structured comparison. On the right, the figure highlights the main functions enabled by this architecture, including comparison, retrieval, provenance tracking, reuse, and AI-assisted analysis (see Figure 1).
Figure 1.
From fragmented Multimedia Play Data to a coordinating infrastructure: the four analytical dimensions of the corpus and the architecture of the proposed PSI, including its two core components, the semantic atlas and the scope ladder.
A central operation in this framework is the transformation of metadata into data. Descriptions, classifications, provenance records, semantic mappings, normalization decisions, and interpretive levels are not treated as secondary administrative information. They are treated as evidence for analysis because they show how different communities define, organize, relate, retrieve, and reuse role-playing knowledge. This shift is especially important for multimedia research, where the interpretive value of complex evidence depends on how its contexts, relations, transformations, and provenance are documented.
The remainder of the article is organized as follows. Section 2 reviews related work on TTRPG studies, computational tools, multimodal analysis, player experience, and knowledge organization. Section 3 presents the conceptual framework that informs the semantic atlas and PSI. Section 4 describes the materials and methods, including the review rationale, research question, search strategy, selection process, extraction matrix, reporting approach, and quality appraisal. Section 5 presents the results across corpus distribution, publication ecosystems, data types, methodological infrastructures, analytical purposes, terminological instability, formalization practices, co-occurrence analysis, and emerging tensions. Section 6 discusses the implications for multimedia research, TTRPG studies, computational analysis, semantic infrastructure design, and provenance-aware knowledge organization. Section 7 concludes by outlining the study’s contributions, limitations, and future research directions.
2. Related Work
The literature relevant to this review can be organized into four overlapping clusters: role-playing as narrative and performance, role-playing in applied educational and therapeutic contexts, computational support for role-playing systems, and knowledge organization for role-playing materials. These clusters do not represent separate fields in practice. They identify recurring research traditions that address different aspects of the same methodological problem: how to interpret, measure, formalize, and retrieve data produced through role-playing activity.
2.1. Role-Playing as Collaborative Narrative, Performance, and Authorship
A first body of work examines role-playing as an emergent form of collaborative narrative, performance, authorship, and social interaction [13,14,15,16]. This literature establishes that role-playing is not a fixed textual object but a situated activity produced through participants, rules, characters, frames, artifacts, and audiences. Its central contribution is conceptual: it shows that the object of analysis is not only the fictional story but also the interactional process through which that story becomes playable, meaningful, and memorable.
Studies of actual play extend this problem by showing how private or semi-private play becomes recorded, edited, circulated, and adapted for spectators. In these cases, role-playing data are transformed into durable media artifacts, including audio recordings, video episodes, transcripts, fan archives, graphic adaptations, and platform-based commentary. This transformation matters for multimedia research because the session no longer functions only as an event. It becomes a mediated object whose narrative, audiovisual, and paratextual layers can be analyzed across different levels of production and reception.
2.2. Role-Playing in Educational, Therapeutic, and Developmental Contexts
A second body of work examines TTRPGs, LARP, Edu-LARP, and analog games in educational, therapeutic, and developmental contexts [17,18,19,20]. These studies investigate learning, communication, collaboration, empathy, identity, metacognition, social skills, and psychological intervention [21,22]. Their relevance to this review is not limited to applied outcomes. They also show that role-playing generates complex evidence across cognitive, affective, social, narrative, and procedural dimensions.
This literature exposes a measurement problem. Role-playing interventions often unfold across sessions, characters, groups, artifacts, and reflective materials. As a result, researchers must relate heterogeneous evidence, such as session transcripts, field notes, journals, surveys, audiovisual recordings, character materials, and participant reflections. These studies therefore demonstrate both the value of role-playing as a learning or therapeutic environment and the difficulty of standardizing data produced through situated, longitudinal, and collaborative play.
2.3. Computational and AI-Supported Approaches to Role-Playing Data
A third body of work develops computational and AI-supported approaches to role-playing data within the broader field of artificial intelligence in games [23,24]. This cluster includes language-model support for Game Masters, structured game-state datasets, NLP, fantasy-domain NER, semantic annotation, procedural content generation, AI Game Masters, and knowledge-driven scenario generation [25,26]. These studies position RPGs as testbeds for computational creativity, dialog modeling, interactive narrative, and human–AI co-creation.
Their methodological importance lies in the need for contextual stability. Computational systems cannot reliably process or generate role-playing content when entities, actions, rules, scenes, player states, and fictional-world relations remain underspecified [27,28]. Work on language models and game-state representation suggests that computational performance improves when systems can access structured information about characters, actions, rules, and context. Similarly, fantasy-domain NLP shows that general-purpose models require domain-specific annotation and semantic adaptation to handle invented names, specialized categories, and fictional-world relations. These studies show that computational support depends not only on model capability but also on the availability of well-structured semantic infrastructure.
2.4. Metadata, Controlled Vocabularies, and Knowledge Organization
A fourth body of work concerns metadata, controlled vocabularies, ontologies, semantic annotation, and knowledge organization [29]. This literature is central to the present review because role-playing materials are difficult to retrieve, classify, compare, and reuse. Terms such as TTRPG, TRPG, RPG, LARP, actual play, role-play, scenario, campaign, adventure, session, and game system circulate across academic, community, platform, and cataloging contexts with inconsistent meanings.
Smith [5] is especially important because it shows that existing vocabularies often fail to describe TTRPGs with sufficient precision. The problem includes deficient definitions, weak hierarchical structures, and inadequate disambiguation between subject terms and genre/form terms. This lack of precision has direct implications for research infrastructure. If role-playing materials cannot be consistently named, scoped, and related, then they become difficult to discover, compare, preserve, or integrate into computational workflows. Knowledge organization is, therefore, not a peripheral cataloging concern. It is part of the methodological infrastructure required for multimedia TTRPG research.
2.5. Synthesis: From Separate Literatures to Shared Infrastructure
These four clusters answer different disciplinary questions. Narrative and performance studies ask how role-playing events produce stories, authorship, and meaning. Educational and therapeutic studies ask how participation supports learning, reflection, or psychosocial change. Computational studies ask how systems can process, generate, or support role-playing content. Knowledge-organization studies ask how role-playing materials can be named, classified, retrieved, and preserved. This separation is useful when each field studies a narrow object with stable boundaries.
The separation becomes less adequate when the object is multimedia play data. A recorded TTRPG session may simultaneously function as a performance, a learning environment, a conversational dataset, a multimodal interaction, a narrative artifact, a platform-mediated event, and a candidate for semantic annotation. A character sheet may operate as a rule interface, identity document, game-state record, and computational data source. A campaign recap may serve as memory work, narrative compression, community documentation, and metadata for future play. These examples show that TTRPG-derived data often exceed the categories used to study them.
The gap, therefore, is not an absence of literature. The gap is the absence of a connective methodological vocabulary across data types, analytical procedures, and formalization practices. Existing approaches tend to optimize for local disciplinary goals, including interpretation, assessment, intervention, system performance, metadata consistency, or ontology design. Few frameworks explain how these approaches can be coordinated when the same play materials must be analyzed, formalized, retrieved, and reused across research contexts. This review addresses that gap by synthesizing methods and infrastructures that can support a more interoperable approach to TTRPG-derived multimedia data.
3. Conceptual Framework
This study treats TTRPG-derived data as a problem of semantic coordination rather than simple classification. Role-playing materials often occupy several analytical positions at once. A campaign session, for example, may be examined as narrative production, rules enactment, pedagogical interaction, social exchange, computational state, audiovisual record, or archival artifact. These readings are not mutually exclusive. They become problematic only when one interpretive framework is treated as sufficient for all others. This problem aligns with Smith’s [5] analysis of controlled vocabularies, which shows that inadequate definitions, weak hierarchical structures, and unstable distinctions between subject and genre/form terms can reduce the discoverability and analytical precision of TTRPG materials.
The framework begins from the principle of PSI. This type of infrastructure preserves multiple interpretive frameworks while making their relations explicit. This position aligns with knowledge-graph research showing that structured knowledge bases can support information retrieval, question answering, NLP, semantic search, entity retrieval, and knowledge injection into language models [30]. Rather than requiring one vocabulary to function as a universal authority, the framework allows distinct vocabularies, ontologies, and classificatory schemes to coexist as linked but non-collapsed systems. This vocabulary is essential for RPG studies because disagreement often reflects disciplinary perspective rather than error.
This principle is especially important for AI-assisted analysis. Retrieval-Augmented Generation (RAG) depends on providing AI systems with semantically organized contextual information rather than relying only on model-internal representations. Knowledge graphs can supply entities, relations, taxonomies, provenance, and constraints that make retrieval more precise and interpretation more accountable. Domain-specific models such as Graphs and Ontologies for Literary Evolution Models (GOLEM) [31], and broader knowledge bases such as Yet Another Great Ontology (YAGO 4.5) [30], illustrate why structured semantic context matters. AI systems cannot reliably reason over role-playing data if characters, actions, rules, scenes, player states, fictional entities, and source relations remain underspecified.
The second principle is disagreement-as-data. When one field treats “campaign” as a narrative unit, another as a pedagogical intervention, and another as a persistent game-state structure, the difference should not be normalized away automatically. The disagreement identifies a meaningful shift in analytical purpose. Preserving this shift allows researchers to examine how concepts travel, narrow, broaden, or change across disciplinary, technical, and community contexts.
The third principle is stratum theory. A stratum is an interpretive layer that specifies how a concept is being read within a given semantic scheme. The foundational axiom is that one thing can be many things. A “character,” for example, may function as a fictional person, a player character, a rules object, a narrative role, a performance identity, or a session participant. Multi-cardinality is therefore the default condition: a concept can inhabit several identities, schemes, classifications, and interpretive stances at once. Single-cardinality is not inherent to the entity. It is a contextual constraint applied only when a specific research question requires it. In the same way, a rulebook may be read as an artifact, a rules system, a narrative generator, a bibliographic object, or a source of computational entities. Strata make these readings explicit without requiring one interpretation to displace the others (see Figure 2).
Figure 2.
Conceptual model of stratum-based semantic coordination for TTRPG-derived data.
The fourth principle is scheme-aware querying. Queries should not assume that all classifications belong to one hierarchy. Instead, data should be retrieved relative to the scheme, stratum, and provenance through which they were produced. A term classified as a mechanic in one scheme may appear as a narrative procedure, interaction protocol, or pedagogical scaffold in another. Scheme-aware querying preserves the interpretive conditions under which a classification was made and reduces the risk of false equivalence across research traditions.
The fifth principle is ontological coexistence. External vocabularies and ontologies are not absorbed into a single master system. They remain distinct semantic systems connected through typed mappings such as exact match, close match, broad match, narrow match, and related match. This structure enables comparison without erasure. It also allows contested definitions to remain visible, traceable, and queryable.
The proposed semantic “atlas” operationalizes these principles by combining configurable stratum schemes, provenance-aware mappings, definitional stance relations, and semantic links grounded in established knowledge-organization frameworks. These include the Simple Knowledge Organization System (SKOS), the Simple Knowledge Organization System eXtension for Labels (SKOS-XL), the Provenance Ontology (PROV-O), the International Committee for Documentation Conceptual Reference Model (CIDOC CRM), and the Library Reference Model object-oriented formulation (LRMoo) [32]. The purpose of the semantic atlas is not to impose a universal ontology of RPGs. Its purpose is to preserve interpretive plurality while supporting comparison, retrieval, and reuse across heterogeneous TTRPG-derived data.
This conceptual framework guides the review design that follows. Section 4 explains how the scoping review was specified, registered, searched, screened, and structured to identify the data types, analytical methods, and knowledge-organization practices currently used to study TTRPG-derived multimedia data.
4. Materials and Methods
This section describes the review method as a transparent and reproducible procedure, rather than only as a general research design. The methodological account specifies the unit of analysis, selection criteria, screening procedures, extraction instruments, data-processing plan, and validity considerations used to identify, exclude, code, appraise, and synthesize records. This level of procedural detail is necessary because the review maps a heterogeneous field composed of peer-reviewed articles, computational studies, methodological papers, datasets, and semantic artifacts, rather than evaluating the effectiveness of a single intervention, tool, or computational model.
This study uses a scoping review with evidence mapping to examine how data derived from tabletop role-playing games (TTRPGs) are transformed into analyzable evidence. The review follows the OSF-registered protocol (see Data Availability Statement), which defines the study as a scoping review of academic and multivocal sources that use computational, multimodal, multimedia, or knowledge-organization approaches to analyze TTRPG data and data from methodologically adjacent forms of role-playing.
The review centers on TTRPG data. Adjacent RPG forms were included only when they contributed transferable data types, methods, tools, analytical frameworks, or knowledge-organization practices relevant to TTRPG analysis. This scope preserved the review’s focus while recognizing that methodological innovations relevant to TTRPG-derived data are distributed across multiple role-playing traditions.
A scoping review was appropriate because the literature is methodologically dispersed across game studies, education, psychology, human–computer interaction (HCI), artificial intelligence, NLP, library and information science, digital humanities, performance studies, and design research. The review did not estimate intervention effectiveness, compare treatments, or produce a meta-analysis. Instead, it mapped source types, data types, analytical methods, computational tools, terminology, formalization practices, and methodological gaps across a heterogeneous corpus.
The review followed the five-stage structure commonly used in scoping review methodology: (1) research question identification, (2) identification of relevant literature, (3) study selection, (4) data extraction/charting, and (5) reporting of results [33,34]. The process was informed by PRISMA 2020 and by the Preferred Reporting Items for Systematic Reviews and Meta-Analyses Extension for Scoping Reviews (PRISMA-ScR), which emphasize transparent reporting of protocol registration, eligibility criteria, information sources, search strategy, source selection, data charting, appraisal when applicable, and synthesis procedures [35,36]. A completed PRISMA-ScR checklist is provided as Supplementary Material Word Document S3. SPIDER was used as a conceptual guide to specify the sample, phenomenon of interest, design logic, evaluation dimensions, and research types included in the review [37].
4.1. Methodological Rationale
The review was designed to identify and synthesize how recent RPG studies analyze play-derived data through qualitative, computational, multimodal, multimedia, or knowledge-organization methods. Play-derived data were defined as materials generated through, around, or from role-playing activity, including transcripts, audiovisual recordings, images, maps, character sheets, rules references, platform records, game-state data, session artifacts, digital interactions, and retrospective documentation.
The methodological rationale was not to determine whether role-playing “works” as an intervention, learning activity, or design tool. Rather, the review examined how researchers make role-playing data available for analysis. Accordingly, the eligibility criteria in Table 1 were designed to identify sources that were relevant to this methodological aim: sources that address TTRPG or transferable analog/hybrid role-playing contexts, work with multimedia or play-derived materials, and provide an identifiable method, tool, framework, dataset, semantic vocabulary, or knowledge-organization formThe criteria therefore guided the selection of records capable of showing what materials are studied, what methods are used, what analytical purposes guide those methods, how key terms are operationalized, and what gaps limit comparison, reuse, retrieval, or cumulative knowledge-building.
Table 1.
Operationalization of the Inclusion and Exclusion Criteria (Eligibility).
A preliminary exploratory search conducted on 30 April 2026 was used to refine the search logic before formal retrieval. This exploratory stage identified false positives caused by acronyms shared across unrelated fields. In particular, searches using LARP and TRPG retrieved records unrelated to role-playing games, including uses of LARP for Ligand-Assisted Reprecipitation Technique and TRPG for tricuspid regurgitation peak gradient. These findings informed the exclusion terms used in the formal search strings (see Table 1, Eligibility 10). Screening decisions, however, were based on contextual relevance and eligibility criteria rather than keyword presence alone. The complete exploratory-search log, final database-specific search strings, syntax adaptations, exclusion terms, search dates, and record counts are provided in Supplementary Material Word Document S1. This Supplementary File distinguishes exploratory searches from formal retrieval searches so that readers can trace how the final search strategy was developed.
4.2. Research Question Identification
The following central question guides the review:
RQ1. How have qualitative, computational, multimodal, multimedia, and knowledge-organization methods been used to analyze play-derived data in role-playing game studies?
This question operationalized the OSF-registered protocol for the manuscript. It focused the review on data types, analytical procedures, tools, infrastructures, terminological patterns, levels of formalization, and methodological gaps.
The central question was addressed through eight sub-questions:
RQ1.1. What types of sources, formats, and publication channels constitute recent production on the analysis of RPGs and related play-derived data?
RQ1.2. What types of textual, audio, audiovisual, digital, multimodal, multimedia, or play-derived materials are most frequently analyzed?
RQ1.3. What methods, techniques, tools, or analytical frameworks are used to study these materials?
RQ1.4. What analytical purposes guide the use of these methods, techniques, or tools in the included sources?
RQ1.5. What concepts, descriptors, keywords, and terminological patterns show the greatest frequency, centrality, or relevance within the identified corpus?
RQ1.6. What levels of formalization, standardization, or knowledge organization appear in the included sources, including taxonomies, ontologies, knowledge graphs, controlled vocabularies, or SKOS-compatible structures?
RQ1.7. What role do immersion, game mechanics, and character play as objects of analysis within the included sources, and how are they related to collaboration, agency, and narrative co-creation?
RQ1.8. What methodological gaps, thematic concentrations, visibility biases, or retrieval limitations emerge from the analyzed corpus?
4.3. Identifying Relevant Literature
The search and selection process proceeded in three stages. First, a preliminary exploratory search was conducted to test keyword performance, identify false positives, and refine exclusion terms before formal retrieval (see Supplementary Material Word Document S1). Second, the formal search focused on sources published in English or Spanish between 2023 and 2026, reflecting the study’s emphasis on recent methodological developments in RPG studies, including generative AI, semantic annotation, knowledge graphs, controlled vocabularies, structured gameplay datasets, and ontology-oriented approaches (see Supplementary Material Word Document S2). Third, expert-recommended sources were reviewed for methodological relevance. Although the exploratory searches applied a broader “last five years” database filter (2021–2026), the final corpus retained only four foundational 2021–2022 sources recommended by the content expert because of their direct relevance to the review’s methodological focus.
The search strategy was developed using SPIDER as a conceptual guide rather than as a rigid eligibility filter. SPIDER informed the relationship between the review question, the source types, and the search vocabulary. The sample dimension defined the relevant role-playing contexts; the phenomenon of interest focused on the analysis, organization, formalization, or computational processing of play-derived data; the design dimension included empirical, conceptual, methodological, technical, and review-based work; the evaluation dimension covered data types, analytical processes, tools, frameworks, terminology, and levels of formalization; and the research-type dimension allowed qualitative, quantitative, mixed-methods, theoretical, computational, technical, gray, and multivocal literature.
Related search terms were then organized into three Boolean blocks. The first block identified role-playing-related sources using terms such as TTRPG, TRPG, D&D, LARP, actual play, VTT, ARPG, and analog games. D&D was retained as a seed term because preliminary searches showed that relevant TTRPG literature does not always use TTRPG or TRPG explicitly. The second block captured analytical, multimedia, multimodal, computational, and knowledge-organization concepts, including analysis, multimodal analysis, multimedia analysis, transcript analysis, annotation, ontology, knowledge graph, controlled vocabulary, semantic annotation, NLP, NER, machine learning, visualization, qualitative analysis, and mixed methods. The third block consisted of exclusion terms used to reduce false positives caused by acronym ambiguity.
Exclusions were applied only when necessary and were documented by database, interface, date, search string, filters, and number of records retrieved. Full search strings, database-specific syntax adaptations, search dates, filters, exclusion terms, and retrieval counts are provided in Supplementary Material Word Document S2.
The main databases searched were PubMed, Scopus, Web of Science, and Google Scholar. PubMed was used initially to test Boolean syntax and identify acronym ambiguity. Scopus served as the principal interdisciplinary database because it covered computer science, multimedia studies, education, HCI, digital humanities, and game studies. Web of Science complemented Scopus coverage, and Google Scholar was used to identify sources that may not be consistently indexed in conventional databases.
Supplementary strategies were used to improve coverage. These included backward citation searching, forward citation searching, review of highly cited articles, searches of doctoral theses and dissertations, and citation mapping with tools such as Litmaps (Source: https://www.litmaps.com/, accessed on 6 May 2026) when appropriate. Gray and multivocal sources were eligible when they provided methodological, analytical, terminological, technical, or knowledge-organization value. These sources included technical documentation, open repositories, project websites, blogs, podcasts, videos, wikis, forums, and community-based materials.
After the primary search, Primo, ProQuest, and the Directory of Open Access Journals (DOAJ) were consulted as supplementary discovery environments at the recommendation of a content expert. The content expert also recommended additional books and seminal works, resulting in 25 additional resources added to the review corpus. These sources were included only when they met the same criteria of relevance, traceability, accessibility, and methodological contribution used for the primary corpus.
Sources were excluded when RPGs were mentioned only incidentally, metaphorically, or as a secondary example; when they focused exclusively on workplace role training, clinical role-play, simulation, gamification, or strictly digital RPGs without methodological transferability to tabletop, analog, or hybrid role-playing analysis; when no play-derived data, multimedia material, computational method, analytical framework, or knowledge-organization contribution could be identified; or when the full text or sufficient metadata could not be retrieved.
The complete search strategy is provided in Supplementary Material Word Document S2. This file reports the database-specific search strings, syntax adaptations, filters, date limits, exclusion terms, search dates, and record counts used to support reproducibility. The OSF registration separately documents the review protocol, search dates, filters, exclusion terms, and retrieval counts. Additional deposited materials include the preliminary 163-source database exports, the final 35-source corpus exports, and the semantic vocabulary files in JSON-LD and Turtle formats (see Supplementary Files DB1–DB4). The manuscript also includes four appendices that support source-level traceability and auditability: Appendix A, Evidence Matrix, containing Table A1, Evidence Matrix Linking Major Findings to Primary Sources; Appendix B, Source-Level Extraction Matrix; Appendix C, Source-Level Research-Question Alignment Matrix; and Appendix D, Included Sources by First Author in Alphabetical Order. These appendices are distinct from the Supplementary Materials. Supplementary Material Word Document S3, documents compliance with PRISMA-ScR reporting requirements, while the remaining Supplementary Files contain screening documentation, corpus exports, search materials, and semantic vocabulary outputs. References throughout the manuscript have been revised to distinguish clearly between the manuscript appendices and the external Supplementary Files.
4.4. Paper Selection Process
The selection process followed the OSF-registered protocol, which defined the SPIDER fields, eligibility criteria, extraction dimensions, and review questions before formal screening. Sources were eligible when they addressed RPGs in one or more relevant forms and provided methodological, analytical, computational, multimodal, multimedia, or knowledge-organization relevance.
After database and supplementary searches, all records were imported into the review-management workflow and checked for duplicates. Duplicate records were removed or merged before title and abstract screening. Screening decisions were managed through a group-verdict workflow. Individual reviewer triage decisions were promoted into formal group decisions. Records with unanimous agreement were advanced or excluded through bulk action, while records with disagreement or uncertainty were reserved for manual resolution. No unresolved conflicts remained after reconciliation.
Title and abstract screening excluded records that clearly fell outside the review scope. Records were excluded at this stage when they mentioned RPGs only tangentially, focused on unrelated forms of role-play or simulation, lacked methodological relevance, or did not address play-derived data, analytical methods, computational techniques, multimodal materials, or knowledge-organization practices. Records were retained for full-text review when eligibility could not be determined confidently from the title and abstract alone.
Full-text retrieval was conducted as a distinct PRISMA stage. The team verified DOI accuracy, retrieval status, and access to the full text. Retrieval outcomes were documented to support the PRISMA categories “reports sought for retrieval” and “reports not retrieved.” Full-text sources were assessed against the protocol’s eligibility criteria. Sources were excluded when the full text could not be retrieved, the document was inaccessible because of availability constraints, the record was retracted, or the full text showed that the source did not meet the review criteria.
The identification stage produced 302 records from database searches and 32 additional records identified through expert recommendation and other sources, for a total of 334 records before duplicate management. After duplicates were removed, 163 records were retained for title and abstract review. The screening was conducted using the eligibility criteria previously discussed in Table 1, and 126 records were excluded at this stage. A total of 37 full-text items were then assessed for eligibility. Two full-text items were excluded during quality appraisal: one did not use, describe, or analyze multimedia, multimodal, digital, or play-derived materials, and one lacked sufficient retrievable text or metadata, was not a complete text, or exceeded the 150-page threshold. The final corpus therefore consisted of 35 sources included in the evidence synthesis, as summarized in Figure 3.
Figure 3.
PRISMA flow diagram for study identification, screening, and inclusion.
To clarify the selection process beyond the aggregate screening statuses shown in Figure 3, exclusions were organized into substantive categories rather than treated only as workflow labels. Records were excluded when they fell outside the tabletop or hybrid role-playing scope of the review, focused primarily on digital-only RPGs or software systems without transferable relevance to TTRPG data practices, lacked sufficient methodological or semantic contribution, duplicated another record, or could not provide extractable information for the SPIDER and alignment matrices. The exclusion categories and counts were checked against the PRISMA flow diagram and the supplementary screening documentation to ensure consistency between the manuscript and the Supplementary Materials.
To coordinate this process across collaborators, we developed a lightweight web-based triage environment that supported three review-management functions: triage queue monitoring, group-verdict consolidation, and full-text retrieval tracking. The triage queue provided a shared overview of record status during screening; the group-verdict workflow supported transparent reconciliation of inclusion and exclusion decisions; and the full-text retrieval module documented which records had been retrieved, remained pending, or required eligibility review. These tools were used to make screening decisions explicit, auditable, and consistent across the team before final inclusion in the 35-source corpus. An additional methodological output of this work is the web application and its accompanying JSON-based workflow structure, which may be reused or adapted by other researchers to manage study identification, screening, eligibility, and inclusion processes in future scoping reviews or evidence-mapping projects.
Figure 4, Figure 5 and Figure 6 document the three workflow components used to coordinate source selection. Figure 4 shows the triage queue used to monitor screening status across the review. Figure 5 presents the group-verdict workflow used to consolidate collaborative screening decisions. Figure 6 shows the full-text retrieval and eligibility workflow used to track records entering the final stage of corpus selection.
Figure 4.
Triage queue interface used to monitor review-level screening status across total, included, excluded, and undecided records.
Figure 5.
Group-verdict workflow used to consolidate collaborative screening decisions and support transparent inclusion and exclusion judgments.
Figure 6.
Full-text retrieval and eligibility workflow used to track retrieved, pending, unretrievable, and re-screened records prior to final corpus inclusion.
4.5. Full-Text Eligibility Assessment
Table 2 reports the primary exclusion categories used to document the 128 records excluded from the corpus after duplicate management. Of these, 126 records were excluded during title and abstract screening. Because some records could meet more than one exclusion condition, each record was assigned one primary exclusion reason according to the criterion most directly responsible for exclusion. These counts were reconciled with the PRISMA flow diagram and the supplementary screening documentation to ensure consistency across the manuscript and Supplementary Materials.
Table 2.
Exclusion Categories and Record Counts.
4.6. Data Extraction
Data extraction was conducted using a structured SPIDER extraction matrix developed from the OSF-registered protocol, the review questions, and the planned evidence-mapping outputs. The matrix recorded, for each included source, the methodological and conceptual features required to synthesize how RPG studies analyze play-derived data. The extraction process followed PRISMA-ScR items 14 and 15 by specifying the data items sought from each source and documenting the extraction logic used to populate the review database (see Figure 7). The full source-level extraction matrix is provided in Appendix B. The matrix documents how each included source was coded across key analytical dimensions, including methods, data types, and gaps identified. This appendix functions as an audit trail linking the narrative synthesis to the evidence extracted from individual sources.
Figure 7.
SPIDER Extraction Matrix for Coding Included Sources [34,38,39].
Each included source was entered as one row in the extraction matrix. The columns represented the main analytical dimensions of the review: Paper, immersion, mechanics, character, relation, narrative, methods, data_types, knowledge_organization, and gaps_identified. These dimensions corresponded to the review questions and allowed the team to document how each source treated play-derived data, methodological procedures, RPG-specific constructs, and formalization practices.
The Paper column recorded bibliographic identity. The immersion column captured references to immersion, presence, engagement, embodiment, role adoption, and related experiential constructs. The mechanics column documented rules, dice systems, action resolution, character statistics, state tracking, and other procedural elements. The character column recorded how player characters, non-player characters, avatars, roles, or identities were conceptualized. The relation column captured interpersonal, interactional, social, collaborative, or player–system relations.
The narrative column documented treatment of story, authorship, worldbuilding, campaign continuity, actual play, scenario design, or co-created fiction. The methods column recorded qualitative, computational, review-based, design-based, or technical approaches, including discourse analysis, conversation analysis, narrative analysis, scoping review, NLP, NER, semantic annotation, machine learning, and generative AI. The data_types column captured transcripts, audiovisual recordings, Discord logs, Avrae commands, character sheets, maps, structured game states, survey data, interview data, platform traces, technical documentation, and community materials. The knowledge_organization column recorded metadata, controlled vocabularies, taxonomies, ontologies, semantic relations, SKOS-compatible structures, knowledge graphs, annotation schemes, datasets, and formalized categories. The gaps_identified column captured limitations, unresolved problems, methodological constraints, representational biases, retrieval challenges, and future research needs.
Extraction was performed at the source level. Each paper was treated as the primary unit of analysis, even when it contained several methods, data types, or conceptual objects. When a source addressed multiple dimensions, information was recorded across relevant columns. When a dimension was not addressed, the field was left blank rather than inferred. This decision preserved the distinction between explicitly reported information and reviewer interpretation.
The matrix supported both descriptive mapping and interpretive synthesis. Descriptive extraction recorded what each source explicitly reported. Interpretive notes were limited to concise statements clarifying how the source contributed to the review categories. This separation reduced overinterpretation while allowing cross-source comparison.
Human reviewers made all extraction decisions. Digital tools were used to organize the matrix, manage records, track completion, and preserve decision history, but they did not make extraction decisions autonomously. Ambiguous or incomplete entries were flagged for later verification. The final extraction database functioned as both an analytic record and an audit trail linking each included source to the review’s evidence-mapping outputs.
4.7. Quality Appraisal
Quality appraisal used a source-sensitive assessment strategy because the corpus included empirical, conceptual, methodological, technical, community-based, practice-based, and gray-literature sources. The purpose of the appraisal was not to rank sources by disciplinary prestige or exclude sources because they were non-empirical. Instead, the appraisal assessed whether each source provided sufficient methodological clarity, evidentiary support, and relevance to contribute to the synthesis.
For empirical studies, appraisal focused on the clarity of the research question, the fit between the design and aim, the adequacy of the data source or sample, the transparency of the collection and analysis procedures, and the coherence between the evidence and the claims. For qualitative studies, attention was given to analytic transparency, contextual grounding, and the adequacy of the evidence supporting the interpretation. For computational and technical studies, appraisal emphasized reproducibility, clarity of data sources, explicitness of methods, tool or model description, and relevance to the analysis or formalization of play-derived data. For conceptual, methodological, and multivocal sources, appraisal focused on relevance, traceability, analytic rigor, and contribution to terminology, data organization, or methodological understanding.
Table 3 summarizes the source-sensitive quality-appraisal logic used during full-text assessment. Because the corpus included diverse sources, the appraisal did not apply a single hierarchy of evidence. Instead, it assessed whether each source provided sufficient transparency, relevance, and extractable information to support reliable coding into the SPIDER extraction matrix, research-question alignment matrix, and evidence map.
Table 3.
Quality-Appraisal Logic Used During Full-Text Assessment.
Quality appraisal was therefore treated as a fitness-for-extraction assessment rather than a ranking of methodological superiority. Scope-based exclusions referred to records that did not address TTRPG, analog, or hybrid role-playing data practices in a transferable way. Quality-related exclusions referred to full-text records that were topically adjacent but lacked sufficient methodological transparency, extractable data, retrievable content, or alignment with the review’s multimedia, multimodal, digital, or play-derived data focus. This distinction separated records excluded because they fell outside the review scope from records excluded because they could not support reliable coding into the extraction, alignment, or evidence-mapping matrices.
Each source was assessed in relation to the central question and eight subquestions. Appraisal considered whether the source contributed to at least one of the review dimensions: data type, analytical method, computational technique, multimedia or multimodal material, formalization practice, knowledge-organization structure, terminology, or methodological gap. Sources that addressed RPGs but did not provide sufficient methodological, analytical, computational, or knowledge-organization relevance were not retained for the final corpus.
Quality appraisal primarily determined interpretive weight in the synthesis. Sources with clear methods, explicit data descriptions, transparent procedures, and strong alignment with the review questions were treated as stronger evidence. Sources with limited reporting or narrower relevance were retained only when they contributed useful contextual, terminological, or methodological insight. When a source was relevant but methodologically thin, its limitations were documented and taken into account during synthesis.
The appraisal was conducted after title and abstract screening, full-text retrieval, and initial eligibility assessment. Of the 37 sources that reached final appraisal, two theses were excluded because they did not meet the threshold for methodological relevance and extractable contribution to the evidence-mapping aims. The final corpus consisted of 35 included sources, which were carried forward into the SPIDER extraction matrix and the research-question alignment matrix (see Table 4).
Table 4.
Quality Appraisal Exclusions.
This appraisal strategy aligns with the review’s purpose: to map the methodological infrastructure of RPG research rather than evaluate a single intervention or produce pooled outcome estimates. It preserved distinctions between stronger and weaker forms of evidence while allowing the review to represent the interdisciplinary and multivocal character of RPG studies. Removing these last two items brought the total number of final papers to 35 (see Figure 3).
4.8. Reporting Final Results
The final results were reported through descriptive statistics, matrix-based evidence mapping, and interpretive synthesis. Three reporting instruments structured the synthesis. The PRISMA flow diagram documented movement from identification to final inclusion. The SPIDER extraction matrix captured the substantive features of each source. The research-question alignment matrix showed how each paper contributed to the review’s eight analytical subquestions.
To support transparent evidence mapping, the authors developed a research-question alignment matrix (Figure 8). Each row represented one included source, and each column represented one review sub question. Each source-sub question cell was coded using a four-level relevance scheme: Absent, Primary, Secondary, and Mention. Absent indicated that the source did not meaningfully address the sub question. Primary indicated that the sub question was a central focus. Secondary indicated relevant but non-central treatment. Mention indicated a brief or indirect reference. The full research-question alignment matrix is provided in Appendix C. The matrix records how each included source contributed to the review subquestions using four relevance levels: Absent, Mention, Secondary, and Primary. This appendix supports transparency by showing how the synthesis was connected to source-level evidence rather than derived only from narrative interpretation.
Figure 8.
Research-Question Alignment Matrix for Included Sources [5,40].
The alignment matrix served three reporting functions. First, it identified which subquestions were most strongly represented across the corpus. Second, it cross-checked the extraction matrix against the review questions to ensure alignment between protocol and synthesis. Third, it made visible where the literature was concentrated, partial, or thin. The matrix, therefore, functioned as an intermediate analytical tool between extraction and narrative synthesis.
4.9. Semantic Vocabulary Outputs
In addition to the extraction and alignment matrices, the review generated machine-readable semantic vocabulary outputs to support reuse, provenance tracking, and future ontology development. These outputs include a Turtle (TTL) file and a JavaScript Object Notation for Linked Data (JSON-LD) file containing classes, instances, concept schemes, labels, mappings, and metadata associated with the semantic vocabulary developed during the review. The files are deposited in the OSF folder for digital ontologies and are treated as supplementary evidence of the review’s knowledge-organization process. Their purpose is not to replace the narrative synthesis, but to make the emerging vocabulary inspectable, reusable, and extensible for future semantic atlas development (see Supplementary Materials DB5 and DB6).
5. Results
The review identified a fragmented but increasingly connected methodological landscape for the analysis of TTRPG-derived data. Across the final corpus, sources varied by publication type, disciplinary orientation, data modality, analytical purpose, and degree of formalization. The central finding is that RPG studies employ a wide range of qualitative, computational, multimodal, multimedia, and knowledge-organization methods; however, these methods remain unevenly coordinated across research traditions, data models, and vocabularies.
Figure 9 summarizes the data-analysis workflow used to transform the final 35-source corpus into the descriptive, methodological, terminological, and infrastructural results reported in this section. After corpus preparation and full-text extraction, the sources were organized into a shared evidence base and analyzed through four coordinated procedures: descriptive mapping, data and method analysis, terminology and formalization analysis, and synthesis for infrastructure design. These procedures generated the evidence map, comparison framework, semantic vocabulary outputs, reusable workflow, and conceptual infrastructure presented below.
Figure 9.
Data-Analysis Workflow for the Scoping Review.
To make the corpus structure explicit, Table 5 reports the distribution of the 35 included sources. Publication type, publication year, and primary RPG scope are mutually exclusive categories. Methodological/thematic and applied/evidentiary categories are reported according to the primary classification assigned during extraction. The results reported in this section are based on three source-level audit tools. Appendix B provides the extraction matrix documenting methods, data types, and gaps identified for each included source. Appendix C provides the research-question alignment matrix, which records whether each source addressed each review subquestion as a primary focus, secondary focus, brief mention, or absent. Appendix D lists the 35 included sources in alphabetical order by first author to support corpus-level transparency and cross-reference. Together, these appendices link the narrative synthesis to the evidence extracted from individual sources.
Table 5.
Compact Corpus Distribution of the Final Included Sources (n = 35).
The distribution shows that the final corpus is balanced between conference papers and journal articles, with conference papers representing 45.7% of the corpus and journal articles representing 42.9%. The concentration of publications in 2023 and 2025 reflects the recent growth of computational, AI-supported, educational, therapeutic, and knowledge-organization work on RPG data. The thematic distribution also supports the review’s central claim: the corpus is not organized around a single methodological tradition. TTRPG/D&D-centered sources dominate the corpus, but substantial proportions of the included sources address computational, AI, NLP, or technical methods (37.1%), qualitative or interpretive analysis (34.3%), and knowledge organization or formalization (28.6%). This distribution supports the need for an infrastructure capable of coordinating heterogeneous evidence across computational, interpretive, applied, and semantic traditions. A more granular extraction-based count of methods, data types, frameworks, and analytical purposes is provided in Supplementary File DB1, a CSV of all 163 sources (see Supplemental Materials). These records constitute the discovery and reference-management library only; all reported findings derive from the 35 included sources.
Table 6 compares the review and synthesis studies included in the corpus. The table summarizes each study’s review type, scope, search strategy, inclusion and exclusion logic, synthesis approach, and contribution. Quality-appraisal procedures are reported separately in Section 4.8 because appraisal was used methodologically as a source-sensitive fitness-for-extraction procedure rather than as a result category.
Table 6.
Comparison of Review and Synthesis Studies Included in the Corpus.
Table 7 situates the present review in relation to three review and synthesis studies included in the corpus. Together, these sources show that adjacent review traditions have examined computational tools for TTRPGs, therapeutic uses of TTRPGs, and analog games in learning. However, they do not directly address the combined methodological problem examined in this study: how computational, multimodal, multimedia, and knowledge-organization methods make TTRPG-derived play data analyzable, retrievable, comparable, and reusable. The present review therefore extends prior synthesis work by treating data type, method, analytical purpose, terminology, and formalization as interconnected dimensions of a shared infrastructural problem.
Table 7.
Emerging Methodological Patterns.
Table 8 reports the major methodological patterns identified across the final corpus. Three patterns stand out. Computational and AI/NLP methods cluster around structured, machine-readable data such as game states, platform logs, and character sheets; qualitative and interpretive methods predominate for narrative, discourse, and player-experience data; and knowledge-organization work remains comparatively isolated from both. The scarcity of studies that bridge these clusters is itself a central finding, because it shows that the field has developed multiple analytical repertoires without a shared infrastructure for coordinating them. To preserve readability in the main text, the full source-to-finding evidence mapping is provided in Appendix A, Table A1, which identifies the primary sources supporting each major finding.
Table 8.
Data Modalities and Associated Analytical Methods.
Taken together, the results indicate that TTRPG-derived data are increasingly treated as layered evidence. The same play materials may be analyzed as narrative interaction, learning evidence, player experience, computational state, platform trace, audiovisual performance, or semantic resource. This multiplicity is productive, but it also creates challenges for retrieval, comparison, formalization, and reuse.
5.1. Distribution Across Publication Ecosystems
Research on RPG data is distributed across interdisciplinary and multivocal publication ecosystems rather than a single disciplinary venue. Relevant sources appeared in conference proceedings, journal articles, theses, book sections, datasets, technical papers, platform documentation, and actual play media. This distribution shows that TTRPG-derived data are not contained within one field, database, or publication genre.
This dispersion has methodological consequences. No single database, vocabulary, or indexing system captures the relevant literature sufficiently. Sources relevant to TTRPG-derived data appear in game studies, education, psychology, HCI, AI, NLP, digital humanities, library and information science, and practice-based communities. Effective retrieval, therefore, requires search strategies that combine academic databases, citation tracking, technical venues, community documentation, and platform-based sources.
This finding answers the first review sub question by showing that the corpus is not only interdisciplinary but also infrastructurally dispersed. The dispersion itself becomes part of the methodological problem because search terms, indexing practices, source types, and disciplinary vocabularies vary across the publication ecosystem.
5.2. Multimedia and Multimodal Data
The corpus shows that TTRPG research analyzes several forms of play-derived evidence. These include spoken interaction, transcripts, campaign notes, audiovisual recordings, Discord logs, VTT traces, maps, character sheets, structured game states, platform commands, and retrospective documentation. These data types differ in analytical affordance and cannot be treated as interchangeable records of the same event.
Spoken interaction supports conversation analysis, discourse analysis, and analysis of turn-taking, framing, and role-switching. Textual records enable narrative coding, NER, semantic extraction, and evidence mapping. Structured game states support modeling, prediction, and machine learning. Audiovisual media preserve gesture, pacing, tone, embodiment, and performance. Material artifacts, including maps, dice, and character sheets, require interpretive and digitization procedures. Platform traces, including Discord logs and VTT actions, enable interaction analysis and behavioral analytics.
The evidence map, therefore, indicates that TTRPG-derived data operate across narrative, procedural, audiovisual, material, social, and computational layers. Table 8 summarizes the main data modalities and the methods typically associated with them.
The main implication is that TTRPG research increasingly requires multimodal and multimedia infrastructure. A transcript alone may preserve dialog but lose gesture, pacing, tone, map interaction, dice use, interface action, and material context. Conversely, audiovisual evidence may preserve performance but remain difficult to retrieve, compare, or computationally process without structured metadata and annotation.
5.3. Methods, Techniques, and Analytical Frameworks
The reviewed studies used hybrid methodological infrastructures rather than a single dominant method. Qualitative approaches included discourse analysis, conversation analysis, narrative analysis, ethnography, design-based research, and interpretive coding. Computational approaches included NLP, NER, semantic annotation, structured dataset design, machine learning, and AI-assisted generation.
This pattern suggests that computational methods increasingly coexist with qualitative interpretation. They do not replace human analysis. Instead, they require interpretive grounding to define relevant entities, actions, relations, player states, fictional-world references, rules, and contexts. Conversely, qualitative analysis increasingly benefits from structured data management, annotation, and evidence-mapping procedures as corpora grow larger, become multimodal, or are platform-mediated.
A second pattern concerns the degree of formalization. Some sources remain primarily descriptive, while others introduce coding schemes, annotation structures, controlled vocabularies, structured datasets, or AI-oriented knowledge representations. Table 9 summarizes the levels of formalization identified across the corpus.
Table 9.
Levels of Formalization in the Corpus.
5.4. Analytical Purposes
The analytical purposes of the included sources clustered around five functions: facilitation, evaluation, learning, intervention, and generation. Facilitation studies examined tools that support Game Masters, players, designers, or research teams. Evaluation studies focused on player experience, system usability, immersion, interaction quality, and learning outcomes. Educational and therapeutic studies analyzed role-playing as a context for development, communication, collaboration, metacognition, or psychological intervention. Computational studies examined role-playing as a testbed for dialog modeling, narrative generation, entity extraction, state modeling, and human–AI co-creation.
These purposes show that TTRPGs are no longer treated only as narrative artifacts. They are also analyzed as applied interaction systems, learning environments, computational domains, therapeutic contexts, and knowledge-organization problems. The same empirical material may support more than one analytical purpose. For example, a recorded session may function as conversational data, educational interaction, narrative artifact, platform-mediated event, and structured game-state record.
This multi-functionality strengthens the case for semantic infrastructure. When the same material can be used for several forms of analysis, researchers need a way to preserve the conditions under which the material was classified, interpreted, and reused.
5.5. Terminological Instability
Terminological instability emerged as a major methodological issue. Terms such as RPG, TTRPG, TRPG, LARP, actual play, campaign, scenario, immersion, agency, adventure, session, mechanic, and game system circulate across academic, community, platform, and cataloging contexts with inconsistent meanings.
This instability affects more than vocabulary choice. It shapes retrieval, corpus construction, interoperability, and comparison. Controlled vocabulary studies show that existing classification systems often struggle to distinguish TTRPGs from CRPGs, theatrical role-play, training simulations, board games, or works about TTRPGs. Scenario-based studies similarly show that terms used across domains may appear shared while carrying different operational meanings.
The review, therefore, identifies terminology as a methodological condition of analysis. Without explicit definitions, search terms, and classification criteria, studies risk retrieving inconsistent corpora, comparing non-equivalent objects, or formalizing concepts whose meanings differ across contexts. This finding directly supports the need for scheme-aware and provenance-aware approaches to vocabulary design.
5.6. Formalization and Knowledge Organization
Formalization practices ranged from informal description to machine-readable knowledge structures. At the informal level, studies used ethnographic or narrative interpretation without explicit schemas. Semi-structured approaches introduced thematic coding, qualitative matrices, and evidence-mapping tools. More formal approaches used entity tagging, semantic labeling, structured datasets, controlled vocabularies, taxonomies, and semantic relations. The most computationally integrated sources used structured knowledge to support AI-assisted generation, model evaluation, or game-state representation.
This range shows that the field is moving from descriptive categorization toward computationally usable structures. However, the transition remains uneven. Some sources formalize local datasets without making them interoperable. Others prioritize generation, retrieval, or prediction without preserving interpretive context. Knowledge-organization work addresses this problem more directly by showing how definitions, categories, and semantic relations affect discoverability and reuse.
The result supports the need for a PSI. As part of this formalization process, the review produced two machine-readable vocabulary outputs: a TTL representation and a JSON-LD representation of the semantic vocabulary. These files document the transition from extraction categories and conceptual mappings into reusable semantic structures. They include classes, instances, concept schemes, labels, and provenance-oriented metadata that support future implementation of the semantic atlas. Their inclusion strengthens the evidence that the review’s contribution is not only interpretive but also infrastructural. The problem is not simply that TTRPG research lacks formalization. Rather, existing forms of formalization are difficult to align across schemes, data models, disciplinary vocabularies, and analytical purposes. A semantic infrastructure for this field must therefore support comparison without collapsing local meanings into a single universal ontology.
5.7. Emerging Tensions
The corpus revealed five recurring tensions. First, narrative richness versus computational structure: formalization improves comparison, retrieval, and reuse but may reduce narrative and interpretive nuance. Second, accessibility versus methodological rigor: community-generated sources increase visibility and access but complicate validation and provenance. Third, human improvisation versus AI assistance: AI systems can support Game Masters and researchers but may over-structure practices that depend on improvisation, ambiguity, and local judgment. Fourth, D&D availability versus representational diversity: Dungeons & Dragons provides highly visible and processable datasets, but its dominance may bias the field toward fantasy-centric, English-language, and commercially prominent systems while other TTRPGs and adjacent analog forms remain less represented. Fifth, retrieval breadth versus terminological precision: broad search terms improve recall but also increase false positives and semantic noise (see Table 10).
Table 10.
Tensions Emerging Across the Corpus.
These tensions suggest that TTRPG research is entering a transitional methodological phase. The field increasingly produces multimedia and multimodal evidence, yet existing methods remain difficult to integrate across retrieval, analysis, annotation, preservation, and computational reuse. The final tension—retrieval breadth versus terminological precision—was examined further through keyword co-occurrence analysis in VOSviewer (version 1.6.18).
The analysis used full counting and identified 743 keywords across the final corpus. A minimum threshold of five occurrences per keyword resulted in 24 keywords meeting the inclusion criterion. Before generating the visualization, internal coding labels used during the review process, such as CGE, Sample, _First run, and other workflow-specific terms, were excluded because they did not represent substantive concepts in the literature.
The co-occurrence analysis supports the review’s broader argument about traceability and terminological instability by showing that several concepts appeared under multiple lexical variants. For example, “Dungeons & Dragons,” “Dungeons and Dragons,” and “Dungeon & Dragon” were normalized as Dungeons and Dragons (D&D); “role playing game” and “role-playing games” as role-playing game (RPG); and “tabletop roleplaying game,” “tabletop role-playing game,” and “tabletop role-playing games” as “table-top role-playing game (TTRPG)”. Similar normalization was also required for adjacent forms and platforms, including “Massively Multiplayer Online Role-Playing Game (MMORPG)”, “educational live-action role-playing games (Edu-LARP)”, “therapeutic role-play (TRP)”, “virtual table-top (VTT)”, “live-action role-playing games (LARP)”, and “analog role-playing game (ARPG)”.
This normalization is analytically important because keyword variation is not merely orthographic; it affects retrieval, corpus construction, bibliometric mapping, and semantic comparison. In information retrieval, such variation represents a form of vocabulary mismatch: lexically distinct but semantically equivalent forms can reduce recall, distort precision, and fragment conceptually related records across a corpus [53]. From a corpus-methods perspective, normalization also requires transparent decisions about how acronymic, hyphenated, pluralized, and domain-specific variants are merged, counted, and interpreted [54,55]. The need for these normalization procedures therefore reflects both terminological instability in TTRPG scholarship and a methodological requirement for reproducible semantic analysis. The VOSviewer (version 1.6.18) analysis thus supports the review’s central finding that TTRPG-related research lacks stable semantic alignment across publication venues and disciplinary vocabularies and provides empirical evidence for the traceability problem identified in this review.
The resulting network visualization shows that terms such as “Dungeons and Dragons (D&D)”, “table-top role-playing game (TTRPG)”, “role-playing game (RPG)”, “role playing”, “interactive computer graphics”, “natural language processing (NLP)”, and “game design” occupy visible positions within the network. The visualization also shows temporal clustering across the 2023–2025 period, indicating that computational, AI, game-design, and applied social-scientific terms are increasingly connected within the reviewed corpus.
The co-occurrence visualization supports three findings from the evidence map. First, the corpus clusters semantically around D&D and TTRPG-related terminology, consistent with the dominance of TTRPG/D&D-centered sources in the final corpus. Second, computational terms such as NLP and interactive computer graphics appear in proximity to role-playing and game-design terms, indicating that computational and interpretive traditions increasingly intersect. Third, applied social and demographic terms, including adult, male, and humans, are connected to role-playing terms, reflecting the presence of psychological, therapeutic, and social-intervention studies within the reviewed corpus.
The visualization should not be interpreted as a comprehensive bibliometric map of the entire field. It represents the semantic structure of the reviewed corpus only. Its value is therefore diagnostic rather than exhaustive: semantic network analysis is designed to reveal relational structure within a defined textual dataset, not to stand in for field-wide coverage claims [56]. This distinction matters methodologically because corpus representativeness and metadata transparency condition how far any interpretation can be generalized beyond the sampled texts [57]. It confirms that the final corpus combines TTRPG-centered terminology, computational methods, game-design discourse, and applied human-subjects research. It also demonstrates that term normalization is a necessary methodological step for any future semantic atlas or knowledge-organization infrastructure for TTRPG-derived data.
6. Discussion
The results show that the central challenge in TTRPG-derived multimedia research is not the absence of analytical methods. The reviewed corpus includes qualitative interpretation, discourse analysis, conversation analysis, player-experience evaluation, structured datasets, NER, semantic annotation, AI-assisted generation, controlled vocabulary work, and knowledge-organization approaches. The problem is that these methods remain weakly coordinated across data types, disciplinary vocabularies, publication ecosystems, and levels of formalization.
The compact corpus distribution in Table 5 shows that the final corpus is methodologically diverse rather than organized around a single dominant research tradition. Conference papers and journal articles are nearly balanced, and the corpus includes computational, qualitative, knowledge-organization, therapeutic, educational, and multimodal studies. The methodological patterns in Table 7 further show that TTRPG-derived data are studied for multiple analytical purposes, including facilitation, evaluation, learning, intervention, generation, formalization, and retrieval. Table 8 and Table 9 show that TTRPG-derived data operate across multiple modalities and levels of formalization, from spoken interaction and material artifacts to structured game states and semantic annotation. Table 10 identifies the tensions that follow from this condition: narrative richness versus computational structure, accessibility versus methodological rigor, human improvisation versus AI assistance, D&D availability versus representational diversity, and retrieval breadth versus terminological precision.
The keyword co-occurrence analysis in Figure 10 reinforces this interpretation. The need to normalize variants such as “Dungeons & Dragons,” “Dungeons and Dragons,” “role playing game,” “role-playing games,” “tabletop roleplaying game,” and “tabletop role-playing games” shows that the traceability problem is not only conceptual. It appears directly in the metadata and keywords used to retrieve, map, and compare the literature. This section interprets those findings through the conceptual framework proposed in this article and develops the scope ladder as a provenance-aware model for semantic coordination.
Figure 10.
The keyword co-occurrence network.
6.1. From Fragmented Evidence to Semantic Infrastructure
As illustrated in Figure 1, the PSI is proposed as a coordinating rather than reductive framework. Its purpose is not to collapse heterogeneous TTRPG evidence into a single interpretive scheme, but to make differently structured forms of play data traceable, comparable, and reusable across contexts. In this sense, the semantic atlas and scope ladder respond directly to the fragmentation identified in the reviewed corpus.
The results indicate that TTRPG-derived data circulate across several knowledge-making environments: scholarly publications, technical datasets, platform records, community archives, actual play media, therapeutic documentation, educational studies, and computational pipelines. This dispersion creates a methodological problem. If relevant sources are distributed across databases, formats, vocabularies, and publication cultures, then retrieval depends not only on search strategy but also on the semantic alignment of the terms used to describe the field.
This point matters for multimedia research because TTRPG-derived data are not reducible to a single evidence type. A campaign session may produce dialog, gestures, dice outcomes, map interactions, platform commands, character-state changes, GM narration, player reflection, and later recap materials. Each layer may require a different analytical method, but the layers remain connected through the same play event. Without a semantic infrastructure, these materials are difficult to compare, retrieve, annotate, or reuse across studies.
6.2. From Gaps to Requirements
The review, therefore, supports a shift from method accumulation to infrastructure design. Concretely, each dimension of fragmentation identified in the Results maps onto a design requirement of the proposed infrastructure: dispersion across publication ecosystems calls for cross-scheme retrieval; terminological instability calls for provenance- and scheme-aware vocabularies; the plurality of analytical purposes calls for preserving multiple interpretive strata rather than collapsing them into a single ontology; and uneven formalization calls for typed mappings across schemes (see Figure 1) and the gaps-to-requirements mapping (see Table 11). Adding more tools is not sufficient if those tools operate within disconnected vocabularies and incompatible data models. The proposed PSI addresses this problem by coordinating multiple interpretive systems while preserving their provenance, scope, and analytical purposes. Its goal is not to reduce TTRPG research to one authoritative taxonomy, but to make heterogeneous classifications and interpretive positions traceable, comparable, and reusable.
Table 11.
Mapping of gaps identified in the corpus to requirements met by the PSI.
6.3. Terminological Variation as a Traceability Problem
The review shows that vocabulary instability is a structural feature of TTRPG research. Terms such as campaign, scenario, immersion, character, mechanic, player, role, actual play, LARP, VTT, and TTRPG circulate across player communities, game systems, cataloging practices, computational studies, educational research, therapeutic contexts, and performance analysis. These terms are not simply inconsistent. They carry different analytical functions depending on the community, method, and object of study.
The keyword co-occurrence analysis makes this issue empirically visible. Several central concepts appeared under multiple lexical variants and required normalization before the network could be interpreted. These included variants for D&D, RPG, TTRPG, VTTs, LARPs, Edu LARP, TRP, MMORPG, and ARPG. These variants affect retrieval because records that belong to the same conceptual area may not be captured together unless the search strategy anticipates spelling, punctuation, acronymic, hyphenation, and pluralization differences.
This finding reframes terminology as a methodological condition rather than a peripheral naming problem. When concepts are flattened into undifferentiated keywords, the result is reduced semantic precision, weaker retrieval, and limited interoperability between studies. Controlled vocabulary research shows this problem in the difficulty of distinguishing TTRPGs from adjacent forms, related media, and works about RPGs. Computational studies reach a similar problem from another direction: domain-specific entities, fictional-world relations, rules, and gameplay concepts require stable annotation practices before they can be reliably processed.
A provenance-aware approach addresses this problem by preserving the context in which a term is defined, used, or operationalized. In this model, a concept is not only a label. It is also a record of origin, scope, interpretive stance, and use. This approach is especially important for TTRPG studies because the field is transmedia, community-driven, and collaboratively authored. Terms emerge from designers, players, scholars, librarians, software platforms, and archival institutions. A single universal vocabulary would likely erase this plurality. A semantic infrastructure for TTRPG research should therefore support multiple vocabularies while making their relations explicit.
6.4. The Scope Ladder as a Provenance-Aware Semantic Model
To operationalize this approach, this article proposes the scope ladder as a model for organizing concepts by provenance, authority, and visibility. The scope ladder does not replace the semantic atlas introduced in the conceptual framework. Rather, it specifies how concepts can be governed within the atlas. It treats concepts as provenance-bearing entities whose meaning depends partly on the context from which they emerge.
At the narrowest level are review-scoped vocabularies. These contain concepts that matter within a specific review, dataset, or analytical task. They support exploratory coding, temporary distinctions, and project-specific categories that may not persist beyond the study. In the present review, for example, workflow labels and internal coding terms were useful during extraction and analysis but were excluded from the VOSviewer (version 1.6.18) keyword visualization because they did not represent substantive concepts in the literature.
The next level consists of group-scoped vocabularies. These include terms negotiated and reused across several projects by a research group, laboratory, or community of practice. They support continuity without requiring all concepts to become universal field terms. For example, a research group studying TTRPG-derived multimedia data may use stable internal categories for campaign continuity, player agency, platform trace, or semantic annotation across multiple reviews and datasets.
The third level consists of source-paper vocabulary. These preserve terminology coined, adapted, or operationalized by specific sources. This layer is important in TTRPG research because concepts such as bleed, immersion, fiction-first, safety, actual play, campaign, scenario, or mega-campaign may carry distinct meanings in different publications or communities. A source-paper vocabulary allows these meanings to remain connected to their original context before being mapped to broader vocabularies.
The broadest level consists of external named vocabularies and authority systems, including systems such as Library of Congress Subject Headings, Wikidata, CIDOC CRM, LRMoo, SKOS, PROV-O, and other disciplinary vocabularies or ontologies. These systems provide wider interoperability but should not overwrite local conceptual distinctions.
Together, these layers create a compositional semantic environment. A researcher working with a TTRPG dataset may use concepts from the review, the research group, specific source papers, and external authority systems at the same time. The value of the scope ladder is that it makes those layers visible. It allows researchers to ask not only what a concept means, but where it comes from, who uses it, how broadly it circulates, and how it has been mapped to adjacent concepts.
Figure 11 operationalizes this provenance-aware model as a scope ladder. The model shows how researchers can activate multiple vocabulary scopes simultaneously, preserving local interpretive context while supporting broader comparison, retrieval, and interoperability.
Figure 11.
Scope ladder for provenance-aware semantic coordination in TTRPG-derived data.
The model organizes vocabularies across four activated scopes: review-scoped vocabularies, group-scoped vocabularies, source-paper vocabularies, and external named vocabularies or authority systems. The upward direction indicates increasing semantic authority and interoperability, while the downward direction indicates increasing contextual locality and exploratory flexibility.
In this model, the effective vocabulary used in analysis is not a single controlled list but the union of activated scopes. This process allows a researcher to preserve review-specific codes, group conventions, source-paper terminology, and external authority mappings without collapsing them into one hierarchy.
6.5. Implications for Knowledge Graphs, Annotation Systems, and AI-Assisted Analysis
The scope ladder has direct implications for knowledge graphs and annotation systems. In graph-based environments, an annotation should not only link a data fragment to a concept. It should also link that concept to its vocabulary scope, source, definition, and mapping status. Under this model, provenance becomes part of the semantic relation itself rather than secondary documentation added after analysis.
This structure would allow researchers to query both concepts and their histories of use. A graph could identify which concepts were introduced in a specific paper, which were adopted by a research group, which were mapped to external vocabularies, and which remained local to a single review. It could also reveal whether a term functions differently across educational research, computational modeling, cataloging, actual play studies, or TTRPG community discourse.
This model also supports AI-assisted analysis. Retrieval-augmented systems depend on the quality of the semantic context supplied to the model. If concepts, entities, and relations are not scoped, the system may retrieve superficially related but methodologically incompatible materials. Scope-aware knowledge graphs can reduce this risk by preserving distinctions between local codes, source-specific definitions, group vocabularies, and external authority terms. This model does not eliminate interpretation, but it makes interpretive conditions more explicit and auditable.
For TTRPG research, the broader implication is that future infrastructures should treat concepts as socially situated and historically traceable. This idea matters because TTRPG-derived data are not only heterogeneous in format. They are also heterogeneous in authorship, mediation, and interpretive purpose. A character sheet, Discord log, campaign recap, VTT trace, actual play recording, or structured game-state dataset may move across analytical contexts while retaining traces of player agency, rules mediation, platform affordance, and retrospective interpretation. A provenance-aware semantic infrastructure can help preserve these relations while still supporting comparison and reuse.
6.6. Methodological and Practical Implications
The findings suggest four implications for future multimedia research on TTRPGs. First, researchers should document the semantic scope of their analytical categories. Terms such as immersion, character, mechanic, scenario, and campaign should be defined not only conceptually but also operationally, with attention to the data type and analytical purpose involved.
Second, review and annotation systems should distinguish between local coding, source-derived terminology, group vocabularies, and external authority systems. This distinction would improve transparency and help avoid false equivalence between terms that appear similar but function differently across contexts.
Third, computational pipelines should preserve provenance as part of data modeling. This is especially important for AI-assisted analysis, where retrieval, annotation, and generation depend on structured contextual information. Without provenance, computational systems may treat contested or context-specific concepts as stable categories.
Fourth, researchers should report term-normalization decisions when conducting bibliometric, keyword, or semantic analyses. The VOSviewer (version 1.6.18) analysis shows that keyword variation directly affects co-occurrence mapping. Reporting normalization decisions would improve reproducibility and help future researchers understand why particular terms were merged, excluded, or retained.
These implications are practical rather than purely theoretical. They affect how review teams build extraction matrices, how corpora are indexed, how annotations are validated, how datasets are reused, and how AI systems retrieve contextual information. They also support the article’s broader methodological contribution: the semantic atlas is not a universal ontology of RPGs but a framework for coordinating plural, situated, and reusable knowledge about play-derived data.
6.7. Limitations and Future Research
This review has limitations. The corpus is shaped by database coverage, language restrictions, indexing practices, and the visibility of English-language and D&D-centered research. Although supplementary searching and multivocal sources were included, the review cannot fully represent community practices, unpublished tools, non-English scholarship, or local archives that remain difficult to retrieve through conventional systems (see Figure 12).
Figure 12.
Proximity to the act of play. The inner layers—lived practice and auto-ethnographic perspectives—are the least analyzed in the corpus, marking the practice gap.
The review maps methodological patterns rather than evaluating the effectiveness of particular tools, interventions, or computational models. Accordingly, the findings should be interpreted as evidence of an emerging infrastructural problem rather than as a comparative ranking of methods. Taken together, the identified patterns demonstrate both the diversity of Multimedia Play Data in TTRPG research and the absence of a shared infrastructure capable of relating heterogeneous materials without erasing their epistemic differences. Figure 1 synthesizes this problem and presents the conceptual logic of the proposed response. The scope ladder and semantic atlas should therefore be understood as conceptual and methodological contributions that remain to be validated through implementation in review software, annotation environments, knowledge graphs, and AI-assisted retrieval workflows. We emphasize that the PSI is presented as a conceptual, exploratory contribution: it has not yet been implemented or empirically validated as a working system across multiple datasets, and such validation is the central direction for future work.
The keyword co-occurrence analysis should also be interpreted as diagnostic rather than exhaustive. It represents the semantic structure of the reviewed corpus, not the entire field of TTRPG studies. The normalization decisions made before visualization strengthened interpretability but also demonstrated that bibliometric analysis depends on prior semantic judgment. This representation reinforces, rather than resolves, the traceability problem identified in the review.
Future research should therefore focus on applied validation. One direction is to implement a prototype semantic atlas for a bounded TTRPG corpus and evaluate whether scope-aware annotation improves retrieval, comparison, and reuse. A second direction is to test how provenance-aware knowledge graphs affect AI-assisted analysis of session transcripts, character sheets, campaign notes, and platform traces. A third direction is to compare how different communities define and operationalize key TTRPG concepts across languages, systems, and publication ecosystems. A fourth direction is to test whether term-normalization protocols improve reproducibility in bibliometric and evidence-mapping studies of RPG research.
Taken together, the Discussion extends the Results by showing why methodological fragmentation cannot be solved by adding more tools alone. TTRPG research requires semantic infrastructures that can preserve interpretive plurality, document provenance, and support coordination across heterogeneous multimedia evidence.
7. Conclusions
This review examined how qualitative, computational, multimodal, multimedia, and knowledge-organization methods are being used to analyze play-derived data in TTRPG research. The findings show that TTRPG studies increasingly work with complex evidence ecologies composed of speech, gesture, character sheets, maps, rules references, platform traces, audiovisual records, structured game states, annotations, metadata, and retrospective documentation. These materials are not secondary records of play. They constitute Multimedia Play Data: layered, situated, collaborative, and technically mediated evidence that requires methods for interpretation, retrieval, comparison, and reuse.
The review found that the field has developed a broad methodological repertoire, including qualitative interpretation, discourse and conversation analysis, player-experience evaluation, structured datasets, NER, semantic annotation, AI-assisted generation, and controlled vocabulary work. However, these approaches remain unevenly coordinated across publication ecosystems, data modalities, vocabularies, and levels of formalization. The problem is therefore not a lack of methods, but the absence of shared infrastructure for connecting them.
The central contribution of this article is the proposal of a PSI for organizing and analyzing TTRPG-derived Multimedia Play Data. The semantic atlas and scope ladder provide a way to preserve multiple vocabularies, interpretive strata, provenance records, and semantic mappings without imposing a single universal ontology on RPGs. This contribution matters because TTRPG research depends on terms whose meanings shift across communities, systems, disciplines, and analytical purposes. A polyvocal infrastructure allows these differences to remain visible while still supporting comparison, retrieval, reuse, and AI-assisted analysis.
The need for this infrastructure is also practical. TTRPG research is distributed across academic fields, player communities, libraries, archives, software platforms, therapeutic practices, educational settings, and design cultures. These communities often produce related knowledge without shared vocabularies or mutual visibility. A single ontology would risk flattening this diversity by privileging one interpretive system over others. The PSI instead provides a foundation for holding the field’s polysemy together: it makes divergent terms, meanings, and classifications traceable without forcing them into premature consensus.
A practical implication of this work is that metadata should be treated as analyzable data. Descriptions, classifications, mappings, extraction decisions, provenance records, and vocabulary choices are not merely administrative byproducts of review work. Once formalized, they can support conceptual auditing, methodological transparency, longitudinal comparison, and cumulative scholarship. This formalization turns the review from a one-time synthesis into an expandable infrastructure for future research.
This study has limitations. The corpus remains shaped by database coverage, language restrictions, publication visibility, and the dominance of English-language and Dungeons & Dragons-centered research. The review also maps methodological patterns rather than testing the performance of a fully implemented semantic atlas across multiple datasets.
Future work should validate the proposed infrastructure through applied prototypes, comparative annotation studies, AI-assisted retrieval workflows, and longitudinal review updates. Researchers should test whether scope-aware annotation improves retrieval, whether provenance-aware knowledge graphs strengthen AI-assisted analysis, and whether term-normalization protocols improve reproducibility in bibliometric and evidence-mapping studies. The broader task is clear: TTRPG research needs shared infrastructures that preserve plurality rather than erase it, making RPGs a valuable site for advancing multimedia analysis, knowledge organization, human–AI collaboration, and semantic interoperability.
Supplementary Materials
The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/multimedia2030016/s1, Database DB1: CSV of 163 sources (full discovery/reference-management library); Database DB2: RIS of 163 sources; Database DB3: CSV of final 35 sources; Database DB4: RIS of final 35; Database DB5: MC-Vocabulary; Database DB6: FMC-Vocabulary TTL; Presentation PPT1: Refracting Knowledge; Presentation PPT2: Atlas architecture; Word Document S1 Preliminary Search Strategy; Word Document S2: Full Search Strategy; Word Document S3: PRISMA-ScR.
Author Contributions
C.L.: Conceptualization, Methodology, Validation, Formal analysis, Investigation, Resources, Writing—Original Draft, Writing—Review and Editing, Visualization, Supervision, Project administration. J.M.: Conceptualization, Software, Validation, Formal analysis, Investigation, Resources, Data Curation, Writing—Review and Editing, Visualization. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data management plan associated with this research is publicly available through DMP Tool [58]: Cristo Leon, Marcos O. Cabobianco, James Lipuma, Julian Marcone, Agustina Cinanni, and Romano Ponce-Díaz (2026), DMSP para “Narrativas Transmedia y Convergencia: Creando un Repositorio Digital Transnacional para los juegos de rol (JdR) de Mega-Campañas” [Data Management Plan], https://doi.org/10.48321/D12Q16 (accessed 9 July 2026). The OSF project associated with this work is available at https://osf.io/vs298/ (accessed 31 May 2026) under a CC BY 4.0 International license. The scoping review protocol, Mapeo de técnicas computacionales, multimodales y de organización del conocimiento para datos de juegos de rol de mesa: una revisión de alcance con mapeo de evidencia y productos basados en SKOS, was registered on OSF and is available at https://osf.io/2rm4q/ (accessed 31 May 2026). Data generated during the review process, including evidence tables and derived mappings, will be made available through the associated OSF project as permitted by copyright, licensing, and ethical constraints at https://osf.io/vs298/files/osfstorage (accessed 31 May 2026). The machine-readable semantic vocabulary outputs associated with this study, including the TTL and JSON-LD files, are available through the OSF folder for digital ontologies within the associated project repository.
Acknowledgments
The authors would like to acknowledge the review, discussions, and conversations with Rodrigo Santamaría, Marcos O. Cabobianco, and Tamara Pandolfi, whose feedback and interdisciplinary perspectives contributed to the conceptual development of this work. The authors also acknowledge the librarians at the Robert W. Van Houten Library at the New Jersey Institute of Technology for their support in the literature access, retrieval, and research consultation. During the preparation of this manuscript, the authors used ChatGPT (version 5.5 Thinking) for language refinement, structural drafting, and conceptual organization. The authors reviewed and edited the output and take full responsibility for the content of this publication.
Conflicts of Interest
Author Julian Marcone is the Chief Executive Officer (CEO) of the Kali Foundation, a private-sector organization that was listed as his institutional affiliation at the time this research was conducted and the manuscript was prepared. The Kali Foundation did not provide funding or sponsorship for this study and had no role in the design of the study; the collection, analysis, or interpretation of data; the writing of the manuscript; or the decision to publish the results. The authors have reviewed the relevant potential financial, commercial, and non-financial interests and declare no other conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| Acronym | Full name |
| ARPG | Analog Role-Playing Game |
| CIDOC CRM | International Committee for Documentation Conceptual Reference Model |
| CRPG | Computer Role-Playing Games |
| D&D | Dungeons and Dragons |
| Edu LARP | Educational Live-Action Role-playing Games |
| GOLEM | Graphs and Ontologies for Literary Evolution Models |
| HCI | Human–Computer Interaction |
| JSON-LD | JavaScript Object Notation for Linked Data |
| LARP | Live-Action Role-Playing Games |
| LRMoo | Library Reference Model Object-Oriented Formulation |
| MMORPG | Massively Multiplayer Online Role-Playing Game |
| NER | Named Entity Recognition |
| NLP | Natural Language Processing |
| OSF | Open Science Framework |
| PRISMA | Preferred Reporting Items for Systematic Reviews and Meta-Analyses |
| PRISMA-ScR | Preferred Reporting Items for Systematic Reviews and Meta-Analyses Extension for Scoping Reviews |
| PROV-O | Provenance Ontology |
| PSI | Polyvocal Semantic Infrastructure |
| RAG | Retrieval-Augmented Generation |
| RPG | Role-Playing Game |
| SKOS | Simple Knowledge Organization System |
| SKOS-XL | Simple Knowledge Organization System Extension for Labels |
| SPIDER | Sample, Phenomenon of Interest, Design, Evaluation, Research type |
| TRP | Therapeutic Role-Play |
| TTL | Turtle or Terse RDF Triple Language |
| TTRPG | Table-Top Role-Playing Game |
| VTT | Virtual Table-Top |
| YAGO | Yet Another Great Ontology |
Appendix A. Evidence Matrix
Table A1.
Evidence Matrix Linking Major Findings to Primary Sources.
Appendix B. Source-Level Extraction Matrix
Figure A1.
Example of the comparative extraction matrix generated through the custom review application developed by the authors, showing methodological approaches, data types, and identified research gaps for selected included studies. Source: Authors’ own elaboration based [12,59].
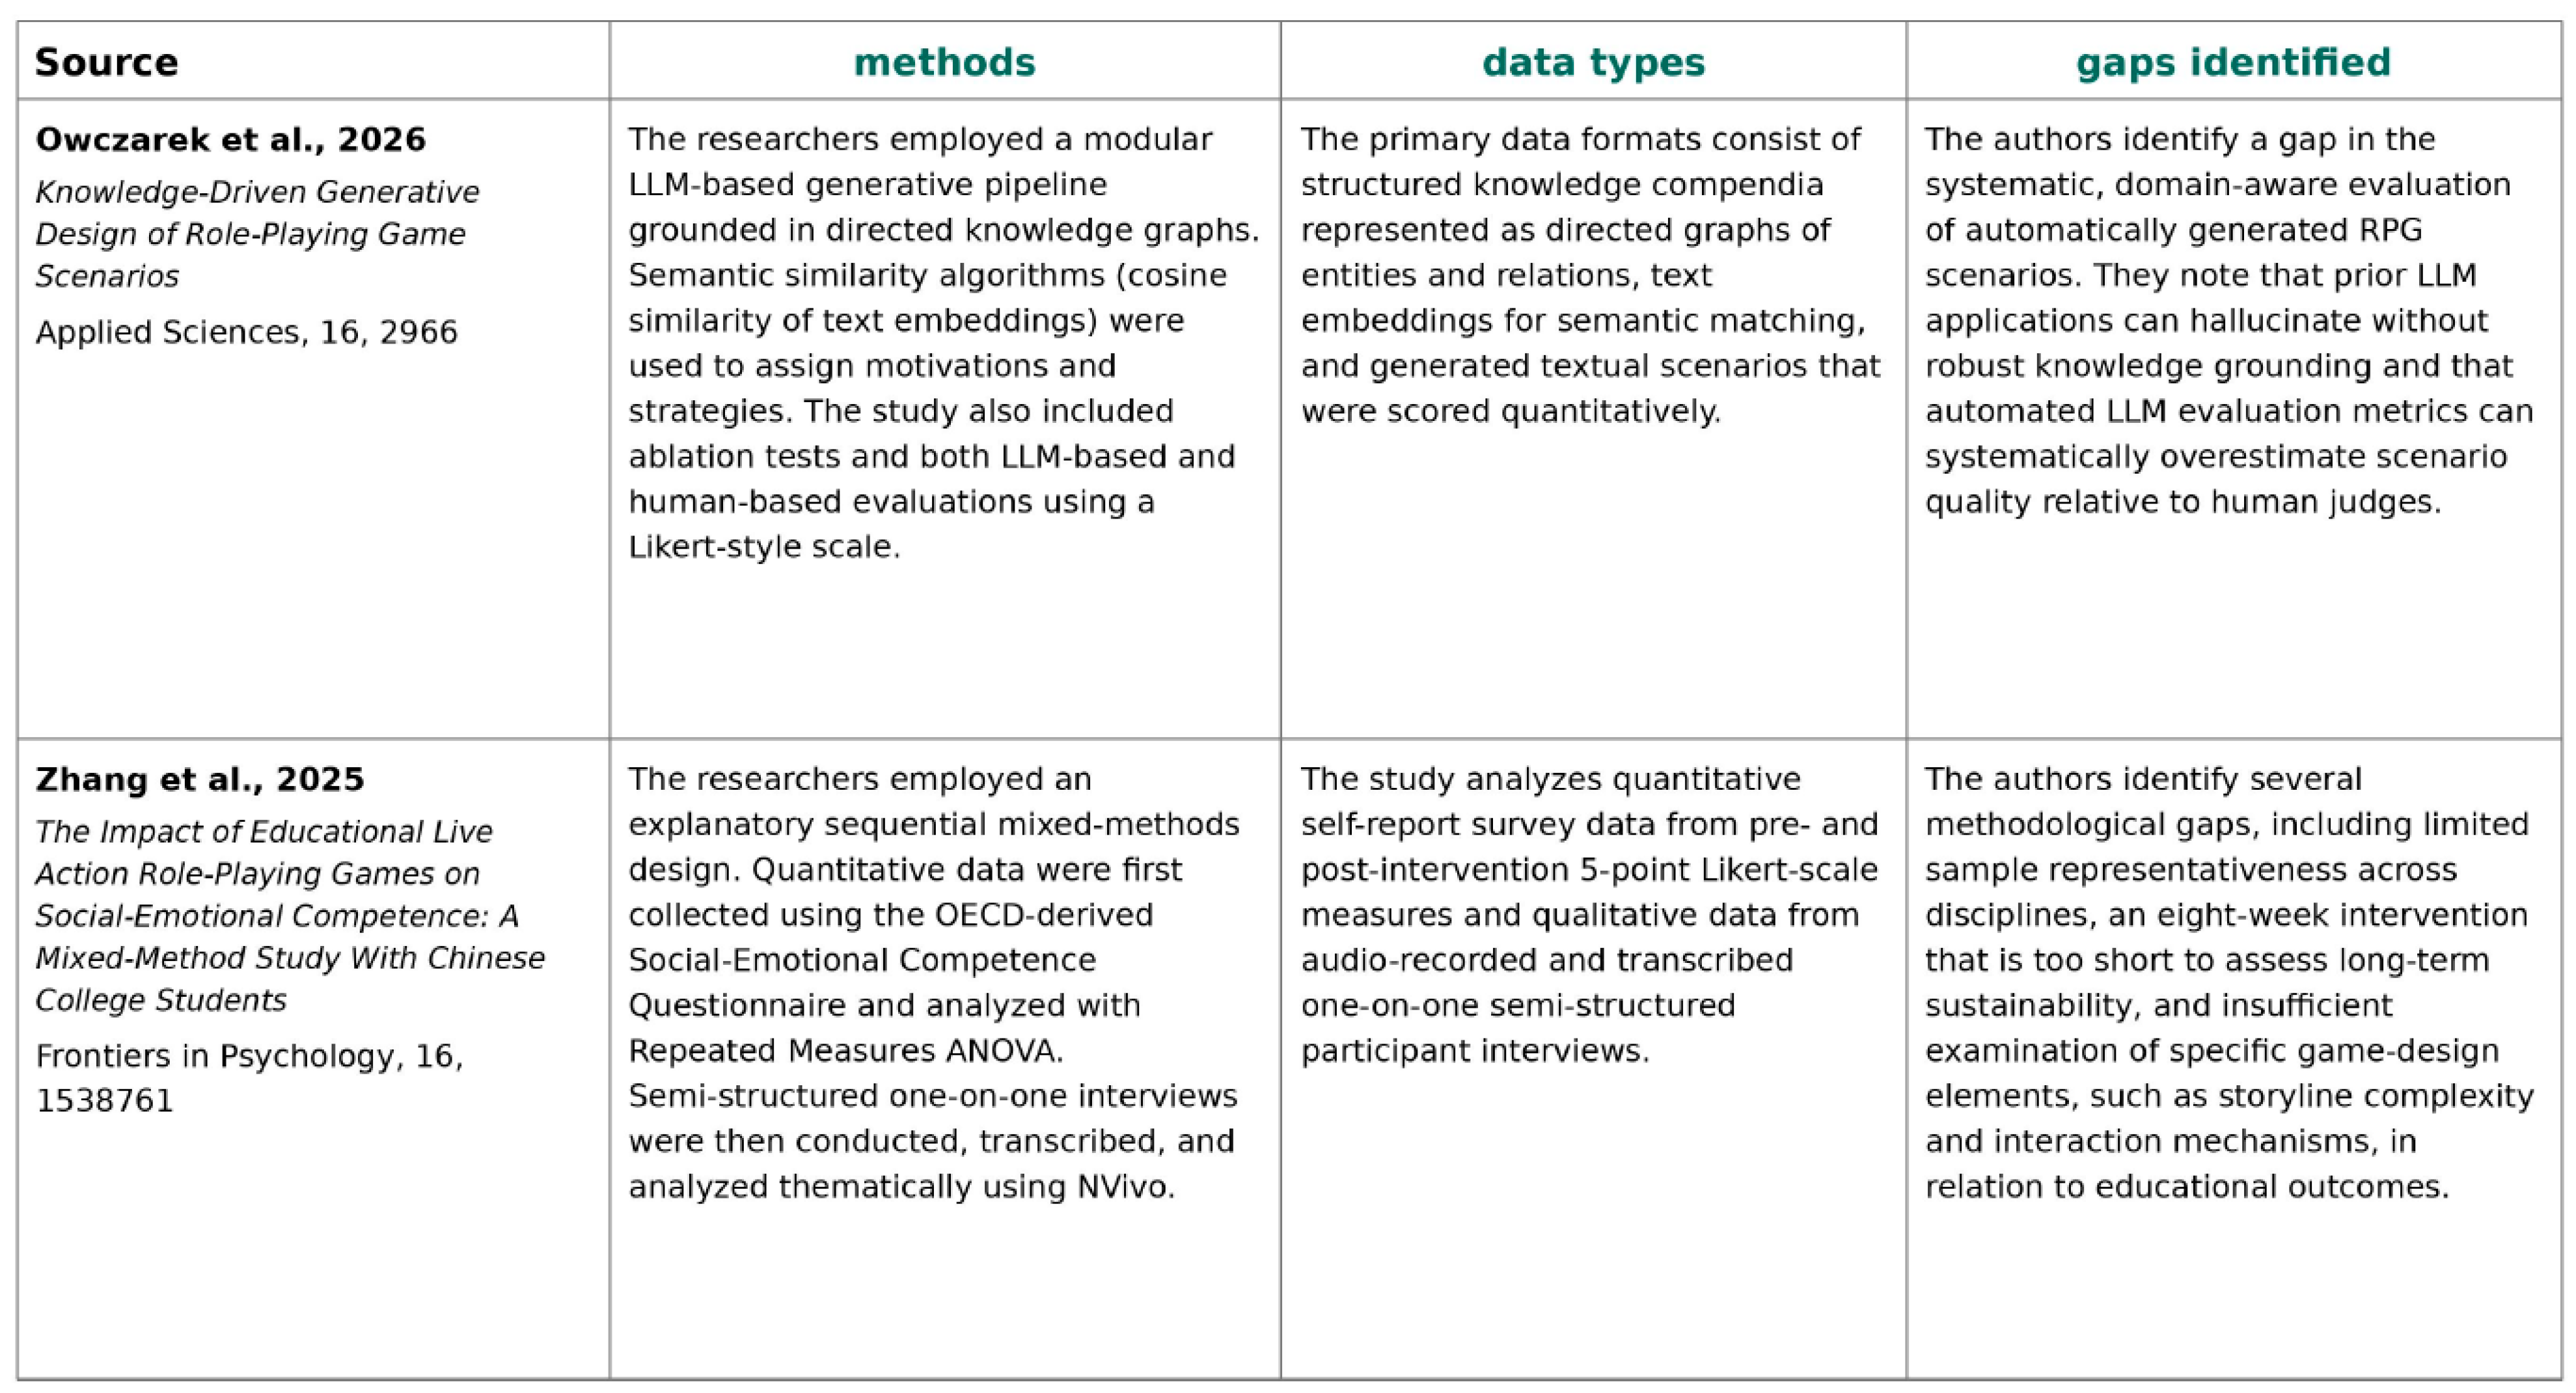
Appendix C. Source-Level Research-Question Alignment Matrix
Figure A2.
Example of the research-question alignment matrix generated through the custom review application developed by the authors. The matrix illustrates the degree to which selected included studies address research sub-questions RQ1.1–RQ1.8 using the coding categories Absent, Mention, Secondary, and Primary. The example displays Owczarek et al. (2026), Smith (2024), and Zhu et al. (2023) [5,12,43]. Source: Authors’ own elaboration based on data extracted from the included studies and visualized through the authors’ custom application [5,12,43].
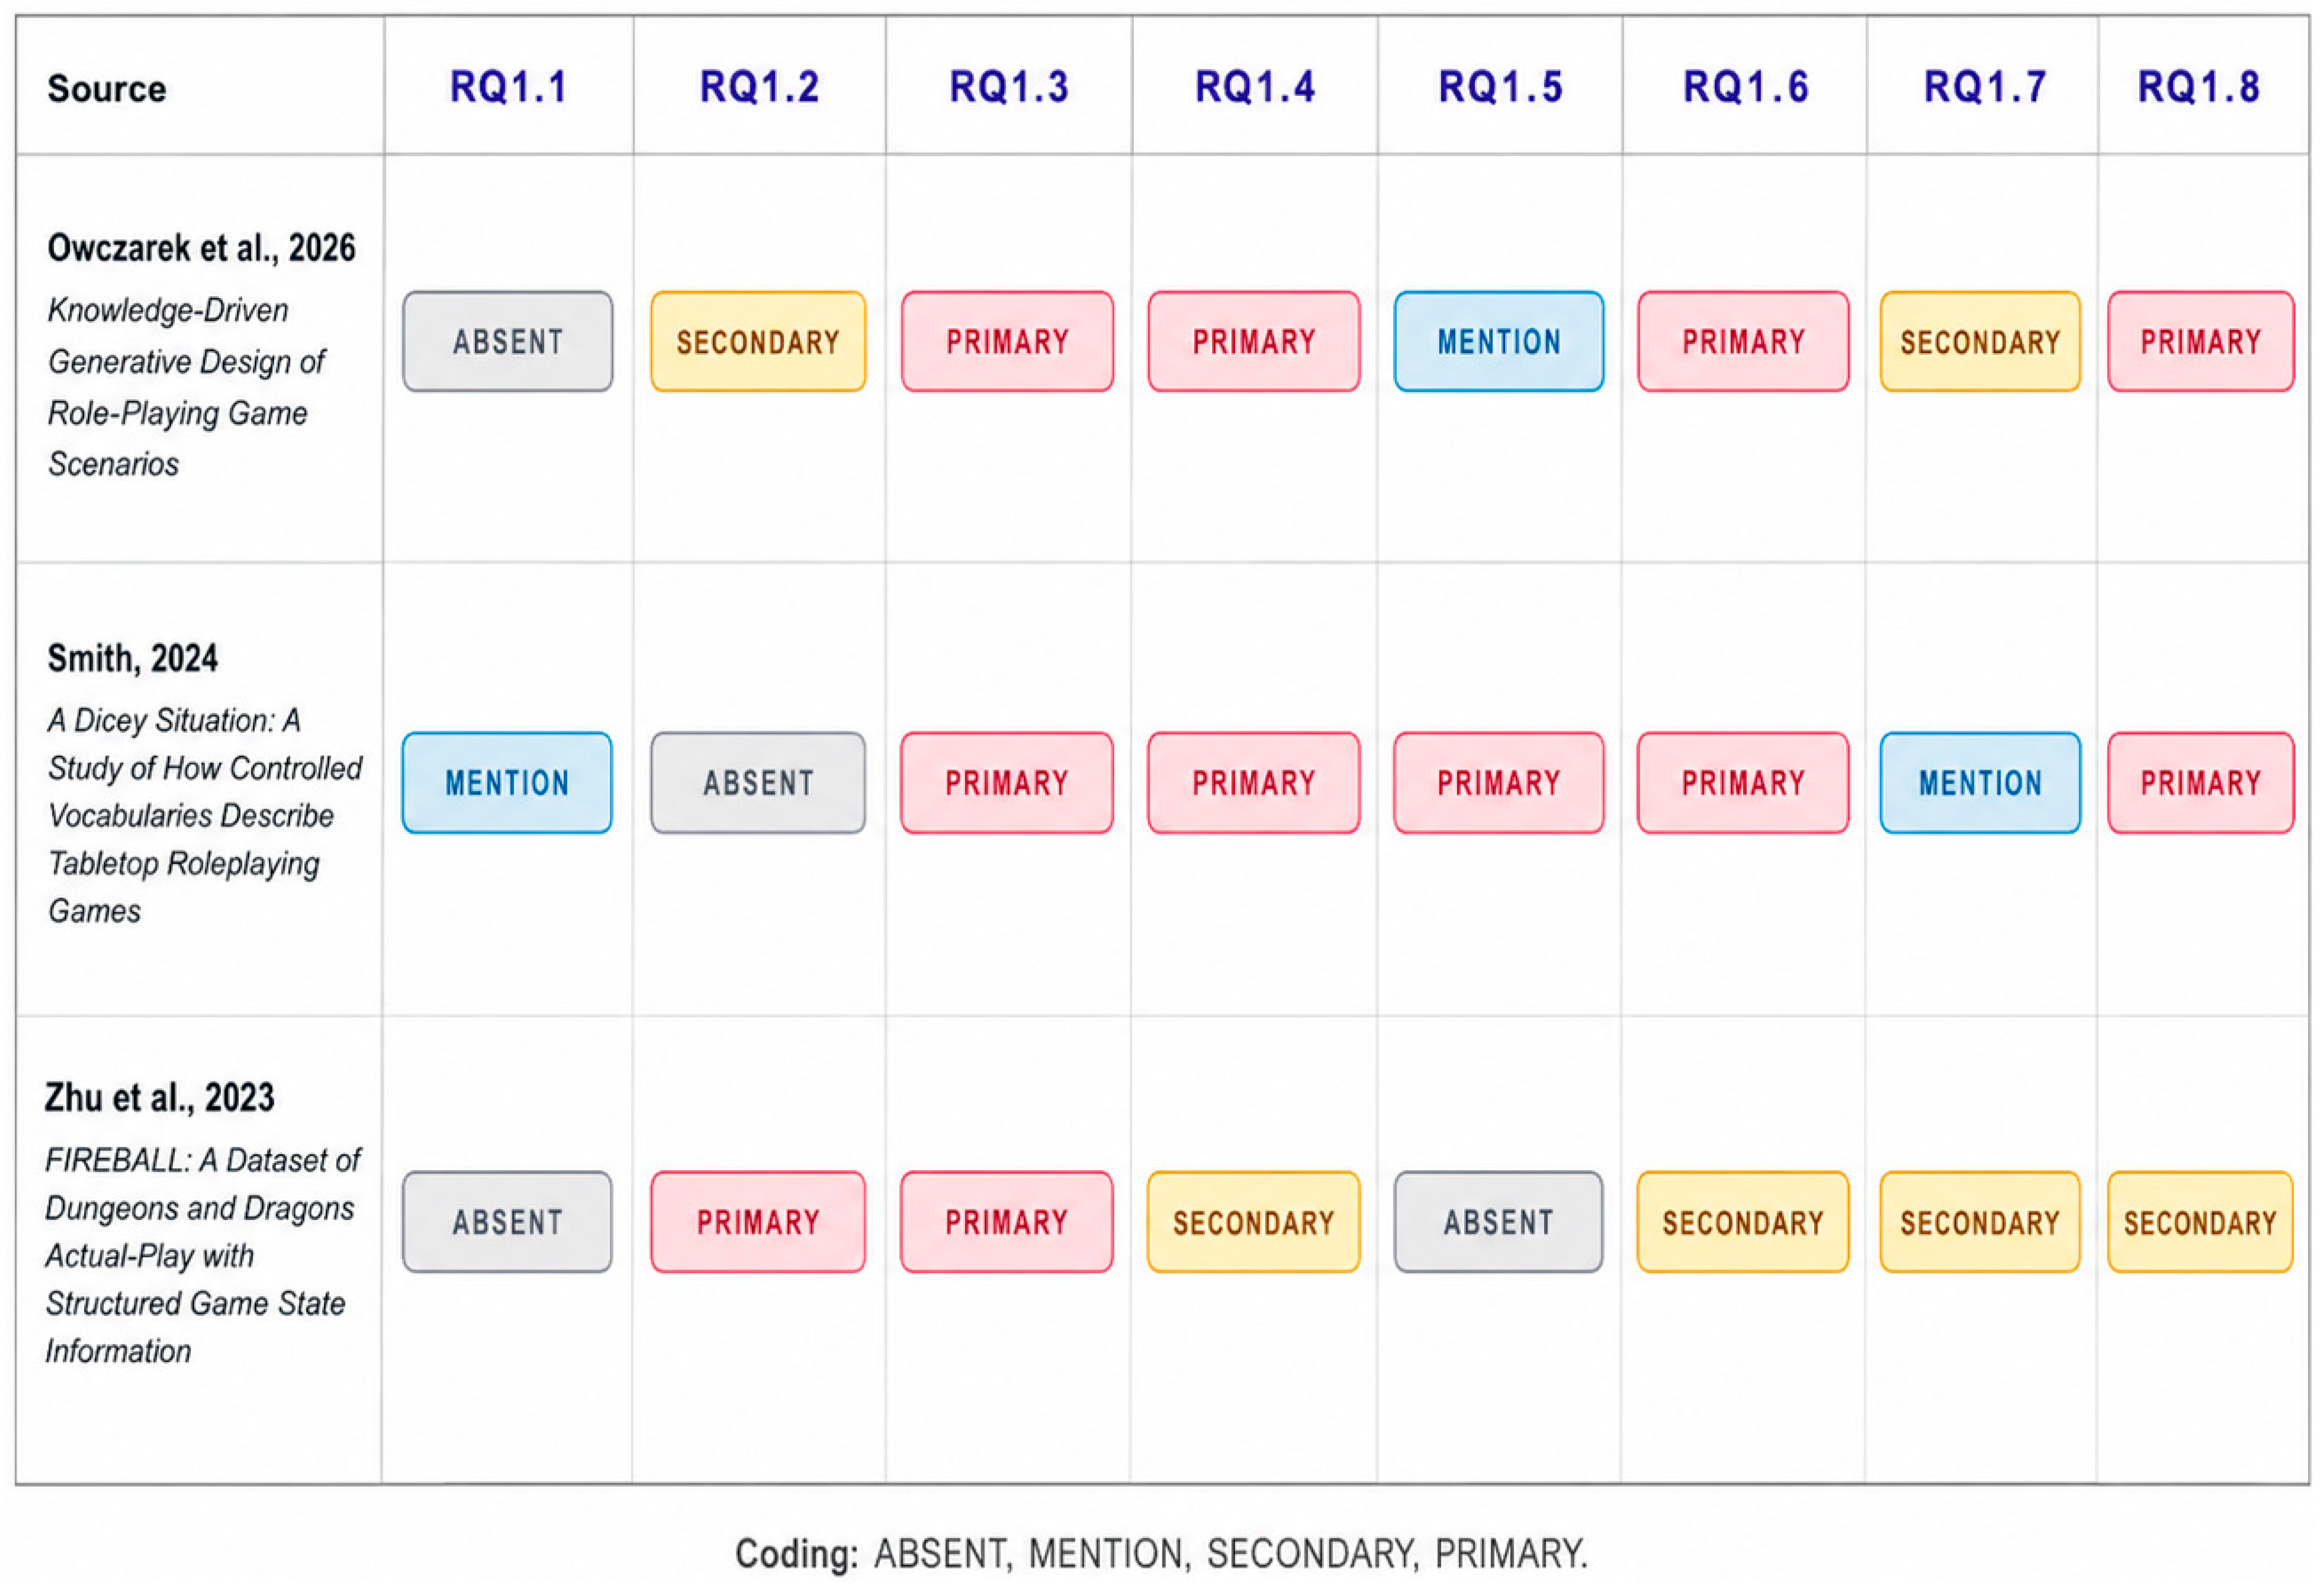
Appendix D. Included Sources by First Author in Alphabetical Order
The final corpus included 35 sources. For transparency and ease of cross-reference, the included sources are listed below in alphabetical order by first author surname.
- Atherton et al. [69];
- Berggren et al. [49];
- Billieux et al. [67];
- Breland [46];
- Brockway [71];
- Harviainen et al. [72];
- Hazlett et al. [39];
- Henning et al. [68];
- Hobbi and Bololia [62];
- James [61];
- Kelly et al. [44];
- Knoetze [48];
- Liapis and Denisova [51];
- Liu et al. [73];
- Maik [47];
- Martinho and Sousa [74];
- Niarchos et al. [60];
- Owczarek et al. [12];
- Peiris and De Silva [50];
- Rosenblad et al. [21];
- Rot et al. [75];
- Sezen et al. [63];
- Shyne and Cooper [38];
- Sivaganeshan and De Silva [45];
- Smith [5];
- Snodgrass et al. [70];
- Sousa et al. [41];
- Tang et al. [40];
- von Kacsoh et al. [65];
- Weerasundara and De Silva [64];
- Whittemore [42];
- Yuliawati et al. [34];
- Zhang et al. [59];
- Zheng et al. [66];
- Zhu et al. [43].
References
- Jones, S. Watch Us Roll: Essays on Actual Play and Performance in Tabletop Role-Playing Games; Studies in Gaming; McFarland & Company, Incorporated Publishers: Jefferson, NC, USA, 2021; ISBN 978-1-4766-7762-0. [Google Scholar]
- Hope, R. Play, Performance, and Participation: Boundary Negotiation and Critical Role. Master’s Thesis, Concordia University, Montreal, QC, Canada, 2017. [Google Scholar]
- Boyd, Z.; Hejná, M. The ‘Critical Role’ of Voice Quality in Dungeons and Dragons: A Case Study of Non-Player Characters Voiced by Matthew Mercer. Lang. Soc. 2025, 55, 278–303. [Google Scholar] [CrossRef] [Scilit]
- Andreasen, C.; Badse, C.; Bøckman, P.; Enghoff, M.; Fatland, E.; Gade, M.; Sebatian Gundel, D.; Hakkarainen, H.; Hansen, R.R.; Henriksen, T.D.; et al. As Larp Grows Up–Theory and Methods in Larp, 1st ed.; Gade, M., Thorup, L., Sander, M., Eds.; Projektgruppen KP03: Frederiksberg, Denmark, 2003; ISBN 87-989377-0-7. [Google Scholar]
- Smith, T.S. A Dicey Situation: A Study of How Controlled Vocabularies Describe Tabletop Roleplaying Games. Cat. Classif. Q. 2024, 62, 99–123. [Google Scholar] [CrossRef] [Scilit]
- Arjoranta, J.; Beltrán, W.; Bienia, R.; Björk, S.; Bowman, S.L.; Brind, S.; Brown, A.; Brown, A.; Castronova, E.; Chen, M.; et al. Role-Playing Game Studies: A Transmedia Approach, 1st ed.; Zagal, J.P., Deterding, S., Eds.; Routledge: New York, NY, USA, 2018; ISBN 978-0-8153-6920-2. [Google Scholar]
- Arjoranta, J.; Beltrán, W.; Bienia, R.; Björk, S.; Bowman, S.L.; Brind, S.; Brown, A.; Burton, A.; Castronova, E.; Castiello Jones, K.; et al. The Routledge Handbook of Role-Playing Game Studies, 1st ed.; Zagal, J.P., Deterding, S., Eds.; Taylor and Francis: Abingdon, UK, 2024; ISBN 978-1-032-27778-3. [Google Scholar]
- Scheff, T. Parts and Wholes: Goffman and Cooley. Sociol. Forum 2011, 26, 694–704. [Google Scholar] [CrossRef] [Scilit]
- Sacksteder, W. Least Parts and Greatest Wholes Variations on a Theme in Spinoza. Int. Stud. Philos. 1991, 23, 75–87. [Google Scholar] [CrossRef] [Scilit]
- Brata Winardy, G.C.; Septiana, E. Role, Play, and Games: Comparison Between Role-Playing Games and Role-Play in Education. Soc. Sci. Humanit. Open 2023, 8, 100527. [Google Scholar] [CrossRef] [Scilit]
- Bowman, S.L. Immersion and Shared Imagination. In Role-Playing Game Studies: Transmedia Foundations; Routledge: New York, NY, USA; London, UK, 2018; pp. 379–394. ISBN 978-1-138-63890-7. [Google Scholar]
- Owczarek, W.; Wróbel, J.; Pęszor, D. Knowledge-Driven Generative Design of Role-Playing Game Scenarios. Appl. Sci. 2026, 16, 2966. [Google Scholar] [CrossRef] [Scilit]
- Laws, R.D. Hamlet’s Hit Points: What Three Classics Narratives Tell Us About Roleplaying Games; Gameplaywright Press: Roseville, MN, USA, 2010; ISBN 978-0-9818840-2-8. [Google Scholar]
- Arjoranta, J.; Bartel, C.; Calleja, G.; Carlson, C.; Edgar, A.; Grabarzcyk, P.; Gregersen, A.; Günzel, S.; Jørgensen, I.; Karhulahti, V.-M.; et al. The Routledge Handbook of Philosophy of Games; Nguyen, C.T., Sageng, J.R., Eds.; Routledge: London, UK, 2025; ISBN 978-1-315-30499-1. [Google Scholar]
- Hergenrader, T. Collaborative Worldbuilding for Writers and Gamers; Paperback; Bloomsbury Academic: London, UK; New York, NY, USA, 2018; ISBN 978-1-350-01666-8. [Google Scholar]
- Grouling Cover, J. The Creation of Narrative in Tabletop Role-Playing Games; McFarland & Company: Jefferson, NC, USA, 2010; ISBN 978-0-7864-4451-9. [Google Scholar]
- Berry, J.; Bjørkelo, K.A.; Brown, A.; Cullinan, M.; Genova, J.; Grasmo, H.; Haarman, S.; Hassan, L.; Leogrande, C.; Mohon-Doyle, K.; et al. Education and Analog Role-Playing Games: TeachRPG–Tabletop Role-Playing Games in the Classroom, Volume II; Haarman, S., Ed.; CRC Press: Boca Raton, FL, USA, 2026; Volume 2, ISBN 978-1-041-07616-2. [Google Scholar]
- Bowman, S.L.; Brockway, D.; Gustafson, K.; Haarman, S.; Hautsch, J.; Johansson, K.; Koljonen, J.; Mallory, S.; Masek, L.; Öberg, P.; et al. Education and Analog Role-Playing Games: Theory and Pedagogy, Volume 1, 1st ed.; Haarman, S., Ed.; CRC Press Taylor & Francis Group: Boca Raton, FL, USA, 2025; ISBN 978-1-040-44172-5. [Google Scholar]
- Bowman, S.L.; Diakolambrianou, E.; Brind, S.; Bandhoesingh, A.; Hugaas, K.H.; Giovannucci, A.; van Tilborg, G.Q.; Baird, J.; Westborg, J.; Suominen, T. Transformative Role-Playing Game Design; Uppsala Scholarly Books: Uppsala, Sweden, 2025; ISBN 978-91-513-2301-5. [Google Scholar]
- Ribeiro, F. Role Playing Game (RPG) Open Pedagogy; United Nations Children Education Fund (UNICEF): New York, NY, USA, 2006. [Google Scholar] [CrossRef]
- Rosenblad, S.R.; Wolford, T.; Brennan, R.S., III; Darnell, J.; Mabry, C.; Herrmann, A. Mastering Your Dragons: Using Tabletop Role-Playing Games in Therapy. Behav. Sci. 2025, 15, 441. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Peters, A.; Woods, J.; Aditijo, C.; Lang, N.; Nguyen, R.; Baird, L.; Webb, C.; McLean, B.; Hatfield, M. Safety, Connection, and Personal Growth: Experiences of Tabletop Role Play Game Groups Amongst Autistic Adolescents and Emerging Adults; Sage: Thousand Oaks, CA, USA, 2025. [Google Scholar] [CrossRef] [Scilit]
- Shaker, N.; Togelius, J.; Nelson, M.J. Procedural Content Generation in Games; Computational Synthesis and Creative Systems; Springer International Publishing: Cham, Switzerland, 2016; ISBN 978-3-319-42714-0. [Google Scholar]
- Yannakakis, G.N.; Togelius, J. Artificial Intelligence and Games; Springer Nature: Cham, Switzerland, 2025; ISBN 978-3-031-83346-5. [Google Scholar]
- Mohapatra, S.K.; Sarangi, P.K.; Sahu, P.; Sharma, S.K.; Sharma, O. Game Data Visualization Using Artificial Intelligence Techniques. In Proceedings of the Proceedings of International Conference on Recent Trends in Computing; Mahapatra, R.P., Peddoju, S.K., Roy, S., Parwekar, P., Eds.; Springer Nature: Singapore, 2023; pp. 351–360. [Google Scholar]
- Wickramarathna, N.C.; Ganegoda, G.U. Invoke Artificial Intelligence and Machine Learning for Strategic-Level Games and Interactive Simulations. In Proceedings of the Artificial Intelligence; Hemanth, J., Silva, T., Karunananda, A., Eds.; Springer: Singapore, 2019; pp. 129–143. [Google Scholar]
- Winnicott, D.W. Realidad y Juego; GEDISA: Barcelona, Spain, 2021; ISBN 978-84-7432-056-5. [Google Scholar]
- Wolf, M.J.P. (Ed.) Navigating Imaginary Worlds: Wayfinding and Subcreation; Routledge: New York, NY, USA, 2025; ISBN 978-1-003-50221-0. [Google Scholar]
- Kneale, W.; Kneale, M. The Development of Logic; Oxford University Press: Oxford, UK, 1985; ISBN 978-0-19-824773-9. [Google Scholar]
- Suchanek, F.M.; Alam, M.; Bonald, T.; Chen, L.; Paris, P.-H.; Soria, J. YAGO 4.5: A Large and Clean Knowledge Base with a Rich Taxonomy. In Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval, Washington, DC, USA, 14–18 July 2024; Association for Computing Machinery: New York, NY, USA, 2024; pp. 131–140. [Google Scholar]
- Pianzola, F.; Cheng, L.; Pannach, F.; Yang, X.; Scotti, L. The GOLEM Ontology for Narrative and Fiction. Humanities 2025, 14, 193. [Google Scholar] [CrossRef] [Scilit]
- Binding, C. Implementing Archaeological Time Periods Using CIDOC CRM and SKOS. In Proceedings of the The Semantic Web: Research and Applications; Aroyo, L., Antoniou, G., Hyvönen, E., ten Teije, A., Stuckenschmidt, H., Cabral, L., Tudorache, T., Eds.; Springer: Berlin/Heidelberg, Germany, 2010; pp. 273–287. [Google Scholar]
- Mak, S.; Thomas, A. Steps for Conducting a Scoping Review. J. Grad. Med. Educ. 2022, 14, 565–567. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yuliawati, L.; Puspieta-Wardhani, P.A.; Ng, J.H. A Scoping Review of Tabletop Role-Playing Game (TTRPG) as Psychological Intervention: Potential Benefits and Future Directions. Psychol. Res. Behav. Manag. 2024, 17, 2885–2903. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Page, M.J.; McKenzie, J.E.; Bossuyt, P.M.; Boutron, I.; Hoffmann, T.C.; Mulrow, C.D.; Shamseer, L.; Tetzlaff, J.M.; Akl, E.A.; Brennan, S.E.; et al. The PRISMA 2020 Statement: An Updated Guideline for Reporting Systematic Reviews. BMJ 2021, 372, 1–9. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Holst, D.; Moenck, K.; Koch, J.; Schmedemann, O.; Schüppstuhl, T. Transparent Reporting of AI in Systematic Literature Reviews: Development of the PRISMA-trAIce Checklist. JMIR AI 2025, 4, e80247. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Methley, A.M.; Campbell, S.; Chew-Graham, C.; McNally, R.; Cheraghi-Sohi, S. PICO, PICOS and SPIDER: A Comparison Study of Specificity and Sensitivity in Three Search Tools for Qualitative Systematic Reviews. BMC Health Serv. Res. 2014, 14, 579. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Shyne, F.; Cooper, S. Computational Tools for Table-Top Role-Playing Games: A Scoping Review. In Proceedings of the 20th International Conference on the Foundations of Digital Games, 15–18 April 2025; Association for Computing Machinery: Graz, Austria, 2025; pp. 1–14. [Google Scholar]
- Hazlett, N.; Smith, L.; Murray, E.; Duncan, A. Exploring Tabletop Role-Playing Games as Meaningful Occupations: A Qualitative Exploratory Study. Occup. Ther. Health Care 2025, 39, 759–776. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Tang, K.; Gasque, T.M.; Donley, R.; Sullivan, A. “It Has to Ignite Their Creativity”: Opportunities for Generative Tools for Game Masters. In Proceedings of the 18th International Conference on the Foundations of Digital Games, Fdg 2023, Lisbon, Portugal, 12–14 April 2023; Lopes, P., Luz, F., Liapis, A., Engstrom, H., Eds.; Assoc Computing Machinery: New York, NY, USA, 2023; p. 63. [Google Scholar]
- Sousa, C.; Rye, S.; Sousa, M.; Torres, P.J.; Perim, C.; Mansuklal, S.A.; Ennami, F. Playing at the School Table: Systematic Literature Review of Board, Tabletop, and Other Analog Game-Based Learning Approaches. Front. Psychol. 2023, 14, 1160591. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Whittemore, R.D. Tabletop Role-Playing Games and the Actual Play Show: Author, Audience, and Adaptation. Master’s Thesis, Virginia Polytechnic Institute and State University, Blacksburg, VA, USA, 2021. [Google Scholar]
- Zhu, A.; Aggarwal, K.; Feng, A.; Martin, L.J.; Callison-Burch, C. FIREBALL: A Dataset of Dungeons and Dragons Actual-Play with Structured Game State Information. In Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), Toronto, Canada, 9–14 July 2023; Rogers, A., Boyd-Graber, J., Okazaki, N., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 4171–4193. [Google Scholar]
- Kelly, J.; Mateas, M.; Wardrip-Fruin, N. Towards Computational Support with Language Models for TTRPG Game Masters. In Proceedings of the 18th International Conference on the Foundations of Digital Games, Fdg 2023; Lopes, P., Luz, F., Liapis, A., Engstrom, H., Eds.; Assoc Computing Machinery: New York, NY, USA, 2023; p. 78. [Google Scholar]
- Sivaganeshan, A.; De Silva, N. Fine Tuning Named Entity Extraction Models for the Fantasy Domain; Institute of Electrical and Electronics Engineers Inc.: Piscataway, NJ, USA, 2023; pp. 346–351. [Google Scholar]
- Breland, L. Pretense Awareness Context and Autism: Insights from Conversation Analysis. J. Autism Dev. Disord. 2021, 52, 2535–2552. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Maik, M. Evaluating AI-Driven Game Masters: Adaptive Avatars for Personalized Tabletop Role-Playing. Entertain. Comput. 2026, 57, 101120. [Google Scholar] [CrossRef] [Scilit]
- Knoetze, F.W.M. Developing the Integrated Analysis Matrix (I-AM): A Data-Minding Approach for Better Ludonarrative Design-Based Research in Education. Int. J. Qual. Meth. 2025, 24, 16094069251390161. [Google Scholar] [CrossRef] [Scilit]
- Berggren, P.; Johansson, B.; Myrén, D. Untangling Scenario Terminology to Improve Exercise Ontology Across Domains. In Proceedings of the International ISCRAM Conference, Halifax, Nova Scotia, Canada, 18–21 May 2025; ISCRAM Association: Brussels, Belgium, 2025; Volume 22. [Google Scholar]
- Peiris, A.; De Silva, N. SHADE: Semantic Hypernym Annotator for Domain-Specific Entities–Dungeons and Dragons Domain Use Case. In Proceedings of the Innovate, Regenerate, and Transform: Advances in Engineering for Sustainable Growth, 25–26 August 2023; Institute of Electrical and Electronics Engineers Inc.: Piscataway, NJ, USA, 2023; pp. 55–60. [Google Scholar]
- Liapis, A.; Denisova, A. The Challenge of Evaluating Player Experience in Tabletop Role-Playing Games. In Proceedings of the 18th International Conference on the Foundations of Digital Games (FDG 2023), Lisbon, Portugal, 12–14 April 2023; Association for Computing Machinery (ACM): New York, NY, USA, 2023; pp. 1–10. [Google Scholar]
- Shackelford, L.D.; Schoettler, M.; Kinniburgh, J.; Halliwell, D. Dungeons and Dialogues: A Collaborative Autoethnographic Account of Gender Performance in Tabletop RPGs. Women Lang. 2025, 48, 89–121. [Google Scholar]
- Nasir, J.A.; Varlamis, I.; Ishfaq, S. A Knowledge-Based Semantic Framework for Query Expansion. Inf. Process. Manag. 2019, 56, 1605–1617. [Google Scholar] [CrossRef] [Scilit]
- Hashimoto, B.; Nelson, K. Recent Trends in Corpus Design and Reporting: A Methodological Synthesis. Res. Corpus Linguist. 2024, 12, 59–88. [Google Scholar] [CrossRef] [Scilit]
- Bauer, M.W.; Gaskell, G.; Bauer, M.W.; Aarts, B. Corpus Construction: A Principle for Qualitative Data Collection. In Qualitative Researching with Text, Image and Sound; SAGE Publications Ltd.: London, UK, 2000; pp. 20–37. ISBN 978-1-84920-973-1. [Google Scholar]
- Park, S.; Hoffner, C.A. Tweeting about Mental Health to Honor Carrie Fisher: How #InHonorOfCarrie Reinforced the Social Influence of Celebrity Advocacy. Comput. Hum. Behav. 2020, 110, 106353. [Google Scholar] [CrossRef] [Scilit]
- Dirdal, H.; Johansen, S.H.; Durrant, P. Representativeness and Metadata Presentation in Learner/Child Corpora: Lessons From the GiG and TRAWL Corpora. Res. Methods Appl. Linguist. 2024, 3, 100145. [Google Scholar] [CrossRef] [Scilit]
- León, C.; Cabobianco, M.O.; Lipuma, J.; Marcone, J.; Cinanni, A.; Ponce-Díaz, R.; Castellano, J. DMSP para “Narrativas Transmedia y Convergencia: Creando un Repositorio Digital Transnacional para los Juegos de Rol (JdR) de Mega-Campañas”; DMPHub: Oakland, CA, USA; New Jersey Institute of Technology: Newark, NJ, USA, 2026. [Google Scholar]
- Zhang, J.; Xu, J.; Li, M. The Impact of Educational Live Action Role-Playing Games on Social-Emotional Competence: A Mixed-Method Study with Chinese College Students. Front Psychol. 2025, 16, 1538761. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Niarchos, A.; Petousi, D.; Katifori, A.; Sakellariadis, P.; Ioannidis, Y. Bridging the Gap Between the Physical and the Virtual in Tabletop Role Playing Games: Exploring Immersive VR Tabletops. In Proceedings of the Interactive Storytelling: 16th International Conference on Interactive Digital Storytelling, ICIDS 2023, Part I; Holloway-Attaway, L., Murray, J.T., Eds.; Springer Science and Business Media: Cham, Switzerland, 2023; Volume 14383, pp. 489–503. [Google Scholar]
- James, R.P. A Corpus Linguistic Analysis of Tabletop Role-Playing Game Blogging. Ph.D. Dissertation, Oregon State University, Corvallis, OR, USA, 2023. [Google Scholar]
- Hobbi, D.M.; Bololia, L. An Autoethnographic Exploration of Tabletop Role-Playing Games as a Therapeutic Tool in Dramatherapy. Arts Psychother. 2026, 97, 102413. [Google Scholar] [CrossRef] [Scilit]
- Sezen, D.; Akcali, A.; Sezen, T.I.; Perks, S.; Stewart, P. Exploring Women’s Role in Creative Industries Through Collaborative Action Research Using Tabletop Role-Playing Games. In Proceedings of the Technology, Innovation, Entrepreneurship and Education, Tie 2023; Crawford, D., Foss, J., Lambert, N., Reed, M., Kriebel, J., Eds.; Springer International Publishing: Cham, Switzerland, 2024; Volume 575, pp. 39–53. [Google Scholar]
- Weerasundara, G.; De Silva, N. Comparative Analysis of Named Entity Recognition in the Dungeons and Dragons Domain. In Proceedings of the Recent Advances in Natural Language Processing, Varna, 4–6 September 2023; Incoma Ltd.: Shoumen, Bulgaria, 2023; pp. 1225–1233. [Google Scholar]
- von Kacsoh, L.; Horst, R.; Dörner, R. From Stat Block to Tabletop: A First-Order Logic Framework for Authoring Immersive RPG Combat Encounters. In Proceedings of the HCI IN GAMES, HCI-GAMES 2025; Springer Science and Business Media Deutschland GmbH: Cham, Switzerland, 2025; Volume 15816, pp. 298–314. [Google Scholar]
- Zheng, Z.; Porter, N.; Hilliard, T.; Yang, F.-J. The Strategic Optimization of a Tabletop Role-Playing Game. In Proceedings of the Scientific Computing and Bioinformatics and Computational Biology, Csc 2024, Biocomp 2024; Hodson, D.D., Grimaila, M.R., Arabnia, H.R., Deligiannidis, L., Wagner, T.J., Eds.; Springer International Publishing: Cham, Switzerland, 2025; Volume 2258, pp. 173–181. [Google Scholar]
- Billieux, J.; Fournier, L.; Rochat, L.; Georgieva, I.; Eben, C.; Malmdorf Andersen, M.; King, D.L.; Simon, O.; Khazaal, Y.; Lieberoth, A.; et al. Can Playing Dungeons and Dragons Be Good for You? A Registered Exploratory Pilot Programme Using Offline Tabletop Role-Playing Games to Mitigate Social Anxiety and Reduce Problematic Involvement in Multiplayer Online Video Games. R Soc. Open Sci. 2025, 12, 250273. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Henning, G.; de Oliveira, R.R.; de Andrade, M.T.P.; Gallo, R.V.; Benevides, R.R.; Gomes, R.A.F.; Fukue, L.E.K.; Lima, A.V.; de Oliveira, M.B.B.Z.N.; de Oliveira, D.A.M.; et al. Social Skills Training with a Tabletop Role-Playing Game, Before and During the Pandemic of 2020: In-Person and Online Group Sessions. Front. Psychiatry 2024, 14, 1276757. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Atherton, G.; Hathaway, R.; Visuri, I.; Cross, L. A Critical Hit: Dungeons and Dragons as a Buff for Autistic People. Autism 2025, 29, 382–394. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Snodgrass, J.G.; Sagstetter, S.I.; Chakrabarti, C.; Branstrator, J.R.; Zhao, K.X.; Lacy, M.G.; Dengah, H.J.F.; Wagner, A.; Giardina, A.; Billieux, J. Tabletop Role-Playing Games as Drama Therapy in the Wild: Developing Personal Bonds with Characters Improves Players’ Self-Concepts. Transcult. Psychiatry 2026, 13634615261418363. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Brockway, D. Collaboration and Empowerment: Reimagining Literacy in the Composition Classroom through Tabletop Role-Playing Games. In Education and Analog Role-Playing Games: Theory and Pedagogy, Volume 1; Haarman, S., Gustafson, K., Eds.; CRC Press: Boca Raton, FL, USA, 2025; Volume 1, pp. 128–144. ISBN 978-1-040-44169-5. [Google Scholar]
- Harviainen, J.T.; Bienia, R.; Bowman, S.L.; Brind, S.; Hitchens, M.; Kot, Y.I.; MacCallum-Stewart, E.; Simkins, D.W.; Stenros, J.; Sturrock, I. Live-Action Role-Playing Games. In The Routledge Handbook of Role-Playing Game Studies; Routledge: Abingdon, UK, 2024; pp. 92–114. [Google Scholar]
- Liu, S.; Wang, J.; Long, Y.; Tan, Y. Motivational and Behavioral Differences Between Traditional and Digital Tabletop Games. In Proceedings of the Advances in Usability, User Experience, Wearable and Assistive Technology, Ahfe 2021; Ahram, T.Z., Falcao, C.S., Eds.; Springer International Publishing: Cham, Switzerland, 2021; Volume 275, pp. 351–359. [Google Scholar]
- Martinho, C.; Sousa, M. CSSII: A Player Motivation Model for Tabletop Games. In Proceedings of the 18th International Conference on the Foundations of Digital Games, Fdg 2023; Lopes, P., Luz, F., Liapis, A., Engstrom, H., Eds.; Assoc Computing Machinery: New York, NY, USA, 2023; p. 13. [Google Scholar]
- aan het Rot, H.; Kortmann, R.; Verbraeck, A.; de Vries, G.; Kooreman, M.; de Bruin, B. Facilitated Tabletop Games in a Mediated Environment. In Proceedings of the Gaming, Simulation and Innovations: Challenges and Opportunities, Indore, India, 6–10 September 2021; Dhar, U., Dubey, J., Dumblekar, V., Meijer, S., Lukosch, H., Eds.; Springer International Publishing: Cham, Switzerland, 2022; Volume 13219, pp. 28–41. [Google Scholar]
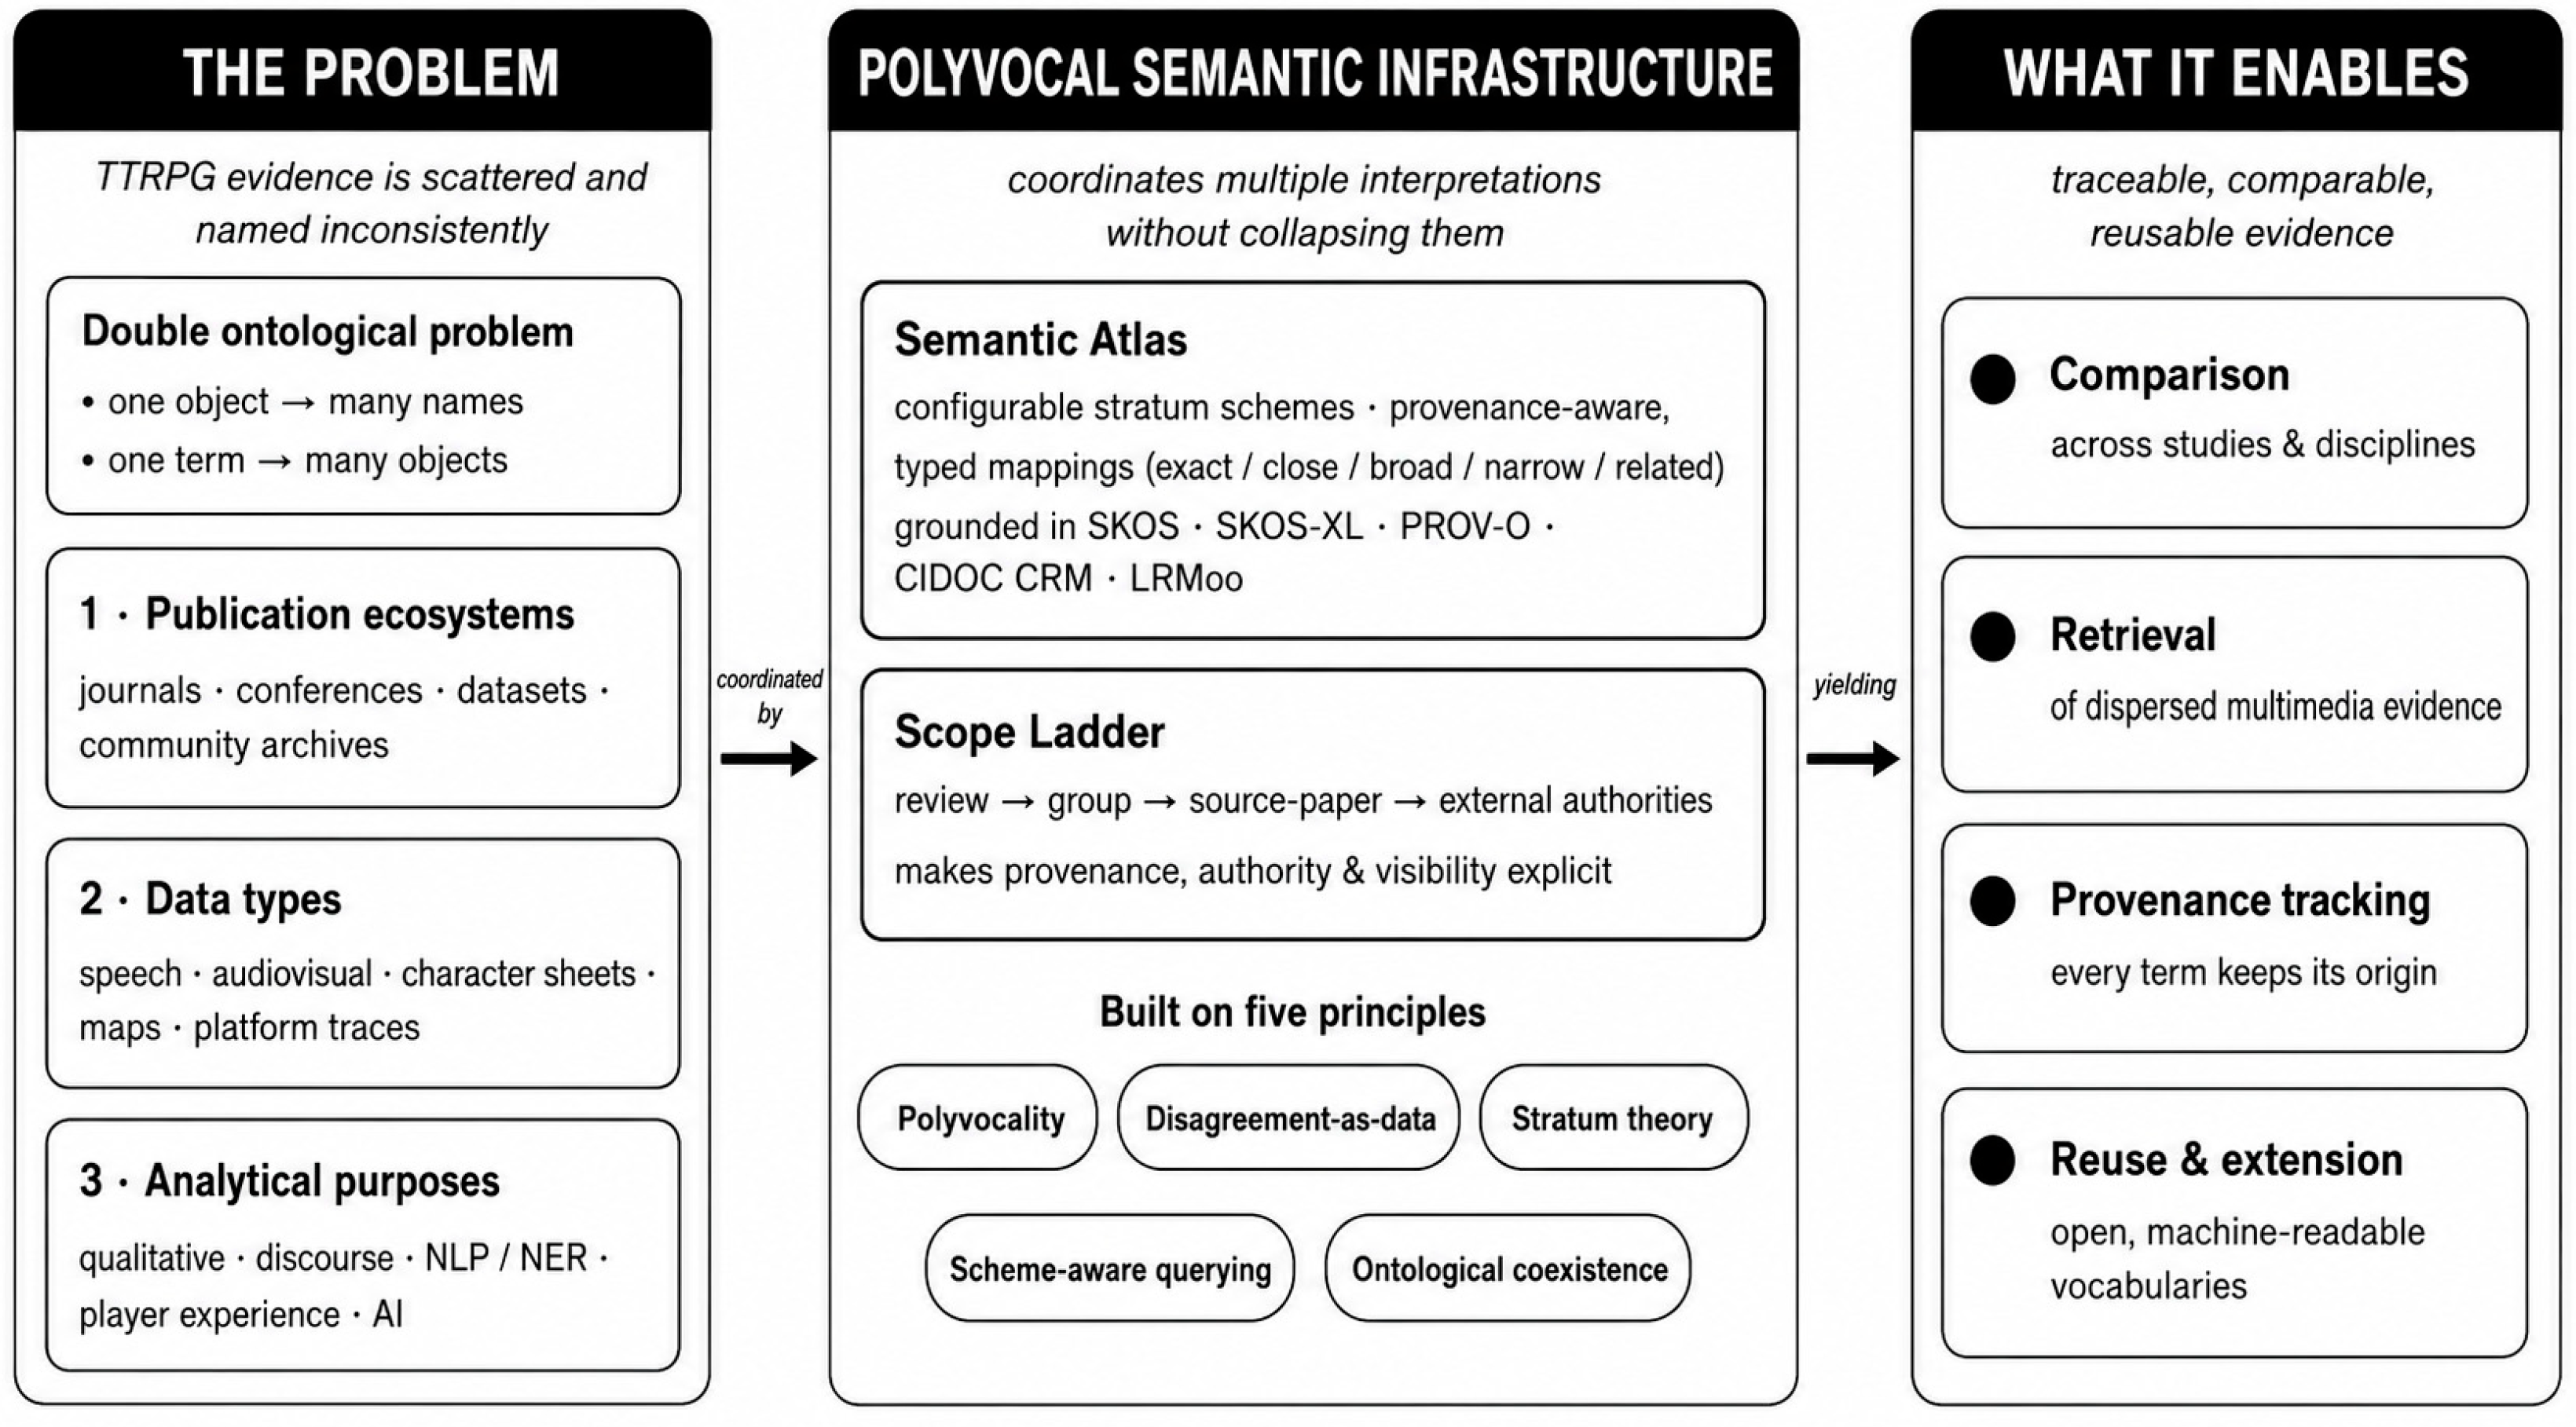
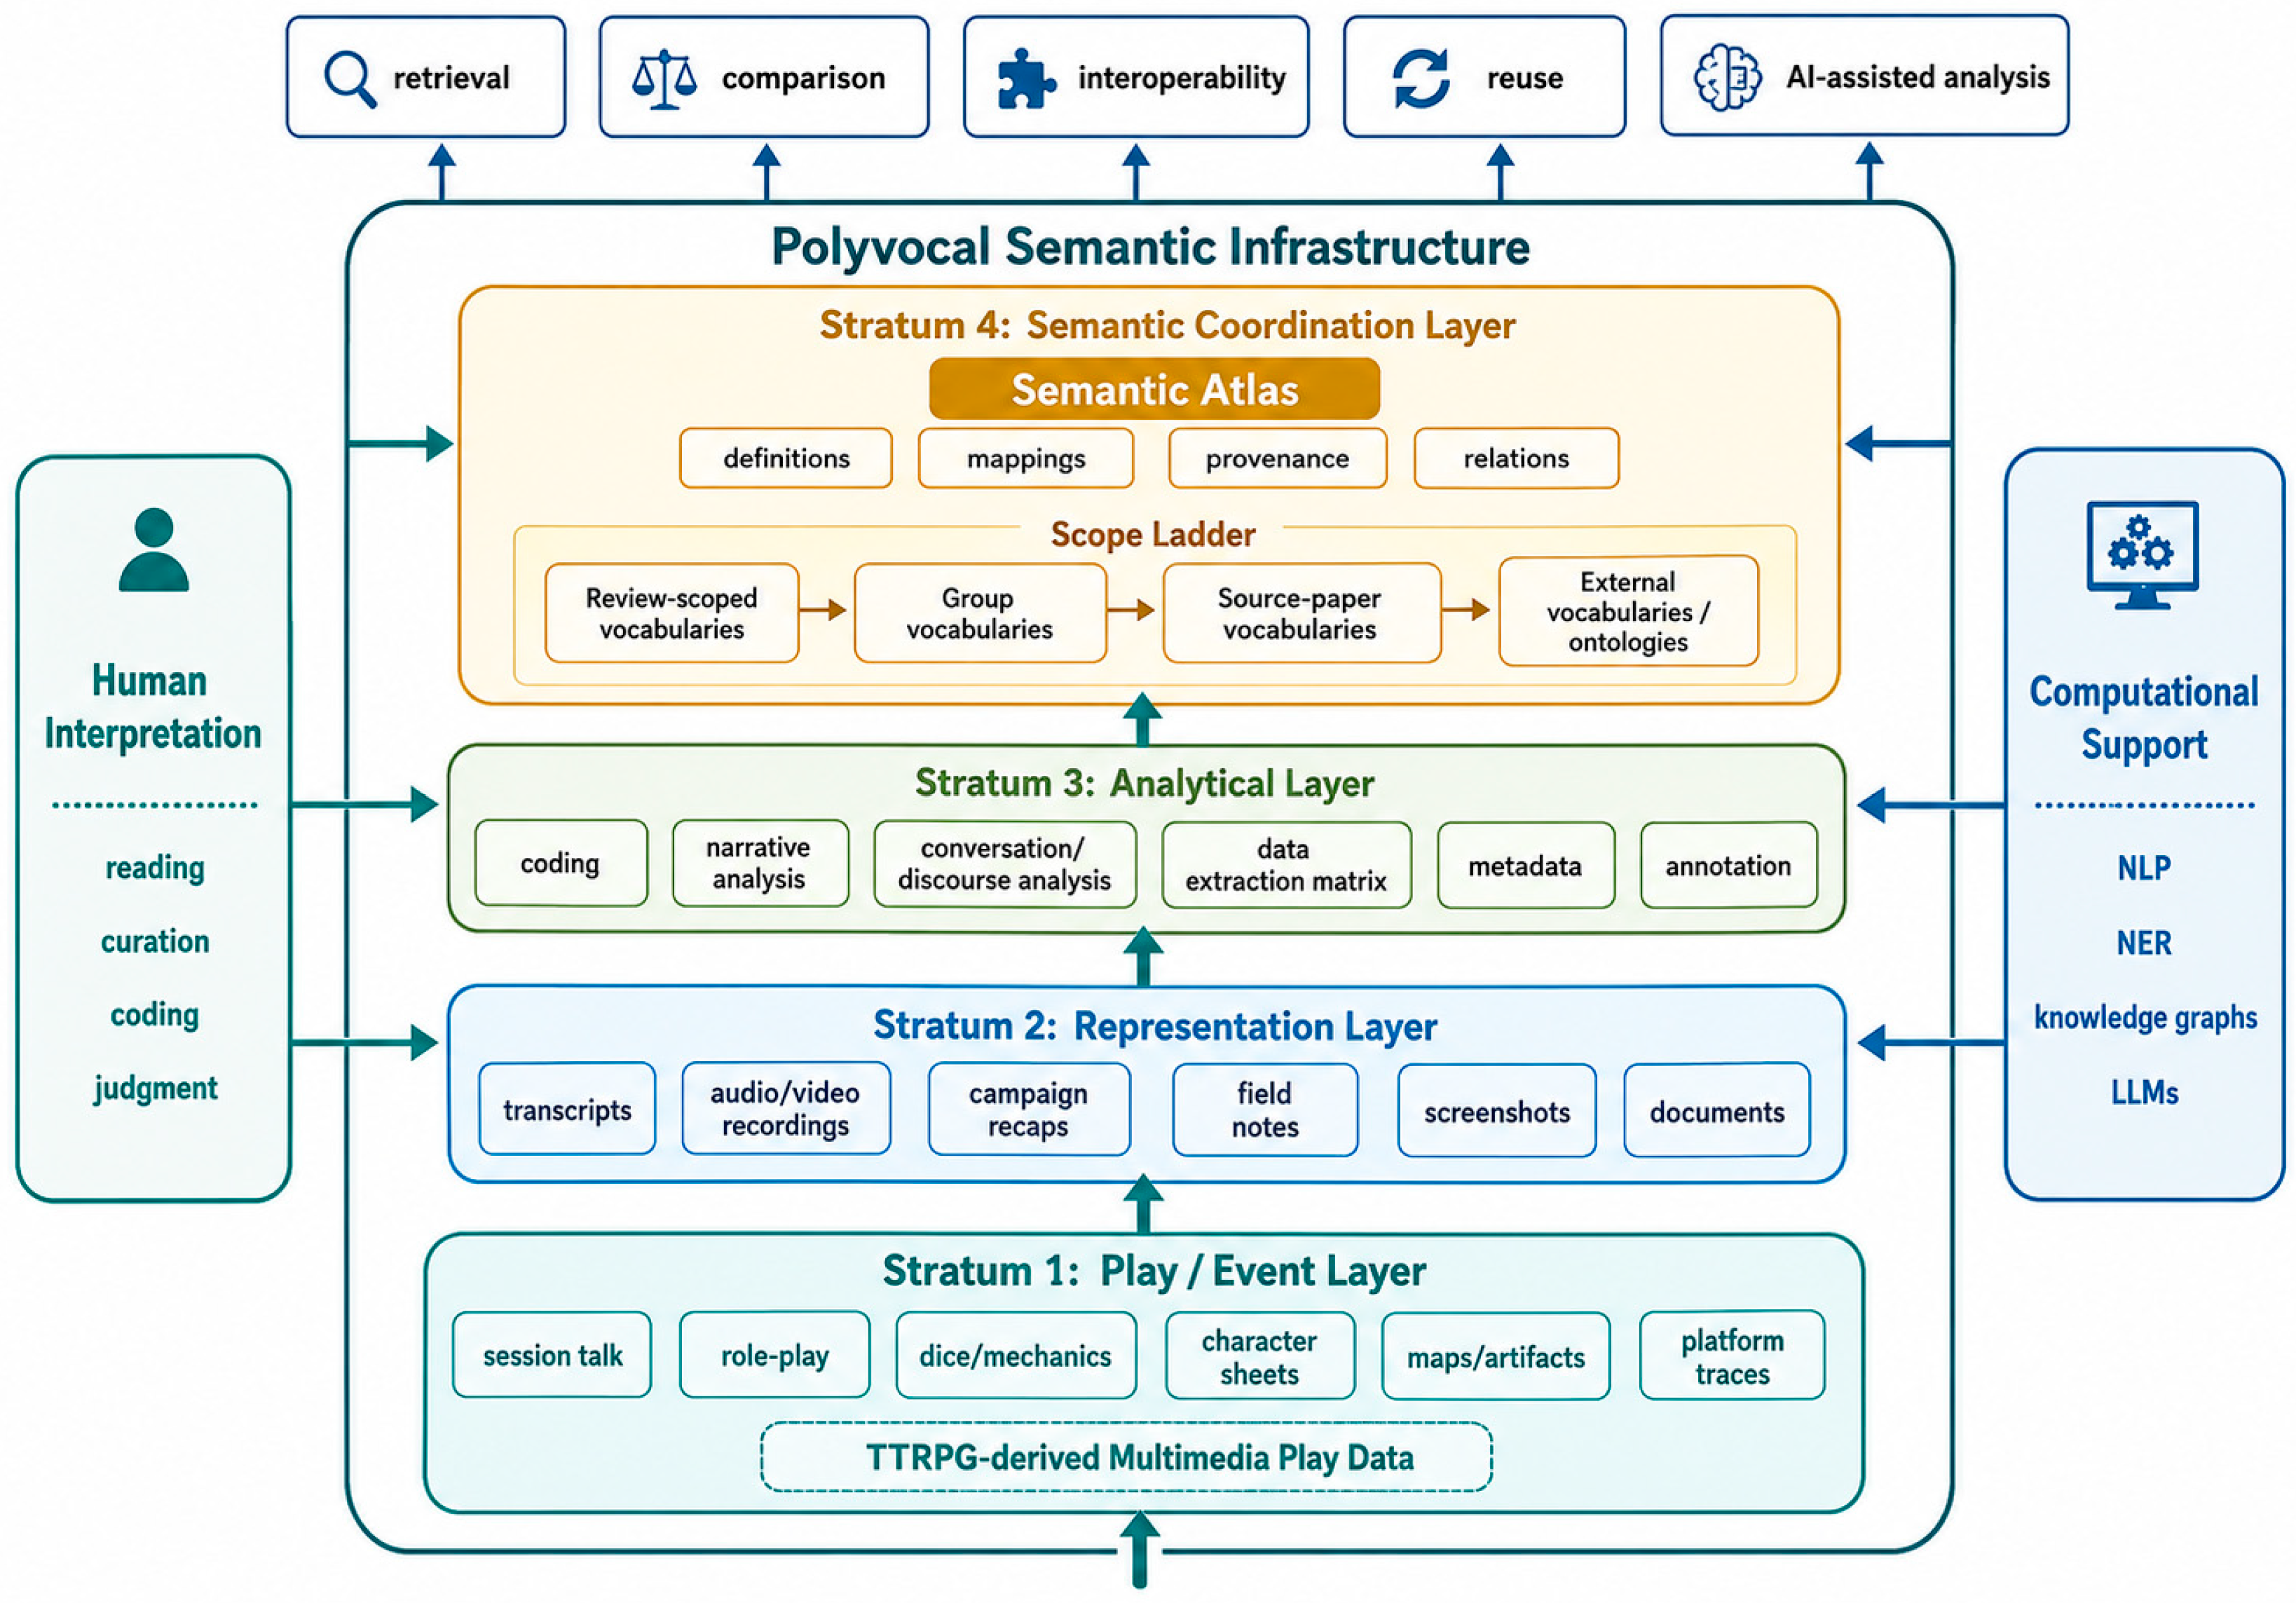
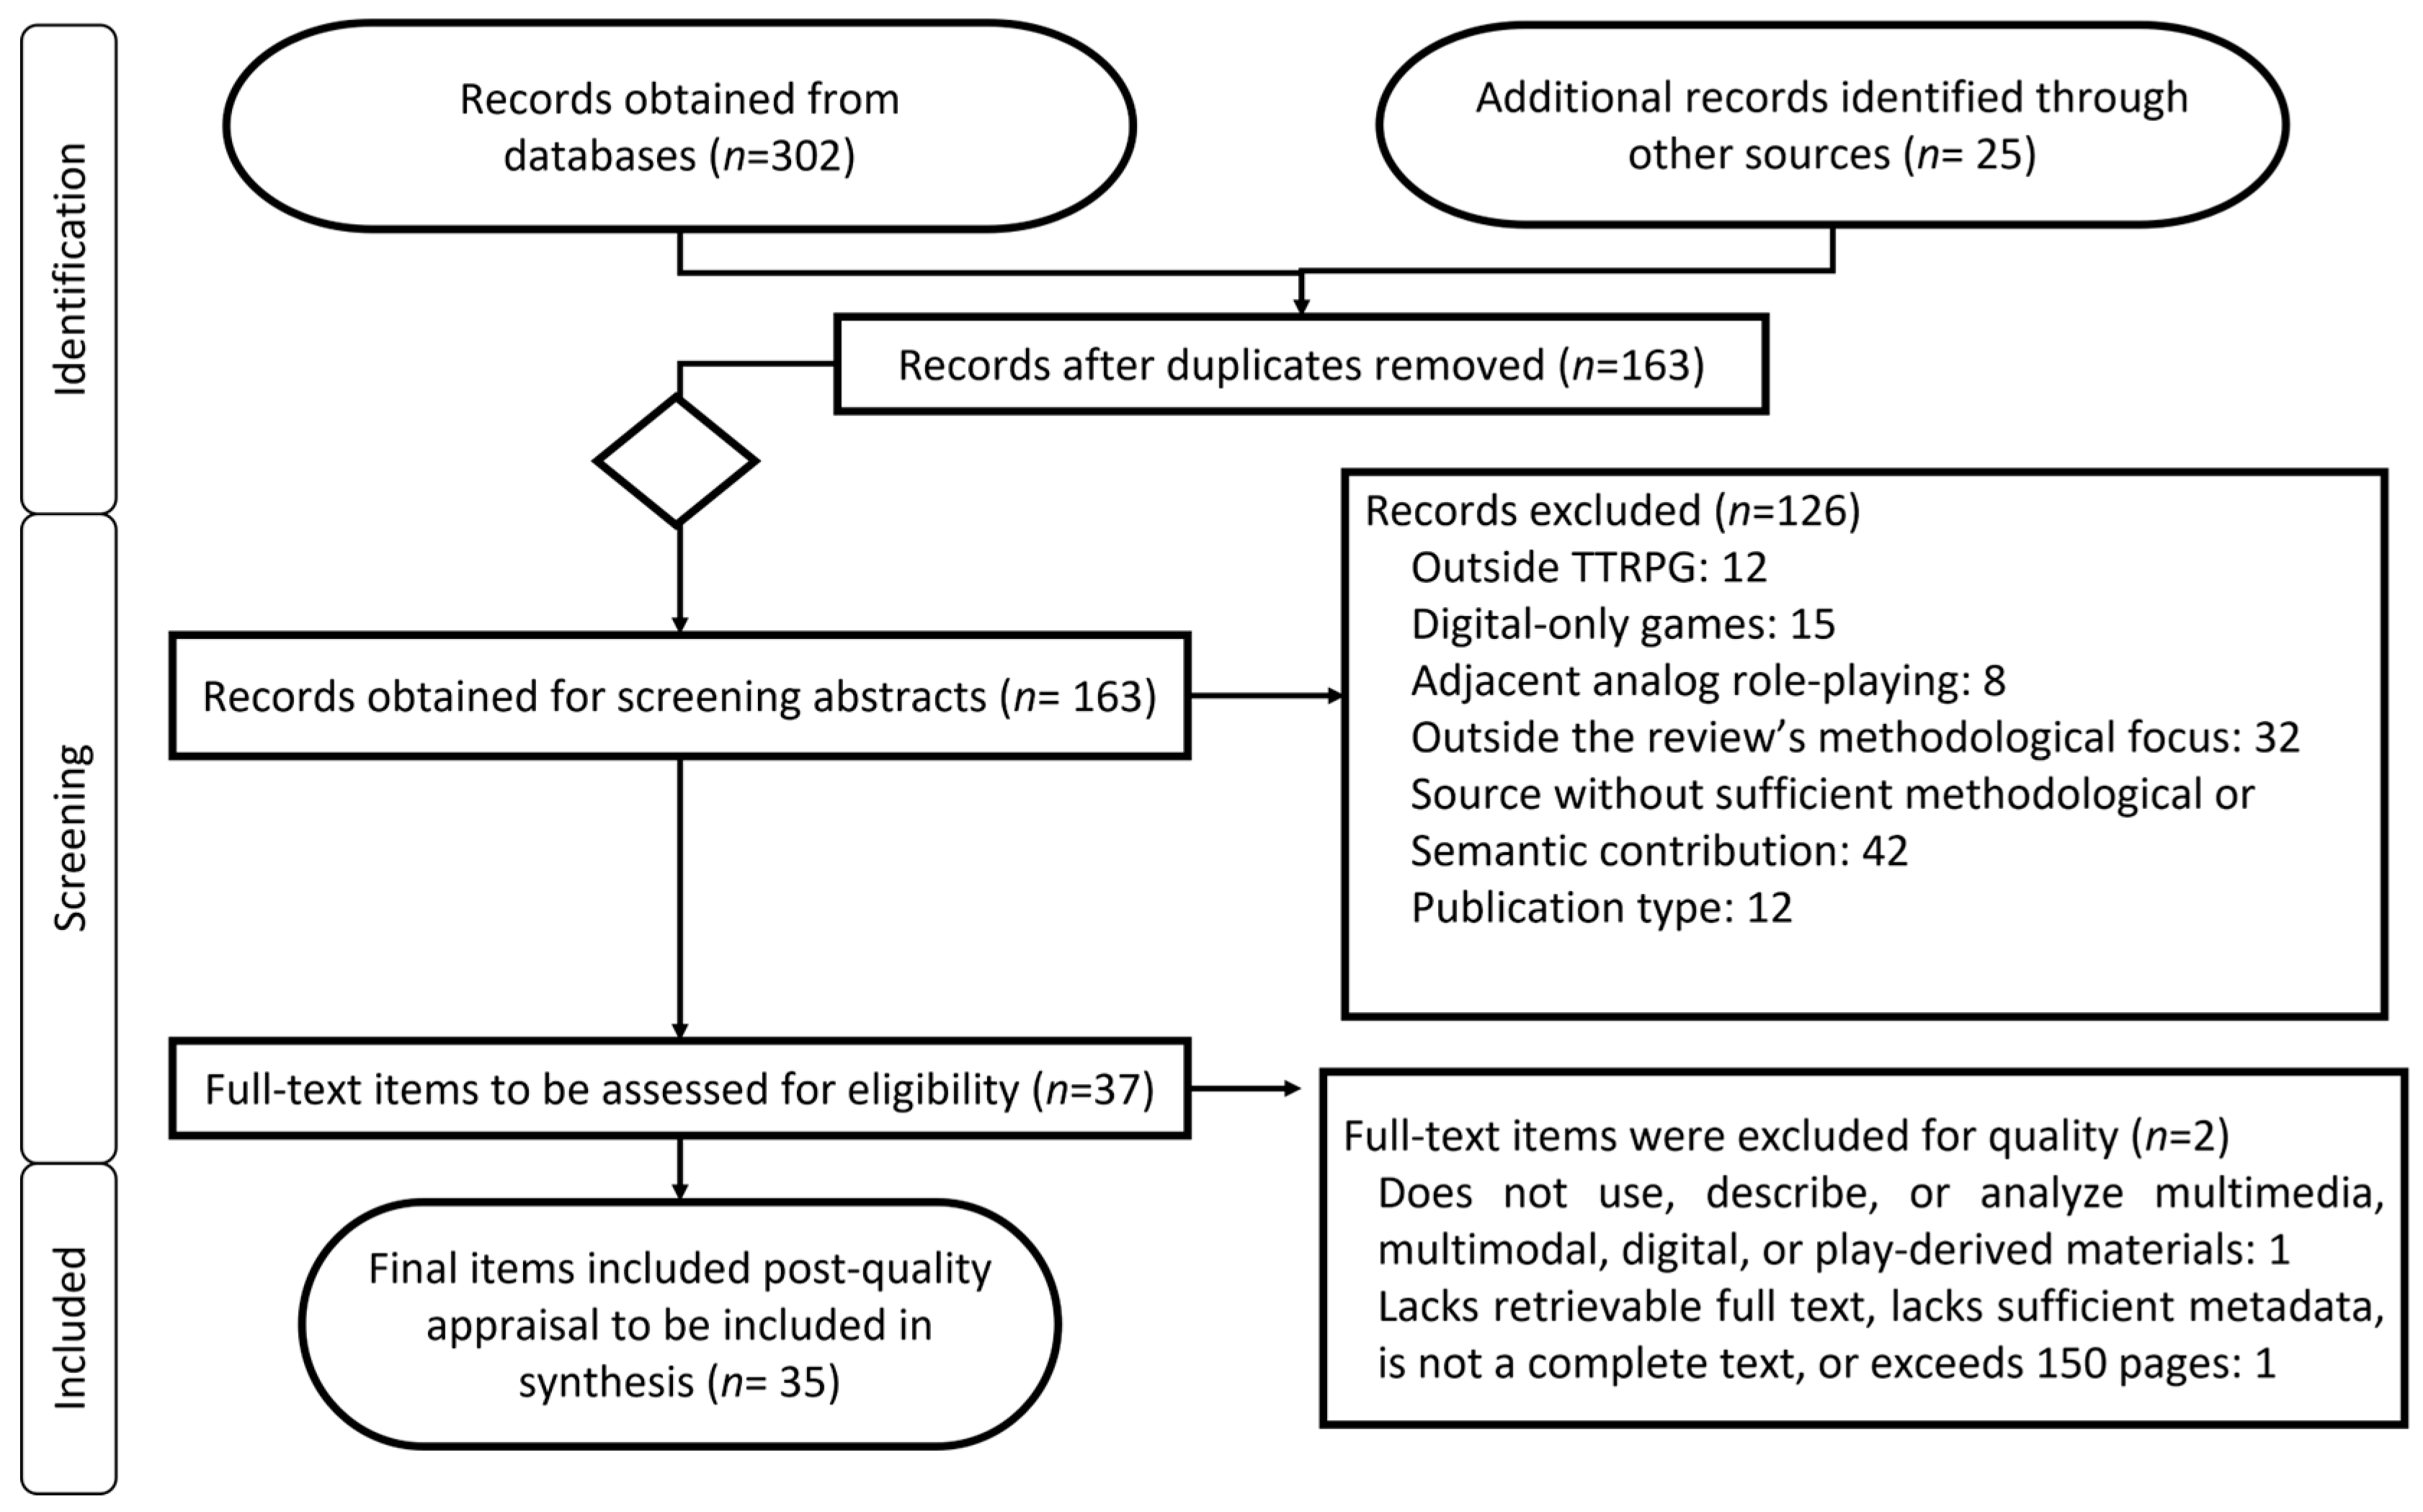
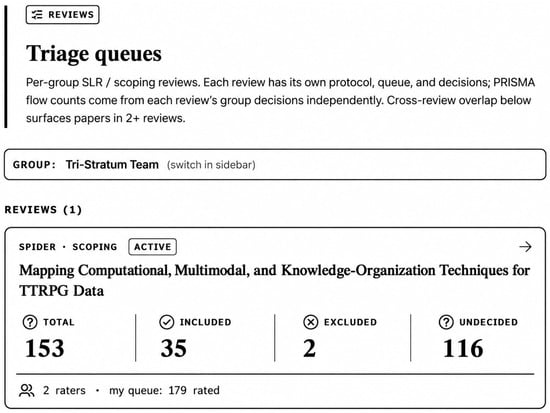
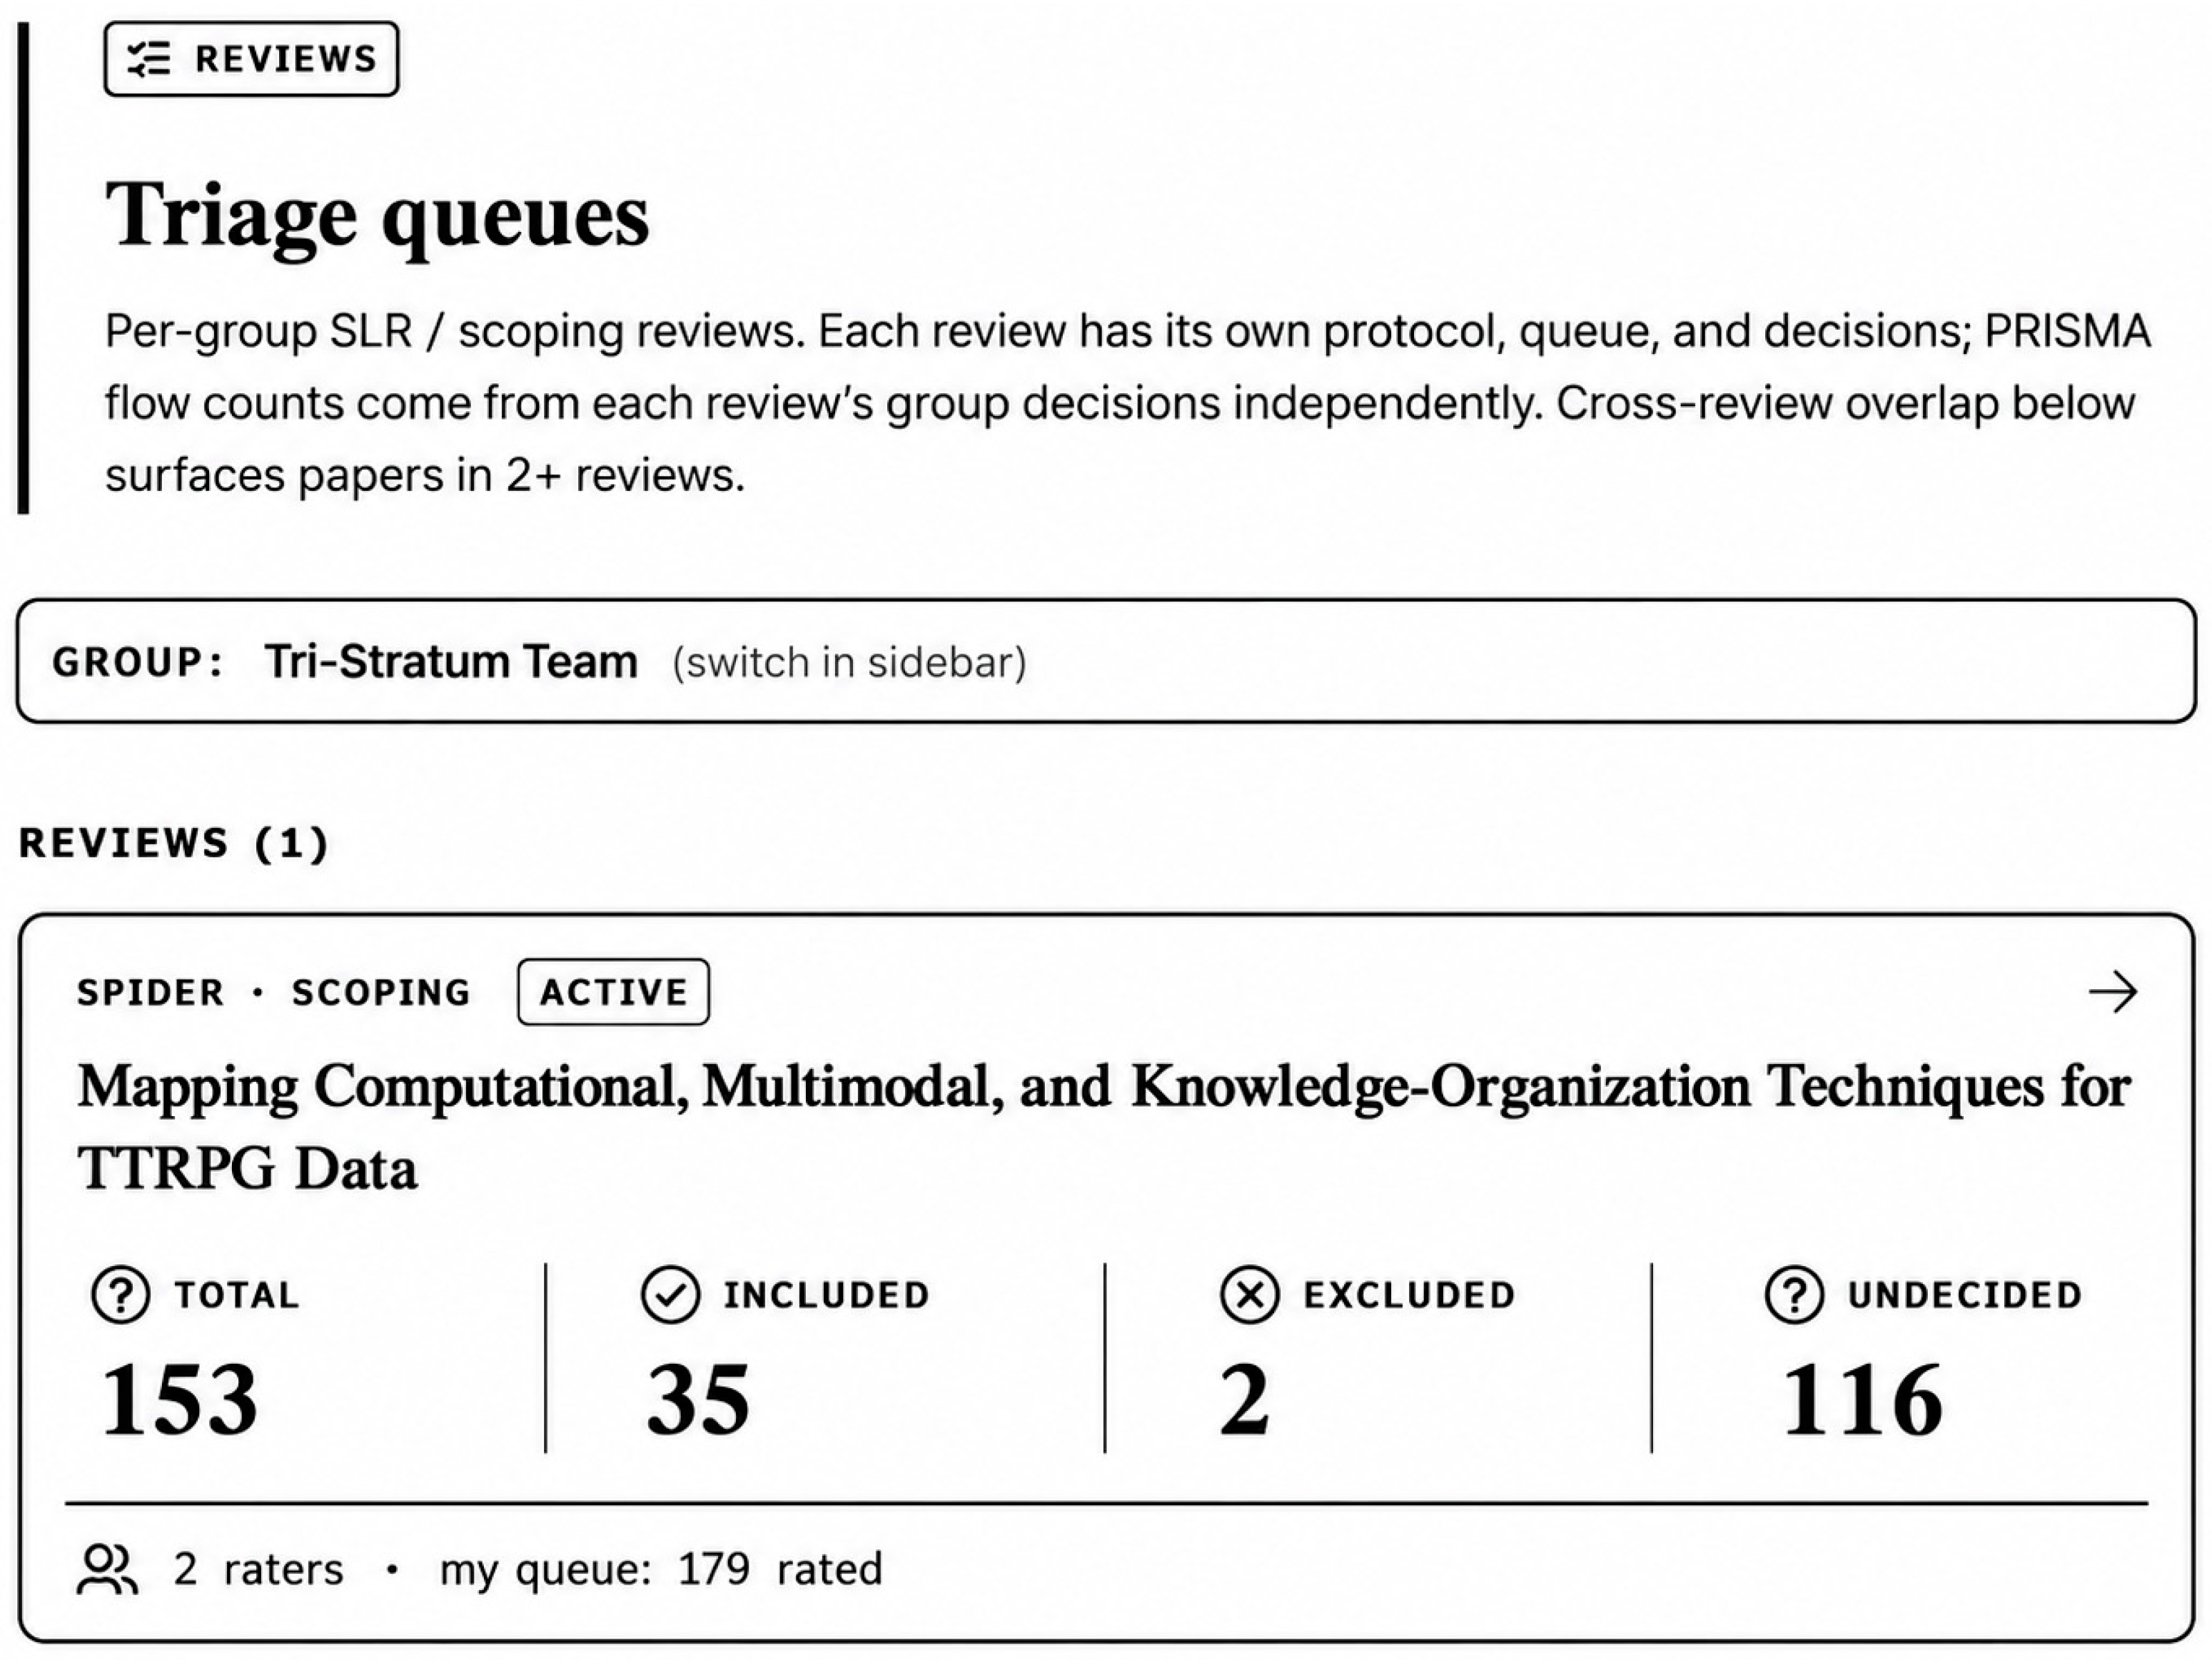
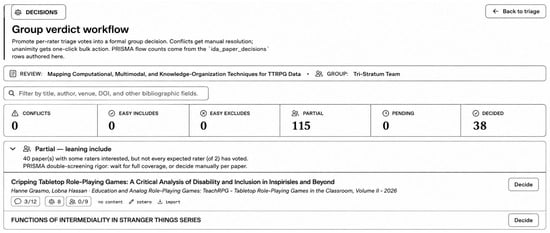
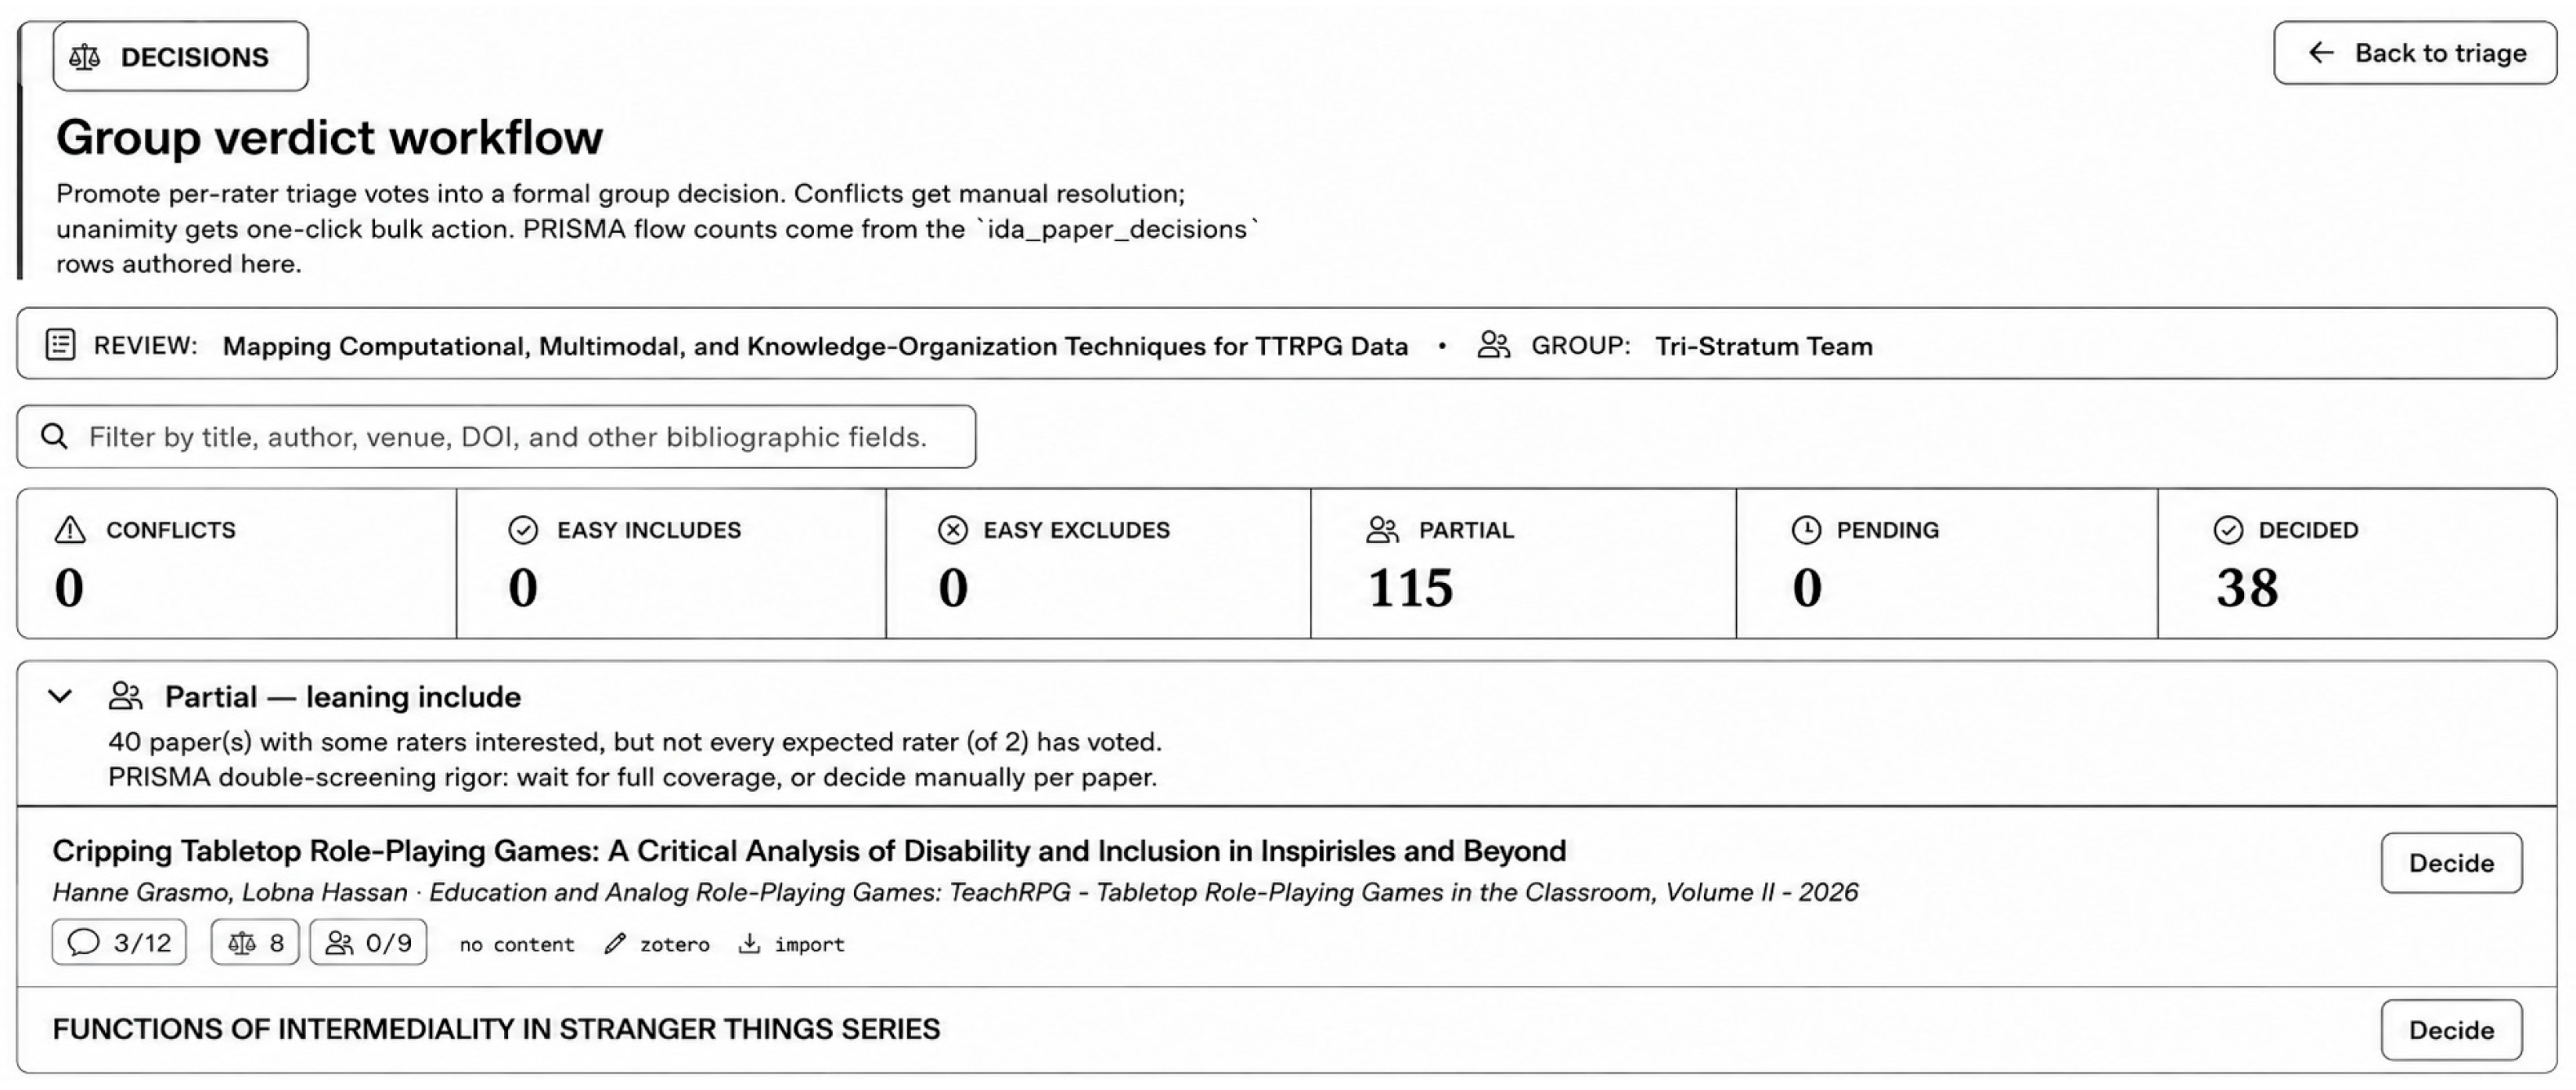
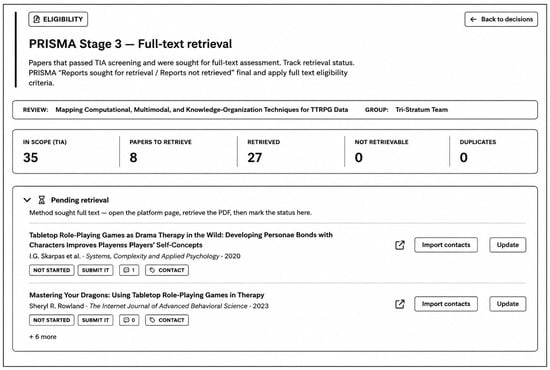
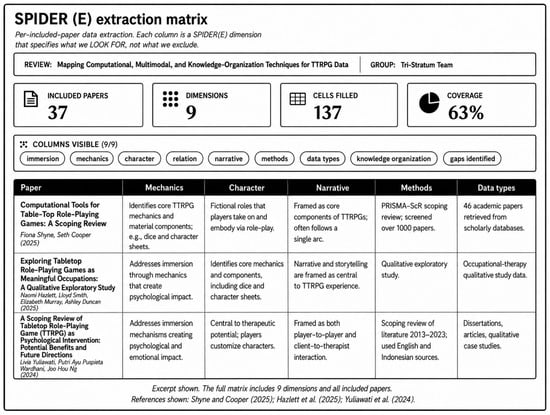
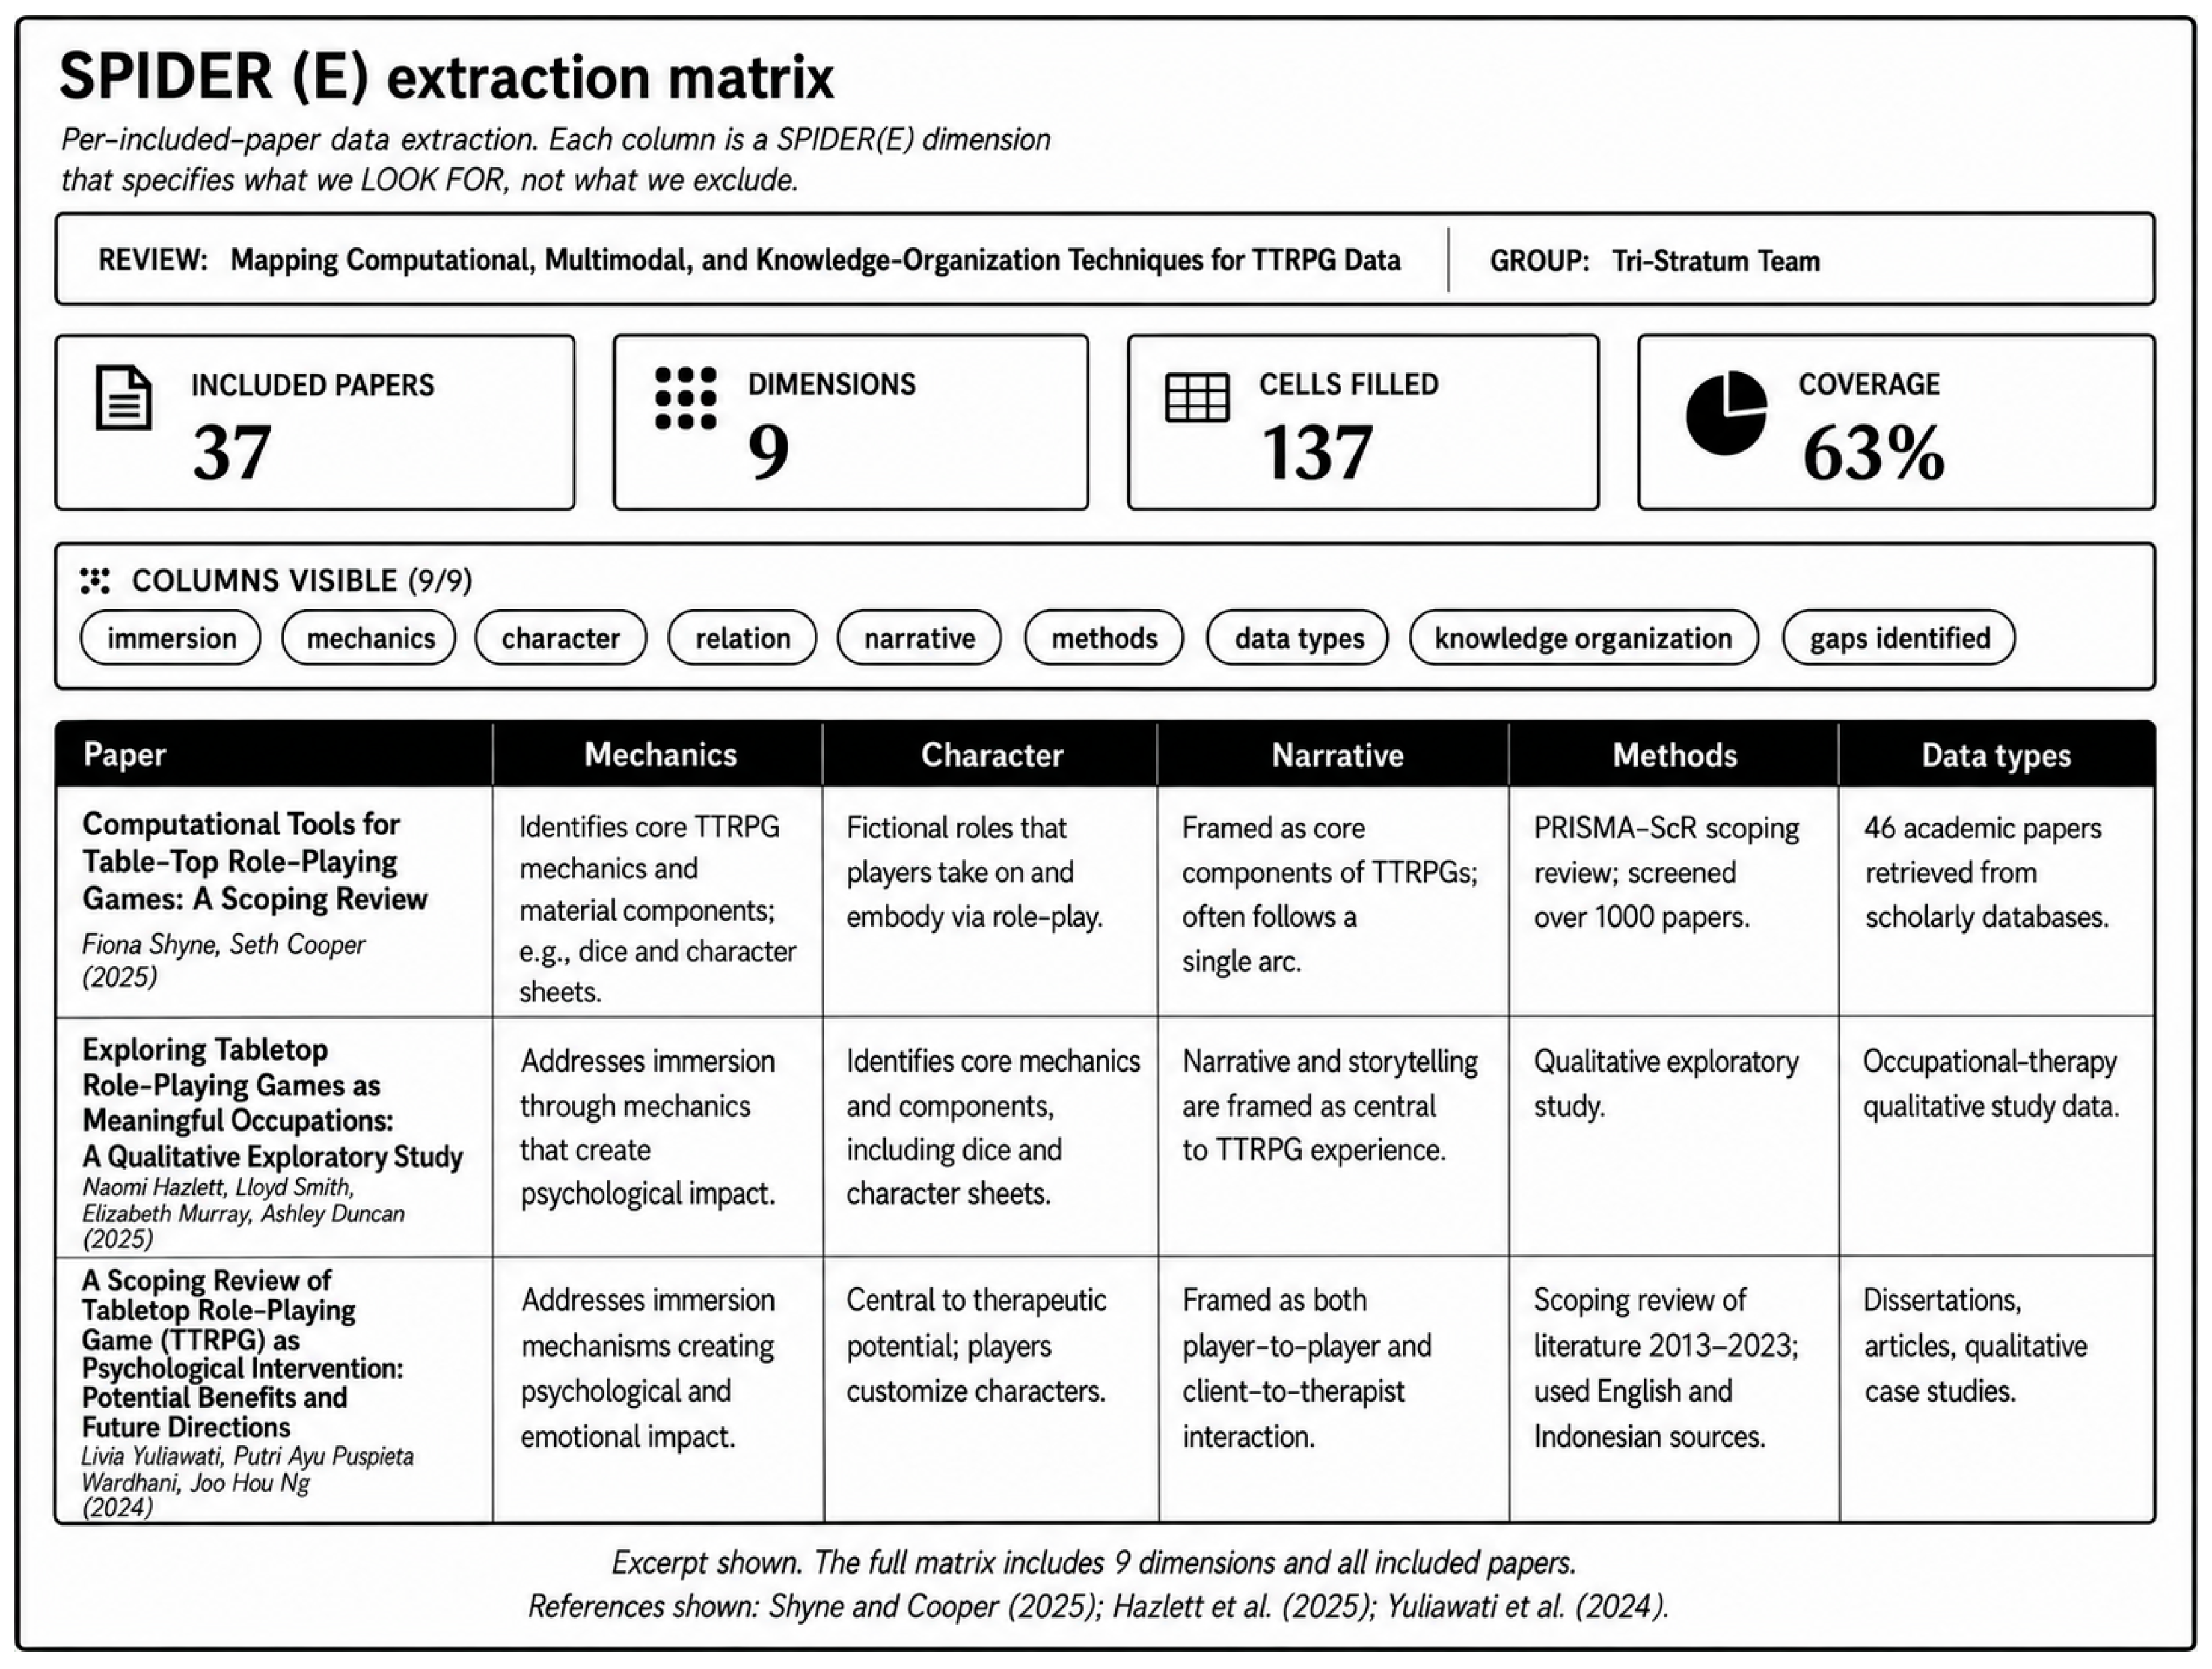
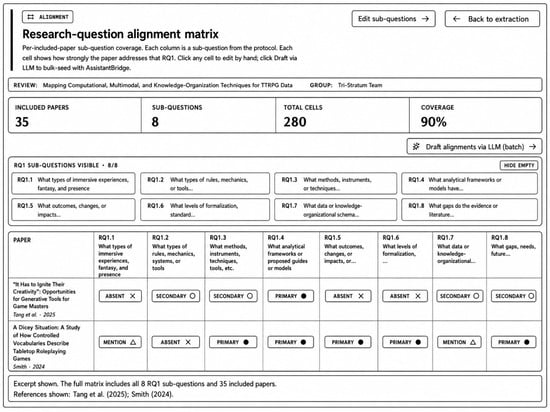
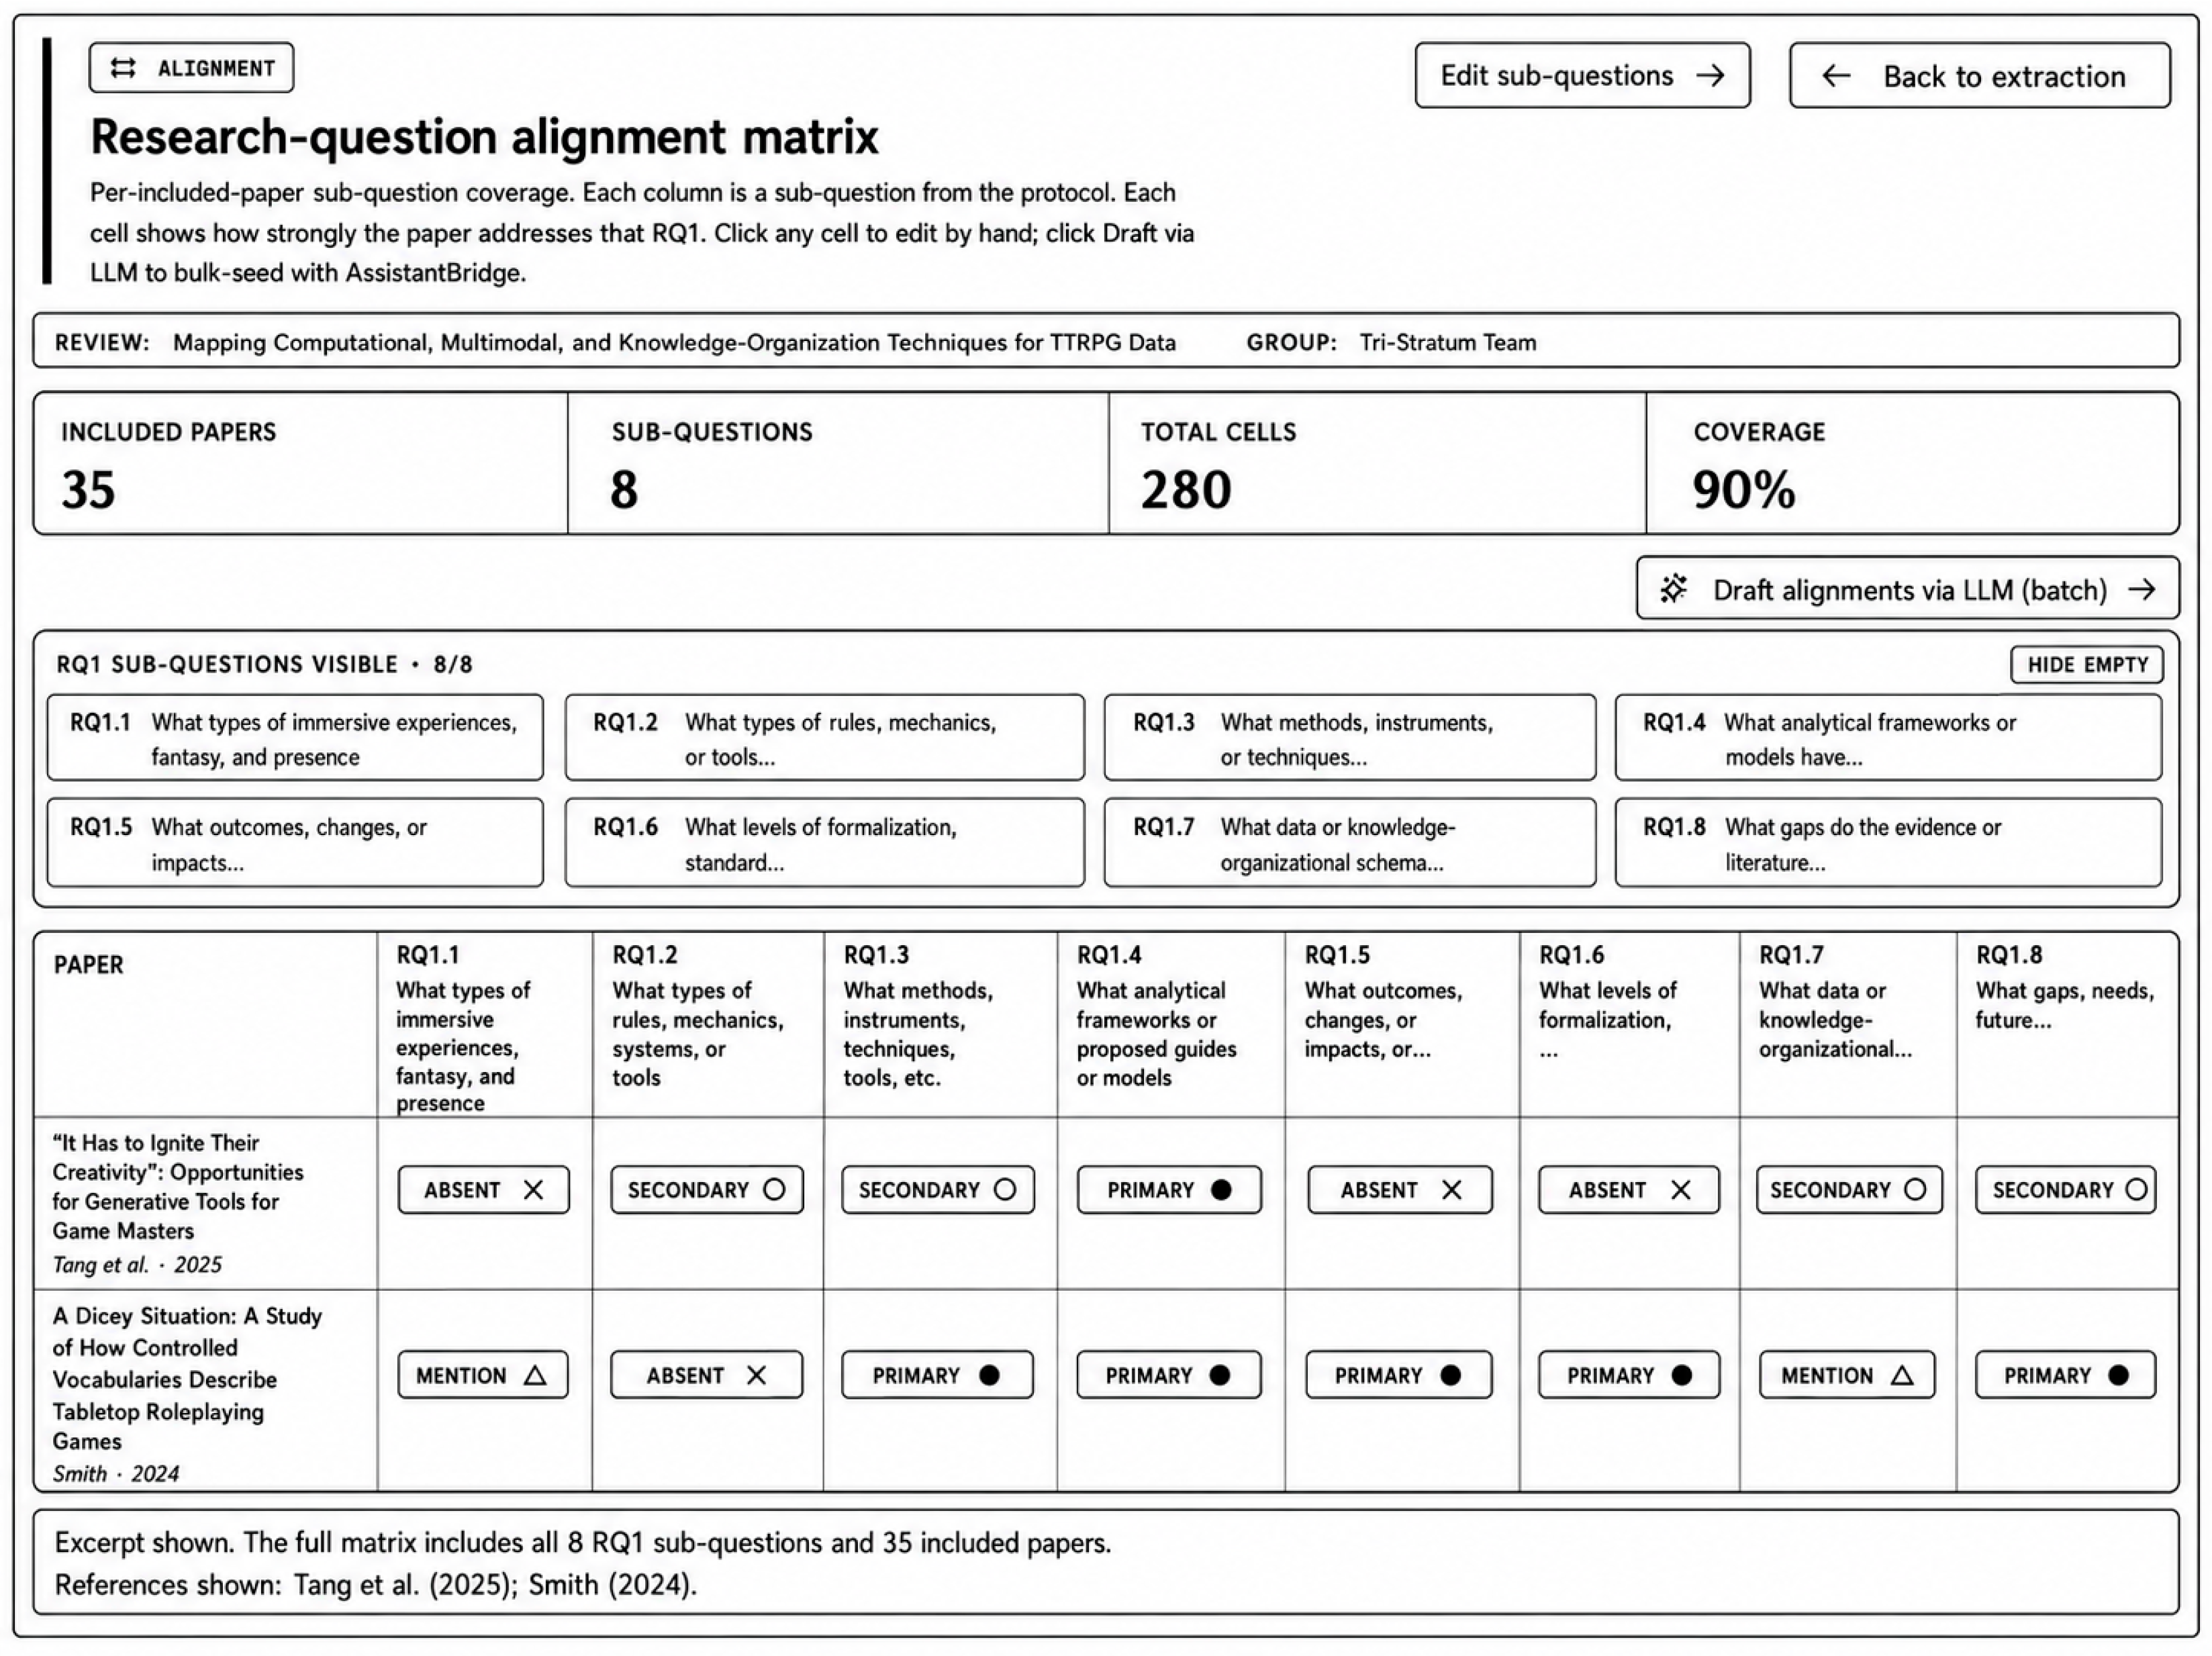
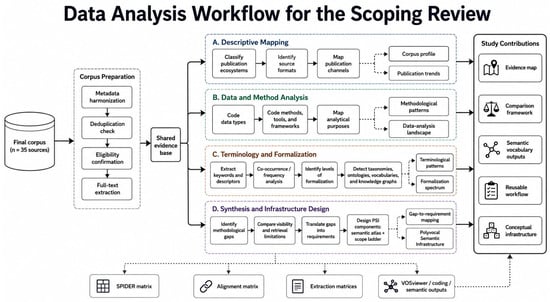
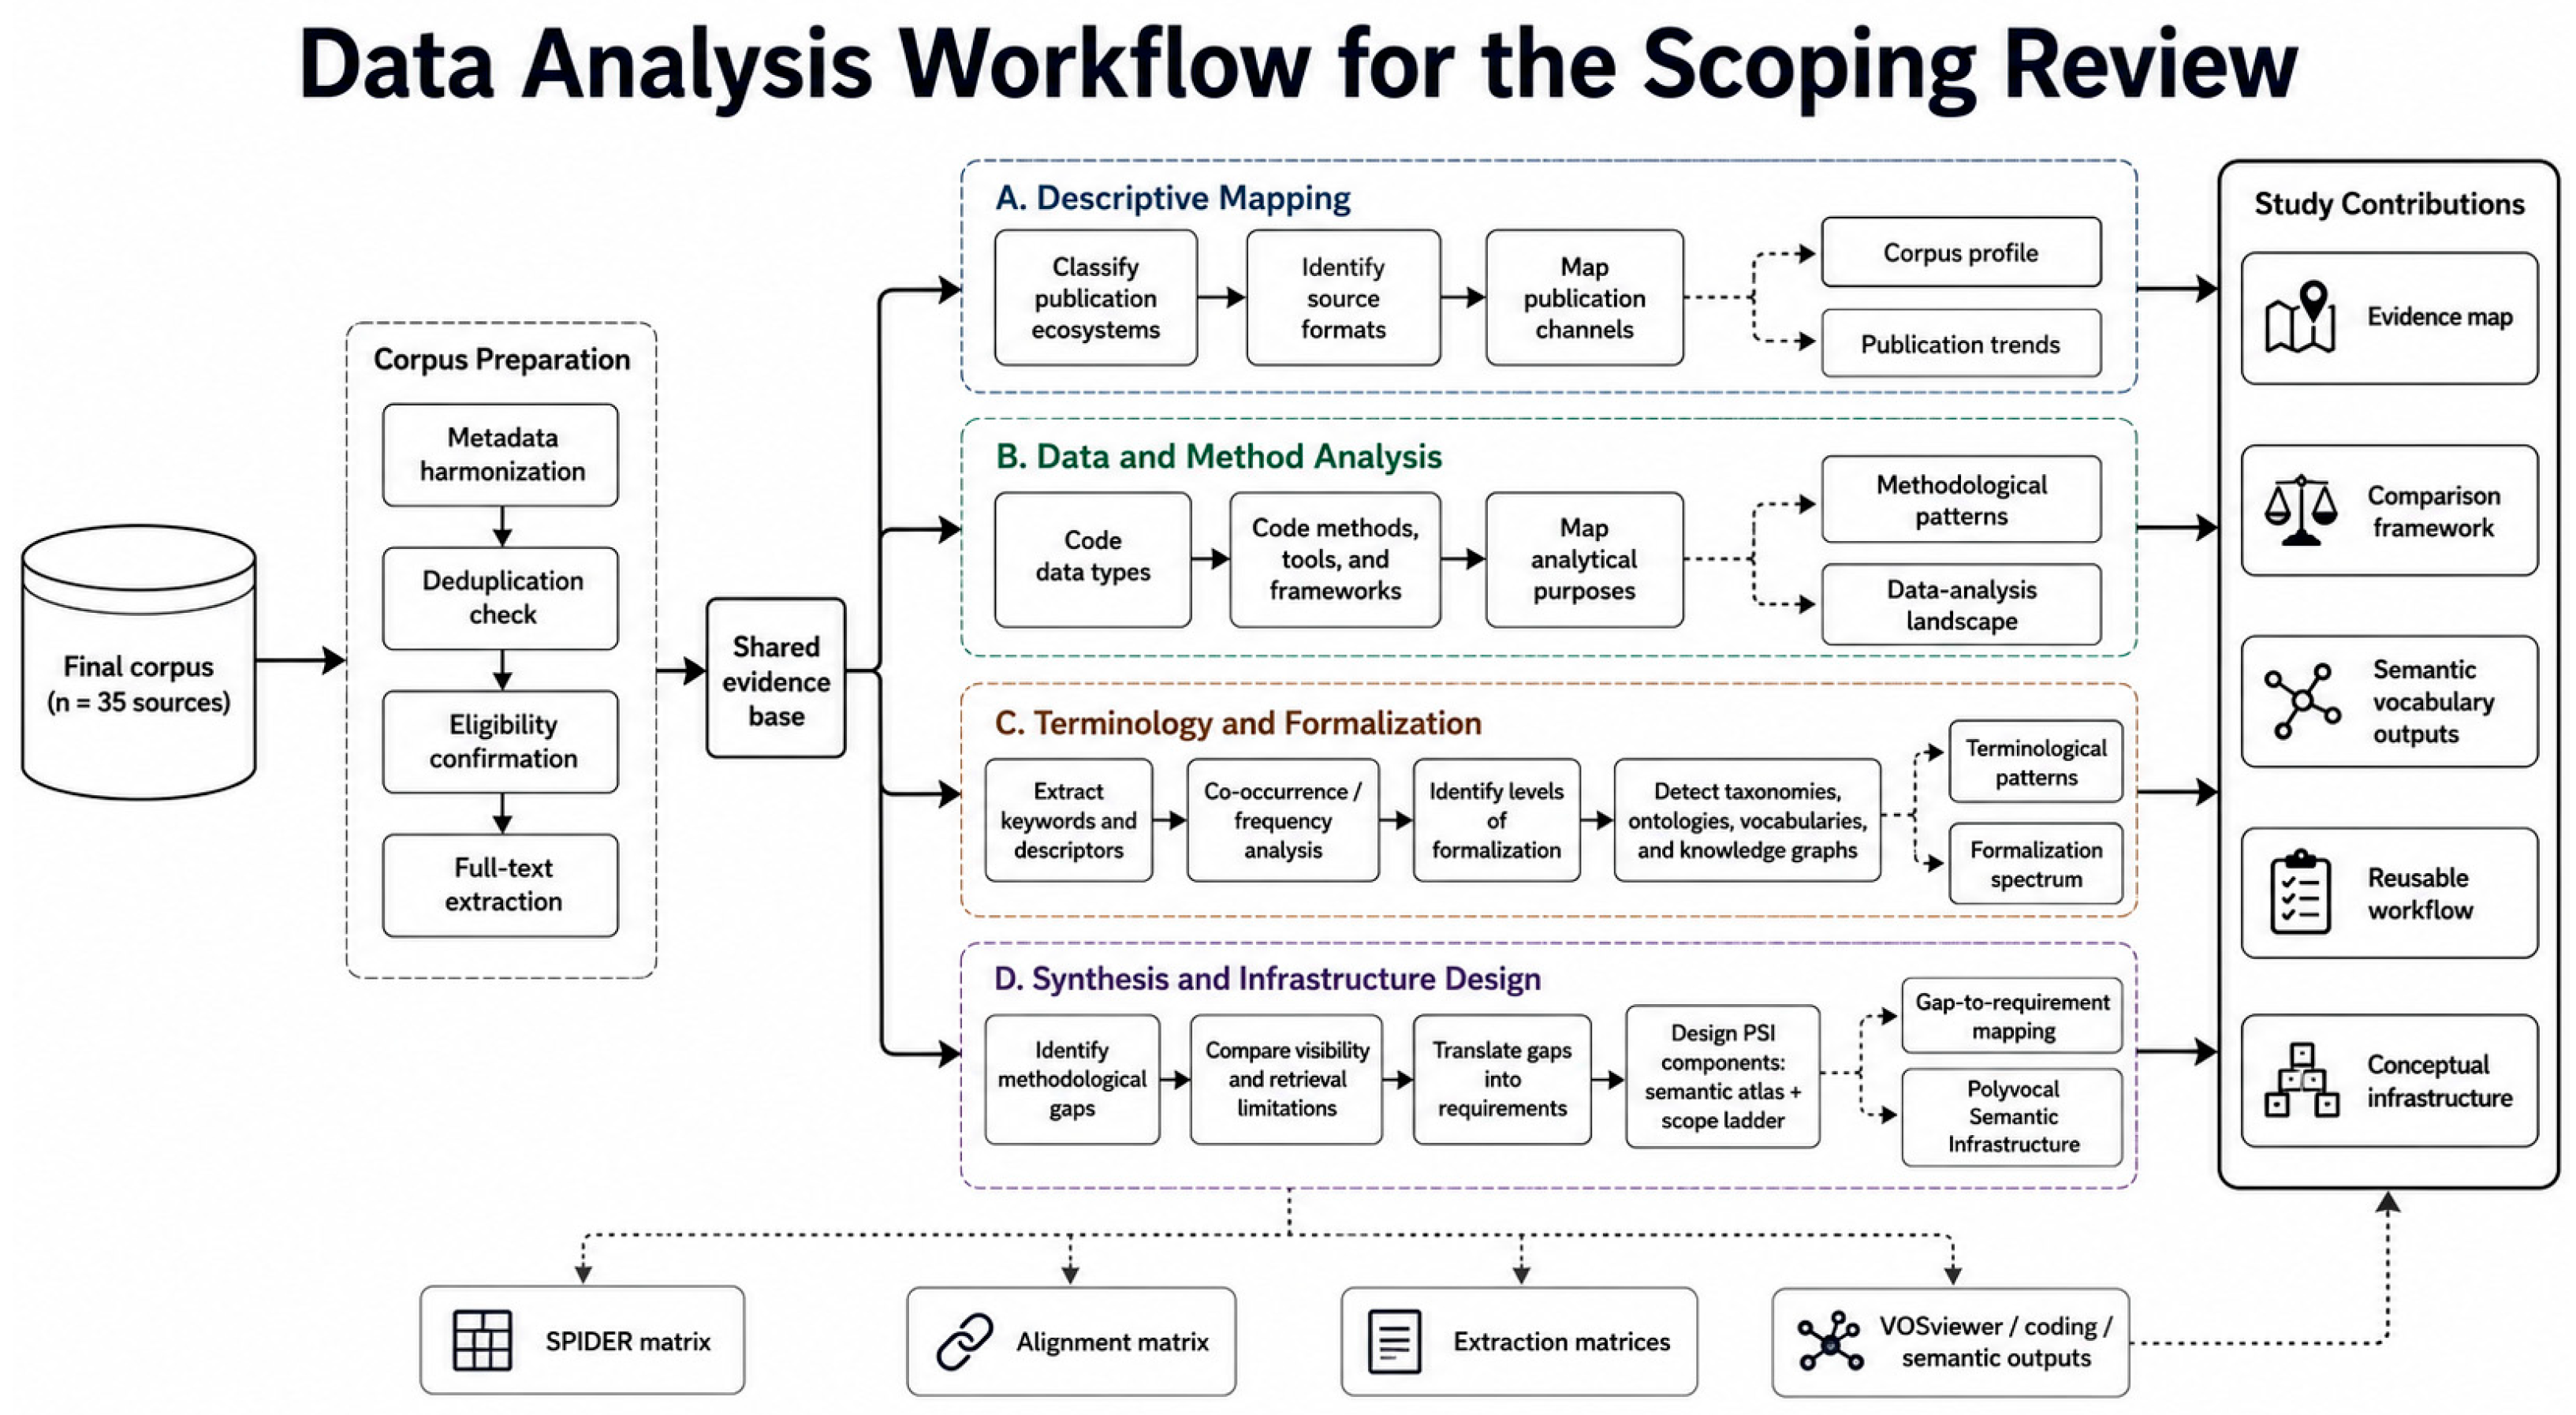
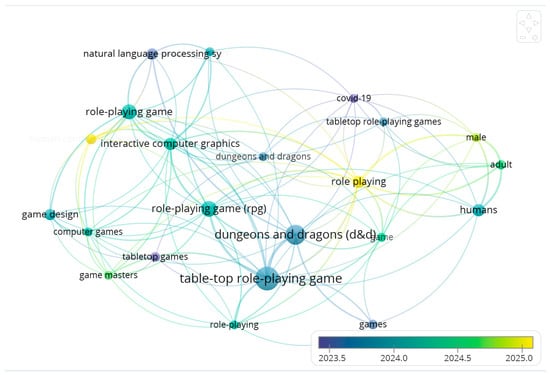
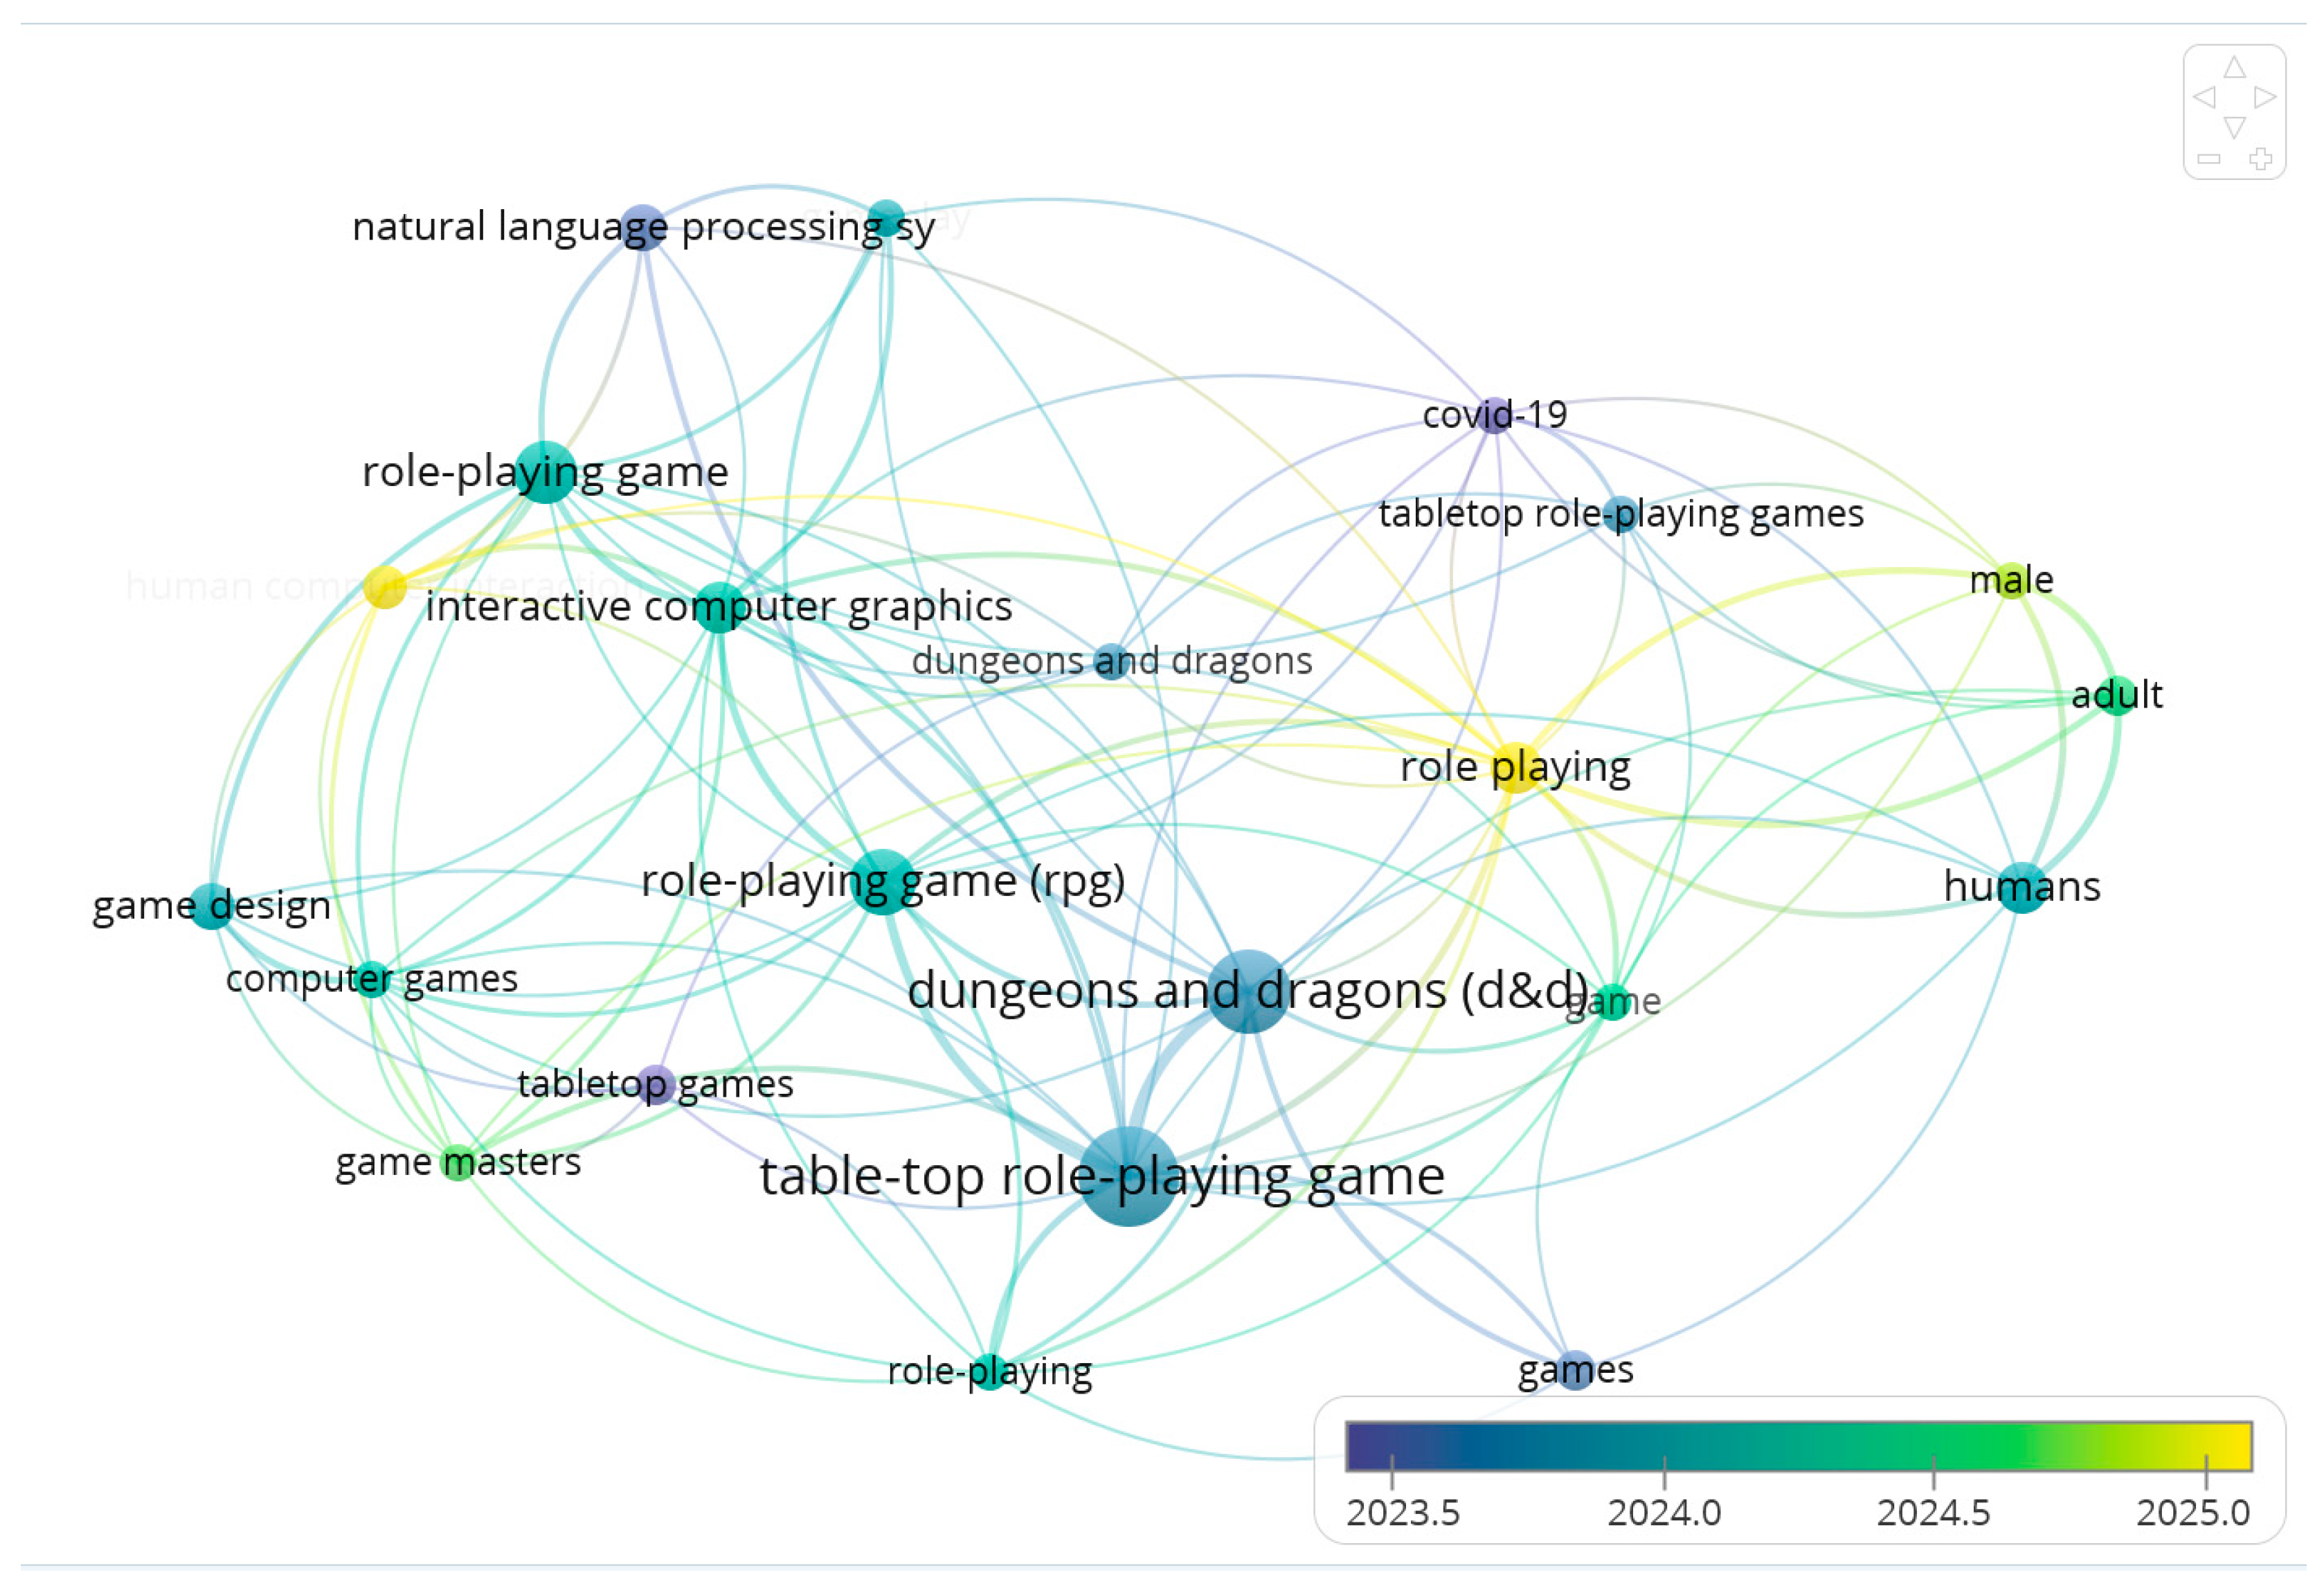
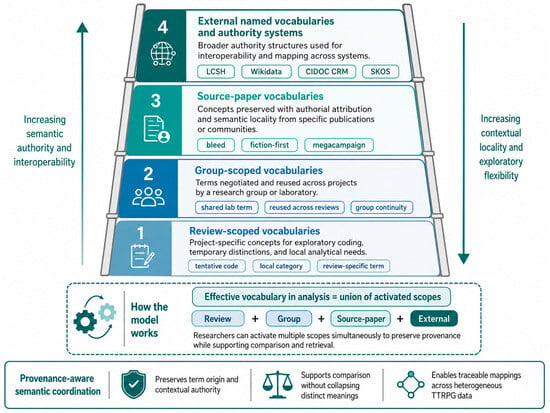
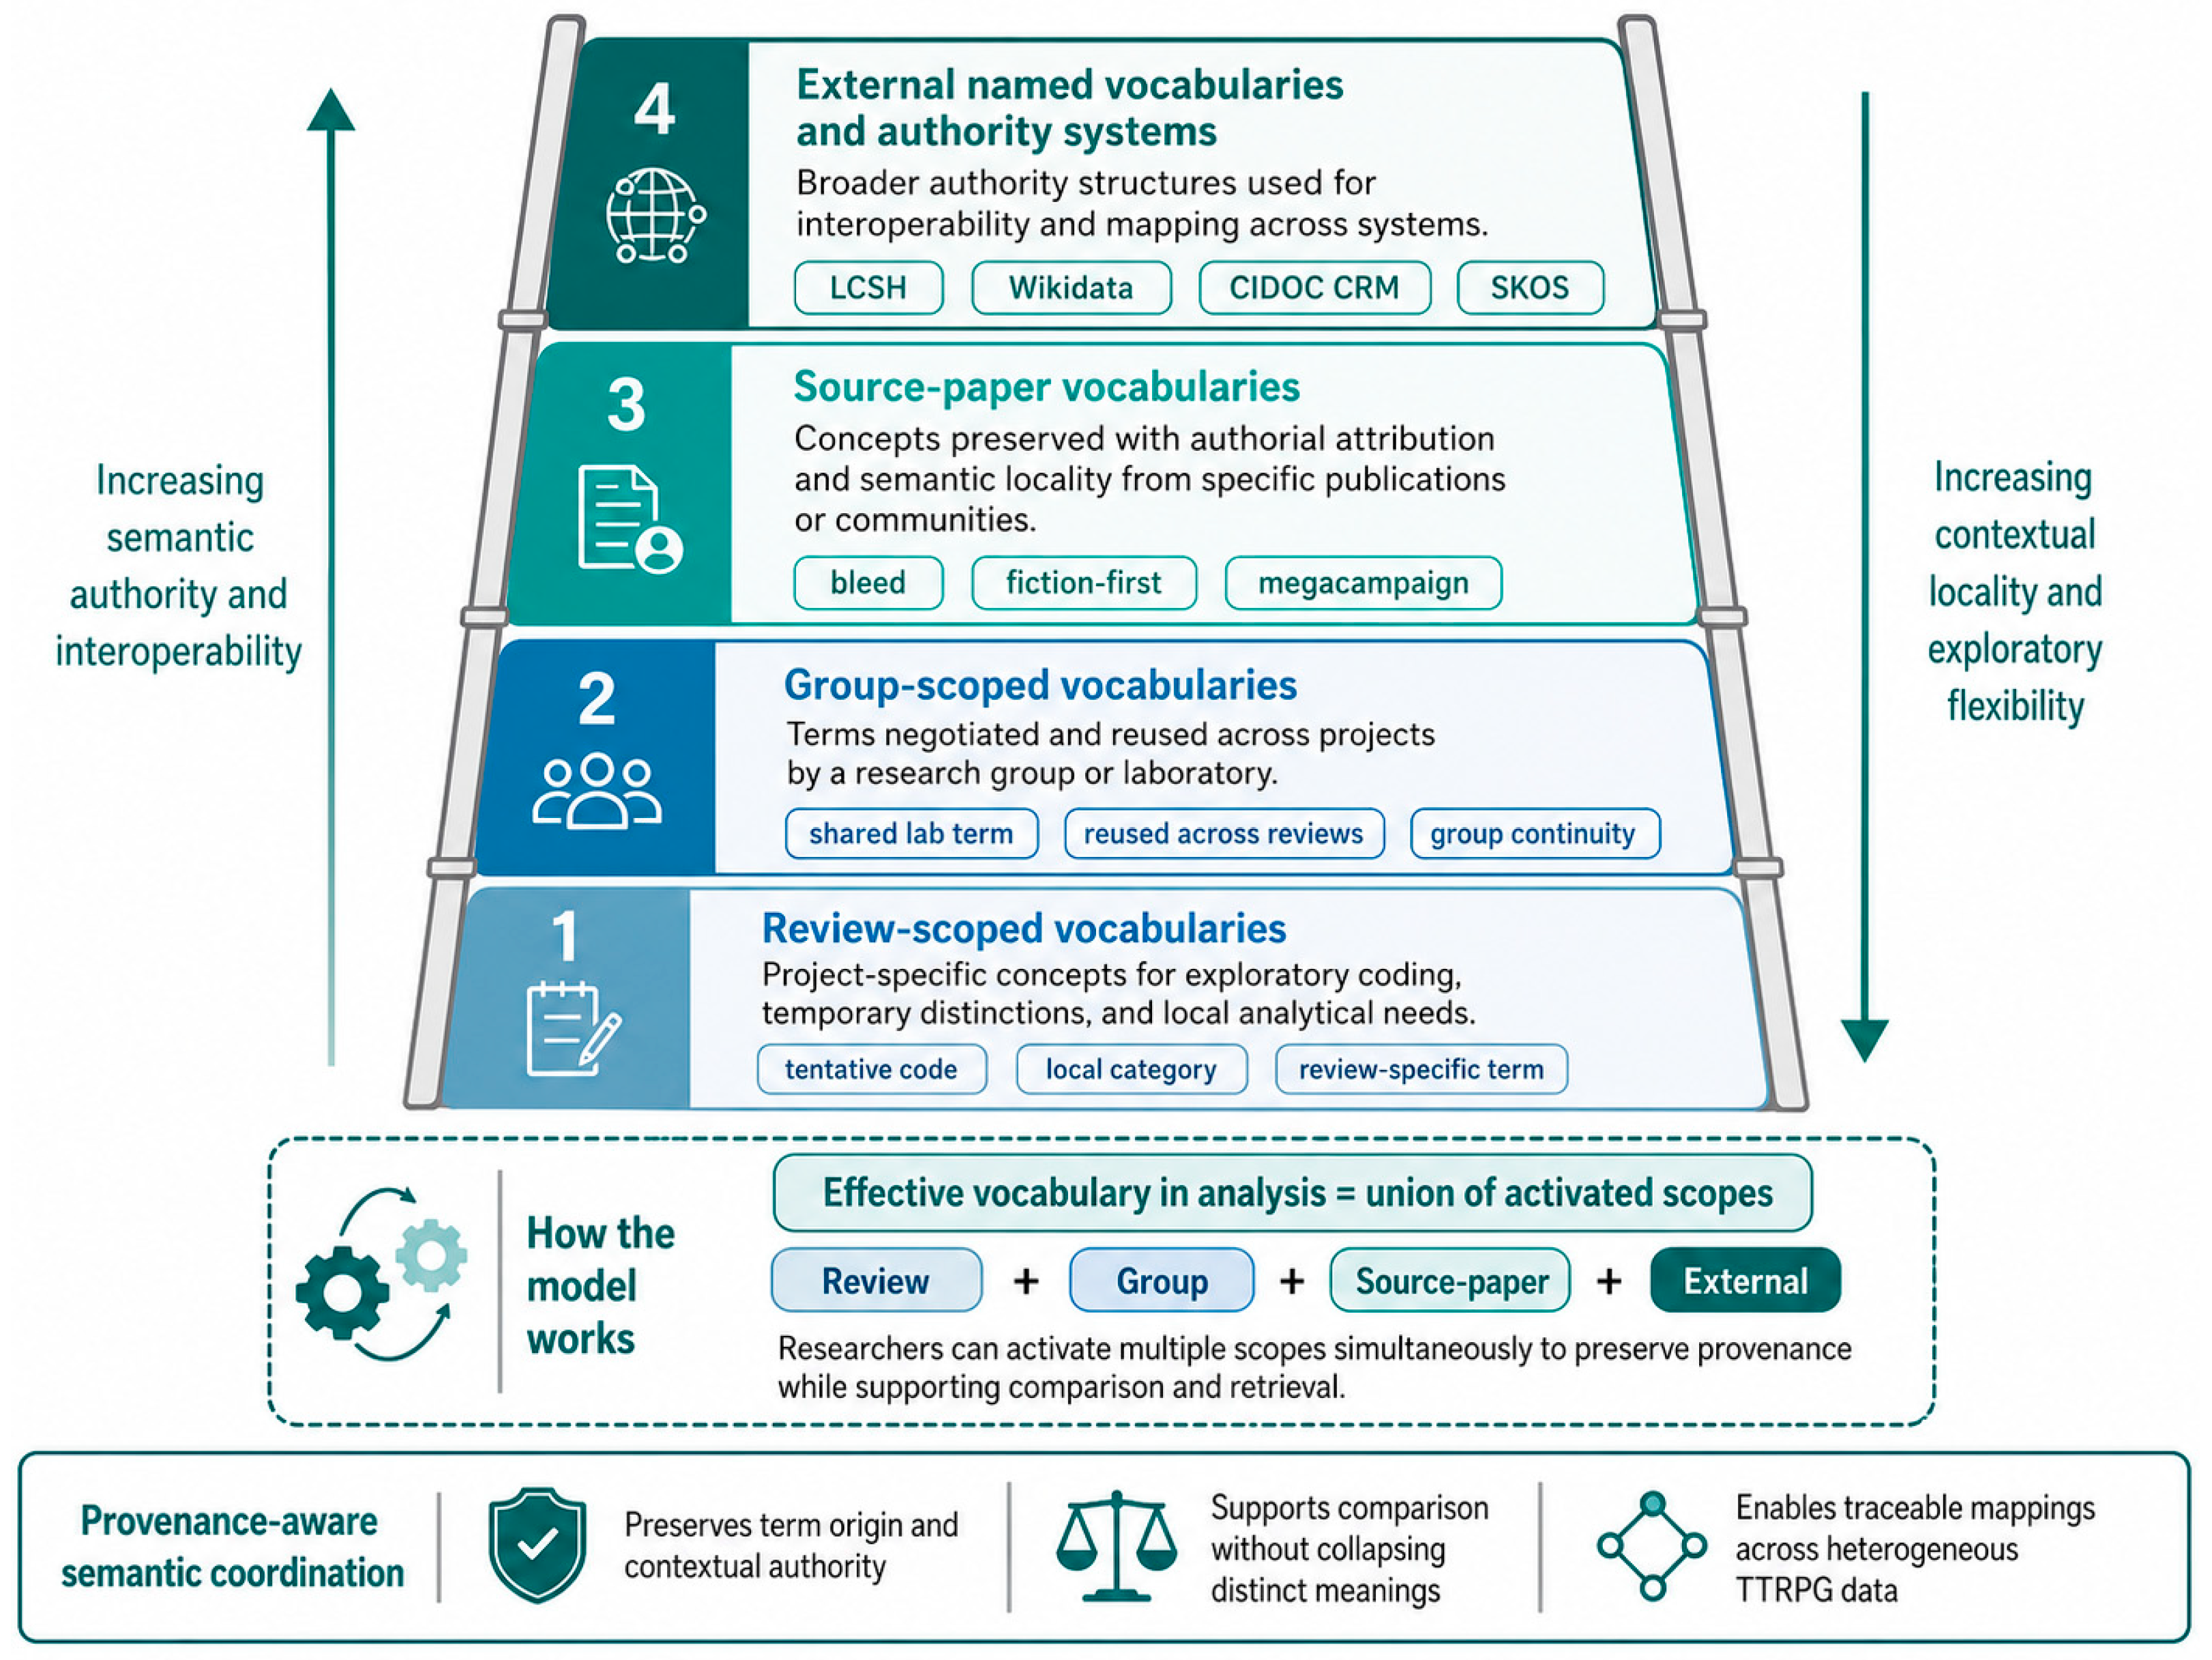
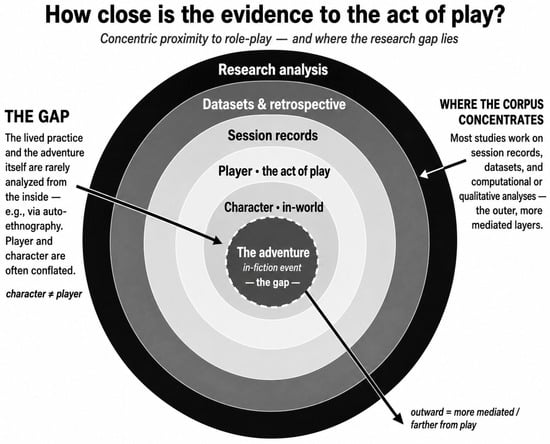
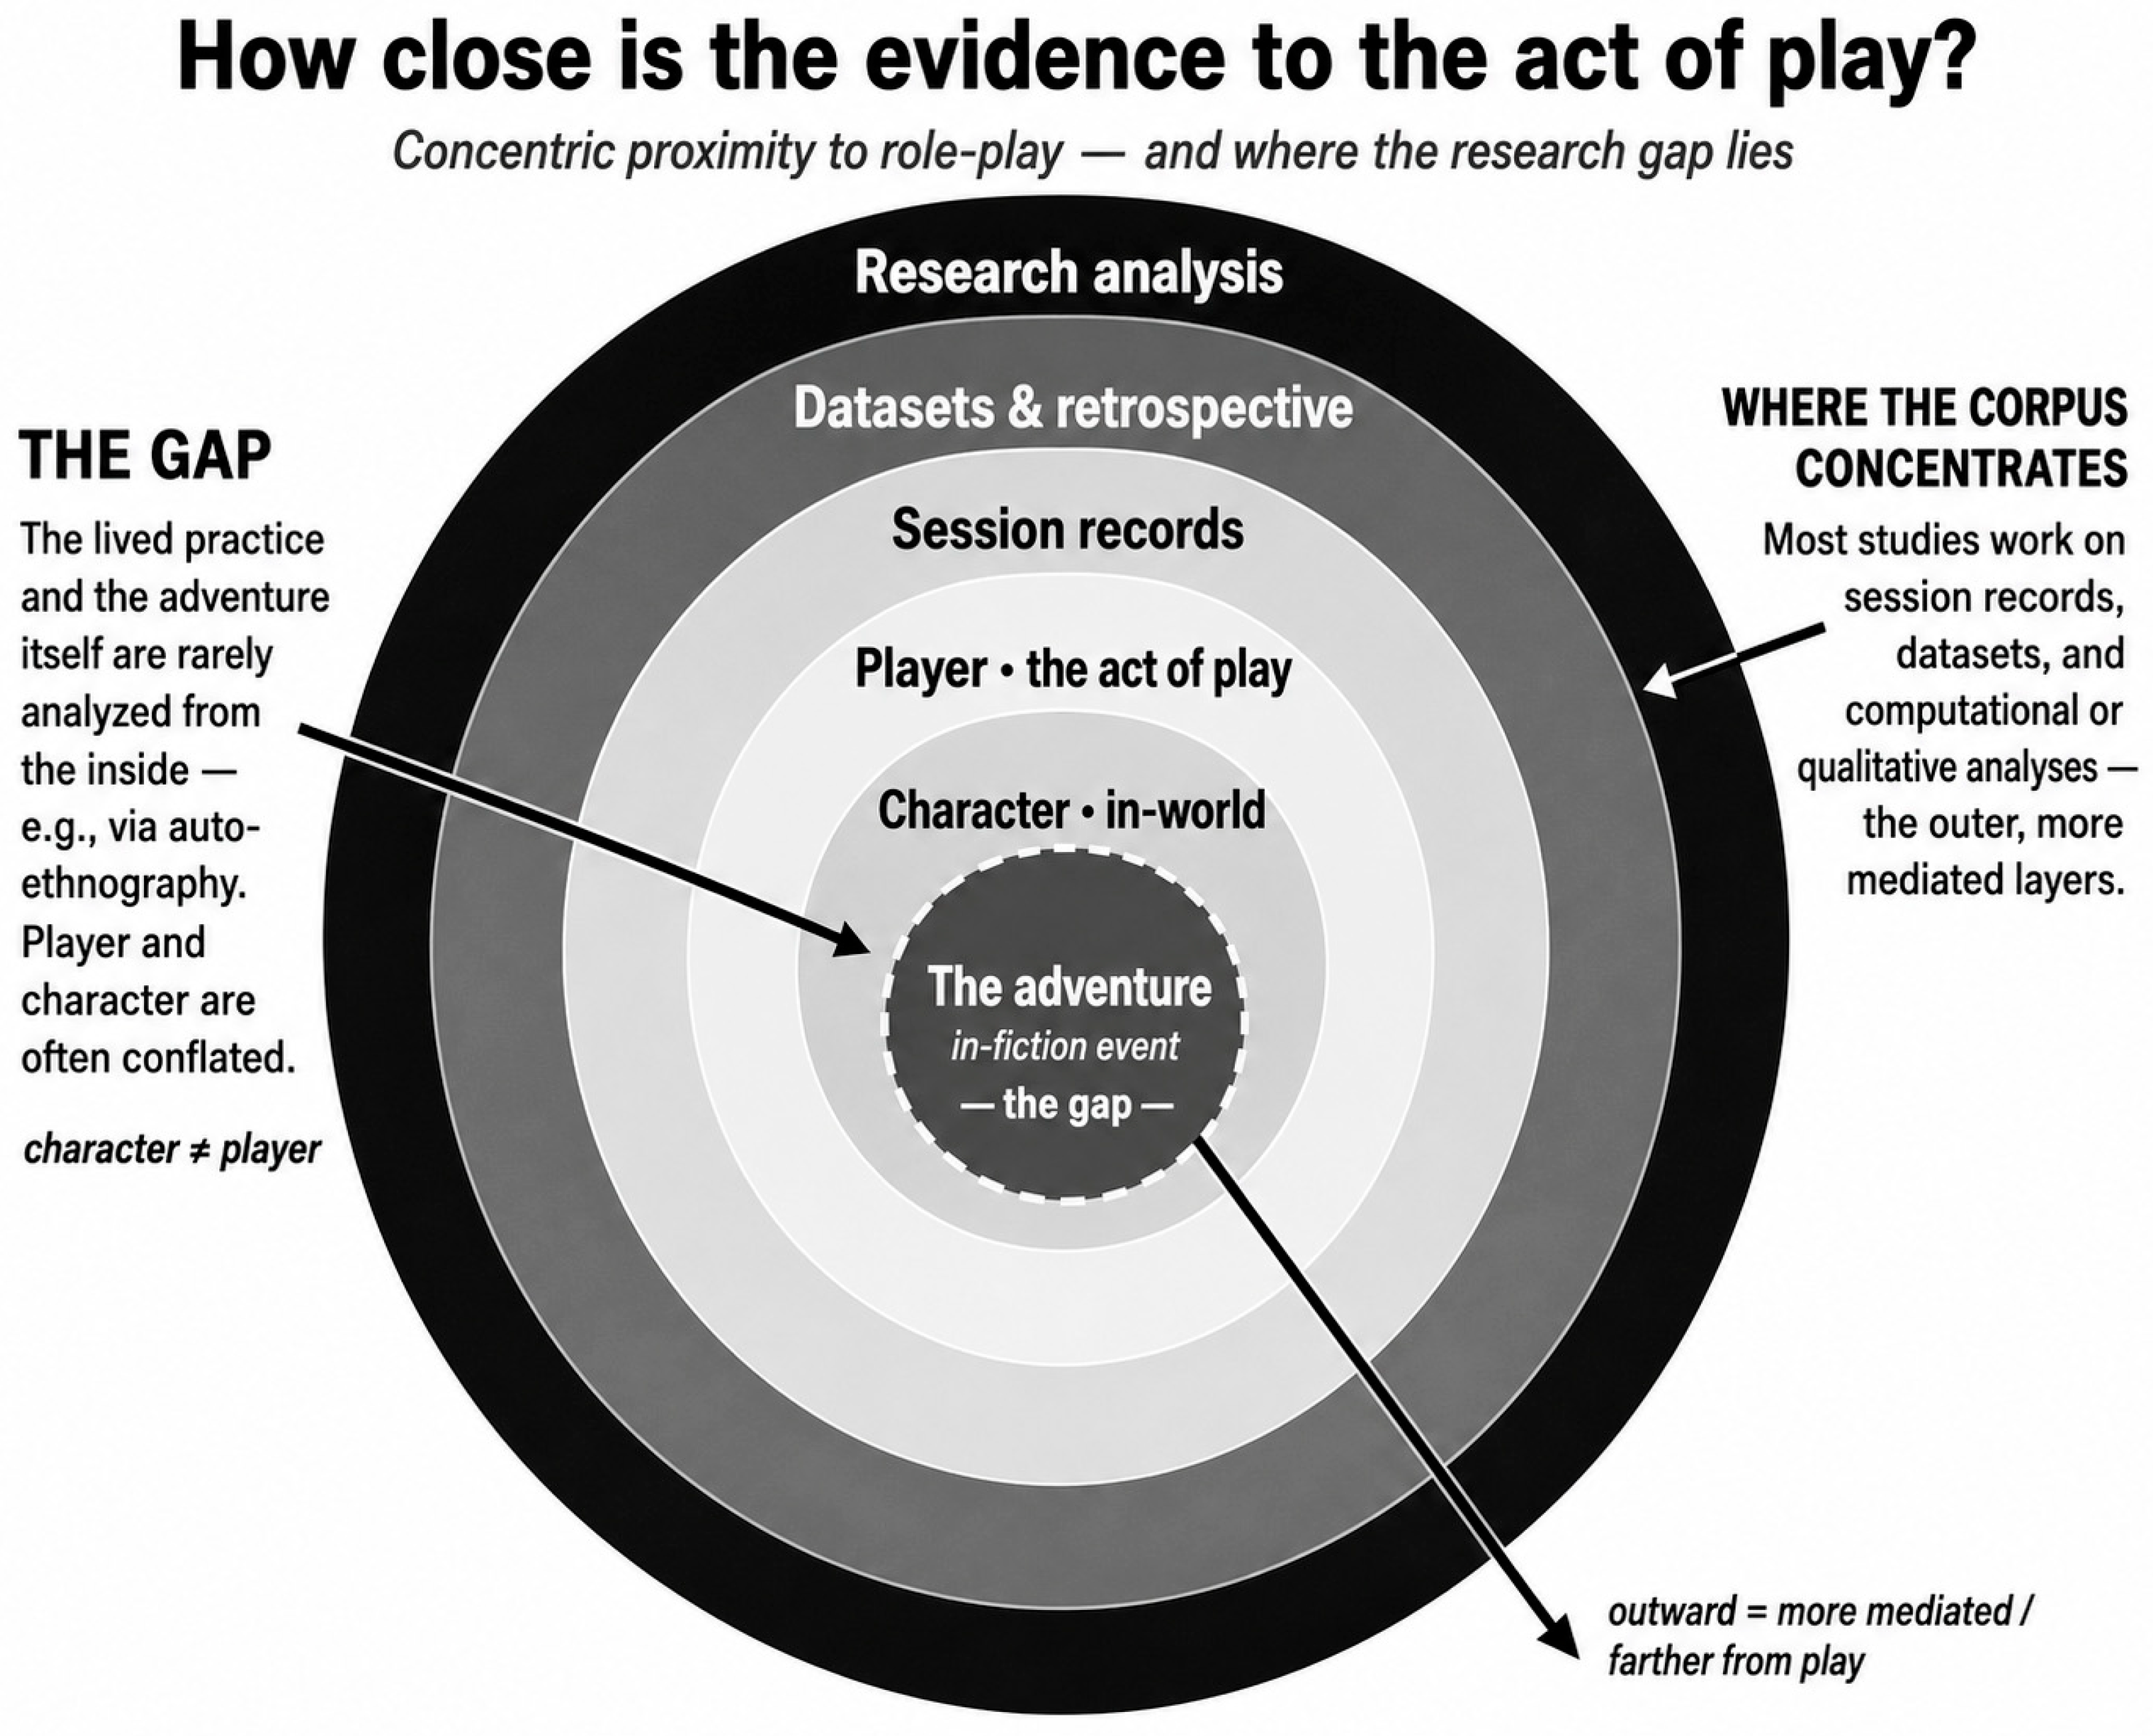

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.