


Abstract
Evidence on generative artificial intelligence adoption remains limited in Latin American engineering education, particularly for undergraduate populations in which paid employment may shape study practices. This exploratory study examined reported ChatGPT (GPT-4o model) use among students enrolled in two undergraduate engineering programs at the Instituto Tecnológico Metropolitano in Medellín, Colombia. Technology Acceptance Model and Unified Theory of Acceptance and Use of Technology research were used as background literature; their core constructs were not measured or tested. The primary 2023 analytic file contained 64 complete records, including 41 “yes” and 23 “no” responses to the direct-use item. Descriptive statistics and a prespecified binary logistic regression evaluated associations with age, gender, and employment status. Age was negatively associated with reported use (odds ratio = 0.910 per year, 95% CI: 0.834–0.993; ). No statistically significant association was detected for gender () or employment status (), and the wide confidence intervals preclude conclusions of no effect. The apparent AUC was 0.719 (95% CI: 0.589–0.849). A separate 2025 pilot (), based on an expanded questionnaire and an independent convenience sample, was analyzed descriptively and not as a replication. In that pilot, all respondents selected ChatGPT, 93.3% selected Gemini (Gemini 2.5 Flash model), and 53.3% selected Copilot (powered by OpenAI’s GPT-4o model); the most frequent activities were writing-related support (63.3%) and both idea generation and concept explanation (60.0% each). The findings provide context-specific, hypothesis-generating evidence and support larger multi-institutional studies that directly measure acceptance constructs, use intensity, verification behavior, and educational outcomes.
1. Introduction
Generative artificial intelligence (GenAI) has moved rapidly from a specialized technology to a routine academic resource. Students use conversational systems for brainstorming, explanation, summarization, writing support, and programming, while institutions continue to debate accuracy, authorship, assessment integrity, privacy, and the possibility that uncritical reliance may weaken independent reasoning [1,2,3]. This dual character makes adoption an educational question rather than a simple measure of access: the same tool may extend learning when its outputs are checked and contextualized, yet produce misinformation or superficial work when it substitutes for disciplinary judgment [4,5].
International research has linked students’ adoption of ChatGPT and related systems to perceived usefulness, ease of use, trust, prior knowledge, social influence, facilitating conditions, and demographic or contextual characteristics [6,7,8]. A large multi-institutional survey found that students commonly valued GenAI for editing, summarization, and idea generation, while also reporting concerns about trust and appropriate use [9]. Evidence is nevertheless uneven across regions and disciplines. Much of the empirical literature has been produced in Asia, Europe, the Middle East, or multinational samples, whereas context-specific evidence from Latin American engineering programs remains comparatively limited.
Colombia provides a relevant setting because participation in digital higher education occurs alongside persistent differences in connectivity, prior technological exposure, and socioeconomic conditions. These inequalities do not determine GenAI adoption, but they can affect the opportunities and support through which students develop digital practices [10]. Medellín is also a large urban education and technology center that receives students from municipalities with heterogeneous access conditions. Within the present 2023 sample, 79.7% of respondents combined employment and study, and 35.9% were born outside Medellín. These characteristics make employment status and background useful contextual descriptors, although they cannot serve as causal proxies for workload, income, or digital access.
The respondents were undergraduates enrolled in the professional Quality Engineering and Production Engineering programs at the Instituto Tecnológico Metropolitano (ITM). Both are undergraduate engineering programs offered in Medellín, and the institutional curricula emphasize quantitative analysis, production systems, quality, and professional problem solving [11,12]. Examining GenAI use in this population can therefore contribute a bounded account of adoption in an applied engineering setting rather than a general estimate for Colombian higher education.
The study addressed one research question: How were age, gender, and employment status associated with reported ChatGPT use among undergraduate engineering students in the 2023 ITM sample, and what descriptive patterns characterized their knowledge, perceived usefulness, and recommendations? The primary objective was to estimate these sample-specific associations using a parsimonious binary logistic regression. A secondary objective was to document an independent 2025 descriptive pilot that captured diversification beyond ChatGPT, academic uses, and verification practices. The 2025 data were retained because they provide a timely institutional snapshot, but they were not used to infer change over time or to validate the 2023 model.
The contribution is deliberately exploratory and hypothesis-generating. It does not test or validate the Technology Acceptance Model (TAM) or the Unified Theory of Acceptance and Use of Technology (UTAUT), does not estimate causal effects, and does not support population-level claims. Instead, it clarifies what can be learned from a small, single-institution survey, reports discrimination and threshold-dependent classification performance as distinct quantities and positions the 2025 pilot as a separate descriptive component.
2. Background and Contextual Rationale
Research on GenAI adoption in higher education brings together technology-acceptance perspectives, evidence on educational opportunities and risks, and the institutional conditions that shape students’ use of these tools. The following background distinguishes established acceptance constructs from the variables available in the present survey, then situates ChatGPT within broader discussions of responsible educational use and AI-supported learning [13,14].
2.1. Technology-Acceptance Literature and the Measured Variables
TAM identifies perceived usefulness and perceived ease of use as central determinants of technology acceptance [15]. UTAUT broadens this account through performance expectancy, effort expectancy, social influence, and facilitating conditions, with demographic and contextual moderators [16]. Recent higher-education studies have applied these models to GenAI by directly measuring multi-item constructs such as usefulness, ease of use, trust, satisfaction, social influence, and behavioral intention [7,8,17].
The questionnaire captured selected adoption-related variables and provides a basis for prospectively testing a more complete acceptance model. It included a single item on perceived usefulness but did not operationalize perceived ease of use, performance expectancy, effort expectancy, social influence, facilitating conditions, trust, or behavioral intention through validated multi-item scales. Accordingly, TAM and UTAUT provide a conceptual frame for interpreting the study, while age, gender, and employment status are treated as contextual covariates rather than proxies for the models’ latent constructs. This distinction preserves alignment between the theoretical concepts discussed and the variables actually measured [18].
To maintain a parsimonious and prospectively defined model, the regression included age, gender, and employment status. Perceived usefulness and self-reported AI knowledge were retained for descriptive analysis because they were measured concurrently with use through single items, leaving their temporal relationship with adoption unresolved. Limiting post hoc model expansion was also appropriate for the available sample and number of outcome events, as unnecessary predictor selection in small datasets can produce unstable coefficients and overly optimistic estimates [19,20].
2.2. Benefits, Risks, and Responsible Educational Use
GenAI can support explanation, formative feedback, coding, translation, idea development, and access to examples, particularly when students retain responsibility for checking outputs and integrating them with disciplinary knowledge [1,9,21]. At the same time, model outputs can be inaccurate, biased, or fabricated, and may conceal the source or reasoning process on which an answer depends [22,23]. In this article, the term “black box” refers to a system whose internal transformations are not directly inspectable by the typical end user, even though the user can observe the prompt and generated output.
Educational responses consequently need to combine access with explicit expectations for verification, attribution, privacy, and academic integrity. UNESCO recommends a human-centered approach that protects agency, inclusion, and data rights, while institutional frameworks emphasize assessment design and AI literacy rather than reliance on prohibition alone [2,4,5]. These principles inform the interpretation of the 2025 verification items, but the policy recommendations in this article are grounded primarily in the broader literature rather than attributed solely to the small samples.
2.3. Supplementary Keyword Map and Technical Overview
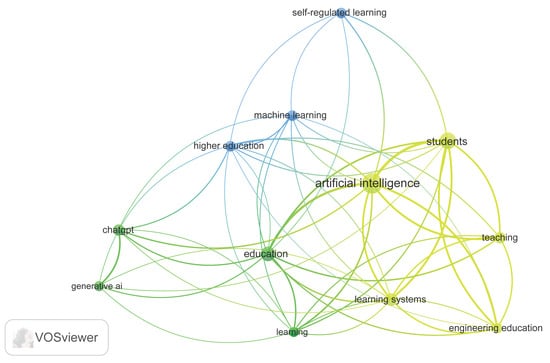
To complement the narrative review, a limited keyword co-occurrence scan was prepared from a Scopus search conducted on 19 December 2024. The search retrieved 96 records; 31 were retained for contextual screening, and 13 were available in full text. Author keywords were visualized in VOSviewer 1.6.18 using association-strength normalization. The map was used only to situate the study thematically; it did not assess study quality, estimate educational effects, or determine the regression variables [24,25]. The resulting thematic relationships are presented in Figure 1.
Figure 1.
Supplementary VOSviewer co-occurrence map of keywords related to artificial intelligence, pedagogy, and higher education. Note. The map provides thematic context and is not presented as a systematic bibliometric analysis.
In Figure 1, larger nodes indicate more frequently occurring keywords and shorter distances indicate stronger co-occurrence; ChatGPT appears near higher education, engineering education, learning, and self-regulated learning.
Beyond this thematic context, understanding the basic operation of large language models helps clarify the user-facing interaction represented in the study. Large language models generate text by estimating context-dependent token sequences from patterns learned during training. Transformer architectures allow models to relate information across a prompt and produce contextually responsive outputs [26].
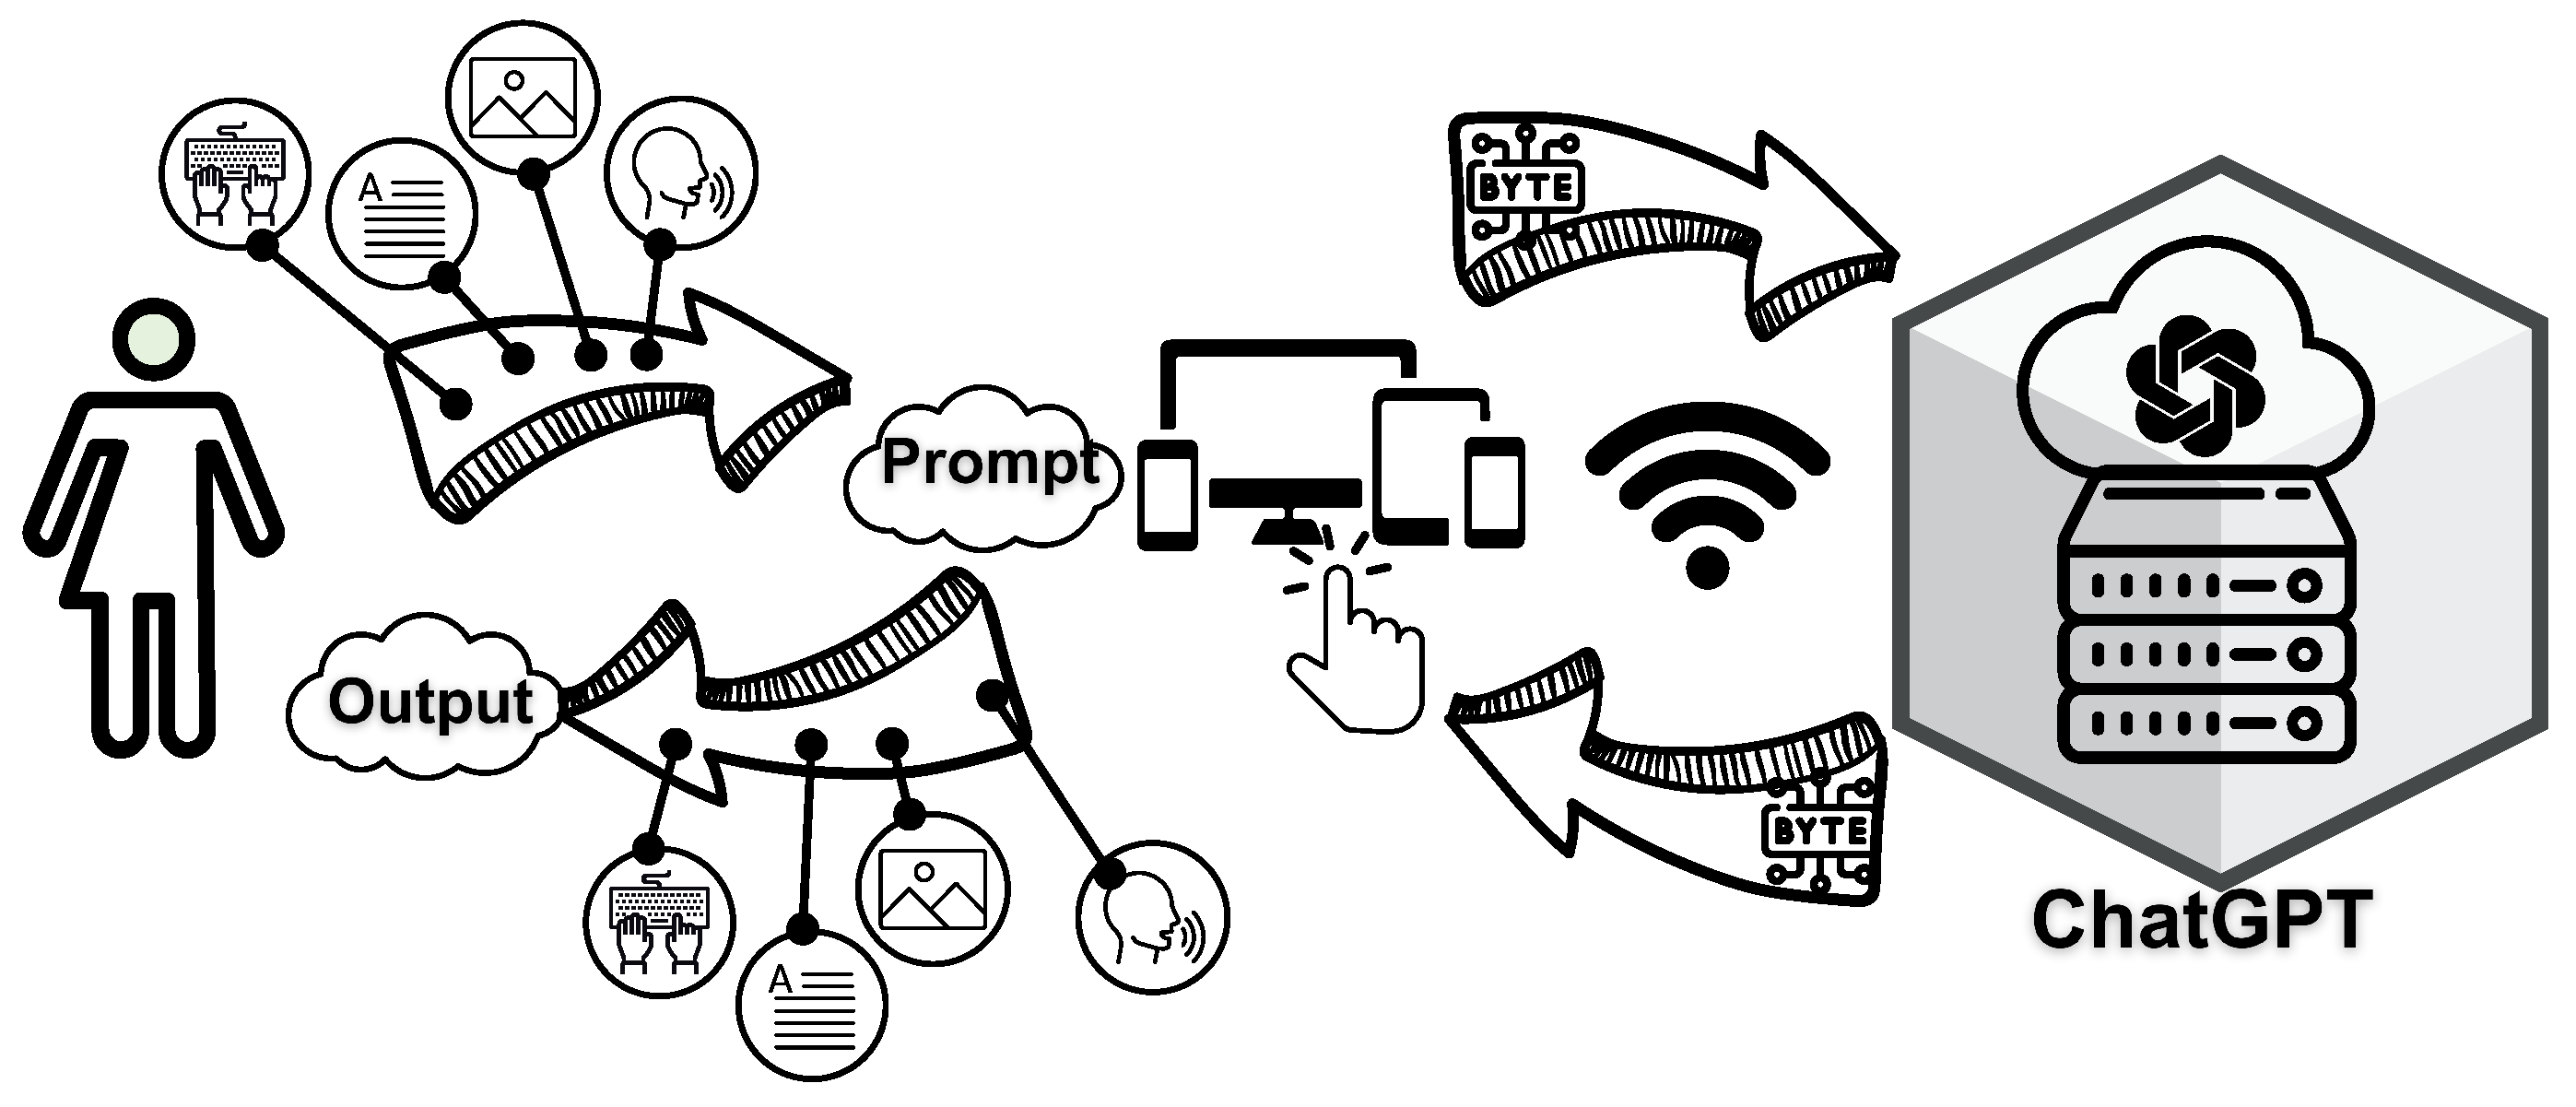
Figure 2 represents the user-facing workflow rather than the model’s complete internal architecture. Its educational relevance lies in the final evaluation stage: although users can observe the prompt and generated response, the evidentiary basis of an output may remain unclear. Students and instructors must therefore examine factual accuracy, source provenance, disciplinary relevance, and possible bias before incorporating generated content into academic work [27,28].
Figure 2.
Simplified user-facing interaction with ChatGPT: a multimodal or textual prompt is transmitted to the model and returned as an output that requires human evaluation.
3. Methodology
This section describes the methodological structure of the study and the boundaries adopted for analysis. It explains the distinction between the 2023 primary survey and the independent 2025 descriptive pilot, details the study setting and participant recruitment, defines the questionnaires and variables, and outlines the statistical procedures. Ethics approval, consent, and data protection are described in the statements following the Conclusions.
3.1. Study Design and Analytic Boundaries
The study comprised two analytically separate components. The primary component was an exploratory cross-sectional survey administered during the second semester of 2023. It supported descriptive analysis and a prespecified binary logistic regression of direct self-reported ChatGPT use. The secondary component was an independent descriptive pilot administered in 2025 with an expanded questionnaire. Because the samples, instruments, response scales, and semesters differed, no participant-level linkage, formal replication, longitudinal estimate, or inferential comparison between years was attempted. Table 1 summarizes these boundaries.
Table 1.
Design and measurement boundaries of the 2023 primary survey and the separate 2025 descriptive pilot.
3.2. Setting, Participants, and Recruitment
The institutional enrollment frame comprised 953 students in the Quality Engineering and Production Engineering programs at ITM during the second semester of 2023. Recruitment information was distributed through the academic channels available to the two programs, and participation was voluntary. Quotas were used pragmatically to seek heterogeneity by program and gender, not to produce probability-weighted population estimates. The archived anonymized workbook does not retain an academic-program variable, so program-specific response counts cannot be reconstructed or imputed. Consequently, neither the adequacy of program-level representation nor program-specific adoption patterns can be evaluated.
A record-level audit of the deposited 2023 workbook confirmed 64 analyzable records. No record was excluded for missing age, gender, employment status, or direct ChatGPT-use response, and no imputation was performed. All descriptive summaries, tables, figures, and inferential results for the 2023 component were generated from this audited 64-record file. The 2025 workbook contained 30 records. Because program affiliation was not retained for that sample, the pilot is reported only at the institutional engineering level and is not attributed to either specific program.
Among the 64 respondents, 41 answered “yes” and 23 answered “no” to the direct-use item P5. The logistic-regression model estimated three predictor coefficients—age, gender, and employment status—in addition to the intercept. The smaller outcome category therefore provided approximately 7.7 observations per predictor coefficient. This ratio is reported as a transparent indicator of data sparsity rather than as evidence that the model was adequately powered, because model stability also depends on total sample size, outcome prevalence, effect sizes, separation, and model complexity [29,30]. Although the model converged, the size of the non-user category and the wide confidence intervals indicate limited precision. The analysis is therefore interpreted as exploratory and hypothesis-generating.
3.3. Questionnaires and Variable Definitions
The 2023 questionnaire was custom designed for concise online administration through Google Forms. Three independent researchers reviewed the wording for relevance, clarity, face validity, and contextual fit. The archival materials do not contain individual reviewer profiles, item-level ratings, or a content-validity index; accordingly, no psychometric validation claim is made. Appendix A reproduces the item wording and response categories available in the study records.
The binary outcome was the direct response to P5, Have you used ChatGPT in your professional training? (yes = 1; no = 0). P6 separately asked how often ChatGPT was used and was answered by every respondent rather than being governed by skip logic. Cross-tabulation showed 29 yes/frequently, 12 yes/rarely, 22 no/rarely, and one no/frequently response. Because P5 directly operationalized adoption and P6 contained one internally discordant record, P6 was retained only for descriptive reporting and was not used to recode the outcome. This distinction also explains why a respondent could have a frequency response despite answering “no” to P5.
Age was entered as a continuous variable. Gender used female as the reference category, and employment status used full-time student as the reference category. Place of birth, AI knowledge, awareness, frequency, usefulness, and recommendation were treated as descriptive variables. The binary P5 item captured reported ChatGPT use but did not distinguish its frequency, intensity, or context.
The 2025 instrument expanded the technology list, changed the frequency scale from two to four categories, and added subscription, academic-activity, verification, perceived-impact, and conditional-recommendation items. The usefulness item retained a five-point anchored structure but the exported workbook stored verbal category labels. Appendix B reports both the response anchors and the labels used in analysis. These changes were made to capture a more diversified GenAI environment; they also prevent direct scale-level comparisons with 2023.
3.4. Statistical Analysis
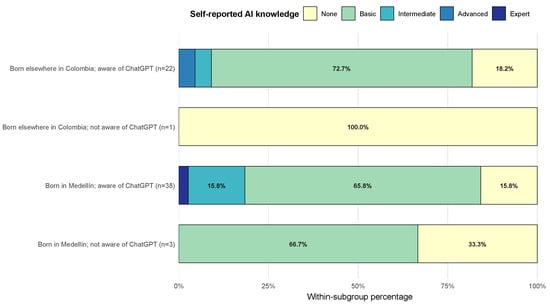
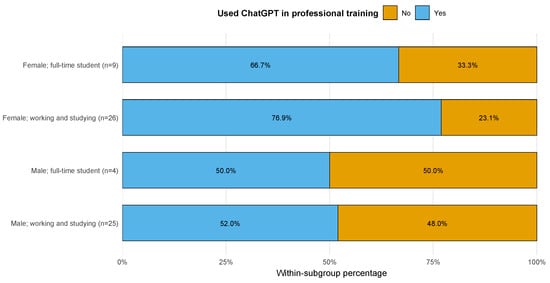
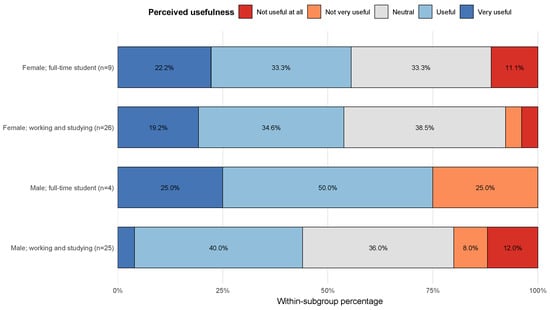
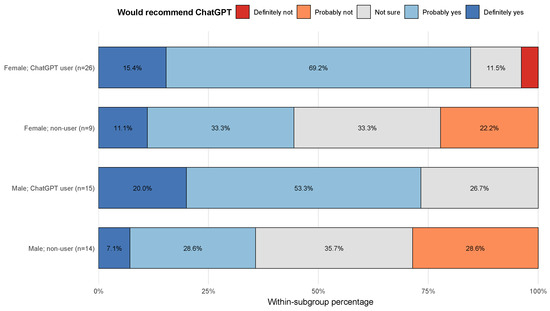
Descriptive statistics included frequencies, percentages, means, standard deviations, medians, interquartile ranges, and ranges, as appropriate to the variable type. Figure 3, Figure 4, Figure 5 and Figure 6 present 100% stacked bars, with percentages calculated within each subgroup and subgroup sample sizes reported in the labels. For the 2025 multiple-response items, each option was summarized as the percentage of the 30 respondents who selected it; consequently, percentages across options may sum to more than 100%.
Figure 3.
Self-reported AI knowledge within birthplace-by-awareness subgroups in the 2023 sample. Note. Percentages are calculated within each subgroup; subgroup sizes are shown in the labels.
Figure 4.
Direct self-reported ChatGPT use within gender-by-employment subgroups in the 2023 sample. Note. Percentages are calculated within each subgroup; subgroup sizes are shown in the labels.
Figure 5.
Perceived usefulness of ChatGPT within gender-by-employment subgroups in the 2023 sample. Note. Percentages are calculated within each subgroup; subgroup sizes are shown in the labels.
Figure 6.
Willingness to recommend ChatGPT within gender-by-direct-use subgroups in the 2023 sample. Note. Percentages are calculated within each subgroup; subgroup sizes are shown in the labels.
Direct self-reported ChatGPT use in the 2023 survey (P5: yes/no) was analyzed using a binary logistic regression model specified as
where denotes a yes response to P5; identifies male respondents, with female as the reference category; and working and studyingi = 1 identifies respondents who combined employment and study, with full-time students as the reference category. Age was entered as a continuous predictor. The three-predictor specification was retained to limit model complexity given the available sample and the smaller outcome category of 23 non-users. Accordingly, the regression was treated as exploratory and hypothesis-generating rather than as a predictive model intended for population-level inference [19,20].
Regression results were summarized using coefficients, standard errors, two-sided Wald p values, odds ratios (ORs), and 95% confidence intervals. Overall model improvement relative to the intercept-only model was evaluated with the likelihood-ratio test, while McFadden and Nagelkerke pseudo- values were used as descriptive measures of model fit. Variance inflation factors were examined for problematic collinearity, and the Hosmer–Lemeshow test was used as a goodness-of-fit diagnostic. Apparent discrimination was summarized by the area under the receiver-operating-characteristic curve (AUC) with its 95% confidence interval, while classification accuracy was calculated at a probability threshold of 0.50. Both measures were obtained from the model-development sample. No internal resampling validation or external validation was performed [31,32,33].
Three supplementary Pearson chi-square tests with Yates’ continuity correction examined unadjusted associations between gender and (i) direct ChatGPT use, (ii) perceived usefulness, and (iii) recommendation. For these analyses, usefulness was collapsed into positive (Useful or Very useful) versus non-positive (Neutral, Not very useful, or Nothing useful) responses, while recommendation was collapsed into positive (Probably yes or Definitely yes) versus non-positive (Not sure, Probably not, or Definitely not) responses. These tests were used to complement the descriptive subgroup figures and were not treated as independent confirmatory analyses. All analyses were conducted in R [34].
4. Results
This section presents the findings in a sequential manner, beginning with the characteristics of the participants and continuing with the descriptive results from the 2023 primary survey. It then reports the exploratory logistic-regression model and concludes with the descriptive findings from the independent 2025 pilot.
4.1. Participant Characteristics
Table 2 summarizes the participant characteristics for the 2023 primary survey and the independent 2025 pilot. All participants were undergraduate engineering students. In 2023, the mean age was 29.1 years (SD 7.6), 54.7% identified as female, and 79.7% reported working while studying. In the 2025 pilot, the mean age was 29.0 years (SD 5.0), 53.3% identified as male, and 90.0% worked while studying. Similar age means do not establish sample equivalence because recruitment and instrumentation differed.
Table 2.
Characteristics of the 2023 primary survey and the independent 2025 descriptive pilot.
4.2. Descriptive Findings from the 2023 Primary Survey
Variable codes and response categories reported in this subsection follow the 2023 questionnaire reproduced in Appendix A. The findings are organized around ChatGPT awareness and self-reported AI knowledge, direct use, perceived usefulness, and willingness to recommend the tool. Descriptive subgroup patterns are reported separately from the supplementary statistical comparisons presented at the end of the subsection.
Awareness of ChatGPT was reported by 60 of 64 respondents (93.8%), while 41 (64.1%) reported direct use in their professional training. Self-reported AI knowledge was predominantly basic (43, 67.2%); 12 respondents (18.8%) reported no AI knowledge, seven (10.9%) selected the intermediate level, and one respondent each selected advanced and expert. The distribution of AI-knowledge levels according to birthplace and ChatGPT awareness is presented in Figure 3.
Among respondents who were aware of ChatGPT, basic AI knowledge predominated in both birthplace groups, while intermediate or higher self-ratings were uncommon. The very small unaware subgroups are included to describe the sample and do not support meaningful comparisons.
Direct ChatGPT use also differed descriptively across gender and employment categories. Overall, 26 of 35 women (74.3%) and 15 of 29 men (51.7%) reported using ChatGPT. To examine how these responses were distributed when gender and employment status were considered jointly, Figure 4 presents direct use within the four gender-by-employment subgroups.
Reported ChatGPT use was higher among women in both employment strata, although the male full-time subgroup contained only four respondents. These patterns are descriptive; the adjusted associations of age, gender, and employment status are reported in the following logistic-regression subsection.
Perceived usefulness showed a mixed distribution across the 2023 sample. Twenty-four respondents (37.5%) rated ChatGPT as useful and nine (14.1%) as very useful, whereas 22 (34.4%) selected the neutral category and nine (14.1%) selected either not very useful or not useful at all. The distribution of these responses across gender-by-employment subgroups is presented in Figure 5.
Positive usefulness ratings appeared in every subgroup, but neutral responses remained common and no consistent employment-related pattern was evident. The 75.0% estimate among male full-time students corresponds to only three respondents and is therefore imprecise.
Recommendation responses were generally favorable, although almost one quarter of the sample remained uncertain. Thirty-three respondents (51.6%) selected probably yes and nine (14.1%) selected definitely yes, whereas 15 (23.4%) were unsure, six (9.4%) selected probably not, and one (1.6%) selected definitely not. To examine whether the distribution of these responses differed according to reported use status and gender, the corresponding subgroup percentages are shown in Figure 6.
Positive recommendations were more frequent among users than among non-users in both gender groups. Because use and recommendation were measured concurrently, this pattern is descriptive and does not establish temporal or causal direction.
The supplementary gender comparisons were not statistically significant for direct ChatGPT use (, ), collapsed perceived usefulness (, ), or collapsed recommendation (, ). These unadjusted analyses provide insufficient evidence of gender-associated differences in the available sample and should not be interpreted as demonstrating equivalence between groups.
4.3. Exploratory Logistic Regression
Table 3 presents the estimates from the exploratory binary logistic regression used to examine the association of age, gender, and employment status with direct self-reported ChatGPT use in the 2023 sample. The table reports the regression coefficients, standard errors, Wald statistics, p values, odds ratios (ORs), and their 95% confidence intervals, allowing both the direction and uncertainty of each association to be evaluated.
Table 3.
Exploratory binary logistic regression of direct ChatGPT use in the 2023 sample ().
After adjustment for gender and employment status, each one-year difference in age was associated with an estimated 9.0% lower odds of reporting ChatGPT use (OR = 0.910, 95% CI: 0.834–0.993; ). This estimate describes an exploratory association between respondents and does not establish a causal effect or within-person change over time. No statistically significant association was detected for gender or employment status. Their wide confidence intervals, particularly for employment status, leave the direction and magnitude of these associations uncertain.
The likelihood-ratio comparison with the intercept-only model yielded , . McFadden and Nagelkerke pseudo- values were 0.105 and 0.176, respectively. Variance inflation factors ranged from 1.14 to 1.34, and the Hosmer–Lemeshow test yielded . The apparent AUC was 0.719 (95% CI: 0.589–0.849). At a probability threshold of 0.50, the model correctly classified 42 of 64 observations, corresponding to an apparent accuracy of 65.6%. These statistics summarize performance in the model-development sample. Without internal or external validation, they do not establish predictive performance in other students or institutions.
4.4. Independent 2025 Descriptive Pilot
The descriptive categories reported in this subsection follow the expanded pilot instrument reproduced in Appendix B. The 2025 pilot is an independent descriptive snapshot of GenAI tool selection, academic uses, access conditions, and verification practices in the institutional engineering setting. Because program affiliation was unavailable, the findings are not attributed to Quality Engineering or Production Engineering separately.
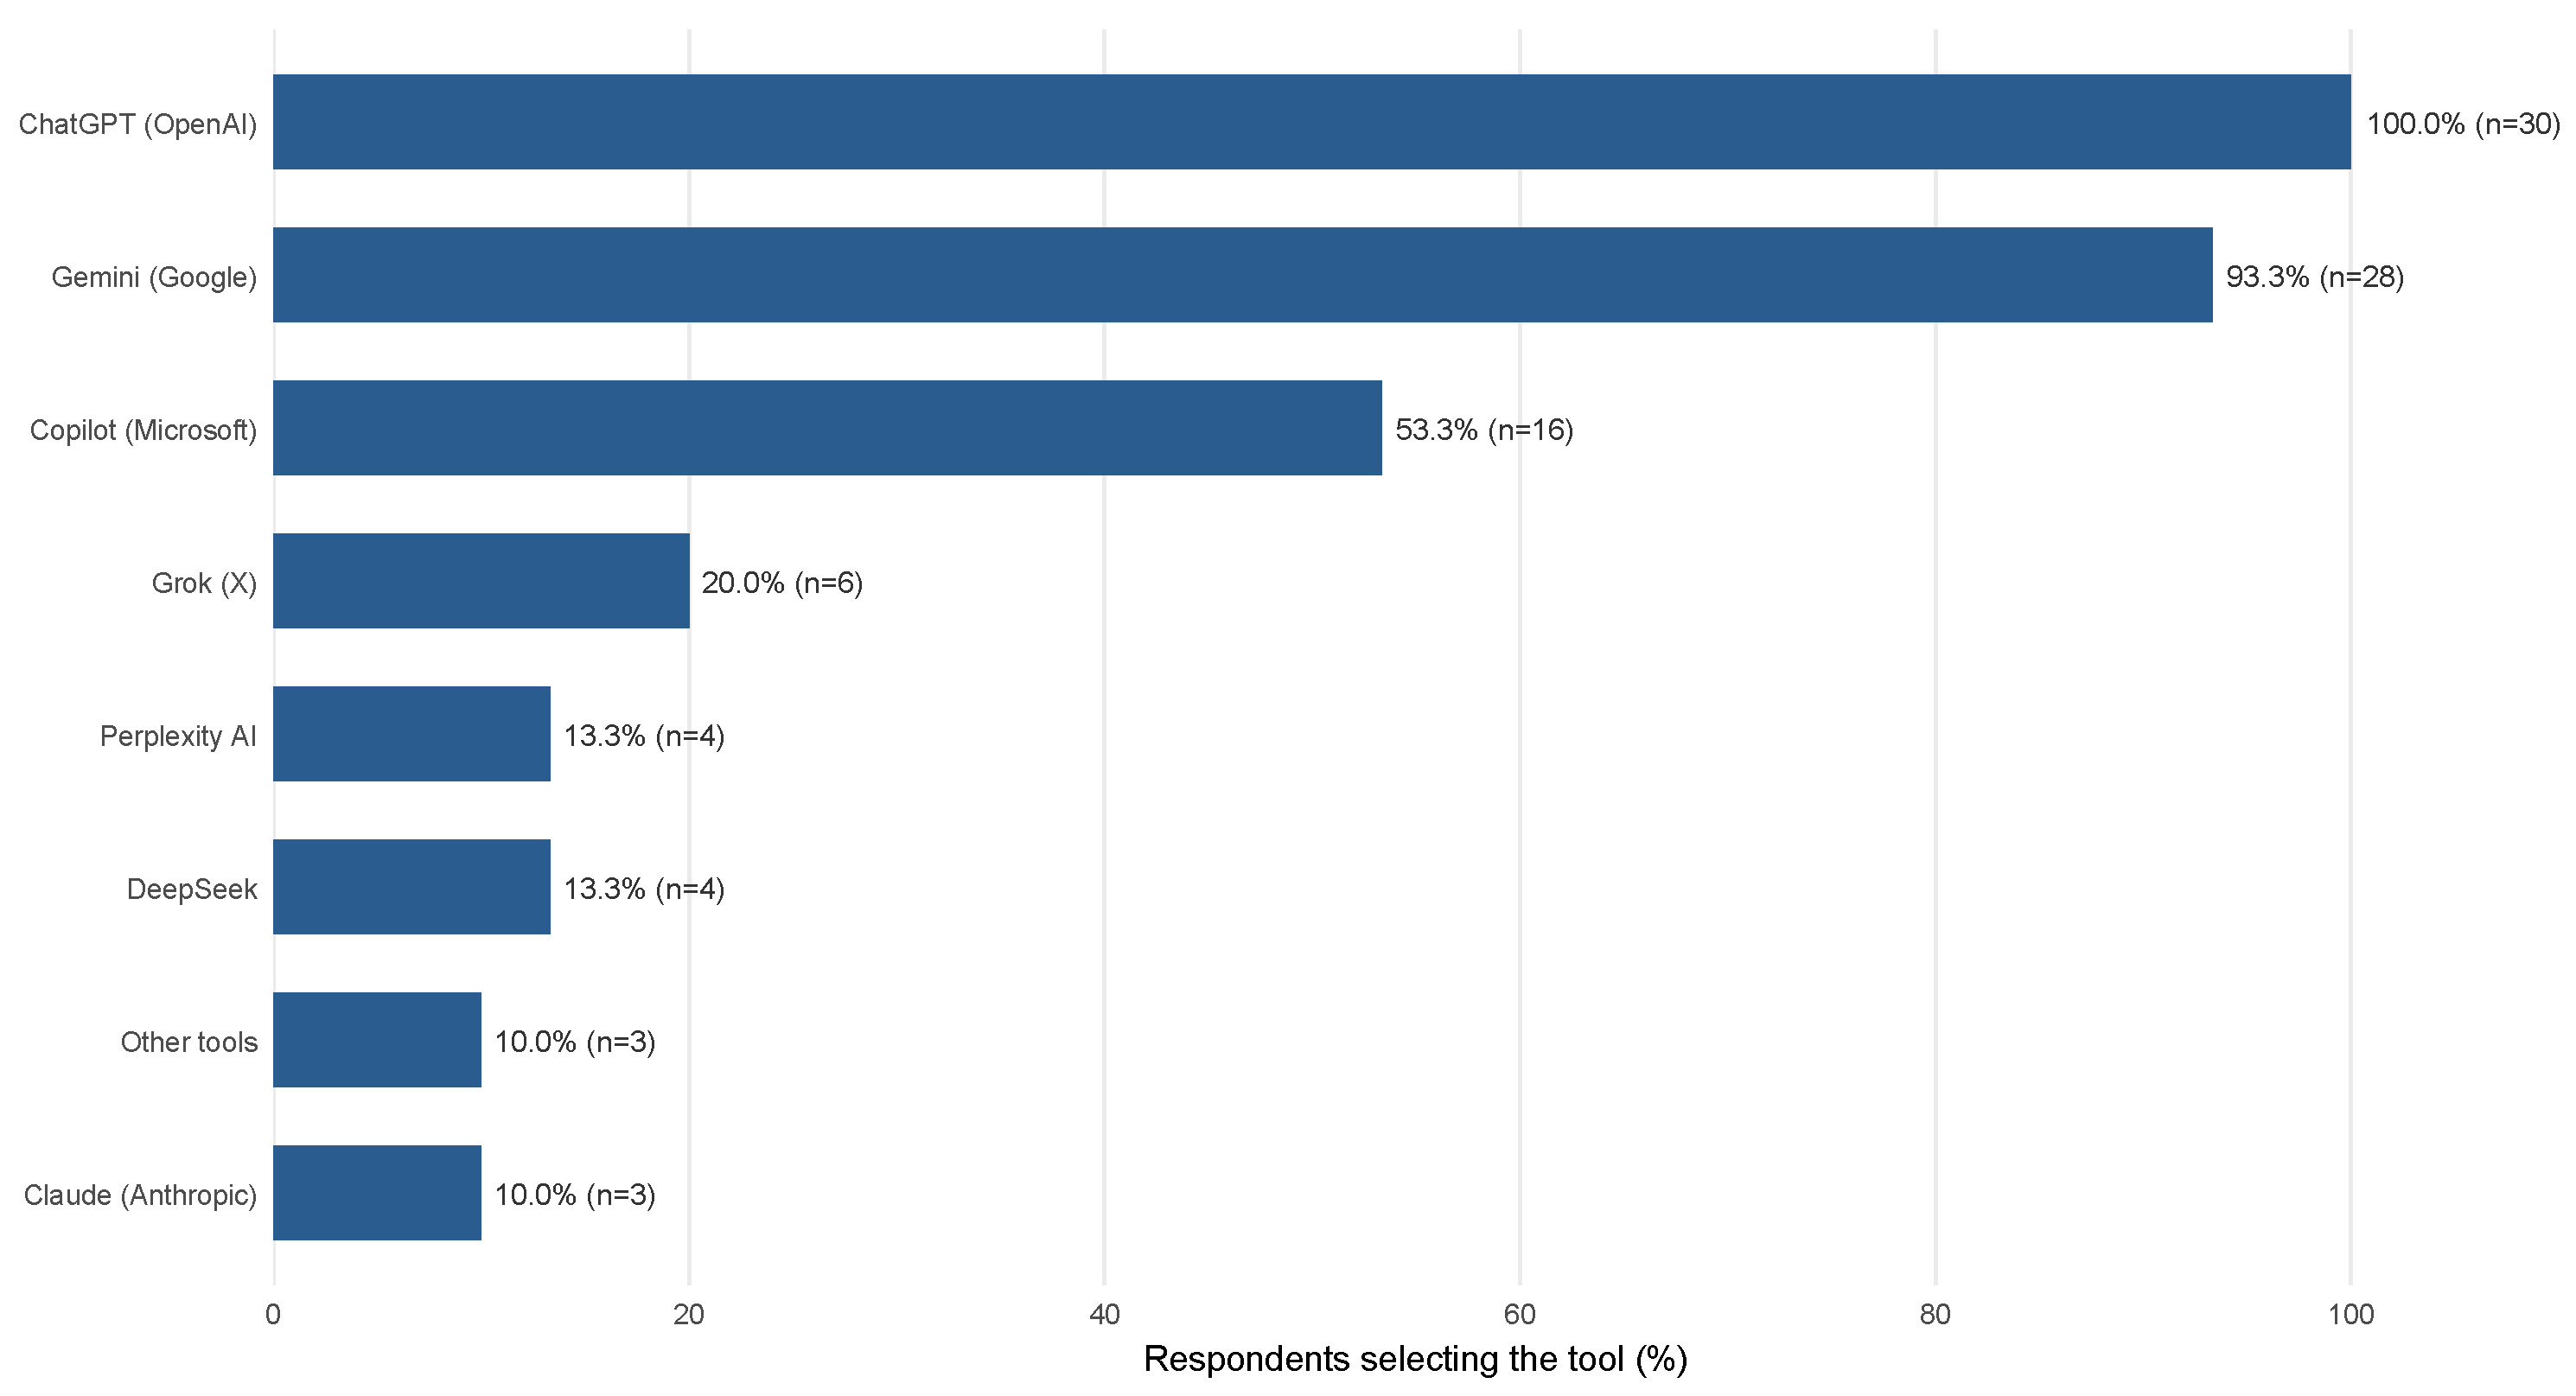
All 30 respondents selected ChatGPT, while 28 (93.3%) selected Gemini and 16 (53.3%) selected Copilot. Grok was selected by six respondents (20.0%), DeepSeek and Perplexity by four each (13.3%), and Claude and other tools by three each (10.0%). Because item P4 allowed multiple selections, the percentages are not expected to sum to 100%. The distribution of selected GenAI tools is presented in Figure 7.
Figure 7.
GenAI tools selected by respondents in the independent 2025 descriptive pilot (). Note. Multiple selections were permitted.
The distribution shows that respondents’ reported use extended beyond ChatGPT, with Gemini and Copilot selected more frequently than the remaining platforms.
Writing, editing, or translation was selected by 19 respondents (63.3%), while idea generation and concept explanation or tutoring were each selected by 18 (60.0%). Thirteen respondents (43.3%) selected mathematical or engineering problem solving, 12 (40.0%) selected summarization, 10 (33.3%) selected reference search, and nine (30.0%) selected programming support. As item P8 also allowed multiple selections, these responses represent the proportion of respondents selecting each activity. The distribution of reported academic activities is shown in Figure 8.
Figure 8.
Academic activities supported by GenAI in the independent 2025 descriptive pilot (). Note. Multiple selections were permitted.
The reported activities were concentrated mainly in writing, idea development, and concept explanation, although respondents also identified disciplinary applications such as engineering problem solving and programming support. These results describe the range of academic uses rather than their frequency or effectiveness.
Use frequency was predominantly occasional, reported by 18 respondents (60.0%), followed by frequent use reported by 10 (33.3%); one respondent reported rare use and one reported use all the time. Twenty-eight respondents (93.3%) primarily used free-access versions of GenAI tools. Verification practices varied: 11 respondents (36.7%) reported verifying outputs sometimes, 10 (33.3%) frequently, six (20.0%) rarely, two (6.7%) always, and one (3.3%) never. Perceived usefulness was high, with 18 respondents (60.0%) rating GenAI very useful, 10 (33.3%) useful, and two (6.7%) neutral. For conditional recommendation, 14 respondents (46.7%) selected use with strict verification, while eight (26.7%) selected use as a support agent while retaining final human judgment. These pilot findings are reported descriptively and are interpreted independently from the 2023 regression analysis.
5. Discussion
This section interprets the main findings in light of the international literature and the specific characteristics of the Colombian engineering-education context. It discusses the theoretical and practical implications of the results, while also addressing the study limitations and the directions that future research should follow to strengthen the evidence base on GenAI use in higher education.
5.1. Principal Findings and Relation to International Evidence
The inverse association between age and reported ChatGPT use provides a hypothesis for further investigation in undergraduate engineering education. Abdaljaleel et al. reported an association between older age and lower ChatGPT usage scores in a multinational study [6], whereas the present analysis examined a binary self-reported use outcome. The findings therefore have a similar direction but concern different measures. In this small, single-institution sample, the age estimate remains dependent on the specified model and requires confirmation in larger studies; the cross-sectional data do not identify a mechanism or establish how an individual’s use changes with age.
No statistically significant association was detected for gender or employment status. International findings on demographic differences are mixed and often depend on the country, discipline, outcome definition, and inclusion of acceptance constructs [3,6]. The current confidence intervals are too wide to support a claim of equivalence. Descriptive differences in Figure 4, Figure 5 and Figure 6 are therefore best treated as candidate hypotheses for a larger study rather than findings about women, men, full-time students, or working students.
The AUC and threshold accuracy describe in-sample performance rather than demonstrated predictive ability in new students. Neither model convergence nor goodness-of-fit testing provides internal or external validation. These results support further investigation of the observed associations rather than individual-level prediction. Studies with larger samples should assess calibration and performance beyond the development data, alongside the stability of the estimated associations [20,32].
The results also show why adoption cannot be reduced to a yes/no indicator. About half of the sample rated ChatGPT useful or very useful, while a substantial group was neutral or negative. Recommendation was more favorable than the usefulness distribution, suggesting that students may view the tool as conditionally valuable even when their own experience is mixed. A future design should distinguish experimentation, occasional use, sustained use, task type, verification, and reliance rather than treating all users as homogeneous.
5.2. Interpretation in the Colombian Engineering Context
The Colombian setting is relevant because the study documents GenAI adoption in a specific undergraduate engineering population in Medellín, where employment and study often coexist. In the 2023 sample, 79.7% of participants worked while studying and 35.9% were born outside Medellín. These observed characteristics describe the sample, but they do not measure workload, socioeconomic conditions, connectivity, commuting conditions, rurality, device access, or prior digital exposure. Inequalities in connectivity and digital access remain important background conditions in Colombia [10]; they are not used here to explain individual responses or the estimated age association.
The age coefficient does not identify why reported use differed by age. Prior exposure to digital technologies, study routines, digital confidence, course progression, peer networks, and institutional support are relevant variables for future research, but the present data cannot distinguish among them. Neither employment status nor birthplace can serve as a proxy for these unmeasured conditions. International evidence indicates that adoption can emerge from interacting individual and institutional factors [3]; in this study, however, those factors remain hypotheses for future measurement rather than mechanisms demonstrated by the model. Employment status was not statistically significant, and its wide confidence interval leaves the direction and magnitude of any association uncertain.
The 2025 pilot adds a separate institutional description of tool selection, access models, academic activities, and verification practices. Because program affiliation was unavailable, these findings are bounded to the institutional engineering setting and are not attributed to either program represented in the 2023 recruitment frame. The pilot identifies variables that future repeated cross-sectional or longitudinal designs could measure consistently, but it does not provide evidence of temporal change or of mechanisms underlying the 2023 age association [14].
5.3. Theoretical Implications
The findings do not validate TAM or UTAUT. The model estimates associations with age, gender, and employment status; a theoretically stronger study would directly measure the central acceptance constructs. Perceived usefulness, ease of use, trust, social influence, facilitating conditions, and perceived risk are plausible proximal determinants supported by prior GenAI adoption research [7,8,17]. Age, gender, and employment status may moderate or contextualize those relationships, but they should not replace them.
A future model should be designed prospectively, use validated multi-item scales, establish temporal ordering, and predefine whether the outcome is intention, initial use, frequency, task-specific use, or responsible-use behavior. Larger samples would also allow interaction terms and nonlinear age effects to be examined without overloading the model. This reframing positions the present findings as a hypothesis-generating basis for a prospectively specified acceptance study.
5.4. Implications for Teaching and Institutional Practice
The direct findings support institutional attention to heterogeneous GenAI adoption and to the verification practices reported in the 2025 pilot, whereas broader recommendations require support from the educational literature. In engineering courses, instructors can ask students to disclose relevant GenAI use, verify technical claims against authoritative sources, document substantive revisions made to generated outputs, and explain the independent reasoning used to accept or reject an AI-produced response. Recent evidence indicates that AI literacy is associated with more accurate ethical judgment and that engineering students and staff recognize both the learning-support potential of GenAI and the need to address reliability, transparency, and over-reliance [21,28].
Institutional guidance should also remain platform-neutral and attentive to unequal access. Common minimum competencies may include prompt evaluation, source-provenance checking, privacy protection, bias recognition, disciplinary validation, and clear distinctions between assistance and substitution. Because access to paid platforms is uneven, policies should not presume that all students use the same tools or subscription models. These recommendations are literature-supported practices that require empirical evaluation and should not be interpreted as outcomes demonstrated by the present single-institution samples [5,9].
5.5. Limitations and Future Research
Several limitations should be considered when interpreting the findings. The 2023 analysis was based on 64 undergraduate engineering students from a single institution recruited through non-probability quota procedures. This sampling strategy limits the external validity of the estimates beyond the study setting, while the relatively small number of non-users reduced the precision of the regression coefficients, particularly for gender and employment status. Because the academic-program identifier was not retained, the adequacy of representation from the two programs and any program-specific differences in adoption could not be assessed. The findings should therefore be understood as institution-specific and hypothesis-generating rather than as estimates of prevalence or effects for engineering students more broadly.
Measurement also imposes important constraints. All variables were self-reported and collected cross-sectionally, making the results potentially sensitive to recall, social-desirability, and volunteer-participation biases [35,36]. The binary P5 outcome captured whether respondents reported using ChatGPT but did not preserve differences in intensity or frequency of use. P6 was administered without skip logic and included one discordant “no/frequently” response, so it was retained for descriptive purposes rather than used to redefine the binary outcome. Moreover, the instrument review supported face and content clarity but did not constitute psychometric validation, and the survey did not include validated multi-item measures of technology-acceptance, trust, or AI-literacy constructs.
The regression model was intentionally parsimonious and included only age, gender, and employment status. Consequently, potentially relevant factors such as prior GenAI experience, digital competence, access conditions, academic workload, course stage, trust, perceived usefulness, and task-specific use were not modeled. No internal or external validation was performed, leaving the stability of the age estimate and the model’s performance beyond the observed sample unestablished. The apparent AUC and accuracy may therefore overestimate performance in new samples. Future studies with larger samples should prospectively specify predictors and, when prediction is an explicit objective, incorporate internal validation, calibration assessment, and out-of-sample evaluation alongside discrimination measures [19,32].
The independent 2025 pilot used an expanded questionnaire and a separate sample, so it provides a contemporaneous descriptive profile of platform choice, academic activities, access, and verification practices rather than an estimate of change from 2023. Program affiliation was unavailable for this sample as well; accordingly, its findings are bounded to the institutional engineering setting and cannot be used to assess program-level representation or differences. A stronger repeated cross-sectional design would retain a stable core instrument, comparable recruitment procedures, academic-program and semester identifiers, and predefined indicators while allowing additional modules for emerging platforms and practices. Longitudinal or multi-institutional studies could further incorporate validated TAM/UTAUT, trust, and AI-literacy measures, frequency and task-specific use, and objective or performance-linked outcomes where appropriate. Mixed-method designs would also help explain how students select GenAI tools, how they evaluate generated outputs, and under what conditions these technologies support or displace independent engineering reasoning.
6. Conclusions
The 2023 analysis contributes a carefully bounded account of ChatGPT adoption among undergraduate Quality Engineering and Production Engineering students in Medellín. In the audited 2023 dataset, 64 respondents provided complete data for a three-predictor logistic model. Older age was associated with lower odds of reported use in this exploratory sample, whereas the gender and employment estimates remained inconclusive.
TAM and UTAUT informed the literature review but were not tested, and the binary use indicator did not capture differences in frequency or purpose. Model-performance statistics describe the observed sample without internal or external validation. The study therefore contributes hypotheses and context-specific evidence for subsequent research rather than a validated basis for prediction or causal explanation.
The 2025 survey contributes a separate descriptive profile of the institutional engineering setting, documenting a multi-tool environment, predominant reliance on free access, diverse academic uses, and uneven verification practices without implying longitudinal or program-level change. Together, the two components identify concrete priorities for larger research: direct measurement of acceptance constructs, consistent repeated instruments, careful distinction between use and reliance, and evaluation of educational practices that strengthen verification, academic integrity, and independent professional judgment.
Author Contributions
Conceptualization, O.E.B.-C. and C.D.C.-Á.; methodology, E.Q.-R.; formal analysis, C.D.C.-Á.; data curation, O.E.B.-C.; writing—original draft, O.E.B.-C. and E.Q.-R.; writing—review and editing, C.D.C.-Á.; visualization, E.Q.-R.; supervision, O.E.B.-C. and C.D.C.-Á. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
This study was approved by the Ethics Committee of the Instituto Tecnológico Metropolitano under project PC24212 on 11 December 2024 and was classified as risk-free research. Before completing the questionnaire, participants received information about the study objectives, the voluntary nature of participation, and the anonymous processing of their responses. No personally identifiable information was collected. Data were processed exclusively for academic and research purposes in accordance with Colombia’s Personal Data Protection Act, Law 1581 of 2012 [37].
Informed Consent Statement
Electronic informed consent was obtained before participants accessed the survey questions. The Google Forms questionnaire included a mandatory item asking whether the student agreed to participate; only respondents who selected “Yes” could proceed with the questionnaire.
Data Availability Statement
The datasets and analytical materials supporting the findings of this study are publicly available in Mendeley Data at https://doi.org/10.17632/9d244nscv5.1. The repository includes the original 2023 survey dataset, the R code used for the logistic regression analysis, and the complete 2025 pilot dataset with the figures and cross-tabulations referenced in the manuscript. For citation purposes, please refer to [38].
Acknowledgments
During the preparation of this manuscript, the authors used ChatGPT (version 5.5, OpenAI) for language editing and stylistic refinement. No generative AI tools were used for study design, data collection, data analysis, or interpretation of results. The authors reviewed and edited all AI-assisted outputs and take full responsibility for the content of this publication.
Conflicts of Interest
The authors declare no conflicts of interest.
Appendix A. 2023 Questionnaire
This appendix presents the item wording and response options used to construct the variables in the 2023 analysis. Items P1–P4 describe participant context, self-reported AI knowledge, and awareness of ChatGPT, whereas P5–P8 capture direct use, use frequency, perceived usefulness, and willingness to recommend the tool. The original item codes are retained to preserve correspondence with the analyses reported in the manuscript.
- Age (years).
- Gender: Female; Male.
- P1. What is your employment status? Working and studying; Full-time student.
- P2. What is your place of birth? Medellín; Another city in Colombia.
- P3. What is your level of knowledge about AI? None; Basic; Intermediate; Advanced; Expert.
- P4. Have you heard about ChatGPT? Yes; No.
- P5. Have you used ChatGPT in your professional training? Yes; No.
- P6. How often do you use ChatGPT in your training? Rarely; Frequently.
- P7. How useful do you consider ChatGPT to be in your professional training? Not useful at all; Not very useful; Neutral; Useful; Very useful.
- P8. Would you recommend the use of ChatGPT in professional training to your colleagues? Definitely not; Probably not; Not sure; Probably yes; Definitely yes.
Appendix B. 2025 Descriptive-Pilot Questionnaire
This appendix presents the expanded instrument used for the independent 2025 descriptive pilot. In addition to participant characteristics, the questionnaire records platform selection, use frequency, access model, academic activities, verification practices, perceived usefulness and impact, and conditions for recommending GenAI. Items permitting multiple responses are identified in their corresponding response formats.
- Age (years).
- Gender: Female; Male.
- P1. What is your employment status? Working and studying; Full-time student.
- P2. What is your place of birth? Medellín; Another city in Colombia.
- P3. What is your place of residence? Medellín; Another city in Colombia.
- P4. Which GenAI tools have you used to support academic and/or professional activities during the last semester? ChatGPT; Gemini; Copilot; Grok; Perplexity AI; DeepSeek; Claude; Other. Multiple selections permitted.
- P5. What is your level of knowledge regarding GenAI? None; Basic; Intermediate.
- P6. How frequently do you use GenAI tools for academic or professional activities? Rarely; Occasionally; Frequently; All the time.
- P7. What type of access or subscription model do you primarily use? Free version; Paid version.
- P8. For which academic activities do you employ these tools? Writing/editing/translation; Idea generation; concept explanation or tutoring; mathematical or engineering problems; summarization; reference search or literature review; programming support. Multiple selections permitted.
- P9. How frequently do you verify AI-generated information using reliable external sources? Never; Rarely; Sometimes; Frequently; Always before use.
- P10. How useful do you consider GenAI for your professional development? Five-point anchors: 1 = not useful at all, 2 = not very useful, 3 = neutral, 4 = useful, and 5 = very useful. The exported dataset stores verbal labels.
- P11. How do you perceive the impact of these tools on critical thinking and problem solving? Decreases my own analytical ability; No impact (neutral); Slightly improves my skills; Significantly improves my skills.
- P12. Which recommendation best reflects your position? Unrestricted use; Use as an agent while retaining final human judgment; Use with strict verification; Restricted use for operational or secondary tasks; I would not recommend use because of risks to critical skills or ethics.
References
- Kasneci, E.; Sessler, K.; Küchemann, S.; Bannert, M.; Dementieva, D.; Fischer, F.; Gasser, U.; Groh, G.; Günnemann, S.; Hüllermeier, E.; et al. ChatGPT for good? On opportunities and challenges of large language models for education. Learn. Individ. Differ. 2023, 103, 102274. [Google Scholar] [CrossRef] [Scilit]
- Cotton, D.R.E.; Cotton, P.A.; Shipway, J.R. Chatting and cheating? Ensuring academic integrity in the era of ChatGPT. Innov. Educ. Teach. Int. 2024, 61, 228–239. [Google Scholar] [CrossRef] [Scilit]
- Ravšelj, D.; Keržič, D.; Tomaževič, N.; Umek, L.; Brezovar, N.; Iahad, N.A.; Abdulla, A.A.; Akopyan, A.; Segura, M.W.A.; AlHumaid, J.; et al. Higher education students’ perceptions of ChatGPT: A global study of early reactions. PLoS ONE 2025, 20, e0315011, Correction in PLoS ONE 2026, 21, e0349691. [Google Scholar] [CrossRef] [Scilit]
- Chan, C.K.Y. A comprehensive AI policy education framework for university teaching and learning. Int. J. Educ. Technol. High. Educ. 2023, 20, 38. [Google Scholar] [CrossRef] [Scilit]
- Miao, F.; Holmes, W. Guidance for Generative AI in Education and Research; UNESCO: Paris, France, 2023. Available online: https://unesdoc.unesco.org/ark:/48223/pf0000386693 (accessed on 10 March 2026).
- Abdaljaleel, M.; Barakat, M.; Alsanafi, M.; Salim, N.A.; Abazid, H.; Malaeb, D.; Mohammed, A.H.; Hassan, B.A.R.; Wayyes, A.M.; Farhan, S.S.; et al. A multinational study on the factors influencing university students’ attitudes and usage of ChatGPT. Sci. Rep. 2024, 14, 1983, Correction in Sci. Rep. 2024, 14, 8281. [Google Scholar] [CrossRef] [Scilit]
- Alshammari, S.H.; Babu, E. The mediating role of satisfaction in the relationship between perceived usefulness, perceived ease of use and students’ behavioural intention to use ChatGPT. Sci. Rep. 2025, 15, 7169. [Google Scholar] [CrossRef] [Scilit]
- Xu, J.; Li, Y.; Shadiev, R.; Li, C. College students’ use behavior of generative AI and its influencing factors under the unified theory of acceptance and use of technology model. Educ. Inf. Technol. 2025, 30, 19961–19984. [Google Scholar] [CrossRef] [Scilit]
- Chung, J.; Henderson, M.; Slade, C.; Liang, Y.; Pepperell, N.; Corbin, T.; Walton, J.; Yu, A.S.; Bearman, M.; Buckingham Shum, S.; et al. The use and usefulness of GenAI in higher education: Student experience and perspectives. Comput. Educ. Open 2026, 10, 100347. [Google Scholar] [CrossRef] [Scilit]
- Barragán Moreno, S.P.; Guzmán Rincón, A. Digital divide as an explanatory variable for dropout in higher education. Int. J. Educ. Technol. High. Educ. 2025, 22, 60. [Google Scholar] [CrossRef] [Scilit]
- Instituto Tecnológico Metropolitano. Ingeniería de la Calidad. Available online: https://www.itm.edu.co/aspirante-pregrado/programas-profesionales/ingenieria-de-la-calidad/ (accessed on 14 August 2026).
- Instituto Tecnológico Metropolitano. Ingeniería de Producción. Available online: https://www.itm.edu.co/aspirante-pregrado/programas-profesionales/ingenieria-de-produccion/ (accessed on 14 August 2026).
- Bond, M.; Khosravi, H.; De Laat, M.; Bergdahl, N.; Negrea, V.; Oxley, E.; Pham, P.; Chong, S.W.; Siemens, G. A meta systematic review of artificial intelligence in higher education: A call for increased ethics, collaboration, and rigour. Int. J. Educ. Technol. High. Educ. 2024, 21, 4. [Google Scholar] [CrossRef] [Scilit]
- Farrokhnia, M.; Banihashemi, S.K.; Noroozi, O.; Wals, A. A SWOT analysis of ChatGPT: Implications for educational practice and research. Innov. Educ. Teach. Int. 2024, 61, 460–474. [Google Scholar] [CrossRef] [Scilit]
- Davis, F.D. Perceived usefulness, perceived ease of use, and user acceptance of information technology. MIS Q. 1989, 13, 319–340. [Google Scholar] [CrossRef] [Scilit]
- Venkatesh, V.; Morris, M.G.; Davis, G.B.; Davis, F.D. User acceptance of information technology: Toward a unified view. MIS Q. 2003, 27, 425–478. [Google Scholar] [CrossRef] [Scilit]
- Shahzad, M.F.; Xu, S.; Javed, I. ChatGPT awareness, acceptance, and adoption in higher education: The role of trust as a cornerstone. Int. J. Educ. Technol. High. Educ. 2024, 21, 46. [Google Scholar] [CrossRef] [Scilit]
- MacKenzie, S.B.; Podsakoff, P.M.; Podsakoff, N.P. Construct measurement and validation procedures in MIS and behavioral research: Integrating new and existing techniques. MIS Q. 2011, 35, 293–334. [Google Scholar] [CrossRef] [Scilit]
- Vittinghoff, E.; McCulloch, C.E. Relaxing the rule of ten events per variable in logistic and Cox regression. Am. J. Epidemiol. 2007, 165, 710–718. [Google Scholar] [CrossRef] [Scilit]
- Heinze, G.; Wallisch, C.; Dunkler, D. Variable selection—A review and recommendations for the practicing statistician. Biom. J. 2018, 60, 431–449. [Google Scholar] [CrossRef] [Scilit]
- Cunningham, E.; Kings, I.; Robbins, P.; Keith, M.J. Integrating generative artificial intelligence into chemical engineering education: Staff and student perspectives. Educ. Chem. Eng. 2026, 55, 100503. [Google Scholar] [CrossRef] [Scilit]
- Ntoutsi, E.; Fafalios, P.; Gadiraju, U.; Iosifidis, V.; Nejdl, W.; Vidal, M.E.; Ruggieri, S.; Turini, F.; Papadopoulos, S.; Krasanakis, E. Bias in data-driven artificial intelligence systems—An introductory survey. WIREs Data Min. Knowl. Discov. 2020, 10, e1356. [Google Scholar] [CrossRef] [Scilit]
- Aler Tubella, A.; Mora-Cantallops, M.; Nieves, J.C. How to teach responsible AI in higher education: Challenges and opportunities. Ethics Inf. Technol. 2024, 26, 3. [Google Scholar] [CrossRef] [Scilit]
- van Eck, N.J.; Waltman, L. Software survey: VOSviewer, a computer program for bibliometric mapping. Scientometrics 2010, 84, 523–538. [Google Scholar] [CrossRef] [Scilit]
- Donthu, N.; Kumar, S.; Mukherjee, D.; Pandey, N.; Lim, W.M. How to conduct a bibliometric analysis: An overview and guidelines. J. Bus. Res. 2021, 133, 285–296. [Google Scholar] [CrossRef] [Scilit]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In Advances in Neural Information Processing Systems; Curran Associates, Inc.: Red Hook, NY, USA, 2017; Volume 30, Available online: https://proceedings.neurips.cc/paper_files/paper/2017/file/3f5ee243547dee91fbd053c1c4a845aa-Paper.pdf (accessed on 10 March 2026).
- Perkins, M. Academic integrity considerations of AI large language models in the post-pandemic era: ChatGPT and beyond. J. Univ. Teach. Learn. Pract. 2023, 20, 7. [Google Scholar] [CrossRef] [Scilit]
- Reed, J.M.; Ferdig, R.E.; Dodson, T.M.; Gunstad, J.; Hughes, J.W. AI literacy and scenario-based ethical judgment about generative AI among undergraduate students. J. Acad. Ethics 2026, 24, 82. [Google Scholar] [CrossRef] [Scilit]
- van Smeden, M.; de Groot, J.A.H.; Moons, K.G.M.; Collins, G.S.; Altman, D.G.; Eijkemans, M.J.C.; Reitsma, J.B. No rationale for 1 variable per 10 events criterion for binary logistic regression analysis. BMC Med. Res. Methodol. 2016, 16, 163. [Google Scholar] [CrossRef] [Scilit]
- Riley, R.D.; Ensor, J.; Snell, K.I.E.; Harrell, F.E.; Martin, G.P.; Reitsma, J.B.; Moons, K.G.M.; Collins, G.S.; van Smeden, M. Calculating the sample size required for developing a clinical prediction model. BMJ 2020, 368, m441. [Google Scholar] [CrossRef] [Scilit]
- Hosmer, D.W., Jr.; Lemeshow, S.; Sturdivant, R.X. Applied Logistic Regression, 3rd ed.; John Wiley & Sons: Hoboken, NJ, USA, 2013. [Google Scholar] [CrossRef] [Scilit]
- Steyerberg, E.W.; Vickers, A.J.; Cook, N.R.; Gerds, T.; Gonen, M.; Obuchowski, N.; Pencina, M.J.; Kattan, M.W. Assessing the performance of prediction models: A framework for traditional and novel measures. Epidemiology 2010, 21, 128–138. [Google Scholar] [CrossRef] [Scilit]
- Robin, X.; Turck, N.; Hainard, A.; Tiberti, N.; Lisacek, F.; Sanchez, J.-C.; Müller, M. pROC: An open-source package for R and S+ to analyze and compare ROC curves. BMC Bioinform. 2011, 12, 77. [Google Scholar] [CrossRef] [Scilit]
- R Core Team. R: A Language and Environment for Statistical Computing; R Foundation for Statistical Computing: Vienna, Austria, 2026; Available online: https://www.R-project.org/ (accessed on 5 July 2026).
- Ried, L.; Eckerd, S.; Kaufmann, L. Social desirability bias in PSM surveys and behavioral experiments: Considerations for design development and data collection. J. Purch. Supply Manag. 2022, 28, 100743. [Google Scholar] [CrossRef] [Scilit]
- Bell, A.; Ward, P.; Tamal, M.E.H.; Killilea, M. Assessing recall bias and measurement error in high-frequency social data collection for human-environment research. Popul. Environ. 2019, 40, 325–345, Correction in Popul. Environ. 2019, 40, 346. [Google Scholar] [CrossRef] [Scilit]
- Republic of Colombia. Ley 1581 de 2012: Por la cual se dictan disposiciones generales para la protección de datos personales. Diario Oficial No. 48.587. 17 October 2012. Available online: https://www.funcionpublica.gov.co/eva/gestornormativo/norma_pdf.php?i=49981 (accessed on 1 December 2025).
- Correa, C. Survey_AI_Tools_2023_2025: Repository for Adoption and Perceptions of AI Tools in Engineering Education. Mendeley Data 2025, V1. Available online: https://data.mendeley.com/datasets/9d244nscv5/1 (accessed on 5 December 2025).
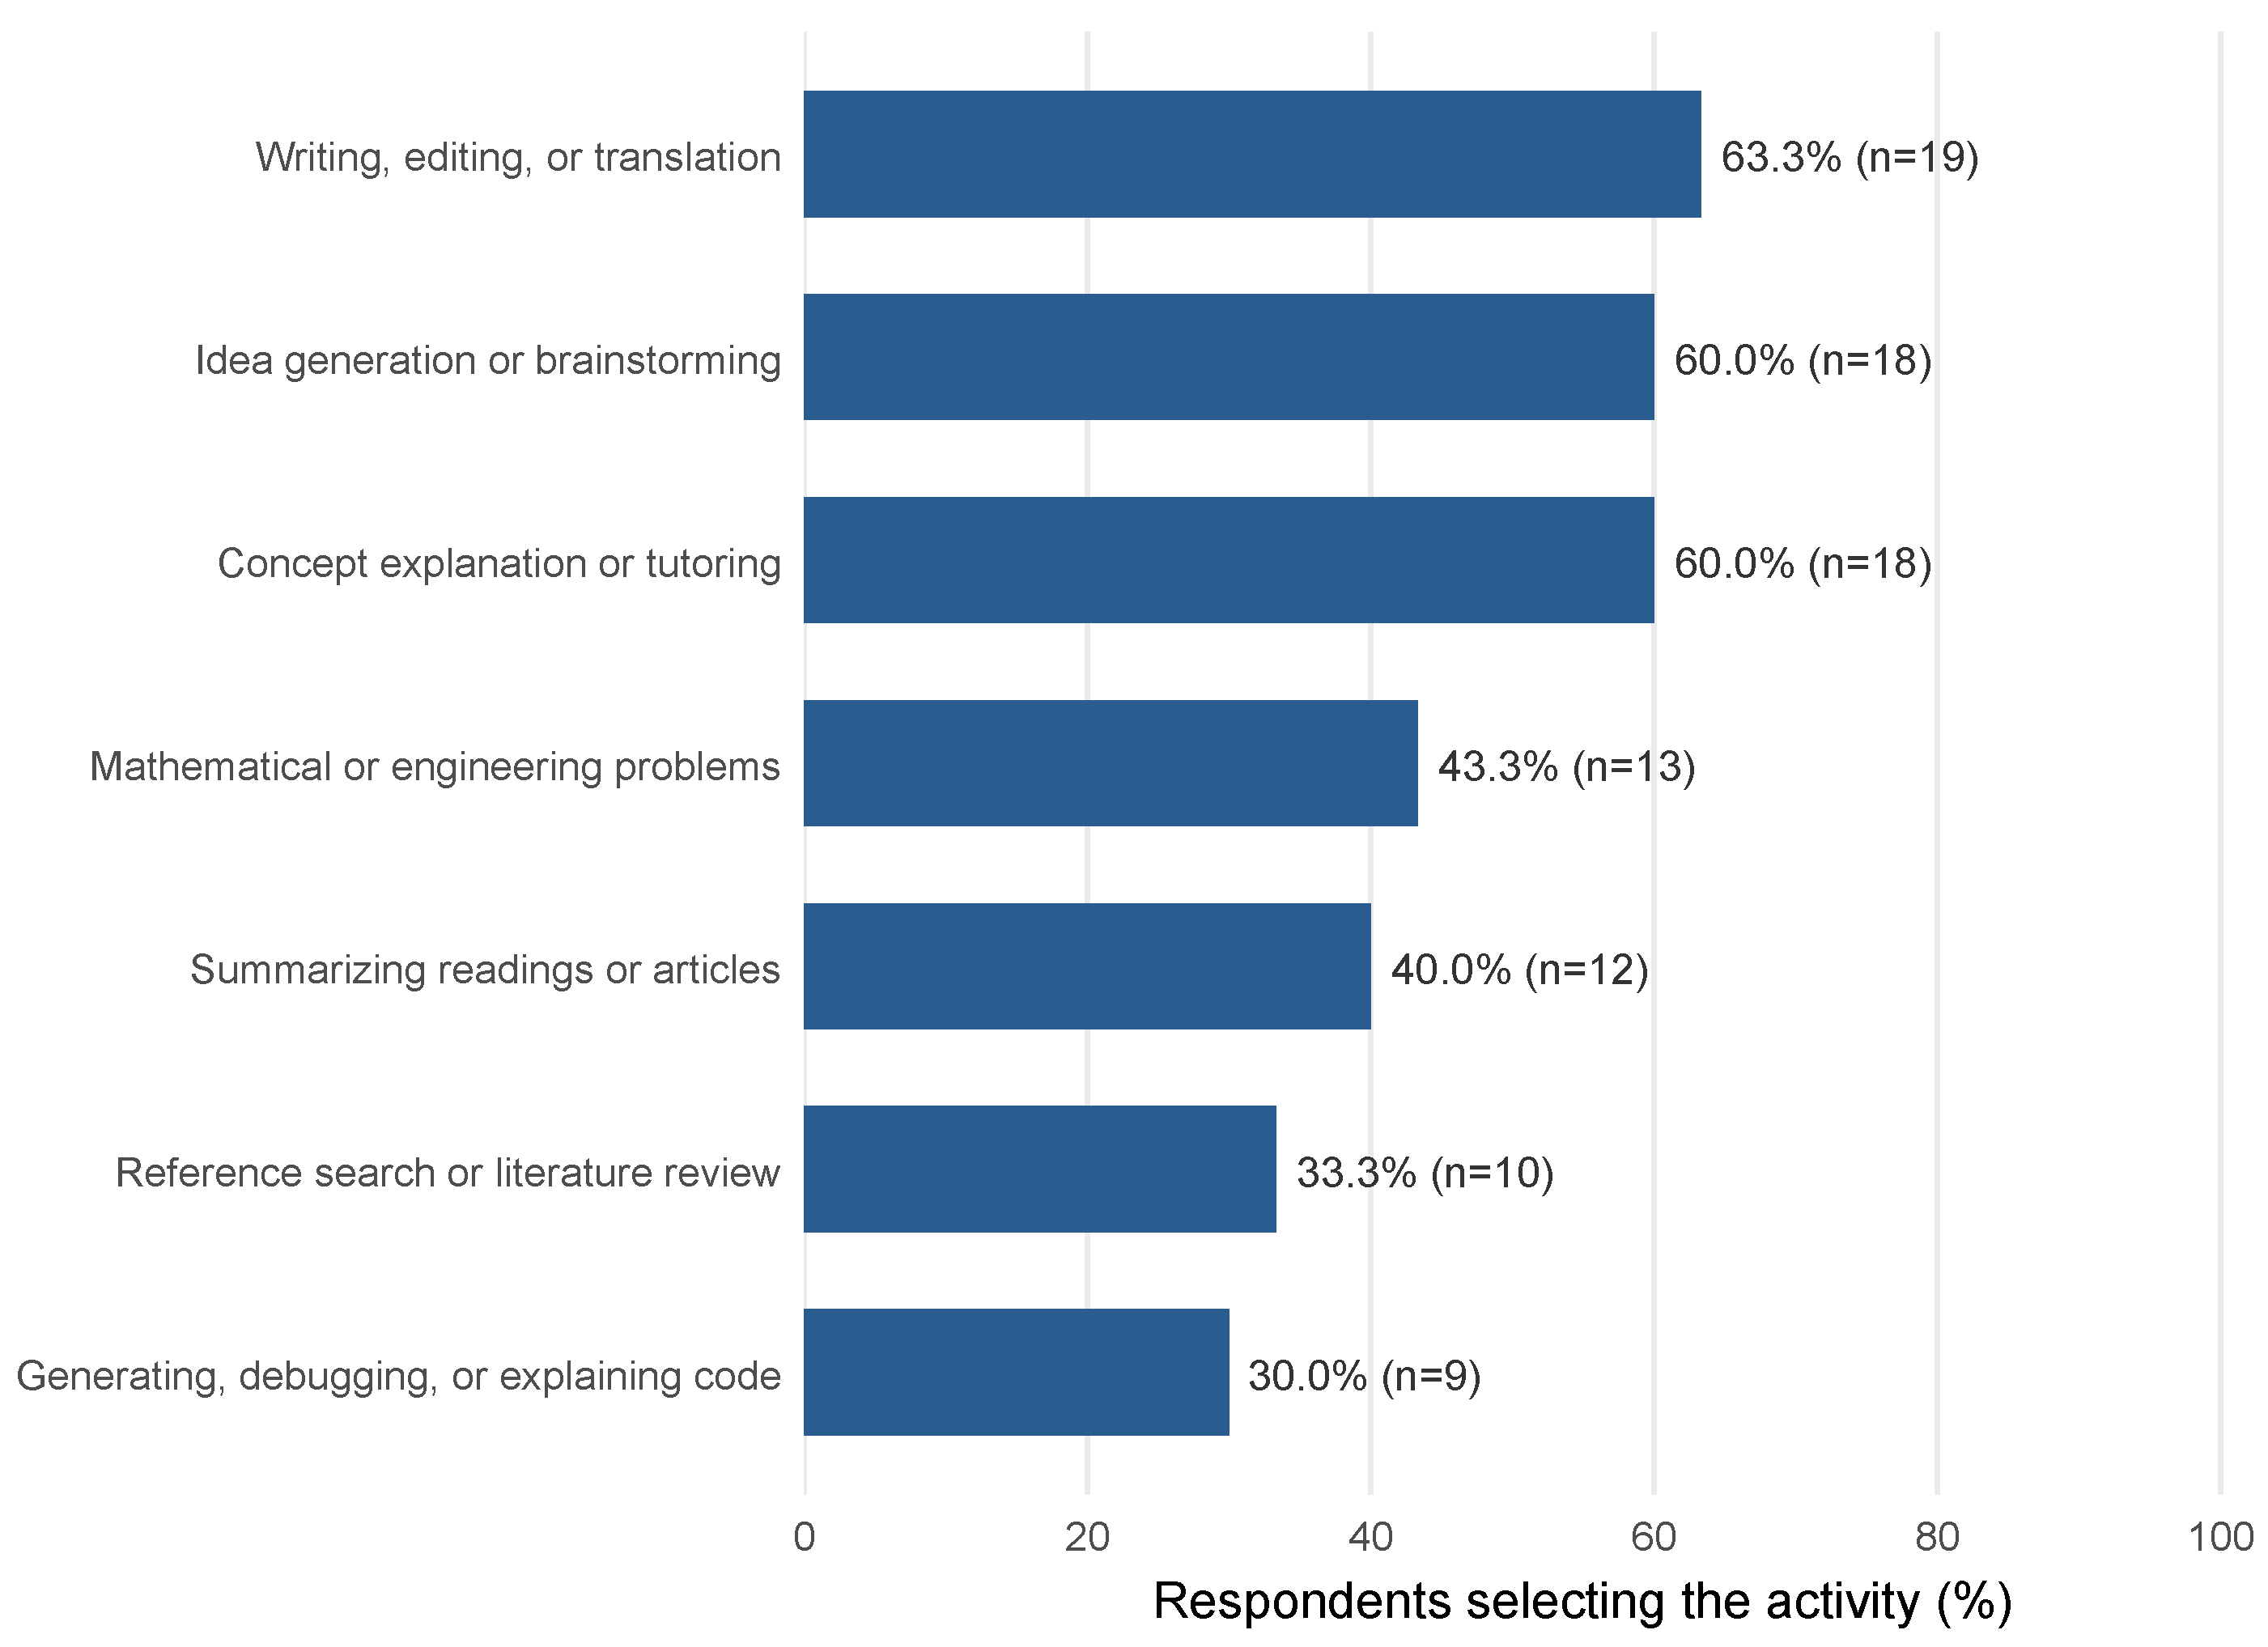

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.