


Abstract
The application of information systems to the documentation and representation of historical–architectural heritage is currently the focus of research, experimentations, and innovations increasingly geared towards awareness, management, and conservation processes. This involves addressing unresolved challenges arising from the effort of translating the inherent complexity of heritage into knowledge that can be applied to monitoring, conservation, informative, cross-relational, and interdisciplinary actions. Processes involving data classification, segmentation, and semantic association for high-level knowledge clustering, exploiting Artificial Intelligence algorithms, are emerging as a potential—albeit ambivalent—aid in the management of digital information sources. The paper explores some State of the Art procedures in the field and ongoing applied research with a particular focus on the concept of adaptive data management, leveraging parametric modeling and applications within 3D point cloud data for the recognition of surface features and diagnostic purposes. The reconciliation of information between the point cloud segmented through Artificial Intelligence algorithms and the HBIM model starts from heritage building laser scanner and photomodeling datasets, analyzing materials and state of conservation features. The experimentation is focused on a reverse approach—the so-called “HBIM-to-Cloud”—with the aim of generating an enriched information cloud defined by the surfaces of the parametric model.
1. Introduction
The development of tools for the digital acquisition of the historical–architectural heritage and cultural assets in general and the implementation of digital information systems are leading to the need to shift perspectives on data management, both from a theoretical, critical, and conceptual standpoint and from a technological–methodological one. The exponential growth of digital data in the cultural heritage sector (point clouds and 3D models, diagnostic information, digital catalogues, and interoperable archives), indeed, has increased the search for methodologies able to transform heterogeneous information into structured and meaningful knowledge. Although digital acquisition technologies offer high precision and accuracy according to the survey purposes, the outcomes in terms of datasets often remain descriptive but “uncritical” and difficult to interpret, revealing a persistent gap between metric accuracy and semantic intelligibility.
In this framework, digital information systems for heritage buildings are at the forefront of innovation processes, as they have the potential to collect and merge different data and sources, facilitating the multilayer representation of complex architectures and elements, supporting documentation, conservation, monitoring, analysis, management, and intervention approaches. BIM (Building Information Modelling), HBIM (Heritage or Historic Information Modelling), and Digital Twins, are the digital information environments on which most experiments and research are currently focusing, particularly with regard to applications in the field of cultural heritage. The uniqueness, complexity, and non-repeatability of the elements that characterize historic architecture provide a crucial challenge in the representation and management of digital data, since shapes, materials, and states of conservation cannot be standardized. The creation of consistently effective and reliable models still raises a number of unresolved issues, ranging from the degree of simplification or geometric abstraction of complex morphologies to the representation of stratified states of conservation, up to efficient systems for information enrichment.
Technological progress has led to the possibility of collecting heterogeneous data rapidly and to the development of complex pervasive information ecosystems around historic buildings. This condition generates a structural imbalance between the amount of available data and their intelligibility. Without a critical and targeted approach and a robust methodological line, redundant, fragmented, and difficult-to-interpret datasets are produced, incapable of conveying the historical, material, and semantic complexity of the assets [1]. The result is a strong and pressing need to turn data into knowledge.
In this context, three areas of research are emerging as particularly significant: HBIM, Digital Twin, and Artificial Intelligence (AI) applications. Whilst the Digital Twin aims to link the physical asset with its digital model in an increasingly meaningful way to support long-term monitoring and conservation, AI-driven processes cover a set of actions for the recognition, classification, semantic enrichment, integration, and interpretation of cultural heritage data. The parametric modelling of historical–architectural heritage, on the other hand, is also increasingly related to the source data obtained through digital surveying (whether laser or photogrammetric), applying the so-called Scan-to-HBIM process, which increasingly relies on point cloud digital model discretization procedures to “break down” the mass of data through segmentations aimed at “facilitating” processes and new forms of data management thanks to ontological schematizations.
These trends highlight the ever-increasing need to link the results of digitalization more closely to the physical world and to have even more effective tools for managing the huge amounts of digital data that can nowadays be obtained.
Moreover, there is a growing need to address the issue of fragile heritage and heritage at risk, through protocols relating to the application and applicability of currently available technologies and the integration of different documentation systems. Digital surveying and data management technologies must help to anticipate risks and mitigate their impacts, as there can be no protection without knowledge, and many of the outcomes achievable through the application of digital technologies remain beyond the reach of the institutional bodies responsible for managing conservation, restoration, or safety measures [2,3]. Restoration begins with surveying; it must then be possible to make decisions based on the available survey data. This highlights the act of responsibility that surveying and documentation represent.
These continuous and progressive changes in the heritage digitization scenario require an interweaving of perspectives to modify the concepts through which we are used to organizing captured reality, leaving behind certainties, recurrently adapting our way of thinking, opening new visions, and adjusting concepts, to rethinking the nature of knowledge and adapting our approaches to what we learn [4] (pp. 12–13).
In this direction, a research framework has been conceived focusing on the “adaptive” information management of digital data in a BIM environment, applied to existing and cultural heritage. The term “adaptive” refers specifically to the population of parametric information models [5], but the concept extends to a paradigm shift in the process ranging from targeted surveying, through data processing, to the logic of connecting the necessary information where it is needed (within the geometric model), whilst addressing complexity and making critical decisions.
The paper presents ongoing experimentations and research outcomes concerning the HBIM workflow, from data acquisition and modeling to information management, focusing on the reconciliation of information between the point cloud processed through AI algorithms and the HBIM model by proposing a reverse approach. The research avenue indeed seeks to provide new insights into the “HBIM-to-Cloud” approach, first and foremost from a methodological point of view, with the aim of resolving the current discrepancy in the Scan-to-BIM process. In order to give an overview of the strategies investigated, the experiments are described in general terms, without going into the specific details of each test. The innovative approach that has been experienced indeed does not concern the assignment of material or “Property Set” (pSet) information in the BIM environment for surface feature management, but the use of intensity information for a deterioration assessment (although this is not the specific focus of this paper) and, particularly, the exchange of information between HBIM-derived and measured point clouds. Assuming that the survey is the essential basis for any analysis of or intervention on historic architecture, gathering all the necessary information before conceiving any interpretative hypothesis or even taking action [6], consideration should be given to the frequent practice of managing separately between the point cloud and the parametric model, once the 3D survey data have been used to generate the model geometries. Conceptually and technically, all these data and information should be available to all those involved in the different phases of the conservation process [7] (p. 18).
The paper is organized as follows: after having briefly framed the main issues and challenges in heritage digital data management and outlined the scope of the paper, Section 1.1 discusses the State of the Art in digital information environments, while Section 1.2 highlights the main research points, questions, and aims. Section 2 is focused on materials and methods, describing the developed methodological workflow centered on the concept of adaptive population in parametric models and BIM-to-Cloud development towards a reconciliation of information between the point cloud processed through AI algorithms and HBIM. Section 3 outlines results obtained by applying the BIM-to-Cloud process, interpolating the survey point cloud with the BIM model in a meaningful way. Section 4 discusses applied methodologies and outcomes in a broader context, while Section 5 concludes the paper focusing on possible visions for the future, to make information accessible, integrating new knowledge to digital models, and to make digital environments truly and effectively available to support heritage conservation.
1.1. State of the Art and Research Framework
Digital information systems are a rapidly evolving research area in the field of cultural heritage, where the issue of organizing, structuring, and classifying digital data cannot be separated from the first and foremost step in any knowledge objective, namely survey, data collection, and documentation. The exponential technological innovation in 3D acquisition tools is leading to unprecedented changes in the amount of data (spatial coordinates) that can be captured, at an ever-faster rate. This trend offers a number of advantages in terms of digital acquisition potential—a pressing need for heritage at risk and for sites affected by overtourism, as highlighted by the European Commission’s study on the Common European Data Space for Cultural Heritage, a flagship initiative of the European Union [8,9]—but it also requires a new awareness in the process of documentation, as well as new skills in the critical analysis, interpretation, and use of data.
There is a need to redesign, at least in part, the ways in which we “interact” with cultural heritage, developing new models of digital data management capable of embracing and supporting the process of change. However, adapting to new scenarios of innovation does not mean passively accepting them. The risk is that of the extreme mystification of technology, assigning the value of the method to the tool, whereas it would be essential to rediscover the “intelligent” relationship between humankind and technology and the relationship between heritage and technological advancement through a knowledge project.
This is the framework in which HBIM can be placed as a potential information-centric environment to manage heterogenous knowledge [10], rather than merely a modeling methodology for geometric reconstruction. Current research focuses on three complementary domains: the semantic definition of model entities [11], the enrichment of information through multidisciplinary datasets, and the sharing and interoperability of knowledge among different platforms and stakeholders. Several research avenues are oriented to extending conventional BIM standards to include specific architectural heritage features. Nevertheless, existing classification systems and IFC schemas (Industry Foundation Classes, open, and standardised formats) still struggle to represent irregular geometries, historical construction techniques, conservation activities, material degradations, and the temporal evolution of heritage assets, prompting the development of dedicated ontologies and semantic extensions such as CIDOC-CRM-based models and HBIM-specific vocabularies [12]. Despite significant progress, several major challenges remain unresolved. Heritage-specific semantic standards are still lacking, interoperability and monitoring platforms remain limited, and information exchange frequently results in data loss. Moreover, existing HBIM implementations often provide static representations that inadequately capture the temporal evolution of buildings, maintenance histories, and continuously updated monitoring information. Recent studies therefore identify AI, knowledge graphs, linked open data, and Digital Twin technologies as promising directions for overcoming these limitations through automated semantic enrichment, dynamic information management, and more effective multidisciplinary integration [13,14].
AI is increasingly being proposed as a possible response to information overload in the cultural heritage sector. Machine Learning (ML) and automated analytical techniques are particularly applied to work with large amounts of data, identifying patterns, recurrences, and correlations that exceed human perceptual and cognitive capacities [15]. Applied to documentary sources, images, three-dimensional data, and metadata, AI-driven processes can accelerate classification, extraction, and linking of information, potentially transforming redundancy into a resource [16] and supporting semantic enrichment, as well as heritage data integration and interpretation. The automated processing of documentary sources and classification of heterogeneous archival materials; semantic standardization and terminological reconciliation through ontologies and linked open data to resolve ambiguities and enhance interoperability; AI-supported knowledge graphs, where ML helps identify entities and possible relationships between documents, HBIM components, materials, places, and actors, strengthening conditions for expert-driven critical interpretation, are some of the applications documented in the literature [17].
Despite its considerable potential, the adoption of AI for cultural heritage data management remains characterized by significant ambiguities. Although it substantially improves the efficiency, scalability, and automation of information processing, it also introduces significant epistemological challenges concerning the opacity of algorithmic models and the delegation of interpretative reasoning to computational systems [18]. Since AI models learn from training datasets that are often incomplete, biased, or overly homogeneous, they tend to reinforce dominant patterns while overlooking exceptions, inconsistencies, and local specificities that are essential for historical and cultural interpretation [19]. This limitation is especially relevant in the context of built cultural heritage, where complexity, stratification, uncertainty, and uniqueness are intrinsic characteristics rather than anomalies. Consequently, the key issue is not simply whether AI should be employed in heritage data management, but rather how it can be integrated into expert-driven workflows in ways that augment interpretation without oversimplifying or compromising the cultural complexity and historical significance of heritage assets.
Several studies on Digital Twin [20,21] applied to historical architectural heritage also focus on the interoperability of digital environments and data, the replication of historical contexts for their enhancement, or the structuring of ontologies for the organization of semantic descriptors [22]. In general, the main topics center on data structuring and support for cultural heritage management and monitoring processes. The digital model therefore opens up enormous potential for cross-fertilization and integration between different disciplinary sectors.
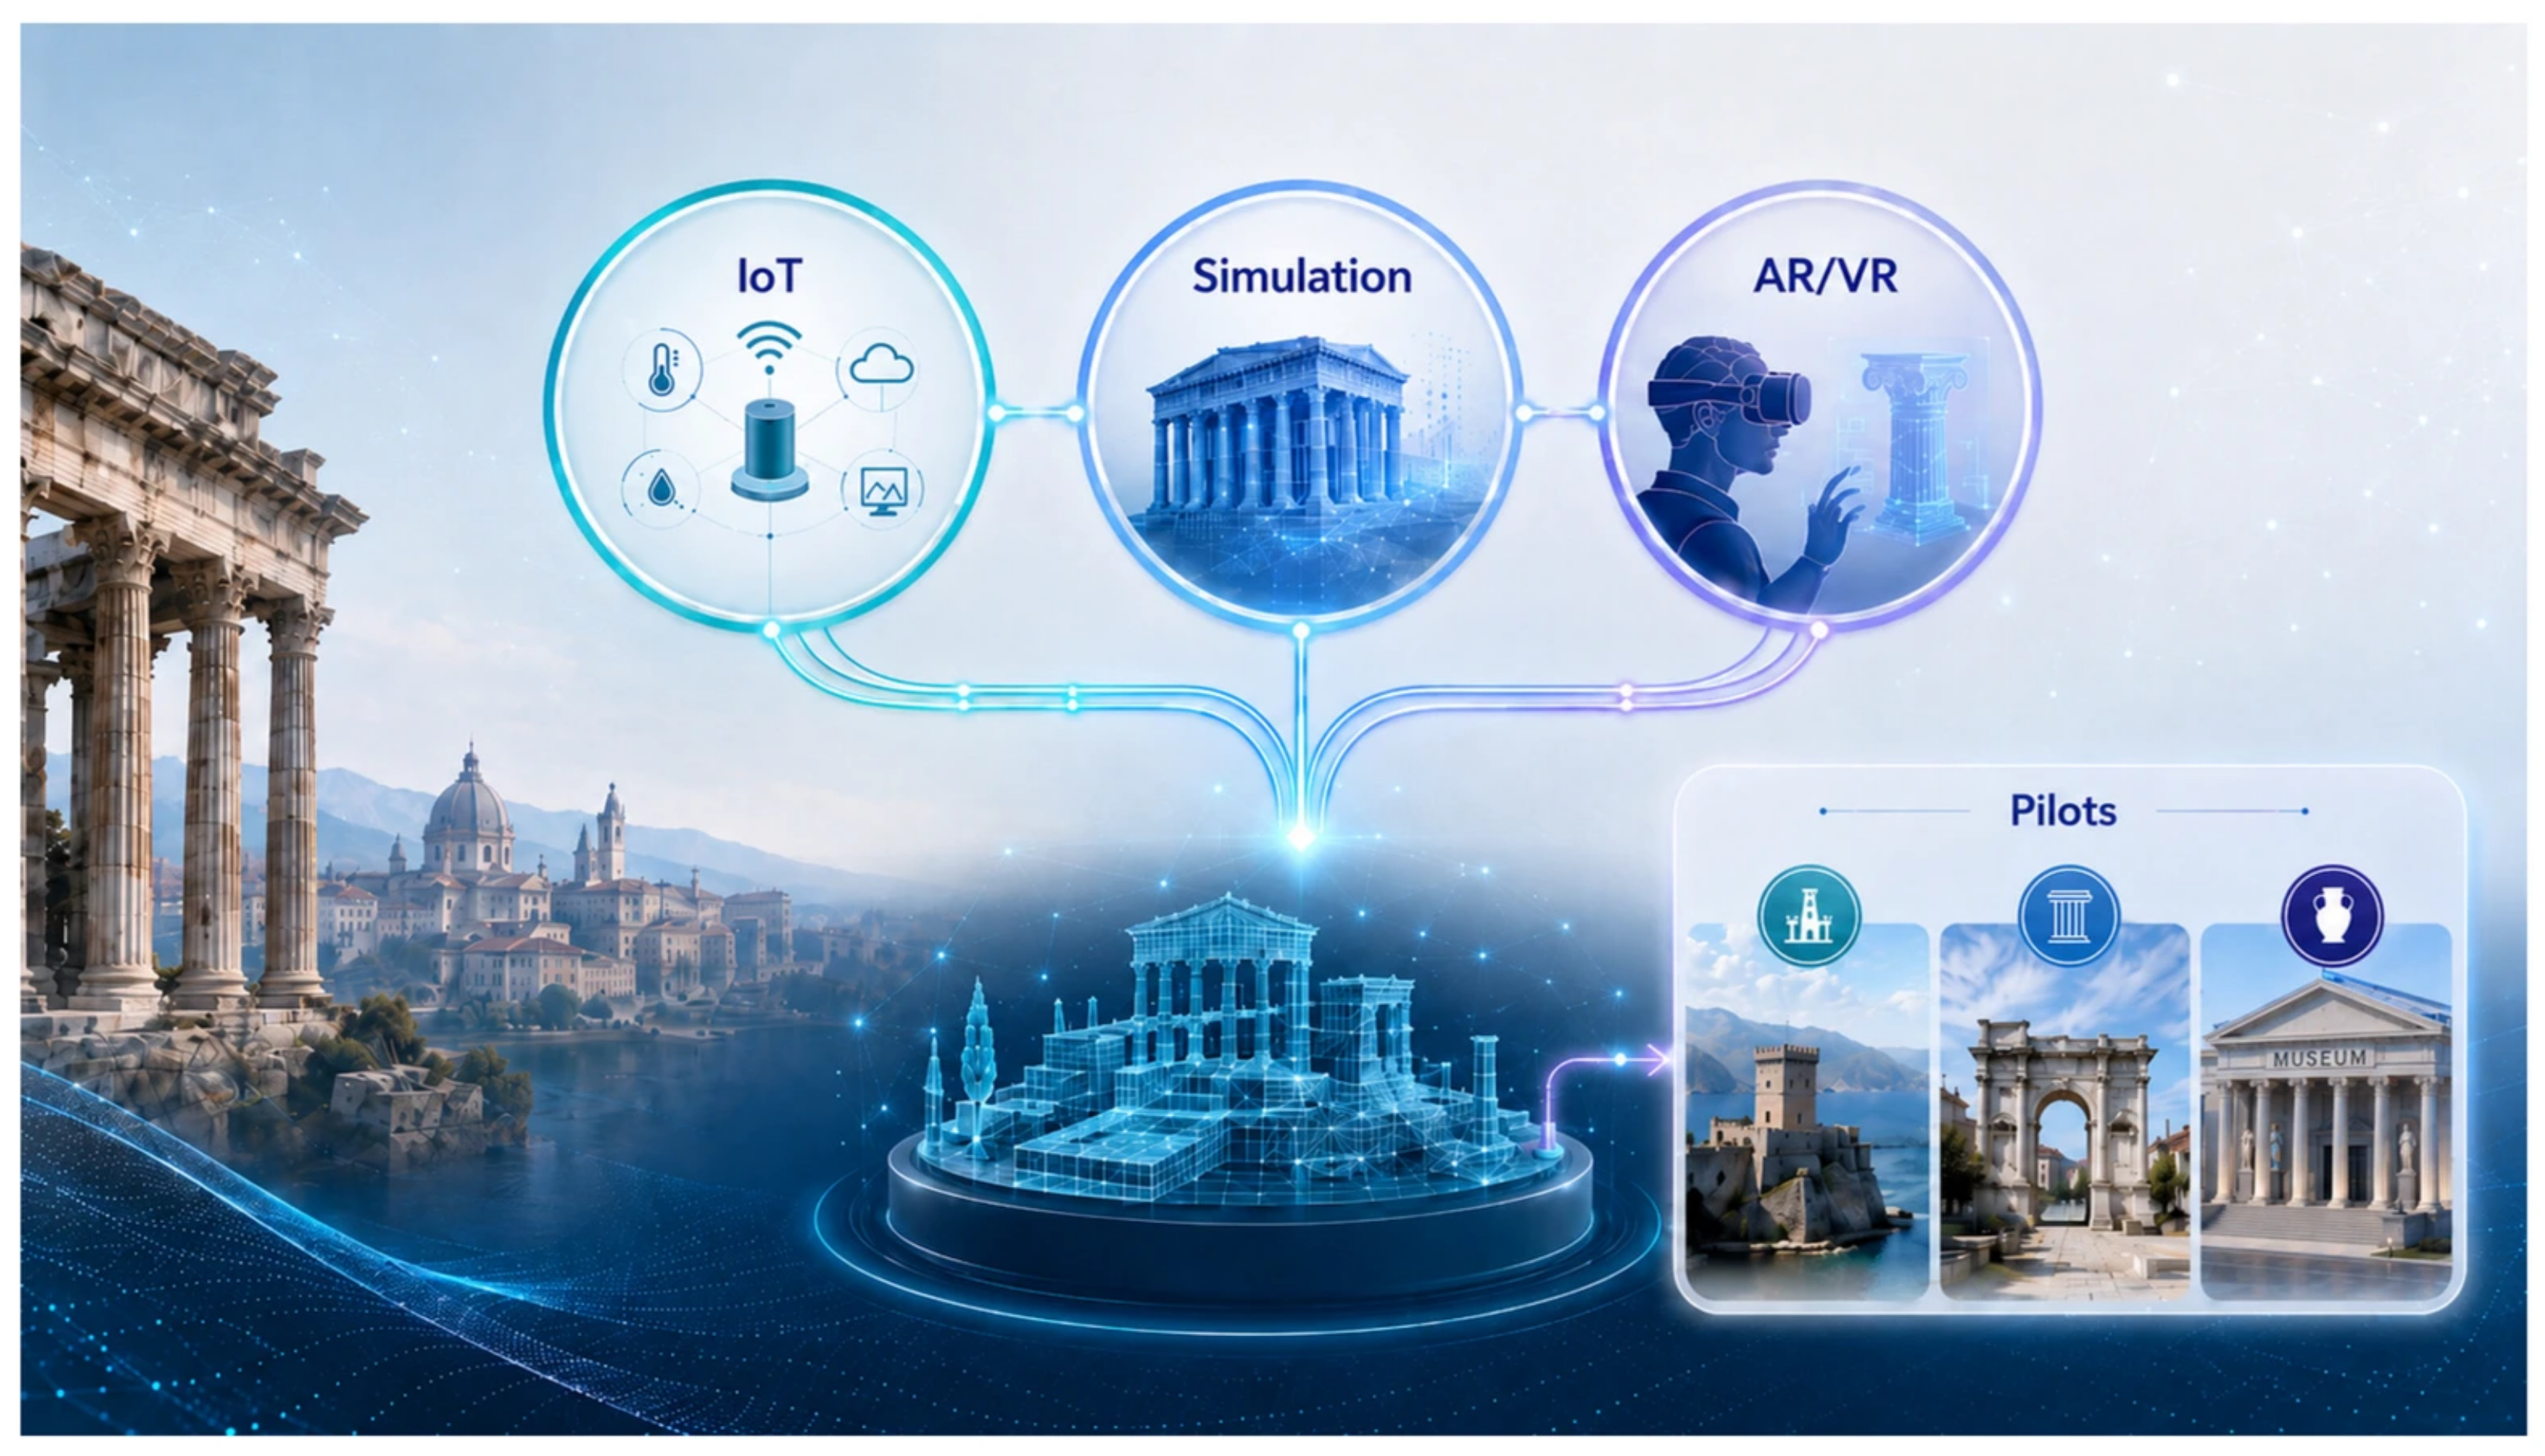
Among the ongoing projects addressing the complex relationship between physical heritage objects and Digital Twins [23] is ARTEMIS—Applying Reactive Twins to Enhance Monument Information Systems, funded by the European Union under the Horizon Europe Programme. At the center of the project is the concept of the Heritage Digital Twin [24], physical heritage objects at different scales (from small artefact to large monuments as real-life pilot studies) along with all the associated digital information (history and related documents, physical measurements and test results, 3D models, environmental data, and records) and the system that connects all of the information together, addressing conservation, restoration, safeguarding, and valorization. ARTEMIS leverages an extended digital documentation of heritage assets with 3D models incorporated into their Digital Twins, by implementing services on heritage data that model the behavior of the real-world assets in different conditions and under the effect of complex external phenomena. In this direction, the project is developing the Reactive Heritage Digital Twin to predict the consequences of real-life events via sensors and other information collected automatically from other systems or resulting from computer-modeled experiments to visualize the outcomes (Figure 1). A cloud-based digital infrastructure will enable the digital data from different sources to be connected together, creating and integrating the necessary tools and services for gathering data and performing experiments, as a research infrastructure integrated with other existing cultural heritage centers and initiatives.
Figure 1.
Outline of the rationale behind the ARTEMIS project for the development of the Reactive Heritage Digital Twin, from real-life data collected via sensors to computer-modeled simulations up to the outcome visualization (source artemis-twin.eu).
This brief overview of the State of the Art in heritage data management within different information systems shows research directions aimed at facing persistent (and increasing) needs and gaps, mainly relating to the descriptive capacity of digital environments and their actual usability for conservation purposes. The research experiences focused on in this paper arise from the following points, questions, and aims:
- Current digital surveying technologies provide massive data that often remain unused and unpurposed, as it is difficult to categorize them according to practical applications and to integrate them into HBIM models [25]. The aim of the research is to tend towards a methodological approach to be translated into operational workflows, enabling the identification of “how many” and which data are required for knowledge, understanding, management, enhancement, or conservation and which thematic documentations are required depending on the specific purpose of the digital representation process [7] (p. 18).
- Technology is changing all operational practices in the field of cultural heritage documentation and conservation, enabling increasingly complex data and information processing, so solutions that facilitate these processes—which does not mean simplify—should be pointed out [7,26].
- One of the key directions is integration, including technologies (by using different tools), data, and outcomes from specific geometrically based diagnostic analyses and information, which must be mapped, integrated, and located in a coherent 3D space, and to which metadata and paradata they can be linked.
- It is essential to ensure the data reliability, starting with a survey that must always have a specific purpose, adapting to specific requirements regarding precision, accuracy, consistency, the level of detail, and the type of representations or outcomes required, as well as the intended users [7] (pp. 20–21).
1.2. Research Objectives
Why is there a need to implement increasingly advanced digital technologies and information systems within the cultural heritage conservation field and to make use of AI applications supporting data processing? Why are digital data capturing and algorithms that aid required? If the goal is to “retain” and preserve heritage values and significances (tangible and intangible), time is needed (for understanding, surveying, documenting, and data processing). This is why AI and “intelligent” digital environments [27] will be more and more required and applied to address critical issues: with so much data available, strategies must be developed to make them useful and targeted, particularly for diagnostics. And since the use of AI tools is spreading so rapidly, it is essential to develop the skills needed to monitor and track the assumptions and results.
Focusing on the analyses of surface features, one of the current challenges is that information representation remains highly heterogeneous, with multiple approaches proposed for modeling materials, diagnostic data, deteriorations, and constructive techniques, each presenting different trade-offs between semantic consistency [14]. The methodology set out in the following section aims at developing the concept of adaptive data management, leveraging parametric modeling and applications within 3D point cloud data for the recognition of surface features for assessment and diagnostic purposes.
The paper is deliberately set out as a conceptual analysis of possible processes, rather than case-study-based work, in order to highlight critical methodological issues in combining the state of conservation and material features within a 3D environment able to make this information retrievable and useful for the assessment and conservation of existing and cultural heritage.
The main research questions that the paper aims to face are as follows:
- How to combine the point cloud segmentation and the parametric modeling in the HBIM environment for a direct comparison, avoiding an assumption of the survey and the HBIM representation as separate steps.
- How to bring the surveyed data at the forefront of interpretative processes by keeping captured information concerning architectural surfaces as the main reference for critical assessment.
- How to strengthen the reconciliation of information between the point cloud processed through AI algorithms and the HBIM model through the reversed approach of the HBIM-to-Cloud.
- How to generate an enriched information cloud defined by the surfaces of the parametric model.
The main objectives of the paper can be summarized as follows:
- To experiment with different approaches to generating point clouds based on the surfaces of BIM models by extracting parameters and information from the objects that make up the parametric surfaces.
- To test the materialization of points on selected surfaces or from individual points in order to obtain a point cloud including data on materials and surface features derived from parametric modeling.
2. Materials and Methods
The research started focusing on the degree of queryability—the ability to create new connections and make data and information operational and actionable. The model should act as an interpretative framework, capable of systematizing relationships between data and information [28] (p. 31).
The research carried out by the author in various heritage contexts and as part of regional, national, international, and European projects [29] is geared towards this aim. In particular, some results of the ongoing project AIM-eBIM—Adapted Information, Management for existing Buildings Information Modeling (funded by the Emilia-Romagna Region under the PR-FESR 2021–2027 Programme)—are discussed, focusing on the concept of adaptive population in parametric models, starting from surveyed data segmentation and connection within the parametric environment.
The experiments described in this paper were performed on two buildings from different historical periods and contexts, allowing a range of materials, construction techniques, and markedly different conservation conditions to be investigated.
- The first case study is the former Monastery of St Agostino in Verucchio, Rimini (Italy), a recently restored medieval complex characterized by a stratigraphic palimpsest of heterogeneous materials, particularly brick and stone masonry, but exhibiting no significant deterioration.
- By contrast, the second case study is the former Colonia Varese in Milano Marittima, Cervia, Ravenna (Italy), an early twentieth-century reinforced-concrete building affected by several forms of deterioration, primarily associated with vegetation growth and moisture, as a result of its prolonged abandonment and a coastal location.
- For both the case studies, the laser-scanner point clouds were registered using targets whose coordinates were determined also through a topographic control network, resulting in the registration errors of less than 5 mm. The point clouds generated through digital photogrammetry showed mean deviations of approximately 1 cm from the laser-scanner data. Both datasets were therefore considered sufficiently accurate for the subsequent analyses and modeling tasks.
These case studies enabled the analysis of a diverse range of surface features. Nevertheless, future experiments should include a larger number of cases to broaden the range of conditions investigated and improve the robustness of the results. Both buildings were surveyed using terrestrial laser scanning and aerial photogrammetry.
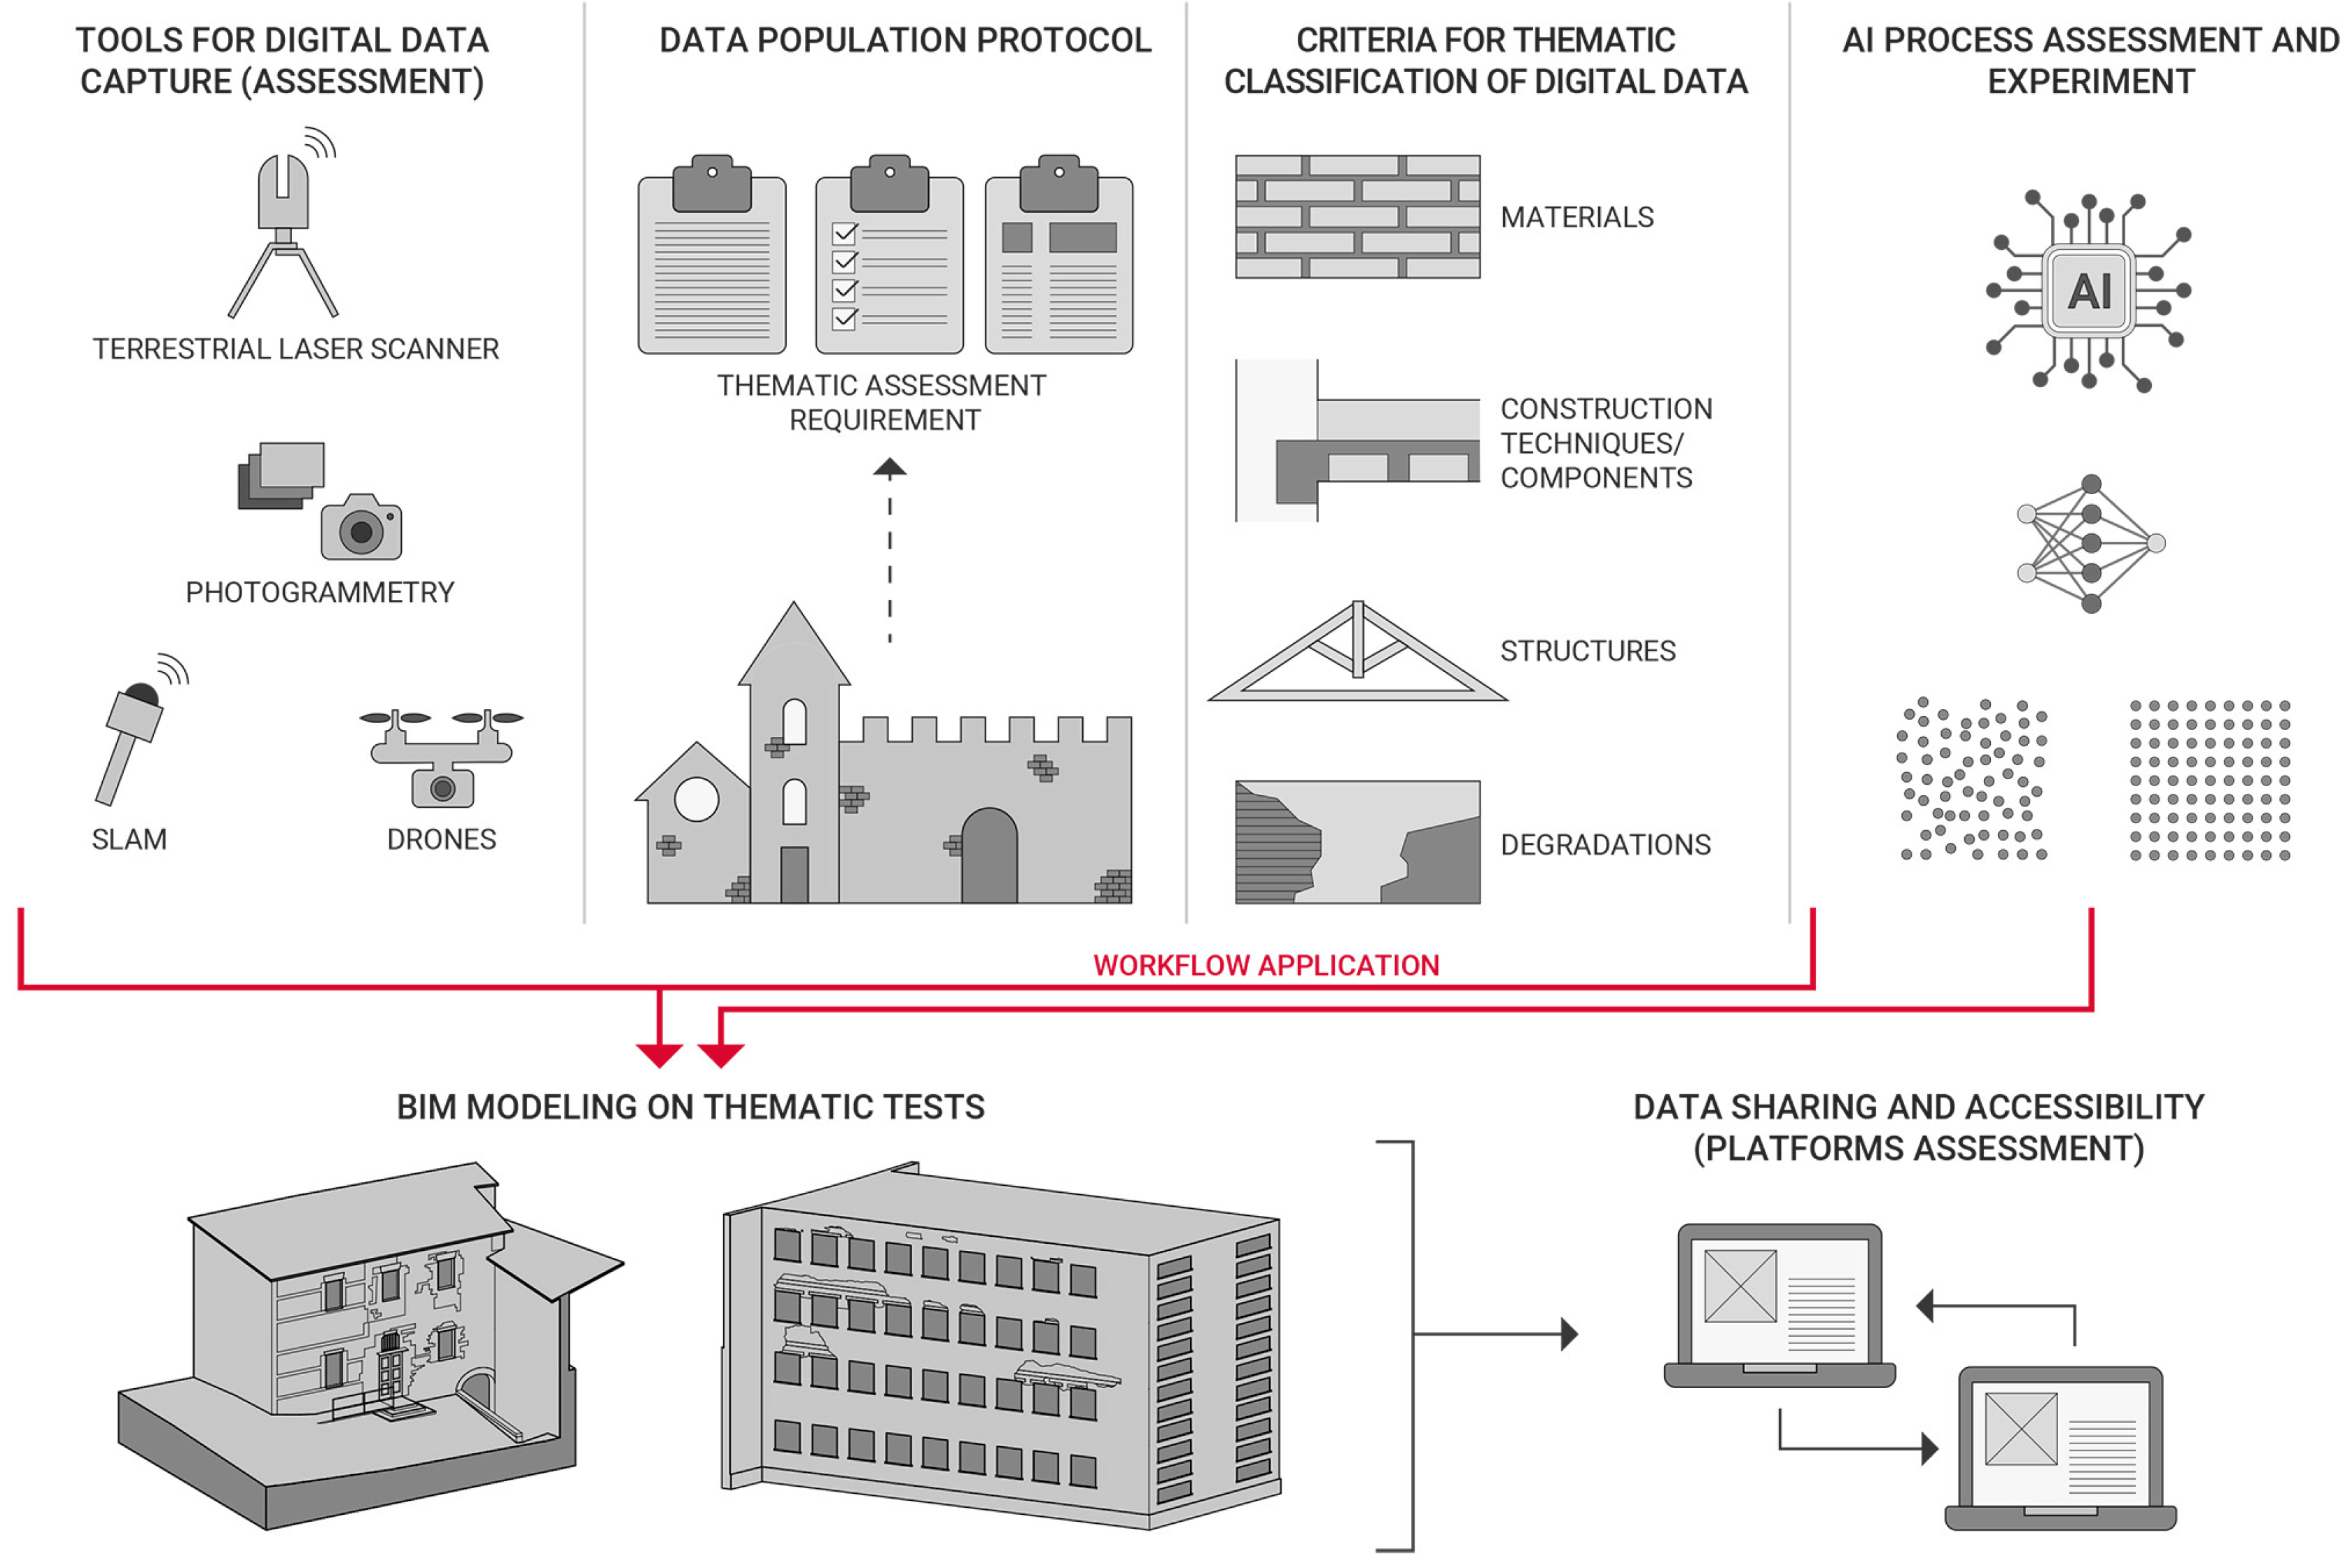
The initial implementation phases focused on two essentially separate procedures: on the one hand, the processing of data obtained from integrated digital surveying (laser scanning and photogrammetry) using AI methods, and specifically Supervised ML to train the algorithm on a case-by-case basis to recognize surface features (materials, construction techniques, and state of conservation); on the other, the application of the Scan-to-BIM process to obtain the geometries of the surveyed historical–architectural contexts onto which the results of the algorithmic classification are grafted (Figure 2).
Figure 2.
Methodological workflow conceptualizing adaptive population in parametric modeling.
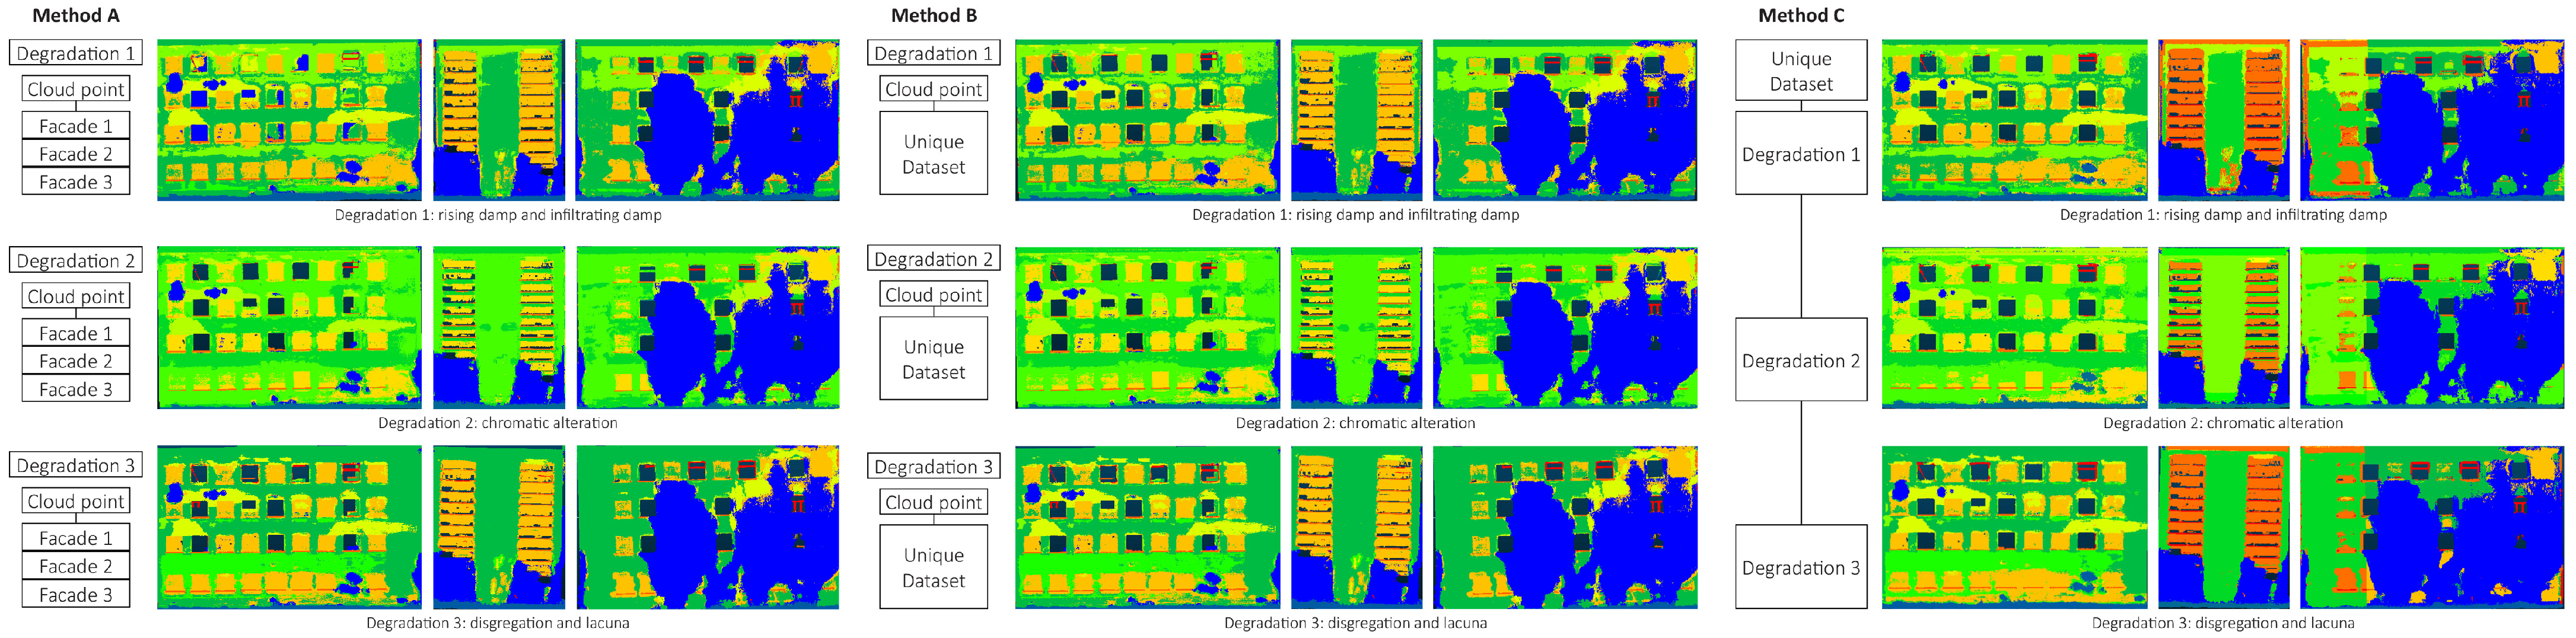
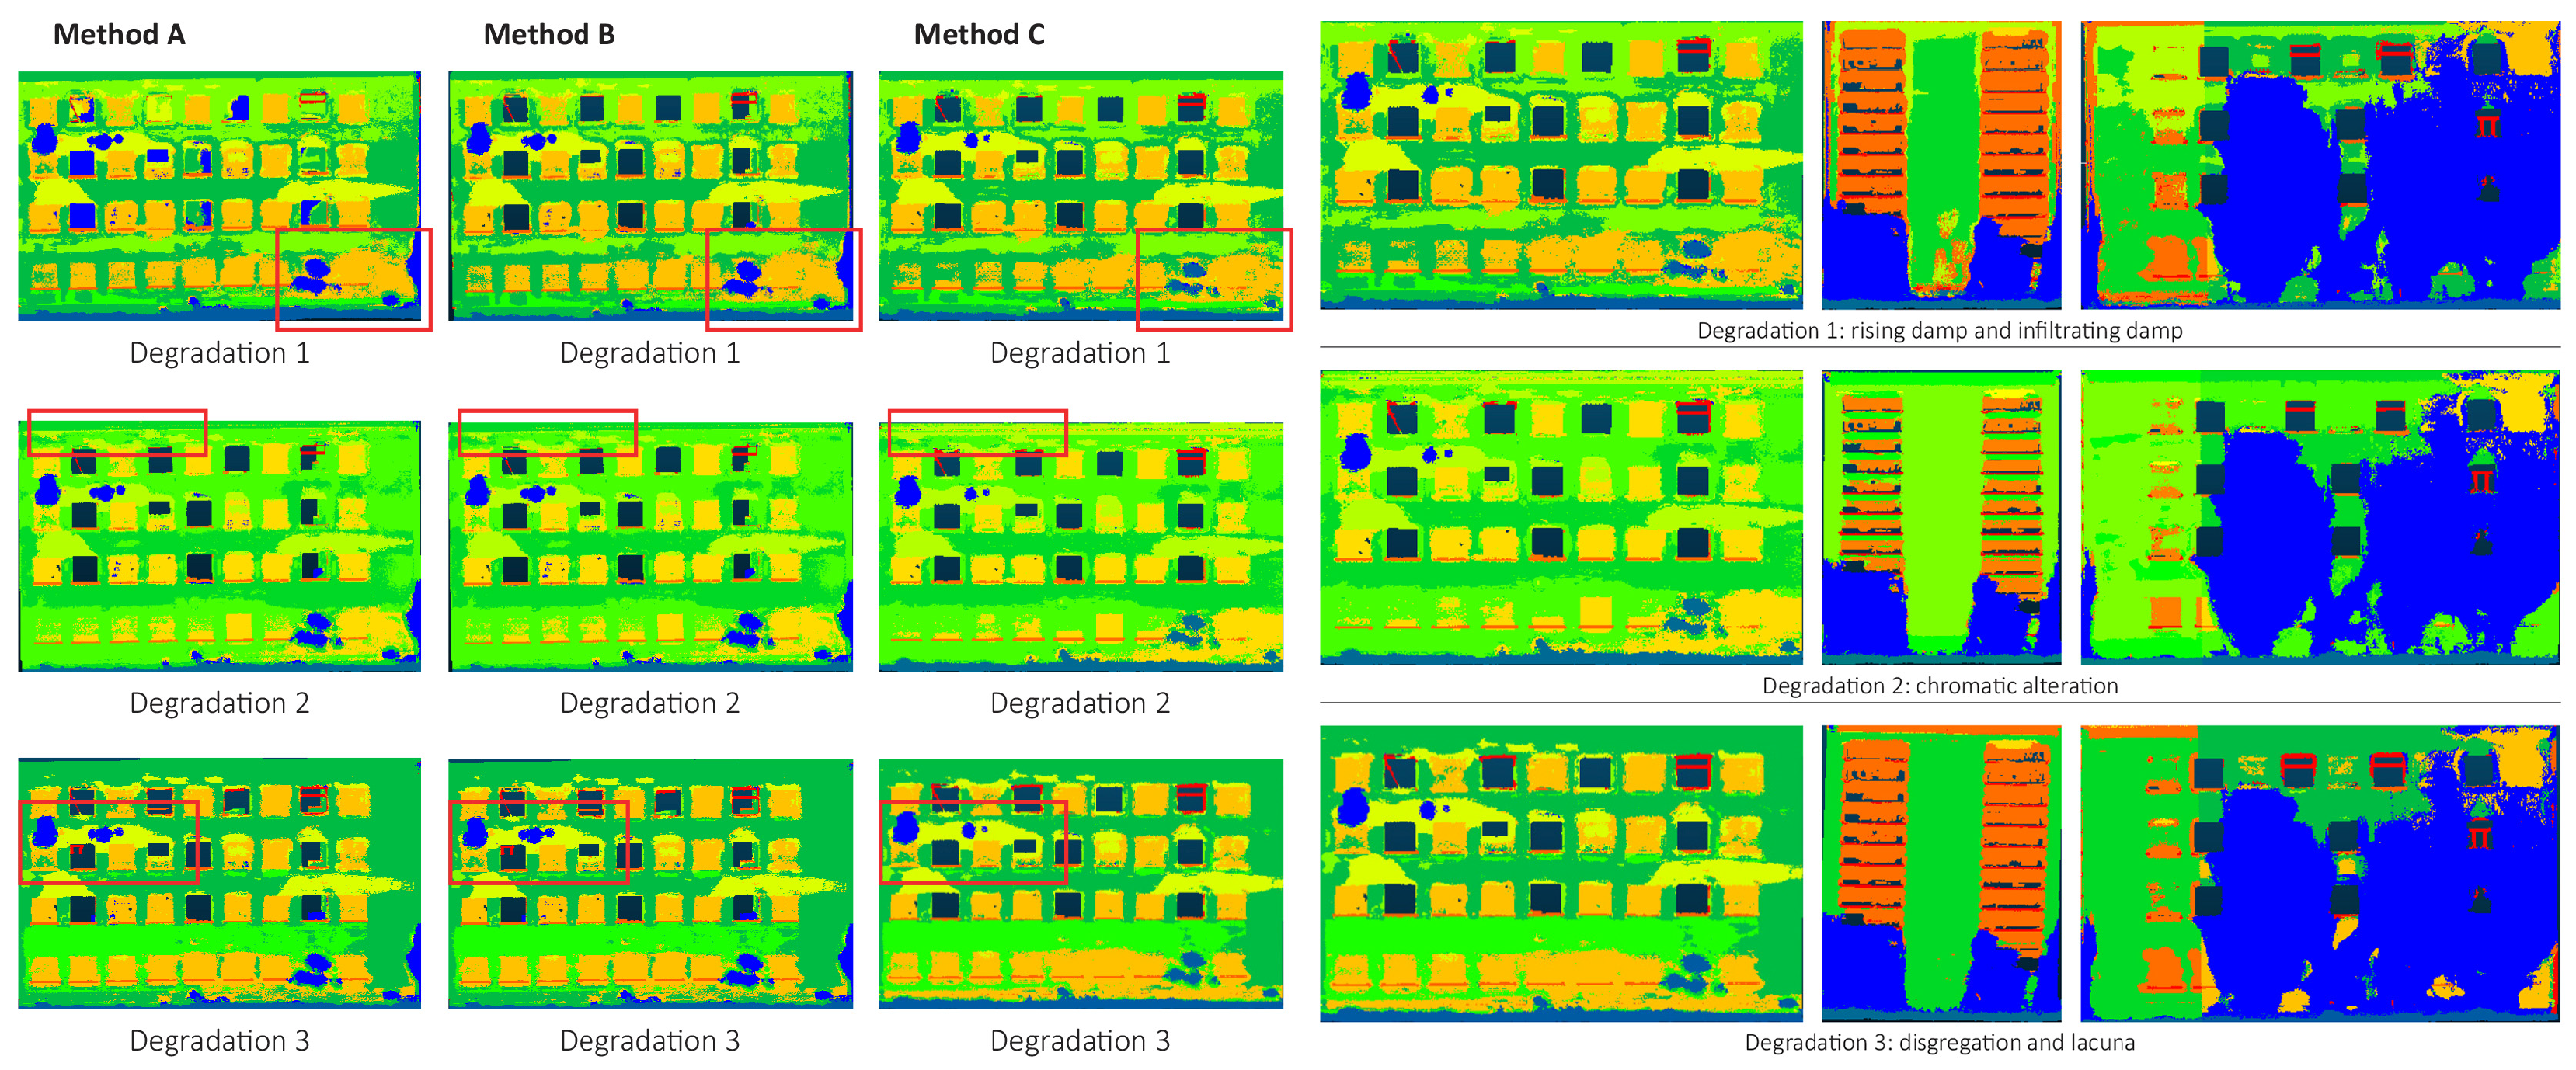
With regard to segmentation and classification procedures, to identify materials and construction techniques, classification algorithms were applied to laser scanning point clouds, following the approach described in [30], through the identification of the target categories, feature extraction, manual annotation, train, test, validation, and the prediction of the classified cloud. Algorithms tested were Random Forest, KNN, GradientBoosting, and eXtreme Gradient Boosting, identifying Random Forest as the best model, according to evaluation metrics, particularly showing a higher F1-score (Figure 3 and Figure 4).
Figure 3.
Overview of three different tests for decay segmentation. Method (A) includes three training datasets, each with a corresponding unannotated dataset to allow for more detailed information management; Method (B) uses the same training datasets, but applying a single unannotated dataset for each façade, which includes both areas already manually annotated and those without a classification; Method (C) is based on a single dataset, with three distinct scalar fields, each corresponding to a different group of deterioration. During the training and testing phases, unclassified areas are excluded, whilst in the prediction phase, classes are assigned progressively.
Figure 4.
On the left, a comparison between the three methods shows that Method (A) and Method (B) tend to preserve information relating to vegetation and architectural structures more effectively, whilst Method (C) has some limitations in distinguishing between similar classes, leading to classification errors in specific areas of the building. On the right, visualizations of the simultaneous prediction of different decays are shown.
The dataset used for material recognition testing is the 3D point cloud of the Verucchio Museum, in which each point is described by 64 features, including spatial coordinates (X, Y, Z), RGB values, and geometric characteristics calculated at three different radii (r = 0.05, r = 0.3, r = 1), which allow details to be extrapolated at different scales.
The dataset used to train the model is a subset of the original one containing an additional variable called ‘Materials’, which indicates the material class associated with each point. There are 15 material classes, representing the various components of the building.
To assess the quality of the predictions, initial tests were carried out using all available features. Then, an alternative configuration was tested by keeping dimensions and geometric features. This approach allowed for a more detailed analysis of the influence of spatial position on the model’s performance.
As an initial step, the annotated dataset was subjected to a correlation matrix analysis to identify any relationships between the features and assess the presence of multicollinearity, which could influence the model’s predictions.
Any null or outlier values were also identified and handled, thereby ensuring the quality of the input data. The dataset was then split into a training set and a test set: the former was used to train the models, whilst the latter was used to evaluate their performance.
A comparative analysis of the Machine Learning models tested (Table 1) for predicting the geometric characteristics of buildings has yielded the following results:
Table 1.
Comparative analysis of Machine Learning models tested.
For the purposes of the testing and based on the initial dataset, Random Forest proved to be an extremely reliable model, with very high accuracy (99.79 per cent) and solid performance across all the metrics evaluated. It proved particularly effective at handling complex datasets, offering a good balance between accuracy and training time. For this reason, it was selected to make predictions on the unlabeled datasets.
A phase was then initiated to optimize the Random Forest parameters (Table 2) in order to identify the configuration that would deliver the best performance in terms of accuracy and generalization.
Table 2.
Machine Learning model fine-tuning.
The parameters at which the best performance was achieved enabled an accuracy of 99.82%.
The analysis of the state of conservation required a more structured approach, due to the overlap of different types of deterioration [31], by applying the methodology described in [32]. The simultaneous presence of multiple forms of decay required a more comprehensive method, including algorithmic image classification. Within these experimentations, also the Intensity Value has been included as additional data to be processed by algorithm procedures, evaluating its incidence in surface feature recognition through feature importance metrics [33]. As previous research demonstrates [34], intensity can make some material features explicit, but it is also affected by several other factors, such as geometric characteristics (angle of incidence), the sensor type, and boundary conditions [35].
As part of the Scan-to-BIM process, a preliminary assessment was carried out regarding the resolution strategies capable of handling information on materials, construction techniques, and states of conservation obtained through AI processes, to be grafted into the parametric model developed starting from digitally surveyed data. The aim was to integrate point cloud geometric and radiometric data with information related to surface specifications, through a Scan-to-BIM approach. To do this, different approaches were tested.
The initial strategies, within the BIM environment used, i.e., Autodesk Revit, focused on managing material information through geometric modeling, exploring representations based on the breakdown of objects and surface subdivisions. In the object-based breakdown, the level of complexity that can be achieved became immediately apparent; however, the representation time was longer, and potential errors at the connections between the subdivided geometries had too significant impacts. Subdividing the surfaces of the reference object reduced representation times and made it possible to define fairly complex areas; however, these lacked assignable information.
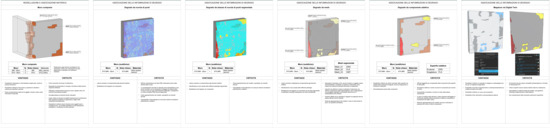
On the basis of these tests, it was decided to make a clear distinction between the information object and the information surface, using the advanced modeling of architectural objects broken down into the core (internal structures) and finishes, or at least to the extent of reconstructing the knowledge framework of the individual element. In this way, each element corresponds to a single reference material—which may be composite—that is appropriately coded. Cladding elements (such as plaster) are therefore volumetric and can be defined separately from the reference object (the wall). Surface subdivisions at the material level are retained only to provide a clearer distinction between composite materials (such as a wall of stone and brick with the brickwork aggregates outlined). The information relating to the state of conservation has been revised following further testing (Figure 5).
Figure 5.
From left to right, samples of modeling tests with the association of materials and states of conservation information, considering composite and subdivided walls; degradation analysis based on point clouds and point cloud images; degradation analysis based on segmented point cloud instances; degradation analysis based on meshes; degradation analysis based on adaptive components; and mapping via Digital Twin. For each test, the advantages and critical issues were analyzed.
Initially, the assessment of degradation was carried out by superimposing the 3D model directly onto the point cloud calibrated using the Intensity Value color ranges. However, this approach is not easy to read or interpret; this situation is improved by superimposing the RGB data using raster images. Nevertheless, working with images precludes the possibility of integrating additional information, as well as potentially introducing scaling errors in the metric conversion of pixels based on the resolution used (an issue that can have a negative impact on file size and model navigation).
The afterward step therefore involved an overlaid view of the point cloud segmented by the Intensity Value, so as to be able to interact independently with the various classifications. Again, it is not possible to incorporate additional information into the point cloud, but it is possible to generate mesh surfaces derived from it. By doing so, through appropriate conversion and import into the BIM software, it is possible to assign a set of tailored parameters. However, this solution presents a number of limitations, ranging from the file size to the need to redefine the surfaces for greater accuracy compared with the reference model (partly because the point cloud segmentation does not take into account the geometric adjustments made in the geometric parametric representation). Similarly, the use of adaptive surfaces—which are able to match to the surfaces of the model but are based on perimeters derived from meshes—presents significant similar issues, namely an increased file size and a predefined, non-scalable number of vertices.
Given the significant challenges involved in managing cloud-based data—attributed to degradation conditions via ranges of Intensity Values for material surfaces—it was decided to explore an alternative, parallel approach: the simulation of the use of meshes on Digital Twin platforms, as a prototype for the semantic exchange of information between the HBIM and point cloud representations. In this scenario, the BIM is integrated by loading a model composed of surfaces derived from the segmented point cloud, where each mesh can be digitized both semantically—using a purpose-defined classification—and through specific parameters. The only limitation of this solution is that the geometries cannot be edited directly; it is restricted to the informative filling in. However, this condition is consistent with the concept of a maintenance-oriented approach and can therefore be updated over time through subsequent uploads and informatization.
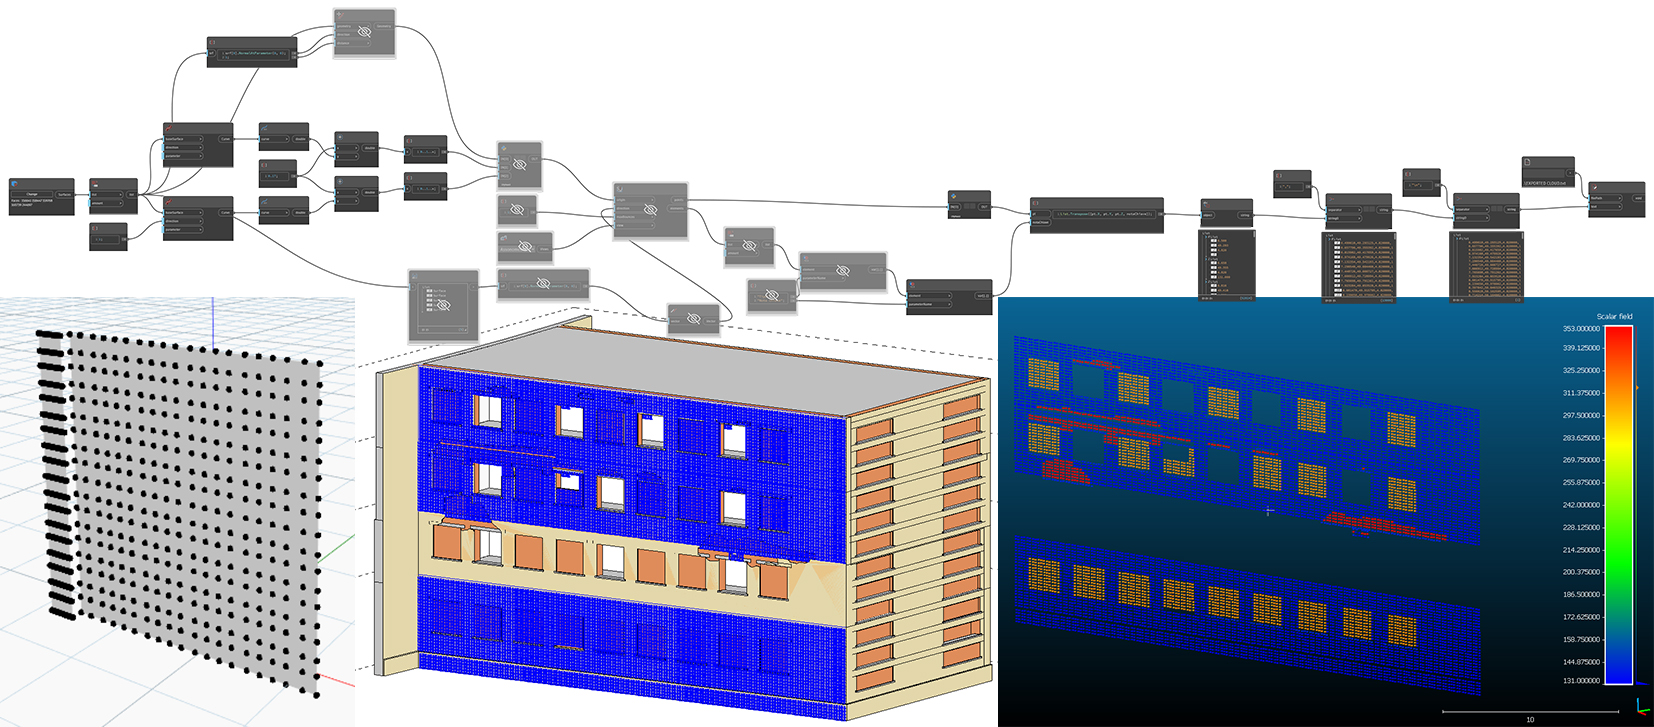
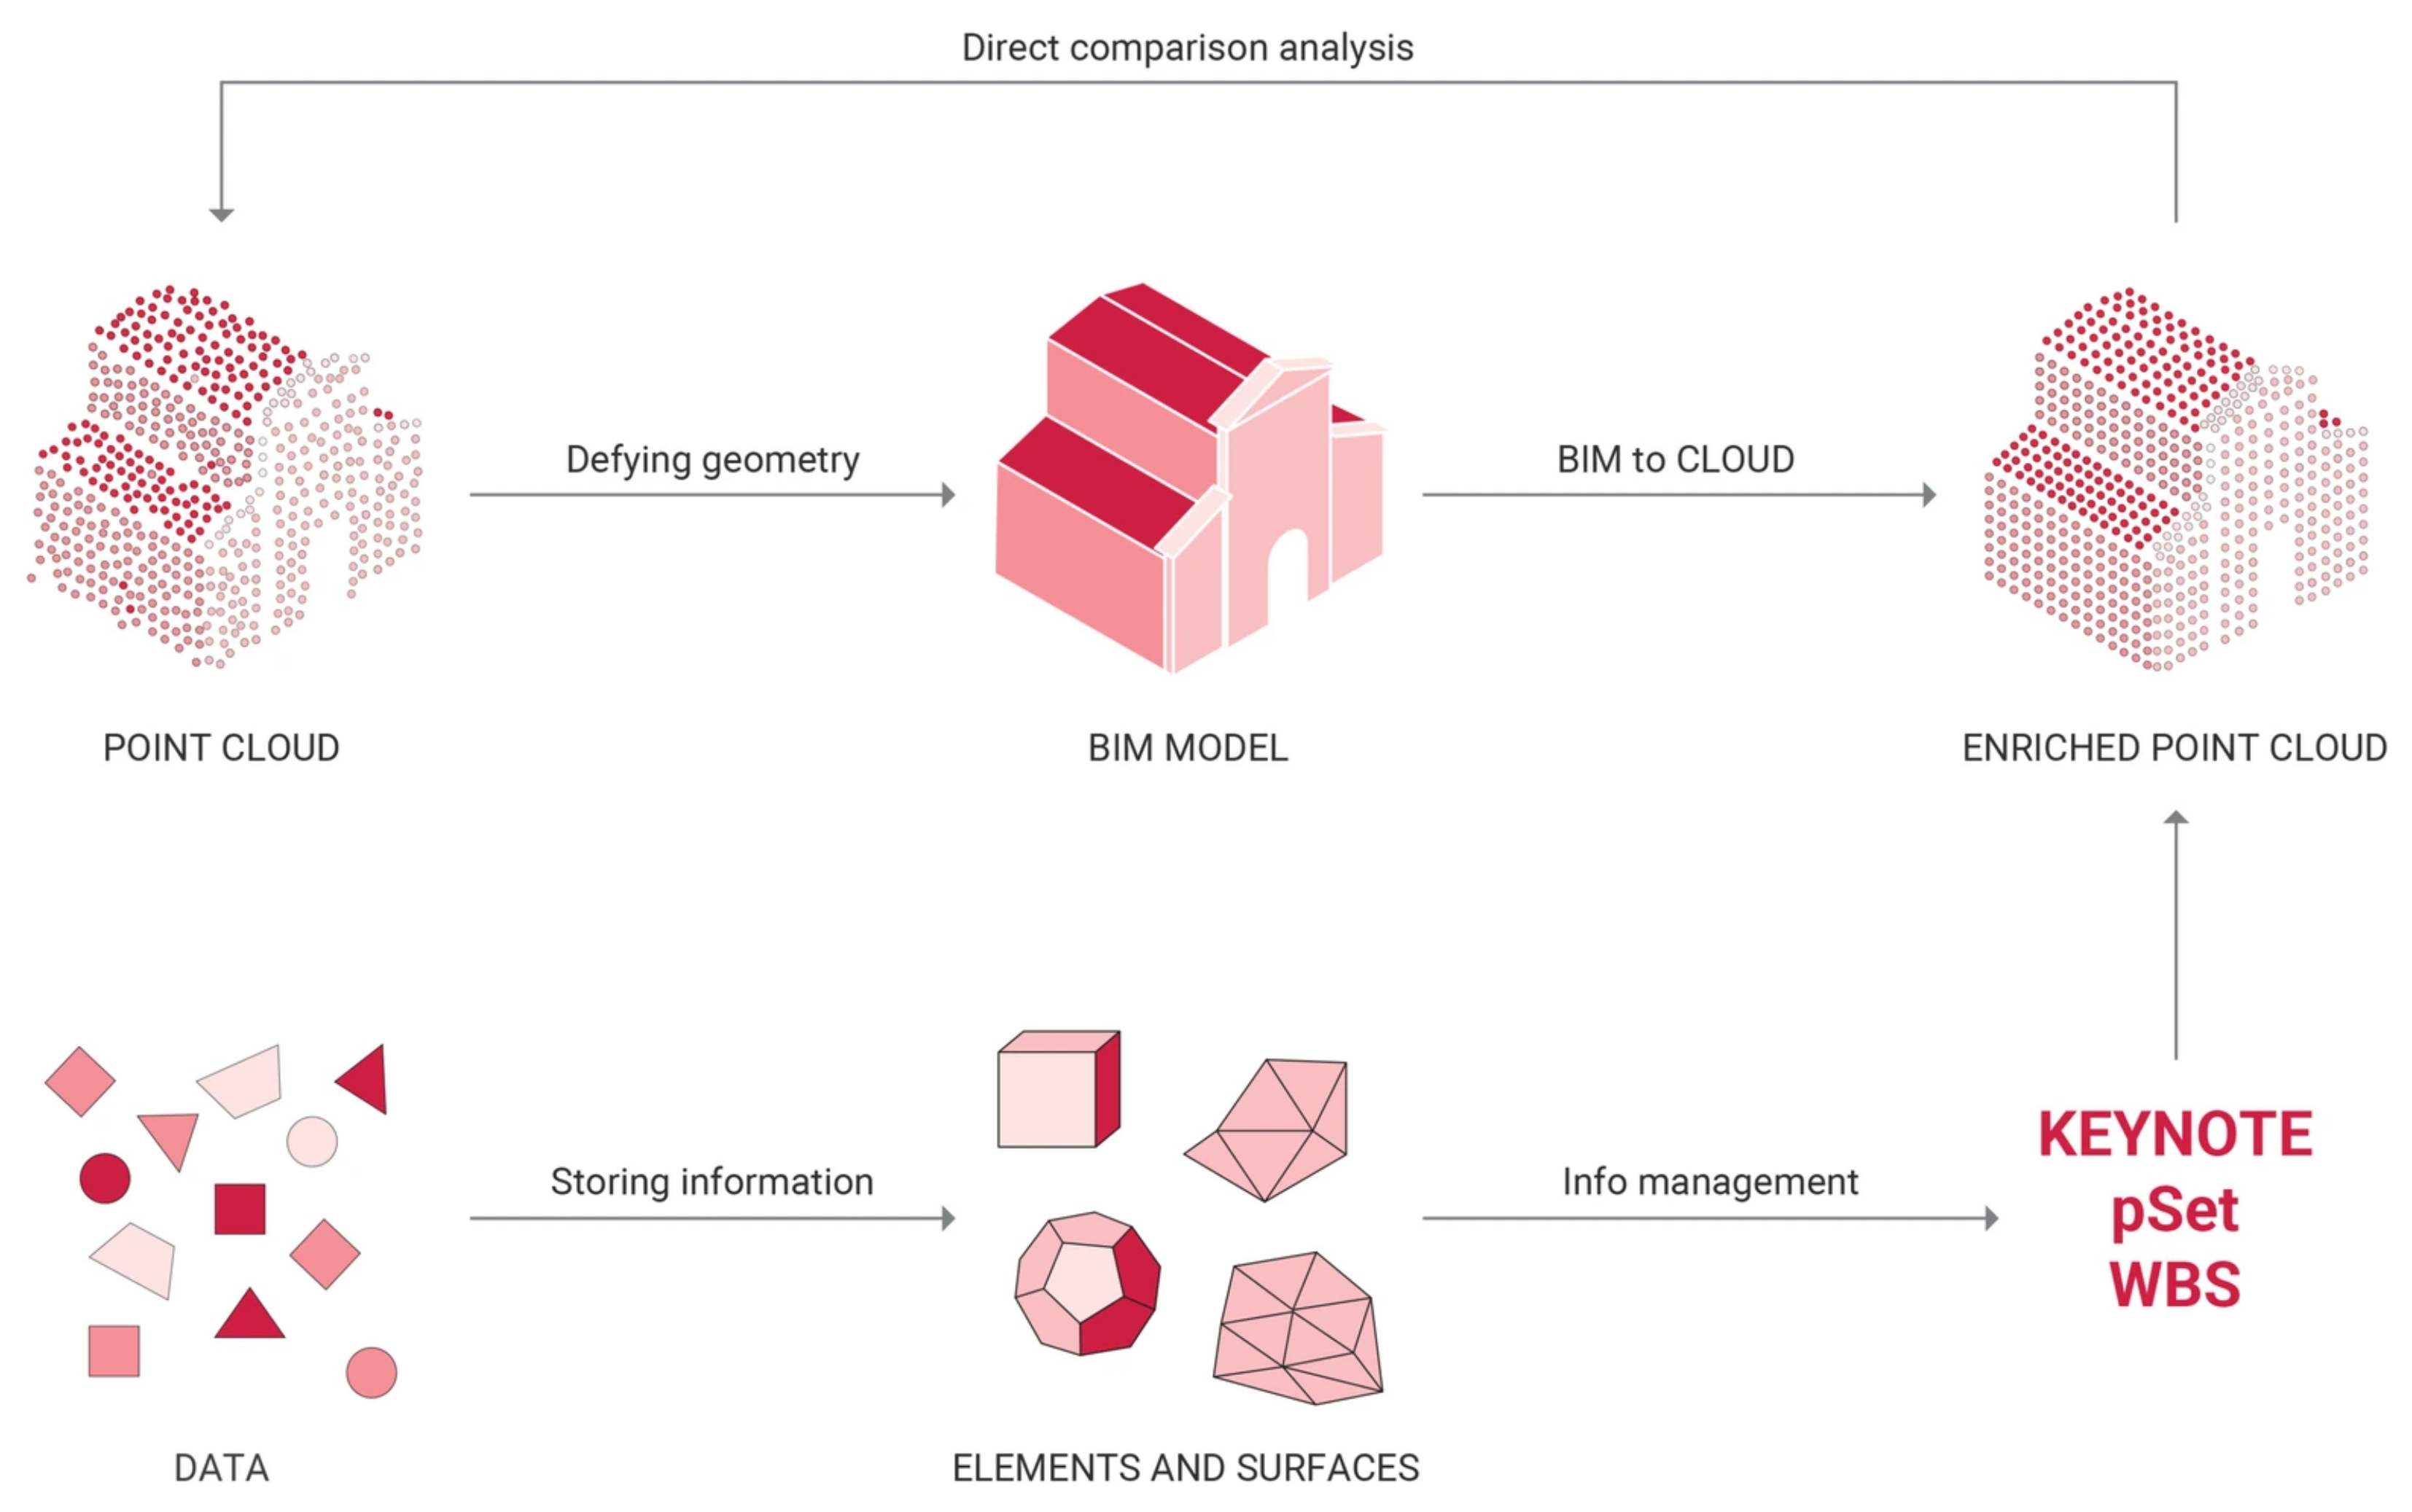
A reverse approach was therefore tested—the “HBIM-to-Cloud”—with the aim of generating an enriched information cloud defined by the surfaces of the parametric model (Figure 6).
Figure 6.
Application of the algorithm for generating points based on the surfaces of the BIM model.
The process involves selecting the surfaces to be analyzed and generating points, arranged on a regular grid, to which information are assigned relating not only to their coordinates but also to the different “Property Sets” (pSets) defined within the model (for instance, relating to material information) (Figure 7).
Figure 7.
Flowchart of the process of returning geometries from the point cloud and breaking down surfaces into enriched points with materials and more data per point.
The grid spacing can be determined using various criteria, primarily the purpose and scale of the analysis. At this initial stage of the experiment, a fairly large value (5 cm) was chosen in order to test the feasibility of the entire process. To study the behavior in greater detail and identify finer features, the grid spacing should be reduced.
The result is an information-rich point cloud that not only facilitates segmentation operations—leveraging the critical approach already used in the model representation—but also allows the data to be interpolated with the cloud of measured data, enabling, for example, the observation of variations in Intensity Value data across defined material areas.
3. Results
A complex reality, to be deeply understood and analyzed, must be divided up, schematized, organized, and translated into a structure through which it can be described and interpreted. To achieve this purpose, data (that can now be obtained rapidly and on a massive scale) should be critically and thoughtfully selected, by focusing on the descriptive capacity of the digital model, to be used as an analytical tool that generates new knowledge.
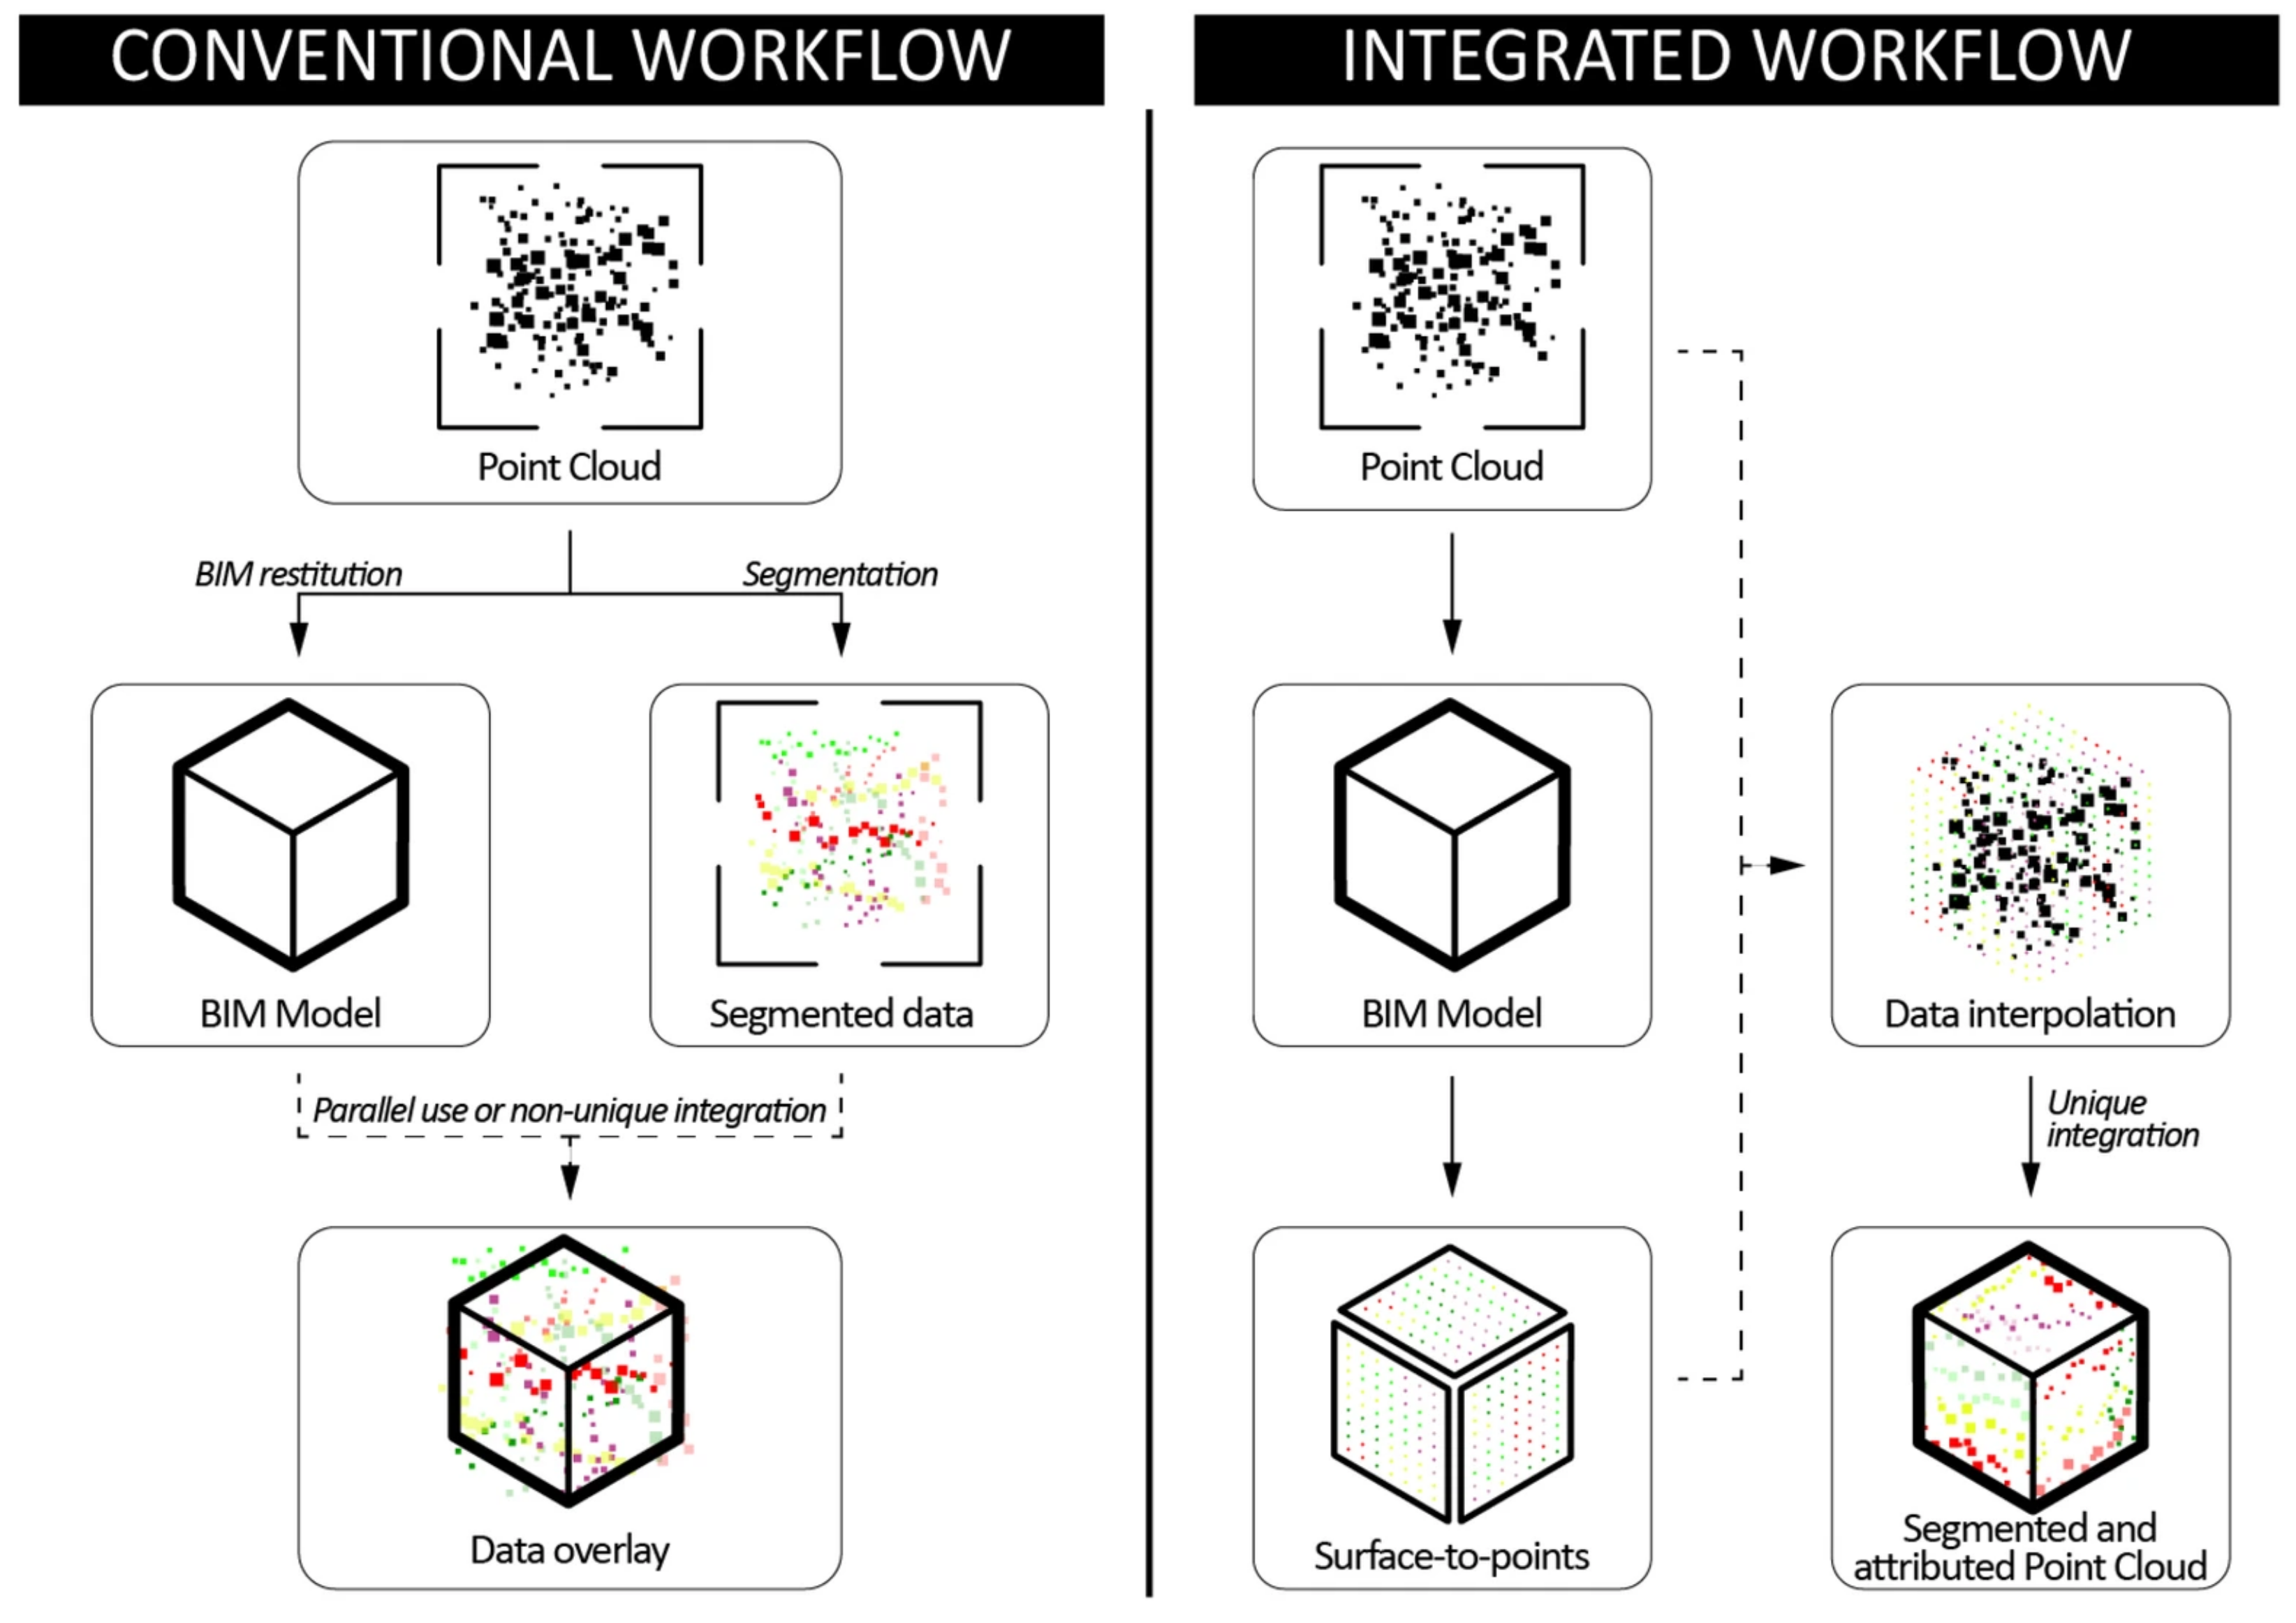
The results obtained from the presented preliminary experimentations stem from a reversal of the approach usually taken when creating parametric information models based on digital survey data. The workflow usually applied involves the generation of the parametric model and the segmentation of the point cloud as parallel processes. The source data from 3D surveying—whether it be a point cloud from laser scanning or photogrammetric surveying—is processed in the Scan-to-BIM workflow to obtain the geometries in a parametric environment and forms the basis for the algorithmic processing of feature extraction, annotation, training, and prediction.
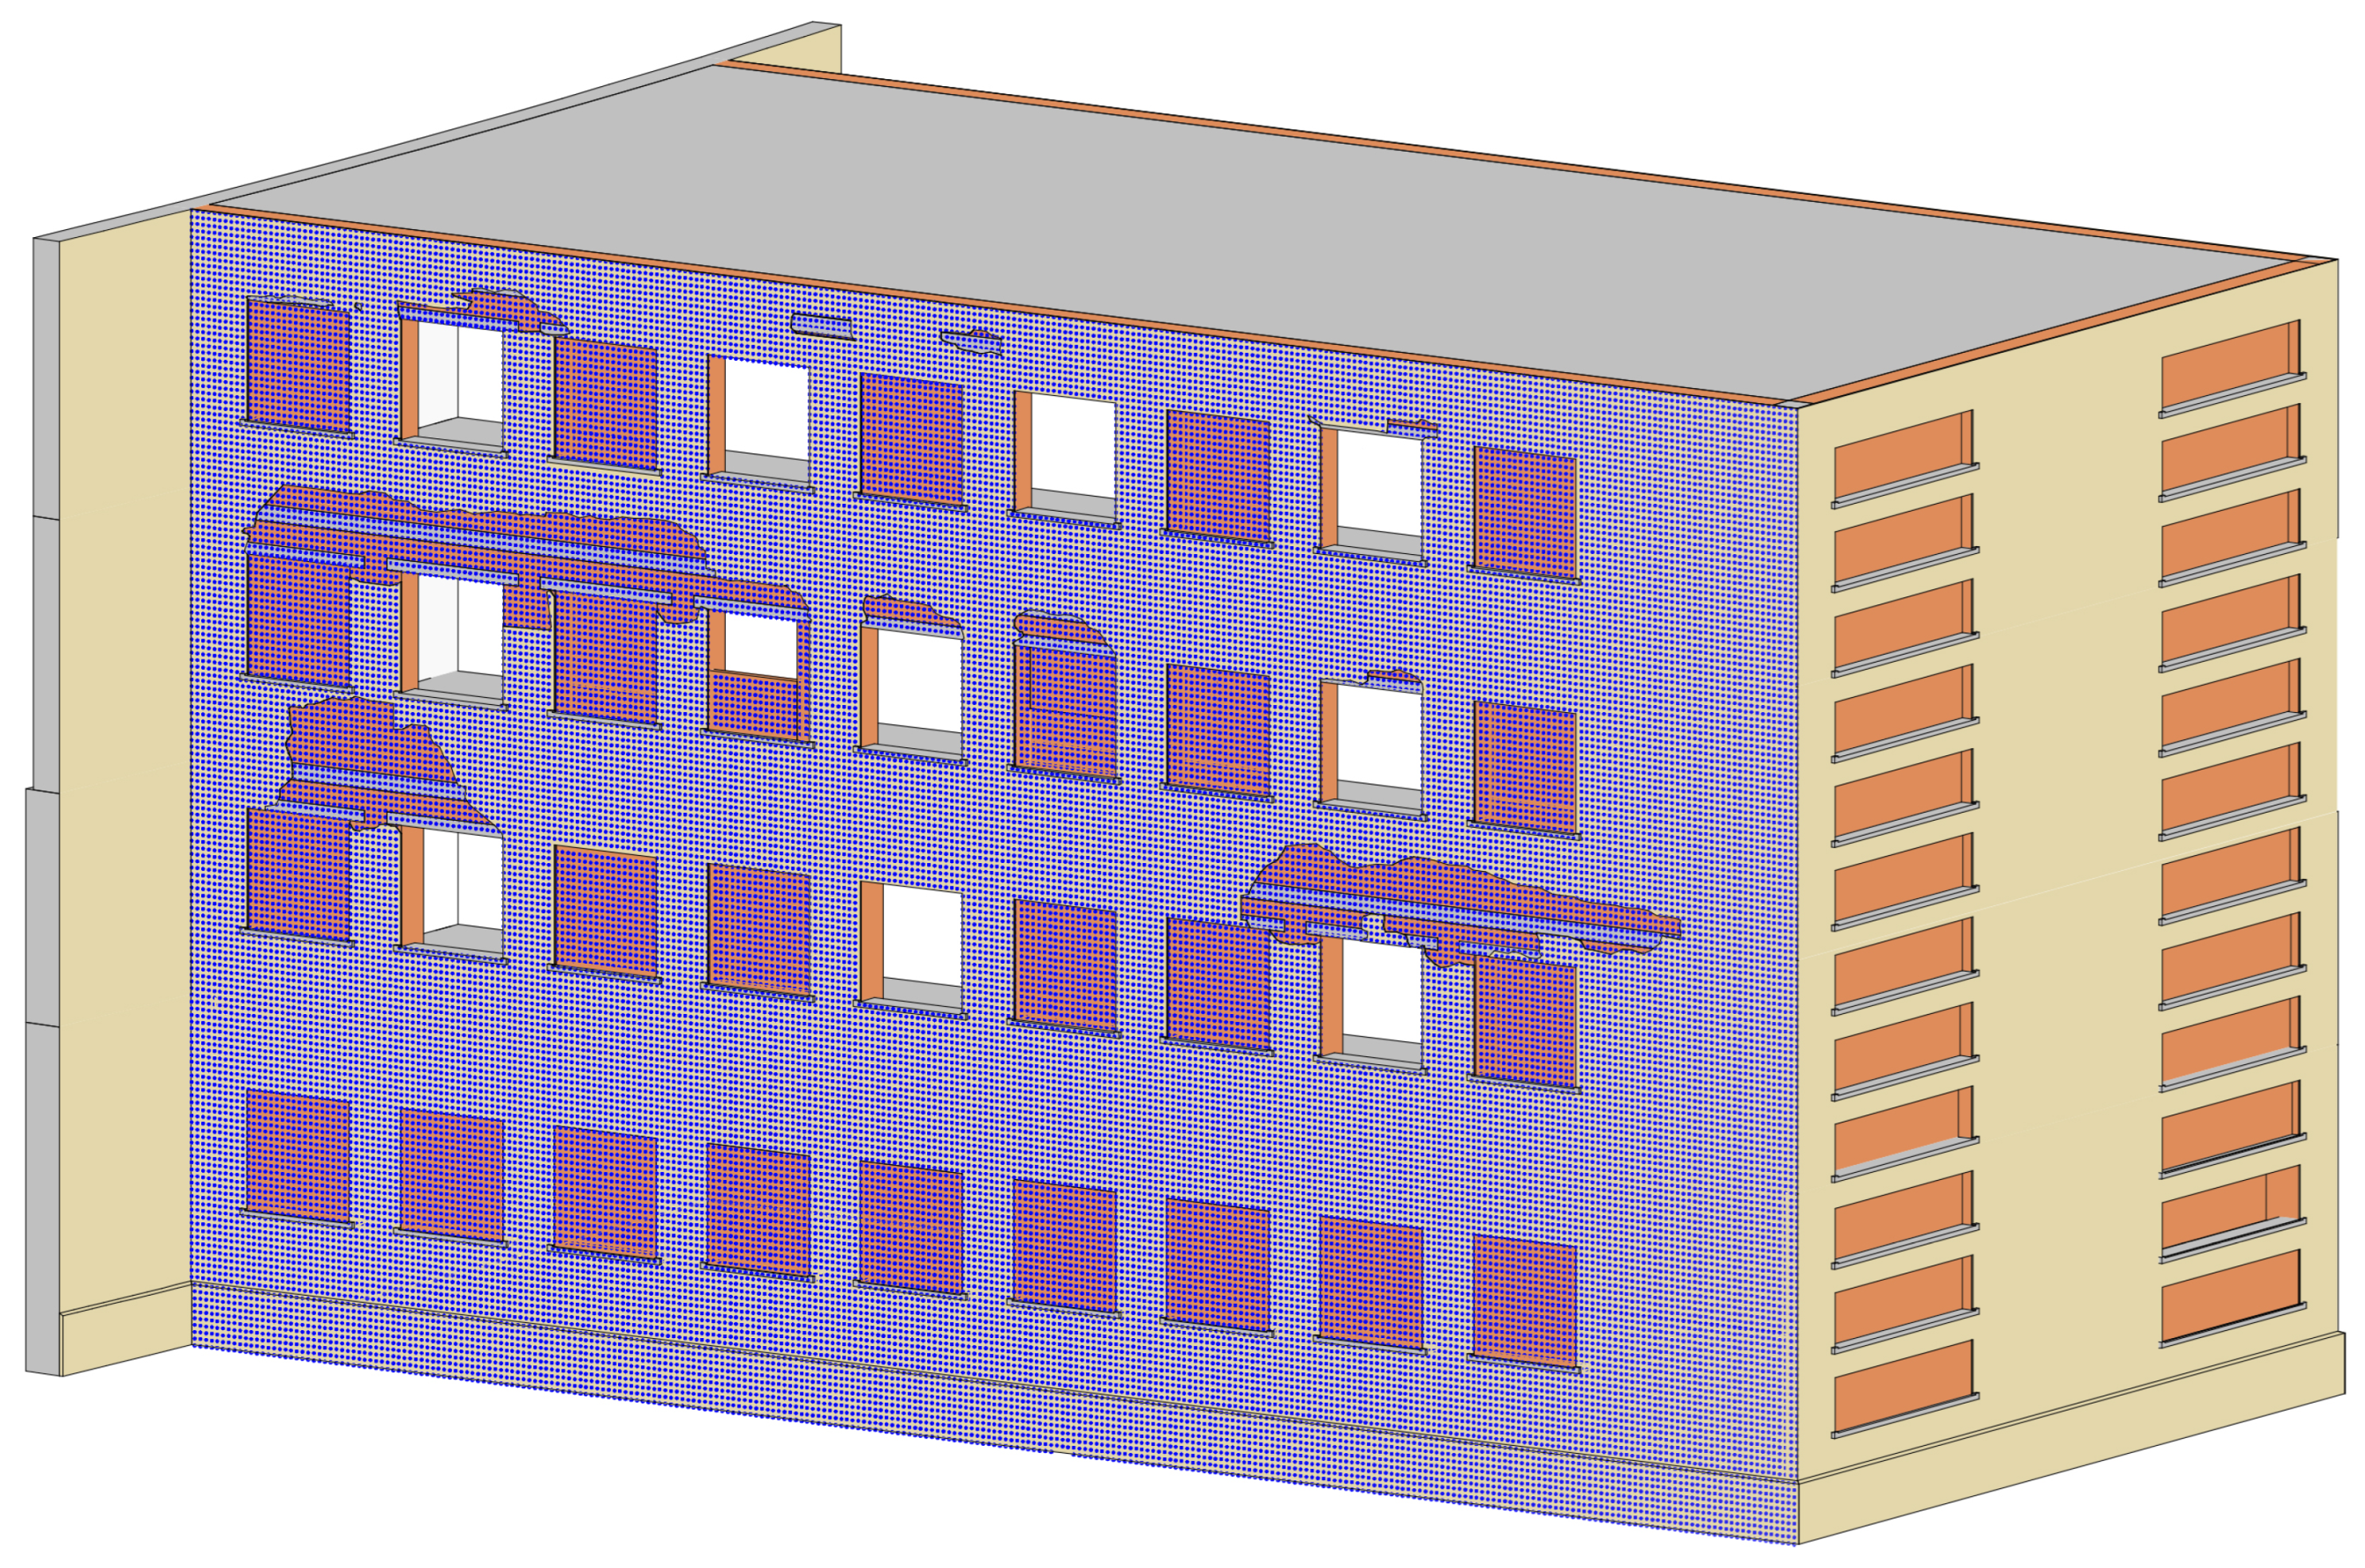
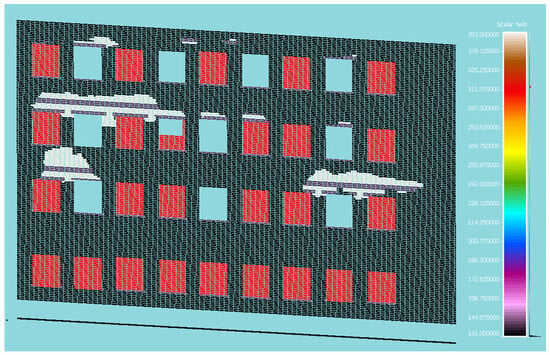
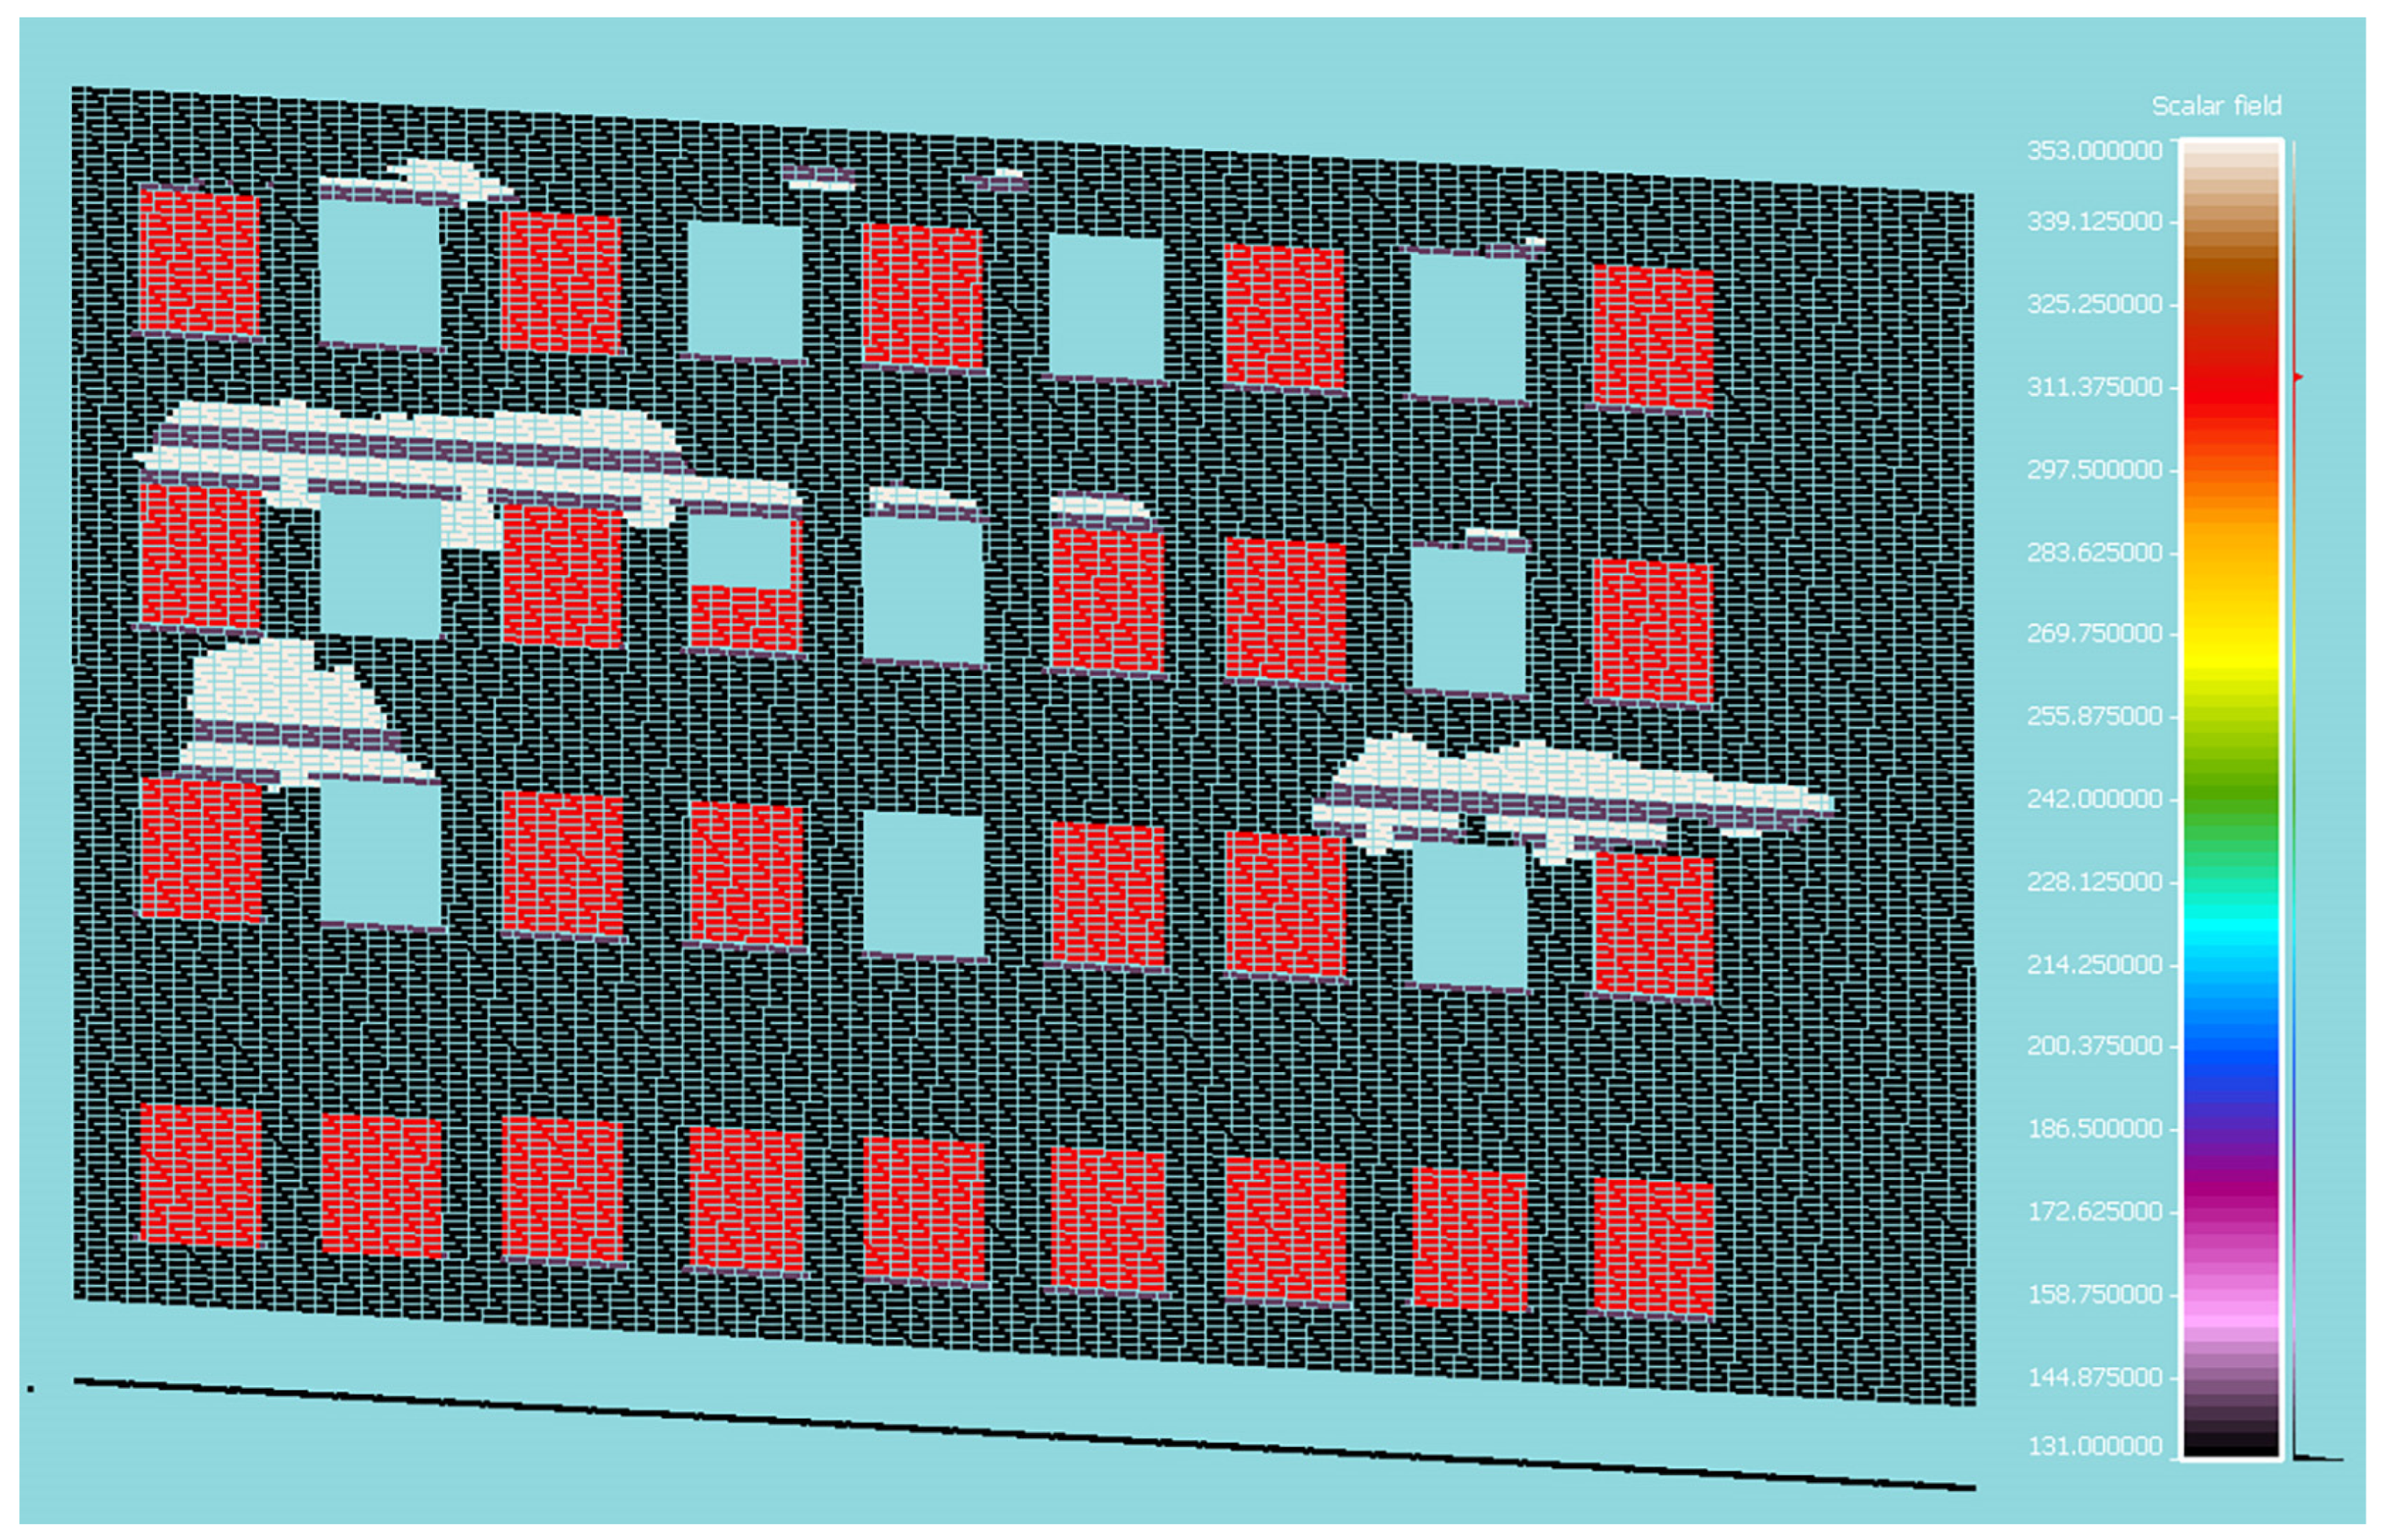
The BIM-to-Cloud process enables a possible new approach to be tested to incorporate information surfaces relating to deterioration conditions, as it is the resulting model—with its adjustments and critical assessments—that defines the segmentation areas of the point cloud through its surface breakdown into points. Specifically, the surfaces of BIM objects are converted into points distributed across a grid with a user-defined spacing (Figure 8), whilst extracting the corresponding material information. In this way, it is possible to interpolate the survey point cloud with that extracted from the BIM model, segmenting it by material value. At this stage, it is also possible to perform the reverse operation, namely to enrich the point cloud extracted from the model with Intensity Value information. This operation allows the point cloud and the model to be compared once again in order to position a surface element (an enriched object) with dimensions equal to those of the grid defined at the outset for each point, using the Intensity Value data (Figure 9).
Figure 8.
Breakdown of external surfaces into points at a predefined, constant grid spacing. The breakdown is carried out using a computational algorithm, which defines the coordinates and also records information on relevant parameters, such as material data.
Figure 9.
Assessment of the point cloud extracted from the BIM model, with the differentiation of material data.
This process is proposed as a strategy to streamline the workflow, involving a direct comparison between the survey point cloud and the computer-generated model point cloud (indirect acquisition of critical assessments during the representation phase).
Two methods were tested.
- The first one involves the generation of points on manually selected surfaces through a user-defined grid that determines the point density. Once the points have been generated, the algorithm populates them with spatial coordinate information and the material-related data of the reference surface, retrieving the latter as a keynote field assigned to the architectural element (wall, beam, column, etc.). The main critical issues identified concern the need to manually select the surfaces, the presence of discontinuities with respect to the assigned surfaces, and the inclusion of vertices and occluded elements.
- The second method involves the generation of points on surfaces from a vector defining an origin and direction, based on which the user-defined grid is projected onto all surfaces that it intersects, as if the model were being “scanned”. The main issues concern any cutting bodies (subtractive volumes), which are interpreted as surfaces, as well as the need to remove external or irrelevant elements. The advantages consist of the faster generation of points across multiple surfaces simultaneously, while retaining the possibility of recording the data according to reference planes. The procedure for populating the points is the same as that used in the first method.
Both methods showed comparable computation times, ranging from approximately one to ten minutes depending on the grid density and the extent of the surfaces. In the specific case examined, for a 500 m2 surface, processing times of approximately one to six minutes were recorded on the same machine for the generation of 50,000 points (10 × 10 cm grid spacing) to 5,000,000 points (1 × 1 com grid spacing). Overall, the second method proved to be more operationally efficient, allowing multiple surfaces to be processed easily and in a scalable manner, as well as being more open to automation within repeatable workflows. However, the methodological approach adopted was based primarily on a visual assessment; analytical evaluations will be carried out in subsequent stages of refinement of the procedure.
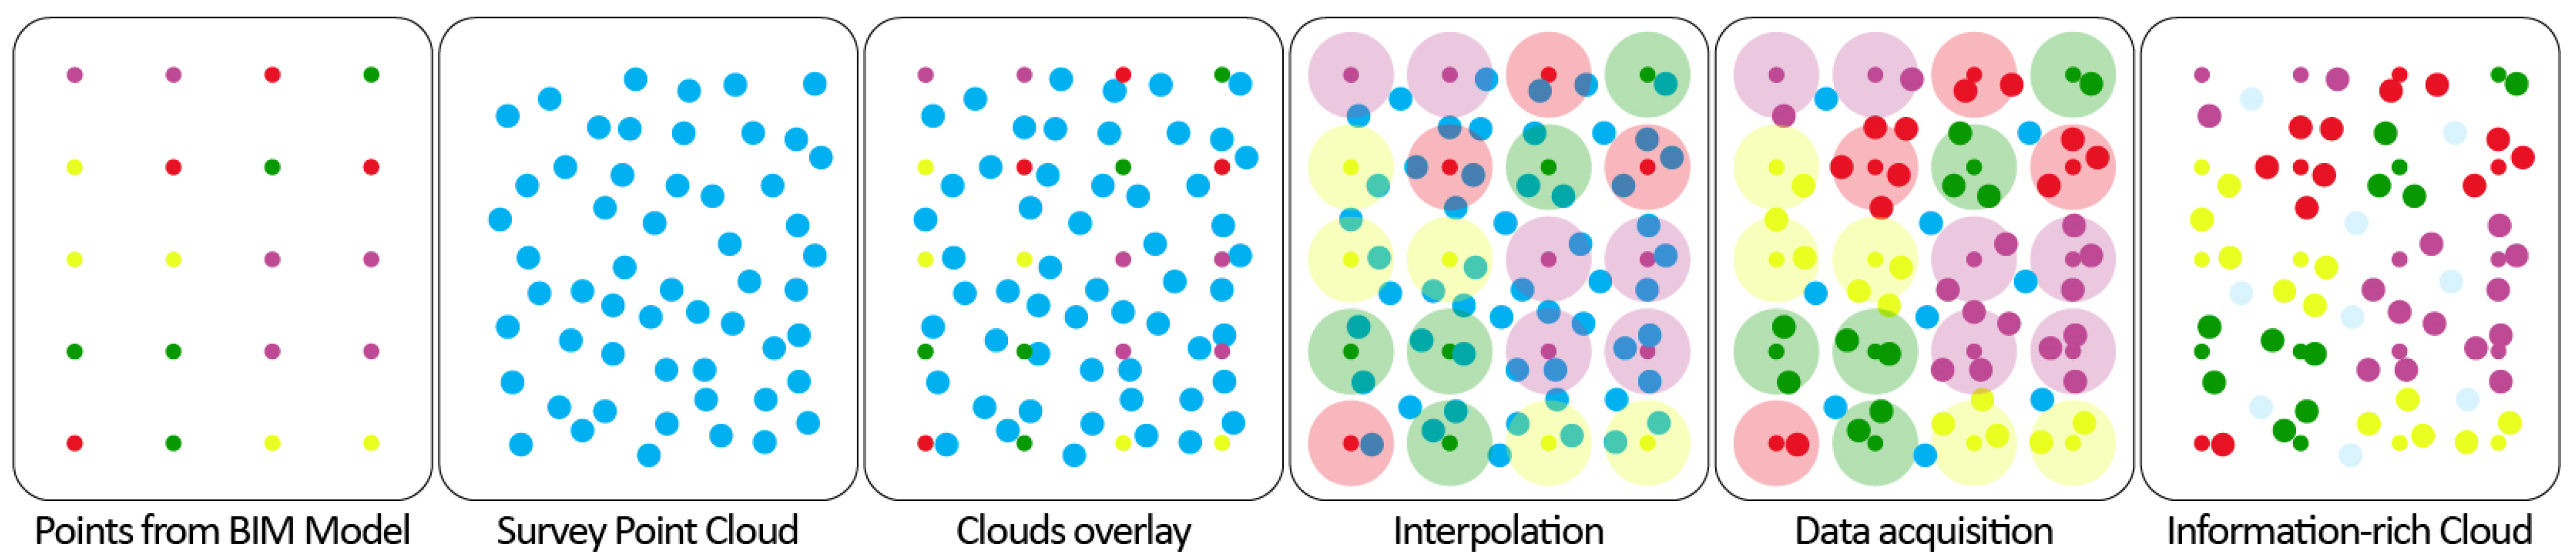
Results from the cloud comparison are based on interpolation tests between the BIM-to-Cloud visualization and the survey point cloud, implementing mutual data exchange for information mapping (Figure 10). Specifically, the schema shows the material data from BIM-to-Cloud to the survey point cloud (through automated segmentation based on the critical and cognitive assessments applied during the modeling phase), and the Intensity Value data from the survey point cloud to BIM-to-Cloud (as a basis for mapping non-homogeneous areas on the same material).
Figure 10.
Conceptual diagram of the processing of the two point clouds to produce an information cloud—i.e., a segmented and information-rich cloud resulting from the breakdown of the BIM model into points.
The issue concerning subtracted solids—which are considered solid surfaces in a parametric environment—is addressed by applying a graphical filter to the model. It is necessary to define a unique coding system for all cut-out elements and distinct openings that do not contain solids (i.e., windows and doors comprising only the frames, without any cut-outs).
A further issue relates to the need to clean up the extracted data by removing elements that should not be included in the point cloud. In this case, the algorithm must be integrated with a specific numerical assignment for surfaces where it has not been assigned or where the value “key note” is present. It is therefore necessary to introduce the option to select elements or surfaces to be excluded from the calculation.
Tests have also revealed the absence of certain elements in the calculated output. In this regard, it is necessary to verify the nature of the exclusion and force the calculation to include elements from the main categories (such as ‘Wall: extrusion’).
4. Discussion
The Scan-to-BIM methodology enables the creation of a parametric three-dimensional digital model from a point cloud—that is, from the surveyed data—through critical assessments, according to the intended use of the information. Once the model has been generated, the point cloud no longer serves a purpose within the BIM environment, except for geometrical validations, and is managed separately for segmentation and the extraction of specific information (spatial coordinates, RGB data, Intensity Values). The BIM model, on the other hand, begins an informative process that can result in a perfectly consistent representation of the as-built condition. Therefore, the reconciliation of information between the processed point cloud and the BIM model may reveal discrepancies at both the geometric and informational levels, with a lack of data within the point cloud.
All tested solutions to integrate surface features within the parametric model presented strengths and weaknesses.
The main shortcomings, in general, concerned the following:
- modeling times;
- discrepancies between the material representation and that of structural elements;
- some properties assigned as key notes lacking further informatization;
- difficulties in interpreting RGB or Intensity Value data when identifying states of conservation;
- the model becoming overly complex;
- discrepancies in the association of images with 3D elements.
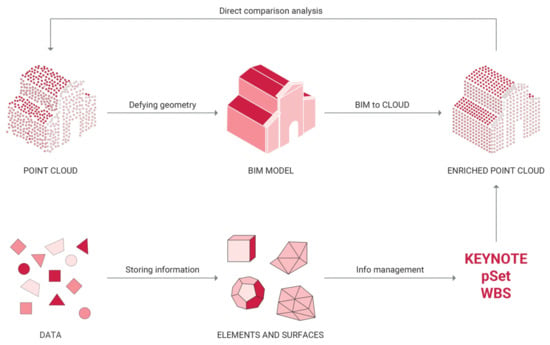
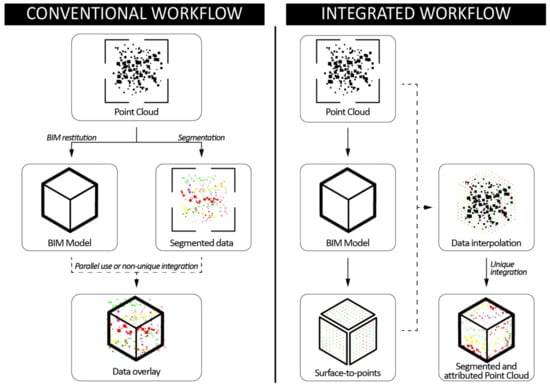
On the other hand, the possibility of working directly within the point cloud derived from laser scanning or photogrammetric processing, also linking available documentation and data, offers the advantage of fully reflecting the existing structure (Figure 11).
Figure 11.
On the left, the “standard” workflow, using point clouds for the geometric reconstruction of BIM models and independent segmentation. On the right, the “integrated” workflow, using point clouds for the geometric reconstruction of BIM models and the breakdown of digital surfaces into point clouds for direct comparison with the source data, to automate segmentation processes in a unique way with respect to the models.
Concerning the application of the BIM-to-Cloud approach for conservation purposes, the information exchange between clouds should be expanded both with regards to cloud segmentation, optimizing the process, and with regards to the gathering and graphical representation of degradation information based on the BIM model. This can be achieved through the following:
- the definition of a database consisting of acquired survey clouds, models represented on the same geometric basis, and clouds extracted from BIM capable of incorporating, through a Deep Learning process, the critical approaches derived from the three-dimensional representation;
- the digitization of the information related to degradation, following algorithmic applications based on the point cloud acquired during the survey phase, into the BIM model through the addition of surfaces based on the BIM-to-Cloud matrix.
The objective will therefore to generate, for each point, an adaptive parametric surface element with dimensions related to the point matrix of the BIM-to-Cloud model, including the Intensity Value information predominant or distinct in multiple project parameters. This approach would resolve many of the critical issues faced in the assessment of digitization techniques for degradation mapping. The objects thus generated would be usable both within Digital Twin platforms and within the BIM model (weight limits permitting). Furthermore, the data would be continuously updated by comparing new clouds of the same object acquired over time.
As regarding strategies for retrieving data from the point cloud—whether manually or using automated processes—the main challenges may arise depending on the use, or rather the purpose, of the models. Extracting data from a point cloud can be effective for the morphological and typological description of constructive elements, whilst the information relating to surfaces can also be processed externally or with the aid of Digital Twin platforms for data management [36]. The focus can be shifted to resolution strategies relating to the specific phase (of the construction cycle) under consideration, thereby assuming that the data extraction fulfils a specific purpose, designed to meet the requirements of a particular phase—such as the preliminary one, where even significant simplification criteria can be applied.
It is relevant, in this context, to mention the LOIN, Level of Information Need (UNI EN ISO 19650-1:2019, UNI EN ISO 7817-1:2024), with reference to the distinction between the LOG (Level of Geometry) and LOI (Level of Information), which need not necessarily be linear as in the now-outdated definition of the LOD (Level of Development) [37]. It is, in fact, possible to have a model that is poor in geometric information—as it is highly simplified—yet rich in terms of information, particularly with regard to analytical references, thereby meeting the requirements of the relevant phase (for instance, preliminary seismic assessment).
With regard to the use of BIM models, while ideally all requirements relating to a building could be addressed by a single model, in practical terms, this is not possible for a wide range of reasons: weight, multiple purposes, multiple disciplines, multiple design phases, a “non-linear” as-built model (i.e., a new as-built model), management (not related to modeling), etc. These considerations further strengthen the categorization of models according to their intended purposes.
It is difficult to derive a simplified model from one at an advanced stage of design or documentation, where there is a tendency to break down even the stratigraphic sequences according to construction methods, installation, or construction times. However, counterintuitive as it may seem, this highly specific distinction between objects and parts does not, in any case, work in synergy with the definition of an analytical model as intended, for instance, for structural engineering assessments [38]: it may allow for the identification of certain joints but not for the structural continuity in terms of behavior.
It is possible to use components that enable the generation of analytical models, such as placing objects—for example, generic coded models—at wall joints; these define the type of joint and its orientation, thereby serving as points for constructing the analytical model through Dynamo processing.
5. Conclusions
The reflections outlined on the documentation of cultural heritage and the creation of digital information systems bring to the forefront the need to shift the critical approach to the outset of the process and to facilitate an in-depth understanding and analysis of cultural heritage, overcoming possible “instrumental” visions. Data acquisition and processing tools cannot be indeed considered the end point in the documentation, analysis, monitoring, and conservation of cultural heritage, but rather food for thought towards adaptive systems able to integrate different digital systems and environments.
A key point concerns the ability to make information accessible, considering parametric environments and informative systems in a broad sense. This means, on the one hand, that the aggregation of information on the physical characteristics of historic architectures must be metrically controlled within the geometric model and easily retrieved, and, on the other hand, that additional knowledge should be integrated into digital models, including historical studies, archival sources, information relating to previous interventions, and all possible diagnostic data when the digital replica is tailored to conservation or restoration processes.
A substantial frame of BIM-related research has indeed concentrated on defining and standardizing representation frameworks such as the Level of Definition (LoD), commonly used to indicate the degree to which a digital model reproduces the geometric characteristics of the existing building. Within the field of architectural conservation, however, restoration planning and preventive maintenance strategies require digital representations that correspond as faithfully as possible to the physical condition of the heritage asset [39,40]. Unlike contemporary construction projects, where design information is progressively refined, reproducing the actual state of historic buildings at the highest LoD is often technically demanding, time-consuming, and economically unsustainable, making conventional BIM workflows less advantageous than traditional documentation approaches. Enhancing the semantic dimension of BIM environments offers a different perspective. Rather than relying exclusively on highly detailed geometric models, semantically enriched yet geometrically simplified representations can performance as comprehensive information repositories, integrating heterogeneous datasets, supporting documentation, and facilitating interdisciplinary collaboration among different specialists. In this sense, the informational value of the model may outweigh the need for exhaustive geometric accuracy [41]. At the same time, research is increasingly extending beyond conventional BIM paradigms.
“HBIM-to-Cloud” processes tested up to now have been developed in the direction of creating a geometrically consistent model, able to include enriched information concerning one of the main requirements in heritage conservation: the ability to manage materials and the related state of conservations as the basis to predict possible interventions.
The approach is based on the control of the consistency of 3D surveyed data, experimenting on State of the Art data classification and segmentation by balancing point clouds or image segmentation according to the different purposes (clustering of materials or degradations). In this direction, the use of Intensity Values is a research avenue under development, to be furtherly experimented to leverage data classification starting from the accuracy of surveyed data for surface characterization.
The HBIM-to-Cloud proposed process is aimed at setting up a workflow involving a direct comparison between the survey point cloud and the computer-generated model point cloud (indirect acquisition of critical assessments during the representation phase). The most promising approach experimented on up to now involves the generation of points on surfaces from a vector defining an origin and direction, based on which the user-defined grid is projected onto all surfaces that it intersects. The advantage is the generation of an enriched information cloud defined by the surfaces of the parametric model. Further experiments are under development in order to fix the main issues, such as subtractive building volumes interpreted by the software as surfaces and the removal of external elements. The fast generation of points across multiple surfaces simultaneously by keeping the opportunity for data recording according to reference planes is one of the main results on which future developments are grounded.
Associating documentation, analytical records, and semantic information directly with reality-based survey outcomes [42], such as laser scanning point clouds and photogrammetric datasets, is particularly promising since it allows the full geometric complexity of the existing architecture to be preserved without requiring complete parametric reconstruction.
Within these approaches, computational ontologies provide the conceptual framework needed to organize and interconnect heterogeneous information [43]. Moreover, the segmentation of surface features via algorithms can lead to the development of semantic structures capable of accurately locating information and establishing meaningful relationships, associations, and inference mechanisms across multiple sources of heritage knowledge [44] (p. 52). As a matter of fact, some specific aspects related to the “construction” of enriched information systems need to be increased and improved, such as informational dimensions, semantic richness, interdisciplinarity, and model manageability and interoperability [14].
Further experiments are currently being developed in order to provide a significant number of datasets and BIM models, taking into account diverse historical–architectural contexts and existing heritage buildings, characterized by different levels of complexity, materials, construction techniques, and states of preservation.
The proposed BIM-to-Cloud methodology represents a possible shift from conventional Scan-to-BIM workflows towards an integrated and bidirectional information framework. By combining semantic enrichment with survey data based on reality, it may provide a scalable strategy in the direction to potentially support heritage documentation, degradation assessments, and long-term conservation. Future developments are oriented to integrating the presented workflow within interoperable Digital Twin environments, in order to test additional actions towards the updating of information throughout the asset lifecycle.
Funding
Part of the procedures and results presented in the paper were developed within the project AIM-eBIM—Adapted Information Management for existing Buildings Information Modelling—funded under the Emilia-Romagna 2021–2027 PR-FESR Operational Programme, Action 1.1.2, Call for Strategic Industrial Research Projects targeting the priority areas of the Smart Specialisation Strategy, with D.G.R. no. 2097/2022 and D.G.R. no. 111/2023—CUP F97G22000480003. Scientific Coordinator: Federica Maietti, TekneHub laboratory of the Technopole of the University of Ferrara. Partnership: CRICT—Interdepartmental Centre for Research and Services in the Construction and Territory Sector of the University of Modena and Reggio Emilia, CIRI EC—Interdepartmental Centre for Building and Construction Research of the Alma Mater Studiorum—University of Bologna, Centro Ceramico—University Consortium for the management of the research and experimentation centre for the ceramic industry, and CIDEA—Interdepartmental Centre for Energy and the Environment of the University of Parma. The companies participating in the partnership are Politecnica Ingegneria e Architettura Soc. Coop., 2S.I. Software e Servizi per l’Ingegneria S.r.l., Tonalite S.p.A., Safe LM srl, and Inception srl. Project website | https://www.aimebim.it (accessed on 11 August 2026).
Data Availability Statement
The datasets, parametric models, and surface feature assessment outcomes presented in this paper are not readily available because data are part of ongoing research. Further inquiries can be directed to the author.
Acknowledgments
The project ARTEMIS—Applying Reactive Twins to Enhance Monument Information Systems is funded by the European Union under the Horizon Europe Programme, Call HORIZON-INFRA-2024-TECH-01 (Next generation of scientific instrumentation, tools, methods, and advanced digital solutions for RIs), Topic: HORIZON-INFRA-2024-TECH-01-04, Type of Action: HORIZON-Research and Innovation Action. Grant agreement ID: 101188009 (project duration: from 1 February 2025 to 31 January 2028). The project is coordinated by the National Institute of Optics of the National Research Council (CNR-INO) and developed by twenty-two beneficiaries and two associate partners. The author is a member of the research team of the project partner Inception. Project website | https://www.artemis-twin.eu (accessed on 21 August 2026).
Conflicts of Interest
The author declares no conflicts of interest.
References
- Marcantonio, C.; Maietti, F. Critical dis-measures. Digital data processing and management in heritage documentation. In Measure/Out of Measure. Proceedings of the 45th International Conference of Representation Disciplines Teachers; Bergamo, F., Calandriello, A., Ciammaichella, M., Friso, I., Gay, F., Liva, G., Monteleone, C., Eds.; FrancoAngeli: Milano, Italy, 2024; pp. 1699–1714. [Google Scholar]
- Carbonara, G. Disegno e documentazione per il restauro: Un impegno interdisciplinare. Disegnarecon 2012, 21–26. [Google Scholar]
- Maietti, F. Knowing to preserve: Towards a deeper awareness of heritage identities and fragilities. In Heritage at Risk. Improving Resilience and Awareness Towards Preservation, Risk Mitigation and Governance Strategies; Balzani, M., Maietti, F., Raco, F., Eds.; CRC Press—Taylor & Francis Group: Abingdon, UK, 2025; pp. 197–206. [Google Scholar]
- Rovelli, C. Sull’eguaglianza di Tutte le Cose. Lezioni Americane; Adelphi: Milano, Italy, 2025. [Google Scholar]
- Maietti, F.; Giau, G.; Zattini, A. Built Heritage Adapted Information Management Through AI. The AIM-eBIM Project. In Representation Across Boundaries: New Links with AI, AI-GEN, and XR Tools for Cultural Heritage and Innovative Design; Giordano, A., Russo, M., Spallone, R., Eds.; Springer: Cham, Switzerland, 2026; pp. 959–978. [Google Scholar]
- International Charter for the Conservation and Restoration of Monuments and Sites (Venice Charter)—1964. Available online: https://www.icomos.org/charters-and-doctrinal-texts/ (accessed on 13 June 2026).
- Rinaudo, F. La documentazione del patrimonio culturale. In H-BI(M)ON. Heritage—Building Information Modelling/MONitoring. Dalla Realtà al Modello e Ritorno; Ottoni, F., Bruno, N., Eds.; Edizioni Quasar: Roma, Italy, 2026. [Google Scholar]
- Farella, E.M.; Rigon, S.; Remondino, F.; Stan, A.; Ioannidis, G.; Münster, S.; Medici, M.; Maietti, F.; Sánchez, A. Methods, data and tools for facilitating a 3D cultural heritage space. Int. Arch. Photogramm. Remote Sens. Spat. Inf. Sci. 2024, XLVIII-2/W4-2024, 197–204. [Google Scholar] [CrossRef] [Scilit]
- European Commission: Directorate-General for Communications Networks, Content and Technology, Common European data space for cultural heritage—Strategy 2025–2030, 2025. Available online: https://data.europa.eu/doi/10.2759/9497280 (accessed on 28 June 2026).
- Lei, Y.; Bruno, N.; Roncella, R. A Data-driven Information Modelling Approach for Cultural Heritage. Int. Arch. Photogramm. Remote Sens. Spat. Inf. Sci. 2025, XLVIII-M-9-2025, 813–820. [Google Scholar] [CrossRef] [Scilit]
- De Luca, L.; Comte, F.; Pamart, A. Dür. air: Reconciling acquisition and interpretation in cultural heritage field documentation. Int. Arch. Photogramm. Remote Sens. Spat. Inf. Sci. 2026, XLVIII-2/W12-2026, 129–136. [Google Scholar] [CrossRef] [Scilit]
- Fiorani, D. Digitalizzazione e conoscenza per il restauro. Per una rivoluzione nella continuità. In H-BI(M)ON. Heritage—Building Information Modelling/MONitoring. Dalla Realtà al Modello e Ritorno; Ottoni, F., Bruno, N., Eds.; Edizioni Quasar: Roma, Italy, 2026; pp. 364–366. [Google Scholar]
- Lovell, L.J.; Davies, R.J.; Hunt, D.V.L. The Application of Historic Building Information Modelling (HBIM) to Cultural Heritage: A Review. Heritage 2023, 6, 6691–6717. [Google Scholar] [CrossRef] [Scilit]
- Parente, M.; Bruno, N.; Ottoni, F. HBIM and Information Management for Knowledge and Conservation of Architectural Heritage: A Review. Heritage 2025, 8, 306. [Google Scholar] [CrossRef] [Scilit]
- Croce, V.; Caroti, G.; Piemonte, A.; De Luca, L.; Véron, P. H-BIM and artificial intelligence: Classification of architectural heritage for semi-automatic scan-to-BIM reconstruction. Sensors 2023, 23, 2497. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Münster, S.; Maiwald, F.; di Lenardo, I.; Henriksson, J.; Isaac, A.; Graf, M.M.; Beck, C.; Oomen, J. Artificial intelligence for digital heritage innovation: Setting up a R&D agenda for Europe. Heritage 2024, 7, 794–816. [Google Scholar] [CrossRef] [Scilit]
- Pansoni, S.; Tiribelli, S.; Paolanti, M.; Di Stefano, F.; Frontoni, E.; Malinverni, E.S.; Giovanola, B. Artificial Intelligence and Cultural Heritage: Design and Assessment of an Ethical Framework. Int. Arch. Photogramm. Remote Sens. Spat. Inf. Sci. 2023, XLVIII, 1149–1155. [Google Scholar] [CrossRef] [Scilit]
- Pierdicca, R.; Paolanti, M. GeoAI: A review of artificial intelligence approaches for the interpretation of complex geomatics data. Geosci. Instrum. Methods Data Syst. 2022, 11, 195–218. [Google Scholar] [CrossRef] [Scilit]
- Antuono, G.; Cera, V.; Campi, M.; D’Agostino, P. The Influence of Data Quality in Supervised ML-AI Classification Approaches for Historical Heritage. In Representation Across Boundaries: New Links with AI, AI-GEN, and XR Tools for Cultural Heritage and Innovative Design; Giordano, A., Russo, M., Spallone, R., Eds.; Springer: Cham, Switzerland, 2026; pp. 595–613. [Google Scholar]
- Cassar, A.; Baker, D.; Ioannides, M. From Digital Twin to Memory Twin: A Holistic Framework for Cultural Heritage Documentation, Interpretation, and Adaptive Reuse. Int. Arch. Photogramm. Remote Sens. Spat. Inf. Sci. 2025, XLVIII-M-9-2025, 203–209. [Google Scholar] [CrossRef] [Scilit]
- Vuoto, A.; Funari, M.F.; Lourenço, P.B. Shaping digital twin concept for built cultural heritage conservation: A systematic literature review. Int. J. Archit. Herit. 2024, 18, 1762–1795. [Google Scholar] [CrossRef] [Scilit]
- Felicetti, A.; Himmiche, A.; Somenzi, M. Knowledge Graphs and Artificial Intelligence for the Implementation of Cognitive Heritage Digital Twins. Appl. Sci. 2025, 15, 10061. [Google Scholar] [CrossRef] [Scilit]
- Dagnaw, G.; Capuano, R.; Muccini, H. Digital Twins for Cultural Heritage: A Systematic Analysis of the State of the Art. ACM Comput. Surv. 2026, 58, 1–35. [Google Scholar] [CrossRef] [Scilit]
- Niccolucci, F.; Felicetti, A.; Hermon, S. Populating the data space for cultural heritage with heritage digital twins. Data 2022, 7, 105. [Google Scholar] [CrossRef] [Scilit]
- Salonia, P. Avatar, gemelli e metafore digitali nel processo di conoscenza per la conservazione: Quanto le tecnologie emergenti sono abilitanti? Restauro Archeol. 2024, 2, 526–531. [Google Scholar]
- Bianchini, C. Rilievo 2.0: Nuove tecnologie, nuovi strumenti, nuovi rilevatori? In Italian Survey & International Experience. Atti del 36° Convegno Internazionale dei Docenti della Rappresentazione, Undicesimo Congresso UID; Giandebiaggi, P., Vernizzi, C., Eds.; Gangemi Editore: Roma, Italy, 2014; pp. 763–768. [Google Scholar]
- Poulopoulos, V.; Wallace, M. Digital technologies and the role of data in cultural heritage: The past, the present, and the future. Big Data Cogn. Comput. 2022, 6, 73. [Google Scholar] [CrossRef] [Scilit]
- Bruno, N. Dalla realtà al modello. Il disegno ragionato della complessità. In H-BI(M)ON. Heritage—Building Information Modelling/MONitoring. Dalla Realtà al Modello e Ritorno; Ottoni, F., Bruno, N., Eds.; Edizioni Quasar: Roma, Italy, 2026. [Google Scholar]
- Iadanza, E.; Maietti, F.; Ziri, A.E.; Di Giulio, R.; Medici, M.; Ferrari, F.; Bonsma, P.; Turillazzi, B. Semantic Web Technologies Meet BIM for Accessing and Understanding Cultural Heritage. Int. Arch. Photogramm. Remote Sens. Spat. Inf. Sci. 2019, XLII 2/W9, 381–388. [Google Scholar] [CrossRef] [Scilit][Green Version]
- Weinmann, M.; Jutzi, B.; Mallet, C. Semantic 3D scene interpretation: A framework combining optimal neighbourhood size selection with relevant features. ISPRS Ann. Photogramm. Remote Sens. Spat. Inf. Sci. 2014, II-3, 181–188. [Google Scholar] [CrossRef] [Scilit]
- Bolognesi, C.M.; Garipova, A.; Kuznetsova, M. Heritage Decay Visible in HBIM Models. Int. Arch. Photogramm. Remote Sens. Spat. Inf. Sci. 2023, XLVIII-1/W2-2023, 253–259. [Google Scholar] [CrossRef] [Scilit]
- Grilli, E.; Remondino, F. Machine Learning Generalisation across Different 3D Architectural Heritage. ISPRS Int. J. Geo-Inf. 2020, 9, 379. [Google Scholar] [CrossRef] [Scilit]
- Giau, G.; Maietti, F. Comparative analyses between sensors and digital data for the characterization of historical surfaces. In Advances in Representation. Digital Innovations in Architecture, Engineering and Construction; Giordano, A., Russo, M., Spallone, R., Eds.; Springer: Cham, Switzerland, 2024; pp. 707–725. [Google Scholar]
- Suchocki, C.; Damięcka-Suchocka, M.; Katzer, J.; Janicka, J.; Rapiński, J.; Stałowska, P. Remote Detection of Moisture and Bio-Deterioration of Building Walls by Time-Of-Flight and Phase-Shift Terrestrial Laser Scanners. Remote Sens. 2020, 12, 1708. [Google Scholar] [CrossRef] [Scilit]
- Kashani, A.G.; Olsen, M.J.; Parrish, C.E.; Wilson, N. A Review of LIDAR Radiometric Processing: From Ad Hoc Intensity Correction to Rigorous Radiometric Calibration. Sensors 2015, 15, 28099–28128. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Cortés Meseguer, L.; García Valldecabres, J. Digital Twins. HBIM information repositories to centralize knowledge and interdisciplinary management of architectural heritage. Vitr.—Int. J. Archit. Technol. Sustain. 2023, 8, 64–75. [Google Scholar] [CrossRef] [Scilit]
- Maiezza, P.; Tata, A. Standard for geometric and informative reliabilities in HBIM models. Disegnarecon 2021, 14, 15-1–15-10. [Google Scholar]
- Inzerillo, L.; Pisciotta, A.; Acuto, F.; Mantalovas, K.; Di Mino, G. Beyond Traditional H-BIM: AI-Powered Modeling for Heritage Bridges. Int. Arch. Photogramm. Remote Sens. Spat. Inf. Sci. 2025, XLVIII-M-9-2025, 615–622. [Google Scholar] [CrossRef] [Scilit]
- Fiorani, D.; Acierno, M.; Cutarelli, S.; Donatelli, A. Transformation of tools and conservation of architecture: Some researches on the use of digital systems for the intervention on the historical buildings. Ép.-Építtud. 2021, 49, 97–131. [Google Scholar]
- Acierno, M.; Fiorani, D. Conservation Process Model: An Ontology for Conservation in Architecture; Sapienza Università Editrice: Rome, Italy, 2025. [Google Scholar]
- Fattore, C.; Buldo, M.; Priore, A.; Porcari, S.; Porcari, V.D.; Fino, M.D. A Comprehensive Overview of Heritage BIM Frameworks: Platforms and Technologies Integrating Multi-Scale Analyses, Data Repositories, and Sensor Systems. Heritage 2025, 8, 247. [Google Scholar] [CrossRef] [Scilit]
- Castellazzi, G.; Cardillo, E.; Lo Presti, N.; D’Altri, A.M.; de Miranda, S.; Bertani, G.; Ferretti, F.; Mazzotti, C. Advancing Cultural Heritage Structures Conservation: Integrating BIM and Cloud-Based Solutions for Enhanced Management and Visualization. Heritage 2023, 6, 7316–7342. [Google Scholar] [CrossRef] [Scilit]
- Roussel, R.; De Luca, L.; Guillem, A.; Comte, F. A cathedral of spatialised annotations portraying the multidisciplinary study of Notre Dame de Paris. In Digital Heritage 2025; Campana, S., Ferdani, D., Graf, H., Guidi, G., Hegarty, Z., Pescarin, S., Remondino, F., Eds.; Eurographics Association: Goslar, Germany, 2025. [Google Scholar]
- Fiorani, D.; Cutarelli, S.; Acierno, M. Dalla modellazione BIM alla formalizzazione del CPM. In H-BI(M)ON. Heritage—Building Information Modelling/MONitoring. Dalla Realtà al Modello e Ritorno; Ottoni, F., Bruno, N., Eds.; Edizioni Quasar: Roma, Italy, 2026; pp. 37–54. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the author. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.