


Highlights
What are the main findings?
- A comprehensive evaluation of 14 statistical, machine learning, and hybrid forecasting models is conducted on unique quarter-hourly substation-level load data, showing that models incorporating lagged variables and exogenous inputs (weather, temporal indicators) substantially outperform all non-lagged counterparts across MAE, RMSE, and MAPE metrics.
- A hybrid averaging model combining OLS, XGBoost, and Feedforward Neural Networks achieves the strongest forecasting accuracy, reducing MAE from 4.55 to 1.61 kWh relative to the standard correction method currently used by Dutch grid operators, with improvements confirmed by paired t-tests and the Diebold–Mariano test.
What are the implications of the main findings?
- Substation-level, data-driven load forecasting significantly sharpens the deviation signals used to detect grid losses from electricity theft, defective meters, and cable faults, enabling grid operators to intervene earlier and more precisely.
- Replacing aggregated correction factors with advanced forecasting pipelines trained on granular, location-specific data is practically feasible—models require infrequent retraining and generate predictions in under five seconds—offering a scalable upgrade path for distribution system operators.
Abstract
Accurate forecasting of electrical load at the substation level is essential for detecting grid losses that pose significant financial and safety challenges. This study investigates whether the standard correction method currently used by grid operators can be improved through the application of advanced forecasting models to granular, location-specific load data. Such improvements are particularly valuable for identifying abnormal consumption patterns indicative of grid losses due to electricity theft, defective meters, or cable damage. This paper evaluates a broad range of statistical and machine learning models—including ARIMAX, SARIMAX, Random Forests, Gradient Boosting Machines, Neural Networks, and Support Vector Regression—based on unique quarter-hourly datasets from several Dutch substations. Two hybrid approaches are proposed, combining the best-performing individual models through a stacked ensemble method and a simpler averaging strategy. The results show that incorporating lagged and additional exogenous variables, along with the application of various advanced models, significantly improves forecasting accuracy compared to the standard correction method, with the best hybrid model reducing MAE and RMSE by approximately 64.7% and 61.6%, respectively, relative to the current operational benchmark. This study demonstrates that substation-level, data-driven forecasting can strengthen the signals used to detect grid losses, offering practical implications for grid operators and policymakers.
1. Introduction
Grid loss, defined as the discrepancy between the electric energy injected into the grid and the used energy that is billed to end-users, presents a pervasive and complex challenge for grid operators. Accurate forecasting of electricity load at electrical substations is essential to identify and mitigate these losses, thereby reducing financial impacts for both grid operators and retail consumers, as part of these losses are ultimately passed on to end-users. Significant deviations between expected and actual load can indicate grid losses caused by unauthorized usage, such as electricity theft by hemp farms or other illegal activities, as well as by defective meters or damaged cables. Such illegal activities do not only result in financial losses, but they also create significant safety hazards, including fire risks from improperly installed grid connections. These risks become more pressing as such operations are increasingly found in residential areas [1]. In 2022, one of the Netherlands’ major distribution-grid operators, Stedin, reported that approximately 15 percent of its total grid loss—equivalent to 120 million kWh of electricity—could be attributed to fraud and theft, amounting to an estimated €25 million in damages [2]. Additionally, in the Netherlands, electricity theft was identified in 1060 hemp farms during the same year, where a total of 75 million kWh was stolen. This represents a notable decrease compared to the 111 million kWh stolen in 2021, which was linked to 1800 dismantled farms. However, law enforcement agencies suggest that this decline is likely also attributable to reduced reporting, driven by growing fears of organized crime and its associated risks, such as violent reprisals [3]. This underscores the urgent need for alternative detection methods.
Previous research has explored various aspects of methods to improve grid management and reduce grid losses. Studies on efficient grid management have primarily focused on optimizing energy distribution, often emphasizing the integration of renewable energy sources [4,5]. Additionally, several studies have examined the detection of unauthorized electricity usage, such as theft or fraud, using techniques like anomaly detection and machine learning models [6,7]. These studies underscore the financial and operational impacts of grid losses and highlight the importance of proactive measures. Although load forecasting and ensemble-based methods are well-established in the broader forecasting literature, relatively little work applies these techniques to the operational problem of grid-loss detection at the substation level. Prior studies typically rely on generalized or publicly available datasets, which fail to capture the complex, localized patterns present in real distribution networks [8]. Moreover, most existing studies focus on aggregated demand forecasting for larger networks and longer time horizons, overlooking the fine-grained, short-horizon, location-specific predictions required to identify unauthorized usage, detect anomalies, and support efficient grid operations [9].
To address this gap, this study develops an improved methodology for forecasting electricity load at the substation level. The model currently used by grid operators relies on aggregated historical averages and generalized correction factors, and therefore cannot capture localized patterns or the influence of important explanatory variables. The proposed forecasting framework incorporates commonly used explanatory information in short-term load forecasting, including temporal indicators, weather-related variables, and lagged load values, to construct more accurate expected-load estimates at the substation level. By evaluating whether more sophisticated forecasting techniques can improve the accuracy of expected-load estimates, this study assesses their potential to strengthen the deviation signals that grid operators rely on when identifying possible grid losses. Although forecasting alone does not reduce grid loss directly, improved forecasting accuracy enhances the detection mechanism used by grid operators. When expected load is estimated more precisely, deviations from normal patterns can be identified earlier and more reliably, enabling faster interventions against theft, meter defects, or cable failures, which ultimately helps reduce energy loss in practice.
This study systematically evaluates a broad range of machine learning techniques—including Random Forest, Gradient Boosting Machines, and Neural Networks—alongside traditional statistical approaches such as ARIMA and SARIMA, as well as the model currently employed by grid operators. In addition, two novel hybrid models were developed: a complex stacked ensemble model and a simpler averaging method, both leveraging the strengths of the best-performing individual models, including OLS, Extreme Gradient Boosting (XGBoost), and Feedforward Neural Networks (FNN), all enhanced with lagged variables. This study was made possible through a close collaboration with Dimaros, a company developing algorithms to detect cannabis farms on behalf of the Dutch government, in partnership with the largest grid operators. These partnerships provided access to detailed, location-specific, quarter-hourly electricity load data from several substations in the Netherlands—data that are typically unavailable for public research due to privacy constraints. This data is used to examine the extent to which electricity load forecasts can be improved. Through a systematic comparison using evaluation metrics such as MAE, RMSE, MAPE, and the Diebold–Mariano test [10], the optimal model for substation-level forecasting was identified.
The findings show that incorporating granular, location-specific data and advanced machine learning techniques significantly improves forecasting accuracy compared to the model currently used by grid operators. While training these models can be computationally intensive, this process does not need to be performed frequently. Once the dataset reaches a sufficient size, the models effectively capture load patterns. Additionally, retraining can be performed in the background while the existing model remains operational, ensuring continuous forecasting availability.
This paper makes three key contributions to the literature:
- This study introduces a unique real-world dataset containing quarter-hourly, substation-level load measurements from a major Dutch distribution system operator. Such granular operational data is rarely available in forecasting research and enables the incorporation of richer explanatory variables—including weather conditions, temporal indicators, and lagged load patterns—that are absent from the forecasting method currently used by grid operators.
- An underexplored question in the literature is addressed by examining whether improved short-horizon forecasts can enhance grid loss detection, a task traditionally based on aggregated historical averages rather than predictive modeling. The expanded feature set enables the first quantitative evaluation of how advanced forecasting methods compare with the traditional model, demonstrating substantial and statistically significant reductions in forecasting error.
- This study provides the most comprehensive assessment to date of forecasting techniques for substation-level load prediction, evaluating 14 statistical, machine learning, and hybrid models under a unified methodological framework that includes out-of-sample overfitting diagnostics and Diebold–Mariano significance testing.
The remainder of this paper is structured as follows: Section 2 provides a comprehensive review of the existing literature, contextualizing the study within the broader body of research. Section 3 details the methodologies employed, including the evaluation metrics. Section 4 describes the datasets utilized in this study, highlighting their characteristics. Section 5 presents the results of the analysis, offering insights into the comparative performance of the models. Section 6 discusses the limitations of the study and suggests potential directions for future research. Finally, Section 7 concludes the paper by summarizing the key findings.
2. Literature Review
Electricity load forecasting has been widely studied across both transmission and distribution systems, resulting in a broad range of methodological approaches. The literature spans traditional statistical models, machine learning techniques, and hybrid frameworks designed to capture complex temporal and nonlinear patterns. This section reviews the main forecasting methods used in prior research, highlighting their capabilities and limitations in the context of short-term electricity load prediction.
A large body of prior work shows that electricity load is strongly influenced by weather conditions such as temperature and sunshine, temporal variables such as hour-of-day, day-of-week, and holidays, and by past load values capturing autocorrelation patterns [11,12,13]. The independent variables used in this study are selected in line with this literature and are chosen to capture location-specific, substation-level temporal and weather-related patterns that define expected electricity consumption.
In parallel, a wide range of time series models has been developed to exploit the temporal structure of electricity load data. Among these, the AutoRegressive Integrated Moving Average with Exogenous Regressors (ARIMAX) and its seasonal extension SARIMAX are frequently applied for short-term load forecasting, particularly when data exhibit linear structures [14,15]. However, their performance often declines in the presence of nonlinearities or complex seasonal behavior. In response to such limitations, alternative statistical models have been developed. For instance, a recent study found that Prophet, a model developed by Facebook, provided superior one-day-ahead load forecasts in scenarios where seasonality and trend variations were more complex [16].
In recent years, machine learning models have gained significant traction in the forecasting domain. Neural networks have been used not only for load forecasting but also for fraud detection using smart meter data [17,18]. Deep learning methods [19], including Feedforward Neural Networks (FNN) [20], have shown strong predictive performance. Similarly, k-Nearest Neighbor (kNN) has been shown to accurately forecast daily residential load, highlighting the versatility of non-parametric models [21]. Beyond Neural Networks, Support Vector Machines (SVM) and their regression counterpart SVR have also proven effective in diverse forecasting applications, including building-level forecasting [22,23]. Moreover, Least Squares SVMs were found to outperform other machine learning approaches in a case study on forecasting hourly residential electricity use, demonstrating their robustness [24]. Tree-based methods have similarly received considerable attention, in part because of their flexibility and accuracy. Decision trees can outperform more complex models such as Neural Networks [25]. Building on this foundation, ensemble methods such as Random Forests and Bagging Regression have delivered strong results across different electricity forecasting contexts [26,27,28]. Even more advanced are Gradient Boosting techniques, including XGBoost, which have demonstrated particularly strong performance in both residential forecasting and electric vehicle load prediction [27,29,30].
In addition to these traditional machine learning approaches, recent work has applied advanced deep learning and Transformer-based architectures to electrical load forecasting across multiple grid levels. For example, several Transformer models have been benchmarked against established deep learning and machine learning methods on large, publicly available datasets for transmission, low-voltage feeder, and client-level loads, showing that Transformer-based approaches can reduce forecast errors significantly compared to strong non-Transformer baselines [31]. Moreover, a Transformer-based deep probabilistic network for load forecasting has reported improved accuracy as well as richer uncertainty quantification for aggregated load series [32]. These studies demonstrate the potential of Transformer architectures for smart-grid forecasting when extensive public data and high-performance computing resources are available, but they also involve complex architectures and hyperparameter optimization pipelines, which can be less efficient for operational purposes. In contrast, the present study focuses on models that are more readily implementable within grid operator workflows and offer a transparent and operationally realistic starting point for grid-loss detection at the substation level.
To further enhance accuracy, hybrid models—combinations of statistical and machine learning techniques—have been proposed. For instance, a hybrid model combining a Convolutional Neural Network (CNN) with a multi-layer bidirectional long short-term memory (LSTM) network demonstrated improved forecasting accuracy compared to individual models [33]. Similarly, ARIMA-SVR and ARIMA-RNN hybrids have been proposed for wind speed forecasting, showing better performance than their individual components [34]. Despite the promising results of these various techniques, their application to grid loss detection and large-scale operational planning poses challenges, particularly in terms of computational demands and the risk of overfitting.
Overall, the existing literature provides a rich foundation of forecasting techniques, ranging from classical statistical models to advanced machine learning and hybrid approaches. However, most prior studies focus on aggregated or residential-level demand and evaluate models under theoretical or controlled settings. Far fewer studies examine forecasting performance using high-resolution substation-level data, which are often restricted due to operational sensitivity and privacy considerations, or consider the implications for operational decision-making within distribution networks. These gaps highlight the need for empirical evaluations based on granular, operational substation-level data, which remains largely unexplored in the existing literature.
3. Methodology
To evaluate the effectiveness of different forecasting techniques in predicting electricity load at the substation level, this section presents a comprehensive comparison of multiple modeling approaches. These include traditional statistical methods such as Ordinary Least Squares (OLS) and time series models, as well as advanced machine learning algorithms and hybrid ensemble techniques. To ensure full reproducibility, all stochastic models were trained using a fixed random seed; preliminary checks confirmed that variability across different seeds was negligible relative to the magnitude of the forecasting errors. Each model is trained and evaluated on the same dataset, with performance assessed through overfitting diagnostics and out-of-sample prediction metrics. By systematically comparing these models, this study aims to identify the most accurate and practical approach for enhancing electricity load forecasts and ultimately reducing grid losses. All forecasts are generated at the quarter-hour level in local Dutch time, using information available up to time t to predict load at min.
3.1. Ordinary Least Squares (OLS) Regression
A baseline for the forecasting framework is established by implementing an Ordinary Least Squares (OLS) regression, a standard linear method that estimates the relationship between electricity load and a set of explanatory variables. The model is specified as
where is the electricity load at time t for substation i, represents the matrix of explanatory variables, is the vector of coefficients estimated by Ordinary Least Squares, and is the error term. Although OLS offers interpretability and computational simplicity, it is limited in capturing nonlinear relationships that are likely present in electricity load data. This motivates the inclusion of more advanced models in the subsequent sections.
3.2. Statistical Time Series Models
Time series models are pivotal for analyzing and forecasting sequentially collected data, a common feature in electricity load studies. Such data inherently exhibit temporal patterns and trends, necessitating the use of specialized time series techniques. These techniques capture the dynamic nature of electricity usage, identifying underlying patterns such as seasonality, cyclical fluctuations, and the influence of external factors.
In this study, three advanced time series methodologies are employed: the AutoRegressive Integrated Moving Average with eXogenous variables model (ARIMAX), the Seasonal ARIMAX model (SARIMAX), and the Prophet model. These models are well-suited for multifaceted analyses, accounting for the internal dynamics of the time series and incorporating external variables that may affect electricity load patterns.
A unique challenge of the dataset is that it consists of multiple non-overlapping time periods from different substations. This structure can complicate time-series analysis, since continuity is typically important for capturing temporal dependencies. Rather than imposing separate adjustments for the discontinuity, the analysis assumes that daily load patterns are sufficiently similar across substations and time periods. To assess generalizability, extensive out-of-sample testing is conducted (see Section 3.6.2).
3.2.1. ARIMAX
The AutoRegressive Integrated Moving Average with Exogenous Regressors (ARIMAX) model is employed to capture temporal dynamics in electricity load while accounting for external influences. ARIMAX extends the classical ARIMA framework by incorporating exogenous variables such as weather and time-based indicators [35]. The model is specified as
Here, denotes the matrix of exogenous regressors and the corresponding coefficients on these regressors. represents the differencing operator applied d times to ensure stationarity. The parameters and correspond to the autoregressive (AR) and moving average (MA) components of the model, respectively. The lag orders p, d, and q were selected based on the Akaike Information Criterion (AIC), which penalizes model complexity to avoid overfitting.
3.2.2. SARIMAX
The Seasonal AutoRegressive Integrated Moving Average with Exogenous Regressors (SARIMAX) model extends ARIMAX by including seasonal components to capture recurring patterns in the data [15]. This is particularly relevant for electricity load data, which often exhibits seasonality driven by temperature, daylight variation, and consumer behavior. The SARIMAX model is defined as
Here, and denote the non-seasonal and seasonal differencing operators, respectively, while S is the number of observations per season. Given the quarter-hourly data, is set to reflect daily seasonality. The parameters , , , and correspond to the autoregressive and moving average components at both non-seasonal and seasonal levels. The lag orders were selected using the Akaike Information Criterion (AIC), ensuring a balance between model fit and complexity.
3.2.3. Prophet
Prophet is a modular forecasting tool developed by Meta (formerly Facebook), designed to handle time series with multiple seasonalities, missing values, and outliers [16]. The model decomposes a time series into trend, seasonality, and holiday effects and is expressed as
where captures non-periodic trends, represents seasonal patterns (e.g., daily or weekly cycles), and models holiday effects. Prophet fits a piecewise linear trend, applies Fourier terms for seasonality, and incorporates custom holidays. This makes it well-suited for electricity load forecasting, where load is driven by structural, cyclical, and event-based factors.
3.3. Machine Learning Algorithms
In forecasting electricity load, machine learning algorithms provide significant advantages due to their capability to identify and model complex nonlinear relationships within data. Unlike traditional statistical models, machine learning methods autonomously detect variable interactions and nonlinear effects, eliminating the need for manual specification of such complexities. This subsection delves into several machine learning techniques applied to forecast electricity load at electrical substations.
Machine learning models, with their flexible structures, are less affected by the challenges of non-overlapping time periods across different electrical substations. Unlike time series models that rely heavily on data sequence and continuity, machine learning algorithms can discern patterns and make predictions even with disjointed temporal segments by shuffling the data before training. This robustness is particularly beneficial in this study, where datasets from multiple substations with varying operational time frames are handled.
A critical component in deploying machine learning algorithms is hyperparameter tuning, which optimizes the configuration of model parameters. A grid search method is used to systematically explore a range of hyperparameter values and determine the most effective combination. This approach involves creating a grid of potential hyperparameters and evaluating the model’s performance for each combination to minimize the Mean Squared Error (MSE) in regression tasks. Minimizing MSE is crucial as it directly relates to the model’s accuracy in predicting outcomes. Table 1 summarizes the key hyperparameter settings used for the machine learning models, while full tuning grids and diagnostics remain documented in Appendix E.2.
Table 1.
Key hyperparameter settings for machine learning models.
3.3.1. Decision Trees
Decision Trees are supervised learning models that recursively split the input space based on feature values to make predictions [36]. For regression tasks, they model the target variable as a function of the input features, expressed as
where f represents the series of decision rules derived from the training data. Due to their transparency and ease of interpretation, Decision Trees are widely used. However, they are prone to overfitting, particularly with deep trees. The maximum tree depth was tuned to balance model flexibility and generalization.
3.3.2. Random Forests
Random Forests are ensemble models that aggregate the predictions of multiple decision trees to improve accuracy and reduce overfitting [37]. The model’s prediction is computed as
where is the prediction of the n-th tree constructed with randomness , and N is the number of trees. Randomness is introduced through bootstrap sampling and random feature selection, which increase tree diversity and robustness. The number of trees and the number of features considered at each split were tuned to optimize the trade-off between model complexity and generalization performance.
3.3.3. Bagging Regression
Bagging Regression, or Bootstrap Aggregating, is an ensemble technique that builds multiple decision trees on different bootstrapped subsets of the training data and averages their predictions to reduce variance. Unlike Random Forests, Bagging uses all available features when splitting nodes, which can preserve more structure in the data [38]. The model is expressed as
where represents the n-th decision tree and N is the total number of trees. Each tree independently estimates the load, and their average forms the final prediction. The number of trees is optimized through hyperparameter tuning to balance model stability and computational efficiency.
3.3.4. Gradient Boosting Machine (GBM)
Gradient Boosting Machines (GBMs) are ensemble methods that build decision trees sequentially, where each new tree corrects the residuals of the previous ones using gradient descent to minimize prediction error [29,39]. The model is defined as
where is the n-th tree, its corresponding weight, and N the number of boosting iterations, i.e., the number of trees. Each tree is a weak learner that contributes incrementally to the final prediction. To tune the GBM model, the number of trees, tree depth, learning rate, and minimum number of observations per terminal node were optimized through grid search.
3.3.5. Extreme Gradient Boosting (XGBoost)
Extreme Gradient Boosting (XGBoost) is an efficient and scalable implementation of gradient boosting that introduces advanced techniques for tree learning, regularization, and pruning [30]. Its prediction function is given by
where denotes the n-th decision tree and N the total number of boosting rounds. Compared to standard GBMs, XGBoost includes built-in regularization terms, improved handling of sparse data, and optimized execution speed. Hyperparameter tuning was performed on key settings, including the number of boosting rounds, maximum tree depth, learning rate, and several regularization parameters, to enhance generalization performance.
3.3.6. Feedforward Neural Network (FNN)
Feedforward Neural Networks (FNNs) are a class of Neural Networks where information flows unidirectionally through fully connected layers [40]. For the electricity load forecasting model, the FNN is defined as
where denotes the nonlinear activation function, and are the weight matrices, and , the bias vectors for each layer. Sigmoid activations are used in the hidden layers, and a linear activation is used in the output layer to accommodate the continuous nature of the target variable. Model training was performed using backpropagation, and key hyperparameters such as hidden layer size and weight decay were optimized to balance fit and generalization.
3.3.7. Support Vector Regression (SVR)
Support Vector Regression (SVR) is a variant of Support Vector Machines designed for regression tasks. The epsilon-insensitive loss function is used to balance prediction accuracy and model simplicity. The model is defined as
where W is the weight vector, is the kernel-induced transformation of the input features, and b is the bias term [22]. The Radial Basis Function (RBF) kernel is used to capture nonlinear dependencies in the load data. To improve performance, key hyperparameters, including cost, epsilon, and gamma, were tuned to jointly control model flexibility, error tolerance, and locality of the kernel response.
3.3.8. k-Nearest Neighbors (kNN)
The k-Nearest Neighbors (kNN) algorithm is a non-parametric method that predicts outcomes by averaging the target values of the k training instances whose input features are most similar to those of the new observation, measured using the Euclidean distance metric [21]. The model is defined as
where denotes the load of the j-th nearest neighbor to . To avoid overfitting or oversmoothing, the optimal number of neighbors k was selected through hyperparameter tuning.
3.4. Hybrid Forecasting Approaches
To further improve forecasting performance and robustness, two hybrid modeling approaches are explored: a stacked ensemble technique and a simpler averaging method. Both approaches combine the strengths of the best-performing individual models, which were selected based on rigorous evaluation using performance metrics, overfitting diagnostics, and the Diebold–Mariano test.
The rationale for introducing hybrid models follows from the fact that the individual forecasting methods used in this study rely on fundamentally different modeling principles. OLS captures the dominant linear relationships between the explanatory variables and electricity load, providing a stable, low-variance baseline, whereas Neural Networks are particularly effective at learning complex temporal patterns. XGBoost, in contrast, captures nonlinear interactions and localized patterns through sequential tree-based boosting, which a purely linear model cannot represent. Because these approaches learn different structural properties of the load data, their predictive outputs are not perfectly correlated. Combining them through a hybrid model therefore provides a principled way to aggregate complementary information from diverse model families. The hybrid approaches—both the stacked ensemble and the simple averaging method—are intended to reduce reliance on any single model class and to improve robustness by leveraging the strengths of a broader set of forecasting techniques.
3.4.1. Approach A: Stacked Ensemble Modeling
Stacked ensemble modeling is a sophisticated machine learning technique that layers models to improve prediction accuracy. The fundamental idea is to use a set of base models, each bringing its unique predictive strengths, and then to employ another model, known as the meta-model or second-layer model, to synthesize their predictions. The procedure of this approach is summarized in Table 2.
Table 2.
Implementation steps of stacked ensemble modeling.
3.4.2. Approach B: Averaging Predictions
In addition to stacked ensemble modeling, a simpler approach is implemented by averaging the predictions of the top models. This method involves taking the predictions from OLS, XGBoost, and FNN, each with lagged variables, and averaging them to produce the final forecast. This approach is computationally less complex and provides a straightforward way to harness the strengths of multiple models.
3.5. Econometric Issues
The analysis employed extensive diagnostic approaches to identify and address econometric issues such as overfitting, multicollinearity, autocorrelation, and non-stationarity. By carefully diagnosing and mitigating these potential problems, the robustness and reliability of the forecasting models were improved. Detailed methodologies for identifying and addressing these issues, along with a comprehensive discussion on their potential impacts on the results, are provided in Appendix C.
3.6. Model Evaluation
3.6.1. Performance Metrics
To evaluate model accuracy, three standard metrics are used: Mean Absolute Error (MAE), Root Mean Squared Error (RMSE), and Mean Absolute Percentage Error (MAPE). (MAE measures the average magnitude of errors, calculated as the mean of the absolute differences between predicted and actual values. RMSE penalizes larger errors more heavily by squaring them before averaging and taking the square root. Following common practice in load forecasting studies, performance for MAE and RMSE is assessed relative to the scale and variability of the data: values below 10% of the average load (MAE) or the data range (RMSE) are considered excellent, while values below 20% are considered good. MAPE expresses the average absolute error as a percentage of actual values, allowing for scale-independent comparisons. Following [41], MAPE values below 10% are considered excellent, and values below 20% are considered good). These metrics are calculated on the test set for all models to ensure consistent and fair comparisons.
3.6.2. Overfitting Diagnostic
A direct comparison between each model’s error on the data used to fit it (training error) and its error on the independent, held-out test set (test error) is used to detect potential overfitting, which indicates poor generalizability. Because the test set is chronologically later than, and disjoint from, the training data, a substantially larger test error than training error indicates that the model may be capturing patterns specific to the training period rather than the underlying signal.
A comprehensive explanation of the methodology and rationale for this diagnostic, as well as details on the threshold for overfitting detection, can be found in Appendix C.1.
3.6.3. Diebold–Mariano Test
The Diebold–Mariano test compares the predictive accuracy of two different models by assessing whether differences in model performance are due to genuine variations in predictive capability rather than random fluctuations [10]. The detailed steps of this test can be found in Appendix D.
In the research, the top models are selected through a comprehensive multi-step process. Initially, each model is evaluated based on performance metrics and overfitting diagnostics to determine its effectiveness in forecasting electricity load. Subsequently, the top five models are subjected to the Diebold–Mariano test for pairwise comparison of their predictive accuracies. This thorough analysis enables us to narrow down the selection to the top three models. These models, demonstrating the best overall performance, are then chosen for integration into the hybrid forecasting approach, as outlined in Section 3.4.
Additionally, the Diebold–Mariano test is employed to evaluate the predictive accuracy of the final hybrid model against each of the top three individual models, identifying the overall best-performing model.
3.6.4. Computational Efficiency
The time required to fit and run the model is crucial, especially for real-time forecasting. In the context of computational efficiency, it is important to recognize the varying needs for hyperparameter tuning and model fitting. Once optimal hyperparameters are established, they typically require infrequent adjustments, particularly in stable environments. However, regular model retraining is necessary to adapt to new data and ensure accuracy. Therefore, computation times for both model fitting and prediction are considered when assessing the practical application of these models.
3.6.5. Comparison with Standard Correction
The chosen forecasting model is evaluated against the standard correction used by grid operators, which serves as a benchmark for assessing its added value in electricity load forecasting. Using metrics such as MAE, RMSE, and MAPE, the accuracy of the standard correction is compared with that of the model. Paired t-tests are conducted to determine whether differences in performance metrics are statistically significant.
4. Data Description
4.1. Data Processing
The analysis utilizes a unique and complex dataset characterized as ‘discontinuous panel data’, covering the period from 1 April 2023 to 9 November 2023, and comprising 37.237 observations. This dataset is composed of multiple smaller datasets, each corresponding to a specific electrical substation (electrical substations serve as central hubs in a neighborhood’s electricity distribution network, receiving high-voltage electricity from power plants and then redistributing it at lower voltages through cables to homes and businesses), resulting in multiple interrupted time series. Each series represents electricity load data over non-overlapping time periods, providing a comprehensive yet segmented view of electricity load across various substations. Consequently, the combined dataset offers a rich and varied perspective on electricity load patterns, despite the absence of continuous temporal overlap typically found in conventional panel datasets.
4.1.1. Dependent Variable
The dependent variable to be forecast is , representing the real electricity load of electrical substation at time t. Each electrical substation has a distinct dataset reflecting its real electricity load. These datasets, provided directly by Enexis, contain quarter-hourly observations, measuring electricity in kilowatt-hours (kWh). Notably, the measured load values can be negative due to decentralized electricity generation, implying that the data captures the net electricity consumed per 15-min interval for each substation i at time t. For privacy considerations, exact locations of the electrical substations have been omitted from the datasets utilized in this research, ensuring that specific substations cannot be identified. The descriptive statistics can be found in Table 3.
Table 3.
Descriptive statistics of the dependent variable.
4.1.2. Independent Variables
Key independent variables in the dataset include:
- Standard correction: The current standard correction data, acquired through MFFBAS, represents the net average electricity consumed per cable type for each quarter of an hour and each grid area [42]. This metric functions as an estimation of actual electricity load and is used by grid operators as a correction factor to determine the presence and extent of grid loss. The standard correction serves as a foundational comparison point for more nuanced analyses and will be used as a benchmark for assessing the predictive accuracy of the models. However, primarily because grid operators have not fully recognized their significance and due to the challenges in collecting all the necessary datasets, it does not account for various external factors that significantly influence load patterns. This might be the reason why the standard correction deviates so much from the real electricity load as illustrated in Figure 1. (The curves have been smoothed to highlight general load trends and systematic deviations between the actual and predicted values). Consequently, the research will explore the impact of including these additional variables in the models on the accuracy of the forecasts. (A detailed elaboration on how the standard correction is composed can be found in Appendix B.1).
- Weather variables: Data from the Koninklijk Nederlands Meteorologisch Instituut [43] is used, comprising measurements from 46 weather stations across the Netherlands. (It is acknowledged that weather data for the exact locations of the electrical substations are unavailable, so data from the nearest weather stations are used for the analysis). From this dataset, the variables and are extracted, where is linearly interpolated for quarter-hour intervals, while is evenly distributed across the hour. To capture the nonlinear relationship between temperature and electricity load, two variables are constructed: (additional electricity required for cooling) and (increased electricity demand for heating), using a benchmark temperature of 20 degrees Celsius, which is widely used as a standard in building and environmental comfort studies. These are calculated as follows:
- Temporal factors: Indicator variables are used to include information on the time of day, day of the week, nighttime, weekends, public holidays, and whether the sun has risen. For public holidays, only the quarter-hours between 08:00 a.m. and 06:00 p.m. are used, as this is the period during which most people normally are working or at school but now have a day off and spend time at home. (The holidays considered can be found in Appendix B.2). Additionally, sunrise and sunset times are based on data from Amersfoort, often referred to as the geographical center of the Netherlands, making it a suitable proxy for the substations’ locations.
- Seasonal patterns: Seasonal patterns are modeled using lagged variables to capture periodic fluctuations in electricity load and reduce autocorrelation in the data. Each model is trained with and without the inclusion of four lagged variables of the dependent variable: , , , and , representing load one and two quarter-hours, one day, and one week prior, respectively. This approach assesses the significance of these variables and their impact on the models’ predictive performance.
Figure 1.
Actual electricity load and standard correction (MFFBAS) over time for substations 1, 2, and 3.
Table 4 provides a concise description of the dependent and independent variables.
Table 4.
Description of the dependent and independent variables.
4.2. Data Preparation
To ensure robust and generalizable forecasting, the datasets are consolidated and prepared using the following steps:
- Stratified sampling and data allocation: Training, validation, and test sets are constructed using stratified sampling to ensure proportional representation from each segmented time period, maintaining overall dataset diversity. For the machine learning models, 70 percent of the data is allocated for training. The training set serves as the primary source for fitting the models, allowing them to learn the underlying patterns and relationships within the data. Subsequently, 15 percent is reserved for validation, aiding in hyperparameter tuning and model selection, while the remaining 15 percent is reserved for testing. In this setup, the test set serves as a novel dataset to evaluate the models’ ability to generalize, ensuring an impartial and objective assessment of their predictive performance.
- Feature alignment and standardization: All non-binary explanatory variables are aligned and standardized across all segments. Standardization involves scaling features to have zero mean and unit variance, ensuring consistency and comparability across different time periods and substations. This is crucial for the proper functioning of machine learning models, particularly those sensitive to feature scaling.
The process of data preparation and feature engineering is essential for creating a robust foundation for the predictive models. Stratified sampling ensures that each data subset used for training, validation, and testing accurately represents the variety of conditions observed in the full dataset. This approach enhances the generalizability of the models, making them more reliable in predicting electricity load across different substations and time periods.
5. Results
The forecasting accuracy and computational efficiency of all models are evaluated to identify those best-suited for practical application. Table 5 presents the performance metrics and overfitting diagnostics for each model.
Table 5.
Comparison of the utilized forecasting models.
High MAPE values may result from data volatility, anomalies, or model-specific limitations. Despite this, the lowest MAPE remains a critical criterion for evaluating relative proportional prediction accuracy. Additionally, a detailed overview of computation times is provided in Appendix E.3. Most models, except for SARIMAX variants, complete fitting in less than 12 min. Predictions, except for Prophet and non-lagged SARIMAX models, are completed in under 5 s. Considering computational efficiency, performance metrics, and overfitting diagnostics, the top five individual models are: OLS with lagged variables, Random Forests with lagged variables, Bagging Regression with lagged variables, XGBoost with lagged variables, and Feedforward Neural Networks (FNN) with lagged variables. These models exhibit a balance between good to excellent performance in MAE and RMSE, reduced overfitting risks, and enhanced computational efficiency, making them highly practical for real-world applications.
Building on the previous evaluation, the top five models are compared in terms of statistically significant differences in predictive performance. Table 6 presents the results of the Diebold–Mariano tests applied to each pair of these models.
Table 6.
Diebold–Mariano test results for pairwise model comparison.
The Diebold–Mariano test results reveal several noteworthy findings. First, OLS and XGBoost perform statistically on par with one another, and both significantly outperform RF, BR, and FNN. Second, RF, BR, and FNN show no significant differences among each other. Since these three models are statistically indistinguishable, computational efficiency is used as an additional criterion to select a third model alongside OLS and XGBoost: FNN has by far the shortest fitting time of the three (see Appendix E.3), and is therefore chosen. Based on the overall pairwise comparisons and this additional criterion, the three best-performing individual models are: OLS with lagged variables, XGBoost with lagged variables, and Feedforward Neural Networks (FNN) with lagged variables.
As shown in Table 5, both hybrid approaches do not exhibit overfitting and perform very similarly to one another. Hybrid approach B, which combines the predictions of the three base models through simple averaging, achieves the lowest MAE and RMSE of all evaluated models, while hybrid approach A, based on a stacked ensemble model, trails slightly behind on all three metrics. Both approaches slightly improve on the accuracy of their individual base models, indicating that combining these three models adds some value, although the improvement is modest. These results suggest strong absolute accuracy, although the relatively high MAPE highlights persistent challenges in capturing proportional accuracy. Furthermore, both hybrid models are highly computationally efficient, with fitting times of little over a minute and prediction times well under one second.
A direct comparison between the hybrid approaches and the top three individual models shows a mixed picture at the level of point estimates: hybrid approach B outperforms OLS and XGBoost on all three metrics (MAE, RMSE, and MAPE), though not FNN on MAPE, while hybrid approach A trails OLS on RMSE and MAPE and trails XGBoost on MAE. To assess whether these differences are statistically meaningful, the Diebold–Mariano test was conducted comparing both hybrid approaches with each of the top-performing individual models (OLS, XGBoost, and FNN). The results showed no significant difference between either hybrid approach and the OLS model. However, both hybrid approaches significantly outperformed the XGBoost and FNN models. A direct comparison between the two hybrid approaches themselves also showed no significant difference in predictive accuracy.
Following a comprehensive evaluation of all models, hybrid approach B is selected as the best-performing model for electricity load forecasting. Although hybrid approaches A and B are statistically indistinguishable in predictive accuracy, approach B is preferred for its structural simplicity: it does not require a separate meta-model, and consequently allows its base models to be trained on the full combined training and validation set, making more efficient use of the available data. Its predictive accuracy, on par with hybrid approach A and significantly better than XGBoost and FNN, allows it to closely track actual consumption values even under volatile conditions—an essential feature for operational and planning purposes in electricity management. Notably, while OLS with lagged variables performs statistically on par with both hybrid approaches, hybrid approach B achieves marginally better point estimates than OLS across MAE, RMSE, and MAPE, suggesting that combining multiple models can still yield a modest edge over the simpler linear alternative.
Compared to the standard correction currently used by grid operators, hybrid approach B performs significantly better. The standard correction yields a MAE of 4.55, RMSE of 6.21, and MAPE of 67.82, which are substantially worse than the top-performing model. Specifically, relative to the standard correction, hybrid approach B reduces MAE by 2.94 kWh, corresponding to a 64.7% reduction in the average deviation between predicted and actual load. A paired t-test confirms that the improvements achieved by hybrid approach B are statistically significant, with a p-value well below 0.05. These findings underscore the value of advanced techniques and the inclusion of additional predictors in improving electricity load forecasts beyond traditional methods. Figure 2 presents these results in a comparative visualization across all lagged individual models, both hybrid approaches, and the standard correction method, confirming that the standard correction’s error is substantially higher than that of any individual or hybrid model across all three metrics.
Figure 2.
Comparison of MAE, RMSE, and MAPE across all lagged individual models, both hybrid approaches (highlighted in blue), and the standard correction method.
Figure 3 illustrates this improvement visually, showing that hybrid approach B’s predictions closely track the volatile fluctuations in actual consumption, whereas the standard correction remains comparatively flat and fails to capture these short-term dynamics. To further validate the predictive accuracy of hybrid approach B, Figure 4 plots predicted against actual electricity consumption on the test set: the tight clustering around the diagonal reference line confirms strong agreement between predictions and observed values, with deviations concentrated among a small number of extreme observations. Figure 5 shows the corresponding distribution of residuals, which is unimodal, approximately symmetric, and centered close to zero, indicating no systematic bias in the model’s predictions.
Figure 3.
Actual electricity consumption, standard correction (MFFBAS), and hybrid approach B predictions over time on the test set.
Figure 4.
Predicted versus actual electricity consumption for hybrid approach B on the test set. The dashed line represents perfect prediction (y = x).
Figure 5.
Distribution of residuals (actual minus predicted electricity consumption) for hybrid approach B on the test set.
To interpret the performance of the hybrid averaging model, it is useful to consider the complementary characteristics of its constituent forecasting methods. OLS captures the dominant linear relationships between the lagged consumption values and the other predictors, providing a stable, low-variance baseline. XGBoost captures nonlinear interactions and localized patterns through sequential tree-based boosting, which a purely linear model cannot represent. Feedforward Neural Networks are well-suited to learning smooth, continuous functional relationships that tree-based models may approximate more coarsely. Because these models rely on different functional forms, their forecast errors are not identical, although they remain fairly strongly correlated, as all three are exposed to the same underlying signal and noise in electricity consumption. (Pairwise Pearson correlations between the models’ forecast errors on the test set range from 0.92 to 0.94). Averaging their predictions therefore only modestly reduces model-specific biases and variance, which provides a plausible explanation for the hybrid model’s consistent, if modest, improvement relative to the individual models.
6. Discussion
The results show a clear improvement in forecasting accuracy once lagged variables are included, indicating that short-run persistence in substation load is a major driver of predictive performance. This is consistent with the idea that electricity demand at the substation level is strongly shaped by very recent consumption patterns, alongside daily and weekly cycles. In practical terms, the lagged variables appear to capture the immediate structure of the load series better than models relying only on weather and calendar information.
Among the hybrid approaches, the simple averaging model and the stacked ensemble performed statistically indistinguishably from one another. This is plausible given that the three base models—OLS, XGBoost, and FNN—capture different aspects of the data but nonetheless produce fairly correlated forecast errors, limiting the extent to which either combination strategy can meaningfully outperform the other. The stacked ensemble is, in principle, more susceptible to the limited amount of validation data available for fitting the meta-learner, which introduces additional estimation noise not present in the simple averaging approach; this may explain the preference for averaging in practice, despite the two approaches performing comparably overall. These results suggest that, for discontinuous substation-level load data, a simpler hybrid strategy is at least as effective as a more complex stacking procedure, while being structurally more robust.
The fact that the advanced models outperform the standard correction suggests that the current correction-based approach used by grid operators leaves relevant information unused. In particular, the standard correction does not fully incorporate location-specific temporal structure, weather sensitivity, or recent load history, all of which matter in short-horizon forecasting. The strong performance of models that do include these variables supports the view that more granular and data-driven forecasting can improve operational decision-making in distribution networks. This also aligns with prior forecasting research showing that lagged load values and exogenous variables often improve predictive accuracy in electricity demand applications.
These findings are important for grid-loss detection because the forecasting model is not an end in itself, but a tool for improving the signal used to identify abnormal deviations. A more accurate expected-load estimate makes it easier to distinguish normal consumption variation from losses caused by electricity theft, defective meters, or cable faults. In that sense, the main value of the proposed approach lies in improving the reliability of the benchmark against which grid losses are detected, rather than merely producing lower forecasting errors. In practical terms, this could be integrated into the grid operator’s monitoring workflow by flagging unusually large deviations between predicted and observed load for further inspection. Because load patterns may change over time, periodic retraining and ongoing performance monitoring would also be necessary to address concept drift and preserve model reliability.
Several limitations should be kept in mind. The dataset does not include winter months, so the models may not fully capture colder-season consumption behavior or seasonal extremes. The analysis also lacks electricity price variables, while consumer behavior—particularly among users with variable contracts—may shift in response to price changes. Additionally, socio-economic characteristics (e.g., building types, income levels, population density) and local infrastructure elements (e.g., solar panels, street lighting, and EV charging stations) were not included, all of which may help explain some of the remaining variation in load. The weather variables are also treated linearly due to the available data’s granularity, which may oversimplify the actual, potentially nonlinear, relationship between weather conditions and electricity consumption. Future work could address these issues by using a longer time span and richer covariates.
Moreover, while the computational results indicate that the proposed forecasting pipeline is compatible with short-horizon operational use, a full analysis of real-time deployment, integration with existing grid monitoring systems, and large-scale scalability across many substations lies beyond the scope of this study and remains an important direction for future work.
Finally, the discontinuous panel structure of the data remains an important methodological constraint. Although the results suggest that the models generalize reasonably well across segmented substation periods, the absence of a fully continuous time series means that caution is still needed when extrapolating to other substations or longer forecasting horizons. Even so, the findings indicate that substation-level forecasting can provide a practical and scalable improvement over the current correction-based approach, especially for strengthening grid-loss detection rather than forecasting demand for its own sake.
Based on these potential improvements, several directions for future research are recommended. First, incorporating dynamic electricity prices could improve the model’s responsiveness to behavioral patterns. Second, expanding standard corrections to include all cable types would allow for more accurate baseline estimations. Third, using nonlinear modeling techniques—particularly for weather-related variables—may better capture complex interactions. Moreover, including winter data and seasonal dummy variables could help eliminate seasonal bias. Lastly, enriching the dataset with socio-economic and infrastructure-related variables, and expanding its scope across more substations and longer timeframes, would enhance the model’s robustness, applicability, and potential for real-time grid management support.
7. Conclusions
Grid losses impose substantial financial and operational burdens on grid operators, particularly in the context of rising energy prices and electricity theft. Improving the accuracy of substation-level electricity load forecasting can support early detection of these losses and contribute to more efficient grid management. This study examined whether the standard correction method currently used by Dutch grid operators could be improved through advanced forecasting techniques. A wide range of statistical and machine learning models was applied to detailed quarter-hourly electricity load data, along with a set of exogenous variables not currently used in practice.
The results show that several individual models, particularly those incorporating lagged variables, outperformed the standard correction method. Among the two hybrid approaches—both combining the predictions of the best-performing individual models, OLS, XGBoost, and FNN—the simple averaging approach was selected as the overall best model. Its predictive accuracy was statistically indistinguishable from both the stacked ensemble approach and OLS individually, and significantly better than XGBoost and FNN individually, confirmed by the Diebold–Mariano test. The averaging approach was preferred over the stacked ensemble for its structural simplicity, as it does not require a separate meta-model and can therefore use the full training and validation data for its base models. It was preferred over OLS for its marginally better point estimates across all three metrics, and because averaging multiple, structurally different models generally improves robustness compared to relying on a single model.
Despite the clear improvements in forecasting accuracy in the proposed models, a number of avenues for further improvement remain. By including data from winter months, the model’s seasonal generalizability may be improved. Additionally, key predictors such as electricity prices, socio-economic indicators, and local infrastructure characteristics were not included. Incorporating such variables in future research may lead to further improvements in forecasting performance. Overall, the findings demonstrate that data-driven forecasting approaches can substantially improve substation-level load prediction, providing a strong foundation for more effective grid loss detection.
Ultimately, while the forecasting models developed in this study do not reduce grid loss directly, their value lies in strengthening the operational detection mechanisms used by grid operators. More accurate and temporally precise load forecasts allow deviations from expected consumption to be identified earlier and more reliably, enabling faster and more targeted interventions against electricity theft, defective meters, or cable faults. As a result, the improved forecasting accuracy demonstrated in this study provides a concrete pathway toward reducing energy losses in real-world grid operations.
Funding
This research received no external funding.
Data Availability Statement
The data used in this study were provided by Enexis under a research collaboration agreement and are not publicly available due to privacy restrictions on substation-level electricity load data. Restricted access to the data may be granted by Enexis upon reasonable request to the corresponding author.
Acknowledgments
I would like to express gratitude to Michaela Kesina for her guidance throughout this research journey. Additionally, I extend my sincere thanks to Dimaros, Enexis, and MFFBAS for granting me the opportunity to delve into a fascinating and valuable area of study.
Conflicts of Interest
The author declares no conflicts of interest.
Appendix A. Grid Loss Information
Appendix A.1. Why Grid Loss Should Be Tackled
There are several compelling reasons to address grid loss. Due to climate change and exacerbated by the Russia–Ukraine conflict that began in February 2022, an energy crisis has emerged, significantly increasing price volatility in the energy market. This, combined with a strong dependence on fluctuating electricity prices and partly short-term electricity purchases, has led to a sharp rise in electricity prices and, consequently, elevated grid loss costs.
Additionally, addressing grid loss involves mitigating fraud and theft, including dismantling illicit operations such as cannabis farms. In 2019 alone, electricity theft was identified in 2300 cannabis farms, illegally tapping a total of 114 million kilowatt-hours (kWh) of electricity. This not only entails high costs but also creates fire hazards due to illicit and improperly installed grid connections, especially as these illegal farms increasingly appear in residential areas [1].
Grid loss significantly contributes to environmental harm as well. Notably, 98 percent of Enexis’s CO2 footprint stems from grid losses. The annual grid loss equates to the annual load of 400,000 households [44]. Liander, another significant Dutch grid operator, mitigates this by “greening” their grid losses, investing in renewable energy sources to offset their impact. In 2018 alone, 187 kilotons of their total grid losses were greened [45]. However, until grid losses become entirely CO2 neutral, they will continue to harm the environment.
While grid operators initially absorb the cost of grid loss, a significant portion is eventually transferred to retailers, affecting retail energy consumers. Consequently, as grid operators face higher costs, retail prices for customers also rise, leading to increased payment defaults, which further exacerbates grid loss.
Appendix A.2. How Grid Loss Is Composed
Grid loss can be broadly categorized into two categories:
- Technical losses: these are the losses that occur naturally and are inevitable due to the physical properties of the components used in the transmission and distribution of electricity. They can be further classified as:
- Transmission losses: These occur in the transmission system due to the resistance and reactance of the transmission lines.
- Distribution losses: These occur in the distribution system and are due to the resistance of the Transformers, conductors, and other equipment.
- Non-technical losses: these are losses that are not due to the physical properties of the system but are instead caused by external factors. They include:
- Fraud and theft: this includes illegal tapping of lines by for example cannabis farms, bypassing meters, and other unauthorized usages.
- Metering inaccuracies: occasionally, the meters used to measure electricity load can be inaccurate, leading to discrepancies in billed and actual load.
- Billing errors: mistakes in the billing process can also lead to non-technical losses.
- Default on payment: though not a loss in the traditional sense, utilities consider electricity that is consumed but not paid for as a loss.
To illustrate, in 2011, grid loss in the Netherlands was approximately 5400 gigawatt-hours (GWh) per year, divided into 70 percent technical and 30 percent non-technical losses, with fraud and theft accounting for about 20 percent of the latter [46]. A poignant example is the dismantling of approximately 5262 cannabis farms involved in electricity theft in 2013. The electricity theft by these farms, often due to illicit connections to the grid, was responsible for a significant portion of grid loss, estimated between 609 and 994 GWh [47]. The high electricity load of these farms, often running for 12 to 18 h daily, coupled with the risks posed by their poor installation practices, not only leads to financial losses but also creates fire hazards. These risks are exacerbated by the increasing prevalence of such farms in residential areas, posing dangers to unsuspecting inhabitants [1].
Appendix B. Composition of Independent Variables
Appendix B.1. Standard Correction
The standard correction is derived from a dynamic load profile, which, when multiplied by the estimated average annual electricity usage, yields the electricity load in kilowatt-hours (kWh) for a specific cable in a specific grid area. Essentially, it is an approach to estimate the electricity load of a large group of connections over a short period based on the estimated annual load. By aggregating these estimates for all cables connected to a specific electrical substation within a quarter-hour time frame, we can approximate the total electricity load for that substation in a given quarter-hour period. This approach allows us to construct a picture of the substation’s load patterns based on the individual contributions of each connected cable.
The dynamic load profile, arithmetic rounded to eight decimal places, for a specific date is available two days later and is based on measurement data from several hundred thousand connections. It is a fraction derived by dividing the total volume of electricity consumed in a specific quarter-hour time frame by a specific cable within a certain grid area, by the estimated total annual electricity load of that specific cable in the same grid area. Each fraction thus represents a part of the total amount of electricity expected to be used in that year by a specific cable, and all fractions added up equals approximately one.
In a mathematical representation, the estimate for the total amount of electricity consumed in a specific quarter-hour interval t by electrical substation i with connected cables , i.e., the standard correction, is calculated by
where indicates the estimated total annual electricity load of cables of type k in the grid area of electrical substation i at the year of quarter-hour interval t. is the load profile of cable k at quarter-hour interval t in the grid area of electrical substation i and is thus derived as
with indicating the total volume consumed in quarter-hour interval t by all cables of type k in the grid area of electrical substation i combined.
Appendix B.2. Holiday
The holidays we take into consideration are
- 1.
- Good Friday: differs each year. Good Friday is the Friday before Easter. On this day, Christians commemorate the crucifixion and death of Jesus.
- 2.
- Easter: differs each year. Easter falls on the first Sunday and Monday after the first full moon in spring. On these days it is celebrated that Jesus rose from the dead, on the Sunday after his crucifixion.
- 3.
- King’s Day: 27 April. It is the birthday of the Dutch king.
- 4.
- Liberation Day: 5 May, once every five years. It is the day on which the liberation from the German occupation in the Netherlands in 1945 is celebrated annually. However, only once in the five years it is considered as a day off, where 2020 was the last time.
- 5.
- Ascension Day: differs each year. Ascension Day or the Lord’s Ascension commemorates in Christianity that Jesus Christ ascended to God, his Father in heaven, 39 days after his resurrection from the dead. Hence, it falls on a Thursday every year, exactly forty days after Easter.
- 6.
- Pentecost: differs each year. First Pentecost falls every year on a Sunday, the 10th day after Ascension Day and the 50th day after Easter Sunday. A day later it is the second day of Pentecost, called Whit Monday. Pentecost is derived from the Greek word ‘pentekostè’, which means fifty. We commemorate the descent of the Holy Spirit on the apostles and the origins of the Christian church.
There are no government-imposed rules regarding which public holidays employees are required to have off [48]. However, most people generally have these days off, except for those working in supermarkets and the hotel and catering industry. Additionally, we only include holidays that do not fall on weekends.
Note that these are the holidays encountered within our current dataset. As the dataset expands, additional holidays should be included.
Appendix C. Econometric Issues
Appendix C.1. Overfitting
Overfitting is a common challenge in statistical modeling, particularly in the context of machine learning. It occurs when a model learns the training data too well, including the noise and random fluctuations. As a result, the model performs exceptionally on the training data but fails to generalize to unseen data, leading to poor predictive performance when encountering new, out-of-sample data.
The complexity of a model is a primary factor contributing to overfitting. Models with an excessive number of parameters or those that are too flexible can capture spurious patterns that do not represent the underlying data-generating process. To detect overfitting, we compare each model’s in-sample error, computed on the data used to fit it, against its error on the independent, chronologically later test set used for the main evaluation in Table 5. A substantially larger error on the test set than on the training data indicates that the model may be capturing noise specific to the training period rather than the underlying signal, and is therefore not generalizing well to genuinely new observations.
In our research, we employed the following strategy to detect overfitting:
- Training versus test comparison: For every model, we use the same final, tuned model underlying the results reported in Table 5 (i.e., fitted on the training and validation data with its optimal hyperparameters). We compute the Mean Squared Error (MSE) of this model on the data used to fit it (training error) and on the held-out test set (test error). Because the test set is chronologically later than, and disjoint from, the training data, this comparison reflects the model’s ability to generalize to genuinely unseen, future observations, rather than relying on a separate, differently-timed validation sample. (For the two bagging-based ensemble methods (Random Forests and Bagging Regression), the model’s out-of-bag (OOB) error is used in place of a naive in-sample training error, since predicting on the same data used to build a bagging ensemble is known to be overly optimistic—each observation has typically already been “seen” by most of the individual trees during their own bootstrap resampling. The OOB error, which evaluates each observation only using the subset of trees that did not include it in their bootstrap sample, avoids this bias and is the standard alternative for this model family).
- Threshold-based evaluation: To determine whether a model exhibits overfitting, we set a threshold of five percent: if the test error exceeds the training error by more than this percentage, the model is considered to potentially be overfitting, as its performance on the data used for fitting appreciably exceeds its performance on genuinely unseen data.
If overfitting is detected, we implement corrective measures such as simplifying the model by removing non-significant variables, introducing regularization techniques like Lasso (L1) and Ridge (L2), or gathering more data to improve the model’s training process. These steps are designed to mitigate the effects of overfitting and aim to strike a balance between model complexity and predictive accuracy. While these measures significantly contribute to enhancing the model’s robustness, it is important to acknowledge that completely eliminating overfitting is challenging, especially in complex models. Therefore, our efforts are focused on reducing the impact of overfitting to ensure the model performs well on new, unseen data.
Appendix C.2. Multicollinearity
Multicollinearity arises when two or more independent variables in a regression model are highly correlated, which makes it difficult for models to ascertain the effect of individual variables on the dependent variable.
In our study, multicollinearity can be an issue due to the inclusion of various correlated predictors, such as temperature and other weather-related variables. Therefore, we check for multicollinearity using Variance Inflation Factors (VIFs). When multicollinearity is detected, we address it by removing or combining collinear variables, or by using dimensionality reduction techniques such as Principal Component Analysis (PCA).
VIF quantifies how much the variance of an estimated regression coefficient is inflated due to multicollinearity among the predictor variables. A VIF of one indicates no correlation among the ith predictor and the rest. Values above five (or ten, more conservatively) suggest problematic multicollinearity [49]. Fortunately, in this research, the VIF does not exceed two and a half, so we do not need to address multicollinearity. Detailed results of the VIF analysis can be found in Appendix E.1.
Appendix C.3. Autocorrelation
In the context of forecasting electricity load using statistical time series and machine learning models, autocorrelation is a pivotal factor that can influence model accuracy. Autocorrelation occurs when a time series exhibits correlation with its own past and future values. For instance, electricity load at time t is often correlated with load at time .
The presence of autocorrelation in the residuals of our models can significantly impact their forecasting performance. If a model fails to account for autocorrelation, it might not accurately capture the underlying temporal dynamics of electricity load, potentially leading to over- or under-estimation of future values.
To assess autocorrelation in our models, we analyze the residuals using tools such as the Autocorrelation Function (ACF) plot and the Ljung–Box test. The ACF plot helps to visualize the degree of autocorrelation in the residuals at different lags, identifying any patterns such as seasonal effects or cyclic behaviors. Significant spikes outside the confidence interval in the ACF plot indicate notable autocorrelation. Similarly, the Ljung–Box test provides a quantitative assessment of autocorrelation in the residuals. It tests the overall randomness based on a group of autocorrelations for a specified number of lags. A significant p-value (i.e., p-value < 0.05) indicates the presence of autocorrelation, underscoring the need for model adjustment to improve forecasting accuracy.
Since significant autocorrelation in the residuals is detected across all models, we will address this issue by incorporating lagged variables, as detailed in Section 4.1.1. While the complete elimination of autocorrelation may not always be feasible, this approach is expected to substantially reduce its impact.
Appendix C.4. Non-Stationarity
Non-stationarity in time series data significantly affects the accuracy of forecasting models. A time series is deemed non-stationary when its statistical properties, such as mean, variance, and autocorrelation, change over time. This can lead to unreliable and misleading forecasts, as the model’s underlying assumptions are often violated. Especially in machine learning models, the assumption of stationary relationships is crucial for model training and prediction accuracy. When this assumption is violated by non-stationary data, models may struggle to generalize over time, ultimately affecting their predictive performance.
The Augmented Dickey–Fuller (ADF) test, a widely used method to assess stationarity, focuses on identifying a unit root in the time series, indicative of non-stationarity. The ADF test operates under the null hypothesis that the time series has a unit root. Thus, if the p-value is below a specified significance level (e.g., p-value < 0.05), we reject the null hypothesis, indicating that the series is stationary. If non-stationarity is detected, techniques like differencing, logarithmic transformation, or decomposition can be applied to stabilize the mean and variance over time.
Fortunately, our analysis confirmed stationarity in the time series at the five percent significance level (p-value < 0.05), laying a solid foundation for accurate modeling and forecasting.
Appendix D. Diebold–Mariano Test
The Diebold–Mariano test operates by focusing on the differences in forecasting errors of two models over the same period. The steps involved are as follows:
- 1.
- Calculation of forecast errors: For each model, forecast errors are calculated as the difference between the actual and the predicted values of electricity load in the test set.
- 2.
- Error differences: The test then considers the squared differences in these errors between the two models. Specifically, for each time point, the squared error of model two is subtracted from the squared error of model one. This method emphasizes the model with lower squared errors, indicating better performance.
- 3.
- Test statistic: The Diebold–Mariano test statistic is derived from the average of these squared error differences. To account for variability in these differences, this mean is divided by the standard deviation of the differences. This calculation normalizes the differences, allowing for a comparison against a standard normal distribution under the null hypothesis. The null hypothesis states that there is no difference in predictive accuracy between the models. The resulting test statistic, therefore, follows a standard normal distribution if the null hypothesis holds true.
- 4.
- Decision-making: The computed Diebold–Mariano test statistic is compared against a critical value from the standard normal distribution. For a 95 percent confidence level, the critical value is approximately ±1.96. If the absolute value of the test statistic exceeds this critical value, the null hypothesis, which posits no difference in predictive accuracy between the two models, is rejected. This indicates a statistically significant difference in forecasting accuracy between the two models. Specifically, if the test statistic is positive and significant, it implies that the second model outperforms the first; conversely, a negative and significant statistic suggests that the first model outperforms the second.
Appendix E. Model Optimization and Evaluation Results
Appendix E.1. Results of the Variance Inflation Factors (VIFs)
Table A1.
VIF results.
Appendix E.2. Hyperparameter Optimization Results
Appendix E.2.1. Decision Trees
- Regular variant: Optimal tree depth = 6.
- Lagged variant: Optimal tree depth = 3.
Appendix E.2.2. Random Forests
- Regular variant: Optimal mtry = 6, optimal number of trees = 900.
- Lagged variant: Optimal mtry = 4, optimal number of trees = 1000.
Appendix E.2.3. Bagging Regression
- Regular variant: Optimal number of trees = 100.
- Lagged variant: Optimal number of trees = 500.
Appendix E.2.4. Gradient Boosting Machine (GBM)
- Regular variant:
- –
- Optimal number of trees = 1000;
- –
- Optimal tree depth = 5;
- –
- Optimal learning rate = 0.1;
- –
- Optimal minimum number of observations in nodes = 20.
- Lagged variant:
- –
- Optimal number of trees = 500;
- –
- Other parameters as per regular variant.
Appendix E.2.5. Extreme Gradient Boosting (XGBoost)
- Regular variant:
- –
- Optimal number of boosting rounds = 300;
- –
- Optimal learning rate = 0.01;
- –
- Optimal maximum tree depth = 6;
- –
- Optimal minimum child weight = 10;
- –
- Optimal gamma = 0.2;
- –
- Optimal subsample = 0.5;
- –
- Optimal colsample_bytree = 0.5.
- Lagged variant:
- –
- Optimal number of boosting rounds = 300;
- –
- Optimal learning rate = 0.1;
- –
- Optimal maximum tree depth = 3;
- –
- Optimal minimum child weight = 1;
- –
- Optimal gamma = 0;
- –
- Optimal subsample = 0.7;
- –
- Optimal colsample_bytree = 1.
Appendix E.2.6. Feedforward Neural Network (FNN)
- Regular variant:
- –
- Optimal size for hidden layer = 9;
- –
- Optimal weight decay rate = 0.001.
- Lagged variant:
- –
- Optimal size for hidden layer = 9;
- –
- Optimal weight decay rate = 0.001.
Appendix E.2.7. Support Vector Regression (SVR)
- Regular variant:
- –
- Optimal cost = 100;
- –
- Optimal epsilon = 0.5;
- –
- Optimal gamma = 0.01.
- Lagged variant:
- –
- Optimal cost = 1;
- –
- Optimal epsilon = 0.5;
- –
- Optimal gamma = 0.01.
Appendix E.2.8. k-Nearest Neighbors (kNN)
- Regular variant: Optimal k value = 20. (The tuning grid was limited to ; since the optimum was found at the upper boundary of this range, the true optimal k may lie beyond it).
- Lagged variant: Optimal k value = 20.
Appendix E.3. Computation Times
Table A2.
Computation times for model fitting and prediction.
Note that for the OLS and statistical time series models, model fitting is performed on the entire dataset, comprising 37,237 observations. In contrast, for the machine learning models, the fitting process involves only the training and validation sets, accounting for 85 percent of the whole dataset, equal to 31,650 observations. Predictions for all models are executed solely on the test set, which represents 15 percent of the total dataset, equal to 5587 observations.
Moreover, for the k-Nearest Neighbors (kNN) model, traditional model fitting as in other algorithms is not applicable. kNN operates by comparing new data points with the existing ones in the training set to determine the closest neighbors. This method does not involve creating an explicit model based on the training data; instead, it uses the combined training and validation datasets for prediction. Therefore, computation time for model fitting is not relevant for kNN, and its performance is directly linked to its prediction phase, where it searches for the nearest neighbors in the dataset.
References
- Nederland, N. Hennepkwekerijen Stelen 114 Miljoen kWh Stroom in 2019. 2020. Available online: https://www.netbeheernederland.nl/nieuws/hennepkwekerijen-stelen-114-miljoen-kwh-stroom-in-2019-1344 (accessed on 26 November 2023).
- Stedin. Stedin Year Report 2022. Technical Report. 2022. Available online: https://jaarverslag.stedingroep.nl/2022/xmlpages/resources/TXP/Stedin/financieel_groep_verslag_2022/pdf/Stedin_Groep_Jaarverslag_2022.pdf (accessed on 23 November 2023).
- Nederland, N. In 2022 Is 75 Miljoen kwh Energiediefstal Ontdekt. 2023. Available online: https://www.netbeheernederland.nl/artikelen/nieuws/2022-75-miljoen-kwh-energiediefstal-ontdekt (accessed on 26 November 2023).
- Javaid, N.; Hafeez, G.; Iqbal, S.; Alrajeh, N.; Alabed, M.S.; Guizani, M. Energy efficient integration of renewable energy sources in the smart grid for demand side management. IEEE Access 2018, 6, 77077–77096. [Google Scholar] [CrossRef] [Scilit]
- Ionescu, L.M.; Bizon, N.; Mazare, A.G.; Belu, N. Reducing the cost of electricity by optimizing real-time consumer planning using a new genetic algorithm-based strategy. Mathematics 2020, 8, 1144. [Google Scholar] [CrossRef] [Scilit]
- Adil, M.; Javaid, N.; Ullah, Z.; Maqsood, M.; Ali, S.; Daud, M.A. Electricity theft detection using machine learning techniques to secure smart grid. In Proceedings of the Complex, Intelligent and Software Intensive Systems: Proceedings of the 14th International Conference on Complex, Intelligent and Software Intensive Systems (CISIS-2020); Springer: Berlin/Heidelberg, Germany, 2021; pp. 233–243. [Google Scholar]
- Iftikhar, H.; Khan, N.; Raza, M.A.; Abbas, G.; Khan, M.; Aoudia, M.; Touti, E.; Emara, A. Electricity theft detection in smart grid using machine learning. Front. Energy Res. 2024, 12, 1383090. [Google Scholar] [CrossRef] [Scilit]
- Voyez, A.; Allard, T.; Avoine, G.; Cauchois, P.; Fromont, E.; Simonin, M. Unique in the smart grid-the privacy cost of fine-grained electrical consumption data. arXiv 2022, arXiv:2211.07205. [Google Scholar]
- Gajowniczek, K.; Ząbkowski, T. Electricity forecasting on the individual household level enhanced based on activity patterns. PLoS ONE 2017, 12, e0174098. [Google Scholar] [CrossRef] [Scilit]
- Diebold, F.X.; Mariano, R.S. Comparing predictive accuracy. J. Bus. Econ. Stat. 2002, 20, 134–144. [Google Scholar] [CrossRef] [Scilit]
- Fahad, M.U.; Arbab, N. Factor affecting short term load forecasting. J. Clean Energy Technol. 2014, 2, 305–309. [Google Scholar] [CrossRef] [Scilit]
- Dong, H.; Gao, Y.; Meng, X.; Fang, Y. A multifactorial short-term load forecasting model combined with periodic and non-periodic features-a case study of qingdao, China. IEEE Access 2020, 8, 67416–67425. [Google Scholar] [CrossRef] [Scilit]
- Sood, R.; Koprinska, I.; Agelidis, V.G. Electricity load forecasting based on autocorrelation analysis. In Proceedings of the 2010 International Joint Conference on Neural Networks (IJCNN), Barcelona, Spain, 18–23 July 2010; pp. 1–8. [Google Scholar]
- Shilpa, G.; Sheshadri, G. ARIMAX model for short-term electrical load forecasting. Int. J. Recent Technol. Eng. (IJRTE) 2019, 8, 2786–2790. [Google Scholar] [CrossRef] [Scilit]
- Elamin, N.; Fukushige, M. Modeling and forecasting hourly electricity demand by SARIMAX with interactions. Energy 2018, 165, 257–268. [Google Scholar] [CrossRef] [Scilit]
- Henzel, J.; Wróbel, Ł.; Fice, M.; Sikora, M. Energy consumption forecasting for the digital-twin model of the building. Energies 2022, 15, 4318. [Google Scholar] [CrossRef] [Scilit]
- Kadurek, P.; Blom, J.; Cobben, J.F.G.; Kling, W.L. Theft detection and smart metering practices and expectations in the Netherlands. In Proceedings of the 2010 IEEE PES Innovative Smart Grid Technologies Conference Europe (ISGT Europe), Gothenburg, Sweden, 11–13 October 2010; pp. 1–6. [Google Scholar]
- Ford, V.; Siraj, A.; Eberle, W. Smart grid energy fraud detection using artificial neural networks. In Proceedings of the 2014 IEEE Symposium on Computational Intelligence Applications in Smart Grid (CIASG), Orlando, FL, USA, 9–12 December 2014; pp. 1–6. [Google Scholar]
- Hollingsworth, K.; Rouse, K.; Cho, J.; Harris, A.; Sartipi, M.; Sozer, S.; Enevoldson, B. Energy anomaly detection with forecasting and deep learning. In Proceedings of the 2018 IEEE International Conference on Big Data (Big Data), Seattle, WA, USA, 10–13 December 2018; pp. 4921–4925. [Google Scholar]
- Luo, X.; Oyedele, L.O.; Ajayi, A.O.; Akinade, O.O.; Delgado, J.M.D.; Owolabi, H.A.; Ahmed, A. Genetic algorithm-determined deep feedforward neural network architecture for predicting electricity consumption in real buildings. Energy AI 2020, 2, 100015. [Google Scholar] [CrossRef] [Scilit]
- Wahid, F.; Kim, D. A prediction approach for demand analysis of energy consumption using k-nearest neighbor in residential buildings. Int. J. Smart Home 2016, 10, 97–108. [Google Scholar] [CrossRef] [Scilit]
- Paudel, S.; Elmitri, M.; Couturier, S.; Nguyen, P.H.; Kamphuis, R.; Lacarrière, B.; Le Corre, O. A relevant data selection method for energy consumption prediction of low energy building based on support vector machine. Energy Build. 2017, 138, 240–256. [Google Scholar] [CrossRef] [Scilit]
- Zhong, H.; Wang, J.; Jia, H.; Mu, Y.; Lv, S. Vector field-based support vector regression for building energy consumption prediction. Appl. Energy 2019, 242, 403–414. [Google Scholar] [CrossRef] [Scilit]
- Edwards, R.E.; New, J.; Parker, L.E. Predicting future hourly residential electrical consumption: A machine learning case study. Energy Build. 2012, 49, 591–603. [Google Scholar] [CrossRef] [Scilit]
- Bashir, A.K.; Khan, S.; Prabadevi, B.; Deepa, N.; Alnumay, W.S.; Gadekallu, T.R.; Maddikunta, P.K.R. Comparative analysis of machine learning algorithms for prediction of smart grid stability. Int. Trans. Electr. Energy Syst. 2021, 31, e12706. [Google Scholar] [CrossRef] [Scilit]
- Nie, P.; Roccotelli, M.; Fanti, M.P.; Ming, Z.; Li, Z. Prediction of home energy consumption based on gradient boosting regression tree. Energy Rep. 2021, 7, 1246–1255. [Google Scholar] [CrossRef] [Scilit]
- Touzani, S.; Granderson, J.; Fernandes, S. Gradient boosting machine for modeling the energy consumption of commercial buildings. Energy Build. 2018, 158, 1533–1543. [Google Scholar] [CrossRef] [Scilit]
- González, C.; Mira-McWilliams, J.; Juárez, I. Important variable assessment and electricity price forecasting based on regression tree models: Classification and regression trees, Bagging and Random Forests. IET Gener. Transm. Distrib. 2015, 9, 1120–1128. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Haghani, A. A gradient boosting method to improve travel time prediction. Transp. Res. Part C Emerg. Technol. 2015, 58, 308–324. [Google Scholar] [CrossRef] [Scilit]
- Ma, F.; Yan, X. Research on the energy consumption estimation method of pure electric vehicle based on XGBoost. In Proceedings of the 2019 3rd International Conference on Electronic Information Technology and Computer Engineering (EITCE), Xiamen, China, 18–20 October 2019; pp. 1021–1026. [Google Scholar]
- Hertel, M.; Pütz, S.; Kolar, J.; Schäfer, B.; Mikut, R.; Hagenmeyer, V. A Benchmark for Electrical Load Forecasting Across Grid Levels: Time-Series Transformers Outperform Established Methods. arXiv 2026, arXiv:2607.15705. [Google Scholar]
- Ahmad, A.; Xiao, X.; Mo, H.; Dong, D. TFTformer: A novel transformer based model for short-term load forecasting. Int. J. Electr. Power Energy Syst. 2025, 166, 110549. [Google Scholar] [CrossRef] [Scilit]
- Khan, Z.A.; Hussain, T.; Ullah, A.; Rho, S.; Lee, M.; Baik, S.W. Towards efficient electricity forecasting in residential and commercial buildings: A novel hybrid CNN with a LSTM-AE based framework. Sensors 2020, 20, 1399. [Google Scholar] [CrossRef] [Scilit]
- Kumar, H.; Arora, P.; Panigrahi, B.K. Wind forecasting: Hybrid statistical and deep neural network approaches. In Proceedings of the 2018 3rd International Conference on Contemporary Computing and Informatics (IC3I), Gurgaon, India, 10–12 October 2018; pp. 62–67. [Google Scholar]
- Neshat, N.; Hadian, H.; Behzad, M. Nonlinear ARIMAX model for long–term sectoral demand forecasting. Manag. Sci. Lett. 2018, 8, 581–592. [Google Scholar] [CrossRef] [Scilit]
- Hambali, A.; Akinyemi, M.; JYusuf, N. Electric power load forecast using decision tree algorithms. Comput. Inf. Syst. Dev. Inform. Allied Res. J. 2016, 7, 29–42. [Google Scholar]
- Divina, F.; Gilson, A.; Goméz-Vela, F.; García Torres, M.; Torres, J.F. Stacking ensemble learning for short-term electricity consumption forecasting. Energies 2018, 11, 949. [Google Scholar] [CrossRef] [Scilit]
- University of Cincinnati. Regression Trees; Technical Report; University of Cincinnati: Cincinnati, OH, USA, 2018. [Google Scholar]
- Chen, Y.; Jia, Z.; Mercola, D.; Xie, X. A gradient boosting algorithm for survival analysis via direct optimization of concordance index. Comput. Math. Methods Med. 2013, 2013, 873595. [Google Scholar] [CrossRef] [Scilit]
- Reza, M. Galaxy morphology classification using automated machine learning. Astron. Comput. 2021, 37, 100492. [Google Scholar] [CrossRef] [Scilit]
- Vivas, E.; Allende-Cid, H.; Salas, R. A systematic review of statistical and machine learning methods for electrical power forecasting with reported mape score. Entropy 2020, 22, 1412. [Google Scholar] [CrossRef] [Scilit]
- MFFBAS. Sectordocumenten. 2023. Available online: https://www.mffbas.nl/documenten/ (accessed on 8 November 2023).
- Koninklijk Nederlands Meteorologisch Instituut (KNMI). Uurgegevens van het Weer in Nederland. 2023. Available online: https://www.knmi.nl/nederland-nu/klimatologie/uurgegevens (accessed on 10 November 2023).
- Enexis. Enexis Year Report 2022. Technical Report. 2022. Available online: https://jaarverslag.enexisgroep.nl/downloads (accessed on 23 November 2023).
- Alliander. Alliander Year Report 2022. Technical Report. 2022. Available online: https://annualreport.alliander.com/external/asset/download/project/f944830a-0416-0000-b759-6ed5a898c2f0/name/Alliander_Annual_Report_2022.pdf (accessed on 23 November 2023).
- Aalberts, A.; Dekker, G.; Jaarsma, S.; Tieben, B.; Vlug, N. Study on the Methodology for Allocating Costs of Grid Losses; Technical Report; KEMA: Arnhem, The Netherlands, 2011. [Google Scholar]
- Giessen, M.; Moolenaar, D.E.G.; van Ooyen-Houben, M.M.J. De Export van in Nederland Geteelde Cannabis; Technical Report; Wetenschappelijk Onderzoek- en Documentatiecentrum: The Hague, The Netherlands, 2014. [Google Scholar]
- Rijksoverheid. Wanneer Zijn de Officiële Feestdagen in Nederland? 2023. Available online: https://www.rijksoverheid.nl/onderwerpen/arbeidsovereenkomst-en-cao/vraag-en-antwoord/officiele-feestdagen (accessed on 8 November 2023).
- Akinwande, M.O.; Dikko, H.G.; Samson, A. Variance inflation factor: As a condition for the inclusion of suppressor variable(s) in regression analysis. Open J. Stat. 2015, 5, 754. [Google Scholar]
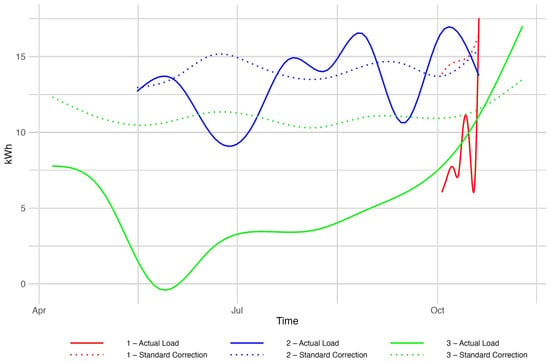
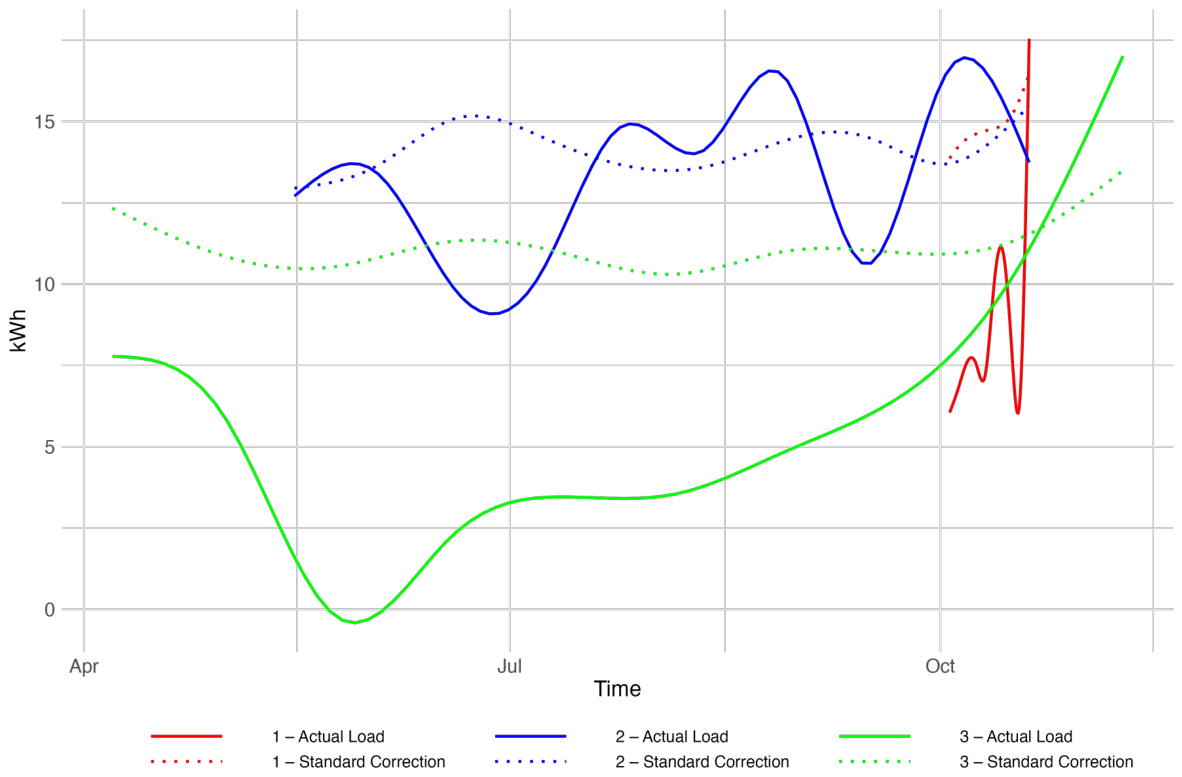
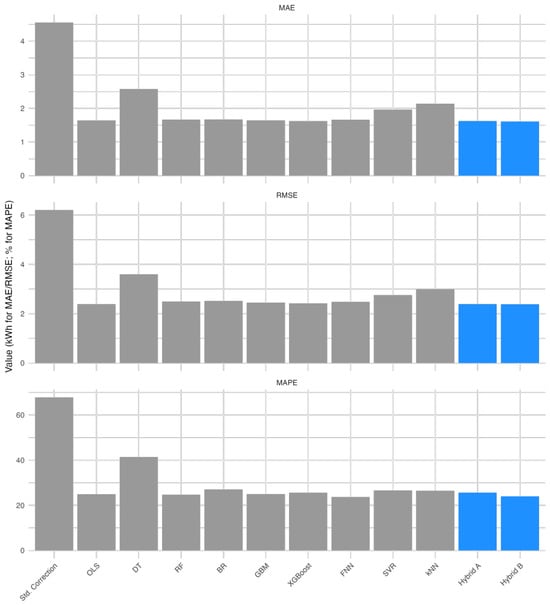
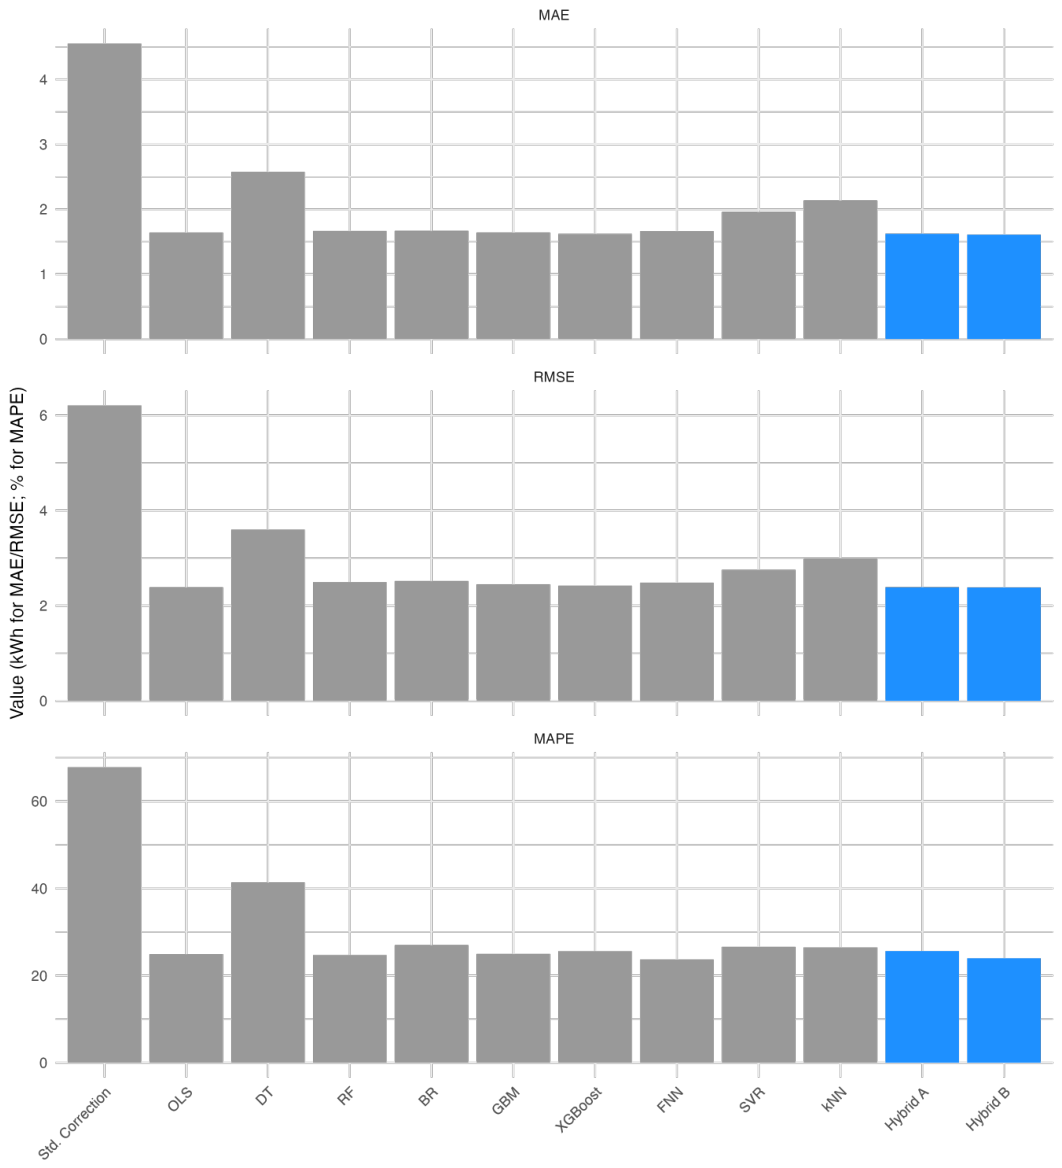
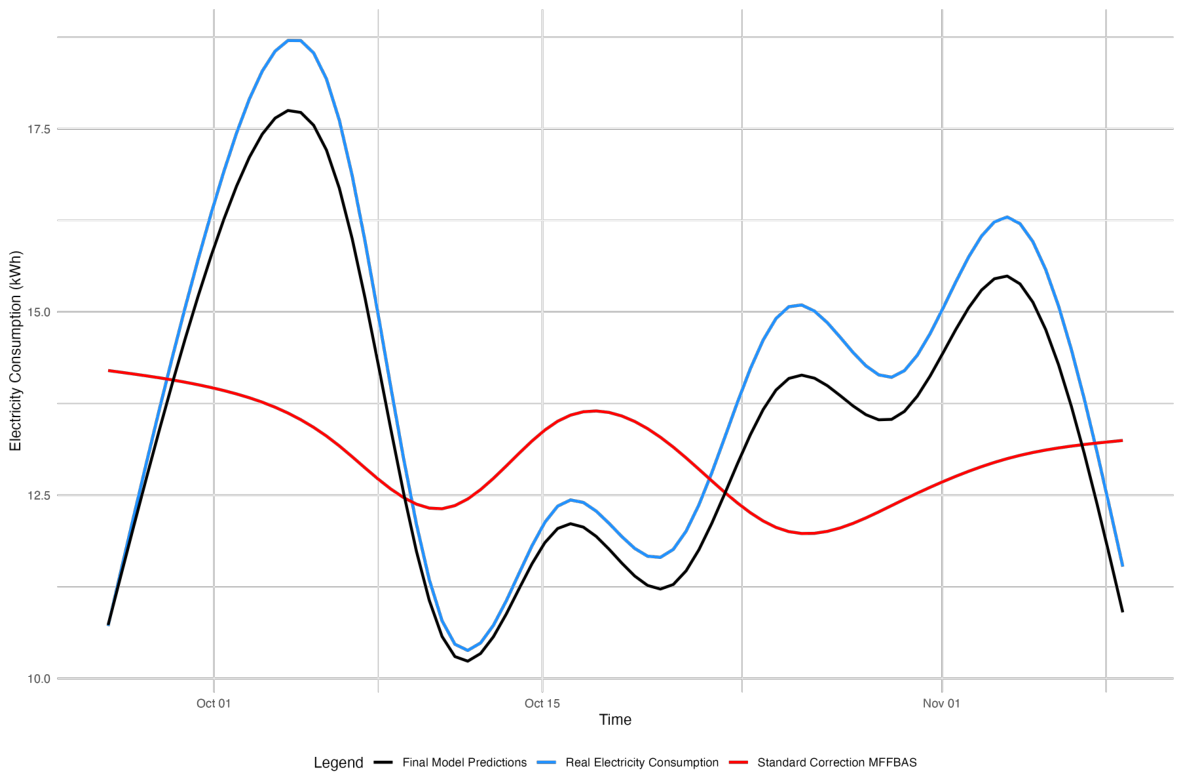
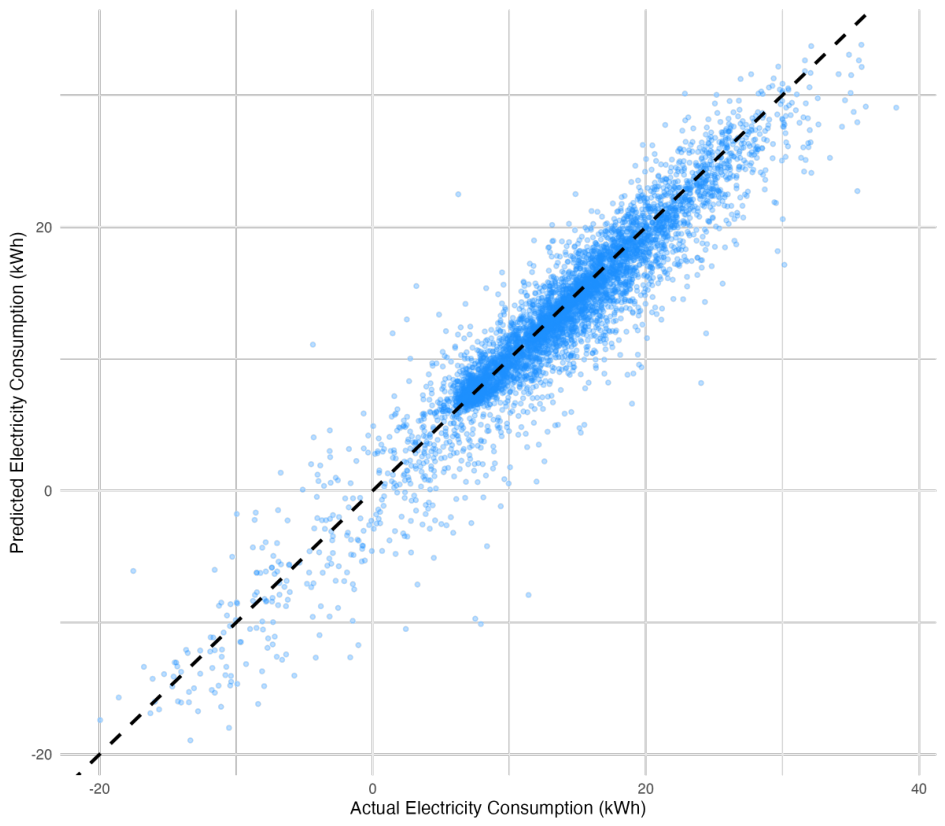
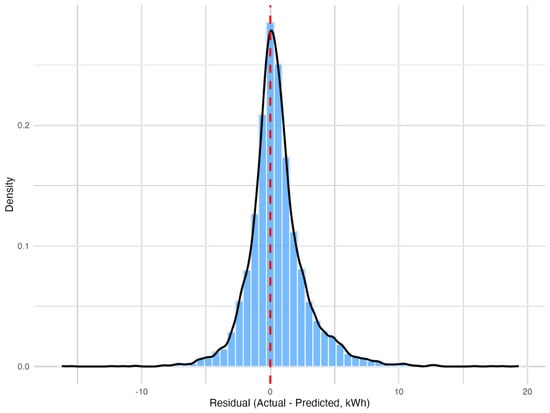
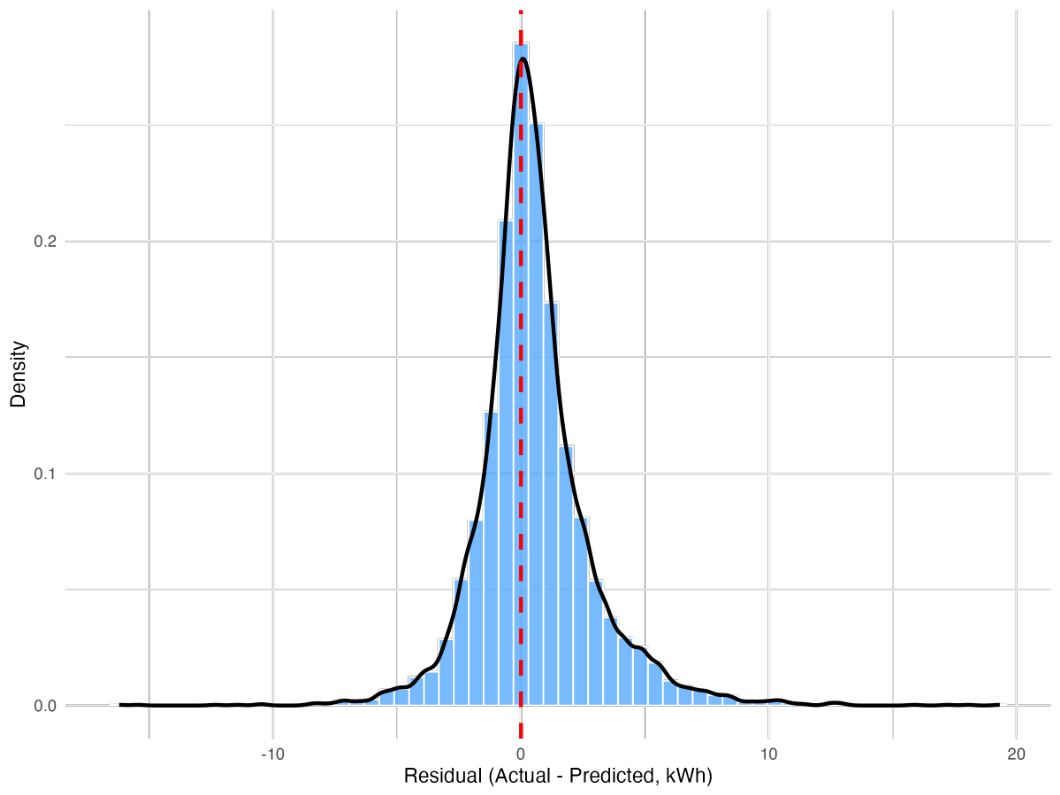

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the author. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.