


Abstract
The widespread adoption of autonomous vehicle technologies requires accurate predictions of coordinated multi-agent motion. While predicting such motion under arbitrary control mechanisms is generally intractable, this paper focuses on certain classes of optimal control where the system dynamics reduce to Lie-Poisson equations. In this context, the goal of the paper is to learn the dynamics solely from data, without prior knowledge of the control Hamiltonian or the inter-agent interaction laws. The main achievement of this paper is the introduction of Control Optimal Lie-Poisson Neural Networks (CO-LPNets), which are built from a composition of Poisson maps. By design, CO-LPNets preserve the system’s Casimir invariants to machine precision. The paper also demonstrates the completeness of these neural networks and highlights their representational efficiency. CO-LPNets are applied to systems of interacting particles on the and Lie groups, modeling coupled rigid body rotations and the spatial navigation of unmanned vehicles, respectively. Numerical evaluations confirm that CO-LPNets accurately learn the global phase-space dynamics from sparse data, faithfully reproducing trajectories over hundreds of time steps. Furthermore, the paper demonstrates the robustness of the architecture against observational noise. Requiring minimal training data (∼200 points per dimension) and highly compact architectures (∼1000 parameters), CO-LPNets offer a highly efficient, structure-preserving solution well-suited for practical edge deployment in autonomous systems.
MSC:
70H33; 70Q05; 68T07
1. Problem Setup and General Approach
Understanding and predicting the collective motion of interacting unmanned vehicles is becoming increasingly important for different everyday uses. Mathematically, the problem considered in this article can be formulated as follows. Suppose we observe the evolution of a system of N interacting elements, each of them evolving in its own phase space. For the unmanned aerial vehicles (UAVs) or underwater drones, the phase space of the individual particle is the Lie group , where is the group of rotations and translations in three-dimensional space. For land-based drones or drones operating on the sea surface, the phase space is the Lie group . Thus, in general, practical applications of unmanned vehicles are occurring on some Lie group G. Suppose that we have observations of each particle of the system, and we know that the objects are connected and controlled, but we have limited information about the actual control procedure and the connection between them. The goal is to predict the collective motion of the system from the data, without the need to decipher the actual information about the method of control. For simplicity of reading, the list of main notations used in this article is shown in Table 1.
Table 1.
List of main notaions.
In its most general formulation, without any information about the control, the prediction of motion is likely impossible. However, with some limited assumptions about the nature of control, a solution to this problem can be found. In what follows, we assume that the collective behavior comes from the optimal control procedure. The process of reducing the symmetry of collective behavior problems using optimal control was developed by Justh and Krishnaprasad [1,2]. These papers show that the control Hamiltonians are of the type allowing complete reduction to coupled Lie-Poisson systems. This paper is devoted to the prediction of the motion exactly in the case of complete Lie-Poisson reduction, as described in [1,2]. Without any knowledge of the system, the actual control Hamiltonian, depending on the directions of control and the control amplitudes, cannot be recovered completely. However, instead of learning the Hamiltonian and the nature of control, the article recreates phase space trajectories and predicts the dynamics of the system in the future, based on the available data observations only, for an arbitrary control Hamiltonian. This goal is fulfilled due to the proposal of a new type of neural network, which we call CO-LPNets (Control Optimal Lie–Poisson Neural Networks), which are a generalization of Lie-Poisson Neural Networks [3] for the problems of optimal control of multiple interacting vehicles.
1.1. Data-Driven Discovery of Differential Equations with Structure
Recent advancements in scientific machine learning focus heavily on identifying the governing dynamics of physical systems from observational data. For autonomous systems evolving on a state space manifold, this typically involves reconstructing the underlying phase flow from a discrete sequence of observed states .
While generic, unconstrained neural networks excel at interpolating data, they frequently fail in engineering and physics applications where long-term stability hinges on respecting known conservation laws. To address this, frameworks like Physics-Informed Neural Networks (PINNs) [4,5] introduce physical boundaries and structural residuals directly into the loss function. However, because PINNs rely on optimization-based soft constraints, they regularly exhibit optimization failures, spectral bias, and severe error accumulation when applied to highly structured geometric systems, such as canonical Hamiltonian or Lie–Poisson dynamics [6]. For these systems, minor violations of the underlying geometry accumulate over time, destroying the qualitative correctness of long-term trajectories. Consequently, the work presented in this article shifts the focus from soft-penalty architectures to exact, structure-preserving data-driven representations.
1.2. Continuous vs. Discrete Geometric Learning Paradigms
Data-driven geometric computing generally splits into two distinct methodological paradigms based on how time is treated:
- 1.
- Continuous Operator Learning: This paradigm aims to learn the continuous-time vector field or infinitesimal flow of the dynamics, modeling the governing operator as . In structured settings, e.g., describing a Hamiltonian system, approaches like Hamiltonian Neural Networks (HNNs) [7] parameterize the vector field via a learned Hamiltonian function. While effective, a significant drawback of this approach is that generating actual trajectories requires pairing the learned model with an external, secondary numerical scheme (e.g., a structure-preserving integrator [8]). Any discretization error introduced by this secondary solver can still degrade the physical invariants.
- 2.
- Discrete Flow-Map Learning: Rather than approximating the continuous vector field, this paradigm directly learns the discrete-time flow map over a fixed time step h. Trajectories are generated strictly through recursive map composition: . This architecture inherently bypasses the need for an external ODE solver. Existing literature has successfully leveraged this framework for canonical systems via SympNets [9] and extended it to non-canonical Poisson spaces [3,10,11,12,13].
The methodology developed in this paper uses the discrete data-driven computing paradigm. In other words, we learn discrete mappings and not the Hamiltonian.
By directly identifying the discrete flow map on the reduced space , our framework eliminates the accumulation of artificial dissipation typical of continuous-operator approximations. As detailed in the subsequent sections, embedding the Lie–Poisson geometry directly into the network architecture allows our model to preserve non-canonical invariant quantities—specifically, Casimir functions—to machine precision indefinitely, ensuring long-term bounded energy errors and stable rollout trajectories even within chaotic regimes.
2. Literature Review
2.1. Data-Based, Structure-Preserving Computing of Poisson Systems
2.1.1. Continuous Systems with Structure
Since the focus of this paper is the data-based computing of control-Hamiltonian systems, a short review of the recent progress in that field is presented below.
Various methodologies exist for applying physics-informed data techniques to Hamiltonian systems while respecting their intrinsic mathematical architecture. Much of the existing literature focuses on canonical Hamiltonian systems, where the state vector is -dimensional, composed of n-dimensional coordinates and n-dimensional momenta ; thus, . In these cases, the evolution equation is governed by a Hamiltonian function , such that the operator takes the form:
where represents the identity matrix. Thus, is a matrix. For an arbitrary smooth function , its’ time evolution along a trajectory of (1) is defined by the canonical Poisson bracket:
This bracket acts as a mapping that transforms two smooth functions into another smooth function of the same variables. Mathematically, it is a bilinear, antisymmetric operator acting on differentiable function, which satisfies the Leibniz rule (acting as a derivative), and fulfills the Jacobi identity:
for all smooth functions . Brackets that possess these four properties but differ from the form in (2) are categorized as general or non-canonical Poisson brackets. The resulting equations of motion are called Hamiltonian (usually for canonical brackets) or Poisson systems, for non-canonical Hamiltonian brackets. The non-canonical systems frequently possess a non-trivial null space, leading to the preservation of specific quantities known as Casimir invariants (or Casimirs). These invariants are structural features of the Poisson bracket itself, which remain constant regardless of the specific Hamiltonian chosen. This proposal concentrates on data-driven computational strategies for a significant class of these non-canonical Poisson systems.
One prominent research direction focuses on extracting the system’s Hamiltonian or its underlying Poisson bracket directly from observed data. This approach was pioneered for canonical systems by Hamiltonian Neural Networks (HNN) [7], which approximate by fitting the observed state evolution through the relations in (1). This approach, respecting the structure of the equations, allows more robust and accurate trajectory approximations than standard neural networks. This approach has been further refined to handle chaotic transitions and adaptive parameter learning [14], with theoretical foundations for the existence of such learned Hamiltonians established in [15].
An alternative strategy is found in Lagrangian Neural Networks (LNNs) [16], which model the Euler-Lagrange equations in the coordinate-velocity space, bypassing the need for a Legendre transform to coordinates. More recently, learning vector fields for non-canonical Poisson brackets was explored in [17], though enforcing the Jacobi identity (3) remains a significant hurdle. Furthermore, recent work [18] utilized kernel ridge regression to learn Hamiltonians from noisy data in Poisson systems. While these methods can accurately reconstruct vector fields, isolating the true Hamiltonian is challenging because it is defined only up to the addition of an arbitrary function of the Casimirs, whereas the ML methods would try to find a particular Hamiltonian.
Crucially, these “continuous” methods assume that once the vector field is learned, it can be solved using standard numerical integration. However, simulating Hamiltonian systems, especially over long time scales, requires caution, as generic solvers are not structure-preserving and thus, for example, violate conservation laws for energy and momenta. To maintain physical validity in long-term simulations, one must employ variational integrators [8,19,20]. While these specialized methods preserve momentum-like quantities to machine precision, they are often significantly more computationally demanding than their non-structure-preserving counterparts.
2.1.2. Discrete Mapping Approach
This paper utilizes a different strategy, namely, determining the phase space transformations that satisfy specific structural properties. For canonical Hamiltonian dynamics, a fundamental theorem by Poincaré asserts that the flow of the system (1)—which maps initial conditions to a state at time t—is a symplectic transformation [21,22,23]. Formally, for a state , the flow must satisfy:
Rather than identifying the governing equations and subsequently integrating them, several researchers have proposed learning these symplectic mappings directly from empirical data.
Early developments in such learning of such symplectic transformations started with Symplectic Recurring Neural Networks (SRNNs) [24], which approximate transformations using discretized symplectic numerical schemes. That work determined that enforcing canonical structures significantly improves robustness when dealing with noisy datasets. Similarly, Non-Separable Symplectic Neural Networks (NSSNNs) were introduced in [25] to approximate symplectic steps for non-separable Hamiltonians, utilizing the explicit integrator proposed in [26]. From a Lagrangian perspective, Ref. [27] explored mappings in the phase space through structure-preserving discretization, a framework we have recently extended to encompass dissipative forces and thermodynamic systems [28].
Further advancements in learning symplectic maps were achieved through three distinct methodologies [9,29]. The first, SympNets [9], constructs dynamics by composing specific types of symplectic layers. In contrast, Generating Function Neural Networks (GFNNs) [29] derive mappings via a generating function approach, allowing for explicit long-term error estimation. Additionally, Ref. [30] introduced HénonNets, which utilize Hénon mappings to learn Poincaré maps while maintaining symplectic integrity. These architectures have successfully simulated the long-term behavior of integrable systems, e.g., pendulums and planetary orbits, and chaotic regimes like the three-body problem, demonstrating the potential of direct transformation learning.
The SympNet framework was adapted for non-canonical Poisson systems in [10] under the name Poisson Neural Networks (PNNs). By invoking the Lie-Darboux theorem, PNNs transform non-canonical coordinates into local canonical ones, assuming a constant-rank Poisson structure. However, this approach faces two major hurdles: the Lie-Darboux transformation is usually (and in most cases) local rather than global, and the model fails to preserve Casimirs exactly. However, Casimir preservation is essential for the reliability of long-term ensemble simulations [31], so we will be interested in methods that preserve Casimirs with machine precision.
An alternative route suggested in [12] involves solving approximate Hamilton-Jacobi equations for symmetry-reduced systems. This allows for the construction of transformations that exactly conserve momentum maps and Casimirs; however, solving the Hamilton-Jacobi equations for general, complex systems remains computationally and analytically prohibitive. More recently, Ref. [32] introduced LocSympNets and their symmetric counterparts, SymLocSympNets, which rely on the composition of volume-preserving mappings. These models have shown high accuracy in long-term simulations of rigid body dynamics, linear advection, and particles in magnetic fields. While these methods are highly effective for Poisson-like problems, their broader application has been limited because the mathematical completeness of their proposed activation matrices remains unproven.
2.2. Optimal Control via Neural Networks
Because of the importance of the problem of optimal control in engineering, and the flexibility of neural networks, optimal control via neural networks remains an active area of research. For example, Ref. [33] introduces the equations of motion in Pontryagin’s principle as a soft constraint, in a framework similar to what later becomes known as PINNs. The authors of [34] used the input convex neural networks for control tractability. Applications of neural networks to problems such as robotic manipulation [35] and landing problems in aeronautics [36] were considered. For a recent survey of applications of neural networks in optimal control problems, we refer the reader to a recent review [37]. While the progress achieved has been substantial, these methods have not used the advances in structure-preserving networks to fully utilize the mathematical structure inherent to Pontryagin’s principle. However, preservation of the structure of the equations in neural networks is essential for reproducing accurate long-term dynamics [3,9], which is exactly the point of this paper.
2.3. Data-Based Predictions for Lie-Poisson Systems
As discussed in more detail in Section 4, the problem of optimal control for coupled autonomous systems naturally adopts the Lie-Poisson structure characteristic of many physical systems. Drawing on the work of [1,2], symmetry reduction of controlled Hamiltonian systems results in a complete Lie-Poisson reduction to the direct product of individual Lie algebras, representing the reduced phase space for each vehicle. The symmetry reduction for multi-particle systems is often incomplete, requiring the tracking of relative Lie group elements in addition to motion on the Lie algebra [38]. However, such complexity is bypassed in Lie-Poisson optimal control due to the specific functional form of the Hamiltonian [1,2].
In Lie-Poisson systems, the Poisson bracket is known a priori, as its explicit form is derived directly from the underlying Lie algebra commutator. Selecting the specific Hamiltonian is a subsequent task dictated by the physics or control objectives of the problem. To facilitate data-driven computing within this framework, Refs. [3,13] developed methods to construct activation maps directly from these brackets. These methods predict dynamics using maps generated by explicit solutions of specific Lie-Poisson systems. As demonstrated in [3], this approach is universally applicable to finite-dimensional Lie-Poisson systems and any Poisson system where explicit integration of the governing equations for suitable transformations is feasible.
The computational advantage of using explicit integration in Lie-Poisson equations to accelerate time-stepping was initially identified in [39], though its application was restricted to specific forms of the Hamiltonian. The methodology developed in this article, by contrast, accommodates arbitrary Hamiltonians. In fact, the Hamiltonian does not need to be specified to construct the Neural Network; only knowledge of the underlying symmetry and the corresponding Lie-Poisson bracket is required. This is a robust assumption, as symmetries and brackets are fundamental to the problem’s geometric formulation and are known exactly. In contrast, the Hamiltonian is often a modeling choice that may only be known approximately [40].
In Lie-Poisson systems, the configuration manifold is defined on a Lie group G. For a group-invariant system, the dynamics can be reduced from the canonical bracket on the cotangent bundle to the dual of the Lie algebra, . This is achieved using the reduced momentum (left-invariant) or (right-invariant). For instance, the rotation of a satellite is described by , where can be represented as a (3-dimensional) vector. The resulting equations of motion and the Poisson bracket for are:
where denotes the Lie algebra commutator. Here, is a matrix-valued function linear in , with a structure determined by the Lie group. These brackets often admit Casimir invariants—functions C such that for any H—which are central to our approach.
Recent works [3,13] utilized the fact that the phase flow of any Hamiltonian constitutes a Poisson transformation that exactly preserves the bracket [22]. These works consider the flows generated by the “test” Hamiltonians of the form , where F is an unknown function and is a parameter vector. For these specific forms, the Lie–Poisson Equation (5) simplify significantly and can be solved analytically, providing the basis for our Lie–Poisson neural network layers.
By taking a composition of these Poisson transformations, the neural network in [3] fits the parameters of F and to approximate the available phase space data. This procedure allows the network to learn the flow with high precision across the entire phase space using a very modest amount of data and relatively few parameters. Critically, this architecture ensures that Casimir invariants are conserved to machine precision regardless of the training data.
While efficient, the mathematical completeness of the transformations proposed in [3] remained unproven. This paper demonstrates that while the LPNets approach can be made complete through certain generalizations, an implementation of these methods is impractical. Instead, this article proposes a more functional generalization of Poisson transformations that enables efficient and practical learning of the evolution across the entire phase space.
3. Contributions of This Paper and Novelty of Results
3.1. Contributions
This paper considers systems arising from the optimal control of the collective motion of a group of particles. The developed methods allow derivation of explicit Poisson transformations for arbitrary Lie-Poisson dynamics, for an arbitrary number of particles, on arbitrary Lie groups, using a generalization of LPNets. These techniques are explicitly developed for interacting identical particles, with each particle evolving on the groups of rotations and of rotations and translations. The first case is relevant to the collective orientation of objects like satellites, or perhaps other objects like antennas, that rotate about their centers. The second case is relevant to the motion of unmanned vehicles in air or water, allowing three-dimensional rotation and translation. For each case, we assume that we know the symmetry group, which leads us to the knowledge of the Poisson bracket for each case. Our goal is to predict the collective motion of these particles from observations.The proposed algorithm proceeds as follows.
In this paper, the proposed method learns the time-step map in phase space without using the analytic expression of the Hamiltonian. The model uses only the available trajectory data and the known Poisson bracket. Although the training and test data are generated from a known Hamiltonian in the benchmark examples, the Hamiltonian itself is not provided to the learning algorithm, which is tasked with learning the discrete phase-space map from data.
- Step 1 We derive the Poisson transformations approximating the mappings in phase space as the flows from the test Hamiltonians, which are computed in the explicit form, as shown in Section 5. For a given Poisson bracket, a control Hamiltonian generates a phase flow that generates a Poisson map of the phase space into itself. That Poisson map is parameterized by a neural network depending on the initial conditions for each step. To learn the dynamics in phase space, the Poisson map will be approximated as a superposition of the Poisson maps coming from the phase flow of a test Hamiltonian. Since every map approximating the full motion is Poisson, it preserves the Poisson bracket and hence the Casimir invariants (Casimirs) to machine precision; hence, the composition of the mappings of the phase flow generated by the test Hamiltonian will also preserve the Casimirs with machine precision.
- Step 2 Given a control Hamiltonian coming from the physical system, we generate the phase flow using a high-precision numerical method. That simulation generates data in phase space that are considered the ground truth data. The test Hamiltonians have several parameters; the parameters are optimized in such a way that the superposition of mappings generated by the test Hamiltonians approximates the flow, on average, for all available data.
- Step 3 After the optimization, we compare numerical solutions, obtained by solving differential equations coming from the true control Hamiltonian (the ground truth), with predictions based on the approximation of the phase flow by a sequence of Poisson transformations as flows from test Hamiltonians.
As an example of the proposed technique, we study the flow for two types of control Hamiltonians, which we call ‘Dictatorship’ and ‘Democracy’. By ‘Dictatorship’, we denote the case when only one particle is interacting with all other particles, and there are no other connections. The ‘Democracy’ means that all the evolving particles are connected to each other. Following [1,2], Lie–Poisson reduced dynamics equations are obtained for and groups in both cases. Interestingly, analytic results for some properties are possible for both of these cases, which are presented below in Section 4, extending the results in [1,2]. For reference, this article also presents the results of Lie–Poisson reduced dynamics equations in the case of one particle, for general reference for these groups, as they have not been presented before in the literature, making the structure of equations for several particles clearer.
3.2. Distinction from Previous Methods
The previous methods, which are closest to the present work, are structure-preserving neural networks for Hamiltonian and Poisson systems, including HNNs [7], SympNets [9], Poisson neural networks based on Lie–Darboux coordinates [10], Hamilton–Jacobi-based constructions for symmetry-reduced systems [12], LocSympNets and SymLocSympNets [32], and LPNets based on Poisson transformations [3,13]. The present paper differs from these approaches in its objective, geometric setting, and construction.
Continuous-time approaches such as HNNs [7], LNNs [16], and related Hamiltonian or Lagrangian neural networks learn a Hamiltonian, Lagrangian, or vector field, after which trajectories are generated by applying a numerical integrator. By contrast, the present method learns the discrete time-step map directly from data. Long-time prediction is therefore obtained by repeated composition of the learned map, without introducing a separate numerical integration scheme after training.
SympNets and related canonical symplectic architectures [9,29,30] provide structure-preserving discrete maps for canonical Hamiltonian systems. The systems considered here are non-canonical Lie–Poisson systems whose reduced phase space is and whose Poisson tensor is degenerate. Accordingly, the structural quantities emphasized in this work are the Casimir invariants associated with the Lie–Poisson bracket, rather than only the preservation of a canonical symplectic form.
Poisson neural networks based on Lie–Darboux coordinates [10] address non-canonical Poisson systems by transforming the dynamics to local canonical coordinates. The construction used here stays in the original Lie–Poisson variables and builds each layer as an explicitly constructed Poisson transformation for the given bracket. Consequently, Casimir preservation follows directly from the architecture and is observed to machine precision in long-time rollouts.
Hamilton–Jacobi-based approaches [12] construct structure-preserving maps for symmetry-reduced systems through Hamilton–Jacobi equations. The present approach instead uses explicitly computable Poisson transformations generated by test Hamiltonians, with parameters learned from trajectory data. This avoids the need to solve Hamilton–Jacobi equations for the interacting collective-motion systems considered here.
LocSympNets, SymLocSympNets, and related volume-preserving architectures [32] have demonstrated accurate long-time behavior for several Poisson-like systems. The architecture proposed here is targeted specifically at Lie–Poisson geometry: the preservation property built into the layers is preservation of the Poisson bracket and the associated Casimir invariants.
Previous LPNets based on Poisson transformations [3,13] are the nearest methodological antecedent of the present work. Building on that direction, this paper develops a formulation adapted to collective optimal-control systems after Lie–Poisson reduction, which is substantially more efficient in approximating the flow maps [3,13] while remaining fully structure-preserving. The method is applied to interacting multi-particle systems on and and requires only trajectory data together with the known Lie–Poisson bracket. It does not require the analytic control Hamiltonian, its gradients, the unreduced equations of motion, the control directions, or the number of controls.
3.3. Novelty of Results
This work achieves the following progress compared to the previous literature:
- 1.
- A novel network architecture of Poisson transformations is presented, specifically formulated for the problems of optimal control of collective motion (although in principle it is also applicable to regular Lie-Poisson systems);
- 2.
- The proposed method preserves all Casimir invariants with machine precision for all times;
- 3.
- The network is highly efficient, allowing accurate learning of complete phase space dynamics of (relatively) high-dimensional systems with only a modest number of data and network parameters;
- 4.
- The architecture of the proposed network allows us to prove completeness, as opposed to earlier results using Poisson transformations for machine learning [3];
- 5.
- The network does not need information about the control directions, the number of control dimensions, or anything else beyond the fact that the control Hamiltonian exists and satisfies symmetry reduction principles [1,41];
- 6.
- The system’s robustness with respect to noise is demonstrated, and improvement of prediction quality with small noise in data is reported.
Note that, according to the proposed method, neither the Hamiltonian H, its gradients, nor the equations of motion are ever computed. Instead, only the composition of Poisson transformations is computed, reproducing the dynamics in phase space of some Poisson system, coming from an unknown control Hamiltonian.
3.4. Plan of the Paper
The rest of this paper is organized as follows. Section 4 presents the theoretical background material necessary for this article. Section 5 gives a detailed explanation of how to construct the Poisson transformations out of the test Hamiltonians, which will be the main tool for data-based computing for optimal control problems, including the proof of completeness of the proposed network. Section 7 demonstrates application of CO-LPNets towards two Lie–Poisson systems, one of which evolves on Lie group, which is described in Section 7.1, and the other one on the Lie group, which is described in Section 7.2 (here N is the number of particles). Section 7.4 studies the dependence of the system on the noise in the data. Section 8 provides the Conclusions and directions for future work. In the Appendix, Appendix A.1 provides detailed derivations of equations of motion; Appendix B provides Lie–Poisson reduced dynamics equations for the case of “single particle” for reference, in order to present the whole theory more clearly. Appendix C provides the exact values of the derivatives of the Hamiltonians used for data generation and ground truth computations. Appendix D of the Appendix provides partial derivatives of the transformations.
4. A Short Review of Symmetry-Reduced Motion of the Particles Under Optimal Control
4.1. The Lie–Poisson Framework for Multi-Agent Optimal Control
In order to establish a self-contained foundation for the proposed data-driven learning methodology, this section outlines the geometric framework of symmetry-reduced optimal control for interacting particle systems. This short derivation allows to define the mathematical structure, the main variables, and how the ground truth trajectories are generated. While all essential kinematic relations, graph topologies, and the final reduced dynamical equations are introduced here, the exhaustive, step-by-step algebraic derivations are deferred to Appendix A.1 to preserve narrative clarity. The formulation of this article builds directly upon the geometric control foundations established in [1,2].
4.2. System Configuration and Network Topology
The considerations start from an ensemble of N identical particles, where the configuration of each individual agent is represented by an n-dimensional Lie group G with an associated Lie algebra . The total configuration space of the collective system is the direct product group . Let be an orthonormal basis for under the standard trace inner product .
The interaction topology among the N agents is modeled by a connected, undirected graph without self-loops, where vertices represent agents and edges denote active communication links. The network architecture is characterized by three standard matrices [42]:
- Adjacency Matrix (A): if a connection between agents i and j exists, and 0 otherwise.
- Degree Matrix (D): A diagonal matrix , where is the degree of vertex .
- Graph Laplacian (B): Defined as . By construction, B is symmetric and positive semi-definite, satisfying , meaning the row and column sums are identically zero.
4.3. Controlled Dynamics and Coupled Cost Functionals
The left-invariant kinematic evolution of the k-th agent on G is governed by:
The system is assumed to be underactuated () with an uncontrolled drift component along a specific algebra direction (). The control velocities are affine in the control inputs :
The control objective is to minimize a G-invariant cost functional depending exclusively on the control inputs:
where the physical coupling between interacting particles is explicitly encoded via a coupling strength parameter [1]:
4.4. Symmetry Reduction and Reduced Hamiltonian Dynamics
In general mechanical systems exhibiting G-symmetry on a product manifold , a complete reduction to the dual algebra is impossible without tracking relative configuration variables , which introduces severe analytical complexity [38]. However, owing to the specific algebraic structure of the control Hamiltonian under Pontryagin’s Maximum Principle [41,43], these optimal control formulations admit a seamless, complete symmetry reduction to a pure Lie–Poisson system.
Let denote the symmetry-reduced co-state (momentum) of the k-th particle, so that , and let isolate its directly controlled components. By applying the first-order optimality condition , an explicit linear mapping between the optimal control inputs and the controlled components arises (see Appendix A.1 for the complete inversion step):
Here, and . Substituting these optimal controls back into the pre-Hamiltonian yields the explicitly reduced control Hamiltonian :
where represents the aggregate momentum vector.
Consequently, the global collective trajectories evolve entirely on according to the Lie–Poisson equations:
where each structural Poisson block is an antisymmetric matrix defined via the structure constants of the underlying Lie algebra ():
Remark 1 (Geometric Properties).
Through left-invariance, Equation (12) can be cast in coordinate-free notation via the co-adjoint action: [22,44]. Crucially, the structure of the Poisson tensor dictates that the origin remains a stationary invariant point for any choice of control Hamiltonian h. This strict structural constraint is heavily leveraged in our data-driven discovery phase.
4.5. Algorithm for Producing the Data in Phase Space
The algorithms presented in this Section are used for producing data for a particular realization of the phase space, which are taken to be N interacting particles in either or .
At first, the Lie–Poisson reduced dynamics Equation (12) are solved for two types of control Hamiltonians described above, which are called ‘Dictatorship’ and ‘Democracy’. Then, short trajectories for and trajectories for are generated; each of length points. The value is chosen for all simulations. The initial conditions for these trajectories are generated randomly with a uniform distribution in the box for every particle . The numerical solutions are obtained using a high-precision Lie-Poisson integrator [45], based on an implicit second-order midpoint rule, with second-order accuracy in the time step. The integrator conserves Casimir invariants with machine precision and the Hamiltonian with an accuracy of about . The same integrator is used to construct ground truth for comparison with the reconstructed solutions obtained by the neural network. Such an accuracy may seem excessive, as it far exceeds any reasonable accuracy of experimental data. However, it is important to have a structure-preserving integrator to avoid possible drift in solutions for the comparison to the reconstructed solutions over long times.
5. Data-Based Computing of the Coupled Lie-Poisson Control Systems
5.1. General Considerations and Completeness Result
The main goal of this article is to approximate and predict the further evolution of the Lie–Poisson system. In what follows, we assume that we do not know the Hamiltonian itself, and thus we do not assume the knowledge of the Lagrangian (9), the form of the controls (7), or a particular form of the Hamiltonian (11). The Lagrangian and controls are assumed to be arbitrary, as long as the non-degeneracy of the Hessian for the pre-Hamiltonian (see Equation (A5) in the Appendix) is satisfied. The goal is to predict the evolution of the Lie-Poisson control system based on available data observations only.
To generate the data set, we consider a set of points corresponding to the start and end points of short trajectories obtained from the exact equations of motion as described in Section 4.5. This procedure of data generation gives a set of data points in the phase space connected by the phase space transformation over a short time interval. The goal is to learn the phase space transformation connecting the data points in some optimal sense that is quantified below.
Remark 2 (On data observability and applicability of the theory).
The ground truth data obtained in Section 4.5 and used for learning the system involves information about the reduced co-state variables μ. Such information is not always directly available from data collected by an external observer. In controlled mechanical systems, however, these variables may be available from the internal control or other ways of estimation, for example through the co-state equations in Pontryagin’s maximum principle, through onboard state estimation, or through momentum reconstruction using the known symmetry-reduced model.
When the reduced variables are not directly observed, they can also be inferred from observable configuration and velocity data by using the geometric constraints of the system. In particular, the coadjoint-orbit structure and the corresponding Noether invariants provide a way to reconstruct latent Lie–Poisson variables consistent with the observed motion. This direction is pursued in the recent related work [46], where latent Lie–Poisson dynamics are learned from observable data without assuming direct access to μ.
Thus, the present CO-LPNet construction should be interpreted as applying to the case where the reduced variables are either measured, estimated, or reconstructed. In this setting, the learned phase-space map can be used to compare the predicted reduced dynamics with the actual evolution of the controlled system, especially when there are inaccuracies in the applied control or in the analytic expression for the control Hamiltonian. To support the practical applicability of the method, this paper also reports the number of trainable parameters and the inference time required for trajectory rollout in the numerical experiments.
As mentioned in Section 1, this work does not seek the approximation of the actual control Hamiltonian from data. Instead, it focuses on the approximation of the mappings of the phase space in the variables between the data points in time using a sequence of structure-preserving Poisson maps. For this purpose, we consider Hamiltonians h for which the equations of motion are analytically solvable. We call such Hamiltonians test Hamiltonians. These test Hamiltonians consist of arbitrary functions of projections of the momenta on a certain vector. Poisson transformations are constructed as flows of these test Hamiltonians and applied sequentially to approximate the flow generated by the real control Hamiltonian. The considerations start with the following
Lemma 1.
Suppose , where , is a vector belonging to the Lie algebra , dual to , and β is a constant. Then the Lie–Poisson reduced dynamics (A16) reduces to equations that are linear in μ.
Proof.
By definition, any Hamiltonian h is a constant, thus, as well. Moreover, since . According to (12), is a block-diagonal matrix. Then, (12) suggests that the Lie-Poisson reduced dynamics equations for i-th component of k-th particle will look as follows:
that is, for every , we have:
It is known that on solutions of (14). Hence, the term multiplying the function is constant on solutions in (14), and thus the Equation (14) can be solved as a linear system of ODEs in the unknown . □
5.2. Connection to Splitting Methods in Numerical Analysis
Any Hamiltonian described in Lemma 1 generates a phase flow that is a Poisson transformation which can be computed analytically. Suppose the total Hamiltonian h can be separated into a finite number of terms described in Lemma 1, i.e., . Then, the idea of splitting methods [47,48] of the traditional numerical analysis is to divide each time step into M sub-steps , with , with each sub-step j yielding the phase flow according to the solution of (14). The total phase flow after time can be approximated as a composition of the phase flows by each sub-Hamiltonian :
5.3. Completeness of Transformations Defined in Lemma 1
To prove the completeness of transformations derived in Lemma 1, a corollary of the Universal approximation theorem for the function and derivatives from [49] can be used:
Theorem 1.
Take a smooth, non-polynomial, monotonically increasing activation function , for example, sigmoid or tanh. Consider any and any compact set U of the phase space. Then, any smooth Hamiltonian can be approximated in U up to the accuracy ϵ in the second Sobolev norm , (the function and its first and second derivatives belong to ):
The universal approximation theorem in [49] is slightly more general: under appropriate smoothness assumptions on the activation function, neural networks can approximate a function together with its derivatives up to order m. Here, only the single-hidden-layer case and approximation up to second derivatives are needed. This restriction is important because Hamiltonians of the form in (16) preserve the explicit integrability property required by Lemma 1, whereas general multi-layer networks would not lead to explicitly integrable sub-step Hamiltonian flows.
Theorem 1 leads to the following
Lemma 2 (On the approximation of phase flow).
Suppose a phase flow of the Poisson system (A16) is defined by a smooth Hamiltonian . Choose a compact set U in the phase space, and some . Then, take any , and choose the set
Then, there is an integer , coefficients , constant vectors in , and such that the flow is approximated by the phase flow of the Hamiltonian
up to the accuracy ϵ, for all as long as the solution generated by the phase flow of the Hamiltonian h does not leave .
Proof.
Let be arbitrary, and set , where is to be determined. Let , where , and assume that U is a compact domain with sufficiently regular boundary. By (16), choose M, , , and such that
Since , the Sobolev embedding gives
If is bounded on U, then the corresponding vector fields
satisfy
Moreover, if is locally Lipschitz on U, then, since h is smooth, is Lipschitz on U; let L be its Lipschitz constant.
The solutions and satisfy the integral equations
Assuming that the initial conditions are the same, , (19) yields the estimate for the error , for all t such that and are in U:
By the integral Gronwall inequality, using and , one obtains
Thus, choosing
guarantees that , for , as long as the exact solution remains in . Since the exact solution is at distance at least from and , the approximate solution remains in U on the same interval. If the exact solution leaves at , then the estimate holds only on the interval . □
5.4. Practical Applications of Completeness Results
In principle, Lemma 2, yielding the completeness result, allows construction of a splitting method based on the approximation of the Hamiltonian by the separable ansatz (17). One would then take M sub-steps on each time step and approximate the flow uniformly in the compact domain U. Thus, Lemma 2 serves as an existence proof of a broad class of splitting methods capable to approximate the phase flow with an arbitrary precision.
In reality, such a straightforward application of the method is not practical. Since only the approximation by single-layer networks is allowed for a separable ansatz (17), the number of terms M needed for accurate approximations of the dynamics can easily become astronomical. Estimates for deep ReLU networks [50], for example, yield the estimates with accuracy for the function and first derivative as , where d is the number of dimensions, although one-layer networks tend to provide even worse approximations. Taking a modest value and the number of dimensions which are used for three interacting particles in in Section 7.2, one arrives to the astonishing number of substeps per time step. Clearly, writing a machine learning scheme with that number of parameters and having that number of substeps is impractical, to say the least. Even if that number is reduced substantially, there will never be enough data in practical applications to construct such a machine learning scheme, which, in addition, will be extremely slow and memory-demanding. In what follows, the paper develops a numerical scheme that has the number of substeps growing quadratically with d, the dimension of the phase space, which is highly efficient. This scheme exploits the block-diagonal structure of the Lie-Poisson matrix to radically reduce the parameter count. With these modifications, the proposed scheme will be able to address a high number of dimensions with a relatively small number of data points (only a few thousand) to learn the complete dynamics of the phase space.
Remark 3 (On polynomial Hamiltonians).
A theorem on polynomial expansion [47], Chapter 3, says that if the Hamiltonian is a polynomial, there exists an expansion where each is a polynomial of one variable. The Hamiltonian given by (11) is quadratic, but that only happened because, following [1,2], a very particular choice of the Lagrangian and controls was made. In general, there is no guarantee that the Hamiltonian is polynomial in components of . The goal of this article is to describe the motion without any restriction on the type of Hamiltonians considered. One may be tempted to use a Taylor expansion of the Hamiltonian to approximate it by a polynomial. Unfortunately, such expansion will fail, for example, if the quadratic Hamiltonian defined by (11), is multiplied by a prefactor and the motion of solutions in the domain is tried to be predicted, as the Taylor expansion will fail beyond . Thus, this article proceeds without making any assumptions on how well the Hamiltonian can be approximated by polynomials.
6. CO-LPNets: General Consideration and Design
6.1. The Design of Poisson Transformations
The solutions of the Equation (14) are constructed with the test Hamiltonian; these solutions generate the transformations that will later be used to learn the dynamics of the phase space. For N interacting particles, each evolving on a Lie group of dimension n, the test Hamiltonians are chosen, where is the chosen component for the k-th case. This test Hamiltonian generates the phase flow according to the equation
where is the basis vector with 1 at the coordinate and 0 otherwise; and is a vector, denoting the initial conditions. The solution of this linear equation depends on the structure of the group, as well as the scalar setting the time scale for the particular equation. Usually, K is taken to be a multiple of , the total number of particles, while , so the index runs repeatedly through a certain number of times.
The crucial observation is that the transformations defined by (23) remain Poisson if is made a function of the initial conditions and held constant during the time step. It is important to note that the value of parameter is set after the Poisson transformation is defined, which does not break the Poisson structure of the transformation itself.
Proposition 1 (Poisson character of the CO-LPNet substeps).
Fix an initial point and evaluate the neural-network coefficient . During the corresponding substep, this value is held fixed as a scalar parameter in the test Hamiltonian
Then the map
is a Poisson transformation. Consequently, each CO-LPNet substep is computed by applying an explicitly constructed Poisson map with the parameter frozen at the value determined from the initial condition of that substep.
Proof.
Once has been evaluated, it is a fixed scalar during the substep. The equation
is therefore the Hamiltonian system generated by the test Hamiltonian with respect to the prescribed Lie–Poisson bracket. The flow of a Hamiltonian vector field on a Poisson manifold is a Poisson transformation. Thus is Poisson for the frozen value of . □
Thus, the dependence of on is used to select one member of the family of Poisson transformations applied at that substep; the selected transformation is then applied with fixed during the time step. If were instead allowed to vary continuously as a state-dependent coefficient during the substep, the above argument would not apply. This is not the construction used in CO-LPNets.
Definition 1.
CO-LPNets A composition of Poisson mappings of phase space generated by Hamiltonians defined by (23) over time forms a Poisson transformation. The parameter is defined as a function of the initial condition for every step through a neural network . The total neural network is constructed as the composition of , with the parameter in each transformation depending on an individual neural network. The neural network constructed by such composition is called CO-LPNets. The construction of CO-LPNets is illustrated on Figure 1.
Figure 1.
A schematic of proposed neural network. The top of the Figure illustrates the learning procedure. The ground truth data involves sets of short pieces of trajectories with the beginning and end points. The neural network consists of a sequence of Poisson transformations , depending on parameters that are applied in sequence to the original points. The Poisson transformations are obtained from the test Hamiltonian , , with the index k running through all the indices of the vector . The parameters are defined by the neural network depending on the initial conditions for each time step , indicated by the black arrows pointing to the network. The network parameters for defining each sequence of transformations are optimized so that the output of the mapping is as close as possible to the ground truth data for the end of the interval. At the bottom of the Figure, the procedure for reconstructing the next step starting from . The reconstruction consists of K intermediate Poisson transformations with the learned parameters. Dark gray arrows indicate repeated applications of the Poisson transformations (circular arrows), with the parameters supplied by the individual shallow networks.
Remark 4 (On the type of networks for ).
In this paper, shallow networks are used for predicting the coefficients of Poisson transformations. The input to these networks consists of all components of and the output is one-dimensional parameter , with one hidden layer of width W. Then, K identical networks are used, each one predicting the value of , . The number of parameters in each network is thus , and the total number of parameters is . The value K is going to be taken as a multiple of the total dimensions (usually equal to ), so the number of parameters in the network grows with the number of particles and dimensions of the group as .
In observations described in this paper, W is taken to be quite small. In particular, in the simulations for particles, the values , and are chosen. For particles evolving in the group, the number of parameters in each network is 34, with the total number of parameters being 306. For group, each network contains 61 parameters, with the total number of parameters equal to 1098.
6.2. On the Completeness of CO-LPNets
Throughout this discussion, the trajectory is assumed to remain in a regular part of the Poisson manifold, i.e., in a region where the rank of the Poisson tensor is constant. Equivalently, the approximation statement is made on compact subsets of a fixed symplectic leaf of constant dimension. Singular leaves, where the rank of changes, are not included in the completeness argument below. The CO-LPNet transformations remain Poisson maps and preserve the Casimir invariants by construction; however, the local spanning argument using the columns of applies only on regular leaves. For the systems considered in this paper, all numerical trajectories are chosen away from the singular points.
To clarify the completeness of the CO-LPNets architecture in relation to Lemma 2, one has to consider the geometric structure of the Lie–Poisson equations. The true dynamics are restricted to a symplectic leaf (a coadjoint orbit) within the dual Lie algebra . The tangent space to this orbit at a point is the image of the Lie–Poisson matrix .
For the test Hamiltonians , one has . The resulting vector fields are therefore proportional to the individual columns of . As the index ranges over the coordinates, these vector fields span the tangent space to the coadjoint orbit, modulo the linear dependencies among the columns of .
The practical CO-LPNet architecture replaces the scalar coefficients by state-dependent functions . This can be viewed as learning how to combine the available local tangent directions along the symplectic leaf. Since any Hamiltonian vector field generated by the same Lie–Poisson bracket lies in the image of , it can be represented locally as a combination of these directions, at least away from changes in the rank of the Poisson tensor.
Thus, with sufficiently expressive functions and a sufficient number of composed transformations , the CO-LPNet architecture provides a geometrically natural approximation class for finite-time phase flows on compact subsets of a fixed symplectic leaf. This is the sense in which the completeness result is used here. No global universal approximation for arbitrary Poisson maps on the full ambient space is claimed here; rather, the statement concerns approximation of dynamically admissible Lie–Poisson evolution on the relevant symplectic leaves, consistent with Lemma 2.
6.3. On Possible Simplifications
Several simplifications of the CO-LPNets can be constructed. One can remove the middle layer and make the output neuron dependent only on one input neuron. Then, each network will contain only two parameters (three in the case of additional scaling), and the total number of parameters will be proportional to K. This was the idea of G-LPNets in [3]. Unfortunately, for Lie-Poisson systems with block-diagonal matrices, such systems may have problems with convergence, as Poisson transformations will be isolated to different particles. A solution to this problem is to consider the output neuron depending on a pair of input neurons. Such a mapping was implemented for this problem as a test case. However, in our opinion, the convergence of that algorithm will be slower, since it is not completely clear a priori how many Poisson transformationsof this type will be needed to achieve convergence.
6.4. The Algorithm of CO-LPNets
- 1.
- Generate several short trajectories of ground truth data. The data will define the ground truth transformations , .
- 2.
- Construct transformations , and compute the following loss functionwhere stands for weights and biases of all networks defining , .
- 3.
- Find the optimal weights
- 4.
- Start with an initial condition , and construct reconstruction steps:Compare the reconstructed solution with the ground truth solution obtained by the Lie-Poisson integrator.
Remark 5 (On the structure of Poisson transformations).
In what follows, it is demonstrated that for the cases considered, namely and , the Poisson transformations have the form , where is a matrix of a certain form. The transformation is nonlinear since . That structure of transformation is a consequence of the solutions to (23). Since every only depends on its own network through a single parameter , the optimization of the loss function (24) can be made highly computationally efficient.
Remark 6 (Scope of the numerical experiments).
The numerical experiments in the following sections are designed to test generalization to new trajectories whose initial conditions are sampled from the same prescribed hypercube containing both the training and validation data. Thus, the experiments demonstrate empirical generalization within the sampled region of phase space. They are not intended to establish global approximation on the full Lie–Poisson phase space in the mathematical sense, beyond the region of available data.
7. Specialization to Particular Groups
7.1. Group
7.1.1. Equations for the Ground Truth Calculations
Let us now apply the general theory to a particular group. The first example is the collective motion of objects, with each object evolving on the Lie group of rotations . The group consists of orthogonal matrices such that , where is a identity matrix, and . This example can be applied to a set of rigid objects rotating to achieve the desired orientation, for example, for observations of a particular target in space.
To find the evolution of particles on the N copies of Lie algebra , the scalar product is defined and the following orthogonal basis is used:
which is normalized so that , with respect to the trace norm. The structure constants for the Lie algebra are where is the Levi-Civita symbol.
For each particle, the vector of is introduced. consists of the components of matrix in the basis :
Thus, according to (12), is a block-diagonal matrix of the following form:
with k-th block equal to the following antisymmetric matrix:
which is just the familiar hat map, mapping vectors in to elements of Lie algebra . As a result of the block-diagonal Poisson tensor (28), each particle has its own Casimir invariant associated with the Lie–Poisson bracket:
The Lie–Poisson Equation (12) are written in vector form as:
which are (formally) N copies of the equations of motion a rigid bodies [21], with the Hamiltonian providing the interaction between the particles.
Assuming that the control acts in the direction and the drift lies in the direction, (7) becomes
After some algebra, the Hamiltonian (A15) for the cases of ‘Dictatorship’ yields:
Similarly, for the case of ‘Democracy’, we obtain
These two cases (‘Dictatorship’ and ‘Democracy’) are simulated for particles, computing 40 trajectories of length 51, thus creating 2000 intervals for learning the phase space. The initial conditions for these trajectories are chosen randomly in the hypercube , where d is the dimension of the phase space, equal to in this case. As mentioned in Section 4.5, a Lie-Poisson integrator was used for computation of the ground truth data, which preserves the system’s structure and Casimirs with machine precision. The value of the parameter is chosen for all simulations. For reference, analytical formulas for the derivatives of the Hamiltonians are presented in Appendix C.1.
Below, the article describes how to construct the Poisson transformations that define the transformations of the phase space. After that, CO-LPNets are built to learn the motion of the system in the whole space where the data is available, and the trajectories of the system that were previously unseen by the algorithm are predicted.
7.1.2. Poisson Transformations Through Test Hamiltonians
Following Section 6, the very specific test Hamiltonians are considered, namely, Hamiltonians, which depend only on a single component i of one particle k. According to (23), the considerations start with the Hamiltonian , where is some constant on that particular time step.
The Lie–Poisson reduced dynamics equations (A16) simplify to give
where means the i-th standard basis vector in the 3-dimensional space. Assuming that we are given initial conditions for , the solution of such an initial value problem is simply
where denoting the rotation matrix with respect to the vector by the angle .
To speed up computation of derivatives of the loss function (24) with respect to the parameters, the partial derivatives of matrices , with respect to , were also computed. These formulas are presented in the Appendix C.1 of the Appendix.
7.1.3. Application of CO-LPNets for Group
The data in phase space is generated according to Section 4.5. In the example, we consider coupled particles, each evolving in . Each component has dimension , so the total dimension of the phase space is . Data are generated for two particle-interaction rules, referred to as “Dictatorship” and “Democracy”. For each interaction rule, 40 trajectories of length 51 are generated, which gives 50 one-step intervals per trajectory and hence 2000 training intervals in total. The initial conditions for these trajectories are chosen randomly in the hypercube . The sampling time step is . As described in Section 4.5, a Lie–Poisson integrator is used to compute the ground truth data, which preserves the system’s structure and Casimirs with machine precision. In these computations, the reference integrator uses the internal time step . The value of the parameter is chosen for all simulations.
After the ground truth data is generated, CO-LPNets are trained directly on the one-step phase-space pairs. For the case, structure-preserving transformations are used, which is the minimum number needed to cycle once through all phase-space coordinate directions. Each transformation is parameterized by a neural network with 9 input neurons, one hidden layer with neurons, tanh activation, and one scalar output neuron. The loss defined in (24) is optimized using the Adam algorithm with learning rate for 10,000 epochs.
After the optimization is complete, the learned CO-LPNet map is tested by simulating 10 new trajectories from random initial conditions in the hypercube . The CO-LPNet map is iterated with the same time step and compared with high-accuracy reference trajectories. Along with the trajectory error, the Hamiltonian error and the Casimir errors are also reported, corresponding to for each particle, to verify that the learned dynamics preserve the Lie–Poisson structure.
For reproducibility, the data-generation seeds were fixed at 1334 for the Dictatorship topology and 1344 for the Democracy topology. The corresponding evaluation initial-condition seeds were 91,111 and 91,121, respectively. The training seed was fixed at 5678 for all reported runs, including parameter initialization and the train/validation split. A validation fraction of was used, and no early stopping criterion was applied; training was stopped only after the prescribed 10,000 Adam epochs. The learned maps were evaluated over a fixed prediction horizon of 1000 time steps.
The results of application of CO-LPNets are shown in Figure 2 for the case of ‘Democracy’, with the corresponding summary of errors in Casimirs, energy, and MAE of all components in Figure 3. The same information is shown in Figure 4 for the case of ‘Dictatorship’, with the corresponding summary of errors in Casimirs, energy, and MAE of all components in Figure 5. The trajectories are reproduced faithfully over 1000 time steps for every particle, the variations of energy in trajectories by CO-LPNets are bounded, and the Casimirs for each particle are preserved with machine precision.
Figure 2.
Trajectory comparison in the case of three particles for group, for the case of ‘Democracy’. Ground truth case is denoted with blue colour, while CO-LPNets—with red colour, for one representative trajectory. All components are plotted, with the particle index indicated by the row, and the component by the column of the table.
Figure 3.
Errors in the Casimir for each particle (left), Total energy (center), and Mean Absolute Error (MAE, right) for the trajectory presented in Figure 2. MAE is computed for all ten reconstructed solutions, not just for the one shown in Figure 2. Again, the ground truth solution is denoted with blue colour, while the results of CO-LPNets are denoted with red colour.
Figure 4.
The comparison of solutions for the case of three particles for the group, the ‘Dictatorship’ case, with all notations and color scheme as in Figure 2.
In all Figures, when comparing the results of the CO-LPNets with the ground truth, a consistent color scheme is used: the ground truth is marked with a solid blue line, and results obtained from CO-LPNets are presented with a solid red line.
It should be emphasized that, while the Casimir invariants are conserved to machine precision, the Hamiltonian energy is not enforced exactly. In the present setting, CO-LPNets preserve the Casimir invariants by construction and therefore keep the learned trajectory on the correct symplectic leaf. The Hamiltonian, however, is not a Casimir; it is an invariant of the particular Hamiltonian flow. Since the architecture enforces the Lie–Poisson map structure rather than the exact Hamiltonian level set, small Hamiltonian drift can occur. Geometrically, this means that the learned dynamics remain on the correct symplectic leaf but may move away from the exact Hamiltonian level set within that leaf.
This distinction is analogous to the classical situation for geometric integrators. The Ge–Marsden result [45] shows that, for general Hamiltonian systems, exact simultaneous preservation of the symplectic or Poisson structure and the Hamiltonian would force the numerical method to coincide with the exact flow, except in special cases or with additional mechanisms such as variable time stepping. Thus, energy drift is not a contradiction of structure preservation: CO-LPNets enforce the Poisson-map structure and Casimir preservation, but they do not impose exact conservation of the Hamiltonian level set.
The results for the experiments are summarized in Table 2, which reports MAE, Peak MAE, Relative Trajectory Error (RTE), Casimir error, absolute energy error, final training loss, and the number of trainable parameters. Absolute rather than relative energy error is reported, since the Hamiltonian is defined only up to an additive constant. The training time was on the order of s per run on the Linux GPU cluster. Detailed timing comparisons are not included in the table because the runs were carried out on different GPU architectures, including both A100 and H100 GPUs, and therefore the timings are not directly comparable across runs.
Table 2.
A summary of CO-LPNet experiments. MAE is averaged over all test trajectories and time levels, while Peak MAE is the largest time-level mean absolute error over the test set. RTE denotes Relative Trajectory Error, Max denotes the maximum Casimir deviation from the ground-truth Casimir values, and Max denotes the maximum absolute energy error. The table also reports the final training loss and the number of trainable parameters.
7.2. Group
7.2.1. Definitions
In this section, the theory is applied to equations of motion for the Lie group of rotations and translations. This group gives a highly practical example as it describes the motion of several interacting objects moving in space, exhibiting both rotations and translations. This example is useful for drone applications. An object in space evolving on the group undergoes rotation and translation . With the use of these quantities , a matrix is formed, and its inverse is computed as follows:
where is the row of three zeros. The multiplicative structure (35) defines a semidirect product group. This group has a corresponding Lie algebra, called . That Lie algebra is six-dimensional; three values are coming from the infinitesimal rotations and three values come from translations.
In order to find an orthonormal basis in the linear space , the elements of are described as matrices and again the trace product of two matrices defined as , is employed. With this product, the following orthogonal basis for the Lie algebra is selected:
which is normalized so that , with respect to the trace norm. The structure constants for the Lie algebra are then computed as follows:
with all other structure constants equal to 0.
Using the mechanical analogy from the mechanical Lie-Poisson systems [22,44], let us separate the full momentum vector for each particle into two three-dimensional vectors and having the meaning of the angular and linear momenta:
Thus, according to (12), is a block-diagonal matrix of the following form similar to (28)
with k-th block equal to the following antisymmetric matrix:
where is a matrix of zeros and is, as usual, the hat map between the components of the vector and the antisymmetric matrix , just as in (29). The matrix defined this way posesses the property for any vector . As a result of the decoupled Poisson tensor, there are Casimirs, with two Casimirs for each particle:
The Lie–Poisson Equation (12) reduce to the well-known form:
which are the equations for N underwater vehicles when the centers of mass and buoyancy coincide, extending the classical single-vehicle case developed by Kirchhoff [51,52,53]. The article assumes that the drift is applied along the first component of linear momentum (the drone moves forward) and there are two controls in angular momentum in the first and second coordinates. The Equation (7) becomes
Using the general Formula (11), after some algebra, the explicit formula for the Hamiltonian for the case of ‘Dictatorship’ is
For the case of ‘Democracy’, the Hamiltonian is given by
The forms for the Hamiltonian (39) and (40) are based on the explicit form of the matrix , which is presented in Appendix C.2.
7.2.2. Data Generation for Learning
The data are generated for two cases, “Dictatorship” and “Democracy”, by simulating the system with particles, each evolving in . Each component has dimension , so the total dimension of the phase space is . For each interaction rule, 80 trajectories of length 51 are generated, giving 50 one-step intervals per trajectory and hence 4000 intervals for learning in phase space. The initial conditions for these trajectories are chosen randomly in the hypercube . The sampling time step is . As mentioned in Section 4.5, a Lie–Poisson integrator is used to compute the ground-truth data, preserving the system’s structure and Casimirs with machine precision. In these computations, the reference integrator uses the internal time step . The value of the parameter is chosen for all simulations. Analytical formulas for the matrices and derivatives of the Hamiltonians are presented in Appendix C.2.
After the ground-truth data are generated, CO-LPNets are trained directly on the one-step phase-space pairs. For the case, structure-preserving transformations are used, which is the minimum number needed to cycle once through all phase-space coordinate directions. Each transformation is parameterized by a neural network with 18 input neurons, one hidden layer with neurons, tanh activation, and one scalar output neuron. The loss defined in (24) is optimized using the Adam algorithm with learning rate for 10,000 epochs.
After the optimization is complete, the learned map is tested by simulating 10 new trajectories from random initial conditions in the hypercube . The CO-LPNet map is iterated with the same time step and compared with high-accuracy reference trajectories. Along with the trajectory error, the Hamiltonian error and the two Casimir errors, corresponding to and , are reported to verify preservation of the Lie–Poisson structure.
For reproducibility, the data-generation seeds were fixed at 1434 for the Dictatorship topology and 1444 for the Democracy topology. The corresponding evaluation initial-condition seeds were 91,211 and 91,221, respectively. The training seed was fixed at 5678 for all reported runs, including parameter initialization and the train/validation split. A validation fraction of was used, and no early stopping criterion was applied; training was stopped only after the prescribed 10,000 Adam epochs. The learned maps were evaluated over a fixed prediction horizon of 200 time steps.
Next, Poisson transformations are constructed as flows generated by test Hamiltonians to create Poisson transformations for CO-LPNets.
To construct the Poisson transformations for CO-LPNets in the case of group, the Hamiltonians which depend only on a single component i, of one particle k, , are considered; more precisely, are taken. To construct the Poisson transformations explicitly, two possibilities are covered: (test Hamiltonian corresponding to the angular momentum) and (test Hamiltonian corresponding to the linear momentum).
7.2.3. Test Hamiltonians for Angular Momenta
This is the case with . Equation (12) simplify as follows:
with and defined as in (36). Again, means the i-th standard basis vector in the 3-dimensional space; is a constant on every time step that will need to be approximated by the neural network. Suppose we are given initial conditions for and at the point , which are denoted as and . The solution of the initial value problem (41) is then given by
7.3. Test Hamiltonians for Linear Momenta
This is the case with . Equation (12) for the kth particle yield the following system of equations:
with the solution
The transformations (42) and (44) can be written as block-diagonal matrices with blocks being identities, and k-th block being a combination of rotations and translations. For brevity, they are not presented here. For the computations of the loss function (24), partial derivatives of these transformations with respect to parameters are presented in Appendix C.2 of the Appendix.
Results from the Application of CO-LPNets for Particles Evolving on
The data in phase space is generated according to Section 4.5. The calculations used coupled particles, each evolving in , having dimension with the total dimension of the phase space being . Then 4000 points are generated in order to match the number of points per dimension with the case described in Section 7.1.3, with ∼222 points per dimension of the phase space. Again, the time step is chosen to be . Data for learning is produced in two cases: ‘Dictatorship’ and ‘Democracy’. After that, CO-LPNets are applied with 18 rotations, the minimum number of rotations allowed to cover all possible motions in space, and the loss defined by (24) is optimized. The optimization is performed with the use of the Adam algorithm with a learning rate of for 10,000 epochs. During that time, the loss decreases from about ∼0.1 to ∼, i.e., by four orders of magnitude. After the optimization is complete, ten trajectories are simulated, starting with random initial conditions in the cube , both using the structure-preserving integrator CO-LPNets with computed parameters.
The results of application of CO-LPNets are shown in Figure 6 for the case of ‘Democracy’, with the corresponding summary of errors in Casimirs, energy, and MAE of all components in Figure 7. The same information is shown on Figure 8 for the case of ‘Dictatorship’, with the corresponding summary of errors in Casimirs, energy, and MAE of all components in Figure 9. One can see that CO-LPNets faithfully reproduce the trajectory over an intermediate time scale (200 steps), preserving Casimirs with machine precision. The Hamiltonian (energy) is not conserved by CO-LPNets, but the deviations of energy are bounded.
Figure 6.
Trajectory comparison in the case of three particles for group, for the case of ‘Democracy’. The ground truth case is denoted with blue colour, while CO-LPNets is denoted with red colour, for one representative trajectory. Only the first three components , are plotted, with particle index indicated by the row, and the component by the column of the table.
Figure 7.
Conservation of the Casimirs (top), Errors in the energy (bottom left) for a sample trajectory, Mean Absolute Error (MAE) for all ten test trajectories (bottom right), for the case of ‘Democracy’ for . The ground truth case is denoted with blue colour, while CO-LPNets are denoted with red colour. Notice, again, preservation of the Casimirs with machine precision, and quite accurate conservation of the energy on average by CO-LPNets.
Figure 8.
Trajectory comparison in the case of three particles for group, for the case of dictatorship. Only the first three components of six are plotted for every particle, with the number of the particle corresponding to the row in the table, and the component to the column of the table. Color scheme and notations are identical to Figure 6.
Figure 9.
Summary of ‘Dictatorship’ governance for three particles evolving on . Errors in Casimirs (top), Errors in the energy (bottom left), and Mean Absolute Error (MAE) for all ten test trajectories (bottom right). Both Casimirs are conserved with machine precision for all particles, as expected. Color scheme and notations are identical to Figure 7.
The results for the experiments are summarized in Table 3, which reports MAE, Peak MAE, Relative Trajectory Error (RTE), Casimir error, absolute energy error, final training loss, and the number of trainable parameters. Here MAE is averaged over all test trajectories and time levels. Absolute rather than relative energy error is reported, since the Hamiltonian is defined only up to an additive constant. As in the case, the training time was on the order of s per run on the Linux GPU cluster; detailed timing comparisons are not reported because the runs were carried out on different GPU architectures.
Table 3.
A summary of results for CO-LPNet experiments. MAE is averaged over all test trajectories and time levels, while Peak MAE is the largest time-level mean absolute error over the test set. RTE denotes Relative Trajectory Error, Max denotes the maximum Casimir deviation from the ground-truth Casimir values, and Max denotes the maximum absolute energy error. The table also reports the final training loss and the number of trainable parameters.
The prediction horizon used for the examples is shorter than in the examples because the system is substantially more difficult to predict, due to both its higher dimension and the more complex coupling in the dynamics. For , the reduced phase space has dimension 9, whereas the reduced phase space has dimension 18. In addition, the Lie–Poisson dynamics couples angular and translational momentum variables, leading to faster accumulation of trajectory error under repeated application of the learned map. In the reported simulations, the MAE for the examples reaches values of order after roughly 100 time steps, whereas comparable error levels for the examples occur only over much longer integrations, up to 1000 time steps. For this reason, the numerical comparison for is reported over 200 steps, while the examples are reported over 1000 steps. Over these respective horizons, the accumulated MAE for the examples is of the same order as the accumulated MAE for the examples over 1000 steps. The MAE panels in Figure 7 and Figure 9 show the corresponding error-versus-time behavior for the simulations.
7.4. Studies of the Effects of Noise in Data on Method Accuracy
Since one cannot expect the data forming the input to the neural networks to be perfect, studying the robustness of the system with respect to noise is of ultimate importance for practical applications. This paper studies the case where the underlying system is fully deterministic, but the collected data representing the system’s evolution are only known up to a certain accuracy.
More precisely, the initial data is perturbed by a small amount of additive noise. The article proceeds with the assumption that the noise follows a zero-mean normal distribution , where the noise amplitude (standard deviation) is chosen from the discrete set . The network is trained on this noisy data, then test trajectories are reconstructed and compared against the unperturbed ground truth. To ensure statistical robustness, five independent noise realizations are evaluated for every value of , and the final metrics are averaged.
For brevity, the results of this study are presented exclusively for the group with three interacting particles under the democracy topology, as previously detailed in Section 7.1. In Figure 10, the reconstructed trajectories from the noisy data are illustrated for all nine momentum components. Visually, the trajectories generated under small values remain nearly indistinguishable from the exact ground truth.
Figure 10.
Trajectory reconstruction performed by the system trained on data corrupted by Gaussian noise , with standard deviations . Color code: Black represents the Ground Truth; Purple represents (clean data); while the blue, cyan, yellow, orange, and red solid lines correspond to and , respectively.
In order to analyze the system’s performance, the integration errors and conservation properties are evaluated as a function of the noise level (Figure 11). As expected from the geometric structure of the architecture, all Casimir invariants are preserved to machine precision irrespective of the noise level (left panel). The trajectory accuracy shows an interesting non-monotone dependence on the injected noise: in these experiments, the reconstruction improves for small amounts of noise ( and ) compared with the noiseless baseline (), before degrading for .
Figure 11.
Quantitative error analysis of the system trained on noisy data. Left: The absolute drift in the Casimir invariants, , confirming preservation to machine precision for all noise levels. Center: The absolute drift in energy conservation, , averaged over all realizations. Right: The Mean Absolute Error (MAE) of the predicted trajectories relative to the ground truth, averaged across all test trajectories, components, and noise realizations. The color code matches that of Figure 10.
This observation may be consistent with a regularization-like effect, since very small noise in the training data can discourage overfitting to a finite set of sampled trajectories. However, the present experiments show only an observed behavior in the tested configurations; they do not establish a general improvement mechanism. In particular, it is not claimed that noise-induced regularization has been proved for this architecture, nor that adding noise should generally improve prediction. A systematic investigation of this effect, including independent repetitions over noise realizations, initial data, and training seeds, is left for future work.
For the additional noise robustness study, the baseline CO-LPNet architecture (, , ) was used with particles, time step , and coupling strength . The simulations covered and with both Dictatorship and Democracy coupling topologies. The clean data sets contained 40 trajectories for and 80 trajectories for , with 51 points per trajectory.
All noisy models were trained with the same schedule as the baseline: Adam optimization with learning rate , full-batch updates, validation fraction , training seed 5678, and 10,000 epochs.
Noise was injected into both endpoints of each one-step training pair before the training/validation split, using independent coordinate-wise samples with amplitudes . For Gaussian noise, was used; for uniform noise, was used; and for Poisson noise, with was used. Thus all three noise models have zero mean and variance per coordinate.
After training, the learned map was evaluated from 10 clean initial conditions and compared with clean ground-truth trajectories over 1000 steps for and 200 steps for . Table 4 reports the resulting mean trajectory error.
Table 4.
Noise robustness study for CO-LPNet. Entries show the mean rollout error against clean ground-truth trajectories after training on noisy one-step data. Column labels denote the noise law and amplitude: G is Gaussian, U is uniform, and is Poisson.
7.5. Ablation Studies
In order to study the efficiency of the method, an ablation study over selected architectural hyperparameters is presented. Table 5 reports the mean error between the ground-truth and learned trajectories for several network widths and numbers of Poisson-map repeats , using the same training schedule. Lower values indicate better performance. The results show that the more economical width gives the best accuracy for both cases, while gives the best accuracy for both cases. The optimal number of repeats is except for the Democracy case, where gives the smallest error.
Table 5.
CO-LPNet width and Poisson-repeat ablation. Entries show mean error compared to the ground truth; and are the baseline. The best result in each row is shown in bold.
Next, Table 6 reports the effect of varying the number of data points per trajectory used for learning, while keeping the number of trajectories fixed: 40 for and 80 for . Thus correspond to 400, 1000, and 2000 one-step training pairs for , and to 800, 2000, and 4000 one-step training pairs for , respectively. The same table also reports the effect of varying the time step h, with all other parameters fixed. Increasing the amount of training data generally improves accuracy, although the deterioration for remains moderate in several cases. The dependence on the time step is stronger: the smallest step size gives the lowest error in all four cases, while the largest step size leads to substantially larger trajectory errors.
Table 6.
CO-LPNet ablation in training-data size and time step. Entries show the mean error compared to the ground truth trajectories. The best result within each ablation group and each row is shown in bold.
Finally, Table 7 reports the effect of varying the coupling strength and the number of particles N. The dependence on is not monotone across all cases: gives the smallest error for Democracy, while gives the smallest error for Dictatorship and both cases. This reflects the fact that changing the coupling strength modifies both the interaction scale and the complexity of the resulting trajectories. The particle-number ablation shows the expected trend: gives the smallest error in all four cases, while increasing N makes the prediction problem higher-dimensional and more difficult.
Table 7.
CO-LPNet ablation in coupling strength and particle number. Entries show the mean rollout error. The best result within each ablation group and each row is shown in bold.
7.6. Comparison with Alternative Structure-Preserving Methods
CO-LPNets are compared with two alternative structure-preserving methods: the original LPNets [3] and a PNN-type symplectic neural network [10]. All models were trained on the same clean one-step trajectory data, with particles, time step , coupling strength , and the same train/validation split. The experiments used 40 training trajectories, while the experiments used 80 training trajectories; each trajectory contained 51 time points. The models were trained using Adam optimization with learning rate for 10,000 epochs. Evaluation was performed by applying the learned map repeatedly from 10 clean initial conditions and comparing with clean ground-truth trajectories over 1000 steps for and 200 steps for .
For CO-LPNets, the baseline architecture , , and was used, where W is the width of each coefficient network, D is its depth, and P is the number of repeated Poisson transformations. The LPNets baseline used the same Lie–Poisson flow layers, but with each coefficient depending only on its corresponding coordinate rather than on the full coupled state. Thus, LPNets preserve the relevant Lie–Poisson structure, but have a more restricted representation of the coupled dynamics. The PNN baseline was implemented as a learned invertible coordinate transformation, followed by a symplectic network in the transformed coordinates, followed by the inverse coordinate transformation.
The PNN comparison should be interpreted with care. PNNs are naturally designed for systems where a global set of canonical, or Darboux, coordinates is available on each symplectic leaf. In contrast, the systems considered here evolve on noncanonical Lie–Poisson spaces. For example, for the symplectic leaves are spheres, which cannot be covered by a single global Darboux chart. Consequently, the PNN architecture is not geometrically matched to the problem: it must learn both an effective coordinate representation and the dynamics without access to a globally valid canonical chart. PNN is therefore included as a reference baseline, while noting that it is being applied outside the setting in which its canonical symplectic structure is naturally valid.
Table 8 shows that CO-LPNets give the smallest mean error in all four test cases. The improvement over LPNets indicates that allowing the coefficient functions to depend on the full coupled state is important for accurately representing the interacting particle dynamics. The larger errors for PNN are consistent with the absence of a global Darboux representation for the Lie–Poisson systems considered here.
Table 8.
Comparison of CO-LPNets, LPNets, and PNN baselines. Entries show the mean error against clean ground-truth trajectories; the best result in each row is shown in bold.
Finally, the computational cost of CO-LPNets is comparable to that of the competing neural-network methods considered here. In the laptop implementation, training typically required approximately 5–40 min on an Apple MacBook Pro with an M2 Max processor, depending on the case. On the Linux GPU cluster, the corresponding training times were on the order of s per run, as reported above. Evaluation of learned trajectories was considerably cheaper, usually taking less than one minute, and was much faster than generating the corresponding ground-truth trajectories with the implicit Lie–Poisson integrator. Within this comparable computational cost, CO-LPNets achieved substantially higher trajectory accuracy, as shown in Table 8.
8. Conclusions and Future Work
The main contribution of this paper is the presentation of a novel method for learning the full phase-space behavior of general Lie–Poisson systems, particularly those relevant to optimal control. The proposed models are highly efficient, using a relatively small number of trainable parameters and requiring a modest amount of data. The completeness of the learned transformations is discussed, and a formal connection is established between the present construction and the established field of structure-preserving splitting methods. The proposed method is called CO-LPNets. The illustrative examples involving interacting particles on the and groups demonstrate the potential of the method and its applicability to higher-dimensional systems. By design, CO-LPNets preserve the underlying Poisson structure and conserve Casimir invariants to machine precision. The robustness of the method with respect to noise is also demonstrated.
The goal for future work is to extend this approach to the optimal control of interacting particles evolving on the group, which is important for quantum computing. Another compelling problem is the interaction of several agents evolving on different Lie groups, where one group is a subgroup of another. For example, a flying drone evolves on the group, while a land-based or sea-surface drone evolves on the group, which is a subgroup of . Thus, the evolution of such a control system can be considered on the direct product group . Theoretical studies of such systems have been undertaken in [54]; extending the machine-learning methods proposed in this article to these more general and practically important cases is a natural direction for future work.
Finally, the described methods can be applied to rigorous, structure-preserving reduced-order modeling (ROM) of Lie–Poisson systems. While recent literature allows for the rigorous construction of ROMs for canonical systems [55,56,57], there is no apparent general mathematical mechanism for reducing a high-dimensional Lie–Poisson bracket to a lower-dimensional space while preserving its Poisson structure. The proposed method computes the dominant motions directly in the full Lie–Poisson space using the most essential Poisson mappings for the dynamics, potentially leading to a substantial reduction in computational complexity. This approach will be developed in future work.
Author Contributions
Conceptualization, V.P.; Methodology, S.H. and V.P.; Software, S.H. and V.P.; Validation, S.H. and V.P.; Formal analysis, S.H. and V.P.; Investigation, S.H. and V.P.; Resources, S.H. and V.P.; Data curation, V.P.; Writing—original draft, S.H. and V.P.; Writing—review & editing, S.H. and V.P.; Visualization, S.H. and V.P.; Project administration, V.P.; Funding acquisition, V.P. All authors have read and agreed to the published version of the manuscript.
Funding
SH was mainly supported by the Vanier Canada Graduate Scholarships (Vanier CGS) awarded by the Natural Sciences and Engineering Research Council (NSERC). VP and SH were partially supported by the NSERC Discovery Grant. VP was also partially supported by the Shelby Foundation at the University of Alabama.
Data Availability Statement
The raw data supporting the conclusions of this article will be made available by the authors on request.
Acknowledgments
We are grateful to Anthony Bloch, Denys Cherhykalo, Chris Eldred, François Gay-Balmaz, Tristan Griffith, Anthony Gruber, Melvin Leok, Andrew Sinclair, Irina K. Tezaur, and Dmitry Zenkov for fruitful and engaging discussions. We would also like to thank the University of Alabama and the Office of Information Technology for providing high-performance computing resources and support that contributed to these research results. Use of AI in this work: No artificial intelligence (AI) was used in the conceptualization of this manuscript or in the development of the scientific ideas presented in this paper. AI tools were used in the final stages of preparation only to improve grammar, clarity, and readability. AI-assisted coding was also used during the software development phase of the project. After the initial NumPy codebase for the particle system was written manually, the large language models Gemini Pro and ChatGPT GPT-5.6 Codex were used to assist with scaling the data generation, implementing the learning procedure for CO-LPNets, and implementing the ablation studies and competing methods, namely LPNets and PNN. All AI-assisted code was reviewed and validated by the authors. The authors take full responsibility for the code performance and the results presented in this paper.
Conflicts of Interest
The authors declare no conflicts of interest.
Appendix A. Background: Optimal Control and Symmetry Reduction
Appendix A.1. The Lie-Poisson Theory of Optimal Control of Coupled Interacting Particles
This section outlines the theoretical framework for symmetry-reduced optimal control of N interacting particles. This chapter is presented for reference to define the system and explain how the ground truth data for the application of the proposed learning method was computed. Our derivation follows [1,2] quite closely, including the notation used, although we try to be concise here and skip a few details. Readers interested in the comprehensive derivations are encouraged to consult those primary sources.
We consider a system of N identical particles, where the configuration of each individual agent is represented by a Lie group G. Consequently, the total configuration manifold for the collective system is given by the direct product group .
To reflect on the connection of this theory to mechanics, we first address symmetry reduction for mechanical systems before extending it to optimal control. A mechanical system on is traditionally characterized by the canonical Poisson bracket on the cotangent bundle . In this representation, the system state is defined by the coordinates and their conjugate momenta .
As introduced in Section 1, the full symmetry reduction of such canonical systems yields Lie-Poisson systems (5) (see [22], Chapter 10). For any system defined on a Lie group G, there is an associated Lie algebra with a bracket for elements . Moreover, is defined as the duality pairing between the algebra and its dual space , where the momentum co-vector is . For functions , the partial derivatives reside in , forming the Lie–Poisson bracket structure seen in (5). Since the focus of this paper is on left-invariant dynamics, the negative sign convention in the bracket definition is adopted through the paper.
Appendix A.2. Pontryagin’s Maximum Principle: Linking Optimal Control and Hamiltonian Dynamics
Pontryagin’s Maximum Principle provides the formal bridge between optimal control and Hamiltonian mechanics. Consider a system governed by the differential equation subject to control inputs . Here, x, and u may be scalars or vectors; if x is a vector, then a is a vector-valued function with the same number of components as x. Suppose we also have fixed boundary conditions and . Then, the objective is to minimize the following cost functional:
where the control Lagrangian L encodes optimality criteria such as minimum time, energy, or effort. Pontryagin’s Maximum Principle [58,59] introduces a co-state and defines the control Hamiltonian as . The necessary conditions for an extremum are:
The last two equations are identical in their form to the canonical Hamilton’s equations, where x serves as the coordinate and as the momentum.
In the present study, we assume the control Lagrangian L is unknown, rendering the exact Hamiltonian in (A2) inaccessible. Furthermore, we assume no prior knowledge regarding the specific nature of the control —including its dimensionality, application axes, or functional form. However, we do assume that the symmetry of the configuration manifold is known, and the resulting Pontryagin’s Hamiltonian possesses the required symmetry criteria. This assumption is physically and mathematically justified, as the space in which the particles evolve is usually geometrically well-defined. The objective is to forecast the system’s trajectory by synthesizing this known geometric symmetry with observational data of its past evolution. To this end, the symmetry reduction theory for optimal control is applied as formulated in [1,2].
Appendix A.3. Symmetry Reduction Applied to Optimal Control
The Lie–Poisson Reduction Theorem [22] (see the proof for presented in Section 13.2 of that paper), derives the Lie–Poisson bracket from the general canonical bracket through a process known as symmetry reduction. In classical mechanics, this procedure is utilized to map the evolution of a system from the full phase space, which is typically the cotangent bundle of a configuration manifold, to the Lie algebra. Since the phase space is the cotangent bundle of the full Lie group (all coordinates and momenta), the reduction to the Lie algebra of that group, which is a linear space, is a drastic simplification. A practical example is the simulation of satellite dynamics via Euler’s equations; the motion is calculated within the space of angular momenta rather than the more complex space of orientation matrices and their associated momenta.
Symmetry reduction in optimal control mirrors the Lie-Poisson reduction for in canonical Hamiltonian systems [60,61]. As described in [41,43] (pp. 227–267), this process reduces the optimality conditions in (A2) to a Lie–Poisson system when Lie group symmetries are present. For an optimal control problem involving a single agent, the state variable x in (A2) is assumed to reside on a Lie group G. In this geometric context, the co-state acts as the mathematical analogue of mechanical momentum. If the Pontryagin Lagrangian is determined solely by the control u, and that control directly influences velocities, as is the case in (A10) below, the resulting Hamiltonian H permits a complete symmetry reduction to a Lie–Poisson system.
This theoretical framework extends to the collective dynamics of multiple interacting controlled agents. Drawing again on the mechanical analogy, we begin with a canonical Hamiltonian , where each configuration belongs to G and each momentum resides in the cotangent space . If the system exhibits symmetry only with respect to the group G, rather than the full product manifold , a complete Lie-Poisson reduction is generally not possible. Instead, the reduced space must include additional Lie-group-valued variables representing relative configurations, defined as . The resulting governing equations then consist of Lie-Poisson components coupled with the evolution of these relative elements [38], introducing significant analytical complexity.
To illustrate this point, consider describing the evolution of coupled rigid bodies. The global rigid body symmetry in a coupled two-body system [60,62] allows a reduction from the initial phase space which is a cotangent bundle of , i.e.,
to the reduced manifold . Physically, this reduction captures the coupled evolution of the two momenta along the relative orientation of the objects. Consequently, in mechanical problems involving manifolds with G-symmetry, complete reduction to is rare unless the Hamiltonian possesses a highly specific structure.
Similar constraints would, in principle, apply to the optimal control of interacting particles [1,2]. However, due to the unique functional form of the control Hamiltonian, these systems actually achieve a complete symmetry reduction to the pure Lie-Poisson case. This useful fact bypasses the need to explicitly track relative orientations.
The following section provides the mathematical formulation for the collective dynamics of N controlled particles. This foundation is necessary for examining the ‘Dictatorship’ and ‘Democracy’ control Hamiltonian models discussed in Section A.5. Although the primary focus of this paper is a data-driven methodology, a rigorous exposition of this general theory is essential to illustrate how the ground-truth data used for learning is generated.
Appendix A.4. The General Theory of Controlled Dynamics of N Interacting Particles
The following derivation adheres to the notation established in [1,2]. The connectivity between particles is modelled, using a connected, undirected graph where the vertex set is . The graph contains no self-loops, and represents the degree of vertex . Below, several foundational definitions are introduced to start with.
Definition A1 (Definition of graph quantities).
- 1.
- Let A be the adjacency matrix with elements for . The entries are defined so that if a connection exists between vertices and , and otherwise.
- 2.
- The degree matrix D is a diagonal matrix defined as.
- 3.
- The graph Laplacian is given by , with elements denoted by for .
By construction, the matrices A, D, and B are symmetric [42]. Furthermore, the Laplacian satisfies , where is the vector of ones. Consequently, serves as an eigenvector of B corresponding to the zero eigenvalue; physically, this implies that the row and column sums of B are identically zero.
Consider an ensemble of N agents interacting via a control protocol modeled by this graph. In the framework used here, the particles (vehicles) correspond to vertices, and edges represent active communication or physical coupling. The article assumes that each agent evolves on a finite-dimensional Lie group G; therefore, the collective system state resides in , the direct product of N copies of G. Let n denote the dimension of the Lie group G and its associated Lie algebra . The inner product is defined as for . This inner product defines the trace norm . A basis , selected for the Lie algebra, is assumed to be orthonormal under the trace inner product. Additionally, let represent the duality pairing between the primal and dual spaces [2].
The derivation of symmetry reduction for Pontryagin’s maximum principle in this context was originally presented in [1,2,41], and is succinctly reproduced here. This paper focuses on the specific case where the state . The optimal control problem (A1) such that the Lagrangian depends exclusively on the controls, is examined, leading to the minimization objective:
Since is independent of the group configuration g, it is a G-invariant Lagrangian. Each variable generates the control within the Lie algebra , governed by the kinematic equation:
subject to fixed boundary conditions and . The canonical state and co-state equations (the last two equations in (A2)) are superseded by equations derived from the Lie–Poisson bracket via the Lie–Poisson Reduction Theorem (see, e.g., [22], Section 13.2). The link between controls and symmetry-reduced momenta corresponds to the first condition of (A2). We define the pre-Hamiltonian as:
where is the momentum in the cotangent space, and resides in the dual of the collective Lie algebra. While should be formally referred to as the ‘symmetry-reduced co-state’, we will adopt the mechanical analogy and refer to it simply as ‘momentum’.
For simplicity of exposition, the analysis is restricted to Lie groups admitting a matrix representation. This is not really a limitation of the method since all Lie groups likely to be encountered in practical problems can be represented in terms of matrices. Consequently, both the group elements g and the algebra elements are expressed as block-diagonal matrices:
where the aggregate control vector is with total dimension . In this formulation, the pre-Hamiltonian (A5) becomes:
The condition for optimality with respect to the control variables u, i.e., the first extremal condition in (A2), becomes:
where is the composite momentum vector. By the implicit function theorem [63], one can solve (A7) for provided the Hessian is non-degenerate. If is linear in u, this non-degeneracy condition reduces to the requirement that the Hessian of the Lagrangian, , which is assumed to hold true.
Adopting the framework of [1,2], the Lagrangian specific to interacting particles is considered:
where is a coupling constant. Utilizing the relationship between the adjacency matrix A and the Laplacian B (where diagonal elements and off-diagonals ), we can restructure the Lagrangian (A8) as:
We assume the control velocities are affine functions of the control inputs :
Here, , and the basis is orthonormal. The system is underactuated () with a drift component aligned with an uncontrolled direction (). While the precise form of (A10) is treated as unknown during the discovery phase, the knowledge of its’ particular form is essential for generating the ground truth data.
Further, the dual basis for the coalgebra is introduced, denoted . Letting be the expansion coefficients such that , the optimality condition (A7) simplifies to:
for and . Differentiation of the Lagrangian (A8) establishes the relationship between momenta and controls:
To vectorize this, let be the full momentum vector of length . The vector of the m controlled components for the k-th agent is denoted as . The relationship between the controlled momentum components and control inputs is then:
where ⊗ is the Kronecker product. Since the eigenvalues of B are non-negative, the matrix inverse exists for . The coupling matrix is defined as:
Solving for the controls yields . Substituting these optimal controls back into the pre-Hamiltonian (A6) yields the reduced control Hamiltonian (up to a constant) [1,2]:
Crucially, this reduced system evolves entirely on , avoiding the need for variables describing relative orientation. The collective dynamics for are governed by the Lie–Poisson equations:
where the Poisson tensor block is an antisymmetric matrix defined by:
Here, are the structure constants satisfying .
Remark A1 (Geometric structure).
Asa result of the complete symmetry reduction, Equation (A16) can be expressed in coordinate-free notation as , where denotes the co-adjoint action of the Lie algebra (assuming left invariance [22,44]).
Remark A2.
The structure of the Poisson tensor implies that remains a stationary point for any control Hamiltonian h.
To further detail the reduced Hamiltonian , specific graph Laplacians B and particle dynamics on specific Lie groups must be considered.
Appendix A.5. Two Different Cases of Adjancency Matrix
In what follows, two cases of an adjacency matrix are considered, in order to be concrete. The first case refers to the adjacency matrix A when one ‘leading’ particle is connected to all other particles, which we call ‘Dictatorship’. Another case happens when the adjacency matrix A is such that all particles are connected with all other particles, which we will denote as ‘Democracy’. In these two cases, the inverse matrix , appearing in the corresponding part of the matrix defined by (A14), can be explicitly computed. The matrix is always invertible, but explicit formulas, introduced below, are useful for analytic considerations.
Appendix A.6. The Case of ‘Dictatorship’ Governance
At first, the ‘Dictatorship’ case is considered, that is, the case, when particle 1 is connected to all other particles. There are no other connections between particles (edges of the graph). In this case the adjacency matrix A is given by the matrix
The degree matrix is the matrix , and the graph Laplacian is the matrix
Moreover, for this particular case of ‘Dictatorship’ control, after some algebra, the exact formula for the inverse of is obtained:
Appendix A.7. The Case of ‘Democratic’ Control
Next, the ‘Democracy’ case is considered, that is, when each particle is connected to all of the others. In other words, we have a complete graph. In this case, the adjacency matrix A is given by the matrix
the degree matrix is the matrix , and the graph Laplacian is the matrix
In this particular case, the inverse of the matrix is also given explicitly as
The inversion of the matrix does not allow explicit formulas as in the case of ‘Dictatorship’ (A18) or ‘Democracy’ (A19). Thus, it is advantageous to consider the dynamics for these particular cases of interactions between the particles, as they allow additional analytical insights into the problem.
Analytical solutions may be obtained for a single particle dynamics for particular groups in terms of elliptic functions. Such solution for a particle evolving on group was obtained in [2]. In the Appendix, these analytical solutions are derived for group in Appendix B.2 and a particular realization of the control in group in Appendix B.3. While the single-particle solution does not address the collective behavior, we present these solutions for reference since they allow analytical solutions, and, to our knowledge, have not been described before.
Appendix B. Lie–Poisson Reduced Dynamics for a Single Particle
Appendix B.1. Single Particle Equations in the General Case
This section computes the equations of motion for the single particle, that is, . It is clearly not a coupled case, but it also has its own pedagogical merit. In this case, the Poisson tensor will comprise only one block and, thus, will simplify (A17) for a single particle:
where , again, denote structure constants for the corresponding Lie algebra . Moreover, now the matrix , and we can take . Then , . Finally,
According to (A15), the Hamiltonian looks as follows, since the particle index always equals :
where m is the number of controls. Reference [2] considered the case of group; while this paper extends these considerations to and groups.
Appendix B.2. The Case of Single Particle Dynamics Evolving on SO (3)
In this Section, the Lie–Poisson reduced dynamics are considered for a single particle evolving on group. The values (one control in the first element) and (drift in the second element) are used. With the use of (A17) and in terms of notation (27) for k = 1, the Poisson tensor is
According to (A22), the Hamiltonian becomes
The Casimir function is which clearly satisfies .
For this single particle problem, the Lie–Poisson reduced dynamics equations (A16), where , are given by
or, equivalently,
One verifies that h is a conserved quantity, as we have
Hence, the Hamiltonian and the Casimir function are conserved quantities. From (A24) the following second-order equation is derived:
that is,
In fact, (A25) is the same as Equation (36) in [1] and Equation (3.24) in [2] (which, we remind the reader, was written for group), with the only difference . Equation (A25) can be solved in terms of Jacobi elliptic functions. Interestingly enough, (A25) also appears in the theory of elasticity [64].
Appendix B.3. The Case of Single Particle Dynamics Evlving on SE (3) with a Particular Hamiltonian Allowing Analytical Solution
In this Section, the Lie–Poisson reduced dynamics for a single particle, evolving on group, are introduced. Controls are used in the first two coordinates (rotations), while drift is used in 4-th coordinate (first linear momentum). Using (A17) and notation (36) for , the Poisson tensor is
With the use of (A21):
According to (A22), the Hamiltonian looks like
There are two Casimir functions: and which clearly satisfy and .
For this single particle problem the Lie–Poisson reduced dynamics equations (A16), where , are given by
or, equivalently,
One verifies that h is a conserved quantity due to
Hence, the Hamiltonian and both Casimir functions are conserved quantities. No further simplification of equations is possible.
However, if we were to consider a slightly different Hamiltonian with (drift in the 3rd linear momentum coordinate), so that , then Lie-Poisson Equation (A16) can be simplified and solved exactly for particular initial conditions. For this single particle problem the Lie–Poisson reduced dynamics equations (A16), where are given by
or, equivalently,
One verifies that h is a conserved quantity due to
The third equation of (A28) yields that . Let us suppose the initial condition , that is, . In this case the system of Equation (A27) simpifies as follows:
Differentiating the fourth equation of (A29) we obtain the second-order equation
Substituting expressions for the Hamiltonian h and the first Casimir , we derive:
Notice that . Integration of this equality yields
Substituting from (A30) and performing the integration explicitly, we obtain
where D is an arbitrary constant which appears due to integration.
Our next goal is to perform a linear exchange of variables with such constants A and B (to be determined below) that the Equation (A31) will turn into
which can be solved using Weierstrass elliptic functions ( and are some constants). Performing the above mentioned exchange of variables, the Equation (A31) is rewritten as
Comparing (A32) and (A34) yields that we must have and . That is, the desired exchange of variables is . Then the Equation (A34) takes the form
That is, comparing (A32) and (A35), we obtain constants and .
Appendix C. Computations of Gradients of Hamiltonians
Appendix C.1. SO (3) Group
Appendix C.1.1. Dictatorship
Appendix C.1.2. Democracy
Similarly, gradients for each particle are canculated as
The partial derivatives with respect to are computed as
Appendix C.2. SE (3) Group
Appendix C.2.1. Dictatorship
The matrix in (A15) can be computed explicitly as
That expression leads to the Hamiltonian in the case of ‘Dictatorship’ (39):
Taking partial derivatives of (39) yields
with
We need to find the derivatives of h with respect to and . We start with . We see that
Next, we consider derivatives of h with respect to . We observe that
Appendix C.2.2. Democracy
The matrix can be again computed explicitly as
Using that matrix and the expression (A15), we arrive to the expression for the Hamiltonian given by (40):
Then the gradients of that Hamiltonian are calculated as follows:
with
We see that the derivative with respect to the first component for each particle is given by
while the derivative with respect to the second component is given by
All in all, we see that the Hamiltonian h, and, hence, partial derivatives and are symmetric to each other with respect to the first and second components of all particles. This fact makes sense intuitively as well, since we suppose that control is applied equivalently in both components.
Appendix D. Derivatives of the Transformation Matrices with Respect to Parameters
The partial derivatives of matrices, which are Poisson transformations for group:
The partial derivatives of matrices, which are Poisson transformations for group:
Explicitly:
Then, the partial derivatives are:
References
- Justh, E.W.; Krishnaprasad, P. Extremal collective behavior. In Proceedings of the 49th IEEE Conference on Decision and Control (CDC); IEEE: Piscataway, NJ, USA, 2010; pp. 5432–5437. [Google Scholar][Green Version]
- Justh, E.W.; Krishnaprasad, P. Optimality, reduction and collective motion. Proc. R. Soc. A Math. Phys. Eng. Sci. 2015, 471, 20140606. [Google Scholar] [CrossRef] [Scilit]
- Eldred, C.; Gay-Balmaz, F.; Huraka, S.; Putkaradze, V. Lie–Poisson Neural Networks (LPNets): Data-Based Computing of Hamiltonian Systems with Symmetries. Neural Netw. 2024, 173, 106162. [Google Scholar] [CrossRef] [Scilit]
- Raissi, M.; Perdikaris, P.; Karniadakis, G.E. Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations. J. Comput. Phys. 2019, 378, 686–707. [Google Scholar] [CrossRef] [Scilit]
- Karniadakis, G.E.; Kevrekidis, I.G.; Lu, L.; Perdikaris, P.; Wang, S.; Yang, L. Physics-informed machine learning. Nat. Rev. Phys. 2021, 3, 422–440. [Google Scholar] [CrossRef] [Scilit]
- Krishnapriyan, A.; Gholami, A.; Zhe, S.; Kirby, R.; Mahoney, M.W. Characterizing possible failure modes in physics-informed neural networks. Adv. Neural Inf. Process. Syst. 2021, 34, 26548–26560. [Google Scholar]
- Greydanus, S.; Dzamba, M.; Yosinski, J. Hamiltonian neural networks. Adv. Neural Inf. Process. Syst. 2019, 32, 15353–15363. [Google Scholar]
- Marsden, J.E.; West, M. Discrete mechanics and variational integrators. Acta Numer. 2001, 10, 357–514. [Google Scholar] [CrossRef] [Scilit]
- Jin, P.; Zhang, Z.; Zhu, A.; Tang, Y.; Karniadakis, G.E. SympNets: Intrinsic structure-preserving symplectic networks for identifying Hamiltonian systems. Neural Netw. 2020, 132, 166–179. [Google Scholar] [CrossRef] [Scilit]
- Jin, P.; Zhang, Z.; Kevrekidis, I.G.; Karniadakis, G.E. Learning Poisson systems and trajectories of autonomous systems via Poisson neural networks. IEEE Trans. Neural Netw. Learn. Syst. 2022, 34, 8271–8283. [Google Scholar] [CrossRef] [Scilit]
- Vaquero, M.; Cortés, J.; de Diego, D.M. Symmetry preservation in Hamiltonian systems: Simulation and Learning. arXiv 2023, arXiv:2308.16331. [Google Scholar]
- Vaquero, M.; de Diego, D.M.; Cortés, J. Designing Poisson Integrators Through Machine Learning. arXiv 2024, arXiv:2403.20139. [Google Scholar]
- Eldred, C.; Gay-Balmaz, F.; Putkaradze, V. CLPNets: Coupled Lie-Poisson Neural Networks for Multi-Part Hamiltonian Systems with Symmetries. Neural Netw. 2025, 189, 107441. [Google Scholar] [CrossRef] [Scilit]
- Han, C.D.; Glaz, B.; Haile, M.; Lai, Y.C. Adaptable Hamiltonian neural networks. Phys. Rev. Res. 2021, 3, 023156. [Google Scholar] [CrossRef] [Scilit]
- David, M.; Méhats, F. Symplectic learning for Hamiltonian neural networks. arXiv 2021, arXiv:2106.11753. [Google Scholar]
- Cranmer, M.; Greydanus, S.; Hoyer, S.; Battaglia, P.; Spergel, D.; Ho, S. Lagrangian neural networks. arXiv 2020, arXiv:2003.04630. [Google Scholar]
- Šípka, M.; Pavelka, M.; Esen, O.; Grmela, M. Direct Poisson neural networks: Learning non-symplectic mechanical systems. arXiv 2023, arXiv:2305.05540. [Google Scholar]
- Hu, J.; Ortega, J.P.; Yin, D. A global structure-preserving kernel method for the learning of Poisson systems. J. Nonlinear Sci. 2025, 35, 79. [Google Scholar] [CrossRef] [Scilit]
- Leok, M.; Shingel, T. General techniques for constructing variational integrators. Front. Math. China 2012, 7, 273–303. [Google Scholar] [CrossRef] [Scilit]
- Hall, J.; Leok, M. Spectral variational integrators. Numer. Math. 2015, 130, 681–740. [Google Scholar] [CrossRef] [Scilit]
- Arnol’d, V.I. Mathematical Methods of Classical Mechanics; Springer Science & Business Media: Berlin/Heidelberg, Germany, 2013; Volume 60. [Google Scholar]
- Marsden, J.; Ratiu, T. Introduction to Mechanics and Symmetry: A Basic Exposition of Classical Mechanical Systems; Springer Science & Business Media: Berlin/Heidelberg, Germany, 2013; Volume 17. [Google Scholar]
- Putkaradze, V. A Concise Introduction to Classical Mechanics; Springer: Berlin/Heidelberg, Germany, 2025. [Google Scholar]
- Chen, Z.; Zhang, J.; Arjovsky, M.; Bottou, L. Symplectic recurrent neural networks. arXiv 2019, arXiv:1909.13334. [Google Scholar]
- Xiong, S.; Tong, Y.; He, X.; Yang, S.; Yang, C.; Zhu, B. Nonseparable symplectic neural networks. arXiv 2020, arXiv:2010.12636. [Google Scholar]
- Tao, M. Explicit symplectic approximation of nonseparable Hamiltonians: Algorithm and long time performance. Phys. Rev. E 2016, 94, 043303. [Google Scholar] [CrossRef] [Scilit]
- Sharma, H.; Najera-Flores, D.A.; Todd, M.D.; Kramer, B. Lagrangian operator inference enhanced with structure-preserving machine learning for nonintrusive model reduction of mechanical systems. Comput. Methods Appl. Mech. Eng. 2024, 423, 116865. [Google Scholar] [CrossRef] [Scilit]
- Eldred, C.; Gay-Balmaz, F.; Putkaradze, V. Variational Neural Networks for Observable Thermodynamics (V-NOTS). arXiv 2025, arXiv:2509.09899. [Google Scholar]
- Chen, R.; Tao, M. Data-driven prediction of general Hamiltonian dynamics via learning exactly-symplectic maps. In Proceedings of the International Conference on Machine Learning, PMLR, Virtual, 18–24 July 2021; pp. 1717–1727. [Google Scholar]
- Burby, J.W.; Tang, Q.; Maulik, R. Fast neural Poincaré maps for toroidal magnetic fields. Plasma Phys. Control. Fusion 2020, 63, 024001. [Google Scholar] [CrossRef] [Scilit]
- Dubinkina, S.; Frank, J. Statistical mechanics of Arakawa’s discretizations. J. Comput. Phys. 2007, 227, 1286–1305. [Google Scholar] [CrossRef] [Scilit]
- Bajārs, J. Locally-symplectic neural networks for learning volume-preserving dynamics. J. Comput. Phys. 2023, 476, 111911. [Google Scholar] [CrossRef] [Scilit]
- Effati, S.; Pakdaman, M. Optimal control problem via neural networks. Neural Comput. Appl. 2013, 23, 2093–2100. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.; Shi, Y.; Zhang, B. Optimal control via neural networks: A convex approach. arXiv 2018, arXiv:1805.11835. [Google Scholar]
- Kim, Y.H.; Lewis, F.L.; Dawson, D.M. Intelligent optimal control of robotic manipulators using neural networks. Automatica 2000, 36, 1355–1364. [Google Scholar] [CrossRef] [Scilit]
- Sánchez-Sánchez, C.; Izzo, D. Real-time optimal control via deep neural networks: Study on landing problems. J. Guid. Control Dyn. 2018, 41, 1122–1135. [Google Scholar] [CrossRef] [Scilit]
- Wang, X.; Dou, Y.; Yi, X.; Zhang, Y.; Li, X.; Li, B.; Peng, H.; Wang, L.; Teo, K.L. When Optimal Control Meets Neural Network: A Comprehensive Survey. Arch. Comput. Methods Eng. 2026, 33, 6797–6852. [Google Scholar] [CrossRef] [Scilit]
- Ellis, D.C.; Gay-Balmaz, F.; Holm, D.D.; Putkaradze, V.; Ratiu, T.S. Symmetry reduced dynamics of charged molecular strands. Arch. Ration. Mech. Anal. 2010, 197, 811–902. [Google Scholar] [CrossRef] [Scilit]
- McLachlan, R.I. Explicit Lie–Poisson integration and the Euler equations. Phys. Rev. Lett. 1993, 71, 3043. [Google Scholar] [CrossRef] [Scilit]
- Tonti, E. The Mathematical Structure of Classical and Relativistic Physics: A General Classification Diagram; Springer: Berlin/Heidelberg, Germany, 2013. [Google Scholar] [CrossRef] [Scilit]
- Krishnaprasad, P.S. Optimal Control and Poisson Reduction; Institute for Systems Research Technical Reports: College Park, MD, USA, 1993. [Google Scholar]
- Fax, J.A.; Murray, R.M. Information flow and cooperative control of vehicle formations. IEEE Trans. Autom. Control 2004, 49, 1465–1476. [Google Scholar] [CrossRef] [Scilit]
- Jurdjevic, V. Optimal Control, Geometry, and Mechanics. In Mathematical Control Theory; Springer: New York, NY, USA, 1999; pp. 227–267. [Google Scholar] [CrossRef] [Scilit]
- Holm, D.D.; Schmah, T.; Stoica, C. Geometric Mechanics and Symmetry: From Finite to Infinite Dimensions; Oxford University Press: Oxford, UK, 2009; Volume 12. [Google Scholar]
- Zhong, G.; Marsden, J.E. Lie-poisson hamilton-jacobi theory and lie-poisson integrators. Phys. Lett. A 1988, 133, 134–139. [Google Scholar] [CrossRef] [Scilit]
- Putkaradze, V. Latent Lie-Poisson Neural Networks (LLPNNs): Discovering the motion of Lie-Poisson systems through observable data and latent dynamics. arXiv 2026, arXiv:2607.28939. [Google Scholar]
- McLachlan, R.I.; Quispel, G.R.W. Splitting methods. Acta Numer. 2002, 11, 341–434. [Google Scholar] [CrossRef] [Scilit]
- McLachlan, R.I.; Quispel, G.R.W. Geometric integrators for ODEs. J. Phys. A Math. Gen. 2006, 39, 5251. [Google Scholar] [CrossRef] [Scilit]
- Hornik, K.; Stinchcombe, M.; White, H. Universal approximation of an unknown mapping and its derivatives using multilayer feedforward networks. Neural Netw. 1990, 3, 551–560. [Google Scholar] [CrossRef] [Scilit]
- Yarotsky, D. Error bounds for approximations with deep ReLU networks. Neural Netw. 2017, 94, 103–114. [Google Scholar] [CrossRef] [Scilit]
- Leonard, N.E. Stability of a bottom-heavy underwater vehicle. Automatica 1997, 33, 331–346. [Google Scholar] [CrossRef] [Scilit]
- Leonard, N.E.; Marsden, J.E. Stability and drift of underwater vehicle dynamics: Mechanical systems with rigid motion symmetry. Phys. D Nonlinear Phenom. 1997, 105, 130–162. [Google Scholar] [CrossRef] [Scilit]
- Holmes, P.; Jenkins, J.; Leonard, N.E. Dynamics of the Kirchhoff equations I: Coincident centers of gravity and buoyancy. Phys. D Nonlinear Phenom. 1998, 118, 311–342. [Google Scholar] [CrossRef] [Scilit]
- Bloch, A.M.; Colombo, L.J.; Gupta, R.; Ohsawa, T. Optimal control problems with symmetry breaking cost functions. SIAM J. Appl. Algebra Geom. 2017, 1, 626–646. [Google Scholar] [CrossRef] [Scilit]
- Peng, L.; Mohseni, K. Symplectic model reduction of Hamiltonian systems. SIAM J. Sci. Comput. 2016, 38, A1–A27. [Google Scholar] [CrossRef] [Scilit]
- Rozza, G.; Stabile, G.; Ballarin, F. Advanced Reduced Order Methods and Applications in Computational Fluid Dynamics; SIAM: Bangkok, Thailand, 2022. [Google Scholar]
- Gruber, A.; Tezaur, I. Variationally consistent Hamiltonian model reduction. SIAM J. Appl. Dyn. Syst. 2025, 24, 376–414. [Google Scholar] [CrossRef] [Scilit]
- Gamkrelidze, R. Principles of Optimal Control Theory; Springer Science & Business Media: Berlin/Heidelberg, Germany, 2013; Volume 7. [Google Scholar]
- Boltyanskii, V.; Gamkreligze, R.; Pontryagin, L. The Theory of Optimal Processes. I The Maximum Principle. Twenty Pap. Anal. Funct. Ordinary Differ. Equ. 1961, 18, 341. [Google Scholar] [CrossRef] [Scilit]
- Krishnaprasad, P. Eulerian many-body problems. Contemp. Math. 1989, 97, 187–208. [Google Scholar] [CrossRef] [Scilit][Green Version]
- Marsden, J.E.; Ratiu, T.S. Reduction of Poisson manifolds. Lett. Math. Phys. 1986, 11, 161–169. [Google Scholar] [CrossRef] [Scilit]
- Grossman, R.; Krishnaprasad, P.S.; Marsden, J.E. The dynamics of two coupled rigid bodies. In Dynamical Systems Approaches to Nonlinear Problems in Systems and Circuits; Society for Industrial & Applied Mathematics: Philadelphia, PA, USA, 1998; pp. 373–378. [Google Scholar]
- Krantz, S.G.; Parks, H.R. The Implicit Function Theorem: History, Theory, and Applications; Springer Science & Business Media: Berlin/Heidelberg, Germany, 2002. [Google Scholar]
- Jurdjevic, V. Geometric Control Theory; Cambridge University Press: Cambridge, UK, 1997. [Google Scholar]
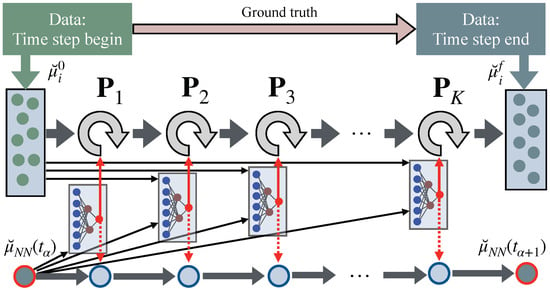
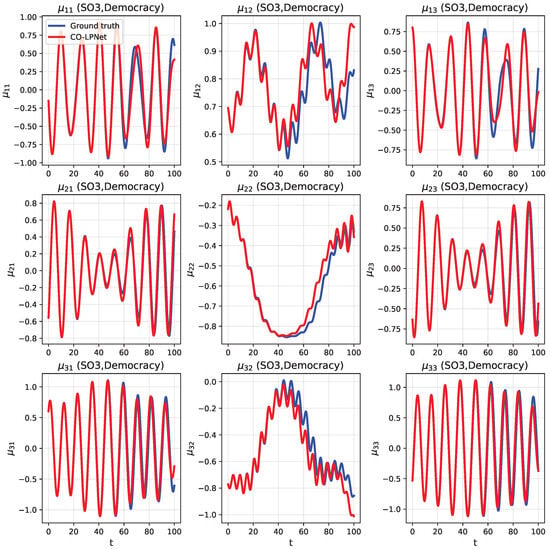
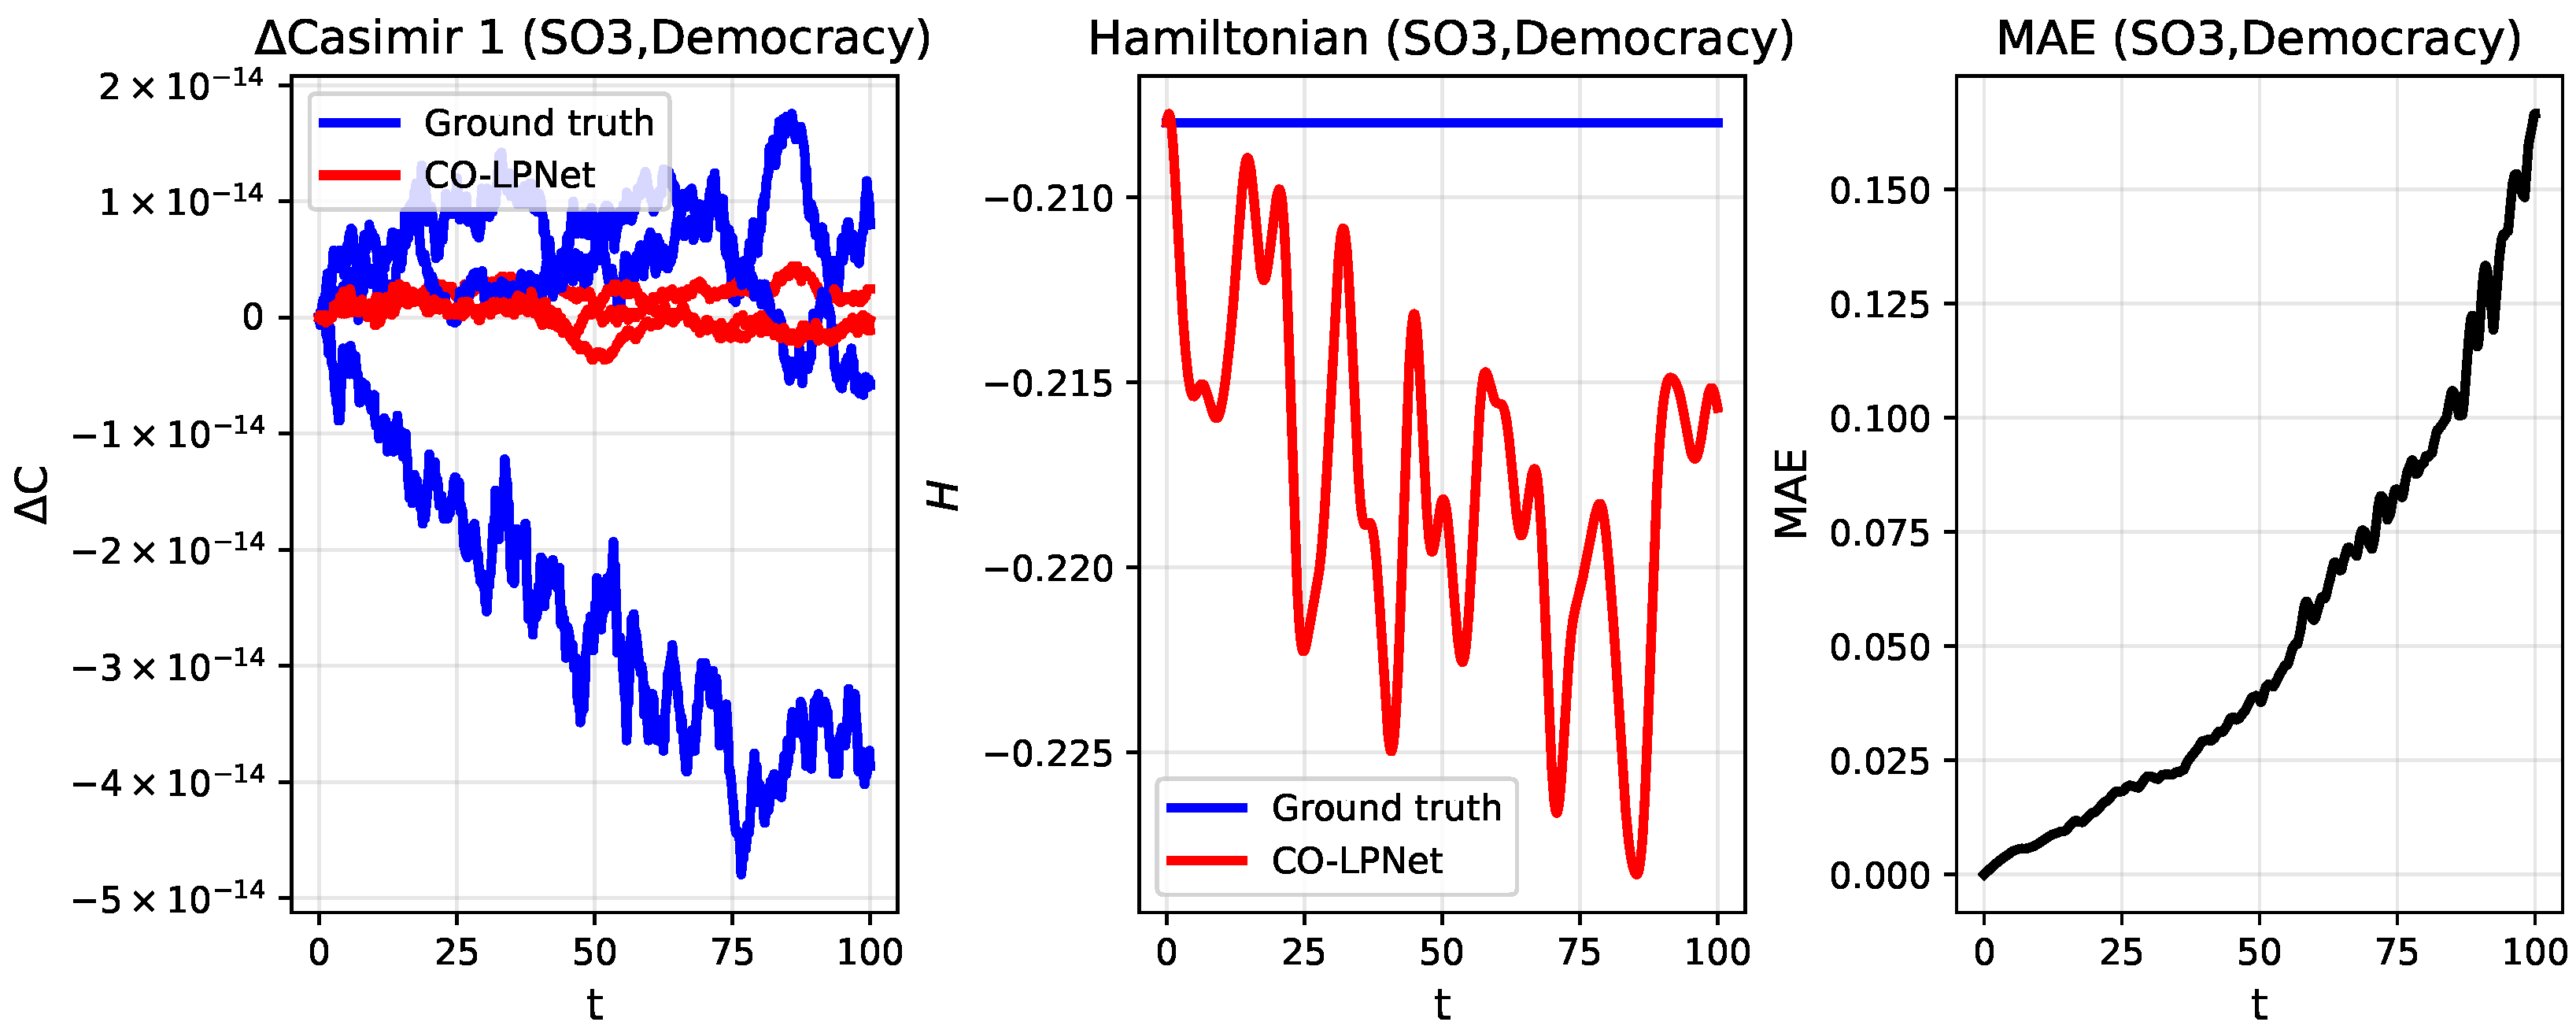
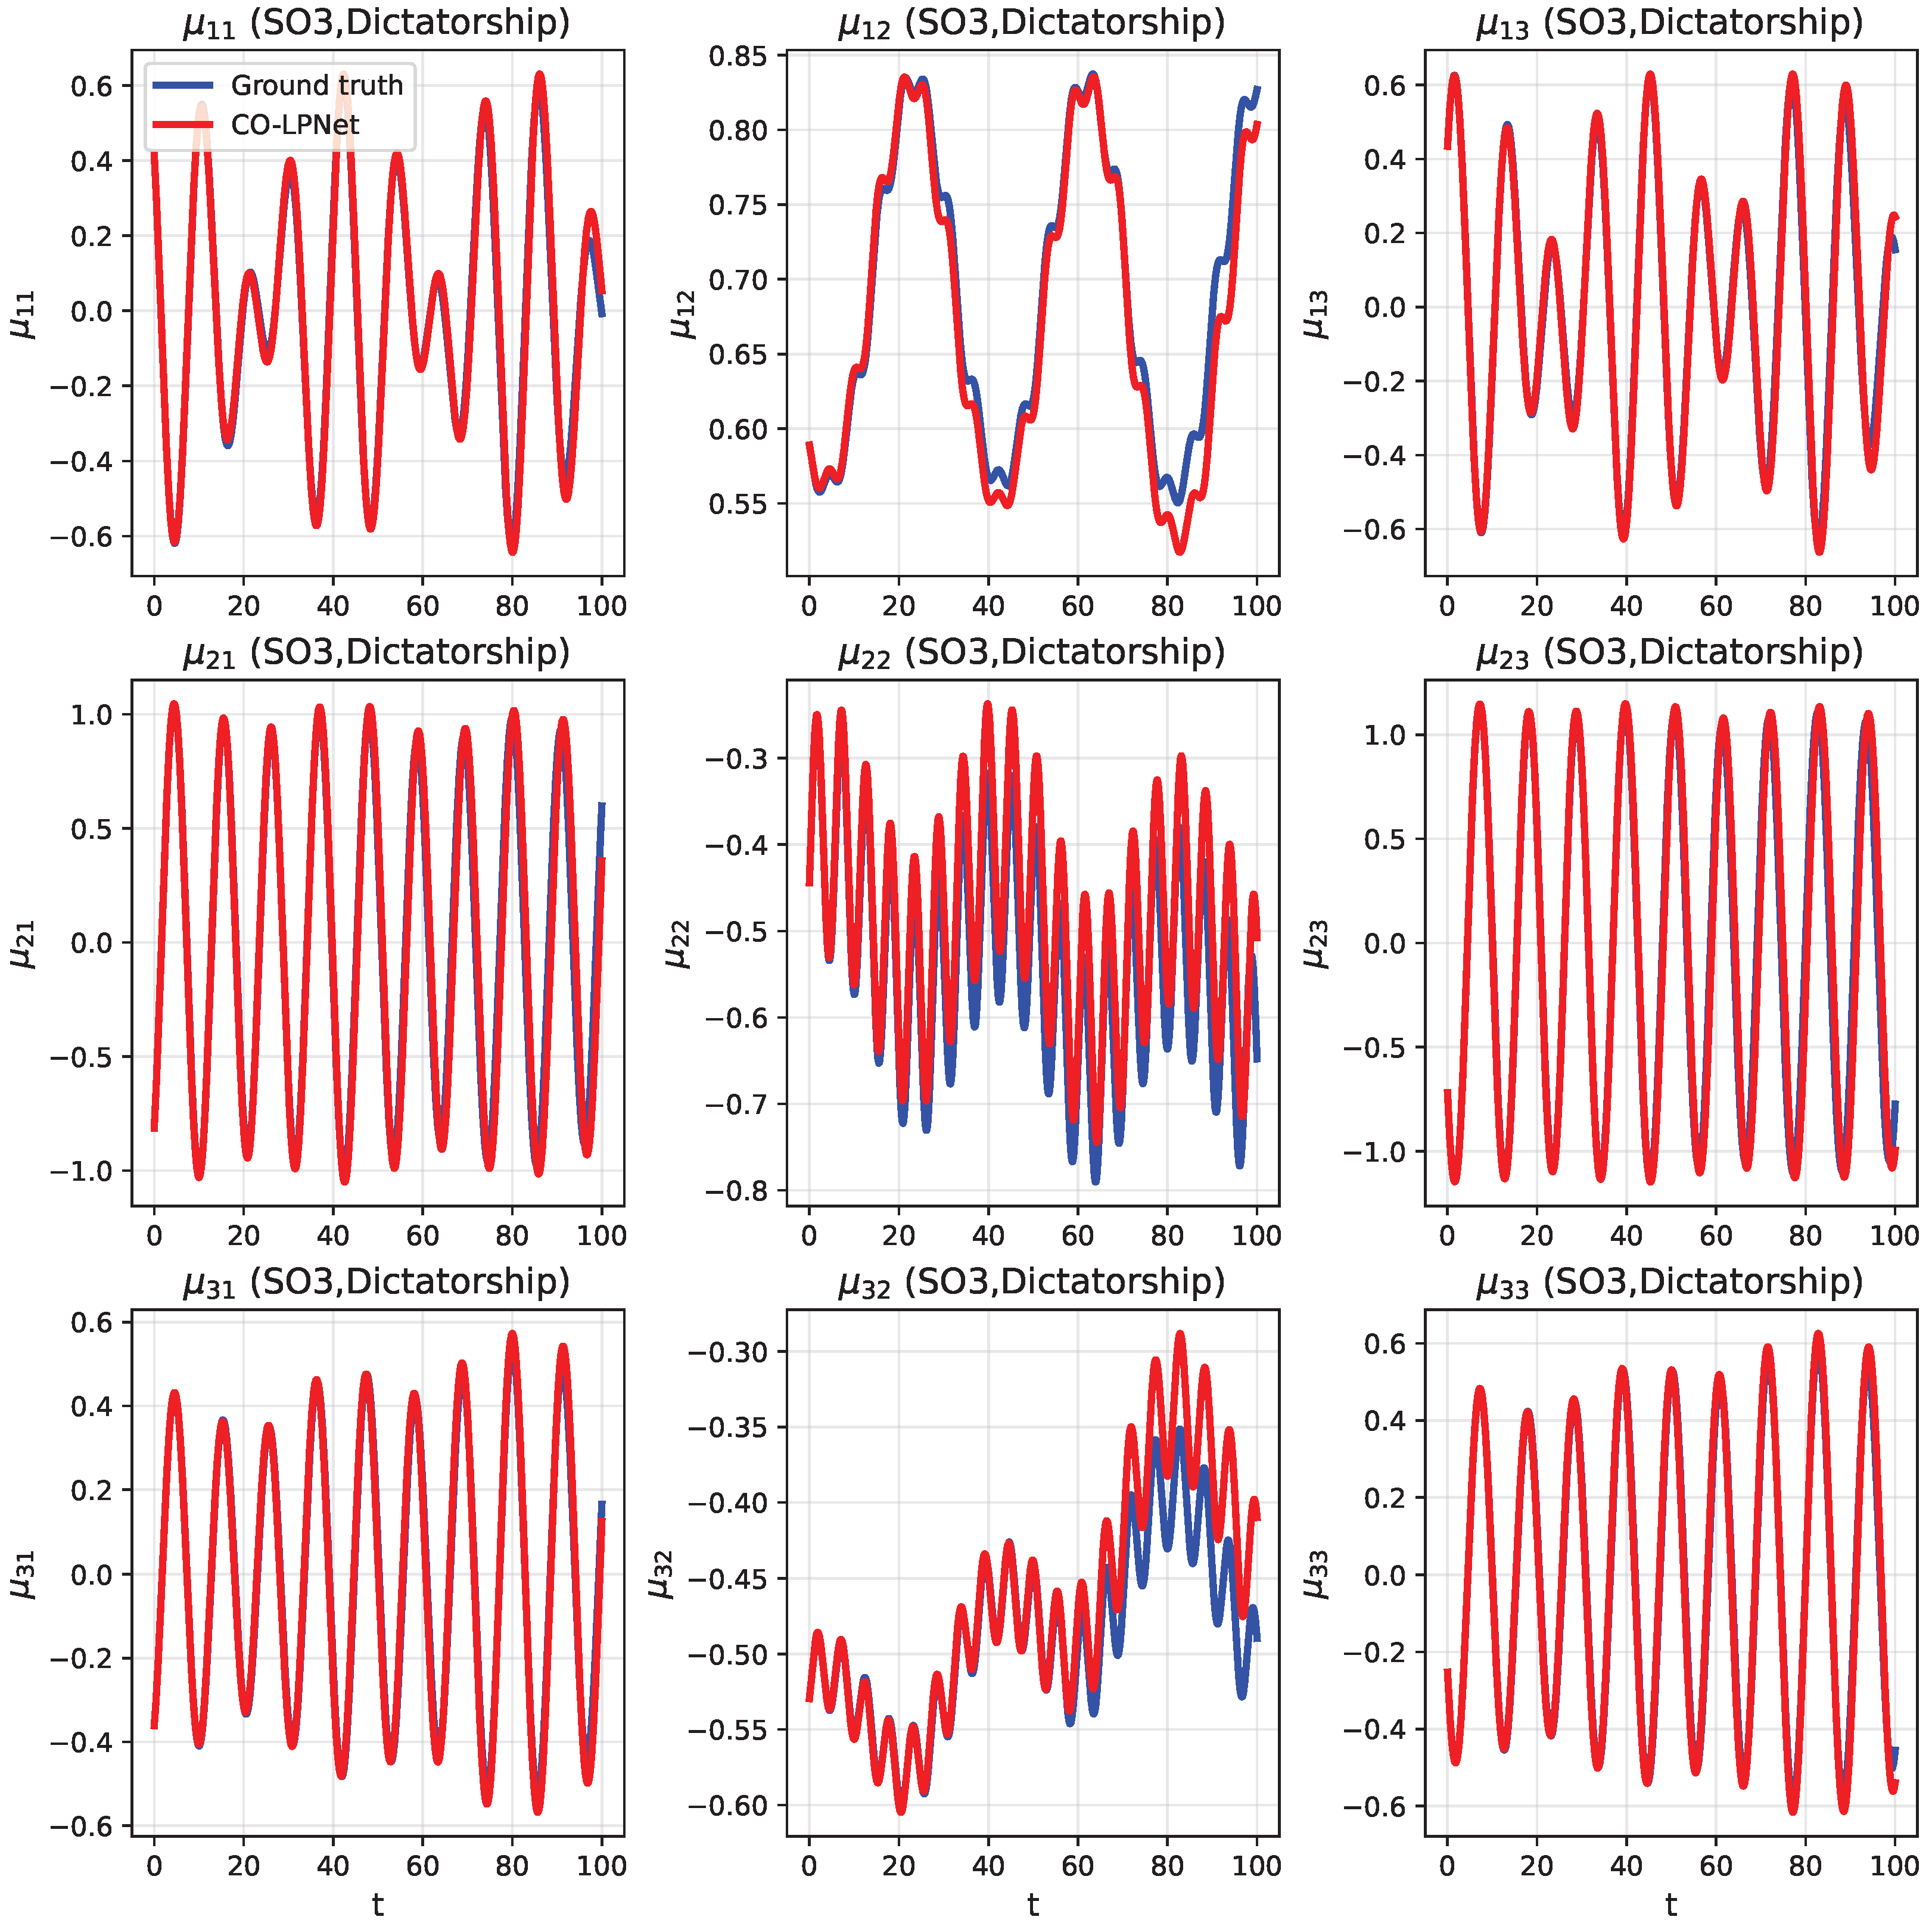
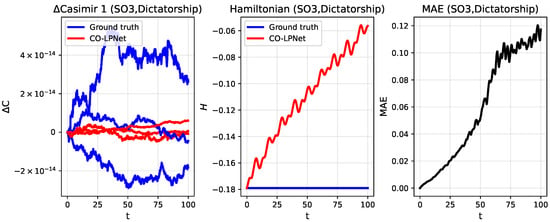
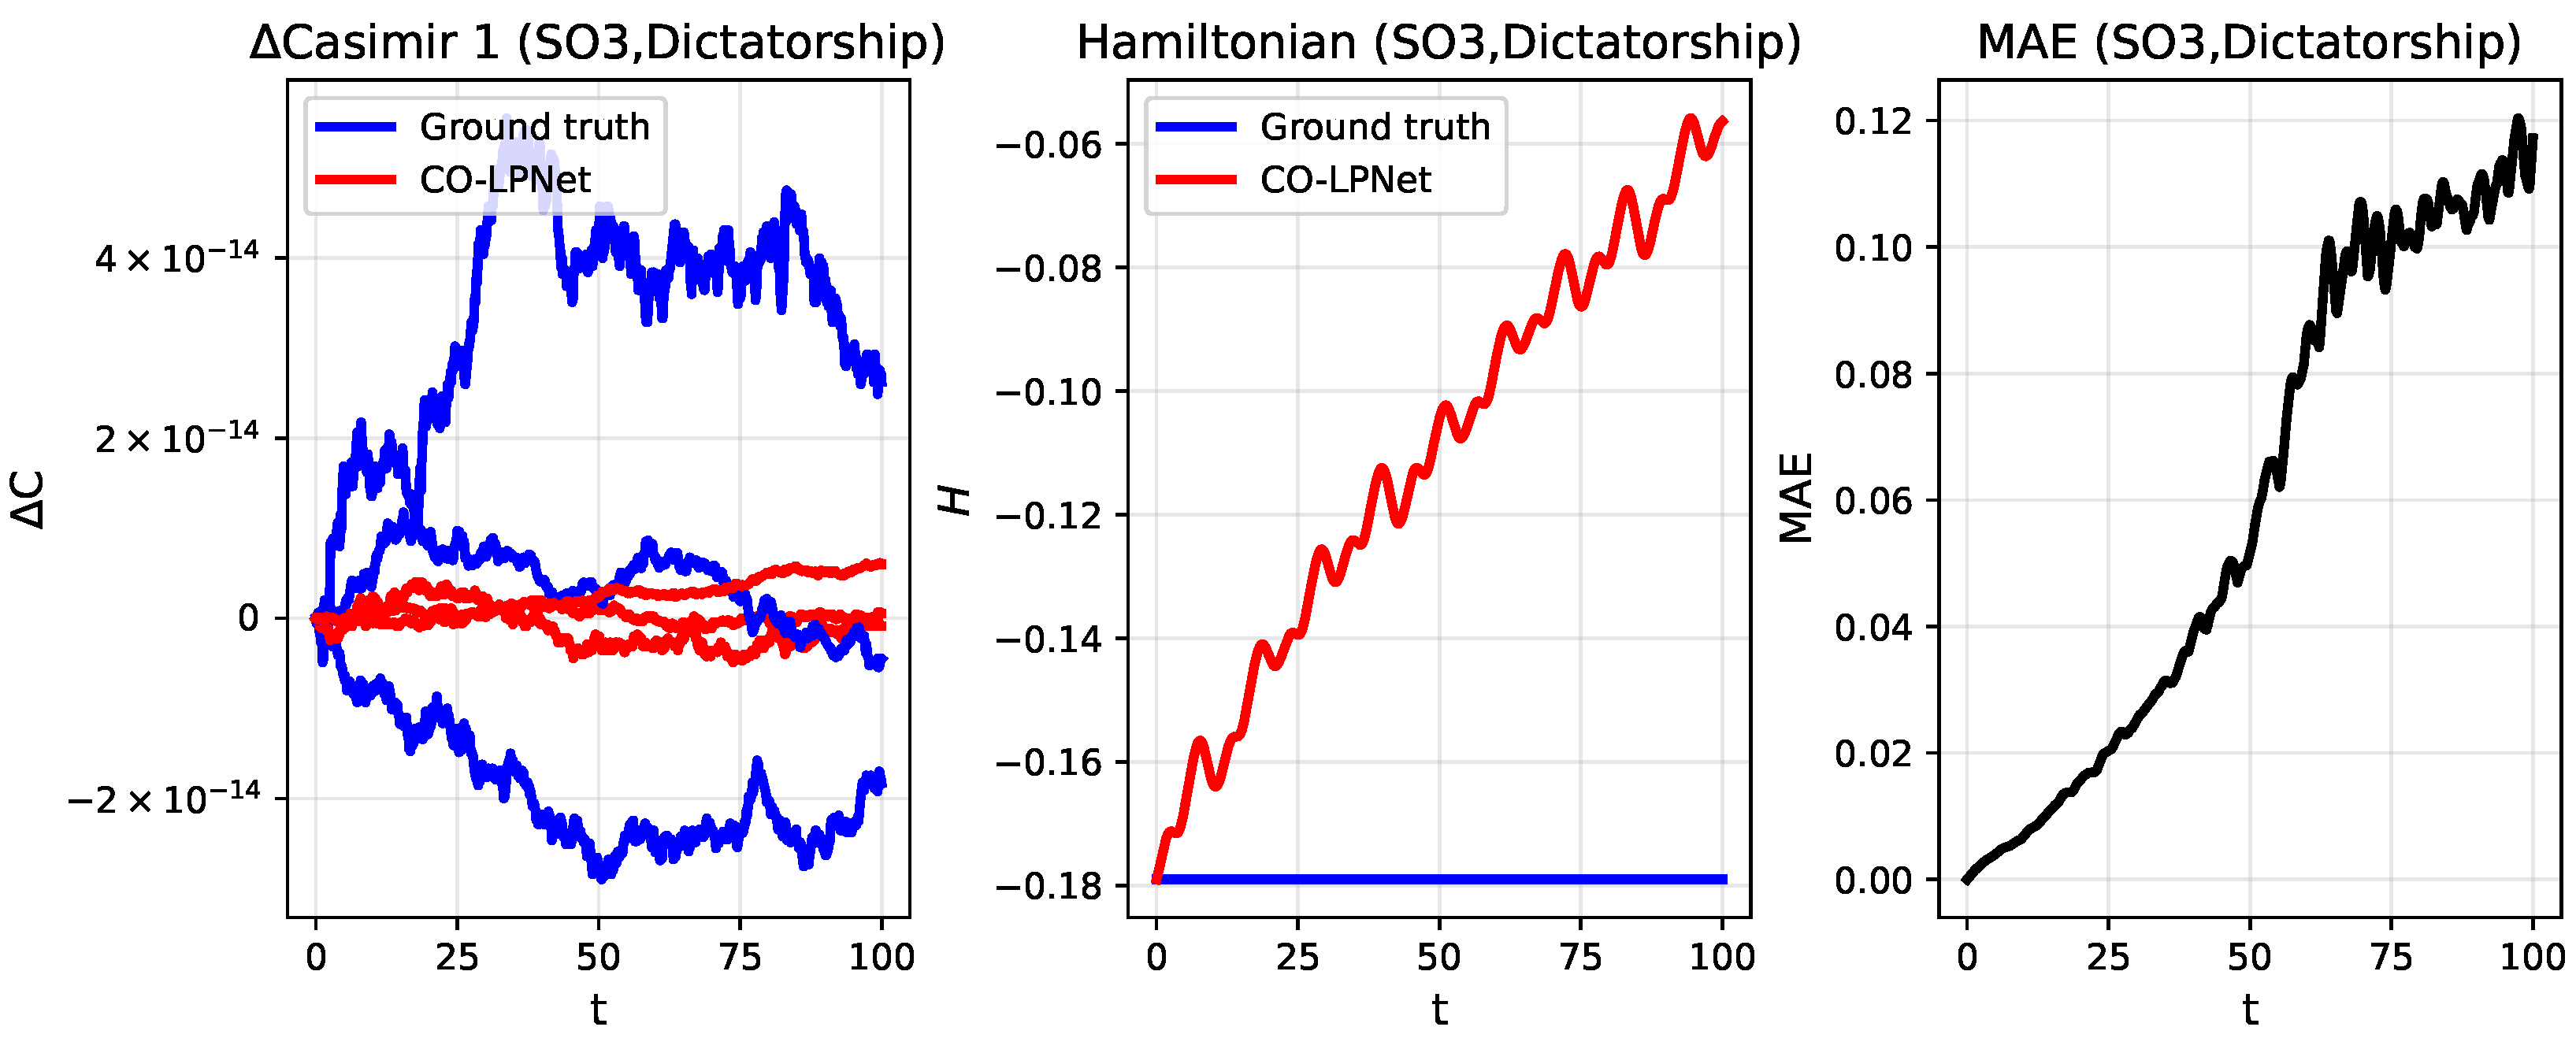
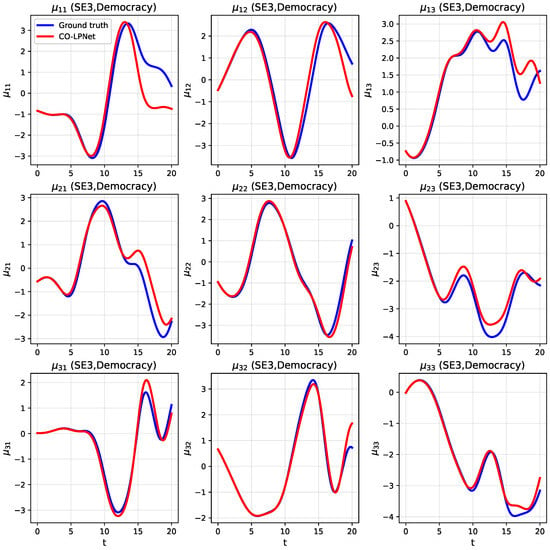
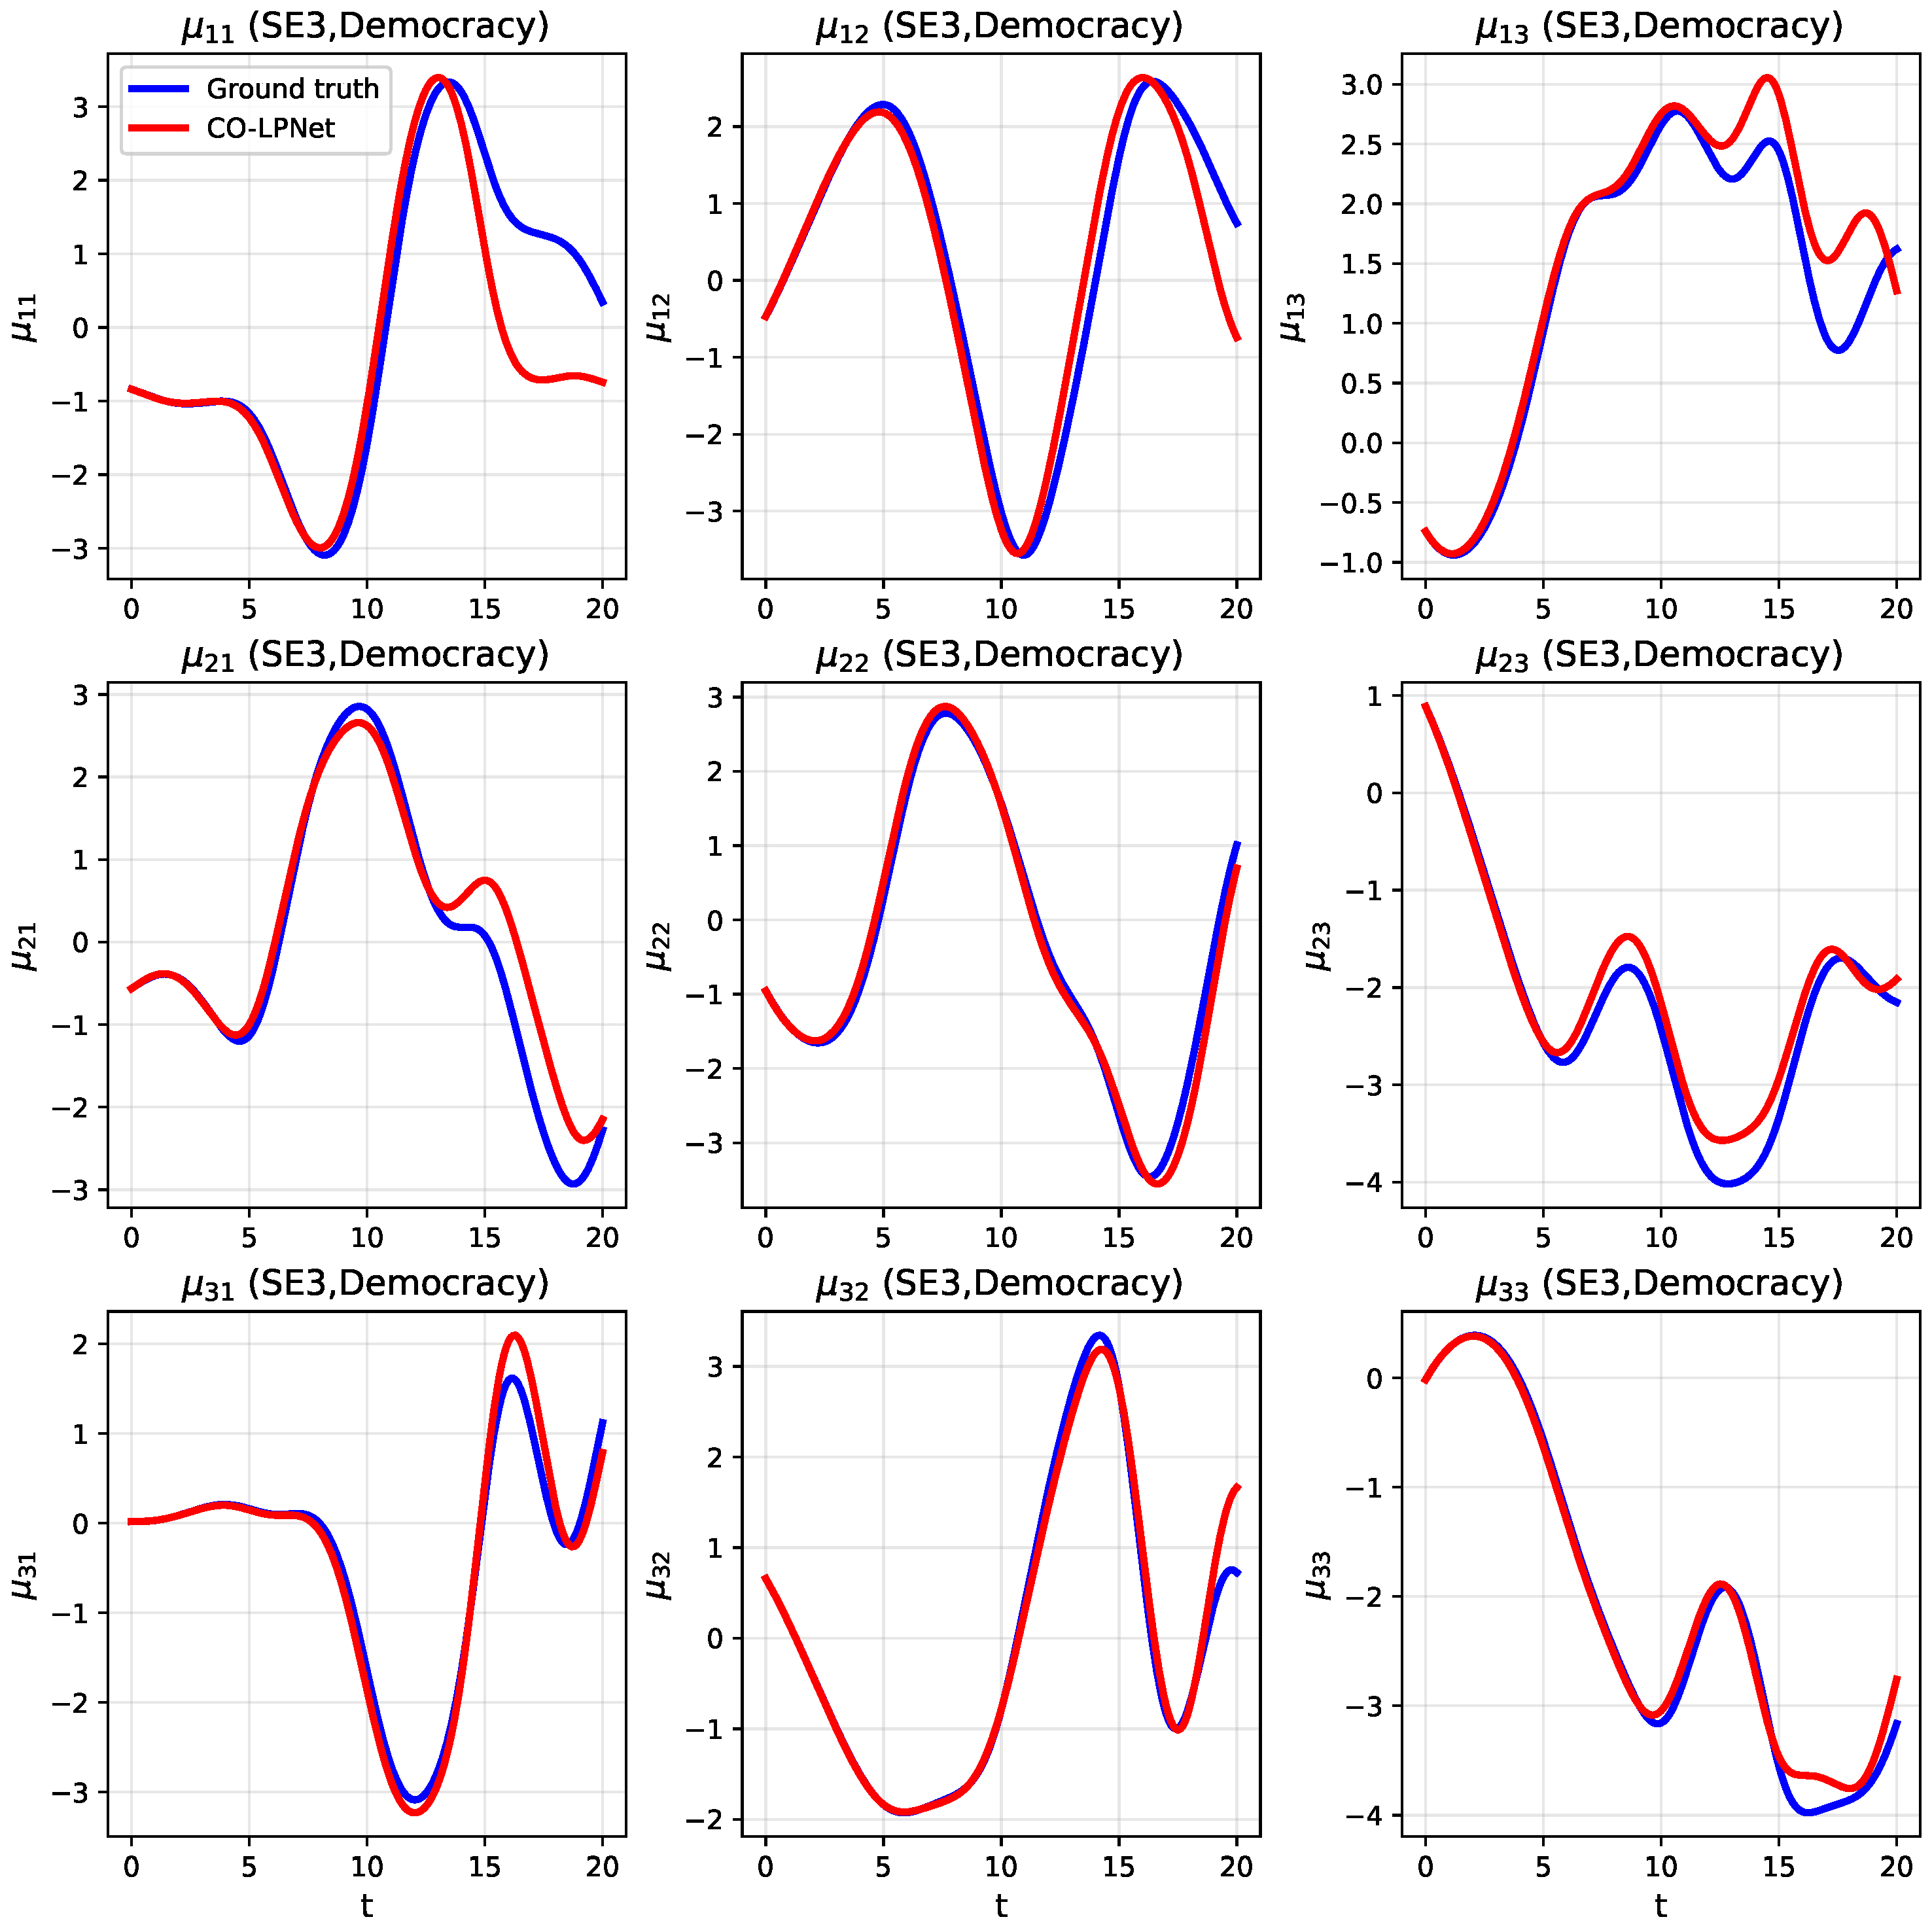
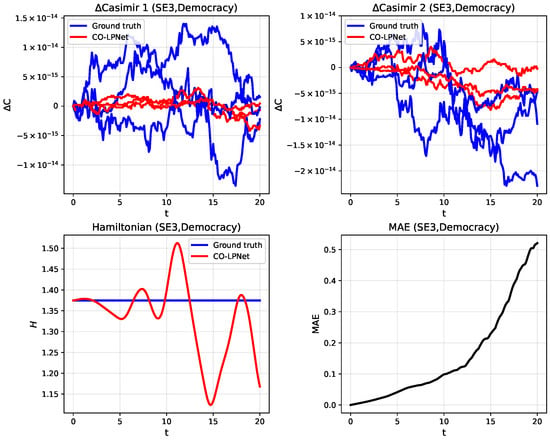
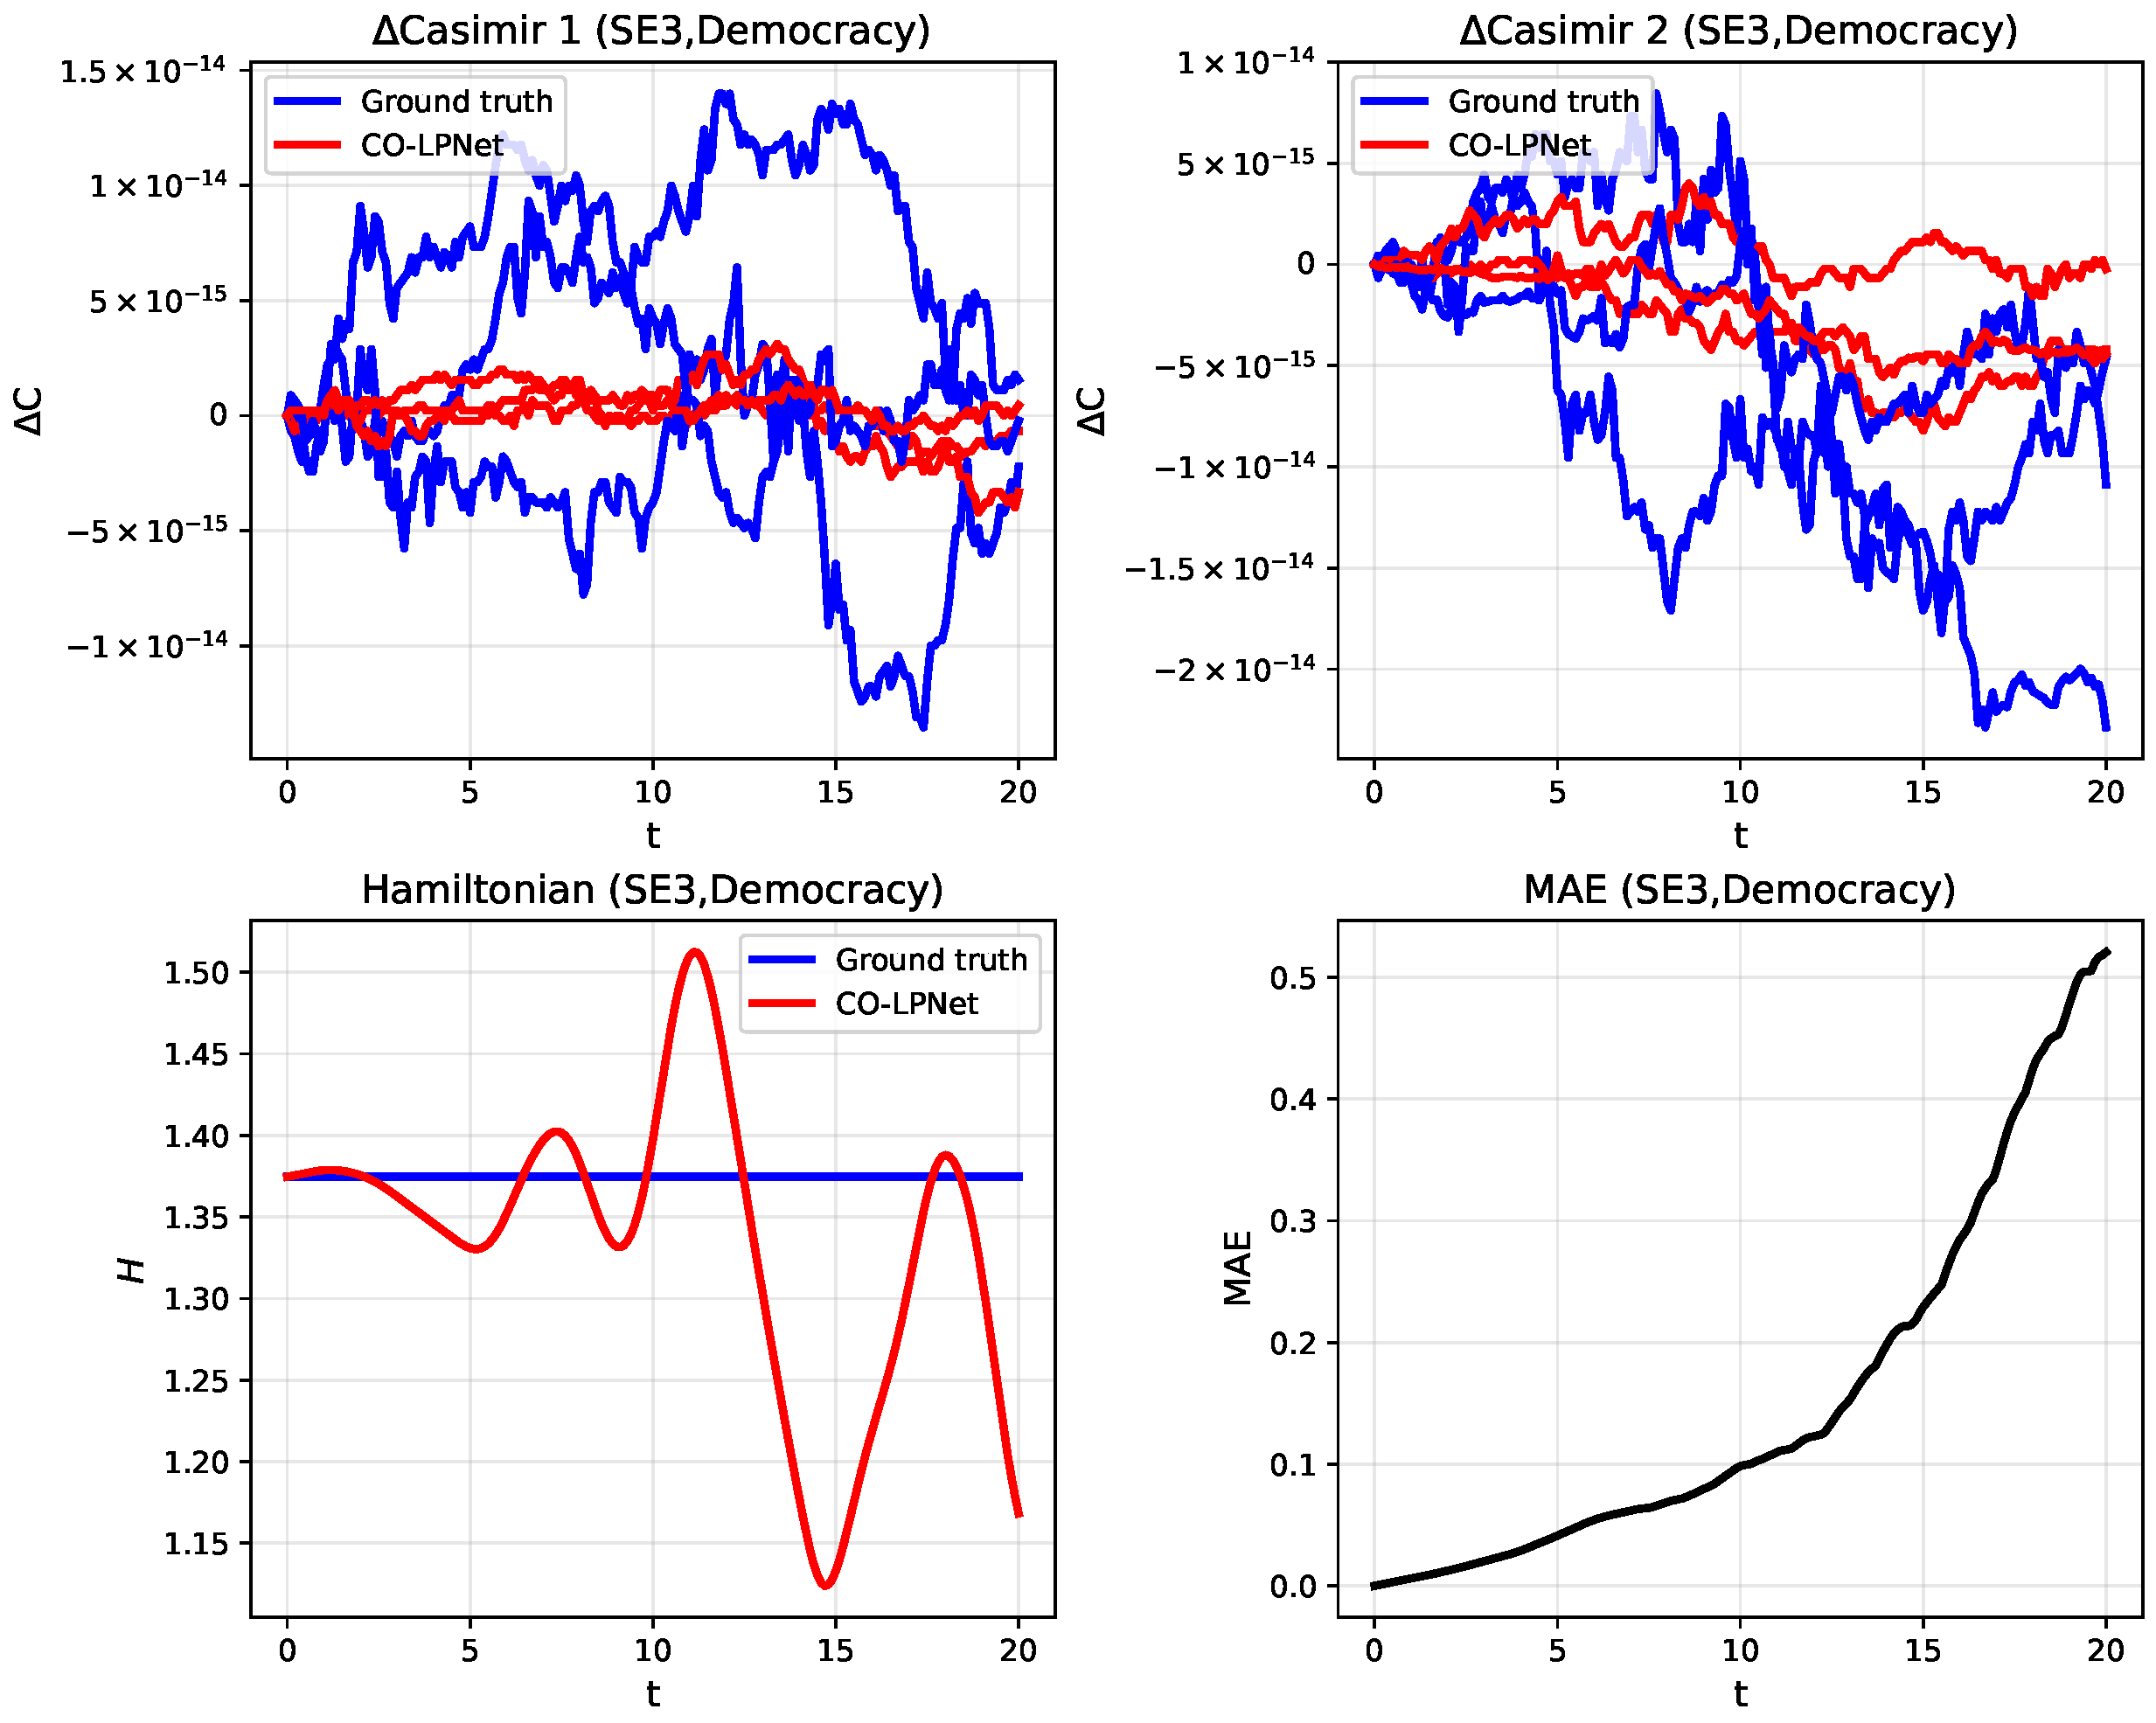
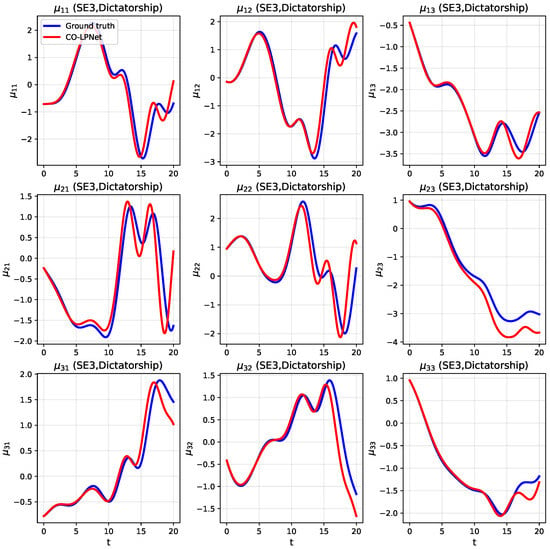
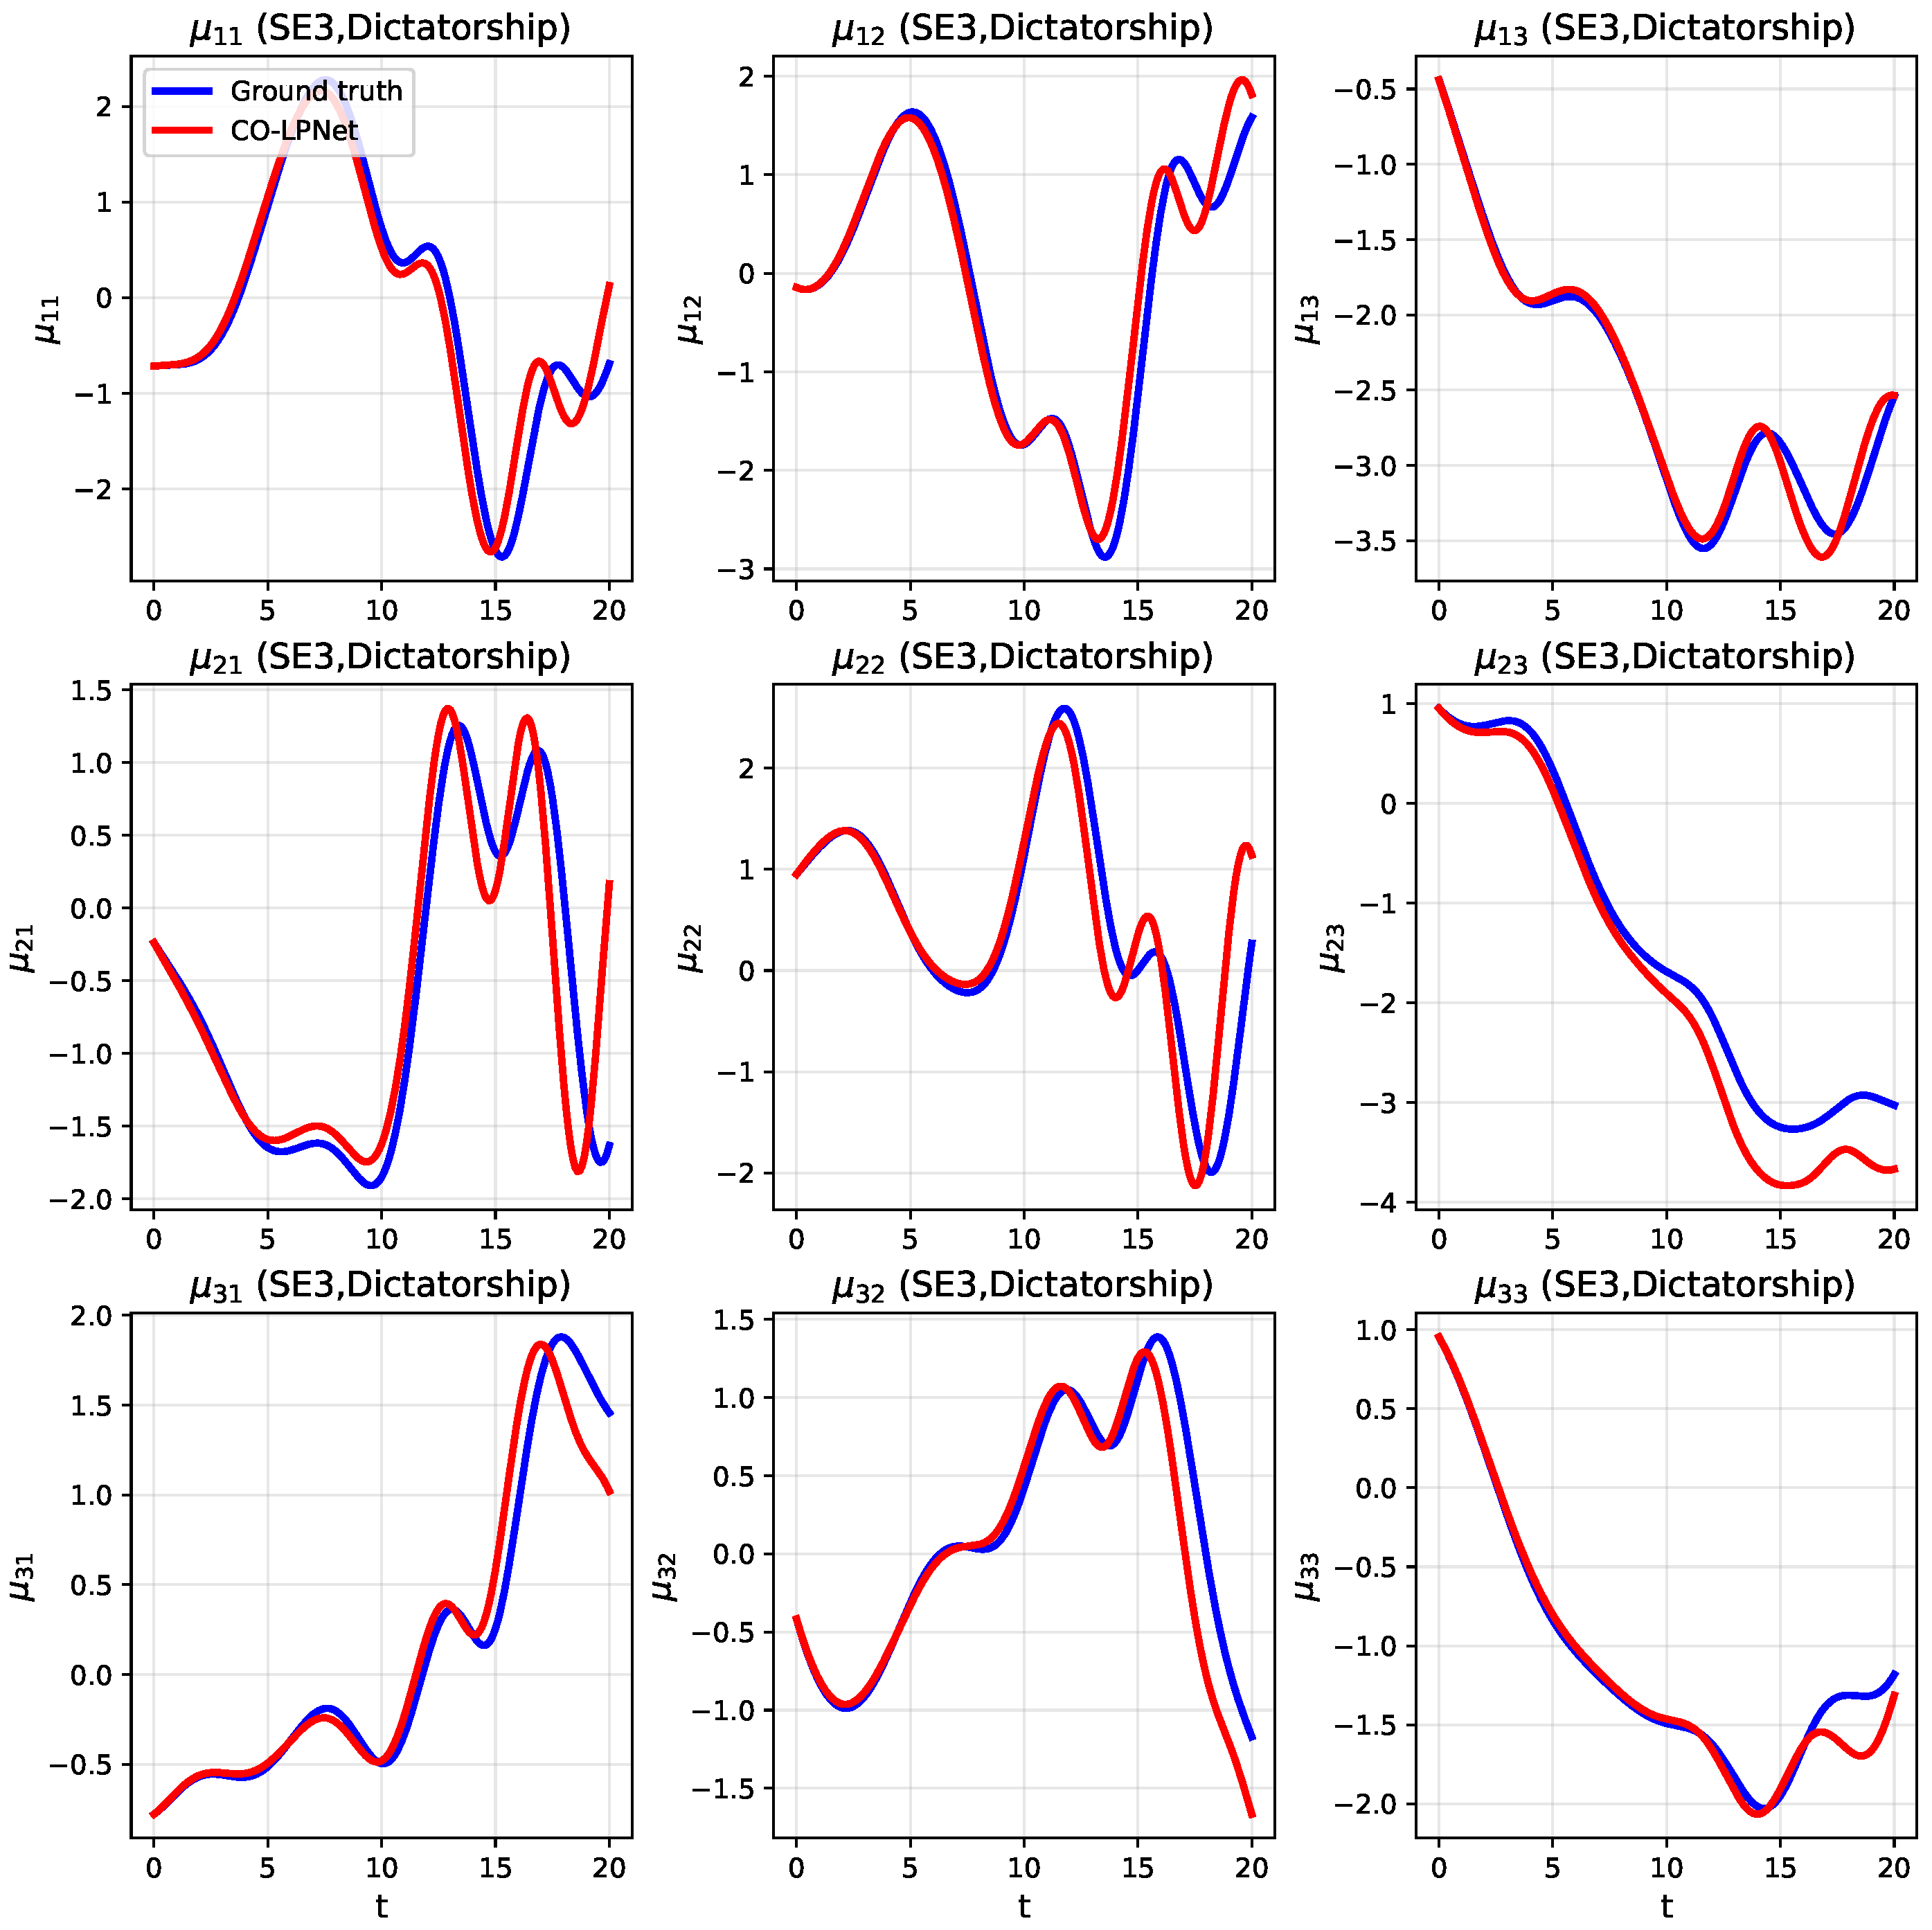
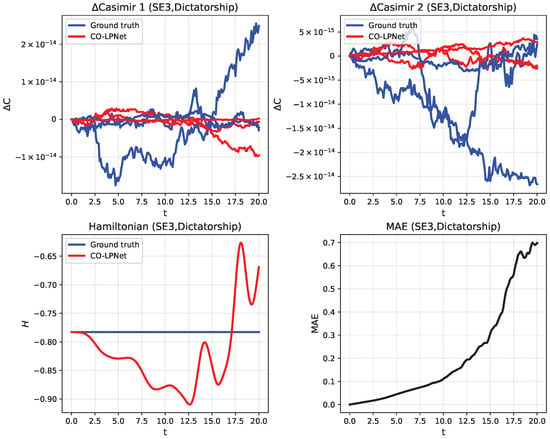
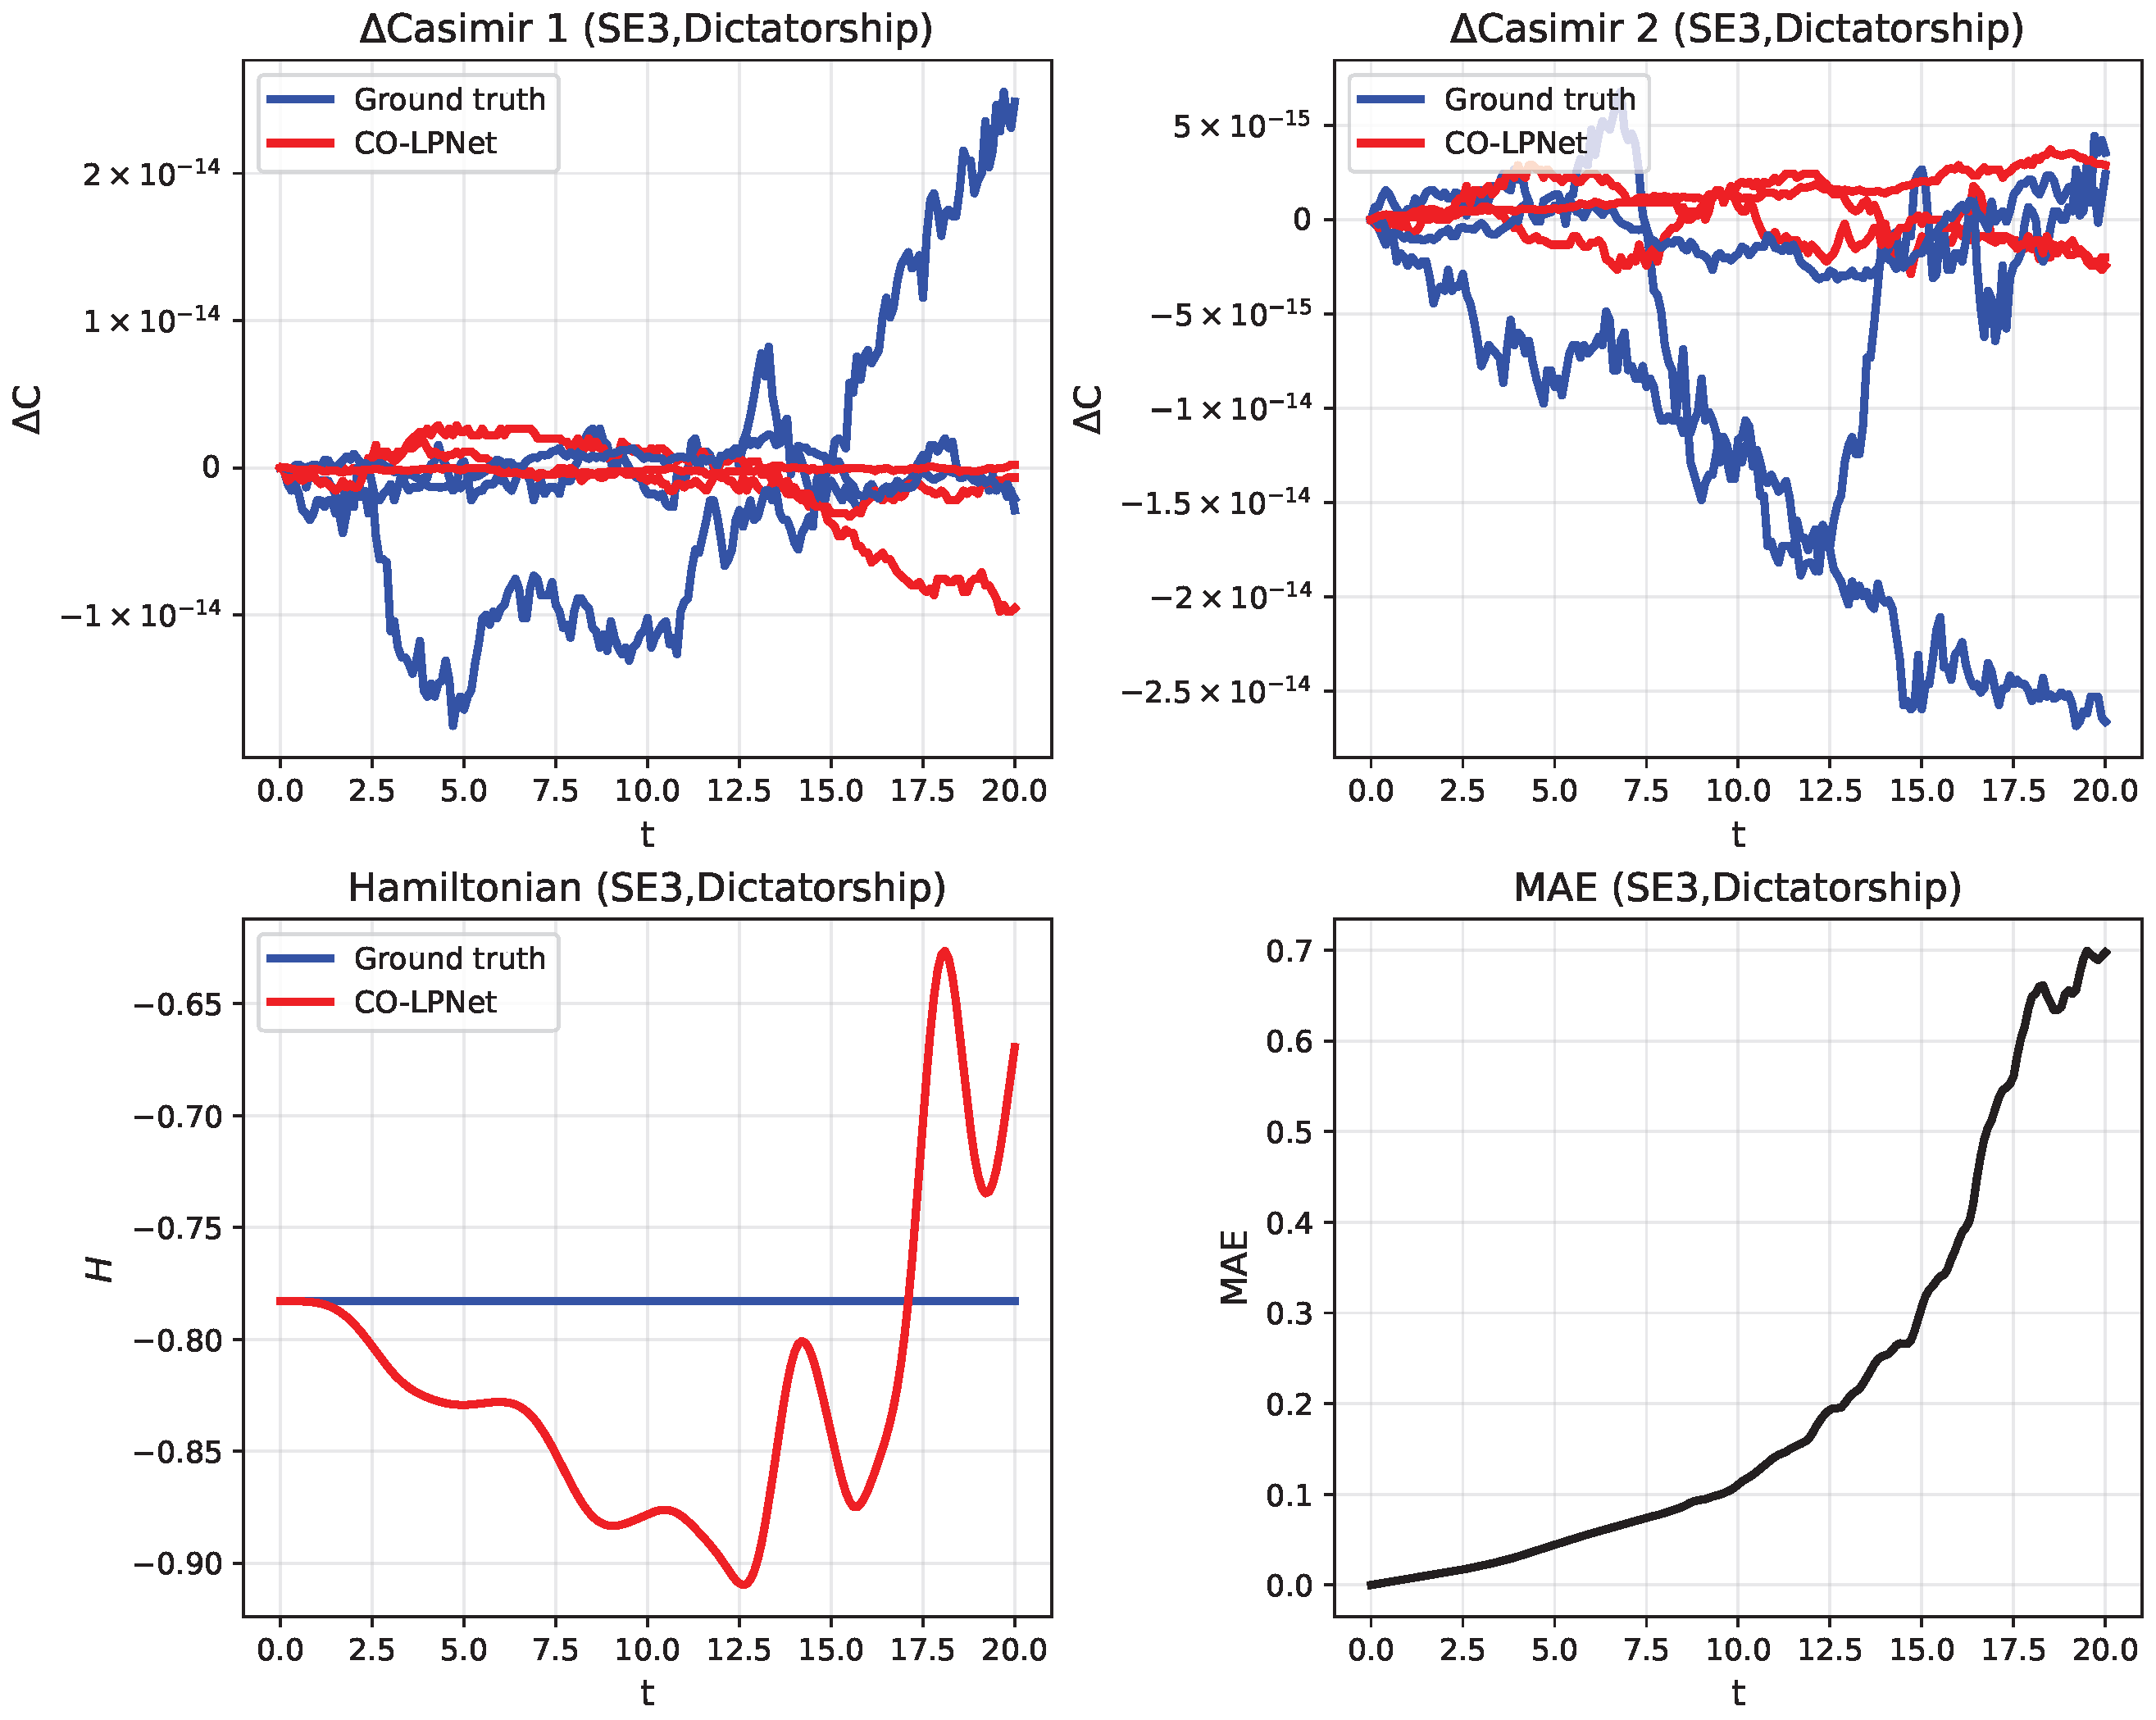
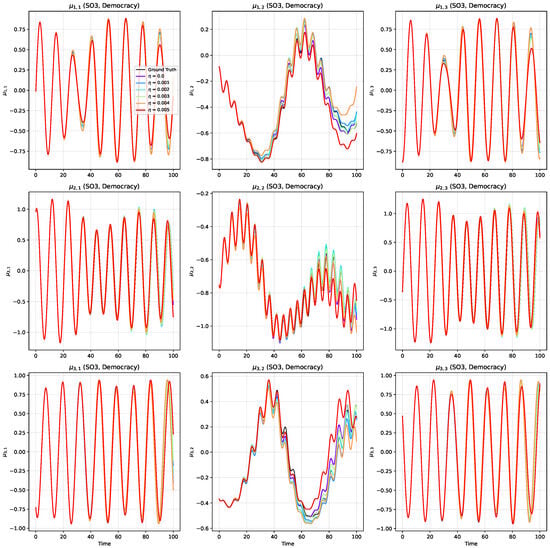
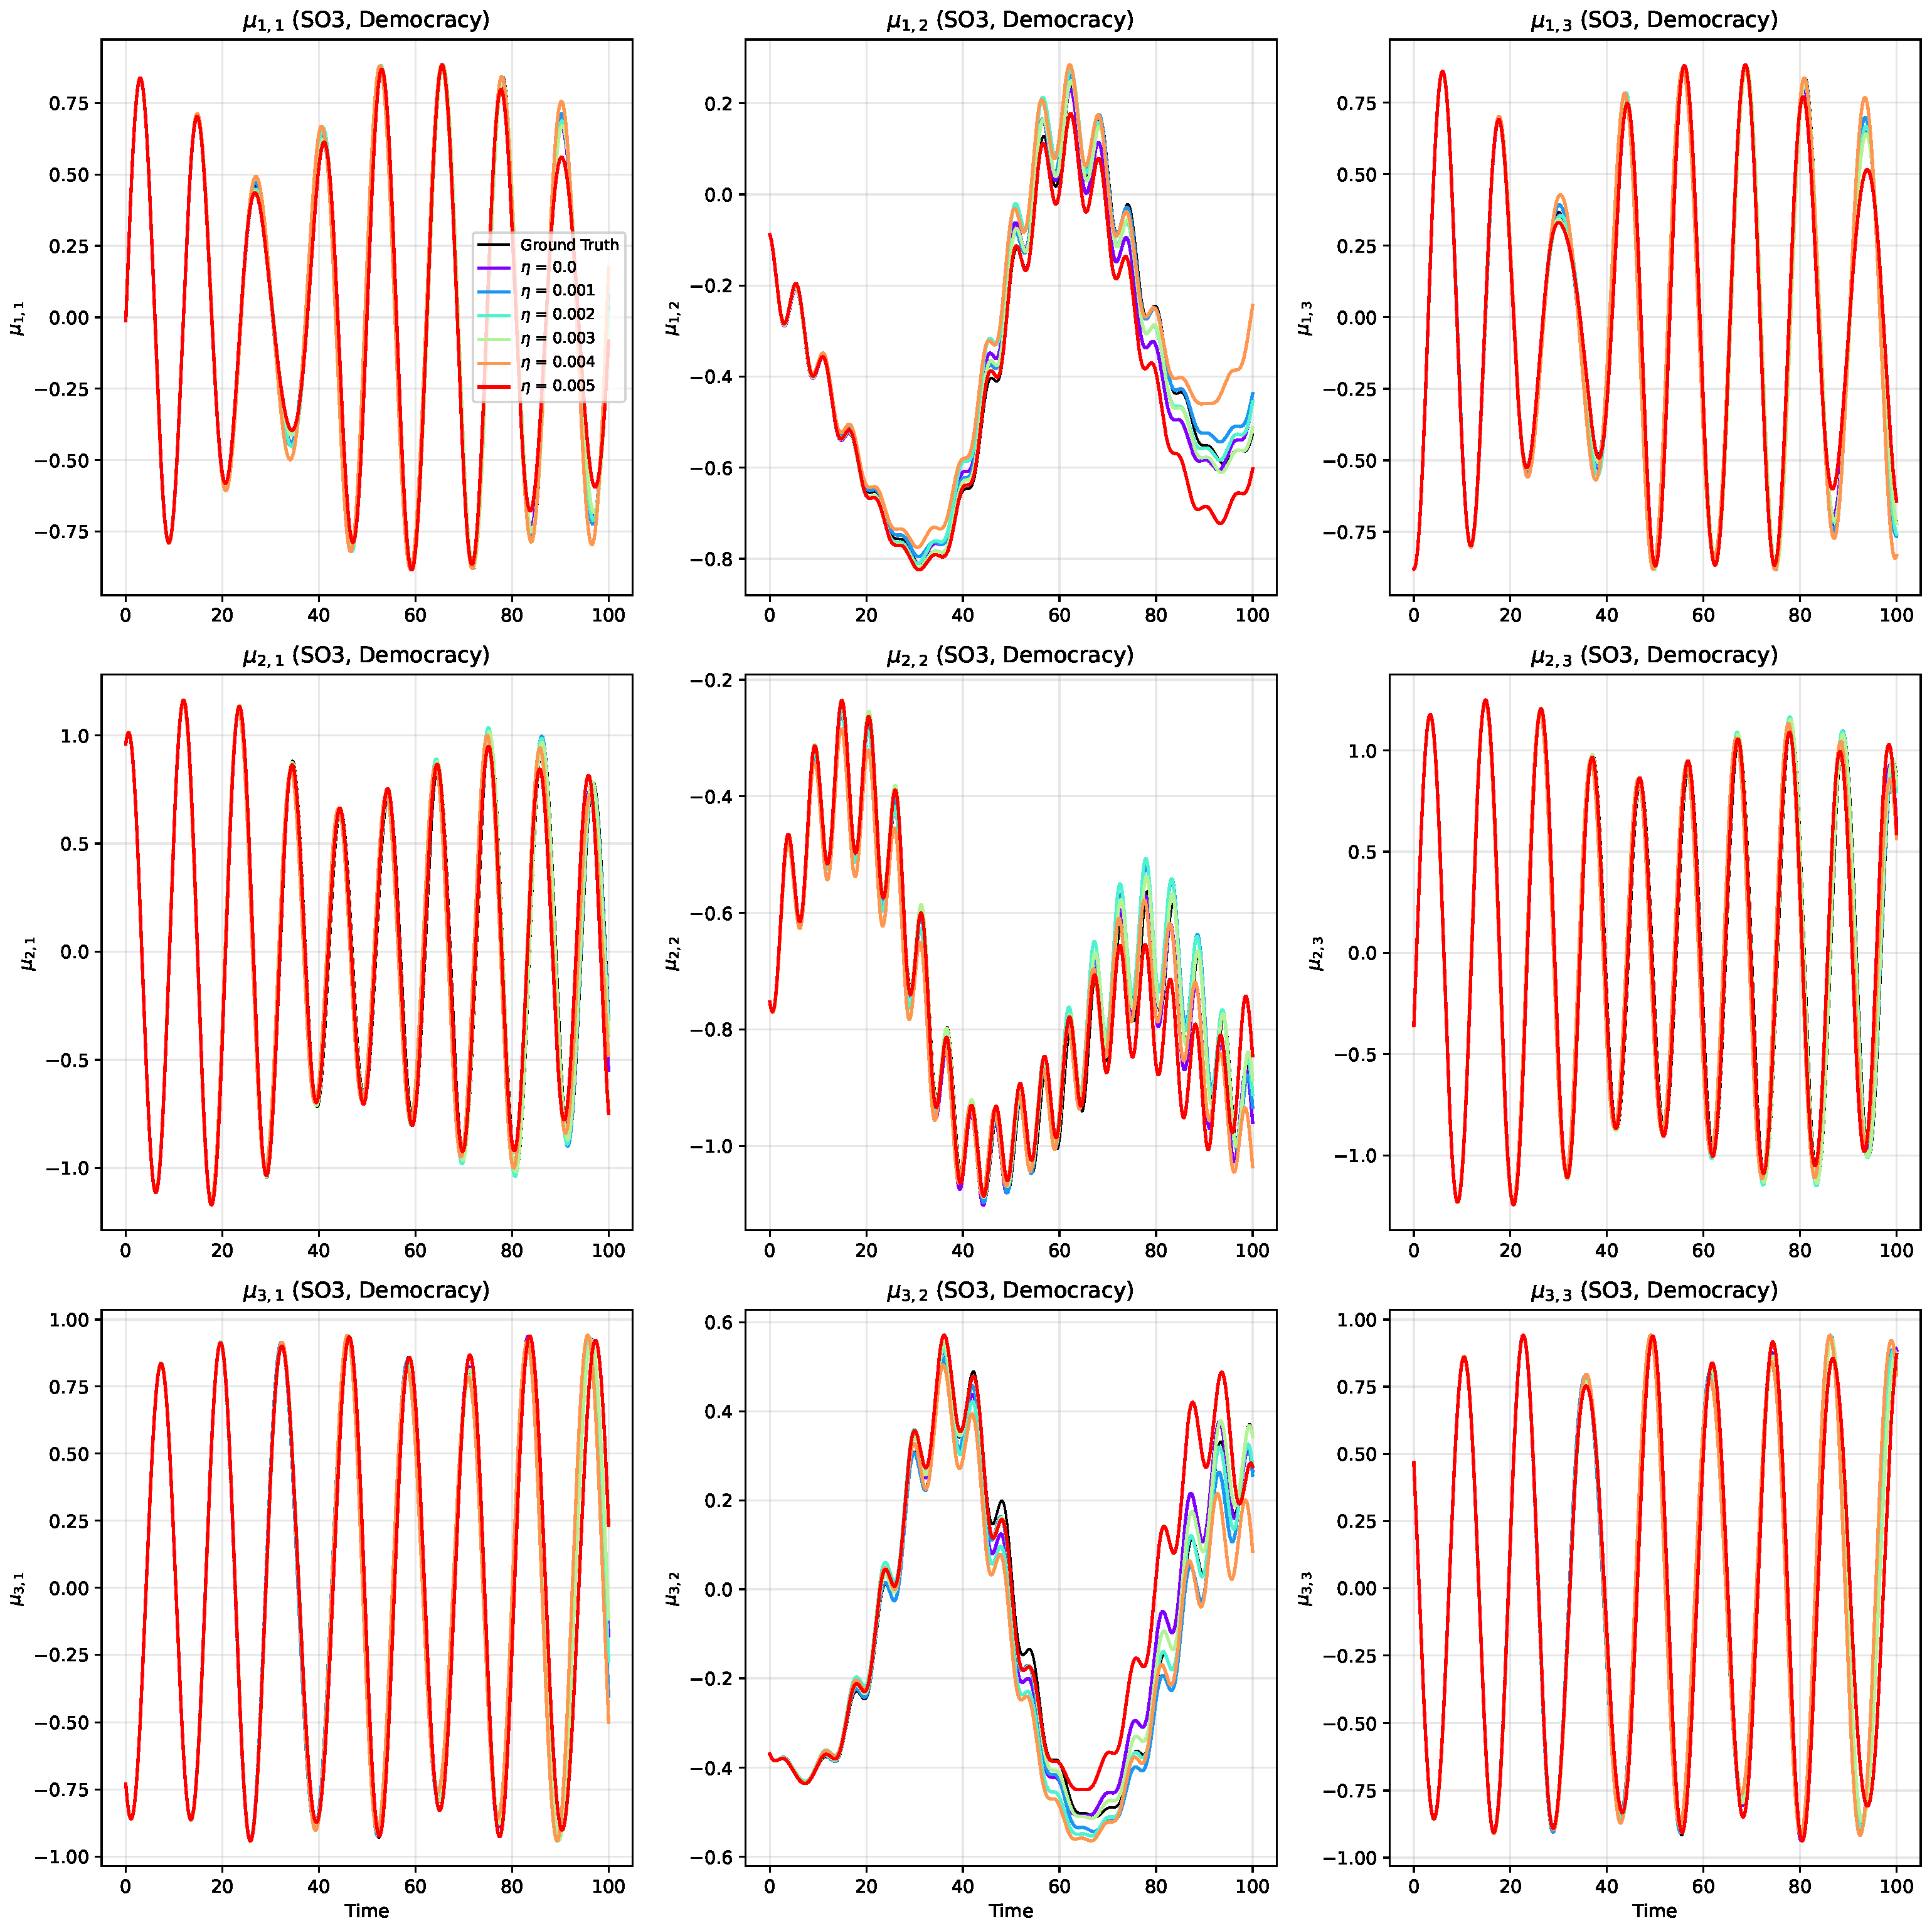
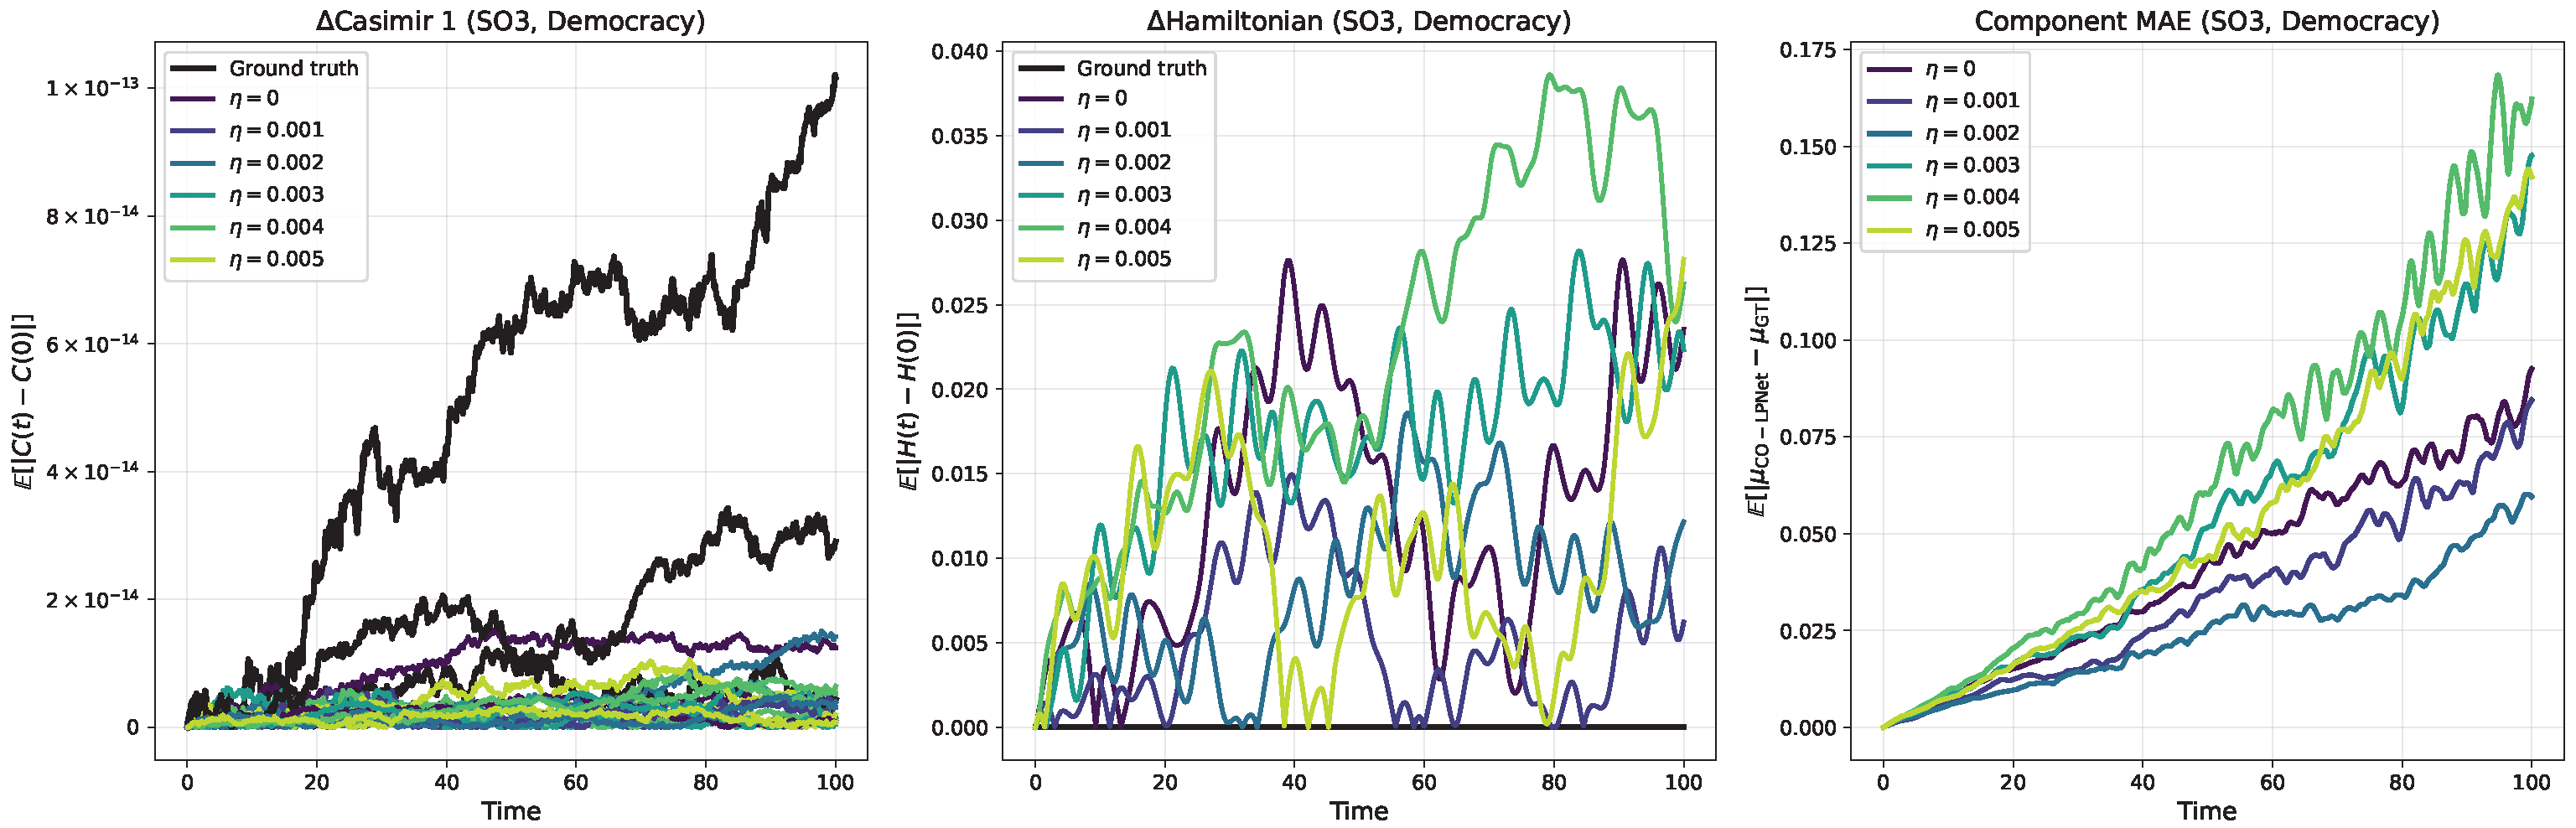

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.