


Abstract
In this article, we introduce a new model with positive support. This model is an extension of the truncated Gumbel distribution, where a shape parameter is incorporated that provides greater flexibility to the new model. The model is parameterized in terms of the p-th quantile of the distribution to perform quantile regression in this model. An extensive simulation study demonstrates the good performance of the maximum likelihood estimators in finite samples. Finally, two applications to real datasets related to the level of beta-carotene and body mass index are presented.
Keywords:
Gumbel distribution; maximum likelihood estimators; quantile regression; truncated distribution MSC:
62E10; 62E15; 62E17
1. Introduction
The Gumbel distribution, also known as the type-I generalized extreme value distribution, is commonly used to model data with extreme observations. This distribution and its extensions have a wide range of applications in several disciplines such as hydrology, economics, finance, climatology and seismology. The probability density function (pdf), the cumulative distribution function (cdf) and the quantile function of a random variable X that follows the Gumbel distribution are given by
where and . Applications of this model in different scenarios can be found in Bhaskaran et al. [1], Gurung et al. [2], Purohit et al. [3], Li et al. [4] and Kang et al. [5].
Several extensions of the Gumbel distribution have been recently proposed in the literature. Hossam et al. [6] presented a statistical model that combines the new alpha power transformation method and Gumbel distribution. Watthanawisut and Bodhisuwan [7] proposed a new extension of the so called Topp-Leone Gumbel distribution that is used to model minimum flow data. Fayomi et al. [8] presented the exponentiated Gumbel-G family of distributions and explored a special case called EGuNH. Nagode et al. [9] introduced a three-parameter Gumbel distribution, which was applied to rope failure data. Oseni and Okasha [10] derived the Gumbel-geometric distribution, which was applied to precipitation and maximum annual wind speed data. Note that all these extensions do not consider a regression framework, and their main objectives rely on the fit of univariate data.
It is evident that regression models have become relevant tools in the era of Data Science. Among them, the so-called quantile regression models (introduced by Koenker and Bassett [11]) are an alternative to the usual regression techniques where the mean response conditional to values of covariates (or explanatory variables) is estimated. The quantile regression models allow us to measure the effects of covariates at different quantiles of the response variable distribution. Thus, they provide an analysis across the entire conditional distribution, as can be seen in Cade et al. [12], Koenker [13] and Wei et al. [14]. The mean, as the only summary measure, is generally quite poor for assessing risk, as it is greatly affected by the presence of outlier observations. Outlier data can be quite strange, but at the same time, these can be enough to cause serious problems when analyzing the information obtained; see, for example, Gómez-Déniz et al. [15], who analyzed extreme values in insurance companies. To our knowledge, there are no studies on quantile regression models based on the Gumbel distribution. Thus, the objectives of this work were to introduce a new generalization of the truncated Gumbel distribution and then establish a quantile regression model based on this novel generalization. To do this, a reparametrization was obtained of the new truncated Gumbel generalization by incorporating a parameter that represents the quantile. We should note that the proposed generalization was achieved by considering the work of Neamah and Qasim [16] and the transformation provided by Cooray and Ananda [17]. The latter authors developed an extension of the half-normal (HN) distribution through the relation , where .
The rest of the paper is organized as follows. In Section 2, we introduce our proposal, the generalized truncated Gumbel (GTG) distribution, and several important properties of this new model are presented. In Section 3, inference is performed, including some initial points to obtain maximum likelihood (ML) estimators and present the observed Fisher information matrix for the proposed model. In Section 4, the reparametrized model in terms of a quantile is presented. In Section 5, the simulation study carried out to analyze the performances of the ML estimators in finite samples for the proposed model without and with covariates is discussed. In Section 6, two real-data applications are presented to illustrate the proposed models, without and with covariates. Finally, in Section 7, some concluding comments are presented.
2. Generalized Truncated Gumbel Distribution
Neamah and Qasim [16] derived a new model with positive support for the Gumbel distribution by truncating its pdf from the left. We will refer to the resulting model of these authors as the truncated Gumbel (TG) distribution, which is defined in the interval . In considering the reparametrization , the pdf of the TG distribution can be written as follows:
where is a scale parameter, is a shape parameter, and and are the pdf and cdf for the standard Gumbel distribution, respectively.
In this work, we considered the transformation developed by Cooray and Ananda [17] to extend the TG distribution. That is, we considered the transformation , where . We will refer to this extension as the generalized truncated Gumbel (GTG) distribution. Important functions, such as the pdf, cdf, hazard and quantile functions of the GTG distribution are provided below.
2.1. Pdf, cdf and Hazard Function
Proposition 1.
Let . Then, the pdf of Z is given by
where , and .
Proof.
Considering the stochastic representation of Z, we have that . Then,
Therefore, the result is obtained by replacing in . □
Remark 1.
We previously mentioned that if , where . Thus, when , we obtain the TG distribution; that is, .
Proposition 2.
Let . Then, the cdf and hazard function of Z are given by
and
respectively, for all .
Proof.
Both functions are obtained immediately from their definitions. □
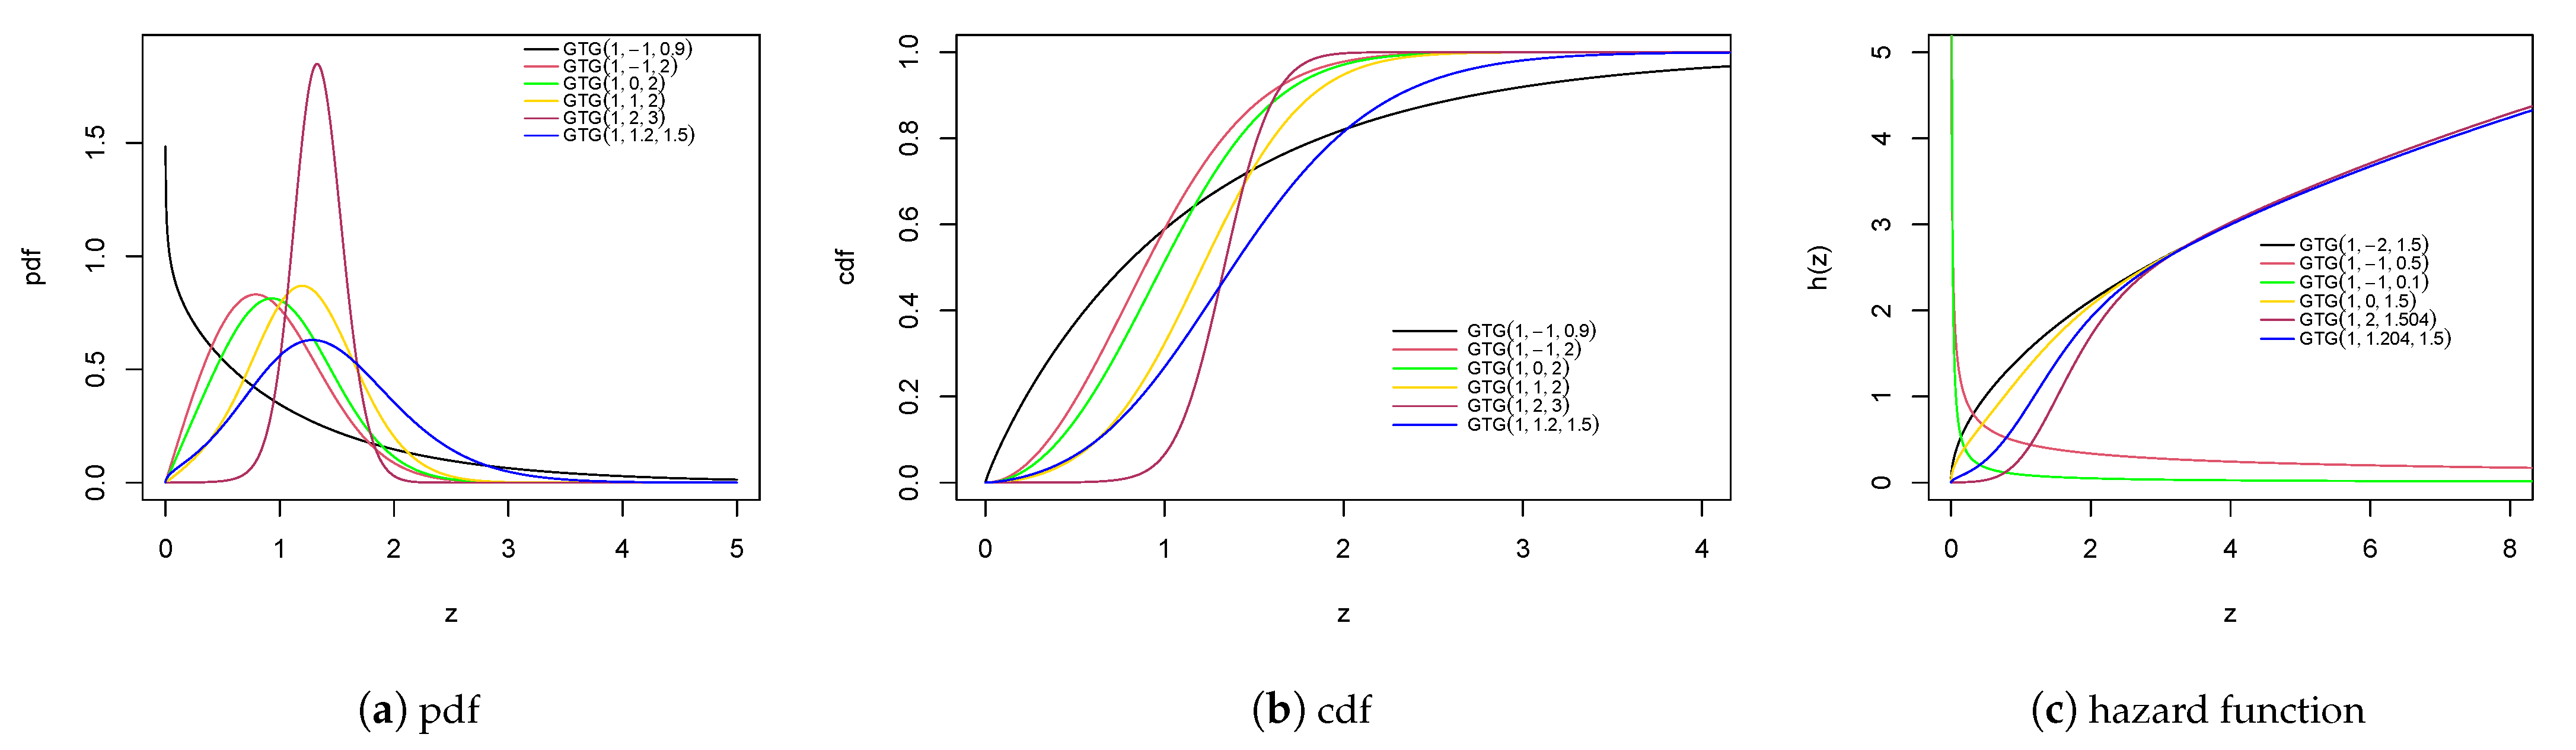
Figure 1 shows the pdf, cdf and hazard function for the model, considering some combinations for and . We observe that the GTG model can have decreasing or unimodal shapes for the pdf, whereas for the hazard function, we can have decreasing or increasing shapes. Also, we observe that for some combinations of and , the cdf rapidly increases, although all of them tend to 1 when z increases.
Figure 1.
Pdf, cdf and hazard function for the model with different value combinations for and .
2.2. Mode
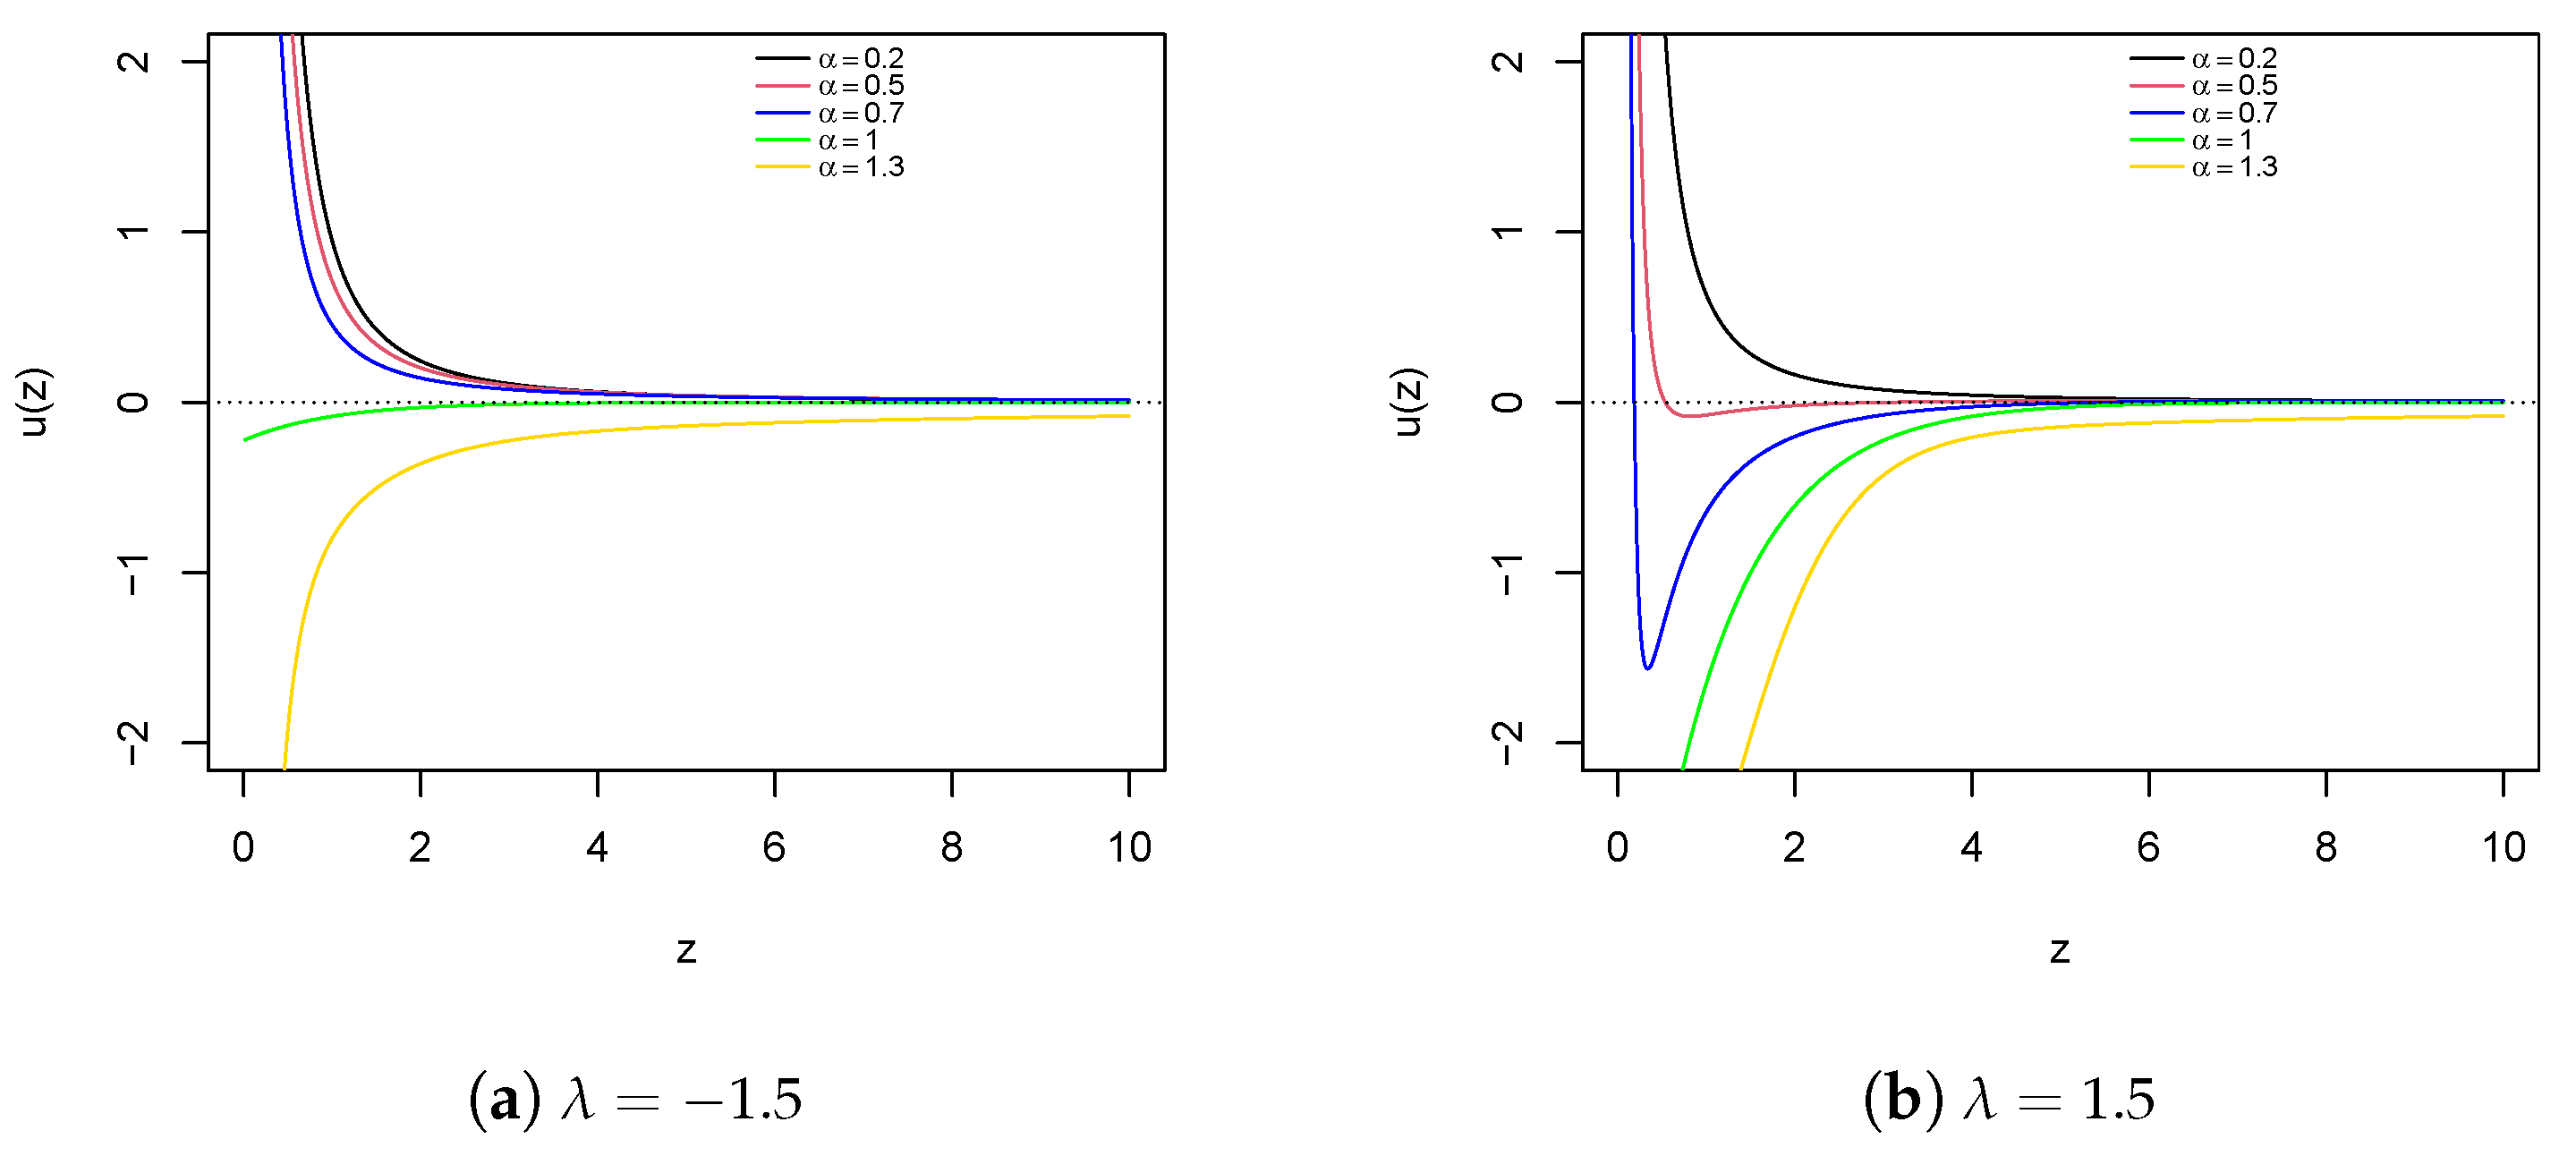
The shape of the pdf of can be examined based on its inflection points. By computing the first derivative of with respect to z, where is the pdf for the GTG model, we obtain that
where . By equating the previous expression to 0, we obtain that
from which the mode of Z can be numerically obtained. The nature of the points are determined by , where is given by
Depending on whether or , where is a solution of Equation (5), the inflection points can be local maxima or minima. Figure 2 shows the shape of for and selected values of and . From here, we observe that the pdf of the GTG distribution is zero when , both for when takes a positive or negative value.
Figure 2.
Shape of for and some value selections of and .
2.3. Quantiles
Proposition 3.
If , then the quantile function of Z is given by
Proof.
It follows from a direct computation, by applying the definition of the quantile function. □
Corollary 1.
The quartiles of the GTG distribution are as follows:
- 1.
- (First quartile) .
- 2.
- (Median) .
- 3.
- (Third quartile) .
Proof.
It is immediate from Proposition 3. □
2.4. Moments
Proposition 4.
Let and n be a positive integer. Then, the n-th moment of Z is given by
where ,, and is the generalized binomial coefficient. When , the sum in stops at .
Proof.
Given the stochastic representation of Z, it is immediate that , where . Then, the moment of Y can be computed by following the properties presented in Neamah and Qasim [16]. □
Corollary 2.
If , then the first four moments and the variance of Z are obtained as follows:
- 1.
- 2.
- 3.
- 4.
- 5.
- .
Proof.
It is immediate from Proposition 4. □
Corollary 3.
Let . Then, the skewness coefficient () and the kurtosis coefficient () are given by
where , and , for .
Proof.
The expressions above are obtained using the definitions of the skewness and kurtosis coefficients; that is,
where , for , are given in Corollary 2. □
Remark 2.
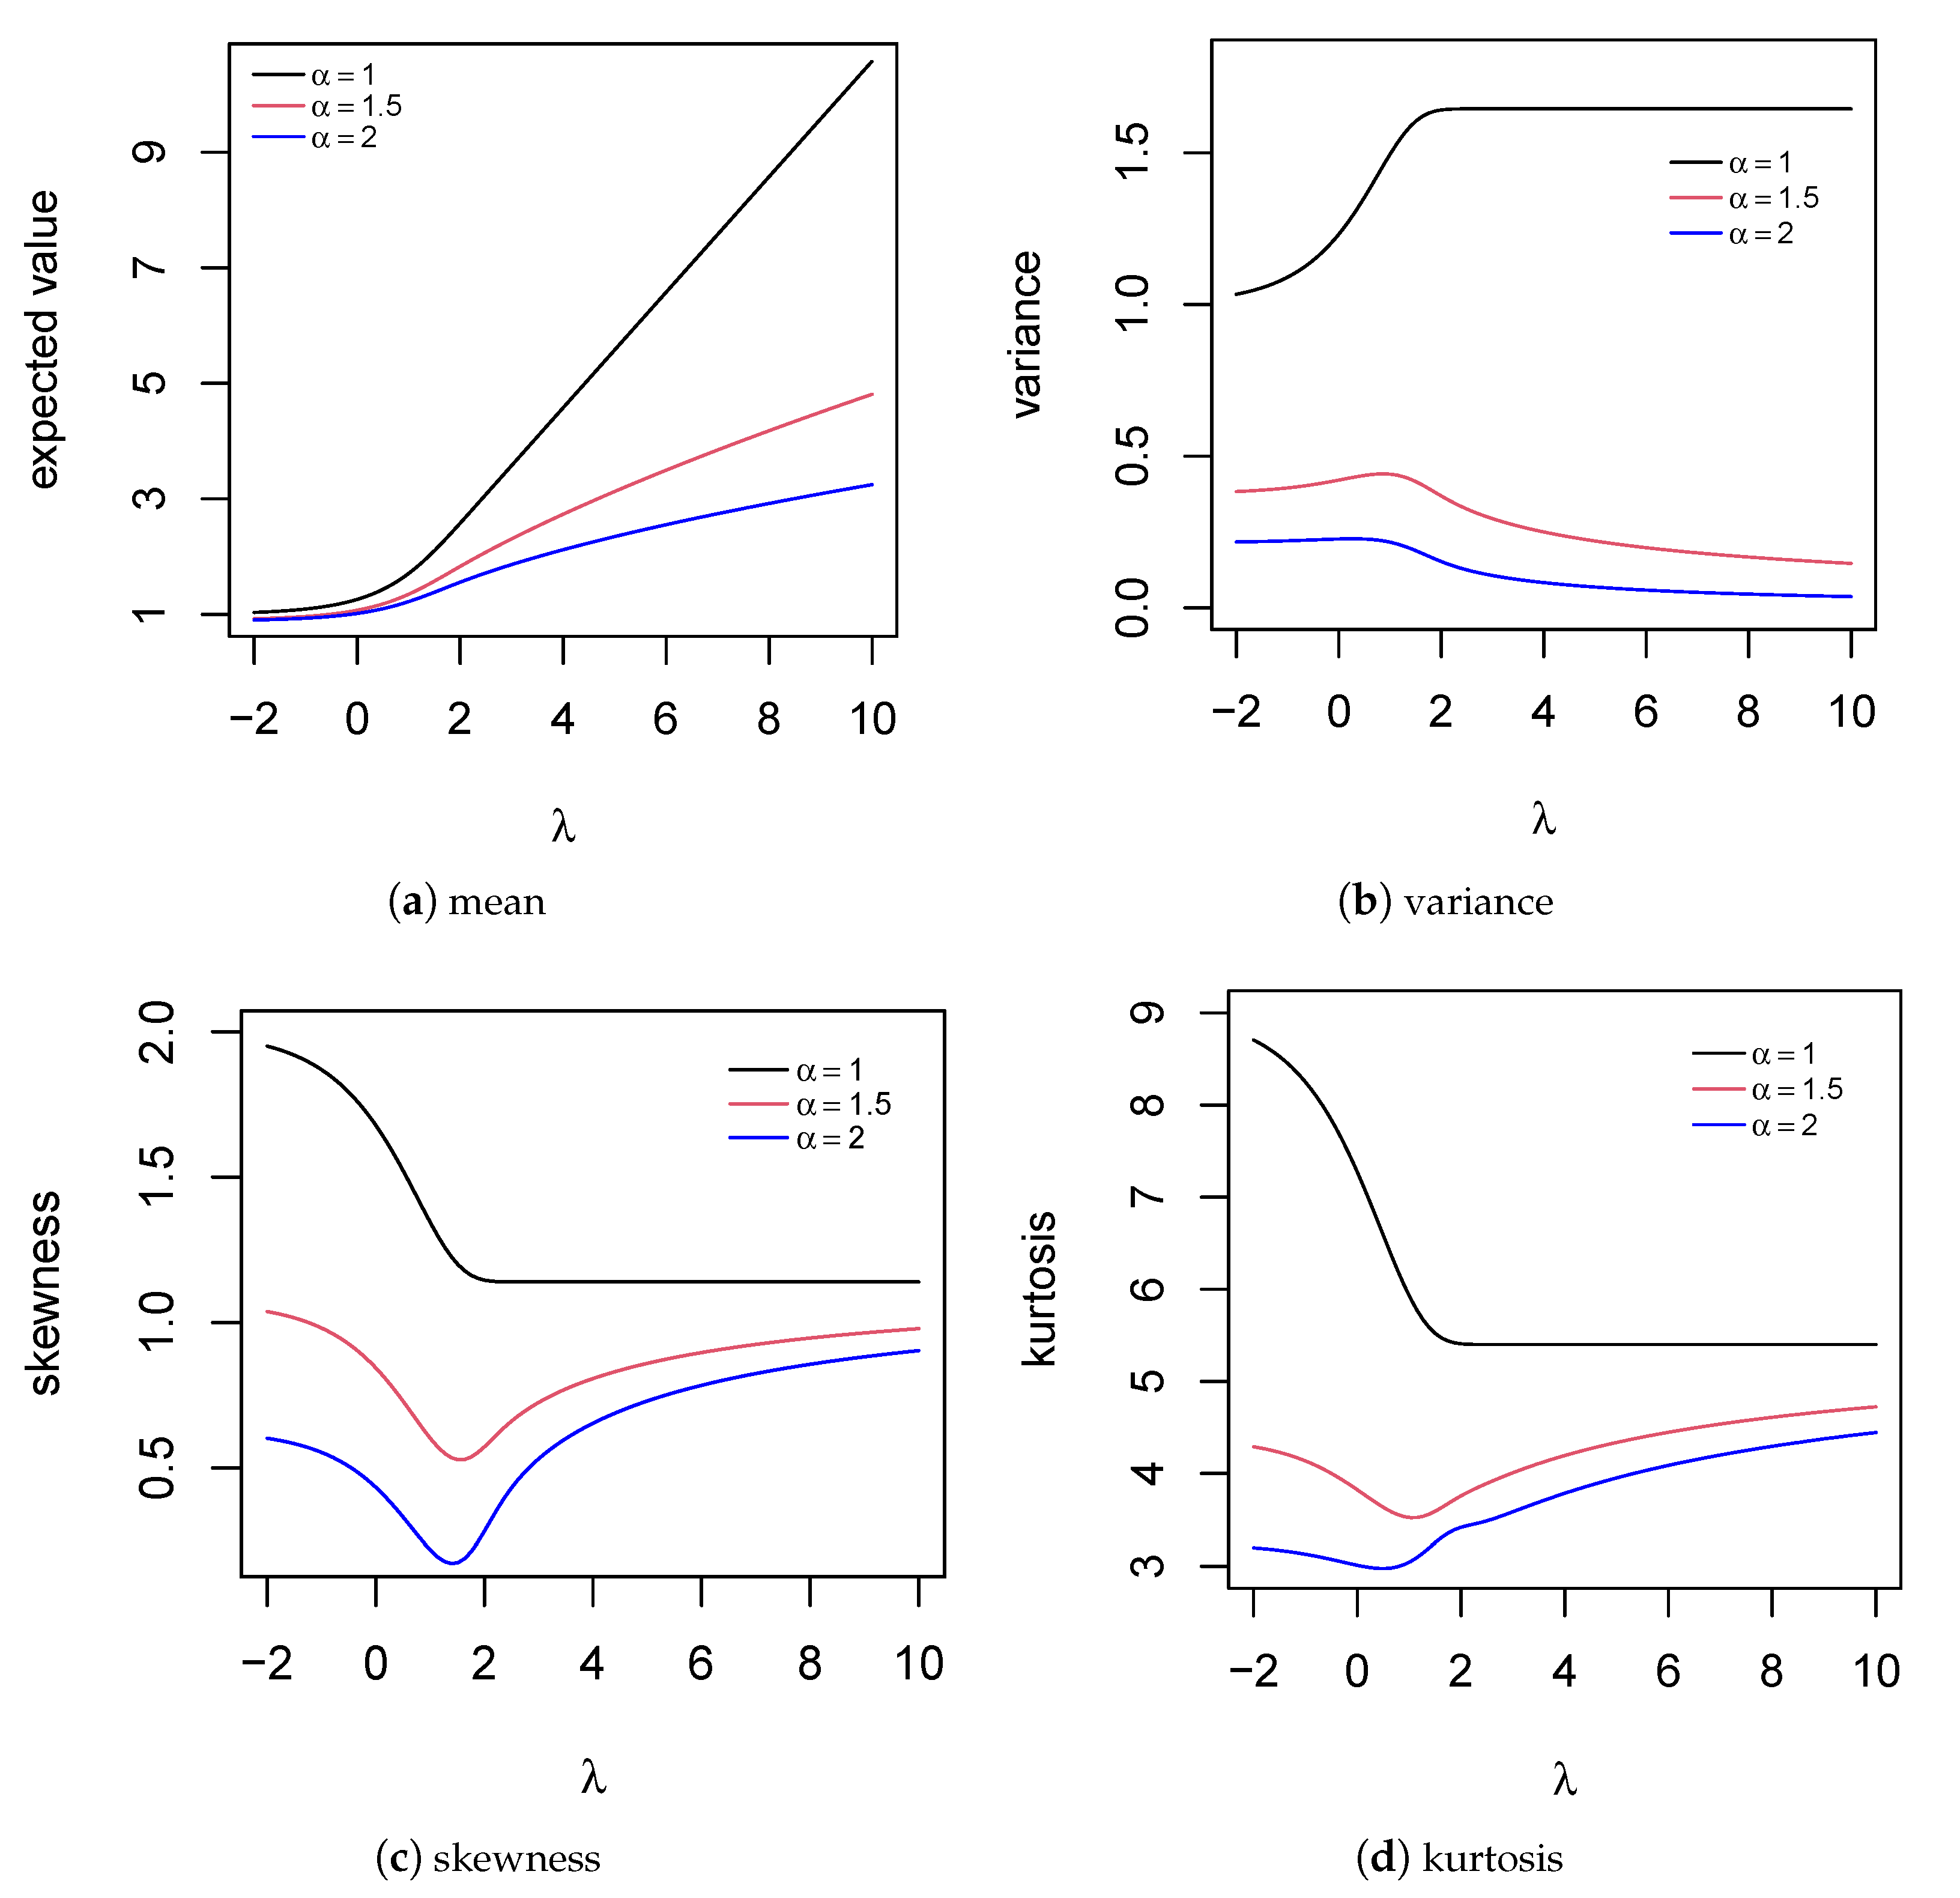
Proposition 4 shows that the moments of the distribution basically depend on the moments of the model. Plots for the expected value, variance, skewness and kurtosis coefficients of the model are given in Figure 3 for different values of the λ and α parameters. The bottom plots in Figure 3 reflect the effect of the α parameter: a lower value of α produces higher values of the skewness and kurtosis coefficients. This fact can also be appreciated in Table 1 and Table 2.
Figure 3.
Plots of the (a) mean, (b) variance, (c) skewness and (d) kurtosis coefficients for GTG (, , ) for as a function of .
Table 1.
Skewness coefficient of the model for different values of and .
Table 2.
Kurtosis coefficient of the model for different values of and .
2.5. Bonferroni Curves
In different disciplines, such as socio-economics and public health sciences, there is a necessity to compare and analyze the inequality of non-negative distributions. Generally, Bonferroni curves are used as graphical methods to achieve the required comparison/analysis (see Bonferroni [18], and Arcagni and Porro [19] for a further discussion about these curves). The following result shows the expressions of these curves for the GTG model.
Proposition 5.
If , then the Bonferroni curves, say , are given by
where , , and .
Proof.
The expression above is obtained using the definition of the Bonferroni curves; that is,
where is the expected value of the corresponding non-negative random variable, and . □
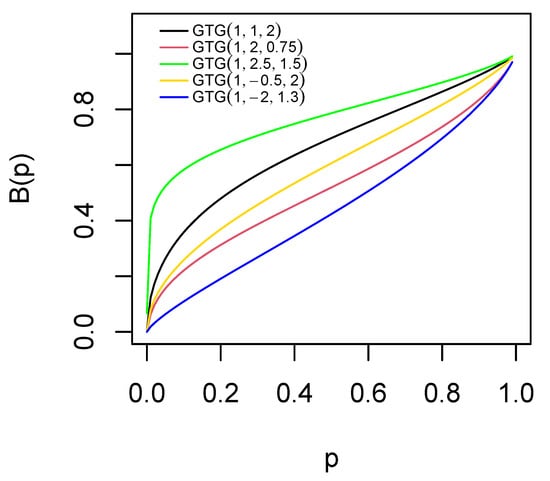
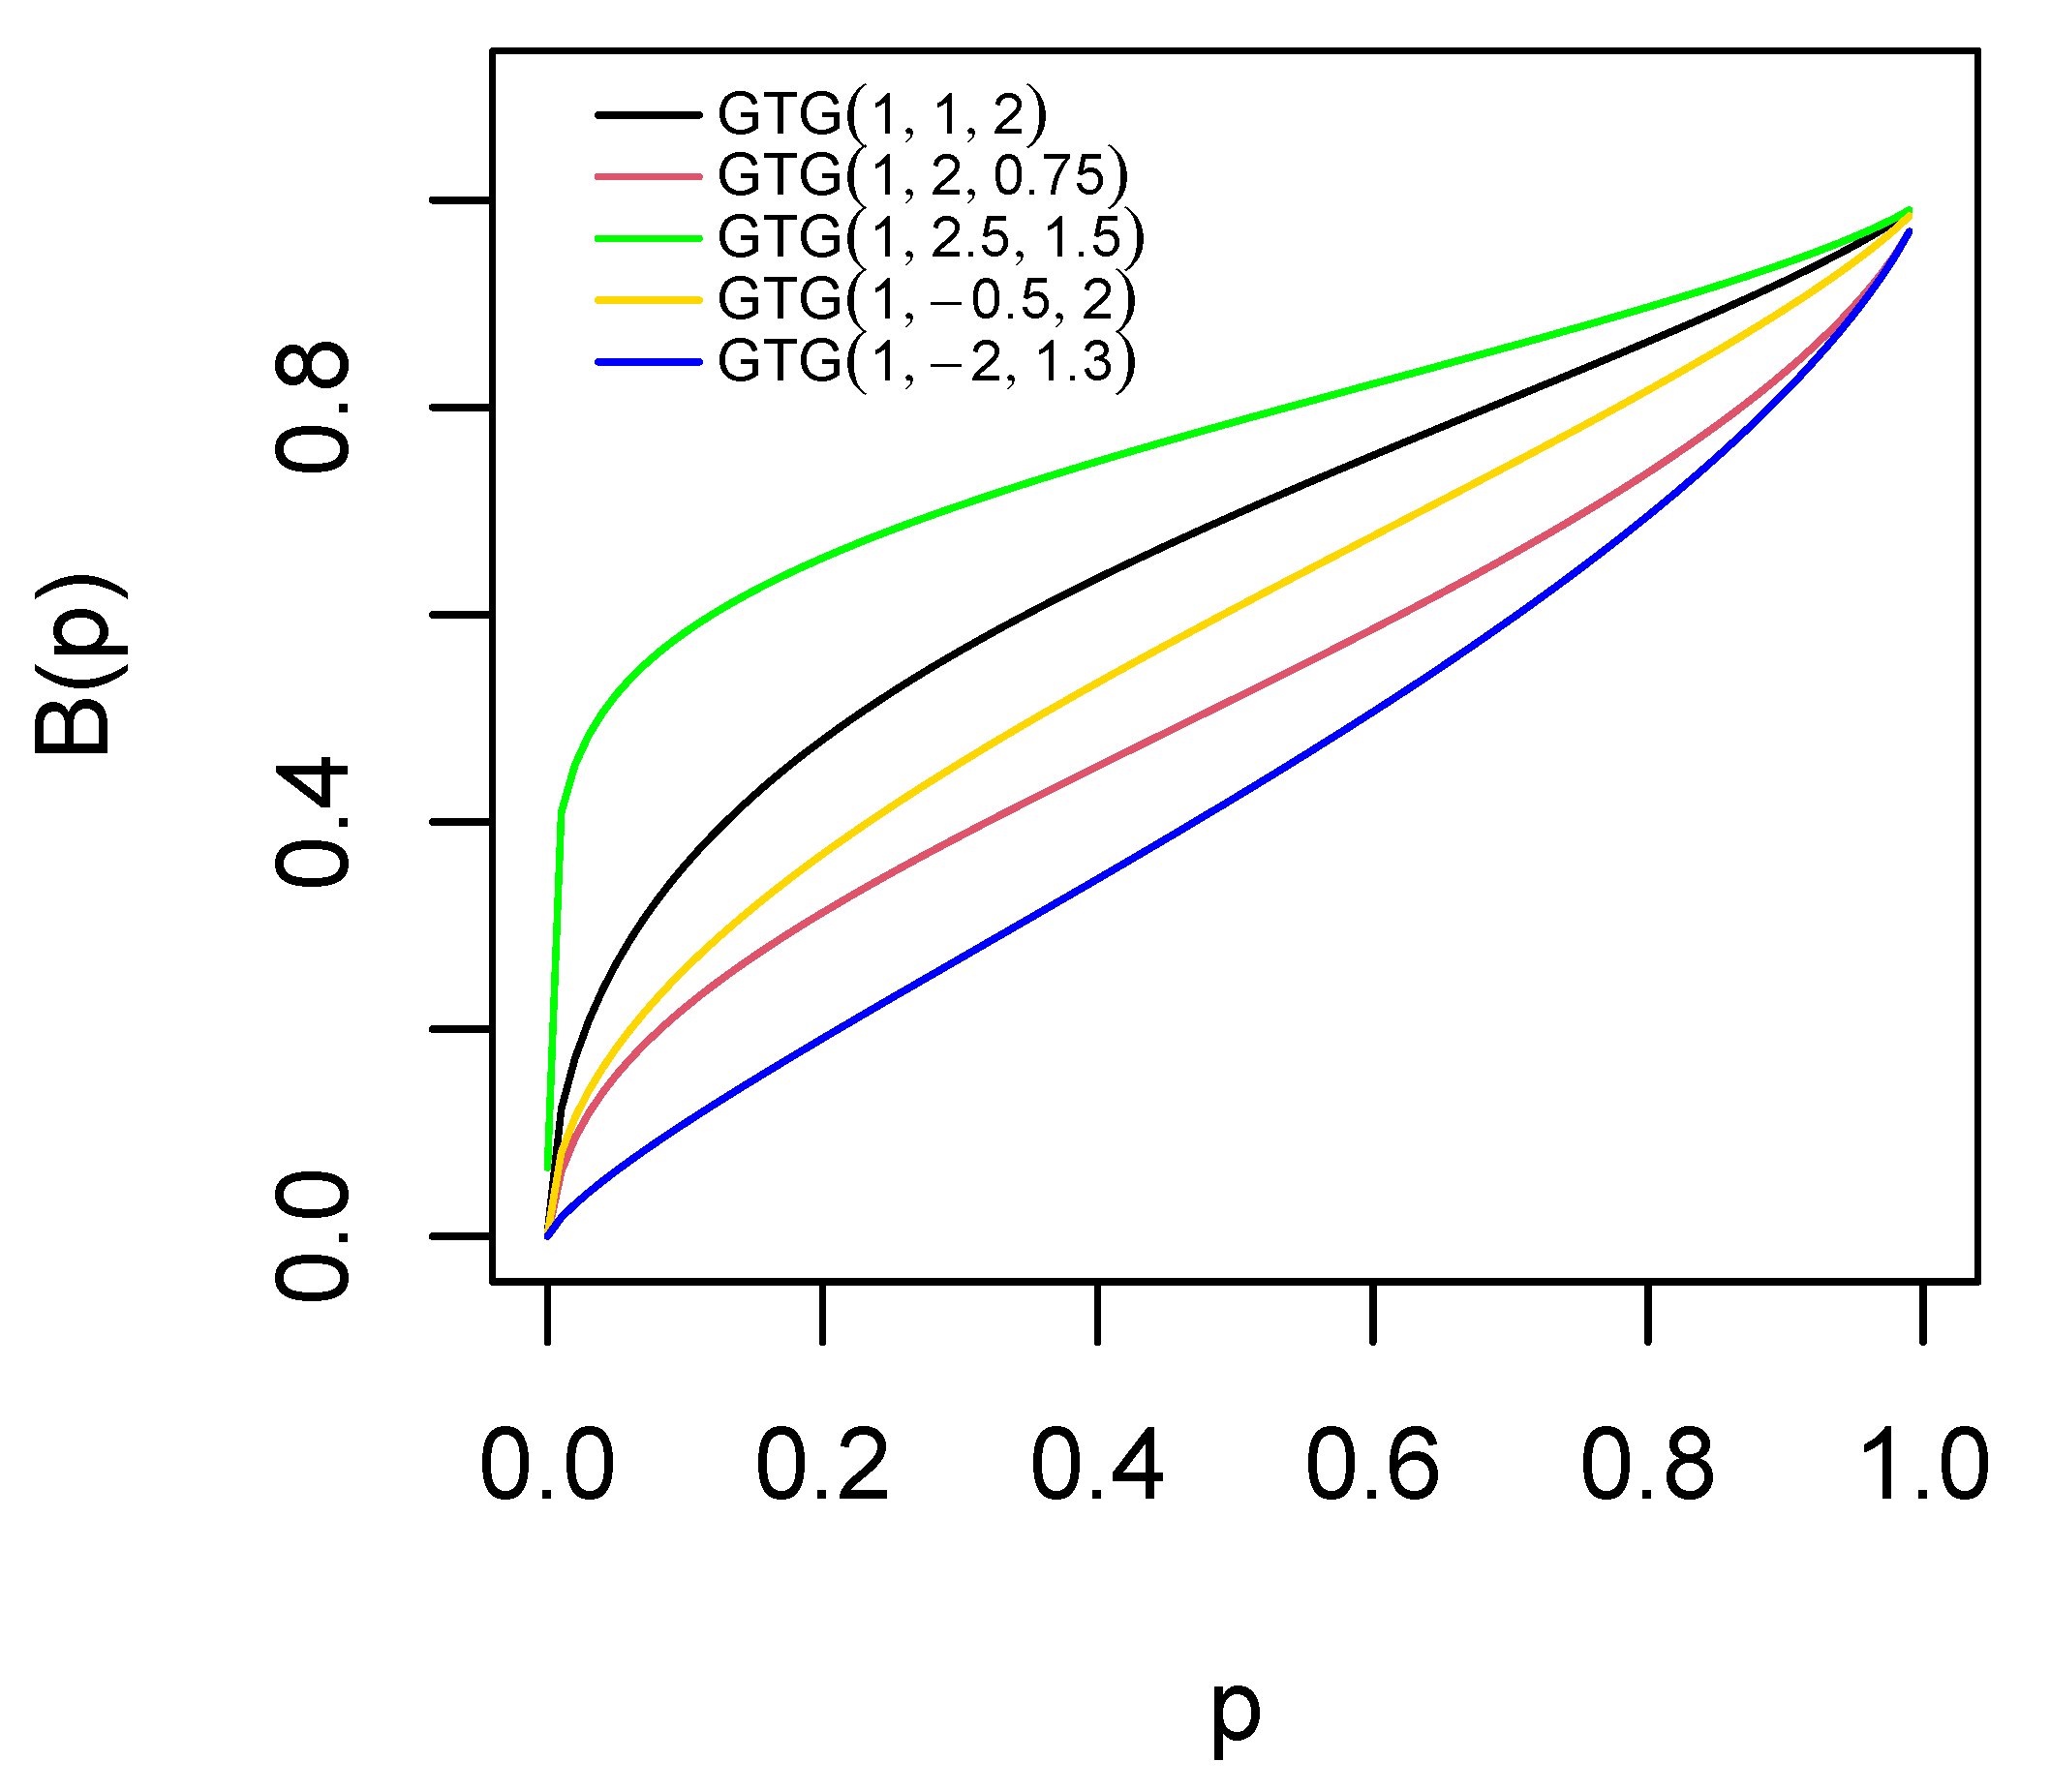
Figure 4 shows the Bonferroni curves for the model, considering different values for and .
Figure 4.
Bonferroni curves for the model, with and for selected values of and .
3. Inference for the GTG Distribution
In this section, we discuss the maximum likelihood (ML) approach for parameter estimation in the GTG model.
3.1. Maximum Likelihood Estimators
Let be a random sample of size n from the model. Then, the log-likelihood function for is given by
where . Therefore, the score assumes the form , where
and
The ML estimators are then obtained by numerically solving the equation , where denotes a vector of zeros with length p. Solutions for Equations (9)–(11) can be obtained using numerical procedures in R [20], such as the Newton–Raphson method. To initialize the numerical algorithm that solves , in the next subsection, we propose an initial point for the vector .
3.2. Initial Points
In this subsection, we propose estimators based on the quantiles for the GTG distribution, and these estimators are an alternative to the moment estimators, which meets the objective of using them as initial values to calculate the maximum likelihood estimators of the GTG distribution.
Let and be the sample quartiles that are based on . Initial values for can be obtained by equating the sample quartiles with the theoretical quartiles. The resulting equations are given by
and
The solutions for and , say and , can be expressed in terms of (the solution for ) as follows:
whereas is obtained from the non-linear equation
Therefore, the initial point based on this method is given by .
3.3. Observed Fisher Information Matrix
The asymptotic variance of the ML estimators, say , can be estimated from the observed Fisher information matrix defined as , with given in Equation (8). Under regularity conditions,
where stands for convergence in distribution, and denotes the standard trivariate normal distribution (see Wang et al. [21]). Moreover, can be estimated from the matrix , whose elements are given by , , and so on. Explicitly, we have that
where .
4. GTG Quantile Regression Model
For the GTG model, the mean has a complicated form, and then, it is not recommendable to consider a mean-parameterized version of the model. On the other hand, and thinking in a context of heterogeneous observations, quantile regression is a more appropriate tool for analyzing data in presence of covariates because they allow for a complete description of the distribution of the response variable (not just a particular measure as is the case when regression on the mean is conducted).
Specifically, for the GTG model and considering that represents the pth quantile of the distribution, we obtain the equation , . By solving such an equation, we obtain
where .
Thus, we can reparameterize the pdf and cdf of the GTG model as
and
respectively, where , , , and is fixed. We refer to this model as the reparameterized GTG (RGTG) model.
The consideration of as a set of q known covariates related to the p-th quantil of the i-th individual can be introduced in the model as follows:
where is a q-dimensional vector of unknown regression parameters (), and is a link function, which is continuous, invertible and at least twice differentiable. A natural choice in this context is the logarithm link, i.e., .
With this framework, the corresponding log-likelihood function for the RGTG quantile regression model is given by
where . The estimation of the regression parameters is obtained by directly maximizing this function.
5. Simulation Study
In this section, we present two simulation studies related to assessing the performances of the ML estimators for the GTG model and the RGTG quantile regression model.
5.1. Without Covariates
In this study, we carried out a simulation study to evaluate the performances of the ML estimators given in Section 3.1. We generated random values from the distribution with Algorithm 1.
| Algorithm 1 Simulating values from the distribution |
|
We used the following sequence to perform a simulation study to evaluate the behavior in finite samples of the MLEs of the GTG model. For , we fixed three values: 1, 2 and 3; for , we fixed two values: 2 and 3; for , we fixed two values: 1 and 2; and for the sample size n we fixed four values: 150, 300, 600 and 1000. For each combination of , , and n, we simulated 1000 replicates of that size and calculated ML estimators and their standard errors. Table 3 summarizes the mean of the estimated biases (bias), the mean of the estimated standard errors (SE), and the squared root of the estimated mean squared errors (RMSE), and each estimated coverage probability (CP) was obtained by taking into account the asymptotic distribution of the ML estimator using a 95% confidence level. Note that as the sample size increases, the bias, SE and RMSE decrease, which suggests that the ML estimators of the GTG model have an acceptable behavior even in finite samples. Moreover, the SE and RMSE terms tend to become closer as the sample size increases, suggesting that the variance of the estimators is well estimated. Finally, the CP terms come closer to the nominal value as n increases, which suggests that the asymptotic approach to the normal of the ML estimators of the GTG model is reasonable, even in finite samples.
Table 3.
Estimated bias, SE, RMSE and CP for ML estimators in finite samples from the GTG model.
5.2. With Covariates
Under this condition, we generated 3000 random samples with a sample size ranging from from the RGTG quantile regression model using three different values for . The structure of the scenarios is defined as follows:
where and . Here, Logis and Bern denote the standard logistic distribution and the Bernoulli distribution, respectively. The code for reproducing the simulations is available from the following repository https://github.com/isaaccortes1989/RGTG/tree/main/Simulation%20Study (accessed on 5 April 2024).
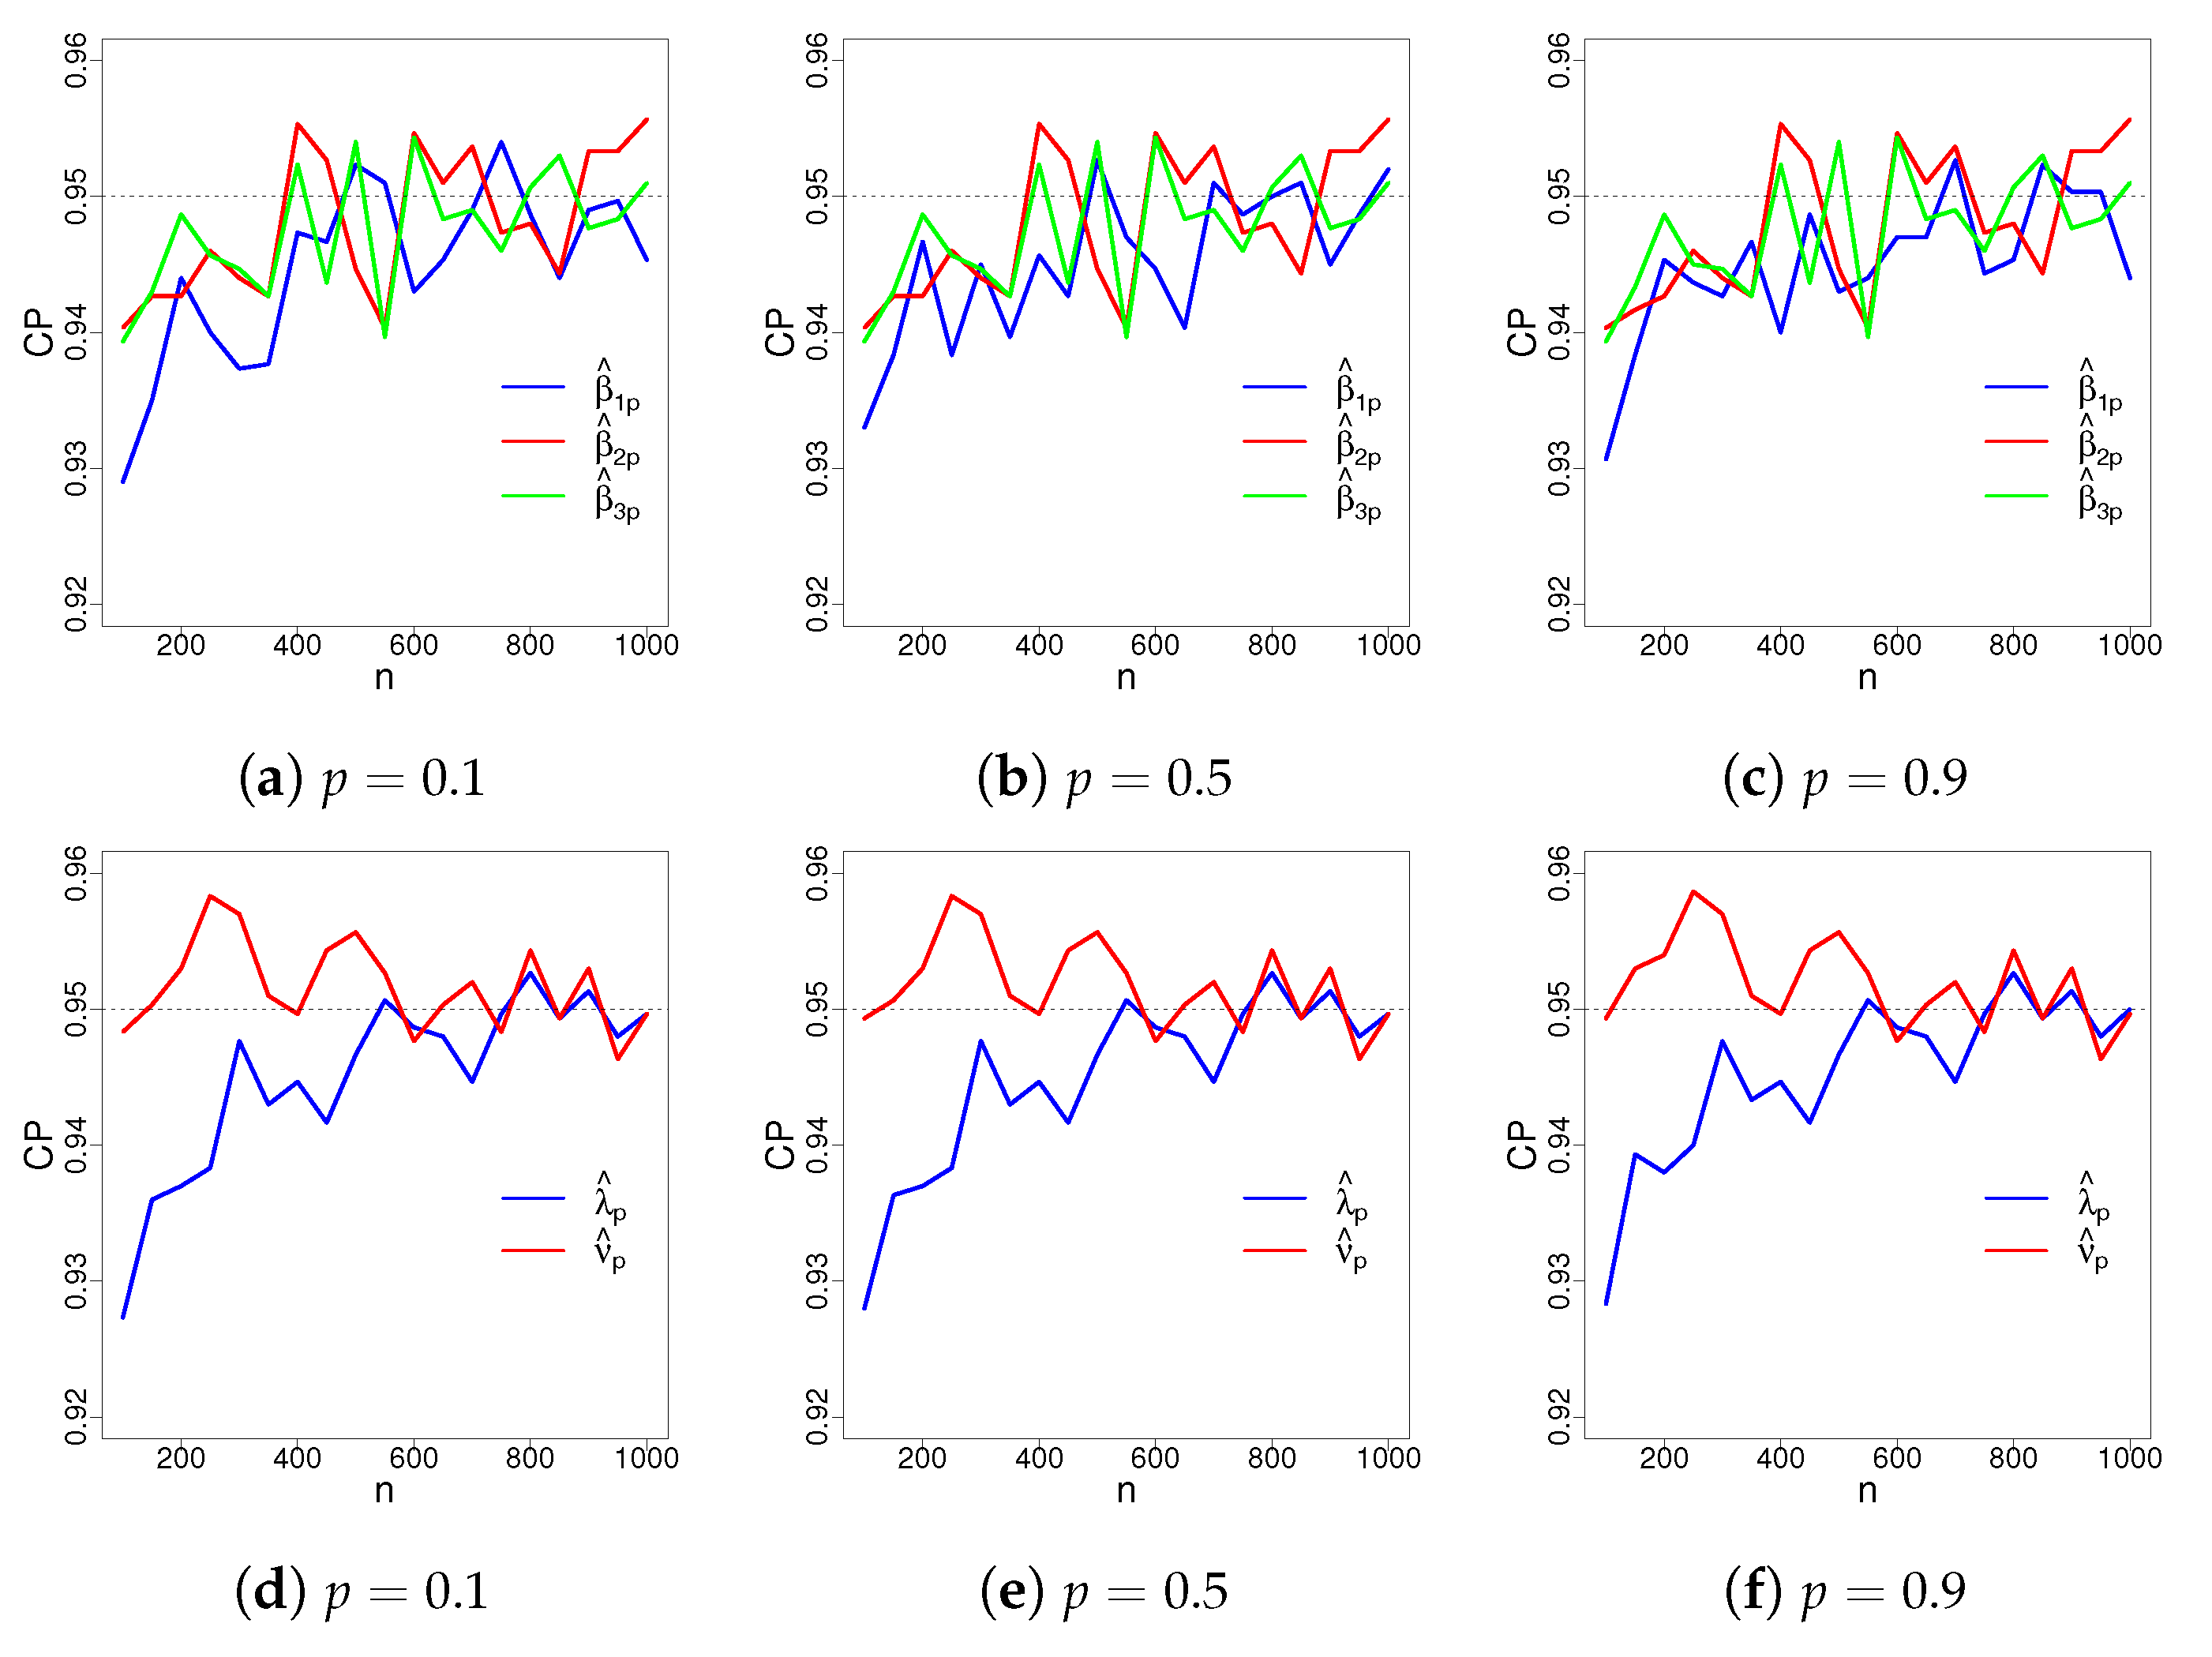
Figure A1, Figure A2, Figure A3, Figure A4 and Figure A5 in Appendix A.1 display the standard deviation (SD), mean of SE, RMSE, mean of the relative bias (RB) and CP of the 95% asymptotic confidence intervals of the estimates, under different sample sizes. It can be observed in Figure A1, Figure A2, Figure A3 and Figure A4 that the first four measures decrease as the sample size n increases, as expected in standard asymptotic theory. Finally, the CPs in Figure A5 indicate convergence to the nominal values.
6. Applications
In this section, we present two applications to real datasets to illustrate the performance of the GTG model and RGTG quantile regression model. The first application is related to the beta-carotene levels in a certain sample of persons. The second application involves explaining Mexican American individuals’ body mass index (BMI) in terms of their waist circumference and sex. The BMI is calculated by dividing a person’s weight in kilograms by the square of their height in meters, . Furthermore, it is a tool that health organizations use to monitor and plan public health programs.
6.1. Without Covariates
We considered the retinol plasma database available at http://lib.stat.cmu.edu/datasets/Plasma_Retinol (accessed on 5 April 2024), which focuses on understanding the determinants of the plasma levels of retinol, beta-carotene and other carotenoids. The main variable of interest is BETADIET, which represents the amount of beta-carotene consumed daily by each individual in micrograms (mcg). The importance of analyzing this variable lies in its direct relationship with the plasma levels of beta-carotene (BETAPLASMA), a key nutrient with antioxidant properties and a precursor of vitamin A. Table 4 presents a summary statistics of BETADIET, in addition to the skewness () and kurtosis ().
Table 4.
Descriptive statistics of the amount of beta-carotene consumed daily by each individual in micrograms (BETADIET).
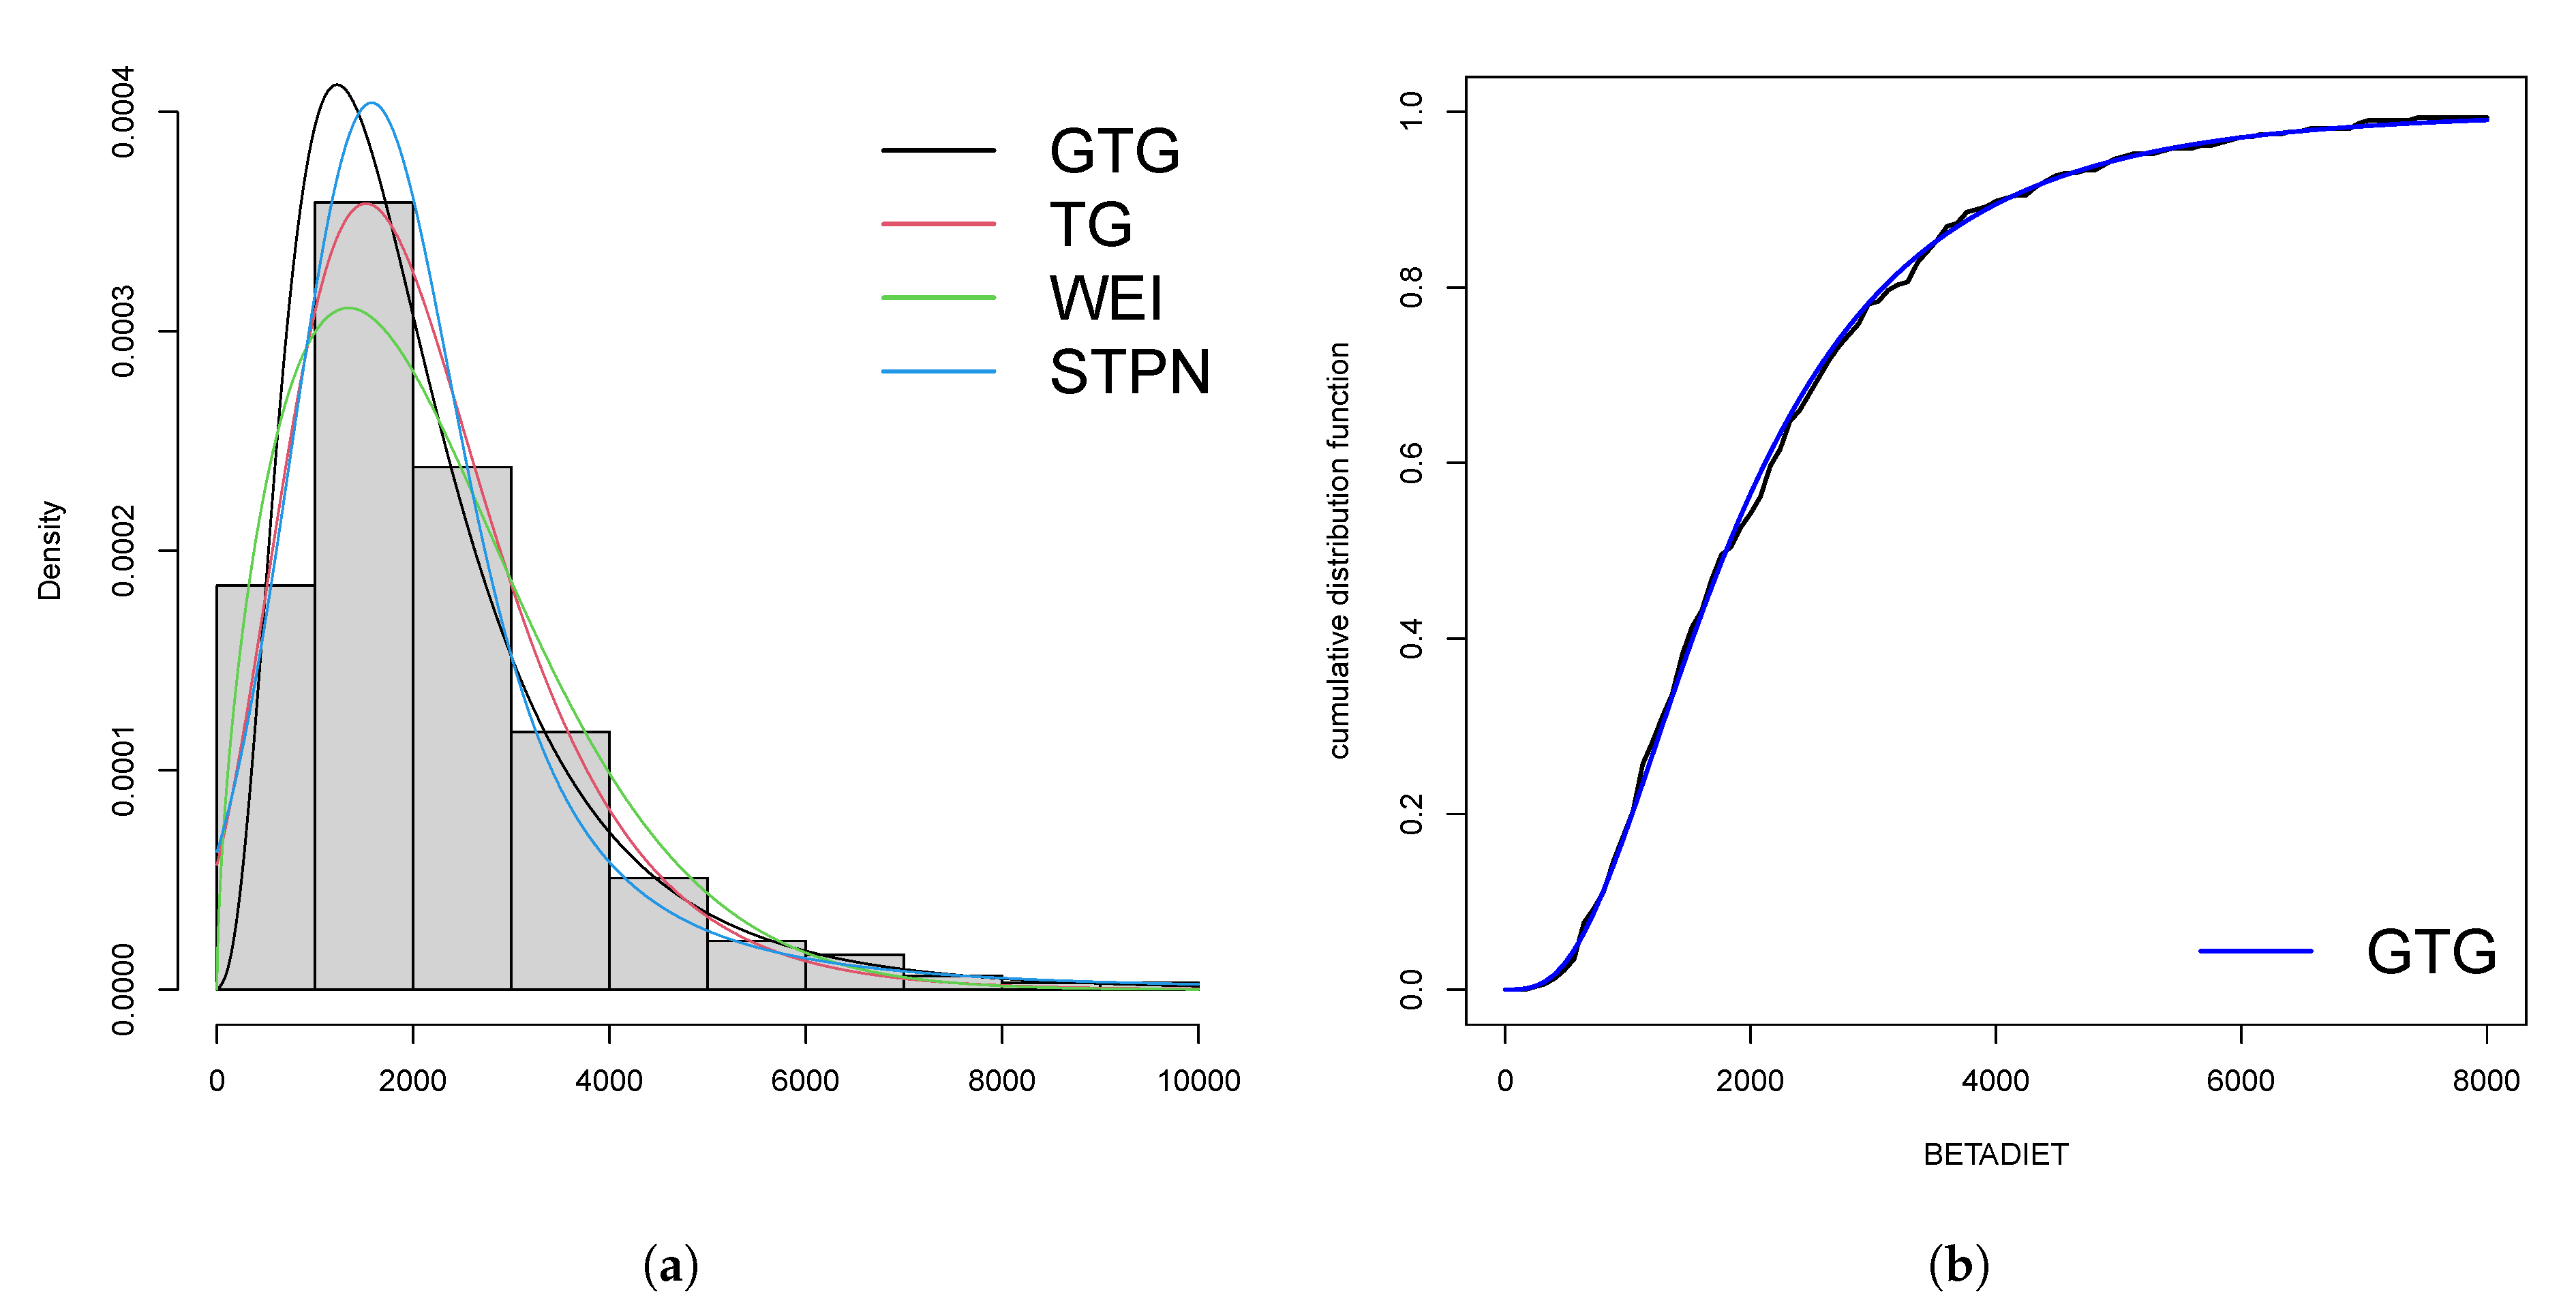
It can be seen from Figure 5 that the GTG has a better fit compared to the GT, Weibull and Slash truncation positive normal (STPN) (see Gómez et al. [22]) models, in addition to a good behavior of the fitted GTG cdf compared to the empirical cdf. Based on the Akaike information criterion (AIC) (see Akaike [23]) and Bayesian information criterion (BIC) (see Schwarz [24]) given in Table 5, we also see that the GTG model is preferred (among the fitted models) for this dataset.
Figure 5.
(a) GTG, TG, Weibull and STPN models adjusted using the maximum likelihood method for BETADIET. (b) Empirical (black) and fitted GTG (blue) cdf for the BETADIET dataset.
Table 5.
Estimated parameters and their standard errors (in parentheses) for the GTG, TG, Weibull, and STPN models for the BETADIET dataset. The AIC and BIC criteria are also presented.
6.2. With Covariates
In this application, we fit the quantile regression model to a dataset provided by Cortés et al. [25]. The dataset comprises the body mass index (BMI) measured in , waist circumference (Waist) in centimeters, age in years and Sex (1 for female and 0 for male) of 1743 individuals who self-identified as Mexican American in the National Health and Nutrition Examination Survey (NHANES) conducted between 2017 and 2018.
Here, we assumed that the BMI follows an RGTG distribution, denoted as . Accordingly, we propose the following structure for modeling:
where , , , and are the parameters used for the estimation, for and .
The parameter estimates and their corresponding standard errors are presented in Table 6, where it is observed that all estimates are statistically significant at all quantiles p. In relation to the interpretations of the regression coefficients, we can consider the following interpretations. We will present the interpretations in relation to the median, but for this problem, they are also valid for the other quantiles considered:
Table 6.
ML estimates of the parameters and their corresponding standard errors (in parentheses) for the RGTG quantile regression model.
- The estimated median BMI for females, assuming a waist circumference of 0, is .
- As , then for a given gender the estimated median, the BMI is increased by 1.013% for each unit that increases the waist circumference.
- As , then for a given waist circumference, the estimated median BMI for females is increased by approximately 1.036 times in comparison with that for males.
- and are the estimates of the shape parameters associates with the median BMI.
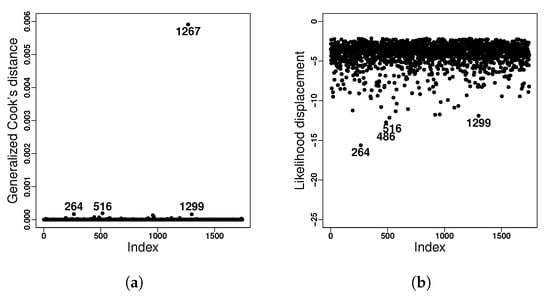
Additionally, to assess the model’s adequacy, we calculated the normalized quantile residuals (NQRs) along with their respective envelopes; see Dunn and Smyth [26]. These can be observed graphically in Figure A6 of Appendix A.2, where observation #1267 is highlighted as atypical. Also, we obtained the measures of a generalized Cook’s distance and likelihood displacement for ; see Figure 6. Here, we highlight that the potentially influential observations are #264, #486, #516, #1267 and #1299.
Figure 6.
(a) Generalized Cook’s distance and (b) likelihood displacement for the NHANES dataset.
Table 7 presents a classification (https://www.nhlbi.nih.gov/health/educational/lose_wt/BMI/bmi_dis.htm (accessed on 5 April 2024)) of overweight and obesity by sex, BMI, waist circumference, and risk of diseases (type 2 diabetes, hypertension, and cardiovascular disease) for the highlighted observations in the residuals, generalized Cook’s distance and likelihood displacement, considering (obese individuals). We observe from the table that observations #264 and #1267 indicate a very poor health status, emphasizing the importance of their detection.
Table 7.
Classification of overweight and obesity by BMI, waist circumference and associated disease risks.
7. Final Discussion
In this work, we proposed a new distribution called generalized truncated Gumbel. The model has quite a few interesting properties, mainly associated with having a cumulative distribution function and a quantile function in closed form. For this reason, an extension of the model was proposed to be used in the context of quantile regression. Future extensions of the model are directed in the context of random effects.
Author Contributions
Conceptualization, H.J.G., K.I.S., D.A. and I.E.C.; formal analysis, K.I.S., D.A., D.I.G. and T.M.M.; funding acquisition, H.J.G. and D.A.; investigation, H.J.G., K.I.S. and I.E.C.; methodology, H.J.G., K.I.S. and D.I.G.; software, I.E.C.; writing—original draft, H.J.G., K.I.S., D.A., D.I.G. and T.M.M.; writing—review and editing, D.A., D.I.G. and T.M.M. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The data are available for Applications 1 and 2. (http://lib.stat.cmu.edu/datasets/Plasma_Retinol, https://www.nhlbi.nih.gov/health/educational/lose_wt/BMI/bmi_dis.htm) (accessed on 5 April 2024).
Conflicts of Interest
The authors declare no conflicts of interest.
Appendix A
Appendix A.1. Behaviors of SD, SE, RMSE, RB and CP
Figure A1.
SDs of the 3000 estimates of , and obtained in the RGTG quantile regression model under different sample sizes.
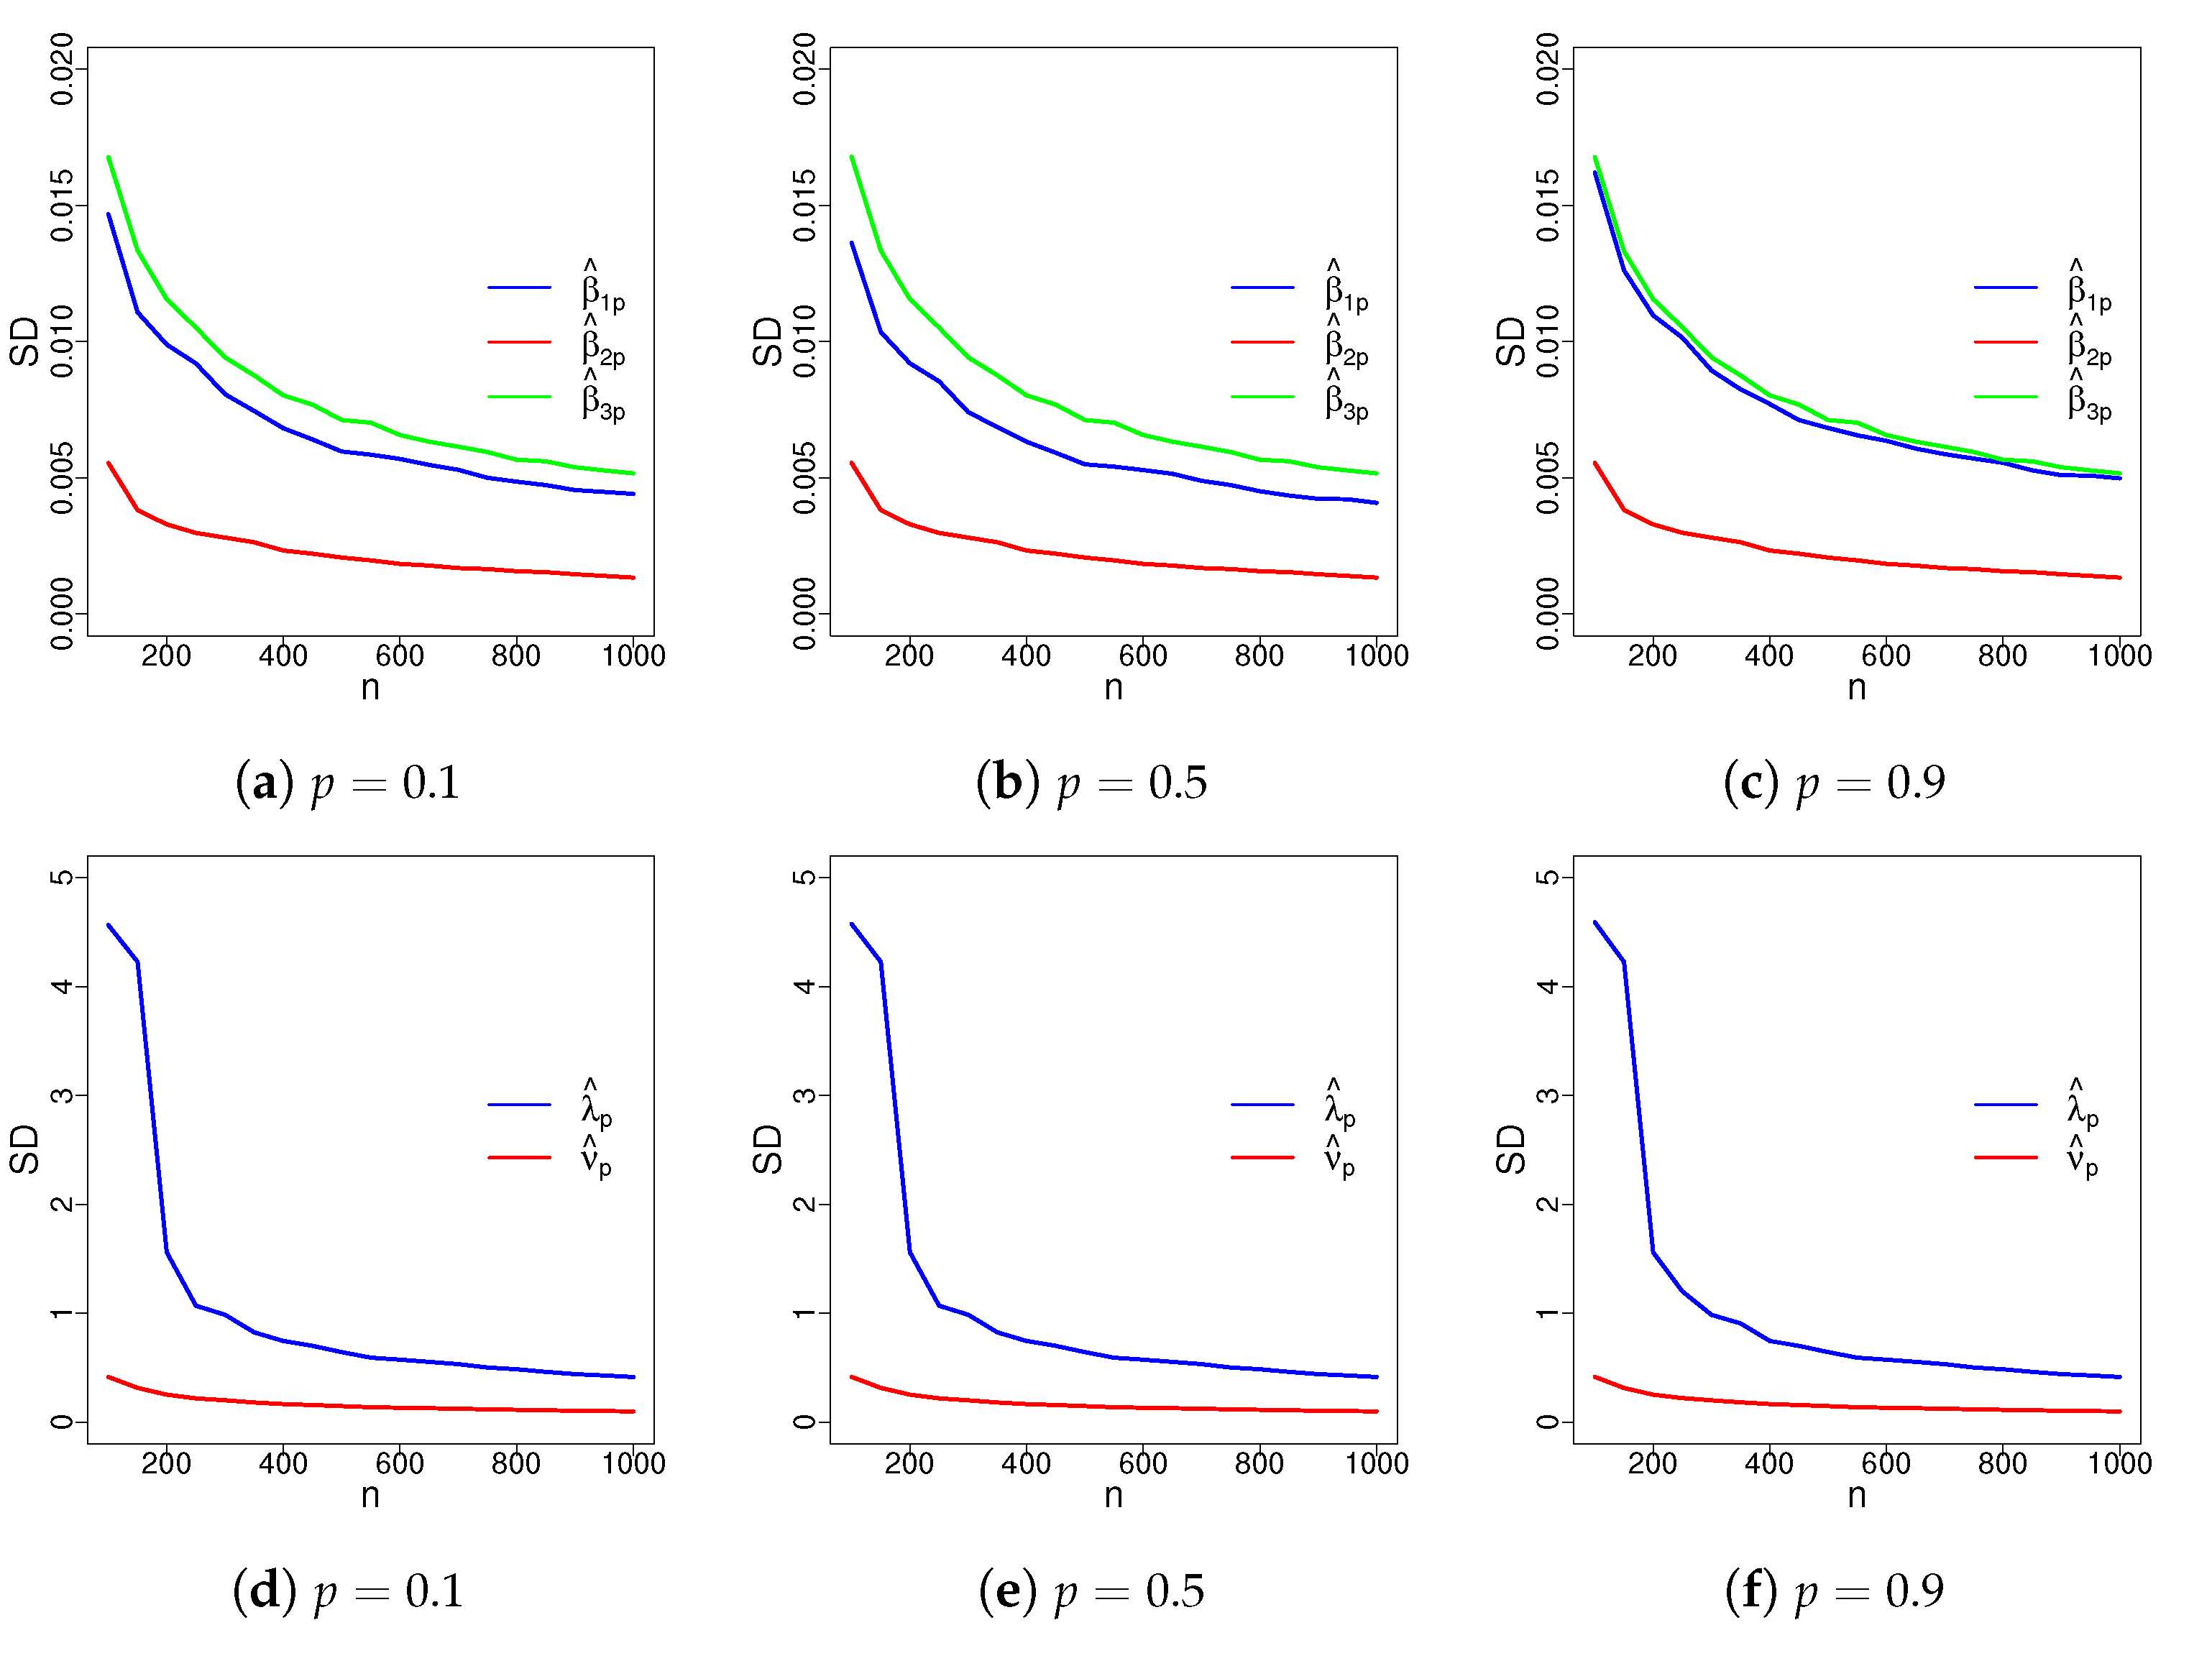
Figure A2.
Means of the asymptotic SE on the 3000 estimates of , and obtained in the RGTG quantile regression model under different sample sizes.
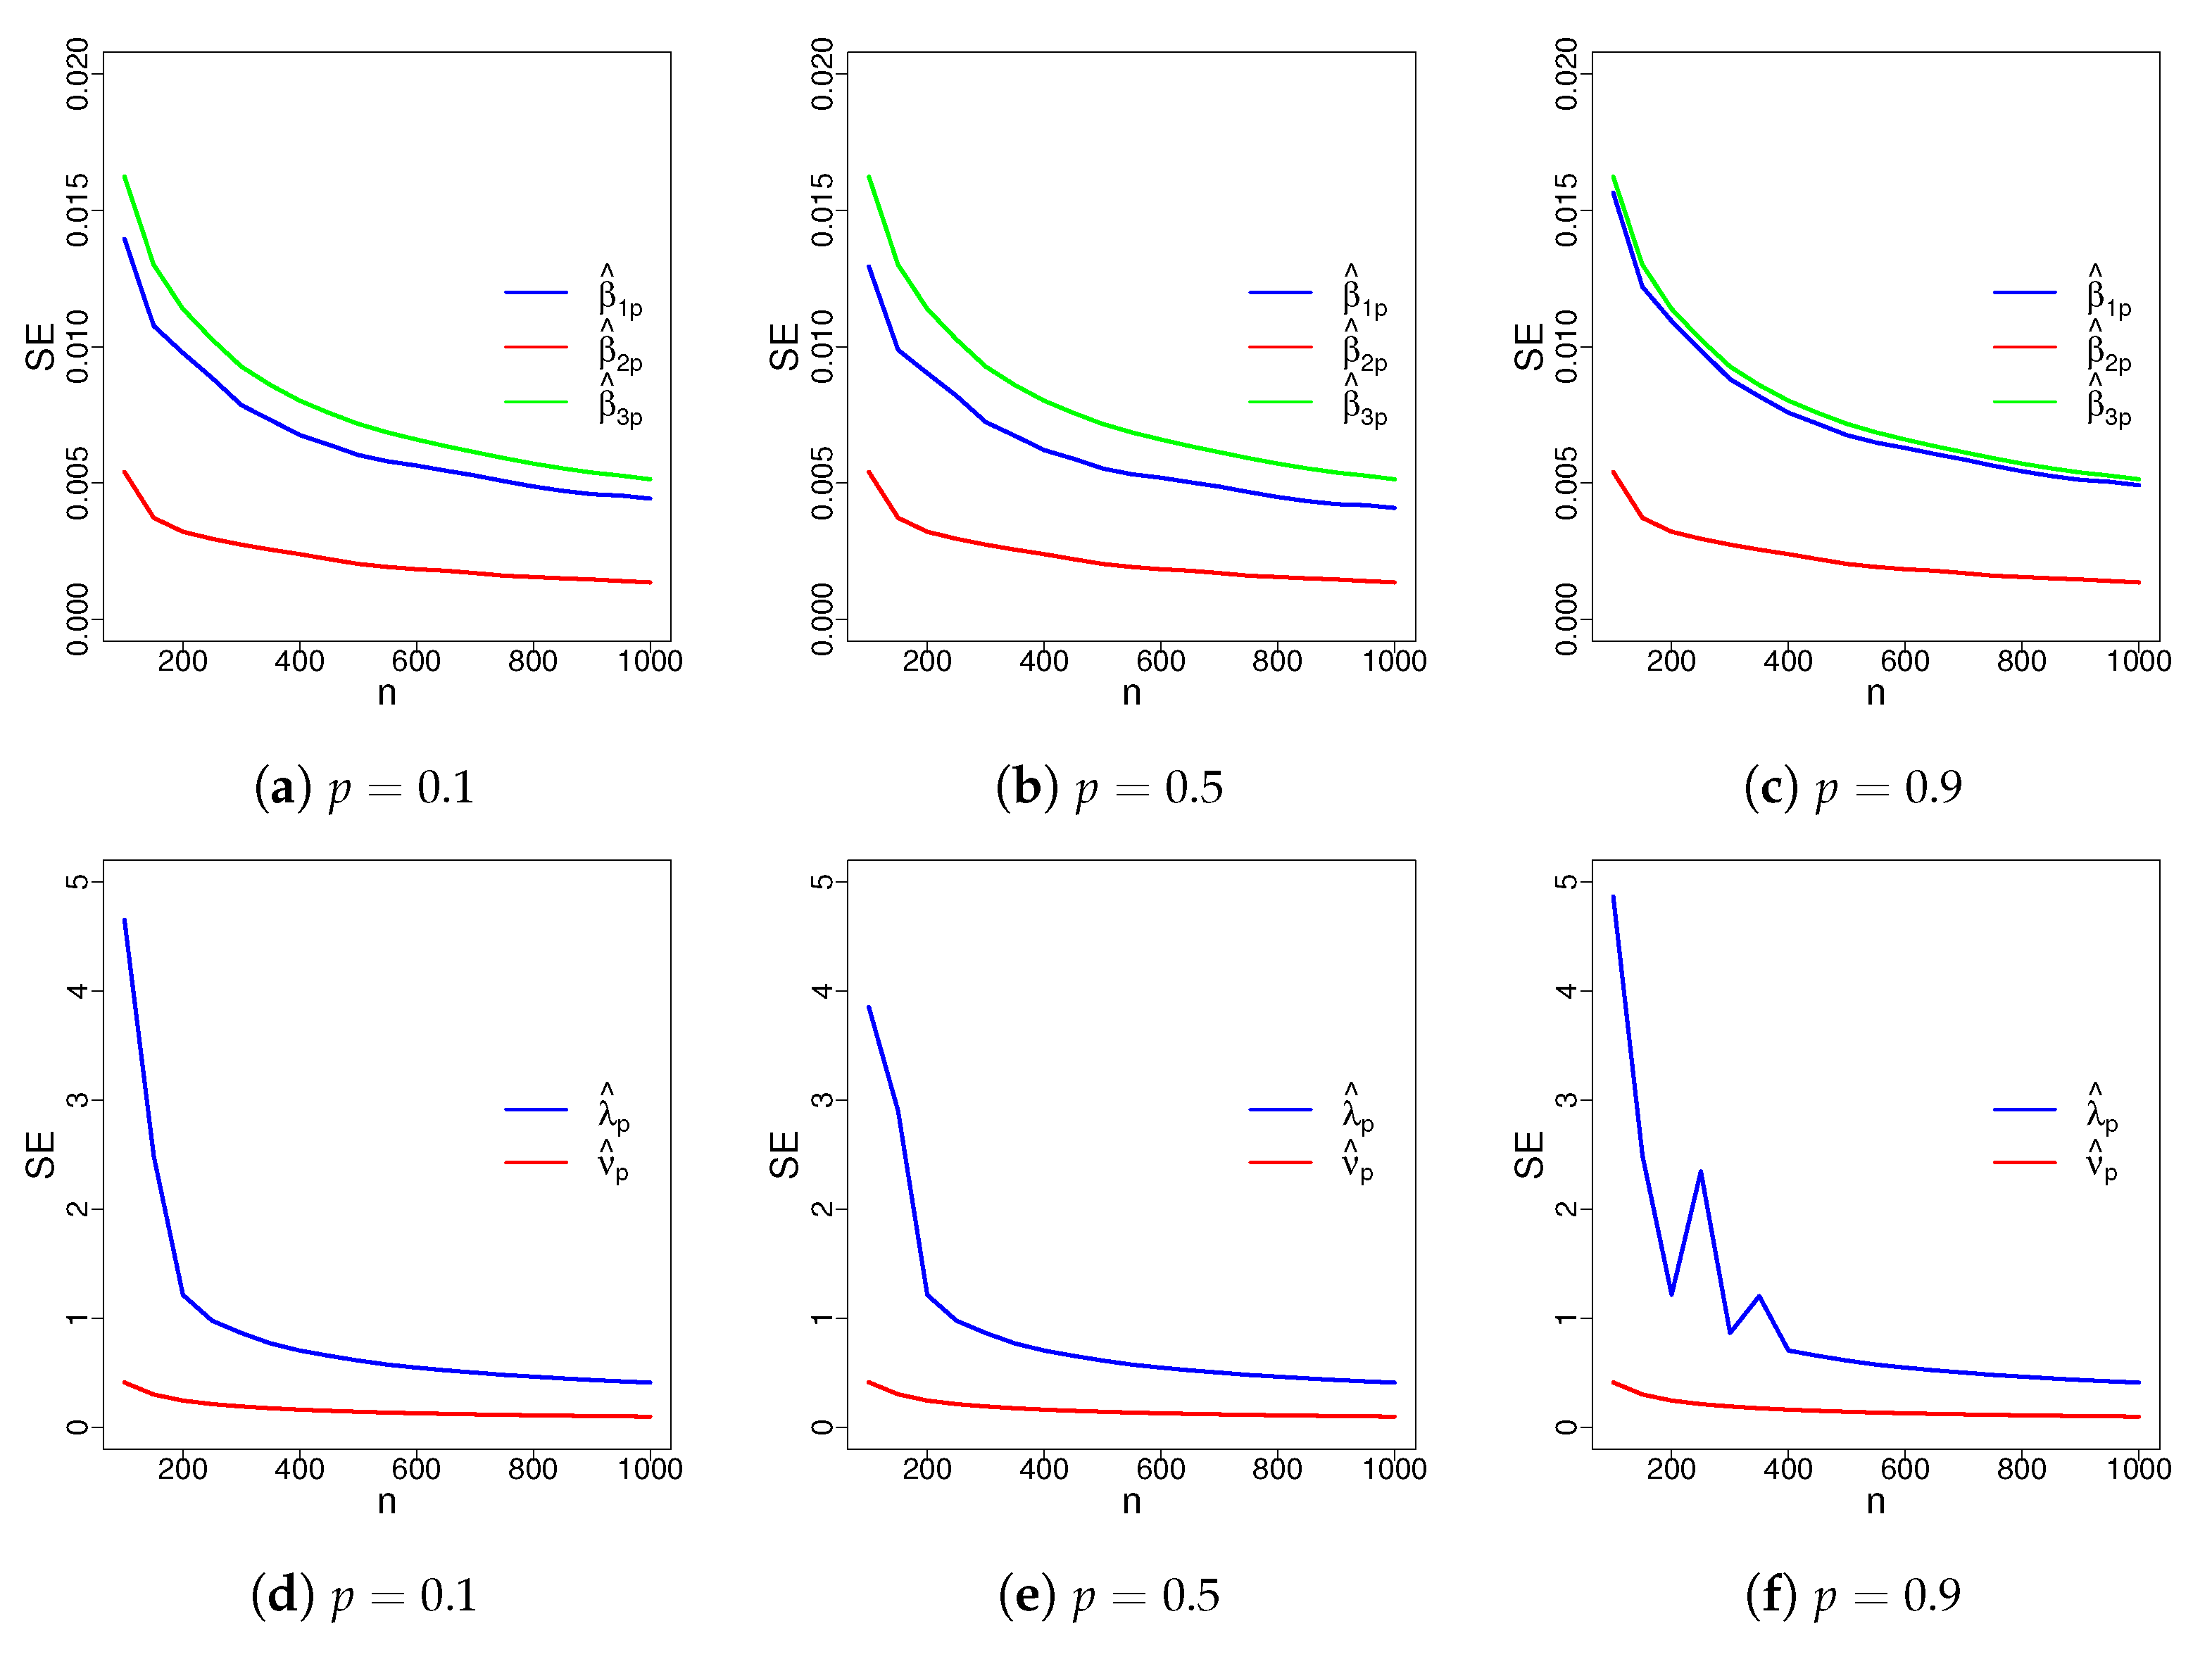
Figure A3.
RMSEs of the 3000 estimates of , and obtained in the RGTG quantile regression model under different sample sizes.
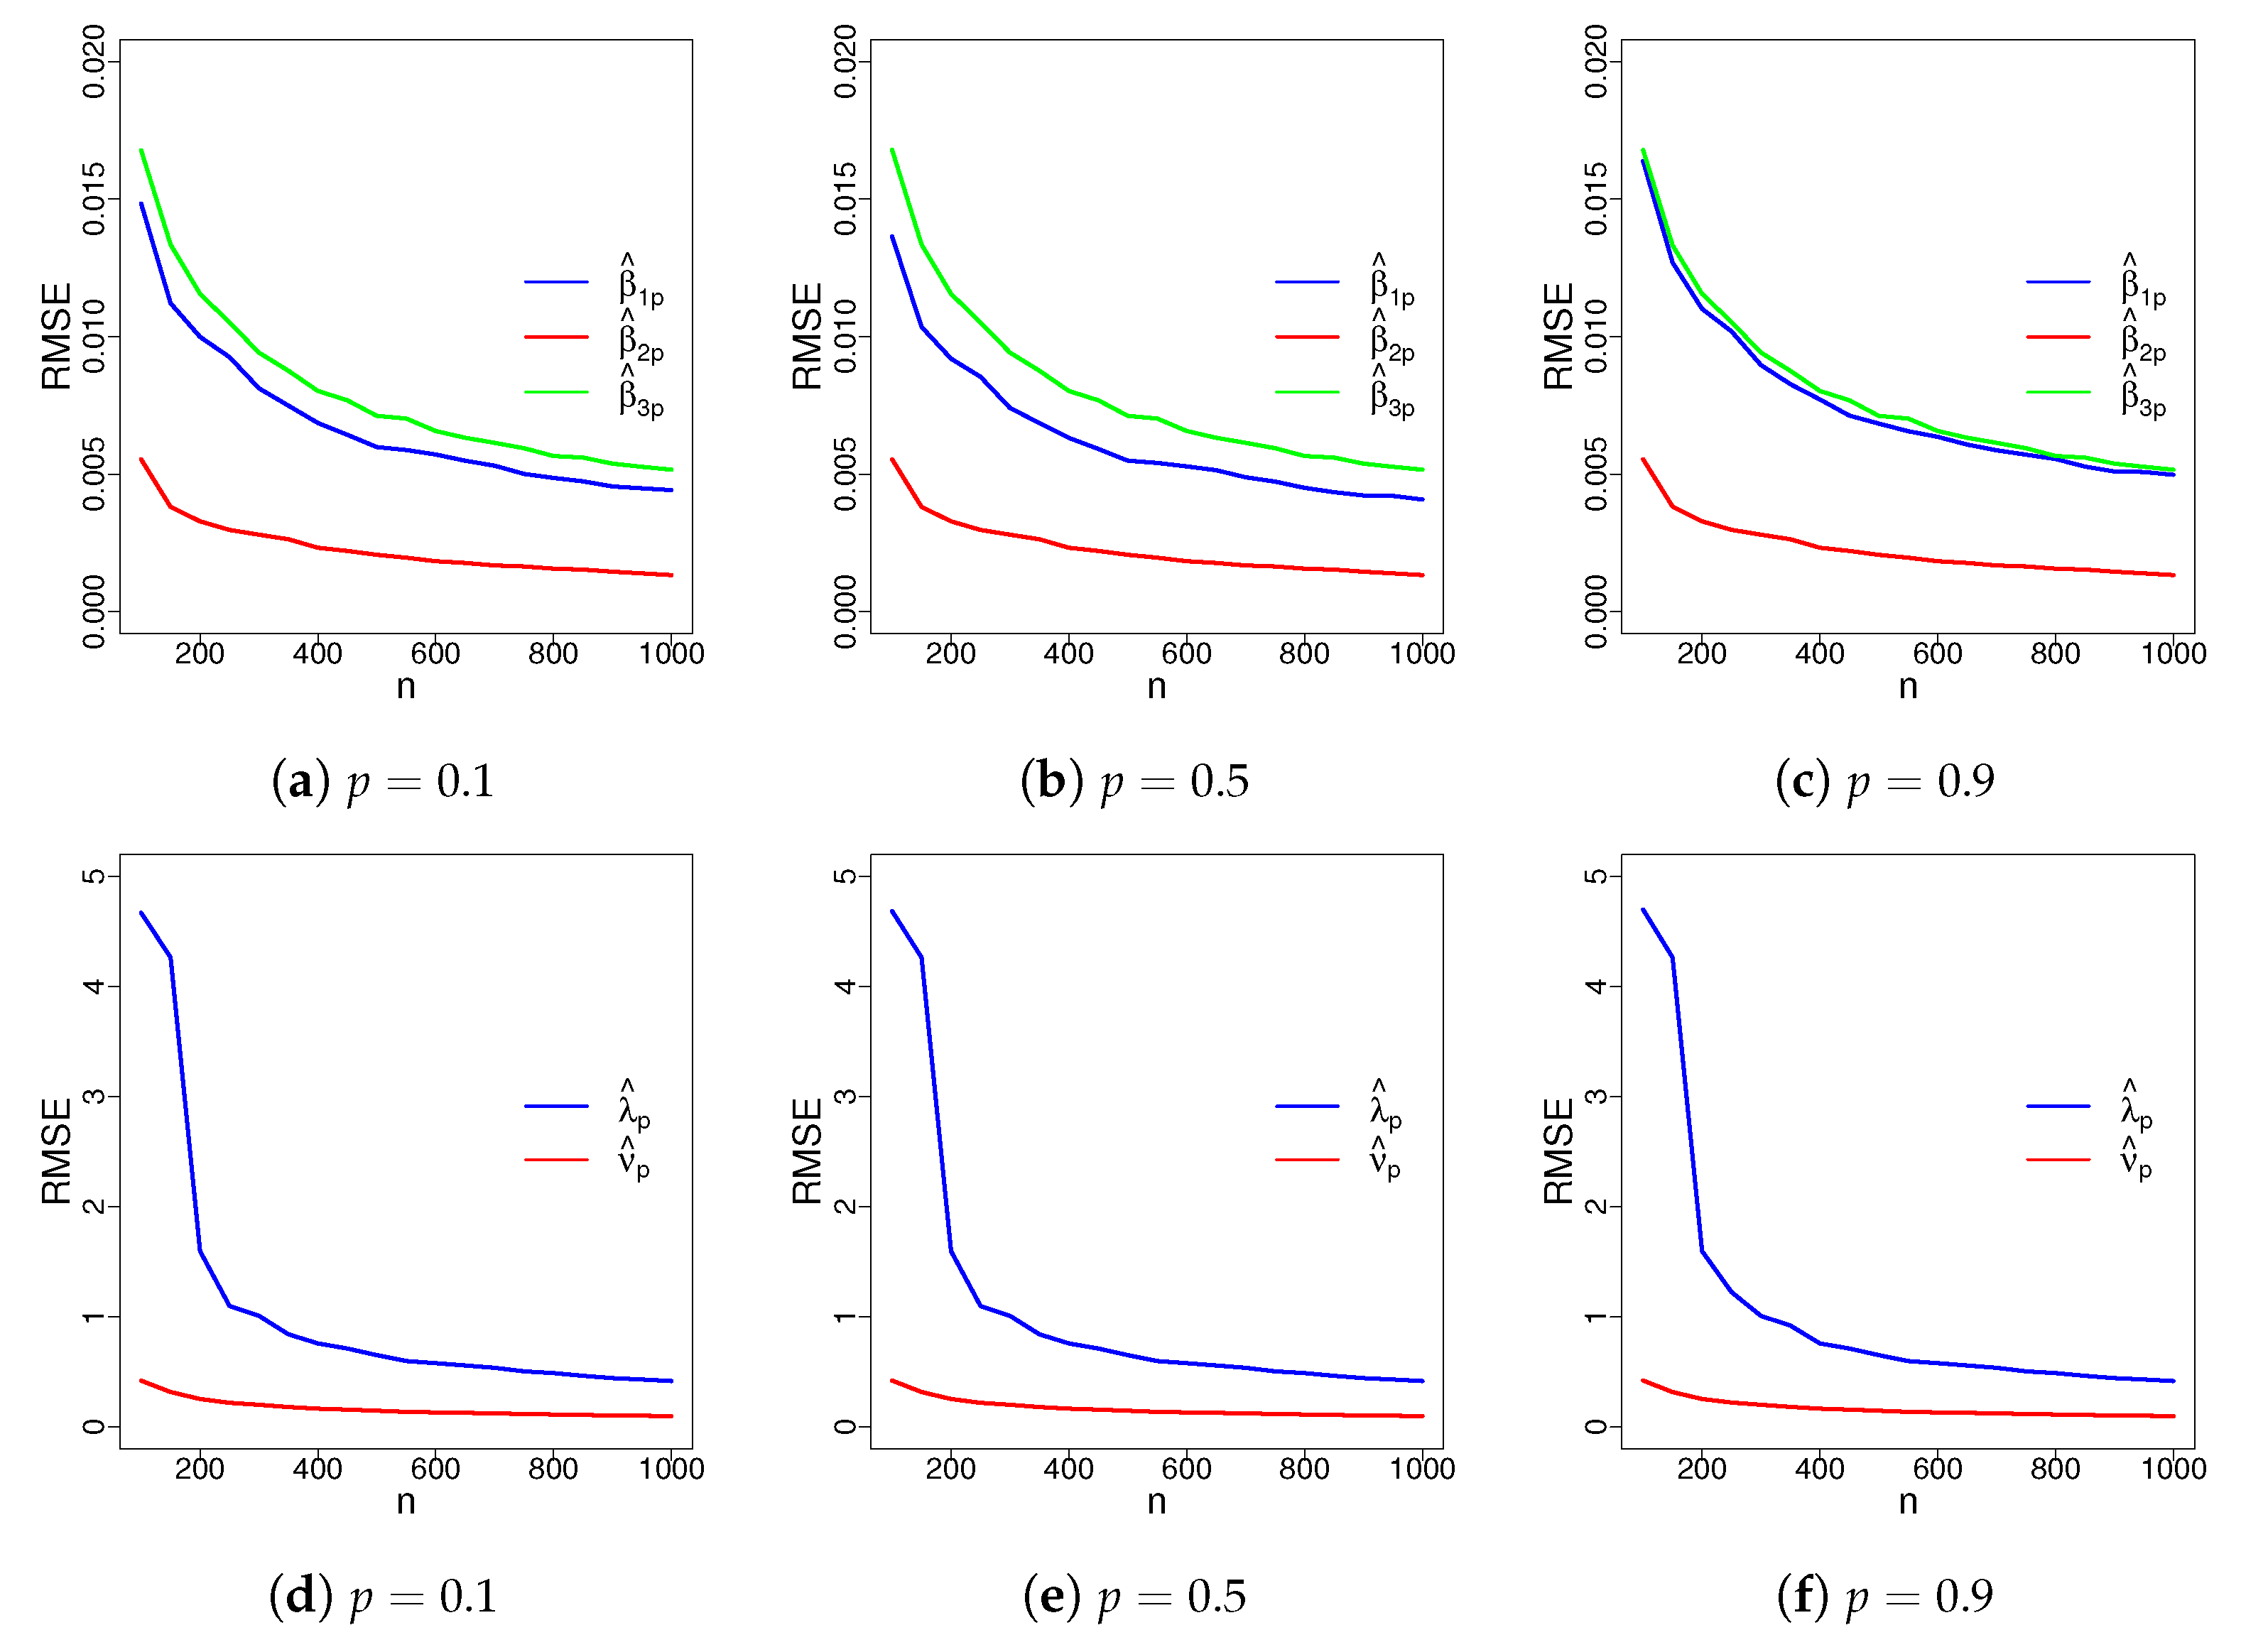
Figure A4.
Means of the RB on the 3000 estimates of , and obtained in the RGTG quantile regression under different sample sizes.
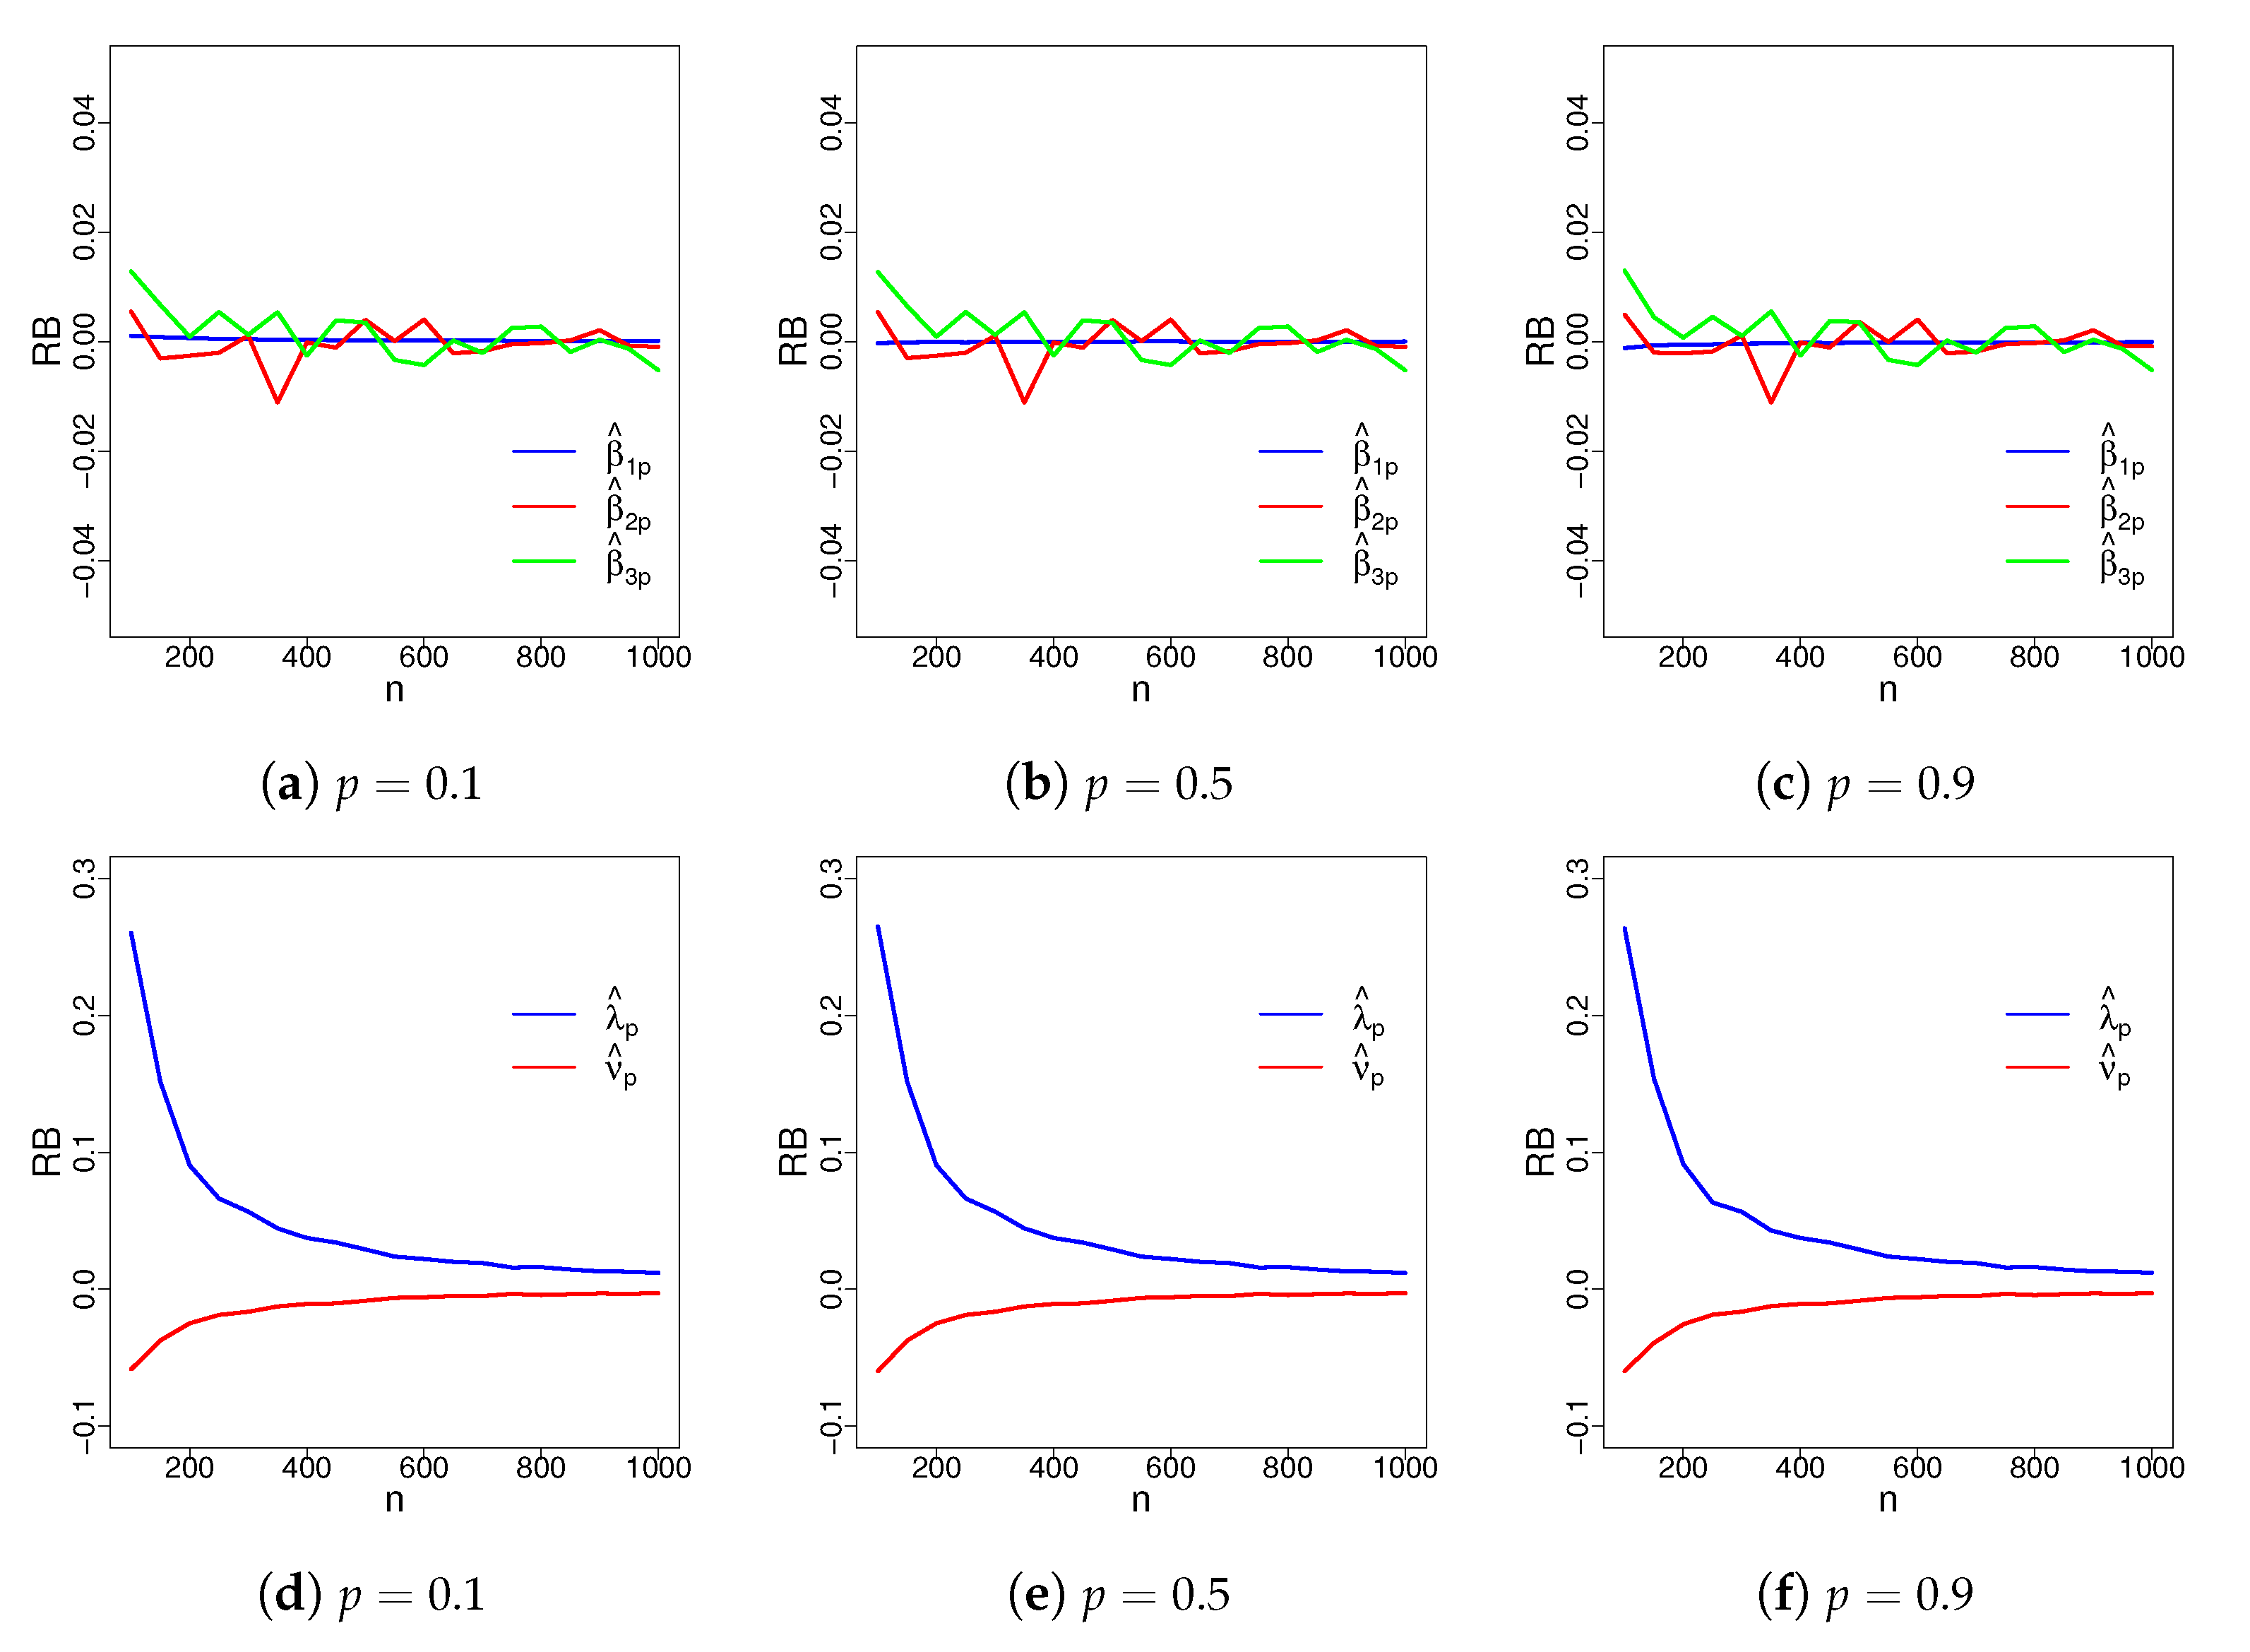
Figure A5.
95% CPs of the , and obtained in the RGTG quantile regression model under different sample sizes.
Appendix A.2. QQ-Plots
Figure A6.
QQ-plots with envelopes for the NQRs under the model from Equation (16) at different probabilities p.
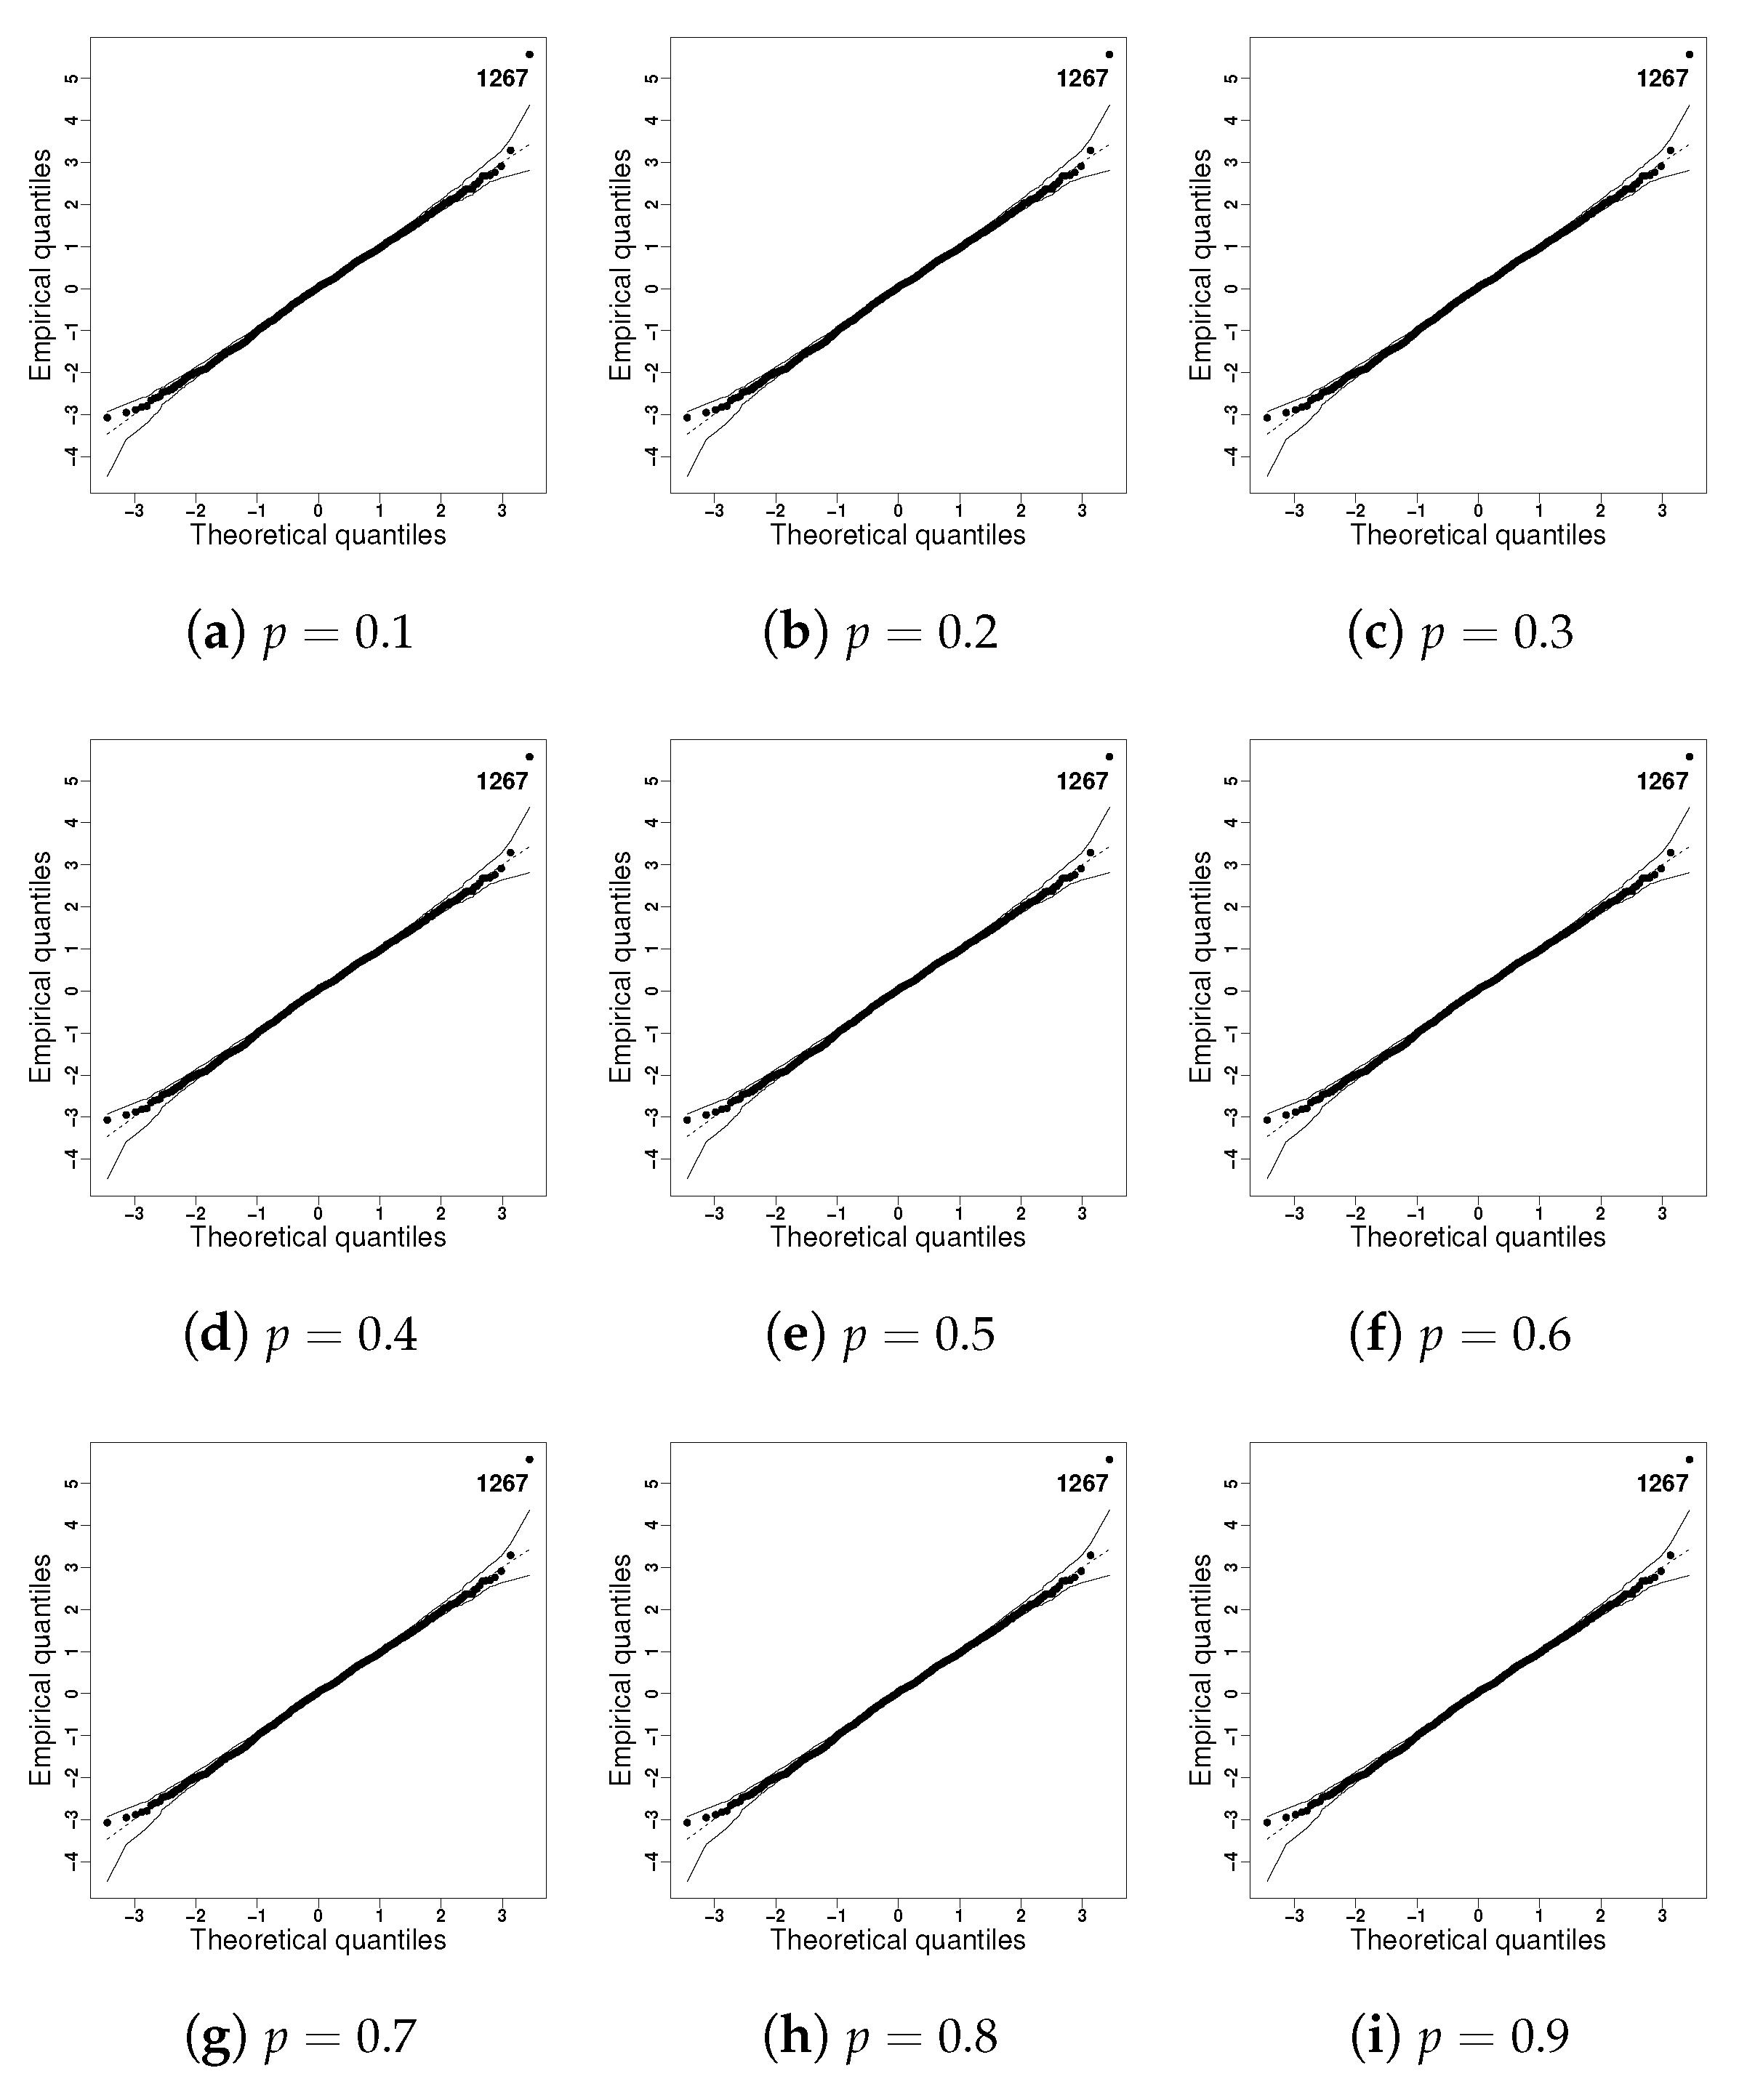
References
- Bhaskaran, S.; Verma, A.S.; Goupee, A.J.; Bhattacharya, S.; Nejad, A.R.; Shi, W. Comparison of Extreme Wind and Waves Using Different Statistical Methods in 40 Offshore Wind Energy Lease Areas Worldwide. Energies 2023, 16, 6935. [Google Scholar] [CrossRef] [Scilit]
- Gurung, B.; Sarkar, K.P.; Singh, K.N.; Lama, A. Modelling annual maximum temperature of India: A distributional approach. Theor. Appl. Climatol. 2021, 145, 979–988. [Google Scholar] [CrossRef] [Scilit]
- Purohit, S.U.; Lalit, P.N. European option pricing using Gumbel distribution. Int. J. Financ. Eng. (IJFE) 2022, 9, 2141002. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Qiao, H.; Yang, A. Reliability Study of Magnesium Oxychloride-Coated Reinforced Concrete Based on Gumbel Distribution. Materials 2023, 16, 2521. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kang, D.; Ko, K.; Huh, J. Determination of extreme wind values using the Gumbel distribution. Energy 2015, 86, 51–58. [Google Scholar] [CrossRef] [Scilit]
- Hossam, E.; Abdulrahman, A.T.; Gemeay, A.M.; Alshammari, N.; Alshawarbeh, E.; Mashaqbah, N.K. A novel extension of Gumbel distribution: Statistical inference with COVID-19 application. Alex. Eng. J. 2022, 61, 8823–8842. [Google Scholar] [CrossRef] [Scilit]
- Watthanawisut, A.; Bodhisuwan, B. The Beta Topp-Leone Gumbel Distribution for Modeling the Minimum Flow Data. Thai J. Math. 2020, 165–174. [Google Scholar]
- Fayomi, A. A new extended Gumbel distribution: Properties and application. PLoS ONE 2022, 17, e0267142. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Nagode, M. Gumbel mixture modelling for multiple failure data. Reliab. Eng. Syst. Saf. 2023, 230, 108946. [Google Scholar] [CrossRef] [Scilit]
- Oseni, B.M.; Okasha, H.M. Gumbel-geometric Distribution: Properties and Applications. Gazi Univ. J. Sci. 2020, 33, 935–941. [Google Scholar] [CrossRef] [Scilit]
- Koenker, R.; Bassett, G. Regression Quantiles. Econometrica 1978, 46, 33–50. [Google Scholar] [CrossRef] [Scilit]
- Cade, B.S.; Terrell, J.W.; Schroeder, R.L. Estimating Effects of Limiting Factors with Regression Quantiles. Ecology 1999, 80, 311–323. [Google Scholar] [CrossRef]
- Koenker, R. Quantile Regression; Cambridge University Press: Cambridge, UK, 2005. [Google Scholar]
- Wei, Y.; Pere, A.; Koenker, R.; He, X. Quantile regression methods for reference growth charts. Stat. Med. 2006, 25, 1369–1382. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Gómez-Déniz, E.; Leiva, V.; Calderín-Ojeda, E.; Chesneau, C. A novel claim size distribution based on a Birnbaum-Saunders and gamma mixture capturing extreme values in insurance: Estimation, regression, and applications. Comput. Appl. Math. 2022, 41, 171. [Google Scholar] [CrossRef] [Scilit]
- Neamah, M.W.; Qasim, B.A. A New Left Truncated Gumbel Distribution: Properties and Estimation. J. Phys. Conf. Ser. 2021, 1897, 12015. [Google Scholar] [CrossRef] [Scilit]
- Cooray, K.; Ananda, M.M. A generalization of the half-normal distribution with applications to lifetime data. Commun. Stat.-Theory Methods 2008, 10, 195–224. [Google Scholar] [CrossRef] [Scilit]
- Bonferroni, C.E. Elementi di Statistica Generale; Libreria Seber: Firenze, Italy, 1930. [Google Scholar]
- Arcagni, A.; Porro, F. The Graphical Representation of Inequality. Rev. Colomb. Estadística 2014, 37, 419–436. [Google Scholar] [CrossRef] [Scilit]
- R Core Team. R: A Language and Environment for Statistical Computing; R Foundation for Statistical Computing: Vienna, Austria, 2023; Available online: https://www.R-project.org/ (accessed on 12 October 2023).
- Wang, H.; Chen, W.; Li, B. Large sample properties of maximum likelihood estimator using moving extremes ranked set sampling. J. Korean Stat. Soc. 2024, 53, 398–415. [Google Scholar] [CrossRef] [Scilit]
- Gómez, H.J.; Gallardo, D.I.; Santoro, K.I. Slash Truncation Positive Normal Distribution and its Estimation Based on the EM Algorithm. Symmetry 2021, 13, 2164. [Google Scholar] [CrossRef] [Scilit]
- Akaike, H. A new look at the statistical model identification. IEEE Trans. Autom. Control 1974, 19, 716–723. [Google Scholar]
- Schwarz, G. Estimating the dimension of a model. Ann. Stat. 1978, 6, 461–464. [Google Scholar] [CrossRef] [Scilit]
- Cortés, I.E.; De Castro, M.; Gallardo, D.I. A new family of quantile regression models applied to nutritional data. J. Appl. Stat. 2023, 1–21. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Dunn, P.K.; Smyth, G.K. Randomized quantile residuals. J. Comput. Graph. Stat. 1996, 5, 236–244. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2024 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).