


Abstract
In this work, a bivariate extension of the univariate exponentiated sinh-normal distribution is proposed. The properties of the new distribution, which is called the bivariate exponentiated sinh-normal distribution, are studied in detail, and the maximum likelihood method is considered to estimate the unknown model parameters. In addition, the extension of the new distribution to the case of regression models is proposed. Monte Carlo simulation experiments are carried out to investigate the performance of the used estimation method, and two applications to real datasets are presented for illustrative purposes.
Keywords:
sinh-normal distribution; exponentiated distribution; maximum likelihood estimation; two-stage estimation procedure MSC:
60E05; 62H05
1. Introduction
The univariate sinh-normal (SHN) model was introduced by Rieck and Nedelman [1] as a non-linear transformation of the normal distribution. A random variable (RV) Z, is said to have a three-parameter SHN model, denoted by , if,
where is a shape parameter, is a location parameter and, is a scale parameter. The probability density function (PDF) of an RV following the distribution, is given by:
where and is the derivative of regarding the Z variable. The SHN distribution is also known as the log-Birnbaum–Saunders (LBS) model. Notice that if , and , then it follows a Birnbaum–Saunders (BS) distribution with parameters and , which is denoted by
The BS distribution was proposed by Birnbaum and Saunders [2] to explain the survival time and the stress produced in the material because of the law of occurred cumulative damage. The BS distribution can also be obtained by applying a non-linear transformation to the normal model, and more details about this distribution can be found in Birnbaum and Saunders [2,3]. Extensions of the BS model to the family of elliptical distributions, or symmetric family of distributions were introduced by Díaz-García and Leiva-Sánchez [4], which are known in the literature as generalized BS (GBS) distribution. Several authors have considered other extensions. For example, Vilca-Labra and Leiva-Sánchez [5] extended the GBS model to situations of skew-elliptical distributions, while Martínez-Flórez et al. [6] studied the BS distribution by supposing that Z follows a power-normal (PN) distribution. The resulting model is called exponentiated BS or alpha-power BS distribution.
The PN distribution, also known as the exponentiated normal model, has been studied by Durrans [7], Gupta and Gupta [8] and Pewsey et al. [9], among others. It is said that the RV Z follows a PN distribution with parameter , which is denoted by , if its PDF is given given by:
where is a parameter that controls the shape of the distribution. The cumulative distribution function (CDF) of the PN model is . On the other hand, the PDF of the RV T, following an alpha-power Birnbaum–Saunders distribution, is given by:
where is:
which is denoted by More information about the BSPN model can be found in Martínez-Flórez et al. [6]. A generalization to the asymmetric models of the SHN distribution was proposed by Leiva et al. [10]. These authors considered that RV Z follows a skew-normal (SN) distribution with parameter , see Azzalini [11]. Thus, the resulting PDF is:
The model in (5) is called log-skew-Birbaum–Saunders, and is denoted by . In addition, Martínez-Flórez et al. [12] proposed an asymmetric extension of the SHN model, by supposing that , resulting in the following alpha-power sinh-normal model,
which is denoted by and, its CDF is given by:
One can show that if , then . An extension of the log-Birnbaum–Saunders (LBS) distribution to regression models has been considered in Rieck and Nedelman [1], which became known as the log-linear BS regression model and can be written as:
where is the log-survival time corresponding to the ith experimental unit, is an unknown parameter vector and is a p-dimensional vector with known values of the explanatory variables and, are independent and identically distributed RVs with .
Univariate asymmetric extensions for the log-BS linear regression model have been given by Leiva et al. [10], Lemonte [13] and Martínez-Flórez et al. [12]. The first two proposals assume that the errors follow an asymmetric sinh-normal distribution, while the latter proposal provides an alpha-power sinh-normal distribution. This latest model is called the log-Birnbaum–Saunders alpha-power normal regression model, which is denoted by .
Some extensions for the bivariate or multivariate situations of the BS and SHN models have been treated in the literature for the cases of symmetric and asymmetric distributions. Díaz-García and Domínguez-Molina [14] for example, introduced a multivariate version of the sinh-normal distribution. The authors defined a multivariate vector with multivariate sinh-normal distribution, denoted by , where is the identity matrix of size . The PDF of is:
Lemonte [15] introduced a version of the multivariate BS regression model, which generalizes the univariate regression model introduced by Rieck and Nedelman [1]. This model is supposed to have n multivariate RVs and, each one measures a number of responses . Thus, in the multivariate log-linear regression model for , it is assumed that where and are vectors of ones and zero, respectively, of size Martínez-Flórez et al. [16] proposed the multivariate log-BS regression model, and Romeiro et al. [17] studied a robust multivariate BS regression model. Marchant et al. [18] considered a multivariate log-linear model for BS distributions. As can be seen, few works have been published where the multivariate log-BS regression model is studied, so new extensions are welcome for this important and applicable case of regression models in survival analyses and other areas of knowledge.
In other cases, multivariate distributions can be built based on the theory of copula for distributions where the marginal distributions are known by using the Sklar’s Theorem, see [19,20]. The way to construct a multivariate distribution from Sklar’s Theorem is as follows: Let be p RVs with continuous CDFs respectively, then, according to Sklar’s theorem, has a unique copula representation:
Moreover, it is well known that many dependence properties of a multivariate distribution depend only on the corresponding copula. Therefore, many dependence properties of a multivariate distribution can be obtained by studying the corresponding copula. Particularly in the case of marginal distributions with distribution SHN, based on the bivariate normal copula, Kundu [21] proposed the bivariate sinh-normal distribution. Specifically, the random vector is said to have a bivariate sinh-normal distribution, which is denoted by if for and , its joint CDF is:
where denotes the CDF of the bivariate normal distribution and is the parameter that controls the dependency relationship in the bivariate normal copula. Kundu [21] studied the main properties of the BSHN model. Kundu and Gupta [22] proposed a bivariate extension for the power-normal model and studied the main properties of the model. This proposal was made by using the Clayton copula. The Clayton copula is usually attributed to Clayton [23]; however, it has been used by Kimeldorf and Sampson [24], and it is defined for as:
The first systematic study of this model was made by Cook and Johnson [25], who interpreted the parameter as a measure of dependence between u and Therefore, independence between variables is obtained when approaches zero. This dependency model can be extended to the multivariate case by considering a p-variate Clayton copula, which is defined by:
where for . Using Equation (9), Kundu and Gupta [22] considered that for , with respective CDF and defined the bivariate PN distribution, which is denoted by for and . The joint CDF is:
where is the parameter that controls the dependency in the Clayton copula.
Lemonte et al. [26] introduced the bivariate Birnbaum–Saunders power-normal (BVBSPN) distribution, which is defined below.
Definition 1.
A bivariate random vector has a BVBSPN distribution, if its joint PDF is given by:
where for and We use the notation
Properties of the BVBSPN distribution as well as the estimation process of the parameters can be seen in Lemonte et al. [26].
In this paper, the goal is to build a skewed bivariate version of the sinh-normal model by assuming that the marginal distributions follow a model and then to study the bivariate sinh-normal regression model. The rest of the paper is organized as follows: In Section 2, we consider the bivariate extension of the univariate SHN power-normal distribution. We study this bivariate extension in detail, derive several of its main properties and perform the estimation process of the model parameters by using the maximum likelihood (ML) method. Section 3 deals with the extension to the case of regression models through the incorporation of covariates. Section 4 presents a Monte Carlo simulation study that was carried out to evaluate the performance of the direct approach to estimate the unknown parameters. Two applications of real datasets for illustrative purposes are presented in Section 5. Finally, Section 6 closes the paper with some concluding remarks.
2. Bivariate Sinh-Normal Exponentiated Distribution
Extending the definition of a sinh-normal RV as a non-linear transformation of a normal RV, we define a vector with bivariate exponentiated sinh-normal distribution.
Definition 2.
A bivariate random vector has a bivariate exponentiated sinh-normal standard distribution, denoted by , if its joint CDF is given by:
where is the parameter that controls the dependency in the Clayton copula and for .
The joint PDF of can be written as:
where for . The joint survival function of is then:
Theorem 1.
If then:
- (i)
- for .
- (ii)
- The CDF of given is:
- (iii)
- , and consequently, , for
Proposition 1.
Let ,
- (i)
- If it follows that .
- (ii)
- .
- (iii)
- .
- (iv)
where for
The following proposition relates the bivariate BS and the bivariate sinh-normal models. This proposition is an extension of the property of the univariate case where the BS distribution and the sinh-normal model are related and by which the model sinh-normal regression is called log-Birnbaum–Saunders (LBS).
Proposition 2.
Let If , then
Proof.
Given that, for , then and thus,
In addition, since , it follows that the Jacobian of the inverse transformation is By using a similar argument to that of , it has that:
By the transformation method for bivariate functions, the result follows. □
One can use Proposition 2 to generate samples from the standard bivariate exponentiated sinh-normal distribution presented in Definition 2. In this case, to generate the bivariate vector with a BSHPN distribution, the algorithm described in Lemonte et al. [26] to generate a BVBSPN is used joint the Proposition 2 with scale parameters and , respectively. To obtain scale and , it is enough to consider the transformed variables, say and as and
Definition 3.
A function g defined in is said to be totally positive of order 2, denoted by , if for all and with ,
Definition 4.
If , then is
Proposition 3.
Let , then is stochastically non-decreasing in and vice versa, for any value of
Found by Kundu and Gupta [22] from the Clayton copula for the BPN model, it follows that for any value of , and the Kendall’s tau and median correlation coefficients become, respectively:
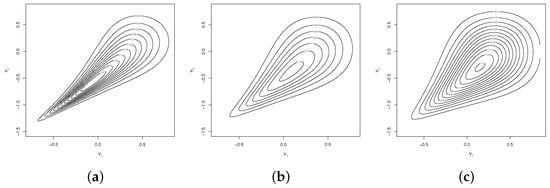
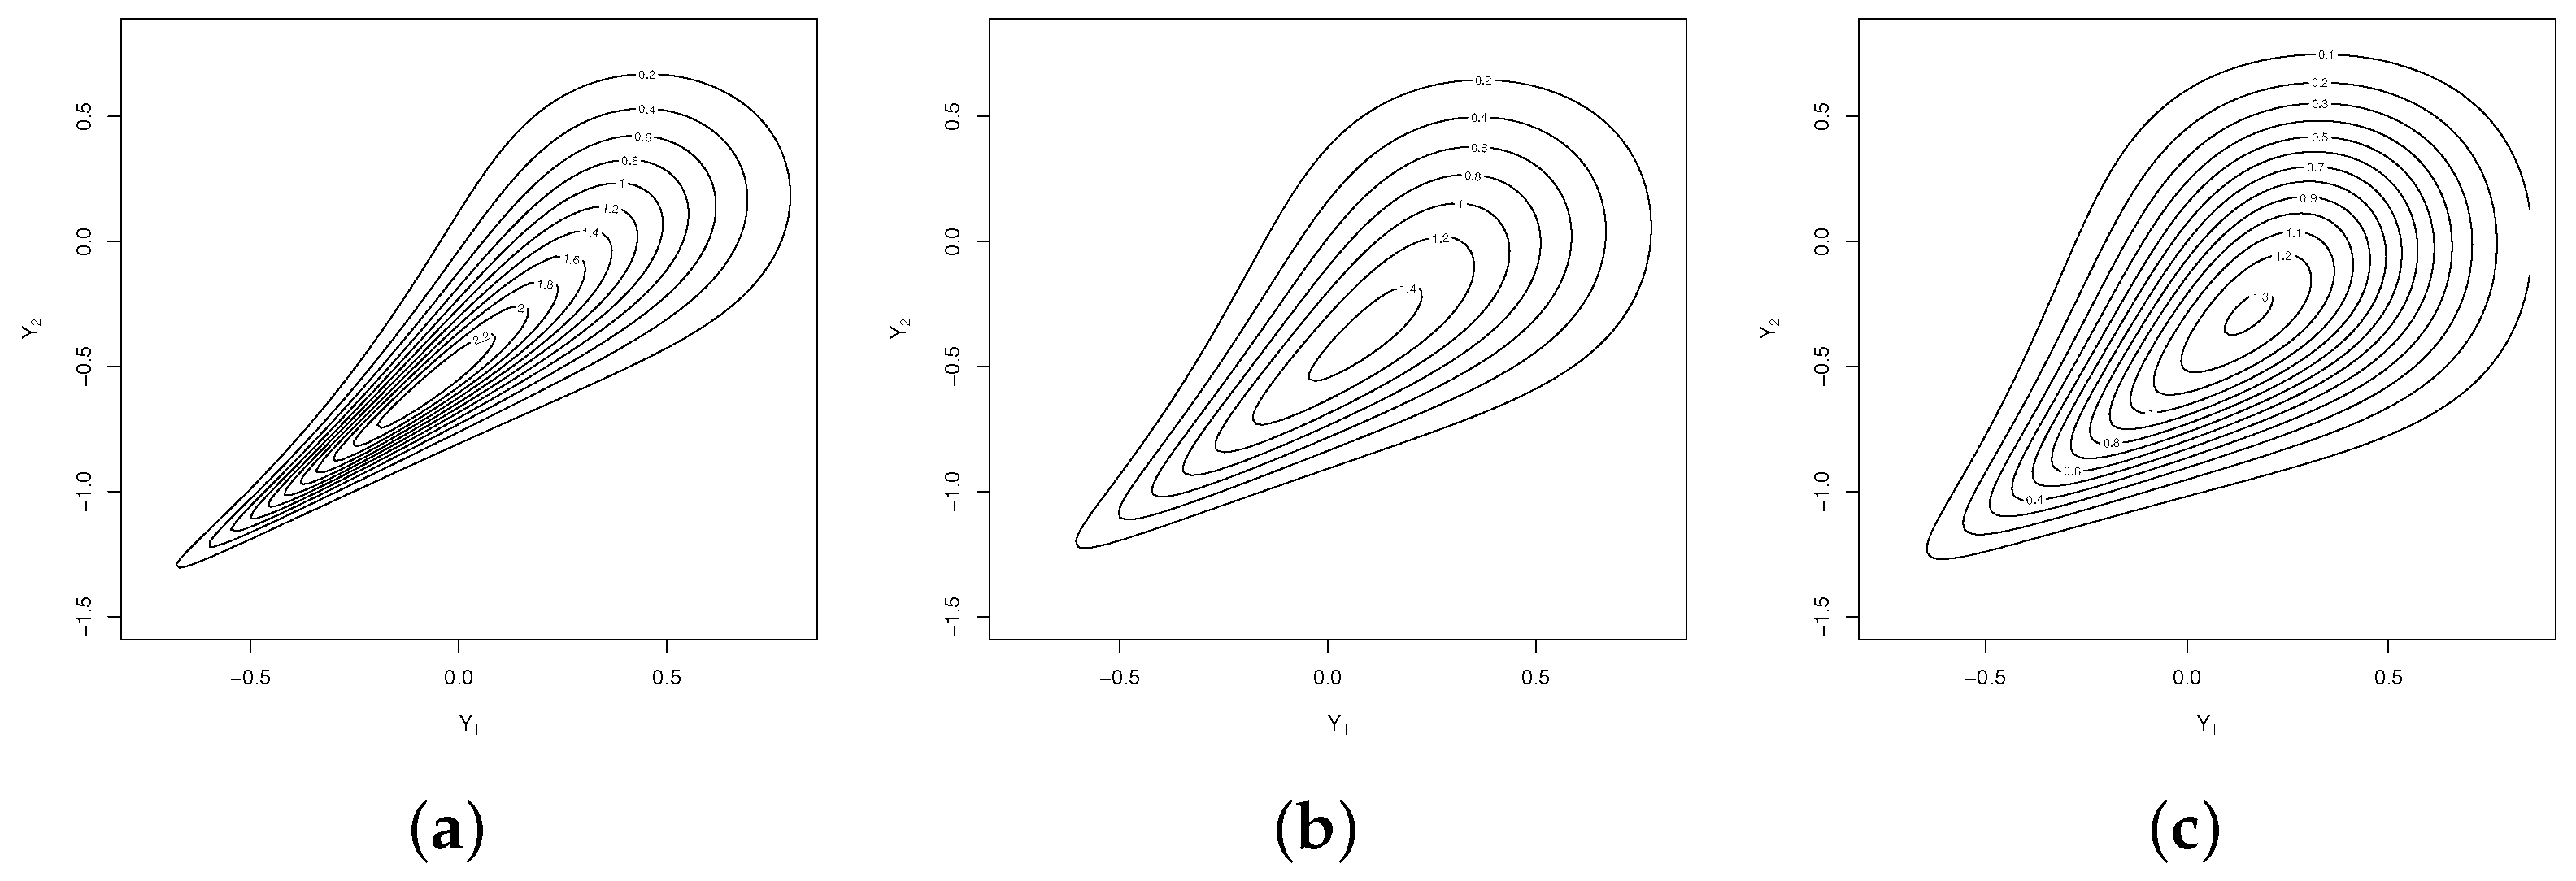
Figure 1 shows the behavior of the distribution, for some selected values of . The influence of the parameter when the marginal distributions have a dependency structure can be seen.
Figure 1.
Density plots. (a) , (b) and (c) .
Statistical Inference
Given the dependence structure induced by Clayton’s copula for the estimating the process of the model parameters , it is used for the maximum likelihood estimation (MLE) and the two-stage estimation method of Joe [27]. For the MLE, we perform a parameterization on then; our focus is on the estimated parameter vector . Thus, for a sample of size n from a distribution, let , the log-likelihood function is given by:
which, upon maximization regarding , , for and , leads to the following equations:
where and for Numerical approaches are required for solving the above system of equations. The observed information matrix follows from minus the second derivatives of the log-likelihood function, this is,
The observed information matrices for both parametrizations and obey the relation , where is a matrix containing derivatives of elements of the vector respect to elements of the vector From this relation, we can write , and . Therefore,
where and, is of the size defined by:
That is, is a block-diagonal matrix and it can be shown to be non-singular. Assuming the existence of the inverse of the matrix, given the regularity of the PN family, it follows that for large samples, the MLE of the parameter vector , is asymptotically normal, that is,
resulting that the asymptotic variance of the MLE , is the inverse of , which we denote by .
Joe [27] proposed a method for estimating copula models which consists of a two-step process as follows: the first step is based on the marginal distributions of the variables which the original model parameters are estimated, in this case, we have the model for Then, assuming that for each , the estimating equations that lead to MLE of the parameter vector are:
where Then, the MLE for the parameters and are the solutions to the equations and , which require numerical procedures.
In the second step, we replace the estimates found in the log-likelihood function step, so everything is limited in maximizing the resulting respective function log-likelihood, i.e., to maximize the function:
where
The elements of the information matrix are given by , with,
Here,
and . The second derivatives are calculated from the log-likelihood function defined in (14) and expectations are calculated numerically by taking the corresponding elements of the matrix .
Finally, , where with being the log-likelihood function of the marginal distributions for the parameter vector and where expectations are calculating regarding the marginal distributions. On the other hand, according to Joe [27], where:
for , with:
The elements of can be obtained numerically by using the model from its respective integrals.
3. Log-BSHPN Regression Model
Regression analysis, despite being a powerful tool in studies where you want to explain a set of dependent variables according to another set of variables, explanatory or dependent, merely assumes a distribution for that models errors, which generally contains at least one parameter that accounts for the correlation among the variables of interest. We now propose to use a distribution that not only contains the parameters of the proposed model, but also explain the structure of marginal dependence of the model errors, from the copula model BSHPN. It stands to reason that if the proposed distribution can explain the structure of dependence between marginal distributions, the best fit is obtained with conventional models that only take a distribution for the errors, since the correlation between variables is implicit in the dependence structure.
3.1. New Model
On the log-Birnbaum–Saunders power-normal (LBSPN) model proposed by Martínez-Flórez et al. [12], it is assumed that the errors follow a distribution and, therefore, the RV , where T represents the survival time, follows the distribution with being the parameters vector and, a p-dimensional vector with values of the set of explanatory variables.
We extend this univariate exponentiated log-linear Birnbaum–Saunders regression model to the case of a bivariate vector. We considered the situation where the bivariate random vector is collected, and the number of measured responses in each observation is n, with denoting a vector of observed dependent variables. Then, by defining a vector of size and a matrix of size with of size and of size and being the vec operator which transforms a matrix in a column vector. Then, the bivariate log-linear Birnbaum–Saunders power-normal regression model, previously defined can be represented as:
where a vector of size and a vector of size , with . That is:
The regression model given in (15) is denoted by , where , and 1 is a vector of numbers one of size 2.
For Theorem 1, it follows that satisfying for ,
- (1)
- where is a vector of unknown parameters.
- (2)
- The shape and skewness parameters in the model do not involve , that is, for , and .
3.2. Inference for the Log-BSHPN Regression Model
In order to estimate the parameters of the model, for a sample , where we define the following expressions: and , with and , where and
To obtain MLEs, we proceed with the same re-parameterization as in the case of the BSHPN model. Then, the log-likelihood function can be written as:
The score functions for the parameter vector are:
where and for Numerical approaches are required for solving the above system of equations. Again, as in the case of BSHPN model, the information matrices can be obtained from the relationship and . Therefore,
where and is defined as in the BSHPN model. In the same way of the model BSHPN, the two-step algorithm can be implemented by maximizing the log-likelihood function (17) for each response variable.
We have that the score function is given by:
The MLEs for the regression parameters and parameters and are the solutions of the equations and , which require numerical procedures. The information matrix can be obtained by proceeding as in the BSHPN model case.
4. Simulation Studies
To investigate the asymptotic properties of the MLEs of the parameters in the introduced models, we conducted two Monte Carlo simulation studies.
4.1. Model without Covariates
In the first simulation, we studied the performance of the MLE of the BSHPN model. We considered the values of the parameters and and and . Without loss of generality, we took and random sample sizes of and 100. For each combination of parameters and sample size, 5000 random samples of the BSHPN model were generated. We used the direct MLE method and, to evaluate the performance of the estimators, the absolute value of the relative bias (RB) and the empirical standard deviation (ESD) were considered. To calculate the MLEs of the parameters, the optim function of the R Development Core Team [28] was used, in joint with iterative methods based on the Newton–Rapshon algorithm to optimize the likelihood function. The results are given in Table 1.
Table 1.
RB and ESD for the BSHPN model.
In general, it can be seen that for the considered sample sizes in the simulation, the RB of the parameter estimators gradually decreases as the sample size increases. This decreasing behavior occurs for some estimators more quickly than for others. In particular, the RB of the , and estimators decreases slowly for values of the parameter . In addition, the ESD has a similar behavior to the RB, with a tendency to decrease. This guarantees the asymptotic convergence of the MLEs of the BSHPN model parameters.
4.2. Model with Covariates
In the second simulation study, we analyzed the behavior of the MLEs of the parameters in the RBSHPN model presented in Section 3. For we generated the covariates and , and we took the values of the coefficients as . We also took the parameter values and and . For each scenario considered, we generate Monte Carlo samples of sizes and 120. Again, we used the absolute value of the RB and ESD to assess the goodness of the MLEs.
Similar to the case without covariates, the results in Table 2 and Table 3 show that the RB of some estimators decreases faster than others. For the , , and estimators, for example, it can be seen that the RB tends to zero when the sample size increases, while the estimator presented higher RB relating to the previous estimators, and they decrease more slow. For the , , and estimators, the RB decreases slowly when the value of n increases. Relating to the ESD, Table 2 and Table 3 show that the estimator presented the highest values of ESD; however, it can be seen that when going from to , the value of the ESD decreased. On the other hand, the estimator with the lowest ESD values was . The previous discussion suggests considering moderate or large sample sizes to achieve a desirable quality in the estimation of the parameters of the fitted models.
Table 2.
RB and ESD for the BSHPN regression model.
Table 3.
RB and ESD for the BSHPN regression model.
5. Illustrations
5.1. First Illustration
To illustrate the applicability of the BSHPN model, we used a dataset available in Johnson and Wichern [29], which corresponds to environmental pollution measures in some areas of the city of Los Angeles, which were taken at noon for several days. It is well known that the concentration of average air pollutants has been used in epidemiological surveillance as an indicator of the level of atmospheric contamination and its associated adverse effects in humans, for example, causing diseases such as bronchitis.
For air pollutant concentration, it is usually assumed that the data are uncorrelated and independent and thus, it does not require the diurnal or cyclic trend analysis; see Gokhale and Khare [30]. The data correspond to measures of carbon dioxide (CO) and, ozone concentration (O), in the atmosphere.
Initially, we estimate univariate SHN and SHPN models for each variable. The parameter estimates (standard error) for the SHN model for the variable CO are and , while for the variable O we obtained the estimates and . As found in Kundu [21], the marginal distributions follow a , , distributions. The Kolmogorow–Smirnov test, with respective p-values given in parentheses, are given by and .
For the model with , we obtained the estimates and while for the variable O, the obtained estimates were and The Kolmogorow–Smirnov values were and , respectively.
From the Kolmogorow–Smirnov distances and their respective p-values, it is clear that the , , models fit better the data than the , , models. Rieck and Nedelman [1] showed that for the SHN model; while Martínez-Flórez et al. [16] showed that for the SHPN model.
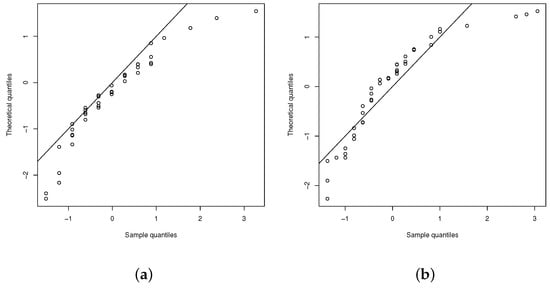
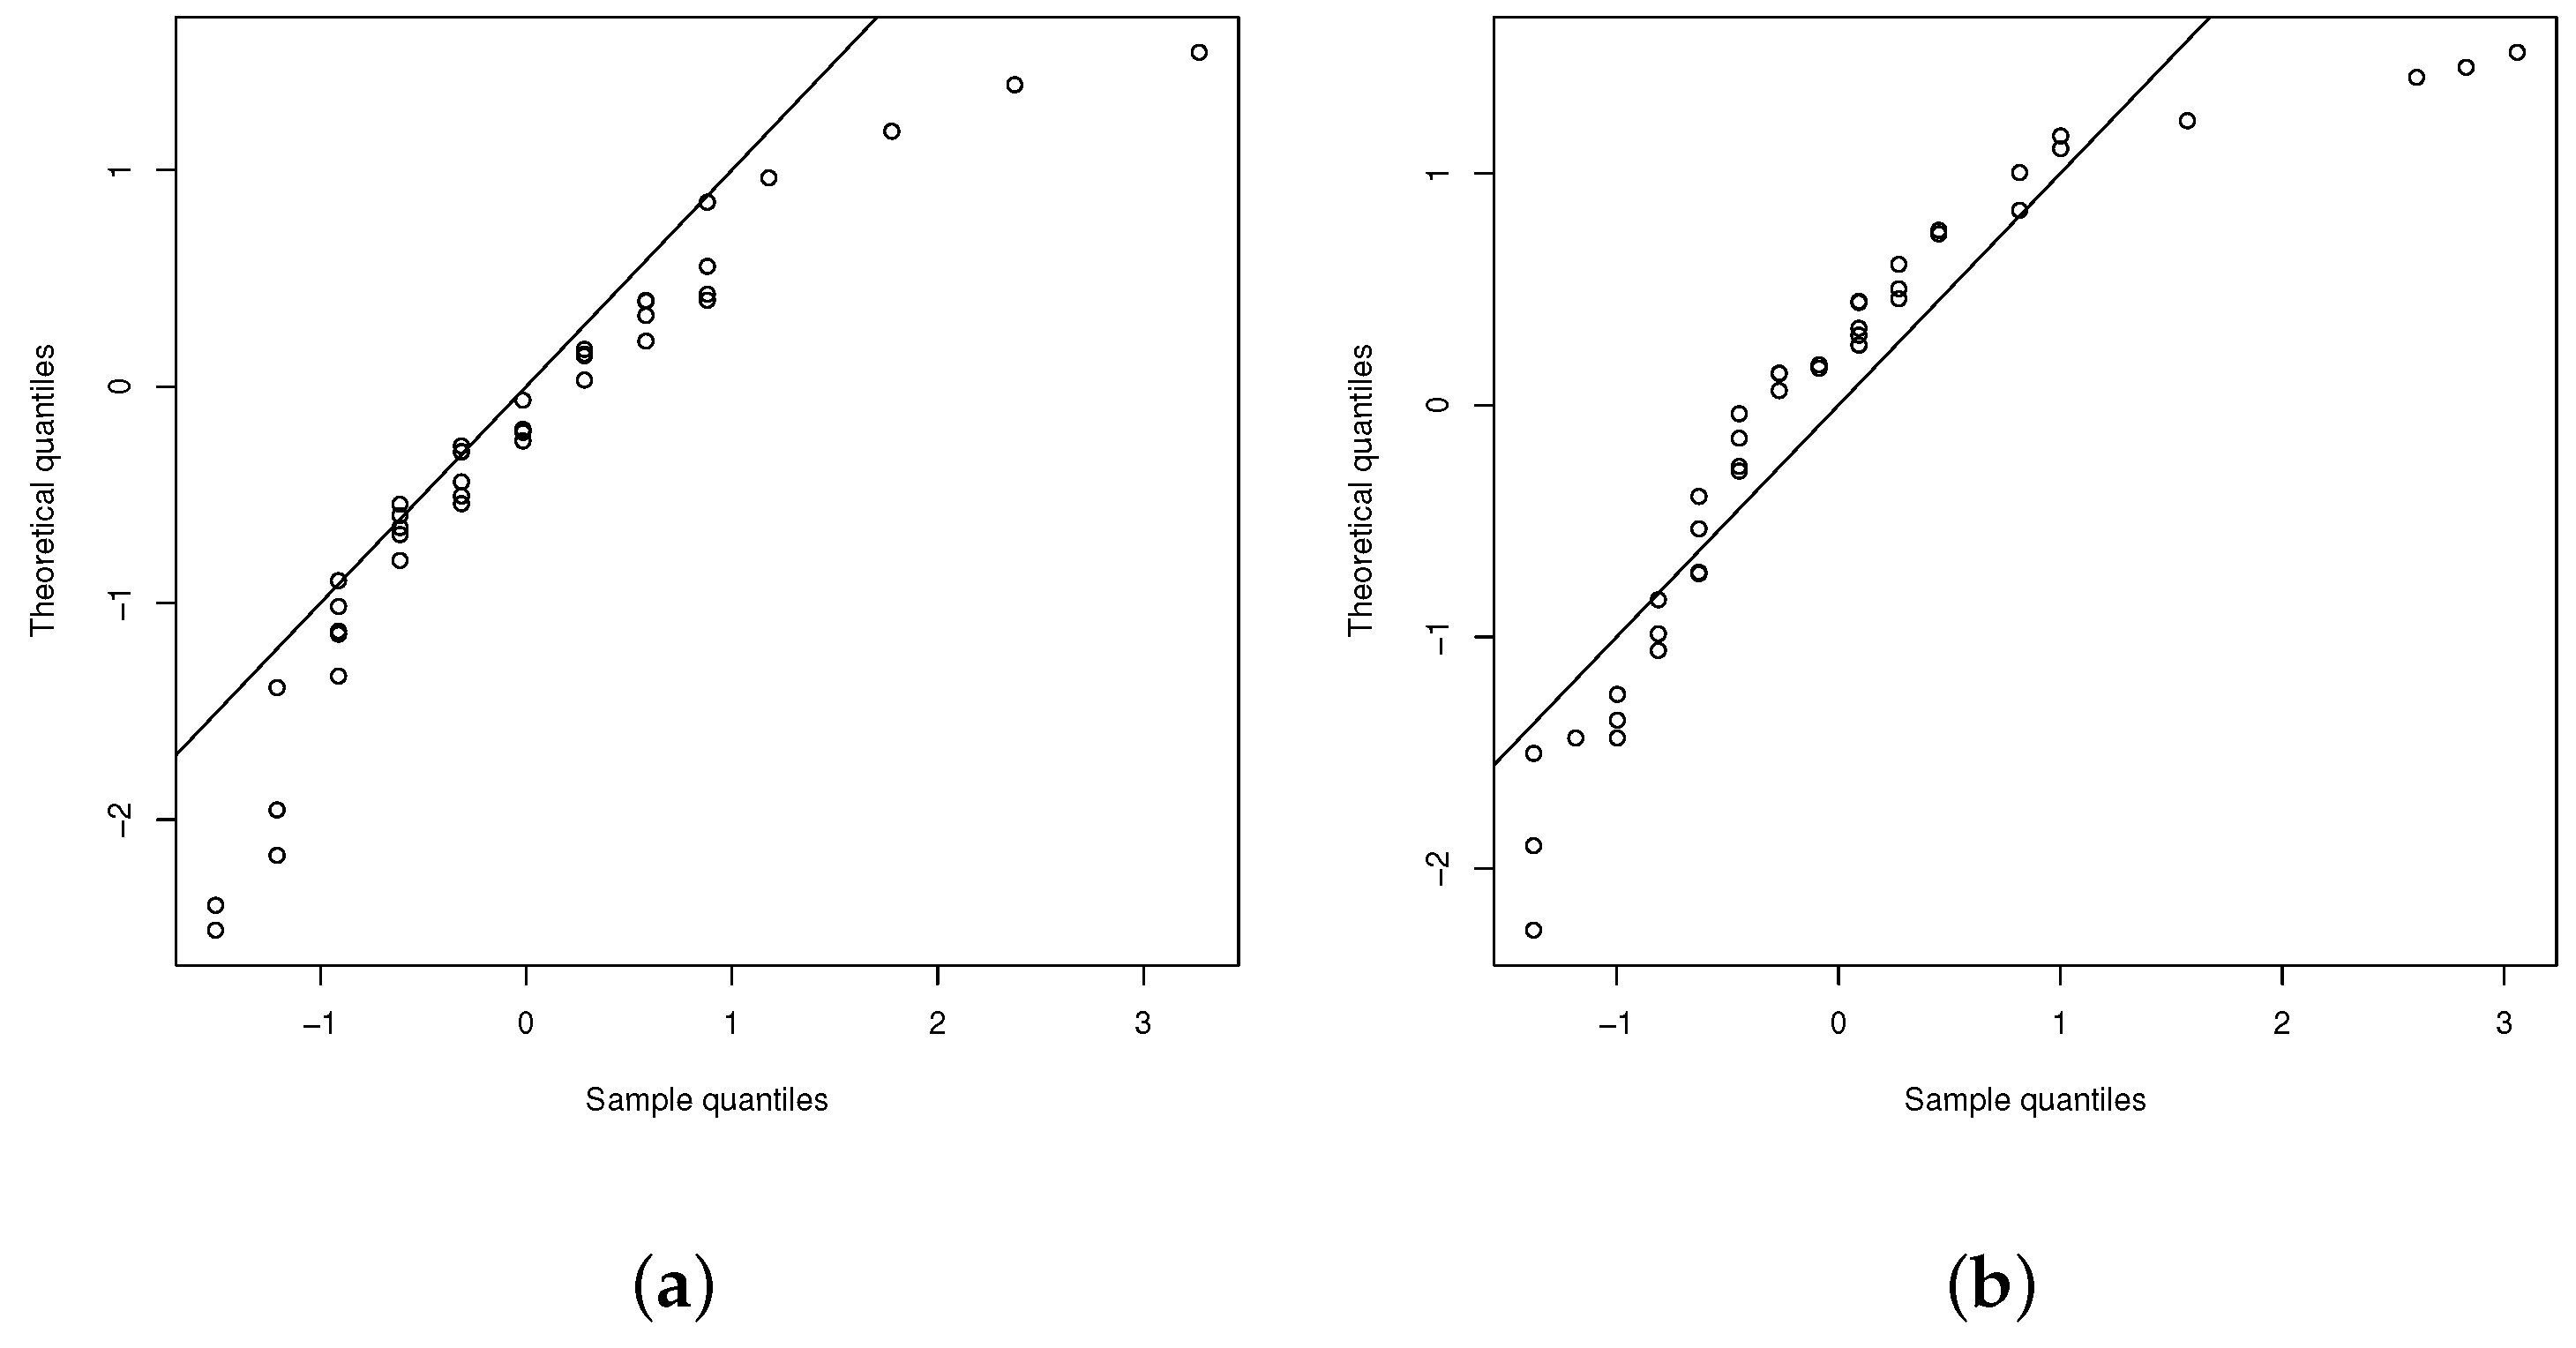
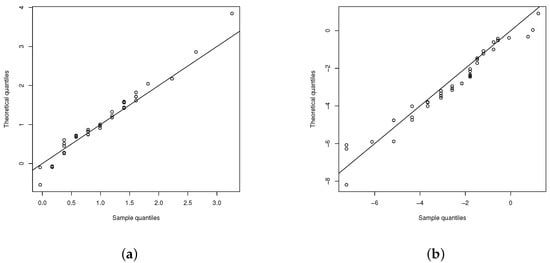
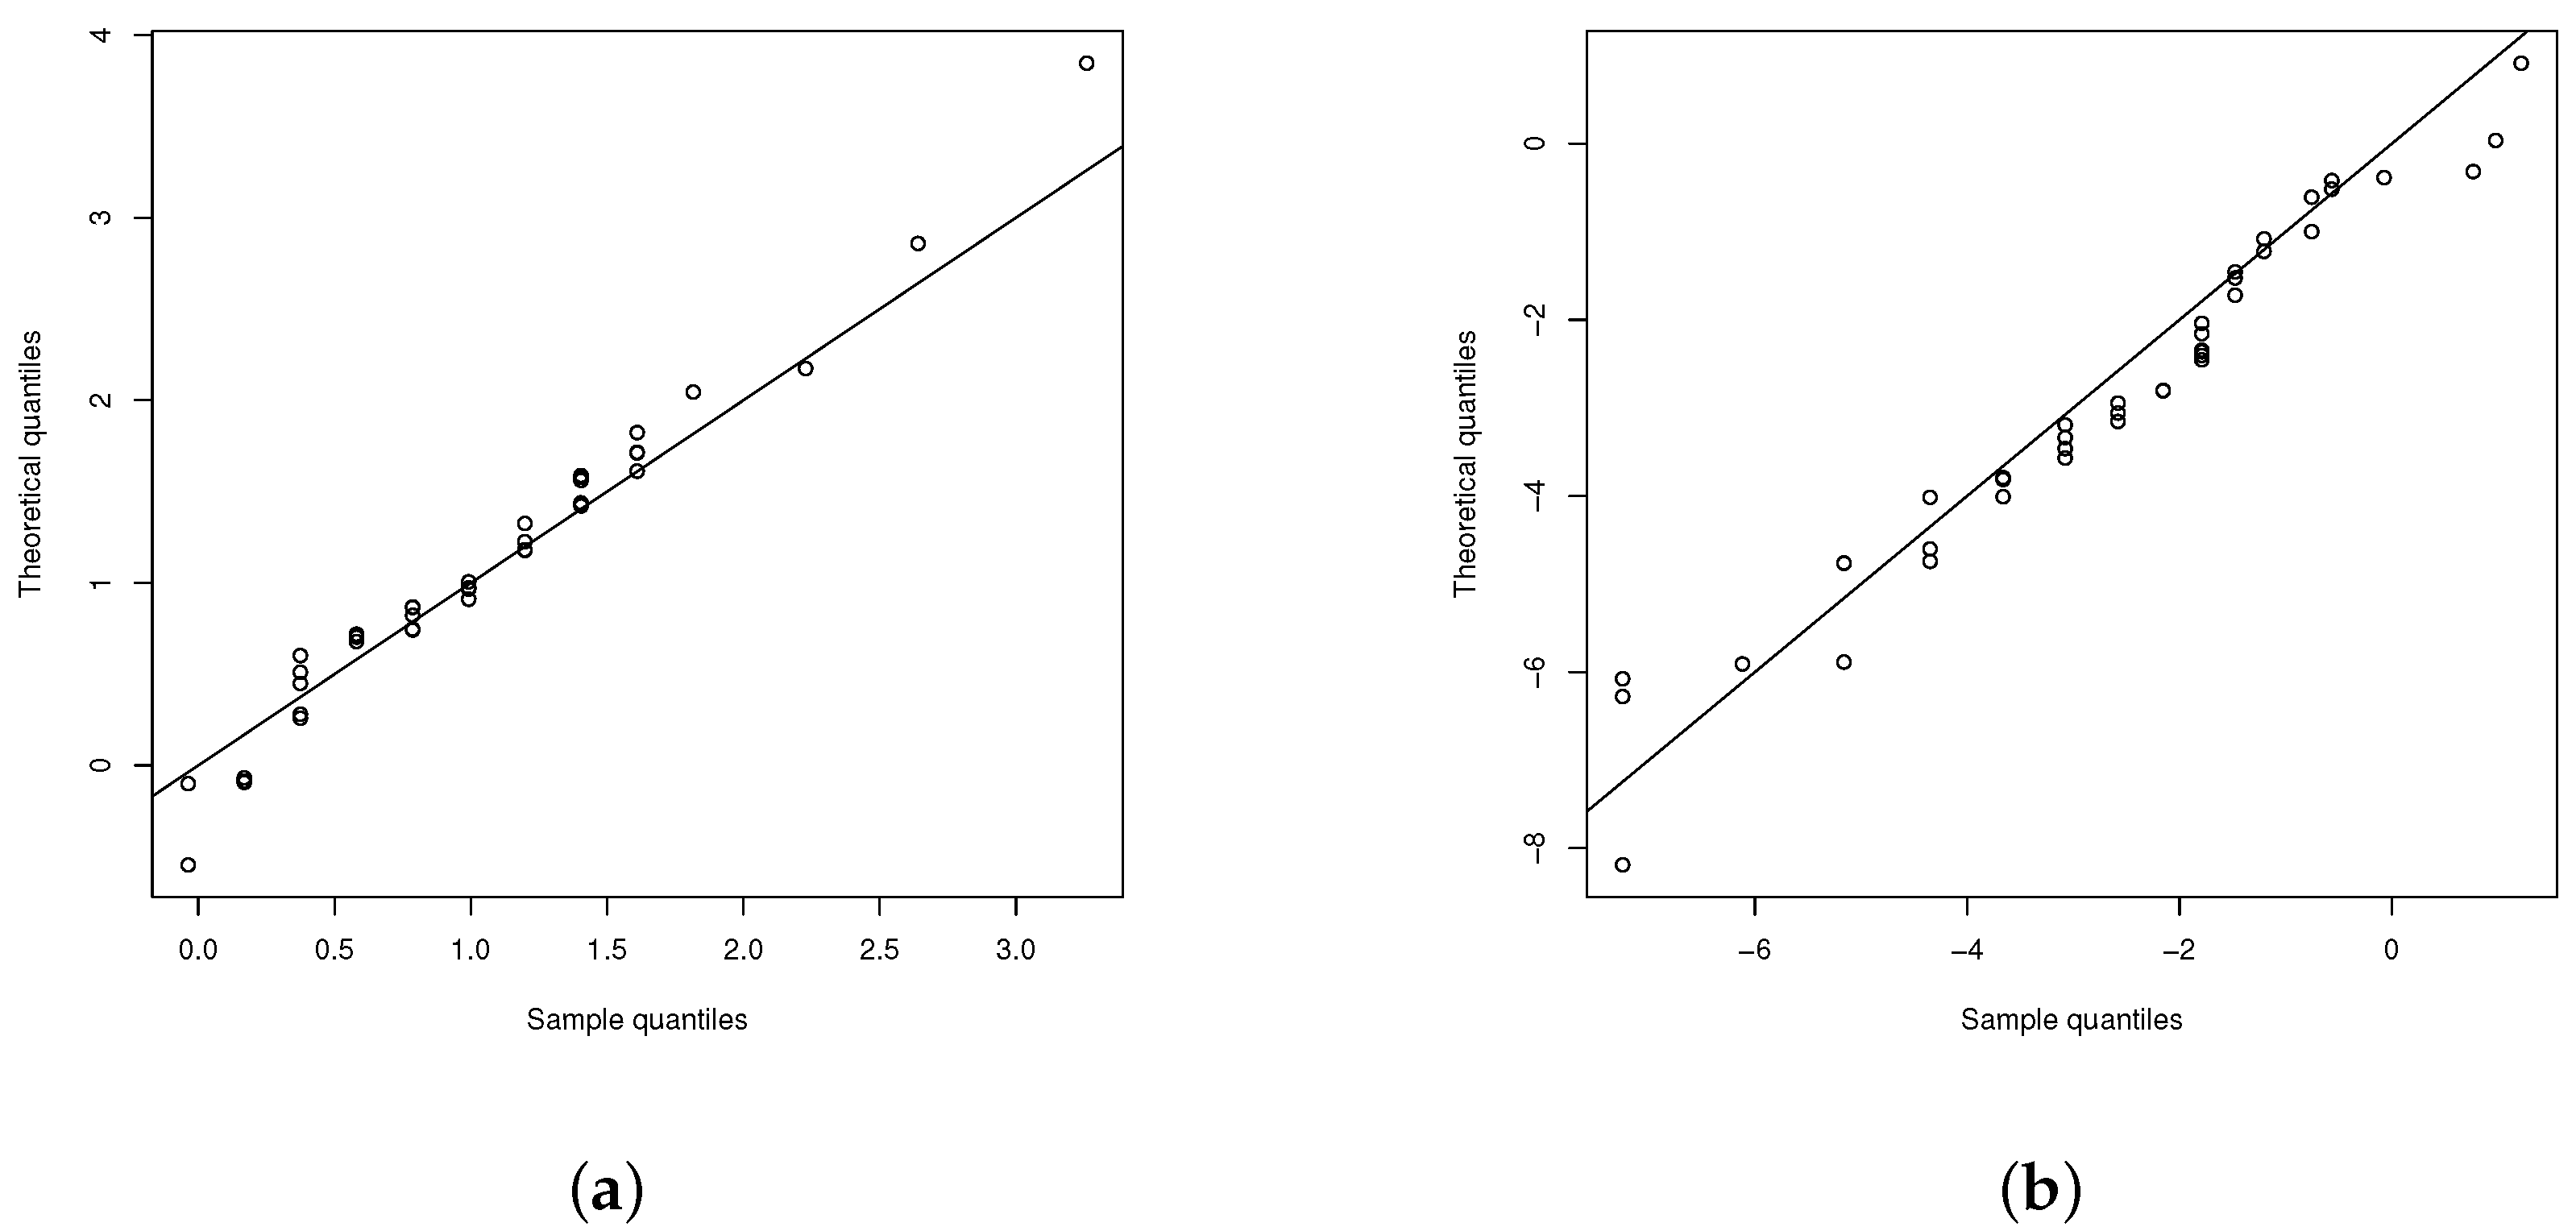
The Figure 2 and Figure 3 show the QQ-plots of the variable for both variables CO and O under SHN and SHNP models. Therefore, it is clear that the SHPN model achieves a much better fit for the air pollution data than the SHN model.
Figure 2.
QQ-plots for SHN models. (a) CO and (b) O.
Figure 3.
QQ-plots for SHPN models. (a) CO and (b) O.
Thus, a bivariate model with skewed marginal distributions fit the air pollution dataset better. Using these parameter estimates as true values, the MLE for parameter was computed under the Clayton copula, leading to Bootstrap confidence intervals were obtained for parameter , given by . Finally, we estimated the bivariate sinh-normal models under a bivariate copula (BSHN), see Kundu [21], and the BSHPN model. The estimates of the parameters are given in Table 4.
Table 4.
Parameter estimates for BSHN and BSHPN distributions.
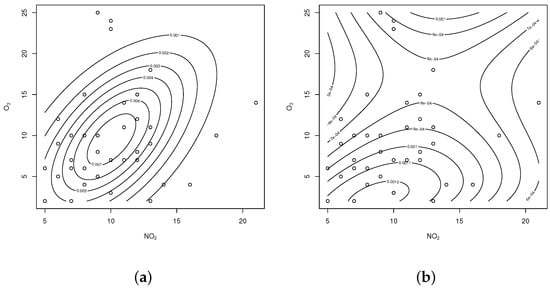
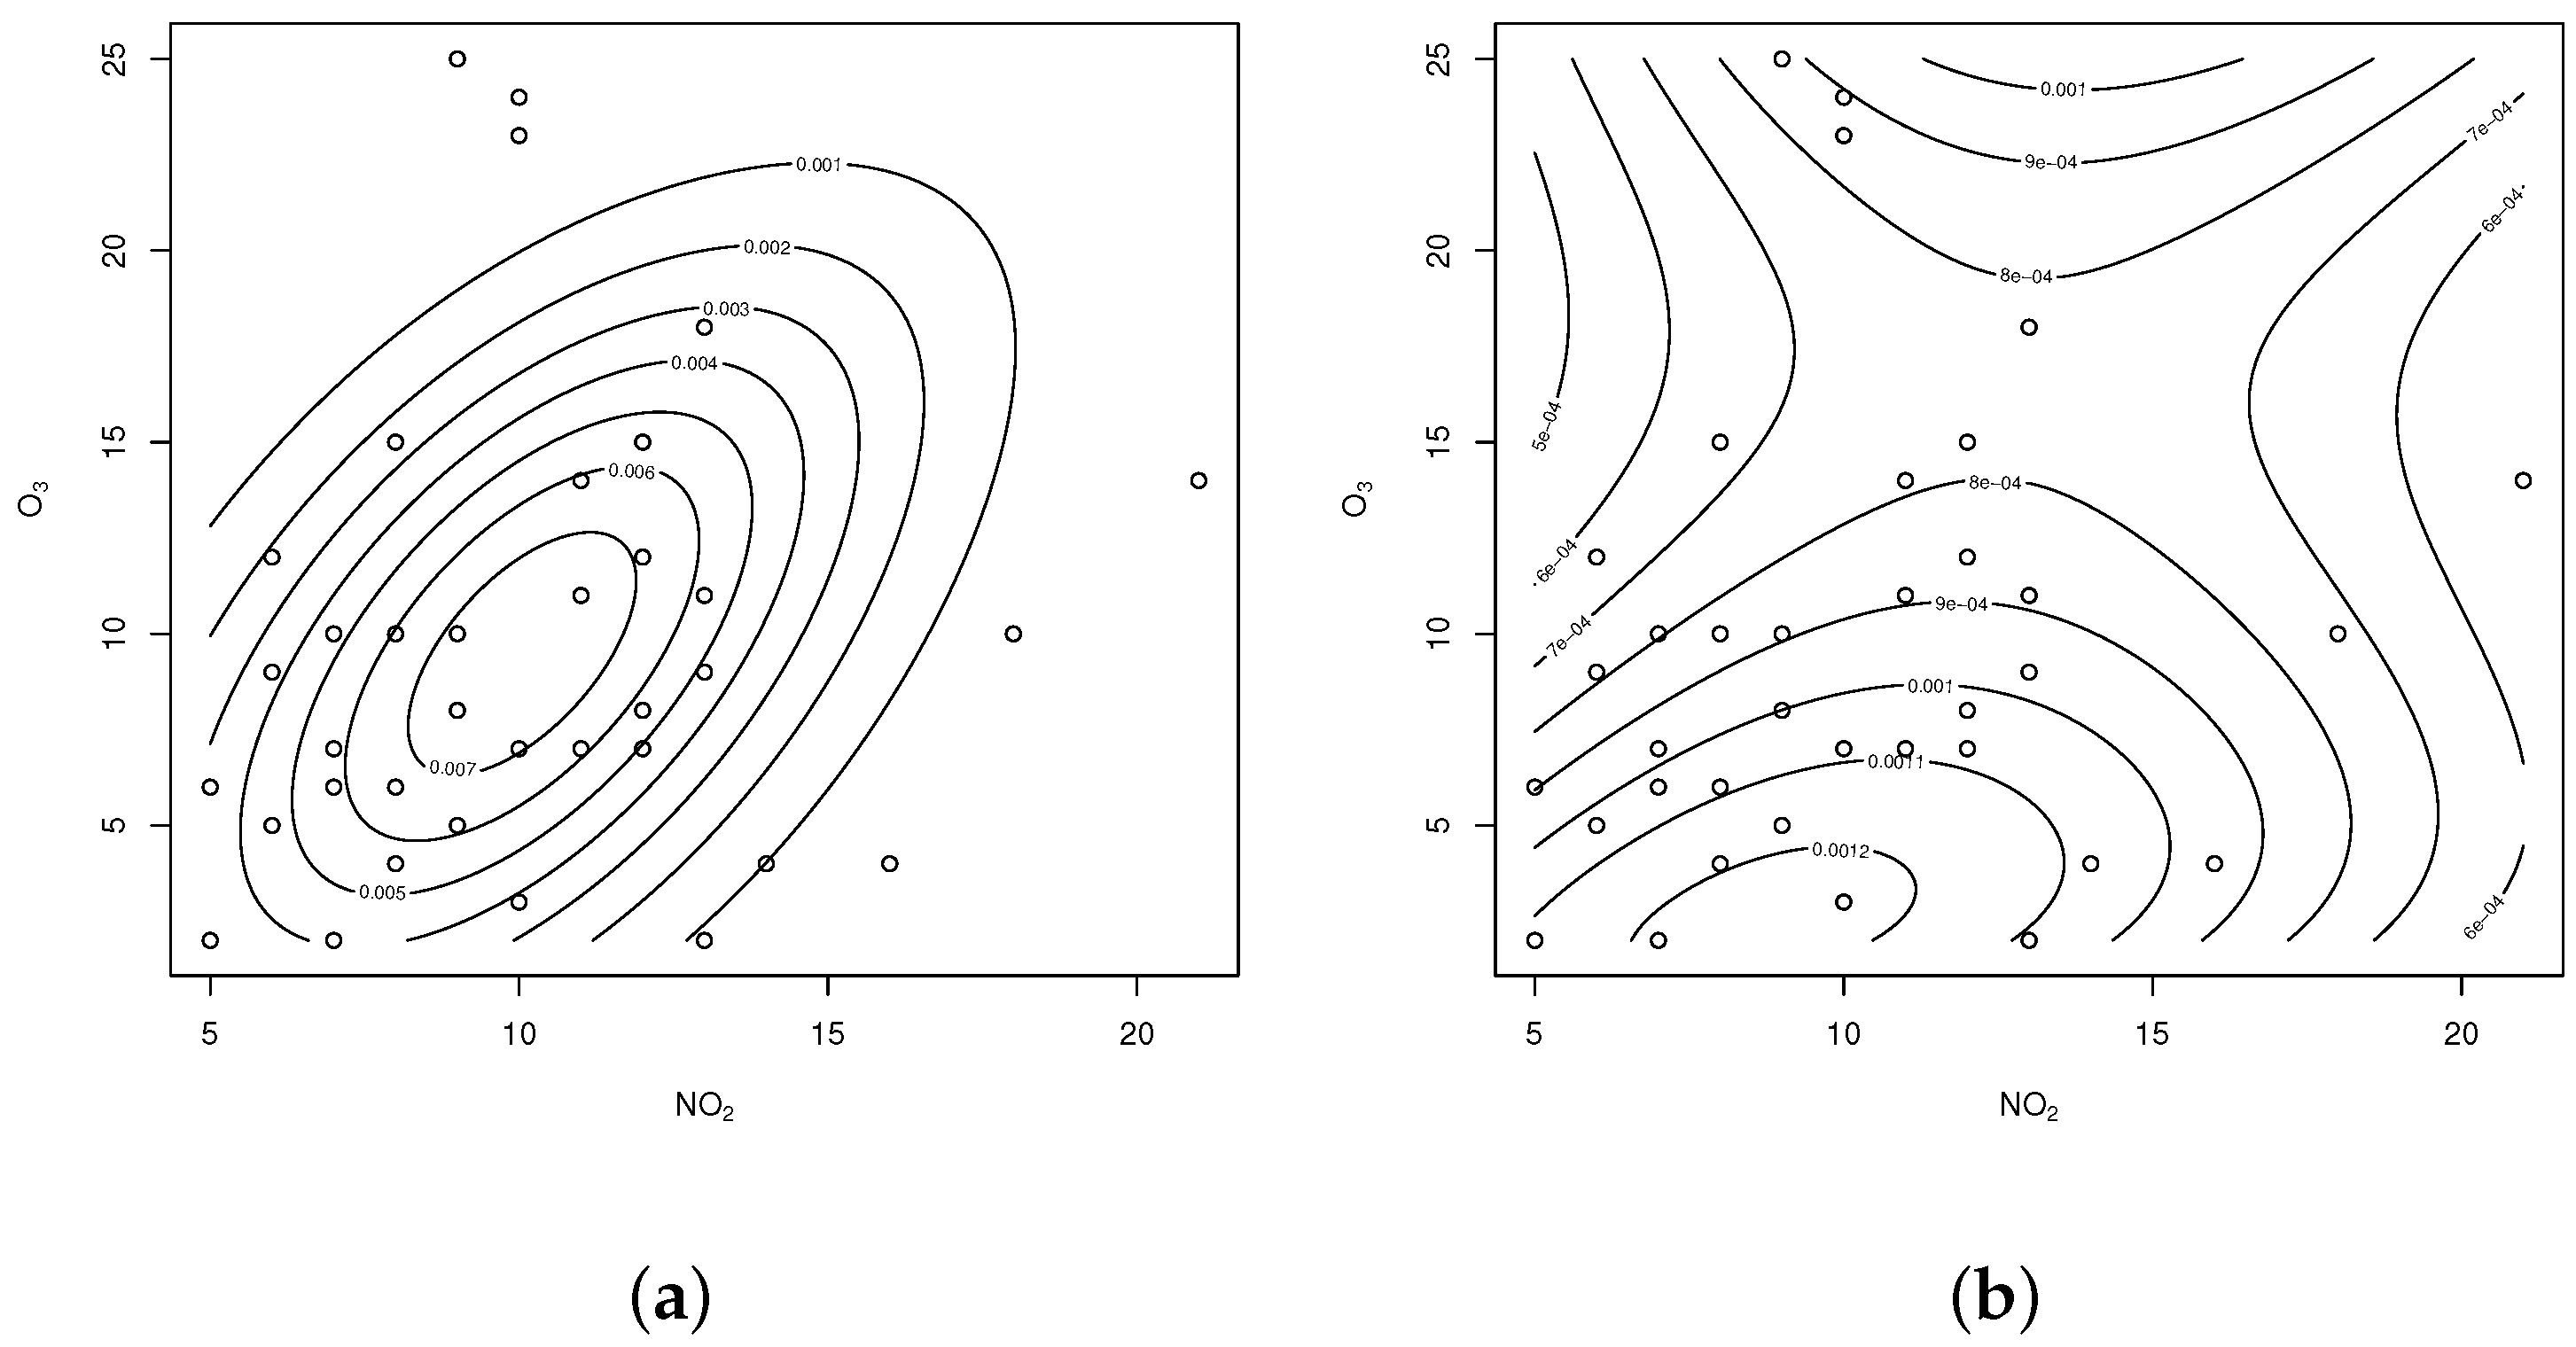
To compare the BSHN and BSHPN models, we used the AIC criteria, see Akaike [31], namely , where k is the number of parameters for the considered model. The best model is the one with the smallest AIC. Thus, for the bivariate SHN model, we obtained , whereas for the bivariate SHN power-normal model, , leading to the conclusion that the BSHPN model fits the air pollution concentration densities better. Figure 4 presents the graphics of the fitted models, where a better fit is clearly seen in the BSHPN model.
Figure 4.
Contour plots. (a) BSHN model and (b) BSHPN model.
5.2. Second Illustration
Our second illustration considers a set of real data available in Lepadatu et al. [32]. The data are from a study where the main objective was to optimize the lifetime of dies and other responses (Von Misses stress, manufacturing force, etc.) in the metal forming process to improve the quality of a product or process, minimizing the effects of variation without removing the causes (because they are too difficult and costly to control).
The log-BS distribution appears in this context since, according to the authors, “the die of fatigue cracks are caused by repeat application of loads, which individually would be too small to cause failure.” The considered models here are: for , and where is the Von Misses stress, is the lifetime of the die and is the work temperature.
Initially, we assume the independent bivariate model proposed by Lemonte [15], RBSHN, where it is assumed that, for For this model, we found that the MLEs were and , with We checked the assumption of homogeneity of the shape parameter Then, as suggested by Cook and Weisberg [33], the power model is usually used in practical situations. Thus, we assume for simplicity that where is the work temperature. Then, implies that ; therefore, for all Therefore, the test of homogeneity of the shape parameter was equivalent to the hypothesis test The statistic of this test was, p-value which leads to not rejecting the null hypothesis, concluding that the assumption of homogeneity of was acceptable.
Finally, we analyzed the assumption of independence of the errors in the proposed models. The Cramer-Von Mises test statistic yielded a calculated value of , with p-value which leads to the rejection of supposition that independence model fits the data well in the study. Therefore, a model that explains the dependence between the proposed model errors can better fit the dataset. Thus, we fit the RBSHPN regression model. The MLE estimates of the bivariate proposed model were: and .
It can be seen that, in any case, the hypothesis of no influence of the parameter for namely is rejected. Therefore, with the hypothesis
For this model, we obtained , which means that the regression model with dependence among the errors of the models better fit the dataset than the independence model.
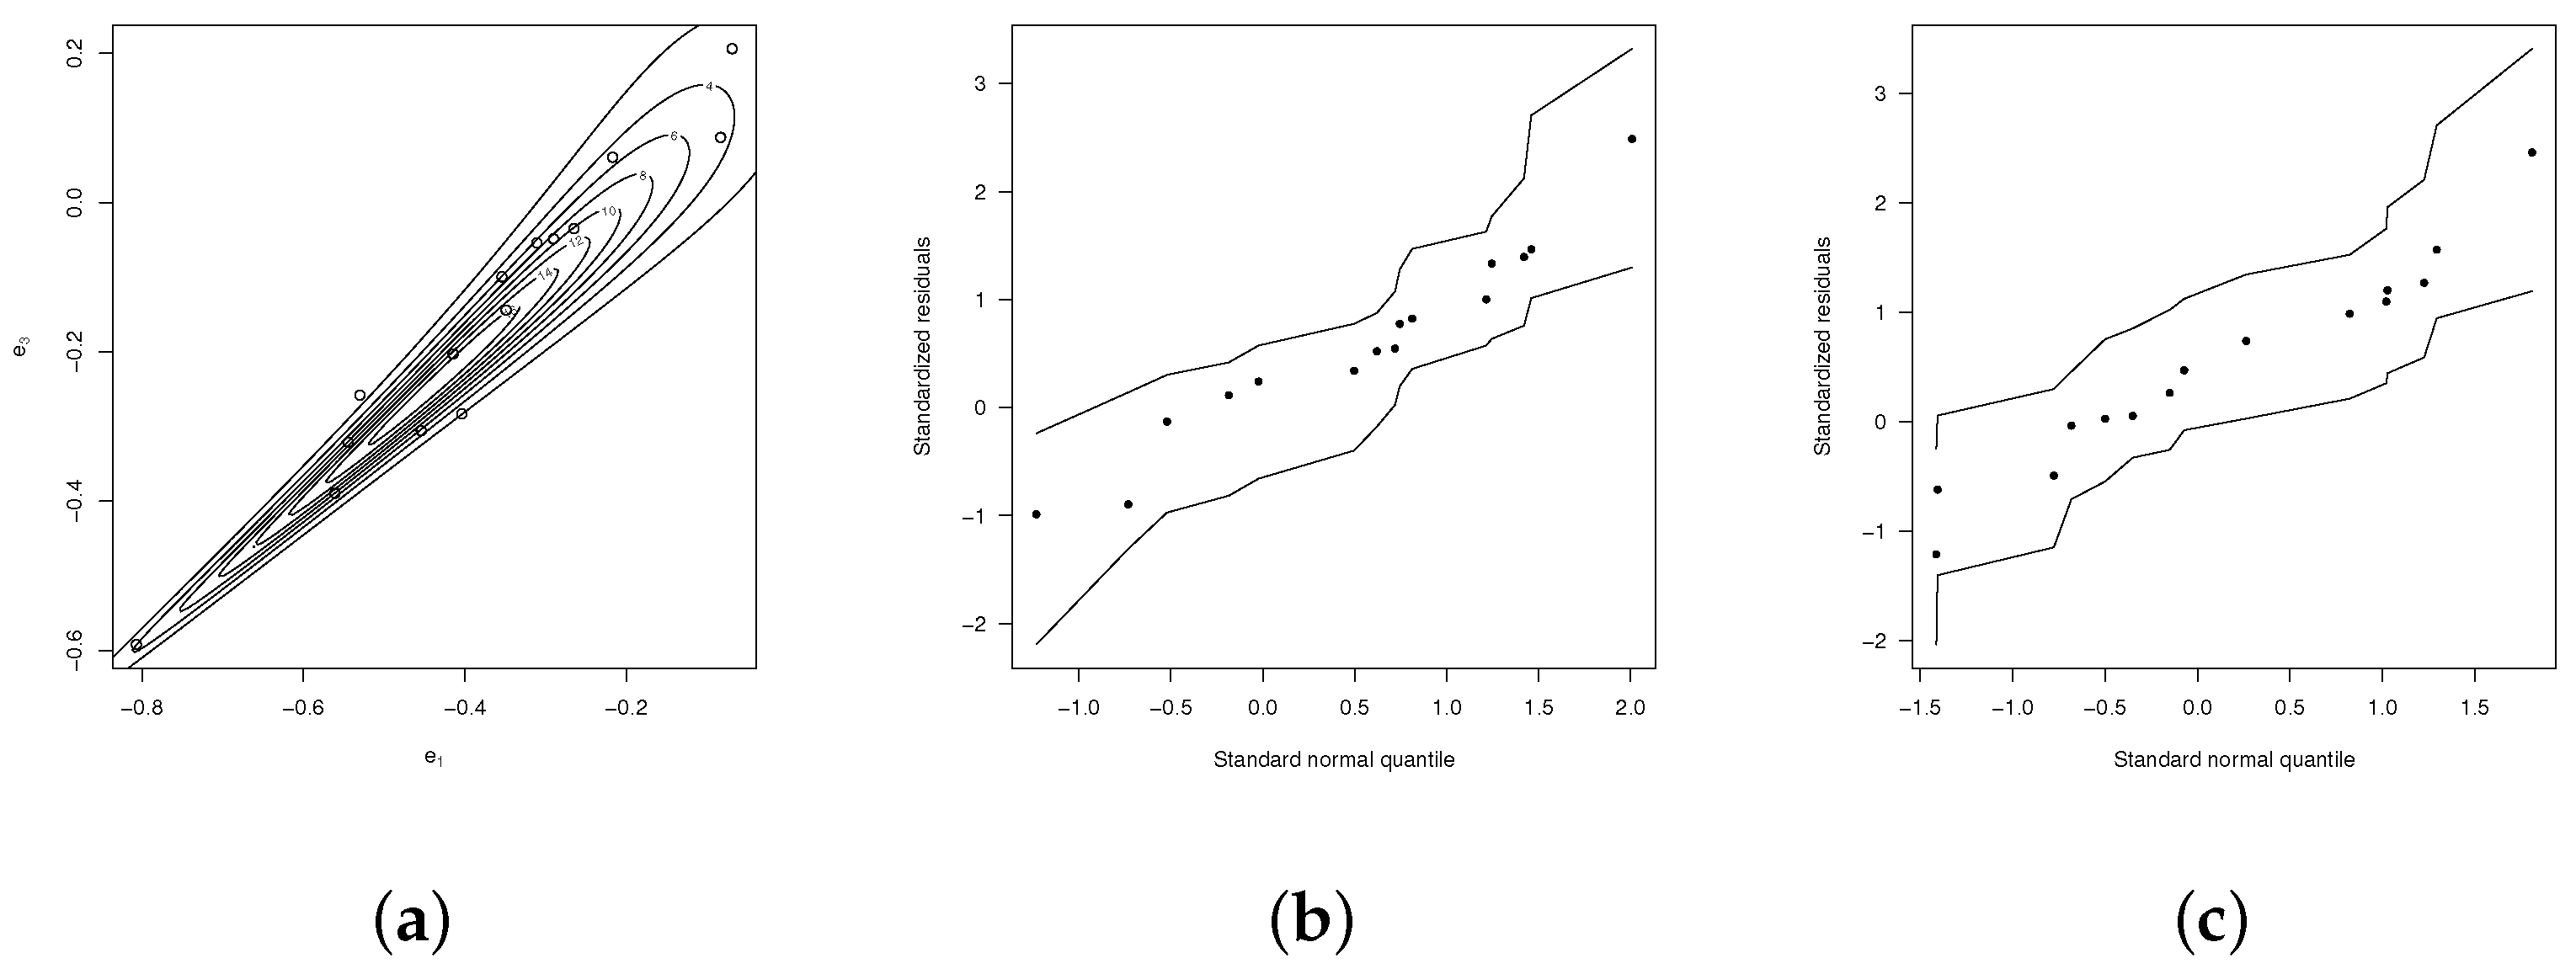
In Figure 5a, we found contour plots of the errors of the RBSHPN fitted model. The dependency or relationship between the errors of the two proposed models was clearly observed in this graph, which are best explained, according to the contour plot, by the models RBSHPN. For the marginal distributions, we present the envelope plots for the errors of the regression models of each marginal from the MLEs of the RBSHPN model, where it can be seen that these marginal models also present a good fit, see Figure 5b,c.
Figure 5.
(a) Contour plot RBSHPN model. (b) Marginal envelope SHN model. (c) Marginal envelope SHN model.
6. Concluding Remarks
In this work, we have introduced a new multivariate distribution from the sinh-normal univariate distribution and the family of power-normal distributions. The new distribution, which can also be called exponential log-Birnbaum–Saunder, is simple and can be used to model positive multivariate data. The new multivariate exponential sinh-normal distribution is an absolutely continuous distribution whose marginals are exponentiated sinh-normal distributions. Using the frequentest approach, the estimation of the parameters of the multivariate exponential sinh-normal model is carried out using the MLE, as well as a two-stage estimation procedure (Joe [20]). We have also presented the extension of the new multivariate distribution to the case of regression models and for the two cases considered, we present the explicit form of the information matrices. Monte Carlo simulations carried out indicate that the estimation method is quite effective to estimate the unknown parameters of the proposed models. We illustrate the methodology developed in this work through two applications to real data. Through the applications of real data, we verify that the bivariate sinh-normal exponentiated and the corresponding extension to the proposed regression models are superior to some existing proposals in the literature and therefore constitute viable alternatives in the analysis of multivariate positive data.
Author Contributions
Conceptualization, G.M.-F., R.B.A.-F. and R.T.-F.; Methodology, G.M.-F., R.B.A.-F. and R.T.-F.; Data curation, G.M.-F. and R.B.A.-F.; Formal analysis, G.M.-F., R.B.A.-F. and R.T.-F.; Investigation, G.M.-F., R.B.A.-F. and R.T.-F.; Resources, G.M.-F., R.B.A.-F. and R.T.-F.; Software, G.M.-F. and R.B.A.-F.; Supervision, G.M.-F.; Validation, G.M.-F. and R.B.A.-F.; Visualization, G.M.-F., R.B.A.-F. and R.T.-F.; Writing—original draft, G.M.-F.; Writing—review and editing, G.M.-F., R.B.A.-F. and R.T.-F. All authors have read and agreed to the published version of the manuscript.
Funding
The research of G. Martínez-Flórez and R. Tovar-Falón was supported by project: Resolución de Problemas de Situaciones Reales Usando Análisis Estadístico a través del Modelamiento Multidimensional de Tasas y Proporciones; Esquemas de Monitoreamiento para Datos Asimétricos no Normales y una Estrategia Didáctica para el Desarrollo del Pensamiento Lógico-Matemático. Universidad de Córdoba, Colombia, Acta de Compromiso Número: FCB-05-19.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
Details about data available are given in Section 5.
Acknowledgments
The authors are very thankful for the constructive comments made by the anonymous reviewers. The authors G. Martínez-Flórez and R. Tovar-Falón acknowledges the support given by Universidad de Córdoba, Montería, Colombia.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Rieck, J.R.; Nedelman, J.R. A log-linear model for the Birnbaum-Saunders distribution. Technometrics 1991, 33, 51–60. [Google Scholar]
- Birnbaum, Z.W.; Saunders, S.C. A new family of life distributions. J. Appl. Probabil. 1969, 6, 319–327. [Google Scholar] [CrossRef] [Scilit]
- Birnbaum, Z.W.; Saunders, S.C. Estimation for a family of life distributions with applications to fatigue. J. Appl. Probabil. 1969, 6, 328–347. [Google Scholar] [CrossRef] [Scilit]
- Díaz-García, J.A.; Leiva-Sánchez, V. A new family of life distributions based on the elliptically contoured distributions. J. Stat. Plann. Inference 2005, 128, 445–457. [Google Scholar] [CrossRef] [Scilit]
- Vilca-Labra, F.; Leiva-Sánchez, V. A new fatigue life model based on the family of skew-elliptical distributions. Commun. Stat.-Theory Methods 2006, 35, 229–244. [Google Scholar] [CrossRef] [Scilit]
- Martínez-Flórez, G.; Bolfarine, H.; Gómez, H.W. An alpha-power extension for the Birnbaum-Saunders distribution. Statistics 2014, 48, 896–912. [Google Scholar] [CrossRef] [Scilit]
- Durrans, S.R. Distributions of fractional order statistics in hydrology. Water Resour. Res. 1992, 28, 1649–1655. [Google Scholar] [CrossRef] [Scilit]
- Gupta, R.S.; Gupta, R.D. Generalized skew normal model. Test 2004, 13, 501–524. [Google Scholar] [CrossRef] [Scilit]
- Pewsey, A.; Gómez, H.; Bolfarine, H. Likelihood-based inference for power distributions. Test 2012, 21, 775–789. [Google Scholar] [CrossRef] [Scilit]
- Leiva, V.; Vilca, F.; Balakrishnan, N.; Sanhueza, A. A skewed sinh-normal distribution and its properties and application to air pollution. Commun. Stat. Theory Methods 2010, 39, 426–443. [Google Scholar] [CrossRef] [Scilit]
- Azzalini, A. A class of distributions which includes the normal ones. Scand. J. Stat. 1985, 12, 171–178. [Google Scholar]
- Martínez-Flórez, G.; Bolfarine, H.; Gómez, H.W. The log-linear Birnbaum-Saunders power model. Methodol. Comput. Appl. Probabil. 2017, 19, 913–933. [Google Scholar] [CrossRef] [Scilit]
- Lemonte, A.J. A log-Birnbaum–Saunders regression model with asymmetric errors. J. Stat. Comput. Simul. 2012, 82, 17751785. [Google Scholar] [CrossRef] [Scilit]
- Díaz-García, J.; Domínguez-Molina, J.R. Some generalisations of Birnbaum-Saunders and sinh-normal distributions. Int. Math. Forum 2006, 1, 1709–1727. [Google Scholar] [CrossRef] [Scilit]
- Lemonte, A. A Multivariate Birnbaum-Saunders regression model. J. Stat. Comput. Simul. 2013, 12, 2244–2257. [Google Scholar] [CrossRef] [Scilit]
- Martínez-Flórez, G.; Azevedo-Farias, R.; Moreno-Arenas, G. Multivariate log-Birnbaum-Saunders regression models. Commun. Stat. Theory Methods 2017, 46, 10166–10178. [Google Scholar] [CrossRef] [Scilit]
- Romeiro, R.G.; Vilca, F.; Balakrishnan, N.; Borelli-Zeller, C. A robust multivariate Birnbaum-Saunders regression model. Statistics 2020, 54, 1094–1123. [Google Scholar] [CrossRef] [Scilit]
- Marchant, C.; Leiva, V.; Cysneiros, F. A multivariate log-linear model for Birnbaum-Saunders distributions. IEEE Trans. Reliab. 2016, 65, 816–864. [Google Scholar] [CrossRef] [Scilit]
- Nelsen, R.B. An Introdution to Copulas; Springer Series in Statistis; Springer: New York, NY, USA, 2006. [Google Scholar]
- Joe, H. Multivariate Models and Dependence Concepts; Chapman and Hall: London, UK, 1997. [Google Scholar]
- Kundu, D. Bivariate sinh-normal distribution and a related model. Braz. J. Probabil. Stat. 2015, 29, 590–607. [Google Scholar] [CrossRef] [Scilit]
- Kundu, D.; Gupta, R.D. Power normal distribution. Statistics 2013, 47, 110–125. [Google Scholar] [CrossRef] [Scilit]
- Clayton, D.G. A model for association in bivariate life tables and its application in epidemiological studies of familial tendency in chronic disease incidence. Biometrika 1978, 65, 141–151. [Google Scholar] [CrossRef]
- Kimeldorf, G.; Sampson, A. Uniform representations of bivariate distributions. Commun. Stat. 1975, 4, 617–627. [Google Scholar] [CrossRef] [Scilit]
- Cook, R.D.; Johnson, M.E. A family of distributions for modelling non-elliptially symmetric multivariate data. J. R. Stat. Soc. Ser. B 1981, 43, 210–218. [Google Scholar]
- Lemonte, A.; Martínez-Flórez, G.; Moreno-Arenas, G. Multivariate Birnbaum-Saunders power-normal model and associated inference. Commun. Stat. Simul. Comput. 2021. [Google Scholar] [CrossRef] [Scilit]
- Joe, H. Asymptotic efficiency of two-stage estimation method for copula-based models. J. Multivar. Anal. 2005, 94, 401–419. [Google Scholar] [CrossRef] [Scilit]
- R Development Core Team. R: A Language and Environment for Statistical Computing; R Foundation for Statistical Computing: Vienna, Austria, 2021; Available online: http://www.R-project.org (accessed on 31 January 2022).
- Johnson, R.A.; Wichern, D.W. Applied Multivariate Analysis, 4th ed.; Prentie-Hall: Hoboken, NJ, USA, 1999. [Google Scholar]
- Gokhale, S.; Khare, M. Vehicle wake factor for heterogeneous traffic in urban environments. Int. J. Environ. Pollut. 2007, 30, 97–105. [Google Scholar] [CrossRef] [Scilit]
- Akaike, H. A new look at statistical model identification. IEEE Trans. Autom. Control 1974, AU-19, 716–722. [Google Scholar] [CrossRef] [Scilit]
- Lepadatu, D.; Kobi, A.; Hambli, R.; Barreau, A. Lifetime multiple response optimization of metal extrusion die. In Proceedings of the Annual Reliability and Maintainability Symposium, Alexandria, VA, USA, 24–27 January 2005; Institute of Electrical and Electronics Engineers: Piscataway, NJ, USA, 2005; pp. 37–42. [Google Scholar]
- Cook, R.D.; Weisberg, S. Diagnostics for heteroscedasticity in regression. Biometrika 1983, 70, 1–10. [Google Scholar] [CrossRef]

Publisher’s Note: MDPI stays neutral with regard to jurisdictional claims in published maps and institutional affiliations. |
© 2022 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).