


Abstract
Reliable visual delineation of ice accretion on aircraft wing leading edges remains challenging because accreted ice often exhibits low visual contrast, translucent and irregular morphology, and ambiguous boundaries. To address these challenges, this study proposes ICE-UNet, a lightweight semantic segmentation network for pixel-wise leading-edge icing detection. The network adopts a compact encoder–decoder architecture and integrates three functional modules: Residual Depthwise Separable Convolution with Batch Normalization and ReLU Activation (Res-DSCBR), Depthwise-Separable Receptive Field Blocks (DSCRFBs), and Convolutional Block Attention Modules (CBAMs). This design reduces model complexity while enhancing multi-scale contextual representation and attention-guided feature refinement. For empirical validation, a dataset of 5000 annotated image–mask pairs was constructed from 1300 original images comprising wind-tunnel video frames and post-icing photographs of the NACA 0020 and Boeing 117 airfoil models. Following augmentation, the 5000 pairs were randomly divided at the image level into training, validation, and test subsets in a 3:1:1 ratio. Experimental results show that ICE-UNet achieves 96.60% accuracy, 93.07% intersection over union (IoU), 96.36% precision, and 96.44% recall, with only 0.76 M parameters and 16.19 GFLOPs. Compared with the baseline U-Net, ICE-UNet improves IoU by 10.33 percentage points while reducing the parameter count and computational cost by 95.6% and 90.0%, respectively. Photometric perturbation tests further indicate that the model maintains stable segmentation performance under moderate brightness and contrast variations, although severe contrast degradation remains a limiting condition. TensorRT-based FP16 acceleration reduced the inference latency from 55.21 ms to 13.69 ms per image on a Tesla V100 GPU without measurable accuracy degradation. Additionally, a MobileNetV3 pre-screening module was integrated to effectively suppress false-positive activations on clean surfaces during continuous monitoring. Collectively, these findings show that ICE-UNet achieved the highest IoU among the ten segmentation models evaluated on this wind-tunnel dataset while retaining a compact architecture.
1. Introduction
Aircraft icing is one of the most critical environmental hazards affecting flight safety [1]. During flight through supercooled cloud environments, ice accretion may occur on aerodynamic surfaces, particularly at the wing leading edge [2]. The accumulated ice alters the airfoil geometry, increases aerodynamic drag, reduces lift generation, and may severely degrade aircraft controllability and operational safety [3,4]. Consequently, accurate and timely detection of wing icing is essential for flight safety assessment, intelligent anti-icing systems, and autonomous aircraft operation.
Conventional aircraft icing detection relies on dedicated sensing technologies, including vibration, thermal, optical, microwave, and fiber-optic devices [5,6,7]. Although these sensors can provide reliable point measurements under defined conditions, their spatial coverage, installation complexity, added weight, and integration cost may constrain widespread use. Indirect model-based approaches have also inferred icing from changes in flight dynamics: Dong and Ai combined in-flight parameter identification with probabilistic neural network classification to detect icing locations [8]. Dong later applied deep neural networks to the detection and characterization of aircraft icing [9]. Such methods provide system-level icing diagnosis but do not directly resolve the spatial distribution and boundary of the accreted ice. Image-based detection offers a complementary non-contact route because it can retain spatial information over the observed aerodynamic surface [10,11].
Deep learning has increasingly been used for aerospace monitoring and icing-related aerodynamic analysis [12,13,14]. Jin et al. developed a residual U-shaped convolutional network for cross-fidelity fusion of numerical and experimental ice shapes [15]. Yu et al. combined a fused super-resolution network with a vision transformer to predict airfoil ice-accretion images [16]. Lin et al. proposed a point-cloud and feature-modulation framework for rapid aerodynamic prediction of arbitrary iced airfoils [17]. Cuozzo et al. introduced neural surrogates for iced-tailplane geometry and lift prediction [18]. These studies demonstrate the potential of data-driven models for ice-shape generation and aerodynamic assessment; however, they do not directly address pixel-level delineation of ice from experimentally acquired wing images. Meanwhile, semantic segmentation networks such as U-Net [19], SegNet [20], PSPNet [21], DeepLabV3+ [22], and UNeXt [23] provide established encoder–decoder paradigms for dense prediction [20], but their transfer to icing imagery requires application-specific treatment of low contrast, irregular boundaries, and computational constraints.
Despite the powerful feature extraction capabilities of existing segmentation networks, applying them to aircraft wing icing encounters several domain-specific challenges. First, ice layers are often semi-transparent and share similar visual appearances with the underlying clean wing surface, resulting in extremely weak feature contrast. Second, the morphology of ice accretion evolves continuously, producing highly irregular and ambiguous boundaries that are difficult to delineate accurately [24]. Third, practical wind tunnel or in-flight operating environments inevitably introduce uneven illumination, reflections, shadows, and complex background interference. Finally, most state-of-the-art networks achieve high accuracy at the cost of substantial computational overhead, severely limiting their deployment on resource-constrained aerospace embedded platforms [25]. Therefore, a fundamental challenge remains: how to robustly segment transparent and irregular icing regions under complex environmental disturbances while maintaining a strictly lightweight profile for real-time deployment.
To systematically evaluate the proposed framework, a dedicated aircraft wing icing image dataset was established using an improved closed-loop icing wind-tunnel system. Systematic icing experiments were conducted, and a pixel-level annotated dataset containing 5000 icing images under different airfoil geometries, angles of attack, and environmental temperatures was constructed. Extensive experiments demonstrate that ICE-UNet achieves an Intersection over Union (IoU) of 93.07% and an Accuracy of 96.60%, outperforming several representative segmentation networks. Furthermore, compared to the original U-Net, the proposed model reduces the parameter count and computational complexity by 95.6% and 90.0%, respectively.
The main contributions of this study are summarized as follows:
- (1)
- A novel lightweight aircraft icing segmentation network, ICE-UNet, is developed by incorporating residual depthwise separable convolutions (Res-DSCBR), multi-scale depthwise separable receptive field enhancement (DSCRFB), and channel–spatial attention mechanisms (CBAM). This synergistic design enables accurate icing localization with significantly reduced model complexity.
- (2)
- Validation experiments are performed on a dataset of images from two standard airfoil models in a desktop icing wind tunnel, encompassing ablation analyses, cross-model comparisons, visualization-based interpretation, environmental robustness assessment, and video-sequence testing. In these images, the proposed framework combines high segmentation accuracy with low computational cost.
- (3)
- A practical two-stage cascaded icing perception framework is established by integrating MobileNetV3-based icing pre-screening and ICE-UNet segmentation. This architecture effectively suppresses false alarms in non-icing scenarios and improves the overall robustness of continuous sequence monitoring. Furthermore, TensorRT acceleration further reduces the measured ICE-UNet segmentation inference time on a workstation equipped with an NVIDIA Tesla V100 GPU (NVIDIA Corporation, Santa Clara, CA, USA).
The remainder of this paper is organized as follows: Section 2 introduces the dataset construction and data preprocessing procedures. Section 3 describes the architecture of the proposed ICE-UNet model. Section 4 presents the comprehensive experimental results, encompassing ablation studies, cross-model comparisons, visualization interpretation, robustness evaluations, and the system-level cascaded improvement strategy. Finally, Section 5 concludes the paper and outlines future research directions.
2. Data and Preprocessing
2.1. Datasets
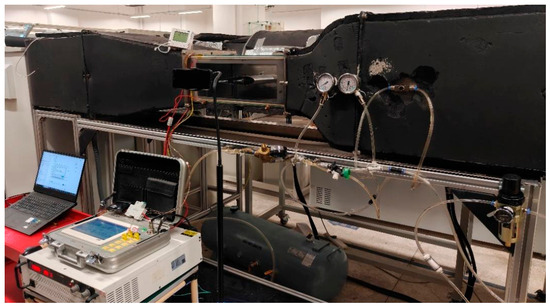
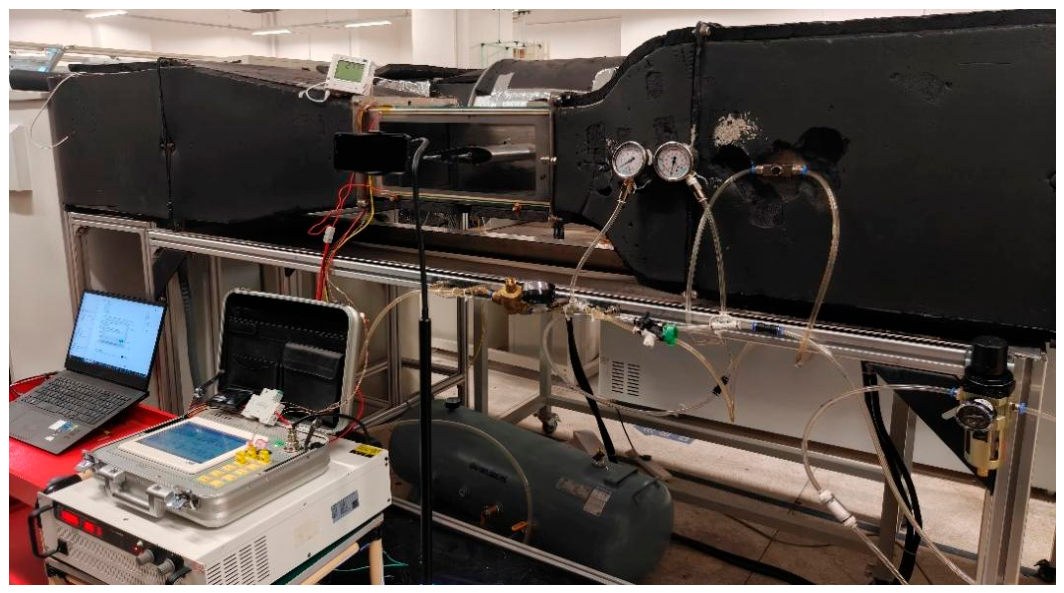
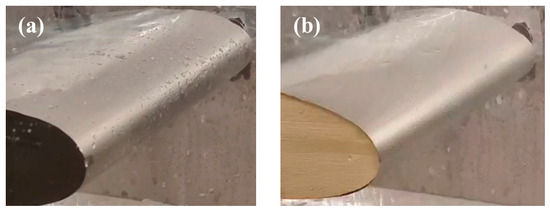
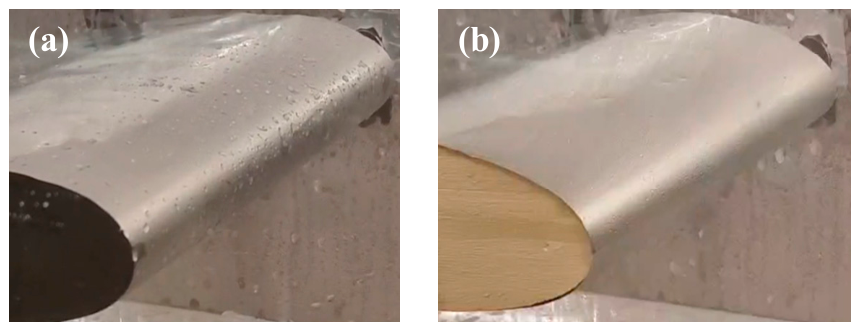
In this study, a desktop recirculating icing wind tunnel (shown in Figure 1) is employed to conduct wing icing experiments under natural light conditions. The airfoil profiles investigated include the NACA 0020 and the Boeing 117, as depicted in Figure 2. The NACA 0020 is a symmetric four-digit airfoil with zero camber; it has a maximum thickness-to-chord ratio of 20%, with the maximum thickness located at approximately 30% of the chord from the leading edge [26]. The Boeing 117 profile used for the second model was also used on the B-29 wing and has been examined in NACA wind-tunnel studies [27].
Figure 1.
Photograph of the desktop recirculating icing wind tunnel.
Figure 2.
Geometric profiles of the airfoils investigated in this study: (a) NACA 0020; (b) Boeing 117.
To systematically investigate the ice accretion characteristics of various airfoil profiles, a parametric study was conducted using a two-factor factorial design. Given that ice formation is highly sensitive to environmental and aerodynamic conditions, the angle of attack (AoA) and ambient temperature were selected as the primary independent variables. The baseline icing environment was established with a liquid water content (LWC) of 2.5 g/m3, a median volume diameter (MVD) of 32.8 μm, and a freestream velocity of 15 m/s. To ensure the reliability and repeatability of the experimental results, these three flow and cloud parameters were held constant. Meanwhile, the specific icing scenarios were varied according to the test matrix outlined in Table 1, facilitating a comprehensive evaluation of their distinct effects on ice accretion behavior.
Table 1.
Experimental test matrix and environmental conditions for airfoil icing.
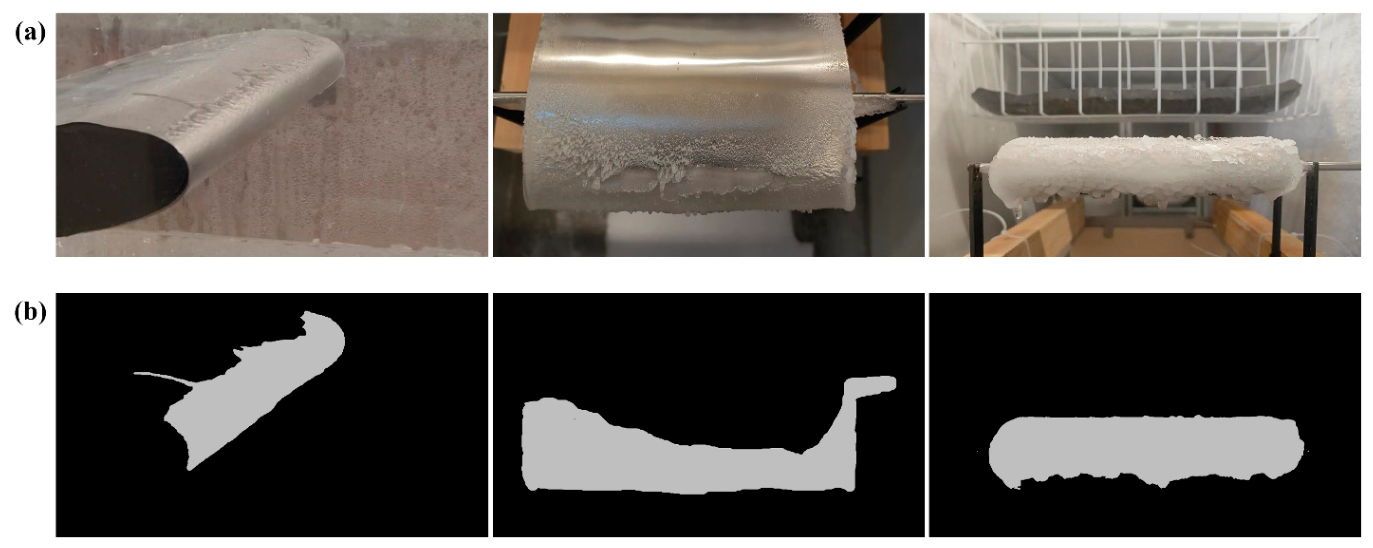
Eight video sequences, each lasting approximately 5 min, were recorded under the experimental conditions listed in Table 1. Frames were extracted at approximately 3 s intervals and manually screened to remove low-quality images. After the icing experiments, additional photographs of the iced airfoil models were taken in a freezer. The retained video frames and post-icing photographs together yielded 1300 original airfoil-icing images. Representative raw images are presented in Figure 3a. Following the augmentation procedures described in Section 2.2, the resulting 5000 image–mask pairs were randomly divided at the image level into training (3000 pairs), validation (1000 pairs), and test (1000 pairs) subsets, corresponding to a 3:1:1 ratio.
Figure 3.
Representative samples from the icing image dataset: (a) raw airfoil-icing images; (b) corresponding ground-truth annotation masks for ice regions.
The Segment Anything Model (SAM) [28] was used to generate initial ice-region masks from point prompts. The candidate masks were visually inspected against the corresponding source images. Boundary discrepancies and non-ice regions incorrectly included in the masks were corrected manually where necessary, including at visually ambiguous transparent-ice boundaries. The resulting binary masks were used as reference annotations for the dataset, as illustrated in Figure 3b.
2.2. Data Augmentation
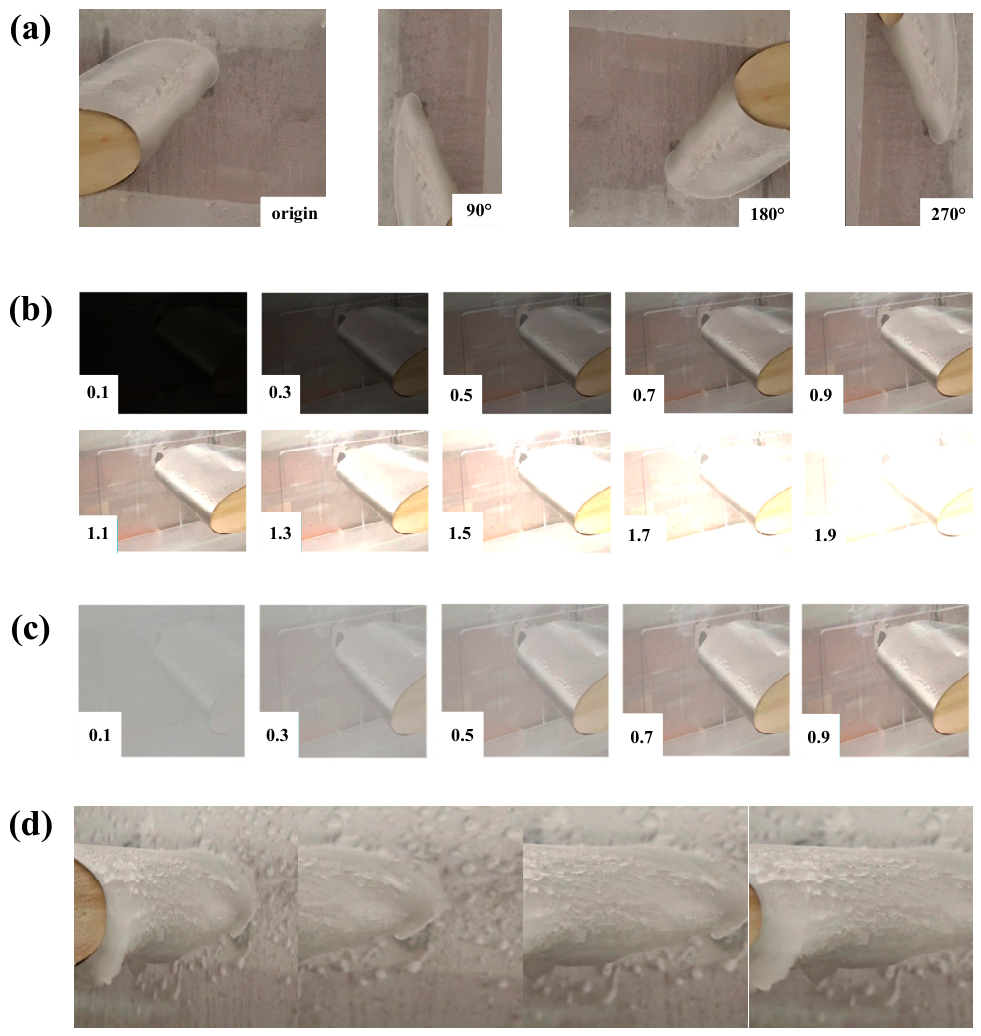
In this study, several standard data augmentation strategies were implemented, including geometric rotation, brightness and contrast adjustments, and random cropping. Image rotation was initially applied to mitigate the limited viewpoint diversity inherent in the extracted video frames. Given that the original samples exhibited relatively uniform spatial orientations, random rotation angles were introduced to increase the structural complexity of the dataset while preserving essential discriminative features. Representative augmentation results, specifically showcasing rotations of 90°, 180°, and 270°, are illustrated in Figure 4a. Brightness scaling was used as a training-time photometric augmentation to introduce global intensity variation into the wind-tunnel images, as illustrated in Figure 4b. Similarly, contrast variation was employed to emulate imaging disturbances encountered during the ice accretion process, such as water mist and environmental light scattering effects. By modulating the image contrast, the model is compelled to better generalize to complex, real-world icing conditions, as depicted in Figure 4c. Finally, random cropping was utilized to bolster the robustness of feature extraction and mitigate the influence of irrelevant background clutter. In this study, a fixed crop resolution of 512 × 512 pixels was adopted. This operation involves randomly initializing the top-left spatial coordinates within the original image bounds, followed by the extraction of the corresponding sub-region. This strategy effectively overcomes the spatial bias inherent in fixed-position cropping and further improves model generalization, as shown in Figure 4d. Collectively, these augmentation operations expanded the 1300 original image-mask pairs to a final dataset of 5000 image-mask pairs.
Figure 4.
Representative airfoil-icing images subjected to various geometric and photometric transformations: (a) rotation; (b) brightness adjustment; (c) contrast variation; (d) random cropping.
2.3. Data Normalization
To ensure the dimensional consistency of the input data while improving training efficiency and convergence stability, all images were normalized prior to model training. Specifically, the entire dataset was first resized to a unified resolution of 512 × 512 pixels. Subsequently, channel-wise normalization was applied across the RGB channels using predefined mean and standard deviation values to standardize the pixel intensity distribution. The mathematical formulation of the normalization procedure is expressed in Equation (1):
where X denotes the original pixel value, μ and σ represent the channel-wise mean and standard deviation, respectively, and Xnorm denotes the normalized value.
3. Model Architecture
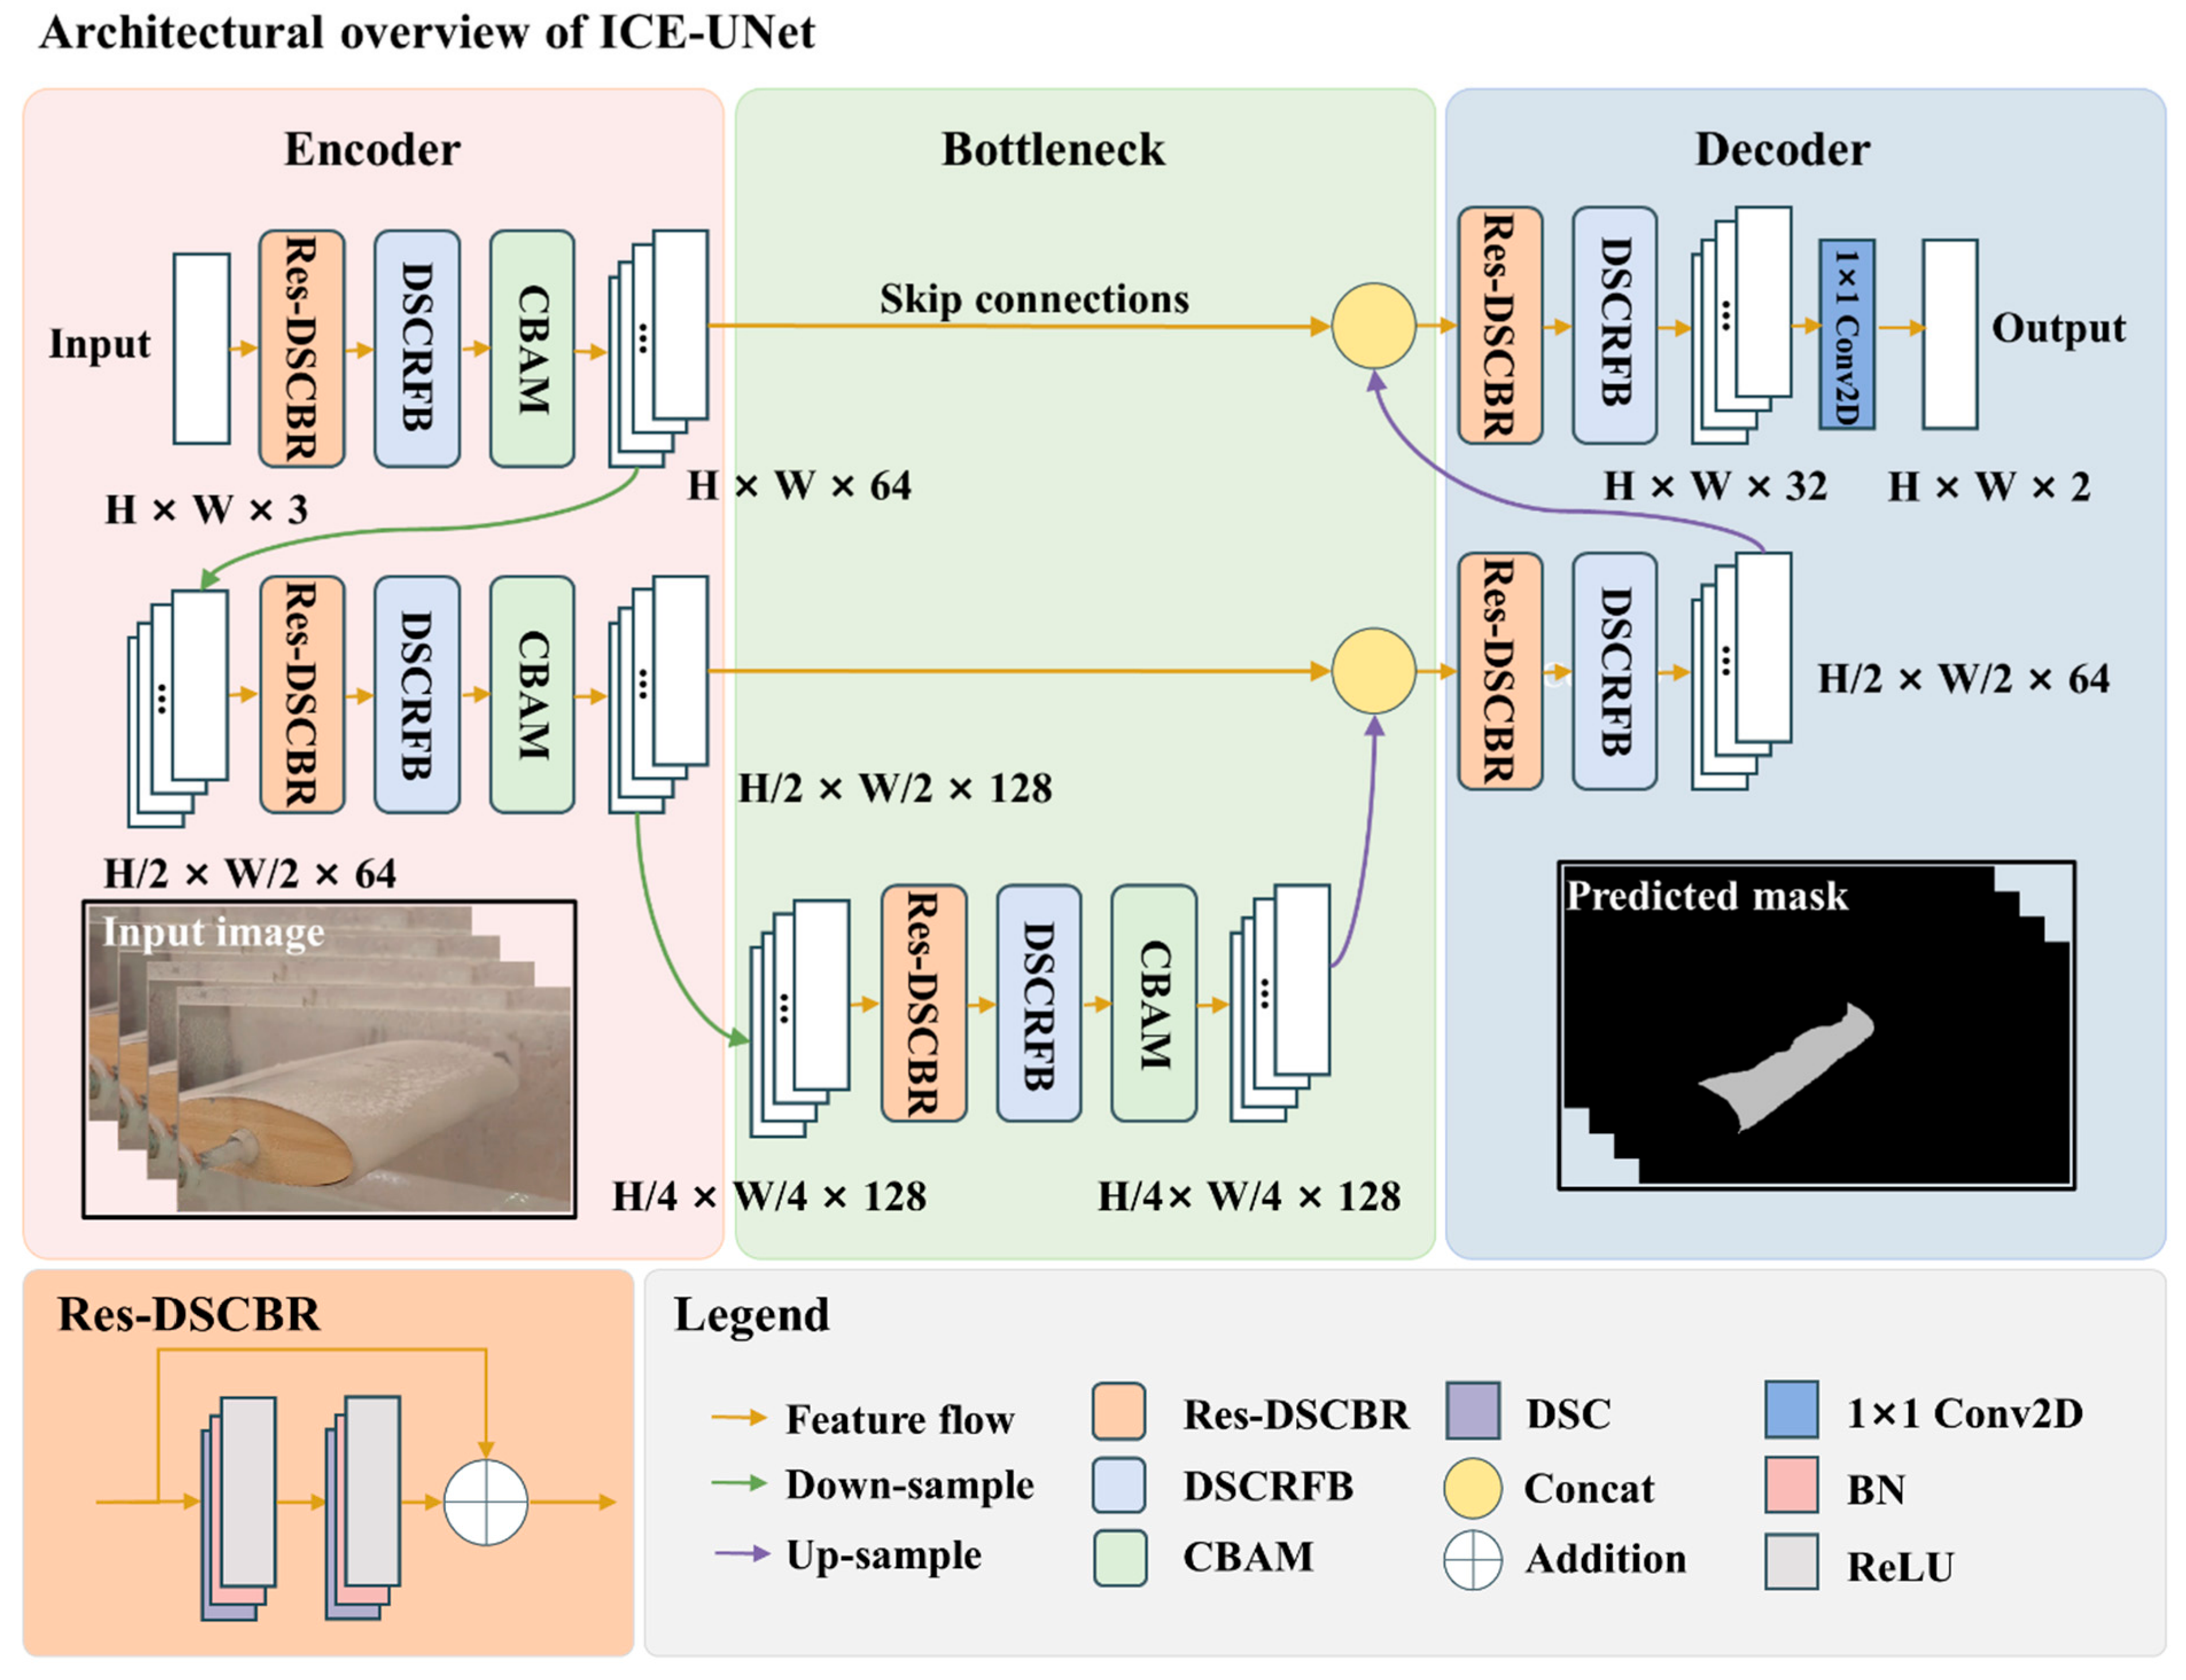
To address the competing requirements of accurate ice-region delineation and computational efficiency, this study proposes ICE-UNet, a lightweight semantic segmentation network for airfoil-icing detection. As shown in Figure 5, ICE-UNet follows an encoder–bottleneck–decoder topology with skip connections for multi-level feature fusion. The encoder progressively extracts ice-related visual features from the input image, the bottleneck aggregates deeper contextual information, and the decoder restores the spatial resolution to generate a pixel-wise predicted mask.
Figure 5.
Architecture of the proposed ICE-UNet with Res-DSCBR blocks, RFB modules, CBAMs, multi-scale feature extraction, and encoder–decoder feature fusion.
The architecture is built around three functional modules: Residual Depthwise Separable Convolution with Batch Normalization and ReLU Activation (Res-DSCBR), Depthwise-Separable Receptive Field Block (DSCRFB), and Convolutional Block Attention Module (CBAM). Res-DSCBR is used as the basic feature extraction unit throughout the network. It replaces standard convolutional operations with depthwise separable convolutions and introduces residual learning to reduce computational cost while maintaining stable feature propagation. DSCRFB is incorporated after Res-DSCBR to enlarge the effective receptive field and capture multi-scale contextual cues associated with different ice shapes and boundary patterns. CBAM is further embedded in the encoder and bottleneck stages to recalibrate channel and spatial responses, thereby emphasizing ice-relevant regions and suppressing irrelevant background features.
In the decoder, upsampled deep features are concatenated with the corresponding encoder features through skip connections, allowing fine spatial details to be recovered during mask reconstruction. The final prediction head maps the decoded feature representation to a two-channel segmentation output using a 1 × 1 convolution. Overall, ICE-UNet combines compact feature extraction, multi-scale receptive field enhancement, and attention-based feature refinement.
To mathematically formulate the forward propagation of the proposed ICE-UNet, the input tensor is defined as
where I denotes the input RGB image, and H and W represent its spatial height and width, respectively.
X(0) = I ∈ ℝ3×H×W
Let c(·) denote a residual depthwise separable convolution block with batch normalization and ReLU activation (Res-DSCBR) that produces c output channels, (·) denote a depthwise-separable receptive field block (DSCRFB) with c output channels, 𝒜(·) denote CBAM-based attention refinement, (·) denote downsampling, (·) denote upsampling, and Concat(·) denote channel-wise concatenation. The first encoder stage extracts low-level spatial features while preserving the original spatial resolution:
E0 = 𝒜(64(64(X(0)))) ∈ ℝ64×H×W
The second encoder stage first reduces the spatial resolution and then increases the channel capacity to enhance semantic representation:
At the bottleneck, another downsampling operation is applied, followed by residual depthwise separable feature extraction, receptive field enhancement, and attention refinement:
The decoder progressively restores the spatial resolution. At the first decoder stage, the bottleneck feature is upsampled and concatenated with the corresponding encoder feature E1:
The second decoder stage further restores the feature map to the original spatial resolution by fusing the upsampled decoder feature with E0:
D0 = 32(32(Concat[(D1), E0])) ∈ ℝ32×H×W
For binary semantic segmentation, the final prediction is obtained using a 1 × 1 convolution followed by a Softmax activation:
The residual depthwise separable convolution block is defined as
where c(·) denotes the main residual branch, and c(·) denotes the projection shortcut used to match the channel dimension when necessary. The main branch is formulated as
where denotes a depthwise separable convolution followed by batch normalization and ReLU activation, whereas denotes a depthwise separable convolution followed by batch normalization. The final ReLU activation is applied after residual addition, as shown in Figure 5. A depthwise separable convolution is decomposed into a depthwise spatial convolution and a pointwise channel-mixing convolution:
C(X) = ReLU[C(X) + C(X)]
DSC(X) = PConv1×1(DWConv3×3(X))
3.1. RFB Module
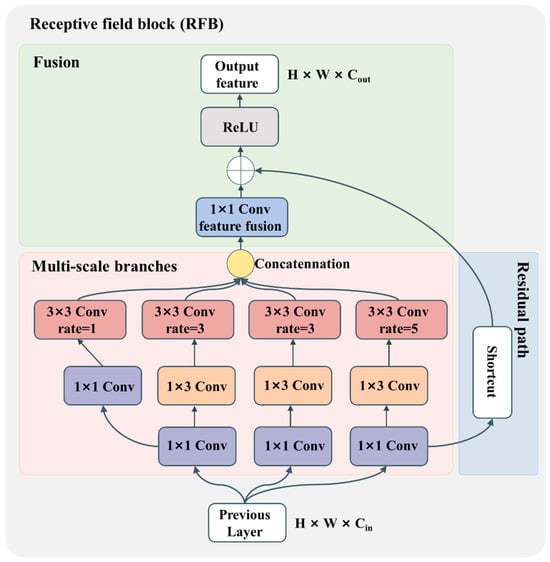
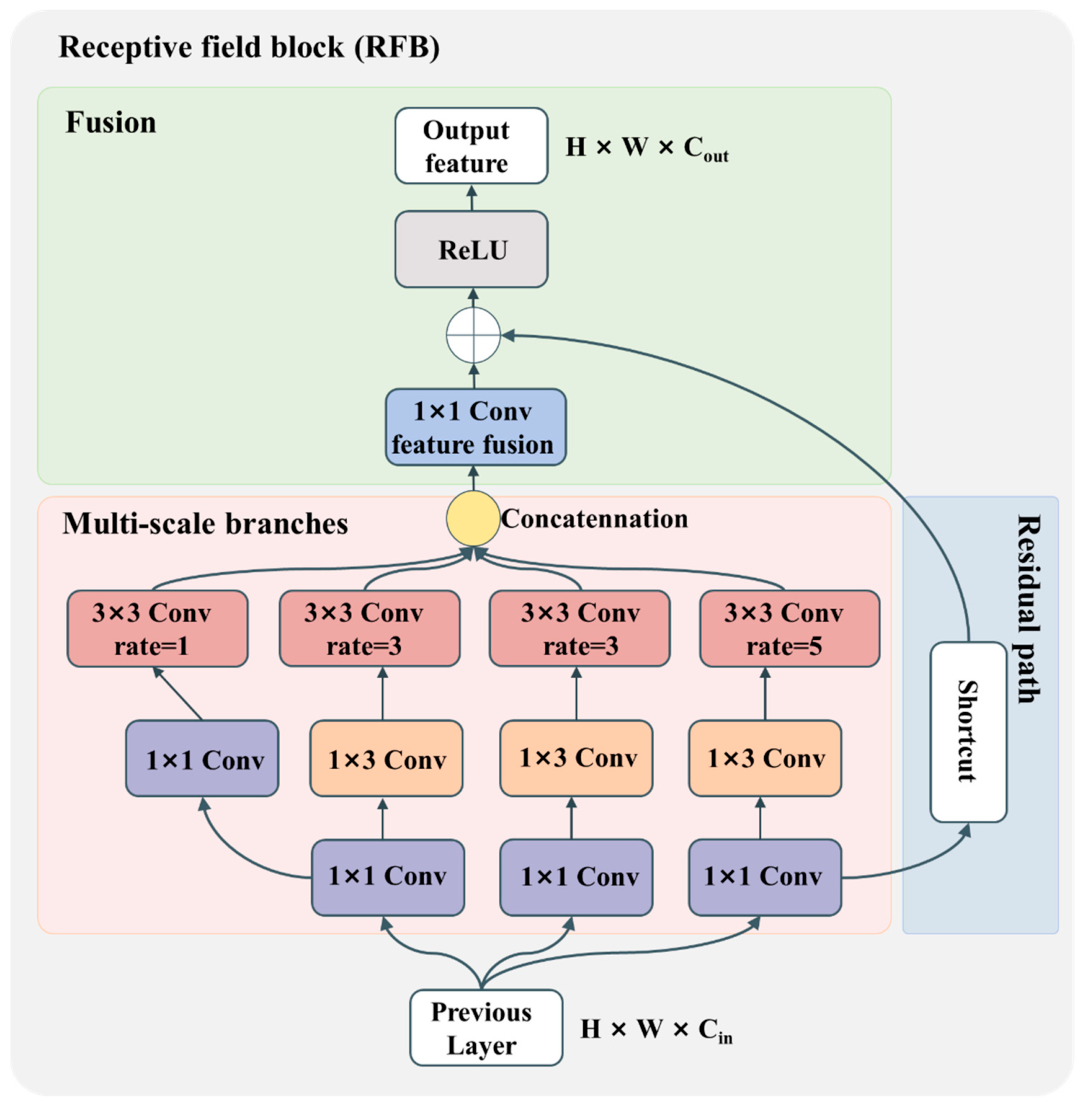
An RFB is integrated into the proposed network architecture to enhance its capability to extract multi-scale icing features. Given that the morphology and spatial distribution of accreted ice regions vary significantly under diverse environmental conditions, conventional convolutions with fixed receptive fields struggle to capture local intricate details and global contextual information simultaneously. The RFB module mitigates this limitation by employing a multi-branch architecture equipped with dilated convolutions at varying dilation rates, thereby expanding the effective receptive field without compromising computational efficiency. As illustrated in Figure 6, the RFB module comprises multiple parallel convolutional branches configured with distinct dilation rates. Branches with higher dilation rates are designed to capture broader contextual information and long-range spatial dependencies, whereas those with lower rates focus on local textures and fine boundary features. The extracted multi-scale feature maps are subsequently concatenated and fused via a 1 × 1 convolution, yielding a highly discriminative feature representation. By aggregating contextual information across multiple spatial scales, the RFB module empowers the network to flexibly accommodate profound variations in ice accretion size and geometry. Consequently, this significantly improves the accuracy and robustness of ice segmentation at the airfoil leading edge.
Figure 6.
Schematic architecture of the RFB module, illustrating multi-scale feature extraction via multi-branch dilated convolutions.Arrows indicate feature flow; the yellow node denotes feature concatenation, and the circled plus sign denotes element-wise addition along the residual path.
3.2. DSC Module
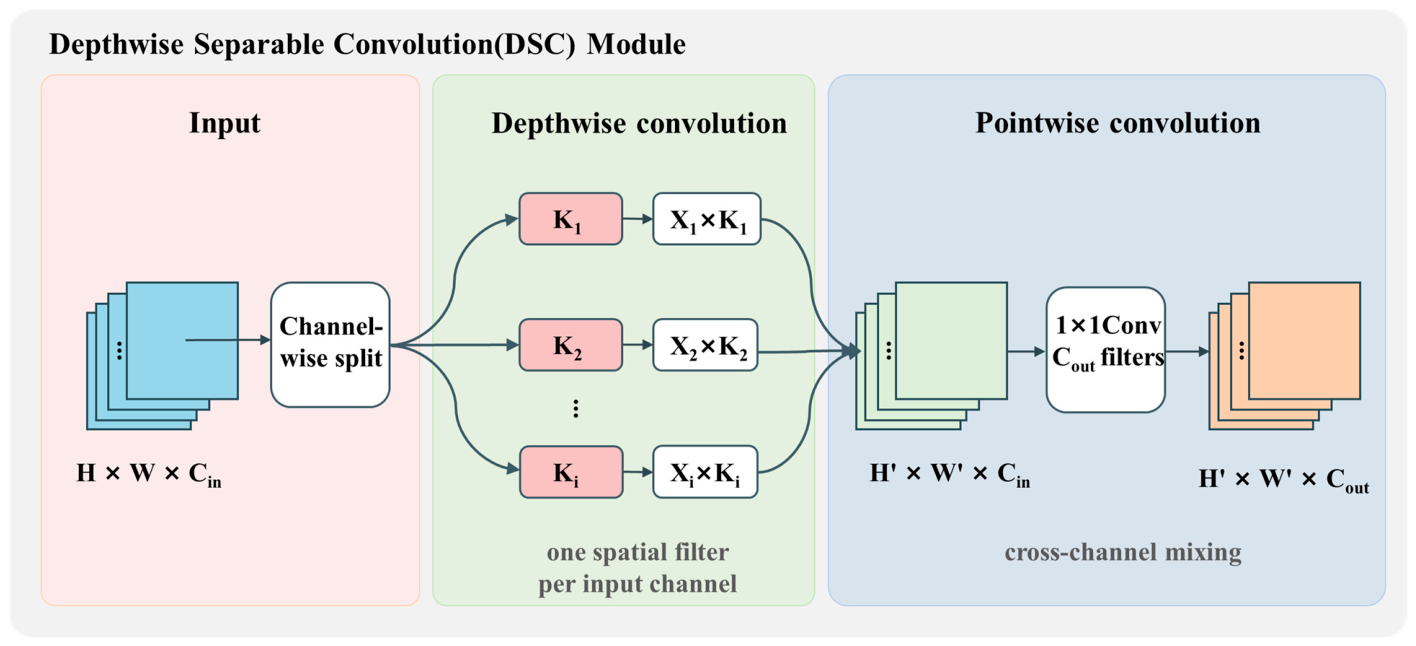
To mitigate computational complexity, the proposed ICE-UNet employs DSC in place of standard convolutional layers throughout the network architecture. As depicted in Figure 7, a standard convolution operation is factorized into two successive stages: a spatial depthwise convolution and a subsequent pointwise convolution. During the depthwise convolution phase, spatial filtering is executed independently across each input channel. This mechanism drastically reduces the required number of convolution kernels, thereby alleviating the computational burden. This is immediately followed by a 1 × 1 pointwise convolution, which aggregates cross-channel information to facilitate feature fusion and enhance the overall representational capacity. Through this decoupled design, the model sustains robust feature extraction performance while achieving a substantial reduction in both total parameter count and computational overhead.
Figure 7.
Schematic of the DSC module, illustrating the decoupling of spatial and channel-wise feature extraction. Arrows indicate feature flow, and the ellipses represent additional feature channels omitted for clarity.
3.3. CBAM
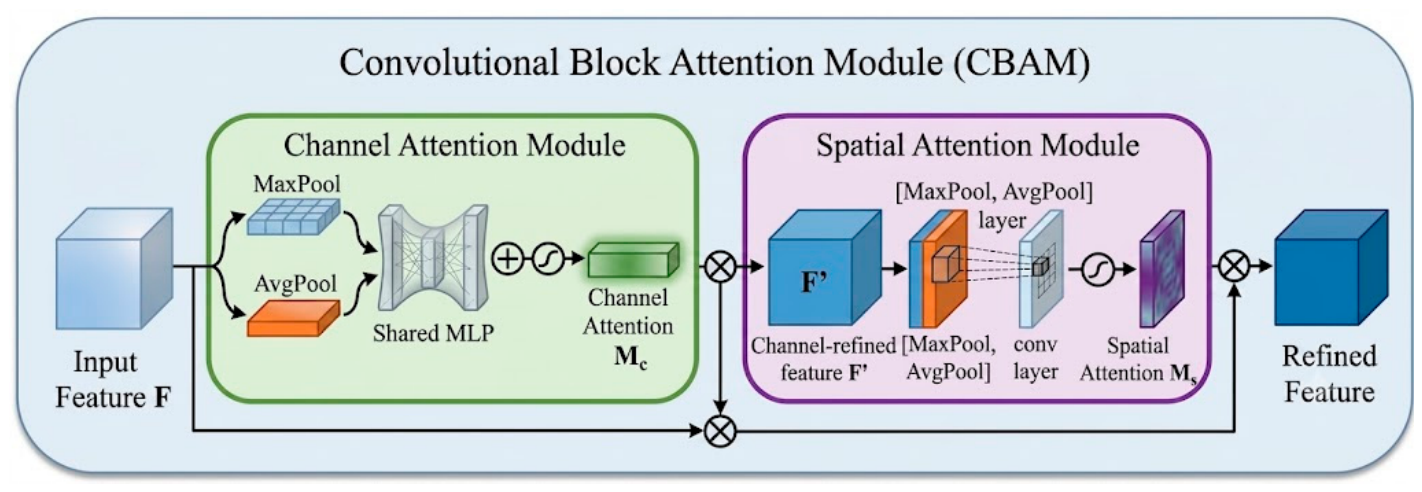
As illustrated in Figure 8, the CBAM is a lightweight attention mechanism that sequentially infers attention maps along two distinct dimensions: channel and spatial. To further augment the model’s capacity to focus on highly informative features, the CBAM is integrated into the ICE-UNet architecture. Specifically, the channel attention submodule adaptively recalibrates the importance of different feature channels by modeling inter-channel dependencies. Subsequently, the spatial attention submodule accentuates the most salient spatial regions within the feature maps. Through this dual-attention design, the network effectively suppresses irrelevant background clutter while enhancing the feature representations intrinsic to ice accretion regions, thereby elevating segmentation performance under complex visual conditions.
Figure 8.
Schematic architecture of the CBAM, illustrating sequential channel and spatial attention mechanisms for enhanced feature discrimination.Arrows indicate feature flow; ⊕ and ⊗ denote element-wise addition and multiplication, respectively, while the S-shaped symbols denote sigmoid activation. The dashed lines connect the pooled feature maps to the spatial convolution.
4. Experimental Results and Discussion
4.1. Implementation Details
The proposed ICE-UNet was developed using PyTorch 2.6.0 with CUDA 12.4 and cuDNN 9.1.0 acceleration. All experiments were performed on a Windows-based computer equipped with a Tesla V100 GPU, a 4-core CPU, and 32 GB of system memory. The input resolution was 512 × 512 pixels, the batch size was 16, and all segmentation models were trained for 100 epochs. The cross-entropy loss was employed as the optimization objective. Adam is employed as the optimizer, and the parameters were set to (β1 = 0.9), (β2 = 0.999), and (α = 1 × 10⁻⁸), with an initial learning rate of 0.001. To further improve convergence performance, a polynomial (Poly) learning rate decay strategy was employed. All comparison models were run using publicly available code and trained from scratch without pretrained weights; their training losses stabilized within the 100-epoch schedule.
4.2. Evaluation Metrics
Segmentation performance was evaluated at the pixel level using Accuracy, Intersection over Union (IoU), Precision, and Recall. A confusion matrix was accumulated across all evaluation images, with ice and background treated as separate classes. Taking ice as the positive class, TP denotes correctly predicted ice pixels, FP denotes background pixels predicted as ice, FN denotes ice pixels predicted as background, and TN denotes correctly predicted background pixels. Overall Accuracy is defined in Equation (12).
For either class (ice or background), the class-wise IoU, Precision, and Recall are defined in Equations (13)–(15) by treating that class as positive. The IoU, Precision, and Recall values reported in this study are the arithmetic means of the corresponding ice-class and background-class values. Thus, the reported metrics are calculated from pixel counts pooled across images, followed by averaging across the two classes. Parameter count, floating-point operations (FLOPs), and per-image inference time were used to characterize model size, computational cost, and inference efficiency.
4.3. Ablation Study
To examine the incremental effect of each design step during the progressive construction of ICE-UNet, a stepwise ablation study was conducted using U-Net as the baseline. Structural optimization (SO), residual structures (Res), RFB, DSC, and CBAM were introduced sequentially under identical training settings. Each comparison between adjacent configurations therefore measures the effect of one design step within the preceding architecture. The quantitative results of this ablation study are summarized in Table 2. The proposed ICE-UNet achieves optimal performance, yielding an accuracy of 96.60%, an IoU of 93.07%, a precision of 96.36%, and a recall of 96.44%. Crucially, this is accomplished while maintaining a highly lightweight profile of merely 0.76 M parameters and 16.19 GFLOPs. Compared to the baseline U-Net (90.97% accuracy, 82.74% IoU, 17.26 M parameters, and 160.76 GFLOPs), ICE-UNet simultaneously delivers substantial gains in segmentation fidelity and a dramatic reduction in computational overhead.
Table 2.
Quantitative ablation study of different architectural components in the proposed ICE-UNet.
Analyzing the step-by-step evolution, the initial structural optimization (SO)—which prunes the baseline U-Net to three stages and caps bottleneck channels at 128—slashes parameters to 1.93 M. However, this naive compression destroys high-frequency spatial details essential for delineating complex ice boundaries, dropping the IoU to 80.57%. The subsequent introduction of residual structures (Res) effectively mitigates this information bottleneck, recovering the IoU to 83.58% by preserving low-level morphological features across deep layers. Furthermore, the RFB module elevates the IoU to 89.61%, providing critical scale invariance to accommodate the diverse, multi-scale nature of ice accretions. Replacing standard convolutions with DSC reduced the model to 0.75 M parameters and 16.17 GFLOPs while increasing IoU from 89.61% to 91.27% in the stepwise configuration. Finally, the CBAM yields the peak performance (96.60% accuracy, 93.07% IoU) at negligible computational cost by selectively amplifying informative features and suppressing ambient interferences like uneven lighting. Collectively, the successive configurations show how the design steps shape the final model’s accuracy–efficiency profile, reaching 93.07% IoU with 0.76 M parameters and 16.19 GFLOPs on the evaluated dataset.
4.4. Performance Comparison
To rigorously assess the effectiveness of the proposed ICE-UNet, 9 widely used semantic segmentation models, namely FCN [29], SegNet [20], U-Net [19], UNext [23], ENet [30], DABNet [31], BiSeNet [32], PSPNet [21], and DeepLabV3+ [22], were selected for comparison. All models were trained and evaluated on the same airfoil-icing dataset under identical experimental settings. The quantitative results, evaluating both segmentation fidelity and computational efficiency, are detailed in Table 3, with the optimal values highlighted in bold.
Table 3.
Quantitative comparison of leading-edge ice segmentation performance across various deep learning models.
As demonstrated in Table 3, the proposed ICE-UNet achieves the highest values for all four segmentation metrics among the ten models evaluated on the present wind-tunnel dataset. Specifically, the model attains an accuracy of 96.60%, an IoU of 93.07%, a precision of 96.36%, and a recall of 96.44%, comprehensively outperforming all competing methods. Compared to the baseline U-Net, ICE-UNet elevates the IoU from 82.74% to 93.07%, a substantial absolute increase of 10.33%. Furthermore, it surpasses high-capacity models such as PSPNet and DeepLabV3+, underscoring its superior capability in accurately identifying ice accretion regions and precisely delineating complex phase boundaries.
Beyond exceptional segmentation accuracy, ICE-UNet exhibits remarkable computational efficiency. The proposed architecture requires merely 0.76 M parameters and 16.19 GFLOPs, which is orders of magnitude lower than those of heavyweight models like PSPNet (49.07 M parameters, 194.40 GFLOPs) and DeepLabV3+ (37.05 M parameters, 50.60 GFLOPs). While certain lightweight networks such as ENet and DABNet boast marginally lower computational overhead, their segmentation fidelity is significantly compromised. For instance, DABNet operates with a comparable parameter footprint (0.75 M) but only yields an IoU of 89.29%, falling far short of ICE-UNet’s 93.07%. These empirical results show that ICE-UNet combines high segmentation precision with low computational cost on images of the two airfoil models evaluated in this wind-tunnel study.
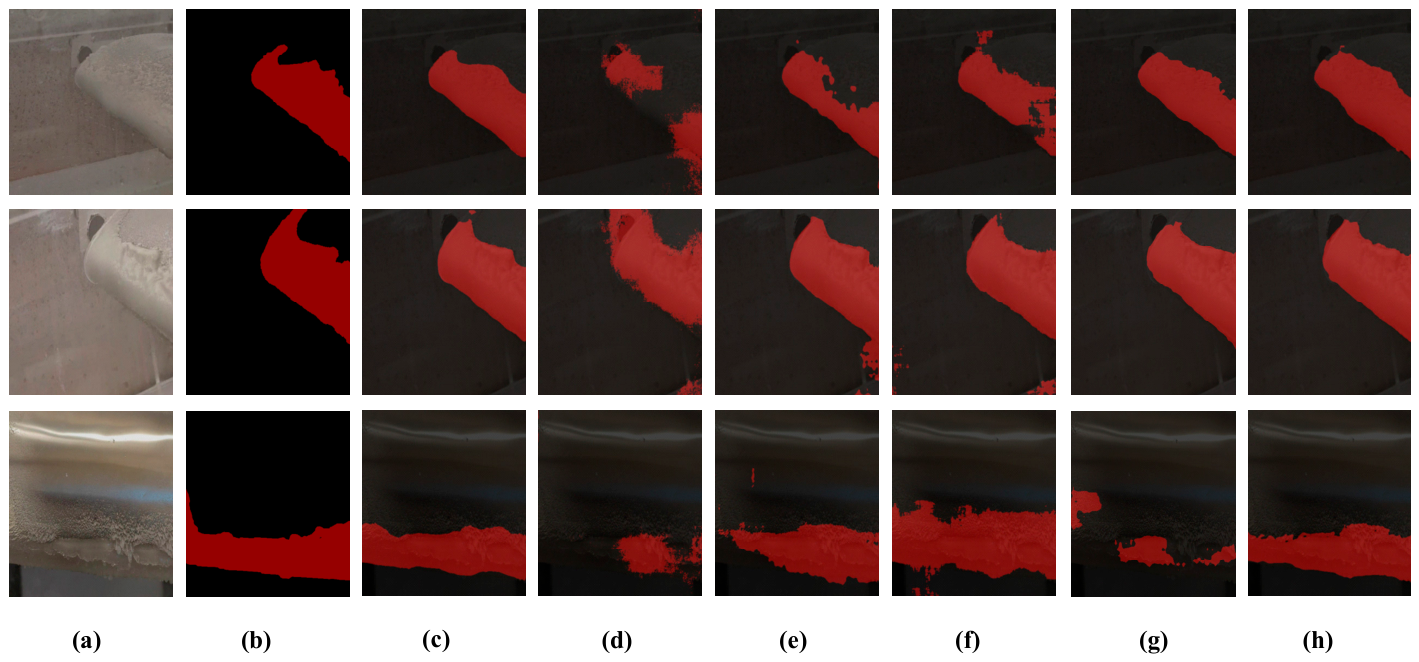
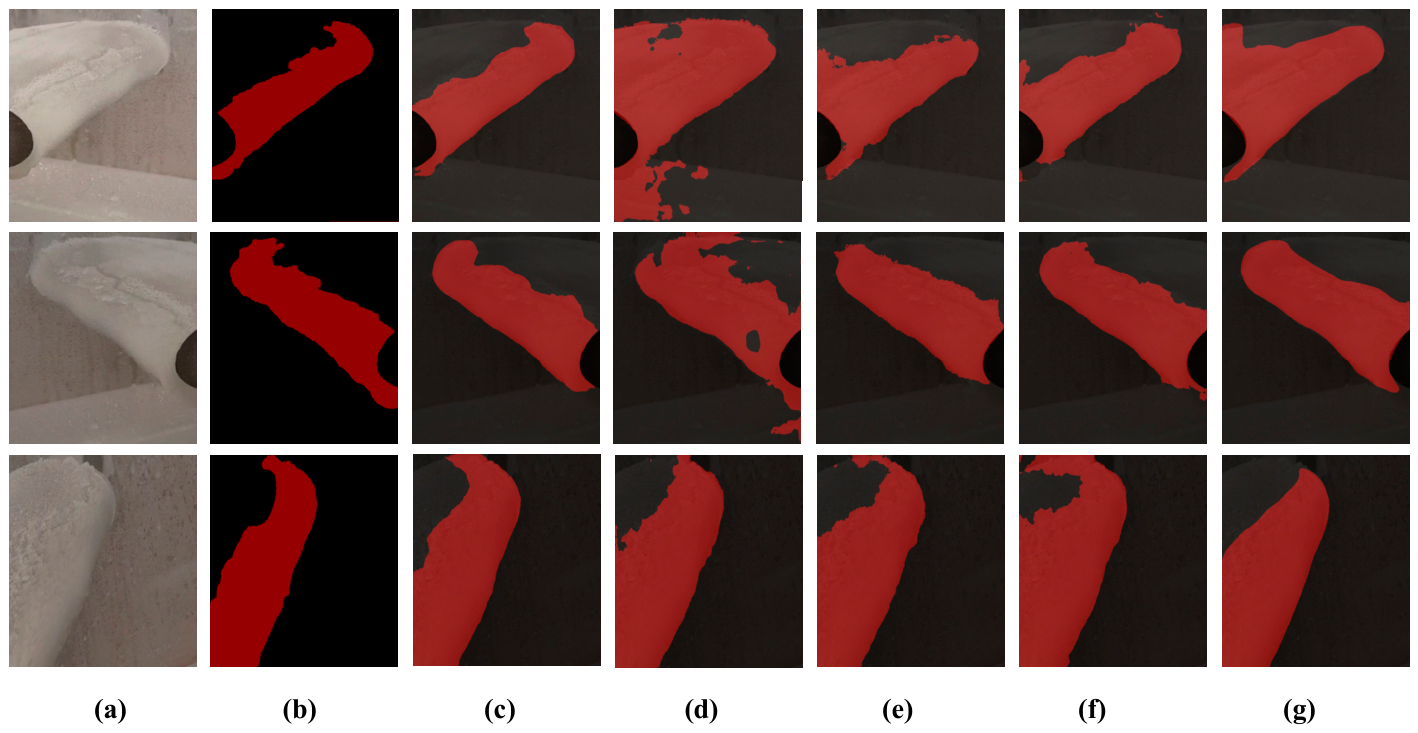
Qualitative evaluations further corroborate these findings. As observed in the visual comparisons (Figure 9 and Figure 10), ICE-UNet consistently generates sharp, coherent, and highly accurate ice-region contours. In contrast, competing models suffer from varying degrees of degradation, including blurred boundaries, incomplete regional segmentation, and heightened vulnerability to wind-tunnel background interference. Overall, the extensive comparative experiments effectively validate the comprehensive advantages of the proposed architecture. ICE-UNet not only establishes superior benchmarks across all accuracy metrics compared to mainstream alternatives but also accomplishes this with an exceptionally minimal computational footprint. This balance between segmentation precision and computational cost supports the use of ICE-UNet for segmenting the evaluated wind-tunnel airfoil images.
Figure 9.
Qualitative visual comparison of airfoil leading-edge ice segmentation results obtained by heavyweight models: (a) original image; (b) ground-truth mask; (c) ICE-UNet; (d) FCN; (e) U-Net; (f) SegNet; (g) PSPNet; and (h) DeepLabV3+.Red indicates the ice regions in the ground-truth mask and model predictions.
Figure 10.
Qualitative visual comparison of airfoil leading-edge ice segmentation results obtained by lightweight models: (a) original image; (b) ground-truth mask; (c) ICE-UNet; (d) FCN; (e) U-Net; (f) UNeXt; and (g) ENet.Red indicates the ice regions in the ground-truth mask and model predictions.
4.5. Grad-CAM Visualization
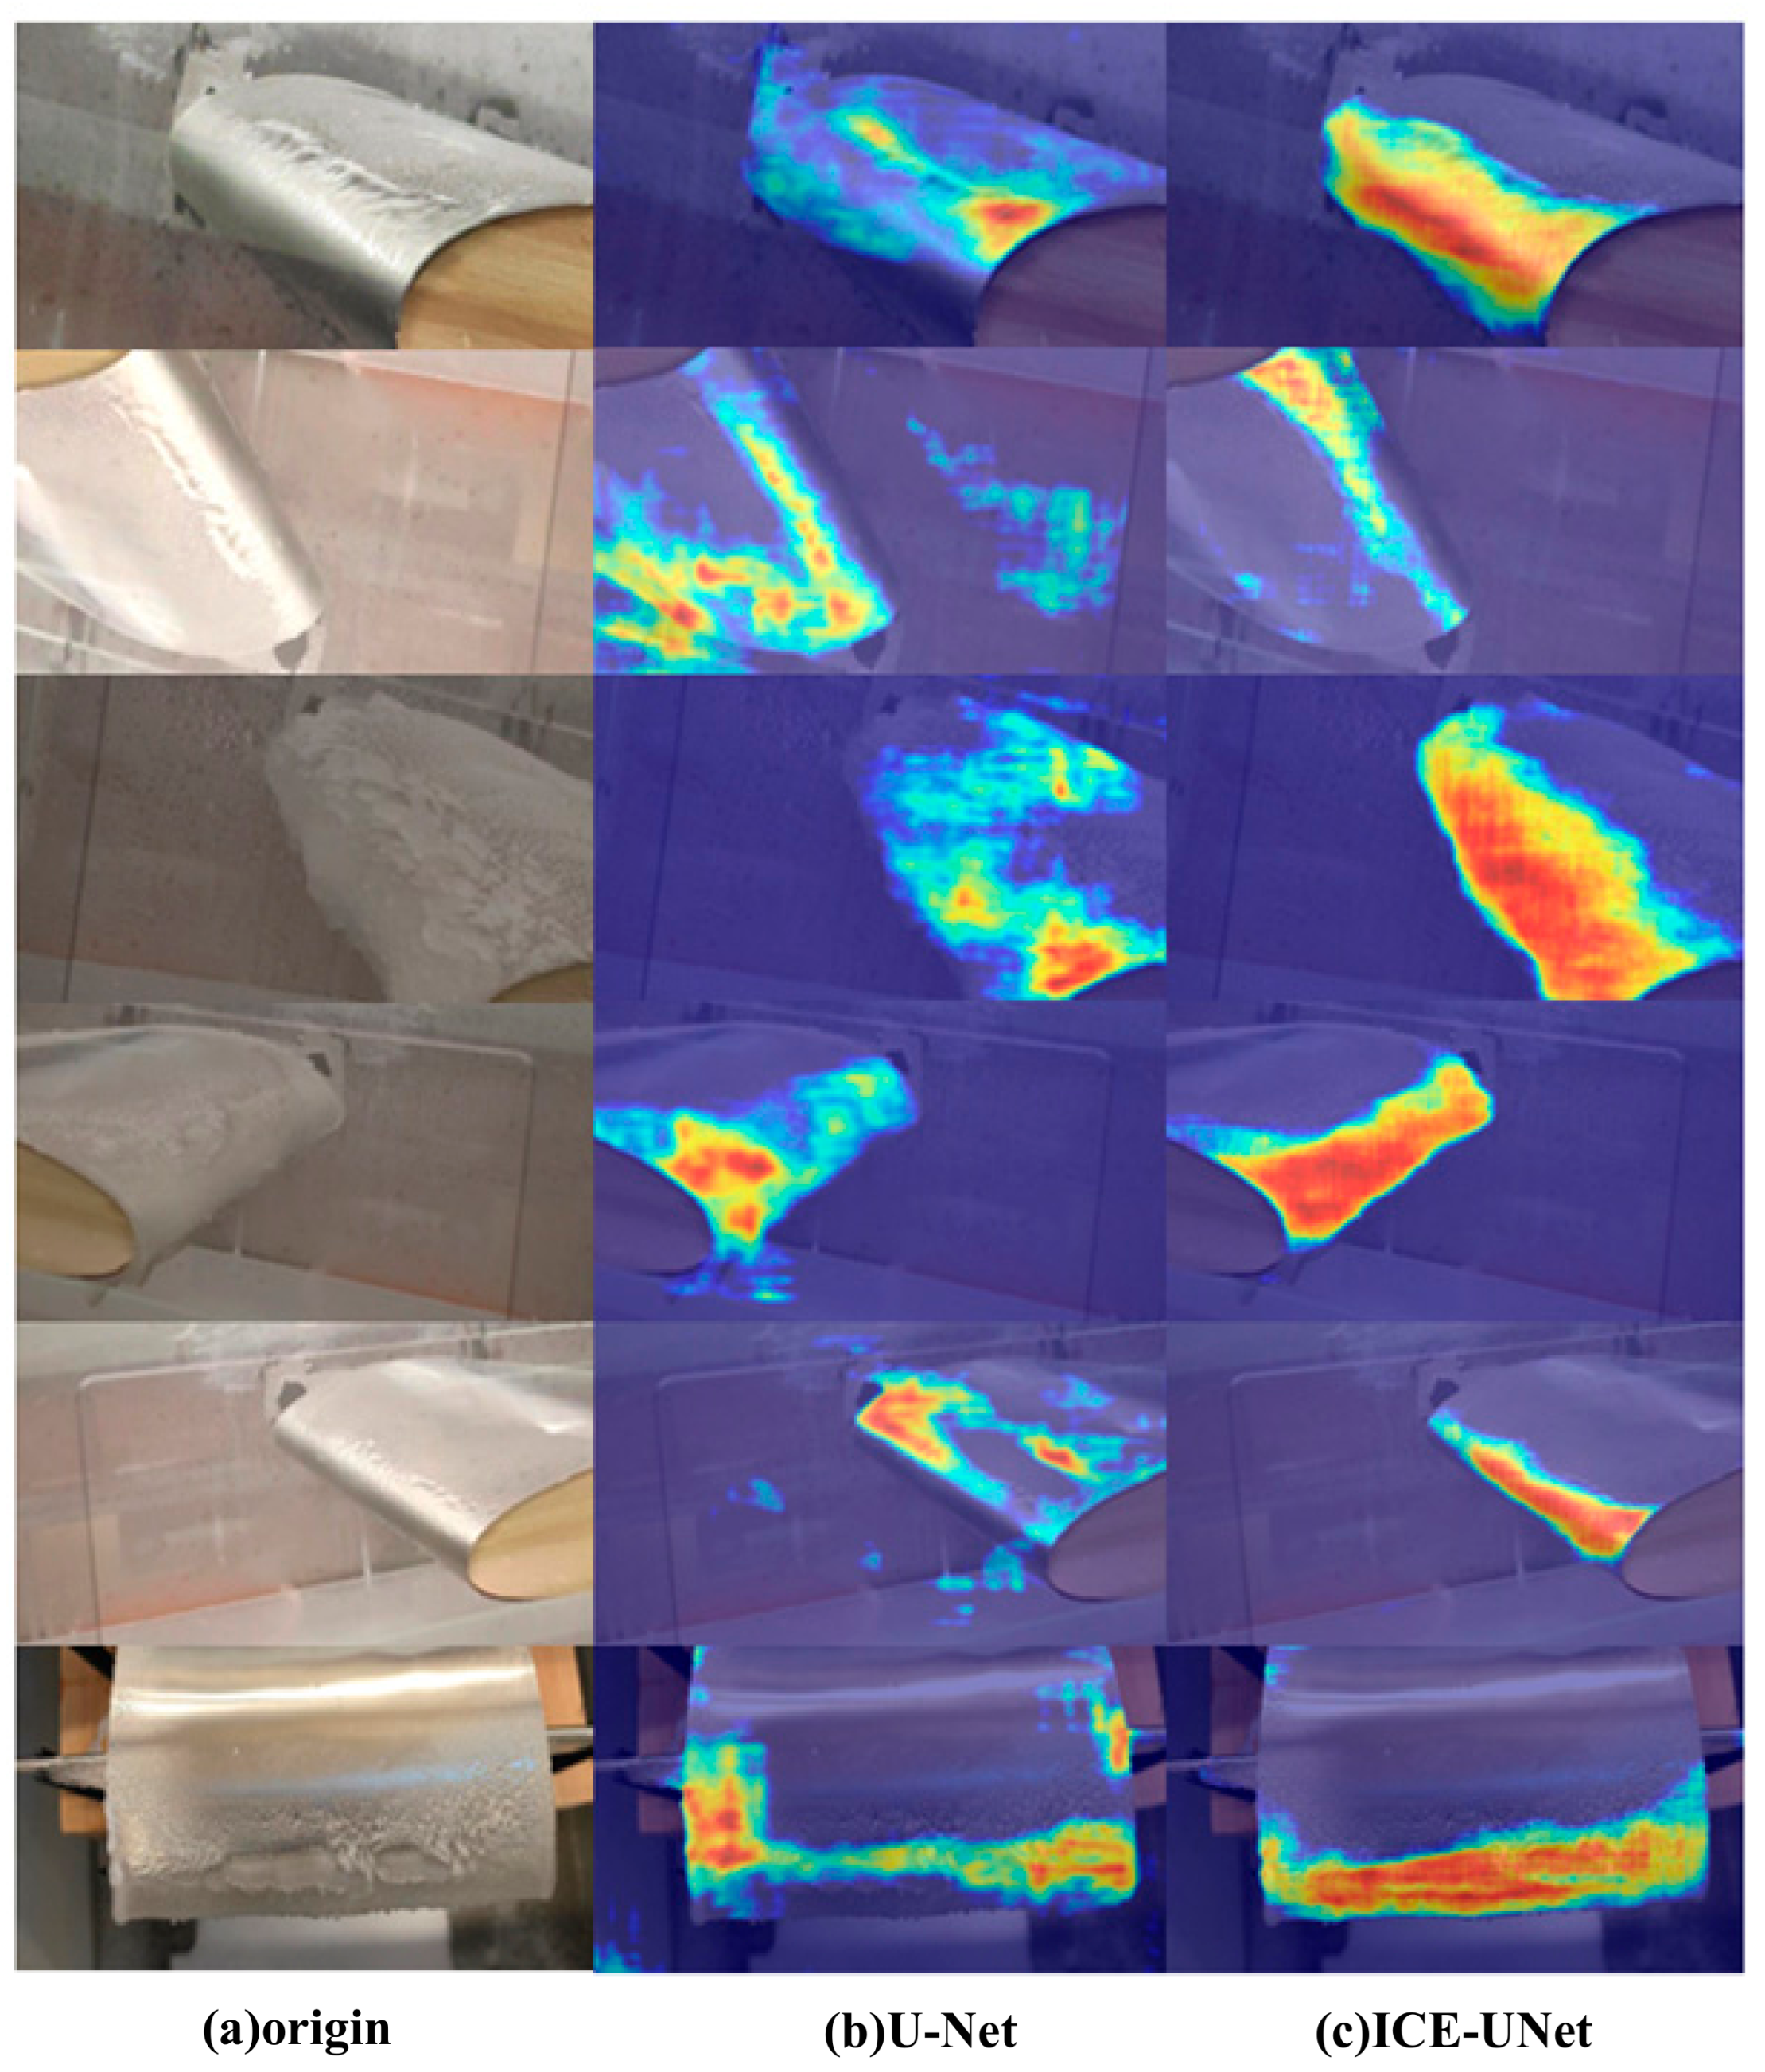
To further evaluate the internal mechanisms of ICE-UNet and to gain an intuitive understanding of its decision-making rationale, this section employs Gradient-Weighted Class Activation Mapping (Grad-CAM) [33]. Heatmaps are generated to visualize the model’s spatial attention distribution across the input images during inference. Specifically, the activation responses of the baseline U-Net and the proposed ICE-UNet are compared using representative samples from the airfoil-icing dataset. In these heatmaps, the color spectrum transitions from cool colors (blue) to warm colors (red), indicating ascending levels of model attention. The warmer regions denote the most salient spatial features that dictate the final segmentation predictions.
As observed in Figure 11b, the high-activation regions of the baseline U-Net are highly dispersed. The model is easily distracted by small surface condensate droplets, scattered ice particles, and irrelevant background clutter, resulting in a diluted focus on the primary leading-edge ice accretion. This lack of spatial focus fundamentally explains the shortcomings observed in the quantitative evaluations, including elevated rates of false positives and false negatives, as well as degraded boundary delineation. In stark contrast, the proposed ICE-UNet demonstrates exceptional feature localization capability (Figure 11c). Its high-activation (warm-colored) responses are densely concentrated on the core ice accretion regions along the leading edge. Conversely, activations corresponding to background environments and non-icing noise elements are robustly suppressed, manifesting as cool-colored regions. This visual evidence intuitively validates the efficacy of the architectural enhancements. Ultimately, these Grad-CAM visualizations provide compelling interpretability for the model’s performance leap. The analysis confirms that, compared to the baseline, ICE-UNet more effectively aggregates contextual information, directing its computational focus toward authentic icing-related features while filtering out extraneous disturbances. This proves that the introduced optimization modules significantly augment the model’s feature discrimination and spatial localization capabilities, thereby ensuring high robustness and precision in airfoil leading-edge icing detection tasks.
Figure 11.
Grad-CAM visualization of airfoil leading-edge ice segmentation: (a) original images; (b) heatmaps generated by the baseline U-Net; and (c) heatmaps generated by ICE-UNet. Warmer colors (yellow to red) indicate stronger relative activation, whereas cooler colors (blue) indicate weaker activation.
4.6. Robustness Under Controlled Photometric Perturbations
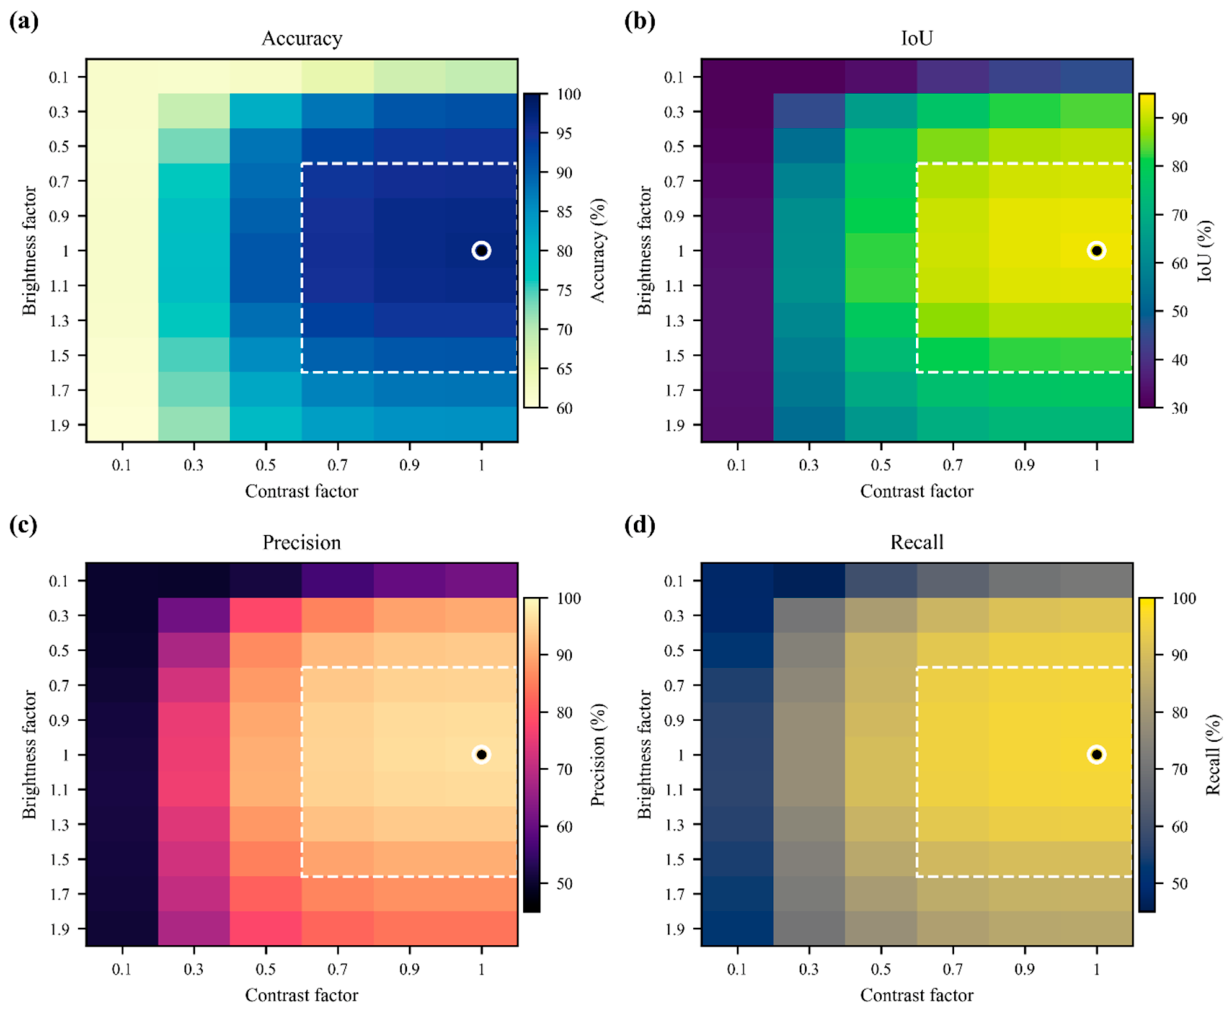
To evaluate ICE-UNet under controlled photometric changes, the brightness and contrast of the held-out test images were systematically adjusted. Figure 12 presents the resulting Accuracy, IoU, Precision, and Recall distributions. The circular markers denote the reference condition, where both factors were set to 1.0. The dashed rectangles indicate the moderate-perturbation range, with brightness factors of 0.7–1.5 and contrast factors of 0.7–1.0.
Figure 12.
Segmentation performance under controlled global brightness and contrast adjustments: (a) Accuracy, (b) IoU, (c) Precision, and (d) Recall. The circular marker denotes the unmodified reference condition, and the dashed rectangles indicate the moderate-perturbation region.
Figure 12a shows the variation in pixel-wise Accuracy. Under the reference condition, ICE-UNet achieved an Accuracy of 96.60%. Accuracy remained above 86% throughout the moderate-perturbation range and exceeded 90% in most cases. When the contrast factor decreased to 0.1, however, Accuracy fell to approximately 61%, irrespective of the brightness level. This result indicates that severe contrast degradation cannot be effectively compensated for by adjusting image brightness.
Figure 12b presents the IoU distribution, which more directly reflects the overlap between the predicted and ground-truth icing regions. The highest IoU of 93.07% was obtained under the reference condition. Within the dashed region, IoU generally remained above 80%, confirming stable ice-region localization under moderate photometric variations. By contrast, reducing the contrast factor to 0.1 decreased IoU to approximately 31–34% across all brightness levels. At a contrast factor of 1.0, IoU decreased to 45.71% under severe underexposure and 72.82% under severe overexposure. These results show that contrast loss exerted a stronger influence than brightness variation alone.
Figure 12c illustrates the corresponding changes in Precision. ICE-UNet achieved a Precision of 96.36% under the reference condition and maintained values above approximately 89% across most of the moderate-perturbation region. This performance indicates that the model produced relatively few false-positive icing predictions under moderate illumination disturbances. Nevertheless, Precision declined to approximately 50–52% when the contrast factor was reduced to 0.1. Severe contrast loss therefore increased the likelihood of background regions being incorrectly classified as ice.
Figure 12d shows that Recall followed a trend similar to that of Precision. The reference Recall reached 96.44%, while values within the moderate-perturbation region generally remained above 85%. This result demonstrates that ICE-UNet retained most icing-region pixels under moderate brightness and contrast variations. Under extremely low contrast, Recall decreased to approximately 48–57%, indicating substantial omission of icing regions. Recall was particularly affected when low contrast was combined with severe underexposure.
A comparison of Figure 12a–d further reveals that Accuracy remained relatively high in several cases where IoU, Precision, and Recall had already deteriorated substantially. This discrepancy can be attributed to the predominance of background pixels in the segmentation images. Consequently, Accuracy alone may overestimate model performance under severe image degradation, whereas IoU provides a more representative measure of ice-region segmentation quality. Overall, ICE-UNet achieved 93.07% IoU at the reference setting and generally maintained IoU above 80% for brightness factors of 0.7–1.5 and contrast factors of 0.7–1.0 in the tested airfoil-icing images, supporting its applicability under comparable imaging conditions.
4.7. Inference Acceleration and a Two-Stage Cascaded Framework
4.7.1. TensorRT Acceleration and Inference Efficiency
To evaluate the deployment feasibility of ICE-UNet, inference efficiency was benchmarked at an input resolution of 512 × 512 pixels on a Tesla V100 GPU workstation. The unoptimized CPU and original GPU implementations required 380.76 ms and 55.21 ms per image, respectively. By leveraging TensorRT for operator fusion and memory optimization, the inference latency was dramatically reduced to 16.46 ms in FP32 mode and 13.69 ms in FP16 mode. Notably, the FP16 precision mode completely preserved the original segmentation metrics (e.g., 96.60% Accuracy and 93.07% IoU), striking the optimal balance between segmentation fidelity and inference speed. The corresponding segmentation metrics and GPU inference times are summarized in Table 4.
Table 4.
Segmentation performance and per-image inference time before and after TensorRT optimization.
While INT8 quantization further decreased the latency to 12.46 ms, it caused a severe degradation in segmentation performance, with the IoU plummeting from 93.07% to 67.22%. Consequently, the marginal speed gain of INT8 does not justify the substantial accuracy loss in safety-critical icing detection tasks. In contrast, the FP16 implementation achieved a remarkable 75.2% latency reduction relative to the original GPU baseline with zero accuracy penalty. These results demonstrate low-latency ICE-UNet segmentation inference on the Tesla V100 workstation and provide a basis for further evaluation of the complete monitoring pipeline.
4.7.2. Two-Stage Cascaded Framework for Continuous Monitoring
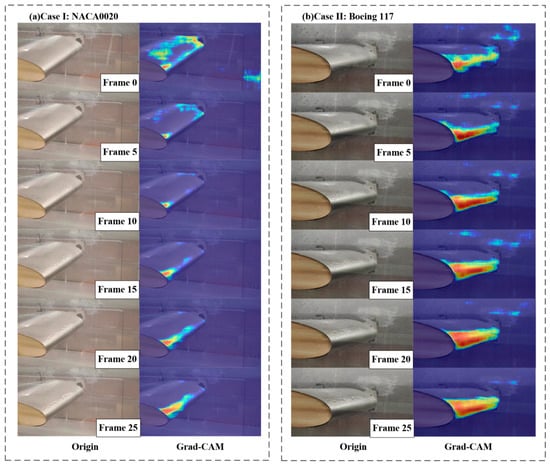
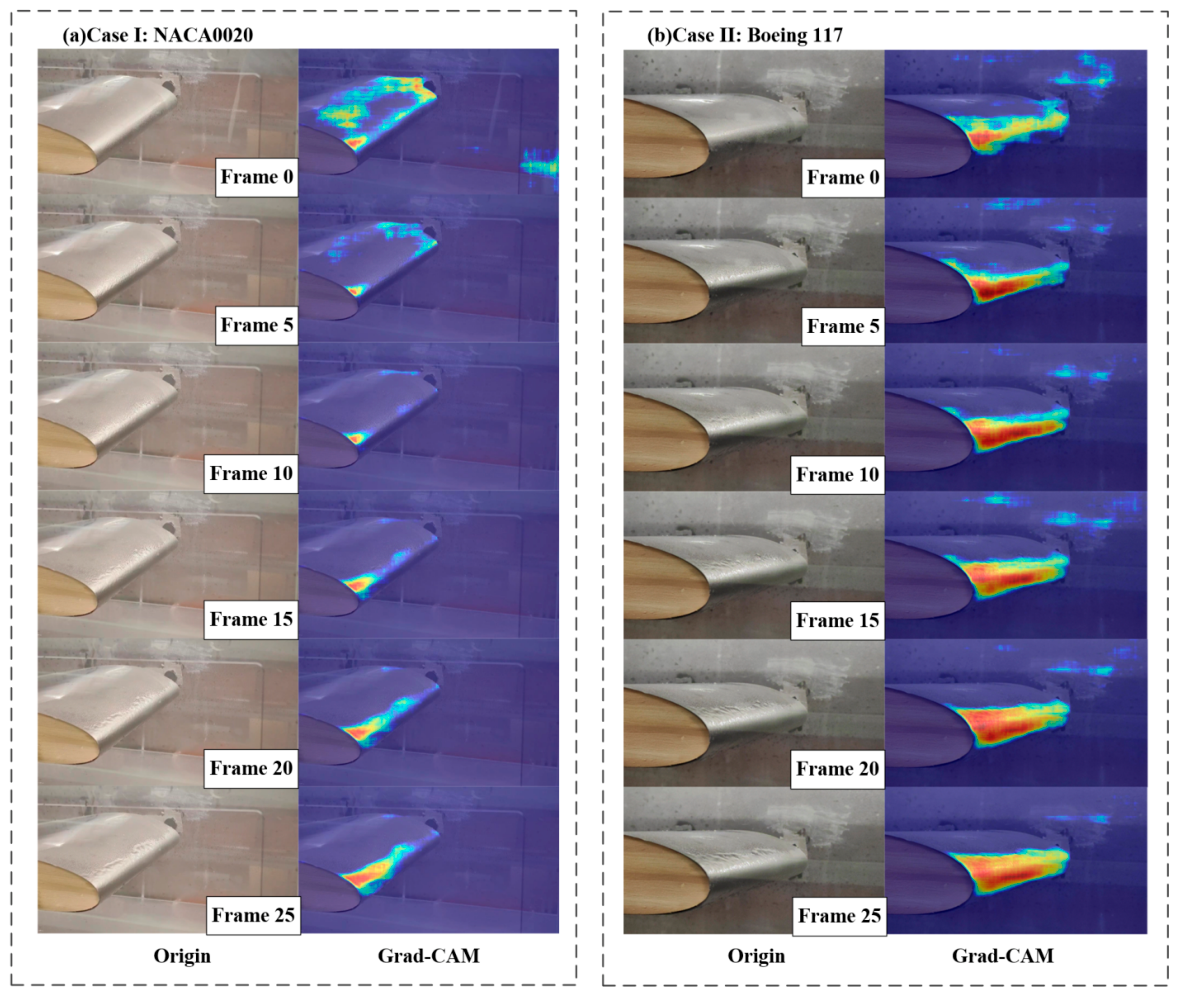
In practical continuous wind-tunnel testing or in-flight monitoring scenarios, aircraft airfoils remain completely ice-free for extended periods. The transition from a clean aerodynamic surface to early-stage ice accretion (e.g., extremely thin, transparent layers) is visually subtle, inherently leading to feature ambiguity. This phenomenon is clearly captured in the temporal Grad-CAM visualizations (Figure 13), which sample the icing process every 5 frames across two distinct airfoil profiles: NACA0020 (Case I) and Boeing 117 (Case II). At Frame 0, when the wings are completely non-iced, applying the pixel-wise segmentation network directly induces false-positive activations on the bare leading edge. Although ICE-UNet accurately and robustly localizes the icing regions once distinct visual cues emerge (e.g., Frame 5 and beyond), continuously running the segmentation model on clean surfaces incurs unnecessary computational overhead and compromises system reliability.
Figure 13.
Temporal Grad-CAM visualization of the transition from an ice-free state to successive stages of ice accretion for (a) NACA 0020 and (b) Boeing 117 airfoils (sampled every five frames). Warmer colors (yellow to red) indicate stronger relative activation, whereas cooler colors (blue) indicate weaker activation. Frame 0 shows the ice-free surface; subsequent frames show the evolution of model activations as visible ice accretion develops.
The proposed framework therefore uses a two-stage cascade. MobileNetV3 [34] first screens each frame for ice presence, and ICE-UNet produces a pixel-wise mask for frames classified as iced. The MobileNetV3 classifier was trained for 20 epochs using the same dataset-splitting strategy as the segmentation experiments. At a decision threshold of 0.5, frames classified as ice-free bypass ICE-UNet, avoiding unnecessary segmentation of those frames.
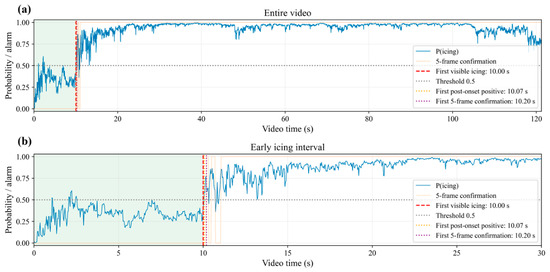
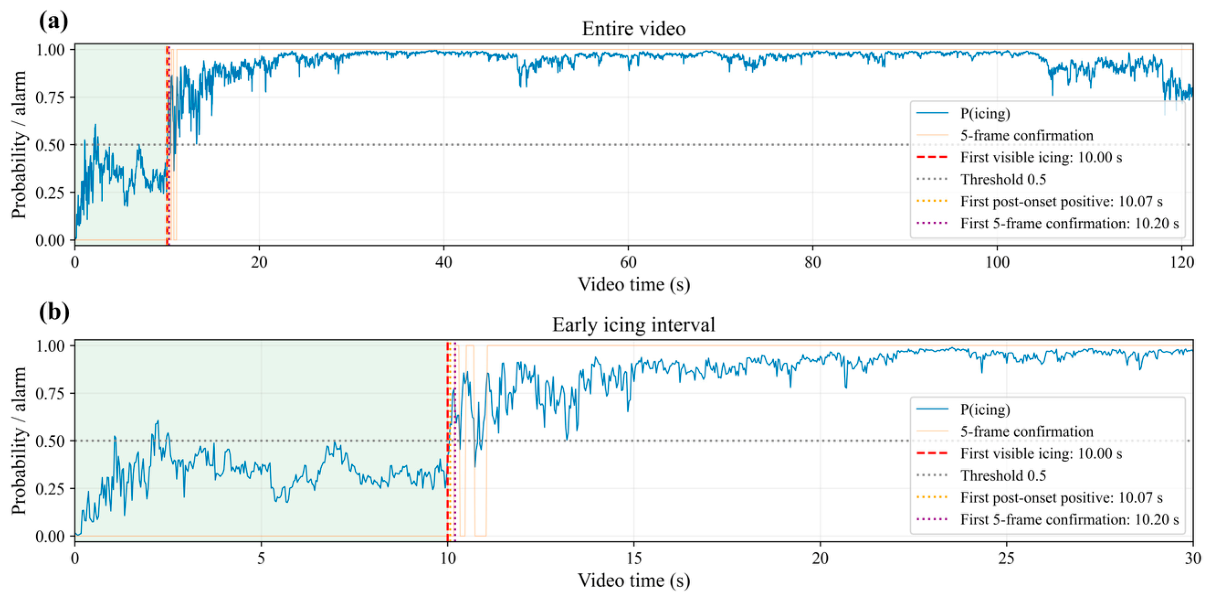
On an image-level validation set of 1369 images (764 iced and 605 ice-free), MobileNetV3 correctly classified 740 iced images and 577 ice-free images, yielding 96.35% precision and 96.86% recall for the iced class and a 4.63% false-positive rate for ice-free images (28/605). Figure 14 presents the temporal probability curve for one recorded video at 30 frames per second. Visible icing first appeared at 10.00 s, followed by the first positive classification at 10.07 s. With an optional five-consecutive-positive confirmation rule, the first confirmed alarm occurred at 10.20 s. None of the 11 positive frames before visible icing produced a confirmed alarm under this rule.
Figure 14.
MobileNetV3 icing probability across one 30 FPS video: (a) full sequence and (b) enlarged onset interval. Visible ice first appeared at 10.00 s. With a 0.5 decision threshold, the first post-onset positive classification occurred at 10.07 s. The first confirmation from an optional five-consecutive-positive-frame rule occurred at 10.20 s. This rule is a temporal post-processing step (orange line in panel b: 1 when the criterion is met, 0 otherwise). Before visible icing, 11 of 300 frames were classified as positive; none reached five-frame confirmation. The light-green shaded area marks the interval before the first visible icing at 10.00 s.
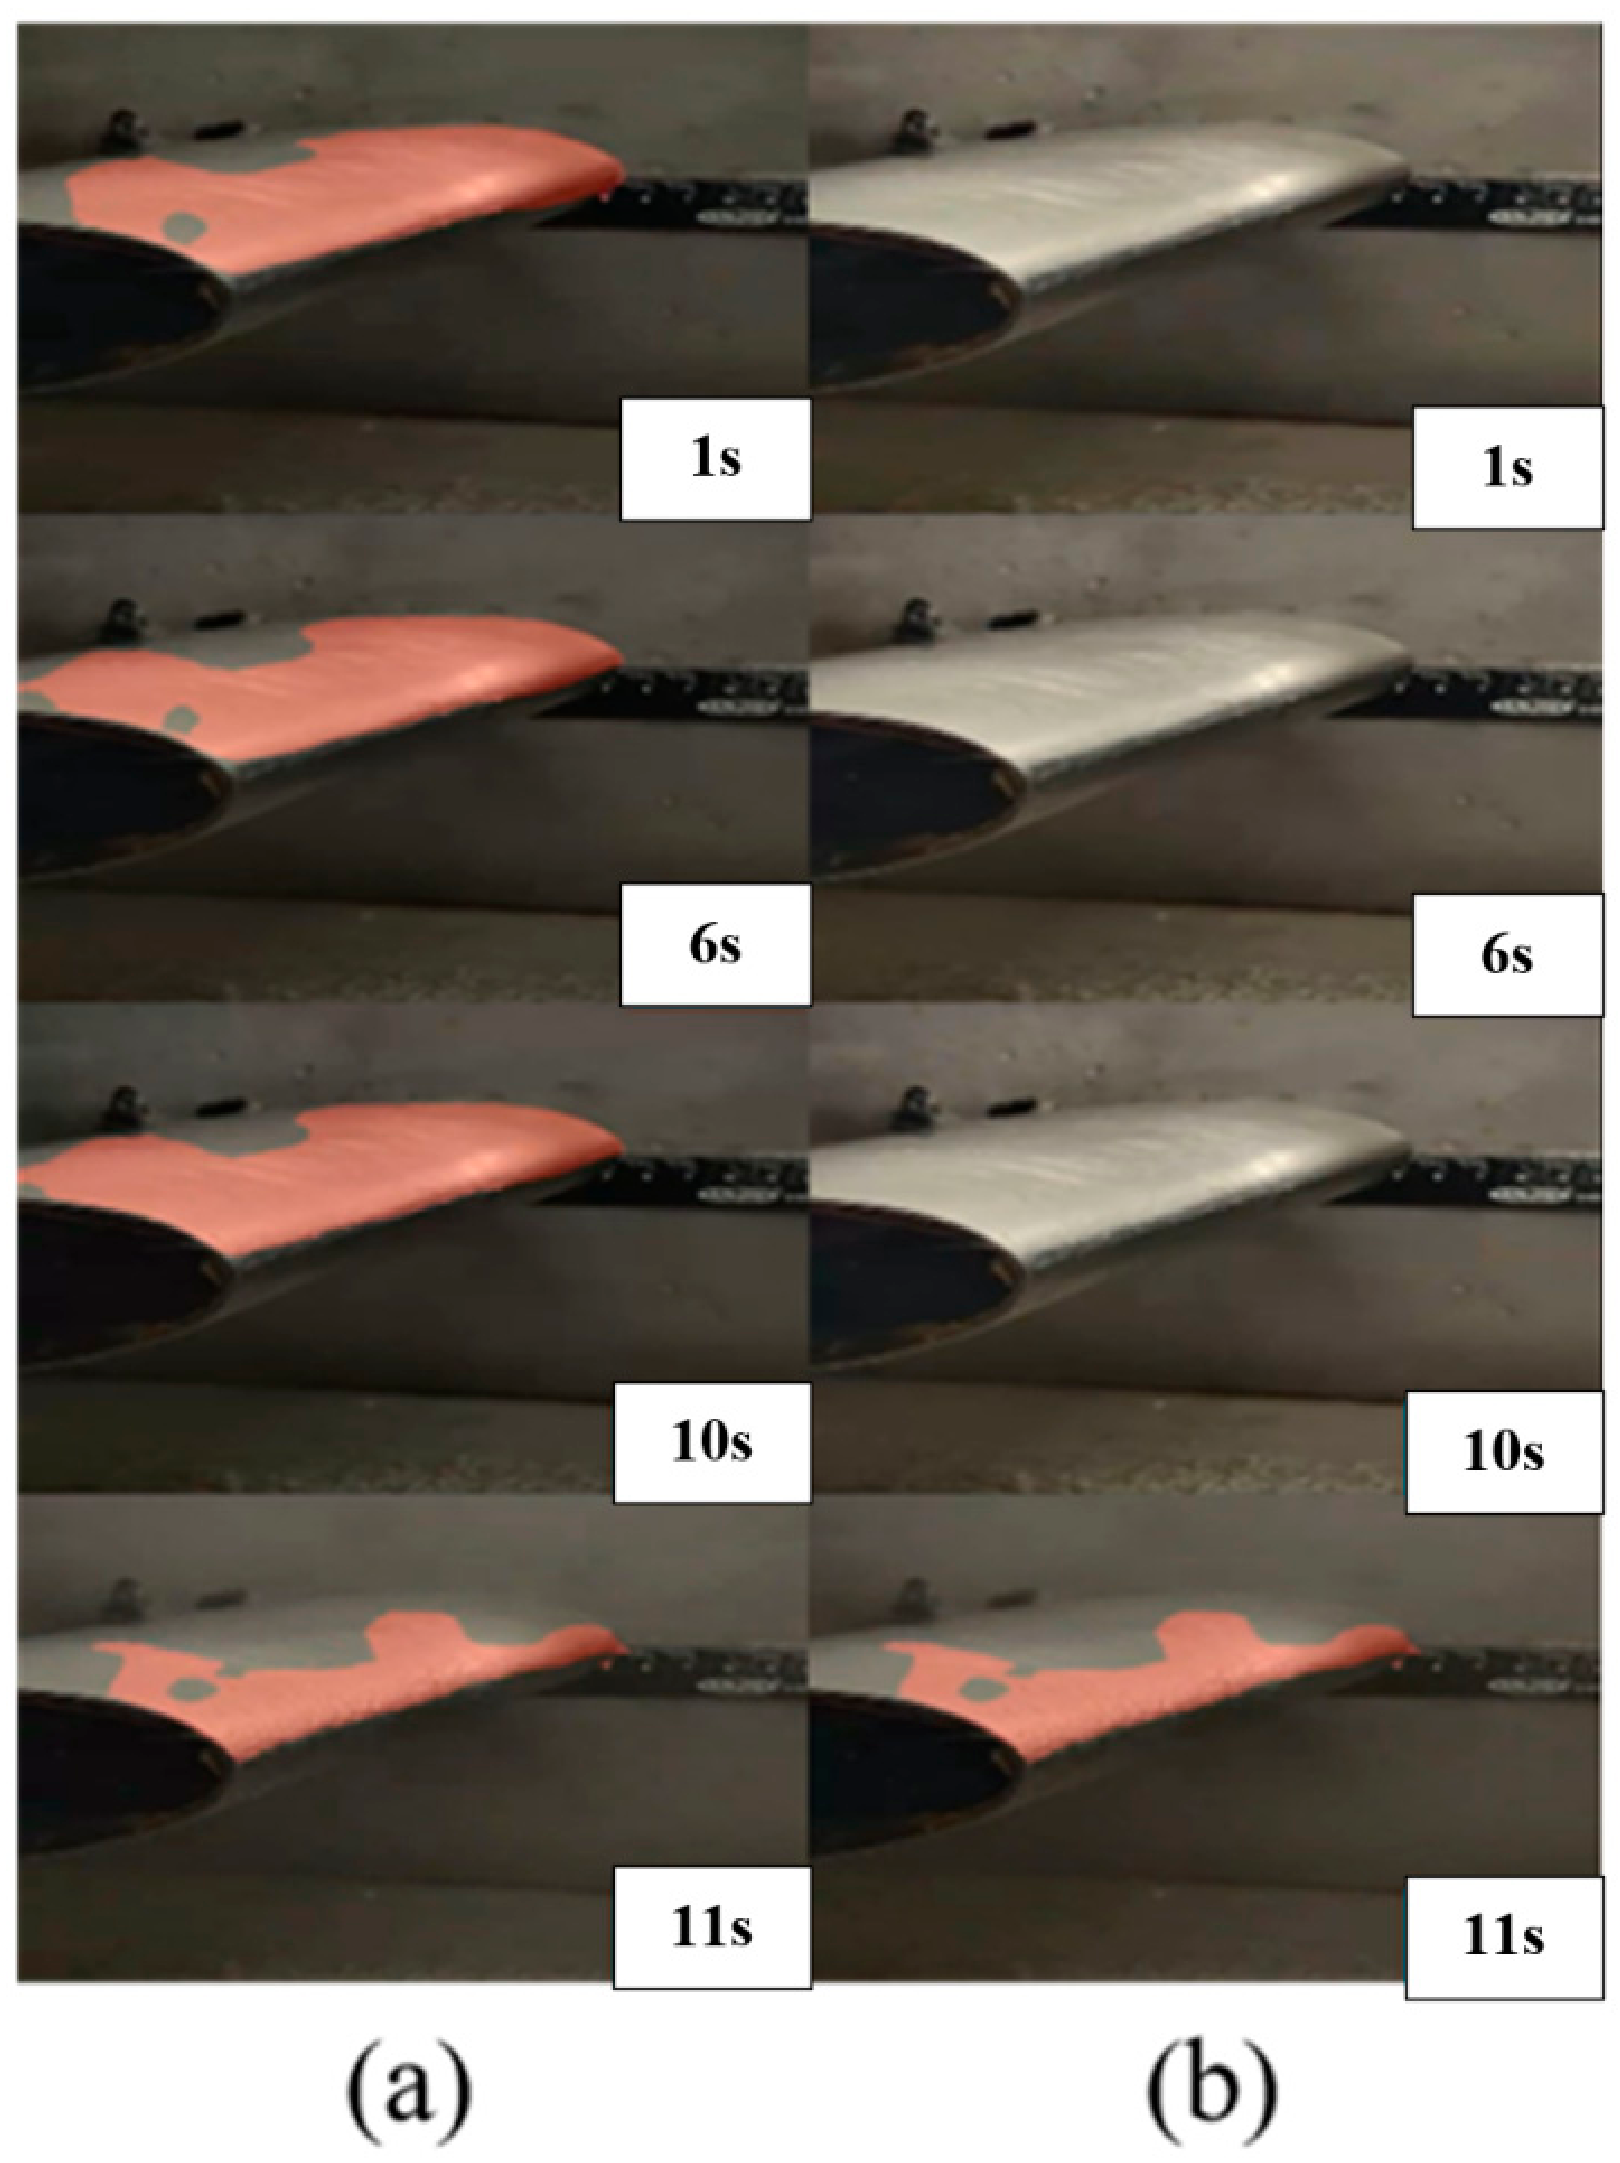
Figure 15 compares the segmentation outputs with and without MobileNetV3 pre-screening. In the representative clean-surface frames shown, pre-screening suppresses the false-positive masks produced without the trigger, while the iced frame retains its segmentation result. This comparison illustrates how the image-level trigger directs ICE-UNet toward frames classified as iced.
Figure 15.
Comparison of icing detection results under two different schemes: (a) without MobileNetV3 pre-screening (note the aggressive false-positive activations on the clean leading edge); (b) with MobileNetV3 pre-screening (clean surface correctly identified).
This cascade directs pixel-wise analysis toward frames likely to contain ice, while successive ICE-UNet masks can show the location and apparent extent of accretion over time. ICE-UNet contains 0.76 M parameters and achieves an FP16 inference time of 13.69 ms per 512 × 512 image on a Tesla V100 workstation. These results provide a compact segmentation stage for camera-assisted wing-leading-edge monitoring and a basis for subsequent evaluation with aircraft imaging and onboard computing hardware.
5. Conclusions
This study proposes ICE-UNet, a lightweight semantic segmentation network tailored for the pixel-wise detection of aircraft wing leading-edge icing. By compressing the conventional U-Net into a streamlined three-stage encoder–decoder architecture and integrating Res-DSCBR, DSCRFB, and CBAM, the proposed design successfully addresses the dual requirements of boundary-sensitive ice segmentation and strict computational efficiency.
On the icing wind-tunnel dataset, ICE-UNet achieved 96.60% Accuracy, 93.07% IoU, 96.36% Precision, and 96.44% Recall, with the highest IoU among the ten evaluated segmentation models. Among the ten representative segmentation models evaluated, ICE-UNet delivered the highest IoU while requiring merely 0.76 M parameters and 16.19 GFLOPs. Compared to the baseline U-Net, the proposed model improved the IoU by 10.33 percentage points while aggressively slashing the parameter count and computational overhead by 95.6% and 90.0%, respectively. The stepwise ablation study traced changes in segmentation performance and computational cost as the architecture was progressively assembled.
Robustness evaluations further demonstrated that the model maintains strong segmentation fidelity under moderate brightness and contrast perturbations, although extreme contrast degradation remains a primary boundary limit. To validate its real-time deployment potential, TensorRT FP16 acceleration was implemented on a Tesla V100 platform, effectively reducing the per-image inference latency from 55.21 ms to 13.69 ms—a 75.2% reduction in per-image inference latency—without any loss in segmentation accuracy. Furthermore, the integration of a MobileNetV3 pre-screening module successfully demonstrated the feasibility of proactively suppressing false-positive activations on clean aerodynamic surfaces during continuous sequence monitoring.
Overall, these results position ICE-UNet as a compact method for pixel-wise analysis of leading-edge icing in the wind-tunnel imagery examined here. The MobileNetV3–ICE-UNet cascade uses image-level screening to direct detailed segmentation toward frames likely to contain ice, while masks across successive frames show the location and apparent extent of accretion. The segmentation results and measured model-level inference efficiency provide a basis for camera-assisted observation of icing development in controlled experiments. Future work will examine additional airfoil geometries, icing conditions, and imaging configurations and measure the latency and reliability of the complete cascade on representative onboard hardware.
Author Contributions
C.T.: Conceptualization, Methodology, Investigation, Formal Analysis, Writing—Original Draft, Writing—Review & Editing. J.H.: Investigation, Data Curation, Validation, Writing—Original Draft. P.Y.: Formal Analysis, Investigation, Writing—Review & Editing. Y.Y.: Formal Analysis, Investigation. Z.C.: Formal Analysis, Validation. Z.X.: Conceptualization, Writing—Review & Editing, Supervision, Project Administration. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the Shenzhen Science and Technology Program (grant number JCYJ20220530145203007).
Data Availability Statement
The raw data supporting the conclusions of this article will be made available by the authors on request.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Wu, Q.; Xu, H.; Pei, B.; Wei, Y. Conceptual design and preliminary experiment of icing risk management and protection system. Chin. J. Aeronaut. 2022, 35, 101–115. [Google Scholar] [CrossRef] [Scilit]
- Hospers, J.M. Eulerian Method for Super-Cooled Large-Droplet Ice-Accretion on Aircraft Wings. Ph.D. Thesis, University of Twente, Enschede, The Netherlands, 2013. [Google Scholar][Green Version]
- Bragg, M.B.; Broeren, A.P.; Blumenthal, L.A. Iced-airfoil aerodynamics. Prog. Aerosp. Sci. 2005, 41, 323–362. [Google Scholar] [CrossRef] [Scilit]
- Lynch, F.T.; Khodadoust, A. Effects of ice accretions on aircraft aerodynamics. Prog. Aerosp. Sci. 2001, 37, 669–767, Corrigendum in Prog. Aerosp. Sci. 2010, 46, 198. [Google Scholar] [CrossRef] [Scilit]
- Ikiades, A. Fiber Optic Ice Sensor for Measuring Ice Thickness, Type and the Freezing Fraction on Aircraft Wings. Aerospace 2023, 10, 31. [Google Scholar] [CrossRef] [Scilit]
- Renno, N.O.; Backhus, R.; Butler, T.; Cooper, C.; Hochrein, K.A.; Madathil, R.; Marr, L.; Miller, R.; Mohan, P.; Musko, S.; et al. A new type of aircraft icing detection system. Sci. Rep. 2026, 16, 210. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Gui, X.; Zeng, F.; Gao, J.; Fu, X.; Li, Z. Detection of Aircraft wing icing and de-icing by optical fiber sensing with FBG array. Measurement 2025, 247, 116748. [Google Scholar] [CrossRef] [Scilit]
- Dong, Y.; Ai, J. Research on inflight parameter identification and icing location detection of the aircraft. Aerosp. Sci. Technol. 2013, 29, 305–312. [Google Scholar] [CrossRef] [Scilit]
- Dong, Y. An application of deep neural networks to the in-flight parameter identification for detection and characterization of aircraft icing. Aerosp. Sci. Technol. 2018, 77, 34–49. [Google Scholar] [CrossRef] [Scilit]
- Musci, M.A.; Mazzara, L.; Lingua, A.M. Ice Detection on Aircraft Surface Using Machine Learning Approaches Based on Hyperspectral and Multispectral Images. Drones 2020, 4, 45. [Google Scholar] [CrossRef] [Scilit]
- Hao, L.; Li, Q.; Pan, W.; Li, B. Icing detection and evaluation of the electro-impulse de-icing system based on infrared images processing. Infrared Phys. Technol. 2020, 109, 103424. [Google Scholar] [CrossRef] [Scilit]
- Iannelli, P.; Angeletti, F.; Gasbarri, P.; Panella, M.; Rosato, A. Deep learning-based Structural Health Monitoring for damage detection on a large space antenna. Acta Astronaut. 2022, 193, 635–643. [Google Scholar] [CrossRef] [Scilit]
- Khalil, S.; Wang, Z.; Aouf, N. Hybrid deep learning based monocular pose estimation for autonomous space docking operations. Acta Astronaut. 2026, 238, 612–629. [Google Scholar] [CrossRef] [Scilit]
- Yan, Y.; Tang, C.; Huang, J.; Cen, Z.; Xie, Z. Visual detection on aircraft wing icing process using a lightweight deep learning model. Aerospace 2025, 12, 627. [Google Scholar] [CrossRef] [Scilit]
- Jin, Z.; Zhang, Z.; Zhang, W.; Zhi, Y.; Xu, Z.; Dakka, S.; Mao, X. Data fusion of airfoil ice shapes with residual U-shaped convolutional neural network. Eng. Appl. Artif. Intell. 2026, 177, 114817. [Google Scholar] [CrossRef] [Scilit]
- Yu, D.; Han, Z.; Zhang, B.; Zhang, M.; Liu, H.; Chen, Y. A fused super-resolution network and a vision transformer for airfoil ice accretion image prediction. Aerosp. Sci. Technol. 2024, 144, 108811. [Google Scholar] [CrossRef] [Scilit]
- Lin, W.; Li, T.; Dang, J.; Peng, B.; Wang, Q.; Yi, X. Rapid aerodynamic prediction of arbitrary 2D iced airfoils via 3D point cloud and Feature-wise Linear Modulation. Aerosp. Sci. Technol. 2025, 166, 110543. [Google Scholar] [CrossRef] [Scilit]
- Cuozzo, C.; Cusati, V.; De Marco, A.; Corcione, S.; Page, J.H.; Zanon, A. AI-driven surrogate modeling for iced tailplane aerodynamic prediction. Aerosp. Sci. Technol. 2026, 168, 111102. [Google Scholar] [CrossRef] [Scilit]
- Ronneberger, O.; Fischer, P.; Brox, T. U-Net: Convolutional Networks for Biomedical Image Segmentation. In Medical Image Computing and Computer-Assisted Intervention—MICCAI 2015; Navab, N., Hornegger, J., Wells, W.M., Frangi, A.F., Eds.; Lecture Notes in Computer Science; Springer International Publishing: Cham, Switzerland, 2015; Volume 9351, pp. 234–241. [Google Scholar]
- Badrinarayanan, V.; Kendall, A.; Cipolla, R. SegNet: A Deep Convolutional Encoder-Decoder Architecture for Image Segmentation. IEEE Trans. Pattern Anal. Mach. Intell. 2017, 39, 2481–2495. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhao, H.; Shi, J.; Qi, X.; Wang, X.; Jia, J. Pyramid Scene Parsing Network. In Proceedings of the 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Honolulu, HI, USA, 2017; pp. 6230–6239. [Google Scholar]
- Chen, L.-C.; Zhu, Y.; Papandreou, G.; Schroff, F.; Adam, H. Encoder-Decoder with Atrous Separable Convolution for Semantic Image Segmentation. In Computer Vision—ECCV 2018; Ferrari, V., Hebert, M., Sminchisescu, C., Weiss, Y., Eds.; Lecture Notes in Computer Science; Springer International Publishing: Cham, Switzerland, 2018; Volume 11211, pp. 833–851. [Google Scholar]
- Valanarasu, J.M.J.; Patel, V.M. UNeXt: MLP-Based Rapid Medical Image Segmentation Network. In Medical Image Computing and Computer Assisted Intervention—MICCAI 2022; Wang, L., Dou, Q., Fletcher, P.T., Speidel, S., Li, S., Eds.; Lecture Notes in Computer Science; Springer Nature: Cham, Switzerland, 2022; Volume 13435, pp. 23–33. [Google Scholar]
- Tian, L.; Tu, J.; Liu, H.; Kong, W.; Han, N.; Tian, W. Experimental study on the icing hazards over the propeller of a Low-Altitude flight UAV under changeable liquid water content environment. Exp. Therm. Fluid Sci. 2025, 169, 111546. [Google Scholar] [CrossRef] [Scilit]
- Mazhar, S.; Atif, N.; Bhuyan, M.K.; Ahamed, S.R. Block attention network: A lightweight deep network for real-time semantic segmentation of road scenes in resource-constrained devices. Eng. Appl. Artif. Intell. 2023, 126, 107086. [Google Scholar] [CrossRef] [Scilit]
- Ladson, C.L.; Brooks, C.W.; Hill, A.S.; Sproles, D.W. Computer Program to Obtain Ordinates for NACA Airfoils; NASA Langley Research Center: Hampton, VA, USA, 1996. [Google Scholar]
- Whitcomb, R.T. The Relation Between Spanwise Variations in the Critical Mach Number and Spanwise Load Distributions; National Advisory Committee for Aeronautics: Hampton, VA, USA, 1944. [Google Scholar]
- Kirillov, A.; Mintun, E.; Ravi, N.; Mao, H.; Rolland, C.; Gustafson, L.; Xiao, T.; Whitehead, S.; Berg, A.C.; Lo, W.-Y.; et al. Segment anything. In Proceedings of the 2023 IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 1–6 October 2023; pp. 3992–4003. [Google Scholar]
- Long, J.; Shelhamer, E.; Darrell, T. Fully convolutional networks for semantic segmentation. In Proceedings of the 2015 IEEE Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Boston, MA, USA, 2015; pp. 3431–3440. [Google Scholar]
- Paszke, A.; Chaurasia, A.; Kim, S.; Culurciello, E. ENet: A Deep Neural Network Architecture for Real-Time Semantic Segmentation 2016. arXiv 2016, arXiv:1606.02147. [Google Scholar] [CrossRef] [Scilit]
- Li, G.; Yun, I.; Kim, J.; Kim, J. DABNet: Depth-wise Asymmetric Bottleneck for Real-time Semantic Segmentation 2019. arXiv 2019, arXiv:1907.11357. [Google Scholar] [CrossRef] [Scilit]
- Yu, C.; Wang, J.; Peng, C.; Gao, C.; Yu, G.; Sang, N. BiSeNet: Bilateral Segmentation Network for Real-Time Semantic Segmentation. In Computer Vision—ECCV 2018; Ferrari, V., Hebert, M., Sminchisescu, C., Weiss, Y., Eds.; Lecture Notes in Computer Science; Springer International Publishing: Cham, Switzerland, 2018; Volume 11217, pp. 334–349. [Google Scholar]
- Selvaraju, R.R.; Cogswell, M.; Das, A.; Vedantam, R.; Parikh, D.; Batra, D. Grad-CAM: Visual Explanations from Deep Networks via Gradient-Based Localization. In Proceedings of the 2017 IEEE International Conference on Computer Vision (ICCV); IEEE: Venice, Italy, 2017; pp. 618–626. [Google Scholar]
- Howard, A.; Sandler, M.; Chen, B.; Wang, W.; Chen, L.-C.; Tan, M.; Chu, G.; Vasudevan, V.; Zhu, Y.; Pang, R.; et al. Searching for MobileNetV3. In Proceedings of the 2019 IEEE/CVF International Conference on Computer Vision (ICCV); IEEE: Seoul, Republic of Korea, 2019; pp. 1314–1324. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.