


Abstract
Adversarial training is one of the most successful approaches to improve model robustness against maliciously crafted data. Instead of training on a clean dataset, the model is trained on adversarial data generated on the fly. Based on that, a group of geometry-aware methods are proposed to further enhance the model robustness by assigning higher weights to the data points that are closer to the decision boundary during training. Although the robustness against the adversarial attack seen in the training process is significantly improved, the model becomes more vulnerable to unseen attacks, and the reason for the issue remains unclear. In this paper, we investigate the cause of the issue and claim that such geometry-aware methods lead to a sharp minimum, which results in poor robustness generalization for unseen attacks. Furthermore, we propose a remedy for the issue by imposing the adversarial weight perturbation mechanism and further develop a novel weight perturbation strategy called Geometry-Aware Weight Perturbation (GAWP). Extensive results demonstrate that the proposed method alleviates the robustness generalization issue of geometry-aware methods while consistently improving model robustness compared to existing weight perturbation strategies.
1. Introduction
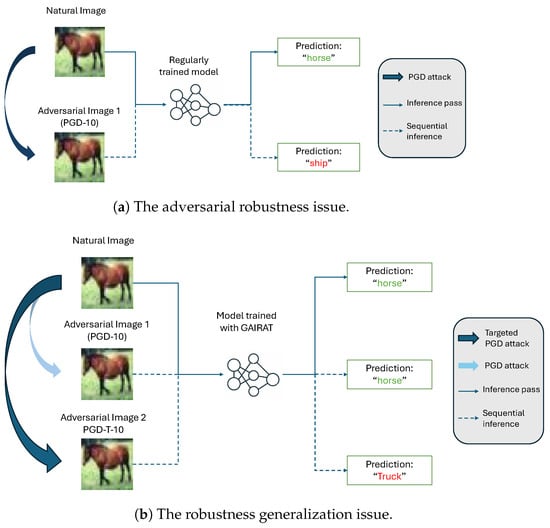
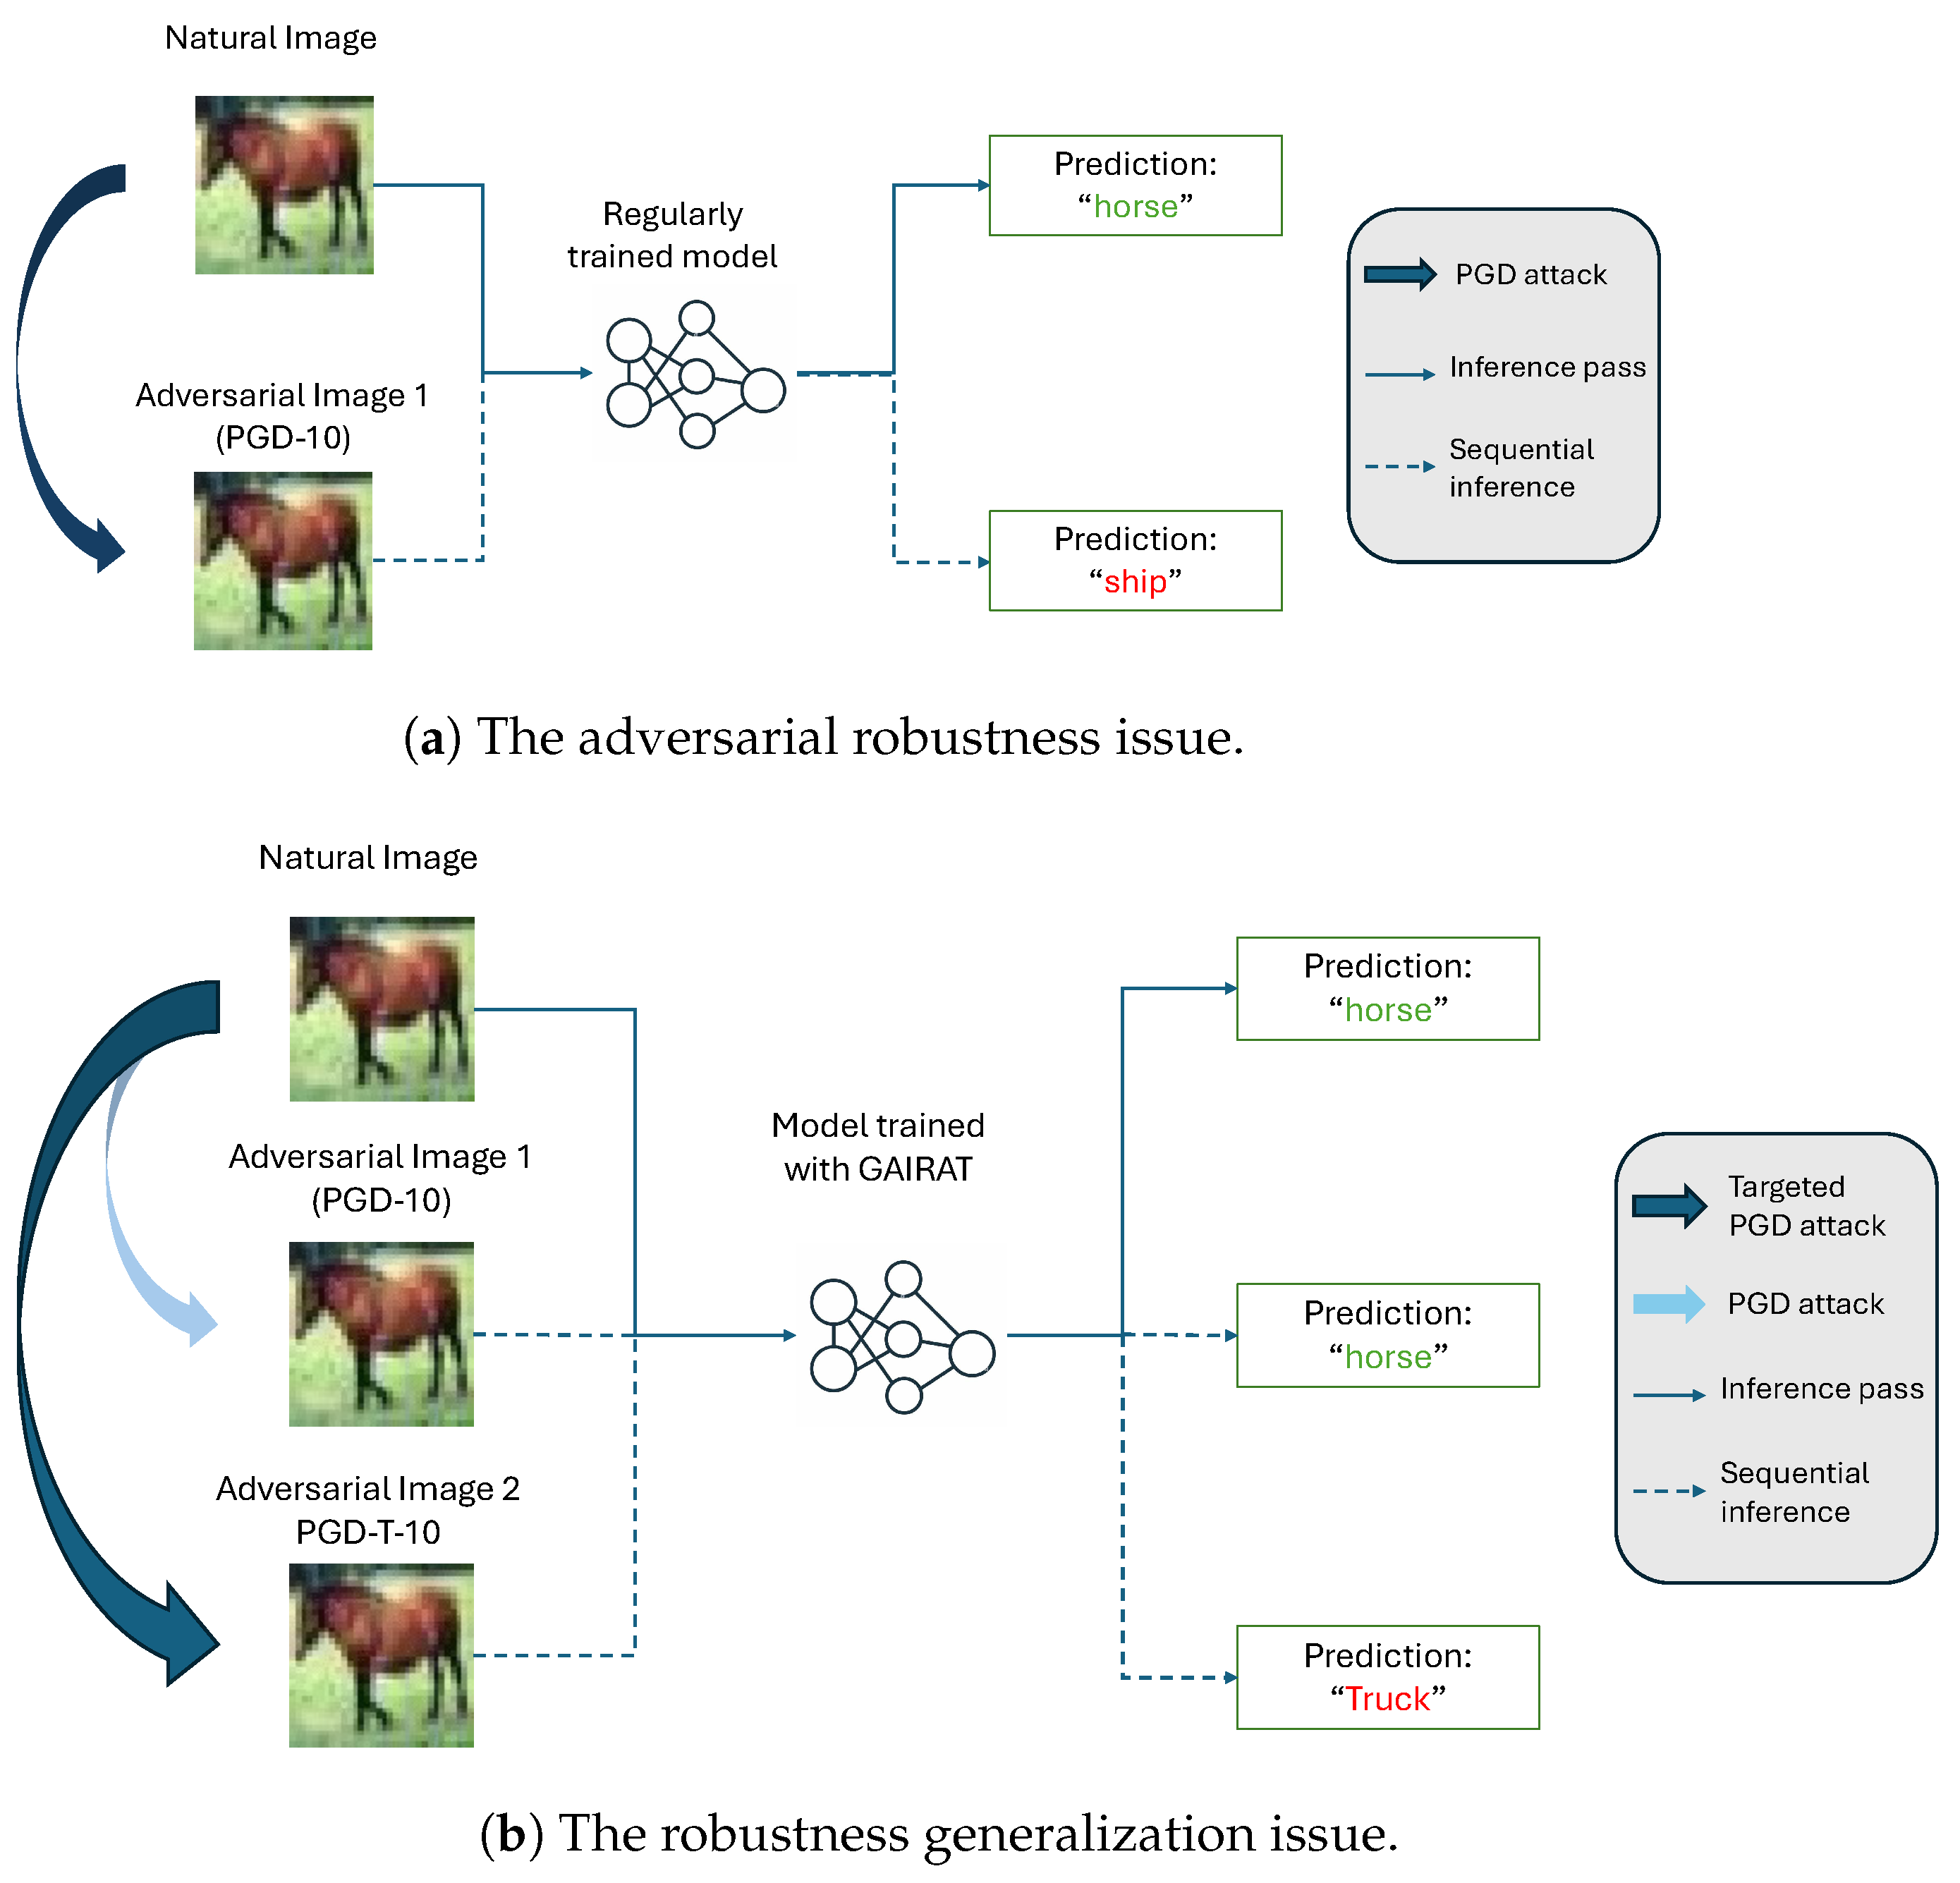
Deep neural networks (DNNs) are known to be vulnerable to maliciously generated adversarial examples, which severely limits their applications in safety-critical areas [1], for example, autonomous driving [2]. As shown in Figure 1a, we can find an adversarial example by marginally perturbing a natural image using a PGD attack [3]. Although it is easy for a person to correctly classify both images and ignore the minor change between them, a regularly trained model can be easily fooled by the adversarial example and make a wrong prediction. To improve model robustness, adversarial training (AT) [3] has been demonstrated to be highly effective where approximate worst-case adversarial examples are used to train the model.
Figure 1.
An illustration of the problems under consideration in this paper. As shown in (a), a regularly trained model is fooled by an adversarial example generated with a PGD attack, although there is no obvious difference between the natural image and its adversarial counterpart. GAIRAT is proposed to improve the model robustness. However, it is found that, although the robustness against the PGD attack is improved, the model can be easily fooled by adversarial examples generated with unseen attacks during training, for example, the targeted PGD attack, as shown in (b).
Based on the vanilla AT, geometry-aware instance-reweighted adversarial training (GAIRAT) is developed [4] following a straightforward intuition that the data closer to the decision boundary are more “attackable” and should be assigned a higher weight during training. While models trained with GAIRAT demonstrate robustness improvement against the adversarial attack imposed during training, they unexpectedly become more vulnerable to other unseen attacks, such as the logit-scaling attack [5] and the targeted PGD attack [3], as illustrated in Figure 1b. This issue of poor robustness generalization makes GAIRAT less appealing than other AT variants, such as TRADES [6] and MART [7], because the model robustness against the PGD attack no longer reflects the overall robustness of the model for GAIRAT. Zhang et al. [4] suggested that robustness generalization can be improved by incorporating more adversarial data generated by various attacks. However, the cost of adversarial data simulation can be prohibitively high, making the suggested remedy impractical. Therefore, to develop a practical solution that improves the robustness generalization of GAIRAT, it requires further study on the root cause of the issue. Additionally, similar ideas to GAIRAT have been successfully applied in regular training settings, such as AdaBoost [8] and focal loss [9]. This suggests that GAIRAT still holds untapped potential for achieving overall improvements in model robustness by addressing its robustness generalization issue.
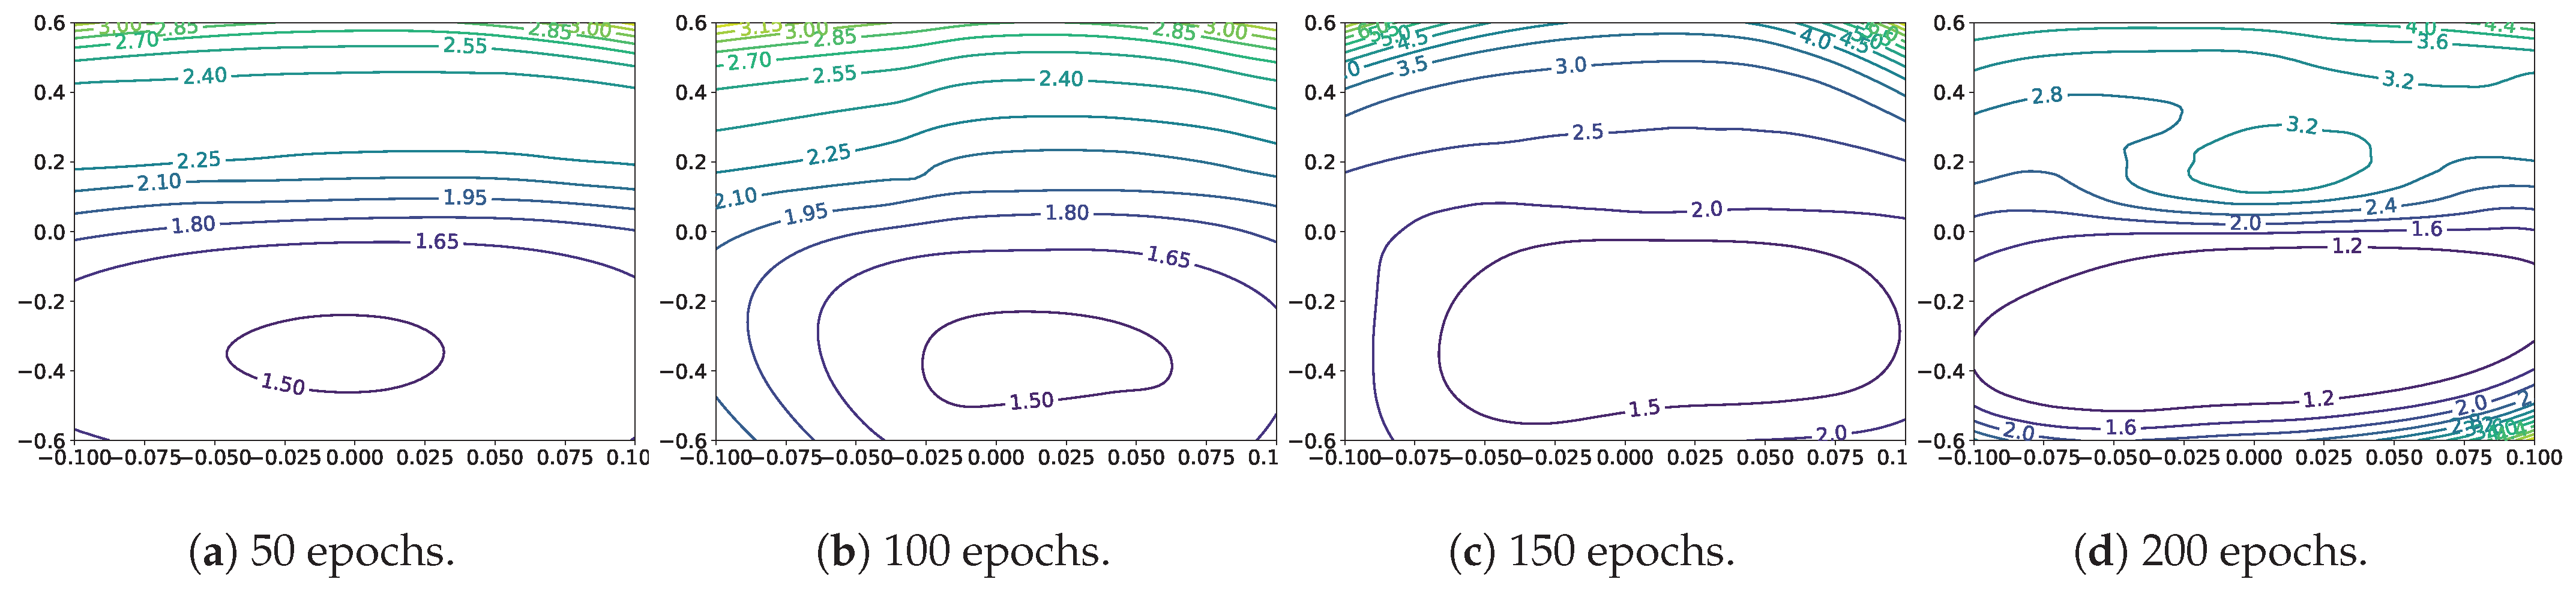
To explore the causes of the issue, we inspect the model’s weight loss landscape [10] based on the checkpoints saved during the training with GAIRAT. In Figure 2, we present a 2D visualization of the weight loss landscape for each checkpoint [11]. It is observed that the landscape roughness significantly increases as the training progresses, indicating that GAIRAT converges to a sharp local minimum. Since the flatness of the weight loss landscape is commonly used as an indicator of generalization in the standard training scenario [11,12], we claim that the robustness generalization issue of GAIRAT is led by the lack of regularization in the weight loss landscape during training. Adversarial weight perturbation (AWP) [10] is a powerful approach that achieves superior model robustness by explicitly regularizing the weight loss landscape flatness. It motivates us to combine GAIRAT and AWP to achieve a better generalization in terms of robustness against various types of adversarial attack.
We first substantiate our claim that the robustness generalization issue of GAIRAT arises from a rough weight loss landscape. Specifically, we apply the same criterion proposed in GAIRAT to determine the importance of each adversarial example. To emphasize the training of more important examples, we increase their losses by assigning higher weights to them during the adversarial perturbation of model weights, which is different from GAIRAT, which directly uses the importance scores as weights of adversarial risks. We empirically show that our method converges to a flatter local minimum and leads to a model that is more robust to unseen attacks, which supports our claim about the reason for the robustness generalization issue. Treating this approach as the baseline, we find that, although it achieves higher model robustness, it suffers from a more severe robust overfitting issue [13] when compared with the vanilla AWP [10]. Recent studies on robust overfitting suggest that increasing the weights of examples with low adversarial risk is crucial for eliminating robust overfitting [14,15]. Based on that, we propose a criterion that determines the importance of an adversarial example during weight perturbation by considering its adversarial risk and its distance to the decision boundary. In a nutshell, examples that are closer to the decision boundary and have a lower adversarial risk are assigned higher importance scores during weight perturbation. With this importance criterion, we develop a novel weight perturbation strategy, namely, the Geometry-Aware Weight Perturbation (GAWP). The proposed method not only significantly alleviates the robustness generalization issue of GAIRAT [4], but also outperforms existing weight perturbation strategies such as AWP [10] and RWP [14]. The main contributions of this paper are summarized as follows:
- We identify that the geometry-aware adversarial training method GAIRAT converges to a sharp local minimum. By incorporating GAIRAT with AWP, we can obtain a flatter optimization result that is shown to be robust against unseen attacks. It provides a better understanding of the robustness generalization issue of GAIRAT.
- We claim that the model weight perturbation of the data that are close to the decision boundary and have a low adversarial risk is essential for achieving higher model robustness and avoiding robust overfitting.
- A novel weight perturbation strategy, GAWP, is developed in this paper. Extensive experiments demonstrate that GAWP outperforms not only GAIRAT, but also existing weight perturbation strategies, achieving superior model robustness.
Figure 2.
Contours of weight loss landscape for 4 checkpoints saved during the training with GAIRAT [4]. The analysis is based on a PreAct ResNet-18 [16] and CIFAR-10 [17] dataset. Two directions are used for the 2D visualization. One direction is determined by weight perturbation, and the other one is a random orthogonal direction.
2. Related Work
2.1. Adversarial Attacks
Let denote the input space and represent the norm ball of radius centered at the clean input data x. The associated label of x is denoted by y. Considering a class classifier , an adversarial attack method is designed to find an adversarial example , such that
To find , it is common to solve a constrained optimization problem defined in terms of a surrogate function L. The model’s classification accuracy on the adversarial data is considered as the measure of robustness, making it essential to design a comprehensive adversarial attack method for an objective evaluation of the model robustness. Here, we introduce several widely used adversarial attack methods.
Projected Gradient Descent (PGD). PGD [3] finds adversarial data by approximately solving the optimization problem (1), where the surrogate loss is the cross-entropy loss denoted by :
Starting with a point uniformly sampled inside the ball , PGD perturbs x for K steps with a step size :
Here, represents the projection function that projects back into the ball if necessary.
AutoAttack (AA). As shown in recent studies [18,19], cross-entropy loss can be easily manipulated by simply rescaling the output logits of the model, meaning that measuring the model test accuracy under the PGD attack alone can overestimate the model robustness. For more objective evaluation of the model robustness, AA [18] generates adversarial examples with an ensemble of complementary attacks consisting of three white-box attacks and a black-box attack. During the evaluation, AA considers the benchmark model as robust only if it correctly classifies all types of adversarial examples, making it one of the most reliable evaluation methods for model robustness.
2.2. Adversarial Training
To defend against adversarial attacks, it is intuitive to train the model on adversarial data, namely, adversarial training (AT) [3]. Given a training dataset with n samples, denoted by , training with AT is formulated as a min–max optimization problem:
where is a DNN with trainable parameters . The adversarial risk is the objective function for the outer minimization. For AT,
Based on AT, numerous variants have been proposed to further enhance model robustness. One group of methods follows the same definition of adversarial risk as vanilla AT but further boosts the model robustness by assigning unequal weights to different adversarial examples, for example, geometry-aware instance-reweighted adversarial training (GAIRAT) [4]. Based on a straightforward intuition that a data point closer to the decision boundary is less robust, GAIRAT proposes to emphasize the training on those less robust examples. Specifically, the outer minimization is reformulated as
where is a non-increasing function w.r.t., the distance from the to the decision boundary. Additionally, it is required that and . One method of realization is proposed as follows: the geometric distance between and the decision boundary can be approximated by the least number of iterations that the PGD attack needs to generate an adversarial example to successfully fool the model given the maximum number of attack iterations K. Based on that, one possible design of is proposed as follows:
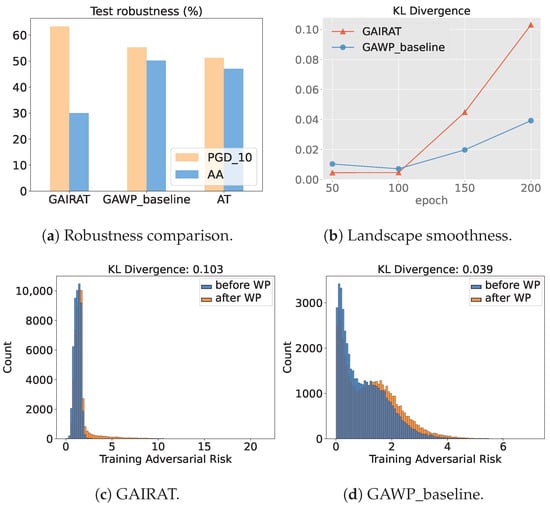
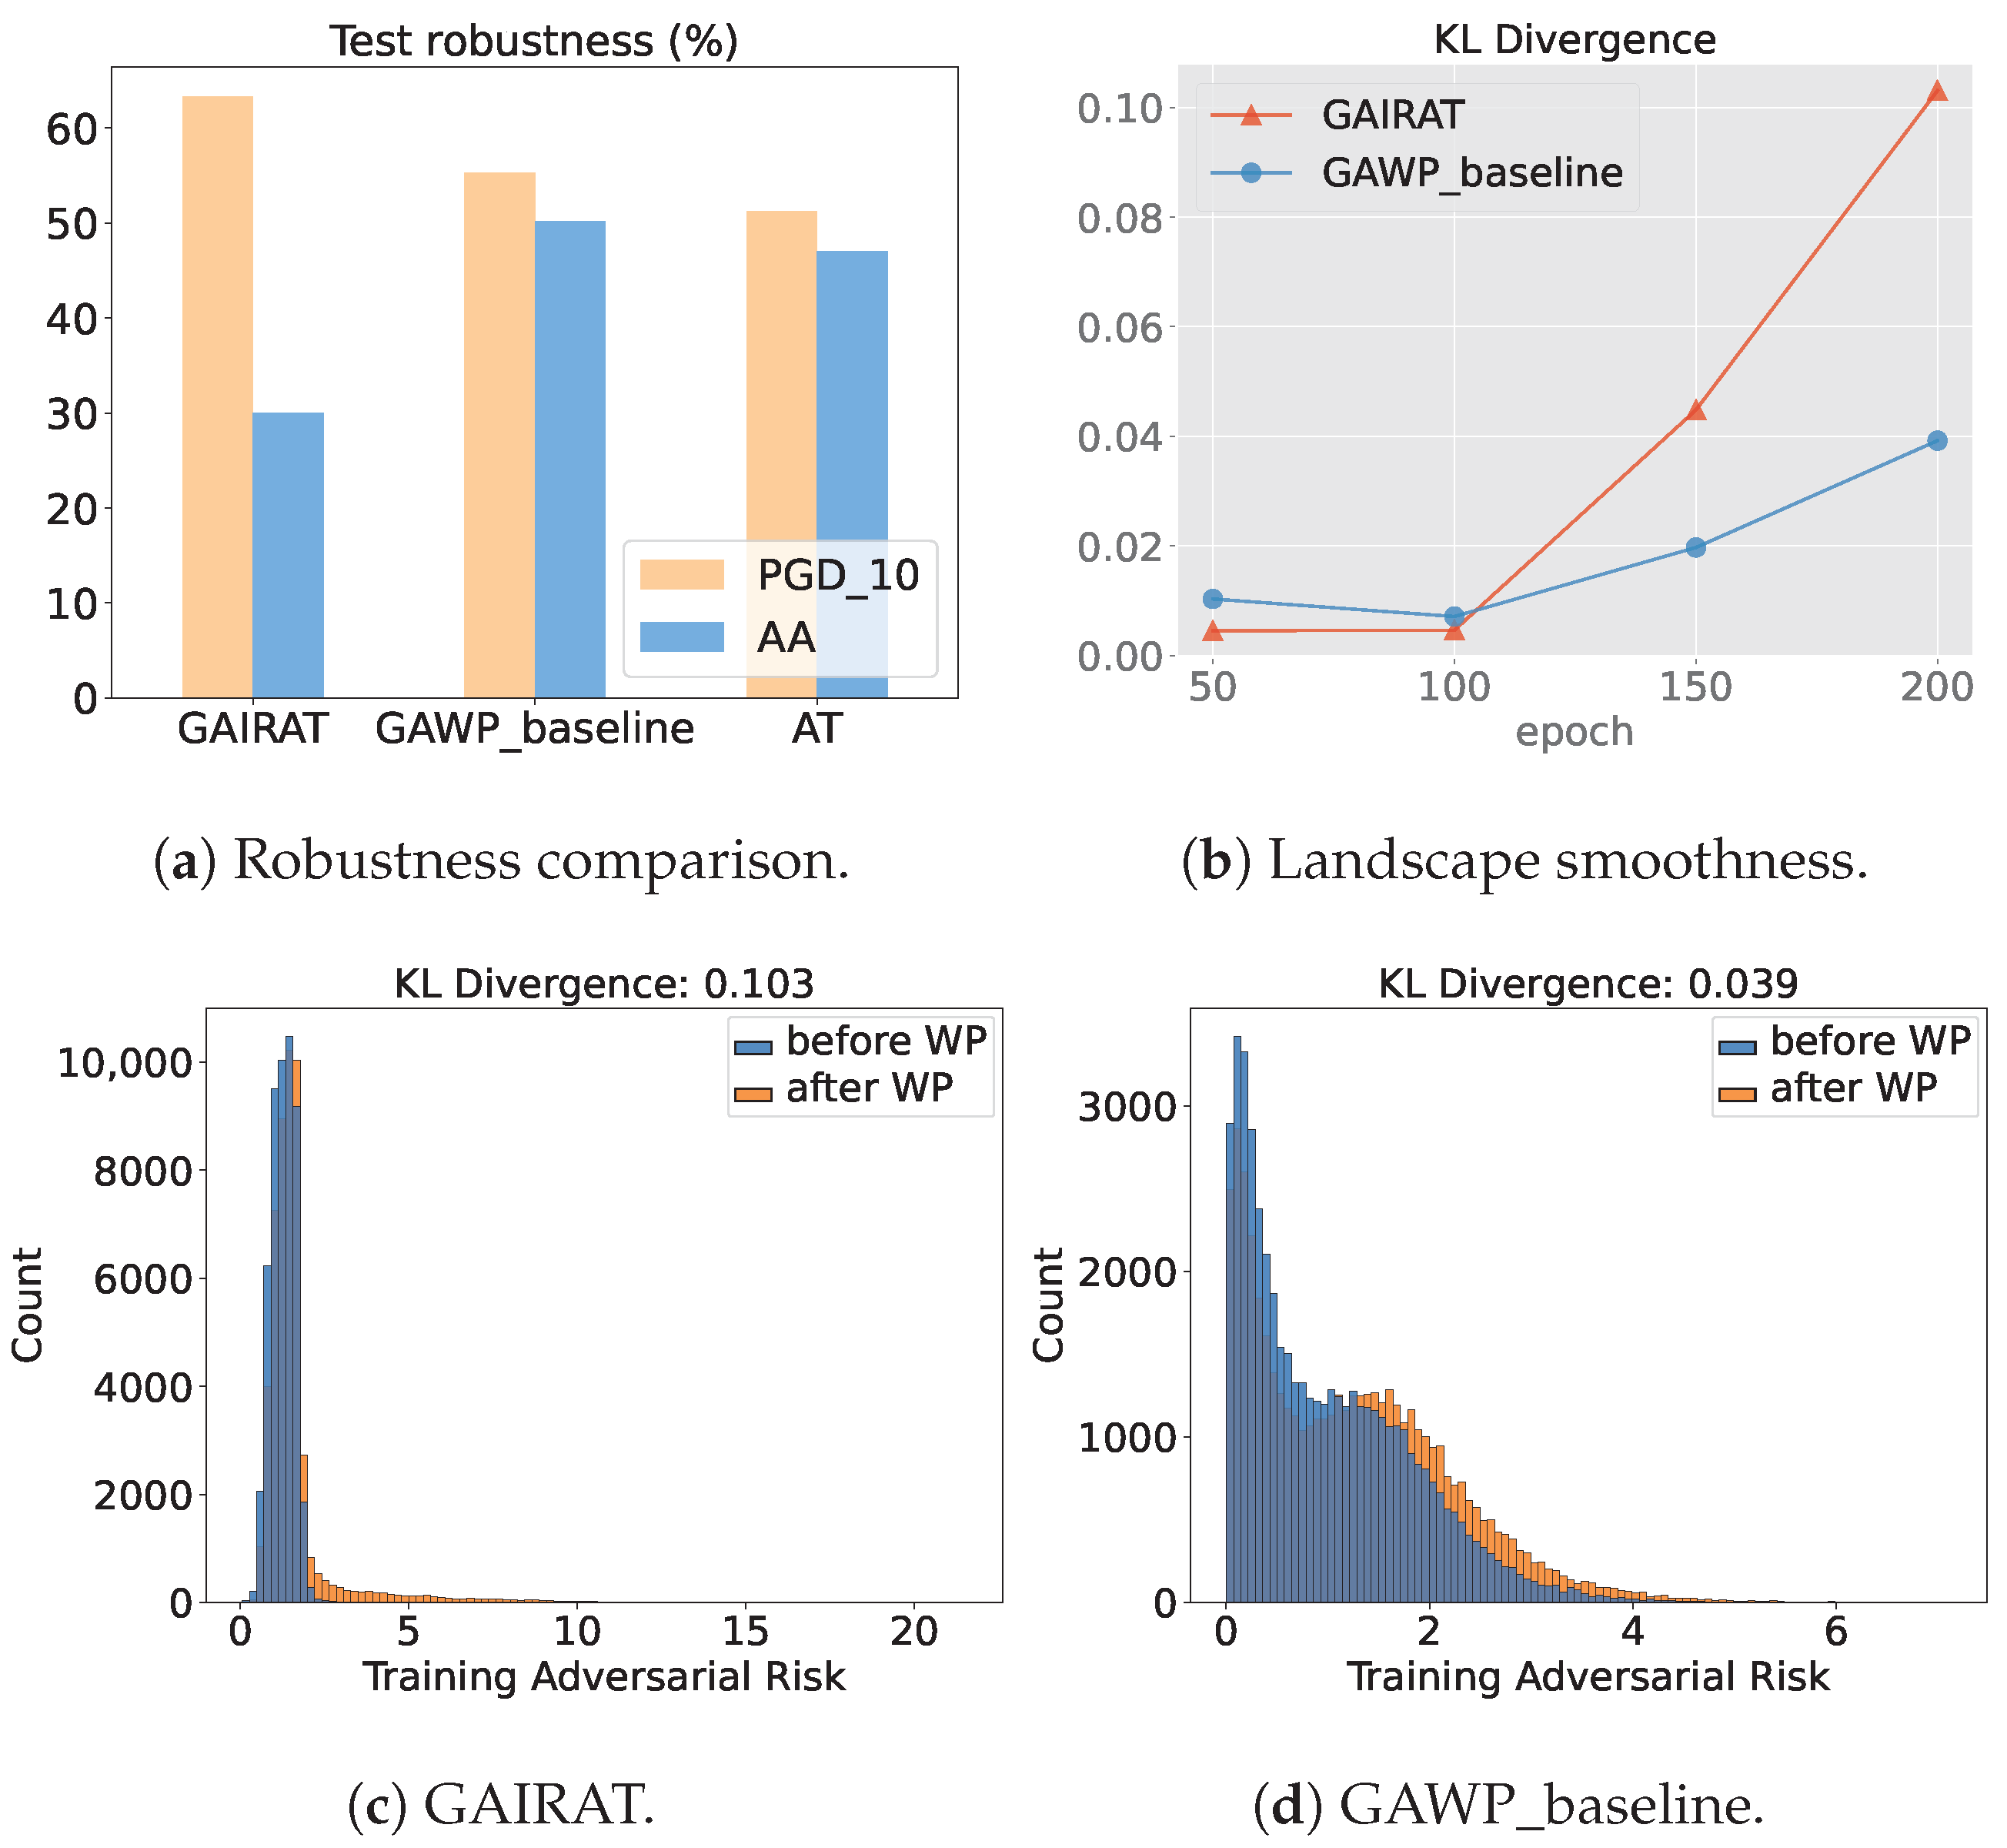
where represents the normalization operation by the batch sum, and is a constant controlling the shape of the function. Note that, as , Equation (6) is equivalent to assigning equal weights to all the adversarial examples, and GAIRAT degrades to vanilla AT. In essence, both AT and GAIRAT train a model based on adversarial data generated under the PGD attack. However, it is observed that, although GAIRAT achieves superior robustness against the PGD attack, the trained model is more vulnerable to adversarial unseen attacks during training [5] as compared to vanilla AT. As can be observed in Figure 3a, for GAIRAT, there is a more significant gap between model performances under the PGD attack and AA, indicating poor robustness generalization.
Figure 3.
Comparison between GAIRAT and the baseline version of GAWP (GAWP_baseline). A comparison of model robustness is provided in (a). “PGD_10” represents the test accuracy against a 10-step PGD attack under the norm, which is seen during training. “AA” denotes the test accuracy against AutoAttack [18], representing the model robustness against unseen attacks. In (b), the Kullback–Leibler (KL) divergence between the adversarial distributions before and after a 5-step weight perturbation attack is shown. A smaller value indicates less sensitivity to the weight perturbation. A visualization of these loss distributions is provided based on the trained models after the 200-epoch training of GAIRAT (c) and GAWP_baseline (d).
Another group of AT variants is proposed to improve model robustness via novel designs of the adversarial risk . TRADES [6] develops a new design of adversarial risk through a theoretical analysis of the trade-off between the model robustness and its accuracy on the natural data. MART [7] reformulates the problem based on the intuition that misclassified and correctly classified examples should be differentiated during adversarial training. Technically, unlike the definition of adversarial risk (4) in vanilla AT, these methods propose alternative designs, summarized in Table 1.
Table 1.
Adversarial risk definitions for AT and its variants. Here, represents the cross-entropy loss, is the boosted cross-entropy loss [7] and denotes the Kullback–Leibler divergence. is a constant hyper-parameter. Note that, for MART, the adversarial examples are generated in the same manner as vanilla AT.
2.3. Adversarial Purification
As an alternative to adversarial training, adversarial purification refers to a group of defense methods that transform an adversarial example into its counterpart on the manifold of normal data using generative models. Meng and Chen proposed MagNet [20], which uses a collection of auto-encoders [21] for adversarial example purification. More recent methods such as defense-GAN [22] and DiffPure [23] apply more advanced generative models (GAN [24,25], Diffusion model [26]) to recover clean images through a reverse generation process. Although shown to be effective in defending against unseen attacks, these methods still suffer from the shortcomings of current generative models, for example, the mode collapse issue in GANs [24]. In addition to that, the extra purification process significantly increases the time complexity during inference, making them inapplicable for real-time tasks [23]. Considering these limitations, we focus on developing a more advanced adversarial training method in this paper.
3. Methodology
In this section, we first introduce the adversarial weight perturbation (AWP) mechanism [10] in detail. Then, we empirically investigate the underlying cause for the poor robustness generalization of GAIRAT [4] from the perspective of weight loss landscape smoothness. Based on this observation, we propose an effective remedy for the issue by incorporating GAIRAT with AWP. We further discuss how to utilize the geometric signal to guide weight perturbation for improving the model robustness, and a novel weight perturbation strategy, Geometry-Aware Weight Perturbation (GAWP), is proposed.
3.1. Preliminaries
Adversarial weight perturbation is proposed based on the key insight that, for a model with a smoother weight loss landscape, the gap between training robustness and test robustness is narrower [10]. Therefore, it is proposed to explicitly regularize the model’s weight loss landscape by imposing a double perturbation mechanism during adversarial training:
Here, is the feasible region of weight perturbation, i.e., , where denotes the constraint on weight perturbation size. In essence, problem (7) is equivalent to , where the term explicitly regularizes the flatness of the weight loss landscape during training. Technically, for each step of weight perturbation, v is updated as follows:
Following AWP, it is discovered that, by assigning higher importance scores to the small-loss data during AWP, the model robustness is further enhanced, leading to advanced variants of AWP such as RWP [14] and MLCATWP [15]. Particularly, for RWP, v is updated based on the following:
Here, is the minimum loss value that is set as a hyper-parameter before training. MLCAT follows a similar update rule to compute v, where the difference lies in the design of indicator function .
3.2. Understanding the Robustness Generalization Issue of GAIRAT
We examine the model robustness of the “best” model returned by GAIRAT (the model with the highest test accuracy under the PGD-10 attack). In particular, a PreAct ResNet-18 [16] is trained with GAIRAT on CIFAR-10 [17] for 200 epochs following the same setting as in the original paper [4]. As shown in Figure 3a, although the test accuracy under the PGD-10 attack is as high as , it drops significantly to under the AA, suggesting poor robustness generalization. Furthermore, we investigate the model weight loss landscape smoothness based on 4 checkpoints saved every 50 epochs of training. For quantification purposes, we measure the smoothness of the weight loss landscape with the Kullback–Leibler (KL) divergence between the adversarial risk distributions before and after a 5-step adversarial weight perturbation with the perturbation size . A lower KL divergence means the model is less sensitive to weight perturbation, implying a smoother weight loss landscape. According to Figure 3b, as the training of GAIRAT progresses, the model’s sensitivity to weight perturbation considerably increases, suggesting that the model gradually converges to a sharp local minimum. We further claim that this is the potential reason for the robustness generalization issue of GAIRAT.
To testify to our claim, we impose proper regularization on the smoothness of the weight loss landscape to improve the robustness generalization of GAIRAT. We apply the same rule as GAIRAT to determine the importance of each adversarial sample. However, we impose importance scores during weight perturbation rather than the outer minimization. Specifically, model weights are adversarially perturbed based on
In this manner, the training on the data that are closer to the decision boundary is implicitly emphasized through the weight perturbation mechanism. Regarding this approach as the baseline (GAWP_baseline), we observe that the performance gap between the PGD-10 attack and the AA obviously shrinks (PGD-10: , AA: ), as shown in Figure 3a. Additionally, comparing against GAIRAT, the GAWP_baseline converges to a flatter local minimum, based on Figure 3b–d. In a nutshell, the experimental results support our claim about the cause of the poor robustness generalization of GAIRAT, which motivates us to develop a novel weight perturbation strategy that considers the geometric distance of each adversarial example to the decision boundary.
3.3. Geometry-Aware Weight Perturbation
Although the baseline version of GAWP effectively alleviates the robustness generalization issue of GAIRAT, it is observed that the proposed method suffers from the robust overfitting issue and only marginally improves the model robustness when compared against AWP; see Table 2. In particular, we observe that the model robustness starts degrading and never recovers after training for around 120 epochs with the GAWP_baseline, indicating robust overfitting. Therefore, we seek to further improve the model robustness by eliminating robust overfitting for the baseline method.
Table 2.
Test robustness (%) on CIFAR-10 using PreAct ResNet-18 under the threat model. We focus on model performance on the clean data (“Natural”) and adversarial data under AutoAttack (“AA”) and PGD-10 attack (“PGD-10”). For PGD-10, we present the highest model robustness that is ever achieved (“Best”) and after the whole training process (“Last”). Their performance gap is also recorded (“Diff”), indicating the severity of the robust overfitting [13].
For numerous adversarial training methods, it is a prevalent phenomenon that there is an obvious gap between the best and last model robustness, termed the robust overfitting issue [13]. To tackle the issue, various remedies have been proposed, such as semi-supervised learning [27], temporal ensembling [28], pruning [29] and label smoothing [30]. Moreover, recent studies [15,31] have sought an explanation for why robust overfitting occurs. It is discovered that, as AT progresses, a portion of adversarial data becomes easy to learn and fails to provide enough adversary strength. Additionally, the robust overfitting issue is found to be eliminated by simply increasing the adversarial risk of such small-loss data. It motivates us to introduce the adversarial risk as an additional factor when computing the importance score of each adversarial example.
Inspired by previous studies on robust overfitting [14,15,31], small-loss data should be assigned a higher importance score. Therefore, we propose to determine the importance of each example by its adversarial risk as follows:
Here, m denotes the batch size. By combining it with Equation (6), the importance score is computed as follows:
Based on this, we propose Geometry-Aware Weight Perturbation (GAWP), summarized as Algorithm 1. Here, we take the combination of GAWP and vanilla AT as an example. Note that it can be extended to other classic methods such as TRADES [6] and MART [7]. For each optimization step, we sample one batch of data and generate corresponding adversarial examples with the PGD attack. The importance score of each adversarial sample is determined by its adversarial risk and geometric distance to the decision boundary, which is then applied to weight perturbation. In essence, during weight perturbation, GAWP focuses more on small-loss data that are close to the decision boundary.
| Algorithm 1 Geometry-Aware Weight Perturbation (GAWP) |
| Input: DNN , training dataset , batch size m, learning rate , PGD step size , PGD steps , PGD constraint , GAWP stepes , GAWP constraint , parameter . Outout: Adversarially robust model . Repeat Sample a mini-batch with a size m from training set . Generate one batch of adversarial examples based on Equation (2) for steps. for do Compute based on Equation (12). end for Initialize for do end for Until training converges |
4. Experimental Results
In this section, we conduct extensive experiments to verify the effectiveness of GAWP, providing experimental settings, robustness evaluation and ablation studies.
4.1. Experimental Setup
For the model architecture, we use PreAct ResNet-18 [16] and Wide ResNet-34-10 [32]. Three datasets are considered: CIFAR-10, CIFAR-100 [17] and SVHN [33]. For CIFAR datasets, we apply random crops with four pixels of padding and random horizontal flips for the data augmentation. The proposed method GAWP is compared with a number of baseline methods including the vanilla AT [3], GAIRAT [4] and TRADES [6]. We also compare GAWP with advanced weight perturbation strategies, particularly AWP [10], RWP [14] and MLCATWP [15]. For adversary generation, a 10-step PGD attack with a random start is applied following the setting in [3]; under the threat model, the attack budget and the perturbation step size for the CIFAR datasets while for SVHN; and, under the threat model, and for all datasets. All experiments are conducted on four NVIDIA GeForce 2080Ti GPUs. The program is developed based on PyTorch 1.8.1 [34].
Training parameters. We use an SGD optimizer with a momentum of and a weight decay of . The model is trained for 200 epochs with a batch size of 128. The learning rate starts with ( for SVHN) and decays by 0.1 at the and epoch, respectively. For GAWP, the number of weight perturbation steps is set as , the perturbation constraint and for all datasets. The hyper-parameter settings of the baseline methods follow the recommendations of their original papers.
4.2. Robustness Evaluation
In this section, we present the main results of robustness evaluation for GAWP and various benchmark methods. We showcase the effectiveness of GAWP from two aspects: firstly, it enhances the robustness generalization of GAIRAT and avoids overfitting issues; secondly, GAWP consistently improves the test robustness across different datasets and threat models compared to other weight perturbation strategies.
4.2.1. Mitigating Robustness Generalization and Overfitting Issues
To validate that GAWP improves the robustness generalization of GAIRAT, we compare vanilla AT, GAIRAT and AT-GAWP using PreAct ResNet-18 on CIFAR-10. The evaluation results are presented in Table 3. For the checkpoint that achieves the highest test accuracy against PGD-10 attack, “Natural” denotes the model performance on the clean test data, and “AA” denotes the test accuracy under AutoAttack. It is observed that AT-GAWP achieves the highest model robustness against AutoAttack under both and threat models when compared to the other two baselines. Therefore, the robustness generalization issue of GAIRAT is effectively addressed in AT-GAWP.
Table 3.
Test robustness (%) on CIFAR-10 using PreAct ResNet-18. The highest accuracy or the smallest performance gap in each setting is marked in bold.
As for the robust overfitting issue, the test accuracy against PGD-10 attack is selected as the measure of robustness. The extent of robust overfitting is quantified with the performance gap (“Diff”) between the highest robustness ever achieved (“Best”) and the robustness of the last epoch checkpoint (“Last”). A larger gap indicates more severe robust overfitting. As shown in Table 3, both AT and GAIRAT suffer from robust overfitting, with a gap of over across all settings. On the contrary, the performance gap significantly shrinks for AT-GAWP (<1%), indicating effective suppression of robust overfitting.
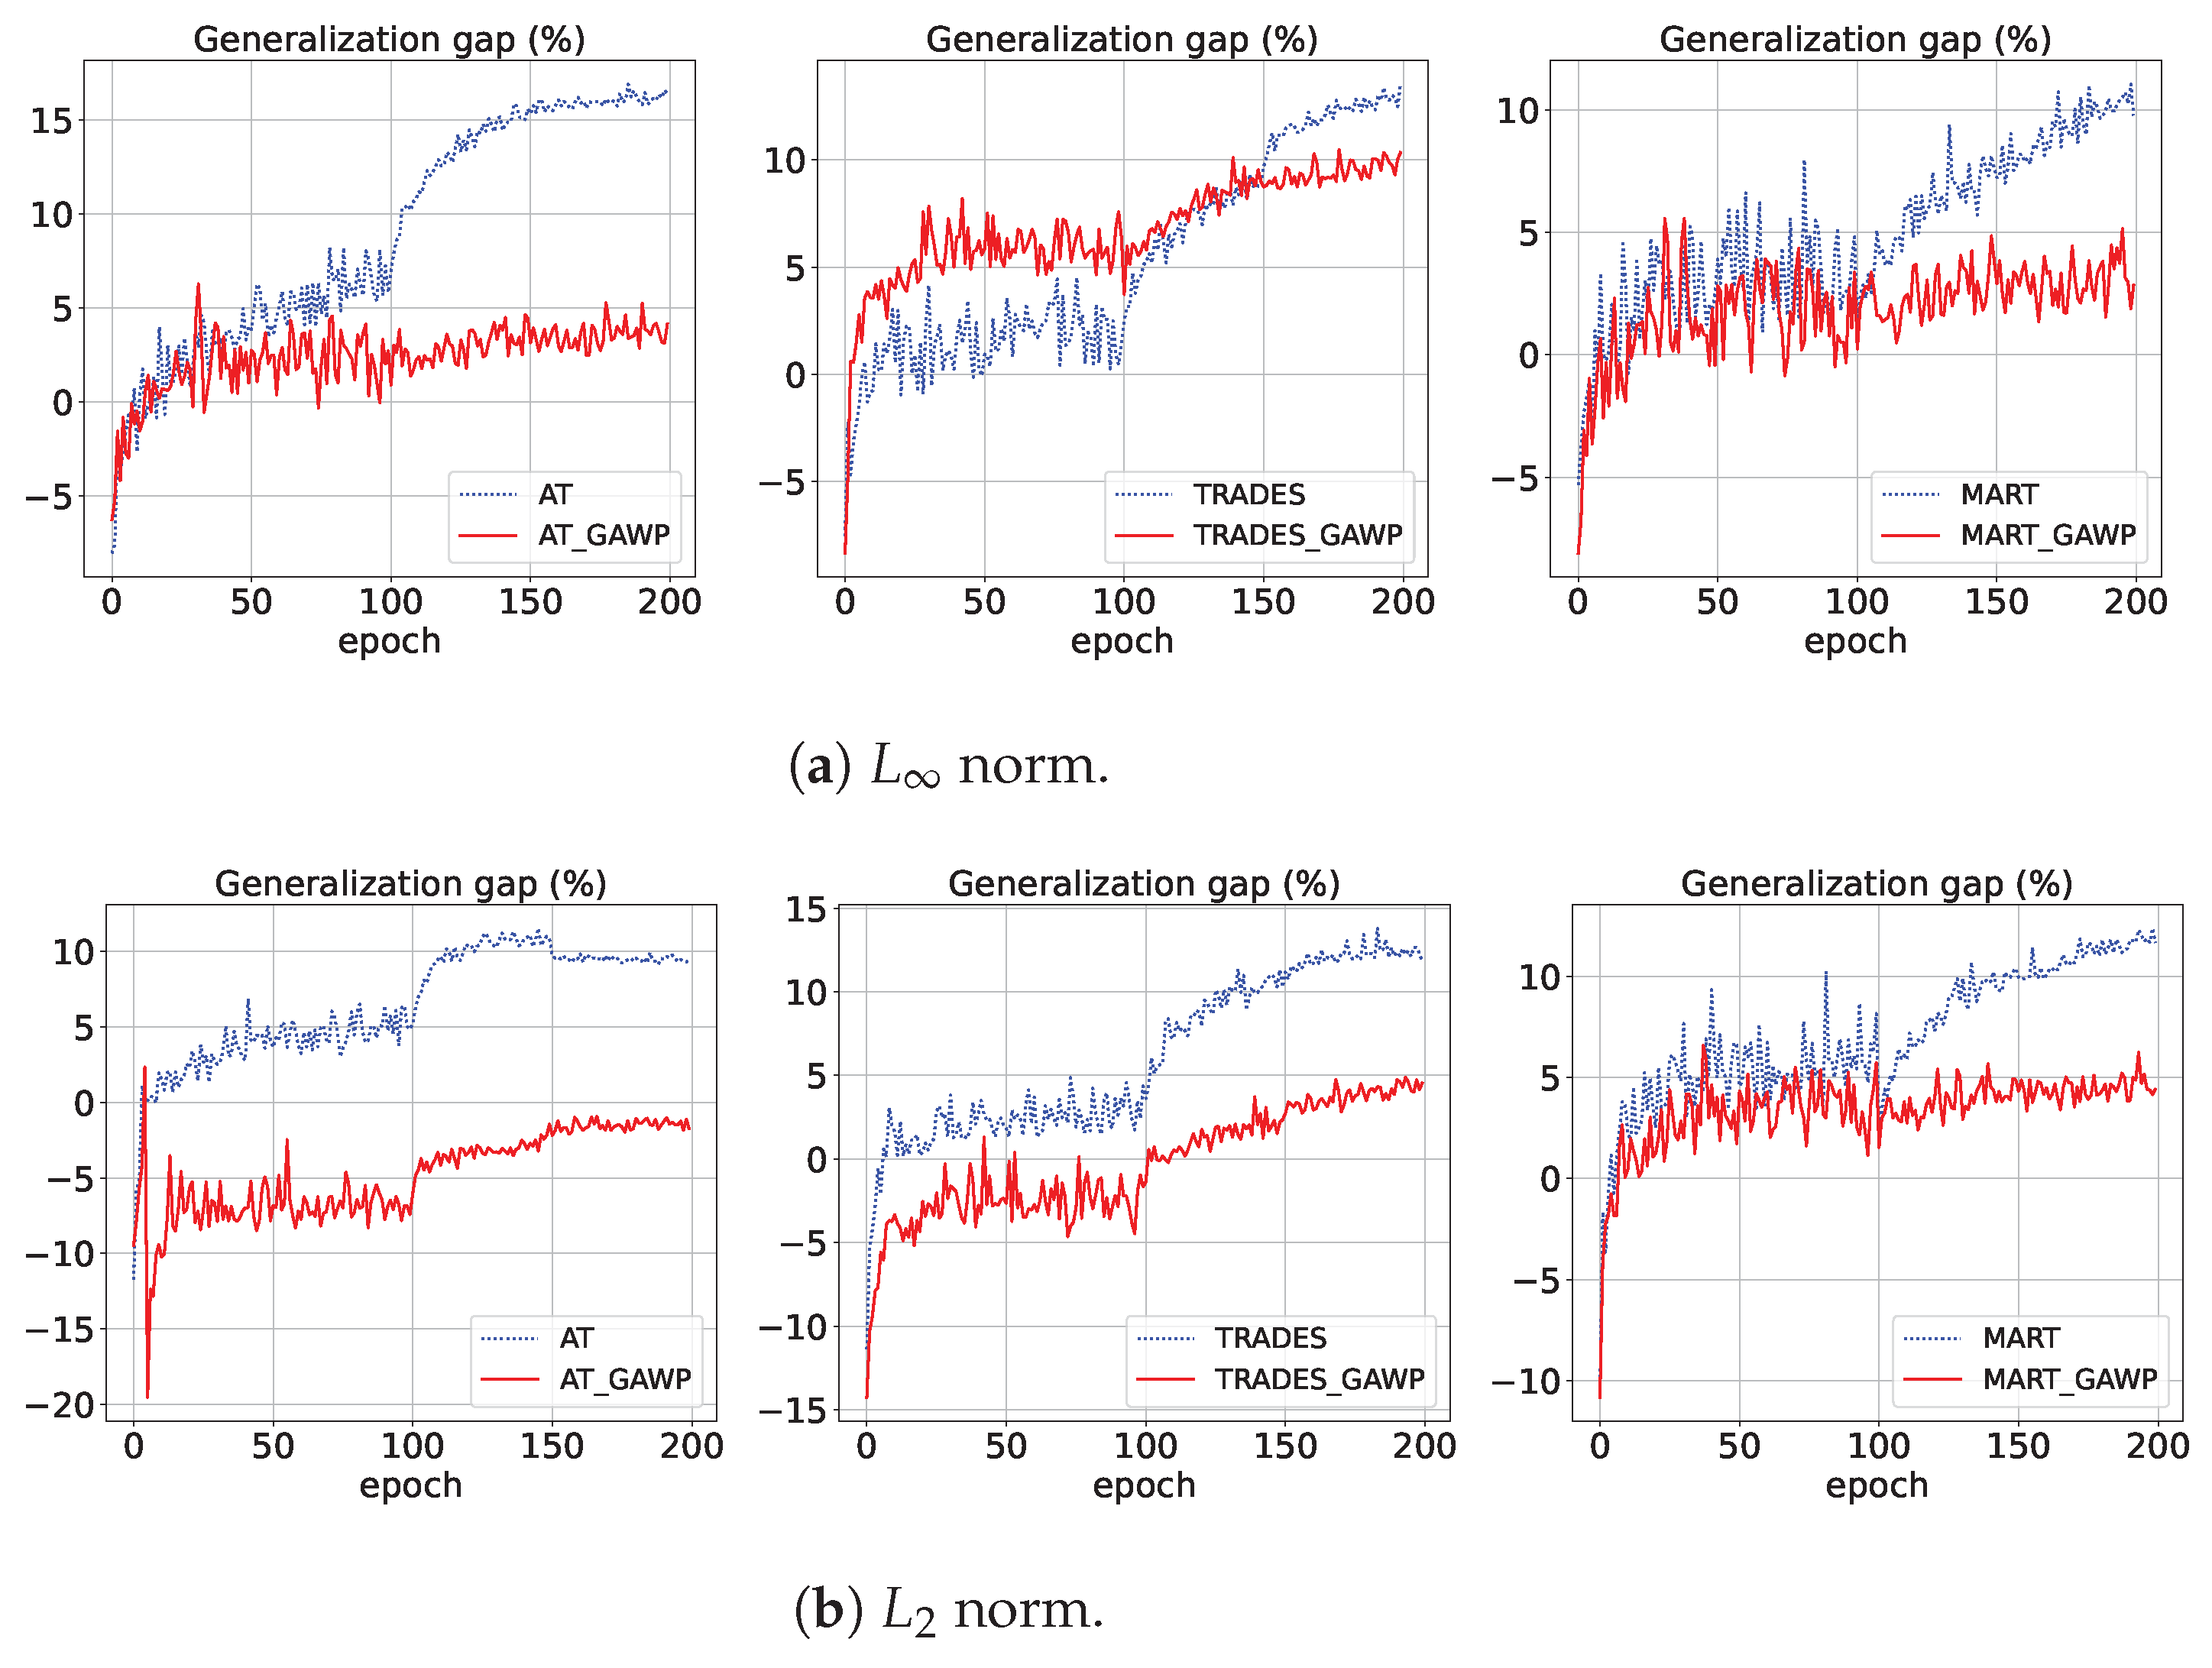
Along with exploring robust overfitting, we also examine the model’s generalization on natural data. The generalization gap, defined as the difference between training accuracy and test accuracy, is commonly chosen as an indicator of generalization. A smaller generalization gap implies a better generalization. According to Figure 4, when training with vanilla AT, the generalization gap surges after training for 100 epochs, showing a degradation of generalization to unseen natural data. With the help of GAWP, the generalization gap consistently stays below during the whole training process. For both and threat models, we obtain the same observation. Therefore, we claim that GAWP not only mitigates robust overfitting but also boosts the generalization to unseen natural data.
Figure 4.
A comparison in terms of generalization gap (training accuracy - test accuracy) on the natural data. With the help of GAWP, the overfitting issues is obviously alleviated, and the trained model possesses better generalization to unseen data. Such an observation applies for both settings of norm (a) and norm (b).
In addition to vanilla AT, we also extend GAWP to TRADES and MART. The experimental results are summarized in Table 3 and Figure 4. Similar patterns have been observed when combing GAWP with TRADES and MART. In conclusion, GAWP consistently enhances robustness generalization, improves natural data generalization and mitigates robust overfitting across various baseline methods and threat models.
4.2.2. Imposing Geometric Distance Benefits Weight Perturbation
Unlike existing weight perturbation strategies, we propose to determine the importance score of each adversarial example based on not only its adversarial risk but also its geometric distance to the decision boundary. Recall that the vanilla AWP treats all the adversarial examples equally during weight perturbation, while RWP conducts weight perturbation only on the data with an adversarial risk lower than a threshold. To showcase that weight perturbation benefits from the introduced geometric information, we compare AT assisted by GAWP (AT-GAWP) to vanilla AT, AT-AWP, AT-RWP and AT-MLCATWP using Wide ResNet-34-10 across different datasets and threat models. Based on the checkpoint that achieves the highest PGD-10 robustness for each benchmark method, we conduct the robustness evaluation and summarize the results in Table 4.
Table 4.
Test robustness (%) using Wide ResNet-34-10 across different datasets and threat models. The highest accuracy in each setting is marked in bold.
It is observed that GAWP consistently outperforms the other baseline weight perturbation strategies across different datasets and threat models in terms of test accuracy both on the clean dataset and under AutoAttack. This is due to GAWP providing a more comprehensive way to estimate the importance of each adversarial example during weight perturbation. We further claim that, to enhance the model robustness, weight perturbation benefits from assigning adversarial examples with unequal importance scores. In addition, an adversarial example with a lower adversarial risk and that is closer to the decision boundary should be assigned a higher importance score during weight perturbation.
4.3. Ablation Studies
4.3.1. Effect of Different Ways to Determine Importance Scores
GAWP determines the importance score of each example based on and . To observe the effect of each component, we conduct an ablation study and present the results in Table 5. When using only (GAWP_baseline), the model robustness against AutoAttack is , which is comparable to AWP (). Applying only, we can obtain a robustness of under AutoAttack, which is comparable with the state-of-the-art strategy RWP (). Using an ensemble of and (GAWP), model robustness is further improved. Similar patterns are observed on the natural data (“Natural”). Based on our observations, we assert that and work complementarily in determining the importance of each example during weight perturbation, both providing essential training signals.
Table 5.
Ablation study for examining the effect of each component based on CIFAR-10 using Wide ResNet-34-10 under the threat model. The highest accuracy is marked in bold.
For , we testify another design following the same idea:
Unlike , removes the nonlinearity led by the operation while assigning a higher importance score to the data with a lower adversarial risk. For , we investigate its reversed version, , defined as follows:
Opposite to , assigns a higher weight to the data that are more distant from the decision boundary. We conduct experiments based on the various strategies to determine the importance scores of adversarial examples during weight perturbation, and the results are summarized in Table 6.
Table 6.
Ablation study for comparing different importance score determination strategies based on CIFAR-10 using Wide ResNet-34-10 under the threat model. The highest accuracy in each setting is marked in bold.
It is observed that applying leads to a more robust model due to the additional operation. Additionally, assigning a higher importance score to the data that are further away from the decision boundary results in degradation of the model robustness. This observation supports our claim that, during weight perturbation, the data closer to the decision boundary deserve a higher importance score.
4.3.2. Hyper-Parameter Sensitivity
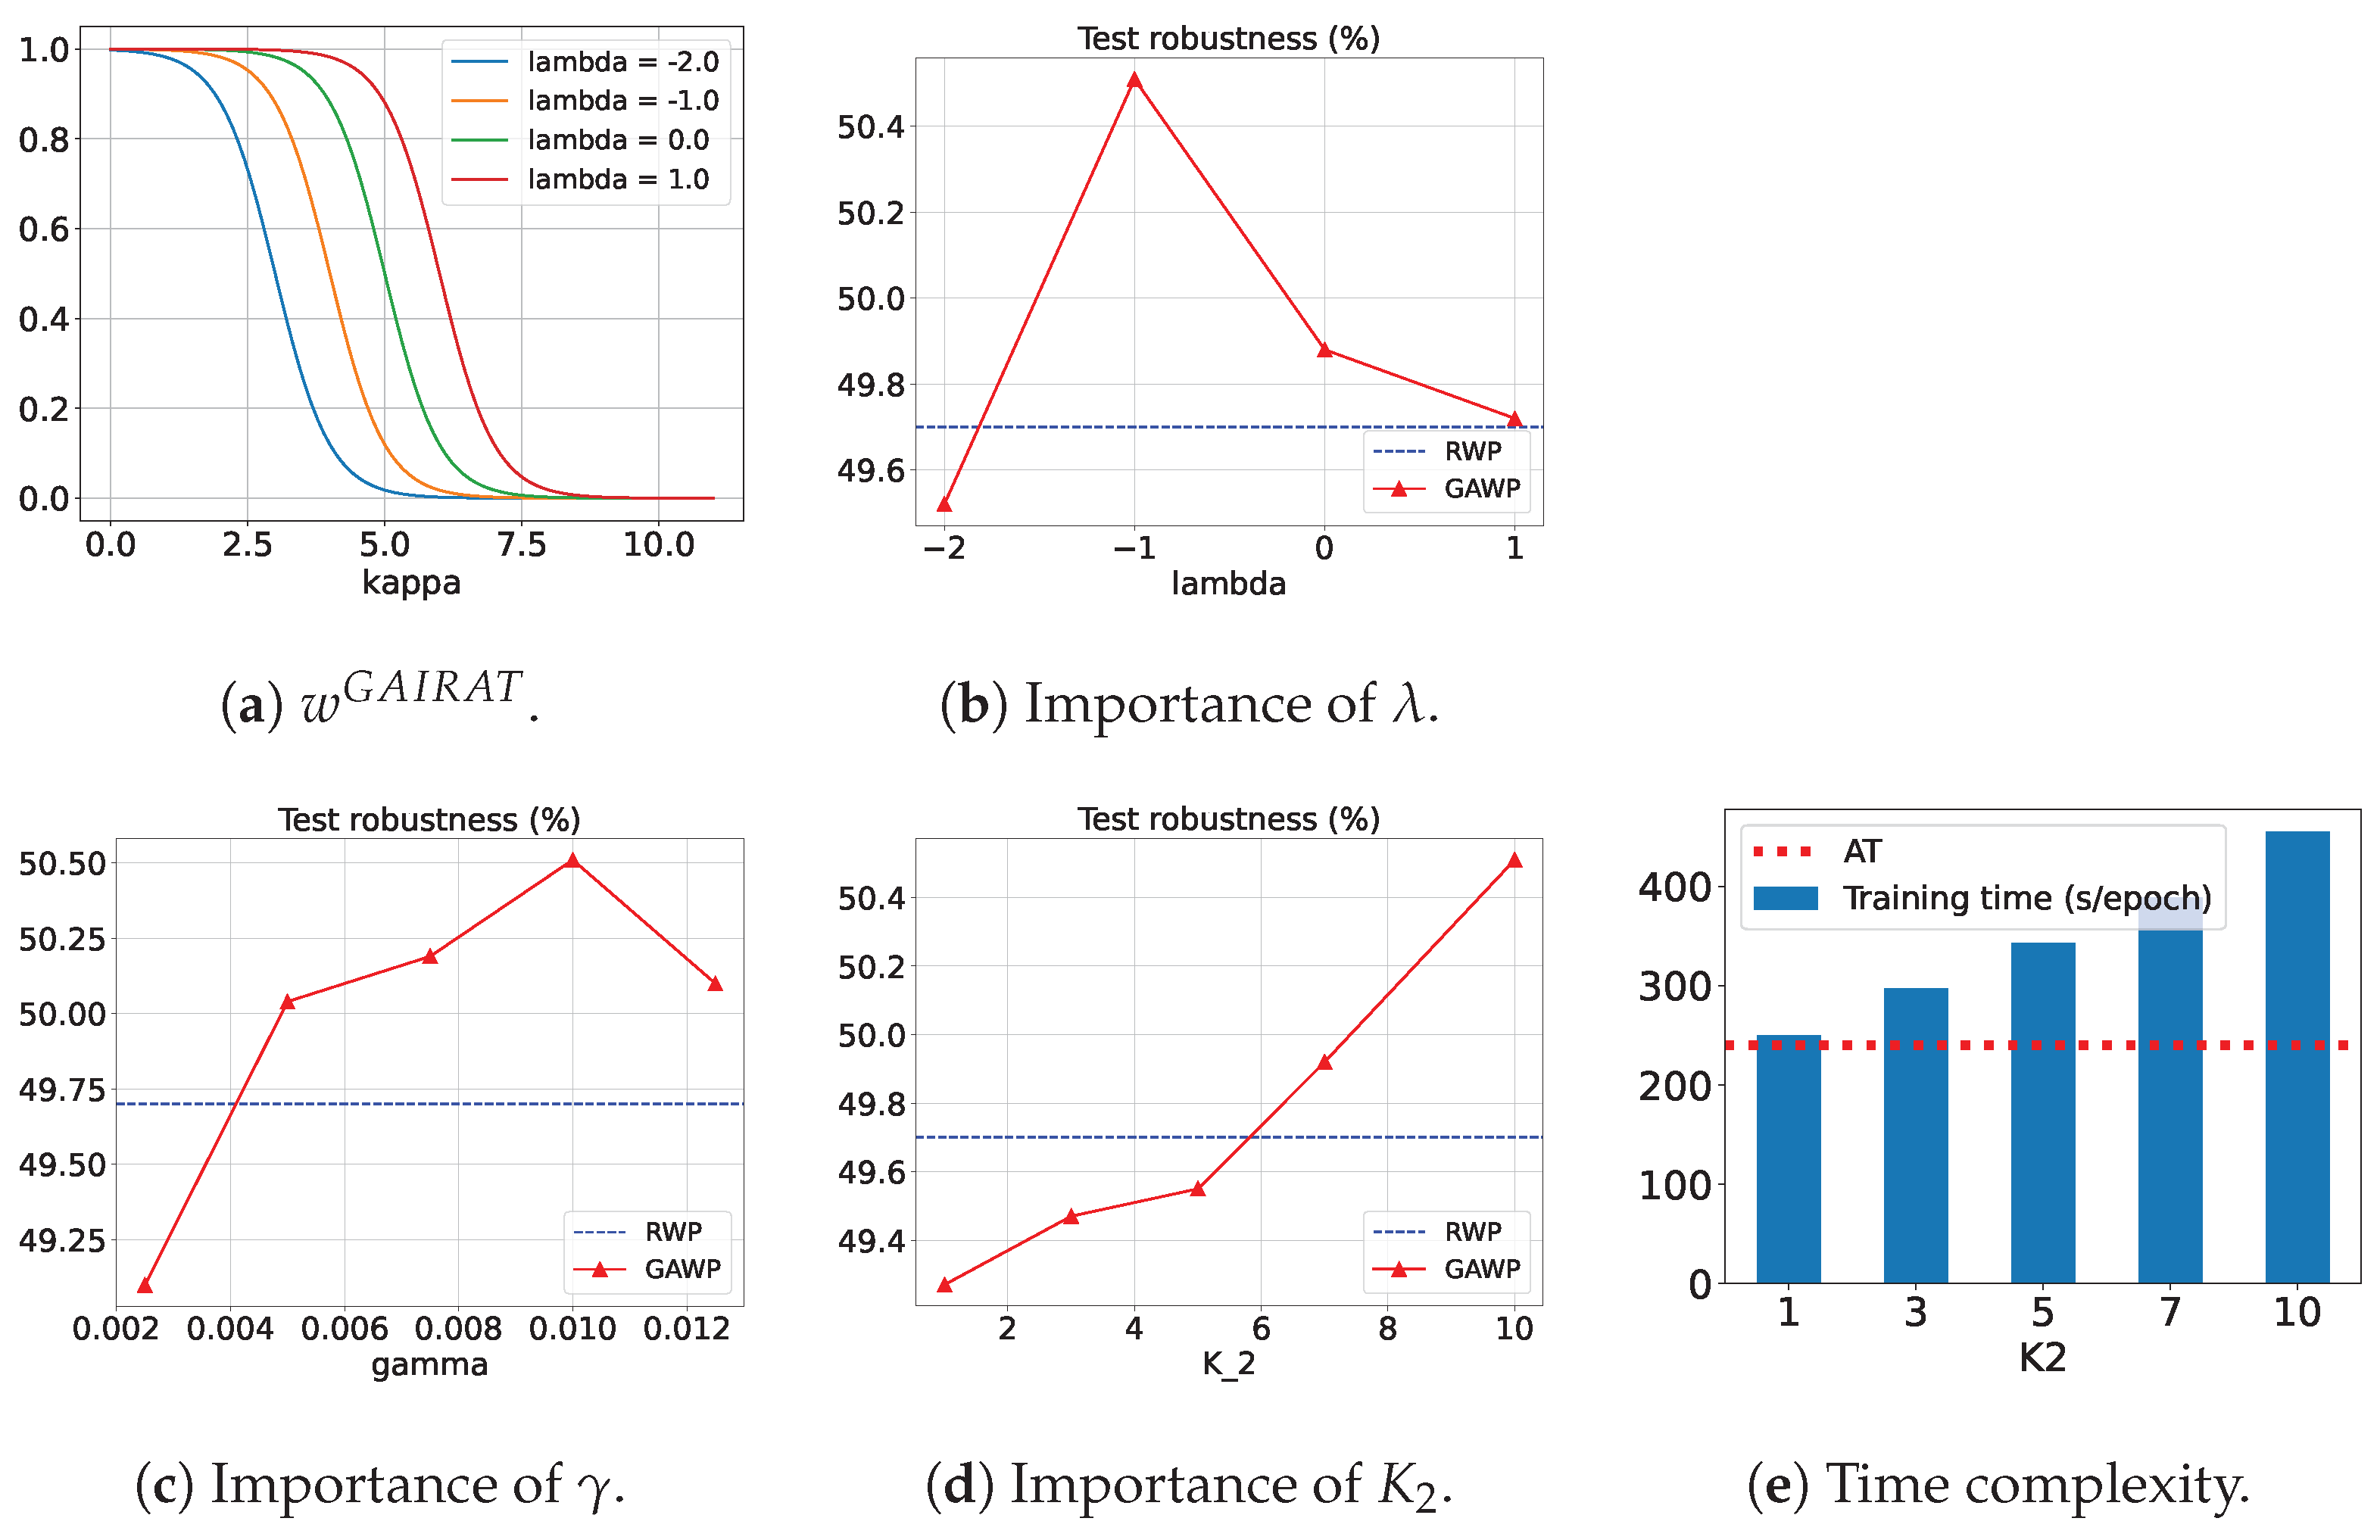
In this part, we investigate how sensitive the performance of GAWP is to the values of three main hyper-parameters: , and . Recall that defines the shape of . controls the size of the feasible region during the weight perturbation. is the number of steps for weight perturbation. We focus on the combination of AT and GAWP in this part. The analysis is based on CIFAR-10 under the threat model using PreAct ResNet-18.
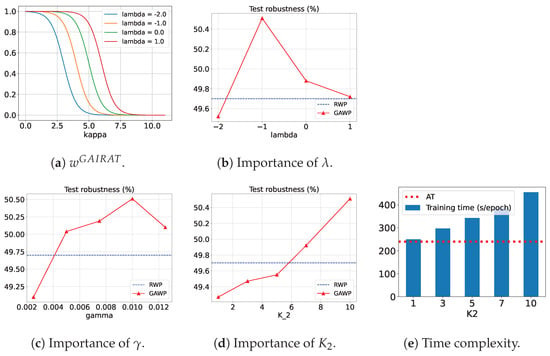
We first explore the performance of GAWP under different settings of . Recall that is the number of attack steps required for an example to fool the model. A smaller indicates that the adversarial example is closer to the decision boundary. is defined to assign a higher weight to the example that is closer to the decision boundary, while the hyper-parameter controls the shape. As shown in Figure 5a, as increases, tends to assign equal weights to all the examples, which degrades to vanilla AT as . To showcase the effect of , we train models under different values of while fixing and . Four values of are examined in the ablation study, and the results are summarized in Figure 5b. It is observed that the model achieves the highest robustness with , which is the same as the default setting proposed in GAIRAT [4].
Figure 5.
The ablation study investigating the importance of three hyper-parameters: , and . The parameter determines the shape of , as shown in (a). Measuring the model robustness in terms of the test accuracy under AutoAttack, the results of ablation study in terms of , and are presented in (b), (c) and (d), respectively. With different values of , the time cost per epoch of training is presented in (e).
We also investigate the effect of . Fixing and , the performance of GAWP is examined with a that varies from 0.0025 to 0.0125. It can be observed in Figure 5c that the model achieves the highest robustness when . Model robustness decreases rapidly when , indicating that the regularization is insufficient. When , the model robustness starts decreasing, showing that over-regularization is also detrimental to the training process.
As for studying the effect of , based on the results of previous studies, we fix and . The parameter of GAWP varies from 1 to 10. It can be observed in Figure 5d that the model achieves higher robustness as increases, which meets our expectation. Using RWP (, ) as the baseline, GAWP obviously outperforms RWP with the same . Such an observation further reflects the benefits of imposing geometric information to determine the importance of each example during weight perturbation. We also summarize the average time cost of one training epoch for each setting in Figure 5e. As increases, it takes longer for training due to the additional time complexity caused by the weight perturbation.
5. Limitations and Future Work
To provide a balanced view of our work, the limitations of the proposed method and future research directions are discussed in this section. There are two main limitations that await further study.
Extension to other data types. Note that the proposed method is only discussed in the context of image data. This is because the proposed method is based on a well-defined continuous optimization problem (7), which can be significantly different for text data or audio data. For text data, the generation of adversarial examples [35,36] is a discrete problem, and it requires the elimination of grammatical and semantic problems perceptible to humans [37,38]. For audio data, although the adversary generation process is similar to that in the image setting [39,40], the training process may be entangled with regular training [41] or introduce additional models [42]. Since the problem formulations in these settings are different from (7), whether the insights provided in this paper can be applied to text data or audio data remains unclear, which suggests an interesting research direction.
Theoretical proof. Although the effectiveness of AWP [10] has been theoretically justified, the reason why treating examples in an unequal manner enhances model robustness is still unaddressed. Similar to related works such as RWP [14] and MLCATWP [15], this paper develops a weight perturbation strategy based on empirical intuitions. Although the effectiveness of the proposed method has been substantiated by extensive experiment results, discovering how to understand the robustness improvement from a theoretical perspective remains an open question.
6. Conclusions
In this paper, we investigate the robustness generalization issue of GAIRAT from the perspective of the weight loss landscape. We identify that GAIRAT leads to a sharp local minimum and mitigate the robustness generalization issue by imposing regularization on the weight loss landscape through weight perturbation. Inspired by this, we propose Geometry-Aware Weight Perturbation (GAWP). Unlike existing weight perturbation strategies, we impose additional geometric information of each adversarial example along with its adversarial risk to determine its importance score during weight perturbation. Comprehensive experiments show that GAWP eliminates the robustness generalization issue of GAIRAT and improves adversarial robustness across various network architectures and datasets (Table 3) as compared to existing weight perturbation strategies (Table 4).
Note that GAWP is a general adversarial training method that can be applied to various real-world computer vision applications, especially those requiring model robustness against input perturbations. For instance, the intelligent power line inspection system detects external obstacles of transmission lines in the power grid [43,44]. Technically, the system acquires image data using visual sensors and leverages object detection techniques to identify obstacles in the images. In real-world scenarios, the acquired images may be distorted by the sensor noise or adverse weather conditions. Therefore, it is essential for the object detection model to maintain its performance despite these perturbations. In the near future, we plan to apply GAWP to train the model of an intelligent drone-based power asset management system to further enhance its robustness.
Author Contributions
Conceptualization, Y.J.; methodology, Y.J. and H.-D.C.; software, Y.J.; validation, Y.J. and H.-D.C.; formal analysis, Y.J.; investigation, Y.J.; resources, H.-D.C.; writing—original draft preparation, Y.J.; writing—review and editing, H.-D.C. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The original data presented in the study are openly available at https://www.cs.toronto.edu/~kriz/cifar.html (accessed on 3 September 2024) and http://ufldl.stanford.edu/housenumbers/ (accessed on 3 September 2024). Code is available at https://github.com/yj373/GAWP (accessed on 3 September 2024).
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Bai, T.; Luo, J.; Zhao, J.; Wen, B.; Wang, Q. Recent Advances in Adversarial Training for Adversarial Robustness. In Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, Montreal, QC, Canada, 19–26 August 2021; pp. 4312–4321. [Google Scholar]
- Yurtsever, E.; Lambert, J.; Carballo, A.; Takeda, K. A Survey of Autonomous Driving: Common Practices and Emerging Technologies. IEEE Access 2020, 8, 58443–58469. [Google Scholar] [CrossRef] [Scilit]
- Madry, A.; Makelov, A.; Schmidt, L.; Tsipras, D.; Vladu, A. Towards Deep Learning Models Resistant to Adversarial Attacks. In Proceedings of the International Conference on Learning Representations, Vancouver, BC, Canada, 30 April–3 May 2018. [Google Scholar]
- Zhang, J.; Zhu, J.; Niu, G.; Han, B.; Sugiyama, M.; Kankanhalli, M.S. Geometry-aware Instance-reweighted Adversarial Training. arXiv 2020, arXiv:2010.01736. [Google Scholar] [CrossRef] [Scilit]
- Hitaj, D.; Pagnotta, G.; Masi, I.; Mancini, L.V. Evaluating the Robustness of Geometry-Aware Instance-Reweighted Adversarial Training. arXiv 2021, arXiv:2103.01914. [Google Scholar] [CrossRef] [Scilit]
- Zhang, H.; Yu, Y.; Jiao, J.; Xing, E.; El Ghaoui, L.; Jordan, M. Theoretically Principled Trade-off between Robustness and Accuracy. In Proceedings of the International Conference on Machine Learning, Long Beach, CA, USA, 9–15 June 2019; pp. 7472–7482. [Google Scholar]
- Wang, Y.; Zou, D.; Yi, J.; Bailey, J.; Ma, X.; Gu, Q. Improving Adversarial Robustness Requires Revisiting Misclassified Examples. In Proceedings of the International Conference on Learning Representations, Addis Ababa, Ethiopia, 26 April–1 May 2020. [Google Scholar]
- Freund, Y.; Schapire, R.E. A Decision-Theoretic Generalization of On-Line Learning and an Application to Boosting. J. Comput. Syst. Sci. 1997, 55, 119–139. [Google Scholar] [CrossRef] [Scilit]
- Lin, T.Y.; Goyal, P.; Girshick, R.; He, K.; Dollár, P. Focal Loss for Dense Object Detection. In Proceedings of the IEEE International Conference on Computer Vision, Venice, Italy, 22–29 October 2017; pp. 2980–2988. [Google Scholar]
- Wu, D.; Xia, S.T.; Wang, Y. Adversarial Weight Perturbation Helps Robust Generalization. Adv. Neural Inf. Process. Syst. 2020, 33, 2958–2969. [Google Scholar]
- Li, H.; Xu, Z.; Taylor, G.; Studer, C.; Goldstein, T. Visualizing the Loss Landscape of Neural Nets. Adv. Neural Inf. Process. Syst. 2018, 6389–6399. [Google Scholar]
- Neyshabur, B.; Bhojanapalli, S.; McAllester, D.; Srebro, N. Exploring Generalization in Deep Learning. Adv. Neural Inf. Process. Syst. 2017, 30, 5947–5956. [Google Scholar]
- Rice, L.; Wong, E.; Kolter, J.Z. Overfitting in adversarially robust deep learning. In Proceedings of the International Conference on Machine Learning, Virtual, 12–18 July 2020; pp. 8093–8104. [Google Scholar]
- Yu, C.; Han, B.; Gong, M.; Shen, L.; Ge, S.; Bo, D.; Liu, T. Robust Weight Perturbation for Adversarial Training. In Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, Vienna, Austria, 23–29 July 2022; pp. 3659–3665. [Google Scholar]
- Yu, C.; Han, B.; Shen, L.; Yu, J.; Gong, C.; Gong, M.; Liu, T. Understanding Robust Overfitting of Adversarial Training and Beyond. In Proceedings of the International Conference on Machine Learning, Baltimore, MD, USA, 17–23 July 2022. [Google Scholar]
- He, K.; Zhang, X.; Ren, S.; Sun, J. Identity mappings in deep residual networks. In Proceedings of the European Conference on Computer Vision, Amsterdam, The Netherlands, 11–14 October 2016; pp. 630–645. [Google Scholar]
- Krizhevsky, A. Learning Multiple Layers of Features from Tiny Images; Technical Report 0; University of Toronto: Toronto, ON, USA, 2009. [Google Scholar]
- Croce, F.; Hein, M. Reliable evaluation of adversarial robustness with an ensemble of diverse parameter-free attacks. In Proceedings of the International Conference on Machine Learning, Virtual, 12–18 July 2020; pp. 2206–2216. [Google Scholar]
- Carlini, N.; Wagner, D. Towards Evaluating the Robustness of Neural Networks. In Proceedings of the 2017 IEEE Symposium on Security and Privacy (SP), San Jose, CA, USA, 22–26 May 2017; pp. 39–57. [Google Scholar]
- Meng, D.; Chen, H. MagNet: A Two-Pronged Defense against Adversarial Examples. In Proceedings of the 2017 ACM SIGSAC Conference on Computer and Communications Security, Dallas, TX, USA, 30 October–3 November 2017; pp. 135–147. [Google Scholar]
- Vincent, P.; Larochelle, H.; Bengio, Y.; Manzagol, P.A. Extracting and composing robust features with denoising autoencoders. In Proceedings of the 25th International Conference on Machine Learning, Helsinki, Finland, 5–9 July 2008; pp. 1096–1103. [Google Scholar]
- Samangouei, P.; Kabkab, M.; Chellappa, R. Defense-GAN: Protecting Classifiers against Adversarial Attacks Using Generative Models. In Proceedings of the International Conference on Learning Representations, Vancouver, BC, Canada, 30 April–3 May 2018. [Google Scholar]
- Nie, W.; Guo, B.; Huang, Y.; Xiao, C.; Vahdat, A.; Anandkumar, A. Diffusion Models for Adversarial Purification. In Proceedings of the International Conference on Machine Learning, Baltimore, MD, USA, 17–23 July 2022; pp. 16805–16827. [Google Scholar]
- Goodfellow, I.; Pouget-Abadie, J.; Mirza, M.; Xu, B.; Warde-Farley, D.; Ozair, S.; Courville, A.; Bengio, Y. Generative Adversarial Nets. Adv. Neural Inf. Process. Syst. 2014, 27, 2672–2680. [Google Scholar]
- Gulrajani, I.; Ahmed, F.; Arjovsky, M.; Dumoulin, V.; Courville, A.C. Improved Training of Wasserstein GANs. Adv. Neural Inf. Process. Syst. 2017, 30, 5767–5777. [Google Scholar]
- Ho, J.; Jain, A.; Abbeel, P. Denoising Diffusion Probabilistic Models. In Proceedings of the Advances in Neural Information Processing Systems, virtual, 6–12 December 2020; Volume 33, pp. 6840–6851. [Google Scholar]
- Carmon, Y.; Raghunathan, A.; Schmidt, L.; Duchi, J.C.; Liang, P.S. Unlabeled Data Improves Adversarial Robustness. Adv. Neural Inf. Process. Syst. 2019, 32, 11190–11201. [Google Scholar]
- Dong, Y.; Xu, K.; Yang, X.; Pang, T.; Deng, Z.; Su, H.; Zhu, J. Exploring Memorization in Adversarial Training. In Proceedings of the International Conference on Learning Representations, Virtual, 25–29 April 2022. [Google Scholar]
- Chen, T.; Zhang, Z.; Wang, P.; Balachandra, S.; Ma, H.; Wang, Z.; Wang, Z. Sparsity Winning Twice: Better Robust Generalization from More Efficient Training. In Proceedings of the International Conference on Learning Representations, Virtual, 25–29 April 2022. [Google Scholar]
- Chen, T.; Zhang, Z.; Liu, S.; Chang, S.; Wang, Z. Robust Overfitting may be mitigated by properly learned smoothening. In Proceedings of the International Conference on Learning Representations, Vienna, Austria, 3–7 May 2021. [Google Scholar]
- Lin, L.; Spratling, M. Understanding and combating robust overfitting via input loss landscape analysis and regularization. Pattern Recognit. 2023, 136, 109229. [Google Scholar]
- Zagoruyko, S.; Komodakis, N. Wide Residual Networks. In Proceedings of the British Machine Vision Conference, York, UK, 19–22 September 2016. [Google Scholar]
- Netzer, Y.; Wang, T.; Coates, A.; Bissacco, A.; Wu, B.; Ng, A.Y. Reading Digits in Natural Images with Unsupervised Feature Learning. In Proceedings of the NIPS Workshop on Deep Learning and Unsupervised Feature Learning, Granada, Spain, 12–17 December 2011. [Google Scholar]
- Paszke, A.; Gross, S.; Massa, F.; Lerer, A.; Bradbury, J.; Chanan, G.; Killeen, T.; Lin, Z.; Gimelshein, N.; Antiga, L.; et al. PyTorch: An Imperative Style, High-Performance Deep Learning Library. In Proceedings of the Advances in Neural Information Processing Systems; Wallach, H., Larochelle, H., Beygelzimer, A., d’Alché-Buc, F., Fox, E., Garnett, R., Eds.; Curran Associates, Inc.: Red Hook, NY, USA, 2019; Volume 32. [Google Scholar]
- Zhao, Z.; Dua, D.; Singh, S. Generating Natural Adversarial Examples. In Proceedings of the International Conference on Learning Representations, Vancouver, BC, Canada, 30 April–3 May 2018. [Google Scholar]
- Kim, Y.; Jernite, Y.; Sontag, D.; Rush, A.M. Character-Aware Neural Language Models. In Proceedings of the Thirtieth AAAI Conference on Artificial Intelligence, Phoenix, AZ, USA, 12–17 February 2016; pp. 2741–2749. [Google Scholar]
- Wang, Y.; Gao, J.; Cheng, G.; Jiang, T.; Li, J. Textual Adversarial Training of Machine Learning Model for Resistance to Adversarial Examples. Secur. Commun. Netw. 2022, 2022, 4511510. [Google Scholar]
- Li, L.; Qiu, X. TextAT: Adversarial Training for Natural Language Understanding with Token-Level Perturbation. arXiv 2020, arXiv:2004.14543. [Google Scholar]
- Raina, V.; Gales, M.J.F.; Knill, K. Universal Adversarial Attacks on Spoken Language Assessment Systems. In Proceedings of the Interspeech, Shanghai, China, 25–29 October 2020; pp. 3855–3859. [Google Scholar]
- Wu, H.; Liu, S.; Meng, H.M.; Lee, H.y. Defense Against Adversarial Attacks on Spoofing Countermeasures of ASV. In Proceedings of the ICASSP 2020—2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Virtual, 4–9 May 2020; pp. 6564–6568. [Google Scholar]
- Li, R.; Jiang, J.Y.; Wu, X.; Hsieh, C.C.; Stolcke, A. Speaker Identification for Household Scenarios with Self-attention and Adversarial Training. In Proceedings of the Interspeech, Shanghai, China, 25–29 October 2020. [Google Scholar]
- Li, X.; Li, N.; Zhong, J.; Wu, X.; Liu, X.; Su, D.; Yu, D.; Meng, H. Investigating Robustness of Adversarial Samples Detection for Automatic Speaker Verification. In Proceedings of the Interspeech, Shanghai, China, 25–29 October 2020; pp. 981–985. [Google Scholar]
- Lv, X.L.; Chiang, H.D. Visual clustering network-based intelligent power lines inspection system. Eng. Appl. Artif. Intell. 2024, 129, 107572. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Chen, Q.; Zhu, L. A survey of intelligent transmission line inspection based on unmanned aerial vehicle. Sci. Rep. 2022, 12, 6617. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2024 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).