Implementing a Cognitively Grounded Artificial Moral Advisor: A Multi-LLM Multi-Agent Approach Based on the Cognitive–Reflective Equilibration Model

Abstract
1. Introduction
2. Theoretical Framework
2.1. Artificial Moral Advisors
2.1.1. Conceptual Foundations and Typological Development of Artificial Moral Agents
2.1.2. From Autonomous Agents to Advisory Systems: The Artificial Moral Advisor Paradigm
2.2. Multi-Agent Systems
- a role-differentiated multi-agent structure, in which agents are specialized by assigned reasoning role (role-based cooperation; Liu et al., 2025);
- a multi-LLM configuration assigning multiple heterogeneous LLMs to distinct reasoning roles, so that alternatives and counterarguments are generated independently rather than by a single model (cross-reflection and debate-based cooperation; Liu et al., 2025);
- a procedural control structure implementing the orchestration mechanisms of task decomposition and allocation, control-flow sequencing, state management and persistence, and error detection and recovery, realized as an explicit state graph (Zhu et al., 2026);
- a knowledge-base and reasoning-bank design for retrieval-based grounding (retrieval-augmented generation; Liu et al., 2025);
- communication-interface design principles that standardize agent-to-tool and agent-to-agent information exchange (the MCP and A2A concepts; Zhu et al., 2026);
- an execution coordination scheme based on hierarchical and centralized interaction structures (Li et al., 2024; Zhu et al., 2026);
- an agent procedure design reflecting the five functional modules of profile, perception, self-action, interaction, and evolution (Li et al., 2024; Wang et al., 2024);
- a dedicated evaluation component separate from the task-performing agents (agent evaluator; Liu et al., 2025), realized in CREA as the Measurement Agent.
2.3. The Cognitive–Reflective Equilibration Model (CREM)
2.3.1. Theoretical Foundations: Integrating Piaget and Rawls
2.3.2. The Humanities-Based Meta-Model of Ethical Decision-Making
2.3.3. The Conceptual Model (CCREM)
2.3.4. The Operational Model (OCREM): Four Stages, Twenty Steps
2.3.5. Prior Validation of OCREM
2.3.6. From CREM to CREA: The Gap Addressed Here
2.4. Recent Research on Ethical AI
2.4.1. Ethical Decision-Making in AI
2.4.2. Ethical Multi-Agent Systems
2.4.3. Synthesis: Positioning the Present Study
3. Methods
3.1. System Implementation and Infrastructure
3.2. Agent Architecture and CREM Workflow
3.3. Knowledge Components: EPKB and ERB
3.4. Multi-LLM Ensemble and Outcome Measures
3.5. Experimental Conditions
3.6. Data Preparation and Statistical Analysis
4. Results
4.1. Design and Implementation (RQ1)
4.1.1. Client Interface
4.1.2. Agent Architecture and Workflow
4.1.3. Knowledge Components: EPKB and ERB
4.1.4. Multi-LLM Ensemble Design
4.2. Evaluation
4.2.1. Level of Advice Quality Across Architectures (RQ2)
4.2.2. Pairwise Comparisons Among Architectures (RQ3)
4.2.3. Internal Consistency of Architecture-Level Measurement Scores
4.2.4. Differences in Cronbach’s α Across Architecture Development Stages
4.2.5. Extended Descriptive Statistics and Distributional (Box-Plot) Analysis
4.2.6. Reported Call Counts, Tokens, Latency, and Cost
4.2.7. Summary of Findings
5. Discussion
5.1. Principal Findings in Relation to the Research Questions
5.2. Theoretical Implications
5.2.1. Cognitive Grounding and Computational Reflective Equilibrium
5.2.2. Comparative Interpretation with Prior Work
5.2.3. The Trade-Off Between Procedural Fidelity and Deliberative Expansion
5.2.4. Contribution to Artificial Moral Advisor Theory
5.3. Confounds and Alternative Explanations
5.4. Limitations and Future Work
6. Conclusions
Supplementary Materials
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Acknowledgments
Conflicts of Interest
Abbreviations
| A2A | Agent-to-Agent (protocol) |
| AMA | Artificial Moral Advisor |
| BM25 | Best Matching 25 (lexical ranking function) |
| CI | Confidence Interval |
| CREA | Cognitive–Reflective Equilibration Architecture |
| CREM | Cognitive–Reflective Equilibration Model |
| CSV | Comma-Separated Values |
| dz | Cohen’s dz (matched-samples effect size) |
| EPKB | Ethical Principles Knowledge Base |
| ERB | Ethical Reasoning Bank |
| JSON | JavaScript Object Notation |
| KRB | Knowledge/Reasoning Bank |
| LLM | Large Language Model |
| MCP | Model Context Protocol |
| NAI | Normative Alignment Index |
| OCREM | Operational Cognitive–Reflective Equilibration Model |
| RAG | Retrieval-Augmented Generation |
| RQ | Research Question |
| SD | Standard Deviation |
| SSE | Server-Sent Events |
Appendix A. OCREM Requests and Moral Dilemma Cases

| Stages | Procedural Requests |
|---|---|
| Stage 1 Cognitive Processing | The text of the ethical dilemma or judgment case is inserted at the head of the prompt, and the model is directed to work through the numbered requests in order. |
| 1. Identify and explain the objective elements of the case: the stakeholders involved, the established facts, and the ethical considerations at stake. | |
| 2. State an intuitive moral judgment about the case, with its grounds, building on the Step 1 analysis. | |
| 3. Drawing on the Step 1 analysis, survey a range of ethical principles or ethical judgment cases that bear on the dilemma. | |
| 4. Set the Step 2 intuition against the principles and cases collected in Step 3 and characterize how they relate. | |
| 5. Classify that relation as fully mutually supportive, partially inconsistent, or completely inconsistent. | |
| 6. Where full mutual support holds, give the rationale, adopt the supported judgment as the final decision, write a decision statement, and jump to Step 18. | |
| Stage 2 Reflective Processing | 7. For each partial or complete inconsistency found in Step 5, articulate its underlying reason. |
| 8. Assess whether the conflict can be resolved by selecting among, or mutually adjusting, the intuitive judgment, the principles, and the cases. | |
| 9. If resolution is judged feasible, justify this and proceed directly to Step 11 (Step 10 is skipped); if infeasible, proceed to Step 10. | |
| 10. Where resolution is infeasible, explain why, forecast and appraise the consequences of the impasse, and terminate the procedure. | |
| 11. Sketch alternative ethical principles or judgment cases beyond those examined in Step 3. | |
| 12. Lay out the considerations for and against the Step 2 intuition, and for and against the Step 3 principles and cases. | |
| 13. Do the same for each alternative introduced in Step 11. | |
| 14. Consolidate Steps 12–13 into the intuitive judgment and its competing judgments; for every competitor, tally supporting and opposing opinions drawn from external information (statistics, expert views, etc.) and convert the tallies into percentage support and opposition ratios. | |
| 15. Justify the scores assigned in Step 14 by citing the external evidence used. | |
| Stage 3 Equilibration (Ethical Judgment) | 16. If one or more competing judgments lead the opposition by 30 points or more in support score, select one of them or adjust among them to determine the optimal ethical judgment, write a decision statement, and jump to Step 18; otherwise continue to Step 17. |
| 17. Where no judgment clears the threshold, draft a decision statement that coordinates the competing judgments summarized in Step 14. | |
| Stage 4 Ethical Implementation and Evaluation | 18. Compare the initial intuition with the final decision reached through Steps 1–17, and state whether consistency has been preserved and justification achieved through the refined ethical principles. |
| 19. Project the outcomes to be expected if the final decision were enacted. | |
| 20. Appraise whether the outcomes projected in Step 19 would contribute to resolving the dilemma originally posed. |
| Category | No. | Field | Moral Dilemma Cases |
|---|---|---|---|
| Human | 1 | Medical | How a physician should proceed when financial hardship leads a patient to decline treatment they need |
| 2 | Environment | Weighing zero-packaging eco-friendly goods against plastic-wrapped goods that keep products fresher | |
| 3 | Counseling | What a social worker should do when a domestic-violence victim asks that the abuse be kept confidential | |
| 4 | Social Welfare | How to triage several urgent aid requests when welfare resources cannot cover them all | |
| 5 | School | Whether, and in what way, to step in upon witnessing a friend being bullied | |
| 6 | War | A wartime situation in which an infant’s crying threatens to reveal hiding villagers to searching enemy troops | |
| 7 | Rescue | Whether an already-full lifeboat should take aboard additional survivors | |
| 8 | Finance | How a financial professional should act when a client’s interests collide with the firm’s | |
| 9 | Construction | What a site supervisor should do on discovering safety hazards at a construction site | |
| 10 | Workplace | Whether to disclose product defects or to honor an obligation of corporate confidentiality | |
| AI | 11 | AI Recruitment | Whether an AI hiring system shown to be biased should remain in use |
| 12 | AI Speaker | Trading off the emergency-response capability of AI speakers against personal privacy | |
| 13 | Facial Recognition CCTV | Crime-preventive facial-recognition CCTV versus the stigmatization of former offenders | |
| 14 | Police Robot | The ethics of deploying police robots in view of their malfunction risks | |
| 15 | Deepfake | Therapeutic uses of deepfake technology to recreate deceased individuals versus its potential for abuse | |
| 16 | Cleaning Robot | Adopting cleaning robots at the cost of employment opportunities for older workers | |
| 17 | Drone Delivery | Job losses among delivery workers that a drone-delivery rollout may cause | |
| 18 | AI Weapons | The defense benefits of AI-weapons development weighed against their malfunction risks | |
| 19 | AI-Generated Images | Whether AI-generated artworks should be eligible for exhibition prizes | |
| 20 | Care Robot | Effects of emotional care robots on the parent–child relationship |
Appendix B. Technical Implementation Details
Appendix B.1. Software Stack and Infrastructure
Appendix B.2. Workflow Branching
Appendix B.3. Retrieval Parameters
Appendix B.4. Measurement Aggregation
Appendix C. Measurement Agent—Evaluation Metric Definitions
Appendix C.1. Overview of Evaluation Metrics
| Metric | Measurement Target | Scale | Representative Value |
|---|---|---|---|
| Consistency | Integrated data from Steps 18–20 (initial judgment ↔ final decision) | 1–5 points | mean |
| Justifiability | Integrated data from Steps 18–20 (justification by the enhanced principle) | 1–5 points | mean |
| Procedural Validity | Each stage of the 20-step CREM process (A1–A20) | 1–5 points | mean of stage means |
| NAI (Normative Alignment Index) | Final decision ↔ ethical-principle alignment | Relevance 0–5 pts Alignment 1–5 pts | GAI |
| Metric | Evaluation Query (LLM Prompt) | Response Format | Formula |
|---|---|---|---|
| Consistency | Across the outcomes derived from the CREM-based ethical decision-making procedure, compare the intuitive moral judgment of the ethical dilemma with the final ethical decision and assess whether logical consistency has been established.
| score = N, reason ≤ 3 sentences | Statistics computed after parallel measurement by 5 LLMs:
|
| Justifiability | Across the outcomes derived from the CREM-based ethical decision-making procedure, compare the intuitive moral judgment of the ethical dilemma with the final ethical decision and assess whether justification has been achieved through an enhanced ethical principle, thereby establishing justifiability.
| score = N, reason ≤ 3 sentences | Statistics computed after parallel measurement by 5 LLMs:
|
| Procedural Validity | The following is the execution result of the 20-step CREM-based ethical decision-making process. Assign a 5-point-scale score only to the executed steps and provide the reason in three sentences or fewer. For N/A (non-executed) stages, respond with score = N/A.
| A1: score = N, reason = … … A20: score = N, reason = … |
|
Appendix C.2. NAI (Normative Alignment Index)—Detailed Process
| Stage | Evaluation Query (LLM Prompt) | Response Format | Formula |
|---|---|---|---|
| Step 1 Ethical Relevance | Rate the relevance of the corresponding ethical principle/case to the given dilemma and final ethical decision on a 0–5 scale, and briefly explain your reasoning. (0: not relevant at all–5: extremely relevant)
| score = N, reason = … |
(rl = 0–5 score of LLM ℓ) |
| Step 2 Normative Alignment | Rate the normative alignment between the final decision and the corresponding ethical principle/case on three dimensions, each on a 1–5 scale: 1. Consistency: the principle and final decision align without contradiction 2. Justifiability: the principle contributes to justifying the decision as its basis 3. Priority: principles align without conflict | consistency = N, justifiability = N, priority = N, reason = … |
|
| Final Aggregate (GAI) | Using the relevance (Ri) of the filtered principles as weights, compute a weighted average of the alignment (Ai) to derive the overall alignment index. | — | GAI = Σ(Ai × Ri)/Σ Ri
|
References
- Arvan, M. (2022). Varieties of artificial moral agency and the new control problem. Humana.Mente Journal of Philosophical Studies, 15(42), 225–256. [Google Scholar]
- Behdadi, D., & Munthe, C. (2020). A normative approach to artificial moral agency. Minds and Machines, 30(2), 195–218. [Google Scholar] [CrossRef] [Scilit]
- Belloni, A., Berger, A., Boissier, O., Bonnet, G., Bourgne, G., Chardel, P.-A., Cotton, J.-P., Evreux, N., Ganascia, J.-G., Jaillon, P., Mermet, B., Picard, G., Rever, B., Simon, G., de Swarte, T., Tessier, C., Vexler, F., Voyer, R., & Zimmermann, A. (2015). Dealing with ethical conflicts in autonomous agents and multi-agent systems. In Artificial intelligence and ethics: Papers from the 2015 AAAI workshop. AAAI Press. [Google Scholar]
- Cervantes, J.-A., López, S., Rodríguez, L.-F., Cervantes, S., Cervantes, F., & Ramos, F. (2020). Artificial moral agents: A survey of the current status. Science and Engineering Ethics, 26(2), 501–532. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Chen, Y.-J., Albarqawi, A., & Chen, C.-S. (2025). Enhancing clinical decision-making: Integrating multi-agent systems with ethical AI governance. In 2025 IEEE conference on computational intelligence in bioinformatics and computational biology (CIBCB) (pp. 1–7). IEEE. [Google Scholar] [CrossRef] [Scilit]
- Cheung, V., Maier, M., & Lieder, F. (2025). Large language models show amplified cognitive biases in moral decision-making. Proceedings of the National Academy of Sciences of the United States of America, 122(25), e2412015122. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Conitzer, V., Sinnott-Armstrong, W., Borg, J. S., Deng, Y., & Kramer, M. (2017). Moral decision making frameworks for artificial intelligence. Proceedings of the AAAI Conference on Artificial Intelligence, 31(1), 4831–4835. [Google Scholar] [CrossRef] [Scilit]
- Daniels, N. (1979). Wide reflective equilibrium and theory acceptance in ethics. The Journal of Philosophy, 76(5), 256–282. [Google Scholar] [CrossRef] [Scilit]
- Fabre, E. F., Mouratille, D., Bonnemains, V., Palmiotti, G. P., & Causse, M. (2024). Making moral decisions with artificial agents as advisors. A fNIRS study. Computers in Human Behavior: Artificial Humans, 2(2), 100096. [Google Scholar] [CrossRef] [Scilit]
- Ferrell, O. C., Harrison, D. E., Ferrell, L. K., Ajjan, H., & Hochstein, B. W. (2024). A theoretical framework to guide AI ethical decision making. AMS Review, 14(1), 53–67. [Google Scholar] [CrossRef] [Scilit]
- Firt, E. (2025). What makes full artificial agents morally different. AI & Society, 40(1), 175–184. [Google Scholar] [CrossRef] [Scilit]
- Formosa, P., & Ryan, M. (2021). Making moral machines: Why we need artificial moral agents. AI & Society, 36(3), 839–851. [Google Scholar] [CrossRef] [Scilit]
- Gal, K., & Grosz, B. J. (2022). Multi-agent systems: Technical & ethical challenges of functioning in a mixed group. Daedalus, 151(2), 114–126. [Google Scholar] [CrossRef] [Scilit]
- Ghazali, F., BaniRostam, T., & Pedram, M. (2025). Developing artificial moral agents: Key research processes, techniques, and challenges. AI and Tech in Behavioral and Social Sciences, 3(1), 92–108. [Google Scholar] [CrossRef] [Scilit]
- Giubilini, A., & Savulescu, J. (2018). The artificial moral advisor. The “ideal observer” meets artificial intelligence. Philosophy & Technology, 31(2), 169–188. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kahneman, D. (2011). Thinking, fast and slow. Farrar, Straus and Giroux. [Google Scholar]
- Kim, C., & Ahn, S. (2026). Cognitive-reflective equilibration model: An ethical decision-making framework for LLM-based AI systems. Systems, 14(7), 881. [Google Scholar] [CrossRef] [Scilit]
- Landes, E., Voinea, C., & Uszkai, R. (2025). Rage against the authority machines: How to design artificial moral advisors for moral enhancement. AI & Society, 40(4), 2237–2248. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Li, X., Wang, S., Zeng, S., Wu, Y., & Yang, Y. (2024). A survey on LLM-based multi-agent systems: Workflow, infrastructure, and challenges. Vicinagearth, 1(1), 9. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y., Lo, S. K., Lu, Q., Zhu, L., Zhao, D., Xu, X., Harrer, S., & Whittle, J. (2025). Agent design pattern catalogue: A collection of architectural patterns for foundation model based agents. Journal of Systems and Software, 220, 112278. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y., Moore, A., Webb, J., & Vallor, S. (2022). Artificial moral advisors: A new perspective from moral psychology. In Proceedings of the 2022 AAAI/ACM conference on AI, ethics, and society (pp. 436–445). Association for Computing Machinery. [Google Scholar] [CrossRef] [Scilit]
- Machado, J., Sousa, R., Peixoto, H., & Abelha, A. (2024). Ethical decision-making in artificial intelligence: A logic programming approach. AI, 5(4), 2707–2724. [Google Scholar] [CrossRef] [Scilit]
- Mashayekhi, M., Ajmeri, N., List, G. F., & Singh, M. P. (2022). Prosocial norm emergence in multi-agent systems. ACM Transactions on Autonomous and Adaptive Systems, 17(1–2), 3. [Google Scholar] [CrossRef] [Scilit]
- Misselhorn, C. (2022). Artificial moral agents: Conceptual issues and ethical controversy. In S. Voeneky, P. Kellmeyer, O. Mueller, & W. Burgard (Eds.), The Cambridge handbook of responsible artificial intelligence: Interdisciplinary perspectives (pp. 31–49). Cambridge University Press. [Google Scholar]
- Muntean, I., & Howard, D. (2014). Artificial moral agents: Creative, autonomous, social. An approach based on evolutionary computation. In J. Seibt, R. Hakli, & M. Nørskov (Eds.), Sociable robots and the future of social relations: Proceedings of robo-philosophy 2014 (pp. 217–230). IOS Press. [Google Scholar] [CrossRef] [Scilit]
- Murukannaiah, P. K., Ajmeri, N., Jonker, C. M., & Singh, M. P. (2020). New foundations of ethical multiagent systems. In Proceedings of the 19th international conference on autonomous agents and multiagent systems (pp. 1706–1710). International Foundation for Autonomous Agents and Multiagent Systems. [Google Scholar]
- Myers, S., & Everett, J. A. C. (2025). People expect artificial moral advisors to be more utilitarian and distrust utilitarian moral advisors. Cognition, 256, 106028. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Nagenborg, M. (2007). Artificial moral agents: An intercultural perspective. The International Review of Information Ethics, 7, 129–134. [Google Scholar] [CrossRef] [Scilit]
- Osasona, F., Amoo, O. O., Atadoga, A., Abrahams, T. O., Farayola, O. A., & Ayinla, B. S. (2024). Reviewing the ethical implications of AI in decision making processes. International Journal of Management & Entrepreneurship Research, 6(2), 322–335. [Google Scholar] [CrossRef] [Scilit]
- Piaget, J. (1985). The equilibration of cognitive structures: The central problem of intellectual development (T. Brown, & K. J. Thampy, Trans.). University of Chicago Press. (Original work published 1975). [Google Scholar]
- Piccialli, F., Chiaro, D., Sarwar, S., Cerciello, D., Qi, P., & Mele, V. (2025). AgentAI: A comprehensive survey on autonomous agents in distributed AI for Industry 4.0. Expert Systems with Applications, 291, 128404. [Google Scholar] [CrossRef] [Scilit]
- Putica, A., Khanna, R., Bosl, W., Saraf, S., & Edgcomb, J. (2025). Ethical decision-making for AI in mental health: The Integrated Ethical Approach for Computational Psychiatry (IEACP) framework. Psychological Medicine, 55, e213. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Queloz, M. (2025a). Can AI rely on the systematicity of truth? The challenge of modelling normative domains. Philosophy & Technology, 38(1), 34. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Queloz, M. (2025b). On the fundamental limitations of AI moral advisors. Philosophy & Technology, 38(2), 71. [Google Scholar] [CrossRef] [Scilit]
- Rawls, J. (2017). A theory of justice. In L. May, & J. B. Delston (Eds.), Applied ethics: A multicultural approach (6th ed., pp. 21–29). Routledge. [Google Scholar]
- Robbins, R. W., & Wallace, W. A. (2007). Decision support for ethical problem solving: A multi-agent approach. Decision Support Systems, 43(4), 1571–1587. [Google Scholar] [CrossRef] [Scilit]
- Senghor, A. S., Bright, T. J., Kakim, S., Norris, K. C., Antwi, H. A., Cooper, J. K., Mullins, C. D., & Baquet, C. (2025). A community-based approach to ethical decision-making in artificial intelligence for health care. JAMIA Open, 8(4), ooaf076. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Stenseke, J. (2024). Artificial virtuous agents in a multi-agent tragedy of the commons. AI & Society, 39(3), 855–872. [Google Scholar] [CrossRef] [Scilit]
- Stomberg, M., & Tröschel, M. (2024). Enabling moral agency in distributed energy management: An ethics score for negotiations in multi-agent systems. ACM Sigenergy Energy Informatics Review, 4(4), 116–128. [Google Scholar] [CrossRef] [Scilit]
- Tassella, M., Chaput, R., & Guillermin, M. (2023). Artificial moral advisors: Enhancing human ethical decision-making. In 2023 IEEE international symposium on ethics in engineering, science, and technology (ETHICS) (pp. 1–5). IEEE. [Google Scholar] [CrossRef] [Scilit]
- Tolmeijer, S., Kneer, M., Sarasua, C., Christen, M., & Bernstein, A. (2020). Implementations in machine ethics: A survey. ACM Computing Surveys, 53(6), 132. [Google Scholar] [CrossRef] [Scilit]
- Wallach, W., Franklin, S., & Allen, C. (2010). A conceptual and computational model of moral decision making in human and artificial agents. Topics in Cognitive Science, 2(3), 454–485. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, L., Ma, C., Feng, X., Zhang, Z., Yang, H., Zhang, J., Chen, Z., Tang, J., Chen, X., Lin, Y., Zhao, W. X., Wei, Z., & Wen, J. (2024). A survey on large language model based autonomous agents. Frontiers of Computer Science, 18(6), 186345. [Google Scholar] [CrossRef] [Scilit]
- Wiedeman, C., Wang, G., & Kruger, U. (2020). Modeling of moral decisions with deep learning. Visual Computing for Industry, Biomedicine, and Art, 3(1), 27. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Woodgate, J. (2025). Ethical decision-making in multi-agent systems. In Proceedings of the 24th international conference on autonomous agents and multiagent systems (AAMAS 2025) (pp. 2991–2993). International Foundation for Autonomous Agents and Multiagent Systems. [Google Scholar]
- Xi, Z., Chen, W., Guo, X., He, W., Ding, Y., Hong, B., Zhang, M., Wang, J., Jin, S., Zhou, E., Zheng, R., Fan, X., Wang, X., Xiong, L., Zhou, Y., Wang, W., Jiang, C., Zou, Y., Liu, X., … Gui, T. (2025). The rise and potential of large language model based agents: A survey. Science China Information Sciences, 68(2), 121101. [Google Scholar] [CrossRef] [Scilit]
- Yamani, A., Baslyman, M., & Ahmed, M. (2025). Multi-agent LLMs as ethics advocates for AI-based systems. In Proceedings of the 2025 IEEE 33rd international requirements engineering conference workshops (REW) (pp. 524–532). IEEE. [Google Scholar] [CrossRef] [Scilit]
- Yilmaz, L., Franco-Watkins, A., & Kroecker, T. S. (2017). Computational models of ethical decision-making: A coherence-driven reflective equilibrium model. Cognitive Systems Research, 46, 61–74. [Google Scholar] [CrossRef] [Scilit]
- Zafar, M. (2025). Normativity and AI moral agency. AI and Ethics, 5(3), 2605–2622. [Google Scholar] [CrossRef] [Scilit]
- Zheng, L., Chiang, W.-L., Sheng, Y., Zhuang, S., Wu, Z., Zhuang, Y., Lin, Z., Li, Z., Li, D., Xing, E. P., Zhang, H., Gonzalez, J. E., & Stoica, I. (2023). Judging LLM-as-a-judge with MT-bench and chatbot arena. Advances in Neural Information Processing Systems, 36, 46595–46623. [Google Scholar] [CrossRef] [Scilit]
- Zhu, Y., Liu, L., Yu, J., & Zhang, D. (2026). LLM-based multi-agent orchestration: A survey of frameworks, communication protocols, and emerging patterns. Future Inernet, 18(6), 326. [Google Scholar] [CrossRef] [Scilit]




| CCREM Stage | Theoretical Correspondence | Content |
|---|---|---|
| 1. Original State of Equilibrium | Piaget: initial equilibrium/Rawls: original position | The preparatory condition for both procedures: a cognitively and ethically optimized starting state. It is dynamic rather than static, oriented toward a better equilibrium and in interaction with its environment. |
| 2. Ethical assimilation | Piaget: assimilation/Rawls: narrow reflective equilibrium | A coherence judgment that determines whether the moral judgment held by the current cognitive schema and the ethical principles supplied by the environment support one another. Both source procedures share the method of consistency adjudication. |
| 3. State of Disequilibrium | Piaget: disequilibrium/Rawls: (implicit) inconsistency or conflict | The state exposed when assimilation fails: perturbation, contradiction, or logical inconsistency. It supplies the motivation for the transition to accommodation, and thereby the connecting link between the two theories. |
| 4. Ethical accommodation | Piaget: accommodation via reflective abstraction/Rawls: wide reflective equilibrium | Alternative ethical principles are examined and compared (differentiation and integration), supporting and opposing reasons are analyzed (relativization of concepts), and the weight of those reasons is assessed (quantification of relations), so that a principle is selected or the commitments are mutually adjusted. |
| 5. Better State of Reflective Equilibrium | Piaget: better equilibrium/Rawls: reflective equilibrium | A state more advanced than the starting condition, in which coherence between moral judgment and ethical principles is secured and the revised principles have been justified. |
| Stage | Steps | Function |
|---|---|---|
| 1. Cognitive Processing | 1–6 | Compares and analyzes the initial moral judgment and ethical principles on the basis of objective information |
| 2. Reflective Processing | 7–15 | Recognizes inconsistencies between judgments and principles and explores and compares alternative principles and cases |
| 3. Equilibration (Ethical Decision) | 16–17 | Executes the optimal ethical judgment through weighted selection and adjustment of judgments |
| 4. Ethical Implementation & Evaluation | 18–20 | Implements the justified decision and evaluates its outcomes |
| Theoretical Commitment | Architectural Decision It Licenses | Where Implemented |
|---|---|---|
| CREM specifies four executable stages (Kim & Ahn, 2026) | Four stage-aligned agents, so the division of labor tracks the equilibration cycle rather than an arbitrary functional decomposition | Section 3.2 |
| Assimilation requires ethical principles supplied by the environment, not recalled from within (Piaget, 1975/1985) | The EPKB supplies a curated, citable principle set retrieved at the assimilation step, instead of relying on principles recalled from model parameters | Section 3.3; Step 3 |
| Disequilibrium is the engine of the procedure, not a failure mode (Piaget, 1975/1985) | An explicit conflict-detection step, with a branch that terminates the cycle early when no conflict is found rather than manufacturing one | Section 3.2; Steps 5–6 |
| Accommodation proceeds by reflective abstraction: differentiation, relativization of concepts, quantification of relations (Piaget, 1975/1985) | The Reflective Agent generates alternative principles, produces counterarguments, and scores the relative weights of supporting and opposing reasons as three distinct operations rather than one judgment call | Section 3.2; Steps 7–15 |
| Assimilation requires ethical principles supplied by the environment, not recalled from within (Piaget, 1975/1985), Wide reflective equilibrium requires weighing alternative conceptions and the comparative strength of the reasons for them (Rawls, 2017; Daniels, 1979) | The five-model ensemble is applied at the accommodation stage only, so alternatives are generated by independent models rather than by one model simulating plurality | Section 3.4; Steps 3, 11, 12, 13, 18 |
| Development presupposes accumulated equilibration outcomes (Piaget, 1975/1985) | The ERB stores completed executions for retrieval. Qualification: retrieval is a static similarity lookup and no weights are updated, so this enables reuse rather than development | Section 3.3 |
| Procedural consistency, not outcome acceptability, is what the theory constrains | Procedural validity is measured step by step rather than only at the final recommendation, and is reported as a separate indicator | Section 3.6 |
| Representative Prior Study | Evidence Type | Similarities and Differences with CREA | Implications for CREA |
|---|---|---|---|
| Yilmaz et al. (2017) | Conceptual proposal | Similarity: Implements coherence-driven reflective equilibrium as a computational model Difference: Confined to a single reasoning engine; no multi-agent collaboration structure distributing perspectives | The closest theoretical counterpart to CREM, sharing coherence-driven mutual adjustment between intuitions and principles, which CREA extends with Piagetian equilibration, a 20-step procedure, procedural validity, external principle verification, and multi-LLM evaluation. |
| Wallach et al. (2010) | Conceptual proposal | Similarity: Moral judgment integrating emotion and reason on a cognitive-process substrate Difference: A single-agent cognitive model; no deliberation among conflicting perspectives | Provides cognitive-architecture grounding for CREM’s cognition–reflection–equilibration–decision–action hierarchy, which CREA operationalizes through LLM agent roles, external principle retrieval, and memory/evaluation loops. |
| Conitzer et al. (2017) | Conceptual proposal | Similarity: Oriented toward general, formal ethical reasoning frameworks Difference: A single unified framework; no coordination mechanism for multi-perspective agents | Supports CREA’s multi-LLM adjudication based on reason comparison rather than voting, with separate measurement of justifiability, procedural validity, and normative alignment, complemented by step-level explanations ensuring transparent and verifiable reasoning. |
| Machado et al. (2024) | Computational evaluation | ||
| Murukannaiah et al. (2020) | Conceptual proposal | Similarity: Defines ethics as an inherently multi-agent problem Difference: Stops at conceptual foundations for sociotechnical systems; no concrete deliberative mechanism | Provides a basis for theorizing CREA as an ethical MAS with role-specific responsibilities, mutual critique, and procedural legitimacy, reframing the Reasoning Bank as an institutional record of norms, cases, and accountability rather than simple memory. |
| Mashayekhi et al. (2022) | Computational evaluation | Similarity: System-level norm emergence and fairness assurance Difference: Centered on norm emergence and constraints; does not reach conclusions through coherence deliberation among principles | Extends the EPKB/ERB toward norm learning by recording stakeholder effects, violations, and long-term outcomes, while cautioning that multi-LLM consensus must not be equated with ethicality. |
| Stenseke (2024) | Computational evaluation | Similarity: Computational implementation of norm-based and virtue ethics Difference: Centered on implementing a single ethical theory rather than coherent adjustment of plural principles | Supports extending CREA’s equilibration into sustained moral learning via the Reasoning Bank, with multi-LLM agents representing and reconciling distinct ethical perspectives, evaluated in terms of behavioral consistency and the preservation of dissent rather than consensus alone. |
| Woodgate (2025) | Conceptual proposal | ||
| Yamani et al. (2025) | Computational evaluation | Similarity: Role differentiation and structured debate in LLM multi-agent settings Difference: No theoretical grounding in coherence or reflective equilibrium; weak guarantees of judgment explainability | The closest recent multi-agent LLM comparison: MALEA addresses design-time ethics requirements while CREA covers runtime dilemma deliberation, empirically mitigating the variability and verification problems MALEA identified. |
| Design Dimension | Single-Agent | Multi-Agent | Multi-LLM | Multi-LLM + KRB |
|---|---|---|---|---|
| Agent structure | Monolithic 20-step state graph | Six role-specialized agents | Six role-specialized agents | Six role-specialized agents |
| LLM plurality | 1 primary LLM | 1 primary LLM | one primary LLM + up to five auxiliary LLMs | one primary LLM + up to five auxiliary LLMs |
| Ethical Principles Knowledge Base (EPKB) | Not used | Not used | Not used | Principles + web + document RAG |
| Ethical Reasoning Bank (ERB) | Not used | Not used | Not used | Hybrid-similarity case retrieval (KRB only) |
| In-process LLM deliberation | Primary LLM only | Primary LLM only | 5-LLM ensemble (Steps 3, 11, 12, 13, 18) | 5-LLM ensemble (Steps 3, 11, 12, 13, 18) |
| Measurement (post hoc) scoring | 5-LLM ensemble | 5-LLM ensemble | 5-LLM ensemble | 5-LLM ensemble |
| Indicator | Single | Multi | Multi-LLM | Multi-LLM + KRB |
|---|---|---|---|---|
| Consistency | 4.683 (0.723) | 4.630 (0.567) | 4.745 (0.528) | 4.806 (0.430) |
| Justifiability | 4.626 (0.383) | 4.658 (0.420) | 4.788 (0.351) | 4.832 (0.304) |
| Procedural validity | 4.574 (0.284) | 3.975 (0.318) | 4.066 (0.319) | 4.100 (0.311) |
| Normative alignment index (NAI) | 4.105 (0.672) | 4.076 (0.633) | 4.207 (0.596) | 4.238 (0.554) |
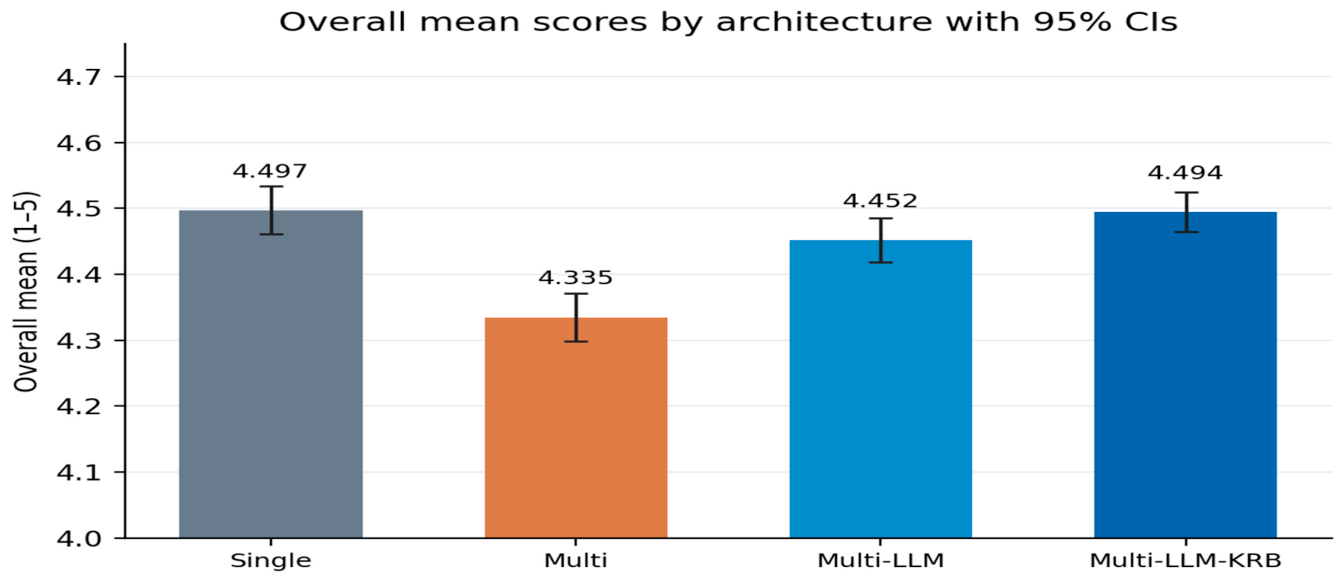
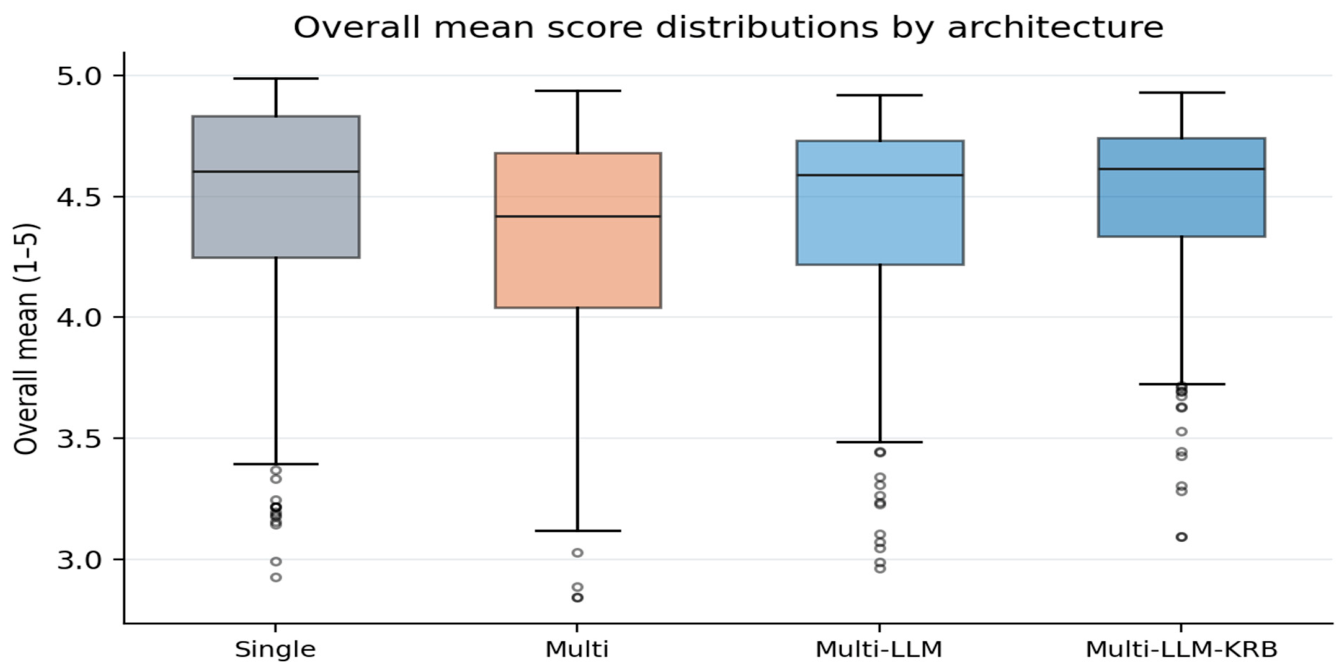
| Overall mean | 4.497 (0.414) | 4.335 (0.410) | 4.452 (0.378) | 4.494 (0.341) |
| Metric | Single | Multi | Multi-LLM | Multi-LLM + KRB |
|---|---|---|---|---|
| Consistency | 15.43 | 12.25 | 11.12 | 8.95 |
| Justifiability | 8.27 | 9.01 | 7.33 | 6.28 |
| Procedural validity | 6.20 | 7.99 | 7.84 | 7.58 |
| NAI | 16.38 | 15.54 | 14.16 | 13.07 |
| Overall mean | 9.21 | 9.46 | 8.49 | 7.58 |
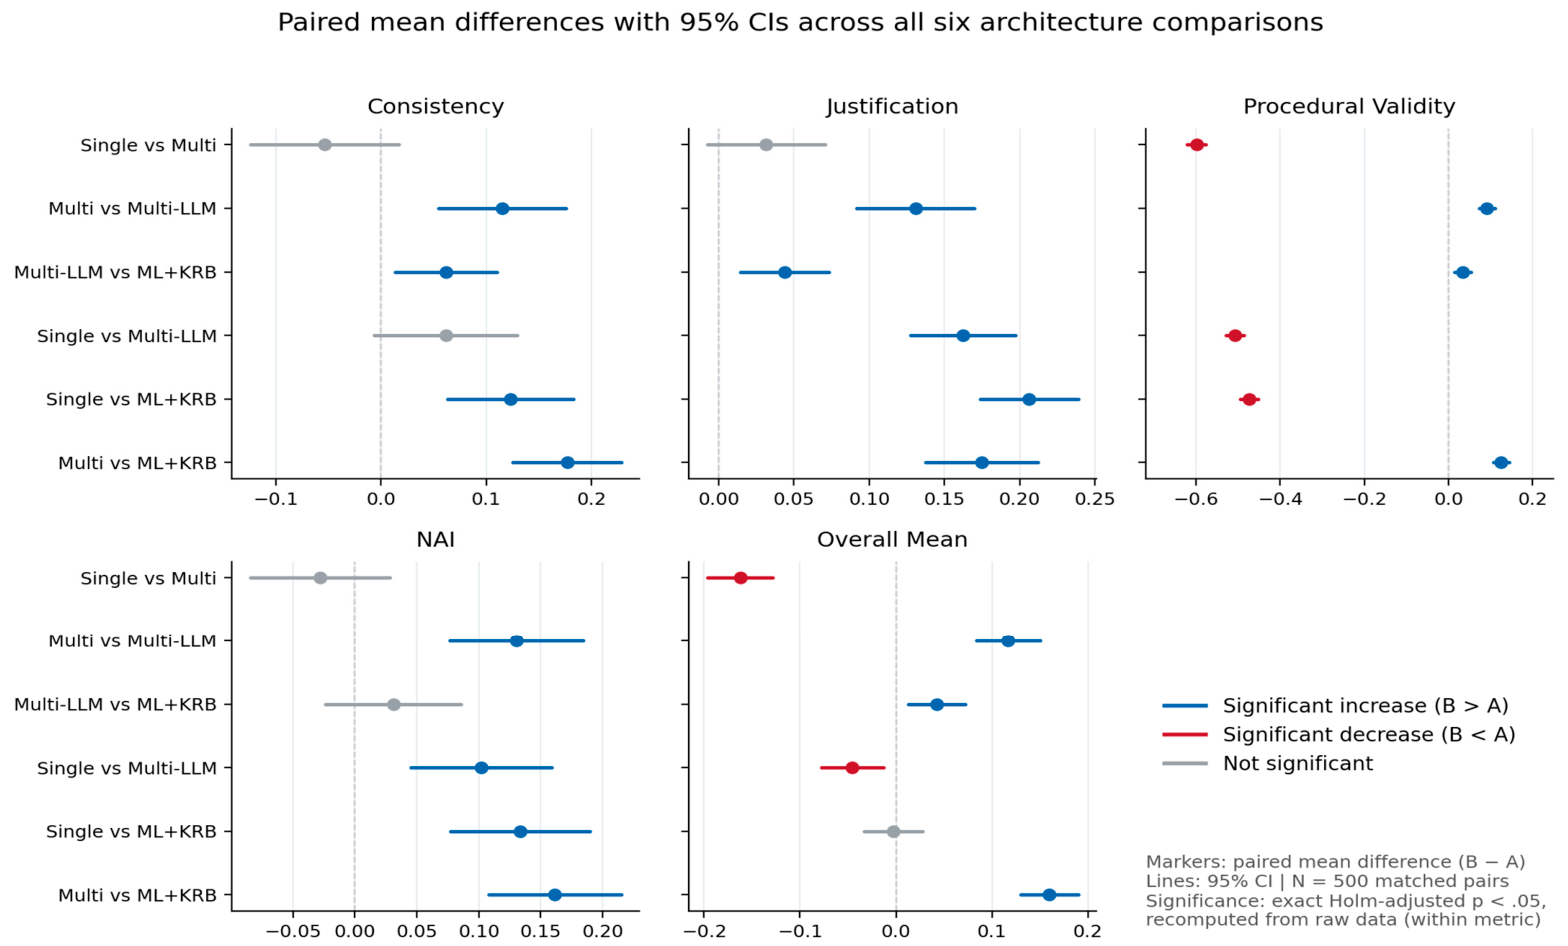
| Metric | Comparison (A vs. B) | Δ (B − A) | 95% CI | t(499) | p | Holm p | dz | Wilcoxon p |
|---|---|---|---|---|---|---|---|---|
| Consistency | Single vs. Multi | −0.054 | [−0.124, 0.017] | −1.494 | .136 | .150 | −0.067 | <.001 |
| Multi vs. Multi-LLM | +0.115 | [0.055, 0.175] | 3.755 | <.001 | <.001 | 0.168 | <.001 | |
| Multi-LLM vs. ML + KRB | +0.062 | [0.013, 0.110] | 2.505 | .013 | .038 | 0.112 | .007 | |
| Single vs. Multi-LLM | +0.062 | [−0.006, 0.129] | 1.783 | .075 | .150 | 0.080 | .265 | |
| Single vs. ML + KRB | +0.123 | [0.063, 0.183] | 4.054 | <.001 | <.001 | 0.181 | <.001 | |
| Multi vs. ML + KRB | +0.177 | [0.125, 0.228] | 6.763 | <.001 | <.001 | 0.302 | <.001 | |
| Justifiability | Single vs. Multi | +0.032 | [−0.008, 0.071] | 1.582 | .114 | .114 | 0.071 | .046 |
| Multi vs. Multi-LLM | +0.131 | [0.092, 0.170] | 6.548 | <.001 | <.001 | 0.293 | <.001 | |
| Multi-LLM vs. ML + KRB | +0.044 | [0.015, 0.073] | 2.946 | .003 | .007 | 0.132 | .003 | |
| Single vs. Multi-LLM | +0.162 | [0.128, 0.197] | 9.151 | <.001 | <.001 | 0.409 | <.001 | |
| Single vs. ML + KRB | +0.206 | [0.174, 0.239] | 12.497 | <.001 | <.001 | 0.559 | <.001 | |
| Multi vs. ML + KRB | +0.175 | [0.137, 0.212] | 9.189 | <.001 | <.001 | 0.411 | <.001 | |
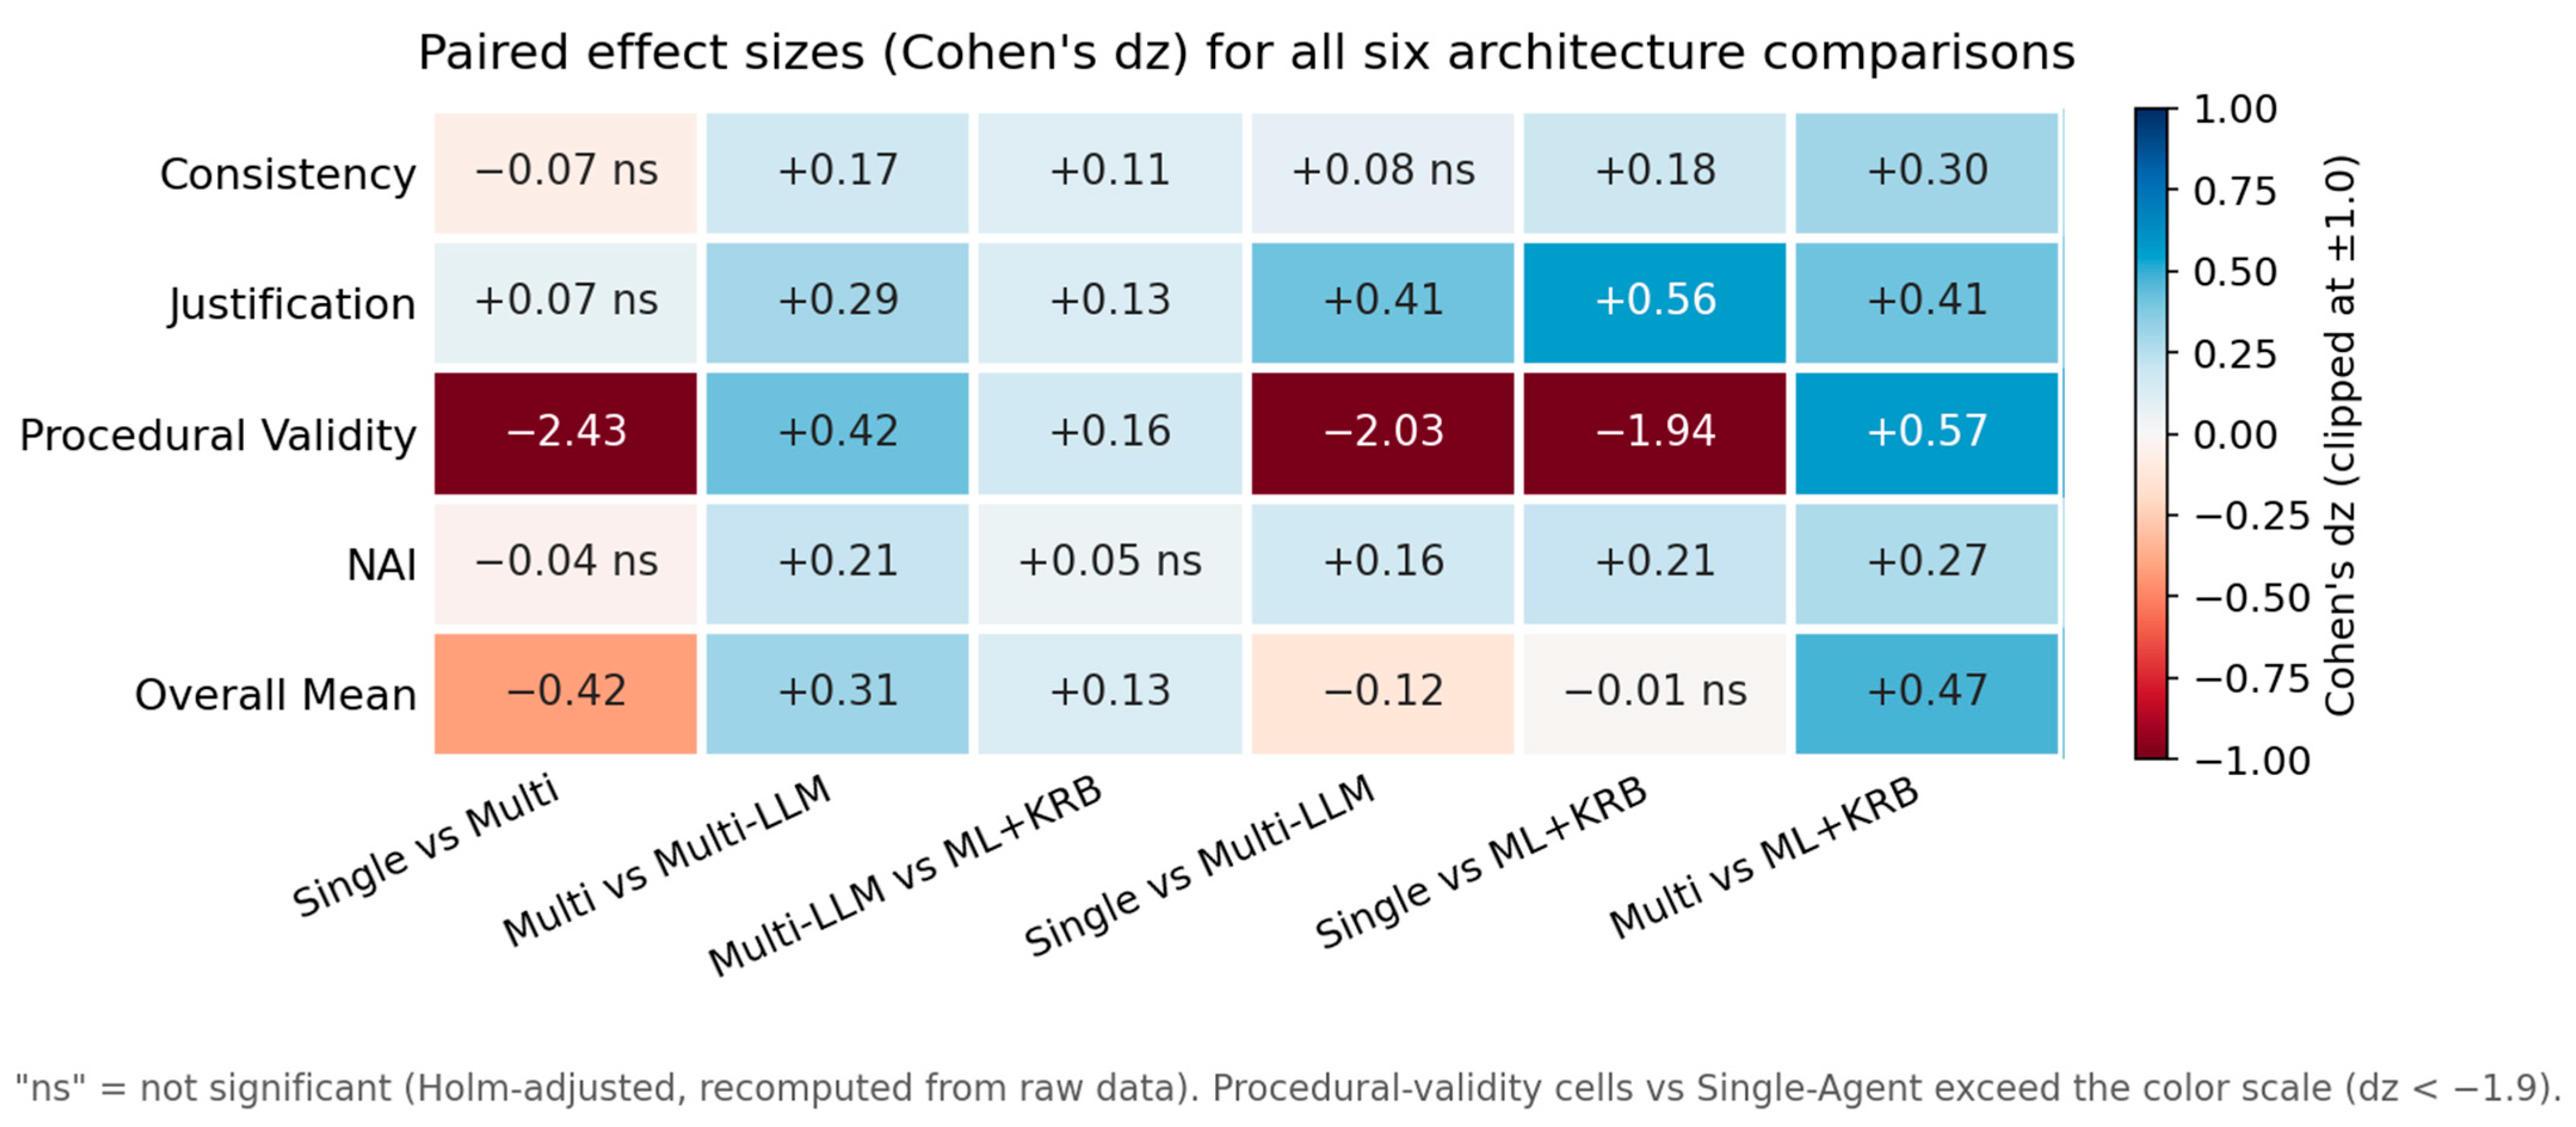
| Procedural validity | Single vs. Multi | −0.599 | [−0.621, −0.578] | −54.438 | <.001 | <.001 | −2.435 | <.001 |
| Multi vs. Multi-LLM | +0.092 | [0.073, 0.111] | 9.470 | <.001 | <.001 | 0.424 | <.001 | |
| Multi-LLM vs. ML + KRB | +0.034 | [0.015, 0.053] | 3.517 | <.001 | <.001 | 0.157 | .003 | |
| Single vs. Multi-LLM | −0.508 | [−0.530, −0.486] | −45.348 | <.001 | <.001 | −2.028 | <.001 | |
| Single vs. ML + KRB | −0.474 | [−0.495, −0.452] | −43.295 | <.001 | <.001 | −1.936 | <.001 | |
| Multi vs. ML + KRB | +0.125 | [0.106, 0.145] | 12.697 | <.001 | <.001 | 0.568 | <.001 | |
| NAI | Single vs. Multi | −0.028 | [−0.085, 0.028] | −0.984 | .325 | .529 | −0.044 | .279 |
| Multi vs. Multi-LLM | +0.130 | [0.076, 0.185] | 4.742 | <.001 | <.001 | 0.212 | <.001 | |
| Multi-LLM vs. ML + KRB | +0.031 | [−0.024, 0.086] | 1.117 | .264 | .529 | 0.050 | .354 | |
| Single vs. Multi-LLM | +0.102 | [0.045, 0.159] | 3.530 | <.001 | .001 | 0.158 | .003 | |
| Single vs. ML + KRB | +0.133 | [0.077, 0.190] | 4.659 | <.001 | <.001 | 0.208 | <.001 | |
| Multi vs. ML + KRB | +0.162 | [0.108, 0.215] | 5.944 | <.001 | <.001 | 0.266 | <.001 | |
| Overall mean | Single vs. Multi | −0.162 | [−0.197, −0.128] | −9.316 | <.001 | <.001 | −0.417 | <.001 |
| Multi vs. Multi-LLM | +0.117 | [0.084, 0.150] | 6.974 | <.001 | <.001 | 0.312 | <.001 | |
| Multi-LLM vs. ML + KRB | +0.043 | [0.013, 0.072] | 2.838 | .005 | .014 | 0.127 | .018 | |
| Single vs. Multi-LLM | −0.045 | [−0.078, −0.013] | −2.724 | .007 | .014 | −0.122 | <.001 | |
| Single vs. ML + KRB | −0.003 | [−0.033, 0.028] | −0.178 | .859 | .859 | −0.008 | .060 | |
| Multi vs. ML + KRB | +0.160 | [0.130, 0.190] | 10.421 | <.001 | <.001 | 0.466 | <.001 |
| Metric | S → M β (p) | M → ML β (p) | ML → KRB β (p) | S → ML β (p) | S → KRB β (p) | M → KRB β (p) |
|---|---|---|---|---|---|---|
| Consistency | −0.054 (.141) | +0.115 (<.001) | +0.062 (.021) | +0.062 (.085) | +0.123 (<.001) | +0.177 (<.001) |
| Justifiability | +0.032 (.121) | +0.131 (<.001) | +0.044 (.010) | +0.162 (<.001) | +0.206 (<.001) | +0.175 (<.001) |
| Procedural validity | −0.599 (<.001) | +0.092 (<.001) | +0.034 (<.001) | −0.508 (<.001) | −0.474 (<.001) | +0.125 (<.001) |
| NAI | −0.028 (.351) | +0.130 (<.001) | +0.031 (.272) | +0.102 (<.001) | +0.133 (<.001) | +0.162 (<.001) |
| Overall mean | −0.162 (<.001) | +0.117 (<.001) | +0.043 (.008) | −0.045 (.011) | −0.003 (.869) | +0.160 (<.001) |
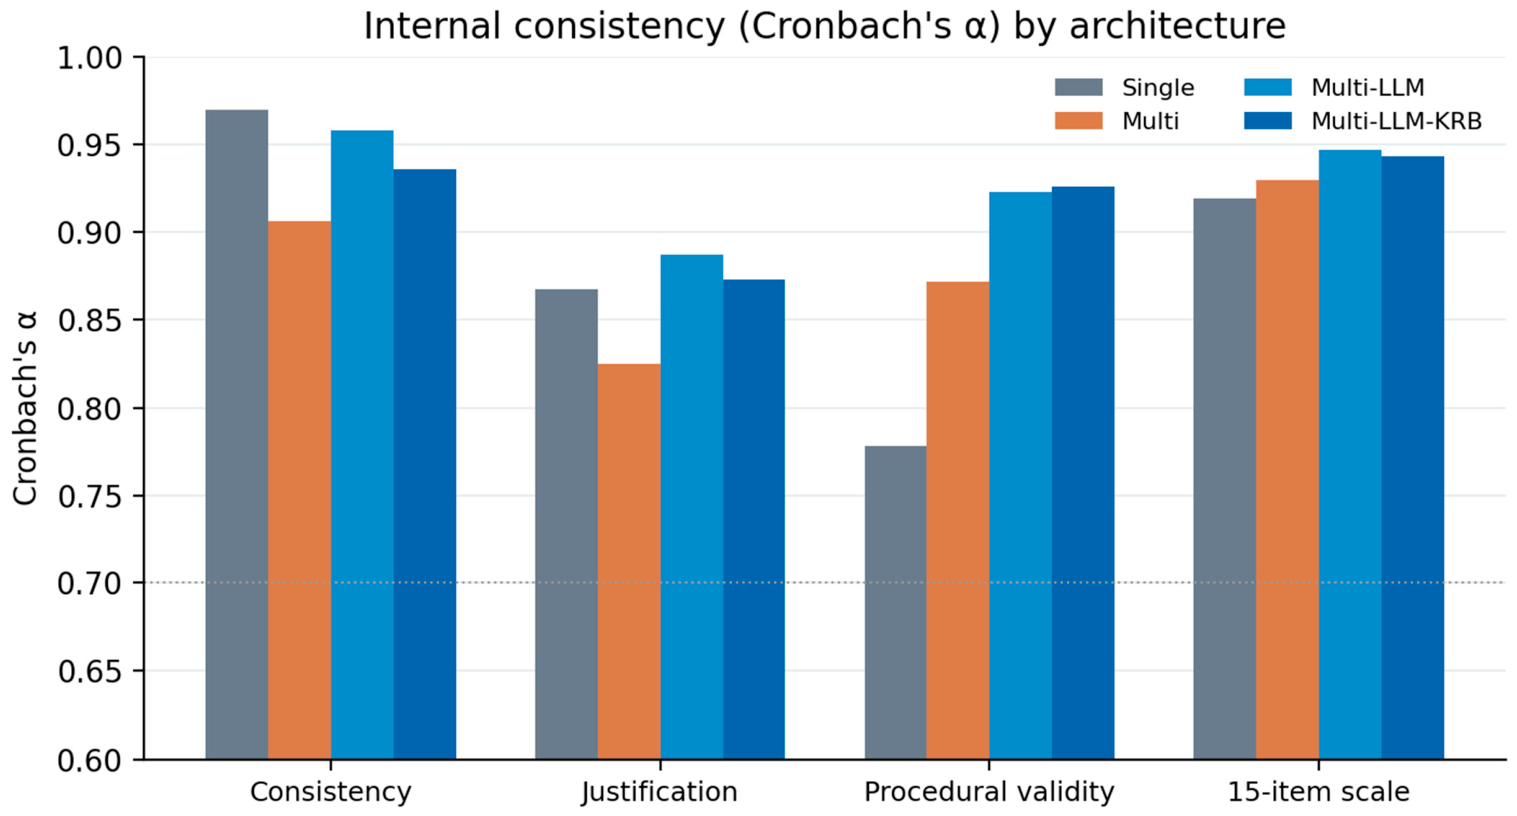
| Scale | Items | Single | Multi | Multi-LLM | Multi-LLM + KRB |
|---|---|---|---|---|---|
| Consistency | 5 | 0.969 | 0.906 | 0.958 | 0.936 |
| Justifiability | 5 | 0.867 | 0.825 | 0.887 | 0.873 |
| Procedural validity | 5 | 0.778 | 0.872 | 0.923 | 0.926 |
| Overall 15-item measurement scale | 15 | 0.919 | 0.929 | 0.947 | 0.943 |
| Execution-level 4-indicator scale | 4 | 0.750 | 0.838 | 0.833 | 0.845 |
| Execution-level 3-indicator scale | 3 | 0.670 | 0.834 | 0.810 | 0.824 |
| Scale | Comparison | Δα (B − A) | 95% Bootstrap CI | Perm. p | Result |
|---|---|---|---|---|---|
| Consistency | S vs. M | −0.063 | [−0.101, −0.036] | <.001 | Significant |
| M vs. ML | 0.051 | [0.022, 0.089] | 0.006 | Significant | |
| ML vs. ML-KRB | −0.022 | [−0.054, 0.008] | 0.144 | n.s. | |
| Justifiability | S vs. M | −0.043 | [−0.117, 0.013] | 0.229 | n.s. |
| M vs. ML | 0.062 | [0.001, 0.136] | 0.090 | n.s. | |
| ML vs. ML-KRB | −0.014 | [−0.052, 0.028] | 0.600 | n.s. | |
| Procedural validity | S vs. M | 0.094 | [0.062, 0.126] | <.001 | Significant |
| M vs. ML | 0.051 | [0.031, 0.071] | <.001 | Significant | |
| ML vs. ML-KRB | 0.003 | [−0.008, 0.014] | 0.605 | n.s. | |
| Overall 15-item scale | S vs. M | 0.010 | [−0.006, 0.026] | 0.313 | n.s. |
| M vs. ML | 0.017 | [0.005, 0.031] | 0.014 | Significant | |
| ML vs. ML-KRB | −0.004 | [−0.012, 0.005] | 0.433 | n.s. | |
| Exec. 4-indicator scale | S vs. M | 0.087 | [0.057, 0.120] | <.001 | Significant |
| M vs. ML | −0.004 | [−0.033, 0.024] | 0.752 | n.s. | |
| ML vs. ML-KRB | 0.011 | [−0.016, 0.041] | 0.453 | n.s. | |
| Exec. 3-indicator scale | S vs. M | 0.164 | [0.114, 0.217] | <.001 | Significant |
| M vs. ML | −0.024 | [−0.055, 0.006] | 0.132 | n.s. | |
| ML vs. ML-KRB | 0.014 | [−0.018, 0.046] | 0.396 | n.s. |
| Metric | Architecture | N | Mean | SD | Median | Min | Max |
|---|---|---|---|---|---|---|---|
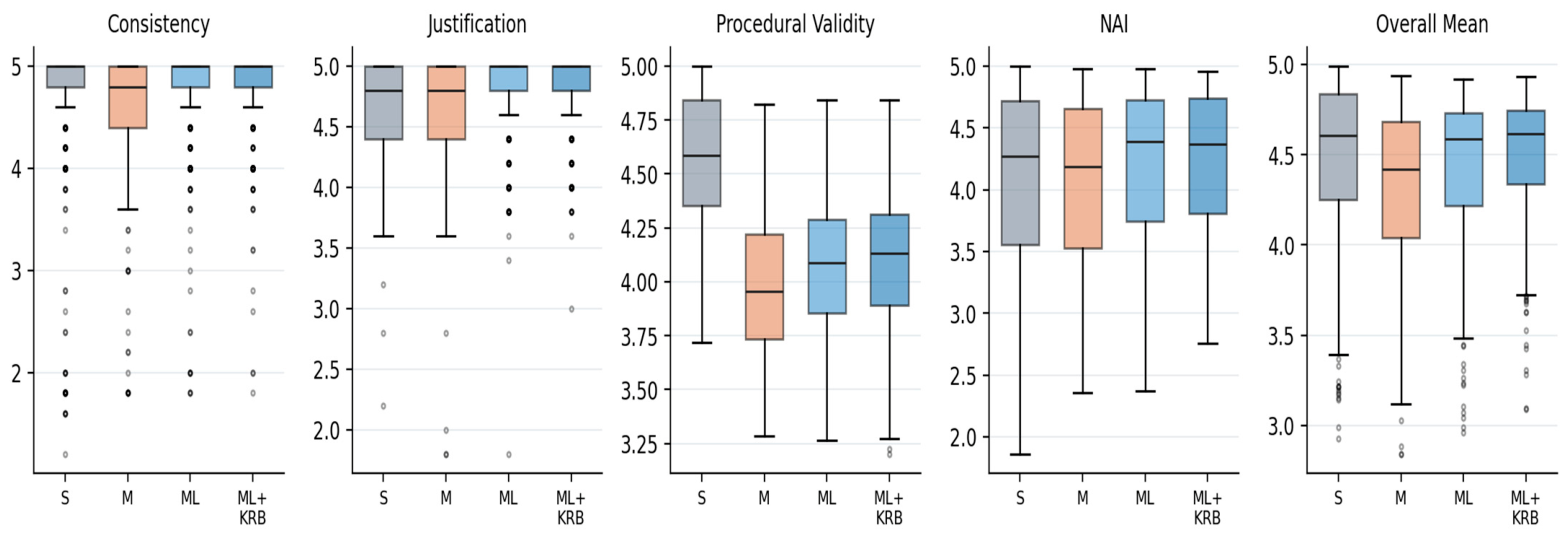
| Consistency | Single | 500 | 4.683 | 0.723 | 5.000 | 1.200 | 5.000 |
| Multi | 500 | 4.630 | 0.567 | 4.800 | 1.800 | 5.000 | |
| Multi-LLM | 500 | 4.745 | 0.528 | 5.000 | 1.800 | 5.000 | |
| Multi-LLM + KRB | 500 | 4.806 | 0.430 | 5.000 | 1.800 | 5.000 | |
| Justifiability | Single | 500 | 4.626 | 0.383 | 4.800 | 2.200 | 5.000 |
| Multi | 500 | 4.658 | 0.420 | 4.800 | 1.800 | 5.000 | |
| Multi-LLM | 500 | 4.788 | 0.351 | 5.000 | 1.800 | 5.000 | |
| Multi-LLM + KRB | 500 | 4.832 | 0.304 | 5.000 | 3.000 | 5.000 | |
| Procedural validity | Single | 500 | 4.574 | 0.284 | 4.588 | 3.718 | 5.000 |
| Multi | 500 | 3.975 | 0.318 | 3.956 | 3.284 | 4.822 | |
| Multi-LLM | 500 | 4.066 | 0.319 | 4.088 | 3.266 | 4.844 | |
| Multi-LLM + KRB | 500 | 4.100 | 0.311 | 4.134 | 3.200 | 4.844 | |
| NAI | Single | 500 | 4.105 | 0.672 | 4.270 | 1.860 | 5.000 |
| Multi | 500 | 4.076 | 0.633 | 4.190 | 2.360 | 4.980 | |
| Multi-LLM | 500 | 4.207 | 0.596 | 4.390 | 2.370 | 4.980 | |
| Multi-LLM + KRB | 500 | 4.238 | 0.554 | 4.370 | 2.760 | 4.960 | |
| Overall mean | Single | 500 | 4.497 | 0.414 | 4.606 | 2.927 | 4.989 |
| Multi | 500 | 4.335 | 0.410 | 4.420 | 2.842 | 4.938 | |
| Multi-LLM | 500 | 4.452 | 0.378 | 4.589 | 2.964 | 4.920 | |
| Multi-LLM + KRB | 500 | 4.494 | 0.341 | 4.615 | 3.094 | 4.933 |
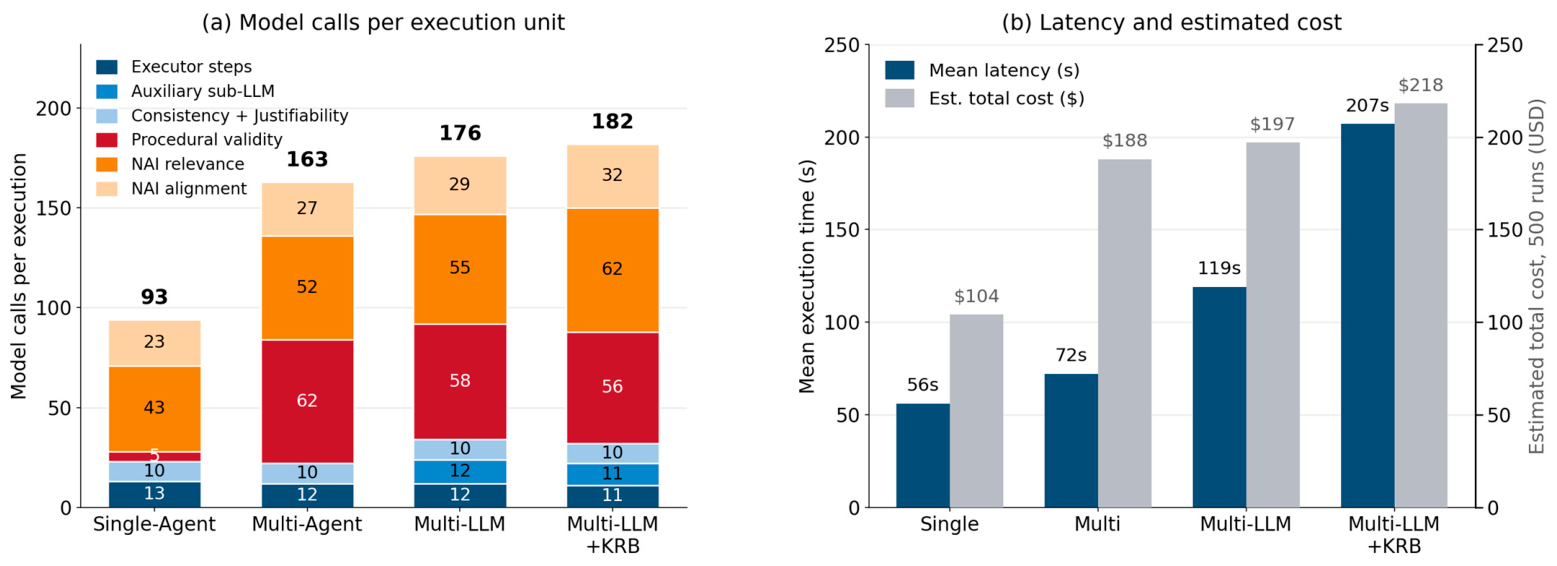
| Condition | Execution Dates | Exec. Calls/Run | Meas. Calls/Run | Total Calls | Exec. Input Tok | Exec. Output Tok | Meas. Tokens | Latency s (vs. Single) | Cost $ |
|---|---|---|---|---|---|---|---|---|---|
| Single-Agent | 2026-04-20–04-27 | 13.07 | 80.35 | 46,709 | 15,265,057 | 1,962,621 | 24,250,987 | 56.1 (1.00×) | 104.48 |
| Multi-Agent | 2026-04-25–05-30 | 12.50 | 150.93 | 81,715 | 20,022,906 | 2,717,971 | 66,631,329 | 72.5 (1.29×) | 188.12 |
| Multi-LLM | 2026-05-02–05-18 | 23.54 | 152.40 | 87,971 | 21,086,434 | 3,074,001 | 73,041,111 | 119.1 (2.12×) | 196.68 |
| Multi-LLM + KRB | 2026-05-04–05-09 | 22.07 | 160.19 | 91,132 | 25,356,503 | 3,746,483 | 85,392,022 | 207.3 (3.70×) | 218.09 |
| Model | Input | Output | Price Basis, as of the Execution Dates (2026-04-20 to 2026-05-30) |
|---|---|---|---|
| GPT-4.1 | 2.00 | 8.00 | Standard uncached API rate; cached input $0.50/M; batch discount excluded |
| Claude Haiku 4.5 | 1.00 | 5.00 | Standard global rate; prompt caching and batch discounts excluded |
| Gemini 2.5 Flash | 0.30 | 2.50 | Stable rate; output price includes thinking tokens |
| Grok-3 | 3.00 | 15.00 | Original Grok-3 rate. From 2026-05-15, the grok-3 model identifier was billed as Grok-4.3 ($1.25/$2.50); this affects 9 of 400 Grok executions |
| DeepSeek V3 | 0.27 | 1.10 | Official list rate; input at cache-miss price (cache hit $0.07/M) |
| Component | Single | Multi | Multi-LLM | Multi-LLM + KRB |
|---|---|---|---|---|
| Consistency (one bundled prompt × 5 evaluators) | 5.0 | 5.0 | 5.0 | 5.0 |
| Justifiability (one bundled prompt × 5 evaluators) | 5.0 | 5.0 | 5.0 | 5.0 |
| Procedural validity | 5.0 (bundled) | 62.3 (per step) | 58.5 (per step) | 55.9 (per step) |
| NAI relevance (5 × principle) | 42.8 | 51.6 | 54.9 | 61.8 |
| NAI alignment (5 × filtered principle) | 22.5 | 27.1 | 29.0 | 32.5 |
| Total measurement calls per execution | 80.4 | 150.9 | 152.4 | 160.2 |
| Executor calls per execution | 13.1 | 12.5 | 23.5 | 22.1 |
| Measurement share of estimated cost | 64.2% | 73.0% | 74.7% | 76.4% |
| Research Question | What the Evidence Shows | Supporting Tables/Figures |
|---|---|---|
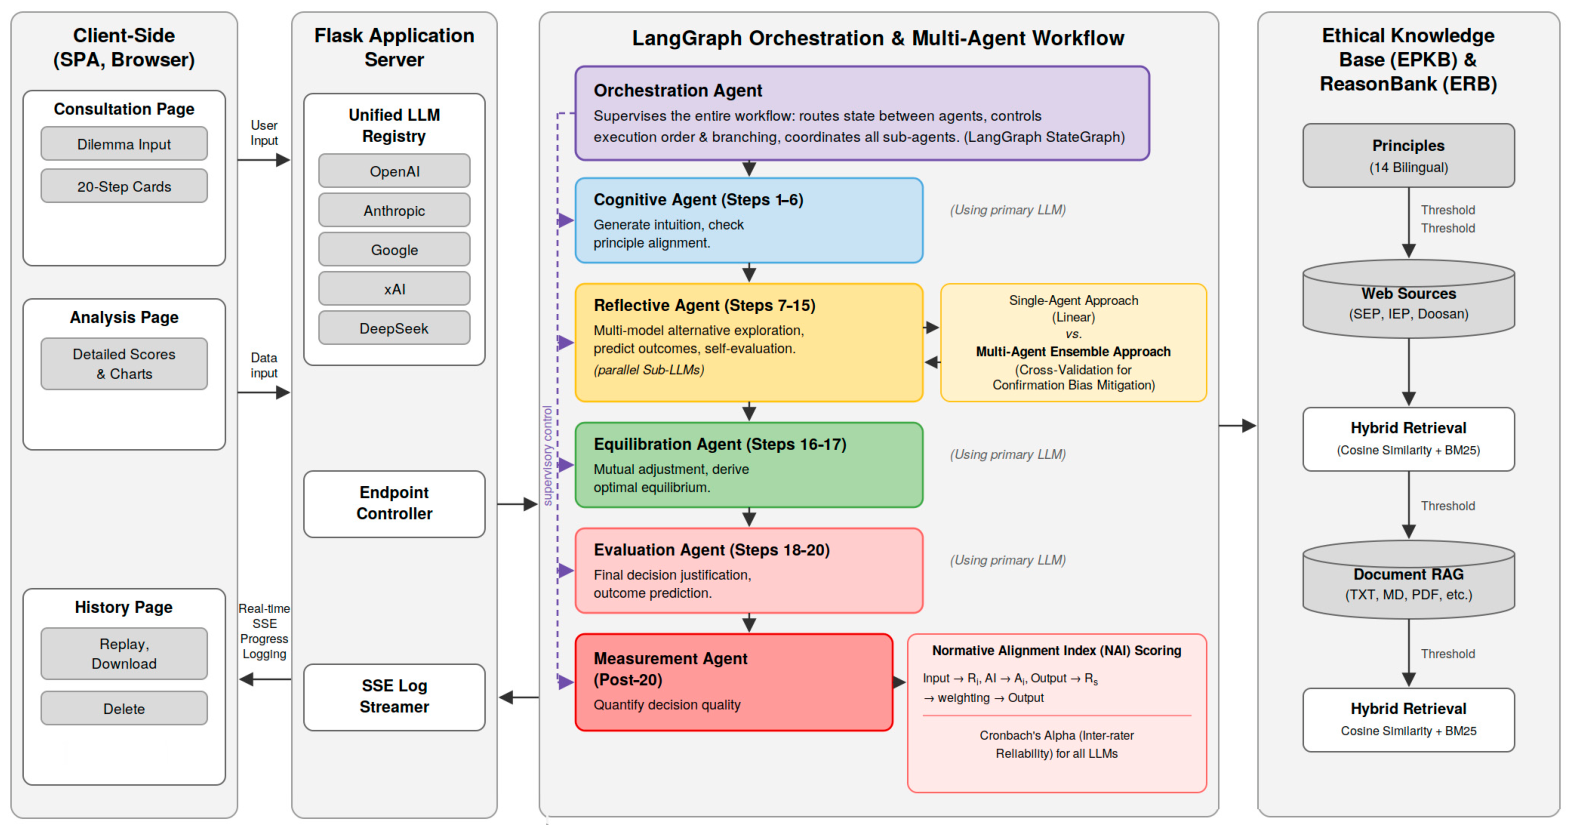
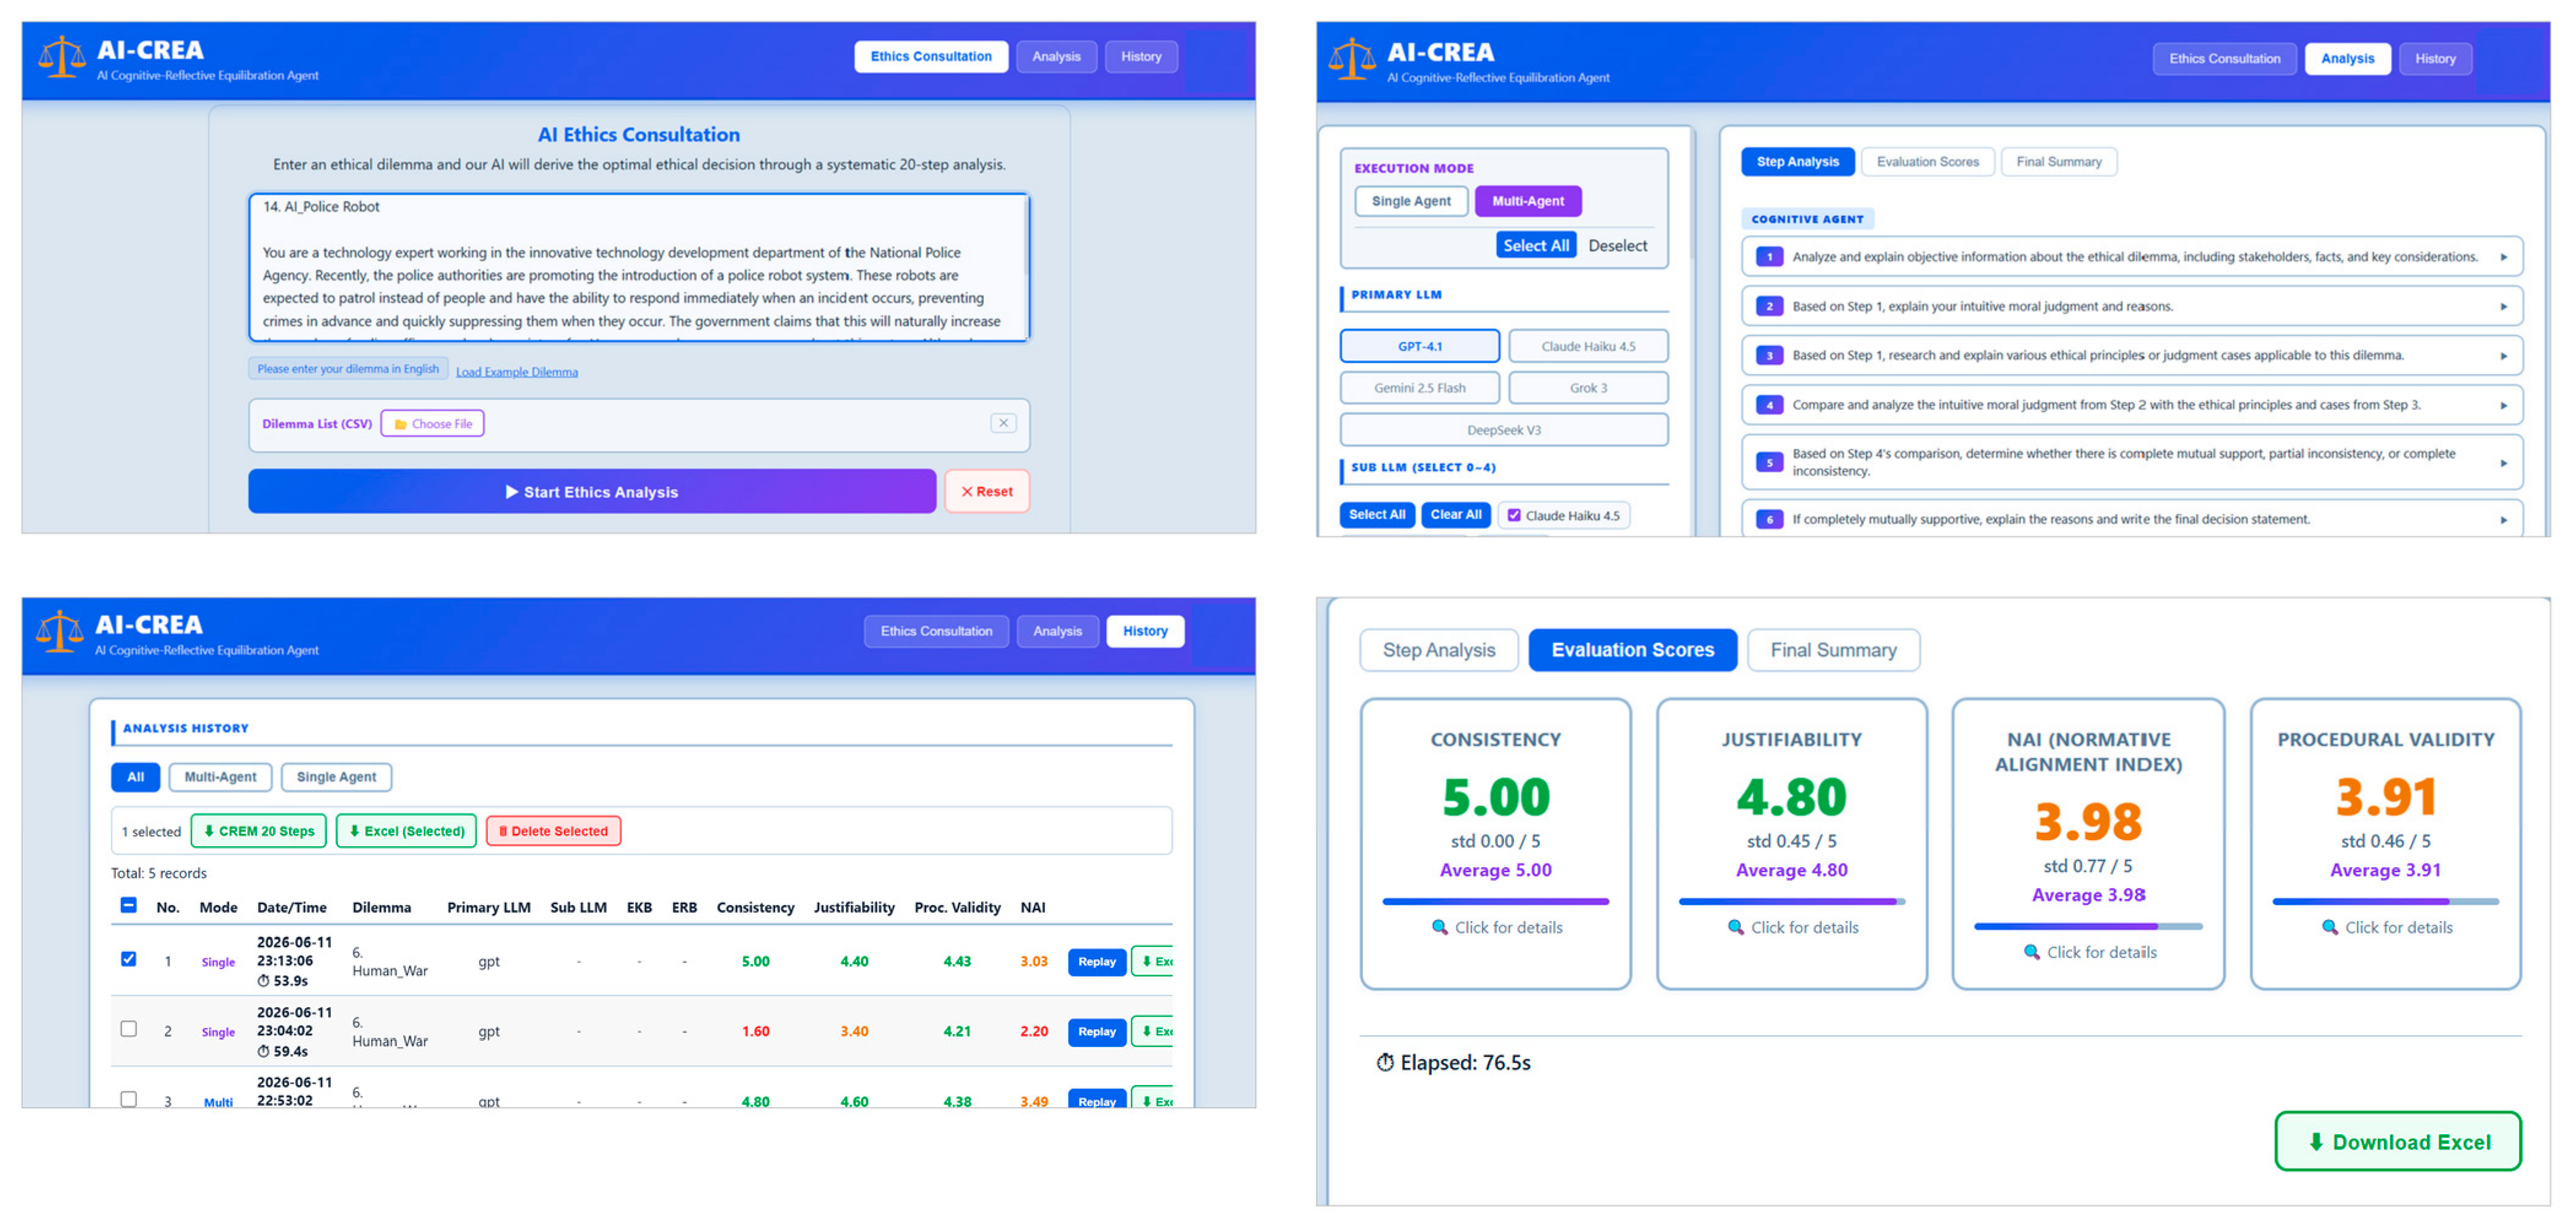
| RQ1. How should a multi-LLM, multi-agent architecture be designed in order to implement CREM as a functioning artificial moral advisor? | CREM was realized as six agent modules under LangGraph orchestration: four stage-aligned reasoning agents, an orchestration agent, and a measurement agent. All four configurations executed the 20-step procedure to completion across 500 execution units each. | Section 4.1; Figure 1 and Figure 2 |
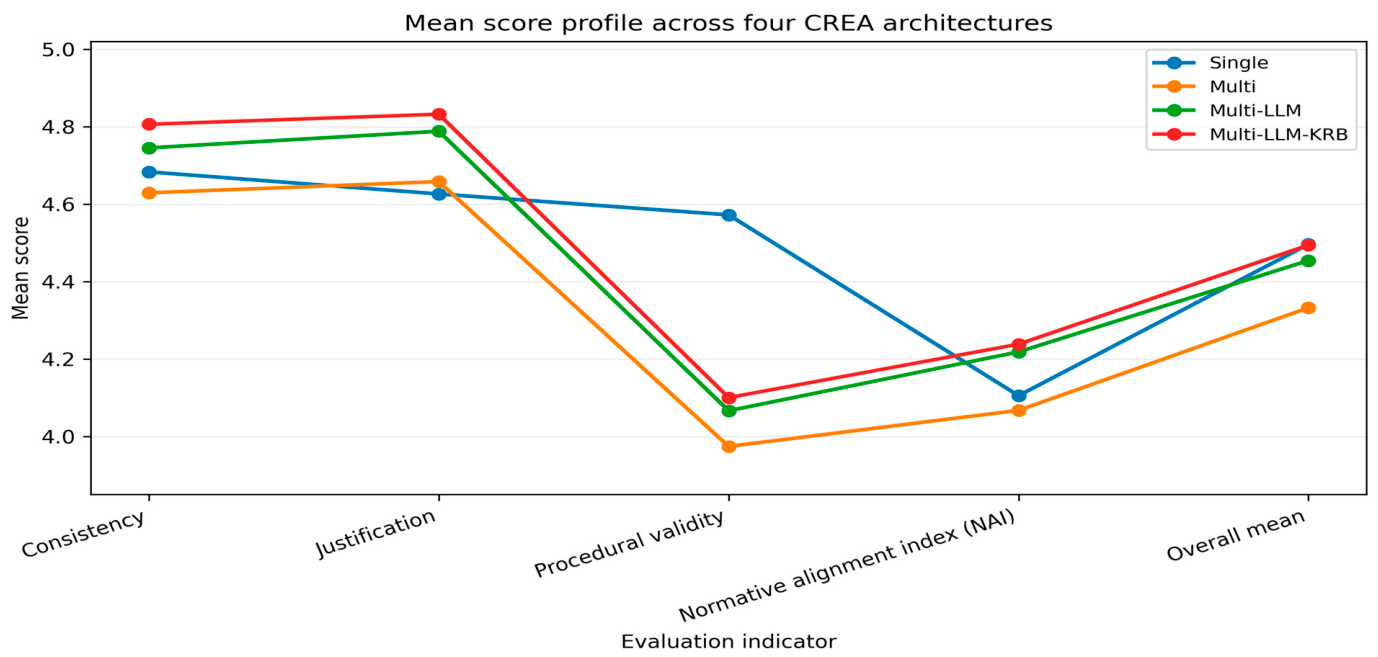
| RQ2. Can a CREM-based AMA deliver advice that is consistent, justifiable, procedurally valid, and normatively aligned? | Under the system’s own measurement, all four configurations scored high on a five-point scale: consistency 4.63–4.81, justifiability 4.63–4.83, NAI 4.08–4.24, procedural validity 3.98–4.57. Distributions are compressed near the maximum on consistency and justification, so ceiling effects apply. These are self-evaluated scores and do not establish normative validity. | Section 4.2.1; Table 6 and Table 7; Figure 3 and Figure 4 |
| RQ3. How does advice quality vary across architectural configurations? | Agent decomposition alone produced no significant gain on any indicator and a large procedural-validity decline. Multi-LLM deliberation improved all five outcomes over the multi-agent baseline (dz = 0.168–0.424). KRB added small further gains (dz = 0.112–0.157) except on NAI. Against single-agent, the full configuration was higher on consistency, justifiability, and NAI, lower on procedural validity, and not significantly different on the overall mean. | Section 4.2.2; Table 8; Figure 5 and Figure 6 |
| Indicator | Single | Multi | Multi-LLM | Multi-LLM + KRB |
|---|---|---|---|---|
| Mean length of a procedural-validity reason (characters) | 167.0 | 433.1 | 437.7 | 438.0 |
| Median length | 151 | 426 | 430 | 430 |
| Reasons empty after parsing | 1.3% | 0.0% | 0.0% | 0.0% |
| Reasons naming a step (“Step N” or “AN”) | 0.8% | 55.1% | 57.6% | 58.1% |
| Per-step “executed” flag written to the record | present | absent | absent | absent |
| Procedural-validity calls per execution | 5 | 5 × executed steps | 5 × executed steps | 5 × executed steps |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Kim, C.; Ahn, S. Implementing a Cognitively Grounded Artificial Moral Advisor: A Multi-LLM Multi-Agent Approach Based on the Cognitive–Reflective Equilibration Model. J. Intell. 2026, 14, 212. https://doi.org/10.3390/jintelligence14090212
Kim C, Ahn S. Implementing a Cognitively Grounded Artificial Moral Advisor: A Multi-LLM Multi-Agent Approach Based on the Cognitive–Reflective Equilibration Model. Journal of Intelligence. 2026; 14(9):212. https://doi.org/10.3390/jintelligence14090212
Chicago/Turabian StyleKim, Chulmin, and Seongjin Ahn. 2026. "Implementing a Cognitively Grounded Artificial Moral Advisor: A Multi-LLM Multi-Agent Approach Based on the Cognitive–Reflective Equilibration Model" Journal of Intelligence 14, no. 9: 212. https://doi.org/10.3390/jintelligence14090212
APA StyleKim, C., & Ahn, S. (2026). Implementing a Cognitively Grounded Artificial Moral Advisor: A Multi-LLM Multi-Agent Approach Based on the Cognitive–Reflective Equilibration Model. Journal of Intelligence, 14(9), 212. https://doi.org/10.3390/jintelligence14090212