


Abstract
Chinese Haipai New Year paintings are an important part of the country’s intangible cultural heritage, and their digital preservation holds great significance. This paper proposes PSE-Net (Pyramid Scale Expansion Network), a deep learning-based segmentation method specifically designed to handle the complex textures and intricate compositions of these artworks. By constructing a dedicated large-scale dataset, we trained PSE-Net to achieve high-precision segmentation by incorporating attention mechanisms and multi-scale feature fusion to better capture detailed features. Experimental results demonstrate that the proposed method outperforms existing approaches (such as ResNet) in terms of segmentation performance, yielding superior results in edge preservation. This work establishes the first automated tool for the pixel-level analysis of Haipai New Year paintings, thereby facilitating museum digitization, art history research, and education. Furthermore, it offers new insights for the image processing and digital preservation of other traditional artworks.
1. Introduction
Haipai New Year Paintings are a special type of folk art with a long history and great cultural value. As a significant part of the intangible cultural heritage of China, these artworks represent the traditional concepts of aesthetics, as well as social life, folk customs, and systems of belief through various periods of history [1]. However, owing to the fragility of the materials, environmental degradation, and the gradual loss of their traditional skills, Haipai New Year paintings are currently under severe threat with regard to their preservation, transmission, or recording. A vast number of precious works still exist in their physical state, which could face permanent damage or loss.
In the current digital age, the integration of information technology with the conservation, preservation, and analysis of Haipai New Year Paintings is becoming more significant [2]. Image segmentation is one such important application of information technology that is widely used in image analysis for conservation purposes. In the context of Haipai New Year paintings, image segmentation would help to identify key areas such as human bodies, design elements, background areas, and representation elements effectively. A detailed understanding of the structure of the image is critical for various applications such as image archiving, image restoration of damaged sections, and analysis of image levels, among other features.
More significantly, accurate segmentation results can provide a technical basis for establishing a structured digital database of Haipai New Year paintings. In real-world applications, such techniques can help museums establish high quality digital databases and enable image restoration and damage analysis software for the restoration of paintings, as well as enable the development of interactive learning platforms for educational purposes. More importantly, accurate segmentation techniques can provide a bridge between computer vision research and humanities studies, as they can enable collaboration between researchers from engineering backgrounds and humanities researchers such as art historians.
Recently, great progress has been achieved by deep learning methods in image segmentation tasks. However, it is difficult to apply existing image segmentation models to Haipai New Year paintings directly since there are various artistic styles, complex textures, complex lines, and complex color distributions in Haipai New Year paintings, which are quite dissimilar to those in crossover image segmentation tasks. It is of great theoretical significance and importance to design image segmentation models for Haipai New Year paintings using deep learning techniques.
Traditional image segmentation techniques were almost entirely dependent on edge detection, region growing, or thresholding. These techniques, although useful for segmented images, tend to perform poorly in complex artworks with high-density textures, as observed in Haipai New Year paintings. Later, machine learning-based approaches with handcrafted features were proposed using techniques such as Support Vector Machines or Random Forest, among others. However, their effectiveness is still limited for dealing with the variability of Haipai New Year paintings. The development of deep learning, in particular with the advent of the Fully Convolutional Network, brought about a significant improvement in image segmentation techniques. Later models like U-Net or SegNet further optimized image segmentation. While some research works have utilized deep learning for the segmentation of murals or paints, it still seems that research work related to the segmentation of Chinese Traditional Haipai New Year paintings is limited. In this research, the aim is to propose a segmentation technique for Chinese traditional Haipai New Year paintings using the PSE-Net framework, with the objective of offering a beneficial resource for digital preservation of heritage. The main research content includes:
- Building a large-scale dataset of Haipai New Year paintings, covering samples from different regions, periods, and styles;
- Designing a deep learning network structure tailored to the features of Haipai New Year paintings to improve segmentation accuracy and robustness;
- Proposing a loss function and training strategy suited to the characteristics of Haipai New Year paintings, addressing issues such as class imbalance;
- Conducting extensive experiments to verify the effectiveness of the proposed method and comparing it with existing approaches.
2. Related Work
2.1. The Culture and Artistic Features of Haipai New Year Paintings
Haipai New Year paintings, also known as Shanghai Xiaojiaochang woodblock New Year paintings, originated from Taohuawu in Suzhou and initially emerged during the Jiaqing era of the Qing dynasty. Following the establishment of Shanghai as an open port in the late Qing dynasty, the genre experienced a rapid proliferation, progressively integrating both Chinese and Western painting styles. This evolution culminated in the formation of a distinctive Haipai artistic language [3].
Haipai New Year paintings inherited the fundamental forms and techniques of their traditional predecessors while undertaking significant stylistic innovations in content and style. These works closely mirrored the lives of urban dwellers, characterized by chromatic vibrancy and audacious compositions, ultimately representing the final flourishing in the history of Chinese woodblock New Year paintings [4]. The emergence of this genre was intrinsically linked to the ascent of Shanghai as a modern metropolis. Amidst the turmoil of the mid-19th century Taiping Heavenly Kingdom movement, which precipitated the decline of Suzhou’s preeminence as an economic hub, a substantial influx of artisans from the Taohuawu school sought refuge in Shanghai. This migration was instrumental in providing the critical talent pool and technical heritage that fueled the development of the Haipai style [5]. Shanghai’s distinctive milieu catalyzed a unique transformation in Haipai New Year paintings. While rooted in tradition, they were reshaped by the modern metropolis. In technique, they upheld classic woodblock printing but embraced Western concepts like perspective and chiaroscuro, breaking from flat, traditional styles to create a modern, dimensional aesthetic.
Haipai New Year paintings are more than folk art; they are a visual record of Shanghai’s rapid societal and economic change. As the city urbanized and commercialized, Haipai paintings became a signature of its culture, depicting the details of modern life and reflecting the profound impact of modernization [6].
Through avenues such as local museums and art exhibitions, Haipai New Year paintings have progressively transcended their status as a local art form to enter the spheres of academic inquiry and cultural preservation, solidifying their position as a vital component of China’s modern cultural heritage. Viewed through the lens of artistic transformation, they represent a pivotal nexus in the modernization of Chinese folk art. While inheriting the traditional craftsmanship of the Taohuawu school, Haipai paintings also embodied the innovative trends of Chinese commercial art. Consequently, in-depth research into Haipai New Year paintings allows for a deeper comprehension of the dynamics of cultural fusion within Shanghai and the Jiangnan region, as well as the broader innovation and metamorphosis of this folk art form.
2.2. Cultural Heritage Digitization
The digitalization of cultural heritage refers to the process of utilizing modern information technology to transform traditional tangible and intangible cultural heritage into digital formats for the purposes of preservation, management, exhibition, and dissemination [7]. In the context of advancing globalization and rapid technological development, the conservation and inheritance of cultural heritage face formidable challenges. Digitalization offers novel pathways for their safeguarding, enabling their conservation and widespread dissemination in the information age. The primary objectives of this digitalization include the conservation and preservation of heritage through detailed digital documentation to prevent the deterioration of physical artifacts. Furthermore, it aims to facilitate information sharing and management by standardizing and systematizing heritage data for global accessibility. It also seeks to create virtual exhibitions and interactions, leveraging technologies like Virtual Reality (VR) and Augmented Reality (AR) to offer the public immersive, online experiences. Finally, this process promotes interdisciplinary research across fields such as history, archaeology, and art history, fostering a more multifaceted understanding of cultural heritage [8].
Technically, cultural heritage digitalization leverages advanced tools. 3D scanning accurately captures artifacts and buildings, while high-resolution imaging preserves minute details in texts and paintings. VR and AR create immersive public experiences, and Big Data with cloud computing enables efficient large-scale data storage and sharing. However, this digitalization is not without its challenges [9]. Key issues include the high cost of precision equipment, the difficulty of long-term data preservation amidst technological obsolescence, the need to address intellectual property and privacy concerns, and the practical difficulties of fostering interdisciplinary collaboration.
Notwithstanding these challenges, the prospects for cultural heritage digitalization remain vast, driven by the continuous advancement of information technology [10]. The application of emerging technologies, such as Artificial Intelligence (AI) and deep learning, holds the potential to significantly enhance digitalization efficiency and address existing limitations. Looking ahead, the role of digitalization is poised to transcend the traditional functions of preservation and exhibition. It will evolve into a pivotal instrument for fostering global cultural exchange and mutual understanding, facilitating deeper intercultural dialogue grounded in respect and comprehension.
2.3. Computer Vision Research on Traditional Artworks
Traditional artworks, such as murals, paintings, folk art, and calligraphy, represent an important category of cultural heritage with rich semantic meaning and complex visual characteristics. In recent years, computer vision techniques have increasingly been applied to the analysis and digital preservation of traditional artworks, forming an interdisciplinary research field that bridges artificial intelligence and cultural heritage studies. Compared with natural images, traditional artworks often exhibit non-photorealistic representations, intricate decorative textures, dense symbolic elements, and strong color stylization, which pose significant challenges for conventional image analysis methods.
Early computer vision studies on traditional artworks mainly relied on handcrafted features for tasks such as color analysis, texture description, and motif extraction. These approaches provided preliminary quantitative tools for art analysis but were limited in their ability to model complex artistic patterns. With the rapid development of deep learning, convolutional neural networks have been widely introduced into artwork analysis tasks, including artwork classification, style recognition, damage detection, and image segmentation. Segmentation-based approaches, in particular, play a crucial role in cultural heritage applications, enabling the decomposition of artworks into meaningful components such as figures, decorative patterns, and background regions.
In practical cultural heritage scenarios, image segmentation supports a wide range of applications, including digital archiving, virtual restoration, pigment and material analysis, and iconographic interpretation. Accurate segmentation results facilitate structured digital documentation of artworks and provide technical support for museum digitization projects, conservation planning, and interactive exhibitions. However, research on traditional artworks remains constrained by limited annotated datasets, high labeling costs, and the reliance on expert knowledge from art historians and conservators. These challenges highlight the necessity of developing task-specific segmentation models tailored to the unique visual characteristics of traditional artworks.
2.4. Overview of Image Segmentation Techniques
Image segmentation is a fundamental task in computer vision, aiming to partition a digital image into semantically coherent regions or objects. With technological advancements, existing segmentation approaches can be broadly categorized into traditional algorithms and deep learning-based methods, each exhibiting distinct characteristics and application scenarios.
Traditional image segmentation methods primarily depend on handcrafted features and mathematical criteria. Threshold-based approaches, such as the Otsu algorithm [11], determine optimal thresholds from grayscale histograms to separate foreground from background, but their effectiveness is limited to high-contrast images. Edge detection methods, including the Canny operator [12], extract object boundaries based on gradient variations. However, they are sensitive to noise and often fail to produce closed contours in complex scenes. Region growing algorithms merge neighboring pixels with similar properties to form connected regions [13], yet their performance heavily depends on the selection of initial seed points. Although these methods are computationally efficient, they generally struggle with images containing complex textures, varying illumination, or overlapping objects.
Deep learning-based segmentation approaches leverage convolutional neural networks to automatically learn hierarchical feature representations, leading to significant improvements in segmentation accuracy. Fully Convolutional Networks [14] pioneered pixel-level prediction by replacing fully connected layers with convolutional layers and employing upsampling operations to recover spatial resolution. U-Net [15] further introduced an encoder–decoder architecture with skip connections, effectively balancing semantic information and spatial details, and has been widely adopted in medical image segmentation. The DeepLab series [16] employed atrous convolution and Atrous Spatial Pyramid Pooling to capture multi-scale contextual information, addressing object scale variation. For instance-level segmentation, Mask R-CNN [17] extended object detection frameworks by adding a mask prediction branch for precise pixel-level segmentation.
More recently, vision Transformers have demonstrated strong potential in complex segmentation tasks. Models such as Swin Transformer [18] utilize self-attention mechanisms to capture long-range dependencies, while Vision Transformer [19] reformulates images as patch sequences to model global contextual relationships. Subsequent improvements, including DeiT [20] reduce reliance on large-scale datasets through distillation strategies. Hybrid architectures, such as CoAtNet [21], integrate the local inductive bias of CNNs with the global modeling capability of Transformers, further advancing segmentation and classification performance.
Current research challenges in image segmentation focus on data efficiency, computational cost, and adaptability to open environments. Weakly supervised learning methods, such as Class Activation Map (CAM)-based approaches [22], and few-shot segmentation techniques based on meta-learning frameworks [23], aim to reduce dependence on dense annotations. Lightweight network designs, including MobileNet and its variants [24,25], knowledge distillation, and neural architecture search [26], target real-time and resource-constrained scenarios. In addition, cross-modal models, such as CLIP-driven open-vocabulary segmentation [27], are expanding the generalization ability of segmentation models toward open-world applications.
3. Method
3.1. PSE-Net Model
This study proposes PSE-Net (Pyramid Scale Expansion Network), an image segmentation model built upon a modified U-Net architecture. The core design focuses on enhancing multi-scale feature representation through a deep fusion of multi-path parallel architecture and hybrid attention mechanisms. Unlike standard U-Net models, PSE-Net introduces a “Pyramid Scale Expansion” strategy to address the specific visual characteristics of Chinese traditional Haipai New Year paintings—specifically the dense symbolic elements, complex decorative textures, and large variations in object scale.
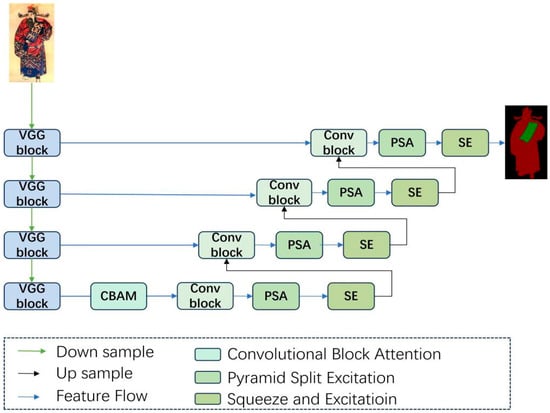
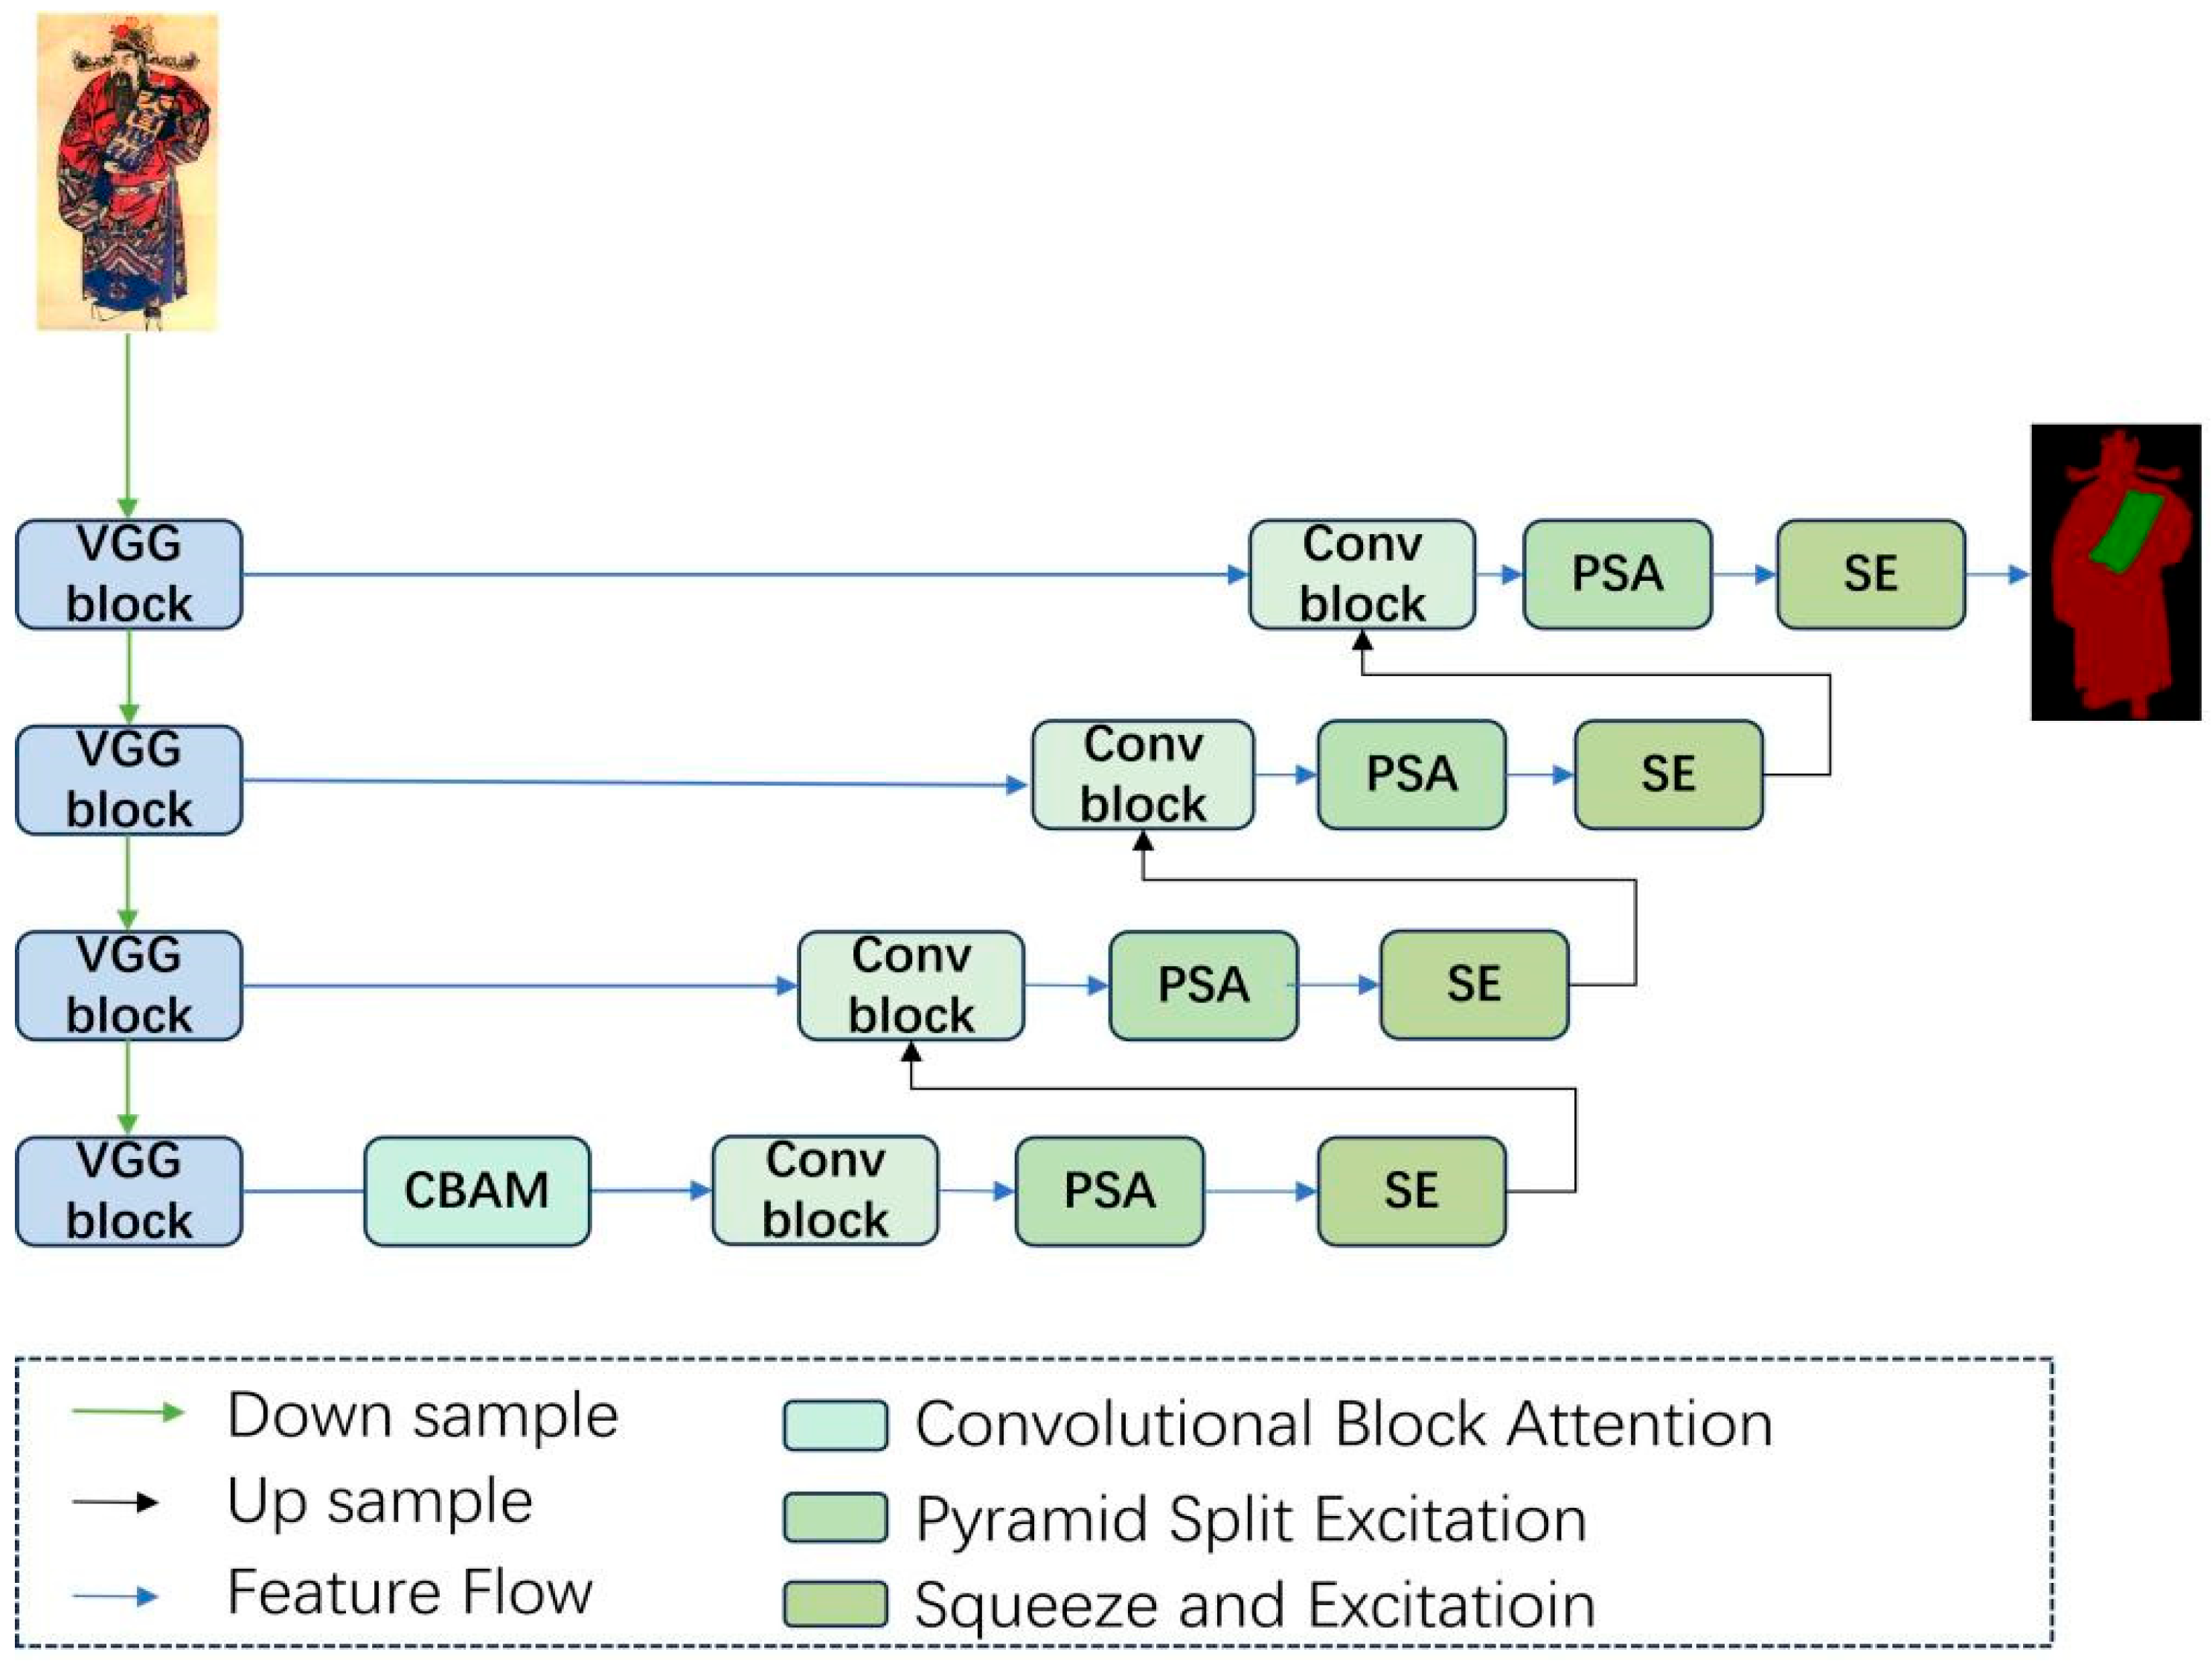
The segmentation model for Haipai New Year paintings based on PSE-Net is illustrated in Figure 1.
Figure 1.
Overall architecture of PSE-Net.
The entire workflow begins with the input features at the top, which first pass through a series of stacked VGG blocks (serving as the U-Net encoder) for basic feature extraction. These classic convolutional modules progressively capture the spatial hierarchy of the image via sequential convolution layers and activation functions. To improve upon the standard U-Net, the extracted features are then split into four parallel processing pathways. For Haipai New Year paintings, such hierarchical feature extraction is essential for simultaneously preserving fine line structures, ornamental contours, and higher-level semantic representations of major figures and symbolic motifs. The extracted features are then split into four parallel processing pathways, enabling differentiated modeling of artistic elements with varying scales and visual complexity.
The first three pathways follow a unified processing chain—features output by each VGG block are first passed through a convolutional block (Conv Block) containing standard convolution and normalization operations to enhance local features. This step helps refine the dense textures and repetitive decorative patterns commonly found in Haipai New Year paintings. Subsequently, the features are fed into the Pyramid Split Attention (PSA) module to model multi-scale spatial context. The PSA module is particularly suitable for Haipai New Year paintings, as important visual components such as figures, clothing patterns, and background ornaments often appear at markedly different spatial scales. By explicitly facilitating cross-scale feature interaction, PSA enhances the network’s ability to capture both global composition and fine-grained artistic details. Finally, a Squeeze-and-Excitation (SE) module performs adaptive recalibration of the channel dimensions, which is beneficial for handling the rich and symbolic color usage in Haipai New Year paintings by emphasizing informative feature channels and suppressing less relevant responses.
The fourth pathway exhibits a distinctive combination of attention mechanisms. After the VGG block, it initially integrates the Convolutional Block Attention Module (CBAM), which simultaneously addresses spatial and channel relations. In the context of Haipai New Year paintings, this early attention guidance helps the network focus on semantically meaningful regions, such as human figures and auspicious symbols, within visually crowded compositions. This is followed by the Conv Block, PSA, and SE modules in sequence, further refining spatial localization and multi-scale feature representation. The pre-integration of dual attention mechanisms in this pathway is therefore well suited for segmenting complex artistic scenes with overlapping elements and intricate layouts.
The green arrows in the network represent down-sampling operations, which progressively compress feature map sizes to enlarge the receptive field and capture global structural information, an important requirement for understanding the overall composition of Haipai New Year paintings. The black arrows denote up-sampling processes for restoring spatial resolution, ensuring that fine edge details and ornamental boundaries are accurately recovered. Blue arrows indicate the transmission of cross-level feature fusion, allowing low-level texture information and high-level semantic cues to be jointly exploited.
Notably, the PSA module facilitates interaction among multi-scale features via a pyramid-based splitting and reassembling strategy, which aligns well with the hierarchical organization of visual elements in Haipai New Year paintings. The SE module employs global pooling to dynamically adjust channel weights, supporting effective discrimination between foreground elements and richly decorated backgrounds. The CBAM module further enhances feature representations through the combined use of spatial and channel attention, enabling robust feature selection in visually complex artistic images.
Through the organic integration of traditional convolutional structures, parallel processing paradigms, and hybrid attention mechanisms, PSE-Net not only retains the strengths of convolutional neural networks in capturing local visual patterns but also enhances sensitivity to salient semantic regions and cross-scale contextual information. These properties make the proposed model particularly suitable for the segmentation of Haipai New Year paintings, where precise spatial localization, detailed boundary preservation, and robust handling of multi-scale artistic elements are simultaneously required.
3.2. PSE Attention Model
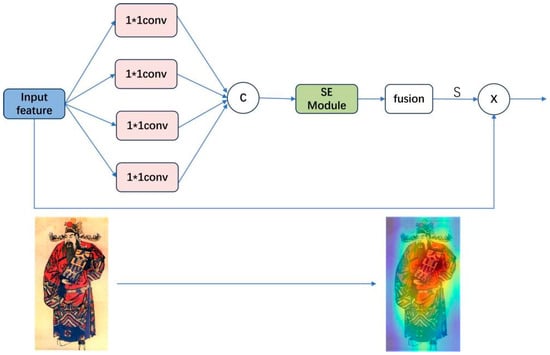
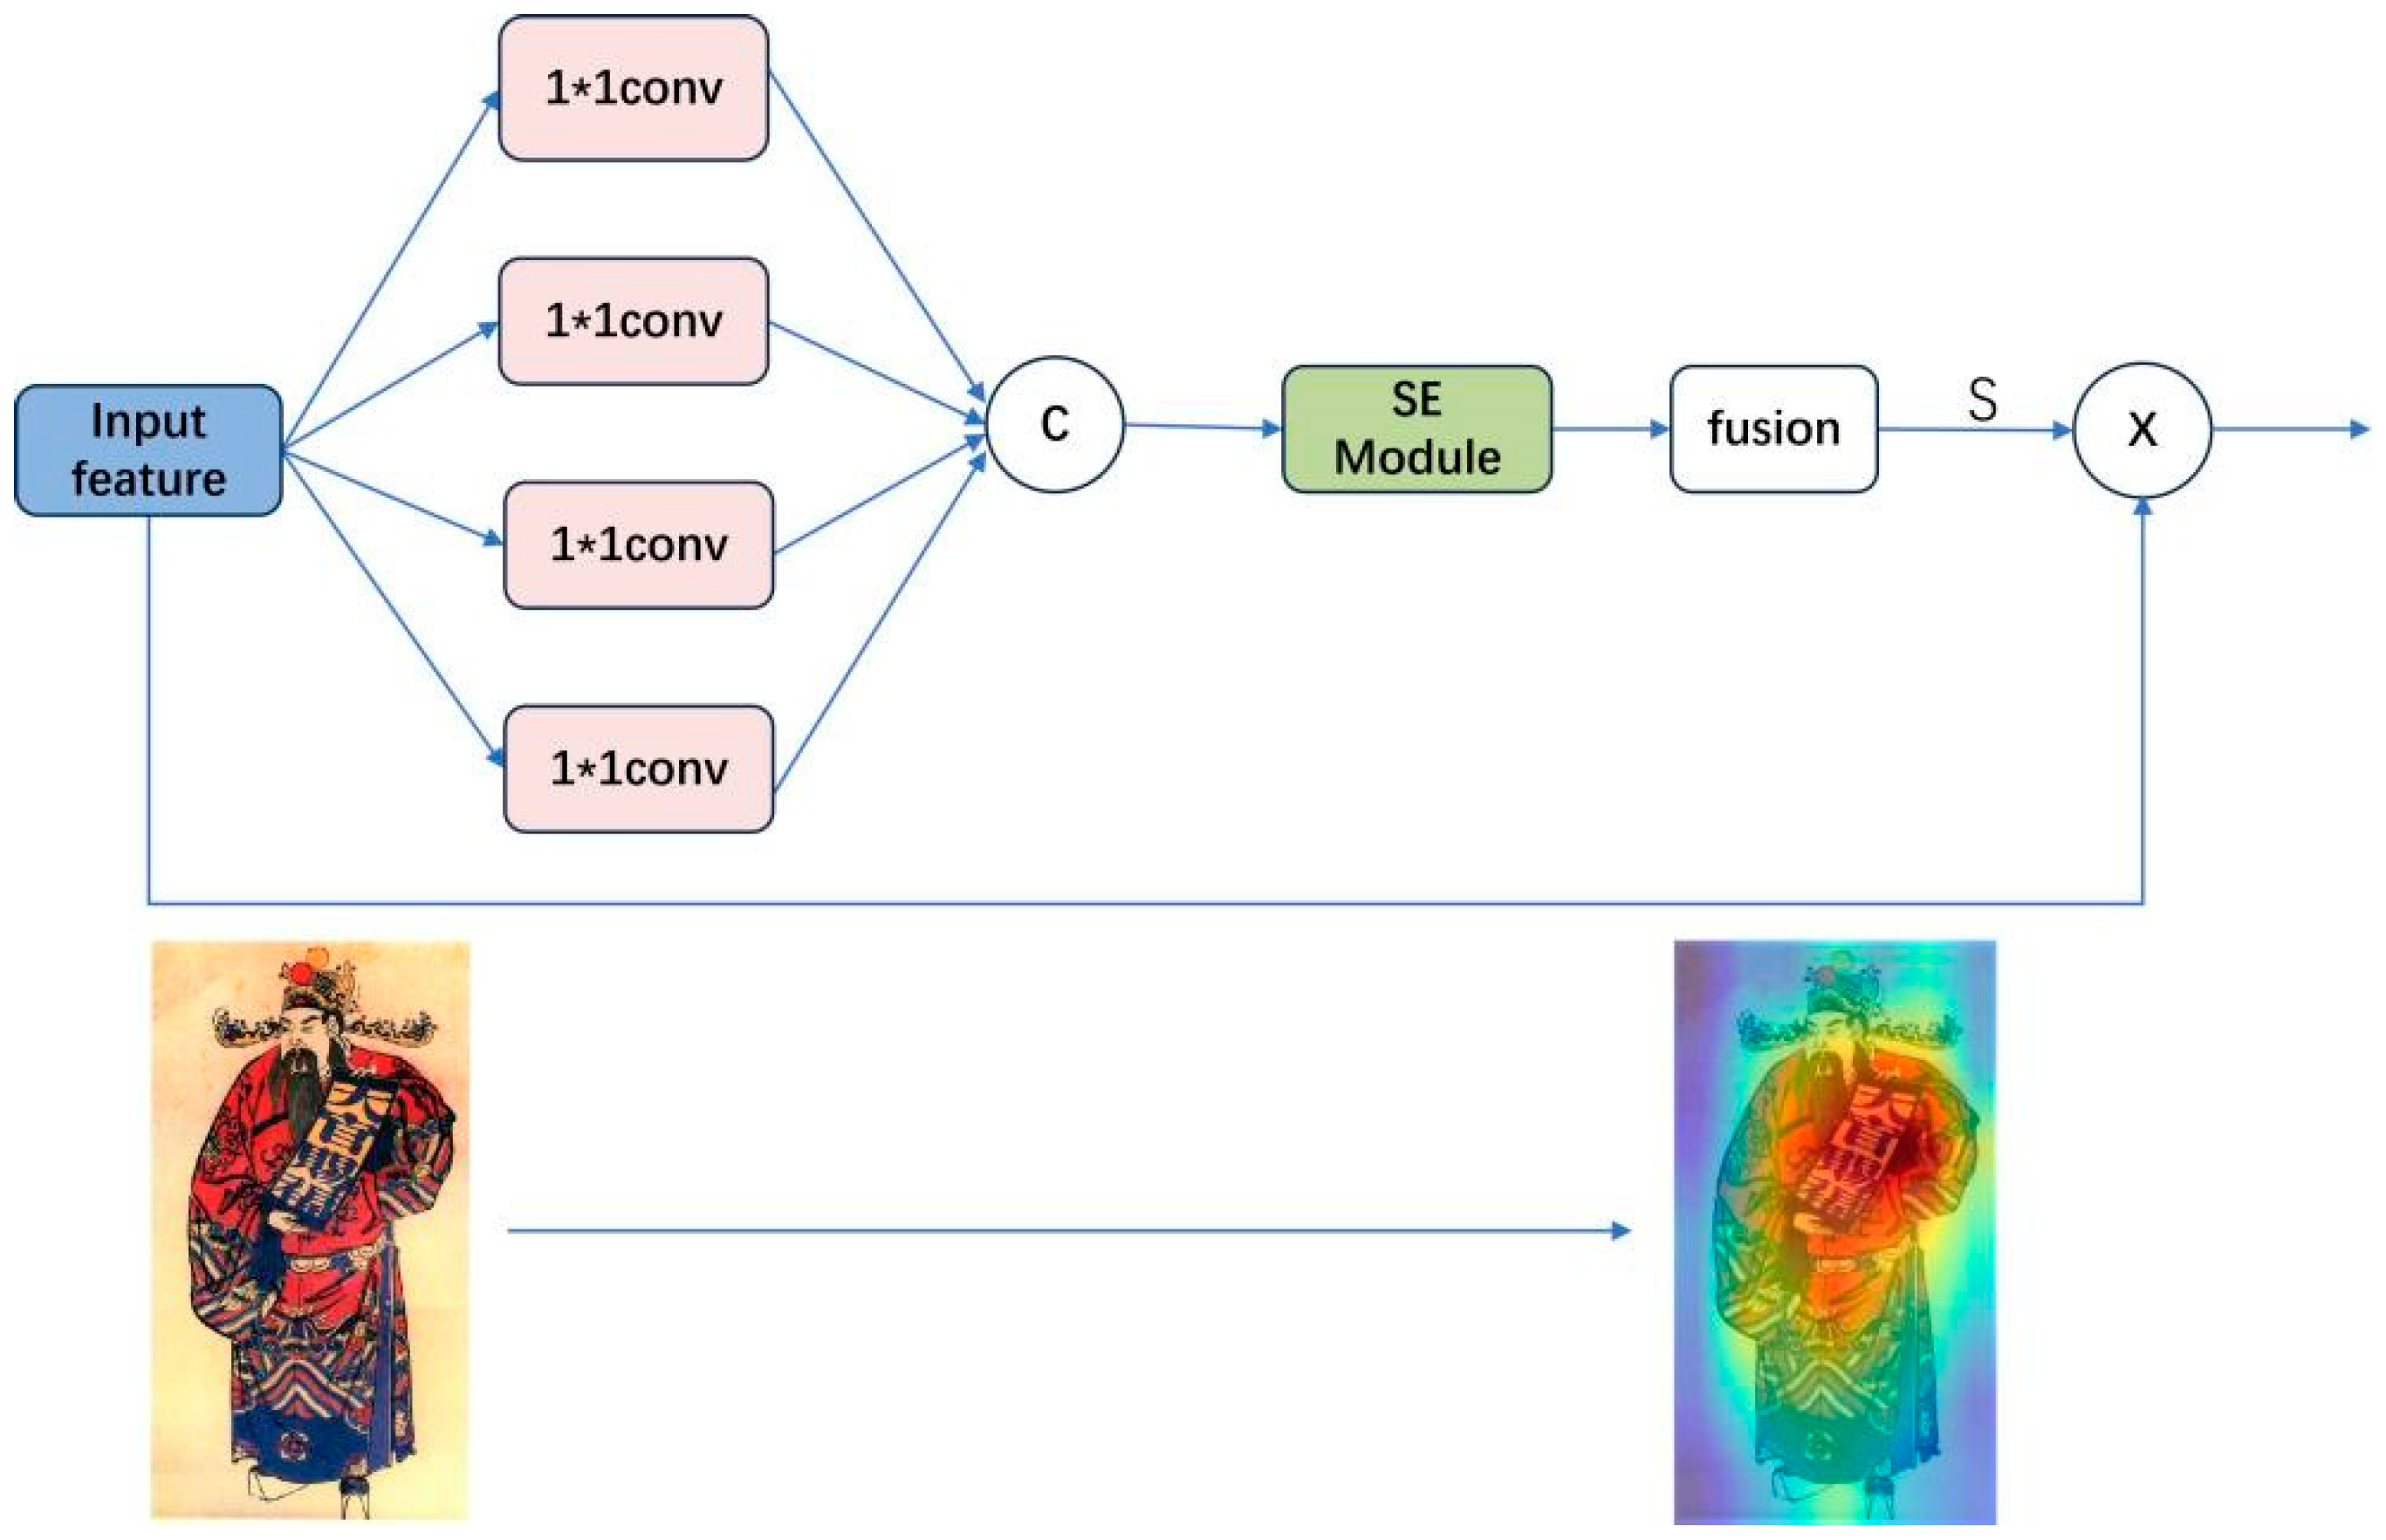
The PSE Attention Module proposed in this paper, as illustrated in Figure 2 and Figure 3, is built upon a three-stage process: feature extraction, attention enhancement, and the generation of spatial-channel mixed attention weights. The detailed procedure is as follows:
Figure 2.
The overall framework of the PSE Attention Module.
Figure 3.
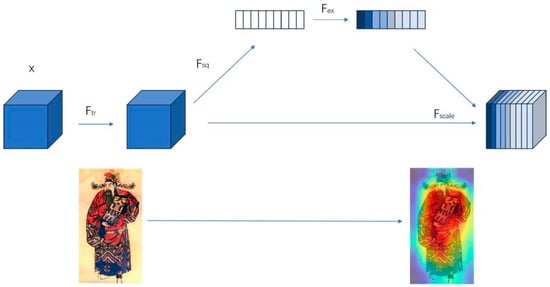
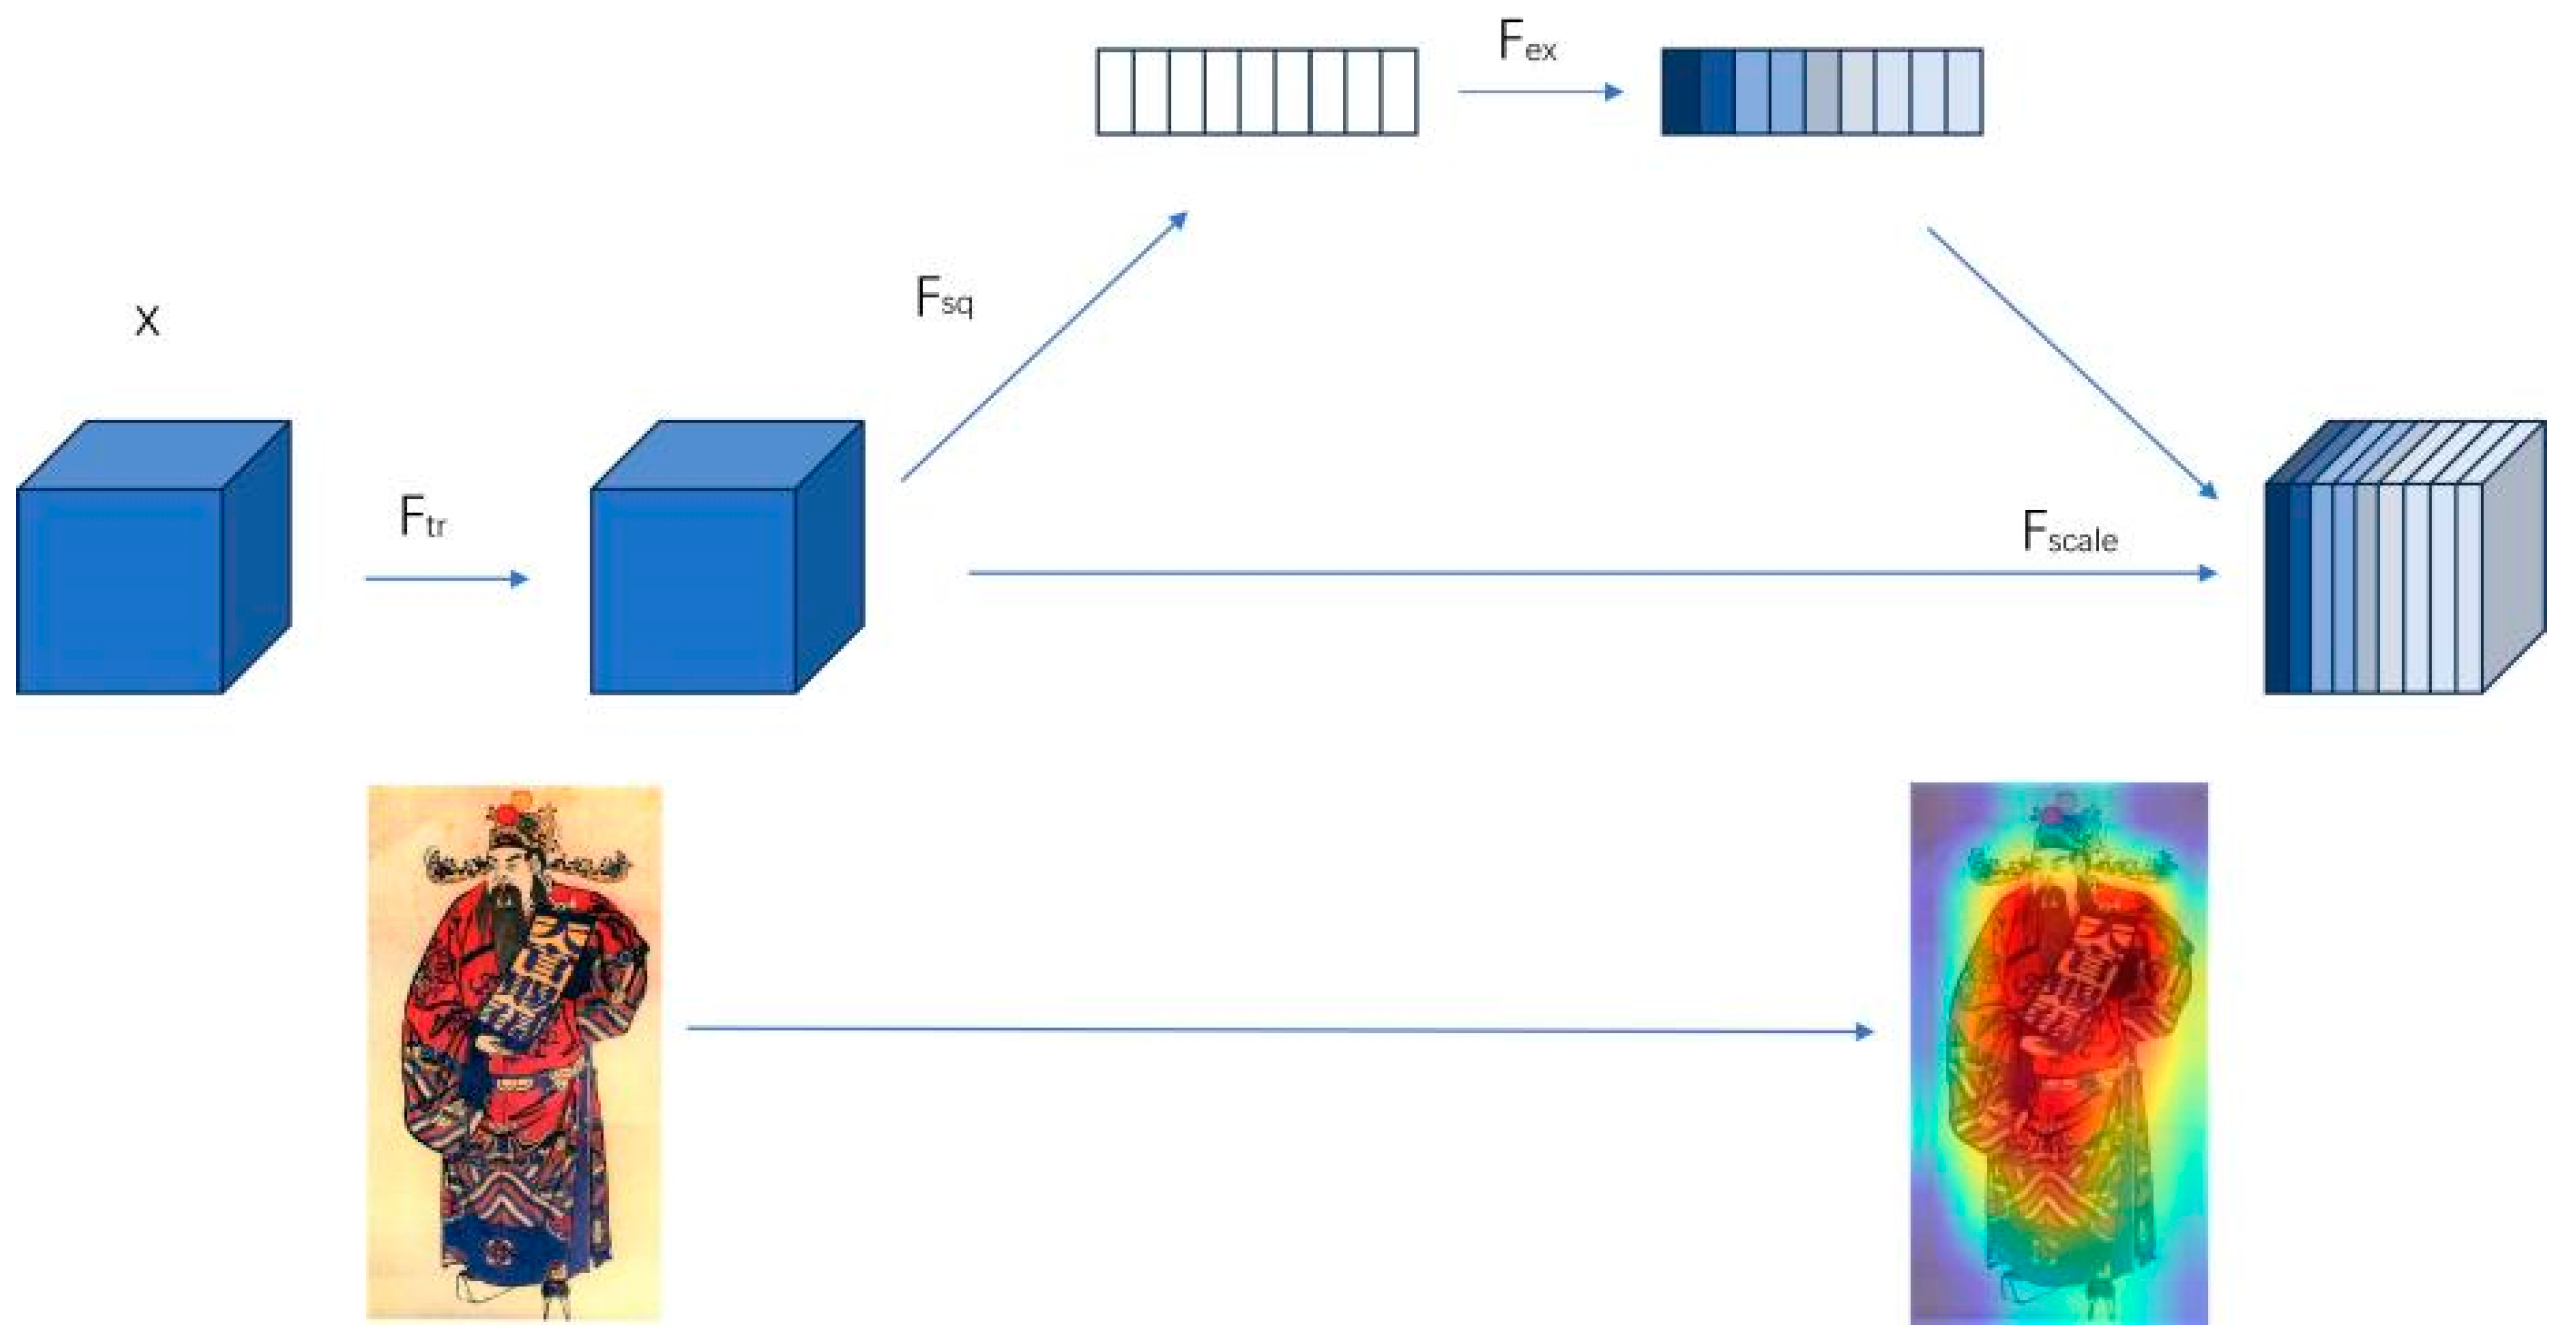
Squeeze-and-Excitation module.
3.2.1. Multi-Scale Feature Extraction
Each branch extracts features using a 1 × 1 convolution, with the number of output channels set to :
where * denotes the convolution operation. .
The 1 × 1 convolution enables efficient channel-wise transformation without altering spatial resolution, allowing the network to flexibly allocate feature capacity across different scales while maintaining low computational complexity. This design is particularly effective for controlling the balance between fine-grained and coarse-grained features in a structured manner. Unlike traditional attention mechanisms that reweight features on a single aggregated feature map, the proposed approach performs explicit multi-scale decomposition before attention-based fusion. Conventional channel or spatial attention methods tend to emphasize globally dominant responses, which may suppress subtle but semantically important details. In contrast, the multi-branch structure preserves heterogeneous feature responses at different scales, ensuring that detailed textures and global semantic structures are both retained prior to fusion. This property is especially beneficial for Haipai New Year paintings, which are characterized by complex compositions, dense decorative patterns, and significant variations in object scale. Dominant central figures often coexist with intricate ornamental details and symbolic motifs, all within a limited spatial region. By enabling independent modeling of such heterogeneous visual elements, the proposed multi-scale feature extraction strategy allows subsequent attention mechanisms to selectively emphasize informative features within each scale. As a result, the network achieves improved segmentation accuracy, enhanced boundary delineation, and better semantic consistency when handling richly decorated and visually complex Haipai New Year painting images.
3.2.2. Attention Enhancement
The concatenation operation merges the results along the channel dimension:
Generation of Spatial-Channel Mixed Weights:
Adjusting feature distribution:
Generating spatial-channel mixed attention weights:
Applying the attention weights to the original input:
Attention enhancement is performed after feature concatenation along the channel dimension, which integrates multi-scale representations into a unified feature space while preserving complementary information from different branches. Instead of directly applying attention to each branch independently, this design enables holistic feature interaction across scales, allowing global context and local details to be jointly considered. Subsequently, channel-wise weighting is applied using the Squeeze-and-Excitation module, as illustrated in Figure 2. The SE mechanism adaptively recalibrates channel responses through global pooling and nonlinear transformation, guiding the network to emphasize informative channels and suppress redundant or noisy features.
Compared with traditional attention mechanisms that focus solely on either channel or spatial dimensions, the proposed strategy generates spatial–channel mixed attention weights, enabling joint modeling of “where” and “what” to emphasize. Conventional channel attention may overlook spatial distribution, while pure spatial attention may fail to capture inter-channel dependencies. By adjusting the feature distribution through mixed attention weight generation, the model achieves more precise feature selection and stronger semantic consistency. The generated attention weights are then applied to the original input features, allowing important visual patterns to be selectively enhanced without disrupting the underlying structural information.
This attention enhancement strategy is particularly advantageous for Haipai New Year paintings. These artworks typically contain visually crowded scenes with overlapping elements, rich color symbolism, and intricate decorative textures. The spatial–channel mixed attention mechanism enables the model to focus on semantically meaningful regions, such as figures and symbolic motifs, while simultaneously adapting to culturally significant color and texture cues. As a result, the proposed design improves robustness to visual complexity, enhances boundary localization, and preserves fine artistic details, making it well suited for accurate segmentation of Haipai New Year painting images.
3.3. Convolutional Block Attention Module
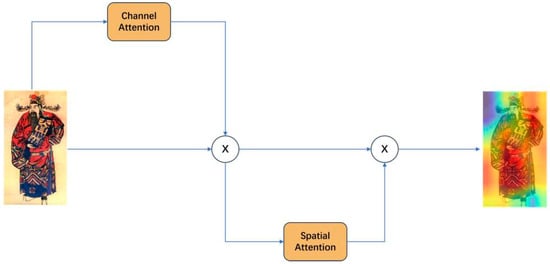
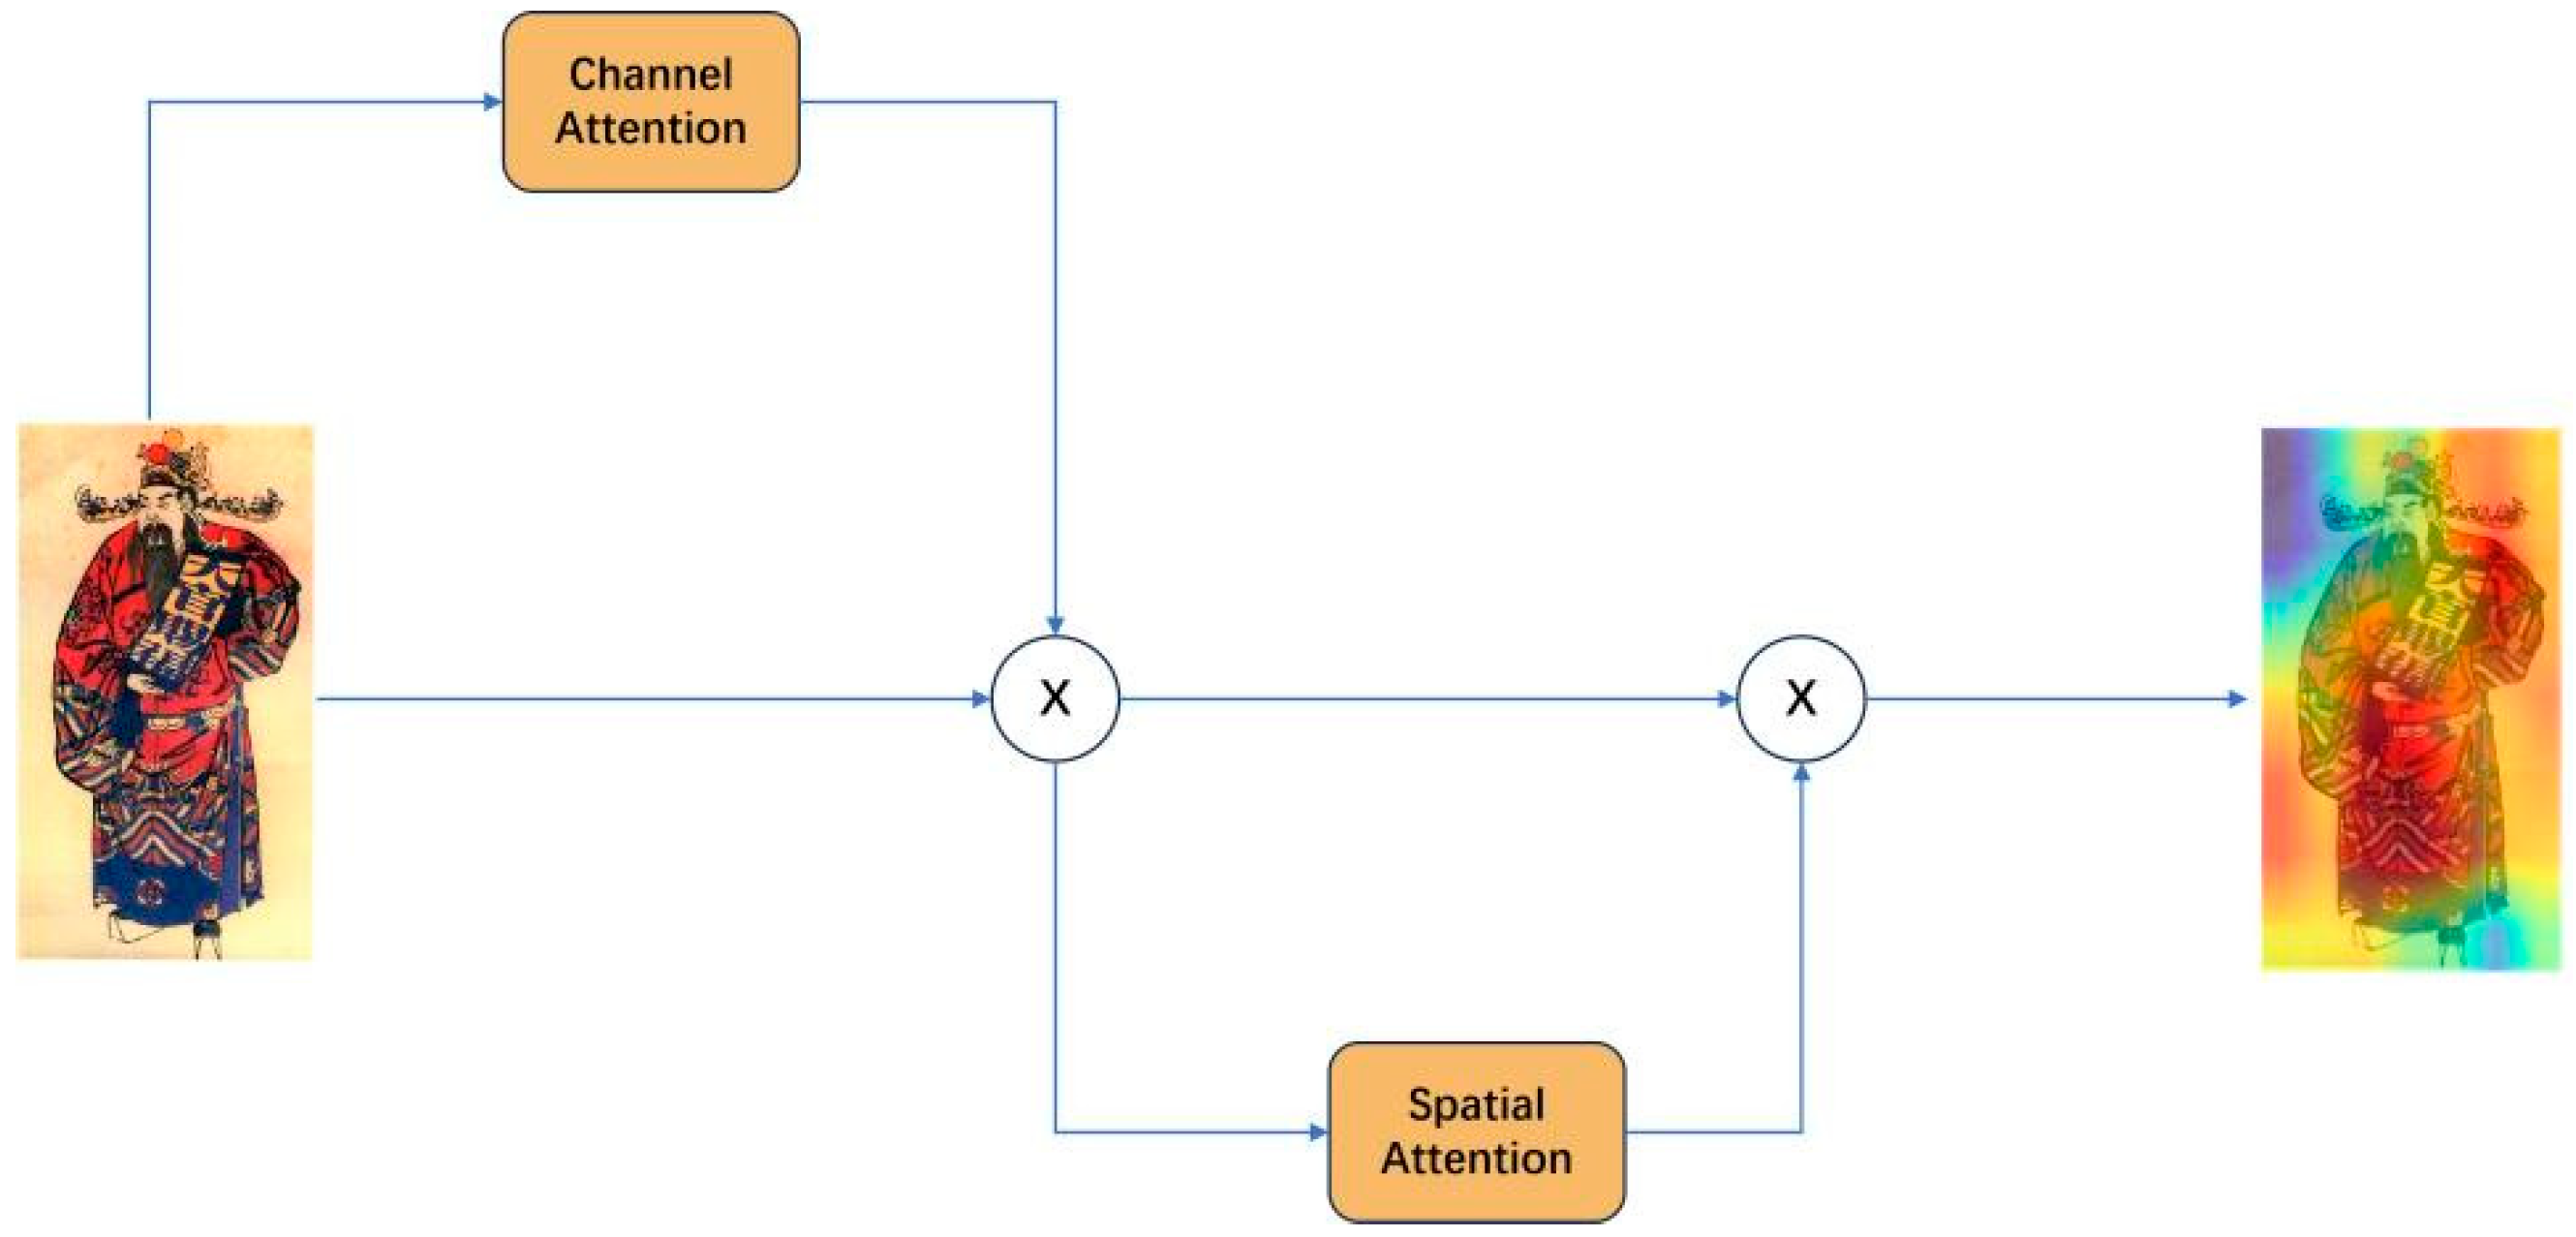
Convolutional Block Attention Module (CBAM) is a lightweight yet effective dual-attention mechanism that sequentially integrates channel attention and spatial attention to refine feature representations. Its core idea is to adaptively emphasize informative features while suppressing irrelevant responses by modeling inter-channel relationships and spatial dependencies. The overall architecture of CBAM is illustrated in Figure 4. This attention mechanism is particularly suitable for visually complex artistic images, such as Haipai New Year paintings, which often contain dense symbolic elements, rich decorative textures, and strong color contrasts within limited spatial regions.
Figure 4.
Architecture of CBAM.
3.3.1. Attention Enhancement
For the input features, global average pooling (GAP) and global max pooling (GMP) are first performed in parallel [28], generating channel descriptor vectors respectively:
GAP captures the overall statistical distribution of feature responses and reflects the global color and texture composition of the image, while GMP emphasizes the most salient activations corresponding to visually dominant elements such as main figures or symbolic motifs. This dual-pooling strategy is well aligned with the characteristics of Haipai New Year paintings, where important semantic elements coexist with richly decorated backgrounds.
The two descriptors are then processed by a shared-parameter multi-layer perceptron with dimensionality reduction and expansion, and their outputs are summed and passed through a Sigmoid function to generate channel attention weights:
Finally, channel-wise weighting is applied:
Through this process, channel attention adaptively enhances channels associated with culturally significant colors, textures, and patterns, while suppressing redundant or less informative decorative details. This is particularly important for segmenting Haipai New Year paintings, as color usage often conveys symbolic meaning and plays a key role in distinguishing foreground elements from complex backgrounds.
3.3.2. Spatial Attention
For the feature maps after channel-wise weighting . First, average pooling and max pooling are performed along the channel dimension [29], generating two spatial feature maps and .
The average-pooled map captures global spatial context, which helps preserve the overall layout and composition of the painting, while the max-pooled map highlights prominent local structures such as edges, line drawings, and contour intersections.
The two feature maps are concatenated and passed through a standard convolution to generate spatial attention weights :
Finally, spatial weighting is applied:
This spatial attention mechanism is particularly effective for Haipai New Year paintings, where multiple visual elements often overlap and boundaries between objects are formed by fine ornamental lines rather than clear photographic edges. By selectively enhancing semantically meaningful regions and suppressing irrelevant background areas, spatial attention improves boundary delineation and reduces confusion between adjacent decorative elements.
4. Experiments
4.1. Experimental Setup and Evaluation Metrics
The experimental environment in this study is built using the deep learning framework PyTorch 12.1 combined with the Python programming language. The computer configuration is as follows: the operating system is Ubuntu 20.04, with 32 GB of system memory, an Intel(R) Xeon(R) Platinum 8255C CPU running at 2.50 GHz, and an NVIDIA GeForce RTX 3090 GPU with 24 GB of video memory. The experiments utilize the Adam optimizer with an initial learning rate of 1 × 10⁻⁴, which is dynamically adjusted based on the batch size.
The evaluation metrics used in this study include Mean Intersection over Union (mIoU), Mean Pixel Accuracy (MPA), and Overall Accuracy (Accuracy), which comprehensively assess the model from three perspectives: regional overlap, class discrimination accuracy, and overall prediction correctness. In image segmentation tasks, the segmented samples can be divided into three categories: true positives (TP), which represent correctly classified positive samples; false positives (FP), which are negative samples incorrectly classified as positive; and false negatives (FN), which are positive samples incorrectly classified as negative [30].
Given the inherent category imbalance within the Haipai New Year painting dataset—stemming from its traditional focus on human figures—mean Intersection over Union (mIoU) and mean Pixel Accuracy (mPA) are prioritized as the primary evaluation metrics. These metrics provide a more robust and objective assessment of segmentation performance across diverse scales and frequencies. While overall Accuracy is recorded, it serves only as a supplementary reference and is not the primary basis for evaluating the model’s effectiveness.
Here, k denotes the total number of classes. The formulas for the three evaluation metrics are as follows:
4.2. Dataset Building and Preprocessing
In this study, we built a custom dataset featuring Haipai New Year painting images. The goal is to accurately segment different visual elements found in these traditional artworks. The dataset construction process includes image selection, annotation, and label format conversion.
Our fieldwork included on-site investigations at several key thematic exhibitions, such as “Huashuo Nianhua” (Storytelling through New Year Paintings) at the Shanghai Baoshan International Folk Art Expo (February 2024), “Yichuan Wanbang—The Sino-Western Culture in New Year Paintings” (December 2024), and “Shanghai’s New Year Flavor—The Inheritance and Development of a Century of Xiaojiaochang New Year Paintings” (January 2025). This meticulous selection process ensures that our dataset comprises samples reflecting the current scholarly and artistic consensus on the significance and value of New Year paintings. Furthermore, by drawing upon the authoritative collection of Haipai New Year paintings from the Shanghai Library and referencing the academic monograph “The Complete Collection of Chinese New Year Paintings: Shanghai Volume”, we further reinforced the classic status and systematic nature of our sample set.
We collected 376 images of Haipai New Year paintings. The Dataset is comprised of works from the late Qing to the early Republican period (c. mid-19th to early 20th century), the apogee of the Haipai New Year paintings. It is important to note that the temporal and geographical scope of the dataset is strictly defined by the historical existence of Haipai New Year paintings. This genre flourished specifically during the late Qing Dynasty and the early Republic of China (circa mid-19th to early 20th century), representing the final flourishing and modern transformation of Chinese woodblock New Year paintings. Consequently, the dataset covers the complete historical span of this art form. Extending the timeline further would result in the inclusion of non-Haipai styles or modern reproductions, which falls outside the scope of this specific heritage preservation study.
Geographically, Haipai paintings are distinct from other regional schools such as Suzhou Taohuawu or Tianjin Yangliuqing due to their unique Western-influenced perspective and urban themes. To preserve the stylistic integrity of the genre, we restricted the dataset to the Shanghai region while ensuring comprehensive thematic coverage by selecting works depicting various subjects, such as figures, opera scenes, and news events characteristic of that period. Thus, the dataset constitutes a representative archive of Haipai art and a valid benchmark for segmentation models tailored to complex artistic imagery.
To ensure the data was manageable and annotation was feasible, we filtered the images based on a specific rule: only images with fewer than five human figures were selected. This helped reduce annotation complexity and improve segmentation accuracy. After screening, 98 images met the criteria and were selected for our target dataset.
To ensure accuracy and cultural consistency in the annotations, the annotation process was carried out by a team of five researchers with backgrounds in art design and computer vision research. Before the formal labeling, four categories were defined: people, plants, animals, and objects. The marking process consists of two stages. In the first stage, the images are assigned to five annotators, and each New Year’s painting image is independently annotated by one annotator using the LabelMe 5.3.1 tool. To resolve ambiguity in complex elements and minimize subjectivity, a cross-validation mechanism was employed in the second phase, where labeled samples were exchanged among team members for review. Any discrepancies found during the validation phase are resolved through discussions or rulings with the authors to ensure a consensus is reached, ensuring that the authentic data of the Shanghai New Year paintings reflects both visual features and is semantically correct.
The images in this dataset retain their original resolutions, which are mostly 502 × 910 and 793 × 526 pixels, to ensure that the intricate details of the linework and textures that are characteristic of Haipai art are maintained. In the course of creating masks for this dataset, blank masks were used to match the original dimensions of the images. In order to accommodate this diverse range of dimensions and increase this dataset, a random cropping technique is used to produce 300 training images. This technique ensures that information is not lost due to the standardization of images to a smaller resolution.
In order to solve the problem of uneven data distribution while maintaining the integrity of the Haipai New Year painting art in the Shanghai schools, this study adopts a targeted data enhancement strategy. Due to the historical rarity of the art form and its creative tradition centered on people, there is a natural sample imbalance in the categories of “animals” and “object” in the raw data. To do this, we do not introduce composite images, but rather take advantage of the rich visual elements contained in high-resolution raw images and process them with standard data enhancement techniques such as Random Cropping and Rotation. This approach fully explores the local features in each painting, significantly increasing the model’s sensitivity to non-subject categories by focusing on smaller, less frequent instances. This ensures that the model can accurately identify the detailed elements in the picture, effectively avoiding misjudging them as backgrounds or directly ignoring them, thereby alleviating the category imbalance while preserving the artistic authenticity of the New Year paintings to the greatest extent.
However, deep learning models require a larger volume of data to generalize effectively. To address the limitation of the small dataset size and the class imbalance shown in Table 1 (where “Man” dominates at 53.52% and “Object” is only 7.18%), we applied data augmentation techniques. The original 98 images were processed using random rotation, horizontal flipping, and cropping. This strategy not only expanded the total dataset to 300 samples (270 for training, 30 for testing) but also allowed us to generate more cropped samples focusing on under-represented classes like “Animal” and “Object,” thereby mitigating the imbalance issue during training.
Table 1.
Dataset Statistics.
We used the LabelMe tool for annotation. Each image was manually labeled at the pixel level to mark different elements in the Haipai New Year paintings. Considering the diversity of elements, we defined four main categories to simplify the annotation: man (human figures), plant, animal, and object.
The dataset statistics are shown in Table 1. The rationale for segmenting Haipai New Year paintings into four primary categories “man, plant, animal, and object” is grounded in a comprehensive assessment of the art form’s cultural essence, its semantic structure, and the practical demands of the task. Artistically, they are semantically distinct, reflecting their unique roles in the composition. Technically, their distinct visual profiles regarding form, texture, and palette facilitate robust feature discrimination by the model. This approach strategically avoids the prohibitive complexity of overly granular labeling, ensuring both annotation quality and feasibility. Thus, the proposed taxonomy strikes a balance between cultural representativeness, visual discriminability, and practical efficiency.
In LabelMe, each target area was carefully marked by hand to ensure accurate boundaries. Each category was assigned a unique color, making it easier to visualize the segmentation labels. After annotation, each image generated a corresponding JSON file. These files stored the coordinates and category labels of all annotated regions.
Since deep learning models typically require label data in the form of masks, we wrote a Python (https://www.python.org/) script to convert the LabelMe JSON files into mask images. The conversion process followed these steps:
- Parse the JSON file and extract the polygon coordinates of each labeled area;
- Create a blank mask image with the same size as the original image;
- Fill the annotated regions with different colors based on their category, making the labels visually identifiable;
- Save the final mask image in PNG format for model training.
Through this workflow, we successfully created a high-quality dataset of Haipai New Year paintings. It consists of 300 original images along with their corresponding segmentation masks. This dataset provides a solid foundation for training the U-Net model and contributes to the underexplored field of segmenting elements in traditional New Year artwork.
4.3. Loss Function
In this work, a hybrid loss function is employed, combining Cross-Entropy Loss, Dice Loss, and Focal Loss. The formulation is as follows, where NNN denotes the total number of pixels (i.e., H × WH\times WH × W), and CCC represents the number of classes.
indicating whether the true label of the i-th pixel belongs to class c, representing the probability that the model predicts the iii-th pixel belongs to class c:
The Cross-Entropy Loss (with default weights) is defined as:
Dice Loss (with adjustable weight, defaulting to 1):
General form for multi-class segmentation, including a smoothing term .
Focal Loss The weight can be adjustable, with a default value of 1:
γ is the focusing parameter, is the class weight.
4.4. Comparative Analysis of Segmentation
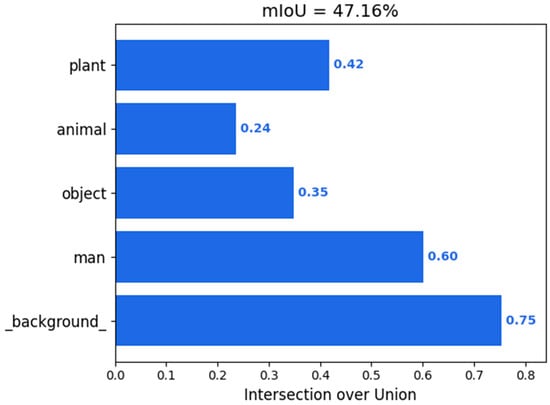
The class-wise evaluation shows clear performance differences among elements in Haipai New Year paintings. The IoU values of each category are shown in Figure 5. The background achieves the highest IoU (75.41%) due to its uniform texture and large spatial coverage, while the “man” category also performs well (60.10%), reflecting stable learning of dominant human structures. In contrast, the “animal” (23.64%) and “object” (34.89%) categories yield lower IoU values, as these elements are typically small, highly stylized, and embedded within dense decorative patterns with ambiguous boundaries. Failure cases mainly occur in images with heavy ornamentation or overlapping symbolic motifs, where fine details are missed or partially segmented. Highly abstract artistic forms and rare stylistic variations further limit generalization. Therefore, the segmentation results should be treated as analytical references, and future work should focus on expanding culturally diverse datasets and enhancing scale-sensitive feature learning.
Figure 5.
Intersection over Union.
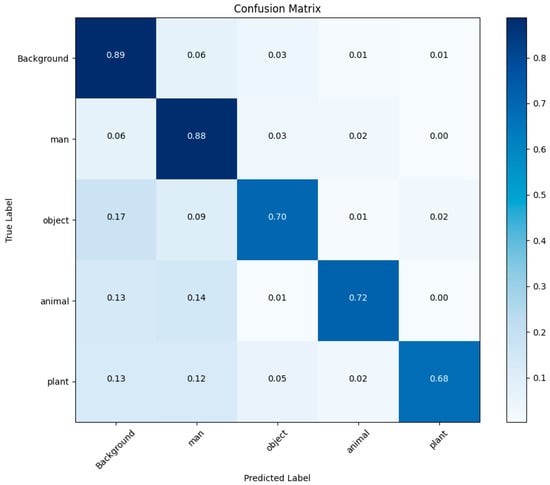
The normalized confusion matrix in Figure 6 illustrates the class-wise prediction performance of the proposed model. The background and man categories achieve the highest recognition accuracy, with diagonal values of 0.89 and 0.88, respectively, indicating reliable discrimination of dominant classes. The object, animal, and plant categories exhibit relatively lower accuracies (0.70, 0.72, and 0.68), mainly due to confusion with the background and man classes. In particular, object samples are frequently misclassified as background (0.17), while animal samples show notable confusion with both background (0.13) and man (0.14). Overall, most misclassifications occur between visually similar or spatially adjacent categories, whereas clear diagonal dominance across all classes demonstrates the robustness of the proposed method.
Figure 6.
Confusion Matrix.
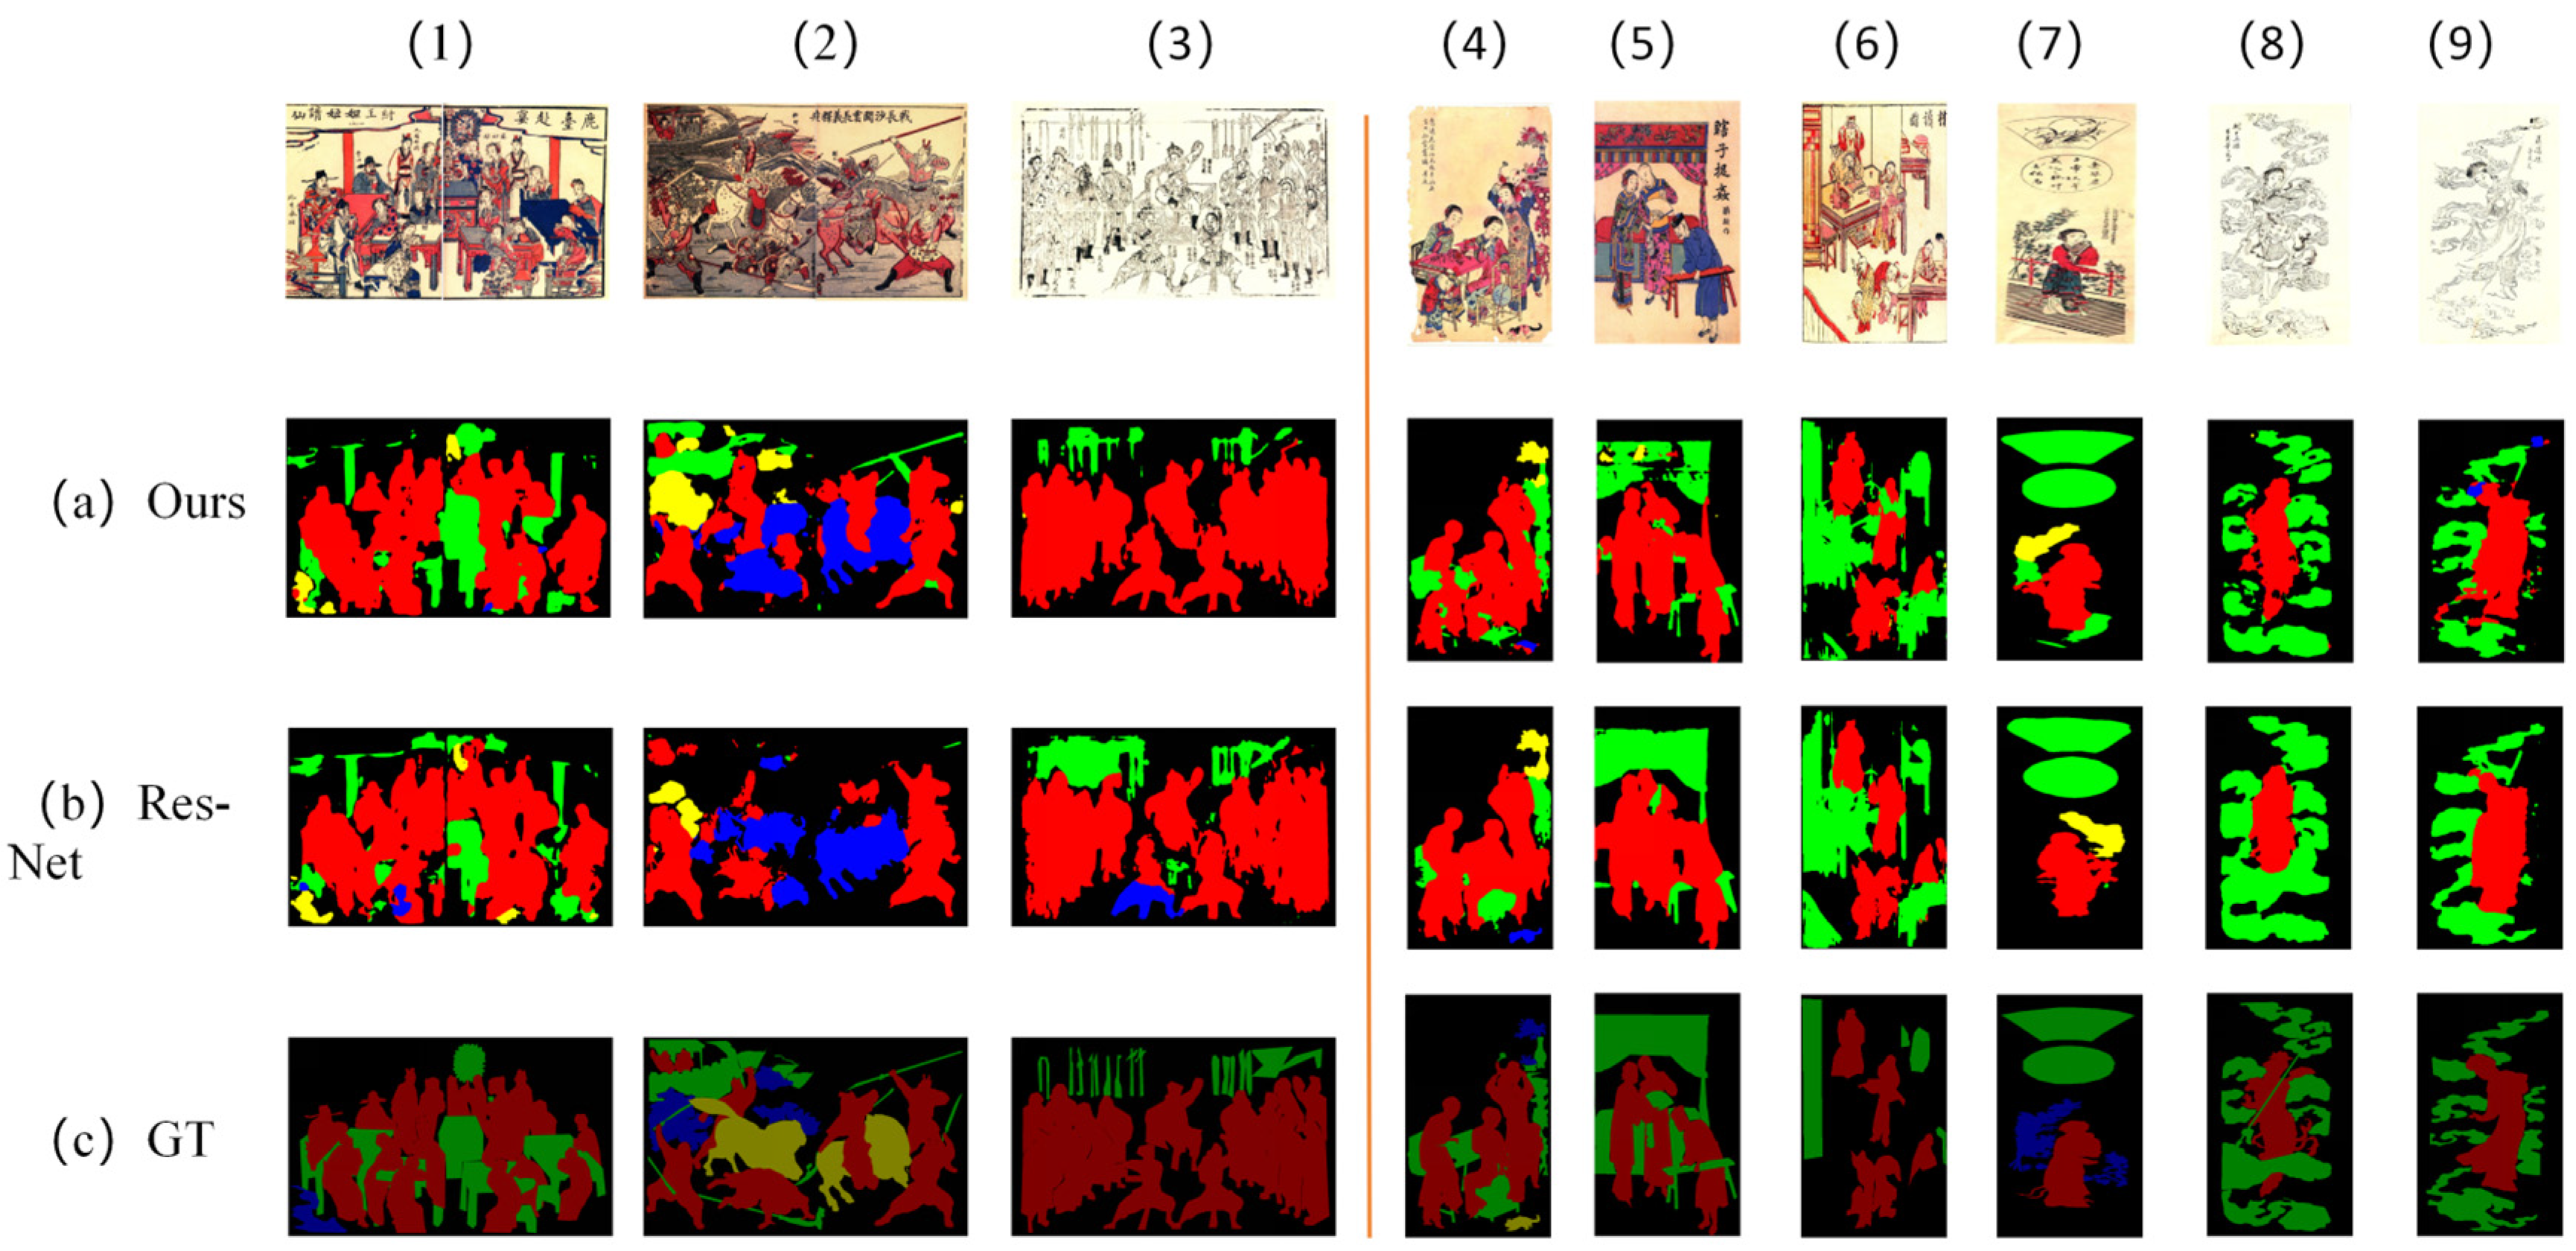
In the comparative experiments with other algorithms, as shown in Figure 5, case (1), ResNet produced incorrect segmentation results, whereas our method achieved more accurate segmentation of the image. In case (2), ResNet’s segmentation results were sparse, losing many details and deviating significantly from the ground truth (GT). In case (3), ResNet incorrectly over-segmented details, while our method closely resembled the GT, accurately restoring the details. Similarly, in case (4), ResNet exhibited erroneous segmentation of details, with considerable differences from the GT.
To make a comprehensive and targeted evaluation, the widely used and basic U-Net structure in the task of semantic segmentation was considered as a comparative baseline. As shown in Table 2, although the U-Net structure obtained an mIoU of 42.52% and Accuracy of 73.05%, it is still not satisfactory compared to the proposed PSE-Net. The main reason for this is the deficiency of the conventional encoder–decoder structure in effectively capturing the “multi-scale semantic features” and “dense ornamental details” in the images of Haipai New Year paintings. In the proposed framework, the PSE module is designed to improve the fusion of multi-scale features.
Table 2.
Comparison of Segmentation Performance Among Different Models.
The impact of maintaining these original resolutions varies across different semantic categories. For dominant elements like “Man” (60.10% IoU), the high resolution provides stable “structural features” and sufficient global context for accurate recognition. However, for “Animal” (23.64% IoU) and “Object” (34.89% IoU) categories, resolution is even more critical because these elements are typically small and “deeply embedded within dense decorative patterns”. The “pixel-level ambiguity” caused by “overlapping symbolic motifs” makes these regions particularly difficult to segment. PSE-Net addresses these challenges by utilizing its “Pyramid Scale Expansion” strategy to integrate multi-scale features, thereby preserving the integrity of “ornamental boundaries” that might otherwise be lost in complex, high-density textures.
Quantitative error analysis using the confusion matrix in Figure 6 also points to specific challenges in the segmentation process for the complex artistic elements. Although high recognition accuracies of 0.89 and 0.88 are reported for “Background” and “Man” classes, respectively, significant confusion is observed in the smaller classes. For instance, 17% of the “Object” class instances are confused with “Background”, whereas “Animal” instances show significant confusion not only with “Man” (14%) but also “Background” (13%). All the above errors are intrinsically related to the visual characteristics of Haipai-style artworks. In fact, “Object” and “Animal” elements in the artwork are “typically small-scale” and deeply embedded within dense decorative patterns.” Moreover, the boundaries in the artwork are often defined by fine ornamental strokes rather than clear edges, which in turn leads to “pixel-level ambiguity” in the visually crowded areas where symbolic elements overlap. In order to address the specific failure modes in the segmentation process, future research will aim to utilize stronger edge-detection priors as well as investigate the use of Transformer-based architectures in the context of the segmentation task.
In summary, based on the visual results from these experiments, our proposed method, PSE-Net, more effectively extracts decorative patterns from the traditional Haipai New Year painting images. To further provide an intuitive comparison of the network models, the best-performing model from each network—defined as the one with the lowest loss value—was evaluated on the test set, and the corresponding experimental metrics were calculated. Through quantitative data analysis, the generalization ability of each algorithm was assessed. The evaluation results are presented in Table 2, and the corresponding qualitative visualization results are shown in Figure 7.
Figure 7.
(a) The number of people exceeds five. (b) The number of people is less than five. (c) GT.
The quantitative results in Table 2 show that PSE-Net achieved a Mean Intersection over Union (mIoU) of 47.16%, a 2.52% improvement over the ResNet baseline. A detailed class-wise analysis reveals distinct performance differences:
Background (Highest Performance): Achieved the highest IoU (75.41%) due to its relatively uniform texture and large spatial coverage.
Man (Good Performance): The “Man” category achieved a solid IoU of 60.10%. Human figures are the most dominant subjects, providing ample training data, and possess stable structural features.
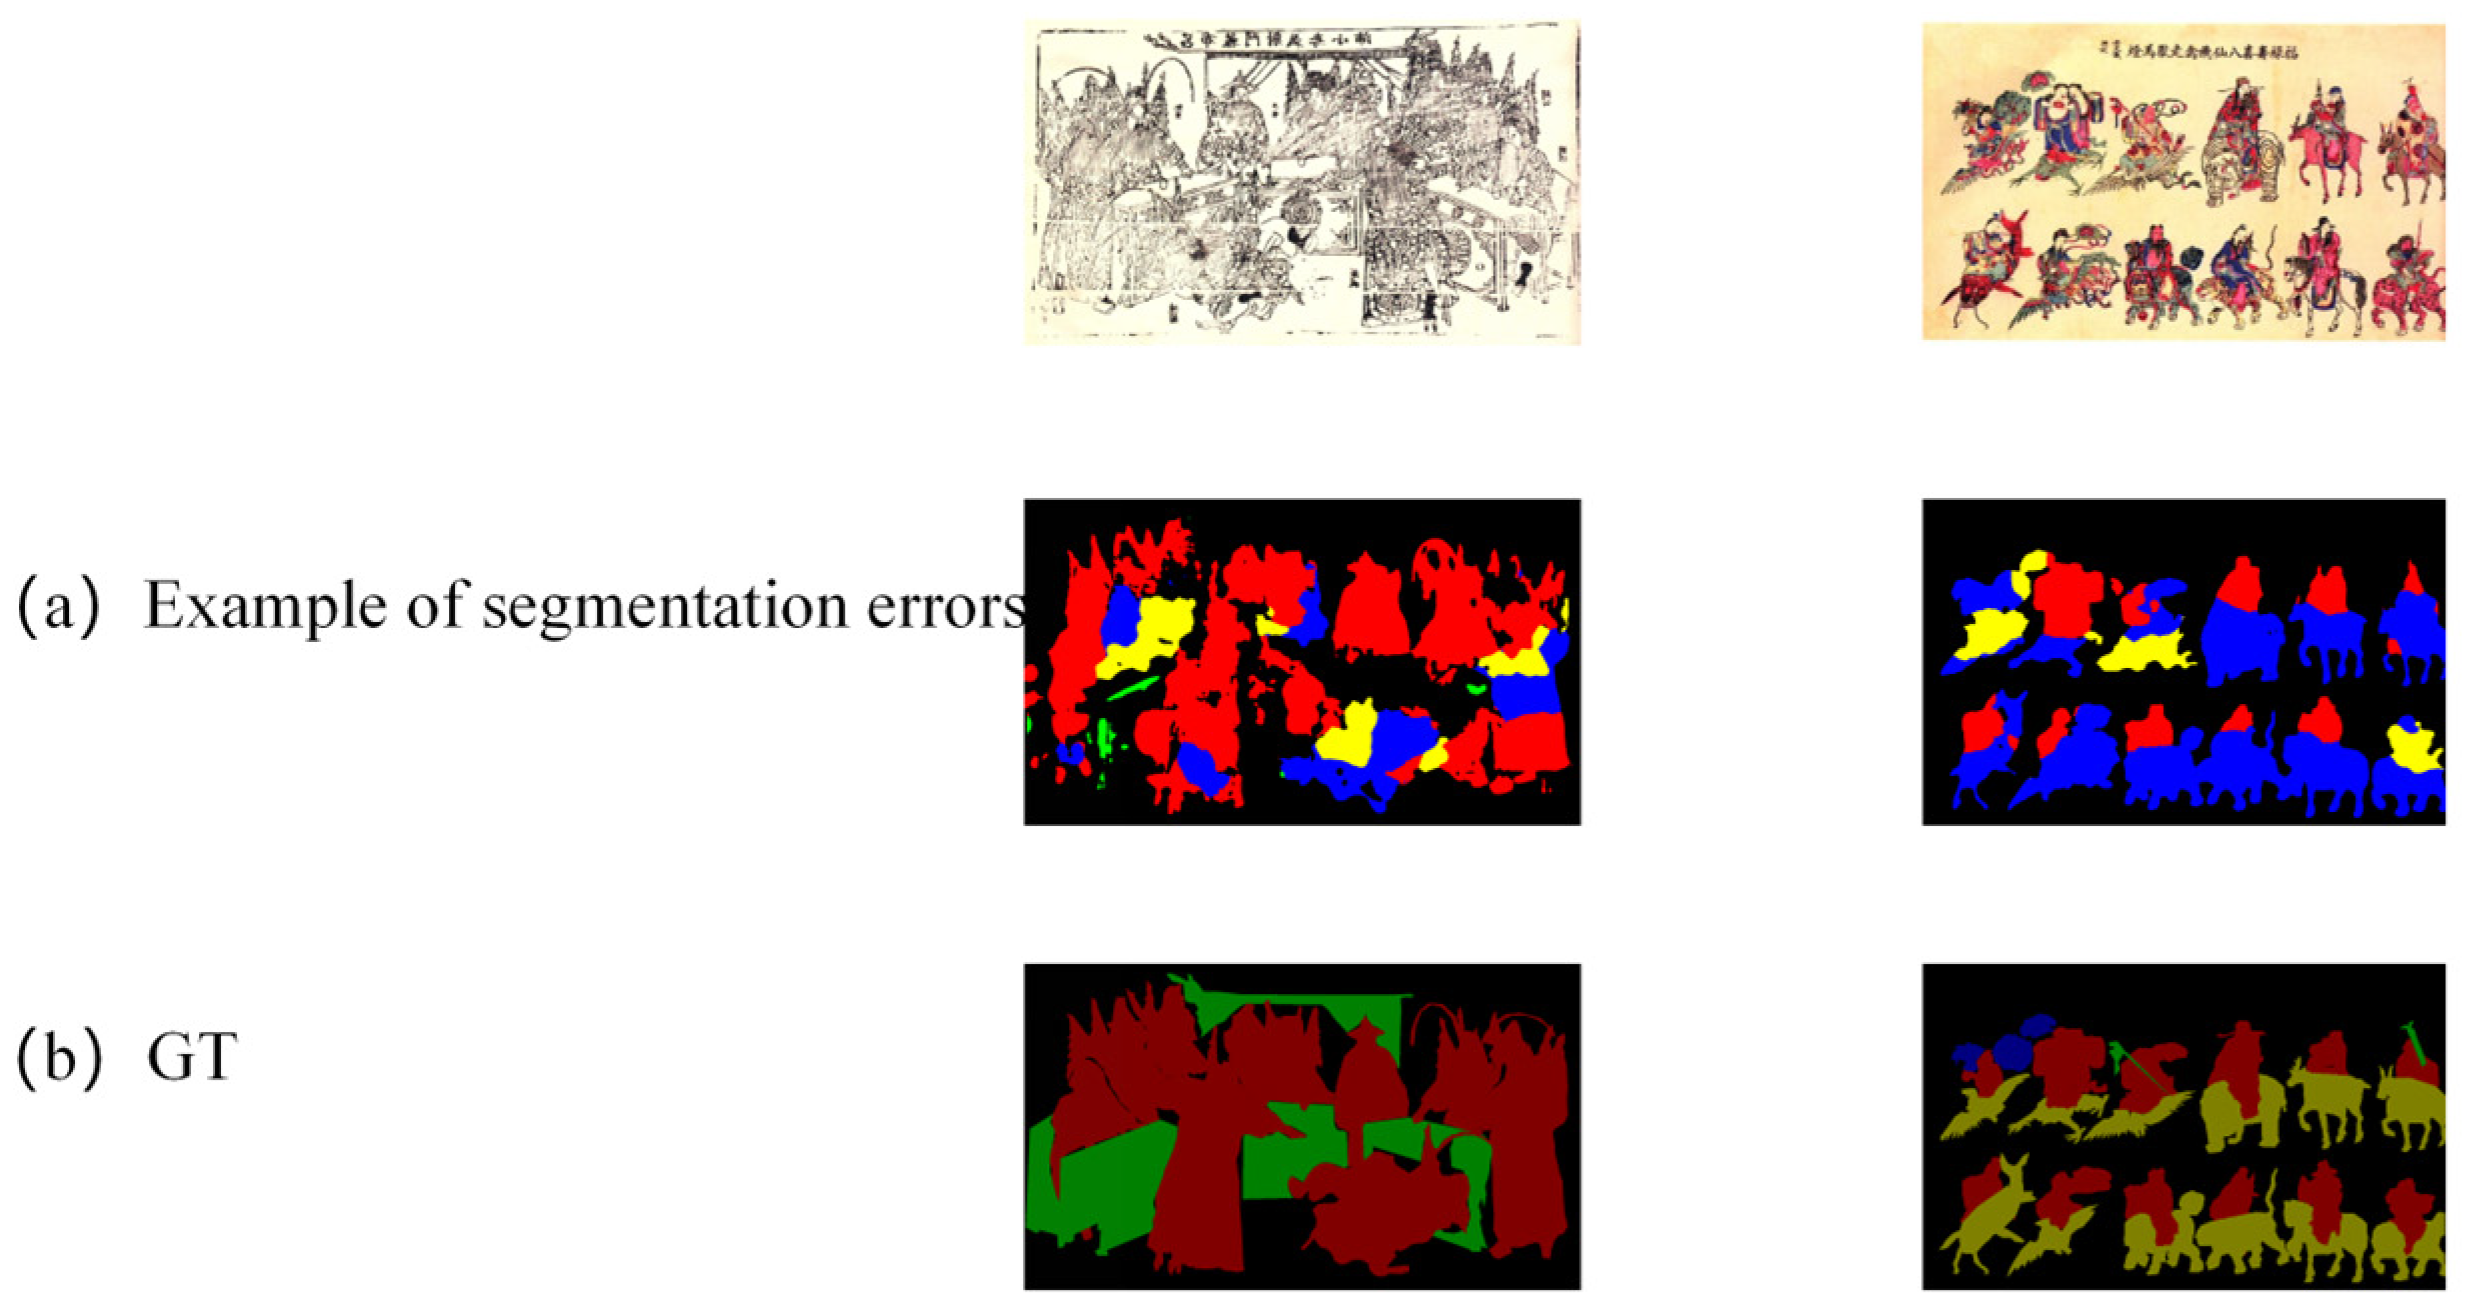
In Figure 8, some examples of the segmentation process anomaly for the New Year painting images are shown. The first row shows the original images, the second row presents the incorrect segmentation results produced by our model, and the third row shows the ground truth segmentation results. In the wrong segmentation results, some typical anomaly examples can be found, such as boundary anomaly, region anomaly, and segmentation anomaly. The reasons for the anomaly are the complex texture, many color patterns, and ambiguous boundaries in the New Year painting images.
Figure 8.
Visualization of segmentation anomalies.
Failure Case Analysis: Despite the improvements, failure cases still occur, primarily in images with heavy ornamentation or overlapping symbolic motifs. For instance, when small “Objects” (like fans or weapons) overlap with purely decorative patterns on clothing, the model often struggles to distinguish the semantic boundary, resulting in partial segmentation or confusion with the “Man” class. Future work will focus on incorporating stronger edge-detection priors to resolve these ambiguities.
4.5. Ablation Study
As shown in Table 3, the ablation study systematically evaluates the differentiated contributions of each module in PSE-Net through multi metric comparisons. The complete model achieves the best performance across all core metrics, including global accuracy of 75.54%, mean pixel accuracy of 63.16%, and mean Intersection over Union of 47.16%, demonstrating the effectiveness of the collaborative module design for segmenting complex artistic images. When the channel attention module SE is removed, the mIoU decreases by 1.14% from 47.16% to 46.02%, indicating its important role in enhancing fine grained boundary segmentation. This effect is particularly relevant for New Year paintings, where object contours and decorative patterns are often defined by subtle color and texture variations. The SE module adaptively recalibrates channel responses, strengthening discriminative features associated with fine ornamental structures and stylized outlines.
Table 3.
Ablation Study.
The removal of the Convolutional Block Attention Module results in the most severe degradation in mean pixel accuracy, with a drop of 4.33% from 63.16% to 58.83%. This highlights the importance of joint spatial and channel attention for accurate pixel level localization. In Haipai New Year paintings, dense decorations and repetitive motifs create strong background interference. The spatial attention component of CBAM guides the network to focus on semantically meaningful regions, while channel attention suppresses irrelevant patterns, improving local consistency in segmentation results. Eliminating the Pyramid Scale Expansion PSE module leads to a clear decline across all evaluation metrics, with mIoU decreasing by 4.20% from 47.16% to 42.96%. This confirms the critical role of multi scale feature modeling in handling the large scale variation inherent in New Year paintings, where dominant figures, symbolic animals, and fine decorative elements coexist within the same image. Further analysis shows strong functional complementarity among the modules. When only the SE module is retained, the model exhibits noticeably reduced performance in complex scenes, with mean pixel accuracy of 58.83% and mIoU of 43.44%. This indicates that a single attention mechanism is insufficient to address both spatial localization and scale variation. By contrast, the complete model integrates channel recalibration, spatial sensitivity, and multi scale fusion, forming a feature representation framework that aligns well with the highly decorative, stylized, and multi scale characteristics of Haipai New Year paintings.
5. Discussion
To ensure that symbolic meaning and artistic integrity are preserved, an interdisciplinary approach was adopted throughout the research process. For instance, a classification hierarchy consisting of the “Man,” “Plant,” “Animal,” and “Object” categories was developed in consultation with art history experts to accurately reflect the traditional iconographic structures of Haipai art. Furthermore, the validation of segmentation results involved close collaboration between technical researchers and art experts, particularly when addressing complex scenarios characterized by significant “element adhesion” and “dense decoration.” By jointly analyzing whether the model-generated boundaries align with the inherent artistic logic of the paintings, a culturally responsible and semantically accurate outcome was ensured.
PSE-Net shows strong segmentation performance on Haipai New Year paintings. However, its limitations are closely related to the intrinsic characteristics of this art form. Haipai New Year Paintings feature stylized line work and symbolic abstraction. Visual elements often overlap. Object boundaries are formed by fine ornamental strokes rather than clear photographic edges. These factors introduce pixel-level ambiguity and increase segmentation difficulty in densely decorated regions. Limited annotated data further constrains the model’s generalization to rare stylistic variations.
Despite these challenges, PSE-Net provides practical value for cultural heritage practitioners. It enables efficient pixel-level separation of figures, objects, and decorative patterns. This supports digital archiving, restoration planning, and quantitative stylistic analysis in a non-invasive manner.
The architectural design of the PSE-Net has been specifically tailored to address the common visual problems in conventional artworks, such as Dunhuang murals and Miao embroidery, which also share common characteristics such as dense lines, large scale variations, and colorful styles with Haipai New Year paintings. For example, the “complex lines and blurred boundaries” in the murals resulting from historical degradation also share common characteristics with the intricate decorative lines in Haipai artworks, which also demand the precise preservation of the lines and the hierarchical feature extraction in the framework. In addition, the unique channel recalibration in the PSE component also has a special advantage in the case of embroidery artworks, where the distinction between the patterns in the foreground and the backgrounds often relies on the recalibration of the colors in the channels instead of the clear outlines in the photographs.
Although the framework has a high structural scalability in coping with different types of conventional art images, it should be further fine-tuned or transferred to adapt to the unique stylistic characteristics and historical differences in different types of cultural heritage artworks.
Ethical issues must also be considered. Automated segmentation may oversimplify artistic intent or symbolic meaning. Digital results should not be treated as authoritative reconstructions. They should serve as analytical references. Interpretation and validation should involve art historians and heritage practitioners to preserve the authenticity and cultural integrity of Haipai New Year paintings.
The practical utility of the PSE-Net extends beyond the scope of quantitative evaluation and encompasses a variety of cultural heritage applications in the real world. For example, the high-precision segmentation results provide the technical basis for the establishment of a structured digital database, which makes it possible to meet the needs of advanced archiving practices, such as the retrieval of all Haipai New Year paintings that include specific “animal” or “object” elements in the motifs—an essential aspect of modern museum practices and art history studies. In addition, in the context of virtual exhibitions and the development of interactive education tools, the segmentation of the elements of a painting makes it possible to digitally decompose the layers of the artwork. This allows the viewer to better understand the intricate compositional layers and artistic elements of Haipai New Year paintings that are not always easy to comprehend in their physical state.
6. Conclusions
With the growing emphasis on intangible cultural heritage preservation, this study addresses the challenges of complex composition, diverse styles, and blurred boundaries in traditional Chinese New Year paintings by proposing an image segmentation method based on PSE-Net that enables high precision analysis of artistic elements at the pixel scale. A dataset containing 376 representative Haipai New Year painting images from different regions and schools was constructed to support model training and evaluation. By introducing attention mechanisms and feature fusion across different spatial scales into PSE- Net, the proposed method achieves clear performance improvements over conventional ResNet architectures, with an mIoU of 47.16%, an mPA of 63.16%, and an overall accuracy of 75.54%, while ablation experiments confirm the complementary contribution of attention modules and pyramid structures to feature enhancement.
In addition, although this study mainly concentrates on deep learning-based segmentation methods, classical image segmentation methods such as thresholding, edge detection, and region growing can be valuable references. This is especially the case when the training data are scarce. In the future, it is possible that hybrid methods that combine classical image processing methods and deep learning methods will be further explored. The hybrid methods may be beneficial in improving the robustness and stability of the segmentation results. In addition, the hybrid methods may be beneficial in improving the interpretability of the deep learning-based segmentation results by incorporating structural and texture information.
As the first study to systematically apply semantic segmentation to the structural analysis of Haipai New Year paintings at fine spatial resolution, this work fills an important research gap and provides technical support for applications such as digital archiving, style quantification, automated restoration, and image enhancement, while also showing good scalability to other forms of traditional art imagery. However, the limited size of the dataset restricts the representation of regional and historical diversity, indicating that future research should expand data collection through collaboration with museums and cultural institutions, incorporate higher resolution and multimodal data, and explore semi-supervised or active learning strategies to reduce annotation costs. Further improvements may include combining Transformer architectures with convolutional networks to better model global contextual relationships, optimizing network structures for lightweight deployment, and extending the framework to restoration, stylistic analysis, and semantic interpretation tasks, while close collaboration with art historians and careful consideration of cultural authenticity and ethical impact remain essential for responsible digital processing of traditional art.
Author Contributions
Conceptualization, Y.Z. and J.Z.; methodology, Y.Z.; software, D.D.; validation, J.Z., J.L. and D.D.; formal analysis, Y.Z.; investigation, Y.Z.; resources, J.L.; data curation, Y.Z.; writing—original draft preparation, Y.Z.; writing—review and editing, J.L. and J.Z.; visualisation, Y.Z.; supervision, J.Z.; project administration, Y.Z.; funding acquisition, Y.Z. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The datasets generated and/or analyzed during the current study are available from the corresponding author on reasonable request.
Acknowledgments
The authors have reviewed and edited the output and take full responsibility for the content of this publication.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- UNESCO. Convention for the Safeguarding of the Intangible Cultural Heritage; UNESCO: Paris, France, 2003. [Google Scholar]
- Giaccardi, E. Heritage and Social Media: Understanding Heritage in a Participatory Culture; Routledge: London, UK, 2012. [Google Scholar]
- Duan, L. In search of the memory of the past: A brief account of Shanghai Xiaojiaochang New Year paintings. Southeast Cult. 2009, 3, 122–126. [Google Scholar]
- Zhao, W. From “different origins, same style” to “same image, different painting”: Exploring the evolution from Jiangnan Taohuawu New Year paintings to Shanghai Xiaojiaochang New Year paintings based on images of women and children. Art Obs. 2022, 11, 55–58. [Google Scholar]
- Zhang, W. From Taohuawu to Xiaojiaochang: The transfer and development of modern Suzhou New Year paintings in Shanghai. J. Suzhou Art Des. Technol. Inst. 2018, 1, 55–58. [Google Scholar]
- Yang, G. Urban customs in New Year paintings: An interpretation of the artistic characteristics of Shanghai Xiaojiaochang New Year paintings. Art Work 2018, 3, 96–98. [Google Scholar]
- Khan, N.A.; Shafi, S.M.; Ahangar, H. Digitization of cultural heritage: Global initiatives, opportunities and challenges. J. Cases Inf. Technol. 2018, 20, 1–16. [Google Scholar] [CrossRef] [Scilit]
- Sotirova, K.; Peneva, J.; Ivanov, S.; Doneva, R.; Dobreva, M. Digitization of cultural heritage—Standards, institutions, initiatives. In Access to Digital Cultural Heritage: Innovative Applications of Automated Metadata Generation; Paisii Hilendarski: Plovdiv, Bulgaria, 2012; pp. 23–68. [Google Scholar]
- Bohumelová, M.; Hvorecký, J. Digitized art promotes the cultural heritage. In Proceedings of the 13th International Conference on Emerging eLearning Technologies and Applications (ICETA), Stary Smokovec, Slovakia, 26–27 November 2015; pp. 1–5. [Google Scholar]
- Pandey, R.; Kumar, V. Exploring the impediments to digitization and digital preservation of cultural heritage resources: A selective review. Preserv. Digit. Technol. Cult. 2020, 49, 26–37. [Google Scholar] [CrossRef] [Scilit]
- Otsu, N. A threshold selection method from gray-level histograms. IEEE Trans. Syst. Man Cybern. 1979, 9, 62–66. [Google Scholar] [CrossRef] [Scilit]
- Canny, J. A computational approach to edge detection. IEEE Trans. Pattern Anal. Mach. Intell. 1986, 8, 679–698. [Google Scholar] [CrossRef] [Scilit]
- Vincent, L.; Soille, P. Watersheds in digital spaces: An efficient algorithm based on immersion simulations. IEEE Trans. Pattern Anal. Mach. Intell. 1991, 13, 583–598. [Google Scholar] [CrossRef] [Scilit]
- Long, J.; Shelhamer, E.; Darrell, T. Fully convolutional networks for semantic segmentation. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Boston, MA, USA, 7–12 June 2015; pp. 3431–3440. [Google Scholar]
- Ronneberger, O.; Fischer, P.; Brox, T. U-Net: Convolutional networks for biomedical image segmentation. In Proceedings of the MICCAI 2015, Munich, Germany, 5–9 October 2015; pp. 234–241. [Google Scholar]
- Chen, L.C.; Papandreou, G.; Schroff, F.; Adam, H. Rethinking atrous convolution for semantic image segmentation. arXiv 2017, arXiv:1706.05587. [Google Scholar] [CrossRef] [Scilit]
- He, K.; Gkioxari, G.; Dollár, P.; Girshick, R. Mask R-CNN. In Proceedings of the ICCV 2017, Venice, Italy, 22–29 October 2017; pp. 2961–2969. [Google Scholar]
- Liu, Z.; Lin, Y.; Cao, Y.; Hu, H.; Wei, Y.; Zhang, Z.; Lin, S.; Guo, B. Swin transformer: Hierarchical vision transformer using shifted windows. In Proceedings of the ICCV 2021, Montreal, QC, Canada, 10–17 October 2021; pp. 10012–10022. [Google Scholar]
- Khan, S.; Naseer, M.; Hayat, M.; Zamir, S.W.; Khan, F.S.; Shah, M. Transformers in vision: A survey. ACM Comput. Surv. 2022, 54, 1–41. [Google Scholar] [CrossRef] [Scilit]
- Touvron, H.; Cord, M.; Jégou, H. DeiT III: Revenge of the ViT. In Proceedings of the ECCV 2022, Tel Aviv, Israel, 23–27 October 2022. [Google Scholar]
- Dai, Z.; Liu, H.; Le, Q.V.; Tan, M. CoAtNet: Marrying convolution and attention for all data sizes. In Advances in Neural Information Processing Systems (NeurIPS 2021); Curran Associates, Inc.: Red Hook, NY, USA, 2021; pp. 3965–3977. [Google Scholar]
- Zhou, B.; Khosla, A.; Lapedriza, A.; Oliva, A.; Torralba, A. Learning deep features for discriminative localization. In Proceedings of the CVPR 2016, Las Vegas, NV, USA, 27–30 June 2016; pp. 2921–2929. [Google Scholar]
- Finn, C.; Abbeel, P.; Levine, S. Model-agnostic meta-learning for fast adaptation of deep networks. In Proceedings of the ICML 2017, Sydney, Australia, 6–11 August 2017; pp. 1126–1135. [Google Scholar]
- Howard, A.G.; Zhu, M.; Chen, B.; Kalenichenko, D.; Wang, W.; Weyand, T.; Andreetto, M.; Adam, H. MobileNets: Efficient convolutional neural networks for mobile vision applications. arXiv 2017, arXiv:1704.04861. [Google Scholar] [CrossRef] [Scilit]
- Sandler, M.; Howard, A.; Zhu, M.; Zhmoginov, A.; Chen, L.C. MobileNetV2: Inverted residuals and linear bottlenecks. In Proceedings of the CVPR 2018, Salt Lake City, UT, USA, 18–23 June 2018. [Google Scholar]
- Zoph, B.; Le, Q.V. Neural architecture search with reinforcement learning. arXiv 2016, arXiv:1611.01578. [Google Scholar]
- Radford, A.; Kim, J.W.; Hallacy, C.; Ramesh, A.; Goh, G.; Agarwal, S.; Sastry, G.; Askell, A.; Mishkin, P.; Clark, J.; et al. Learning transferable visual models from natural language supervision. In Proceedings of the ICML 2021, Virtual Event, 18–24 July 2021; pp. 8748–8763. [Google Scholar]
- Zhang, P.; Xu, Q. A study on lung nodule segmentation based on mixed attention mechanism of multiple sensory fields and grouping. J. Guangxi Norm. Univ. (Nat. Sci. Ed.) 2022, 40, 76–87. [Google Scholar] [CrossRef]
- Du, X.; Ma, Z.; Qiu, S.; Lu, Y. Motor imagery EEG signal recognition based on convolutional attention mechanism. Comput. Eng. Appl. 2021, 57, 181–185. [Google Scholar]
- Zhang, B.; Huang, C.; Wang, Q.; Wan, L.; Zhou, L. Research on segmentation of Miao costume patterns based on RSKP-UNet model. Silk 2022, 59, 119–125. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.