


Abstract
Deep-sea polymetallic nodules are vital strategic mineral resources. However, residual low-contrast features from complex seabed conditions, densely overlapped targets and severe seabed clutter greatly degrade the accuracy and real-time performance of automatic segmentation. This paper proposes a lightweight instance segmentation model, PWC-YOLO. Firstly, a partial convolution-based C3k2-PConv module is constructed to reduce computational cost. Secondly, Wavelet Statistical Cross-Attention (WSCA) replaces the built-in self-attention of C2PSA to suppress underwater noise and enhance the feature expression of tiny nodules. Thirdly, Converse2D reverse convolution upsampling recovers lost contour details of nodules. A manually annotated dataset of Clarion–Clipperton Zone nodules is established for evaluation. Ablation experiments validate that the PWC-YOLO model reaches 95.2% BBox mAP50 and 95.8% Mask mAP50, with only 2.47 M parameters and 9.3 GFLOPs at an inference speed of 88 FPS. Comparative experiments indicate that PWC-YOLO achieves competitive mask segmentation accuracy with fewer parameters and lower computational overhead, yielding a favorable accuracy–complexity trade-off against mainstream segmentation models. Visual results verify favorable robustness within the tested deep-sea scenes, showing favorable lightweight properties with only 2.47 M parameters and 9.3 GFLOPs, which provides potential prerequisites for future lightweight deployment on underwater edge computing devices.
1. Introduction
With the rapid advancement of global low-carbon energy transition and the sustained expansion of advanced manufacturing industries, the demand for critical mineral resources such as manganese, nickel, copper, cobalt and rare earth elements has shown a continuous and rigid growth trend. At the same time, the shortage and uneven distribution of terrestrial mineral resources have become increasingly prominent, which has seriously restricted the sustainable development of strategic emerging industries. In this context, deep-sea mineral resources, as an important strategic alternative to land-based minerals, have gradually become a key area of competition for marine scientific research and resource development in various countries.
Polymetallic nodules, rich in Mn, Ni, Cu, Co, and rare earth elements, are among the most economically valuable seafloor mineral resources [1]. As one of the most representative deep-sea mineral resources, they are widely distributed in abyssal plains of the global ocean, and their large reserves and potential for development make them core resources for supporting future clean energy supply chains and high-end manufacturing systems.
The Clarion–Clipperton Zone (CCZ) is the most representative and resource-rich area of polymetallic nodules worldwide, with huge reserves and great exploration significance [2,3]. It has the characteristics of high nodule abundance, a large coverage rate and a high metal grade. However, the deep-sea environment of 3500–6000 m water depth, weak illumination, and low contrast brings severe challenges to fine detection and quantitative analysis [4]. Deep-sea optical imaging suffers from light absorption and scattering effects under different seawater optical properties, which induce illumination attenuation and image quality degradation [5]. Traditional detection methods are difficult to meet the requirements of large-scale, high-efficiency and high-precision resource investigation.
In recent years, near-seabed optical imaging has become the main method for high-resolution investigation of nodules. Nevertheless, traditional manual interpretation is inefficient, and existing deep learning methods are difficult to cope with dense, small, overlapping nodules and low-quality images [6,7]. Optical images can intuitively reflect the shape, size, distribution and coverage of nodules, providing a reliable data basis for quantitative resource evaluation. Nevertheless, the traditional manual visual interpretation method has low efficiency, high subjectivity, poor consistency and high labor cost, which cannot adapt to the processing needs of massive near-seabed image data.
Instance segmentation can realize individual separation, quantity statistics, and contour extraction of nodules, which is critical for accurate resource evaluation. As the latest one-stage instance segmentation model, YOLOv11 has obvious advantages in speed and accuracy. Therefore, this study carries out instance segmentation of CCZ polymetallic nodules based on YOLOv11.
The main contributions are as follows:
- (1)
- Aiming at dense and overlapping nodules, the lightweight C3k2-PConv module based on partial convolution is proposed to enhance instance discrimination ability. We reconstruct the original C3k2 bottleneck structure with PConv to cut redundant channel computation, which reduces model parameters while retaining multi-scale feature extraction capacity for crowded, adhesion-prone polymetallic nodules, alleviating target feature loss caused by network lightweight compression.
- (2)
- To address residual low-contrast characteristics and seabed clutter existing after standard image preprocessing, Wavelet Statistical Cross-Attention (WSCA) is designed to improve feature representation. WSCA replaces the native self-attention inside the C2PSA block of YOLOv11-n, significantly boosting the feature response of tiny, low-brightness nodules.
- (3)
- Converse2D reverse convolution upsampling is adopted to balance accuracy, lightweight, and real-time performance. This module substitutes nearest interpolation in the neck network to recover lost nodule edge details, satisfying the computing limits of underwater edge equipment such as deep-sea detection robots.
2. Related Work
2.1. Deep-Sea Polymetallic Nodule Exploration and Image Analysis
Polymetallic nodules are strategic mineral resources widely distributed in abyssal plains. Traditional exploration methods mainly include acoustic detection, sediment sampling, and manual interpretation, which are inefficient and have difficultly meeting the needs of large-scale detection [4,6].
With the development of optical observation systems, high-resolution seafloor images have become the key data for nodule identification and coverage estimation [7,8]. Early automated analysis adopted traditional image processing methods such as morphological operations and template matching, but these methods are sensitive to illumination and noise and lack robustness [9,10,11]. When the scene is complex, the segmentation effect is unstable, and it is impossible to effectively identify small, overlapping and semi-buried nodules.
To improve data quality, researchers established standardized preprocessing workflows including scale calibration and illumination normalization and constructed analysis-ready datasets, which laid a foundation for deep learning-based research. In addition, hyperspectral imaging technology has also been applied to the identification of small nodules and semi-buried nodules [12,13].
2.2. Deep Learning-Based Nodule Detection and Segmentation
Deep learning has become the mainstream method for nodule image analysis. In object detection, researchers improved YOLO-series models by adding attention mechanisms and multi-scale fusion to enhance detection performance [14]. Aiming at the characteristics of small targets and dense distribution of nodules, these improvements enhance the model’s ability to detect small nodules and overlapping nodules and improve the accuracy and recall rate of detection.
In segmentation tasks, most studies focus on semantic segmentation based on U-Net and its variants to extract nodule regions and calculate coverage but cannot separate individual nodules in dense distribution [15,16,17,18]. Therefore, it cannot complete the key steps of single nodule counting, size measurement and morphological parameter extraction, which limits the accuracy of resource quantitative evaluation.
To reduce labeling costs, unsupervised and semi-supervised learning methods have been introduced for deep-sea nodule segmentation to reduce dependence on labeled samples [19]. For underwater deployment, lightweight modules and attention mechanisms are widely used to balance accuracy and speed [20,21,22]. These methods reduce the dependence on a large number of labeled samples and improve the generalization ability of the model in small sample scenarios.
In recent years, diffusion models, ensemble learning, and transfer learning have further improved the accuracy of nodule assessment, but instance segmentation for dense and small nodules is still insufficient [23,24]. In addition, deep learning-based underwater segmentation methods have also been widely studied in marine visual tasks [25]. However, most models are designed for conventional scenes and lack targeted design for the extreme characteristics of the deep-sea environment; the balance between accuracy, lightweight and real-time performance still needs to be improved.
3. Methodology
3.1. Overview of PWC-YOLO Architecture
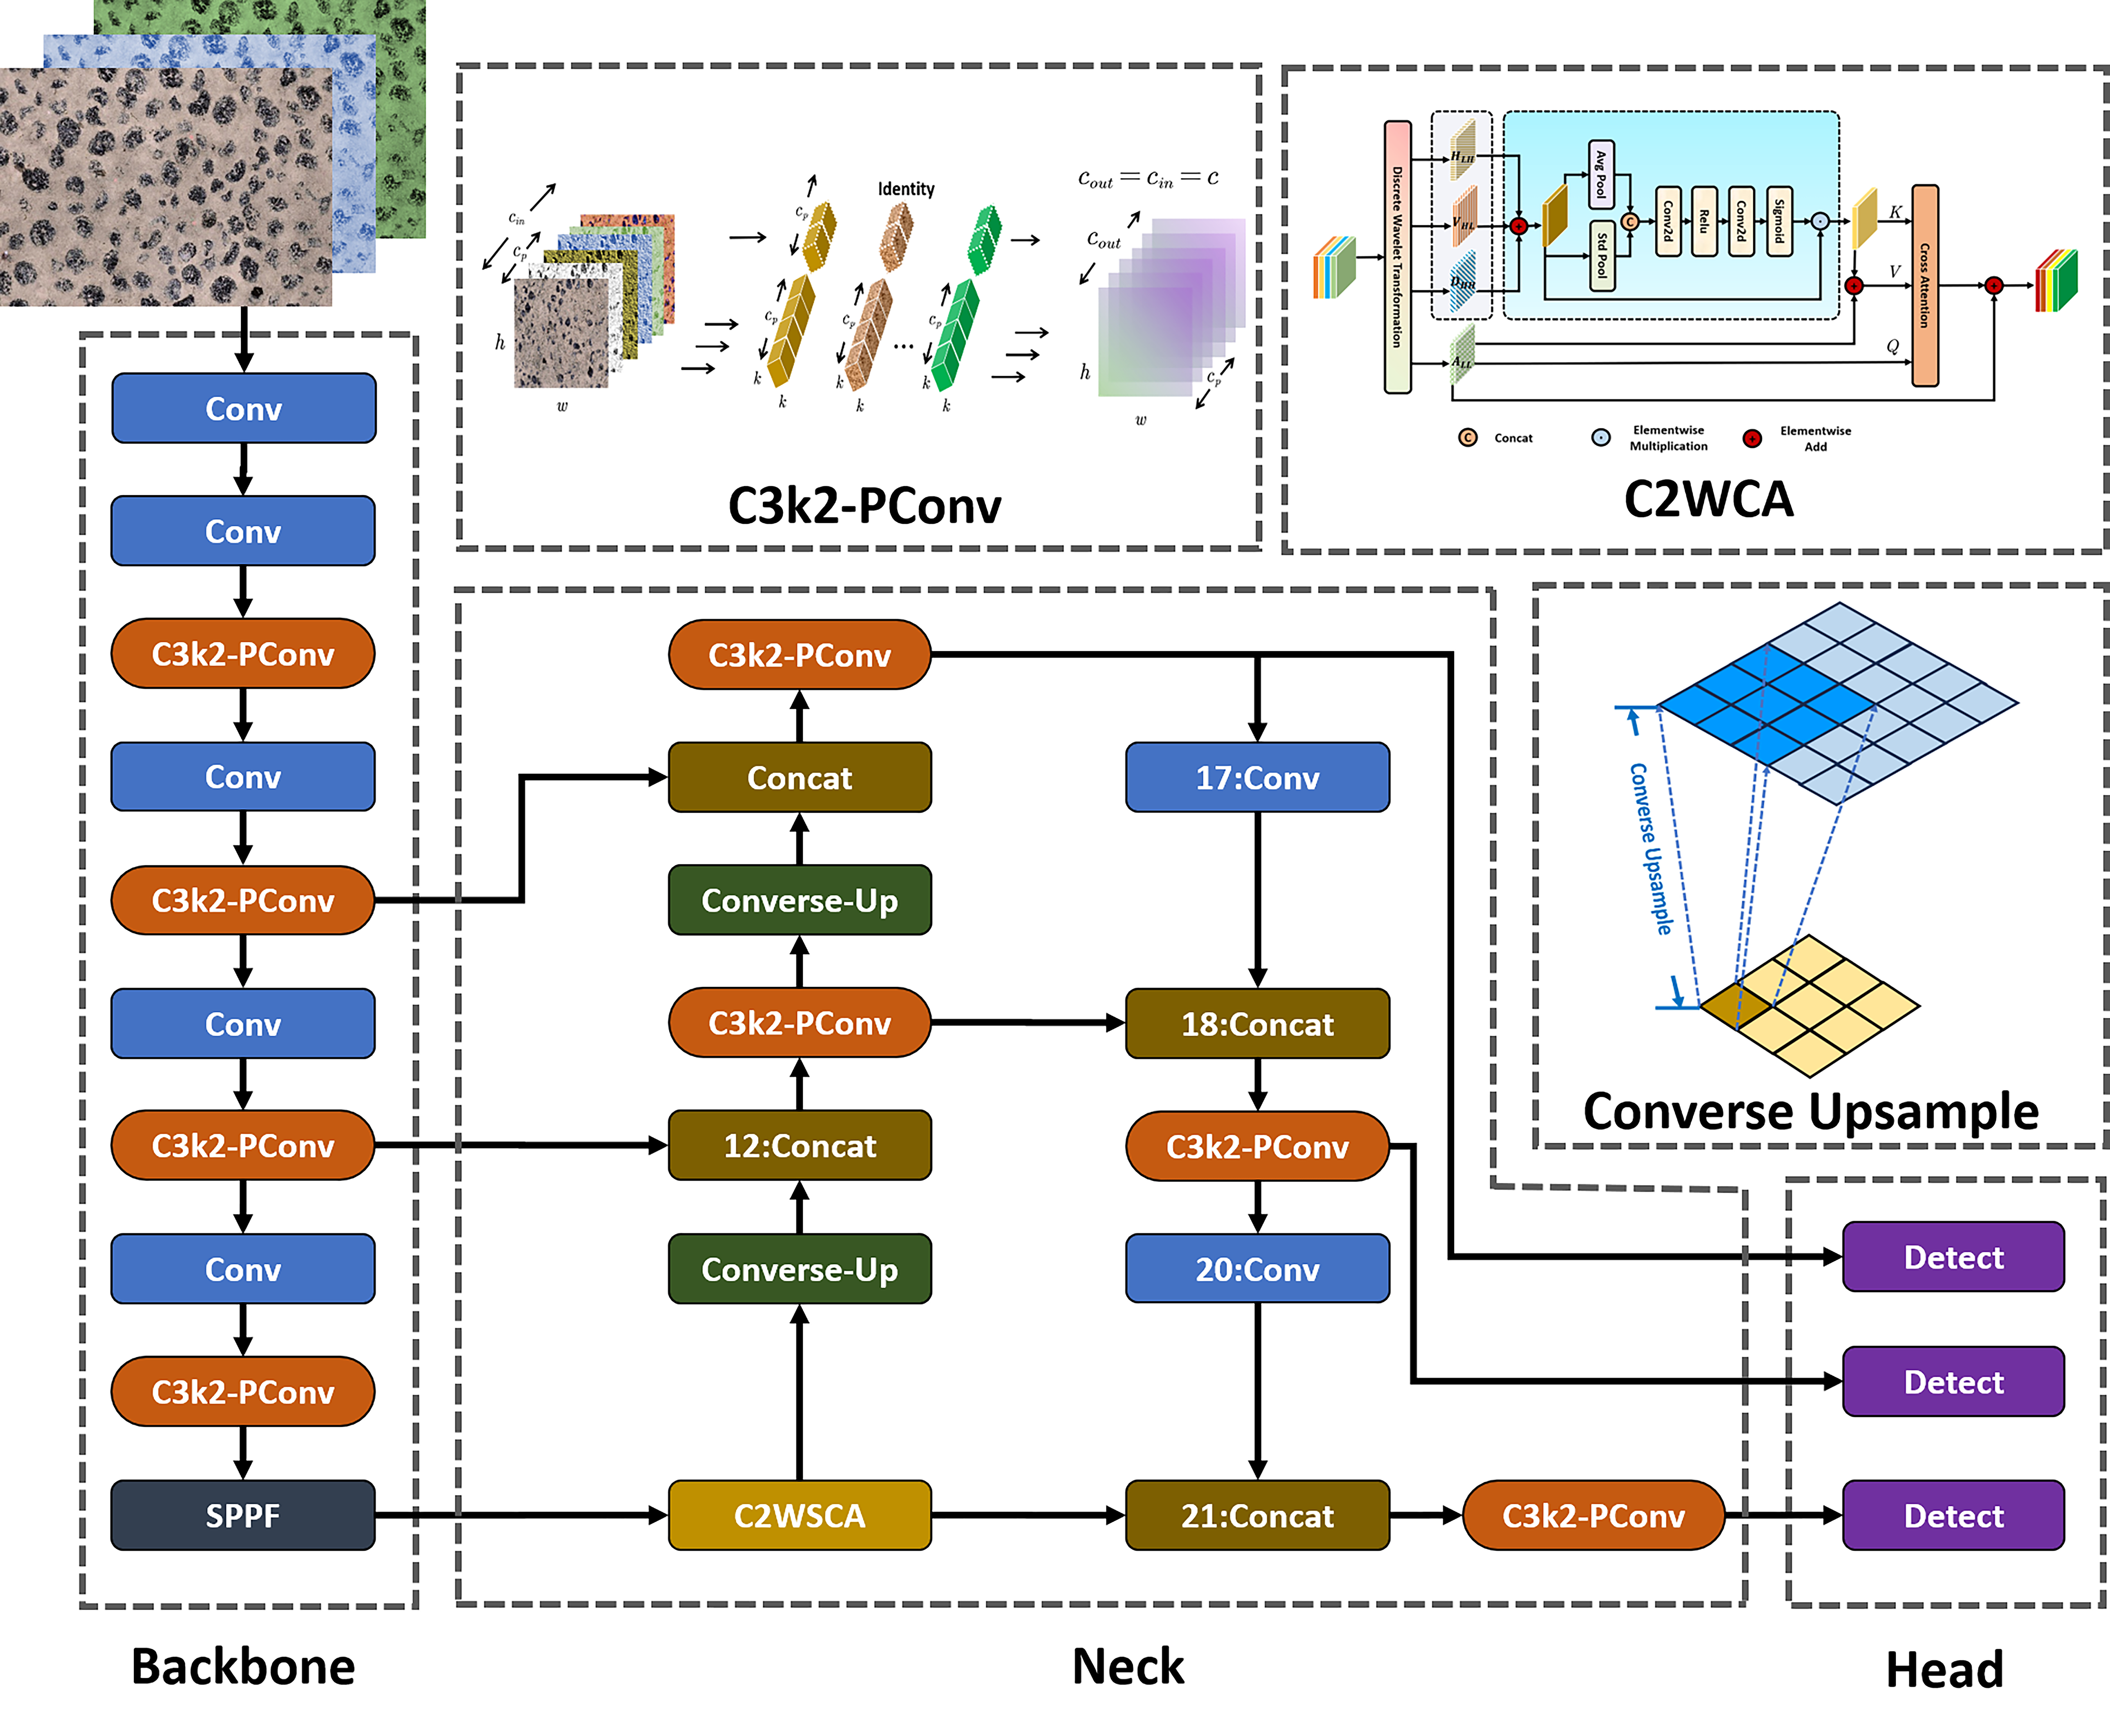
To tackle the challenges of low-contrast, complex seabed background interference and inaccurate segmentation boundaries of deep-sea polymetallic nodules, this study proposes an improved instance segmentation model based on YOLOv11-n-seg. The overall network structure of the proposed PWC-YOLO model is illustrated in Figure 1.
Figure 1.
The architecture of the PWC-YOLO model.
Compared with the original YOLOv11-n-seg, the proposed model mainly carries out three improvements: (1) the C3k2 module is modified to C3k2-PConv with partial convolution, which reduces redundant computational overhead of the backbone and realizes efficient hierarchical feature extraction for polymetallic nodules. (2) A novel WSCA attention module is constructed to replace the original attention block, which suppresses seabed clutter interference and enhances the feature representation of small nodules through the cross-attention mechanism. (3) Converse2D reverse convolution upsampling (Converse Upsample) is used to replace nearest interpolation within the neck network, recovering lost fine contour details of nodules and boosting the multi-scale feature fusion effect for instance segmentation.
These three optimizations effectively reduce model parameters and computational complexity while guaranteeing segmentation precision, yielding favorable lightweight properties that offer potential prerequisites for future lightweight deployment on underwater edge computing hardware.
3.2. C3k2-PConv Module for Lightweight Feature Extraction
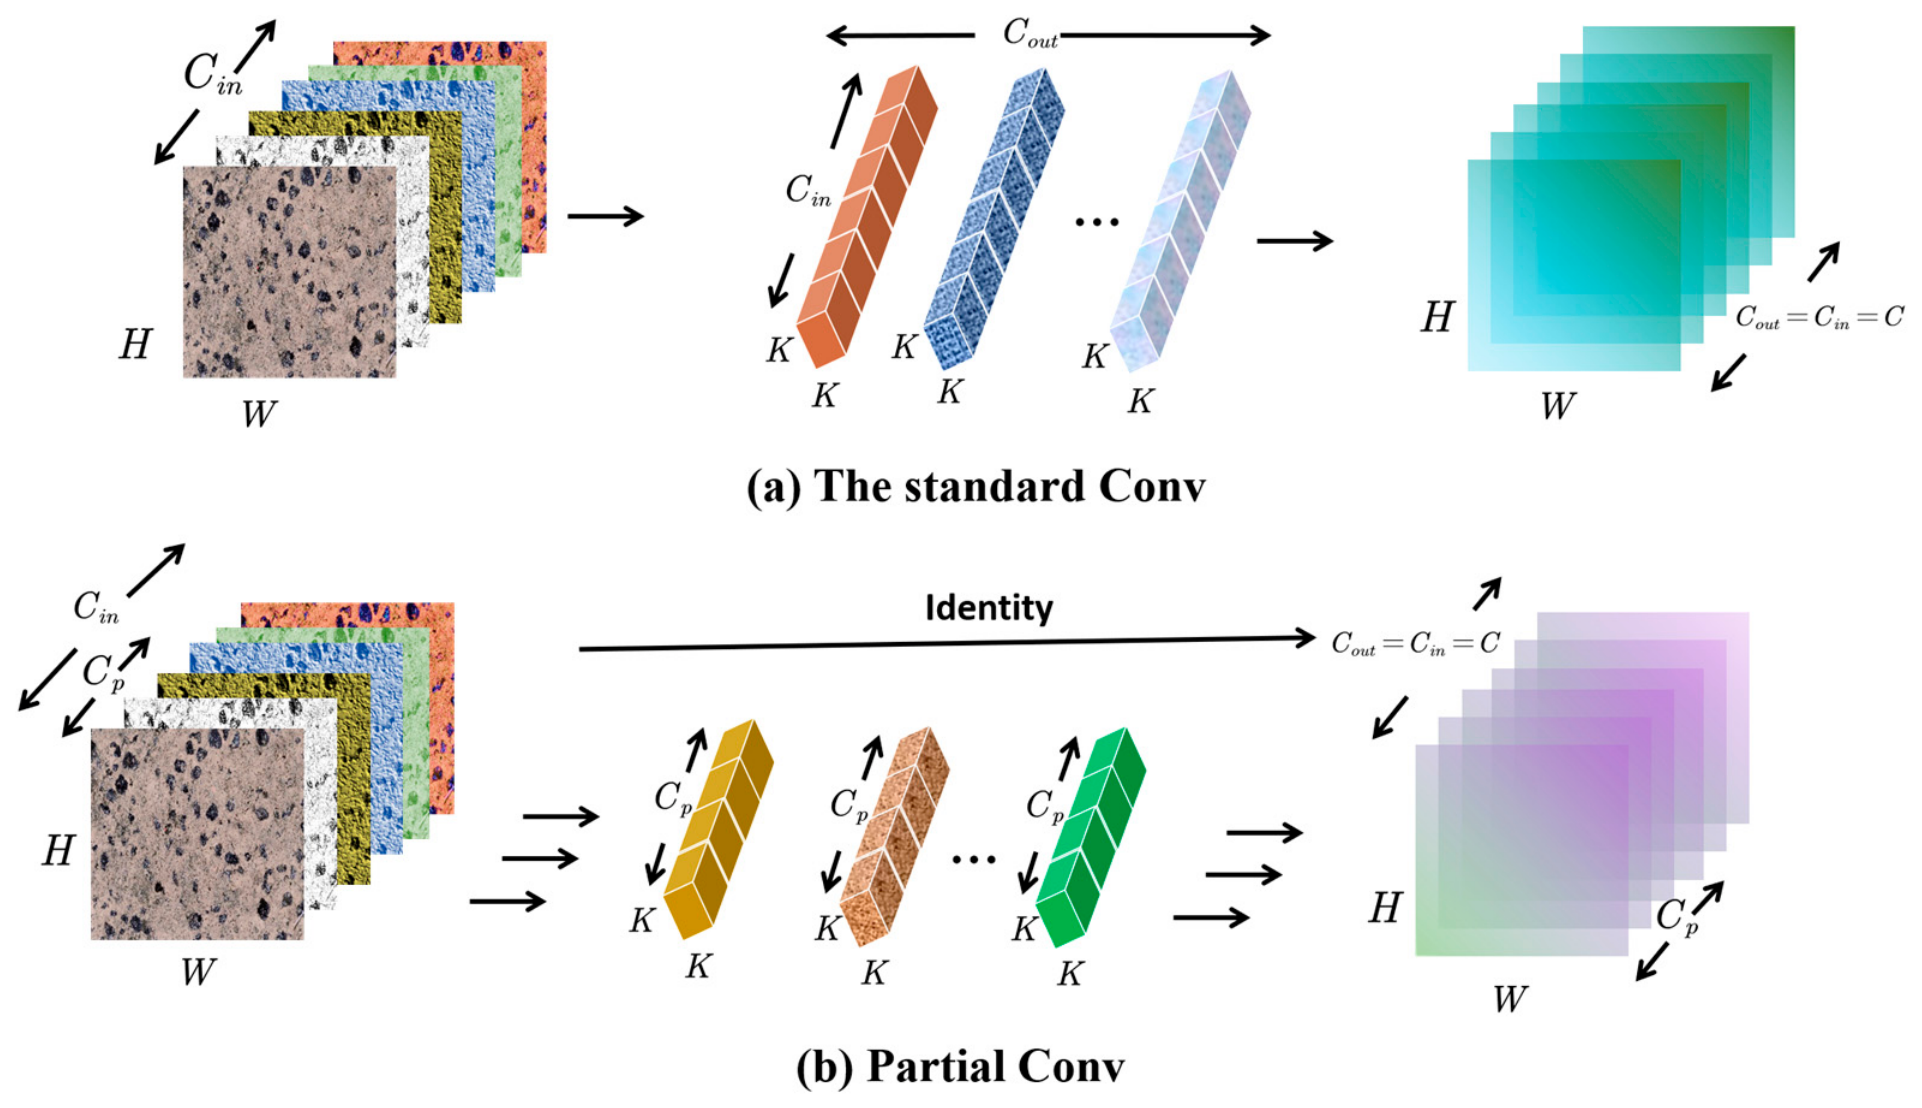
To alleviate the intensive computational overhead incurred by the backbone and neck sub-networks within the YOLOv11 detection paradigm, this paper leverages the partial convolution module (PConv) [26] to reconstruct the original C3k2 module for lightweight optimization and develops a feature extraction module termed C3k2-PConv with suppressed computational cost. Distinct from the standard convolution that manipulates all feature channels simultaneously, PConv adopts a channel-separated computation paradigm: merely a contiguous subset of channels is designated for spatial feature convolution, while the remaining channels are propagated via identity mapping without additional arithmetic operations, thereby eliminating massive redundant computations introduced by full-channel convolution.
Figure 2 provides a structural comparison between the standard convolution and PConv. To conform to the contiguous memory-addressing mechanism of hardware facilities, PConv selects successive front or rear channels as the computational branch; in this study, the channel dimensions of input and output feature maps are constrained to be identical. Given an input feature tensor , the standard convolution adopts full-channel kernels to realize feature transformation, and its total floating-point operations and memory access overhead are quantified by Equations (1) and (2):
Figure 2.
The structural comparison between the standard convolution and partial Conv (PConv).
In contrast, PConv solely employs compact kernels with limited channel dimensionality during forward inference, and the corresponding formulations for computational and memory consumption are presented as Equations (3) and (4):
A channel proportion factor is widely adopted for quantitative evaluation in industrial deployment scenarios. Comparative analyses demonstrate that the FLOPs of conventional convolution are 16-fold higher than those of PConv under identical input configurations, and its memory access cost is quadrupled. This observation validates that PConv is capable of reducing overall computational and storage consumption while fully preserving the representational capacity of spatial features, which endows PConv with inherent lightweight merits.
Capitalizing on the intrinsic low-computation property of PConv, hierarchical reconstruction is implemented on the bottleneck unit encapsulated in C3k2 [27,28]: two cascaded standard convolutions inside the bottleneck block are entirely substituted with PConv operators to formulate a lightweight primitive Bottleneck–PConv. By embedding this lightweight bottleneck into the original dual-parallel-channel architecture of C3k2, a refined C3k2-PConv module is obtained. The proposed module reduced network parameters and computational complexity while completely inheriting the native adaptive feature extraction performance of C3k2. Figure 3 illustrates the comprehensive topological connections of three lightweight architectures, including Bottleneck–PConv, C3k-PConv and the refined C3k2-PConv module.
Figure 3.
The structures of C3k2-PConv module, C3k-PConv and the Bottleneck–PConv.
3.3. Wavelet Statistical Cross-Attention
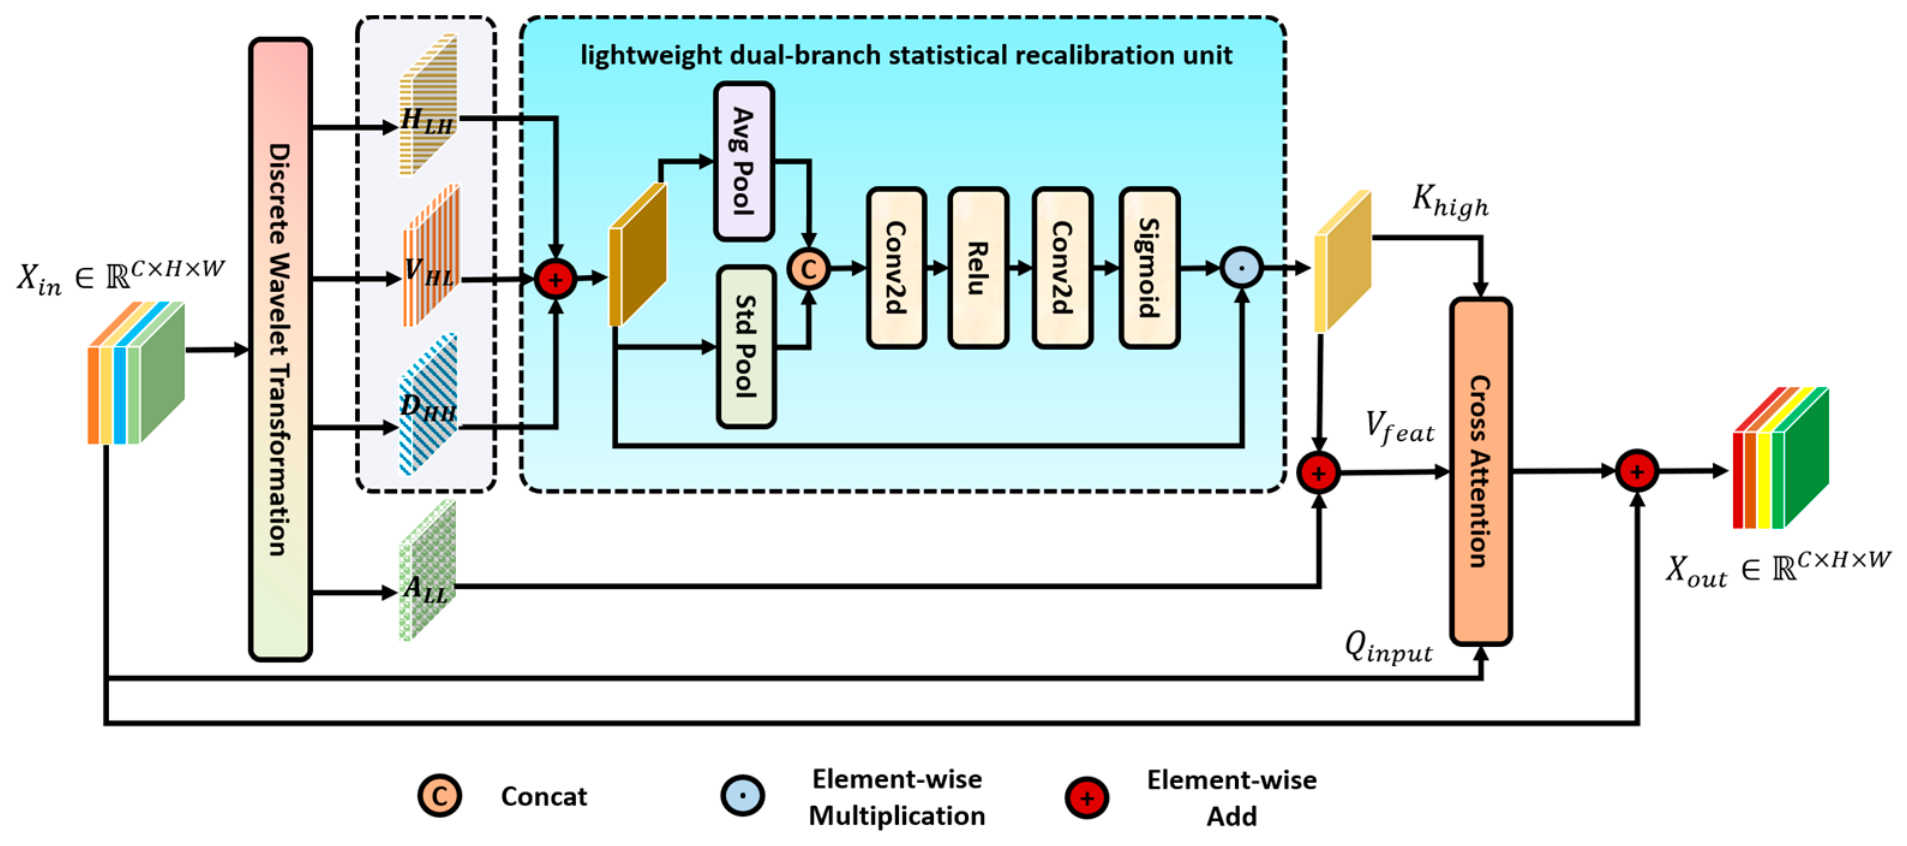
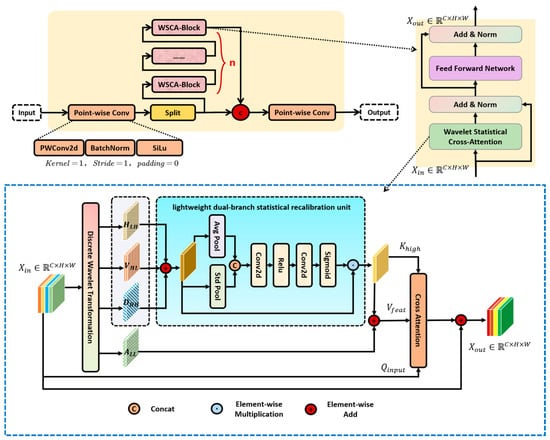
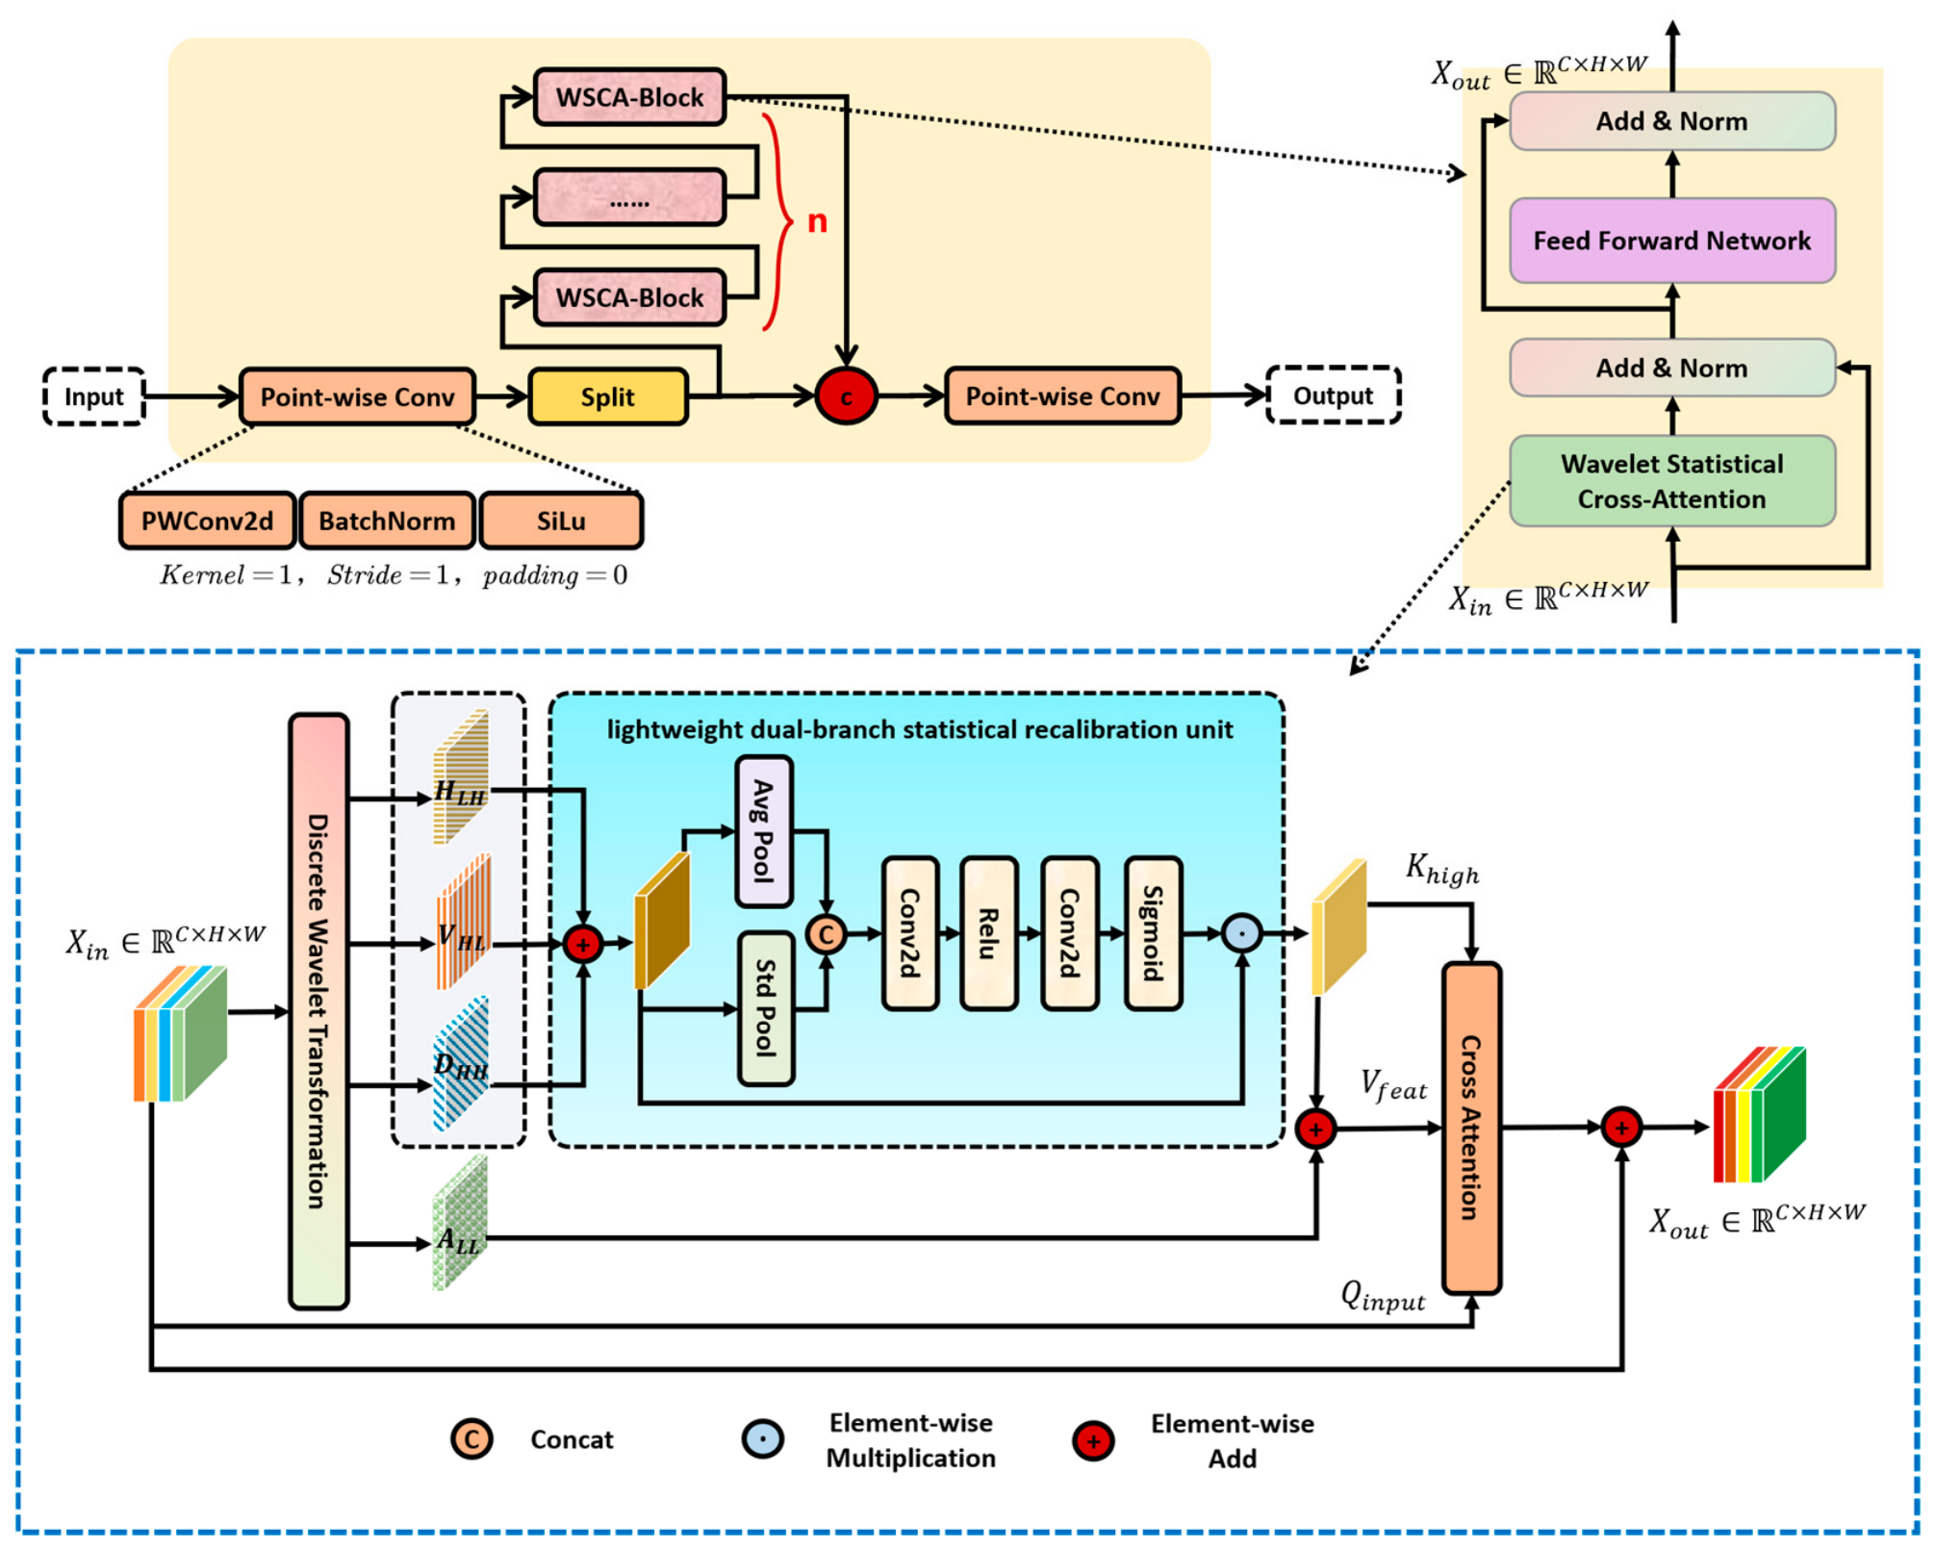
To achieve high-precision instance segmentation of polymetallic nodules under residual water-column noise and undulating seabed terrain in preprocessed seafloor imagery, this paper proposes a Wavelet Statistical Cross-Attention (WSCA) module. The proposed module can directly replace the native multi-head self-attention embedded in the C2PSA unit of the YOLOv11 segmentation branch and resolves the semantic coupling between the seabed background and nodule targets as well as water clutter aliasing defects existing in the native multi-head self-attention. Combined with Haar wavelet decomposition and adaptive frequency-domain statistical recalibration, the module strengthens feature representation of residual low-contrast, small-scale deep-sea nodule targets with extremely low computational overhead. The overall architecture of WSCA is illustrated in Figure 4.
Figure 4.
The structure of Wavelet Statistical Cross-Attention.
Different from conventional channel-spatial lightweight attention modules such as SE, ECA, CBAM and coordinate attention, which mainly perform feature recalibration purely in the spatial or channel dimension, the proposed WSCA is designed as an integrated replacement block for the native self-attention inside C2PSA. It combines Haar discrete wavelet transform, dual-branch statistical recalibration and cross-attention in a coupled manner to separate nodule contour texture from complex seabed background interference, and it is tailored for the special characteristics of deep-sea nodule imagery.
The input feature map is decomposed into four orthogonal frequency sub-bands via discrete Haar wavelet transform (DWT):
In this work, the Haar wavelet is adopted as the decomposition basis for WSCA. Compared with Daubechies and other wavelet families, the Haar wavelet is completely parameter-free and has minimal computational overhead, which fits the lightweight design requirement for potential underwater edge-device deployment. It can well separate low-frequency large-scale seabed background components and high-frequency texture-clutter information from deep-seafloor nodule images. Although Daubechies-series wavelets provide smoother filter coefficients, they require additional predefined filter banks and bring extra computational cost. For the polymetallic nodule segmentation task in this paper, switching to Daubechies wavelet would increase computational burden without obvious performance gain. Accordingly, we choose the Haar wavelet for our frequency-domain decomposition [29].
From empirical observation on deep-sea seafloor images, the low-frequency component predominantly encodes global seabed topography and large-scale flat sediment background semantics, though it cannot be entirely free of residual high-frequency water-column clutter noise. Three high-frequency branches carry contour cues of nodule deposits: and capture horizontal and vertical boundaries of polymetallic nodules, respectively, while is largely dominated by diagonal clutter induced by seawater scattering and camera imaging, yet faint nodule-related texture features can still exist within this sub-band. Element-wise summation is performed on all high-frequency sub-bands to obtain a unified high-frequency texture representation:
To mitigate interference from high-frequency seabed water clutter and channel feature imbalance, a lightweight dual-branch statistical recalibration unit is devised. Global average pooling and global standard deviation pooling are executed in parallel to capture channel-wise sediment intensity distribution and nodule texture fluctuation characteristics:
Dual statistical features () are concatenated along the channel dimension. As is shown in Equation (11), the number of channels is first reduced from to (where represents the reduction ratio, default ) and then restored back to . Here, , , is the ReLU function and is the sigmoid function.
As is shown in Equation (12), the normalized weight matrix recalibrates high-frequency feature maps to suppress clutter-dominant channels and amplify channels sensitive to nodule ore boundaries. The clutter-denoised purified serves as frequency-enhanced key features for cross-attention matching, exclusively storing texture priors of nodule boundaries.
To integrate global seabed topographic background semantics and refined local boundary cues of nodule deposits, a unified full-band fusion strategy is adopted to generate value features. The denoised high-frequency nodule texture representation is element-wise summed with clutter-free low-frequency sediment components to construct feature tensors with comprehensive seabed contextual information:
This fusion paradigm completely retains large-scale flat sediment background and refined nodule edge contour details, enabling the model to distinguish genuine polymetallic nodule deposits from irrelevant interference such as seabed silt and benthic organism textures.
Strict semantic decoupling is conducted among , and to eliminate feature coupling interference between the seabed background and nodule targets. The original seabed feature map is flattened into to avoid feature loss of small-scale, low-contrast nodule targets. The frequency-purified and full-band fused are flattened as keys and values for cross-attention, respectively. The features are reshaped for multi-head attention:
where is the token length, , is the number of heads and is the dimension per head.
The mathematical formulation of multi-head cross-attention is defined as
The attention-enhanced features are reshaped to the original spatial resolution and fused with raw seabed input via residual connection to obtain the optimized feature representation for polymetallic nodule segmentation:
The proposed WSCA module makes a favorable balance between the segmentation accuracy of deep-sea exploration tasks and the computational efficiency of underwater edge devices. The statistical recalibration unit only introduces a tiny quantity of trainable parameters, and Haar wavelet decomposition is fully parameter-free. Benefiting from downsampled frequency-domain key and value sequences, the theoretical time complexity of attention is optimized from of vanilla dense self-attention to , which cuts floating-point operations and inference latency, complying with the computational constraints of real-time polymetallic nodule instance segmentation for deep-sea in-situ detection and underwater robots.
Figure 5 depicts the structure of the improved C2WSCA block modified from the original C2PSA unit in the segmentation branch of YOLOv11. The native multi-head self-attention embedded in C2PSA is entirely replaced by our proposed WSCA module to suppress complex seabed noise interference. Stackable WSCA–Block groups are integrated inside C2WSCA to extract robust feature representations of deep-sea polymetallic nodules.
Figure 5.
The structure of the C2WSCA module and WSCA–Block module.
3.4. Upsampling Module Based on Reverse Convolution Converse2D
According to the official Ultralytics YOLOv11 network definition [27], the FPN multi-scale neck leverages nearest-neighbor interpolation for deep low-resolution feature upsampling to concatenate shallow fine-grained features. However, such interpolation merely expands spatial dimensions via fixed pixel filling and fails to reconstruct spatial cues degraded by repeated stride-2 encoder downsampling. To mitigate this limitation, this paper adopts the depth-wise reverse convolution operator Converse2D [30] to fully replace all native interpolation layers within the YOLOv11 neck. This operator formulates the inverse mapping of convolutional downsampling as a regularized least-squares problem and yields a one-step closed-form solution via Fast Fourier Transform, enabling precise recovery of lost fine-grained details in multi-channel feature domains.
denotes the original high-resolution feature map, denotes the learnable depthwise convolution kernel, denotes the low-resolution feature map output by the encoder, stands for channel-wise depthwise convolution, and denotes downsampling with stride . The forward convolutional downsampling process can be mathematically formulated as
The target of this work is to inversely reconstruct the original high-resolution feature given the observed feature , convolution kernel and scaling factor . This inverse reconstruction problem is inherently ill-posed, and direct optimization tends to generate numerically unstable results. Accordingly, a least-squares objective function embedded with a quadratic regularization term is constructed:
where denotes the Frobenius norm. The first term serves as the data fidelity term, constraining that the reconstructed feature matches the input feature after convolution and downsampling; is the regularization coefficient to balance reconstruction error and regularization strength. refers to the initial reconstruction estimation, which is assigned via nearest-neighbor interpolation upsampling in this paper. Compared with zero initialization, this strategy better preserves high-frequency details and accelerates model convergence.
Under the circular convolution boundary assumption, Equation (20) can be transformed into a universal frequency-domain closed-form solution (Equation (21)) applicable to arbitrary via Fast Fourier Transform. The general closed-form solution for arbitrary scaling factor , as well as comprehensive derivations including frequency-domain block averaging and block-wise element-wise multiplication, are elaborated in Reference [30]. This paper omits redundant lengthy frequency-domain derivations and only retains the core simplified model supporting network structural modification. The scaling factor used in s-fold zero-padding is identical to the upsampling stride, and we set in this paper.
where the intermediate frequency term is defined as
where and represent Fast Fourier Transform and inverse Fast Fourier Transform, respectively. denotes the complex conjugate of the frequency-domain transformation of convolution kernel . denotes the FFT result of after -fold zero-padding upsampling; represents the block mean downsampling operator that averages each block for dimension reduction; and denotes the lock-wise element-wise multiplication operator, operating on split feature blocks. is the element-wise squared magnitude of kernel frequency spectrum.
The regularization coefficient is adaptively mapped from a trainable offset parameter with the formulation
where is a learnable scalar of the network and is a tiny constant to avoid a zero denominator in frequency-domain division and guarantee stable numerical calculation. Note that the least-squares problem in Equation (20) yields a closed-form one-step solution and does not optimize . The scalar is updated via the global network back-propagation jointly with other weights, rather than being solved within this least-squares formulation. After random initialization, convolution kernels are normalized by Softmax to enforce non-negative weights with unit sum, which conforms to the physical prior of the point-spread function. The detailed PyTorch-style implementation of the Converse2D module is shown in Algorithm 1.
| Algorithm 1 Code of Converse2D in a PyTorch-like style (fixed , kernel) | |
| # X: input feature map | |
| # K: kernel | |
| # S: stride or upscaling factor, fixed S = 2 for YOLO neck | |
| # p2o: convert point-spread function (PSF) to optical transfer function (OTF) | |
| # splits: divide a tensor of shape […, H, W] into […, H/S, W/S, S^2] distinct blocks | |
| # The following two steps are supplemented in this paper for detection edge artifact suppression | |
| 1 | pad = kernel_size − 1 = 2 |
| 2 | X = circular_pad(X, pad_width = pad) |
| # X: B, C, H, W | |
| 3 | B, C, H, W = X.shape |
| # lambda: regularization parameter | |
| 4 | lambda = torch.sigmoid(bias − 9.0) + 1 × 10⁻⁵ |
| # upsample X: B, C, H × S, W × S | |
| 5 | Y_S = upsample(X, scale = S) |
| # interpolate X: B, C, H × S, W × S | |
| 6 | X_0 = nn.functional.interpolate(X, scale_factor = S, mode = ‘nearest’) |
| # FFT kernel: B, C, H × S, W × S | |
| 7 | FK = p2o(K, (H*S, W*S)) |
| # complex conjugate | |
| 8 | FK_conj = torch.conj(FK) |
| # element-wise squared magnitude | |
| 9 | FK_2 = torch.pow(torch.abs(FK), 2) |
| 10 | FKY = FK_conj * torch.fft.fftn(Y_S, dim = (−2, −1)) |
| # L: B, C, H × S, W × S | |
| 11 | L = FKY + torch.fft.fftn(lambda * X_0, dim = (−2, −1)) |
| 12 | FKL = FK.mul(L) |
| # split and calculate mean: B, C, H, W | |
| 13 | FKL_S = torch.mean(splits(FKL, S), dim = −1, keepdim = False) |
| 14 | FK2_S = torch.mean(splits(FK_2, S), dim = −1, keepdim = False) |
| 15 | Fdiv = FKL_S.div(FK2_S + lambda) |
| # element-wise multiplication | |
| 16 | Fmul = FK_conj * Fdiv.repeat(1, 1, S, S) |
| 17 | Fout = (L − Fmul)/lambda |
| # inverse FFT output: B, C, H × S, W × S | |
| 18 | out = torch.real(torch.fft.ifftn(Fout, dim = (−2, −1))) |
| # This step is supplemented in this paper to remove padded boundary | |
| 19 | out = crop_boundary(out, pad * S) |
| 20 | return out |
4. Experiments
4.1. Dataset Description and Preprocessing
The image source of this research is the public standardized optical seafloor dataset released by Mbani & Greinert (2023) in Scientific Data [8], archived in the PANGAEA database. All images were acquired during the RV SONNE SO268 scientific cruise in 2019 within the Clarion–Clipperton Zone (CCZ). The CCZ, located in the equatorial Pacific Ocean, is a representative sea area rich in polymetallic manganese nodules, characterized by ultra-deep water and complex benthic backgrounds.
The underwater imaging equipment adopted is a towed Ocean Floor Observation System (OFOS) carrying a Canon EOS 5D Mark IV camera (30 MP, 24 mm lens, Cannon, Japan) with artificial strobe supplementary lighting, and the average sampling water depth reaches 4250 m. Three built-in laser pointers realize accurate scale calibration, and the USBL underwater navigation system records the real-time position of the acquisition platform.
All original images have undergone unified professional preprocessing to eliminate quality degradation caused by underwater light attenuation, which provides consistent and high-quality image input for subsequent pixel-level instance segmentation tasks. The main preprocessing procedures include: (1) light cone correction, where Z-score normalization is used to compensate radial illumination attenuation; (2) contrast enhancement, where adaptive histogram equalization is used to improve visual feature clarity; (3) color normalization, where histogram matching is used to ensure consistent brightness and chromaticity; and (4) spatial standardization, with a uniform scale at 21.5 pixels/cm and a fixed seafloor coverage of 1.6 m2 per image.
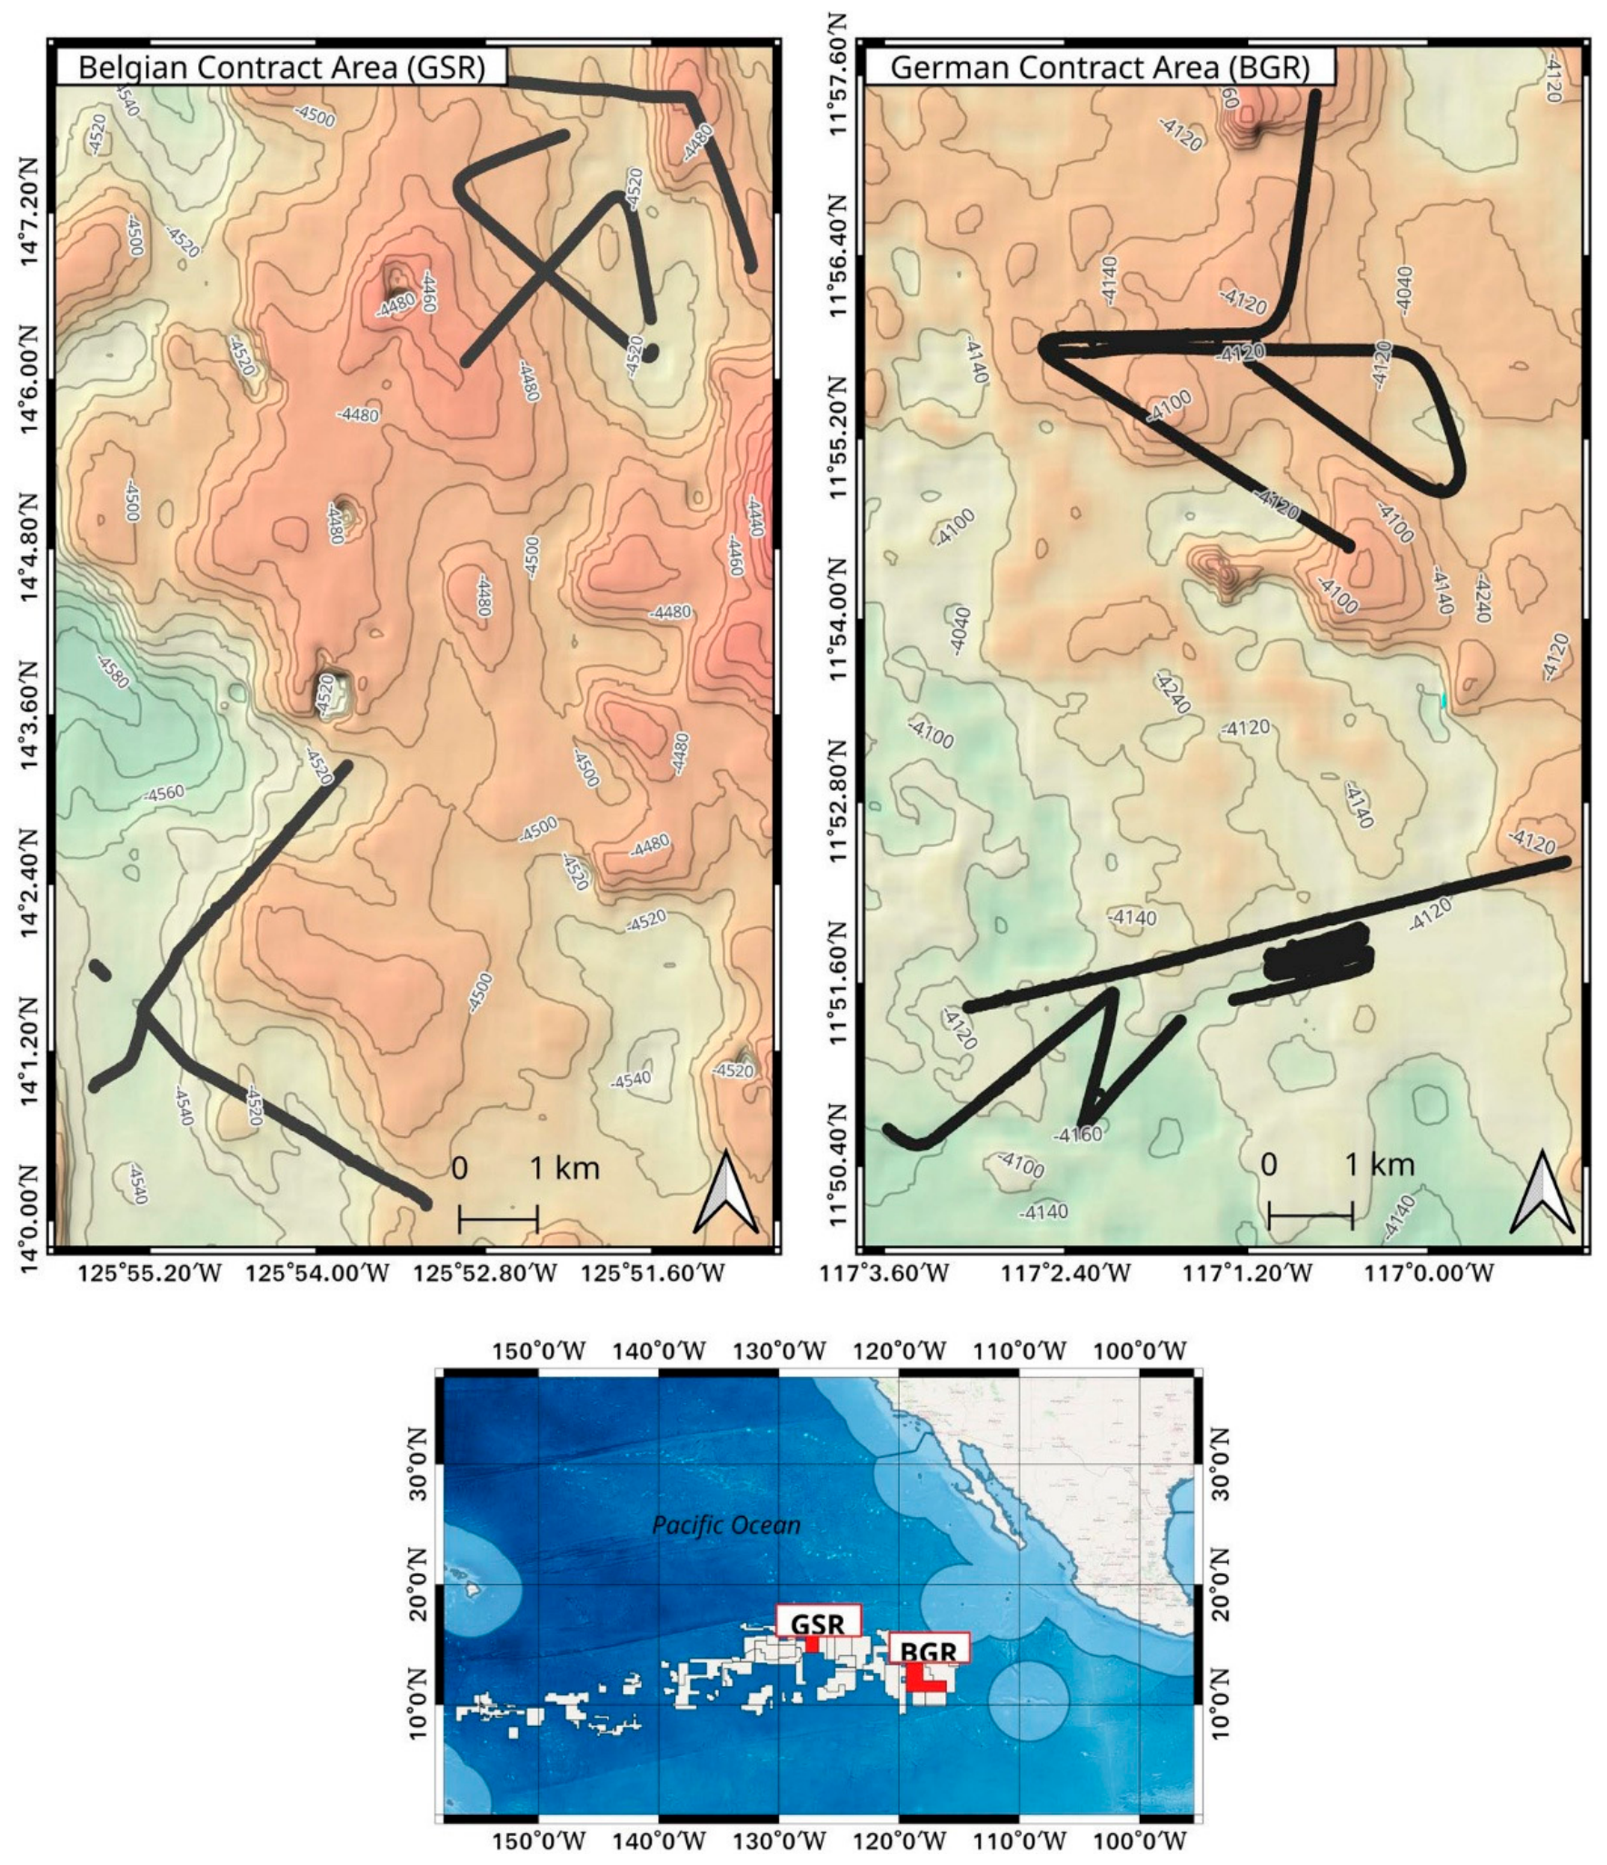
The geographic extent, bathymetry and OFOS survey routes of the investigated Belgian (GSR) and German (BGR) contract areas within the CCZ are illustrated in Figure 6, which is adapted from Mbani & Greinert (2023) [8]. The upper panels of Figure 6 display bathymetric maps of the Belgian (GSR) and German (BGR) contract areas, where black lines indicate the OFOS survey tracks. The bottom map of Figure 6 marks the geographic locations of the two contract areas in the eastern Pacific Ocean. All model training and evaluation experiments in this manuscript are performed on these preprocessed standardized seafloor images.
Figure 6.
Overview of the study area in the Clarion–Clipperton Zone (CCZ). Reproduced from [7], Figure 1, licensed under CC BY 4.0.
4.2. Construction of Instance Segmentation Dataset
The original open dataset only provides preprocessed raw seafloor images, without any bounding box or pixel mask annotations. To match the training requirements of the improved YOLO instance segmentation algorithm proposed in this paper, we randomly select 1000 images from the total 40,476 available pictures and complete full manual annotation independently.
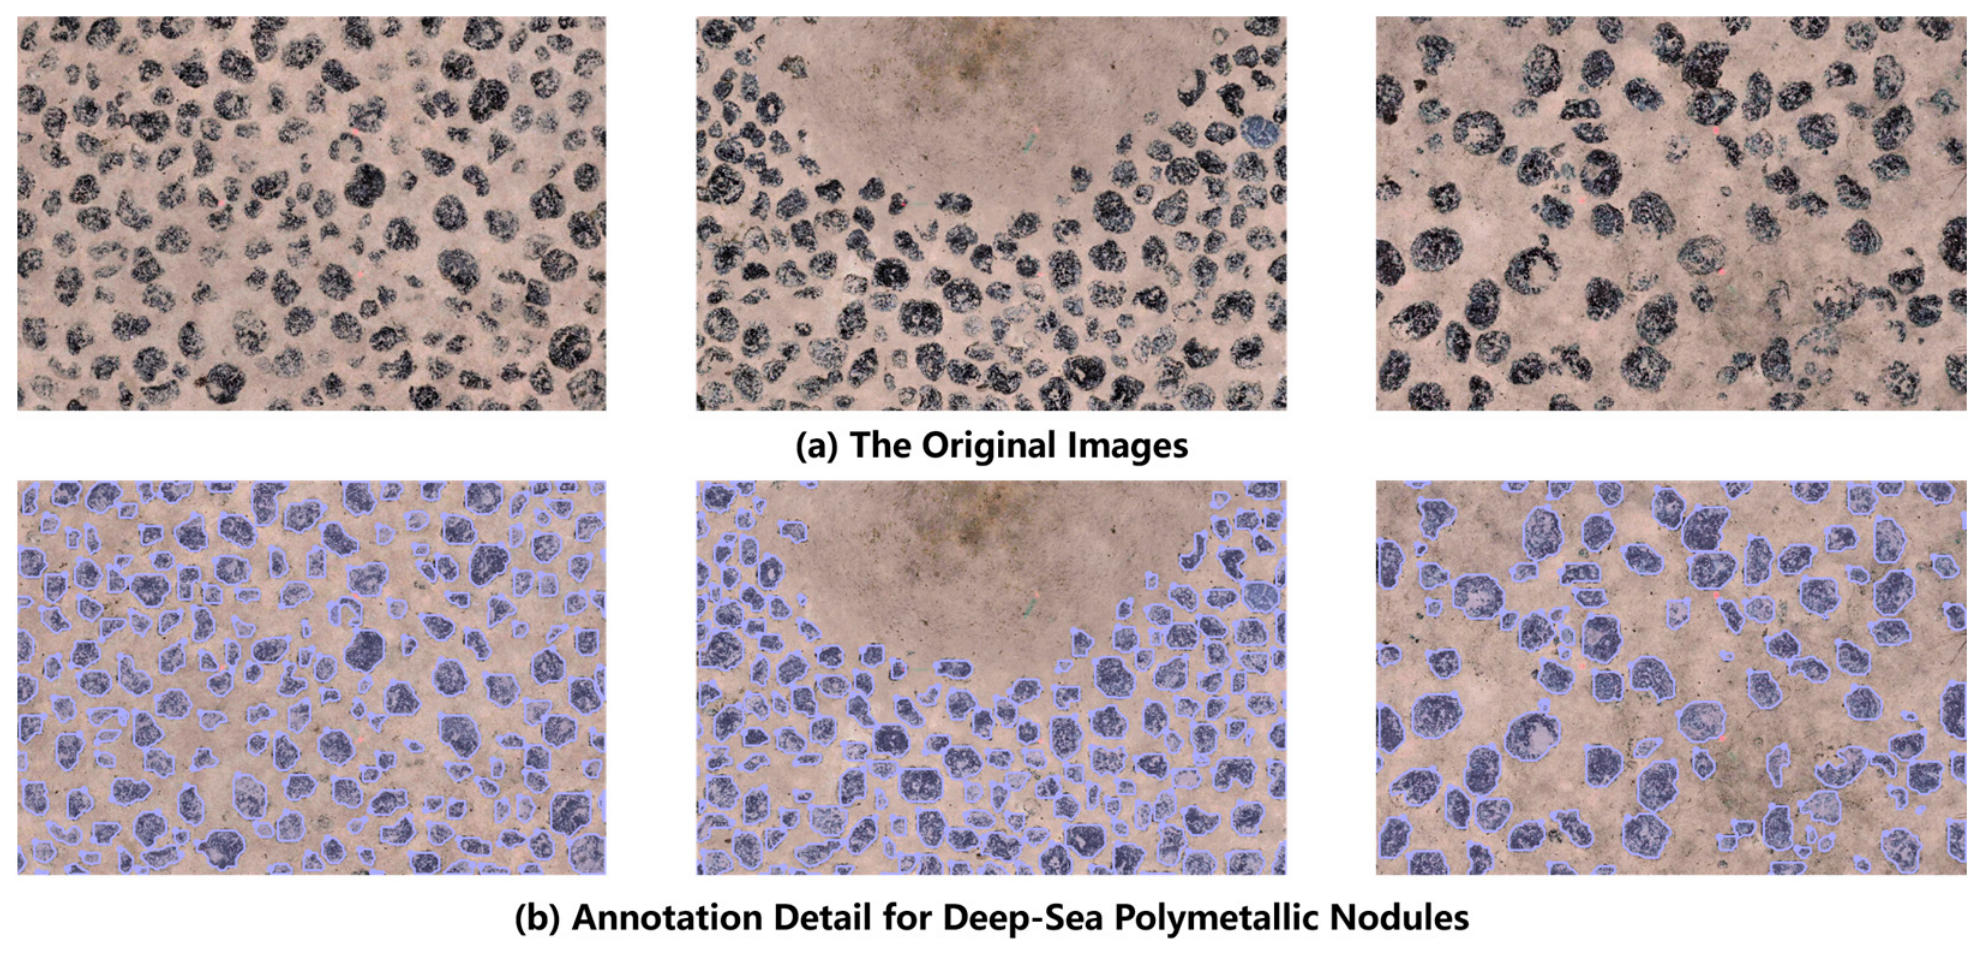
This dataset only contains a single foreground category: polymetallic manganese nodules. For each selected image, we label two forms of annotations simultaneously: external bounding boxes for target location and dense pixel-wise instance masks. The pixel masks can effectively separate individual nodules under severe overlapping and adhesion scenes, which is the core requirement of instance segmentation tasks. All annotations are completed via the open-source labeling tool X-Any-Labeling v4.0. Figure 7 shows representative examples of raw seafloor images and the corresponding manually labeled instance masks.
Figure 7.
Examples of original seafloor images and manual annotation for deep-sea polymetallic nodules.
The annotation work was performed by researchers within our group with background knowledge of deep-sea mineral resources. Unified internal annotation guidelines were followed during labeling. For partially buried or occluded nodules, only the visually exposed contour area was delineated for instance masks; nodules completely covered by sediment were not annotated. For ambiguous blurry seafloor objects that cannot be reliably distinguished as polymetallic nodules, these targets were discarded and not labeled.
An internal two-step quality-control procedure was adopted. After the initial mask and bounding-box labeling finished by one annotator, a second researcher with marine-geology expertise performed full cross-validation over all 1000 images. Mask contours, semi-buried instances and ambiguous samples were carefully inspected and manually revised.
The data splitting follows the standard ratio widely accepted in instance segmentation research: 700 images for the training set (70%), 200 images for the validation set (20%), and 100 images for the test set (10%).
The self-built annotated dataset satisfies the data demand of deep-sea manganese nodule segmentation in marine engineering scenarios, and its core advantages are summarized below:
- Standardized image resolution: uniform 3360 × 2240 pixel size with stable scale and illumination distribution;
- Authentic complex deep-sea scenes: cover sparse, moderate and densely overlapped manganese nodule distribution states;
- Unified spatial coverage: each frame corresponds to a fixed 1.6 m2 seabed range to guarantee stable segmentation evaluation results;
- Representative sample distribution: contains four types of seabed substrates (Class A–D) distributed across the CCZ sea area.
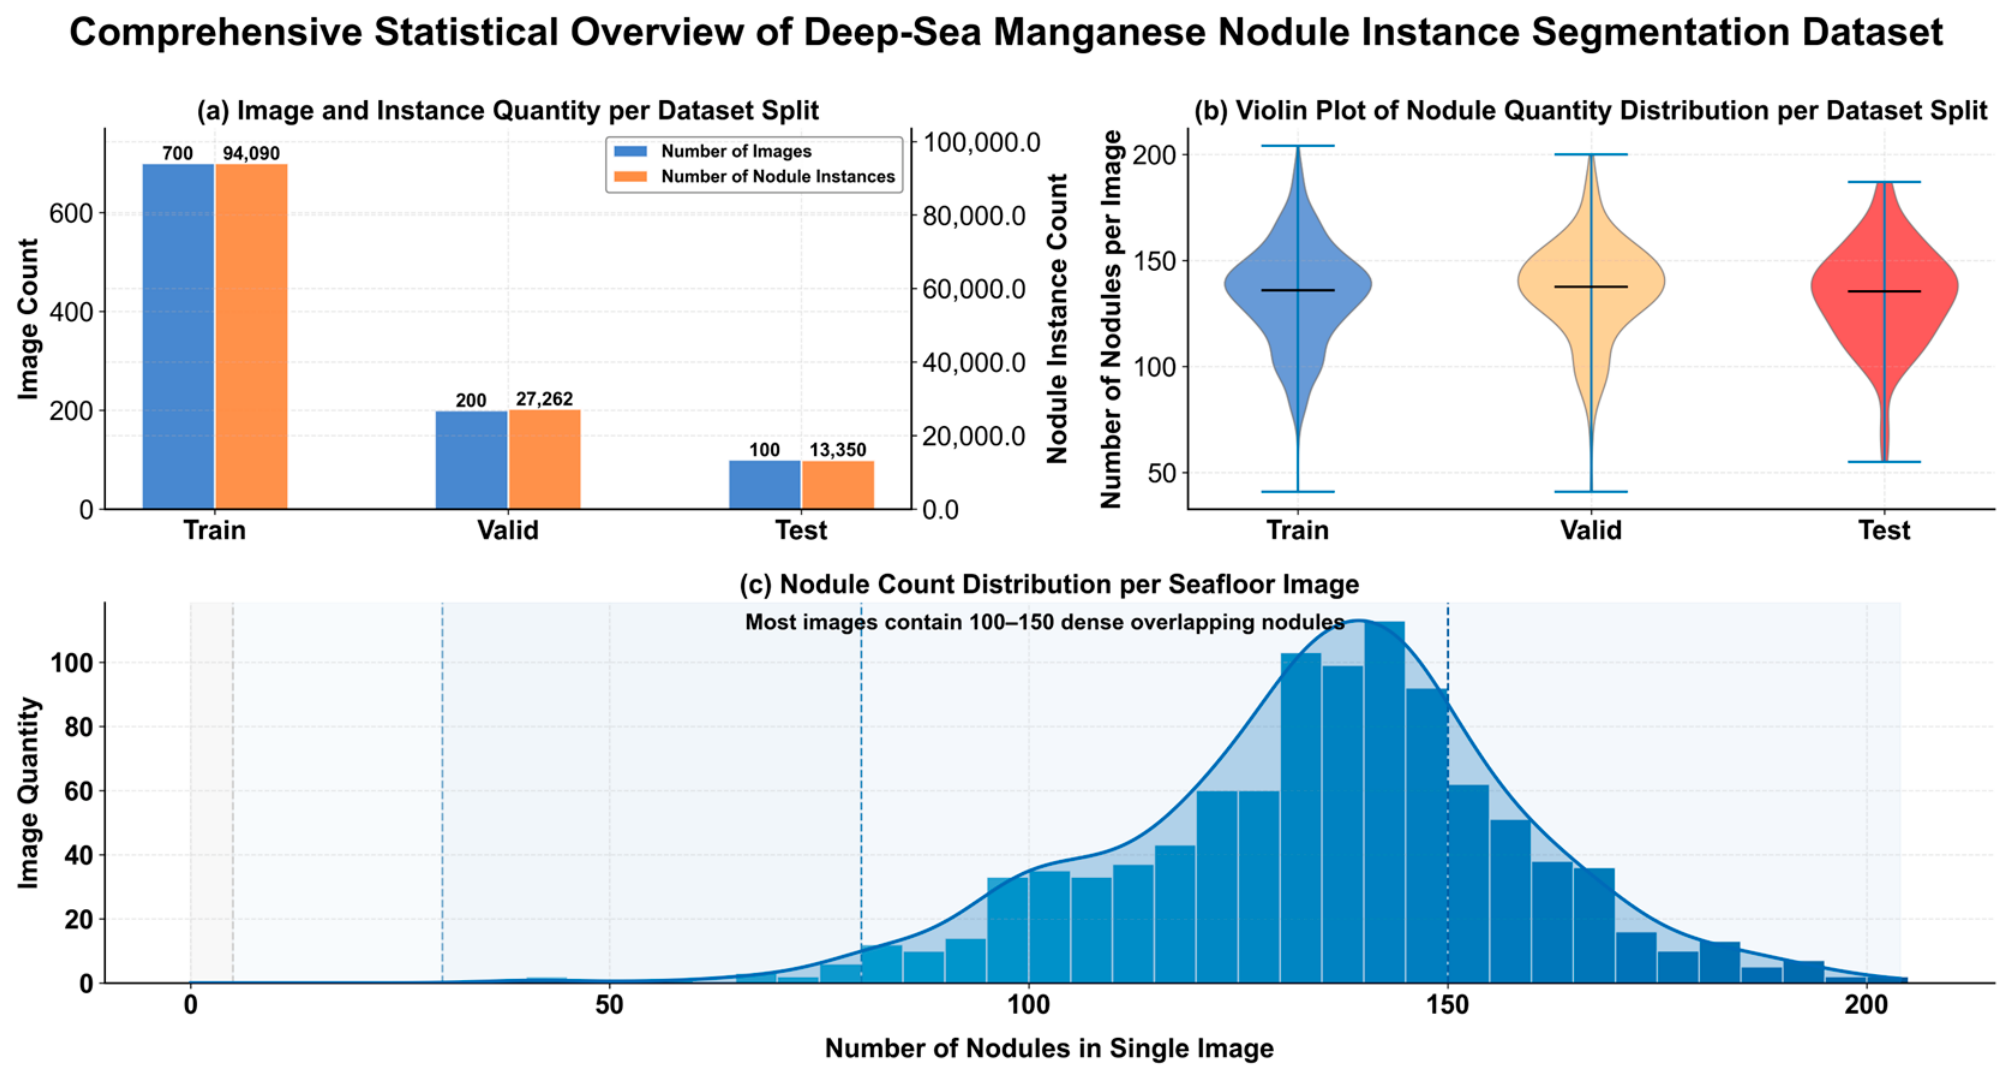
To visually display the scale and internal distribution characteristics of the manganese nodule segmentation dataset, statistical charts are supplemented in Figure 8. The statistical content includes the number of images and annotated nodule instances in each data subset, the quantity distribution of nodules contained in a single image, and the pixel area distribution of individual manganese nodule targets. These statistics prove that the dataset covers multi-scale nodules with various density levels, which can comprehensively test the segmentation capacity of the improved YOLO model under complex overlapping interference.
Figure 8.
Comprehensive statistical overview of the constructed manganese nodule segmentation dataset.
Comprehensive statistical visualizations in Figure 8 analyze the scale and sample balance of the self-built manganese nodule segmentation dataset. Figure 8a shows that the annotated dataset is randomly divided at a 7:2:1 ratio, including 700 training, 200 validation and 100 test seafloor images, with corresponding annotated nodule instances of 94,090, 27,262 and 13,350. The violin plot in Figure 8b indicates comparable median nodule quantities per frame among three subsets, which eliminates prominent distribution bias caused by random partition. Figure 8c displays the global frequency histogram and smoothed KDE curve of nodule numbers in standardized 1.6 m2 seafloor frames. Four graded background bands categorize scenes into sparse, moderate, medium-dense and ultra-dense nodule ranges. The distribution peak reveals most underwater frames contain 100–150 heavily overlapping nodules, the most typical complex benthic scene in the CCZ region.
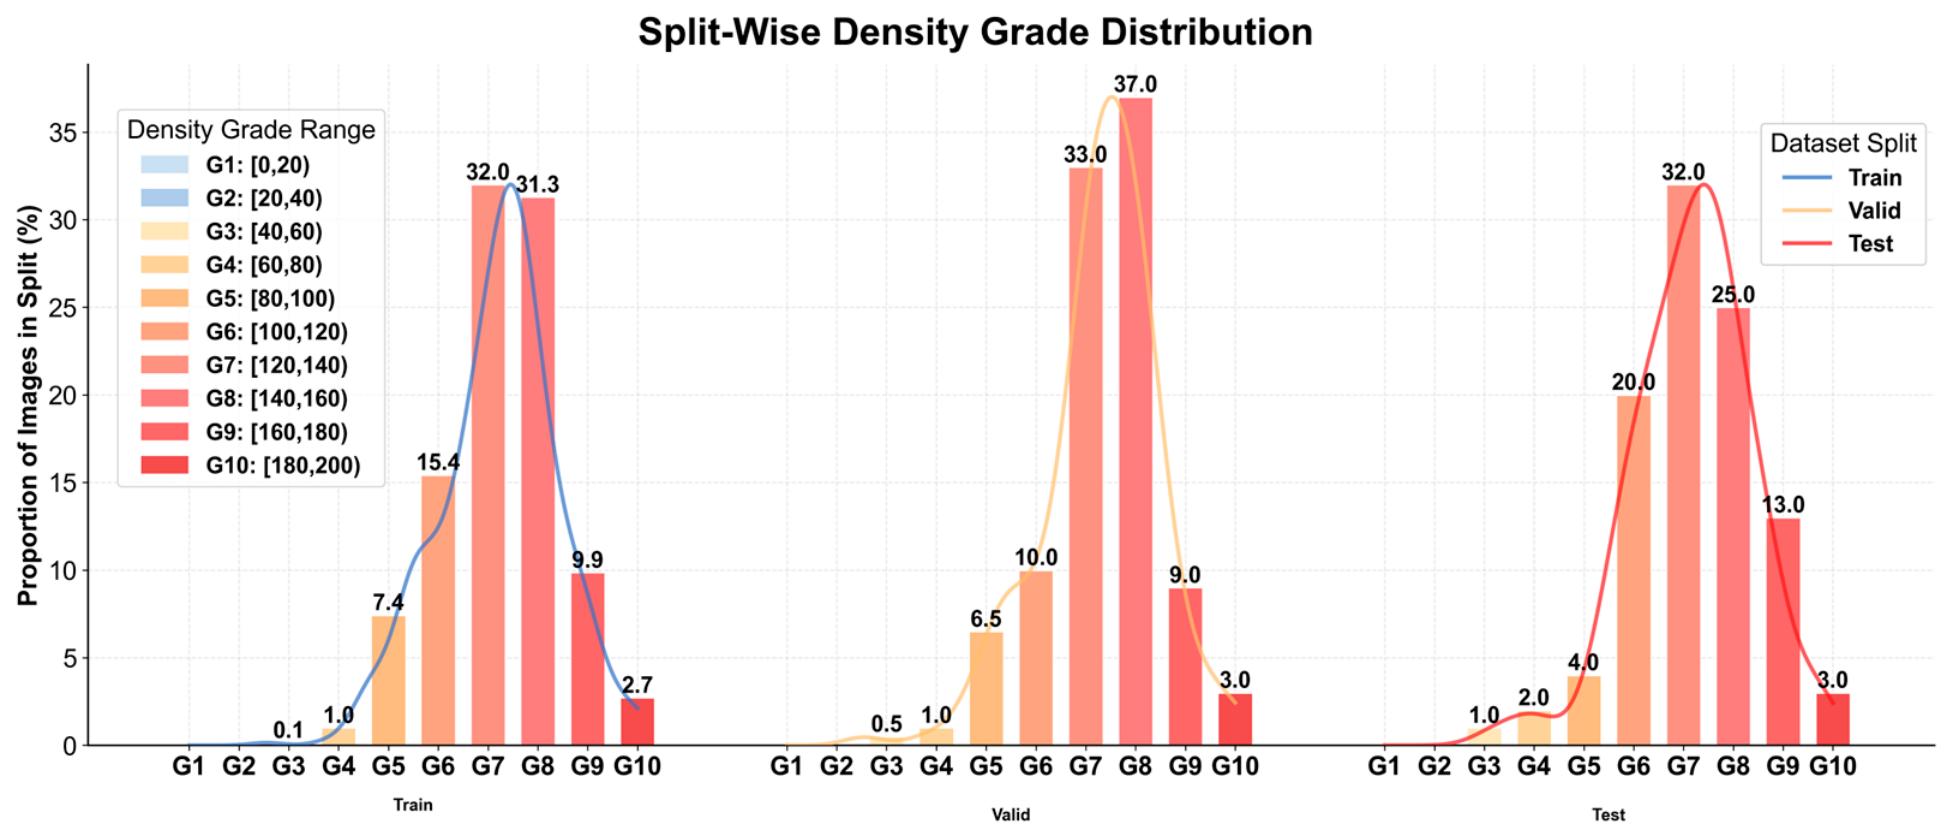
The split-wise density grade graph in Figure 9 further classifies per-image nodule counts into ten equal-width intervals with a step of 20. Bars in Figure 9 represent the proportion of images within each density grade, while smooth curves reflect the overall distribution trend of each subset. All three partitions reach their proportion peaks in the G6–G8 high-density range (100–160 nodules per frame), with peak ratios of 32.0%, 37.0% and 32.0% for the training, validation and test sets, respectively. Low-density samples (G1–G4) only occupy a small share in each group, and ultra-dense G10 samples account for less than 3% of images per subset. The highly consistent density distribution across splits demonstrates that random splitting avoids obvious distribution drift, providing uniform nodule density features for model training and testing.
Figure 9.
Split-wise density grade distribution of manganese nodules.
It should be noted that random image-level train–validation–test splitting is adopted in this study. Consecutive OFOS frames collected along survey transects share highly correlated seabed textures, illumination conditions and nodule distributions, which may introduce spatial–temporal leakage and potentially overestimate the generalization performance for completely unseen seafloor regions. Complete geospatial metadata corresponding to our annotated 1000-image subset is not fully accessible in the present work. Therefore, geographically disjoint dataset partitioning based on survey tracks is reserved for future investigations.
4.3. Experiment Environment
The hardware and software configurations of the experimental environment are shown in Table 1. The operating system is Ubuntu-22.04, the central processing unit (CPU) is Intel(R) Xeon(R) Platinum 8358P CPU @ 2.60 GHz (32 cores, 64 threads), and the graphics processing unit (GPU) is equipped with an NVIDIA GeForce RTX-3090 with 24 GB video memory (10,496 CUDA cores). System memory comprises 40 GB DDR4 ECC RDIMM with 3200 MHz clock rate.
Table 1.
Hardware and software environment configuration for the experiments.
4.4. Parameter Setting
As shown in Table 2, the experimental setup includes 300 training epochs to ensure sufficient model convergence, with a batch size of 4, an initial learning rate set to 0.01, 8 CPU workers for data loading, and a Stochastic Gradient Descent (SGD) optimizer to drive the neural network training process. The momentum parameter was set to 0.937, and the weight decay was set to 0.0005.
Table 2.
Parameter setting for the experiments.
4.5. Evaluation Metrics
To comprehensively assess the localization, segmentation and lightweight performance of the manganese nodule segmentation model, two branches of accuracy metrics and efficiency indicators are adopted.
Detection and mask segmentation share six unified metrics: precision, recall, F1-score, mAP50, mAP75 and mAP50-95. Precision measures the suppression of background false positives, while recall reflects the capability to avoid missing dense overlapping nodules and the F1-score balances the two. mAP50 evaluates basic target matching under IoU = 0.5, mAP75 judges fine contour segmentation with strict IoU = 0.75, and mAP50-95 provides overall performance across full IoU intervals. These metrics are split into box detection and mask segmentation groups to quantify localization and pixel segmentation quality separately.
For lightweight evaluation, Params, GFLOPs and FPS are utilized. Params and GFLOPs reflect network spatial and computational complexity, and FPS characterizes real-time inference speed for underwater online deployment.
5. Results and Discussion
5.1. Ablation Study
To investigate the independent efficacy and collaborative interaction of the three proposed blocks C3k2-PConv, WSCA and Converse2D within the YOLOv11-n instance segmentation framework, we perform ablation experiments under identical training configurations. All quantitative results are presented in Table 3: “√” represents enabling the corresponding component, and “−” denotes disabling it. Module A = C3k2-PConv, Module B = WSCA, and Module C = Converse2D. Detection metrics evaluate bounding box localization, and segmentation metrics assess mask prediction quality. mAP50, mAP75 and mAP50-95 correspond to average precision under IoU thresholds of 0.5, 0.75 and the range from 0.5 to 0.95, respectively. Params and GFLOPs denote model parameter quantity and computational complexity, while FPS reflects the real-time inference speed of the model.
Table 3.
Ablation experiment results.
Group 1 corresponds to the original YOLOv11-n baseline without any improved components, which constructs a complete performance benchmark covering detection and segmentation quality as well as model scale and inference speed. All subsequent experimental groups are compared against this baseline to identify the performance fluctuation rules brought by single or stacked modules.
When only C3k2-PConv is introduced in Group 2, the module’s lightweight structural design effectively reduces model parameters and GFLOPs. Its FPS reaches 96, slightly lower than the baseline of 117, illustrating that reduced theoretical GFLOPs do not guarantee practical runtime speedup on desktop GPU hardware. From detection indicators, the improved mAP50, mAP75 and mAP50-95 demonstrate that this block strengthens feature extraction for coarse and strict boundary box localization. However, the simultaneous decline in mask precision, recall, F1 and all mask AP metrics reveals that the structural compression for lightweight inevitably damages the feature representation required for delicate mask prediction, forming a clear trade-off between detection optimization, segmentation degeneration and inference speed.
Solely deploying WSCA in Group 3 achieves synchronous performance promotion across nearly all detection and segmentation metrics without additional computational overhead. This group achieves the highest FPS of 121 among all settings, outperforming the baseline in both accuracy and inference speed. The growth of detection recall and F1 reflects that the attention mechanism of WSCA recovers missed target features to boost localization completeness. Meanwhile, the consistent elevation of mask recall, F1, mAP50, mAP75 and mAP50-95 verifies that this block enhances multi-scale feature modeling, which benefits both target localization and high-fidelity mask contour reconstruction under strict IoU thresholds.
Standalone Converse2D in Group 4 barely disturbs detection recall and comprehensive AP metrics, while slightly lifting detection precision. This module brings the lowest FPS of 77, introducing extra computational burden for mask detail optimization. The core optimization effect concentrates on the segmentation branch: the simultaneous rise in mask mAP75 and mAP50-95 indicates that Converse2D focuses on repairing high-IoU mask edge details, without sacrificing the original target localization capacity of the backbone network.
The combination of C3k2-PConv and WSCA in Group 5 retains the lightweight advantage of C3k2-PConv, yet partial detection indicators including mAP75 suffer mild attenuation compared with WSCA alone, with an FPS of 107 close to the baseline. Fortunately, all segmentation metrics maintain the upper level achieved by single WSCA. This phenomenon proves that C3k2-PConv’s lightweight compression partially offsets WSCA’s feature enhancement on high-IoU box localization, while the mask feature representation optimized by WSCA is robust against structural compression.
The stacked structure of C3k2-PConv and Converse2D in Group 6 fails to generate mutual compensation, with an FPS of 88. The lightweight compression of C3k2-PConv weakens the mask detail refinement effect of Converse2D, resulting in synchronous declines of detection mAP75 and all mask AP indicators. It can be concluded that the two modules possess conflicting optimization orientations and lack positive synergistic interaction.
The combination of WSCA and Converse2D in Group 7 delivers the optimal comprehensive segmentation performance among all ablation groups, and its FPS is 87. WSCA provides global multi-scale feature enhancement, and Converse2D further refines mask high-IoU details, leading to peak mask mAP50-95 and competitive mask mAP75. In addition, all detection indicators are stably maintained at a high level, which fully demonstrates the potential complementary trends between the two mask-oriented modules under this single training realization.
The full model integrating three blocks in Group 8 inherits the lightweight property of C3k2-PConv and realizes the maximum detection mAP50 across all groups, with an FPS of 88 comparable to Group 6. It should be explicitly noted that the reported 88 FPS is tested on desktop RTX 3090. Params and GFLOPs are theoretical complexity indicators, which are necessary but insufficient prerequisites for embedded real-time execution. Benefiting from the synergy of WSCA and Converse2D, all mask metrics remain competitive. Although mask comprehensive AP is slightly lower than the data of Group 7, under the present single-run experimental outcome, this integrated scheme achieves the optimal balance covering localization precision, mask quality and computational overhead, which is more suitable for practical deployment scenarios with limited hardware resources.
5.2. Comparison with State-of-the-Art Methods
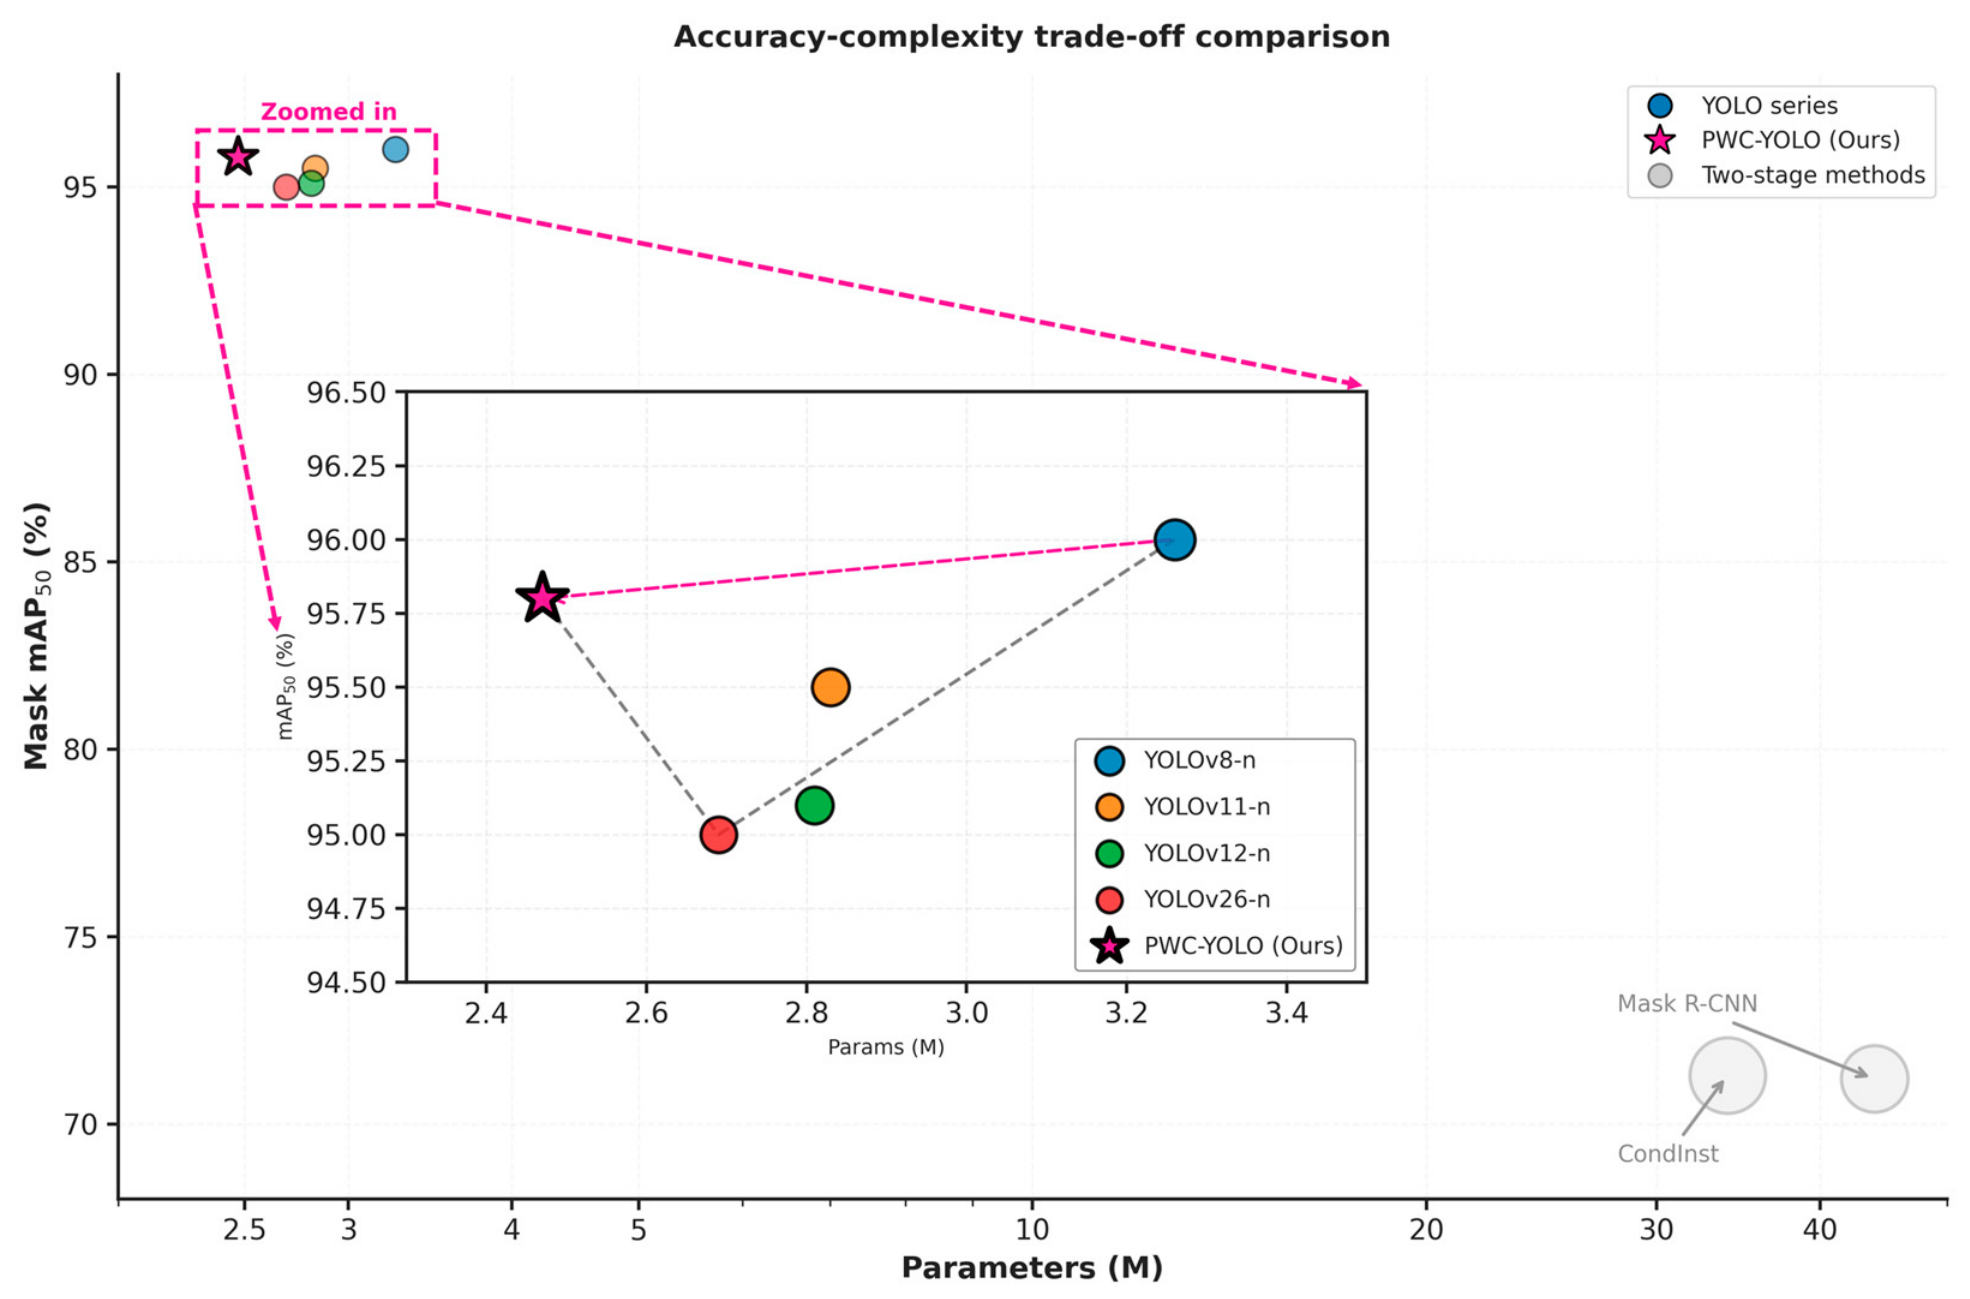
To further verify the performance of the proposed PWC-YOLO for deep-sea polymetallic nodule instance segmentation, comprehensive comparative experiments are conducted against mainstream one-stage lightweight YOLO-series models (YOLOv8-n, YOLOv11-n, YOLOv12-n, YOLOv26-n) and classical two-stage instance segmentation approaches including Mask R-CNN [31] and CondInst [32]. Quantitative experimental results are reported in Table 4, and the accuracy–complexity Pareto trade-off of all competing models is visualized in Figure 10.
Table 4.
Comparison of detection performance of different SOTA models on the deep-sea polymetallic nodule dataset.
Figure 10.
Performance–parameter trade-off of instance segmentation methods on the deep-sea polymetallic nodule dataset.
Compared with the two-stage Mask R-CNN and CondInst, our method achieves prominent advantages in model complexity: the number of parameters is only 2.47 M and GFLOPs reaches 9.3, which is far lower than those of Mask R-CNN and CondInst. Although Mask R-CNN and CondInst obtain higher precision values, they suffer from obvious recall degradation and extremely heavy computational overhead, and their mask mAP50-95 only reaches 52.3 and 54.5, respectively, which cannot satisfy real-time underwater deployment requirements.
In comparison with other lightweight YOLO-n variants, PWC-YOLO obtains competitive bounding-box detection performance. Specifically, our model yields the mask mAP50 of 95.8% and mask mAP75 of 83.1% and obtains a competitive mask mAP50-95 of 72.3%. Meanwhile, PWC-YOLO attains the smallest parameter size and computational cost among all compared YOLO-n models and maintains an acceptable inference FPS of 88. As illustrated in the zoom-in sub-plot of Figure 10, PWC-YOLO obtains competitive segmentation accuracy under the minimal model size.
To further explore the cross-domain generalization of PWC-YOLO, additional comparative experiments are conducted on the public UIIS underwater instance segmentation dataset [33], as reported in Table 5. PWC-YOLO still exhibits competitive performance against other two-stage Mask R-CNN, CondInst and lightweight YOLO-n variants. On this independent underwater dataset with different imaging characteristics, the result indicates that the proposed module designs can adapt well to variable underwater imaging conditions beyond the deep-sea polymetallic nodule scenes.
Table 5.
Comparison of detection performance of different SOTA models on UIIS dataset [33].
Experimental results demonstrate that PWC-YOLO achieves an excellent trade-off between segmentation accuracy, model parameters and inference speed for deep-sea polymetallic nodule segmentation tasks.
5.3. Visualization of Detection Results
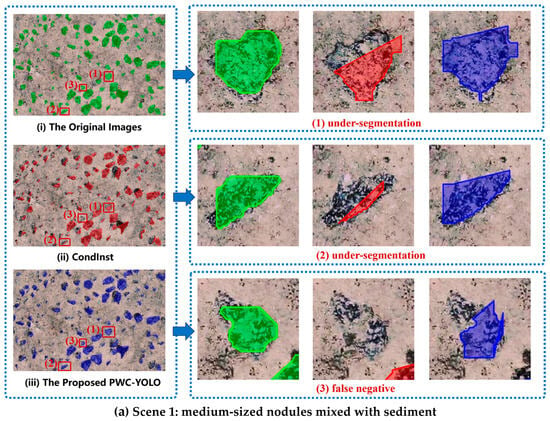
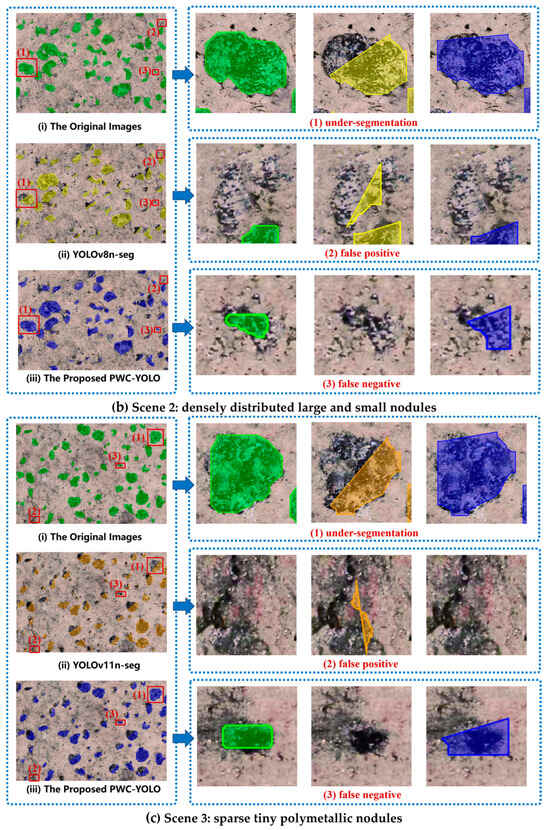
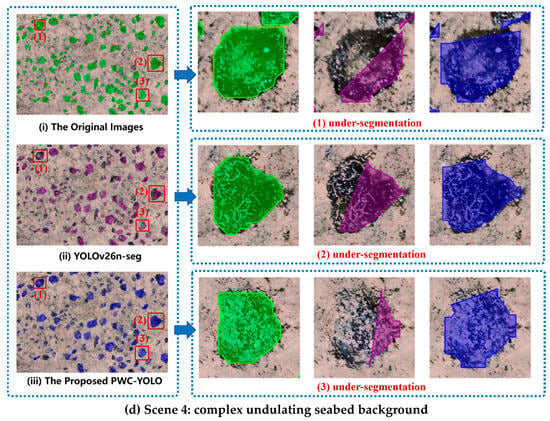
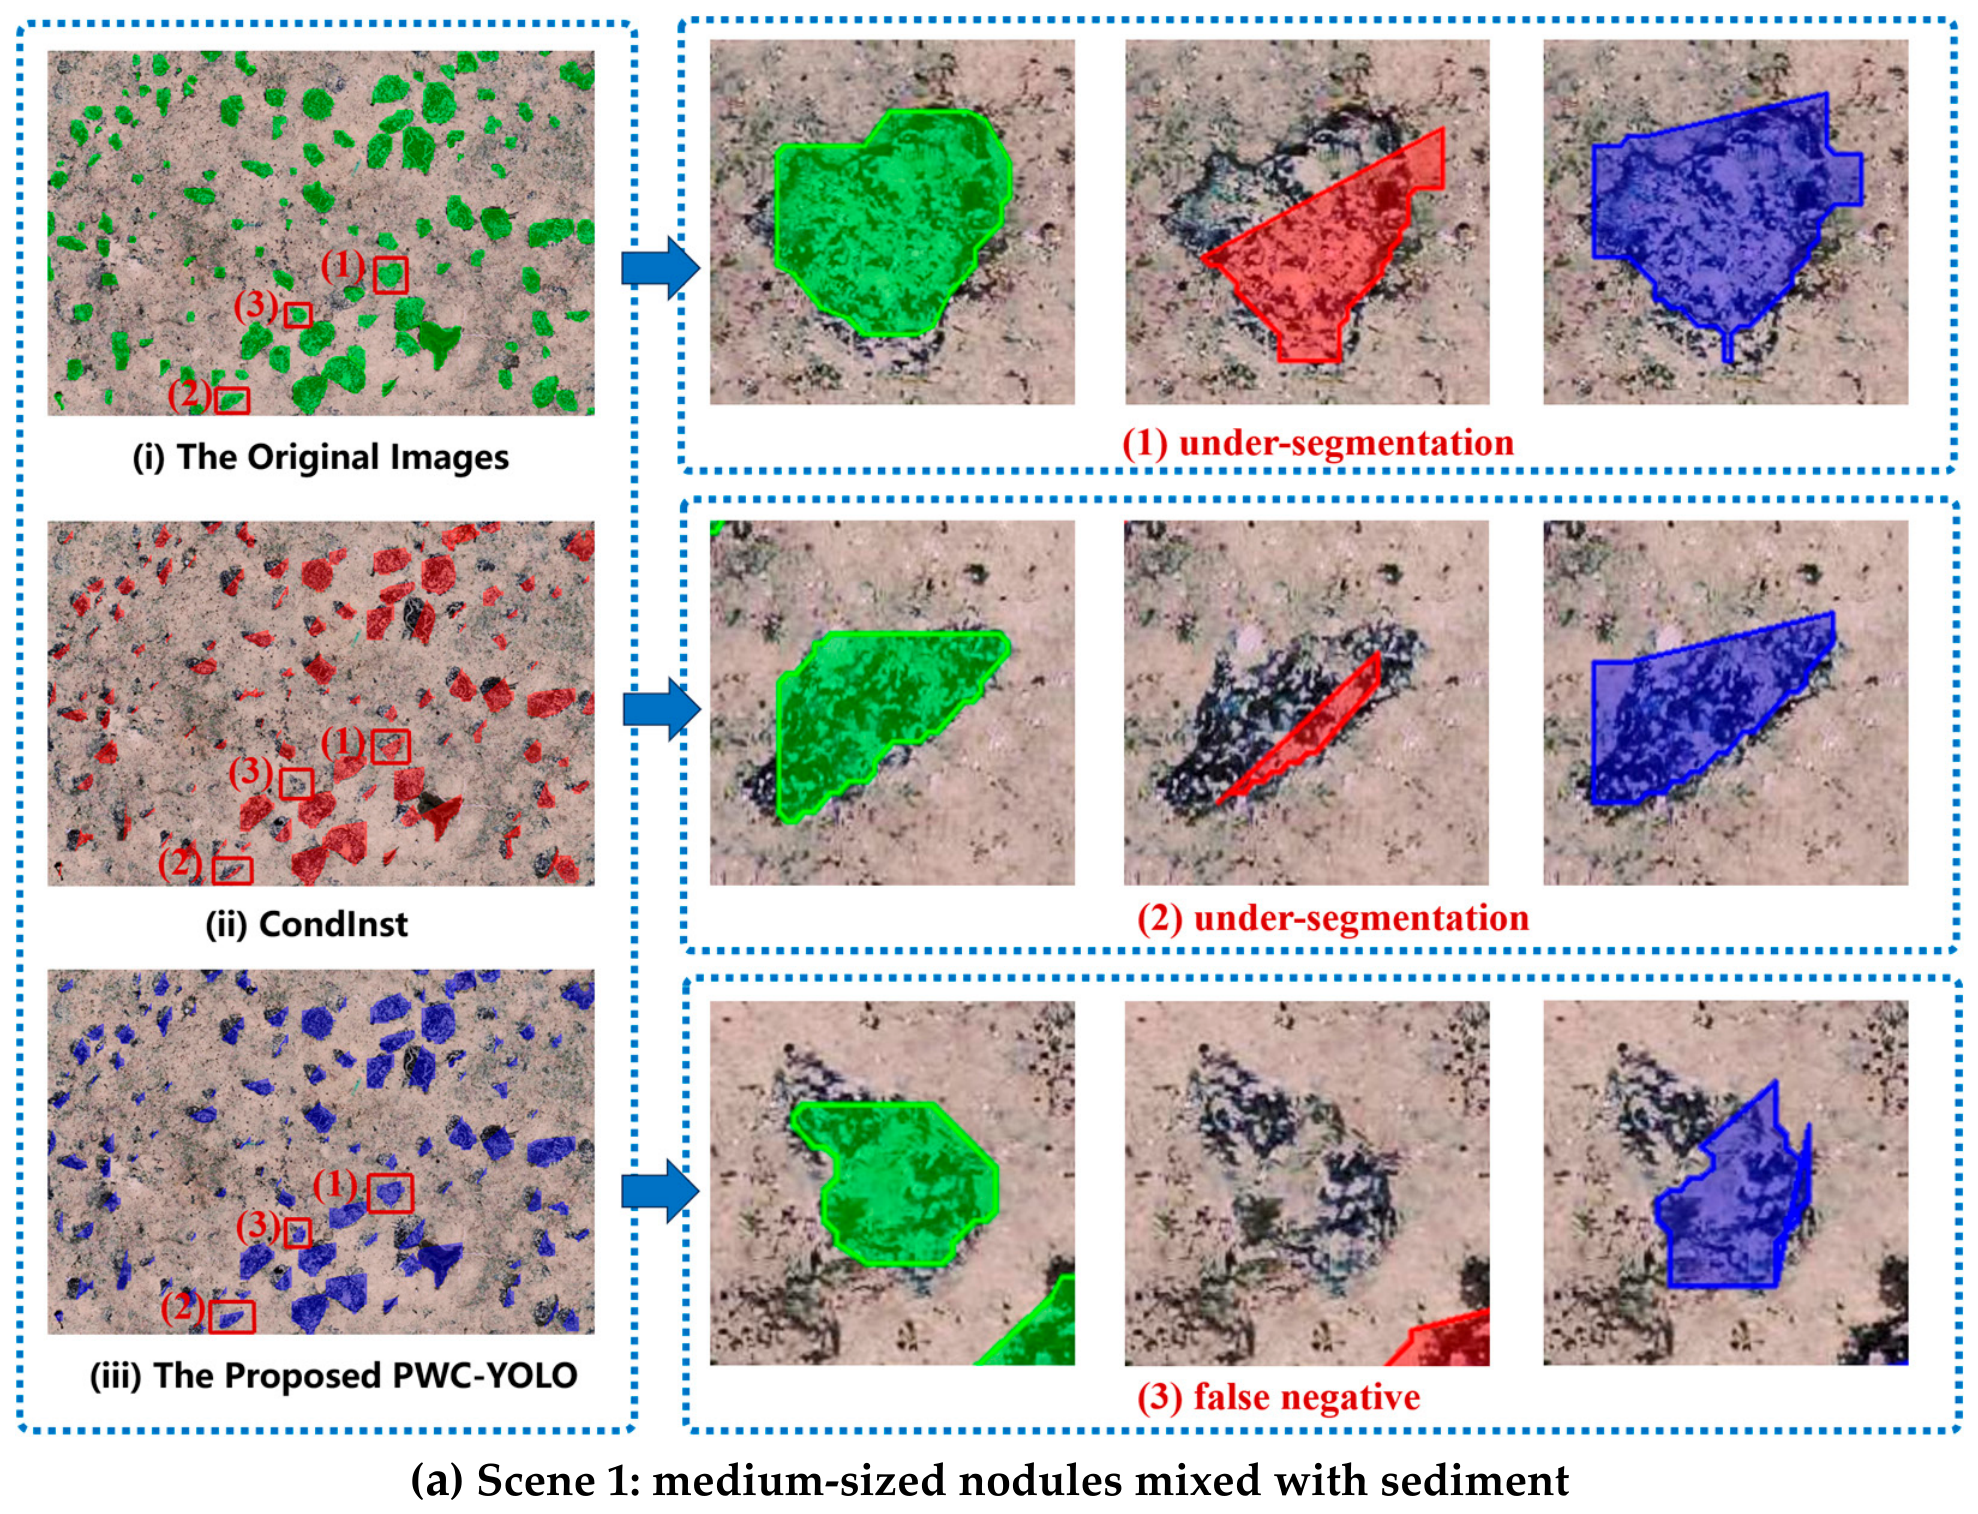
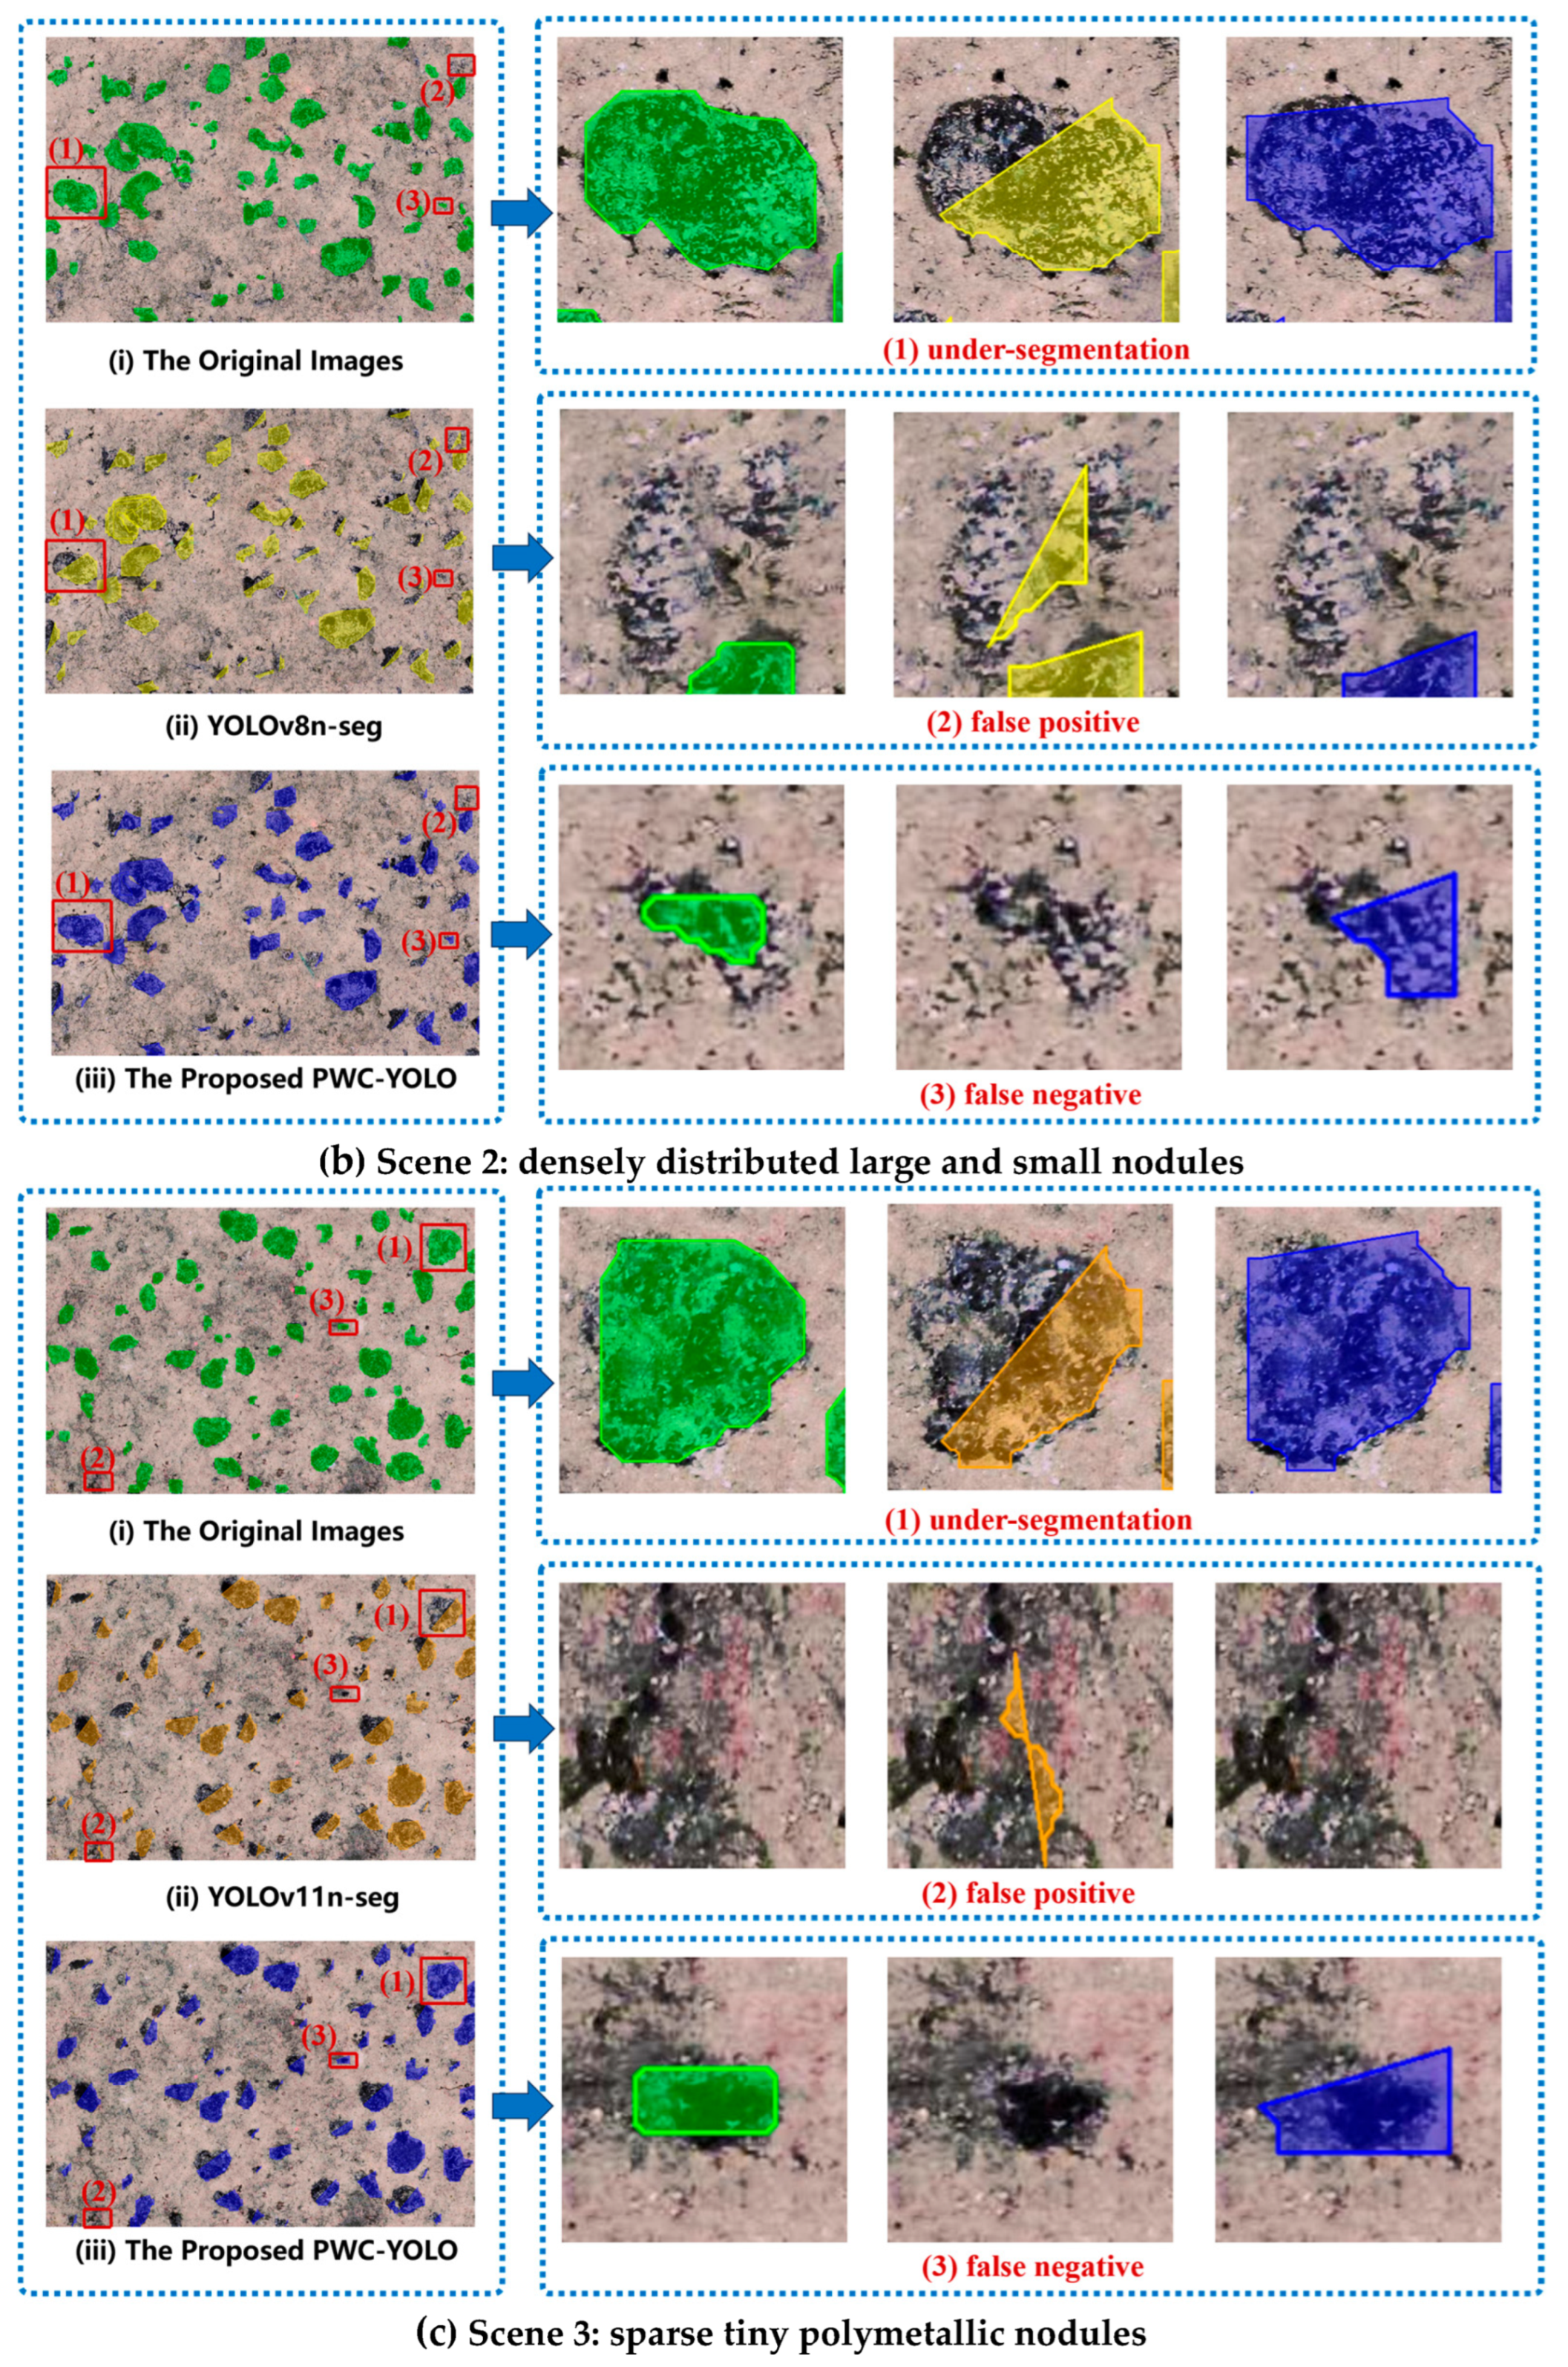
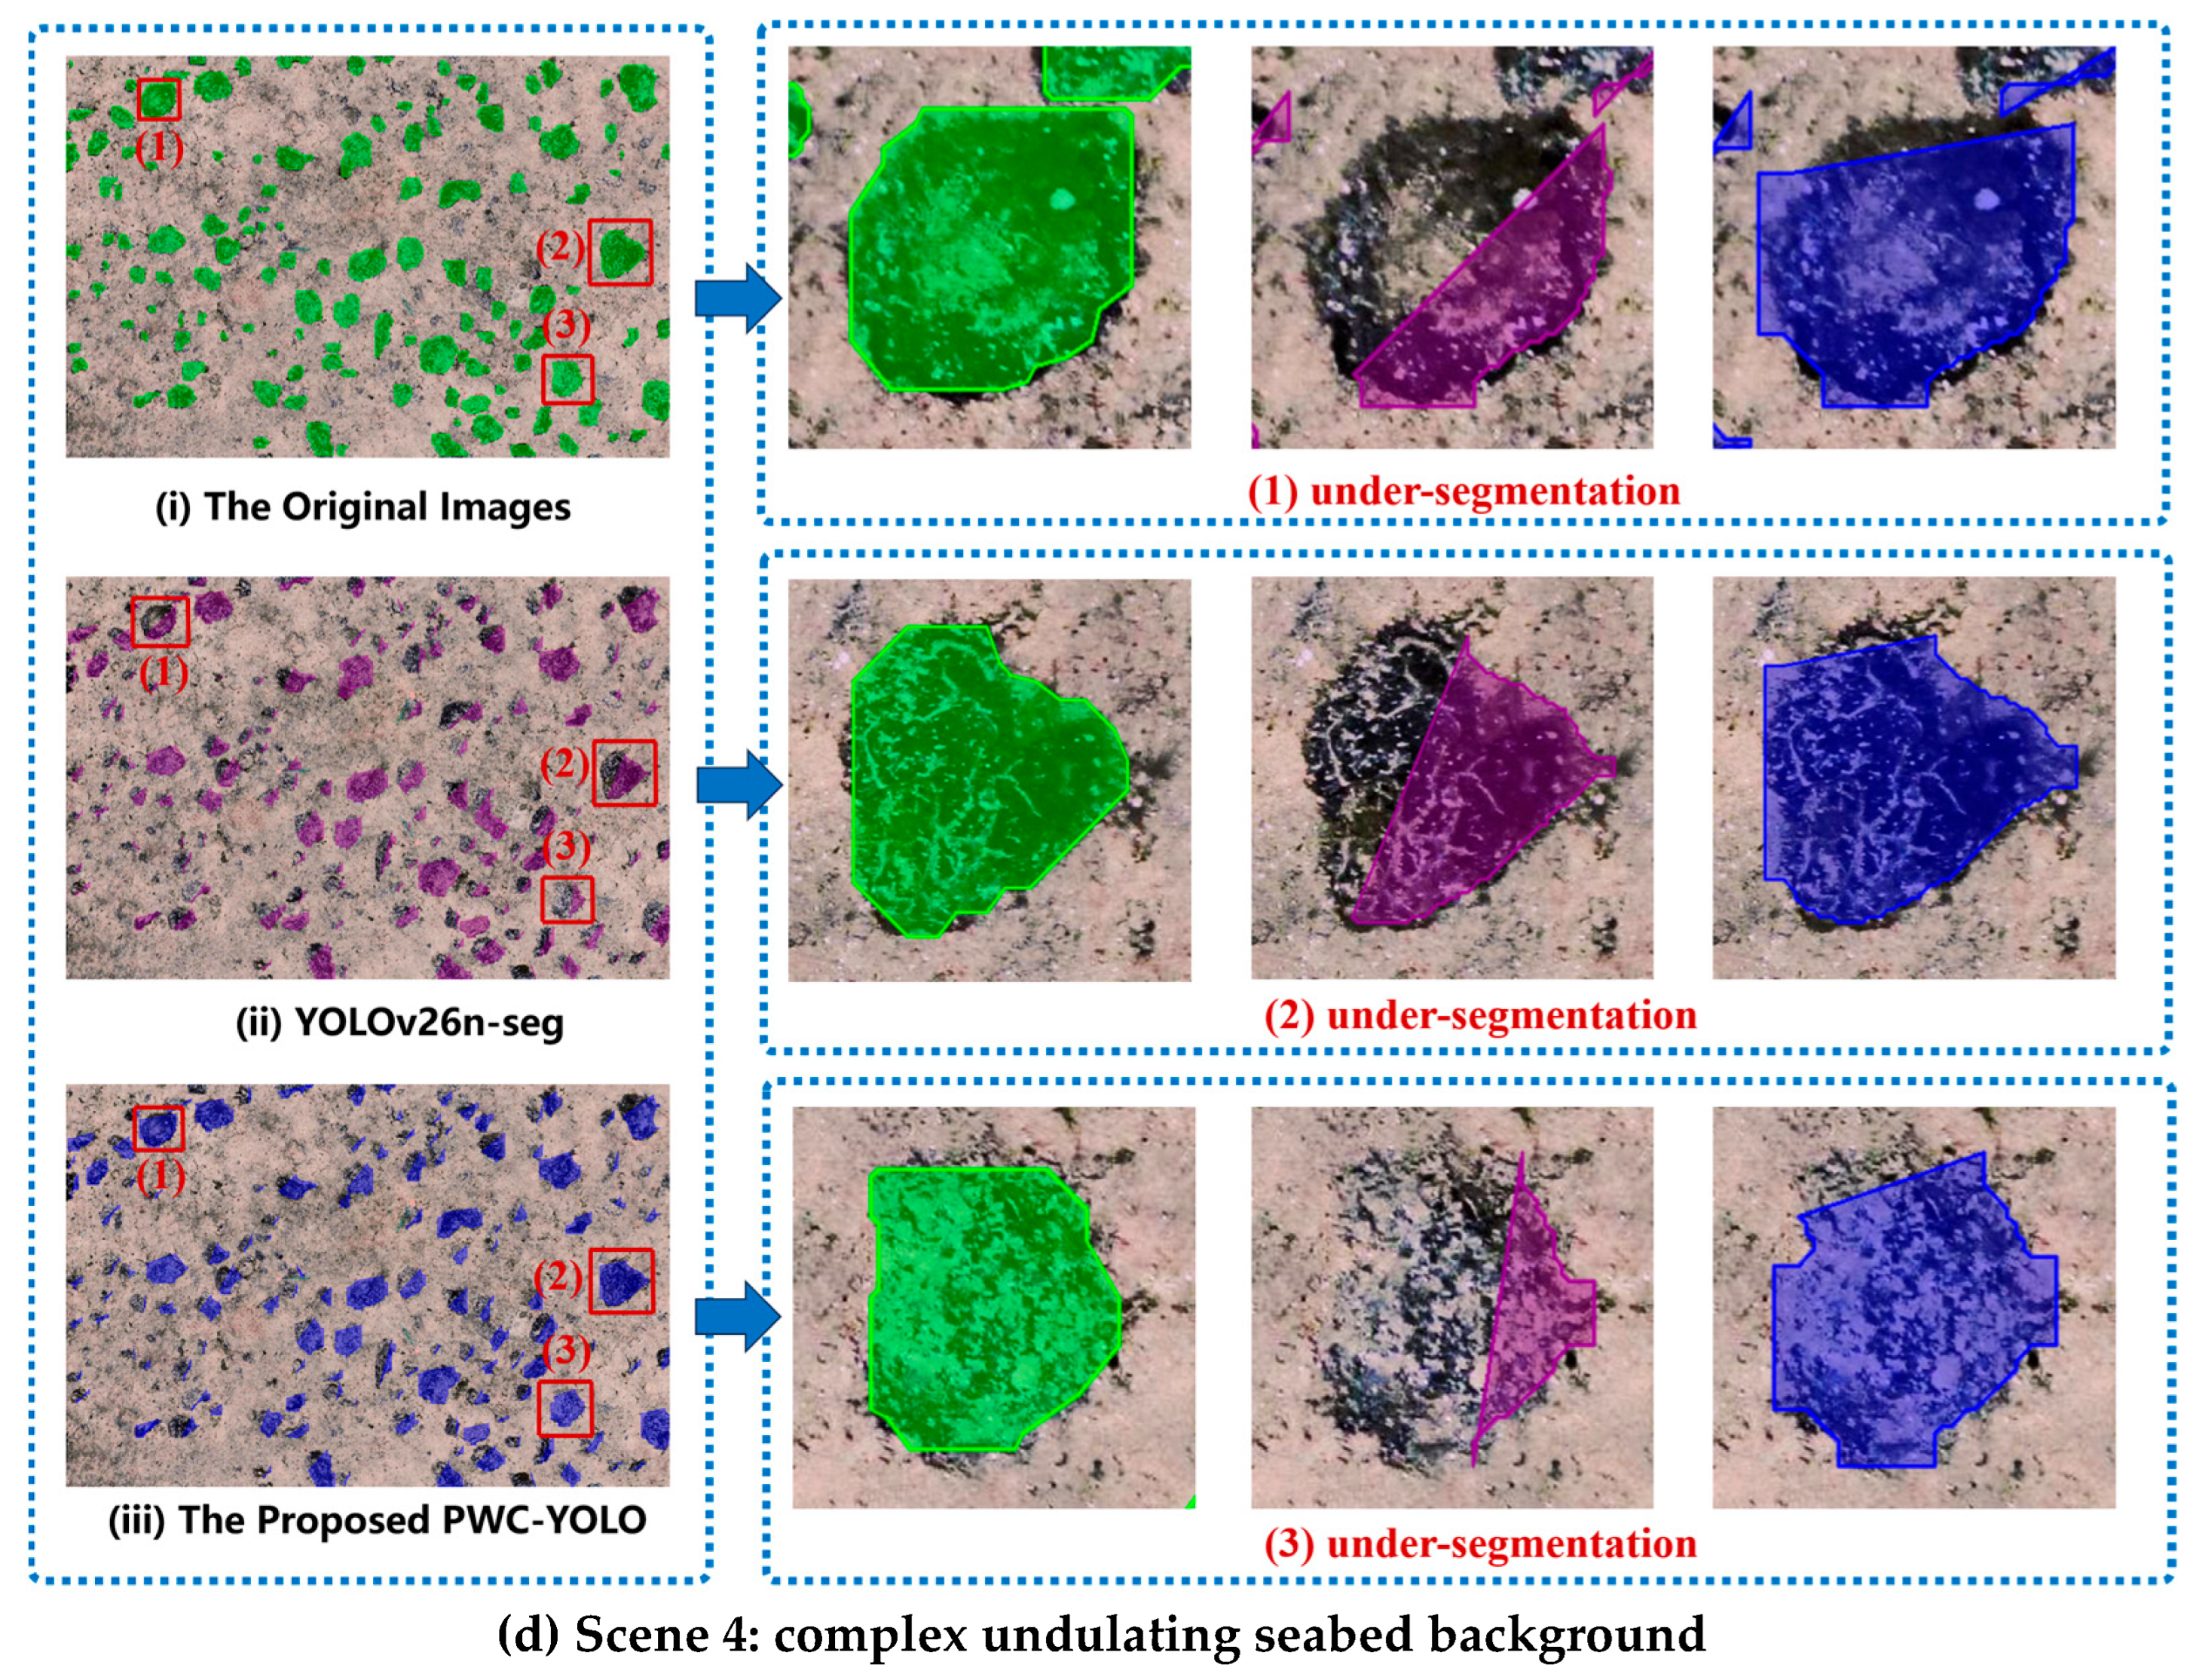
Figure 11 qualitatively compares the instance segmentation performance of various algorithms on four typical deep-sea seabed scenes with different nodule sizes, densities and background noise. The four scene groups (a)–(d) are assigned separate comparison titles, and each group consists of three subpanels marked -i, -ii and -iii: -i denotes the original seafloor image with ground truth masks; -ii presents segmentation outputs of mainstream SOTA models including CondInst, YOLOv8n-seg, YOLOv11n-seg and YOLOv26n-seg; and -iii displays the prediction results of our proposed lightweight PWC-YOLO model.
Figure 11.
Qualitative instance segmentation comparison of polymetallic nodules under the deep-sea seabed scenes.
- (a)
- Scene 1: Segmentation comparison of medium-sized nodules mixed with sediment.
- (b)
- Scene 2: Segmentation comparison of densely distributed large and small nodules.
- (c)
- Scene 3: Segmentation comparison of sparsely distributed tiny polymetallic nodules.
- (d)
- Scene 4: Segmentation comparison of nodules under complex undulating seabed background.
From subpanels (a)-ii to (d)-ii, CondInst, YOLOv8n-seg, YOLOv11n-seg and YOLOv26n-seg all exhibit obvious segmentation defects across all test scenes. These contrast models suffer from incomplete nodule contour extraction, false-positive detection of seabed sediment, and severe missed detection of micro-scale nodules. Benefiting from the lightweight C3k2-PConv module, WSCA, and Converse2D detail-reconstruction upsampling, the PWC-YOLO in (a)-iii to (d)-iii generates complete, smooth and accurate segmentation masks. The proposed method effectively suppresses background clutter interference and fully retains subtle edge features of tiny nodules, showing overwhelming visual advantages over the selected state-of-the-art segmentation algorithms.
5.4. Analysis of Counting Errors Under Different Nodule Density Grades
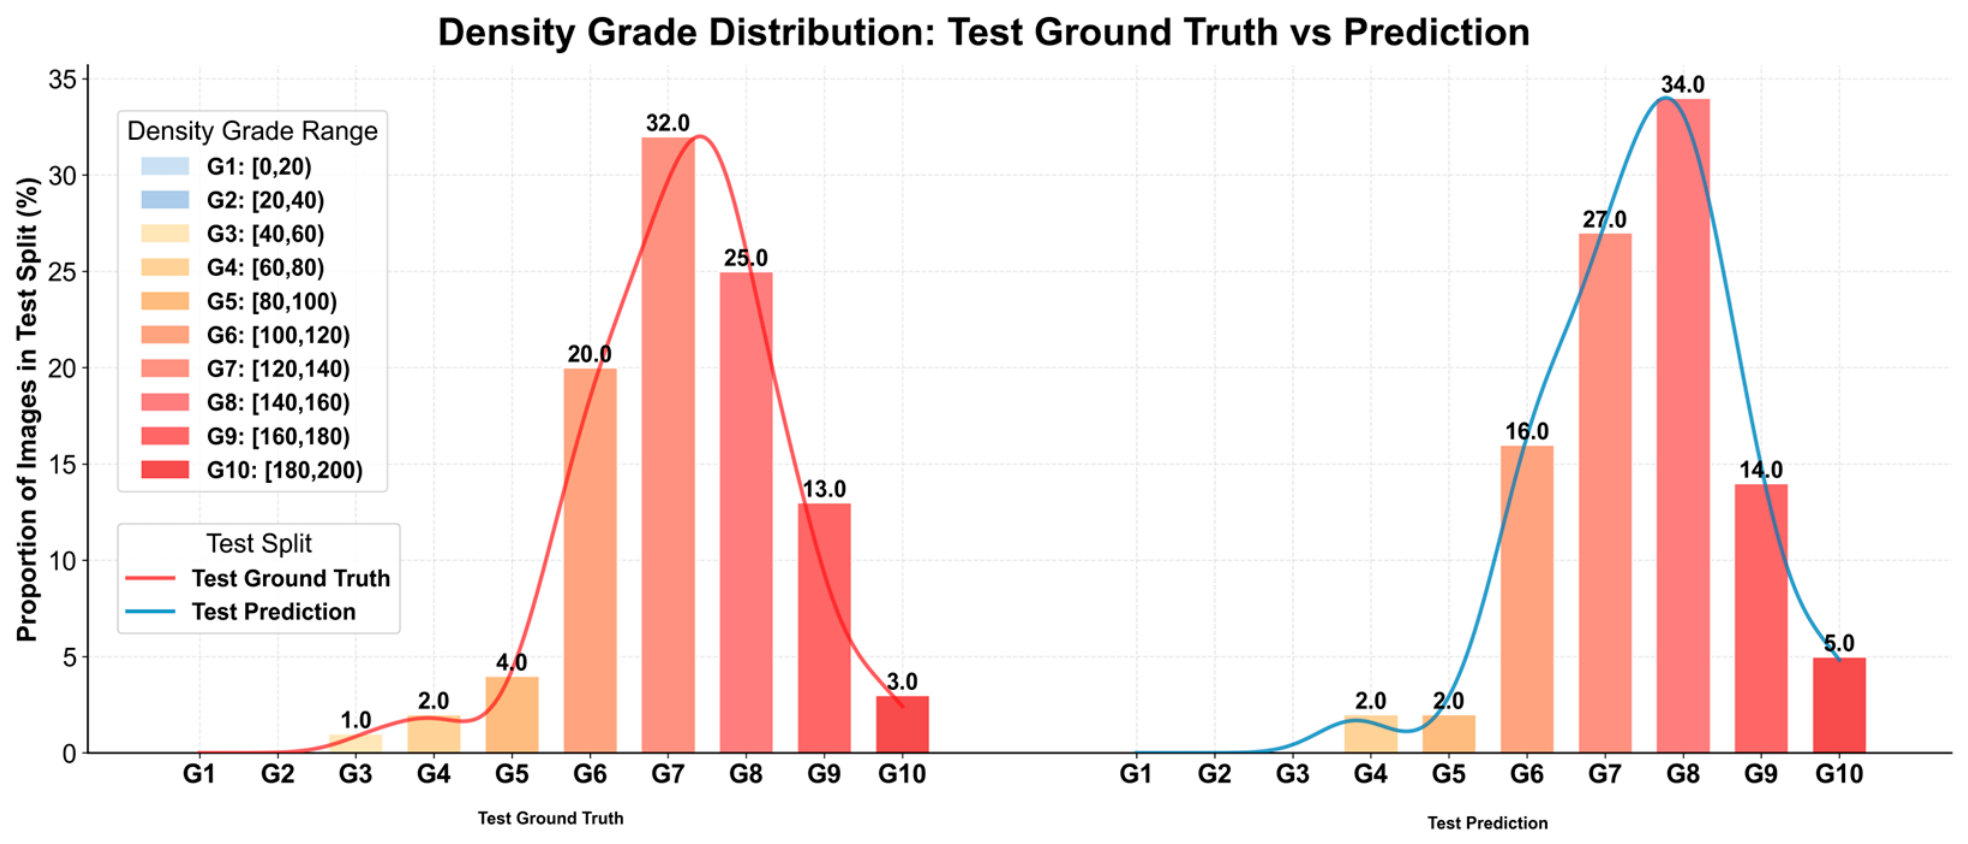
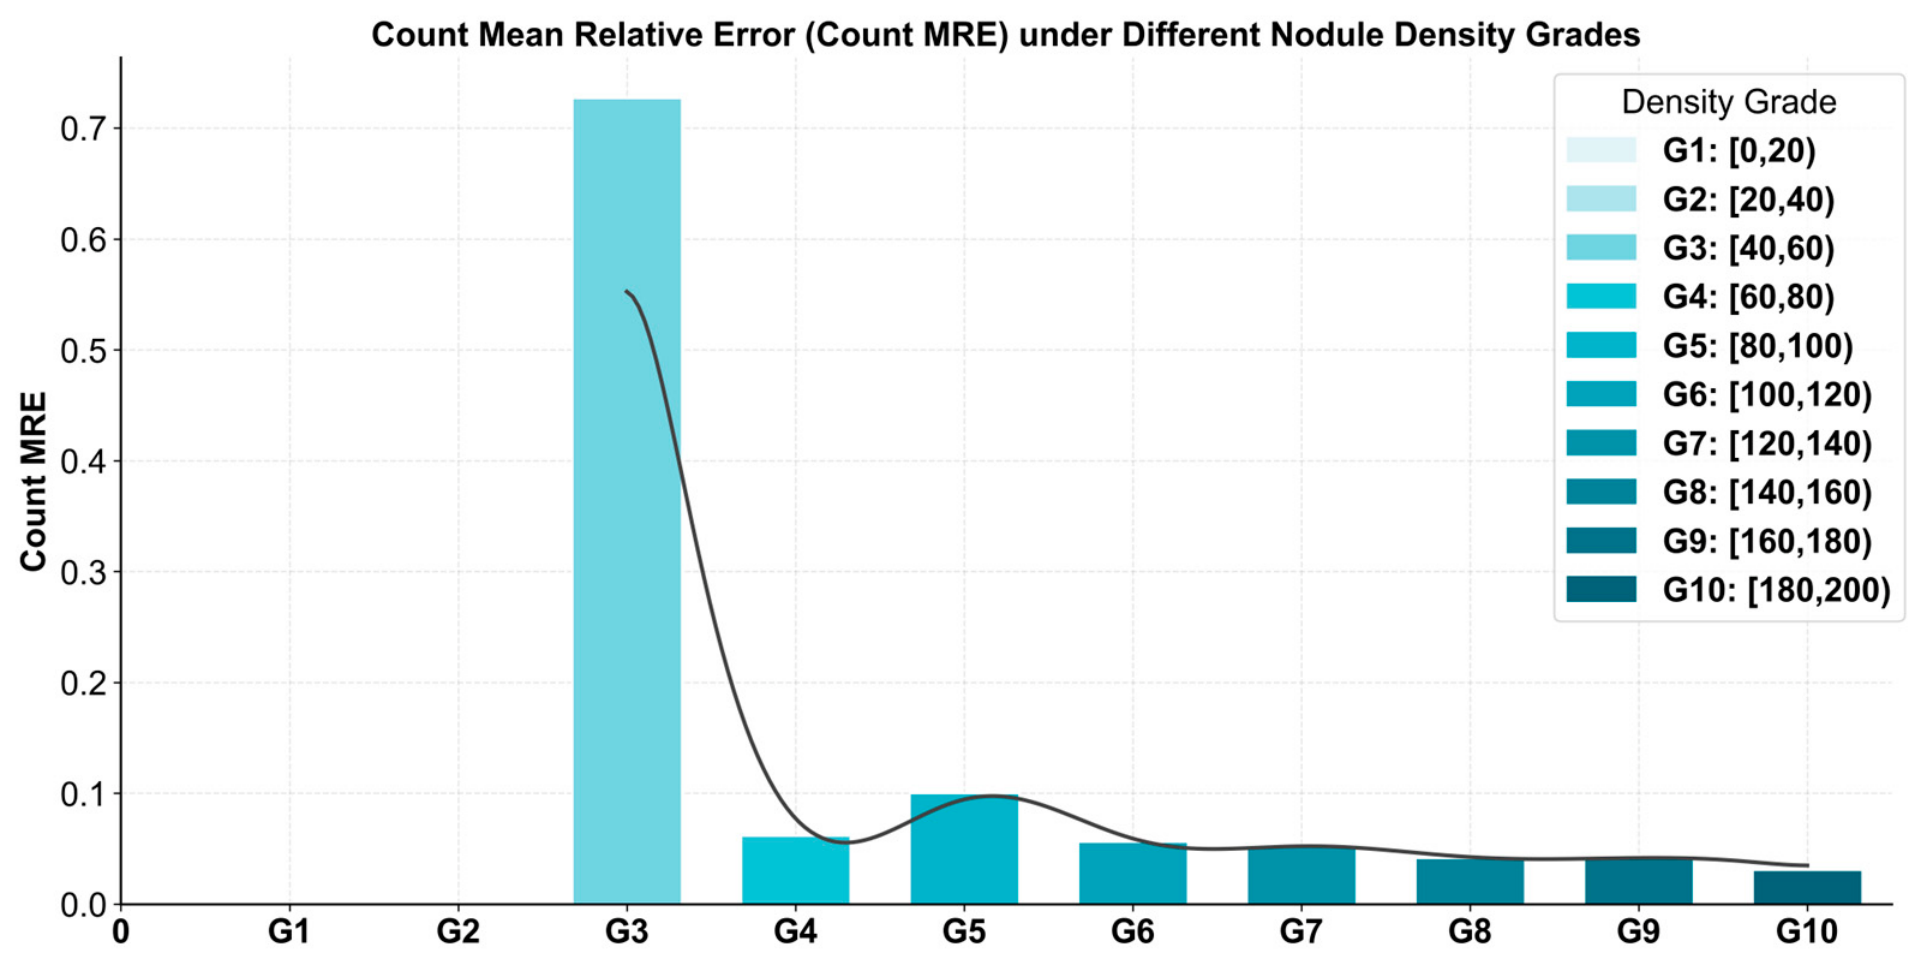
To further evaluate the performance of the proposed model for abyssal nodule resource estimation, we divided the test set into ten density grades (G1–G10) according to the number of nodules within each image. Stratified analysis was conducted from two perspectives: distribution consistency and counting relative error. Figure 12 compares the proportion distribution of ground truth and prediction across all density grades. The overall trend of the predicted density distribution is consistent with the ground truth, demonstrating that the model can capture the nodule abundance distribution of the test set. Nevertheless, the peak of the predicted distribution shifts slightly in high-density regions, indicating that target adhesion in crowded scenes interferes with instance segmentation and counting.
Figure 12.
Distribution of test images over nodule density grades: ground truth versus model prediction.
Figure 13 shows the count mean relative error (Count MRE) for each density grade. The Count MRE is relatively high at the low-density grade G3, which is mainly attributed to the limited number of samples in this group; a small amount of mis-segmentation can greatly amplify the relative error. As the nodule density increases (G4–G10), Count MRE decreases rapidly and remains at a low level. The results demonstrate that the proposed model can stably identify and count nodule instances under medium- and high-density conditions, showing promising potential to support abyssal nodule abundance assessment.
Figure 13.
Count mean relative error across nodule density grades.
6. Conclusions
Aiming at the challenges of low-contrast, dense overlapping targets, complex seabed background interference and limited computing resources for deep-sea polymetallic nodule instance segmentation, this paper proposes an improved lightweight instance segmentation model PWC-YOLO based on YOLOv11-n-seg. Three targeted structural optimizations are elaborated: the C3k2-PConv lightweight feature extraction module built with partial convolution, the WSCA replacing C2PSA original self-attention, and Converse2D reverse convolution upsampling for fine contour reconstruction.
A self-annotated dataset containing 1000 standardized CCZ seabed optical images is constructed for model training and evaluation. Ablation experiments verify that each improved component brings positive gains to segmentation performance, and the combination of the three modules realizes a favorable trade-off between segmentation accuracy, model size and inference speed. The complete PWC-YOLO model reaches 95.2% BBox mAP50 and 95.8% mask mAP50, with 2.47 M Params, 9.3 GFLOPs and 88 FPS, balancing localization precision, mask detail reconstruction and real-time inference capability. Comparative experiments with mainstream one-stage and two-stage segmentation models demonstrate that PWC-YOLO achieves a competitive mask mAP50-95 with the fewest parameters and GFLOPs among evaluated lightweight segmentation models. PWC-YOLO provides potential prerequisites for future lightweight deployment on underwater edge computing hardware. Visual comparison results on four typical tested deep-sea scenes further prove that the proposed model effectively avoids under-segmentation, false positives and missed detection of micro-nodules under complex sediment interference for these investigated seafloor conditions.
This study has several inherent constraints. Limited by incomplete geospatial and transect metadata of the annotated subset, reliable cross-transect generalization evaluation cannot be performed. All experimental results are obtained from single training runs, and the seafloor images used have undergone illumination preprocessing. Further validation of the WSCA module, embedded edge deployment tests and extended marine science evaluation metrics remain open for future exploration. Future work will adopt semi-supervised learning to reduce labeling effort, fuse hyperspectral information to improve detection of semi-buried nodules, and conduct these supplementary experiments to promote practical onboard detection for deep-sea mining.
Author Contributions
X.L.: Conceptualization, Data Curation, Formal Analysis, Investigation, Methodology, Software, Writing—Original Draft, Writing—Review and Editing; H.J.: Conceptualization, Data Curation, Funding Acquisition, Formal Analysis, Investigation, Methodology, Writing—Original Draft, Writing—Review and Editing; F.Q.: Project Administration, Supervision, Writing—Review and Editing; B.Y.: Validation, Visualization; D.F.: Funding Acquisition, Project Administration, Resources, Supervision; M.Y.: Funding Acquisition, Investigation; G.L.: Validation, Visualization. All authors have read and agreed to the published version of the manuscript.
Funding
This research was financially funded by National Natural Science Foundation of China-Liaoning Joint Fund (U21A20106), the National Natural Science Foundation of China (62003335), the Natural Science Foundation of Liaoning Province (2019-KF-03-03), the Youth Innovation Promotion Asso-ciation of the Chinese Academy of Sciences (2023209), and the Fundamental Research Project of SIA (2024JC2G08, 2022JC1K06).
Data Availability Statement
Data will be made available on request.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Hein, J.R.; Koschinsky, A.; Kuhn, T. Deep-ocean polymetallic nodules as a resource for critical materials. Nat. Rev. Earth Environ. 2020, 1, 158–169. [Google Scholar] [CrossRef] [Scilit]
- Hein, J.R.; Mizell, K.; Koschinsky, A.; Conrad, T.A. Deep-ocean mineral deposits as a source of critical metals for high- and green-technology applications: Comparison with land-based resources. Ore Geol. Rev. 2013, 51, 1–14. [Google Scholar] [CrossRef] [Scilit]
- Kuhn, T.; Wegorzewski, A.; Rühlemann, C.; Vink, A. Composition, formation, and occurrence of polymetallic nodules. In Deep-Sea Mining; Springer: Berlin/Heidelberg, Germany, 2017; pp. 23–63. [Google Scholar] [CrossRef] [Scilit]
- Wong, L.J.; Kalyan, B.; Chitre, M.; Vishnu, H. Acoustic assessment of polymetallic nodule abundance using sidescan sonar and altimeter. IEEE J. Ocean. Eng. 2020, 46, 132–142. [Google Scholar] [CrossRef] [Scilit]
- Almonacid, L.; Játiva, P.P.; Azurdia-Meza, C.A.; Dujovne, D.; Soto, I.; Firoozabadi, A.D.; Gaitan, M.G. On the path loss performance of underwater visible light communication schemes evaluated in several water environments. In 2023 South American Conference on Visible Light Communications; IEEE: New York, NY, USA, 2023; pp. 12–16. [Google Scholar] [CrossRef] [Scilit]
- Prabhakaran, K.; Varshney, N.; Ramesh, R.; Muthuvel, P.; Gopkumar, K.; Ramadass, G.A. Underwater image and video processing to detect polymetallic nodule abundance using haar-cascade and template matching feature. In Proceedings of the OCEANS; IEEE: New York, NY, USA, 2022; pp. 1–6. [Google Scholar] [CrossRef] [Scilit]
- Mbani, B.; Schoening, T.; Gazis, I.Z.; Greinert, J. Implementation of an automated workflow for image-based seafloor classification with examples from manganese-nodule covered seabed areas in the Central Pacific Ocean. Sci. Rep. 2022, 12, 15338. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Mbani, B.; Greinert, J. Analysis-ready optical underwater images of manganese-nodule covered seafloor of the Clarion-Clipperton Zone. Sci. Data 2023, 10, 316. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Schoening, T.; Jones, D.O.B.; Greinert, J. Compact-morphology-based polymetallic nodule delineation. Sci. Rep. 2017, 7, 13338. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, X.; Yu, F. An unsupervised multiple joint optimization method for underwater manganese nodule image enhancement. In Proceedings of the IEEE International Conference on Electrical, Automation and Computer Engineering; IEEE: New York, NY, USA, 2023; pp. 1632–1636. [Google Scholar] [CrossRef] [Scilit]
- Gazis, I.Z.; Schoening, T.; Alevizos, E.; Greinert, J. Quantitative mapping and predictive modeling of Mn nodules’ distribution from hydroacoustic and optical AUV data linked by random forests machine learning. Biogeosciences 2018, 15, 7347–7377. [Google Scholar] [CrossRef] [Scilit]
- Sun, K.; Wu, Z.; Wang, M.; Shang, J.; Liu, Z.; Zhao, D.; Luo, X. Accurate identification method of small-size polymetallic nodules based on seafloor hyperspectral data. J. Mar. Sci. Eng. 2024, 12, 333. [Google Scholar] [CrossRef] [Scilit]
- Wang, M.; Wu, Z.; Zhang, K.; Zhao, D.; Zhou, J.; Luo, X.; Shang, J.; Liu, Y. Mixed Seabed Sediment Classification Based on Transferred Convolutional Neural Network: A Case Study in the Ancient River Valley. IEEE Trans. Geosci. Remote Sens. 2023, 61, 4205116. [Google Scholar] [CrossRef] [Scilit]
- Vijayalakshmi, M.; Sasithradevi, A.; Muthuvel, P. NodYOLO-GAM: A hybrid multi-scale attention-enhanced CNN for real-time polymetallic nodule detection. Signal Image Video Process. 2025, 19, 1098–1106. [Google Scholar] [CrossRef] [Scilit]
- Hao, Y.; Yan, S.; Yang, G.; Luo, Y.; Liu, D.; Han, C.; Ren, X.; Du, D. Image segmentation and coverage estimation of deep-sea polymetallic nodules based on lightweight deep learning model. Sci. Rep. 2025, 15, 10177. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ding, Z.; Liu, C.; Wang, X.; Ma, G.; Cao, C.; Li, D. Semi-supervised learning network for deep-sea nodule mineral image segmentation. Appl. Ocean Res. 2025, 154, 104356. [Google Scholar] [CrossRef] [Scilit]
- Dong, L.; Wang, H.; Song, W.; Xia, J.; Liu, T. Deep sea nodule mineral image segmentation algorithm based on Mask R-CNN. In Proceedings of the ACM Turing Award Celebration Conference-China; Association for Computing Machinery: New York, NY, USA, 2021; pp. 278–284. [Google Scholar] [CrossRef] [Scilit]
- Ronneberger, O.; Fischer, P.; Brox, T. U-Net: Convolutional networks for biomedical image segmentation. In Proceedings of the Medical Image Computing and Computer-Assisted Intervention; Springer: Cham, Switzerland, 2015; pp. 234–241. [Google Scholar] [CrossRef] [Scilit]
- Ye, P.; Han, C.; Zhang, Q.; Gao, F.; Wu, G. An Application of Hyperspectral Image Clustering Based on Texture-Aware Superpixel Technique in Deep Sea. Remote Sens. 2022, 14, 5047. [Google Scholar] [CrossRef] [Scilit]
- Liu, X.; Yang, J.; Xu, W.; Liu, Y.; Wang, Y. DSM-Net: A multi-scale detection network of sonar images for deep-sea mining vehicle. Appl. Ocean Res. 2025, 158, 104551. [Google Scholar] [CrossRef] [Scilit]
- Tomczak, A.; Kogut, T.; Kabała, K.; Abramowski, T.; Ciążela, J.; Giza, A. Automated estimation of offshore polymetallic nodule abundance based on seafloor imagery using deep learning. Sci. Total Environ. 2024, 956, 177225. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Shao, M.; Song, W.; Zhao, X. Polymetallic Nodule Resource Assessment of Seabed Photography Based on Denoising Diffusion Probabilistic Models. J. Mar. Sci. Eng. 2023, 11, 1494. [Google Scholar] [CrossRef] [Scilit]
- Song, W.; Dong, L.; Zhao, X.; Liu, T.; Zheng, N. Review of nodule mineral image segmentation algorithms for deep-sea mineral resource assessment. Comput. Mater. Contin. 2022, 73, 1649–1669. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; Li, J.; Su, B.; Cui, Y. Subsea nodule recognition and deployment detection method based on improved YOLOv8s. IEEE Access 2025, 13, 70533–70547. [Google Scholar] [CrossRef] [Scilit]
- Drews, P., Jr.; Souza, I.; Maurell, I.P.; Barros, A. Underwater image segmentation in the wild using deep learning. J. Braz. Comput. Soc. 2021, 27, 12. [Google Scholar] [CrossRef] [Scilit]
- Chen, J.; Kao, S.-H.; He, H.; Zhuo, W.; Wen, S.; Lee, C.-H. Run, Don’t Walk: Chasing higher FLOPS for faster neural networks. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition; IEEE: New York, NY, USA, 2023; pp. 12021–12031. [Google Scholar] [CrossRef] [Scilit]
- Khanam, R.; Hussain, M. YOLOv11: An overview of the key architectural enhancements. arXiv 2024, arXiv:2410.17725. [Google Scholar] [CrossRef] [Scilit]
- Jegham, N.; Koh, C.Y.; Abdelatti, M.F.; Hendawi, A.M. YOLO Evolution: A comprehensive benchmark and architectural review of YOLOv12, YOLO11, and their previous versions. arXiv 2024, arXiv:2411.00201. [Google Scholar] [CrossRef] [Scilit]
- Scarrica, V.M.; Camastra, F.; Diodati, G.; Quaranta, V. Fault Detection in a Blower by Machine Learning-Based Vibrational Analysis. In Progresses in Artificial Intelligence and Neural Systems; Esposito, A., Faundez-Zanuy, M., Morabito, F., Pasero, E., Eds.; Smart Innovation, Systems and Technologies; Springer: Singapore; Volume 184. [Google Scholar] [CrossRef] [Scilit]
- Huang, X.; Liu, S.; Zhang, K.; Tai, Y.; Yang, J.; Zeng, H. Reverse Convolution and its Applications to Image Restoration. In Proceedings of the IEEE/CVF International Conference on Computer Vision; IEEE: New York, NY, USA, 2025; pp. 10507–10516. [Google Scholar] [CrossRef] [Scilit]
- He, K.; Gkioxari, G.; Dollár, P.; Girshick, R. Mask R-CNN. In Proceedings of the IEEE International Conference on Computer Vision; IEEE: New York, NY, USA, 2017; pp. 2980–2988. [Google Scholar] [CrossRef] [Scilit]
- Tian, Z.; Shen, C.; Chen, H. Conditional Convolutions for Instance Segmentation. In Proceedings of the European Conference on Computer Vision; Springer: Cham, Switzerland, 2020; pp. 282–298. [Google Scholar] [CrossRef] [Scilit]
- Lian, S.; Li, H.; Cong, R.; Li, S.; Zhang, W.; Kwong, S. WaterMask: Instance Segmentation for Underwater Imagery. In Proceedings of the IEEE International Conference on Computer Vision; IEEE: New York, NY, USA, 2023; pp. 1305–1315. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.