3.1. What Do We See and What Do We Not See When We Perceive a Square?
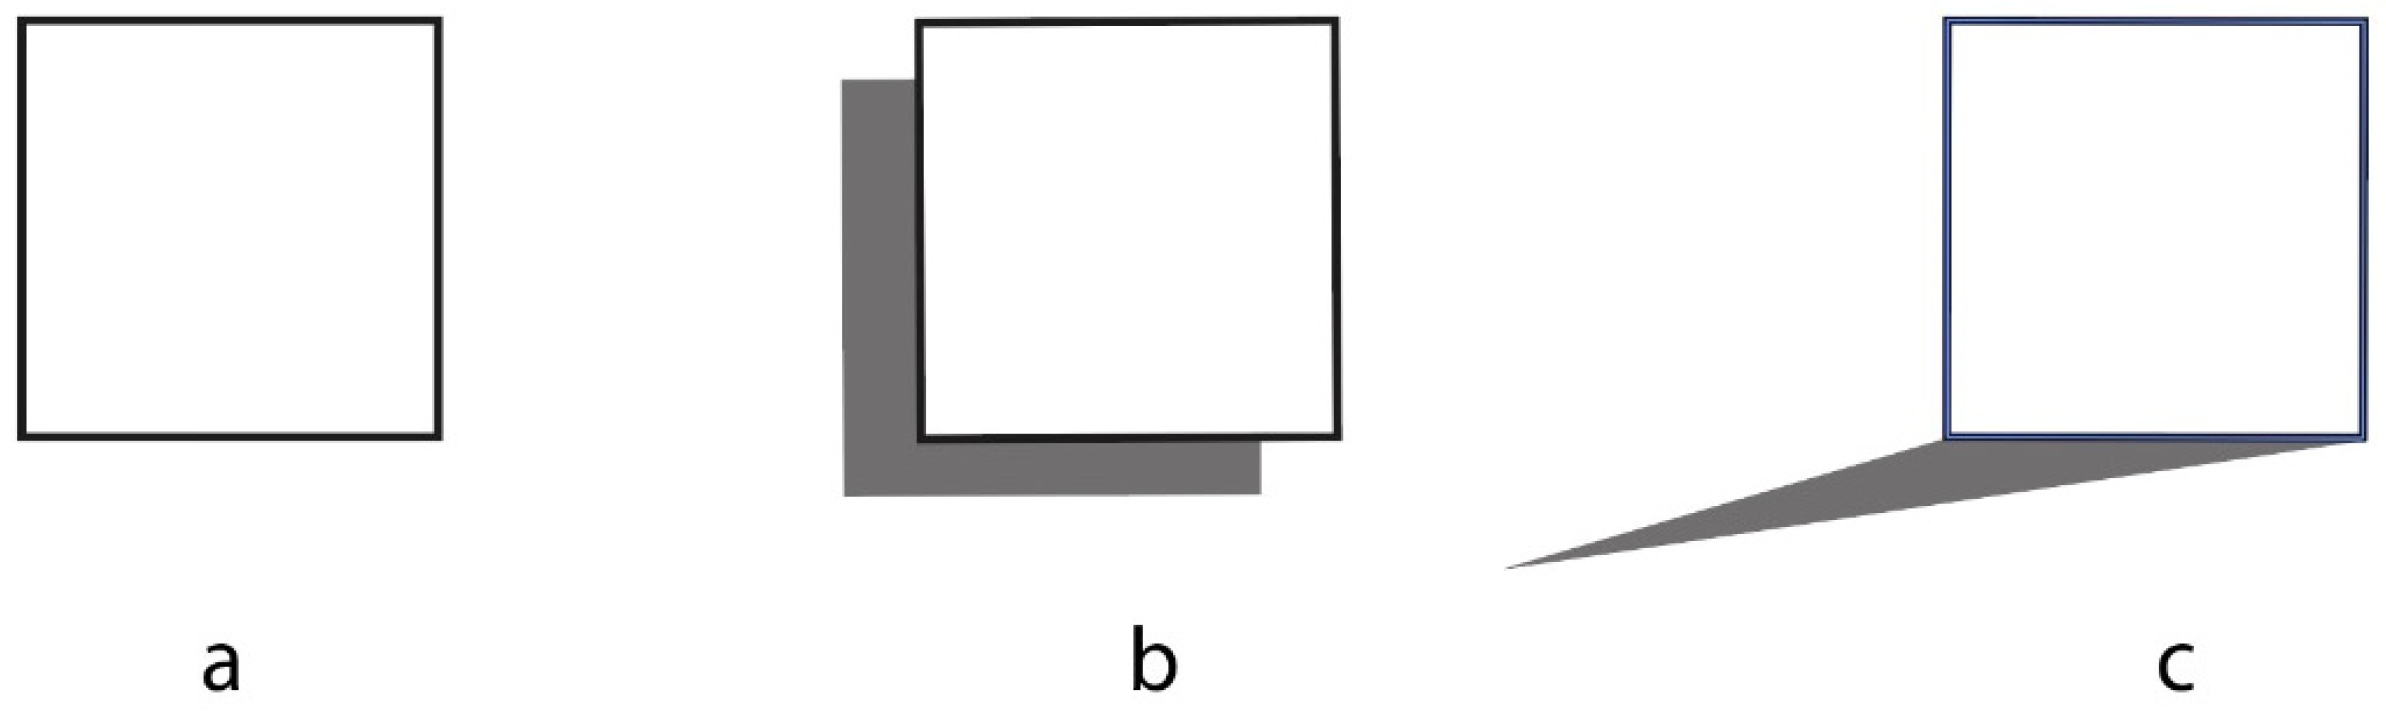
Figure 1a was spontaneously described very concisely by all subjects as a square. The word “square” denotes the object being observed and describes what is currently perceived and potentially perceivable.
The description “a square” is immediate, unambiguous, and unique. No other words are needed to describe what is seen and the fact that what is seen is a square. The term “square” indicates the name of the figure and, in particular, of the perceived shape that is a square. In other words, the description refers only and exclusively to the shape. Among the many possible attributes, the shape is the one first indicated by the description. The name of the perceived object refers to its shape [
25,
26,
27,
28].
This long series of specifications might appear excessively redundant. However, it can be understood if we ask what color the square is. Starting with such a question, the same subjects, who previously stopped at just the name, showed a clear surprise, becoming aware of the coexistence of a set of perceptual possibilities. The reader might experience the same impressions [
14].
The most likely answer is the following: the square is white. Immediately after, the same subjects added an alternative, albeit less immediate answer: it is transparent. A third, even less probable answer, was as follows: it is black. So, the square can be white, transparent, and black in decreasing order of immediacy. The three possible answers are placed in three layers of probable appearance. When asked to scale the visual salience of the three answers in percentage terms, the results were, respectively, as follows: 60%, 30%, and 10%.
To summarize, since the initial response included only and exclusively the shape of the object, this implies that shape is what emerges first. Color is not as immediate as shape. If the question posed to the subjects concerns the perceived color, the answer reveals a series of possibilities, with the least immediate being related to the color of the contours, which is the color of the shape. These preliminary results assume and suggest that the color of an object fills its internal region as a surface color. Despite the interior of the figure being as white as the background, within the shape the perceived color takes on qualities that have been defined as surface color [
29,
30]. Therefore, the interior does not appear empty but of a solid color different from that of the background (see [
6]).
Phenomenally, color is not necessarily mentioned by subjects. While shape is shown in the foreground of the appearance, color lies below the foreground. From a syntactic point of view, we can state that while shape represents the noun, color appears as its adjective. It is not an accident that we nominalize the shape and mark the color adjectivally by saying “a white square and not a square white”. “White” is in all languages regarded as an attribute of the shape, not the other way around. The asymmetry between the two expressions is clearly perceptible. We suggest that this asymmetry reflects the belonging of the two attributes to two different phenomenal layers.
By definition, a noun is a part of speech that identifies a thing. Nouns are fundamental in the structure of sentences because they serve as subjects, objects, and complements. This is the case of the shape. Meanwhile, an adjective is a part of speech that describes, qualifies, or specifies a characteristic of a noun. Adjectives provide additional information and can indicate quality, quantity, size, color, origin, and other properties of the nouns they refer to. Between shape and color, the latter assumes the role of an adjective and, as such, appears in the background of the shape and can be omitted.
One could then advance the following preliminary hypothesis, yet to be confirmed, according to which the syntactic structure of spontaneous descriptions might perhaps isomorphically reflect the phenomenological structure of appearance and immediacy of perceptual qualities.
The following results demonstrate what has just been stated. If the most immediate description of
Figure 1a is only and exclusively “a square”, when asking for a more detailed description, what subjects spontaneously add is “a white square”. Asking for an even more detailed description yields “a white square with black borders”. Proceeding further with the same question, the following responses are obtained: “a white square with black borders on a white background”, “a small white square with black borders on a white background”. At this point, the responses were exhausted. Despite being asked for more details, no further responses were provided.
It is worth noting that the color of the contours, and thus of the shape, in turn becomes an adjective just like the color of the square. Naturally, its position in the third plane demonstrates once again the spontaneous stratification of the phenomenology of appearance. It is fundamental to understand in what order the different perceptual qualities are arranged, which together give rise to the object in its completeness and complexity. It is crucial to ask not only how but also why the phenomenology of appearance is stratified in this way. To answer these questions, let us take further steps.
If the details provided by the subjects stop at the description of the shape and color of the square and of its contours, we must not forget a wide multiplicity of other properties visible indirectly or only a posteriori, after explicit suggestions from the experimenter. An example concerns the spatial arrangement of the square. After a clear suggestion, the mediated response from the subjects was: the square is lying on a horizontal plane. Less likely is the other possible answer: the square is standing upright, arranged in the third dimension perpendicular to the horizontal plane. In both descriptions, sketched, respectively, in
Figure 1b,c, both the presence and relative position of the observer are totally implicit, who looks from above in one case, while the other observes the square in fronto-parallel vision and close to the plane on which the square stands. Yet, while we look, we not only see the objects under observation but, in all cases, also ourselves fixating on them from a precise location in space. However, being able to see oneself during observation is something relegated even further down the phenomenal gradient of appearance. The implicit and almost invisible localization of the observer can be explained by assuming seeing as a sensory modality primarily aimed at exploring the external world, its objects, and their shapes.
It is worth noting that the emergence of a new element, totally invisible explicitly but implicitly or amodally visible, is the horizontal plane. It is generated by the square regardless of the perspective in which it appears. The square does not appear to levitate or gravitate in an empty space like a planet in the universe but is supported or lying on a plane. Space becomes an object, a solid horizontal plane that hosts the square. This also occurs when the square is seen in a two-dimensional space, which is possible although less likely than the other two previously described. Under these conditions, it appears flattened on a background that is still seen as a solid flat surface containing the square.
We can therefore suggest that while in the case of color and spatial arrangement of the square, both three-dimensional and two-dimensional, we are faced with visible attributes that are nevertheless invisible or not immediately visible. In the case of the horizontal plane, it is an invisible object that becomes visible. We will return to the relationship between visible invisible and invisible visible in the next section.
It is worth noting that the element components that make up the square are visible and invisible at the same time. According to Gestalt psychologists, it is the square that emerges, that is, the shape of the whole, while the individual parts and their arrangement remain almost invisible, as if camouflaged in the background. The parts are the angles and sides of the square, but even before there are the four segments, two of which are vertical and two horizontal, they are mutually orthogonal. The component elements are also subject to stratification along a phenomenal gradient. Angles and sides are seen more in the foreground compared to the four vertical and horizontal segments. Their orthogonality is even more invisible.
The dual spatial arrangement of the square described earlier also suggests another property relegated to the lowest layers of the phenomenal gradient. This is the material of which the square appears to be composed. Even if it is not possible to specify in detail its raw material, it is instead possible to perceive that it is a homogeneous, smooth, solid and dense material, almost crystalline although not glossy. The square can also be perceived as being composed only of a sort of wire that defines its contours, while its interior is empty. In this case, the material that makes up the contours appears rigid and solid like iron.
That is not all. We have not yet covered the totality of properties distributed along the phenomenal gradient. It is indeed from the progressively less immediate properties that we can understand and scientifically appreciate the nature and the notion of what we have called the phenomenal gradient. Among all the descriptions proposed by the subjects through suggestions or when they are simply asked to say what they see, they do not contemplate, for example, the static nature of the square, which appears perfectly motionless and heavy, especially when seen lying on the horizontal plane. Other properties that are implicit and invisible at first glance are being balanced, orderly, regular, closed, harmonious, iconic, symbolic, perfect, etc.
The square can also be perceived as piece of art, as one of the most significant examples of abstract art marking a turning point in the history of modern art. The square has been a fundamental work of the Suprematist movement, founded by Malevich (see [
31]), aimed at liberating art from traditional representation and move it towards a new form of expression based on simple geometric shapes and primary colors. The square, for Suprematists, represents the essence of abstraction, removing any superfluous details. For them, there is a sort of zero point of form or a tool useful to explore a modern spirituality, seeking to express the infinite and the absolute through a pure and simple form.
It also represented a provocation and a challenge to the artistic conventions of the time. These last properties of the square are not necessarily visible. For most of our subjects (60%), they are completely invisible properties impossible to be perceived even through direct suggestions.
The exploration and understanding of the phenomenal gradient can have significant scientific value. On one hand, it allows for the study of perceptual and cognitive processes and mechanisms from a new perspective. Additionally, it describes in detail the relationship between consciousness and the phenomenal gradient. Moreover, it could shed light on the evolutionary and adaptive correlates of the complex structure of perception, which can also be relevant on a comparative level between different organisms and species. Last but not least, it concerns the effects that the study of the phenomenal gradient can have in reference to computational processes related to vision and artificial intelligence.
In this regard, it is worth reporting below how an artificial subject like ChatGPT 4o “sees” and “describes” (the model output/the model-generated description) at various levels the same square previously described by human subjects. When asked “what do you see?”, the answer was “The image shows a simple black-outlined square on a white background. The square is defined by four straight lines of equal length, creating a geometric shape with 90-degree angles at each corner. The interior of the square is entirely white, with no additional features or details”.
When asking for a more and more detailed description, the answer was “The image depicts a black-outlined square centered on a white background. The square’s borders are composed of four straight, equally long lines that meet at right angles, forming four 90-degree corners. The thickness of the black outline is consistent throughout, creating a uniform and well-defined edge around the square. Inside the square, the area is completely white, without any shading, texture, or additional markings. The contrast between the black outline and the white interior emphasizes the shape and gives it a stark, minimalist appearance. The white background surrounding the square further highlights its clean and simple design, drawing the viewer’s focus directly to the geometric form”.
An even more detailed description was “The image shows a geometric figure, specifically a square, positioned centrally on a plain white background. The square is outlined with a solid black line, which is uniform in thickness, measuring approximately 1–2 pixels wide. This line forms the perimeter of the square, defining its boundaries clearly against the contrasting white background. Each side of the square appears to be of equal length, contributing to the characteristic property of a square where all sides are congruent. The corners where the sides meet are precise right angles (90 degrees), ensuring the shape maintains perfect geometric regularity. The interior of the square is filled with a pure, unblemished white, matching the background outside the square. This creates an illusion of a cut-out or an empty space defined solely by the black outline. There are no gradients, textures, or additional elements within the interior of the square, reinforcing its minimalistic aesthetic. The placement of the square on the canvas is such that it is centered, providing a sense of balance and symmetry to the overall composition. The simplicity of the design draws attention to the form itself, emphasizing the purity and clarity of the geometric shape. The overall effect of the image is one of stark simplicity and abstract minimalism, focusing entirely on the basic elements of shape and contrast. This can evoke a variety of interpretations, potentially inviting viewers to contemplate the relationship between space, form, and void”.
A first note concerns the fact that in both human and artificial subjects, a phenomenal gradient emerges, although the differences are very pronounced. What is striking is the structuring by attributes in human subjects, with shape in the foreground, then proceeding with color, spatial arrangement, and material properties up to the more expressive ones, compared to a structuring based mainly on detailing with characteristics that are more analytical geometric in the case of the artificial observer. Further comparisons through the following stimuli will allow for a deeper exploration of similarities and differences between the two phenomenal structures.
3.2. Variations in a Square Without Change
A new group of subjects immediately describes
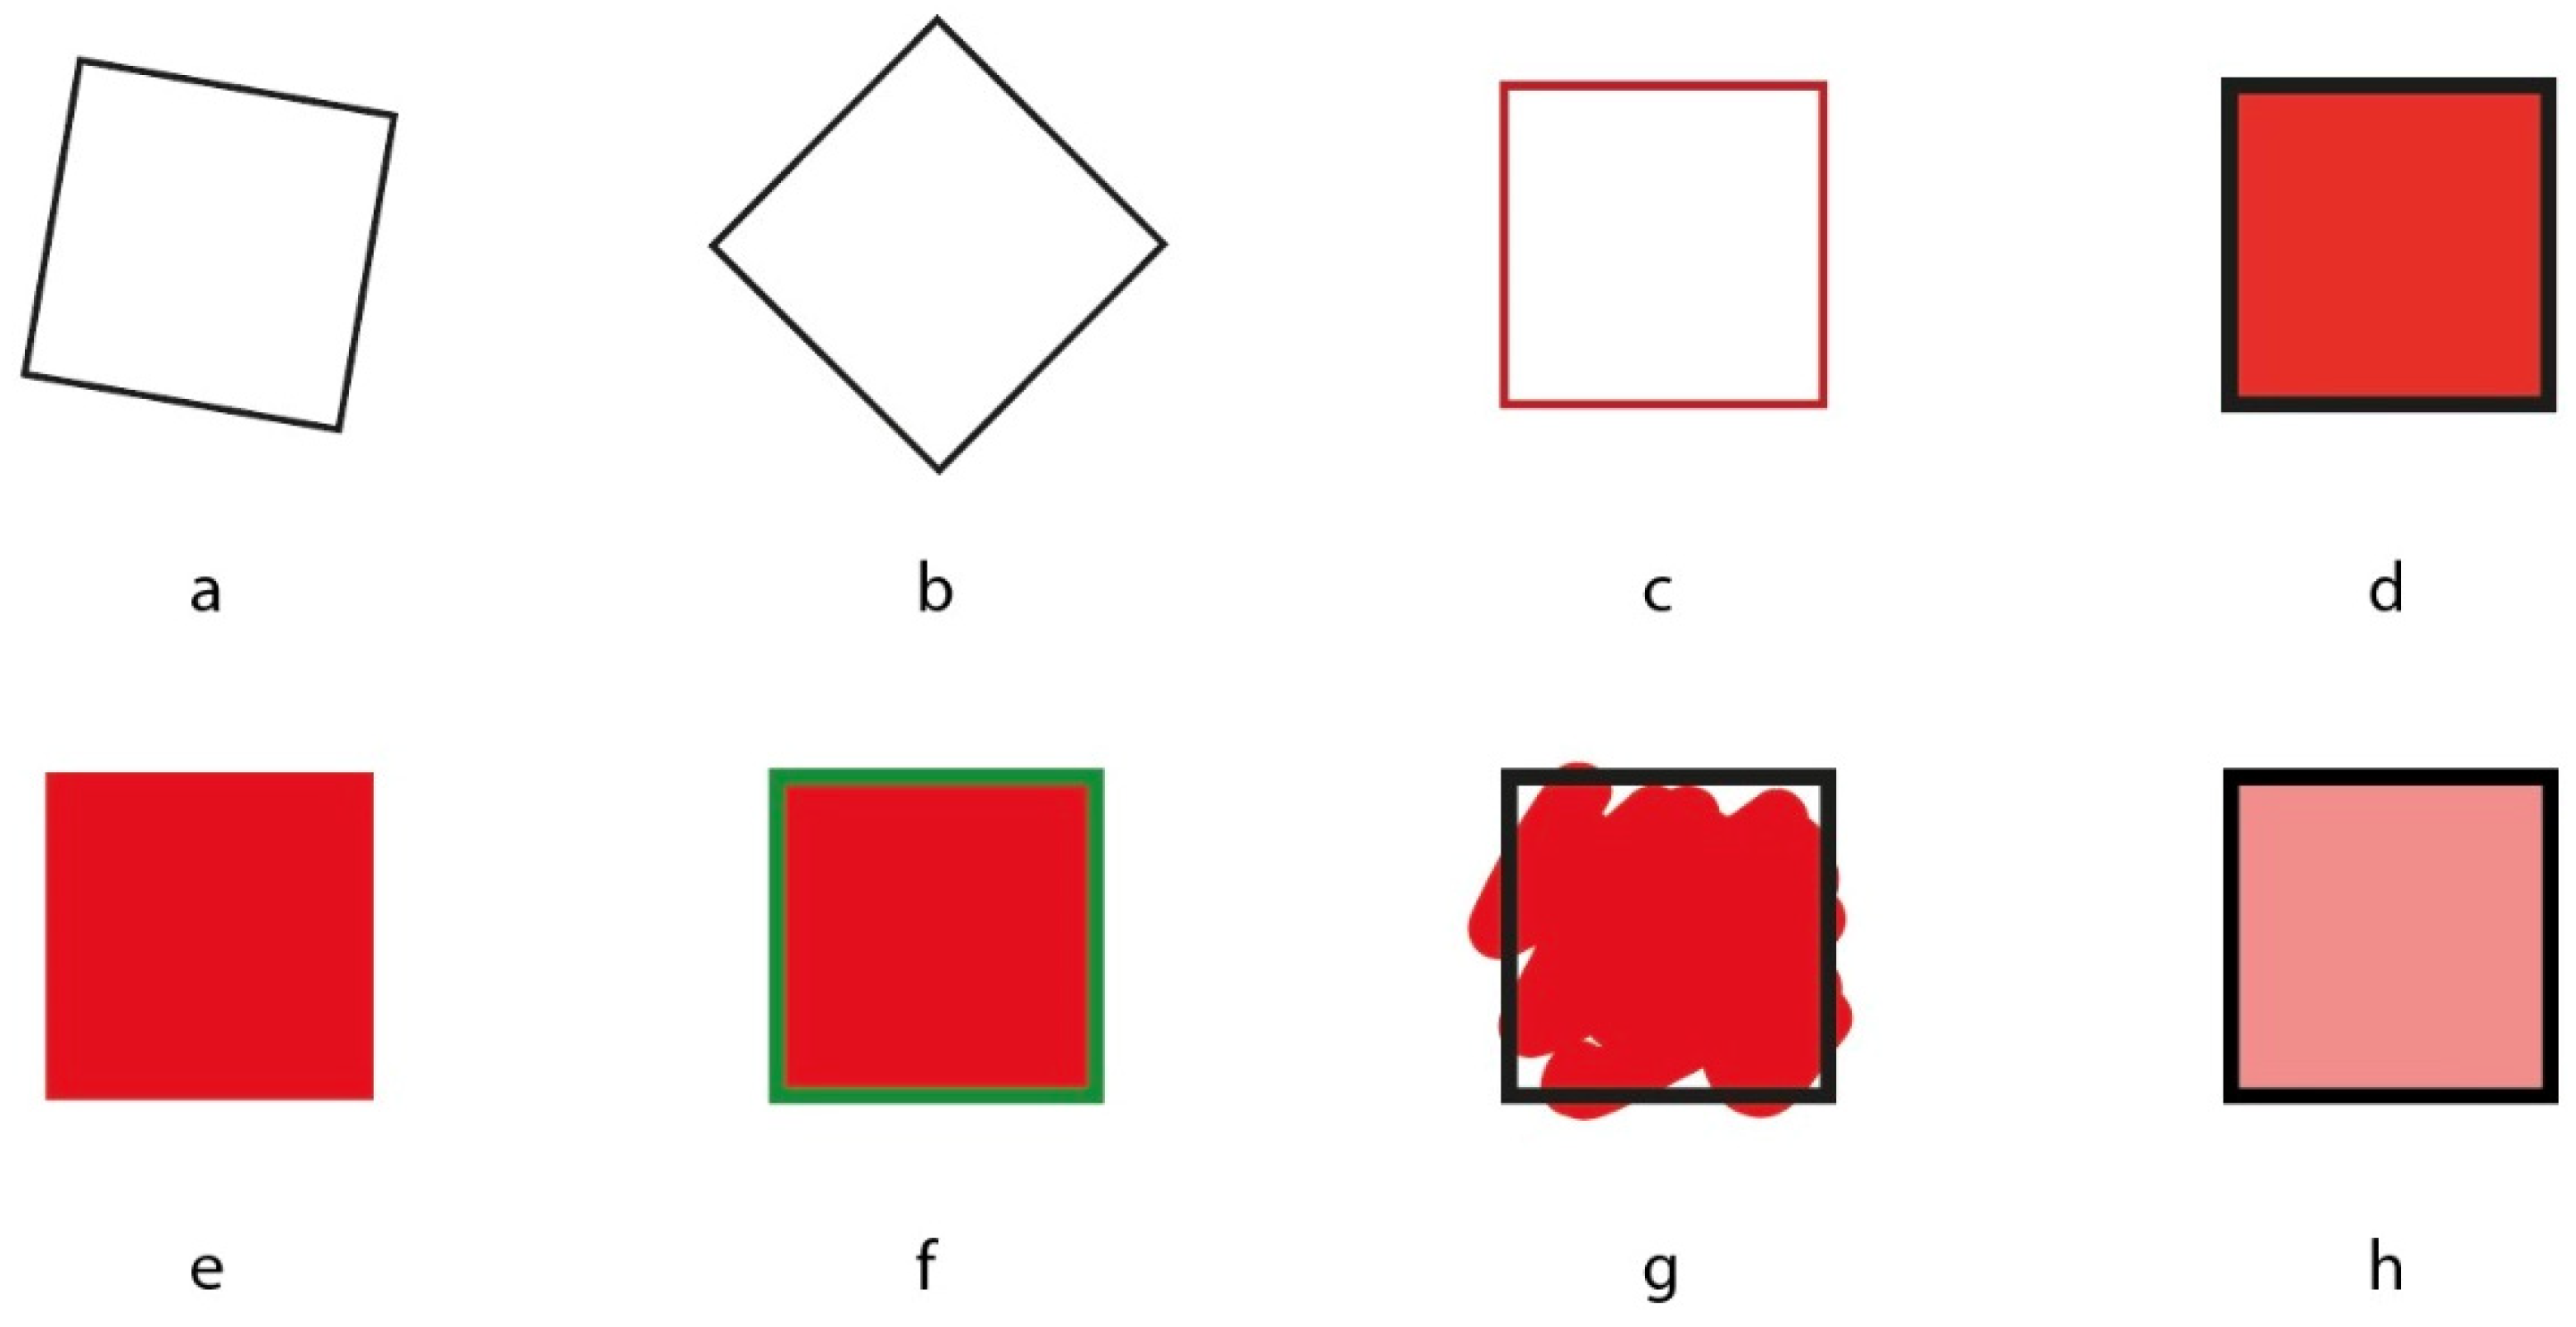
Figure 2a as a rotated square. All the properties previously described for the square in
Figure 1a have also been stratified in
Figure 2a in a similar manner along the phenomenal gradient, starting from the shape up to the expressive qualities close to invisibility. What is interesting to note, in this case, is the presence of rotation, as an emerging attribute from the reference shape of the square. It is as if
Figure 2a were the square from
Figure 1a with a change. In other words, it is a square in the background, but what emerges in the foreground is the change: the rotation. Similarly, the artificial intelligence describes
Figure 2a as follows: “I see an image of a square that appears to be tilted or rotated slightly. The square is defined by a black outline and has no other markings or colors inside”.
Figure 2b was described as a rhombus or a diamond. When asked “why is it seen as a rhombus despite being a square rotated by 45 degrees?”, the most common answer was “the square shows the sides, while the rhombus shows the edges. While the first appears flattened, the second appears pointed” [
31]. In the case of the AI, the answer was “The shape appears as a diamond because it is a square that has been rotated 45 degrees. In its standard position, a square has sides parallel to the horizontal and vertical axes. When rotated, the corners of the square point up, down, left, and right, creating the appearance of a diamond. This change in orientation gives the square a different visual perception, making it look like a diamond instead of a typical square”. The AI provided a more geometrically accurate explanation focusing on the rotation and axes.
Human subjects describe
Figure 2c as a square. Only after a more detailed request do they report seeing a square with red contours. When asked “what color is the square?”, the most common answer was white, then transparent, and finally red. The AI responds: “The image shows a simple red square with a thin border on a white background. The square is centered in the image”. By asking “what is the color of the square?”, the answer was unique: the color of the square is red.
Human perception is more complex and articulated, as well as more syntactically structured. This indicates that human perception follows a kind of syntax or hierarchical organization. In contrast to the AI’s straightforward description, humans organize visual information in a way that is similar to how language is structured, with primary and secondary elements. Humans initially focus on the overall shape (a square), then notice specific features (red contours) when prompted and then have varying interpretations of the square’s color (white, transparent, red).
For human subjects,
Figure 2d appears very simply as a red square. Only after specific questions was the black border mentioned. Artificial intelligence describes the stimulus as follows: “the image shows a red square with a black border on a white background. The square is filled with a solid red color, and the black border is relatively thin. The square is centered in the image”.
These results highlight several interesting points. First of all is simplicity vs. detail. While humans provide a simple, essence-capturing description, the AI offers a more analytical description of the image. The AI output biases a black border, which was not mentioned in the human description. This could indicate that the boundaries are specifically related to the shape and not to the color. Human brain specializes the roles of different attributes, i.e., if one component of the object (e.g., the boundary contours) drives the shape, then it cannot show another attribute like the color and vice versa (see also [
31]).
Moreover, while the AI includes information about the square’s position (centered) and the background color, the human description does not mention them. More generally, humans seem to abstract the essential information (shape and primary color) while ignoring what they might consider non-essential details (border, background, positioning).
It is worth noting that to highlight certain attributes, it is necessary to make less important attributes implicit or hidden, attributes that are less relevant for defining what is seen in the simplest and most immediate way. Some attributes are more significant in defining the identity of an object compared to others. Shape is more identity related, constant, and immutable in defining an object compared to its color, which, however, is more so than the spatial position or other characteristics present in the lower layers of the phenomenal gradient.
In other words, to show something, it is necessary to hide something else, hence hiding in order to show. To bring something to the foreground, other perceptual qualities must be pushed to the background. More generally, to see something, it is necessary to make something else invisible, i.e., placed in the background. This creates a true computational economy of seeing, where the most important things come first, then the rest. This can be a starting hypothesis to explain the formation of the phenomenal gradient.
For human subjects,
Figure 2e–h are also red squares, although in the case of
Figure 2f, the description for a small portion of the subjects (30%) becomes a red square with green edges. In the case of
Figure 2g, it is not necessary for the color to fill the entire square shape for the square to appear red [
23,
31].
Figure 2h appears as a light red square. Now, the attribute “light” becomes an adjective of the color, i.e., less salient than color within the phenomenal gradient. While the red color is mentioned by all subjects, it being light is not equally immediate, being mentioned by only half of the subjects.
The related immediate descriptions of the AI are as follows.
Figure 2e: “The image shows a red square on a white background. The square is completely filled with red and has no visible borders”.
Figure 2f: “I see a square with a green border, and the inside of the square is filled with a solid red color. The green border is relatively thin compared to the red area inside. The red color is uniformly distributed within the boundaries of the square”.
Figure 2g: “I see a square with a black frame, and inside it, there is a red blotch. The red blotch does not have a defined shape and appears to be spread randomly within the square”.
Figure 2h: “A black square outline or frame. Inside the frame is a solid light red or pink square that completely fills the interior space. The edges of the inner square align perfectly with the black frame, creating a neat, geometric appearance. The color of the inner square is uniform, without any variation or texture visible”.
The comparison between humans and AI highlights again the previous points: simplicity vs. detail, role specialization of shape and color, and human abstraction of essential information vs. AI geometrical details. Another noteworthy result concerns the visible emergence of invisible objects such as the horizontal plane, previously described, which is absent in the artificial subject. Beyond structuring appearance along a phenomenal gradient, a peculiarity of human vision is the formation of invisible objects that give meaning, generate some form of consistency, justify and explain what we perceive, as well as the formation of the phenomenal gradient itself. In the following section, changes capable of eliciting emerging visible invisibles will be introduced.
3.3. Changes and Emerging Objects Within a Square
The stimuli, described in the previous section, have not brought about significant changes from a phenomenal point of view, apart from
Figure 2a,b. This is mainly because there are no evident dissimilarities along the shape of the reference square. In fact, the chromatic variations do not generate any real change or any new emerging object. This is presumably due to the position of color in the background of the phenomenal gradient compared to emerging shape. Introducing extensive changes and dissimilarities along the shape of the square is supposed to represent the main source for the emergence of significant phenomenal changes of a totally different nature compared to color. This would further corroborate the hypothesis of the phenomenal gradient as a place or structure where objects and their attributes are organized.
Across stimuli that primarily manipulated local geometry, the model’s descriptions largely remained at the level of explicit shape/color. For stimuli designed to elicit amodal completion and event interpretations in humans, human reports frequently included completion/material/causal attributions, whereas model outputs tended to (i) restate visible geometry and (ii) provide less stable event-level interpretations.
Unlike color, dissimilarities along the shape of the square would no longer represent adjectives providing additional information but would be true emerging objects, not detached or totally segregated from the square but in close relationship with it. We will see in this section how this occurs.
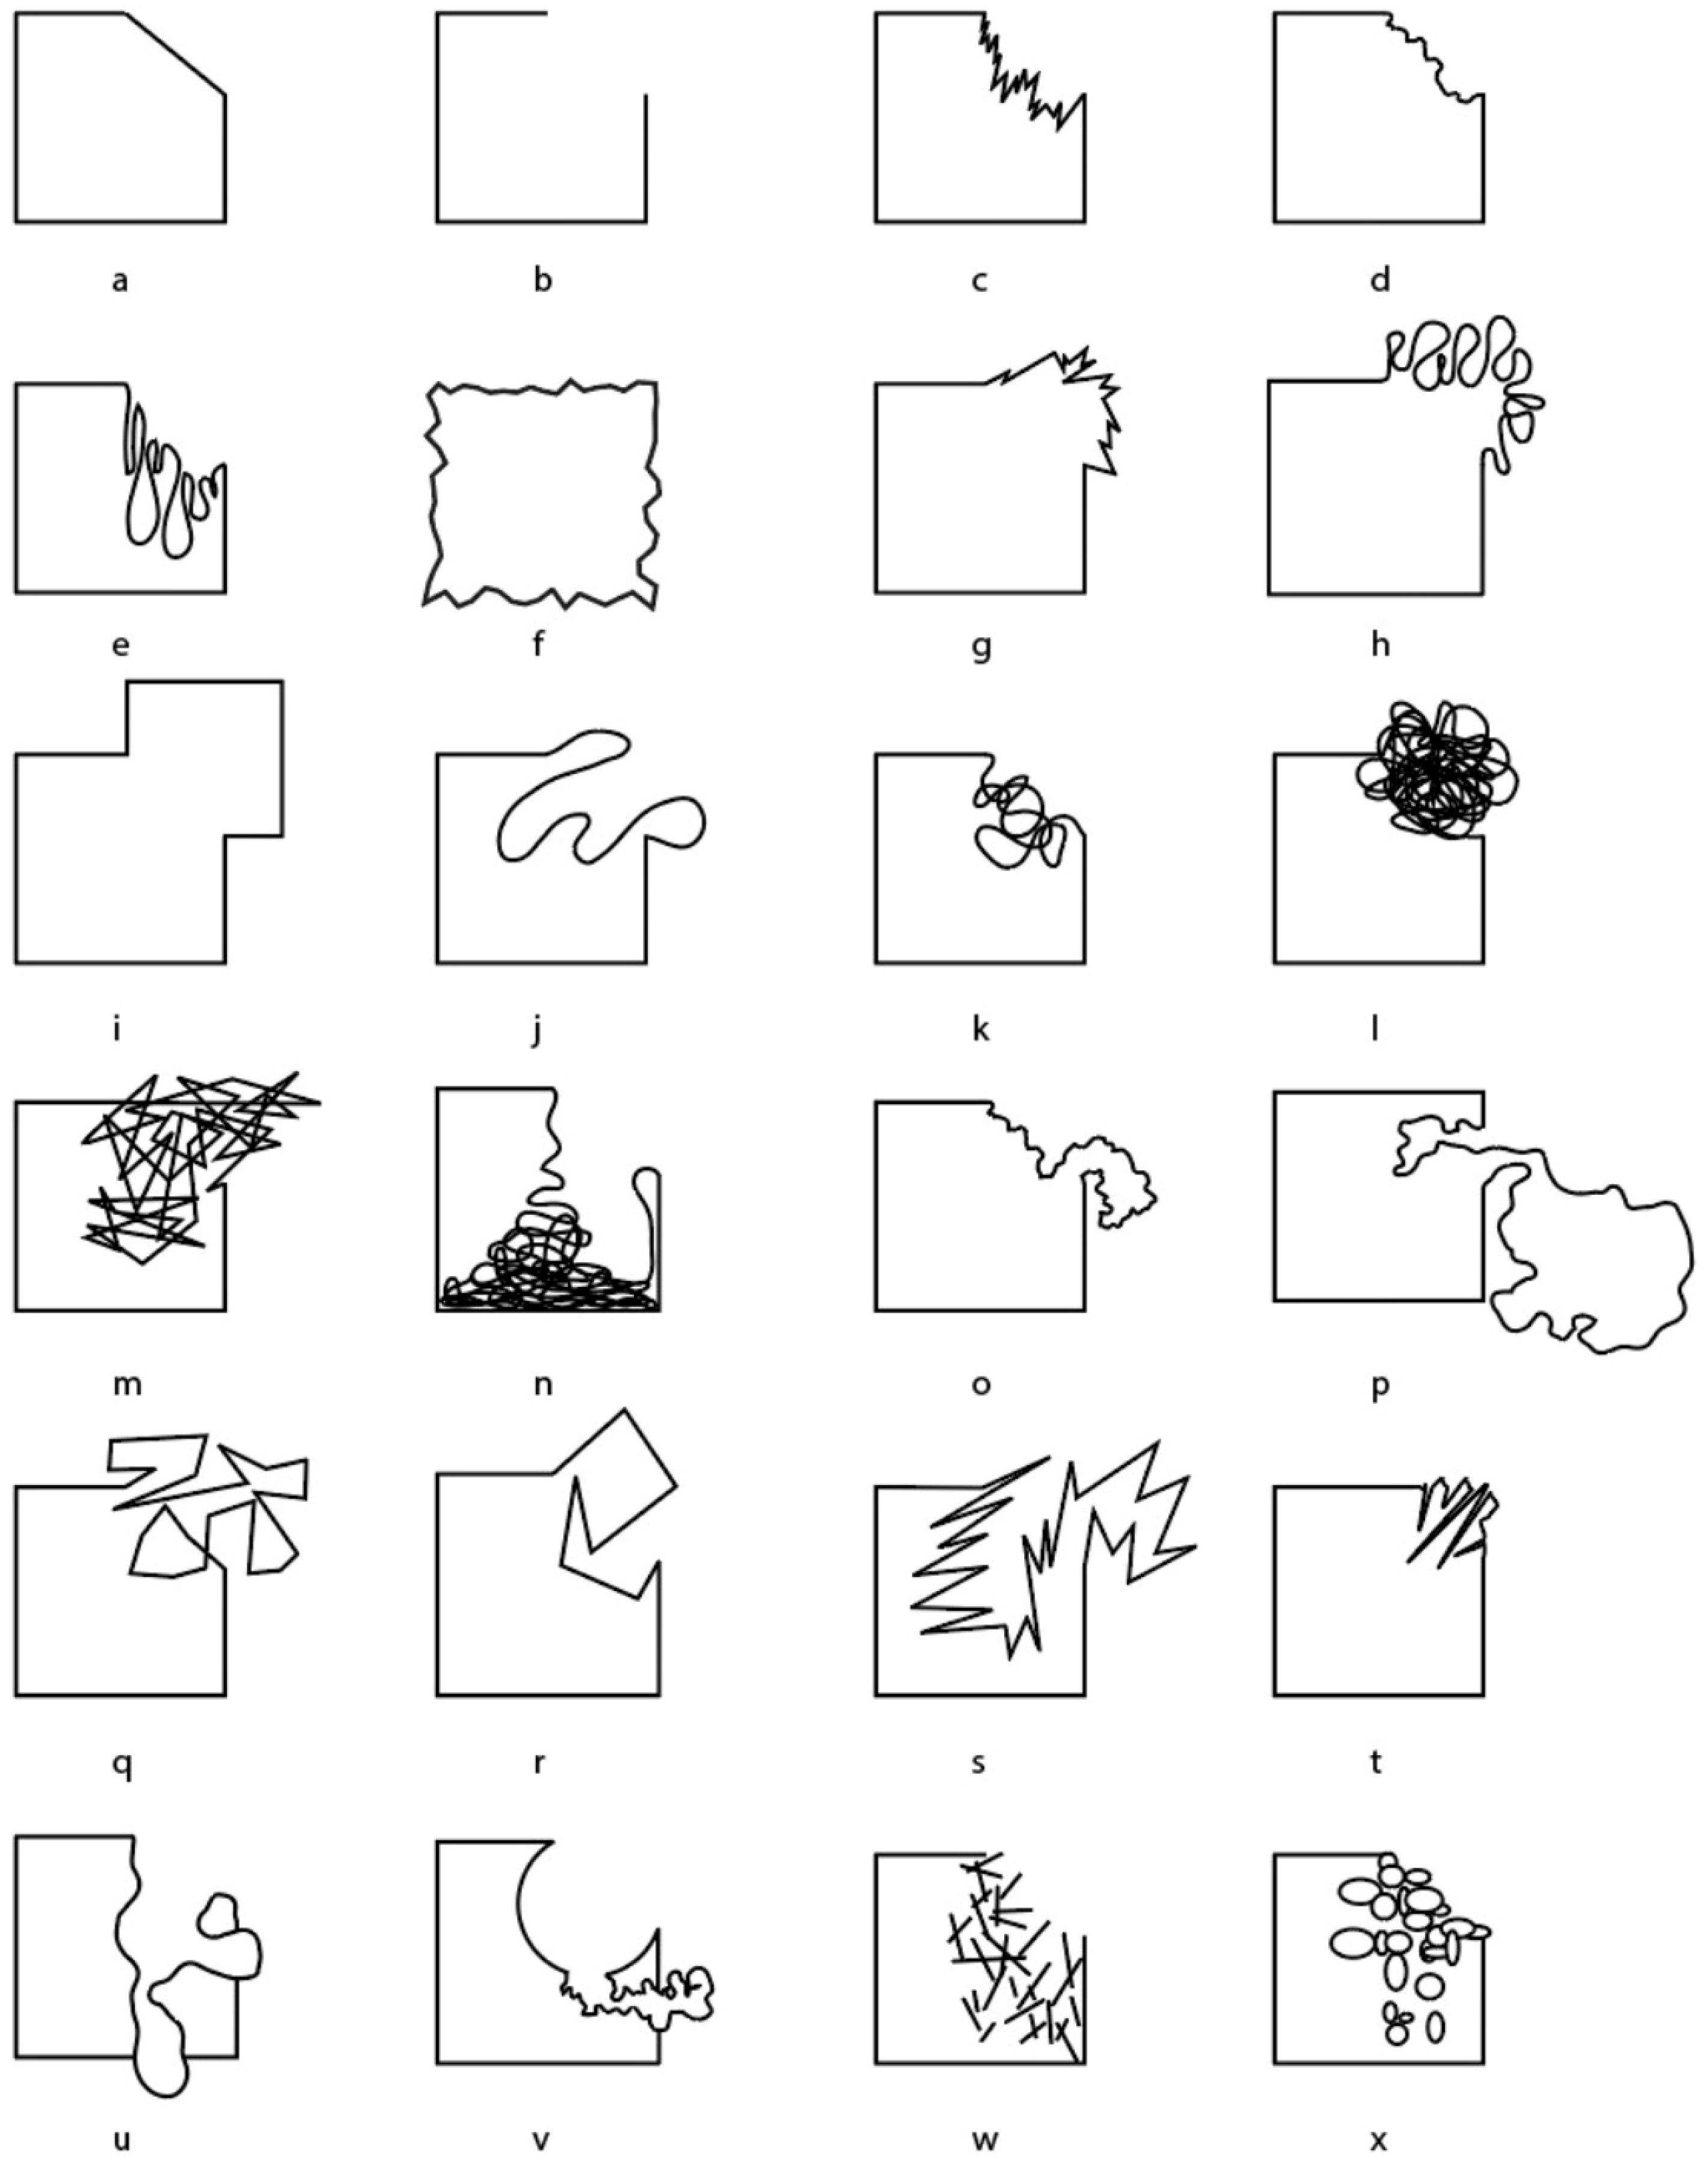
Figure 3a was spontaneously described as a rounded square and, with more details along the phenomenal gradient, as a square of white paper with a corner clipped by scissors. Qualitatively different is the AI’s description: “the image shows a geometric shape that resembles a square with one corner cut off. It has five sides, making it a pentagon. The top right corner of the shape is truncated, giving it a distinctive appearance compared to a regular pentagon or square. The lines are black, and the shape is outlined against a white background. More in details, the image is a geometric figure with the following characteristics: it is a five-sided polygon (pentagon); the bottom side is horizontal and of a certain length; the left side is vertical and equal in length to the bottom side; the right side is also vertical but slightly shorter than the left side; the top side is horizontal, matching the length of the right side; the top right corner is cut off, resulting in a slanted line connecting the top and right sides; all lines are black, and the shape is outlined clearly; the shape is set against a plain white background. The truncated corner gives it a distinctive appearance, making it different from both a regular square and a regular pentagon”.
The pentagon does not appear in human descriptions although it is visible, albeit in the background of the phenomenal gradient. Moreover, several visible invisibles emerge: the paper, the cause of the cut, and especially the scissors. Causality becomes the phenomenal explanation, the justification for the fact that an amodal square is seen even though modally it is and can be perceived as a pentagon [
19]. In other words, the cause of the cut, in turn caused by the scissors, justifies and imparts meaning to the square and the change that are immediately seen.
These visible invisibles are part of how humans organize visual elements to create meanings from what they see, filling in gaps amodally with assumed new information. Amodal completion refers to the human tendency to perceive complete shapes even when parts are occluded, obscured or missing [
20,
32,
33]. In other terms, the human mind quickly creates a causal chain (the corner was cut with scissors) to complete and explain what it sees. The emergence of causality imparts meaning to the perception and completes and justifies why we see a square with a cut corner rather than simply a pentagon.
The AI does not engage in this kind of causal visual inference. It describes what it literally sees without making assumptions about how the shape came to be or what it might represent. The AI provides a much more geometrically precise description, identifying it as a pentagon and giving exact details about side lengths and angles without the emerging phenomenal interpretation placed in the foreground by humans.
In short, humans typically report completion, material, and causal/event interpretations, whereas the model tends to generate descriptions emphasizing local geometry and explicitly visible components. We interpret this divergence as reflecting different inductive biases and constraints: human reports arise from perceptual organization and perceptual inference, while model outputs arise from learned textual/image–text regularities and instruction-following objectives.
Figure 3b is perceived as the perimeter of an incomplete square with a missing corner. AI describes the figure as follows: “The image depicts an incomplete square or rectangle. Here are the detailed characteristics: the figure is an incomplete square or rectangle with three complete sides and part of a fourth side; the bottom side is horizontal and fully drawn; the left side is vertical and fully drawn, perpendicular to the bottom side; the top side is horizontal but only partially drawn, starting from the left side and stopping before reaching the right side; the right side is vertical but only partially drawn, starting from the bottom side and stopping before reaching the top; all lines are black, straight, and of equal thickness; there is a clear gap in the top and right sides, making the shape incomplete; the bottom-left corner forms a right angle (90 degrees); the bottom-right and top-left corners also form right angles, but the lines do not extend to complete the angles on the top and right sides; the background is plain white with no additional elements or markings”.
The human description is concise and meaningful by immediately identifying the shape as a square, despite it being incomplete. This shows the human tendency to recognize and complete familiar shapes, even when parts are missing. On the contrary, the AI provides a much more detailed, geometric description by focusing on describing exactly what is visible, including the lengths of lines, their orientation, and the angles formed.
This comparison highlights further differences between human and AI output biases. Humans tend to use prior knowledge to interpret and complete shapes, while AI describes what it sees more literally and in greater detail. The human perception demonstrates concepts like Gestalt principles and amodal completion, while the AI shows a more analytical, element-by-element approach to description.
Moreover, even if both outcomes acknowledge the incompleteness of the shape, the human description implies a complete square with a missing part, while the AI describes it as an incomplete figure without perceiving and assuming what it might be if completed. The human description is more holistic, focusing on the overall concept rather than specific details. While the AI explicitly mentions the white background and the absence of additional elements. The human description does not mention this component, focusing solely on the main shape. ‘First things first’ can be considered a useful simplified motto to understand the formation of the phenomenal gradient.
Figure 3c appears as a square plate of a glass-like material with a corner shattered by a violent blow imparted by an object similar to a hammer. In the case of the AI, (for reasons of brevity, we omit the purely geometric description similar to that of the previous and subsequent figures concerning the sides and angles, the lines, the vertices, and the background) the description is as follows: the image shows predominantly a square with one side partially eroded or jagged. The jagged section has multiple peaks and troughs, creating a saw-tooth effect. The exact number of peaks and troughs varies, and they are irregular in length and angle.
This stimulus reveals a clear difference between visual interpretation and description, more particularly, it shows several visible invisibles: a causal phenomenon, a violent blow from an object similar to a hammer. On the contrary AI makes no causal inferences, but only describes the visible features. Moreover, humans perceive specific material, glass-like, that implies a 3D object by using the term plate. AI describes it as a 2D shape: a square.
These comparisons have significant implications for AI development, particularly in areas like computer vision and natural language processing. They suggest that to achieve more human-like perception and description, AI systems might need to incorporate the following: causal reasoning capabilities, knowledge of materials (see [
34]) and their properties, understanding of real-world physics, ability to make contextual inferences, and integration of multi-modal information (visual, tactile, functional). All of this underscores the complexity of human visual processing and interpretation, which goes far beyond pattern recognition to include aspects of physics, causality, and real-world knowledge.
Figure 3d is described as a square of soft material as if it had been gnawed by some rodent. The AI description was as follows: the image shows a square with one side partially eroded in a wavy or uneven manner. The figure is predominantly a square, but with an irregular, wavy section that has multiple curves, creating a natural, flowing effect. Again, for brevity, the geometrical details have been removed, being similar to the previous AI descriptions and to the following.
These differences continue to suggest the gap between human perception, which readily incorporates holistic real-world knowledge and causal inference, and AI analysis, which focuses on detailed geometric description without making inferences about materials, causes, or real-world contexts.
Figure 3e shows a rubbery square that is melting and dripping in one corner due to heat. The AI description: “The image shows a square with one side partially eroded in a looping or irregular manner. Multiple loops of varying sizes and shapes creates a whimsical, flowing effect”. These strong differences continue to highlight the challenges in developing AI systems that can interpret images in ways that align with human perception and understanding. They also underscore the depth and complexity of human visual processing, which goes beyond pattern recognition to include aspects of physics, causality, and real-world knowledge.
Figure 3f shows a sheet of paper that has been crumpled by hand and then reopened. For the AI description, the image shows a square with jagged, irregular edges resembling to a square that has been roughly cut or torn.
Especially in this figure, but actually in the others as well, another visible invisible object is time. In all the illustrated cases, there is a component that appears as the background, a square, from which some kind of event or change emerges. While amodally completing the square, just as the perception of a figure amodally completes the background, the change and dissimilarity along the shape gives rise to new emerging objects and qualities that appear as visible invisibles. As a matter of fact, allowing the amodal completion of the square implies generating the notion of time, which can only be linked to that events. Time and changes, dissimilarities that can be more generally defined as “happenings” are phenomenally two realities that imply each other, two sides of the same coin. When one is present, the other is always present as well. One cannot be perceived without the other. When something happens, even under static conditions, it is presumed that there is a past, a present (crystallized in the image under observation), and a future, which can be seen as still in progress or concluded.
Talking about happening implies giving meaning to something much simpler, which we can call much more aseptically “dissimilarity”. All the events illustrated in
Figure 3 are dissimilarities, mostly corresponding to the top right corner, appearing as changes and, more phenomenally as happenings. These dissimilarities are conspicuous, true objects emerging from the background of the square, unpredictable and unexpected conditions that become the true source of new information. The dissimilarities become visual novelties by activating a chain of other emerging qualities that justify and bring together similarities and dissimilarities, making the former totally homogeneous, thus generating the square, and accentuating the latter, i.e., by making them to assume a new and emerging meaning. This kind of complex organization, structured within the layers of the phenomenal gradient, generates whole information where all the components of the visual field appear meaningful and useful. In this way, the complex relation between similarity and dissimilarity within the same figure puts together all the elements, reducing uncertainty and entropy, thus adding value to a decision-making process.
Time is a visible invisible, and the concept of time, though not physically present in static images, is perceived and inferred by human observers, but it is not reported in any of the previous and following AI descriptions. In addition, the fact that the square is perceived as a background, with changes or events emerging from it, highlights the visual tendency to separate stable elements from dynamic or dissimilar elements in a scene. Since changes and dissimilarities are perceived as new, emergent information, it suggests that our perceptual system is particularly attuned to novelty and difference.
More generally, regions of dissimilarity in the image (changes, irregularities) contain more information in the information-theoretic sense. They introduce unpredictability, increasing information content. The regular, unchanging parts of the square are instead highly predictable, thus containing less information. Moreover, the visual dynamics of deriving emergent meanings from dissimilarities can be seen as the outcome of information processing. Thus, reducing uncertainty by introducing new emerging objects and cause on the dissimilarities, useful in explaining and completing the square on the background, is a way visual perception reduce entropy.
Amodal completion (perceiving the complete square) can be considered as a form of information compression that reduces the complex visual input to a simpler, more familiar concept (a square with a modification). Novel or unexpected elements (like the happenings in the square) have high information value. However, the complementation and consistent integration between the completion of the square and the emerging meaning of the happening, useful in explaining the amodal square, is the most effective way to reduce the information load and the entropy of the visual world. The reduction in entropy occurs through three different ways: reduction in the unexpected and uncertain multiplicity of the elements that compose the dissimilarity, completion of the square through the segregation of the happening, and, finally, complementation and bringing together of the square and the happening in a concise and compact form.
We suggest that human vision is a mechanism aimed at reducing the entropy of the uncertain multiplicity of fragments and dissimilarities of the perceptual world. This aligns with information theory principles [
35]. On the contrary, AI descriptions seem to increase the entropy compared to a human observer. The different lengths of the human and AI descriptions corroborate what has just been stated.
These theoretical notes suggest that AI systems might benefit from being designed to be more sensitive to areas of high information content (dissimilarities, unexpected elements) in images. Moreover, the phenomenal structuring of visual information into background and figure elements could be a useful principle in developing more sophisticated image segmentation algorithms. Further theoretical notes will be discussed through the phenomenology of the following figures.
In
Figure 3g, a strange eruption or small explosion manifests in the top right corner. AI description: the image shows a square with a section near the top right corner modified by a jagged, sawtooth-like pattern. The jagged extension consists of several sharp, angular points that protrude from the top right corner of the square. The extension begins near the top middle part of the square and continues outward through the top right corner, extending slightly downward along the right side. The pattern resembles a sawtooth or lightning bolt effect with sharp, defined points.
In
Figure 3h, the square appears as a sort of inflorescence or a growing of living matter starting from its interior. AI description: The image shows a square with a section near the top right corner modified by a wavy, looping pattern extending outward. The looping extension consists of several interconnected loops that extend outward from the top right corner of the square. The loops are smooth and continuous, giving the appearance of an organic, flowing design. The extension begins near the top middle part of the square and continues outward through the top right corner, extending slightly downward along the right side.
Interestingly, both descriptions note the organic quality of the pattern, though they express this in different ways. These observations continue to highlight key aspects of human vs. AI perception. Humans readily interpret static images in terms of dynamic processes (growth, expansion), while AI descriptions remain more static. Human perception integrates knowledge from various domains (biology, physics) to make sense of visual patterns. AI provides more detailed geometric descriptions but does not make inferences about what the patterns might represent in the real world. These findings suggest again the following areas for potential improvement in AI systems: developing AI that can infer dynamic processes from static images; integrating multidisciplinary knowledge to interpret visual patterns; enhancing AI’s ability to recognize and describe organic qualities in a more holistic way; developing AI that can infer potential origins or causes for observed patterns.
In
Figure 3i, the square seems to be multiplying or self-cloning, starting from one of its corners. The AI description: The image shows a square with an additional geometric shape attached to the top right corner. The additional smaller square is rotated and appears to be protruding out of the main square. The connection between the two squares forms additional angles and intersections, creating a complex geometric figure.
The contrast between these descriptions continues to highlight the challenges in creating AI systems that can interpret images in ways that align with human perception. It also underscores the rich, inferential nature of human visual processing, which goes beyond simple pattern recognition to include concepts of process, causality, and analogy.
In
Figure 3j, the square appears to be fluttering like a sheet moved by the wind blowing mostly on one of its corners. AI description: The image shows a square with an irregular, wavy extension protruding from the top side and top right corner. The wavy extension consists of two prominent, smooth curves that protrude from the top side and the top right corner of the square. The larger curve extends from the middle of the top side towards the right, while a smaller curve protrudes from the top right corner, giving the appearance of fluid, organic shapes.
In
Figure 3k, a corner of a thread-like square seems to be knotting itself, twisting on itself. AI description: The image shows a square with a small, irregular pattern of loops near the top right corner. The tangled pattern consists of several overlapping loops creating a small, chaotic appearance. The loops intersect and overlap in a seemingly random manner, forming a loose, web-like structure. The pattern is concentrated near the top right corner but does not extend far into the square.
In
Figure 3l, the top corner of the square tangles up, creating a sort of chaotic circular ball of yarn. The AI description: The image shows a square with a dense, tangled pattern of loops concentrated at the top right corner. The tangled pattern consists of numerous overlapping loops creating a dense, chaotic appearance. The loops intersect and overlap in a seemingly random manner, forming a complex, web-like structure. The densest part of the pattern is located in the top right corner, with loops extending slightly towards the center and less densely towards the other parts of the square.
These descriptions suggest further key aspects of human vs. AI perception. Humans readily infer material properties and apply associated behaviors to abstract shapes. Visual perception often interprets static images as moments in dynamic processes, while AI tends to describe static configurations. Vision may attribute agency or intentionality to inanimate objects in images, while AI describes patterns as passive features. Human descriptions often focus on the overall concept or implied action, while AI provides more detailed geometric descriptions. Humans frequently use analogies to familiar objects or actions to understand and describe abstract shapes. AI can provide more objective descriptions of complexity and extent, while humans might imply these through action-based descriptions. Human vision integrates knowledge of physical behaviors and properties, while current AI systems typically rely solely on visual data.
In
Figure 3m, a square appears as if crystals are rapidly growing in the top right, gradually filling it. AI description: The image shows a square with a section inside filled with a complex, intersecting line pattern, mainly concentrated at the top right corner. The intersecting pattern consists of numerous straight lines crossing each other at various angles, creating a dense, chaotic appearance. The lines intersect in a seemingly random manner, forming a complex web-like structure. The densest part of the pattern is located in the top right corner, with lines extending towards the center and less densely towards the other parts of the square.
In
Figure 3n, the contours of a square seem to unroll like a thread and pile up at its base. AI description: The image shows a square with a section inside filled with a chaotic, tangled line pattern. The tangled pattern consists of numerous overlapping and intersecting curved lines, creating a dense, chaotic cluster at the bottom. Some lines extend upward from the cluster, forming a looser, more open tangled pattern. The right side has a notable loop extending out from the dense cluster, creating an additional irregularity.
In
Figure 3o, a square made of foam seems to be losing matter that slowly detaches from one of its corners. AI description: The image shows a square with a small, irregular, wavy extension protruding from the top right corner. The extension appears to be a small, amorphous, wavy shape that starts from a small wavy section at the top right corner of the square and expands outward. The edges of the extension are smooth and flowing, with no sharp angles or straight lines, giving it a natural, organic appearance.
In
Figure 3p, the square seems to be erupting much more matter than it appears to contain. The matter that comes out seems to slowly inflate like a sort of balloon. AI description: The image shows a square with a large, irregular, wavy shape extending from its top right corner. The extension appears to be an amorphous, blob-like shape that starts from a small wavy section at the top right corner of the square and expands outward. The edges of the extension are smooth and flowing, with no sharp angles or straight lines, giving it a natural, organic appearance.
In
Figure 3q, the square seems to be faceting, breaking, or projecting large pieces outward. AI description: The image shows a square with several additional geometric shapes attached to and extending from the top right corner. The additional shapes are a mixture of polygons with varying numbers of sides and angles. These shapes overlap and intersect in some areas, creating a visually complex pattern that extends outward from the top right corner of the main square.
In
Figure 3r, a piece of the square is torn off and broken by an invisible force. AI description: The image shows a square with an additional geometric shape attached to the top right corner. The additional smaller square is rotated and appears to be protruding out of the main square. The connection between the two squares forms additional angles and intersections, creating a complex geometric figure.
Human perception often infers causes for observed effects, even when the cause is not visible in the image. In addition, we may infer damages or changes to the integrity of original shapes, while AI tends to maintain the original shape and describe additions to it. Human perception may introduce invisible elements to explain visible effects—in
Figure 3r, it is an invisible ‘visible invisible’ thing or force—while AI sticks strictly to describing visible elements.
In
Figure 3s, a square is broken through and shattered in a zigzag pattern by something unknown, maybe an electric shock. AI description: The image shows a square with a section featuring a jagged, lightning-bolt-like pattern extending from the top right corner. The jagged section has sharp, angular lines that zigzag from the top side down to the right side, creating a dramatic, lightning-bolt-like effect. The lines vary in length and angle, creating a chaotic and dynamic appearance.
In
Figure 3t, a square brick of stone, perhaps marble, with a corner damaged or shattered due to a received blow. AI description: A square with a section of one side modified by a pattern resembling cracks or jagged lines, creating a chaotic pattern.
In
Figure 3u, a square with the top part melting and seeming to empty out, but it strangely appears full at the bottom. The emptying part seems to be simultaneously filling up. The flowing void appears full. It is an impossible figure. AI description: A square with a large, irregular, wavy extension protruding from the right side, disrupting the straight lines of the right and bottom edges, resembling a fluid or blob-like shape.
While humans perceive paradoxes or impossibilities (simultaneously empty and full), AI describes what is visually present without noting logical inconsistencies. Human vision explores and checks consistency within the visual world. This applies not only to human vision but also to animal vision. Consider, for example, an antelope constantly on alert, attentive to verifying the consistency that random noises do not imply the presence of a predator. For its part, the leopard must be able to assess the consistency of its own random noises compared to those produced by the surrounding environment in order to camouflage them effectively.
In
Figure 3v, the square shows a missing circular surface with an appendage similar to an intestine that, while being empty, is simultaneously also full. AI description: A square with one side partially removed in a combined smooth and irregular wavy pattern, resembling a large semicircle cut out from the top side.
Figure 3w features a square that shatters into many tiny pieces similar to twigs or segments that fall to the ground. AI description: A square with a section filled with intersecting lines, resembling a crisscross or shattered pattern, creating an irregular and chaotic appearance.
In
Figure 3x, the square, made of oval components similar to stones, seems to collapse in the top right corner, perhaps due to its weight or because they are not cemented. AI description: A square with one side partially filled with a cluster of ovals of various sizes, overlapping and clustering together in the top right portion. In these latest figures, for simplicity, all detailed geometric descriptions related to the different components of each stimulus have been omitted.
The comparison continues to highlight the rich, inferential nature of human visual processing, which integrates real-world knowledge, causal reasoning, and even the ability to perceive logical paradoxes.
To complete this section, let us make some general theoretical considerations. Our results might have significant implications for neuroscience, particularly in understanding the neural mechanisms underlying visual perception and cognition. The suggested phenomenal gradient, where shape is prioritized over color and other attributes, suggests a hierarchical organization in attribute visual processing. This aligns with current understanding of the visual cortex’s organization, where different visual features are processed in distinct areas and integrated at higher levels. Our study may help refine our models of how information flows through the visual system, from primary visual cortex (V1) through higher-order visual areas.
The human ability to perceive visible invisibles and complete partially occluded shapes might support the role of top-down processing in vision. This implicates higher cortical areas, including the prefrontal cortex and parietal areas, in shaping visual perception. Future neuroimaging studies could investigate how these areas interact with visual cortices during the perception of ambiguous or incomplete visual stimuli.
Moreover, the tendency to make causal inferences from static images suggests involvement of brain areas associated with causal reasoning, such as the medial prefrontal cortex and temporoparietal junction. This highlights the need for neuroscientific investigations into how these higher cognitive areas interact with visual processing regions during perception of complex scenes.
The human tendency to make causal inferences from static images might suggest involvement of brain areas associated with causal reasoning, such as the medial prefrontal cortex and temporoparietal junction. This highlights the need for neuroscientific investigations into how these higher cognitive areas interact with visual processing regions during perception of complex scenes.
Our results can also have several implications for computational theories of vision and artificial intelligence. The phenomenal gradient supports the use of hierarchical models in computer vision, where different features are processed at different levels of abstraction. This aligns with the success of deep learning models in computer vision tasks, which inherently implement a form of hierarchical processing.
The strong difference between human and AI interpretations, particularly in causal reasoning, suggests a need for integrating causal inference capabilities into computational models of vision. This might involve developing hybrid models that combine traditional computer vision techniques with causal reasoning frameworks. In addition, the ability to perceive visible invisibles and make context-dependent interpretations suggests that computational models can be designed to integrate contextual information and prior knowledge more effectively, such as by developing more complex attention mechanisms or incorporating memory systems into visual processing models.
Our findings support the idea that visual perception can be understood as a process of entropy reduction. This aligns with information theory approaches to perception and cognition, suggesting that computational models should be designed to optimize information compression and extraction of meaningful patterns from visual input.
The ability of humans to infer causes and complete partial shapes might support the Bayesian view of perception as a process of combining sensory evidence with prior knowledge [
31]. The study suggests that human priors are rich and multifaceted, incorporating not just statistical regularities of the visual world, but also causal knowledge and expectations about physical processes. The observed phenomenal gradient also suggests that Bayesian models of vision should be hierarchical, with different levels corresponding to different attributes (shape, color, etc.) and their relative importance in perception. Since humans tend to interpret static images as snapshots of dynamic processes, Bayesian models might incorporate dynamic priors—expectations about how scenes and objects change over time, even when presented with static input. The ability of humans to generate coherent interpretations of ambiguous stimuli supports the Bayesian concept of explaining away, where the presence of one cause for an observed effect reduces the probability of alternative causes. This suggests that Bayesian models of vision should implement complex explaining away mechanisms to account for human-like interpretations of visual scenes.
Our outcomes can also be reconsidered in terms of evolutionary theory, providing insights into the adaptive value of human visual processing. The phenomenal gradient may reflect an evolutionary adaptation for quickly identifying objects in the environment. Rapid shape recognition would be crucial for detecting predators, prey, or other significant environmental features. The human tendency to make causal inferences and perceive happenings even in static scenes may have evolved as a way to predict and prepare for future events. This ability would be highly adaptive in a dynamic environment where anticipating changes could mean the difference between survival and peril.
The ability to perceive visible invisibles and complete partially occluded shapes could have evolved as a mechanism for dealing with partially obscured objects in natural environments. This skill would be crucial for identifying partially hidden predators or prey. The observed tendency of human vision to reduce entropy by generating coherent interpretations of ambiguous stimuli may reflect an evolutionary pressure for cognitive efficiency. By compressing complex visual information into simpler, meaningful representations, the brain can make rapid decisions with limited cognitive resources.
The rich interpretations made by human observers, often involving inferences about texture, material properties, and physical processes, suggest that human vision evolved to integrate information across multiple sensory modalities. This cross-modal integration would be highly adaptive in a complex, multi-sensory environment.