


Abstract
Generative artificial intelligence (AI) is increasingly used to support decision-making in manufacturing quality assurance (QA), but its adoption raises concerns regarding governance, traceability, and auditability. This paper proposes a proactive framework that integrates generative AI into quality management and auditing while preserving standards alignment and human oversight. The framework structures quality activities across supplier, in-process, and post-market domains and across three hierarchical levels—product, process, and operation—to link quality outcomes with documentary evidence requirements. A proof-of-concept (PoC) study in electronics manufacturing focused on New Product Introduction (NPI) planning and compared two parallel workflows: an expert QA team and a generative AI-assisted chatbot workflow. Within a fixed time window, both workflows produced an aligned Process Failure Mode and Effects Analysis (PFMEA), Control Plan, supplier Production Part Approval Process (PPAP) request package, and internal audit evidence pack. Three independent experts evaluated the integrated deliverable package using five indices covering documentation quality and audit readiness, detection and containment logic, process capability and stability, governance and provenance safeguards, and execution (time) efficiency. Compared with the expert package, the generative AI–assisted workflow produced more traceable, governance-rich documentation (ownership, versioning, clause-to-evidence links) and reduced manual audit-evidence consolidation, supporting quality planning and change-control readiness.
1. Introduction
The digital transformation has reshaped how organizations design quality systems and ensure product and process conformity. The widespread use of connected platforms for monitoring, analytics, documentation, and auditing has increased visibility across industries, but it has also exposed persistent weaknesses in data interoperability, end-to-end traceability, and standards-based compliance in quality management (QM) and quality assurance (QA) systems [1,2]. These challenges are further intensified by the rapid integration of artificial intelligence (AI), which is changing how assurance activities are planned, executed, and documented [3]. Recent advances in generative AI and large language models (LLMs) [4,5] have introduced systems capable of interpreting user intent, interacting in natural language, and generating structured, task-specific content. In manufacturing, these capabilities extend beyond conversational support to practical contributions across quality workflows, including drafting and updating control plans, supporting supplier oversight, assisting in-process decisions, and enabling post-market analysis.
At the same time, generative AI introduces important risks for QM/QA and auditing, particularly with respect to decision accuracy, explainability, traceability, and regulatory conformity [6]. In response, governance frameworks and standards are emerging. The National Institute of Standards and Technology (NIST) AI Risk Management Framework emphasizes lifecycle risk management, including data provenance, monitoring, and human oversight [7]. Similarly, AI management system standards of International Organization for Standardization/International Electrotechnical Commission (ISO/IEC) stress organizational controls for responsible development and deployment [8]. In parallel, the European Union (EU) AI Act establishes a risk-based regulatory regime with requirements for technical documentation, transparency, and post-market monitoring, which closely align with QA and audit expectations in manufacturing environments [9]. Together, these developments highlight the need for proactive, evidence-centered mechanisms that keep AI-enabled quality processes auditable and compliant.
Despite the growing use of generative AI in manufacturing, the literature remains fragmented in three important respects. First, many studies focus on isolated assistance functions, such as drafting selected quality documents, supporting inspection decisions, or answering operator queries, rather than on end-to-end integration into the quality management system (QMS). Second, governance-oriented discussions often identify desirable requirements such as traceability, human oversight, and accountability, but they do not translate these into an operational QA architecture with explicit evidence flows, decision gates, and role-specific responsibilities [10,11]. Third, workflow digitization and document automation alone do not ensure that AI-supported outputs are audit-ready, because regulated QA environments require not only faster document generation, but also source-grounded evidence linkage, controlled approvals, change traceability, and defensible escalation logic.
This study addresses these gaps by proposing a structured, governance-centered framework for generative-AI-supported quality assurance and auditing. The framework integrates generative AI across three core QM domains—supplier quality, in-process control, and post-market feedback—while embedding these functions within a hierarchical product–process–operation architecture and a common five-phase QA cycle. It coordinates manufacturer-side and auditor-side activities through governed evidence flows, predefined review and approval mechanisms, and level-specific decision logic. In this design, generative AI functions as a controlled decision-support and documentation-support layer rather than as an autonomous quality-control authority.
The main contribution of the study lies in combining three elements within a single operational model: (1) a multi-level and multi-branch framework for integrating generative AI into QA practice; (2) explicit linkage between AI-supported outputs and auditable evidence requirements through governance, traceability, and role-based control mechanisms; and (3) a dedicated five-index evaluation system for assessing generative-AI-supported QA deliverables in terms of documentation quality, detection and containment logic, process capability stability, governance and provenance, and time efficiency. The framework operationalizes this logic by linking PFMEA, the Control Plan, the supplier PPAP request package, and an internal audit evidence pack to explicit evidence flows, role-based approvals, and KPI-triggered escalation gates across product, process, and operation levels. In this way, the study advances beyond workflow digitization, governance checklists, and document automation by positioning generative AI as a controlled and evaluable component of a broader QMS-aligned assurance architecture.
To examine the practical applicability of the framework, the study includes a bounded proof-of-concept (PoC) case in electronics manufacturing focused on new product introduction (NPI) quality planning. The PoC compares a conventional expert-only workflow with a generative-AI-assisted workflow under shared input, deliverable, and time constraints. The purpose of this case is to provide exploratory evidence of feasibility and comparative value in a representative QA planning task rather than to claim broad generalizability across all manufacturing settings.
Accordingly, the objectives of this study are fourfold: (1) to define practical control mechanisms for the responsible use of generative AI in regulated QA contexts, including human-in-the-loop approval, data governance, and traceability; (2) to develop a structured framework for integrating generative AI across supplier-related preparation, in-process monitoring, post-run correction, and review; (3) to operationalize and test this framework through a proof-of-concept case and a dedicated evaluation index system; and (4) to derive role-specific implications for the main stakeholder groups involved in QA and auditing.
The remainder of the paper is organized as follows. Section 2 reviews advances in generative AI relevant to quality management and auditing, with an emphasis on industrial LLM and multimodal applications. It also summarizes relevant metrics, indices, and standards and introduces the evaluation index system used in this study. Section 3 surveys current research on generative AI applications, highlighting benefits, limitations, and standardization trends across supplier quality management, in-process quality control, and post-market surveillance. Section 4 presents the proposed framework, including its functional areas, alignment with the Plan–Execute–Improve cycle, associated controls, and implementation artifacts. Section 5 reports the case study from the smart-home sector, including the study design, KPIs, and comparative results for conventional and generative-AI-assisted QA workflows. Section 6 concludes with the main findings, implications for policy and compliance, and directions for future research and scaling.
Note: A list of abbreviations is provided in the Supplementary Materials.
2. Generative AI for Manufacturing Quality Assurance and Auditing: Applications, Standards, and Evaluation
Generative AI in manufacturing quality management is advancing rapidly with progress in NLP, computer vision, and multimodal models. These tools support QA across the lifecycle, from documentation and decision support to compliance and audit preparation. Accordingly, this section: (1) situates generative AI in manufacturing QA and auditing use cases; (2) reviews key metrics, indices, models, and standards that guide measurement and multi-level evaluation; and (3) presents the evaluation index system used in this study.
2.1. Generative AI in Quality Assurance Contexts
Generative AI refers to AI systems that learn patterns from data and produce new, context-relevant outputs such as text, images, or code. NIST defines generative AI as “the class of AI models that emulate the structure and characteristics of input data in order to generate derived synthetic content” [12]. In manufacturing QA, generative AI is typically deployed via platforms that integrate pretrained LLMs into planning, documentation, process oversight, and auditing tasks.
Unlike rule-based expert systems, generative AI can interpret natural-language requests and support cross-document reasoning (e.g., drafting PFMEAs/control plans, summarizing deviations, and structuring audit evidence). It does not replace SPC, conventional machine vision, or MES logic; rather, it complements Quality 4.0 environments by handling unstructured information and improving decision support and documentation continuity.
Because generative models can produce plausible but incorrect content, their use in regulated QA settings requires governance and verification. Consistent with NIST trustworthy AI guidance and the NIST Generative AI Profile, AI-supported QA outputs should remain valid, transparent, accountable, and traceable within the QMS [12,13].
2.2. Key Quality Metrics, Models, and Standards in Manufacturing and the Proposed Evaluation Index System
This subsection synthesizes key quality metrics, evaluation indices, reference models, and standards that form the foundation for assessing how generative AI can be integrated into QM. These measurement and governance elements also inform the level-specific KPI bundles used later in the proposed framework.
Quality Metrics and Indices
Manufacturing enterprises employ quantitative metrics and indices to monitor quality performance at product, process, and operation levels. These measurements are central to diagnosing inefficiencies, meeting regulatory and customer requirements, and supporting continuous improvement. Commonly used product-, process-, and operation-level indicators include:
- First Pass Yield (FPY)—measures the percentage of products manufactured correctly without rework [14].
- Defects per Unit (DPU), Defects Per Million Opportunities (DPMO), and Parts Per Million (PPM)—normalize defects across production scales [13,15,16,17].
- Process Capability Indices (Cp/Cpk)—reflect how well a process meets specification limits [18].
- Overall Equipment Effectiveness (OEE)—evaluates availability, performance, and quality effectiveness of equipment [19].
- Cost of Poor Quality (CoPQ)—aggregates costs from scrap, rework, and warranty claims [20].
These metrics are increasingly monitored through dashboards and may be combined into composite indices or level-specific KPI sets that support operational decision-making. For instance, Lean Quality Control approaches track FPY, OEE, and CoPQ to evaluate operational stability and waste reduction [21]. With IoT data capture and predictive maintenance, early signals of deterioration (e.g., declining Cp/Cpk or OEE) can be detected earlier and acted upon before nonconformities propagate.
Quality Models and Methodologies
Metrics are operationalized through structured methodologies aimed at continuous improvement. The PDCA (Plan–Do–Check–Act) cycle underlies many quality management systems and informs phases of planning, execution, monitoring, and control [22]. Other influential methodologies include:
- Six Sigma—uses the DMAIC (Define–Measure–Analyze–Improve–Control) framework to reduce defects. AI and Machine Learning (ML) methods increasingly support analysis and diagnosis [23].
- Lean and Lean Six Sigma (LSS)—applies tools such as 5S, value stream mapping, and error-proofing (poka-yoke) to reduce waste and variability [24].
- Statistical Process Control (SPC)—maintains stability via control charts; ML-enhanced SPC supports dynamic anomaly detection [25].
- Failure Mode and Effects Analysis (FMEA)—a core tool for proactive risk management; generative AI can support failure identification and action prioritization [26].
- Total Quality Management (TQM) and Root Cause Analysis—long-established approaches increasingly augmented by digital analytics and data-driven systems [27].
These methodologies define the logic and structure within which generative AI must operate to remain aligned with established quality objectives and to produce outputs that are acceptable for internal governance and external audits.
Quality Standards and AI Integration
Quality standards institutionalize best practices and provide compliance frameworks. In manufacturing, ISO 9001 remains foundational, specifying Quality Management System (QMS) requirements based on the process approach and PDCA logic [28]. Sector-specific extensions add rigor for high-consequence environments; for example, IATF 16949 supplements ISO 9001 with stringent quality planning and defect prevention requirements and emphasizes core tools (e.g., Advanced Product Quality Planning—APQP, Part Approval Process—PPAP, Measurement System Analysis—MSA, SPC) [29,30]. Laboratory-centric standards such as ISO/IEC 17025 impose requirements on technical competence, measurement traceability, and validated methods [31].
Alongside classical quality standards, AI-specific governance standards are increasingly relevant to QA and auditing. ISO/IEC 42001 establishes requirements for an AI management system, including governance structures and risk controls for AI-enabled operations [8]. Supporting standards and auditing guidance further help operationalize measurement integrity, evidence quality, and audit consistency. However, conventional quality metrics (e.g., FPY, DPMO, Cp/Cpk) and standards assess manufacturing performance but do not fully capture the quality of generative-AI-supported outputs, which are often documents and evidence packages. Because key risks relate to traceability, provenance, change control, and audit defensibility, we propose a dedicated evaluation index system that measures these dimensions alongside prevention logic, capability stability, and execution efficiency.
Proposed evaluation system for generative-AI-based QA
Building on the metrics, models, and standards discussed above, this study adopts a five-index evaluation system for generative-AI-based QA. Such a dedicated index system is necessary because generative-AI-based QA must be evaluated not only in terms of conventional quality outcomes, but also in terms of evidence traceability, governance safeguards, and audit readiness of AI-supported outputs. Documentation Quality (DQ) assesses the completeness, internal consistency, and audit readiness of the generated deliverables, including cross-references, clause-to-evidence linkage, and metadata integrity; this index is grounded in documented-information and audit-evidence requirements in quality-management and auditing standards [28,32]. Detection and Containment (DC) evaluates how well the artifacts anticipate and manage nonconformities through explicit containment rules, hold/stop triggers, and coverage of rare or edge-case scenarios, which aligns with defect prevention, nonconformity control, and reaction-planning requirements in ISO 9001 [28] and IATF 16949 [29]. Process Capability Stability (PCS) assesses whether capability expectations for Critical-to-Quality characteristics (CTQs) are supported by monitoring and reaction logic that helps sustain process performance during ramp-up; this reflects established SPC- and capability-oriented quality practice as well as process-control expectations in ISO 9001 [28] and IATF 16949 [29]. Governance and Provenance (GP) evaluates accountability, review and approval structures, version control, source and change traceability, and audit defensibility, and is guided by ISO 9001 [28], ISO/IEC 42001 [8], ISO 19011 [32], and the NIST AI Risk Management Framework [7]. Finally, Time Efficiency (TE) index measures the reduction in effort required to produce the necessary artifacts and evidence package within a fixed time window; while this is not a direct certification criterion, it is relevant from the perspective of continuous improvement and lean quality practice [21]. Collectively, these five indices provide the evaluation logic later operationalized in Section 5 and help connect the proposed framework to both recognized standards and observable QA outcomes.
For the purposes of the PoC, these five indices are treated as analytically distinct evaluation dimensions rather than as components of a single latent measurement scale. Their role is to translate the framework’s intended QA and audit outcomes into observable assessment criteria for the integrated deliverable package. Accordingly, DQ operationalizes documentation completeness, internal consistency, and audit readiness; DC operationalizes the explicitness and coverage of detection, containment, and hold/stop logic; PCS operationalizes capability-oriented monitoring and reaction rules; GP operationalizes accountability, approvals, version control, and change traceability; and TE operationalizes the effort required to produce the integrated artifacts within the fixed PoC window. To improve transparency and rating consistency, the operational score anchors for all five indices are reported in the Supplementary Materials.
Conventional manufacturing metrics such as FPY, DPMO, Cp/Cpk, and OEE remain essential for assessing process and production performance, but they do not adequately capture whether AI-supported QA artifacts are source-grounded, internally consistent, reviewable, traceable across revisions, or defensible in audit contexts. This methodological gap is especially important in regulated QA environments, where the quality of documentation and evidence structures is itself a critical object of assessment. The proposed five-index evaluation system therefore extends conventional performance measurement with criteria tailored to generative-AI-supported QA outputs, thereby providing the evaluative basis for the framework developed later in the paper.
3. Related Work
Rather than cataloguing studies individually, this section compares the dominant application categories and framework types in order to identify the main unresolved methodological and governance gaps that motivate the proposed framework.
3.1. Applications of Generative AI Tools for Quality Assurance in Manufacturing Companies
Over the last decade, shop-floor and laboratory quality assessment has evolved from paper-based records and stand-alone SPC tools toward integrated digital environments that connect SPC, MSA, eQMS, MES, and PLM. This shift has enabled systematic data capture, risk-based sampling, and closed-loop dashboards. The latest transition introduces generative and multimodal AI capabilities that can draft QMS-managed documentation, explain deviations, link records across systems, and compile audit-ready narratives, provided that outputs remain source-grounded and are released only after formal review and sign-off within the QMS [33]. In parallel, predictive-quality and digital-twin research provides methods and performance baselines for evaluating impact on operational outcomes such as FPY, PPM/DPMO, Cp/Cpk, CAPA timeliness, and audit nonconformities [34,35].
The main categories of generative-AI-enabled assistants and their associated assurance controls can be summarized as follows:
- QMS/MES/PLM-embedded copilots support drafting of PFMEA sections, control plans, PPAP summaries, and work instructions using CTQs, specifications, SPC/MSA results, and NCR/CAPA histories. Their benefits lie in faster revision cycles and more consistent documentation, but safe use requires approved-source grounding, versioned audit trails, and human sign-off [36].
- Vision–language assistants for AOI and in-process diagnostics combine AOI imagery with SPC signals to generate operator-facing explanations and defect interpretations. Although they can strengthen image-based diagnostics, in regulated QA contexts they remain advisory and require MSA-aligned validation and periodic requalification [37,38].
- Retrieval-augmented generation (RAG)-based QA assistants answer line-side questions by retrieving approved work instructions, control plans, and standards, then generating cited responses. Hybrid retrieval designs improve precision and traceability, making them suitable for governed QA knowledge support [39].
- Supplier quality and incoming-inspection copilots summarize supplier defect histories, identify documentation gaps, and suggest risk-based sampling adjustments. Their use requires clear SQE responsibility, access control, and traceable rationale trails [36].
- CAPA and audit-evidence assemblers draft 8D/CAPA narratives and compile evidence packages from logs, test results, and event records. Their value lies in documentation completeness and evidence structuring, but they require schema checks, explicit approvals, and role-based validation [40].
- Metrology and laboratory reporting aides support method descriptions, uncertainty narratives, and result summaries in ISO/IEC 17025-type settings. These outputs must remain consistent with validated methods, documented uncertainty budgets, and authorized sign-off practices [41].
- Simulation and digital-twin scenario generators support “what-if” inspection planning, process stress testing, and rapid hypothesis generation before process changes are released. Their value is strongest in pre-production and optimization contexts, but they require verification and validation, input lineage controls, and human approval of resulting actions [35].
Across these categories, recurring assurance controls include human-in-the-loop approval for release-relevant artifacts, strict source grounding with citations, segregation of duties in audit workflows, role-based access control, data minimization, monitoring for drift with periodic revalidation, and documented change management for prompts, templates, and retrieval indexes [12,13]. Evaluation should also consider operational and compliance outcomes, such as FPY, PPM/DPMO, Cp/Cpk, CAPA lead time, and audit findings, in order to verify that AI strengthens assessment quality rather than introducing new failure modes. Independent evaluations further highlight the limitations of vision–language and multimodal LLMs on industrial tasks, reinforcing the prevailing practice of deploying them as decision-support systems rather than autonomous control mechanisms in regulated QA [42].
Table 1 compares these tool categories in terms of typical QA tasks, primary data, integrations, example outputs, and key assurance controls in order to clarify how each tool type fits within the broader quality ecosystem.
Table 1.
Comparison of widely used generative AI tool categories for manufacturing quality assurance.
The reviewed tool categories show that generative AI is already being applied across multiple QA functions, but mostly in fragmented and task-specific ways. Document-centric copilots improve drafting speed and consistency, RAG assistants strengthen governed access to approved knowledge, and multimodal or digital-twin-based systems support anomaly interpretation and adaptive monitoring. However, these applications differ substantially in their assurance requirements and cannot be treated as interchangeable layers of automation. Some require citation enforcement, version control, and formal sign-off, whereas others require advisory-only use, validation discipline, and close alignment with shop-floor control systems. This fragmentation suggests that the literature is richer in tool demonstrations than in integrated QA architectures. In particular, it reveals continuing methodological needs for explicit evidence structuring, end-to-end traceability, governed approvals, and system-level alignment with QMS requirements—needs that directly motivate the framework proposed in Section 4.
3.2. Frameworks for Application of Generative AI in Manufacturing Quality Assurance
In parallel with tool development, recent studies have proposed frameworks for embedding generative AI in manufacturing QA, including system architectures, functional scopes, and safeguard mechanisms (Table 2). This subsection reviews representative approaches with emphasis on integration into quality processes, evidence traceability, and risk controls, and positions the operational framework proposed in Section 4.
Recent work illustrates several directions. Rydzi et al. [43] developed a predictive inspection framework for automotive production that uses machine learning to triage end-of-line inspections based on defect risk; although generative components were not central, the study points to the potential role of language models in organizing recurring warranty failure patterns. Nguyen et al. [44] proposed XedgeAI, a human-centered inspection framework combining explainable AI and vision–language models for edge-deployed defect detection. Lin et al. [45] introduced DDD-GenDT, a dynamic data-driven digital twin architecture that uses LLM ensembles to support real-time adaptation, such as tool-wear prediction. A related stream focuses on generative models for QA data augmentation and automation. Shafiee [46] reviewed the use of GANs and VAEs for synthetic defect-image generation, while Thomas [47] and Alsaif et al. [48] reported LLM-based approaches for accelerating FMEA drafting and supporting fault diagnosis. Wang et al. [49] proposed a multimodal LLM framework for real-time shop-floor question answering in inspection and maintenance contexts.
Despite these advances, many published frameworks remain scoped to specific domains or functions and provide limited guidance on integration within a QMS. Cross-cutting requirements such as traceable evidence packaging, role-based approvals, change control, and audit readiness are often treated only implicitly or left to implementation. Shadid et al. [50] similarly observe that many Quality 4.0 frameworks remain conceptual, resource-intensive, and insufficiently validated in real operational settings.
More recent approaches move toward tighter integration of foundation models with curated enterprise knowledge and governance mechanisms. Álvaro and González Barreda [51] presented a retrieval-augmented system for QA that answers operator questions using curated document repositories, while Wan et al. [39] extended this direction by incorporating knowledge graphs to improve factual consistency and traceability. Complementary work by Sun et al. [35] and Mata et al. [52] positions LLMs to support adaptive monitoring and evidence-backed adjustments as process states evolve, including within digital twin ecosystems. Across these contributions, a common pattern emerges: scalable manufacturing QA requires not only capable foundation models, but also role-restricted data access, auditable outputs, and explicit QMS-aligned safeguards.
Table 2.
Overview of recent frameworks for applying generative AI in manufacturing quality assurance.
Table 2 shows that many existing frameworks remain tool-specific or function-specific and only partially address the governance mechanisms required for enterprise-scale QA deployment. Recurring gaps include limited support for audit-ready evidence structuring, incomplete end-to-end traceability, and insufficiently explicit approval and oversight mechanisms. These limitations directly motivate the design choices presented in Section 4.
RAG- and knowledge-graph-enhanced assistants can strengthen governed decision support, but their reliability depends on retrieval from versioned sources, strict access governance, and mandatory human validation. Digital-twin-oriented and explainable inspection frameworks improve adaptive monitoring and interpretability, yet they also intensify requirements for lifecycle logging, change management, disciplined versioning, and explicit linkage to source data and approvals.
These limitations motivate our multi-level, multi-branch framework. Rather than treating generative AI as a single tool-centric layer, the proposed framework organizes it within a governed assurance architecture spanning product, process, and operation levels and linking manufacturer, auditor, and oversight roles through a common five-phase cycle.
Despite recent progress toward more structured forms of QA support, important limitations remain. Many existing approaches still focus on isolated functions, such as inspection, question answering, FMEA drafting, or digital-twin adaptation, without fully addressing how generated outputs become controlled, reviewable, and auditable elements of the QMS. Across the literature, three recurring unmet needs are evident: limited support for audit-ready evidence packaging, incomplete end-to-end traceability from operational signals to QA decisions, and insufficiently explicit role-based approvals, oversight, and change-control mechanisms. In addition, validation is often narrow in scope, which limits confidence in enterprise-scale applicability. These gaps directly motivate the present study’s multi-level, multi-branch framework, which is designed not simply to support isolated QA tasks, but to organize generative AI within a governed assurance architecture linking product, process, and operation levels through explicit evidence flow, human oversight, and traceable decision logic.
4. Framework for Generative AI-Supported Quality Assurance in Manufacturing Enterprises
This section introduces a structured framework for embedding generative AI tools—LLM-based assistants, semi-autonomous agents, and analytics components—into industrial QA workflows. The aim is to support a scalable and auditable QA ecosystem by integrating AI capabilities into both manufacturing and assurance activities within a unified, hierarchical architecture.
In this study, auditability is treated as an operational property of the QA documentation lifecycle: outputs are audit-ready only if they are traceable to controlled sources, versioned, approved by accountable roles, and linked to explicit control logic and escalation conditions. This understanding is consistent with management-system auditing guidance and with AI risk-management frameworks that emphasize governance, monitoring, and human oversight throughout the AI lifecycle [32].
The framework addresses growing requirements for quality, compliance, and operational efficiency by coordinating three participant groups: manufacturers (left branch), auditors (right branch), and the central QA oversight/decision workflow. Generative AI supports each group with role-specific functions while maintaining accountability through governed inputs, approvals, and traceable outputs. Within this framework, generative AI is used to support documentation, evidence structuring, anomaly interpretation, and recommendation generation, but it does not act as an autonomous quality-control authority. In regulated settings, release-relevant decisions—including CAPA approval, SPC-related reaction decisions, supplier approval or disposition, and audit conclusions—remain under authorized human responsibility and require review, sign-off, and traceable documentation within the QMS. This design choice is also consistent with broader arguments in the interpretable AI literature that high-stakes decisions should not rely on opaque black-box outputs without strong interpretability and accountability safeguards [53].
Human-in-the-loop review is therefore treated as a required control point for any release-relevant artifact, ensuring that generative AI outputs become audit-ready only after domain-expert verification, approval, and evidence linkage.
As shown in Figure 1 and Figure 2, the framework is deployed across three nested assessment levels—product (Level 1), process (Level 2), and operation (Level 3). Each product is assessed through a defined set of processes, and each process comprises its own (potentially different) number of operations. The QA decision logic follows a common five-phase cycle: planning, pre-run preparation, in-process monitoring, post-run correction, and review. Within this structure, generative AI strengthens real-time visibility, documentation consistency, and response speed, while all release-relevant decisions remain mediated by human review, documented evidence flow, and hierarchical gate assessment across levels and artifacts.
Figure 1.
Overview of the proposed hierarchical QA framework at the product and process levels (Levels 1 and 2). Notes: In both figures, the main vertical sequential path represents the workflow logic; cross-branch and cross-level connectors represent the flow of information and evidence; the left, middle, and right zones indicate responsibility allocation; and the highlighted decision diamonds denote control points associated with gate-based escalation. The size of the green icons representing generative AI tools (left and right branches) indicates the relative extent of generative AI applicability to each quality assessment activity. The flowchart for the operation block is presented in Figure 2.
Figure 2.
Detailed operation-level workflow (Level 3) within the proposed hierarchical QA framework. Notes: The arrows, indicated by dotted lines, represent the path of escalation of the problem to higher analysis and decision-making levels.
More specifically, the framework operates through an evidence-driven causal chain rather than through unrestricted automation. In the planning and pre-run preparation phases, generative AI supports the creation and refinement of inspection rules, control documents, supplier-related materials, and operation-specific criteria, while human actors review and approve these outputs before operational use. During in-process monitoring, AI generates traceable intermediate outputs, such as anomaly alerts, deviation records, updated work instructions, and structured observations derived from sensor, vision, and procedural data, but these remain decision-support signals rather than final QA decisions. In the post-run correction phase, these signals are converted into governed documentation and evidence through root-cause analysis, NCR/CAPA drafting, corrective-action proposals, and auditor-side validation. The validated outputs then enter the central QA workflow through hierarchical decision gates: operation-level evidence is assessed against θop, the resulting conformance status feeds the corresponding process-level gate θpc, and the process-level results subsequently support the final product-level decision θpd. At each stage, non-fulfillment of the relevant acceptance criteria interrupts upward progression and triggers predefined actions, including rework, containment, correction, revalidation, or escalation. In this way, final QA decisions arise not directly from AI outputs, but from controlled interaction among AI-supported analysis, human approval, documented evidence flow, and hierarchical gate assessment.
The three levels define the scope of assessment and the granularity of evidence required. As the framework moves from product- to process- and operation-level assurance, the emphasis shifts from evaluating units or batches to explaining process variation and verifying operation conformance. In parallel, generative AI extends from supporting inspection and defect handling to enabling evidence synthesis, documentation standardization, and traceable, auditable decisions across stakeholders.
Level 1. Product-Level
At this level, QA focuses on discrete units or individual batches. Manufacturers use AI to define inspection parameters, simulate failure modes, and generate tailored quality checklists from historical data and design specs. During execution, AI agents monitor anomalies in sensor and vision data, adjust sampling dynamically, and support frontline teams with chatbot-guided decisions. Post-run, generative AI clusters defects, drafts CAPA reports, and produces structured feedback. Auditors benefit from real-time access to conformance logs and anomaly reports, allowing timely verification of product integrity and decision traceability.
Level 2. Process-Level
Here, the framework shifts focus to production lines and process stability. Generative AI analyzes past performance and suggests control limits, identifies deviations in live SPC charts, and validates machine configurations against standards. Throughout the production run, audit bots monitor procedural compliance, highlight process drifts, and document deviations. After completion, AI-driven analysis correlates defects with process inputs, enabling root cause discovery and CAPA validation. Results feed into broader process improvement cycles and influence future inspection strategies.
Level 3. Operation-Level
At the operation level (Figure 2), the framework supports the execution of a specific manufacturing operation. Generative AI assists with operation setup guidance, operator-facing work instructions, real-time criteria checking and structured data capture, and rapid handling of deviations (reset of the operation (including rework) or escalation to process design review). Operation-level outputs provide the evidence required for the corresponding Level 2 process assessment.
As shown in Figure 1, the proposed framework is represented as a central QA decision workflow (Levels 1 and 2) positioned between manufacturer-facing activities on the left (factory branch) and auditor-facing activities on the right (audit branch). Figure 2 expands the embedded Level 3 operation workflow used within each Level 2 process. All participants follow the same five-phase cycle: planning, pre-run preparation, in-process monitoring, post-run correction, and review.
To ensure that the framework remains grounded in industrial practice and audit rigor, the central decision workflow evaluates performance through three level-specific KPI bundles linked to the hierarchical structure of the framework: θpd, θpc, and θop (Figure 1 and Figure 2). These symbols do not denote abstract standalone thresholds; rather, they represent structured sets of quality indicators assessed against predefined acceptance criteria in support of transparent governance and accountability.
The product-level KPI bundle (θpd) is used to evaluate product-related quality performance and conformity with CTQ requirements. In the proof-of-concept setting, this KPI bundle was operationalized through indicators such as FPY of at least 95%, DPMO of 500 or less, and compliance with defined CTQ-related requirements. If these acceptance conditions are not satisfied, the workflow triggers product-level corrective action.
The process-level KPI bundle (θpc) is used to evaluate process capability, process stability, and control effectiveness. In the PoC, this included criteria such as Cp/Cpk-based capability targets, particularly Cpk ≥ 1.33, together with process-monitoring and reaction logic intended to identify drift and sustain control. In practice, θpc is assessed per process (θpcj). If the acceptance conditions linked to θpc are not met, the workflow initiates process-level correction, containment, or revalidation.
The operation-level KPI set (θop) is used to evaluate operational assurance, governance readiness, and auditability. In the PoC, this included zero major nonconformities, no more than two minor nonconformities, CAPA on-time closure of at least 90%, and verified traceability and data integrity. Where relevant, this level may also incorporate the minimum passing requirements defined by the applicable internal or external assessment scheme. Failure to satisfy the conditions associated with θop initiates formal escalation for higher-level review and documented follow-up.
These KPI sets are established during the pre-run preparation phase to ensure calibration to the specific product, process, and regulatory context. Their values are derived by combining customer and design CTQs, applicable quality standards and regulatory requirements, and historical baseline data from similar products or production lines. In this way, the framework provides a controlled and context-sensitive basis for AI-supported decision-making rather than relying on fixed generic benchmarks.
Validation of the KPI sets is performed through a multi-stage process involving pilot implementation, gate review, and failure-mode examination. During the pilot stage, the selected criteria are tested against actual process variation to verify that the expected levels of yield, capability, traceability, and governance are both operationally feasible and statistically meaningful. In addition, failure scenarios are examined to ensure that escalation logic, nonconformity handling, CAPA response, and data-integrity checks function correctly within the system workflow. This staged validation helps ensure that the KPI sets remain grounded in empirical process performance before the framework is deployed for full-scale production oversight.
Levels 1–3 are linked through an explicit evidence-flow and gate-assessment mechanism. At Level 3, AI-supported operation execution generates records, anomaly flags, conformance checks, and deviation-related documentation, which are reviewed and validated before being assessed against θop. Only validated operation-level evidence proceeds to the corresponding process-level gate θpc1, …, θpcN, where process capability, stability, and control effectiveness are evaluated. If θop is not satisfied, the workflow triggers local reset, rework, or escalation to process design review; if θpc is not satisfied, the workflow triggers process-level correction, containment, or revalidation. Only when the process-level gate is satisfied does the workflow proceed to the product-level decision θpd, where final conformity and release readiness are assessed. At the framework level, each core deliverable—PFMEA, linked Control Plan, supplier PPAP documentation, and the audit-evidence package—serves not only as a planning artifact, but also as a traceable evidence input supporting the hierarchical gate logic from θop to θpc and, ultimately, to θpd. In this way, upward progression depends on validated evidence and gate satisfaction at the immediately preceding level, while the manufacturer and auditor branches jointly provide the generation, review, validation, and documentation functions that make the final QA decision auditable and accountable.
The framework also specifies how generative AI contributes to QA processes across the five workflow phases. Rather than functioning as an autonomous decision-maker, AI supports the generation of structured signals, draft records, and evidence inputs that are subsequently reviewed, validated, and incorporated into hierarchical QA decisions by the responsible manufacturer- and auditor-side actors.
Step 1: Planning
In the planning phase, manufacturers define quality objectives, inspection formats, and evaluation rules with support from generative AI-driven historical analysis, defect pattern prediction, and standards-based planning tools. This ensures alignment of control expectations with prior performance and design intent. Simultaneously, auditors review and validate these definitions using AI to cross-reference industry benchmarks, simulate failure scenarios, and assess compliance frameworks. AI helps both parties converge on clear, measurable goals that form the baseline for subsequent QA actions.
Step 2: Pre-Run Preparation
Manufacturers use generative AI to retrieve and validate control documents, organize inspection data structures, simulate production runs for risk-based prioritization, and assess supplier readiness through automated credential reviews and communication. AI-driven planning agents also generate or refine inspection routines and tooling specifications. On the auditor side, generative AI supports the review of prior audit findings and nonconformance records, highlights common deficiencies, and ensures that control documentation is up-to-date. Interactive AI checklists and training modules help auditors prepare efficiently, while benchmarking tools ensure that audit scope aligns with regulatory and corporate expectations.
Step 3: In-Process Monitoring
During manufacturing execution, generative AI enables real-time anomaly detection by interpreting visual and sensor data streams, dynamically adjusting sampling rates based on process risk, and issuing traceable alerts tied to specific failure modes. It can update work instructions in response to detected deviations and provide decision support via line-side AI chatbots. For auditors, autonomous agents continuously monitor control plan adherence, validate operator inputs, and verify that SPC and MSA procedures remain within acceptable thresholds. AI further detects drift, ensures consistency with digital twin models, and flags anomalies for interim review. These outputs function as documented intermediate signals that trigger human review, additional checks, or corrective action, and they enter the subsequent evidence chain only after validation by the responsible actors.
Step 4: Post-Run Corrections
After production, manufacturers analyze defect logs, perform root cause analysis, and draft CAPA reports. Generative AI helps generate NCR documentation, update control plans, and feed corrective insights back into upstream design or process steps. It also compiles operator-level feedback for broader learning. Auditors, supported by generative tools, evaluate CAPA completeness, verify corrective effectiveness, and request clarifications or supporting evidence as needed. AI-generated summaries and traceability logs ensure completeness and transparency, while systemic recommendations are flagged to drive long-term quality improvements. At this stage, AI-assisted outputs are transformed from draft analytical artifacts into governed evidence packages that can support gate assessment, escalation, and audit follow-up.
Step 5: Review (Post-market Feedback)
In the final phase, manufacturers use generative AI analytics to detect cross-batch trends, identify chronic issues, and guide strategic QA planning. These insights contribute to refining inspection strategies and mitigating recurring risks. Auditors engage in longitudinal analysis of accumulated audit data, using AI to produce comprehensive summary reports that track improvements or degradations in process maturity over time. The outputs inform both compliance assurance and future audit planning cycles. This final phase closes the causal loop by consolidating validated lower-level evidence into higher-level QA judgments, strategic adjustments, and documented learning for subsequent cycles.
This generative AI–enabled industrial QA framework aligns technological innovation with quality assurance rigor, supporting all actors in the manufacturing ecosystem—from production engineers and QA professionals to internal and external auditors. Designed for flexibility and adaptability across diverse manufacturing contexts, it enables a balanced integration of automation and expert oversight. The framework is structured to reflect five core QA phases—planning, pre-run preparation, in-process monitoring, post-run correction, and review—applied across three hierarchical levels of quality control: product-level, process-level, and operation-level assessments.
For manufacturers, the framework ensures timely QA interventions, minimizes waste through early defect prediction, and increases efficiency through automation. For auditors, AI enhances transparency, allows real-time access to structured compliance evidence, and supports consistency across evaluations. By enabling proactive, data-informed action, this model fosters a more resilient, responsive, and explainable QA system.
Moreover, by embedding AI into a clearly phased assessment cycle, the framework promotes industrial QA principles such as consistency, adaptability, continuous improvement, and traceability. It supports personalized quality goals at the product level, dynamic oversight at the process level, and strategic coordination at the operational level. The integration of generative AI strengthens systemic integrity while empowering human actors with the tools to achieve higher precision, compliance, and productivity.
Additionally, generative AI enhances industrial audit processes by supporting the validation of inspection protocols, fairness in sampling procedures, and alignment with established quality control and compliance frameworks. Natural language processing-drive tools can evaluate whether inspection instructions are overly narrow or ambiguous, detect duplications or inconsistencies in control plan documentation, and flag potential procedural gaps that may compromise traceability or integrity. AI-assisted review of operator comments, maintenance logs, and supplier assessments also informs continuous improvement cycles and supports evidence-based QA auditing. Through these capabilities, internal and external audit bodies gain more structured oversight, faster reporting, and greater consistency in evaluating compliance with regulatory and industry-specific standards.
However, implementing generative AI in manufacturing QA also brings critical challenges that require diligent oversight. Chief among them is the potential for bias in automated quality assessments—such as skewed judgment due to unbalanced training datasets or overfitting to past defects. Such risks may lead to either overreporting issues or overlooking emerging deviations. To address this, regular audits of AI tool performance are essential, including calibration reviews, transparency in training data origins, and human-in-the-loop validation of non-conformity assessments. Over-reliance on automation must be avoided: engineers and auditors must retain decision-making authority, particularly in interpreting borderline cases and confirming CAPA effectiveness. Operational policies should mandate hybrid oversight models where AI-generated outputs serve as decision support tools, not final arbiters.
This generative AI–driven framework introduces a robust, tiered approach to industrial QA, integrating innovation while safeguarding process credibility and human accountability. By embedding intelligent automation into inspection design, execution, and audit review, the framework enhances visibility, responsiveness, and documentation across the product, process, and operational levels. It accommodates a broad range of generative AI applications, from predictive analytics and automated anomaly detection to report generation and digital twin validation.
To demonstrate how the proposed framework works in practice, Section 5 applies it in a bounded proof-of-concept (PoC) new product introduction (NPI) quality-planning task. The PoC operationalizes the framework’s assessment logic through three level-specific KPI bundles and reflects the two role branches by requiring both manufacturer-side planning artifacts and auditor-oriented evidence packages.
5. Validation of the Proposed Generative AI-Based Quality Assurance Framework
To assess the practical applicability of the proposed generative AI-enabled QA framework, we conducted a single-case PoC study in electronics manufacturing focused on an NPI quality-planning task. The case was selected because NPI requires standardized and auditable planning artifacts, such as PFMEA, the Control Plan, supplier readiness documentation, and audit evidence packaging, and because traceability and approval governance are operationally meaningful at this stage. The task was performed under the same fixed 10-business-day constraint in two parallel conditions: (1) a team of three QA experts and (2) an LLM-driven workflow using ChatGPT-5-Thinking (hereafter, ChatGPT). The expert-team workflow followed ISO 9001-aligned QMS procedures, including document control, internal review, and formal approval prior to release.
Both conditions received an identical input package comprising the same ST-200 case brief and constraints, a fixed deliverable specification (detailed in Section 5.1), and a shared acceptance logic defined by the KPI bundles θpd, θpc, and θop. Both conditions were required to produce the same four deliverables: a PFMEA, a linked Control Plan, a supplier PPAP request package, and an internal audit evidence pack. This design enabled a direct comparison of planning efficiency, documentation quality, risk coverage, and audit readiness.
The AI-assisted condition was executed under a fixed workflow protocol to improve procedural transparency and comparability. The workflow followed a structured prompting sequence covering PFMEA drafting, linked Control Plan generation, PPAP checklist preparation, and audit-evidence packaging. AI-generated outputs were treated as controlled draft artifacts rather than final release documents and were therefore subject to the same review, document-control, and approval expectations applied within the PoC setting. The study reports the available information regarding the execution context, grounding conditions, and validation procedure, while the detailed prompting sequence and core prompts are provided in the Supplementary Materials. Where platform-level settings were not independently exposed to or controlled by the researchers, this is stated explicitly.
The unit of analysis was the integrated deliverable package produced under each condition. Three independent evaluators then assessed both packages using the same five rubric-based indices: documentation quality and audit readiness DQ, detection and containment DC, process capability stability PCS, governance and provenance GP, and time efficiency (TE) index. Full operational score anchors, rater-level tables, and inter-rater reliability statistics are reported in the Supplementary Materials.
As a PoC, the objective of the study is to demonstrate feasibility and comparative value for a representative NPI task rather than to claim generalizability across all products, plants, or regulatory settings. The case follows the framework’s three-level assessment logic (Levels 1–2 in Figure 1 and Level 3 in Figure 2). Given the single-case PoC design and the small evaluator panel, the quantitative comparison is reported as exploratory evidence; the emphasis is on transparent rubric-based scoring and rater agreement rather than on confirmatory statistical inference.
5.1. Case Study: NPI Quality Planning for Smart Thermostat ST-200
The case concerns quality planning for the ST-200 smart thermostat, which includes an RF mainboard, a capacitive touchscreen, a temperature sensing module, and an injection-molded enclosure. To ensure a controlled comparison, both the expert-only and AI-assisted conditions operated under the same fixed 10-business-day time window and received an identical input package comprising the ST-200 case brief, product and process constraints, CTQ-related requirements, and a fixed deliverable specification defined for the PoC.
Under these shared conditions, both approaches were required to produce the same four readiness deliverables: (1) a PFMEA, (2) a linked Control Plan, (3) PPAP requests/templates for key suppliers, and (4) an evidence package suitable for internal audit review. In addition, both conditions were evaluated against the same acceptance logic defined by the three level-specific KPI bundles θpd, θpc, and θop. This common design basis ensured that any observed differences between the two conditions reflected workflow performance rather than differences in task scope, input availability, or evaluation criteria.
The AI-assisted condition was executed under a fixed workflow protocol to improve methodological transparency and comparability. The workflow followed a structured four-stage prompting sequence aligned with the four PoC deliverables: (1) PFMEA generation, (2) linked Control Plan generation, (3) supplier PPAP templates/requests, and (4) Internal Audit Evidence Pack assembly. ChatGPT was used as a controlled decision-support and documentation-assistance tool and received the same ST-200 technical specification as the expert team. No pre-existing corporate templates or proprietary preformatted artifacts were supplied to the model; instead, it was instructed to generate the required structures from the prompted engineering requirements. After each stage, the generated outputs were reviewed through a human-in-the-loop verification gate before acceptance into the integrated PoC package.
All AI-generated outputs were treated as controlled draft artifacts rather than final release documents and were therefore subject to the same review, document-control, and approval expectations applied within the PoC setting. This protocol was intended to constrain iterative expansion and maintain governed review and acceptance conditions rather than ad hoc refinement. The study reports the available information regarding the execution context, grounding conditions, and validation procedure, while the detailed prompting sequence, representative core prompts, and verification procedure are provided in the Supplementary Materials. Where platform-level settings were not independently exposed to or controlled by the researchers, this is stated explicitly.
Consistent with the framework, three product-specific KPI bundles were defined during pre-run preparation:
- Product-level KPI set (θpd), defined through CTQ-oriented indicators such as FPY ≥ 95% and DPMO ≤ 500.
- Process-level KPI set (θpc), defined through capability and stability indicators, most notably Cp/Cpk ≥ 1.33, together with monitoring and reaction logic.
- Operation-level KPI set (θop), defined through governance and auditability indicators, including zero major nonconformities, no more than two minor nonconformities, CAPA on-time closure ≥ 90%, and verified traceability and data integrity.
If θop is not satisfied, the workflow triggers a reset of the operation (including rework) or escalates to process design review; if θpc is not satisfied, it triggers a reset of the affected process or escalation; and if θpd is not satisfied, the case returns for redesign and/or technology approval at the product level.
5.2. Expert Team Solution
The first solution was developed by a team of three QA professionals with experience in AI-supported manufacturing environments. Operating under the same fixed deliverable scope, time window, and acceptance logic as the AI-assisted condition, the team produced the same four PoC deliverables for comparative evaluation. Their work followed the organization’s ISO 9001-aligned QMS procedures, including document control, internal review, and formal approval workflows [28].
The expert team drafted the required planning artifacts, considered low-frequency failure scenarios, and verified the control logic and reaction plans. Their PFMEA emphasized critical surface-mount technology (SMT), bonding, firmware flashing, and final assembly steps, while the linked Control Plan focused on Cp/Cpk monitoring for CTQs and traceable reaction procedures. Table 3 summarizes the expert team’s PFMEA priorities across high-risk steps and final assembly.
Table 3.
Extract of PFMEA—expert team.
Overall, the expert documentation was clear and suitable for the NPI task. However, compared with the AI-assisted package, it included fewer explicit mechanisms for clause-to-evidence mapping, formalized change logging, and predefined audit-trigger logic supporting rapid audit packaging.
Table 3 presents representative PFMEA entries from the expert team’s solution across high-risk process steps. The associated Control Plan relied on 100% solder paste inspection (SPI), AOI aligned with IPC-A-610 criteria, and torque traceability using DC electric torque tools. Overall, the expert documentation was clear and suitable for the NPI task; however, compared with the AI-assisted package, it included fewer explicit mechanisms for clause-to-evidence mapping, formalized change logging, and predefined audit-trigger logic supporting rapid audit packaging.
5.3. ChatGPT Solution (Generative AI-Driven Planning)
The second condition applied the same deliverable requirements within the proposed framework using ChatGPT. As in the expert-only condition, the AI-assisted workflow operated under the same case constraints, deliverable scope, time window, and acceptance criteria, so that the comparison reflected differences in workflow execution rather than differences in task definition.
The AI-assisted condition was executed under a fixed workflow protocol designed to improve methodological transparency and comparability. The workflow followed a structured prompting sequence comprising four task blocks: (1) PFMEA drafting, (2) linked Control Plan generation, (3) PPAP request/checklist preparation for key suppliers, and (4) audit-evidence package assembly. In each block, the model was instructed to operate only within the scope of the provided case materials, predefined deliverables, and acceptance logic. AI-generated outputs were treated as controlled draft artifacts rather than final release documents and therefore remained subject to document-control requirements, internal review, and formal approval expectations consistent with the PoC setting. Validation was performed through expert review of completeness, consistency, traceability, and alignment with the predefined KPI bundles, while release-relevant judgments remained under human authority.
The AI-assisted workflow was grounded in the provided case materials and did not rely on unrestricted open-ended retrieval. Where retrieval-like support was used, it was limited to the supplied PoC documentation and fixed deliverable context rather than to dynamic enterprise databases or external live sources. The manuscript reports the available information regarding the access context, execution environment, grounding conditions, and review/approval procedure at the level exposed to the researchers. Detailed core prompts and the prompting sequence are provided in the Supplementary Materials, whereas platform-level settings not independently exposed to or controlled by the researchers are explicitly acknowledged as such rather than treated as experimental variables.
The generative model produced a structured PFMEA and linked Control Plan logic, generated PPAP checklist templates for the electronics and plastics suppliers, and assembled an audit-evidence package with embedded traceability references. Table 4 presents an extract of the resulting PFMEA; compared with the expert extract, it places greater emphasis on governance-oriented metadata, such as ownership, residual-risk notation, and evidence linkage, rather than on maintaining a strictly identical set of process steps.
Table 4.
Extract of PFMEA—ChatGPT.
Compared with the expert package, the ChatGPT output added governance-oriented metadata such as responsible-owner tags and rRPN values, together with explicit containment and escalation logic linked to θpd, θpc, and θop. The linked Control Plan also incorporated structured pass/fail criteria and poka-yoke checks, while KPI views and evidence bundles were organized into an audit-ready package supporting faster review and traceability verification.
5.4. Comparative Evaluation
To compare the two NPI quality-planning solutions, we applied a structured set of validation indices that translate the intended outcomes of the framework into observable evaluation criteria (Section 2.2). The indices cover: (1) documentation completeness and audit readiness; (2) prevention-oriented detection and containment logic; (3) stability of capability controls; (4) governance and provenance safeguards; and (5) execution efficiency. They were informed by established quality and audit practice, NIST guidance for trustworthy generative AI, and prior Quality 4.0 and industrial QA literature. All four deliverables (PFMEA, linked Control Plan, PPAP templates/requests, and the audit-evidence package) were assessed as a single integrated planning package rather than scored separately. Each index was scored independently by three QA experts, and the reported value represents the mean of the three ratings. For transparency and reproducibility, the detailed scoring rubric and the supporting expert-rating tables used in the PoC evaluation are reported in Supplementary Sections S3 and S4.
To improve scoring transparency, each index was evaluated using an anchored 0–4 rubric. Under this rubric, DQ ranges from missing or fragmented documentation to audit-ready documentation with explicit trace links; DC ranges from absent or generic containment logic to comprehensive trigger- and action-based logic with edge-case coverage; PCS ranges from absent capability/stability control to early-warning monitoring with robust reaction rules; GP ranges from minimal governance fields to fully traceable and audit-defensible documentation; and TEI ranges from unacceptable delay to substantially faster execution with governance preserved. The unit of assessment was the integrated planning package, because the objective was to evaluate whether the full set of PoC deliverables functioned coherently as a governed QA and audit-readiness bundle.
Table 5 summarizes the comparative results. Conceptually, the indices map to the framework’s level-specific KPI bundles: DC most closely supports θpd, PCS aligns with θpc, and DQ and GP align primarily with θop. TE is cross-cutting, reflecting how efficiently the framework operationalizes product-, process-, and operation-level requirements across the shared five-phase cycle. The five indices were not combined into a single weighted composite score; instead, they were retained as separate but complementary evaluation dimensions in order to preserve diagnostic interpretability. This choice was deliberate, because the PoC was designed to compare the quality, governance, and audit readiness of integrated planning outputs rather than to estimate a latent performance construct. The comparison should therefore be interpreted as a controlled PoC contrast between two planning conditions under shared task constraints, rather than as an attempt to equalize human prior professional knowledge and model pretraining.
Table 5.
Mean expert ratings comparing the expert-team and ChatGPT solutions.
The five indices were not combined into a single weighted composite score. Instead, they were retained as separate but complementary evaluation dimensions in order to preserve diagnostic interpretability. This choice was deliberate, because the PoC was designed to compare the quality, governance, and audit readiness of integrated planning outputs rather than to estimate a latent performance construct. In this sense, the index system functions as a structured decision-support and audit-readiness assessment set, with each dimension capturing a distinct aspect of framework performance.
For robustness, inter-rater reliability was assessed using Percent Agreement (PA), Kendall’s coefficient of concordance (W), Cronbach’s alpha (α), and the intraclass correlation coefficient (ICC(3,1)). The conventional workflow showed moderate to good reliability (PA = 0.773, W = 0.773, α = 0.851, ICC = 0.655), whereas the AI-augmented workflow demonstrated very high agreement (PA = 1.000, W = 0.956, α = 0.981, ICC = 0.946). These results indicate that the structured, evidence-linked outputs generated within the proposed framework were assessed more consistently across reviewers (see Supplementary Materials). Together with the explicit score anchors, the observed inter-rater agreement supports the practical validity of the five-index system as a transparent comparative instrument for assessing QA planning quality and audit readiness in the bounded PoC setting.
As shown in Table 5, the ChatGPT condition achieved higher mean scores across all indices, with the largest margins in GP and DQ, reflecting stronger ownership tagging, versioning logic, and evidence linkage. These results suggest that, under the framework’s document-control and approval requirements, generative AI can strengthen QA planning performance across θpd, θpc, and θop without weakening governance safeguards.
Given the single-case PoC design and the small evaluator panel, this quantitative comparison should be interpreted as exploratory evidence; the emphasis is therefore on transparent rubric-based scoring and rater agreement rather than on confirmatory statistical inference.
5.5. Discussion
This PoC indicates that the proposed framework can operationalize generative AI support for structured industrial QA tasks while preserving control requirements typical of regulated QMS environments. The comparison suggests that generative AI is particularly effective where planning quality depends on structured documentation, cross-referencing, and evidence assembly, whereas expert teams remain strong in pragmatic judgment and context-specific refinement.
A key contribution of the framework is that it ties generative AI support to a repeatable operating rhythm—the five-phase cycle—and to explicit level-specific KPI bundles (θpd, θpc, and θop). Within this structure, AI outputs are treated as controlled inputs to the quality system: they must remain reviewable, attributable, and traceable, and they may trigger product-level corrective action, process-level containment or revalidation, and operation-level escalation only through defined governance pathways.
At the same time, generative AI introduces assurance risks. Model opacity can limit explainability; outputs may contain unsupported statements; and documentation may reflect biases or omissions that affect accountability. To mitigate these risks, the proposed workflow constrains generation to controlled inputs, requires explicit provenance and record-type tagging, applies a human-in-the-loop verification gate after each generation stage, and prohibits autonomous release decisions. These controls operationalize governance and accountability principles consistent with AI risk-management guidance and management-system auditing practices.
From an implementation and stakeholder perspective, the findings support a hybrid deployment model in which generative AI accelerates the first-draft creation of PFMEAs, Control Plans, PPAP templates, and audit-evidence packages, while human experts remain responsible for approval, risk acceptance, and final release through the QMS. For manufacturing stakeholders, this can reduce planning cycle time and improve evidence continuity across teams; for auditors and compliance coordinators, it can strengthen audit readiness through systematic trace linkage, ownership marking, and structured packaging of conformance evidence. More broadly, the results suggest that the value of generative AI in QA and auditing lies not only in faster artifact generation, but in the more systematic structuring of documentation and evidence under governance constraints. This implies that implementation should prioritize source grounding, provenance and versioning, role-based approvals, and traceability links between requirements, controls, and audit evidence. In this sense, the framework provides a structured basis for assessing whether AI-assisted QA artifacts remain reviewable, traceable, and defensible in line with audit principles and emerging AI governance expectations.
6. Conclusions and Future Research
This study proposed a structured framework for integrating generative AI into industrial quality assurance across a standardized five-phase cycle (planning, pre-run preparation, in-process monitoring, post-run correction, and review) and three nested assessment levels (product, process, and operation). The framework also delineates stakeholder roles across manufacturer- and auditor-facing activities and operationalizes evaluation through three level-specific KPI bundles: θpd for product-level quality performance, θpc for process capability and stability, and θop for operation-level assurance, governance, and auditability. In doing so, it connects AI-enabled capabilities, such as PFMEA and Control Plan drafting, anomaly interpretation, evidence packaging, and audit-oriented documentation, to established quality objectives and compliance expectations.
The proof-of-concept NPI case in electronics manufacturing showed that a generative-AI-assisted workflow, when constrained by document control, review and approval checkpoints, and traceability requirements, can generate technically plausible planning artifacts and produce more audit-ready documentation packages within the same time constraints as an expert team. The comparative evaluation indicated consistent gains for the generative-AI condition, particularly in documentation completeness, governance/provenance, and time efficiency, suggesting that the framework can strengthen audit defensibility and reduce planning overhead without removing human accountability. At the same time, expert judgment remains essential for validating assumptions, confirming rare failure logic, and ensuring that AI-generated recommendations remain context-appropriate, especially where safety, regulatory exposure, or process changes are involved.
Based on these findings, three practitioner-oriented recommendations follow. First, AI deployment in QA should be implemented through explicit policies that define allowable use, required evidence, and approval gates, rather than treated as an informal productivity aid. Second, organizations should build capability through targeted training that combines quality standards literacy (e.g., document control, CAPA discipline, and traceability expectations) with practical prompting and validation skills for generative tools. Third, governance should be designed from the outset—through access control, versioning, source grounding, and role-based sign-off—so that AI-generated content can be defended during internal reviews and external audits. For supplier-facing processes, the framework also supports earlier alignment on PPAP expectations, more consistent submissions, and clearer traceability in supplier communications.
This study has several limitations. The empirical validation was bounded to a single proof-of-concept task in one electronics manufacturing context and assessed readiness through planning artifacts and structured indices rather than through full-scale, long-term shop-floor deployment. The comparative evaluation also relied on only three expert raters and a single case, which constrains validation strength and limits external validity. The findings should therefore be interpreted as exploratory and context-specific rather than broadly generalizable, and they may be influenced by evaluator-specific judgment bias. Transferability is most plausible in settings with standardized QA deliverables, mature documented-information practices, controlled source records for provenance anchoring, and the operational capacity to implement human-in-the-loop review, version control, and evidence traceability. In settings with materially different regulatory constraints, lower documentation maturity, or limited traceability infrastructure, the framework remains conceptually applicable but requires context-specific tailoring and revalidation. Accordingly, the framework is positioned as a decision-support and documentation-governance approach, not as an autonomous quality-control system; final acceptance and release decisions remain under accountable human authority. In addition, the framework’s performance is likely to depend on the maturity of the surrounding quality infrastructure, including eQMS discipline, change control, and data availability; organizations with fragmented systems or weak document governance may therefore realize reduced benefits or face higher operational risk.
Future research should extend validation through multi-case and multi-rater studies across multiple products, plants, and industries, including settings with stricter regulatory regimes and higher safety criticality. It should also test the framework in live production environments in order to assess real-time monitoring, escalation behavior, and sustained human–AI collaboration over longer horizons. Finally, the KPI bundles θpd, θpc, and θop could be extended toward more adaptive calibration based on historical capability, risk profiles, and evolving compliance requirements, while preserving auditability through transparent rules, change logs, and controlled approval workflows.
Supplementary Materials
The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/app16094237/s1.
Author Contributions
Conceptualization, G.I., T.Y. and Y.I.; methodology, G.I. and Y.I.; validation, Y.I.; formal analysis, T.Y.; resources, G.I., T.Y. and V.H.; writing—original draft preparation, G.I.; writing—review and editing, G.I., T.Y. and Y.I.; visualization, G.I. and Y.I.; supervision, Y.I.; project administration, G.I.; funding acquisition, G.I., T.Y. and V.H. All authors have read and agreed to the published version of the manuscript.
Funding
This research was partially supported by the Project “Digitalisation of the Economy in a Big Data Environment” BG16RFPR002-1.014-0013, funded by the European Regional Development Fund (ERDF) through the “Programme Research, Innovation and Digitalisation for Smart Transformation (PRIDST)”.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data supporting the findings of this study are contained within the article and no additional datasets were generated or analyzed.
Acknowledgments
The authors thank the academic editor and anonymous reviewers for their insightful comments and suggestions.
Conflicts of Interest
Author Yuliy Iliev was employed by the company Teletek Electronics. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
References
- Escobar, C.A.; McGovern, M.E.; Morales-Menendez, R. Quality 4.0: A review of big data challenges in manufacturing. J. Intell. Manuf. 2021, 32, 2319–2334. [Google Scholar] [CrossRef] [Scilit]
- Mahin, M.; Kadasah, N.; Alsabban, A.; Albliwi, S. Exploring the landscape of Quality 4.0: A comprehensive review of its benefits, challenges, and critical success factors. Prod. Manuf. Res. 2024, 12, 2373739. [Google Scholar] [CrossRef] [Scilit]
- Khinvasara, T.; Ness, S.; Shankar, A. Leveraging AI for enhanced quality assurance in medical device manufacturing. Asian J. Res. Comput. Sci. 2024, 17, 13–35. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Zhao, H.; Jiang, H.; Pan, Y.; Liu, Z.; Wu, Z.; Shu, P.; Tian, J.; Yang, T.; Xu, S.; et al. Large Language Models for Manufacturing. J. Manuf. Syst. 2026, 86, 516–545. [Google Scholar] [CrossRef] [Scilit]
- Mokander, J.; Sheth, M.; Gersbro-Sundler, M.; Blomgren, P.; Floridi, L. Challenges and best practices in corporate AI governance: Lessons from the biopharmaceutical industry. Front. Comput. Sci. 2022, 4, 1068361. [Google Scholar] [CrossRef] [Scilit]
- Chhetri, K.B. Applications of artificial intelligence and machine learning in food quality control and safety assessment. Food Eng. Rev. 2024, 16, 1–21. [Google Scholar] [CrossRef] [Scilit]
- National Institute of Standards and Technology (NIST). Artificial Intelligence Risk Management Framework (AI RMF 1.0) (NIST AI 100-1); U.S. Department of Commerce: Gaithersburg, MD, USA, 2023. [CrossRef] [Scilit]
- ISO/IEC 42001:2023; Information Technology-Artificial Intelligence-Management System. International Organization for Standardization and International Electrotechnical Commission: Geneva, Switzerland, 2023. Available online: https://www.iso.org/standard/81230.html (accessed on 1 January 2026).
- European Union. Regulation (EU) 2024/1689 of the European Parliament and of the Council of 13 June 2024 Laying Down Harmonised Rules on Artificial Intelligence (Artificial Intelligence Act). Off. J. Eur. Union 2024. Available online: https://eur-lex.europa.eu/eli/reg/2024/1689/oj/eng (accessed on 1 January 2026).
- Cassoli, B.B.; Jourdan, N.; Nguyen, P.H.; Sen, S.; Garcia-Ceja, E.; Metternich, J. Frameworks for data-driven quality management in cyber-physical systems for manufacturing: A systematic review. Procedia CIRP 2022, 112, 567–572. [Google Scholar] [CrossRef] [Scilit]
- Ejjami, R.; Boussalham, K. Industry 5.0 in manufacturing: Enhancing resilience and responsibility through AI-driven predictive maintenance, quality control, and supply chain optimization. Int. J. Multidiscip. Res. 2024, 6, 1–31. Available online: https://pdfs.semanticscholar.org/3e49/9a40bdd3e7773ad93e2a7dcd1fdf4fabb6bf.pdf (accessed on 1 January 2026).
- NIST AI. Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile (NIST AI 600-1); National Institute of Standards and Technology: Gaithersburg, MD, USA, 2024. [Google Scholar] [CrossRef] [Scilit]
- Verma, H.; Padh, K.; Thelisson, E. Can AI be Auditable? arXiv 2025, arXiv:2509.00575. [Google Scholar] [CrossRef] [Scilit]
- Raj Mohan, R.; Thiruppathi, K.; Venkatraman, R.; Raghuraman, S. Quality improvement through first pass yield using statistical process control approach. J. Appl. Sci. 2012, 12, 985–991. [Google Scholar] [CrossRef] [Scilit]
- Verna, E.; Genta, G.; Galetto, M.; Franceschini, F. Defects-per-unit control chart for assembled products based on defect prediction models. Int. J. Adv. Manuf. Technol. 2022, 119, 2835–2846. [Google Scholar] [CrossRef] [Scilit]
- Coskun, A.; Serteser, M.; Unsal, I. Sigma metric revisited: True known mistakes. Biochem. Med. 2019, 29, 010902. [Google Scholar] [CrossRef] [Scilit]
- Steiner, S.H.; MacKay, R.J. Effective monitoring of processes with parts per million defective: A hard problem! In Frontiers in Statistical Quality Control 7; Lenz, H.J., Wilrich, P.T., Eds.; Physica-Verlag: Heidelberg, Germany, 2004; pp. 140–149. [Google Scholar]
- ISO 22514-2:2017; Statistical Methods in Process Management-Capability and Performance-Part 2: Process Capability and Performance Measures. International Organization for Standardization: Geneva, Switzerland, 2017. Available online: https://www.iso.org/standard/71617.html (accessed on 31 August 2025).
- Muchiri, P.; Pintelon, L. Performance measurement using overall equipment effectiveness (OEE): Literature review and practical application discussion. Int. J. Prod. Res. 2008, 46, 3517–3535. [Google Scholar] [CrossRef] [Scilit]
- Schiffauerova, A.; Thomson, V. A review of research on cost of quality models and best practices. Int. J. Qual. Reliab. Manag. 2006, 23, 647–669. [Google Scholar] [CrossRef] [Scilit]
- Isack, H.D.; Mutingi, M.; Kandjeke, H.; Vashishth, A.; Chakraborty, A. Exploring the adoption of Lean principles in medical laboratory industry: Empirical evidences from Namibia. Int. J. Lean Six Sigma 2018, 9, 133–155. [Google Scholar] [CrossRef] [Scilit]
- Gueorguiev, T. An approach to integrate artificial intelligence in ISO 9001-based quality management systems. Meas. Sens. 2025, 38, 101787. [Google Scholar] [CrossRef] [Scilit]
- Sood, A.C.; Dhull, K.S. The future of Six Sigma-Integrating AI for continuous improvement. Int. J. Innov. Res. Eng. Manag. 2024, 11, 8–15. [Google Scholar] [CrossRef] [Scilit]
- Abdullah, R.; Lee, H.K.; Abdul Rasib, A.H.; Mansoor, H.O. Lean Six Sigma framework to improve the assembly process at a printer manufacturing company. J. Adv. Manuf. Technol. 2023, 17, 33–46. [Google Scholar]
- Tanuska, P.; Spendra, L.; Kebisek, M.; Duris, R.; Stremy, M. Smart anomaly detection and prediction for assembly process maintenance in compliance with Industry 4.0. Sensors 2021, 21, 2376. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- El Hassani, I.; Masrour, T.; Kourouma, N.; Tavcar, J. AI-driven FMEA: Integration of large language models for faster and more accurate risk analysis. Des. Sci. 2025, 11, e10. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.C.; Liu, R.; Gu, X.; Yang, M. From total quality management to Quality 4.0: A systematic literature review and future research agenda. Front. Eng. Manag. 2023, 10, 191–205. [Google Scholar] [CrossRef] [Scilit]
- ISO 9001:2015; Quality Management Systems-Requirements. International Organization for Standardization: Geneva, Switzerland, 2015. Available online: https://www.iso.org/standard/62085.html (accessed on 1 January 2026).
- IATF 16949:2016; Quality Management System Requirements for Automotive Production and Relevant Service Parts Organizations. International Automotive Task Force: Southfield, MI, USA, 2016. Available online: https://www.iatfglobaloversight.org/iatf-169492016/about (accessed on 1 January 2026).
- Doshi, J.A.; Desai, D. Overview of automotive core tools: Applications and benefits. J. Inst. Eng. India Ser. C 2017, 98, 515–526. [Google Scholar] [CrossRef] [Scilit]
- ISO/IEC 17025:2017; General Requirements for the Competence of Testing and Calibration Laboratories. International Organization for Standardization and International Electrotechnical Commission: Geneva, Switzerland, 2017. Available online: https://www.iso.org/standard/66912.html (accessed on 1 January 2026).
- ISO 19011:2018; Guidelines for Auditing Management Systems. International Organization for Standardization: Geneva, Switzerland, 2018. Available online: https://www.iso.org/standard/70017.html (accessed on 1 January 2026).
- Moosavi, S.; Farajzadeh-Zanjani, M.; Razavi-Far, R.; Palade, V.; Saif, M. Explainable AI in manufacturing and industrial cyber-physical systems: A survey. Electronics 2024, 13, 3497. [Google Scholar] [CrossRef] [Scilit]
- Tercan, H.; Meisen, T. Machine learning and deep learning based predictive quality in manufacturing: A systematic review. J. Intell. Manuf. 2022, 33, 1879–1905. [Google Scholar] [CrossRef] [Scilit]
- Sun, Y.; Zhang, Q.; Bao, J.; Lu, Y.; Liu, S. Empowering digital twins with large language models for global temporal feature learning. J. Manuf. Syst. 2024, 74, 83–99. [Google Scholar] [CrossRef] [Scilit]
- Gao, R.X.; Kruger, J.; Merklein, M.; Kitzig-Frank, H.; Vancza, J. Artificial intelligence in manufacturing: State of the art, perspectives, and future directions. CIRP Ann.-Manuf. Technol. 2024, 73, 723–749. [Google Scholar] [CrossRef] [Scilit]
- Liu, J.; Xie, G.; Wang, J.; Li, S.; Wang, C.; Zheng, F.; Jin, Y. Deep industrial image anomaly detection: A survey. Mach. Intell. Res. 2024, 21, 104–135. [Google Scholar] [CrossRef] [Scilit]
- Xu, H.; Xu, S.; Yang, W. Unsupervised industrial anomaly detection with diffusion models. J. Vis. Commun. Image Represent. 2023, 97, 103983. [Google Scholar] [CrossRef] [Scilit]
- Wan, Y.; Chen, Z.; Liu, Y.; Chen, C.; Packianather, M. Empowering LLMs by hybrid retrieval-augmented generation for domain-centric Q&A in smart manufacturing. Adv. Eng. Inform. 2025, 65, 103212. [Google Scholar] [CrossRef] [Scilit]
- Jans, M.; Alles, M.G.; Vasarhelyi, M.A. A field study on the use of process mining of event logs as an analytical procedure in auditing. Account. Rev. 2014, 89, 1751–1773. [Google Scholar] [CrossRef] [Scilit]
- Rab, S.; Wan, M.; Sharma, R.K.; Kumar, L.; Zafer, A.; Saeed, K.; Yadav, S. Digital avatar of metrology. Mapan 2023, 38, 561–568. [Google Scholar] [CrossRef] [Scilit]
- Picard, C.; Cozot, R.; Boissieux, L.; Segovia, B. Evaluating vision-language models for engineering design (including manufacturing and inspection tasks). Artif. Intell. Rev. 2025, 58, 288. [Google Scholar] [CrossRef] [Scilit]
- Rydzi, S.; Zahradnikova, B.; Sutova, Z.; Ravas, M.; Hornacek, D.; Tanuska, P. A predictive quality inspection framework for the manufacturing process in the context of Industry 4.0. Sensors 2024, 24, 5644. [Google Scholar] [CrossRef] [Scilit]
- Nguyen, H.T.T.; Nguyen, L.P.T.; Cao, H. XEdgeAI: A human-centered industrial inspection framework with data-centric explainable edge AI approach. Inf. Fusion 2025, 116, 102782. [Google Scholar] [CrossRef] [Scilit]
- Lin, Y.Z.; Shi, Q.; Yang, Z.; Latibari, B.S.; Shao, S.; Salehi, S.; Satam, P. DDD-GenDT: Dynamic data-driven generative digital twin framework. IEEE Trans. Artif. Intell. 2025; in press. [CrossRef] [Scilit]
- Shafiee, S. Generative AI in manufacturing: A literature review of recent applications and future prospects. Procedia CIRP 2025, 132, 1–6. [Google Scholar] [CrossRef] [Scilit]
- Thomas, D. Revolutionizing failure modes and effects analysis with ChatGPT: Unleashing the power of AI language models. J. Fail. Anal. Prev. 2023, 23, 911–913. [Google Scholar] [CrossRef] [Scilit]
- Alsaif, K.M.; Albeshri, A.A.; Khemakhem, M.A.; Eassa, F.E. Multimodal large language model-based fault detection and diagnosis in context of Industry 4.0. Electronics 2024, 13, 4912. [Google Scholar] [CrossRef] [Scilit]
- Wang, T.; Zhang, B.; Jiang, D.; Li, D. A multimodal large language model framework for intelligent perception and decision-making in smart manufacturing. Sensors 2025, 25, 3072. [Google Scholar] [CrossRef] [Scilit]
- Shadid, N.; Hamad, K.; Andi, O.; Alamassi, I. Revolutionizing quality management: Exploring Quality 4.0 frameworks in the context of Industry 4.0. In Big Data in Finance: Transforming the Financial Landscape, Volume 2; Alareeni, B., Ed.; Springer: Cham, Switzerland, 2025; pp. 177–192. [Google Scholar]
- Alvaro, J.A.H.; Gonzalez Barreda, J. An advanced retrieval-augmented generation system for manufacturing quality control. Adv. Eng. Inform. 2025, 64, 103007. [Google Scholar] [CrossRef] [Scilit]
- Mata, O.; Ponce, P.; Perez, C.; Ramirez, M.; Anthony, B.; Russel, B.; Apte, P.; MacCleery, B.; Molina, A. Digital twin designs with generative AI: Crafting a comprehensive framework for manufacturing systems. J. Intell. Manuf. 2025, 37, 1049–1072. [Google Scholar] [CrossRef] [Scilit]
- Rudin, C. Stop explaining black box machine learning models for high stakes decisions and use interpretable models instead. Nat. Mach. Intell. 2019, 1, 206–215. [Google Scholar] [CrossRef] [Scilit] [PubMed]
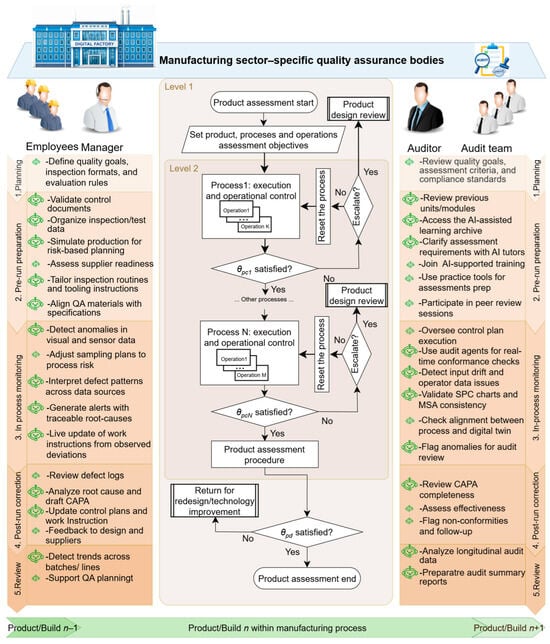
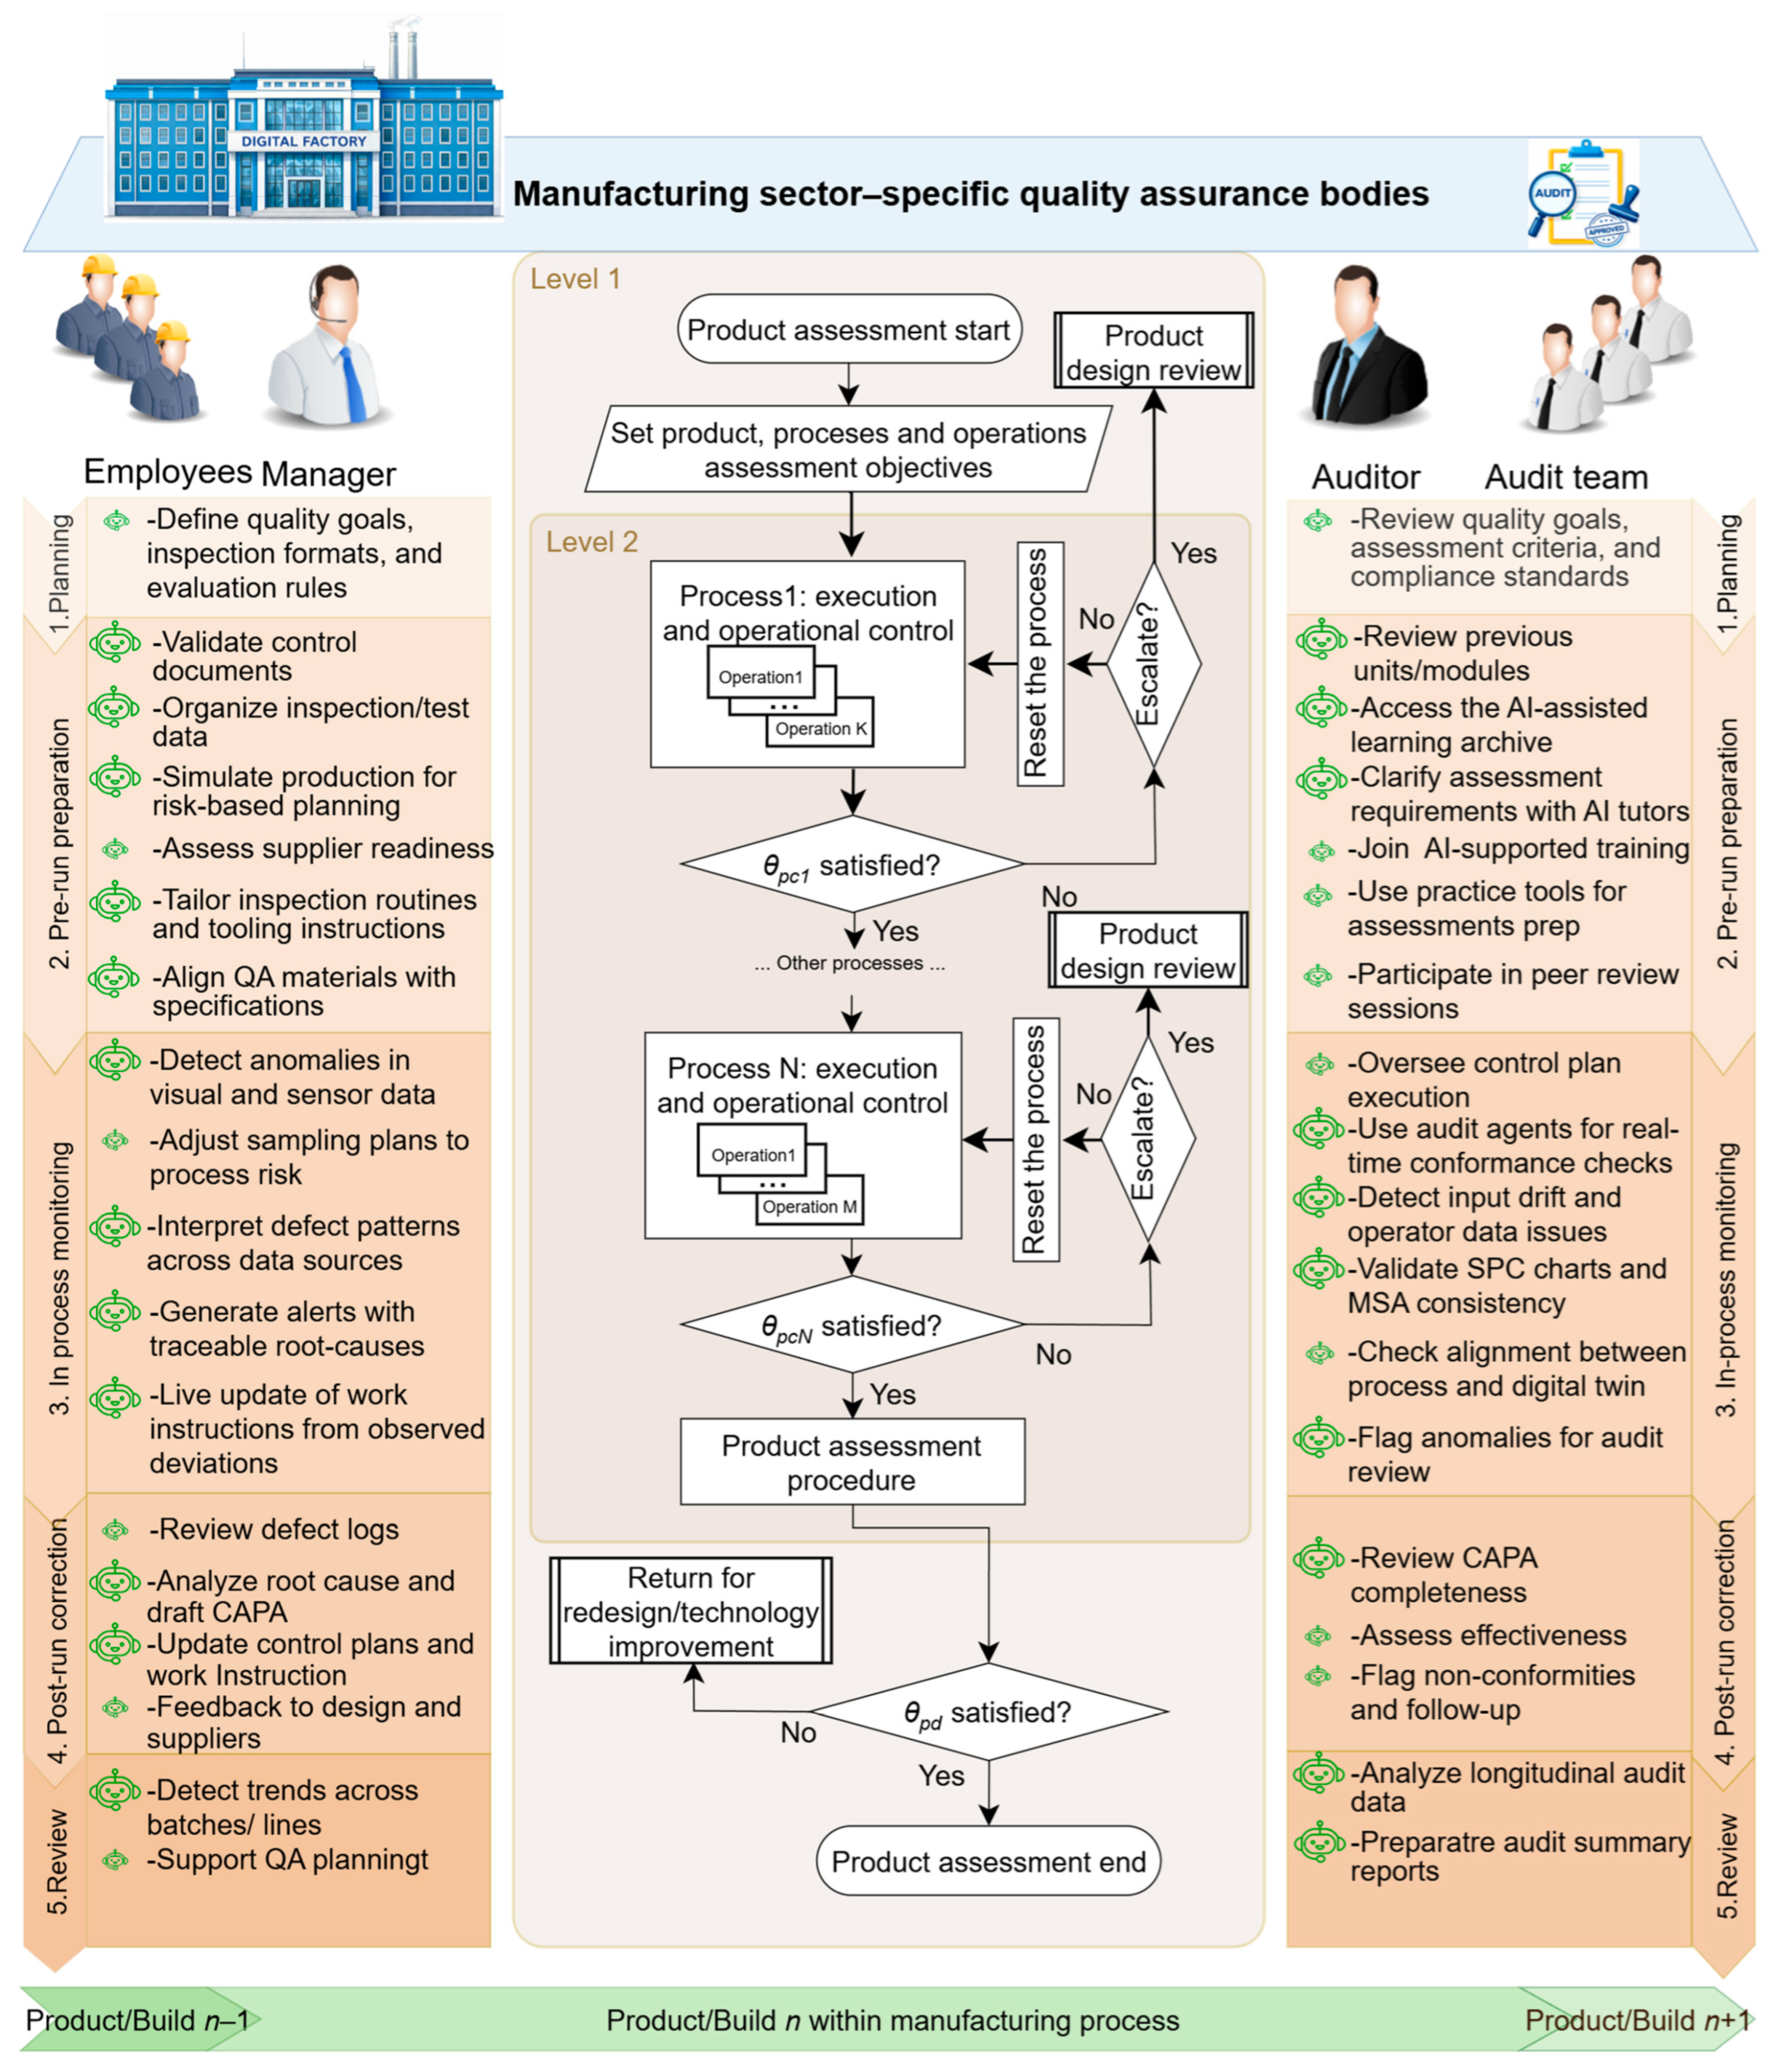
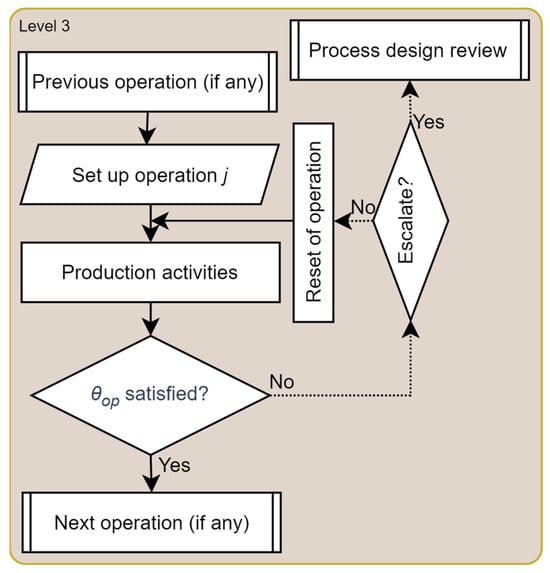
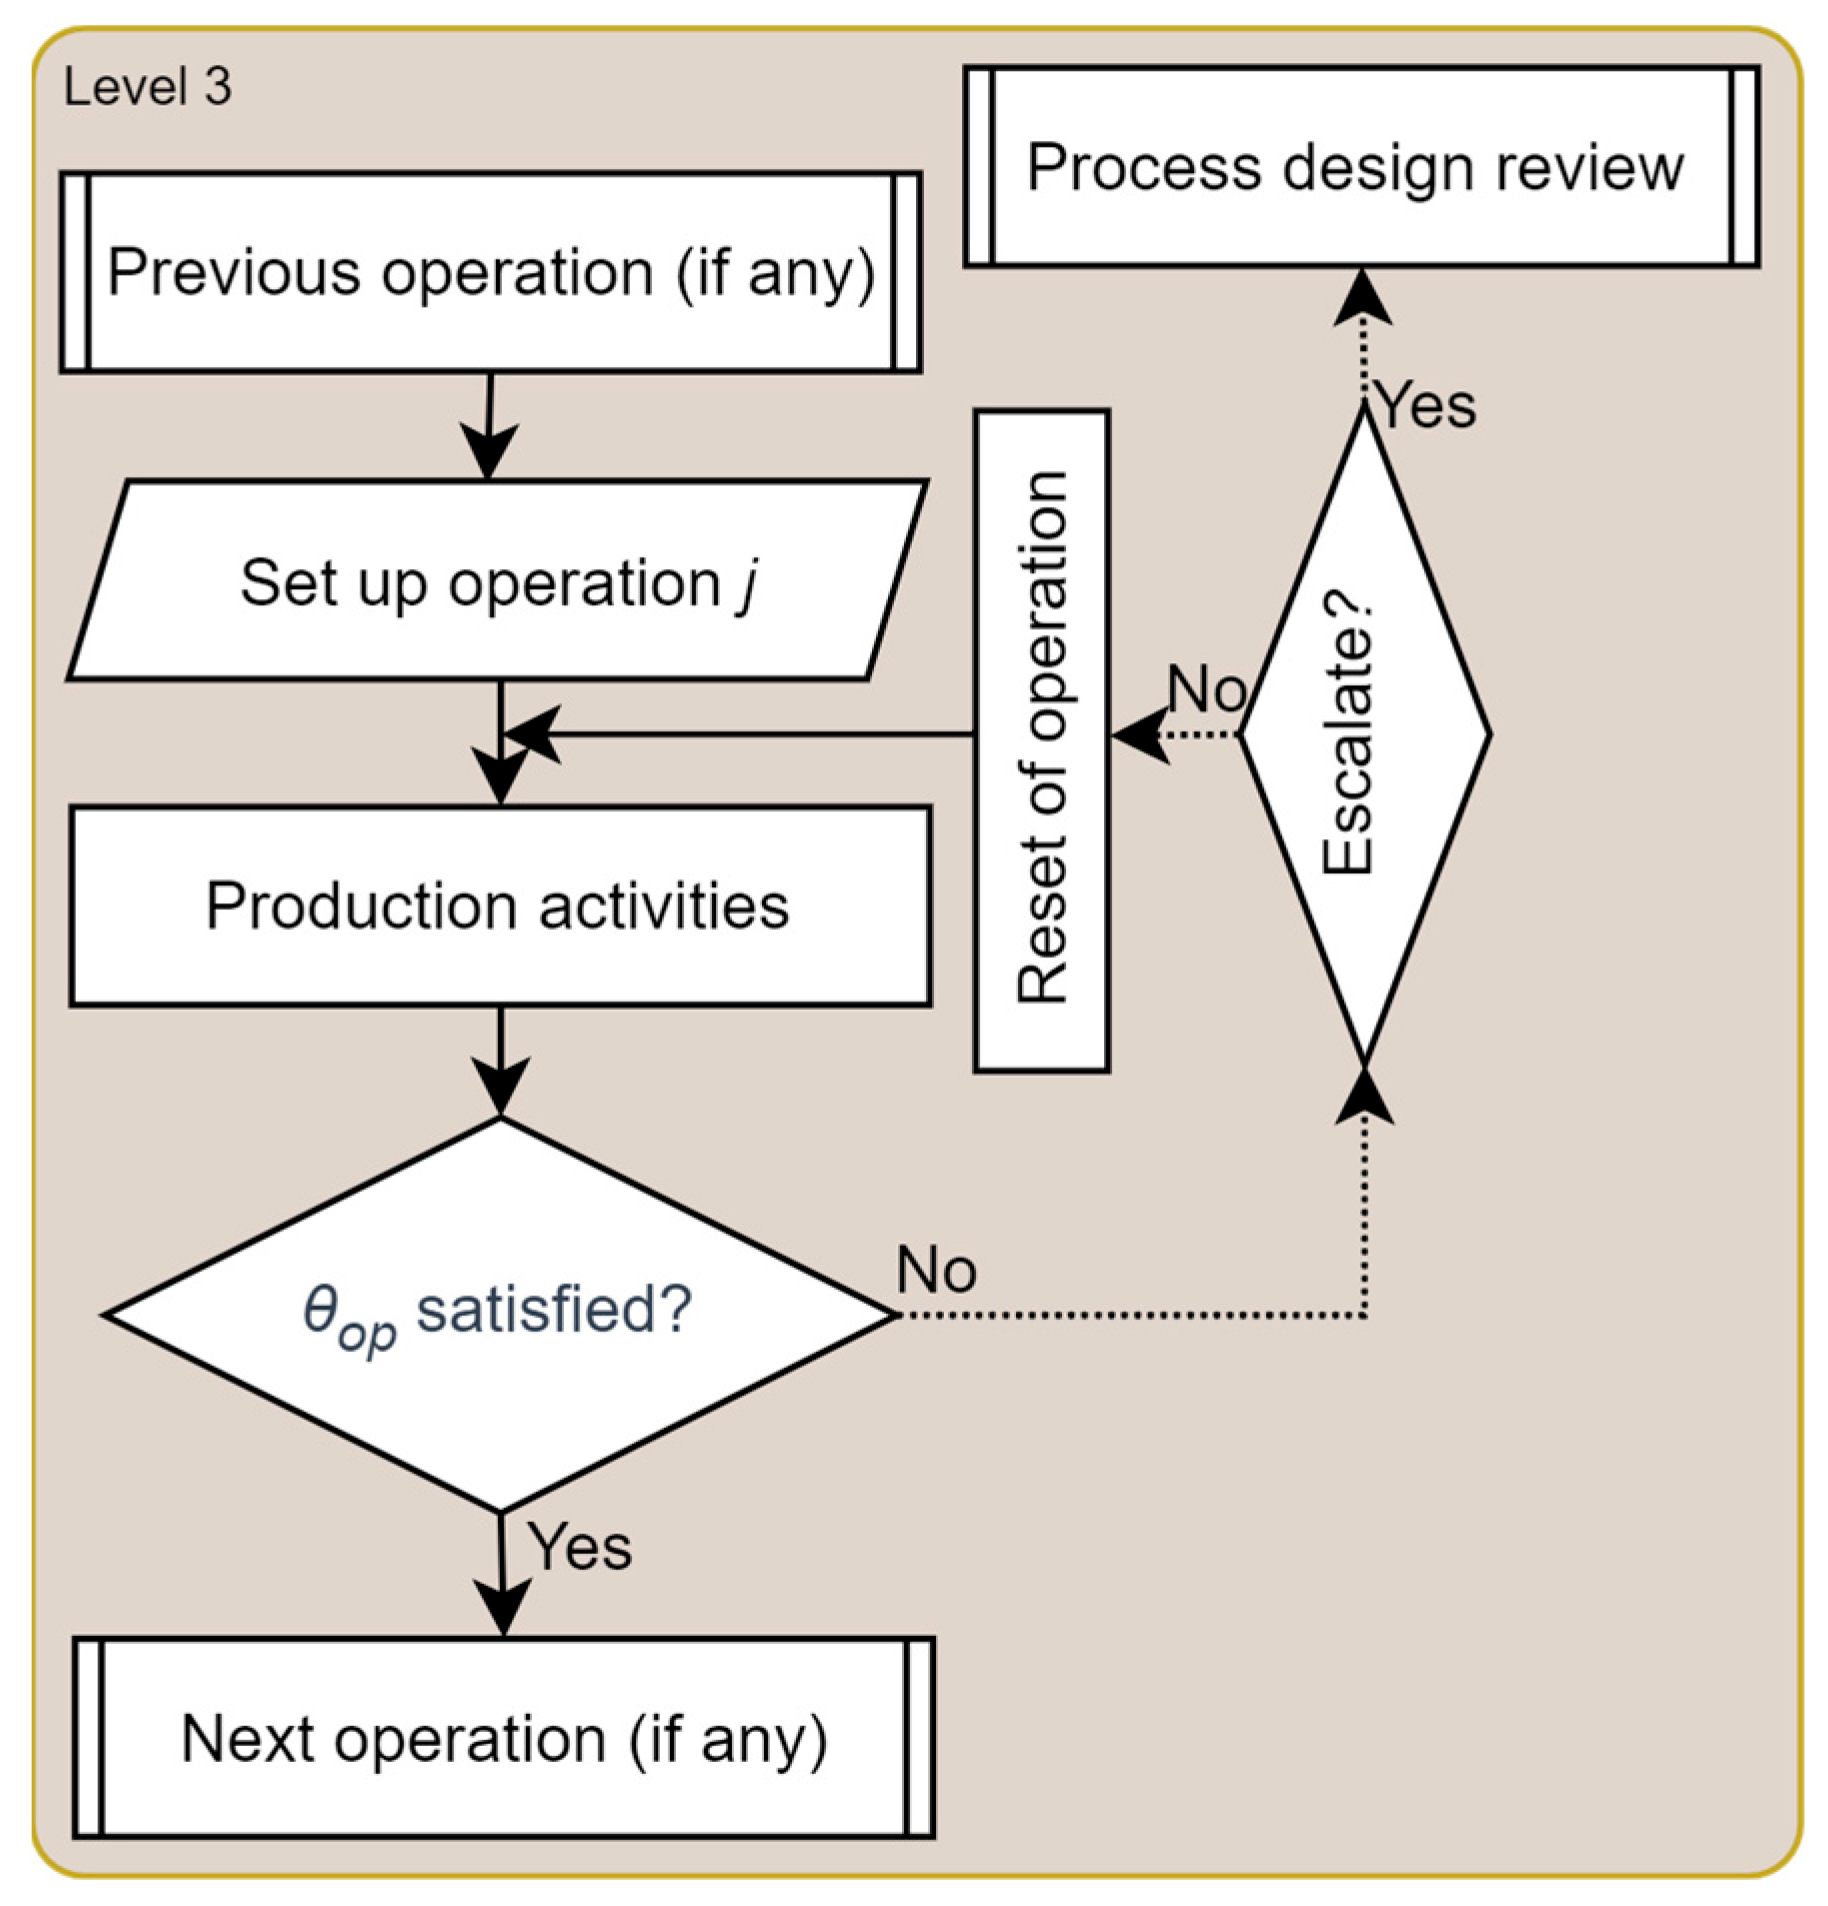

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.