


Abstract
The management of specialty coffee production represents a complex dynamical process characterized by highly nonlinear interconnections between environmental variables, agronomic practices, and chemical compositions. Traditionally, the classification of specialty coffee relies on sensory evaluations conducted by highly certified coffee experts named Q-Graders, using a strict, standardized Specialty Coffee Association (SCA) protocol. However, scientific methods that generate spectral fingerprints provide a more reliable guarantee of quality while also ensuring traceability to the farm of origin. Panamanian Geisha coffee is one of the world’s most expensive award-winning microlots, frequently exceeding 1000 American dollars per pound, with a record-breaking price of over 30,000 American dollars per kilogram in 2025. This research presents an integrated framework that combines Precision Agriculture Management Systems (PAMSs) and a traceability architecture that facilitates the collection of georeferenced coffee bean samples using a mobile application (apps), while preserving the coffee varieties and geographical origin necessary for the subsequent identification of the spectral fingerprint by chemical specialists in their laboratory. A mathematical model is introduced to formally characterize the mobile application’s behavior, distributed structure, and inherent constraints. Serving as a mathematical blueprint, this model identifies critical influencing factors and establishes strategic assumptions to distill complex real-world variables into a rigorous, manageable framework. Large-scale experiments conducted across more than 820 coffee farms in Chiriquí, Panama, demonstrate that the proposed decentralized architecture effectively coordinates the acquisition and synchronization of georeferenced chemical data. The decentralized architecture of the mobile application utilizes private blockchain technology to facilitate autonomous operations, effectively decoupling the system from central authorities to ensure functional continuity in environments characterized by intermittent connectivity.
1. Introduction
Specialty coffee refers to the highest grade of coffee available and is distinguished by its exceptional flavor complexity. It offers a refined sensory experience, often featuring distinct notes of citrus, berry, chocolate, and caramel. In addition to its unique flavor profiles and consistency, this coffee must have a score of 80 points or higher on the Specialty Coffee Association (SCA) scale [1], indicating a superior quality. Because of its superior quality and traceable origins, specialty coffee consistently fetches a higher value than standard commodity beans.
The distinctive flavor of specialty coffee is generally found in the Arabica species (Coffea arabica). This variety is highly regarded for its organoleptic characteristics, which include a fragrant and complex aroma with flavors that can be sweet, fruity, caramel, or chocolate [2] among others. It also has the potential to possess pleasant acidity and a silky, balanced body. The Arabica species is the most productive at elevations above 1000 m (m.a.s.l.), requiring a temperate climate with an annual mean of 17 °C to 21 °C for optimal development [3]. The quality of the coffee is associated with the altitude, as ref. [4] shows how the quality exhibited in the cup by these coffees exceeds 88 points.
In recent years, Panama has stood out for the specialty coffee it produces, with the Geisha variety being the most awarded [5] in the world, consistently setting new standards for excellence. However, other varieties are grown in the country that obtain high scores on the SCA scale and are categorized as specialty coffees. Of these, over 60% of the coffee grown is Arabica. The main Arabica coffee plantations are located in the province of Chiriquí, especially in highland areas such as Boquete, Tierras Altas, and Renacimiento that border Costa Rica. These areas have the ideal altitude, climate, and soil for growing Arabica coffee plants. Growers in these areas lack the spectral fingerprint of the coffee they produce [6]. Moreover, as a food product that is highly susceptible to adulteration, coffee therefore requires scientific methodologies to authenticate its quality. Such measures are essential to prevent fraudulent practices and guarantee both the geographic origin and variety of the beans. Furthermore, they have little recorded information on the coffee varieties being cultivated, which prevents them from conducting traceability studies [7,8,9]. According to ISO 22005:2007 [10], traceability is defined as “the ability to trace the history, application, or location of what is being considered”; however, to strengthen traceability, the blockchain is used because it offers security, full transparency, and efficiency together with traceability. ISO 23635:2022 [11] defines the blockchain as a distributed database for immutable shared records that are secured by cryptography, which is a natural way to strengthen the system.
Records are mostly kept manually without the use of Information and Communication Technologies (ICTs) or Geographic Information Systems (GIS) [12]. This prevents growers from maintaining the quality of the coffee produced and from making quick, assertive decisions regarding improvements in the coffee quality that would allow them to maximize profits at the time of sale, make data-driven decisions [13,14,15], and even use smart technologies to improve farm management [16,17,18,19].
The use of automated systems via the proposed apps provides multiple benefits to producers in the region [20,21,22]. Good information management can improve agricultural productivity [23] and allow studies related to the coffee produced by each farm [24,25,26], encouraging sustainable practices [27] and the adoption of smart practices on farms [28,29].
Panamanian Geisha coffee is one of the world’s most expensive award-winning microlots, frequently exceeding $1000 per pound with a record-breaking price of over 30,000 American dollars per kilogram in 2025. The warranty of the coffee quality generally falls into two categories: product satisfaction and the coffee bean themselves.
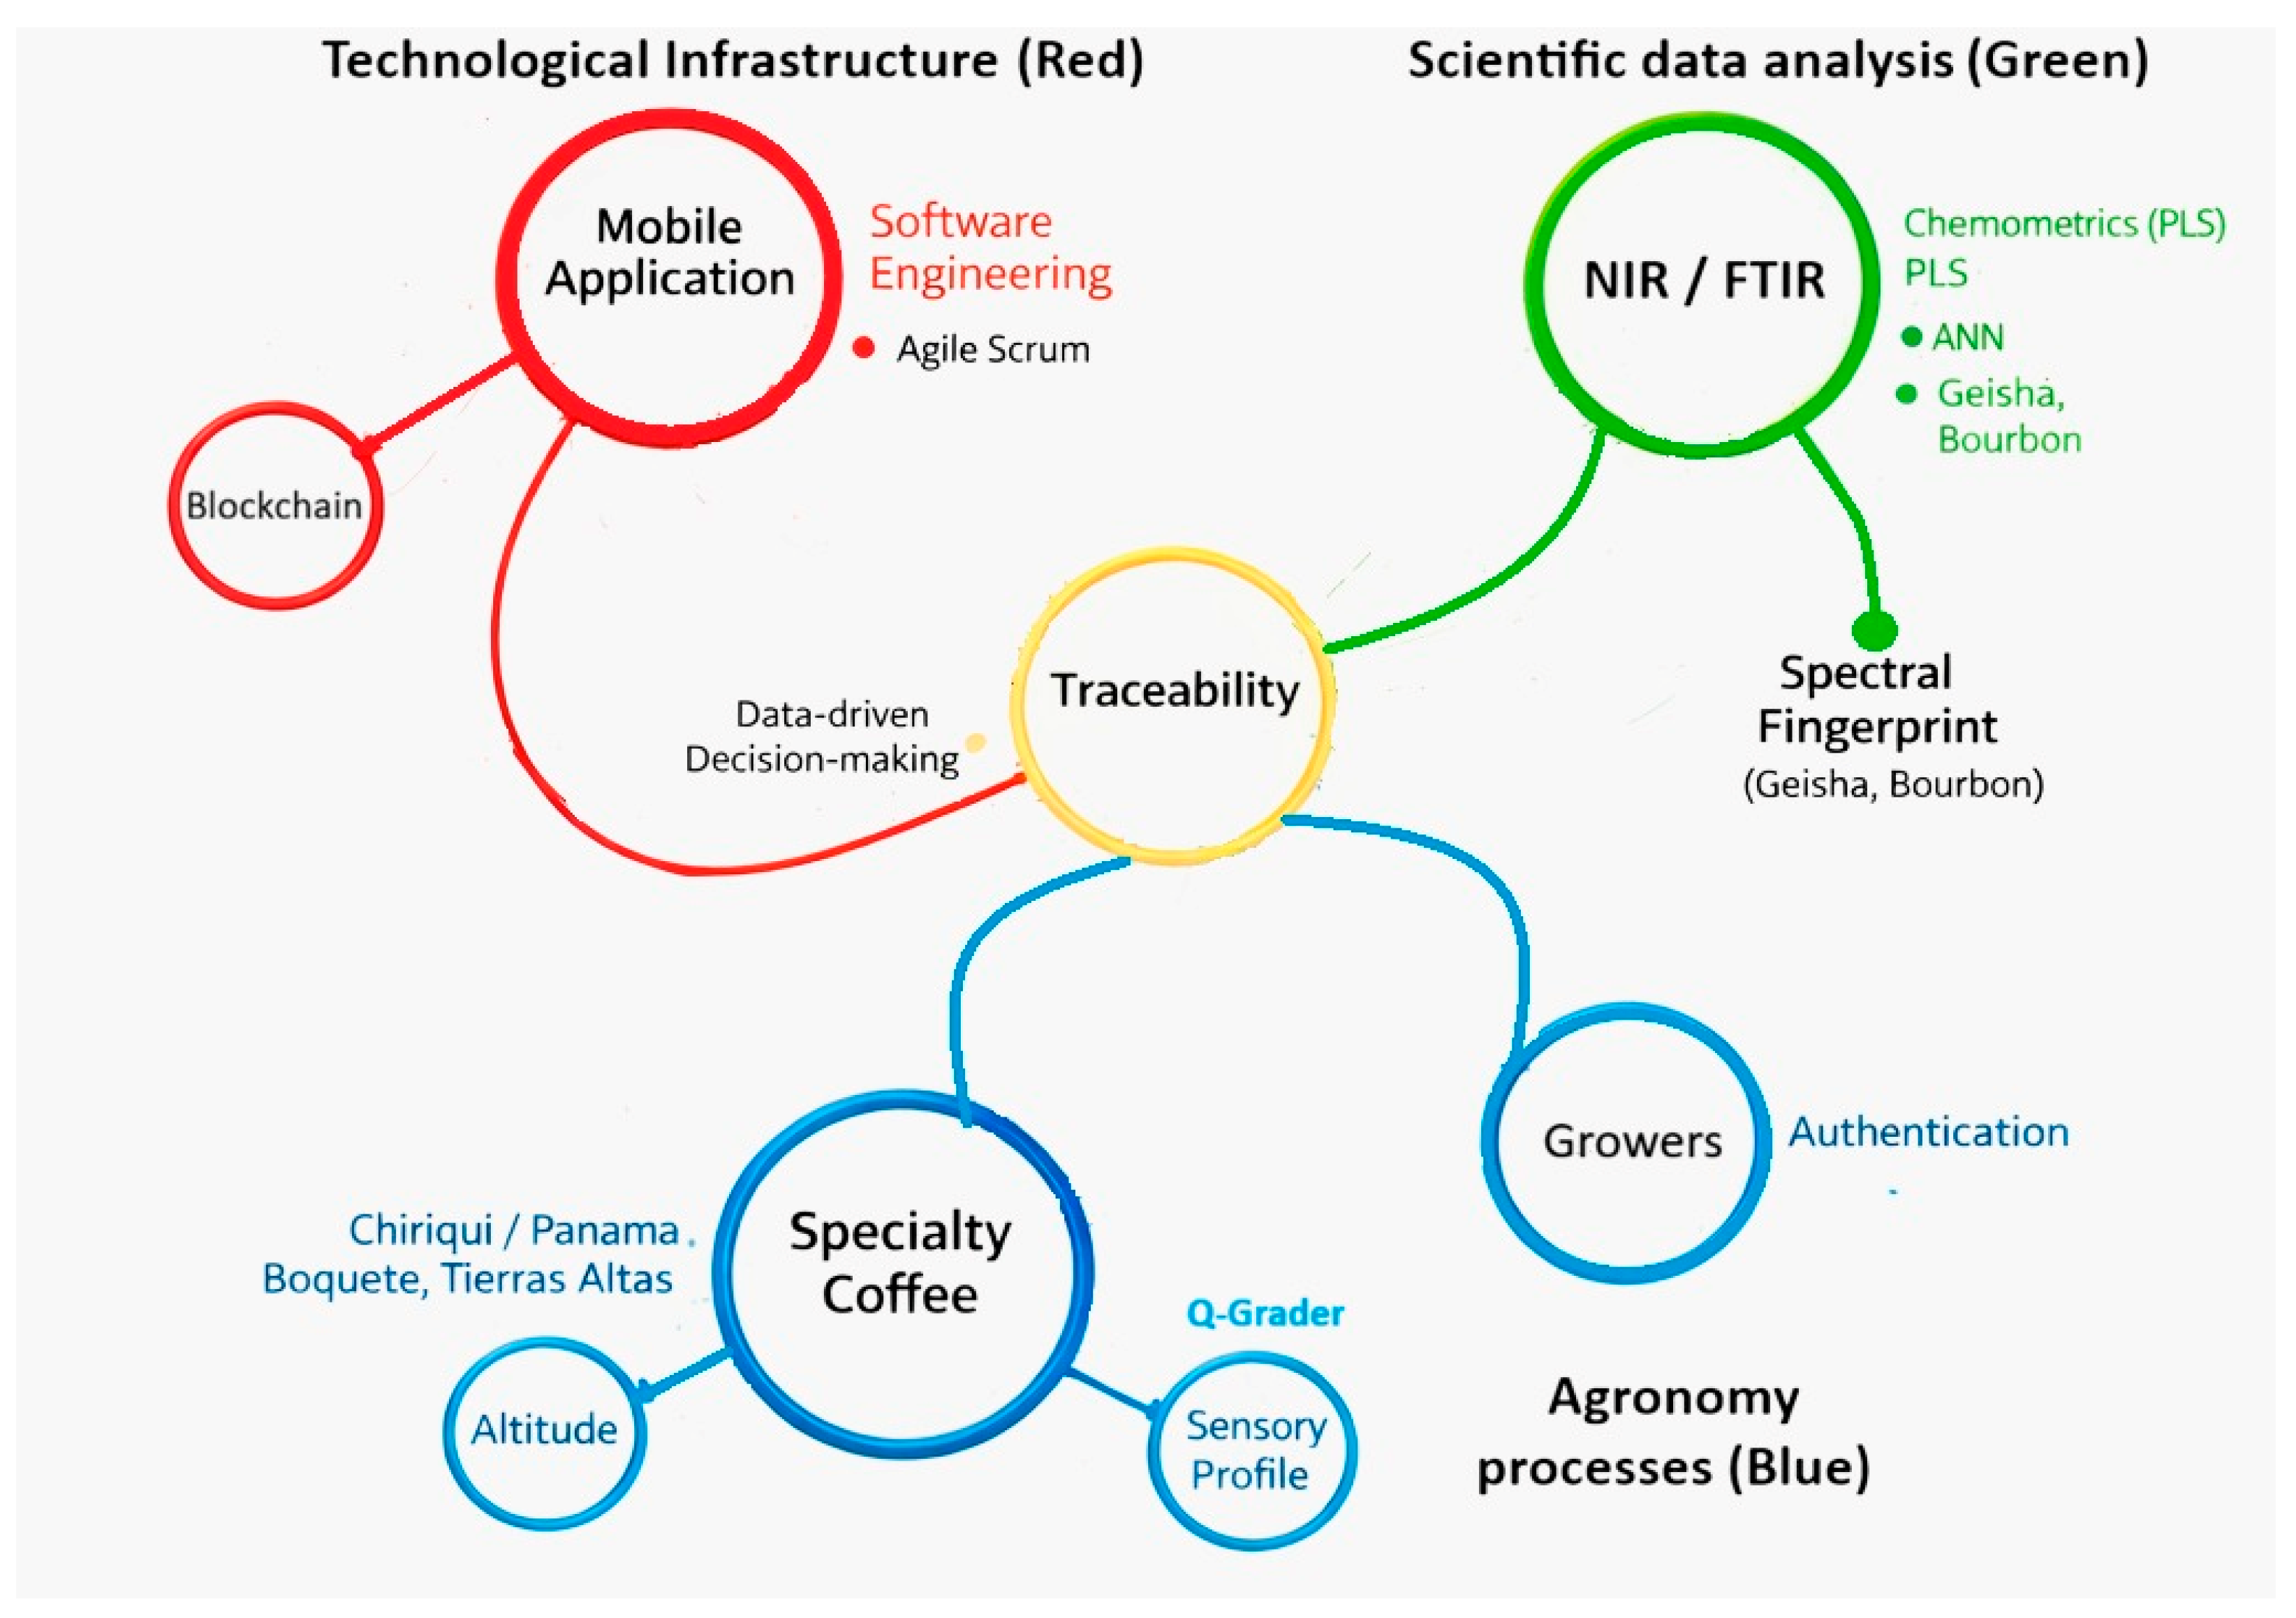
However, only scientific methods could certify the chemometric of the coffee to ensure that the lots belong to a specific region [30]. To achieve this objective, it is necessary to integrate agronomic processes, technological infrastructure, and scientific data analysis, as illustrated in Figure 1. Utilizing a mobile support system via a dedicated app streamlines spectroscopic analysis for specialty coffee farms. By implementing traceability from the farm source to the laboratory, this system accelerates the evaluation process and helps growers working in complex geography and diverse climatic conditions.
Figure 1.
Areas, technologies, and actors related to the study.
Traceability underpins the entire workflow, integrating it into a Precision Agriculture Management System (PAMS) by automatically recording the geospatial data associated with all photographic and video documentation using a cellphone. Data registered through the application are linked to grower-provided samples via a unique identification code. This information is synced to a centralized system to eliminate redundancy and provide robust support for the decision-making process
This research presents an integrated framework that combines Precision Agriculture Management Systems (PAMSs) and a traceability architecture that allows producers to send georeferenced 500 g samples of coffee beans to the chemistry laboratory for subsequent spectral fingerprint identification. Information on the geographic origin and coffee varieties is obtained using a mobile application, which is necessary to establish a unique coffee fingerprint and prevent coffee adulteration.
2. Materials and Methods
2.1. Farm Locations
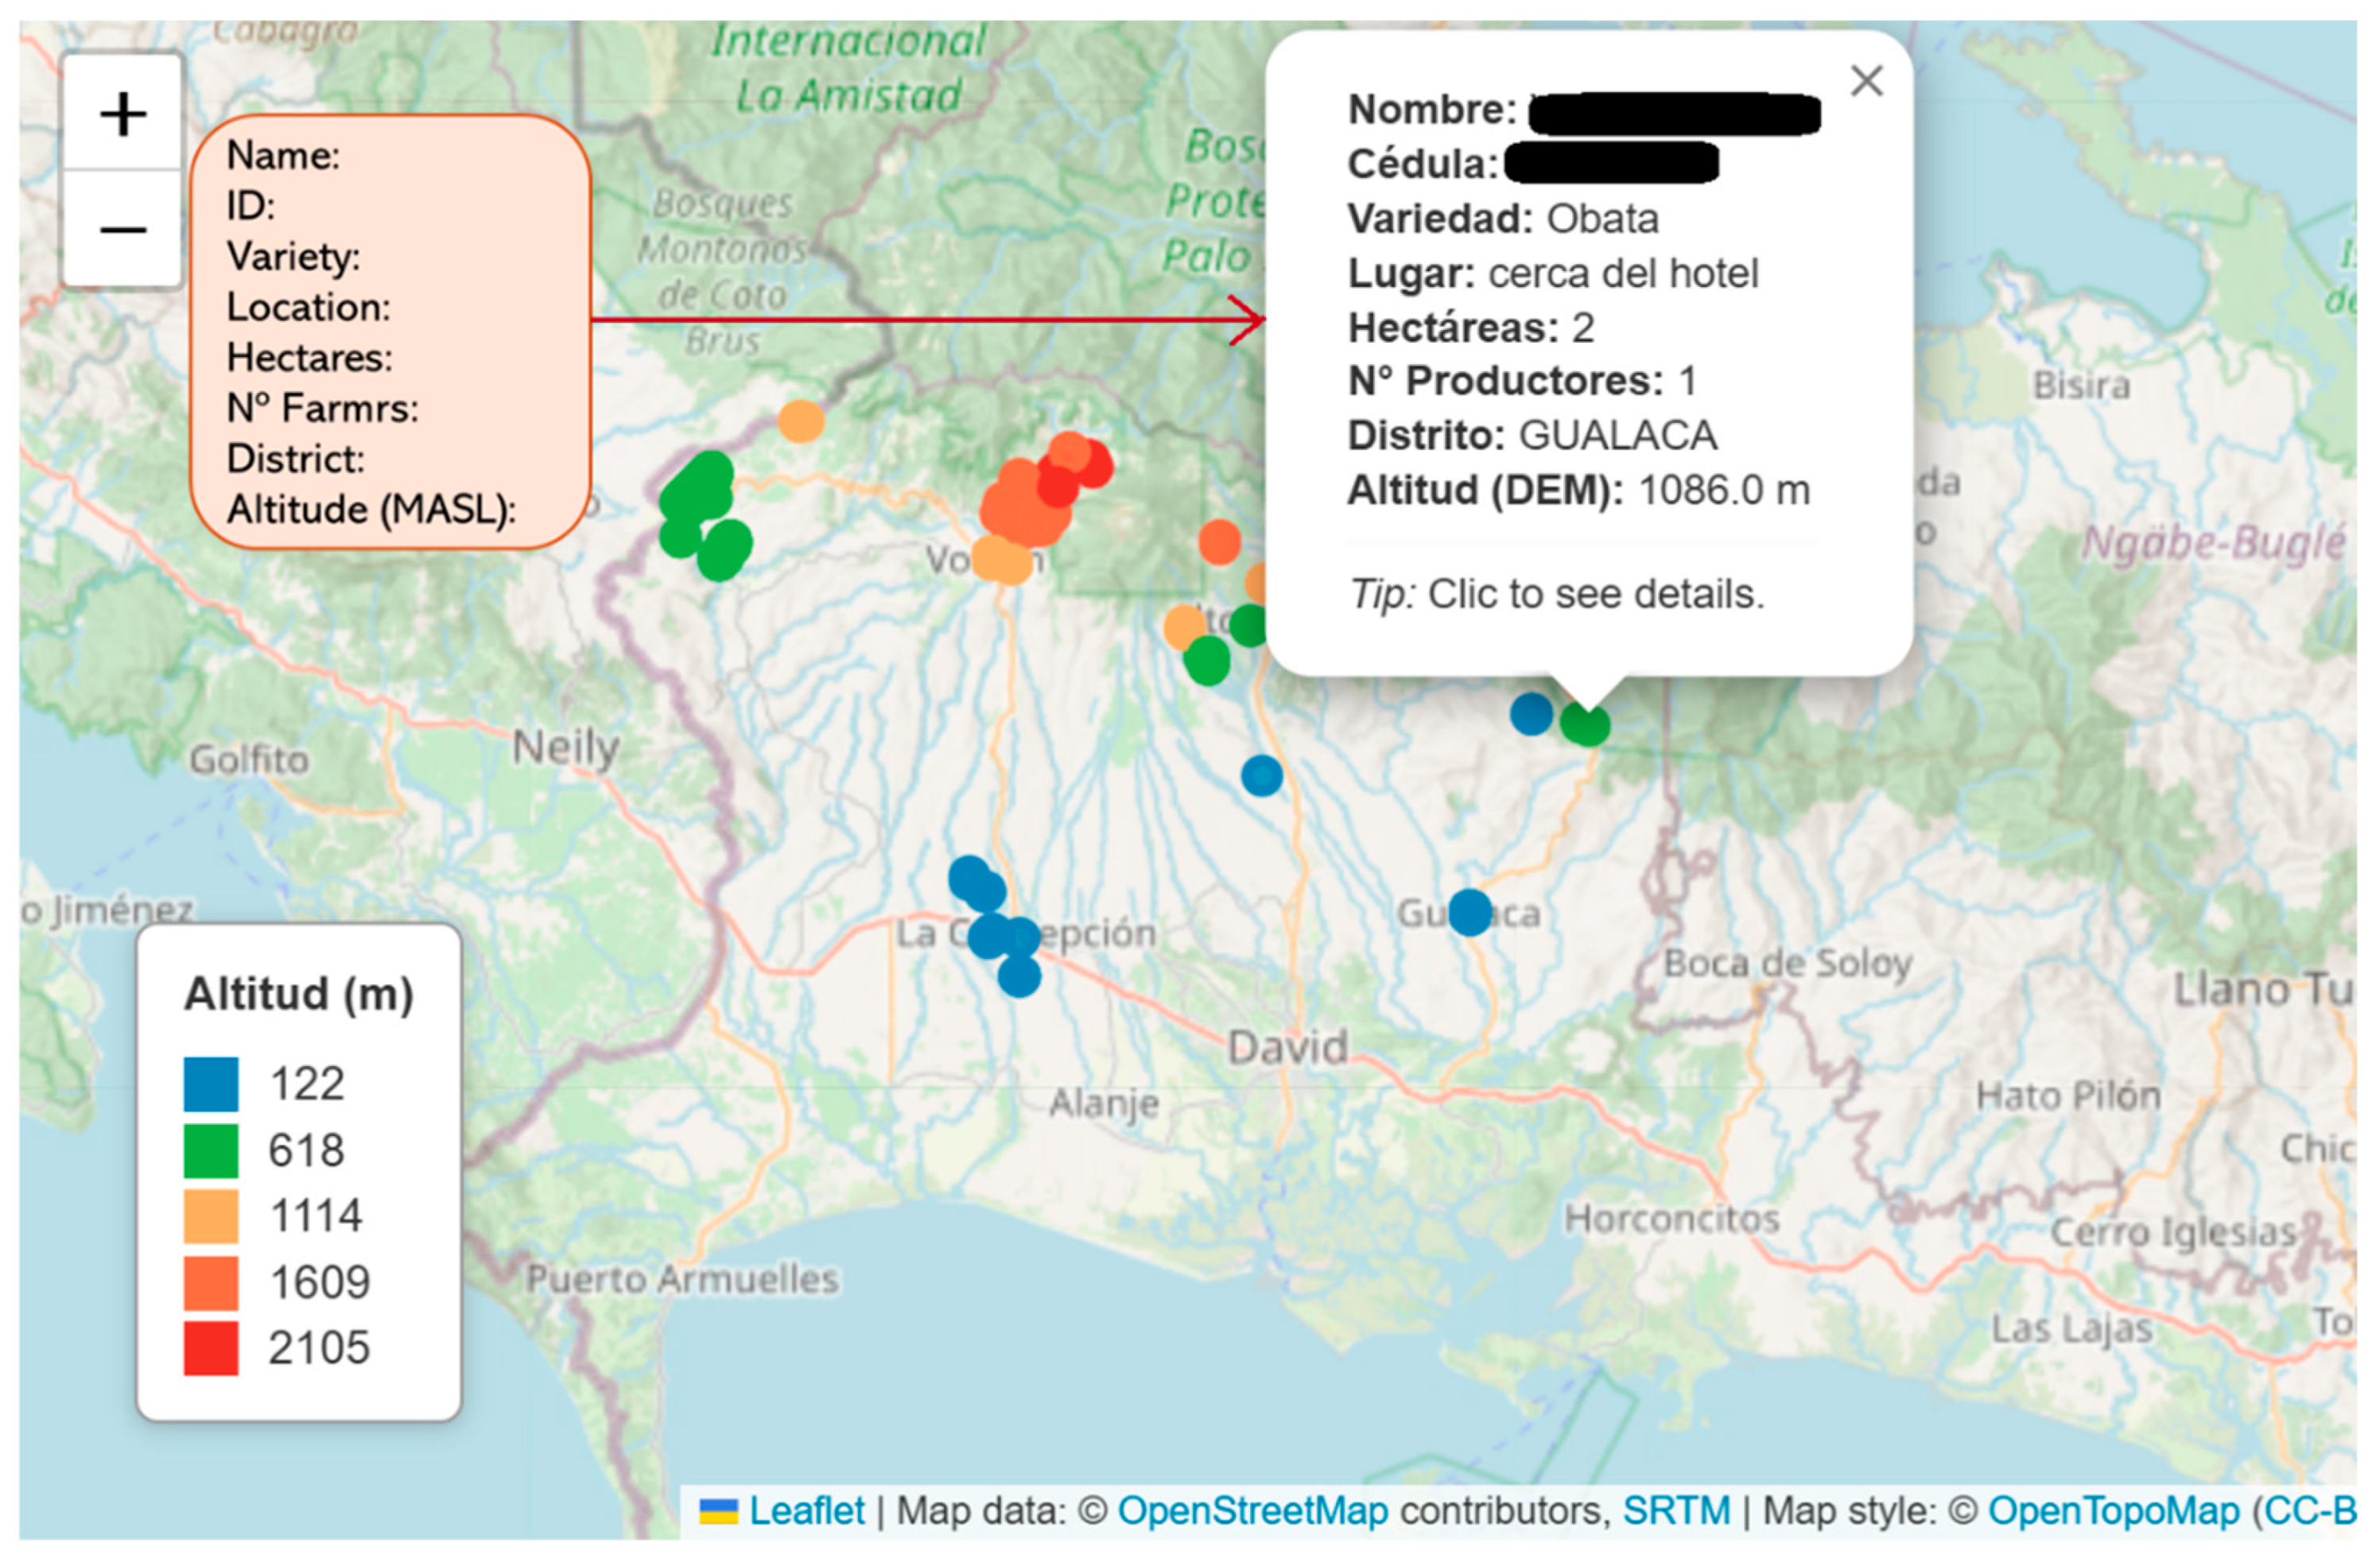
The study area, illustrated in Figure 2, identifies over 820 coffee farms within the Chiriquí province. Currently, the number of producers using the application to collect their coffee bean samples is increasing, which demonstrates the trust placed in us by the coffee sector. It highlights that there are registered farms with Arabica coffee located at altitudes below 1000 m. Although these coffees do not achieve specialty coffee scores, the producers are interested in obtaining the spectral fingerprint of their coffee to conduct future analyses that will allow them to improve product quality and origin certification.
Figure 2.
Topographic map of the coffee producers in the province of Chiriquí.
The coffee farms under study are in Boquete, Tierras Altas, and Renacimiento within the province of Chiriquí. These farms are situated at altitudes ranging from 1300 to 2300 m above sea level with temperatures ranging from 10 °C to 21 °C. The mountainous terrain of these regions provides the ideal elevation and perfect conditions for growing Arabica coffee. This map highlights the geographic distribution of over 820 coffee farms where each data point represents a specific farm and is color-coded by an altitude legend ranging from 122 m (blue) to over 2100 m (red).
This spatial data is a core component of the application, as it provides traceability by linking the spectral fingerprint of the coffee to its exact coordinates and elevation. Additionally, the interactive interface allows for detailed data management, as shown in the pop-up for the grower. This digital map includes georeferenced critical agronomic information such as the coffee species, the scale of the farm in hectares, and topography (altitude in m.a.s.l.). By centralizing this information into a cloud, the system eliminates duplicate records and provides the scientific data necessary to support informed decision-making across the region. As Spanish is the official language of Panama, both the regional map and the application interface are provided in Spanish.
This region has volcanic soil which is rich in nutrients and very fertile, and the climate is also conducive to coffee cultivation [31]; these characteristics allow for the harvesting of high-quality varieties. Each region is distinguished by its unique coffee profile, where the microclimates on farms can vary considerably depending on factors such as altitude, rainfall, and humidity, among others.
It is estimated that the highest quality specialty coffees, with a score above 90, have been grown between 1600 and 1900 m above sea level with an average temperature between 16 °C and 18 °C. The mainly volcanic heritage of the Barú Volcano creates a nutrient-rich terroir, providing the essential conditions for the Geisha variety to reach its peak quality and expression. Table 1 presents the altitude and temperature range of the specialty coffee for each region.
Table 1.
Specialty coffee altitudes and temperatures by region.
2.2. Explanation of the Workflow
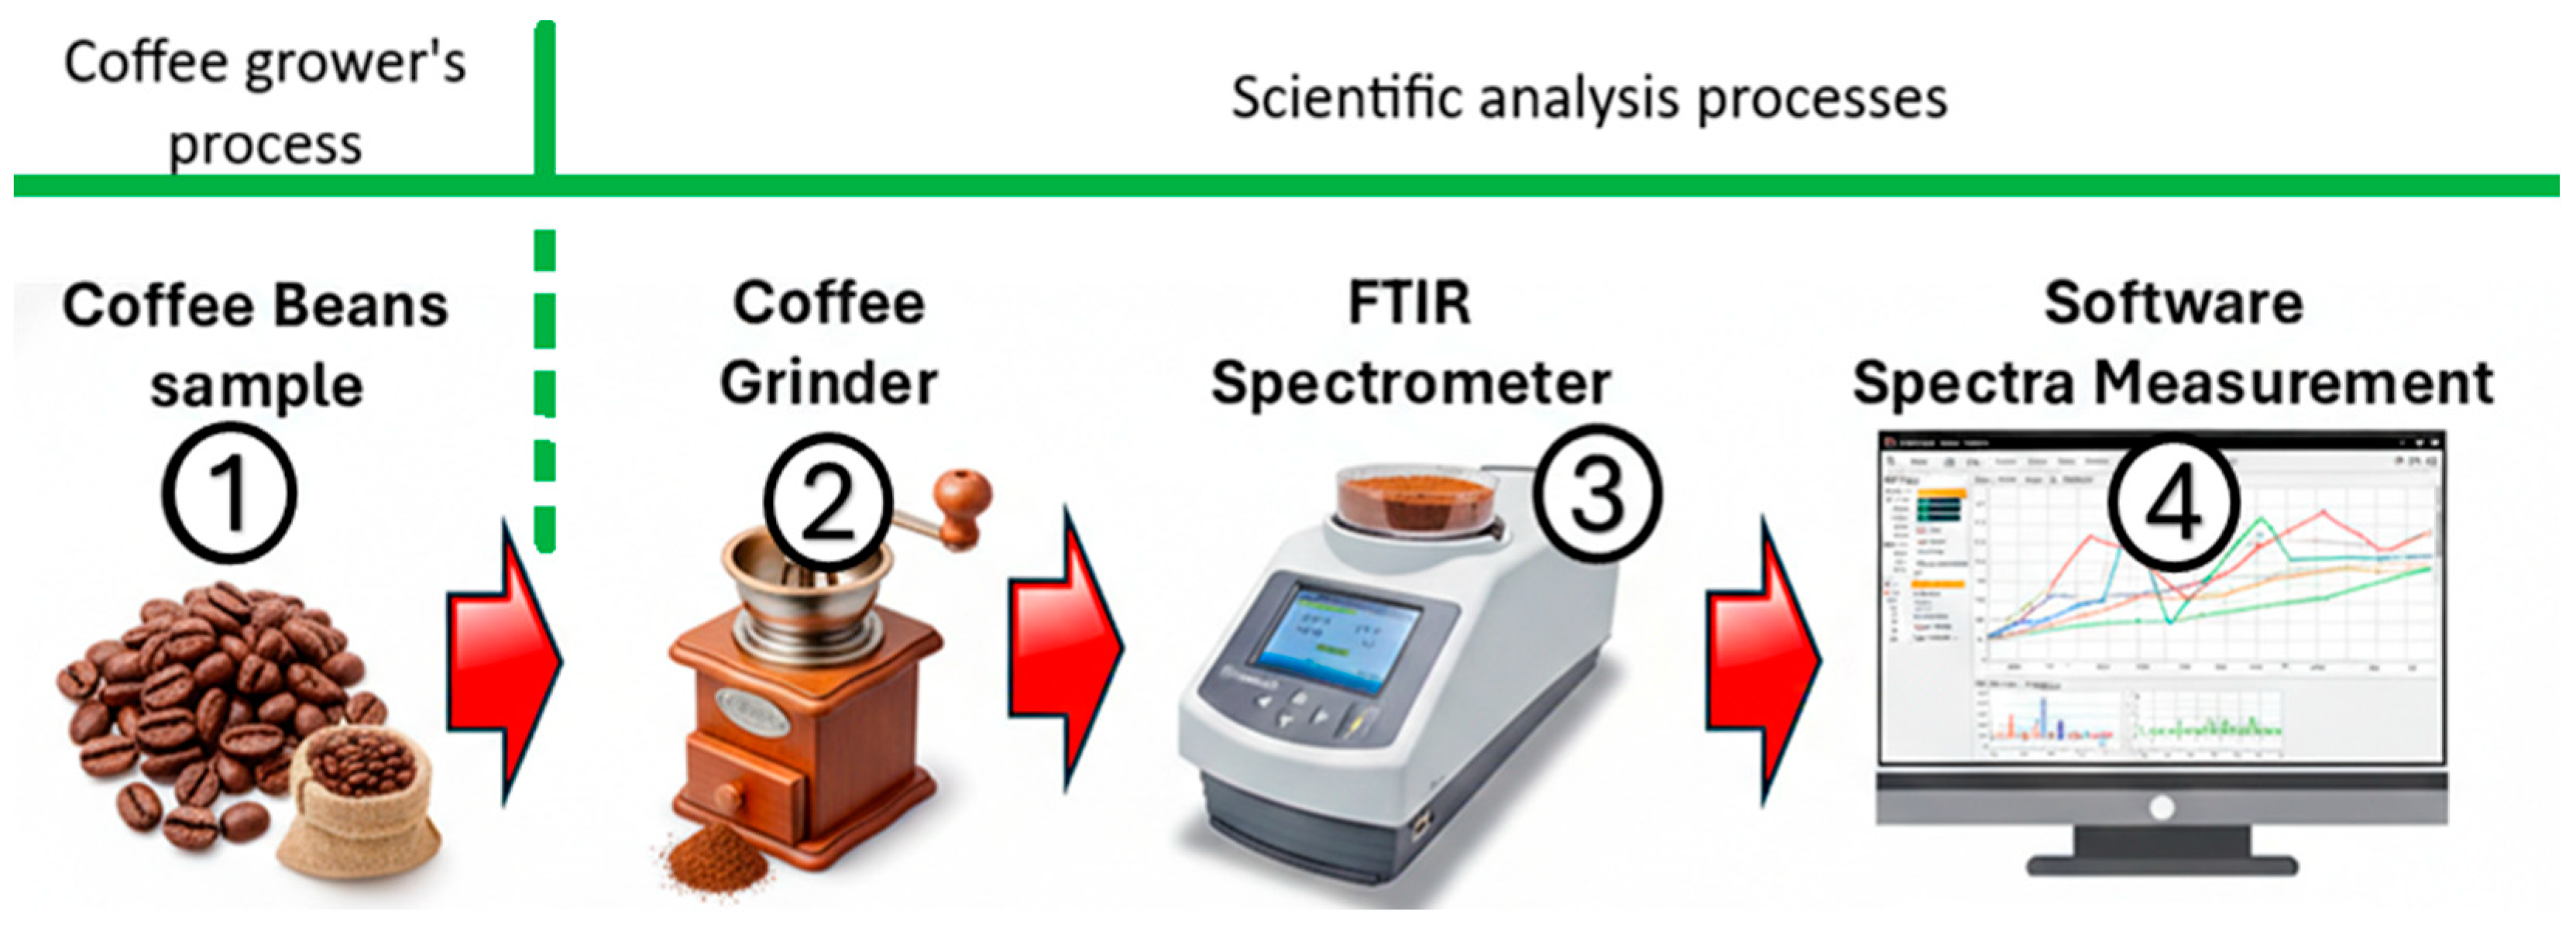
The collection of physical samples and the capture of georeferenced evidence through the apps by coffee producers constitute the foundational step (1) of the workflow. Subsequently, chemical specialists analyze these samples to determine their chemical composition using near-infrared spectroscopy (NIR) or Fourier Transform Infrared Spectroscopy (FTIR). These techniques are well established as reliable, objective, reproducible, verifiable, cost-effective, and environmentally sustainable analytical methods [32]. They enable effective discrimination among different coffee varieties and geographical origins, while also facilitating the detection of potential adulterants.
As illustrated in Figure 3, the overall workflow is structured into two primary phases: coffee grower processes and scientific analysis processes. During the initial phase (1), coffee growers use a mobile application to capture georeferenced photographs and videos directly at the production site. This information is transmitted to a centralized cloud server and secured using a unique immutable digital key. Each sample collected consists of 500 g of parchment coffee.
Figure 3.
Workflow of sample stages.
The subsequent stages are conducted in a laboratory environment by chemometricians, who apply advanced analytical methodologies to generate data-driven insights for decision-making. Grinding (2) represents a critical preparatory step, as spectroscopic measurements are highly sensitive to physical variables such as particle size distribution, compaction, and light scattering effects. The following stages (3 and 4) focus on converting raw, noise-affected spectral signals—often influenced by physical interferences—into structured, actionable analytical outputs.
It is important to emphasize that the performance, robustness, and predictive capability of NIR- and FTIR-based chemometric models for coffee analysis depend primarily on rigorous experimental design and appropriate spectral preprocessing strategies. However, detailed model development and validation procedures fall outside the scope of the present work.
2.3. Methodology Used for the Project
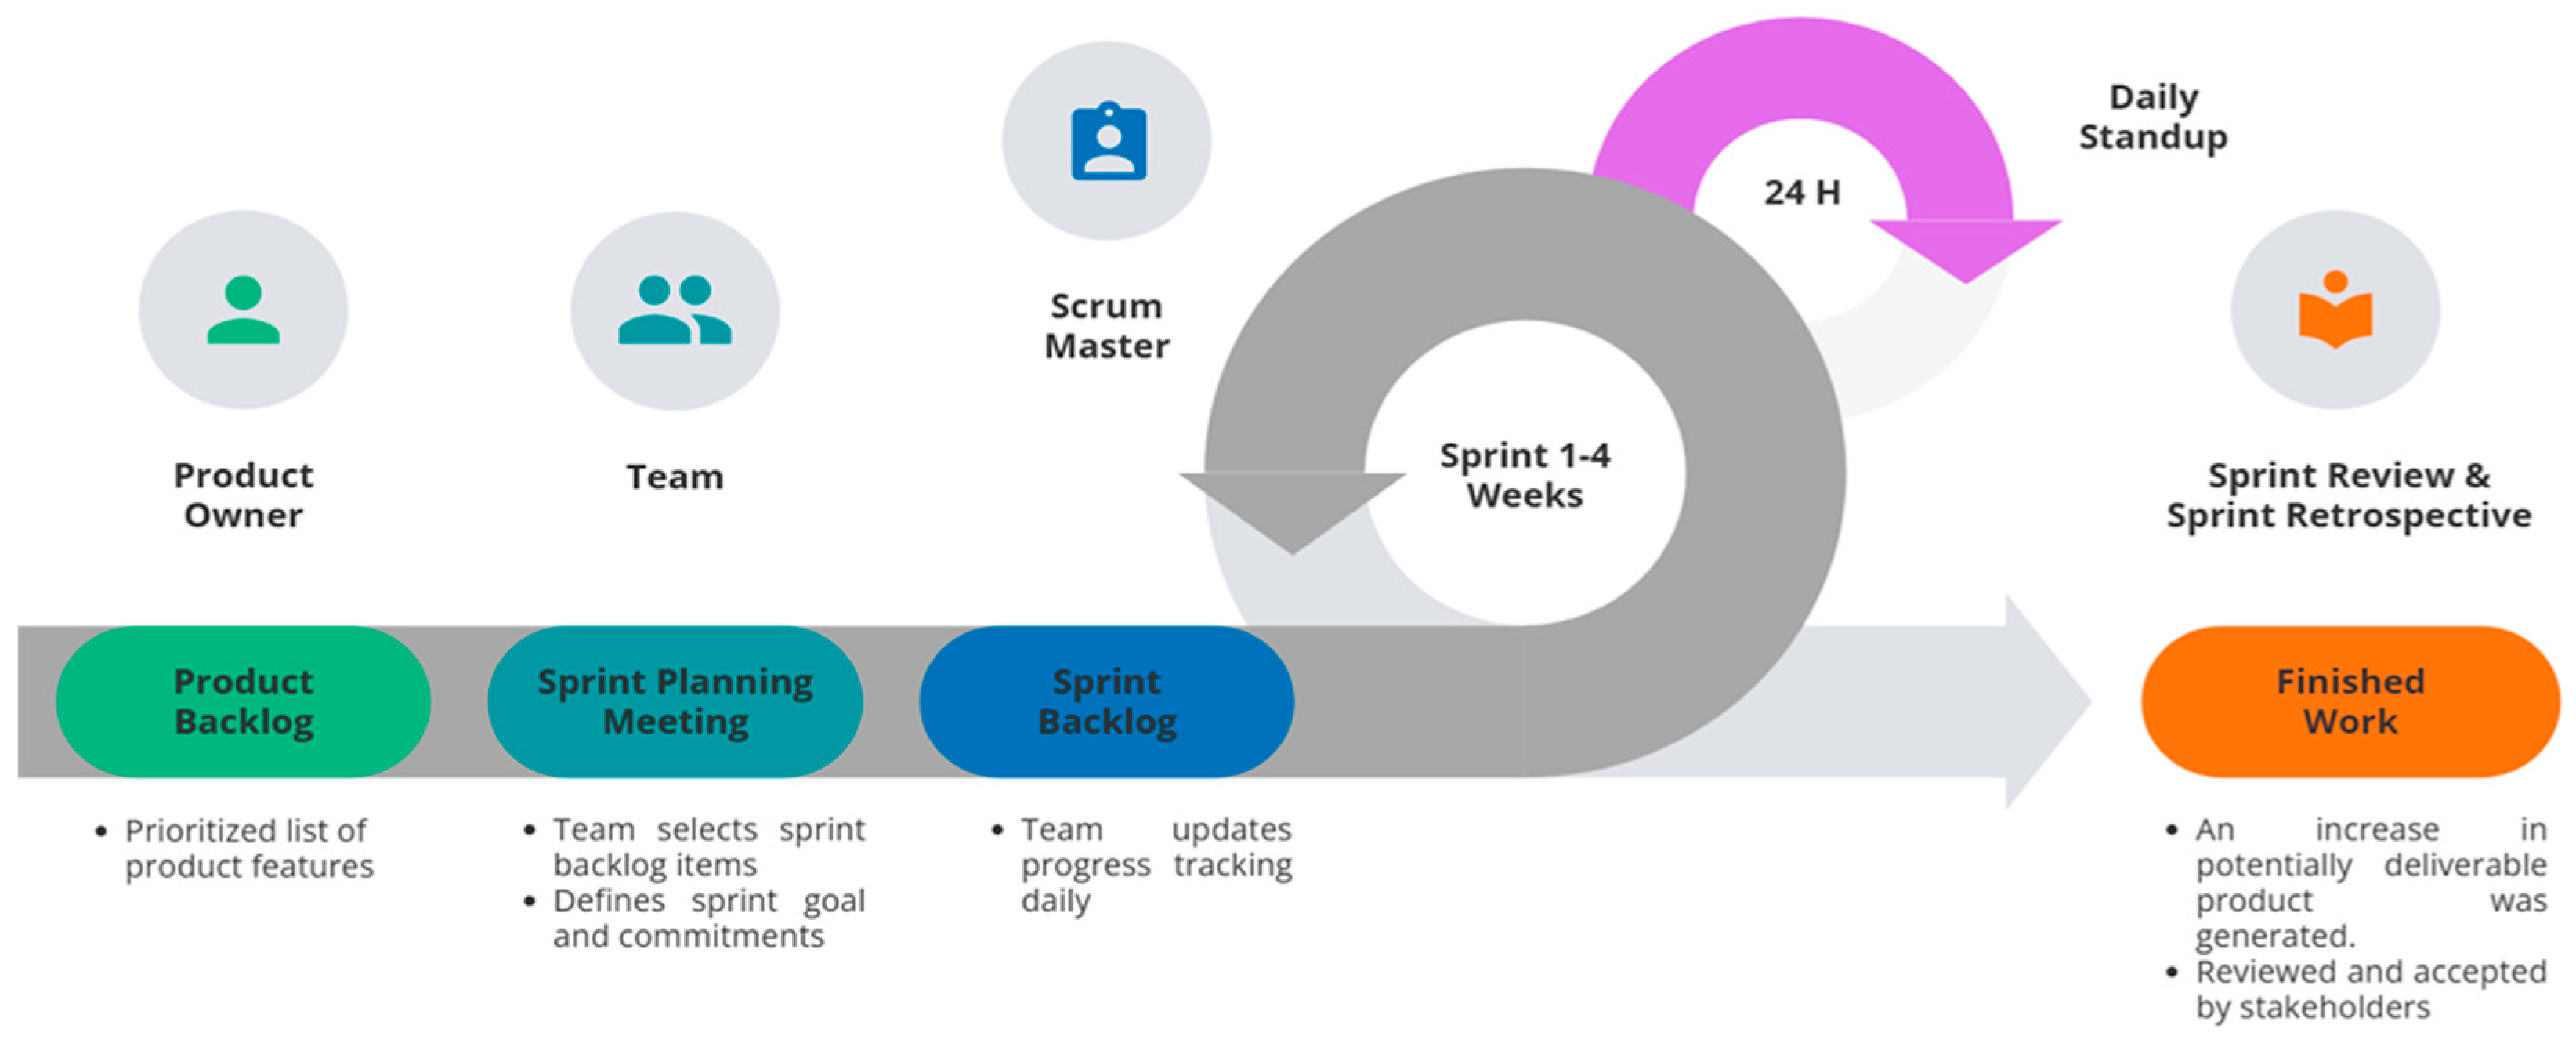
The agile scrum methodology was used during the project because it facilitates collaboration among highly competitive teams and results in high-impact work [33,34,35]; furthermore, it incorporates best practices. It is recommended for use in projects with complex and innovative environments, such as the one that will be carried out with specialty coffee.
The process is divided into three logical phases that occur within each work cycle:
- Planning and Estimation: This stage involves identifying requirements, establishing project objectives, and creating the product backlog.
- Product Backlog: This constitutes the master list of all the project’s features, fixes, and requirements, such as blockchain integration or a QR code scanning module. The producers are responsible for managing this.
- Implementation: The team begins developing the project in sprints, or development cycles, that last two to four weeks. Each sprint starts with a daily scrum meeting to review task progress and adjust the work plan as needed. During each sprint, the team focuses on developing the most important features in the backlog. The result of this phase is the Sprint Backlog.
- Review and Retrospective: Results are evaluated at the end of each sprint. A sprint review is conducted in which the working software is presented to the team for direct feedback. This feedback is used to adjust the product backlog and plan the next sprint. A sprint retrospective is also held in which the team meets privately to analyze their process and identify areas for improvement for the next sprint.
The scrum methodology begins with sprint planning and the development of the product backlog. The project lifecycle concludes with the final delivery sprint. The complete final product, fulfilling the functionalities and requirements defined at the project’s outset, is then delivered. Figure 4 illustrates the process of the scrum methodology.
Figure 4.
Scrum methodology.
2.4. Mathematical Model Representation
A model is a simplification of a complicated phenomenon with the help of mathematical terms and symbols [36], by abstracting a complex real-world application into symbols and relations. It provides several critical benefits for engineering and system design to create a real model of the real-world situation; the real-world problem should be simplified.
Therefore, the mathematical model of this app acts as a blueprint that uses the language of mathematics to define a system’s behavior, structure, and constraints. To do this, multiple assumptions can be made, and key influencing elements must be identified. System S (1) as a tuple means a set of components (states, inputs, outputs, and functions) that fully describe how the system behaves. We model the application as a labeled transition system with data and synchronization:
The system is defined as an ordered collection of components as a tuple in Equation (1); the individual components are detailed in Table 2.
Table 2.
System components presented as tuples.
This system’s entity application sets define the fundamental building blocks of the domain and provides the structural basis for all states and operations detailed in Table 3.
Table 3.
System’s entity application details.
Core functions define the derived structure and semantics over the domain entities E of the static domain universe. They are not transitions, as they are interpretive mappings that give meaning to data instead.
The location function (2) establishes the organizational structure of agricultural data. It maps each farm to its specific zone, effectively representing the spatial relationship between entities.
Provenance function (3) assigns each piece of the coffee farm or coffee process to the user who created it. Conceptually answering the questions of who recorded the data, where, and when, this function plays an important role in the system by providing traceability and accountability.
The farm evidence set function (4), denoted as , represents the complete collection of all evidence items associated with a specific farm . By utilizing the projection function , the system extracts the farm component from the provenance tuple to aggregate all relevant observations belonging to that entity
The edge–cloud architecture , represented in function (5) in this application model, is designed to manage data across two distinct layers: the local field environment and the centralized server . This dual-layer approach allows the system to remain operational in remote farm locations where connectivity might be intermittent.
Data is generated and processed locally at the edge and later consolidated in the cloud, where the use of blockchain is a very important technology to avoid modifications of the coffee samples.
Each stored object is associated with a pair of versions. Every stored object uses a version vector pairing local and cloud versions. This mechanism allows the system to tolerate temporary divergence during intermittent connectivity, ensuring data integrity by identifying deltas for synchronization.
The system’s tolerance for temporary divergence under intermittent connectivity is an important feature, because the estimated population of Panama is approximately 4.5 million to 4.58 million inhabitants as of 2025–2026; however, while 80% of urban households have internet access, this drops to around 46% in rural areas where the coffee farms are located. The global application state at time is defined formally by the function (7).
where represents the authentication and authorization states, represents the user interface state, denotes the logical database, and is the queue of pending operations or synchronization tasks. Together, these components provide a complete snapshot of the system at any moment.
Synchronization is expressed formally in function (8) as the mechanism by which divergent edge and cloud states are reconciled to ensure eventual consistency. At each time , the system identifies the divergence set, which contains all stored objects whose edge versions are more recent than their cloud counterparts.
This synchronization strategy guarantees monotonic progress, avoids data loss, and supports eventual convergence between edge and cloud replicas despite asynchronous execution and intermittent connectivity.
There exists a relationship between the core functions and synchronization, where the core functions define the semantic meaning and provenance of the data, remaining timeless and independent of synchronization. Conversely, synchronization manages the operational propagation of states across distributed components. Combined, they ensure data consistency and correctness, enabling reliable predictive insights and supporting offline operations through a clear formal separation of concerns. This separation of concerns enables scalability and system behavior over time while remaining faithful to local farm constraints such as offline operation and delayed connectivity.
The following explains how the model works when a conflict occurs in order to analyze the system’s guarantees.
Under intermittent connectivity, the edge can execute local transitions while the cloud also receives updates from other edges. A conflict occurs when two distinct updates are concurrently applied to the same logical object without a causal order. Extending the object definition:
- Let edges be indexed (set of users).
- A local edge write is produced by a transition on a specific edge , producing a new candidate value .
Conflict scenario:
Edge updates while edge updates , and the cloud receives them in some order, but they are semantically “concurrent” (neither should overwrite the other without a rule).
Conflict-resolution strategy:
Define each edge to maintain, for each object , the index of the last committed ledger event it has incorporated:
- Let be the ledger position (logical index) of the last applied event for .
- The cloud version corresponds to .
- The edge version corresponds to how many local events for have been emitted but not yet reflected in cloud.
Then:
- When edge creates a new event for : increment .
- When that event is committed and incorporated into the cloud’s materialization: increment .
- Sync pushes events from the edge to the cloud until .
Correctness proof (conflict resolution + convergence):
Based on the previous strategies, we have proved three key properties:
- Safety (Deterministic Resolution): all replicas compute the same final object state given the same committed ledger.
- Monotonicity/no lost updates: committed events are never “undone”.
- Eventual convergence: if communication eventually delivers pending events, edge and cloud states become equal.
Assumptions:
Assumptions 1 (A1). Ledger immutability and total order per channel: once an event is committed, it cannot be changed; all participants observe the same order. (Hyperledger Fabric ordering service + channel semantics.)
Assumptions 2 (A2). Eventual delivery: if an edge remains active, its queued events in Q(t) are eventually submitted and committed when connectivity permits.
Assumptions 3 (A3). Mergers are deterministic and depend only on the current state and event (as defined above).
Assumptions 4 (A4). Events are uniquely identified (no duplicates), or duplicates are detected by id and ignored (idempotence).
Lemma 1 (Deterministic materialization).
For any object and time , is uniquely determined by .
Proof.
By definition . Under A3, is a deterministic function. A fold over a totally ordered sequence with a deterministic operator yields a unique result. □
Lemma 2 (Conflict resolution is well-defined).
If two updates to the same object are concurrent, the resulting state is independent of the replica applying them (edge or cloud) because the ledger order and merge are deterministic.
Proof.
Under A1, all replicas see the same total order of committed events. By Lemma 1, folding the same ordered list yields the same resulting state. Concurrency at creation time does not matter once both events are committed; the ledger order defines the serialization order. For metadata with LWW-DT, ties are resolved by the deterministic comparator. For evidence of this, the union is commutative/idempotent, and the order is irrelevant anyway. □
Lemma 3 (Monotonic progress/no lost updates).
Let be the committed event list for at time . For , is a prefix of , and thus is a prefix-fold of (i.e., later states incorporate all earlier committed events).
Proof.
From A1 (immutability), the ledger only grows by appending new events; it does not delete or rewrite events. Therefore, grows by extension: . Since the state is a fold over the ledger prefix, the later state incorporates all events that defined the earlier state. □
Lemma 4 (Sync decreases divergence).
Let . A successful sync step applied to any reduces the gap by at least 1 and never increases it.
Proof.
By construction, submits pending edge events for to the cloud/ledger and then incorporates newly committed events into the cloud materialization, increasing . Edge version does not increase during the sync step unless a new local write occurs (which is outside the sync operation and treated as a new transition). Therefore, the gap decreases when one pending event is committed and applied; it cannot increase due to the sync itself. □
Theorem 1 (Eventual consistency with deterministic conflict resolution).
If no new local writes to occur after some time , and connectivity allows eventual delivery (A2), then there exists such that:
and this common state is the deterministic materialization of the ledger events for .
Proof.
After , is constant (no new writes). If , then . By A2, sync steps will eventually succeed for . By Lemma 4, each successful sync reduces the finite nonnegative gap by at least 1. Therefore, after finitely many successful sync steps, the gap becomes 0, so .
At that point, both the edge and cloud have incorporated the same committed event prefix for ; by Lemma 1 and Lemma 2, their materialized states are equal and deterministic. □
2.5. Blockchain Architecture and Data Integrity Framework
Blockchain technology is a core component of the decentralized architecture used to strengthen traceability of the coffee samples, data integrity of the coffee farmer, and operational resilience in rural environments. The apps use blockchain to prevent modification of the coffee sample records, reinforce provenance, and provide secure, transparent traceability from farm-level data capture to laboratory analysis.
Hyperledger Fabric is the most suitable option for implementing blockchain technology as it is an open-source platform for building distributed ledger solutions, with a modular architecture that offers confidentiality and resilience. As an enterprise-level permissioned blockchain network, it is necessary to configure the network and the organization data using a Certificate Authority (CA). Furthermore, it functions as a network of nodes or fabric, where each node performs a specific function, such as validating transactions, maintaining the ledger, and executing the chain code.
Core Components of the Architecture
- External Actors: Users (Coffefarmer 1, Coffefarmer 2, …, Coffefarmer n) and the entities (chemometricians specialists, coffee cooperatives, others) interact with the system via the apps or cloud-based requests.
- Cloud Layer and Fabric Client: This tier functions as an intermediary, where user-generated actions and system updates are handled by a fabric client component before being transmitted to the blockchain network.
- Certificate Authority (CA): The CA is responsible for management and network security and oversees the registration and enrollment of the fabric clients.
- Peer Nodes: Transaction proposals are received from the fabric client through smart contract logic and maintain copies of the distributed ledger.
- Ordering Service: This component collects endorsed transactions from peers, sequences them into blocks, and disseminates those blocks to the designated channels.
- Channels: Isolated communication layers within the network to share a dedicated ledger and exchange data privately.
Performance and scalability of a blockchain platform can be affected by many variables such as transaction size, block size, network size, etc. However, with Hyperledger Fabric’s unique execute–order–validate model, transaction processing can be scaled sideways by distributing the workload across peer nodes. Additionally, because it operates as a permissioned blockchain, the need for costly mining processes is eliminated. Together, these features enable Hyperledger Fabric to achieve superior scalability and performance without the technical constraints that affect most other distributed ledger technologies.
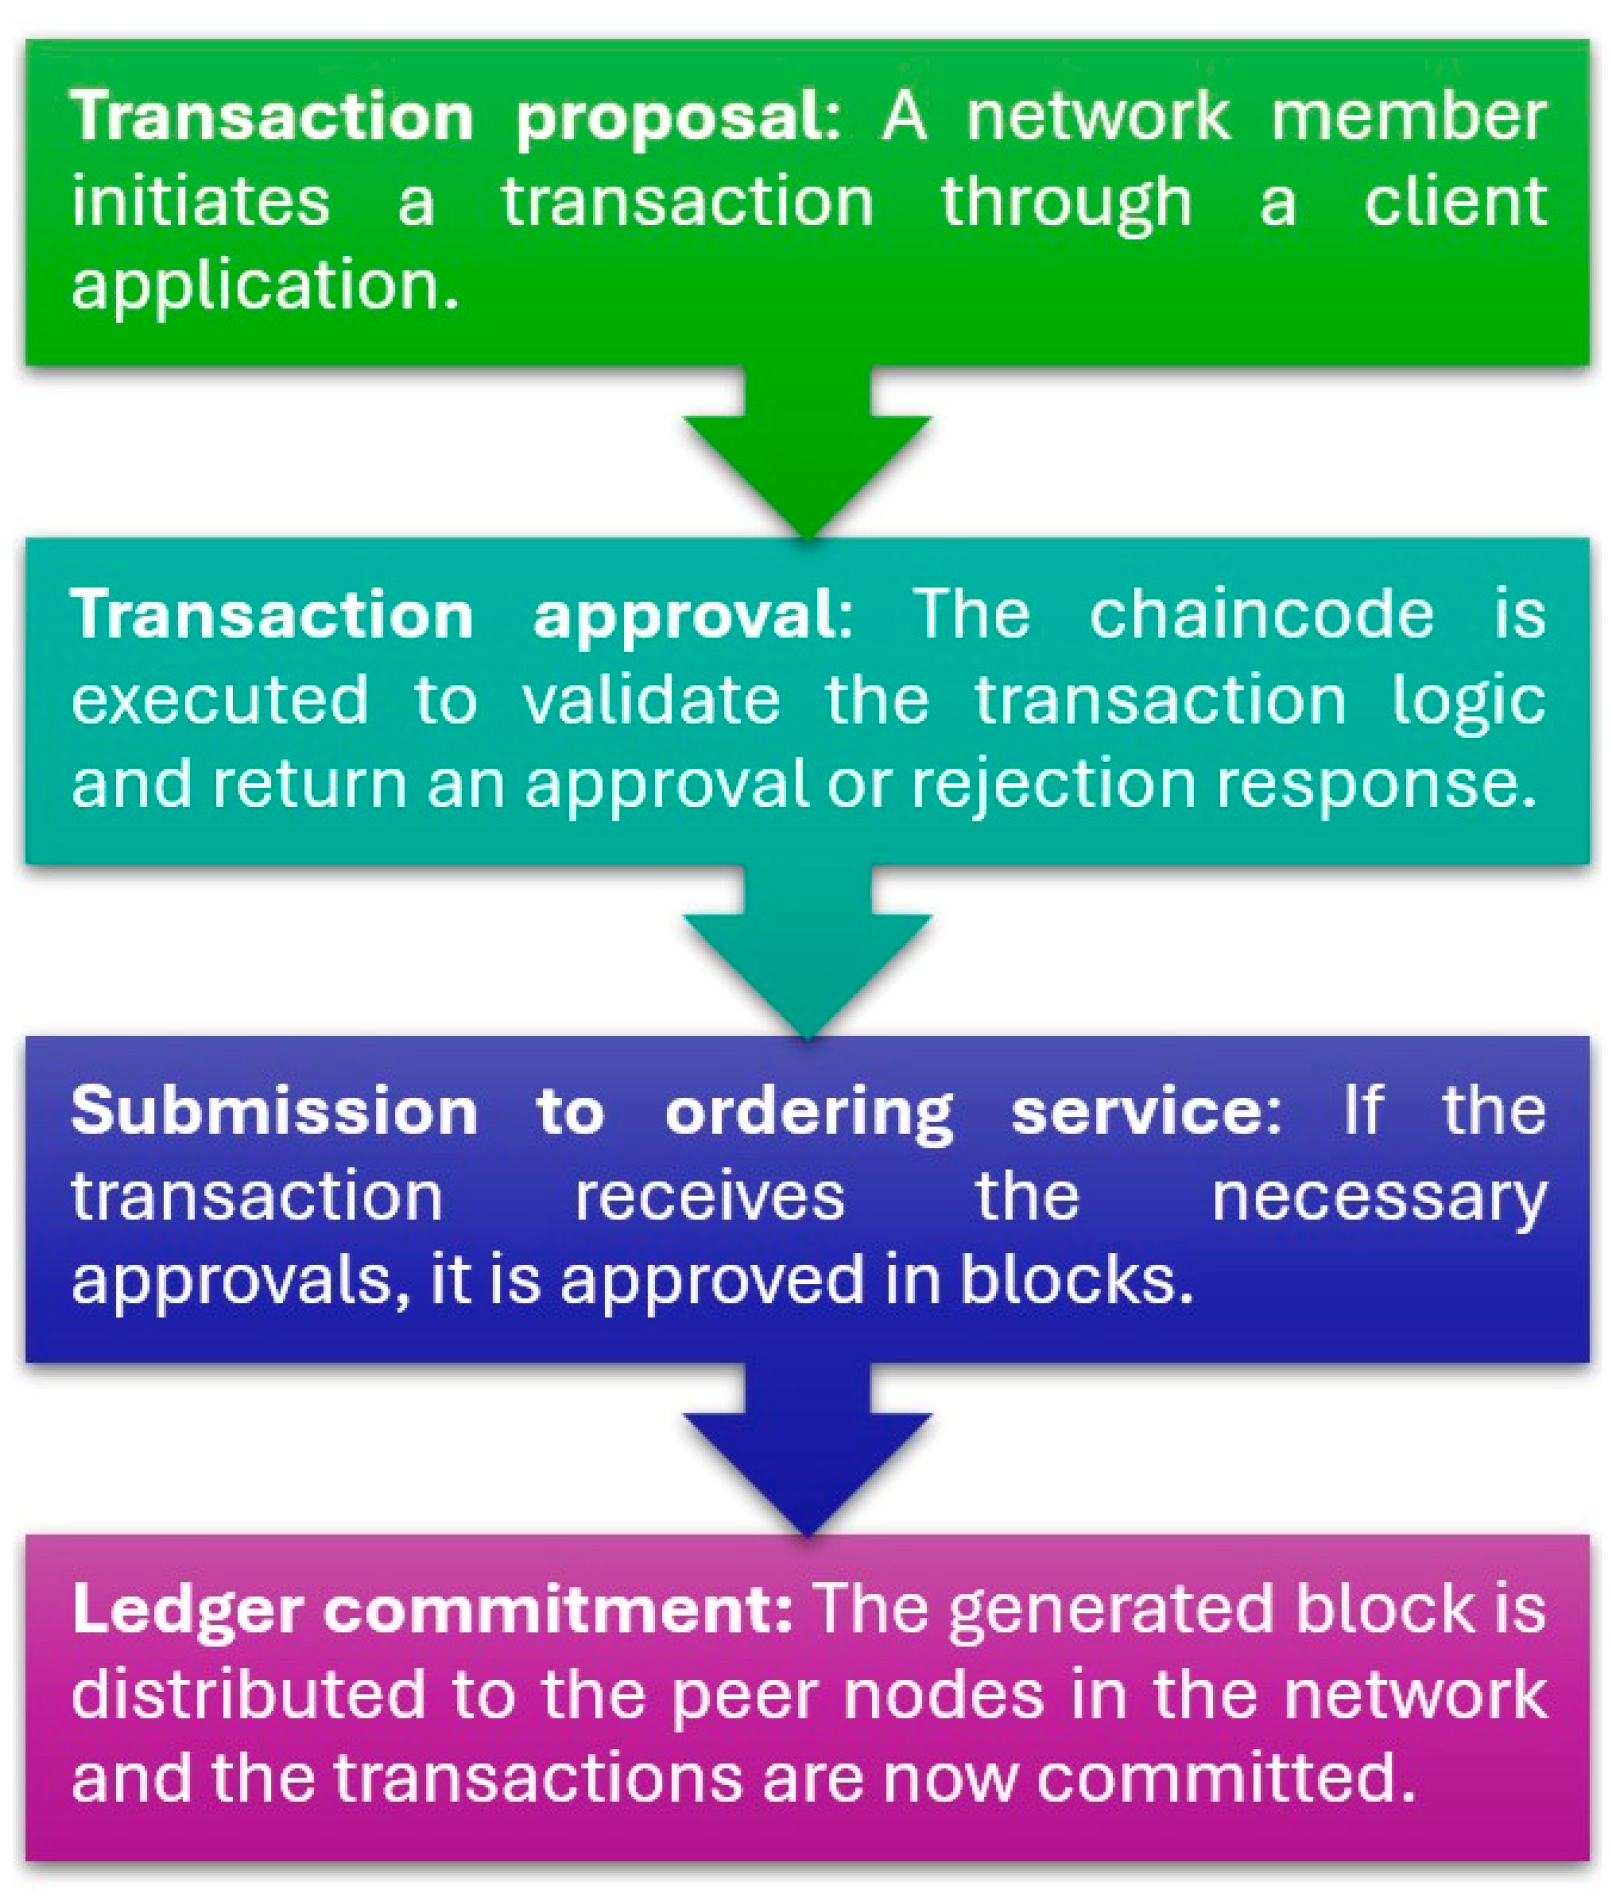
The Hyperledger Fabric transaction workflow follows an execute–order–validate model that begins with a client submitting a proposal to endorsing peers. These peers verify the user’s identity and simulate the transaction via the chaincode, returning a signed endorsement to the client without updating the ledger yet. Once the client collects sufficient endorsements, it forwards them to the ordering service, which sequences the transactions into a block. Finally, this block is broadcasted to all nodes, which validate the endorsement and data integrity before committing the transaction to their local ledgers. For each transaction in the fabric, the following steps are shown in Figure 5.
Figure 5.
Transaction workflow in the fabric.
Hyperledger Fabric was created with a modular framework at its core and therefore allows various components, including consensus mechanisms, identity and key management protocols, and cryptographic libraries, to be customized. RAFT is the most suitable consensus algorithm because it is used to maintain a consistent state across multiple nodes. This is a specific algorithm that falls under the CFT (Crash Fault Tolerance) category. It describes any system that can continue to function even if some of its nodes stop working (crash). It does not handle nodes that only lie or act maliciously, therefore it is well-suited for networks with a limited number of participants who are trusted and well-known.
2.6. Spectral Traceability of the Specialty Coffee
Traceability through spectral fingerprinting in specialty coffees allows the identity of the bean to be protected against fraud, ensuring its terroir, variety, and quality.
The French concept of terroir describes the unique combination of environmental and human factors that give coffee a flavor and personality that cannot be replicated anywhere else in the world. It consists of four fundamental pillars:
- Climate and Microclimate: This includes average temperatures, rainfall patterns, humidity, and sun exposure. In specialty coffees, the temperature range—a term referring to the sharp temperature changes between day and night—forces the bean to mature more slowly, concentrating more sugars and complex acids. The study areas exhibit diverse microclimates with a marked temperature range.
- Geography and Altitude: Altitude also influences the coffee quality, as higher altitudes mean less oxygen and lower temperatures. This slows down plant growth and increases plant density. Other influencing factors include the slope of the land and its orientation relative to the sun.
- The Soil: The chemical composition of the soil, such as pH, minerals, and drainage capacity, nourishes the plant in a specific way. Volcanic soils are notable for their acidity and mineral notes, which are highly valued in the market. The areas studied are characterized by volcanic soil.
- Human Factor and Tradition: Human traditions can influence the producer’s decisions, such as the variety planted and the cultivation techniques used, as well as the processing methods employed, such as fermentation and drying.
Terroir defines the exact chemical composition of the coffee bean, which can be read through its spectral fingerprint. This is equivalent to possessing the environmental DNA which allows us to confirm whether a specialty coffee truly comes from the place indicated on its label.
Spectral traceability is based on the intrinsic chemistry of coffee. This is carried out through the following steps:
- Origin Characterization: This involves mapping the production areas. To do this, coffee samples are collected from farms to create a reference database. Each sample is analyzed using near-infrared (NIR will be used in this study) spectroscopy to capture the chemical signature of the soil and the plant. Values are also obtained, which are “recorded” in the hydrogen and oxygen isotopes of the bean, for various variables such as altitude, rainfall cycle, and soil nutrients.
- Sampling of Green Grain: Before exportation, green coffee is analyzed to verify that its fingerprint matches that of the declared origin. This involves scanning the unroasted beans, whole or ground, with a spectrophotometer to detect if the batch has been mixed with lower-quality beans or beans from another region.
- Monitoring during the Roasting: Roasting alters the chemical composition of coffee, creating a new “fingerprint” in the process. Spectroscopy is used to maintain the roast profile. It validates two key factors for this category: whether the uniformity of the color has been maintained and whether the roasting level is appropriate to highlight the notes of the specialty coffee.
- Sensory Quality Analysis: The sensory quality of the coffee can also be validated by comparing spectral curves with cupping scores (SCA). This is possible because certain spectral signatures are linked to specific high levels of acidity or sweetness, allowing for a quick and objective prediction of cup quality (above 80 points).
- Verification at the Point of Sale: To confirm authenticity, the importer or final roaster can scan the package to see the “fingerprint” that guarantees the coffee is indeed from the specified farm. Spectral data is typically linked to this “fingerprint” via a QR code or, as in this study, a blockchain system.
3. Results
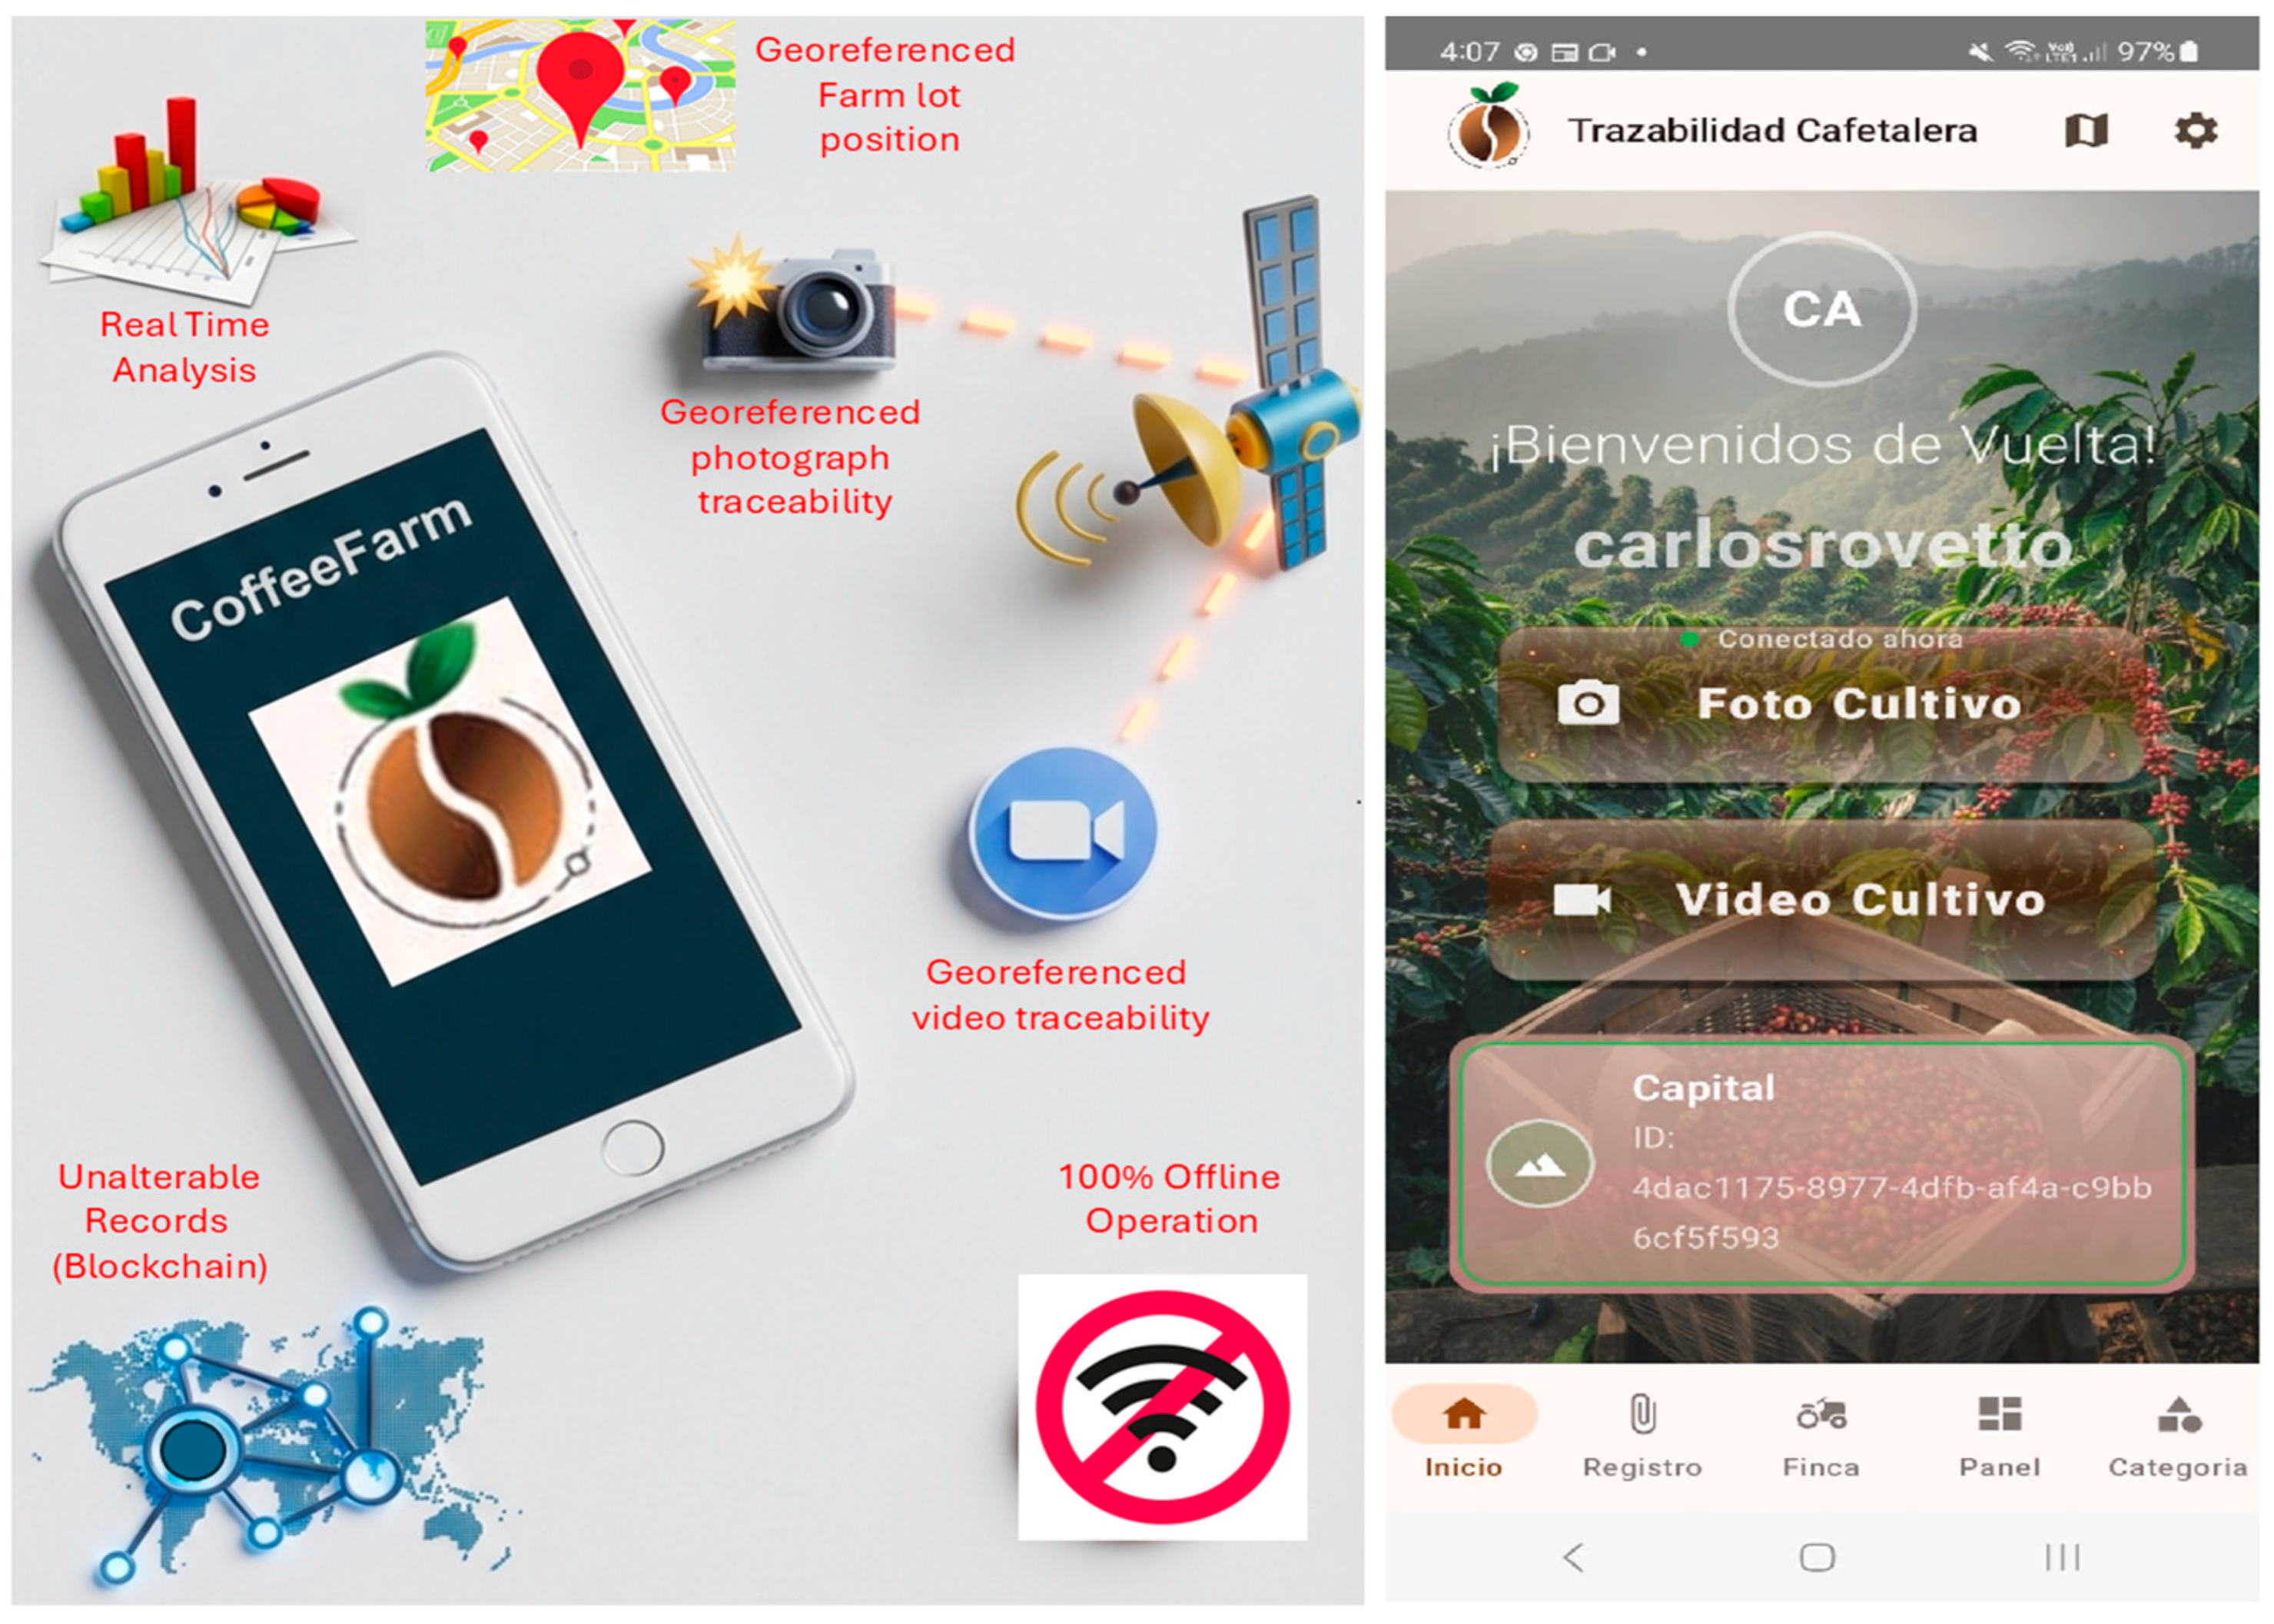
The apps used in the sample collection process and the storage of georeferenced evidence from coffee samples includes several functionalities necessary to ensuring the accuracy of the coffee’s spectral fingerprint. It will also help producers to maintain productivity and coffee quality. Figure 6 presents a general outline of the main features of the apps. This was designed to be easy and intuitive to use for producers.
Figure 6.
Main features of the application.
The development of the application used the best practices and technologies recommended by Google to create native, robust, and scalable Android applications.
- Kotlin Programming Language: selected as the official language for Android development due to its null-safety, conciseness, and complete interoperability with the Java ecosystem.
- The application architecture: implements the MVVM (Model–View–ViewModel) pattern with the following layers:
- ○
- Interface Layer (UI Layer): built with Jetpack Compose, a declarative framework for user interfaces. This layer is limited to displaying the state provided by the ViewModel and notifying user interactions, without containing business logic.
- ○
- ViewModel: manages interface logic and state, using StateFlows to expose data to the UI. It is designed to survive configuration changes, such as screen rotations.
- ○
- Data Layer: manages all data sources using the repository pattern, isolating the ViewModels from the source of the data (local database or web services).
- User Interface Framework: Jetpack Compose, which allows for the development of complex interfaces with less code, is an intuitive framework with reusable components. The visual design strictly adheres to the Material Design 3 (M3) guidelines.
- Local Storage:
- ○
- Structured and Relational Data: Room, an abstraction layer on top of SQLite, is used to simplify database access and perform compile-time query verification for managing batches, farms, and processes.
- ○
- Key-Value Data: Jetpack DataStore is used to store user preferences and session tokens.
- Backend Communication:
- ○
- The application connects to a server using a RESTful API.
- ○
- Retrofit is used to define API calls declaratively, along with OkHttp as the HTTP client.
- ○
- JSON object serialization and deserialization are performed with Moshi and optimized for Kotlin.
- Asynchronous Management: Background operations, such as network calls or database access, are handled with Kotlin coroutines, ensuring a smooth, non-blocking interface.
- Dependency Injection: Hilt is used to manage dependencies throughout the application, simplifying the architecture, facilitating testing, and reducing repetitive code.
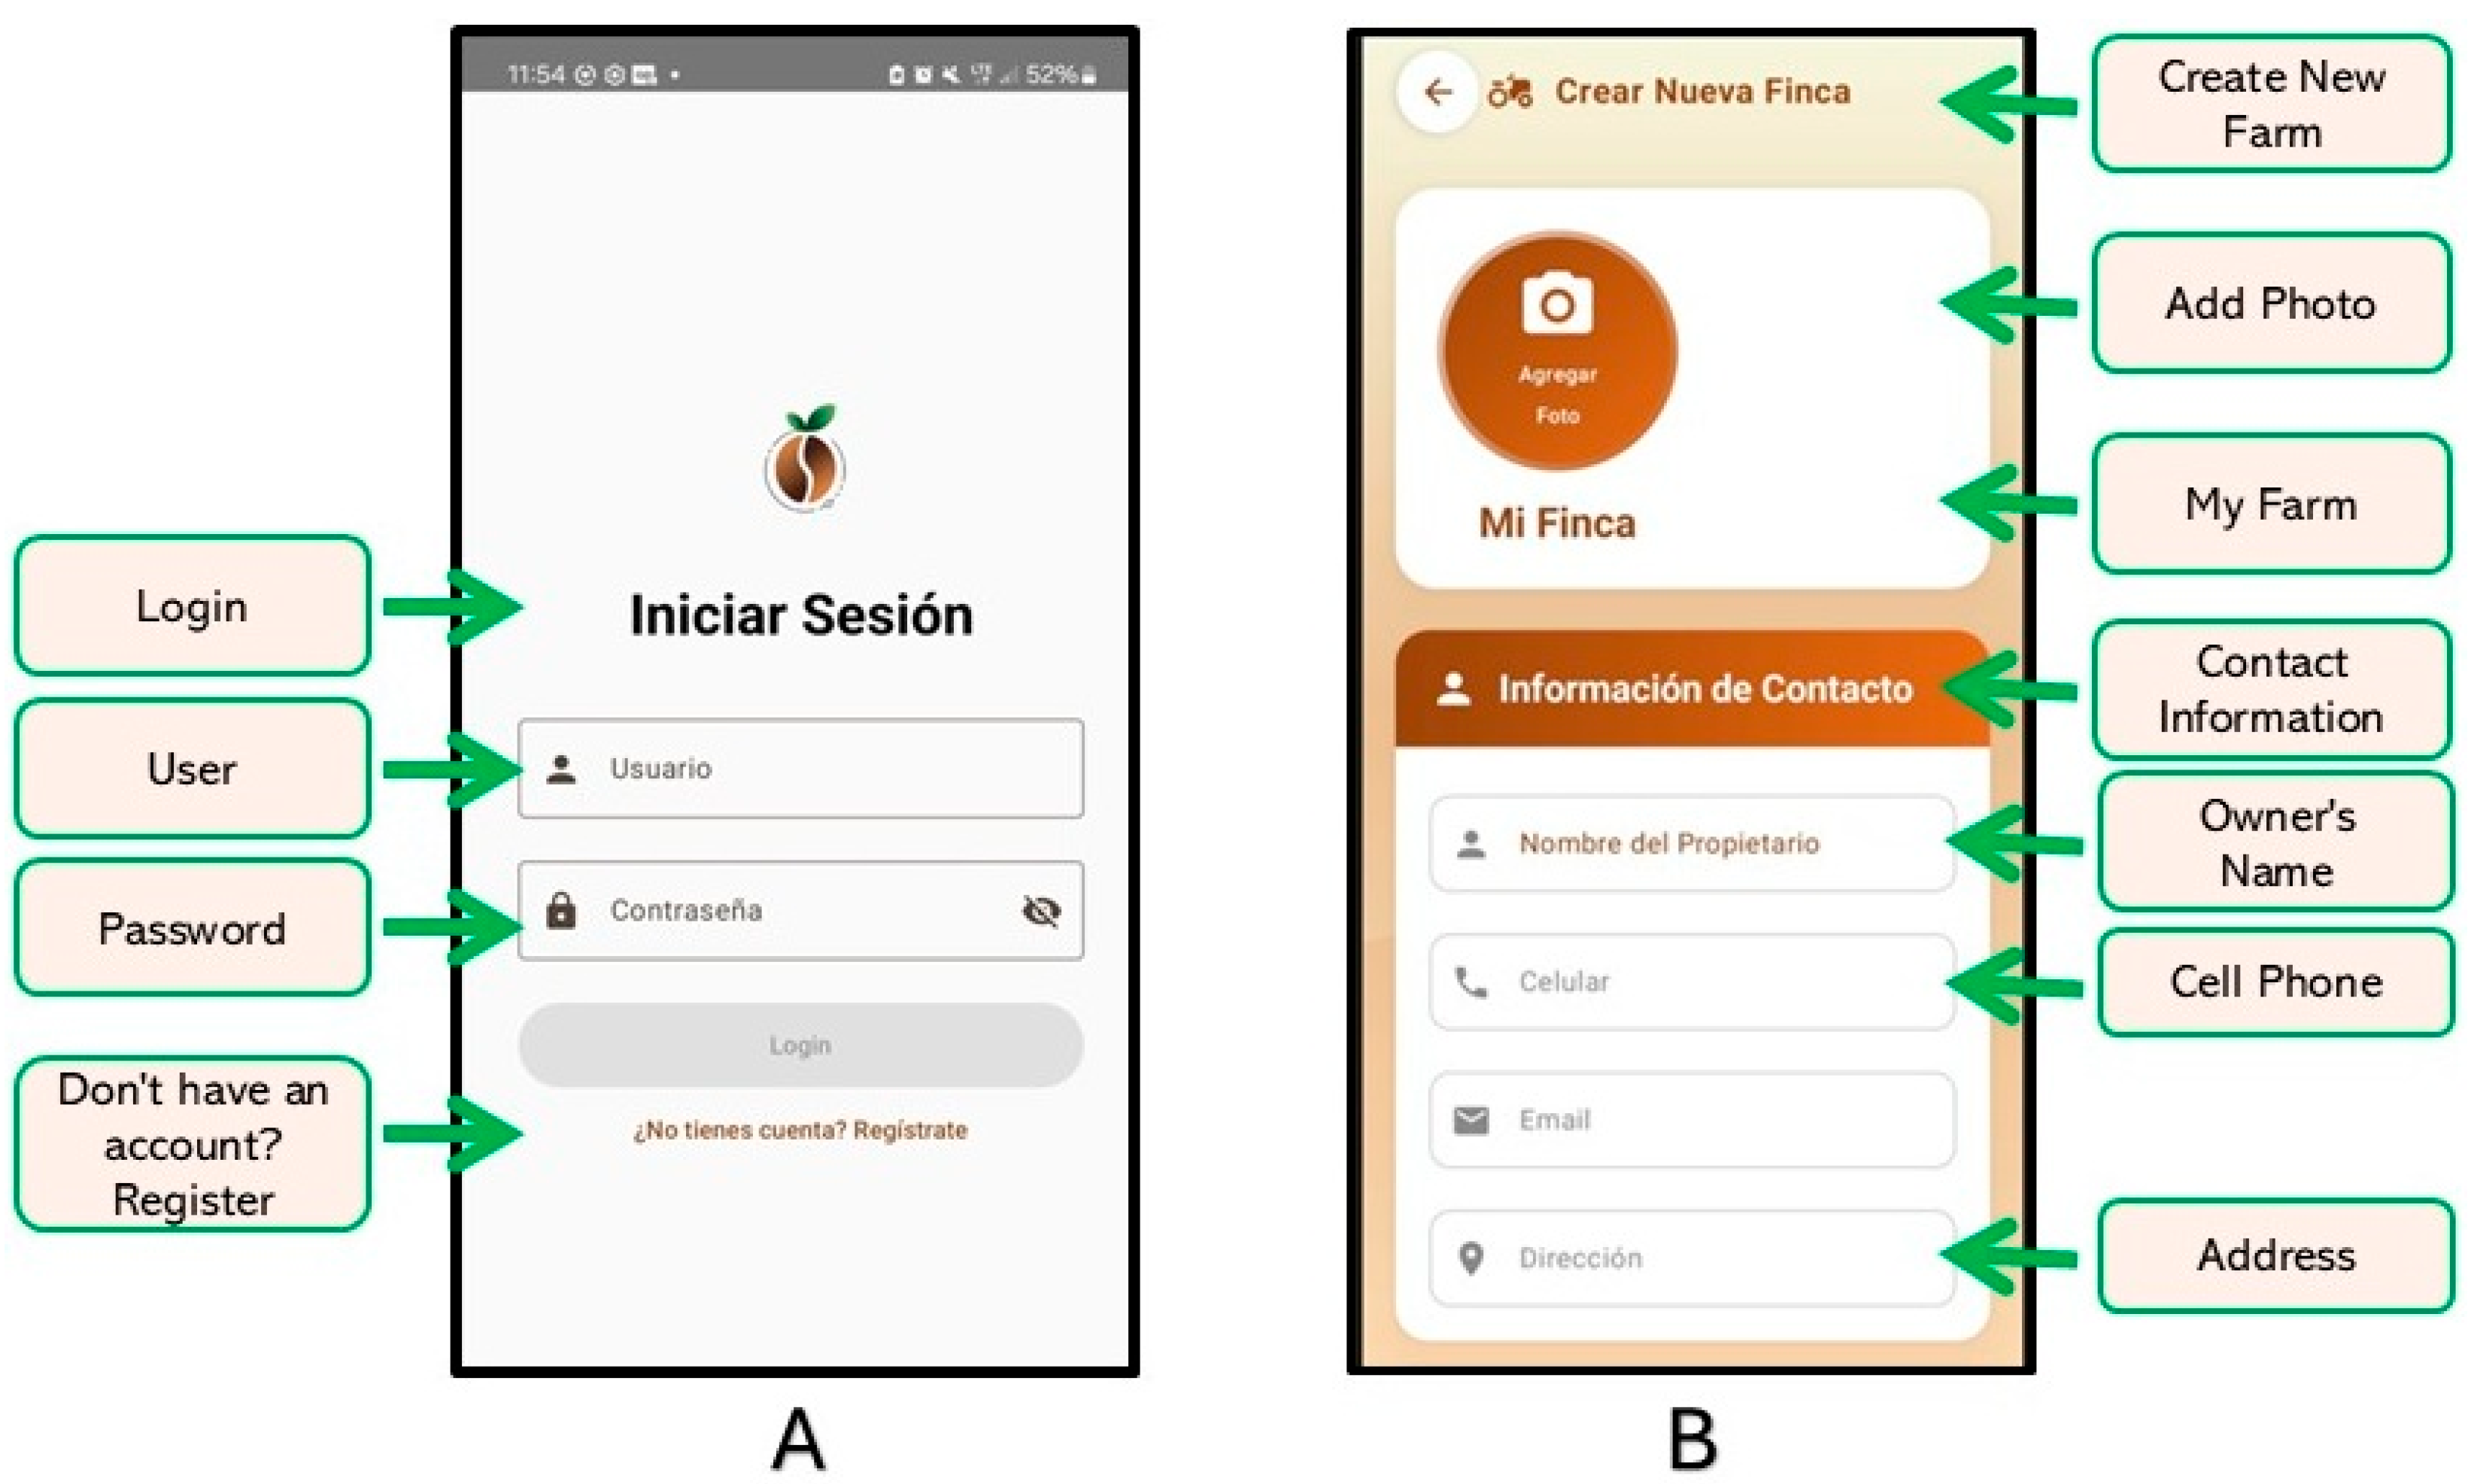
To use the application, each producer must create a username and password to register, as shown in Figure 7A. This will allow them to log in to the application. Formally, it is represented in the model as: .
Figure 7.
Login screen (A) and property registration screen (B).
The following describes the registration process using the application that characterizes the origin of the coffee in the spectral traceability system.
The user must register the farm by completing the corresponding information about the owner. Figure 7B shows the personal information that the coffee farm owner must provide.
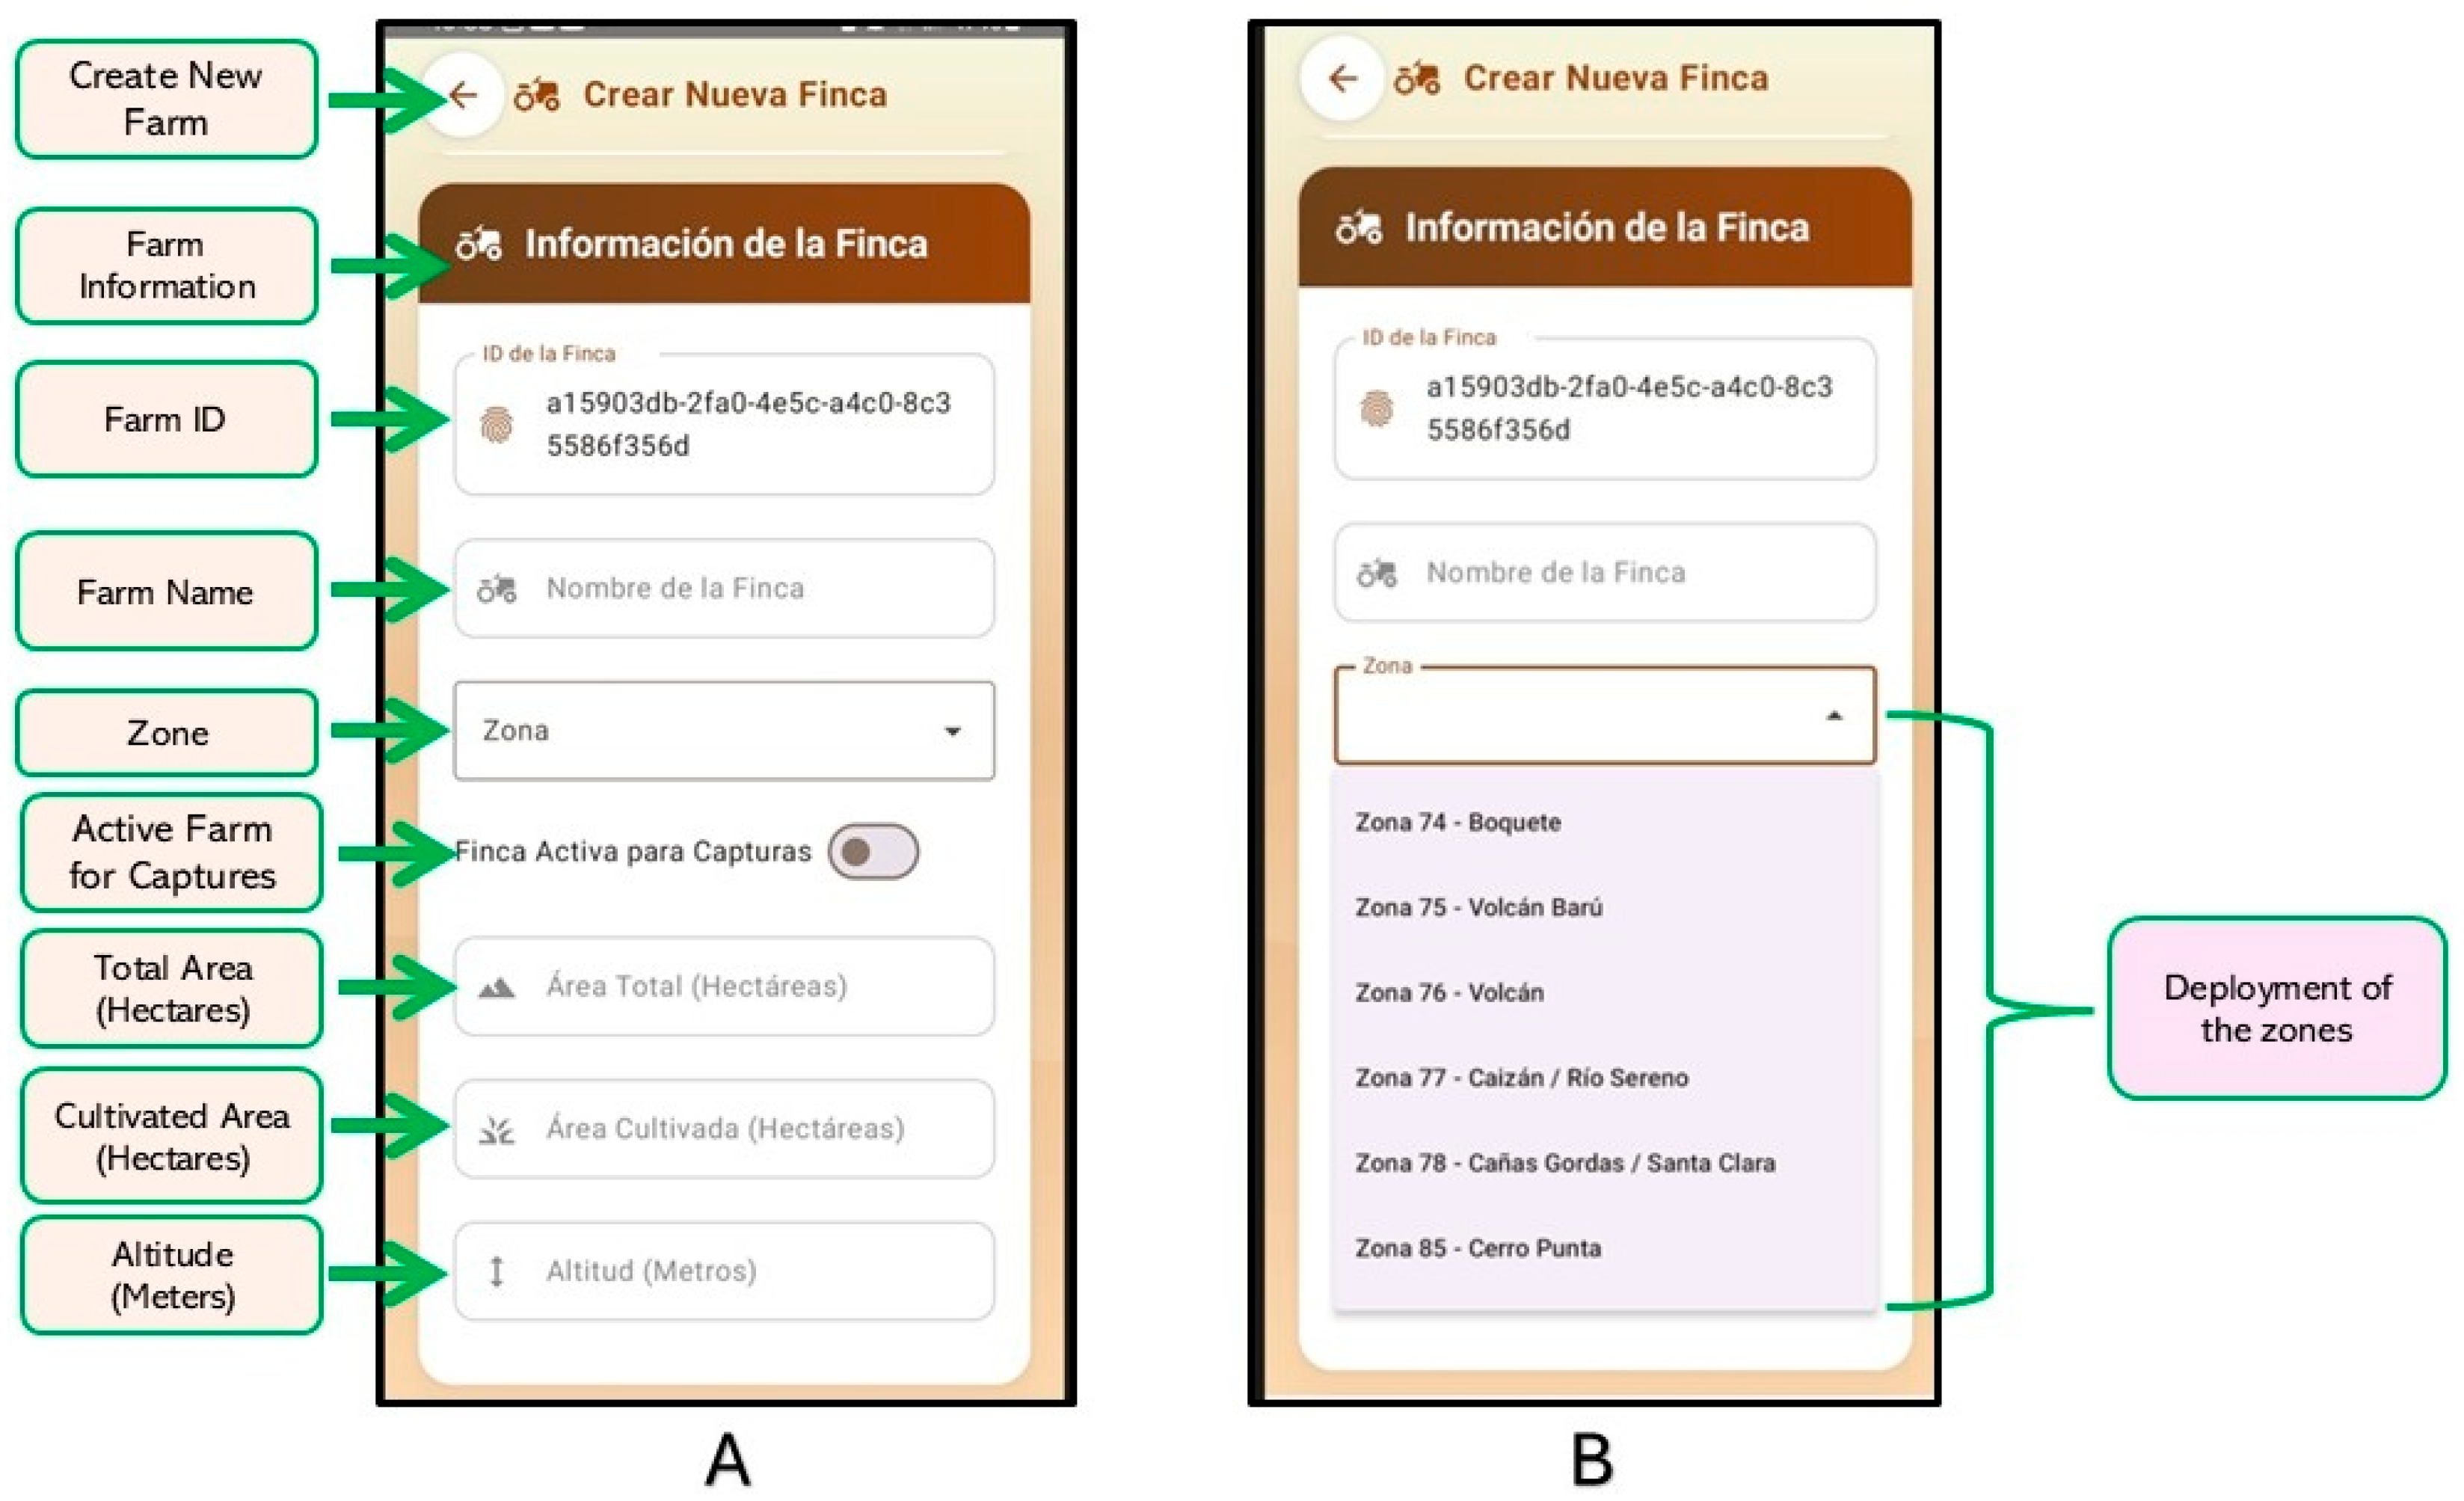
When a property is registered, a unique code is generated, which is the ID that allows access to its information in the database. Additionally, the name by which the property is known in the sector, the zone, the total area, the cultivated area, and the altitude must be entered; this screen can be seen in Figure 8A. Figure 8B shows the screen displaying the areas where property registrations are being carried out. This information establishes a relationship with the property belonging to one or more zones, which is represented in the model as , where . This relationship is used by the Loc location function to locate the specific zone Z in the farm F.
Figure 8.
Property registration screens (A) and Zones of property registration screens (B).
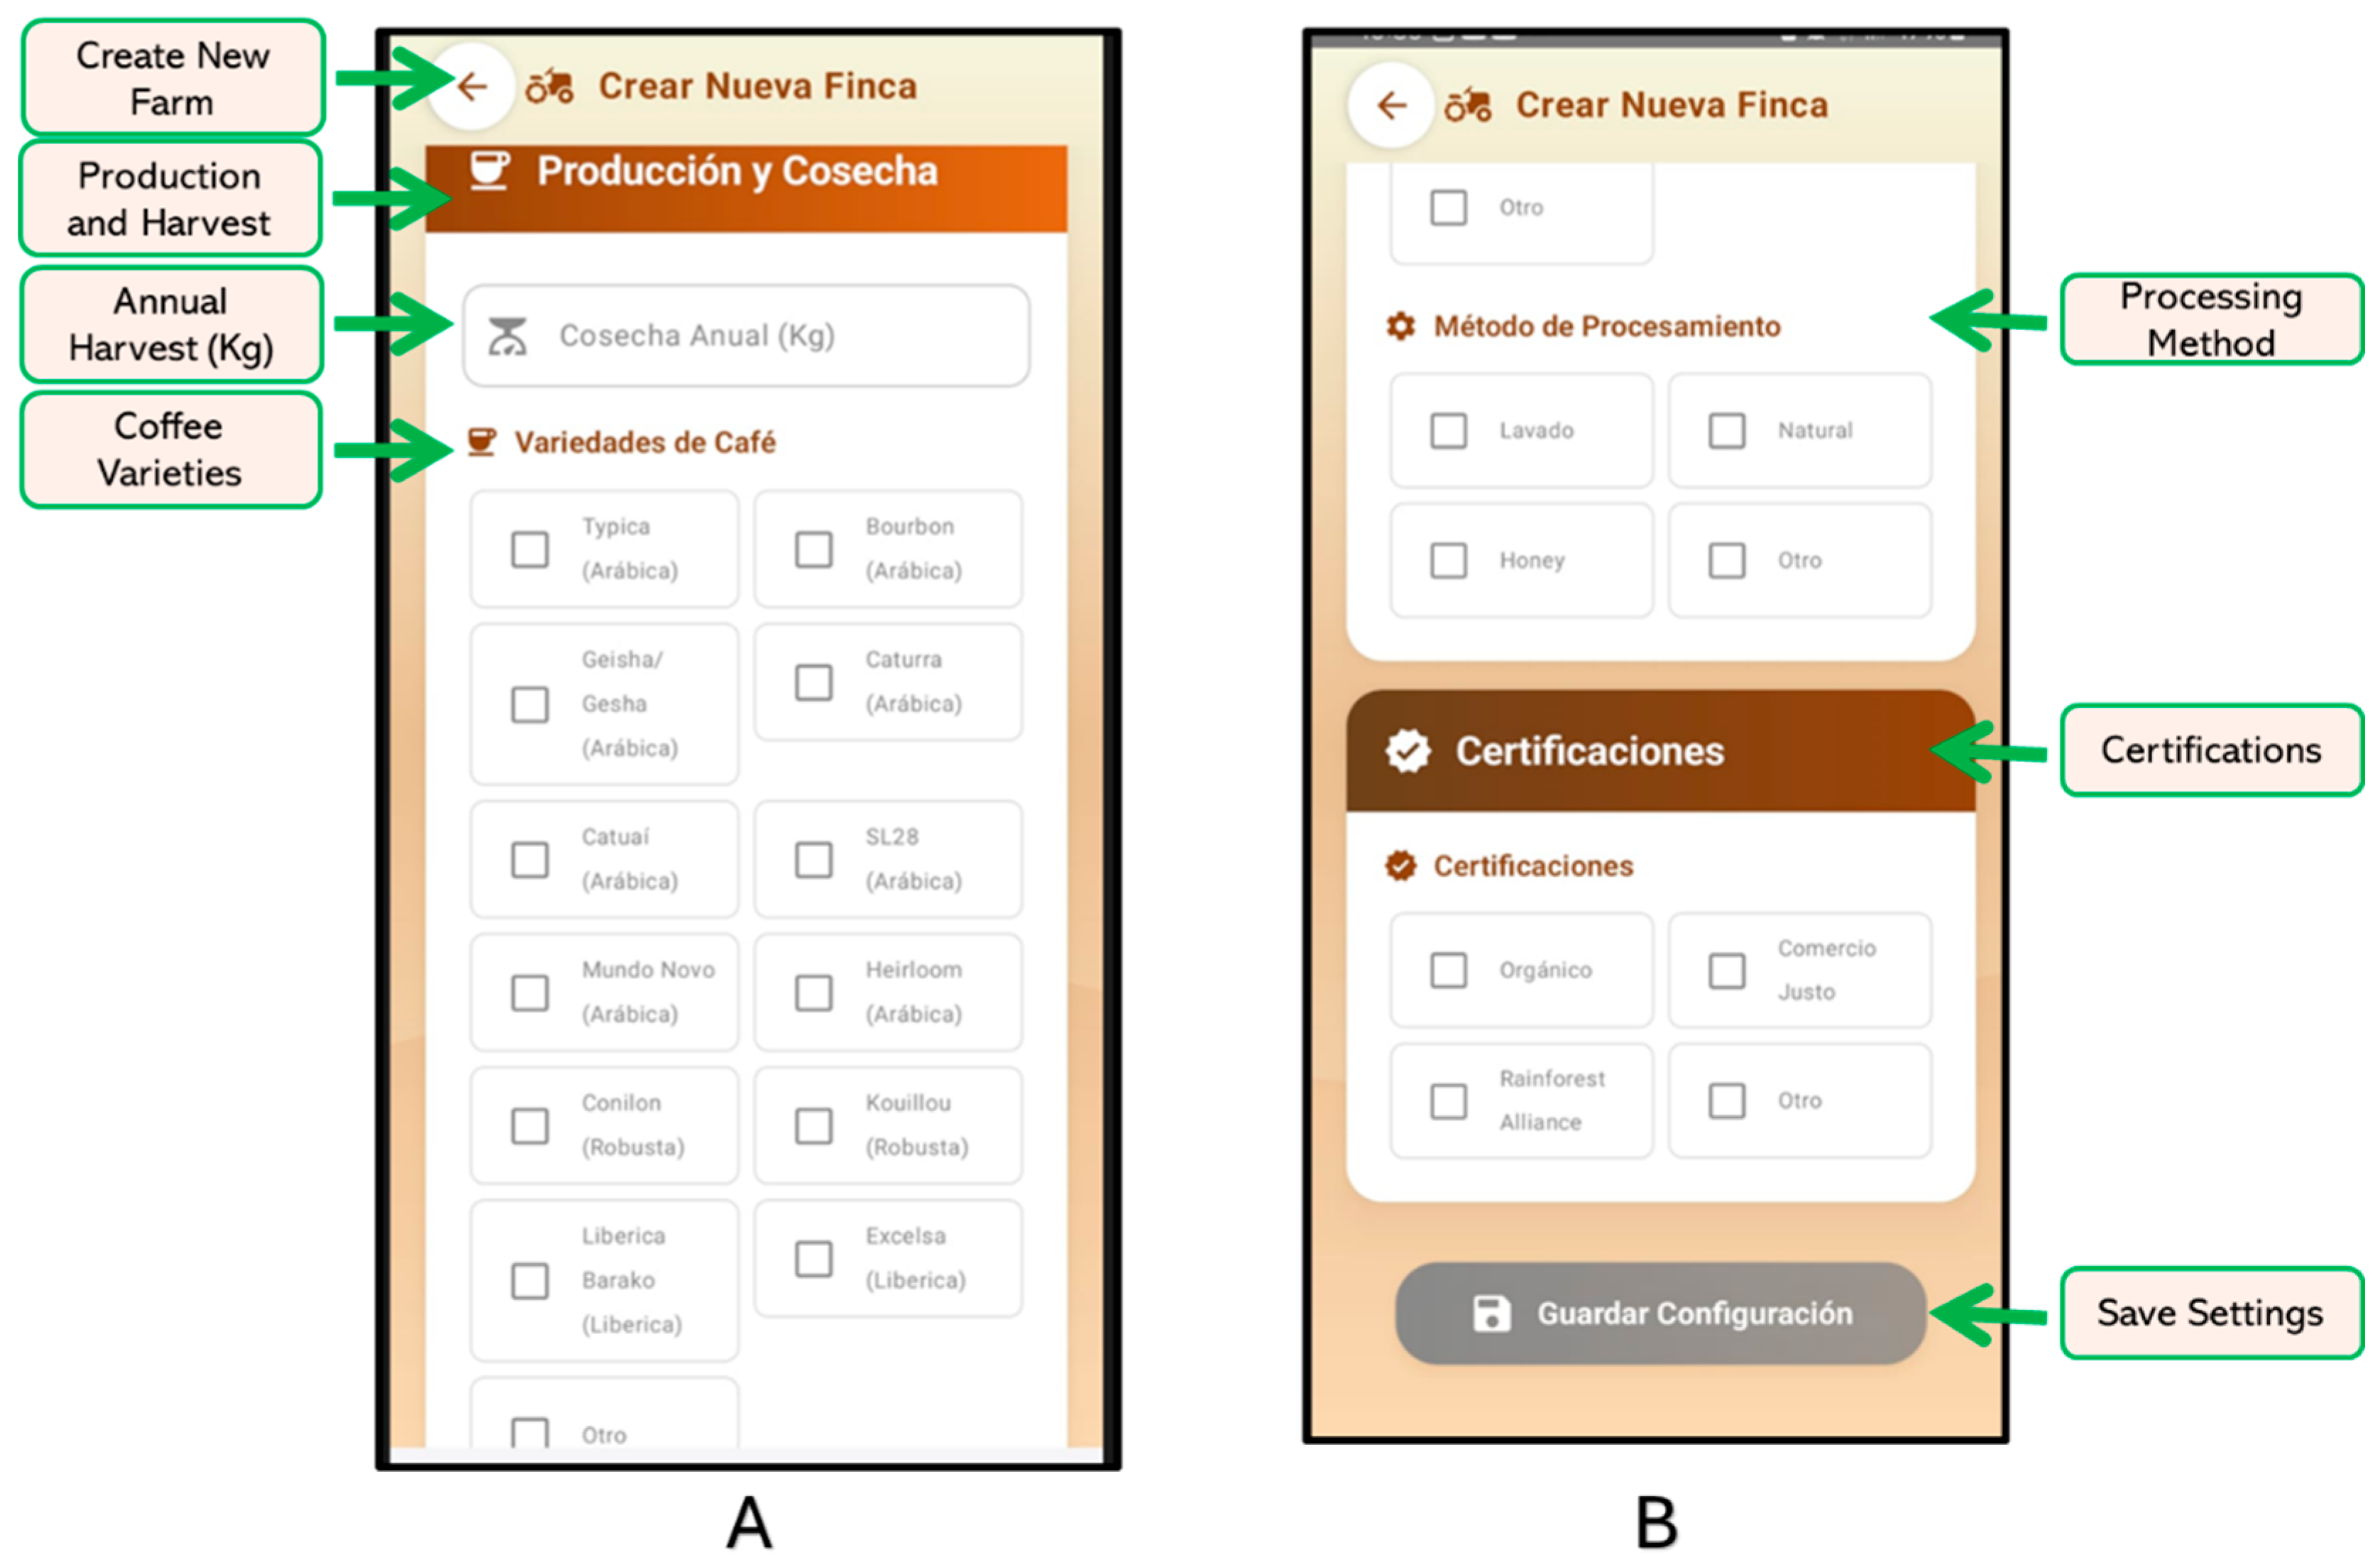
To register the coffee variety planted on the farm, Figure 9A shows the screen with the different varieties that the user can select. A farm can have several coffee varieties planted; in this case, the coffee variety planted on the plot is indicated. Also, the processing method used for the coffee and the certifications held by the farm must be recorded, as this is very important information for specialty coffees as seen in Figure 9B.
Figure 9.
Screens for recording production, harvesting (A), and certifications (B).
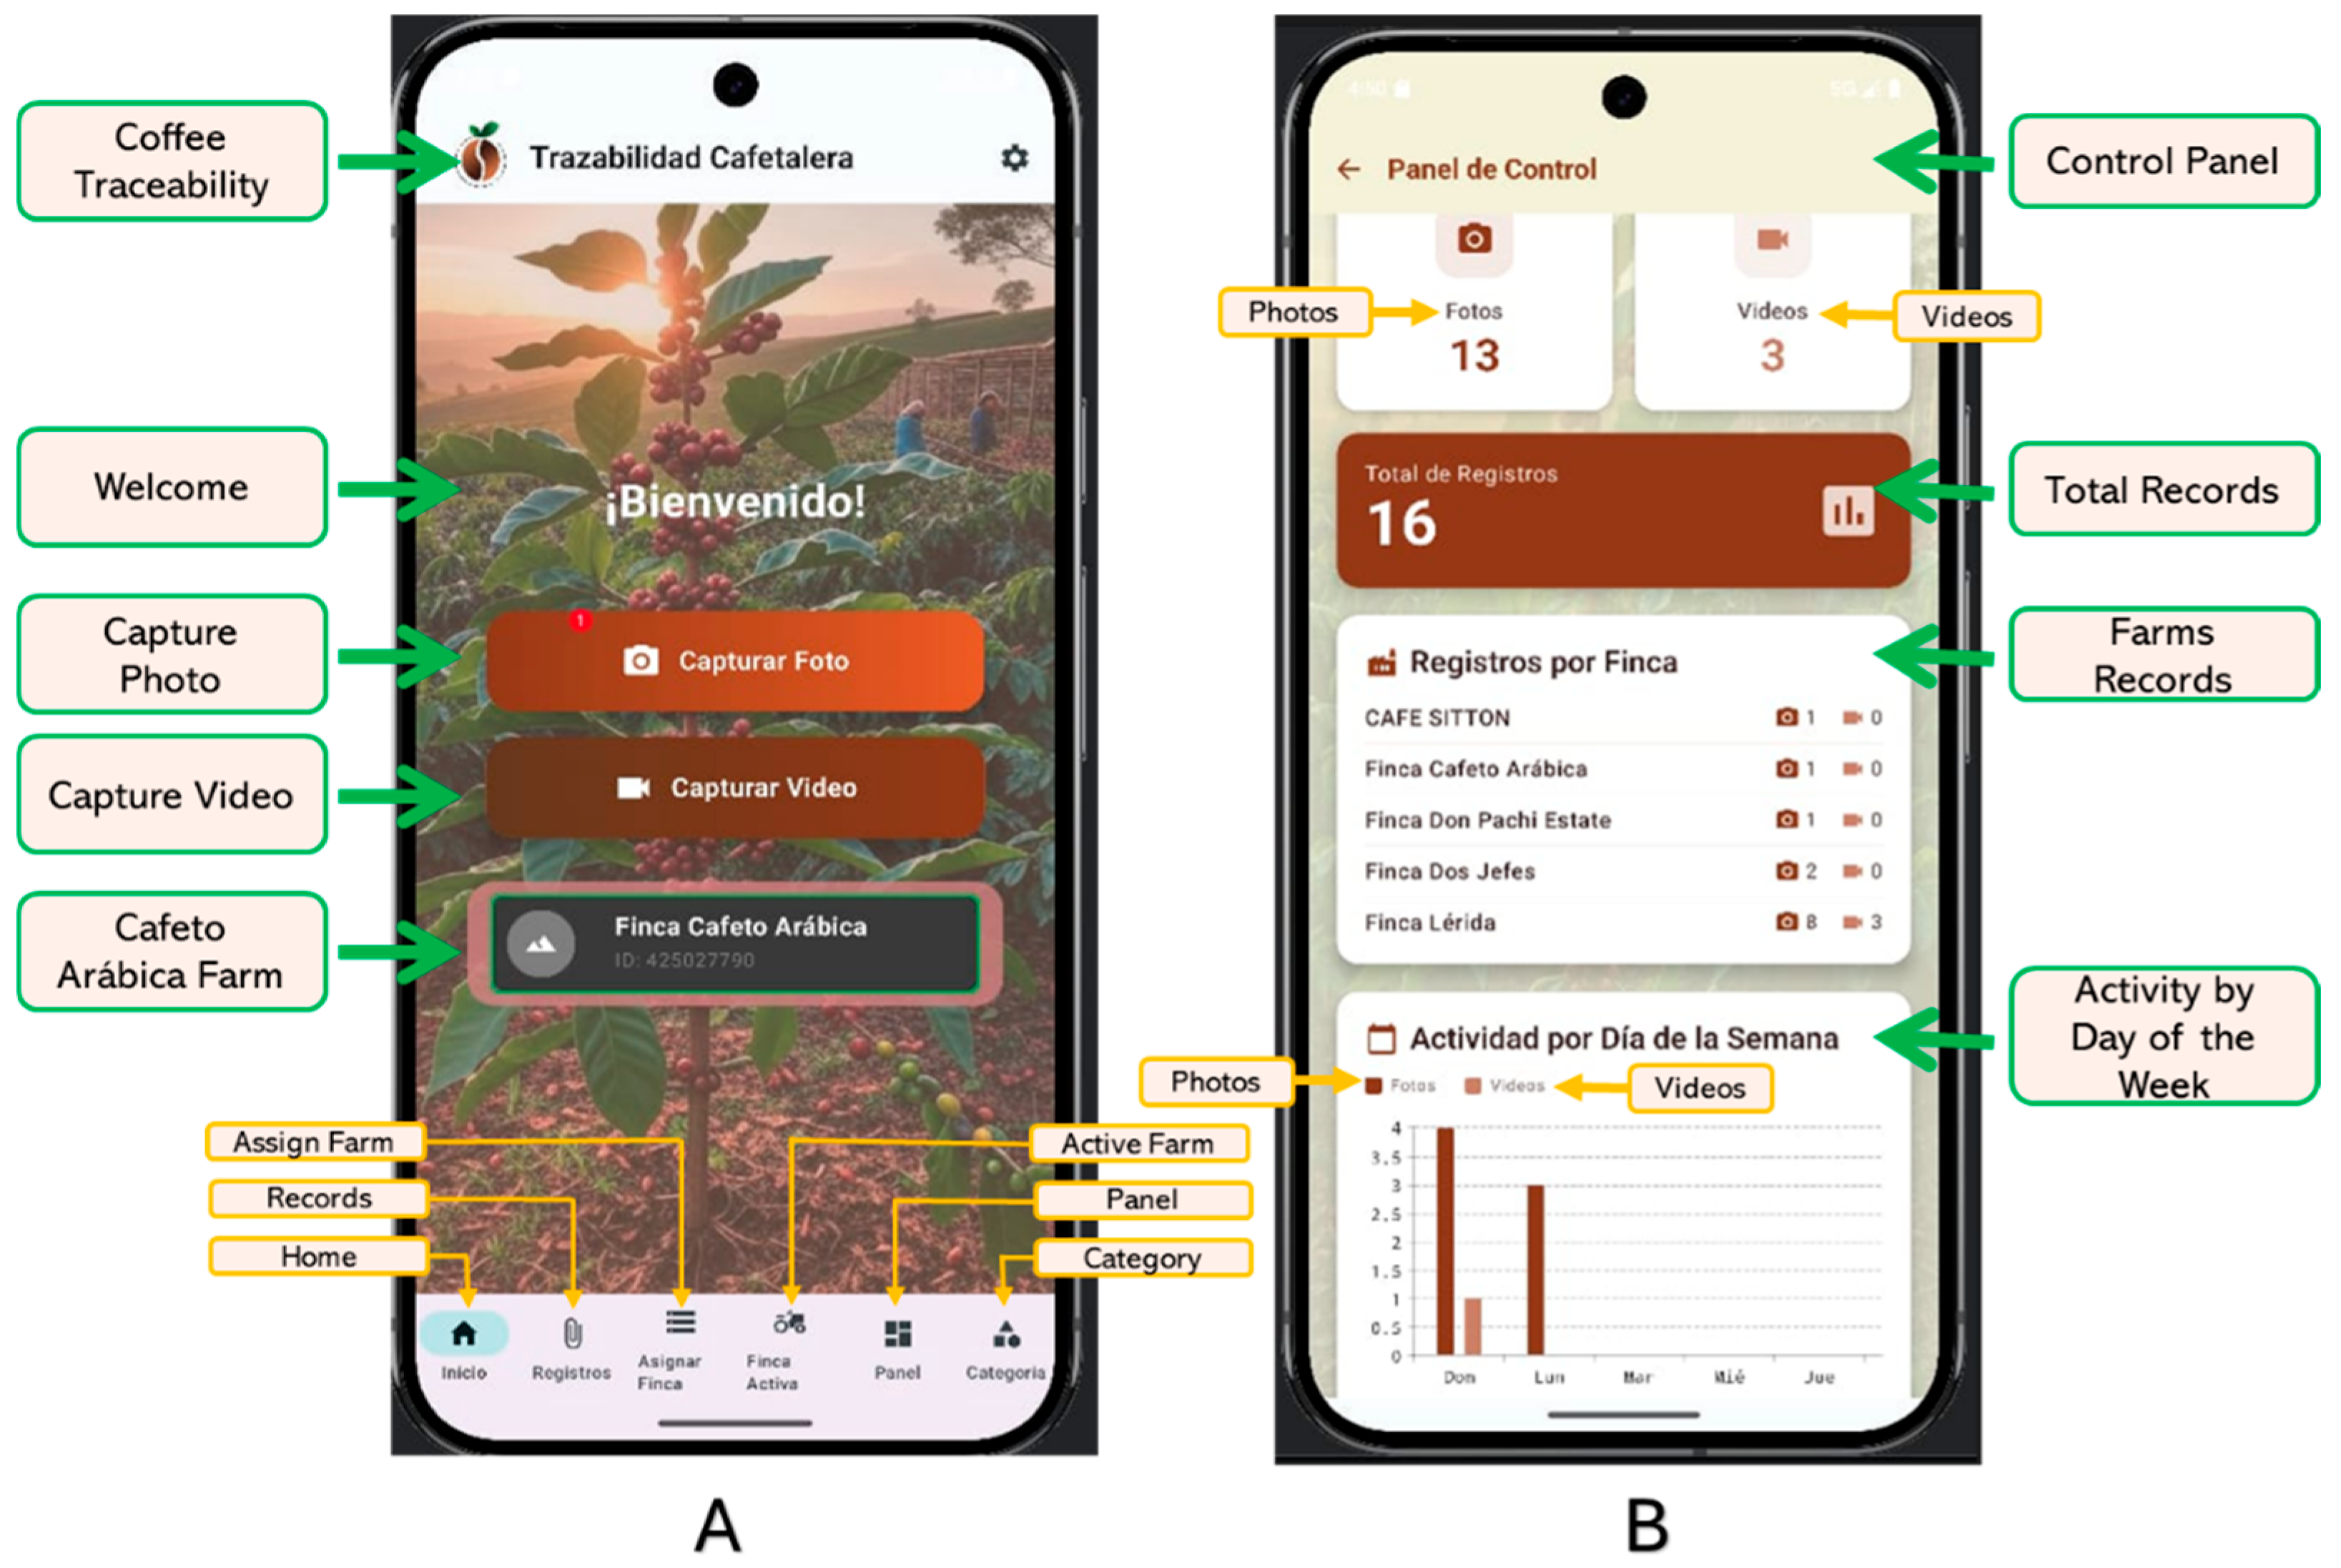
Before the harvest begins, coffee samples are collected from the farms. This involves recording videos and taking photos of the samples by batch, including georeferenced data with the encrypted key to generate the blockchain of this process, as shown in Figure 10A. This data is used for the provenance function (Prov) and farm evidence functions (Hf). Finally, the synchronization function δ (t) ensures that data is sent correctly and stored in the database DB(t).
Figure 10.
Control of the collection of samples from the farm (A) and farm reports (B).
The samples are sent to the chemistry lab where they will be analyzed using near-infrared technology selected by the lab’s chemists. This process is performed outside of the application. The results will be saved in the mobile application once the analysis is complete. Additionally, a record of the activities performed each day is kept, as shown in Figure 10B.
4. Discussion
The results of this study constitute a viable and scalable solution for improving traceability, quality assurance, and decision-making in specialty coffee production through the integration of a framework that combines Precision Agriculture Management Systems (PAMSs) and traceability architecture. A mobile application facilitates the collection of georeferenced coffee bean samples, which are then sent to the chemistry lab for spectral fingerprinting. The evidence of geographic origin and coffee varieties stored in the mobile application is necessary to establish its terrior and a unique spectral fingerprint, as well as to prevent coffee adulteration.
The proposal introduces a data-driven methodology [13,15] capable of supporting producers in the evaluation of data traceability and decision-making that is distinct from the traditional method, which can be costly. Table 4 shows the comparison between the two approaches.
Table 4.
Comparative approaches.
Accurate geospatial, environmental, and management data significantly improves coffee traceability and differentiation. The system allows for terroir measurement and verification by linking altitude, microclimate, soil characteristics, and post-harvest practices. This capability is fundamental for high-value Panamanian specialty coffees, especially the Geisha variety, where origin authentication and fraud prevention are essential for maintaining market confidence and premium pricing [5,24,25].
The proposed system provides a more comprehensive traceability model compared to existing traceability approaches that are primarily based on manual digital records or QR codes. Although QR code-based systems improve access to information, their ability to guarantee authenticity or prevent data manipulation is limited [7,8]. In contrast, the integration of spectral fingerprinting with immutable blockchain records and georeferenced evidence in the proposed system offers a higher level of security throughout the coffee value chain, from the farm to the point of sale [9].
The system facilitates data-driven decision-making for producers, helping to bridge the technological gap between coffee growers and quality certification processes. This supports the integration of smart and precision agriculture technologies to improve productivity, sustainability, and quality consistency in coffee production systems [16,19,28].
The mobile application effectively addresses the problem of internet connectivity, one of the most critical limitations faced by coffee producers in rural regions, by implementing an edge–cloud architecture combined with blockchain-based version control and immutability. This ensures data integrity and enables offline operation.
This approach is consistent with previous research on cloud and edge computing applied to agricultural systems, which identified resilience, consistency, and fault tolerance as essential properties for rural implementations [17,18]. Furthermore, the formal mathematical model presented in this work provides a rigorous abstraction of the traceability, provenance, and synchronization processes, reinforcing the system transparency and reproducibility, an aspect often lacking in comparable agricultural traceability solutions [8,9].
5. Conclusions
This research presents an innovative system for specialty coffee traceability that integrates mobile computing, edge–cloud architecture, and blockchain technology. The system proposes a scientifically based method for characterizing coffee quality and authenticating its origin.
The mobile application enables on-farm data collection, capturing georeferenced evidence, videos, and agronomic data. All of this is achieved without compromising functionality, even under limited connectivity conditions. Furthermore, the formal mathematical model ensures consistency, provenance, and traceability among the distributed components, providing a solid foundation for scalability. Finally, the use of georeferenced information of the coffee is essential to ensure its terroir and the accuracy of the spectral fingerprint of coffee, as well as to prevent coffee adulteration.
The system supports producers in improving the quality, productivity, and market position of their coffee by providing them with data on their coffee production and facilitating data-driven decision-making. Furthermore, it enhances transparency, reduces the risk of coffee adulteration, and strengthens consumer confidence, all crucial aspects for specialty coffees like those produced in Boquete, Tierras Altas, and Renacimiento.
The proposed system represents a significant step toward the digital transformation of specialty coffee production through the use of science-based scalable technologies focused on the producer’s needs. Future plans include an application that interacts with the spectrometer, expanding the system to work with other regions and non-specialty coffee varieties. Additionally, predictive models will be developed and validated under diverse environmental conditions to identify various factors that can contribute to improving coffee quality.
Author Contributions
Conceptualization, E.E.C., M.E.J.-C. and C.A.R.; methodology, M.V.-B. and A.V.; validation, M.V.-B., J.C., and M.E.J.-C.; formal analysis, C.A.R. and A.V.; investigation, A.V., and M.E.J.-C.; data curation, C.A.R., J.C. and E.E.C.; writing—original draft preparation C.A.R.; writing—review and editing, E.E.C. and M.E.J.-C.; supervision, A.V. and E.E.C. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data presented in this study are available upon request from the corresponding author.
Acknowledgments
The authors would like to thank Best of Panama (BOP) for providing access to Q-Grader data standards, as well as the Ministry of Agricultural Development (MIDA) for their data regarding coffee producers. We also extend our gratitude to the staff at the Center for Research on Natural Resources (CIRN) at the Autonomous University of Chiriquí (UNACHI). Finally, we would like to recognize the National Research System of Panama (SNI) for their invaluable support and collaboration throughout this research project.
Conflicts of Interest
Author Jorge Centeno was employed by the Floppyfilms. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
References
- Fadli, F.; Baidhawi, B.; Adhiana, A. Analysis of Coffee Quality Control Based on Sca (Specialty Coffee Association) Standards on Arabica Coffee at Deputroe Coffe. Int. J. Econ. Agribisnis Dev. Stud. 2024, 1, 62–69. [Google Scholar] [CrossRef] [Scilit]
- Assa, A.; Loppies, J.; Amalia, A.; Indriana, D.; Mamang; Utami, R.; Ariyanti, M.; Winaldi, A. Chemical compounds and sensory characteristics of Arabica coffee (Coffea arabica) as a novel specialty coffee from Sinjai Regency, Indonesia. Food Res. 2021, 5, 107–112. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- E Loppies, J.; Assa, A.; Winanda, E.; Utami, R.R.; Amalia, A.N.; Rosniati; Smith, H.; Wahyudi, R. Physical quality and flavor profile of arabica coffee beans (Coffea arabica) from Seko, South Sulawesi as a specialty coffee. IOP Conf. Ser. Earth Environ. Sci. 2024, 1338, 012048. [Google Scholar] [CrossRef] [Scilit]
- Ramos, M.F.; Ribeiro, D.E.; Cirillo, M.Â.; Borém, F.M. Discrimination of the sensory quality of the Coffea arabica L. (cv. Yellow Bourbon) produced in different altitudes using decision trees obtained by the CHAID method. J. Sci. Food Agric. 2016, 96, 3543–3551. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Best of Panama Eauction—Specialty Coffee. 2025. Available online: https://bestofpanama.auction/ (accessed on 9 January 2026).
- Núñez, N.; Saurina, J.; Núñez, O. Liquid Chromatography–High-Resolution Mass Spectrometry (LC-HRMS) Fingerprinting and Chemometrics for Coffee Classification and Authentication. Molecules 2023, 29, 232. [Google Scholar] [CrossRef] [Scilit]
- Querme, M.E.T.; Lima, D.A. Traceability Automation in Coffee Production: A Case Study on QR Code Integration to Optimize Manual Steps. Arch. Adv. Eng. Sci. 2023, 2, 170–180. [Google Scholar] [CrossRef] [Scilit]
- Camacho, J.J.A.; Gómez, A.M.M.; Riaño, L.N.A. Traceability Architecture Technology for Short Commercial Exchange. In Proceedings of the International Conference on Industrial Engineering and Operations Management, Sao Paulo, Brazil, 5–8 April 2021; IEOM Society International: Southfield, MI, USA, 2021; pp. 2695–2708. [Google Scholar] [CrossRef] [Scilit]
- Tadesse, M.D.; Gebresenbet, G.; Ljungberg, D.; Tavasszy, L. Digital Traceability Capabilities: The Case of the Ethiopian Coffee Supply Chain. Future Transp. 2024, 4, 780–794. [Google Scholar] [CrossRef] [Scilit]
- ISO 220052007; [Online]. 2007. Available online: https://www.iso.org/obp/ui#iso:std:iso:22005:ed-1:v1:en (accessed on 16 January 2026).
- ISO 236352022; [Online]. 2022. Available online: https://www.iso.org/obp/ui/es/#iso:std:iso:ts:23635:ed-1:v1:en (accessed on 16 January 2026).
- Kule, E.K.; Kyohangirwe, A.; Midamba, D.C.; Byakatonda, J. Determinants of adoption of climate-smart agricultural technologies among smallholder coffee farmers in Western Uganda. Cogent Soc. Sci. 2025, 11, 2588856. [Google Scholar] [CrossRef] [Scilit]
- Jakkaew, P.; Yingchutrakul, Y.; Aunsri, N. A data-driven approach to improve coffee drying: Combining environmental sensors and chemical analysis. PLoS ONE 2024, 19, e0296526. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Chiang, W.-Y. Using a data-driven marketing strategy on customer relationship management: An empirical case of urban coffee shops in Taiwan. Br. Food J. 2021, 123, 1610–1625. [Google Scholar] [CrossRef] [Scilit]
- Joel, O.T.; Oguanobi, V.U. Data-driven strategies for business expansion: Utilizing predictive analytics for enhanced profitability and opportunity identification. Int. J. Front. Eng. Technol. Res. 2024, 6, 071–081. [Google Scholar] [CrossRef] [Scilit]
- Sott, M.K.; Furstenau, L.B.; Kipper, L.M.; Giraldo, F.D.; Lopez-Robles, J.R.; Cobo, M.J.; Zahid, A.; Abbasi, Q.H.; Imran, M.A. Precision Techniques and Agriculture 4.0 Technologies to Promote Sustainability in the Coffee Sector: State of the Art, Challenges and Future Trends. IEEE Access 2020, 8, 149854–149867. [Google Scholar] [CrossRef] [Scilit]
- Montoya-Munoz, A.I.; Rendon, O.M.C. An Approach Based on Fog Computing for Providing Reliability in IoT Data Collection: A Case Study in a Colombian Coffee Smart Farm. Appl. Sci. 2020, 10, 8904. [Google Scholar] [CrossRef] [Scilit]
- Hong, S.; Park, S.; Youn, H.; Lee, J.; Kwon, S. Implementation of Smart Farm Systems Based on Fog Computing in Artificial Intelligence of Things Environments. Sensors 2024, 24, 6689. [Google Scholar] [CrossRef] [Scilit]
- Bahri, T.S.; Manyamsari, I.; Putri, R.J.; Iskandar, E. Technology needs assessment for the development of smart coffee production in Aceh, Indonesia. IOP Conf. Ser. Earth Environ. Sci. 2024, 1290, 012053. [Google Scholar] [CrossRef] [Scilit]
- Muñoz-Belalcazar, J.A.; Benavides-Cardona, C.A.; Lagos-Burbano, T.C.; Criollo-Velázquez, C.P. Manejo agronómico sobre el rendimiento y la calidad de café (Coffea arabica) variedad Castillo en Nariño, Colombia. Agron. Mesoam. 2021, 32, 750–763. [Google Scholar] [CrossRef] [Scilit]
- Hernández-Salazar, C.A.; González-Estrada, O.A.; González-Silva, G. Integración de la inteligencia artificial y la agricultura de precisión en cultivos de café. Rev. UIS Ing. 2024, 23, 145–158. [Google Scholar] [CrossRef] [Scilit]
- Rojas-Ruiz, R.; Alvarado-Huamán, L.; Borjas-Ventura, R.; Torres, E.C.; Castro-Cepero, V.; Julca-Otiniano, A. Caracterización de Fincas Productoras de Café Convencional y Orgánico en el Valle del Alto Mayo, Región San Martín, Perú. Rev. Investig. Innovación Agropecu. Recur. Nat. 2020, 7, 100–111. [Google Scholar]
- Wulandari, S.; Ferry, Y. Strategies on technology management for coffee smallholder to promote the smart farming implementation. IOP Conf. Ser. Earth Environ. Sci. 2021, 759, 012057. [Google Scholar] [CrossRef] [Scilit]
- Vega, A.; De León, J.A.; Reyes, S.M.; Gallardo, J.M. Modelo matemático para determinar la correlación entre parámetros fisicoquímicos y la calidad sensorial de café Geisha y Pacamara de Panamá. Inf. Tecnológica 2021, 32, 89–100. [Google Scholar] [CrossRef] [Scilit]
- Vega, A.; Reyes, S.M.; Troestch, J. Physicochemical Parameters and Multivariate Analysis to Predict the Sensory Quality in Specialty Coffee from Panama. ACS Omega 2025, 10, 13251–13259. [Google Scholar] [CrossRef] [Scilit]
- Vega, A.; Reyes, S.; León, J.D.; Bonilla, A. Cuantificación de Cafeína en Cafés Comerciales de Panamá. Cienc. Tecnol. 2014, 30, 57–64. [Google Scholar]
- Trigoso, J.-A.C.; Valderrama, N.L.M.; Trujillo, P.-A.R.; Rosero, L.M.G. Sostenibilidad del café: Revisión sistemática de la literatura. Rev. Venez. Gerenc. 2021, 26, 943–961. [Google Scholar] [CrossRef] [Scilit]
- Bahri, T.S.; Nasution, I.S.; Iskandar, E. The study of smart farming for the sustainable coffee plantation. IOP Conf. Ser. Earth Environ. Sci. 2025, 1510, 012051. [Google Scholar] [CrossRef] [Scilit]
- Pradhana, A.A.S.; Kotama, I.N.D. Mobile Application Development for Robusta Coffee Planting Cycle Mapping and Recording as Part of an Initiative to Revitalize Smart-Agriculture Technology. Inform. Dan Sains 2023, 13, 598–603. [Google Scholar]
- Abreu, M.B.; Marcheafave, G.G.; Bruns, R.E.; Scarminio, I.S.; Zeraik, M.L. Spectroscopic and Chromatographic Fingerprints for Discrimination of Specialty and Traditional Coffees by Integrated Chemometric Methods. Food Anal. Methods 2020, 13, 2204–2212. [Google Scholar] [CrossRef] [Scilit]
- Specialty Coffee Panama. [Online]. Available online: https://scap-panama.com (accessed on 3 January 2026).
- Gómez, C.R. Determination of chemical compounds of roasted coffee by Near-Infrared Spectroscopy (NIRS). Cenicafé 2023, 73, e73103. Available online: https://publicaciones.cenicafe.org/index.php/cenicafe/article/view/361/Description (accessed on 7 January 2026). [CrossRef] [Scilit]
- Gamboa, J.P.Z.; Arreaga, C.A.L. Evolución de las Metodologías y Modelos utilizados en el Desarrollo de Software. INNOVA Res. J. 2018, 3, 20–33. [Google Scholar] [CrossRef] [Scilit]
- Hema, V.; Thota, S.; Kumar, S.N.; Padmaja, C.; Krishna, C.B.R.; Mahender, K. Scrum: An Effective Software Development Agile Tool. IOP Conf. Ser. Mater. Sci. Eng. 2020, 981, 022060. [Google Scholar] [CrossRef] [Scilit]
- Pargaonkar, S. A Comprehensive Research Analysis of Software Development Life Cycle (SDLC) Agile & Waterfall Model Advantages, Disadvantages, and Application Suitability in Software Quality Engineering. Int. J. Sci. Res. Publ. 2023, 13, 120–124. [Google Scholar] [CrossRef] [Scilit]
- Heiliö, M.; Lähivaara, T.; Laitinen, E.; Mantere, T.; Merikoski, J.; Pohjolainen, S.; Raivio, K.; Silvennoinen, R.; Suutala, A.; Tarvainen, T.; et al. Mathematical Modelling; Pohjolainen, S., et al., Eds.; Springer: Cham, Switzerland, 2016. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.