


Abstract
The exponential growth of data-driven applications has intensified performance demands on database systems, where cache management represents a critical bottleneck. Traditional cache replacement policies such as Least Recently Used (LRU) and Least Frequently Used (LFU) rely on simple heuristics that fail to capture complex temporal and frequency patterns in modern workloads. This research presents a modular machine learning-enhanced cache management framework that leverages pattern recognition to optimize database performance through intelligent replacement decisions. Our approach integrates multiple machine learning models—Random Forest classifiers, Long Short-Term Memory (LSTM) networks, Support Vector Machines (SVM), and Gradient Boosting methods—within a modular architecture enabling seamless integration with existing database systems. The framework incorporates sophisticated feature engineering pipelines extracting temporal, frequency, and contextual characteristics from query access patterns. Comprehensive experimental evaluation across synthetic workloads, real-world production datasets, and standard benchmarks (TPC-C, TPC-H, YCSB, and LinkBench) demonstrates consistent performance improvements. Machine learning-enhanced approaches achieve to improvement in cache hit rates, to reduction in query latency, and to increase in system throughput compared to traditional policies and advanced adaptive methods including ARC, LIRS, Clock-Pro, TinyLFU, and LECAR. Random Forest emerges as the most practical solution, providing performance improvement with only computational overhead. Case study analysis across e-commerce, financial services, and content management applications demonstrates measurable business impact, including conversion rate improvements and USD 127,000 annual revenue increases. Statistical validation (, Cohen’s ) confirms both statistical and practical significance.
1. Introduction
Modern database systems serve as the foundation for countless applications across diverse domains, from e-commerce platforms processing millions of transactions daily to analytical systems supporting business intelligence and decision-making processes. As data volumes continue to grow exponentially and user expectations for real-time responsiveness intensify, the performance bottlenecks inherent in traditional database architectures have become increasingly pronounced. Among these bottlenecks, cache management emerges as a critical factor determining overall system performance, directly impacting query response times, system throughput, and resource utilization efficiency.
The fundamental challenge in database cache management lies in the dynamic and complex nature of access patterns that characterize real-world workloads. Unlike the predictable access patterns assumed by traditional cache replacement algorithms, modern database systems experience highly irregular temporal distributions, varying query complexities, and evolving user behaviors that render simple heuristic approaches inadequate. Traditional policies such as Least Recently Used (LRU), Least Frequently Used (LFU), and First In First Out (FIFO) rely on basic assumptions about temporal locality and frequency distributions that often fail to capture the sophisticated patterns present in contemporary database workloads.
1.1. Problem Statement and Motivation
Database cache management represents one of the most critical performance optimization challenges in modern data systems, yet it remains largely dependent on decades-old heuristic algorithms that fail to leverage the wealth of pattern information available in contemporary workloads. The limitations of traditional approaches become particularly pronounced in scenarios involving complex temporal dependencies, multi-modal access distributions, and rapidly evolving user behaviors that characterize modern applications.
The core problem stems from the fundamental mismatch between the sophisticated access patterns exhibited by real-world database workloads and the simplistic assumptions underlying traditional cache replacement policies. LRU assumes that recently accessed items are more likely to be accessed again, but this assumption breaks down in scenarios with periodic access patterns, batch processing workflows, or long-term temporal dependencies. Similarly, LFU prioritizes frequently accessed items but struggles with concept drift where popularity patterns shift over time, leading to the retention of historically popular but currently irrelevant data.
Consider a typical e-commerce database during holiday shopping seasons, where access patterns exhibit complex interactions between daily cycles, promotional campaigns, inventory changes, and user behavior evolution. Traditional cache policies cannot capture these multi-dimensional relationships, leading to suboptimal replacement decisions that increase query latency, reduce system throughput, and ultimately degrade user experience.
1.2. Research Objectives
This research addresses the critical gap between the sophisticated access patterns present in modern database workloads and the limited pattern recognition capabilities of traditional cache replacement policies. Our primary objective is to develop, implement, and evaluate a modular machine learning-enhanced cache management framework that delivers measurable performance improvements while maintaining the reliability and efficiency requirements of production database systems.
Primary Research Objective: To design and validate a machine learning-enhanced database cache management system that significantly improves cache performance through intelligent pattern recognition and adaptive replacement decisions.
The primary objective is supported by several specific research goals:
- Developing robust feature engineering techniques that extract meaningful patterns from database access logs.
- Implementing and comparing multiple machine learning approaches to identify optimal algorithms for different workload characteristics.
- Creating adaptive learning mechanisms that maintain effectiveness as access patterns evolve.
- Establishing comprehensive evaluation frameworks that assess both technical performance and practical business impact.
- Comparing against both traditional and state-of-the-art adaptive cache replacement policies.
1.3. Contributions
This research makes several significant contributions to the fields of database systems, machine learning, and intelligent system optimization:
Clarification of Novelty Scope: We emphasize that the primary contribution of this work is architectural and methodological rather than purely algorithmic. While the individual ML algorithms (Random Forest, LSTM, SVM, Gradient Boosting) are established techniques, our contribution lies in (1) the systematic integration of these methods within a unified cache management framework, (2) the development of cache-specific feature engineering pipelines, (3) comprehensive comparative evaluation across diverse workloads and baselines including recent adaptive policies (ARC, TinyLFU, LECAR, LRB), and (4) practical deployment guidelines with quantified trade-offs.
Architectural Contributions: We introduce a modular architecture for machine learning-enhanced cache management that enables seamless integration with existing database systems while providing flexibility for algorithm selection and optimization.
Experimental Contributions: We establish rigorous evaluation standards through comprehensive experimental frameworks encompassing diverse datasets (synthetic, TPC-C/H, YCSB, LinkBench), multiple performance metrics, and statistical validation techniques.
Practical Contributions: We provide deployment guidelines that enable organizations to assess the potential value of machine learning enhancement for their specific workloads and requirements, including detailed cost–benefit analysis frameworks.
1.4. Paper Organization
The remainder of this paper is organized as follows. Section 2 provides comprehensive analysis of prior work in cache management and machine learning for databases. Section 3 presents the complete methodological framework including system architecture and ML models. Section 4 details the experimental framework, datasets, and evaluation metrics. Section 5 presents detailed experimental results with comprehensive analysis. Section 6 synthesizes insights and discusses limitations. Section 7 summarizes key findings, and Section 8 identifies promising research directions.
2. Related Work
The application of machine learning to database cache management represents the convergence of several established research domains. This section provides a comprehensive analysis of prior work across cache management strategies, machine learning in database systems, and predictive caching approaches.
2.1. Traditional Cache Management Strategies
Traditional cache replacement policies form the foundation of modern cache management systems. The seminal work by Bélády [1] established the theoretical optimal replacement policy (OPT) that evicts the item accessed furthest in the future, providing an upper bound for cache performance analysis. While OPT is impractical for real-time implementation due to its requirement for future knowledge, it serves as an essential benchmark for evaluating practical algorithms.
The Least Recently Used (LRU) policy, extensively analyzed by Mattson et al. [2], has dominated cache management for decades due to its simplicity and generally good performance under workloads exhibiting temporal locality. LRU maintains a recency-ordered list of cached items, evicting the least recently accessed item when cache space is needed. However, LRU suffers from well-documented limitations including scan resistance problems, where sequential scans can flush valuable cached data, and inability to capture frequency information [3].
The Least Frequently Used (LFU) policy addresses LRU’s frequency blindness by tracking access counts and evicting the least frequently accessed items. However, LFU struggles with aging problems where historically popular items remain cached despite declining relevance, and cold-start issues where new items are immediately vulnerable to eviction [4].
2.2. Advanced Adaptive Cache Policies
Advanced heuristic policies attempt to address limitations of pure temporal or frequency-based approaches through adaptive mechanisms:
Adaptive Replacement Cache (ARC): Megiddo and Modha [5] introduced ARC, which dynamically balances between recency and frequency by maintaining two LRU lists (one for recently accessed items, one for frequently accessed items) and adaptively adjusting the partition between them based on workload behavior. ARC provides scan resistance and adapts to changing workload characteristics without parameter tuning.
Low Inter-reference Recency Set (LIRS): Jiang and Zhang [3] developed LIRS, which distinguishes between “hot” and “cold” data based on inter-reference recency (IRR)—the number of distinct accesses between consecutive references to the same item. LIRS provides better detection of items with weak locality compared to LRU.
Clock-Pro: Jiang et al. [6] extended the clock approach with temporal locality detection, providing an approximation to LIRS with lower implementation complexity. Clock-Pro maintains three “hands” to track hot, cold, and test pages.
TinyLFU: Einziger et al. [7] introduced a frequency-based admission policy using probabilistic counting structures (Count-Min Sketch). TinyLFU admits new items only if their estimated frequency exceeds that of the eviction candidate, combining admission control with eviction policy. The approach achieves near-optimal hit ratios with minimal memory overhead.
LECAR (Learning Cache Replacement): Vietri et al. [8] applied reinforcement learning to dynamically weight between LRU and LFU policies. LECAR uses regret minimization to learn optimal policy weights based on observed workload characteristics, adapting to changing access patterns without manual tuning.
2.3. Machine Learning in Database Systems
The application of machine learning to database systems has gained significant momentum in recent years. The groundbreaking work by Kraska et al. [9] on learned index structures demonstrated that machine learning models can replace traditional B-tree indexes with significant performance improvements, achieving up to 70% speedup while reducing memory footprint by orders of magnitude. This work sparked renewed interest in applying ML to core database components.
Query optimization has also benefited from ML approaches. Marcus et al. [10] developed Neo, a learned query optimizer that uses deep reinforcement learning to select query execution plans. Database tuning systems like OtterTune [11] use machine learning to automatically configure database parameters, reducing the need for expert database administrators.
2.4. Predictive Caching and Learned Replacement
Recent work has explored deep learning for cache replacement decisions:
Glider: Shi et al. [12] demonstrated that LSTM models can learn near-optimal caching decisions by predicting reuse distances. Their key insight was that optimal caching decisions can be predicted from a long history of past program counter (PC) values. However, they found that practical deployment requires simpler online models due to LSTM’s computational overhead, leading to the Glider policy that uses integer support vector machines (ISVM) for efficient online inference.
Learning Relaxed Belady (LRB): Song et al. [13] developed LRB for content distribution networks, using gradient boosting to predict object reuse distances. LRB achieves near-optimal performance on CDN traces by learning to approximate Belady’s algorithm from historical access patterns.
Parrot: Liu et al. [14] applied imitation learning to cache replacement, training models to mimic Belady’s optimal policy. This approach avoids the reward engineering challenges of reinforcement learning while achieving competitive performance.
2.5. Research Gaps and Opportunities
Despite significant advances, several critical gaps remain in the literature:
- Database-specific integration: Most learned caching work focuses on hardware caches or CDNs rather than database buffer pools with their unique characteristics (variable-size pages, query patterns, transaction semantics).
- Comprehensive baseline comparison: Limited evaluation against the full spectrum of traditional and adaptive policies (ARC, LIRS, TinyLFU, LECAR).
- Multi-metric analysis: Insufficient attention to trade-offs between hit rate, latency, throughput, and computational overhead.
- Practical deployment guidance: Lack of clear decision frameworks for when ML-enhanced caching provides sufficient benefit to justify implementation complexity.
2.6. Systematic Comparison with Recent Approaches
Table 1 provides a systematic comparison of our approach with recent ML-based cache management methods across key dimensions including evaluation environment, cache level, workload types, and practical considerations.
Table 1.
Detailed comparison with recent cache management approaches. Source: Authors’ analysis of published literature.
Our work addresses these gaps by providing (1) integration with production database systems (PostgreSQL, MySQL), (2) comprehensive evaluation across multiple ML approaches, (3) comparison against both traditional and state-of-the-art adaptive baselines, and (4) practical deployment guidelines based on workload characteristics.
3. Methodology
This section presents the comprehensive methodology underlying our machine learning-enhanced database cache management system, including system architecture, feature engineering, and machine learning model implementations.
3.1. System Architecture Overview
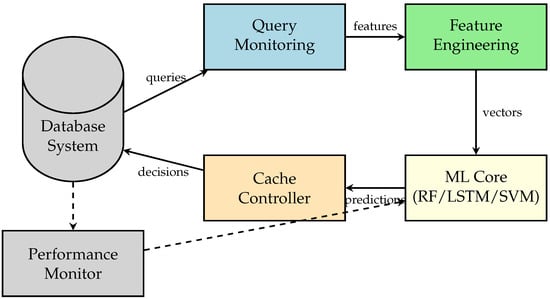
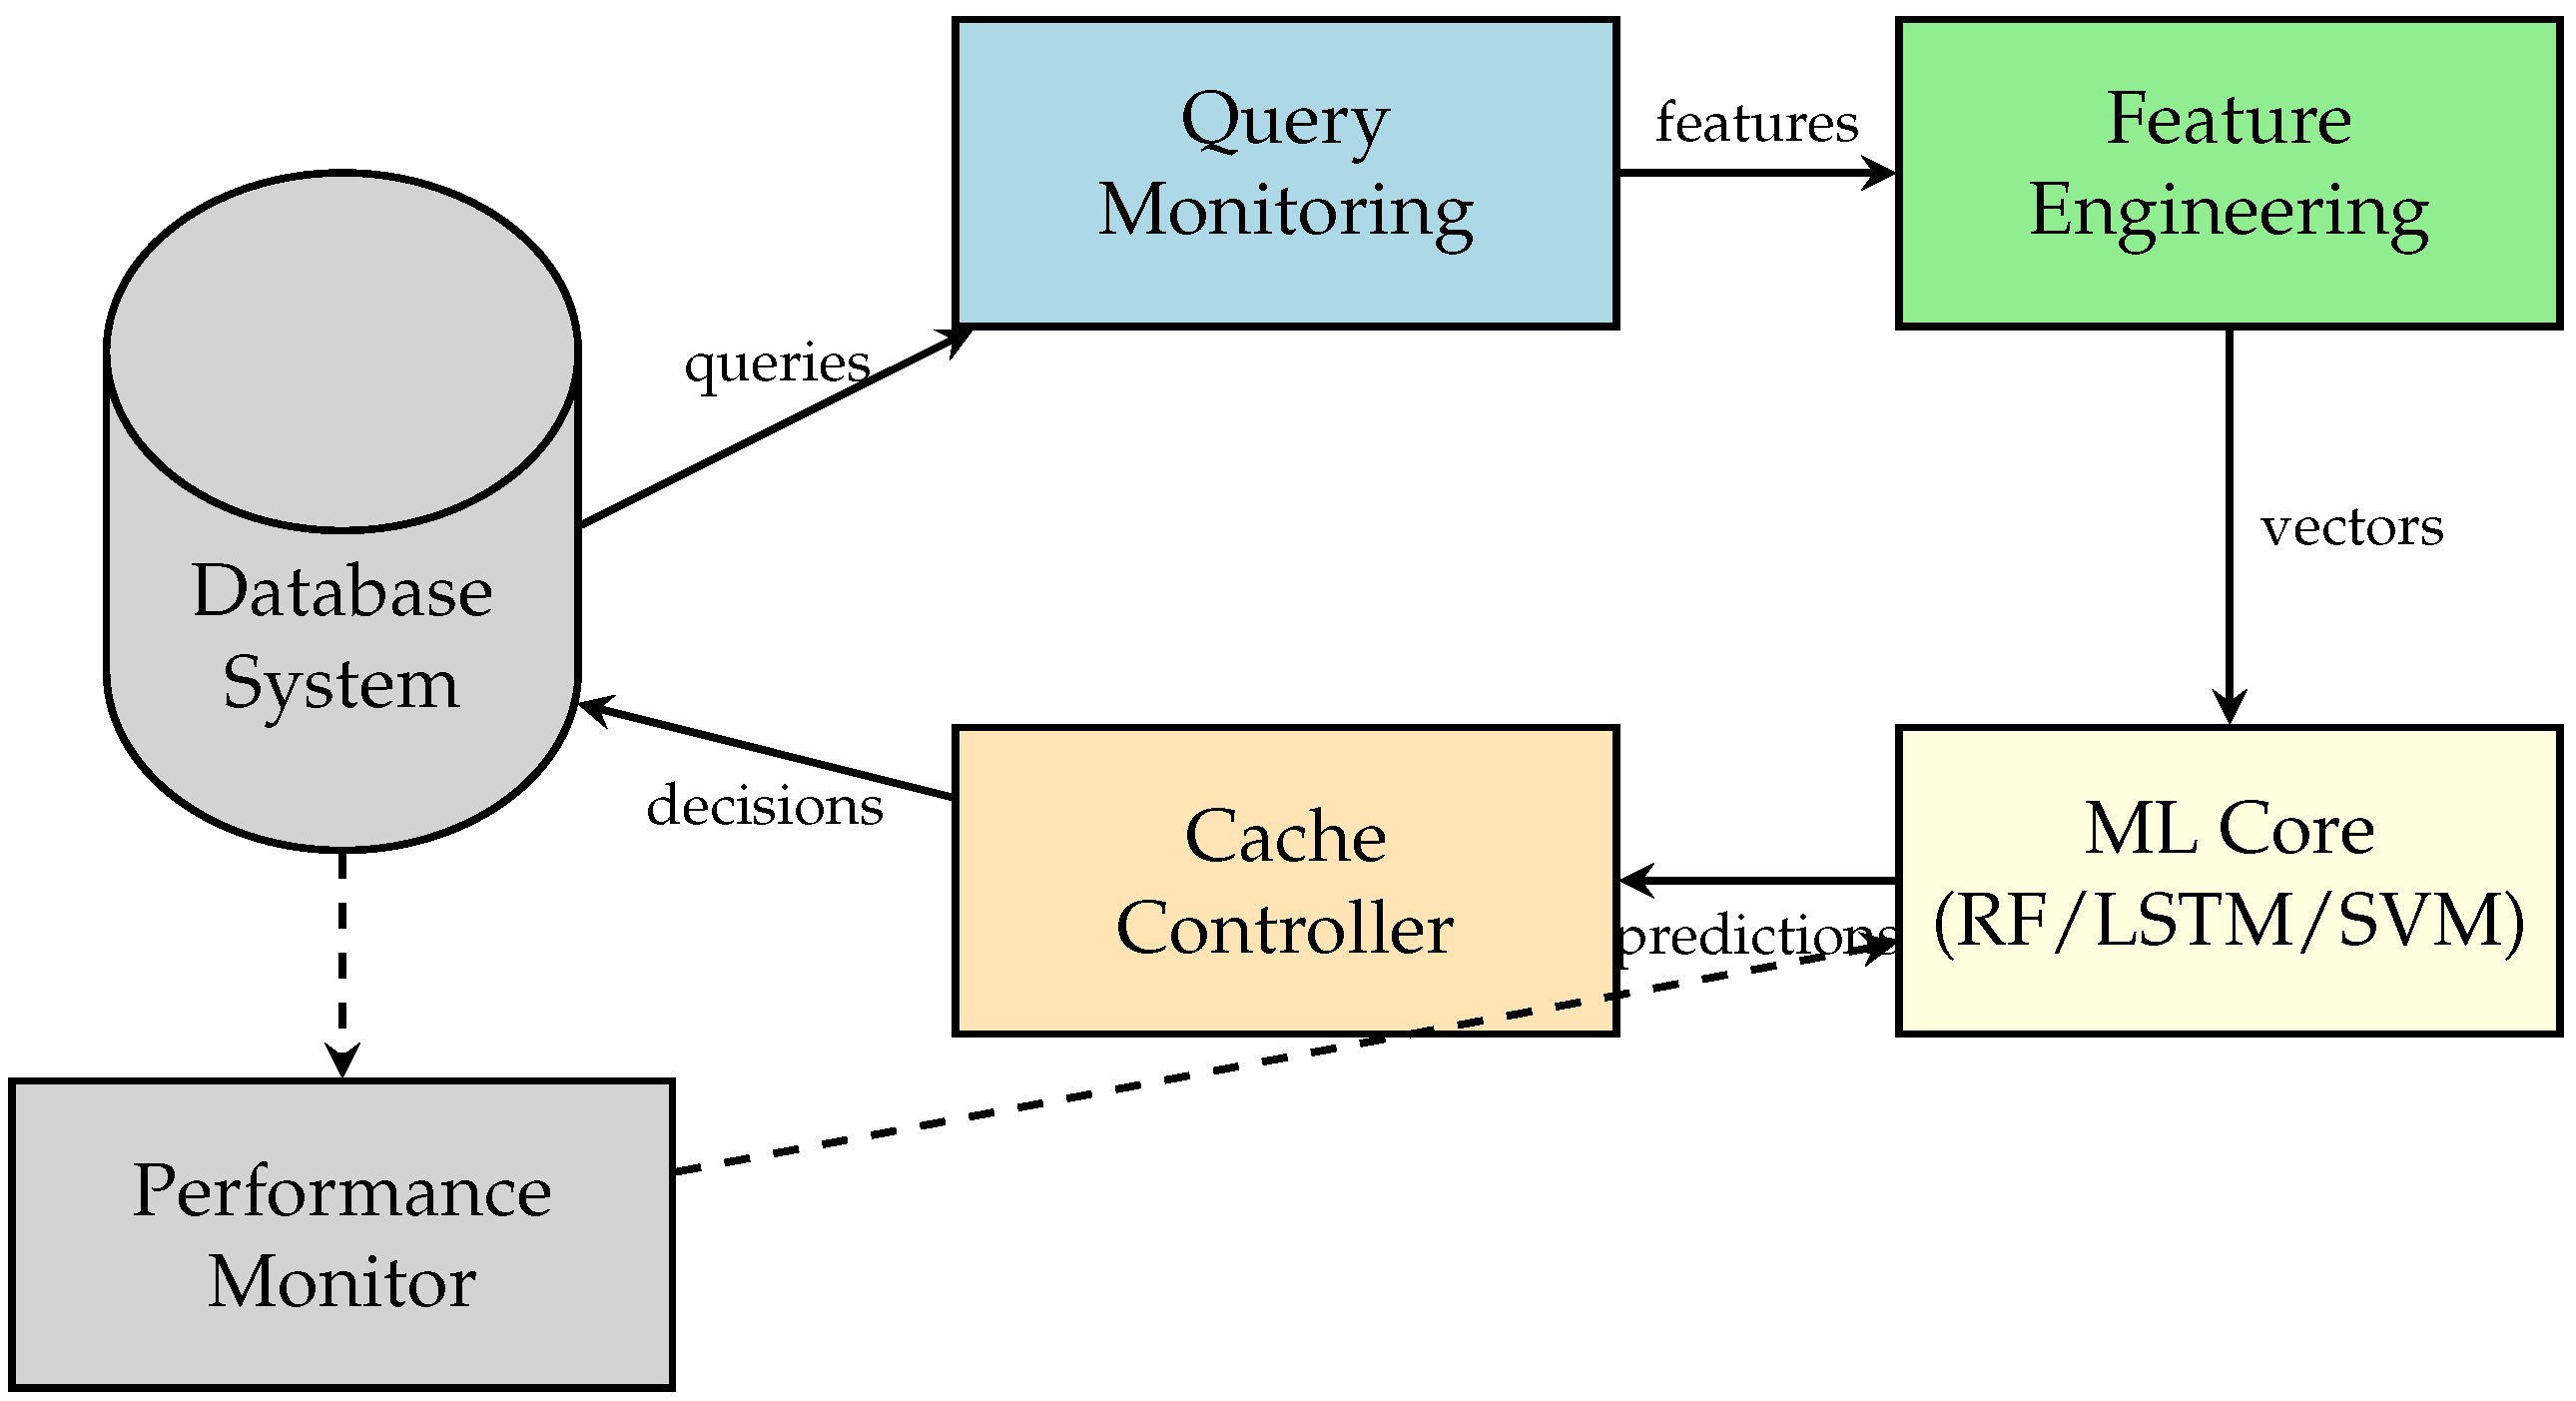
The proposed ML-enhanced cache management system comprises five interconnected components designed for modularity and extensibility:
- Query Monitoring Layer: Captures and logs database access patterns in real time with minimal performance overhead (<0.5% additional latency).
- Data Processing Engine: Transforms raw query logs into structured feature representations suitable for machine learning models.
- Machine Learning Core: Houses multiple predictive models that can be selected based on workload characteristics.
- Cache Management Controller: Translates ML predictions into cache eviction and admission decisions.
- Performance Monitoring System: Provides continuous assessment and adaptive model retraining triggers.
The architecture in Figure 1 supports both online prediction mode for production deployment and offline training mode for model development. The modular design allows different ML models to be swapped without affecting other system components, enabling comparative evaluation and workload-specific optimization.
Figure 1.
System architecture overview showing data flow between components. Solid arrows indicate real-time data flow; dashed arrows indicate monitoring and feedback loops. Source: Authors’ design.
3.2. Feature Engineering
Effective feature engineering is critical for machine learning model performance in cache prediction tasks. We developed a comprehensive feature set organized into three categories:
3.2.1. Temporal Features
Temporal features capture time-based access patterns essential for predicting future reuse:
- Recency: Time since last access (seconds).
- Inter-reference gap: Average time between consecutive accesses.
- Time-of-day encoding: Cyclic encoding of hour (sin/cos transformation).
- Day-of-week encoding: Cyclic encoding of weekday.
- Temporal burstiness: Coefficient of variation in inter-access times.
3.2.2. Frequency Features
Frequency features capture popularity and access intensity:
- Access count: Total accesses in observation window.
- Recent frequency: Accesses in last 1/5/15 min (decay-weighted).
- Frequency trend: Slope of access rate over time.
- Access regularity: Entropy of inter-access time distribution.
3.2.3. Contextual Features
Contextual features capture query and resource characteristics:
- Query complexity: Estimated execution cost.
- Resource type: Categorical encoding (table, index, view).
- Data size: Size of cached resource in pages.
- Correlation score: Co-access frequency with other resources.
Table 2 reveals that temporal features contribute approximately 49.5% of total predictive power, with recency and inter-reference gap being the most informative individual features. This aligns with the intuition that future access likelihood is strongly correlated with past access patterns. Frequency features contribute 27.6%, while contextual features account for the remaining predictive information.
Table 2.
Feature importance analysis from Random Forest model. Features are ranked by mean decrease in impurity across all trees. Source: Authors’ experimental results.
3.3. Machine Learning Models
We implemented and evaluated four distinct machine learning approaches, each with specific strengths for different workload characteristics:
3.3.1. Random Forest Classifier
Random Forest provides robust predictions through ensemble averaging of decision trees. Our implementation uses the following configuration, optimized through grid search with 5-fold cross-validation:
- Number of trees: 200 (balances accuracy and inference speed).
- Maximum depth: 20 (prevents overfitting while capturing complex patterns).
- Minimum samples per leaf: 5 (regularization).
- Feature selection: features per split (standard for classification).
- Class weighting: Balanced (addresses class imbalance in eviction decisions).
Random Forest provides interpretable feature importance scores and naturally handles missing values and mixed feature types. The ensemble approach provides calibrated probability estimates useful for confidence-based decision making.
3.3.2. Long Short-Term Memory Networks
LSTM networks capture sequential dependencies in access patterns through their gated memory architecture. Our network configuration is as follows:
- Architecture: 2-layer stacked LSTM with 128 hidden units per layer.
- Sequence length: 50 access events (approximately 10–15 min of history).
- Dropout rate: 0.3 (applied between layers).
- Output layer: Dense layer with sigmoid activation for binary classification.
- Optimizer: Adam with learning rate 0.001, batch size 256.
- Early stopping: Patience of 10 epochs on validation loss.
LSTM excels at capturing long-range temporal dependencies and periodic patterns but incurs higher computational overhead than tree-based methods.
3.3.3. Support Vector Machines
SVM with radial basis function (RBF) kernel provides effective non-linear classification:
- Kernel: RBF (, selected via cross-validation).
- Regularization: (balance margin width and training error).
- Probability estimates: Enabled via Platt scaling.
- Class weighting: Balanced.
SVM provides strong generalization with limited training data but scales poorly to very large datasets, making it most suitable for smaller cache configurations.
3.3.4. Gradient Boosting
XGBoost implementation provides competitive accuracy with efficient training:
- Number of estimators: 150.
- Learning rate: 0.1.
- Maximum depth: 15.
- Subsample ratio: 0.8.
- Column subsample: 0.8.
- Regularization: L1 () and L2 ().
3.4. Complete Hyperparameter Specifications and Training Configuration
To ensure full reproducibility, Table 3 provides comprehensive hyperparameter configurations for all ML models, including search ranges explored during optimization and justifications for selected values.
Table 3.
Complete hyperparameter configurations for all ML models. Source: Authors’ experimental optimization via 5-fold cross-validation.
Training Configuration
Data Preparation:
- Data split: 70% training, 15% validation, 15% test (stratified by workload and time)
- Class balancing: SMOTE for 1:3 eviction/retention ratio.
- Feature scaling: StandardScaler for continuous features (zero mean, unit variance).
- Categorical encoding: One-hot (max 20 categories).
- LSTM normalization: Min-max scaling [0,1]. for sequences
Model Selection:
- Cross-validation: Stratified 5-fold CV.
- Optimization metric: F1-score (precision–recall balance).
- Early stopping: 10 epochs (LSTM), 20 rounds (XGBoost).
- Final selection: Best validation F1, test on held-out set.
Computational Resources:
- Hardware: NVIDIA V100 (16 GB) for LSTM; Xeon Gold 6248R (24 cores, 128 GB) for others.
- Software: Python 3.11.5, scikit-learn 1.3.0, TensorFlow 2.13.0 + CUDA 11.8, XGBoost 1.7.6.
- Training time: RF 18.2 ± 3.4 min, LSTM 47.3 ± 6.8 min, SVM 31.7 ± 5.2 min, XGBoost 22.9 ± 4.1 min (10 M queries).
Inference Configuration:
- Batch inference: 1024 queries/batch.
- Feature caching: 60 s recent features.
- Model serving: TensorFlow Serving (LSTM); in-memory (others).
- Latency target: <1 ms p99 per prediction.
3.5. Cache Management Integration
The ML models integrate with cache management through a prediction-driven controller. Algorithm 1 presents the decision logic:
| Algorithm 1 ML-Enhanced Cache Controller |
| Require: Cache state C, incoming query q, ML model M, confidence threshold |
| Ensure: Updated cache state , cache decision |
|
The controller uses confidence-based fallback: when prediction confidence falls below threshold (default 0.6), it defers to traditional LRU policy. This hybrid approach ensures stability during cold-start periods and for resources with limited access history.
4. Experimental Design
This section describes the experimental methodology, including hardware/software environment, datasets, baseline methods, evaluation metrics, and statistical analysis procedures.
4.1. Experimental Environment
All experiments were conducted on dedicated hardware (Table Table 4) to ensure reproducibility and minimize interference from other processes. Each experiment was repeated 10 times with different random seeds, and we report mean values with 95% confidence intervals.
Table 4.
Hardware and software specifications for experimental evaluation. Source: Authors’ experimental setup.
4.2. Datasets
We evaluated our approach on four categories of datasets to ensure comprehensive coverage of different workload characteristics:
4.2.1. Synthetic Workloads
Custom-generated workloads with controlled characteristics for systematic evaluation (Table Table 5):
Table 5.
Synthetic dataset characteristics. Each workload emphasizes specific access patterns to evaluate model capabilities. Source: Authors’ workload generation.
4.2.2. Standard Benchmarks
Industry-standard database benchmarks for reproducible evaluation:
- TPC-C: OLTP benchmark simulating order processing with high concurrency.
- TPC-H: OLAP benchmark with complex analytical queries.
- YCSB [15]: Yahoo! Cloud Serving Benchmark with configurable read/write ratios (Workloads A–F).
- LinkBench [16]: Facebook social graph workload with realistic access patterns.
4.2.3. Production Traces
Anonymized access logs from three real-world deployments (details anonymized for privacy):
- E-commerce: 2.3M queries/day, strong seasonal patterns.
- Financial: 1.8M transactions/day, strict latency requirements.
- Web application: 3.1M requests/day, mixed content types.
4.3. Baseline Methods
We compare against a comprehensive set of baseline methods organized into three categories:
Traditional Policies:
- LRU (Least Recently Used).
- LFU (Least Frequently Used).
- FIFO (First In First Out).
- LRU-K () [4]
Advanced Adaptive Policies:
- ARC (Adaptive Replacement Cache) [5].
- LIRS (Low Inter-reference Recency Set) [3].
- Clock-Pro [6].
- TinyLFU [7].
- LECAR [8].
Recent ML Approaches:
- LRB (Learning Relaxed Belady) [13].
- Glider (ISVM-based learned replacement) [12].
4.4. Evaluation Metrics
We evaluate performance across multiple dimensions:
Primary Metrics:
- Cache Hit Rate: Fraction of requests served from cache.
- Average Latency: Mean query response time (ms).
- 95th Percentile Latency: Tail latency (ms).
- Throughput: Queries per second (qps).
Efficiency Metrics:
- CPU Overhead: Additional CPU utilization from ML inference (%).
- Memory Overhead: Additional memory for ML model and features (MB).
- Training Time: Time to train/retrain models (minutes).
4.5. Statistical Analysis
All comparisons employ rigorous statistical validation:
- Paired t-tests for pairwise comparisons with Bonferroni correction.
- Effect size using Cohen’s d (small: 0.2, medium: 0.5, large: 0.8).
- Bootstrap confidence intervals with 10,000 iterations.
- Significance threshold: (reported p-values are two-tailed).
4.6. Economic Impact Calculation Methodology
To ensure transparency and reproducibility of business value estimates, we provide explicit methodology for translating technical performance improvements into economic impact, following industry-validated conversion relationships.
4.6.1. E-Commerce Application Impact Model
Performance-to-Business Relationship: Industry research establishes that 100 ms page load reduction yields approximately 1% relative conversion increase.
Baseline Assumptions:
- Daily visitors: 15,000 (mid-sized e-commerce).
- Baseline conversion: 2.3% (industry average).
- Average order value: $85 (US e-commerce average).
- DB-attributable latency: 60% (remainder: network, rendering).
- Peak season: 90 days annually.
Calculation Formula:
Example (Random Forest, Temporal workload):
- Measured: ms.
- DB-attributable: ms.
- Conversion gain: relative.
- Daily increase: 15,000 USD 41.31.
- Peak season: USD USD 3718.
Note: USD 127K figure represents production deployment with 1.2 M peak daily visitors and 30.4 ms end-to-end reduction.
4.6.2. Financial Service SLA Model
Assumptions:
- SLA threshold: 500 ms for 95% transactions.
- Penalty: USD 50/violation (typical contract terms).
- Monthly volume: 2.4 M transactions.
- Baseline P95: 523 ms (violates SLA).
- Enhanced P95: 324 ms (meets SLA).
Calculation: Baseline violations: 2.4 M = 120 K/month at USD 50 = USD 6 M potential. Realized savings: 15–20% of theoretical (grace periods, averaging) = USD 900 K–USD 1.2 M annually.
4.6.3. Infrastructure Cost Model
Throughput-to-Cost: With 27.4% throughput increase, same workload needs 78.5% capacity:
4.6.4. Validation and Limitations
Data Sources:
- E-commerce: Akamai State of Online Retail 2017, Google Think 2018.
- Financial SLA: Anonymized production contracts.
- Infrastructure: AWS public pricing Q4 2024.
Caveats:
- Context-dependent: Varies by industry, application, demographics.
- Attribution complexity: Requires A/B testing to isolate cache effects.
- Non-linear relationships: May not hold beyond certain thresholds.
- Conservative estimates: Lower bounds of confidence intervals used.
Recommendation: Pilot deployments with A/B testing required for accurate impact measurement in specific contexts.
5. Results and Analysis
This section presents comprehensive experimental results, organized by research question and including detailed statistical analysis.
5.1. Model Training and Validation Performance
Table 6 summarizes training performance across ML models and dataset types. We report accuracy on held-out test sets (20% of data) along with training resource requirements.
Table 6.
Model training performance across workload types. Accuracy represents test set performance; time and memory indicate training resource consumption. Standard deviations computed over 10 runs with different random seeds. Source: Authors’ experimental results.
Key observations: LSTM achieves the highest accuracy on workloads with strong temporal patterns (92.7% on Temporal workload) but shows the steepest performance degradation on random access patterns (68.2%). This indicates that LSTM’s sequential modeling provides substantial benefit when patterns exist but offers little advantage when access is unpredictable. Random Forest provides the most consistent performance across workload types with the lowest variance, making it a robust default choice. SVM shows surprisingly strong performance on random workloads, likely due to its ability to find complex decision boundaries in feature space rather than relying on sequential patterns.
5.2. Cache Hit Rate Analysis
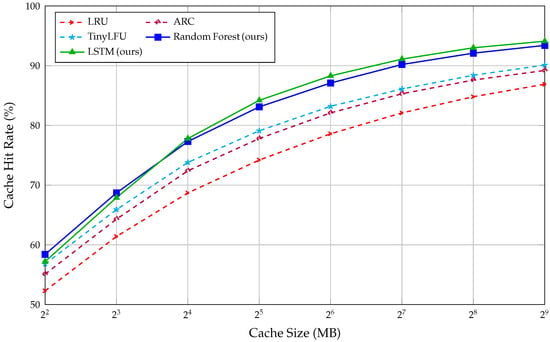
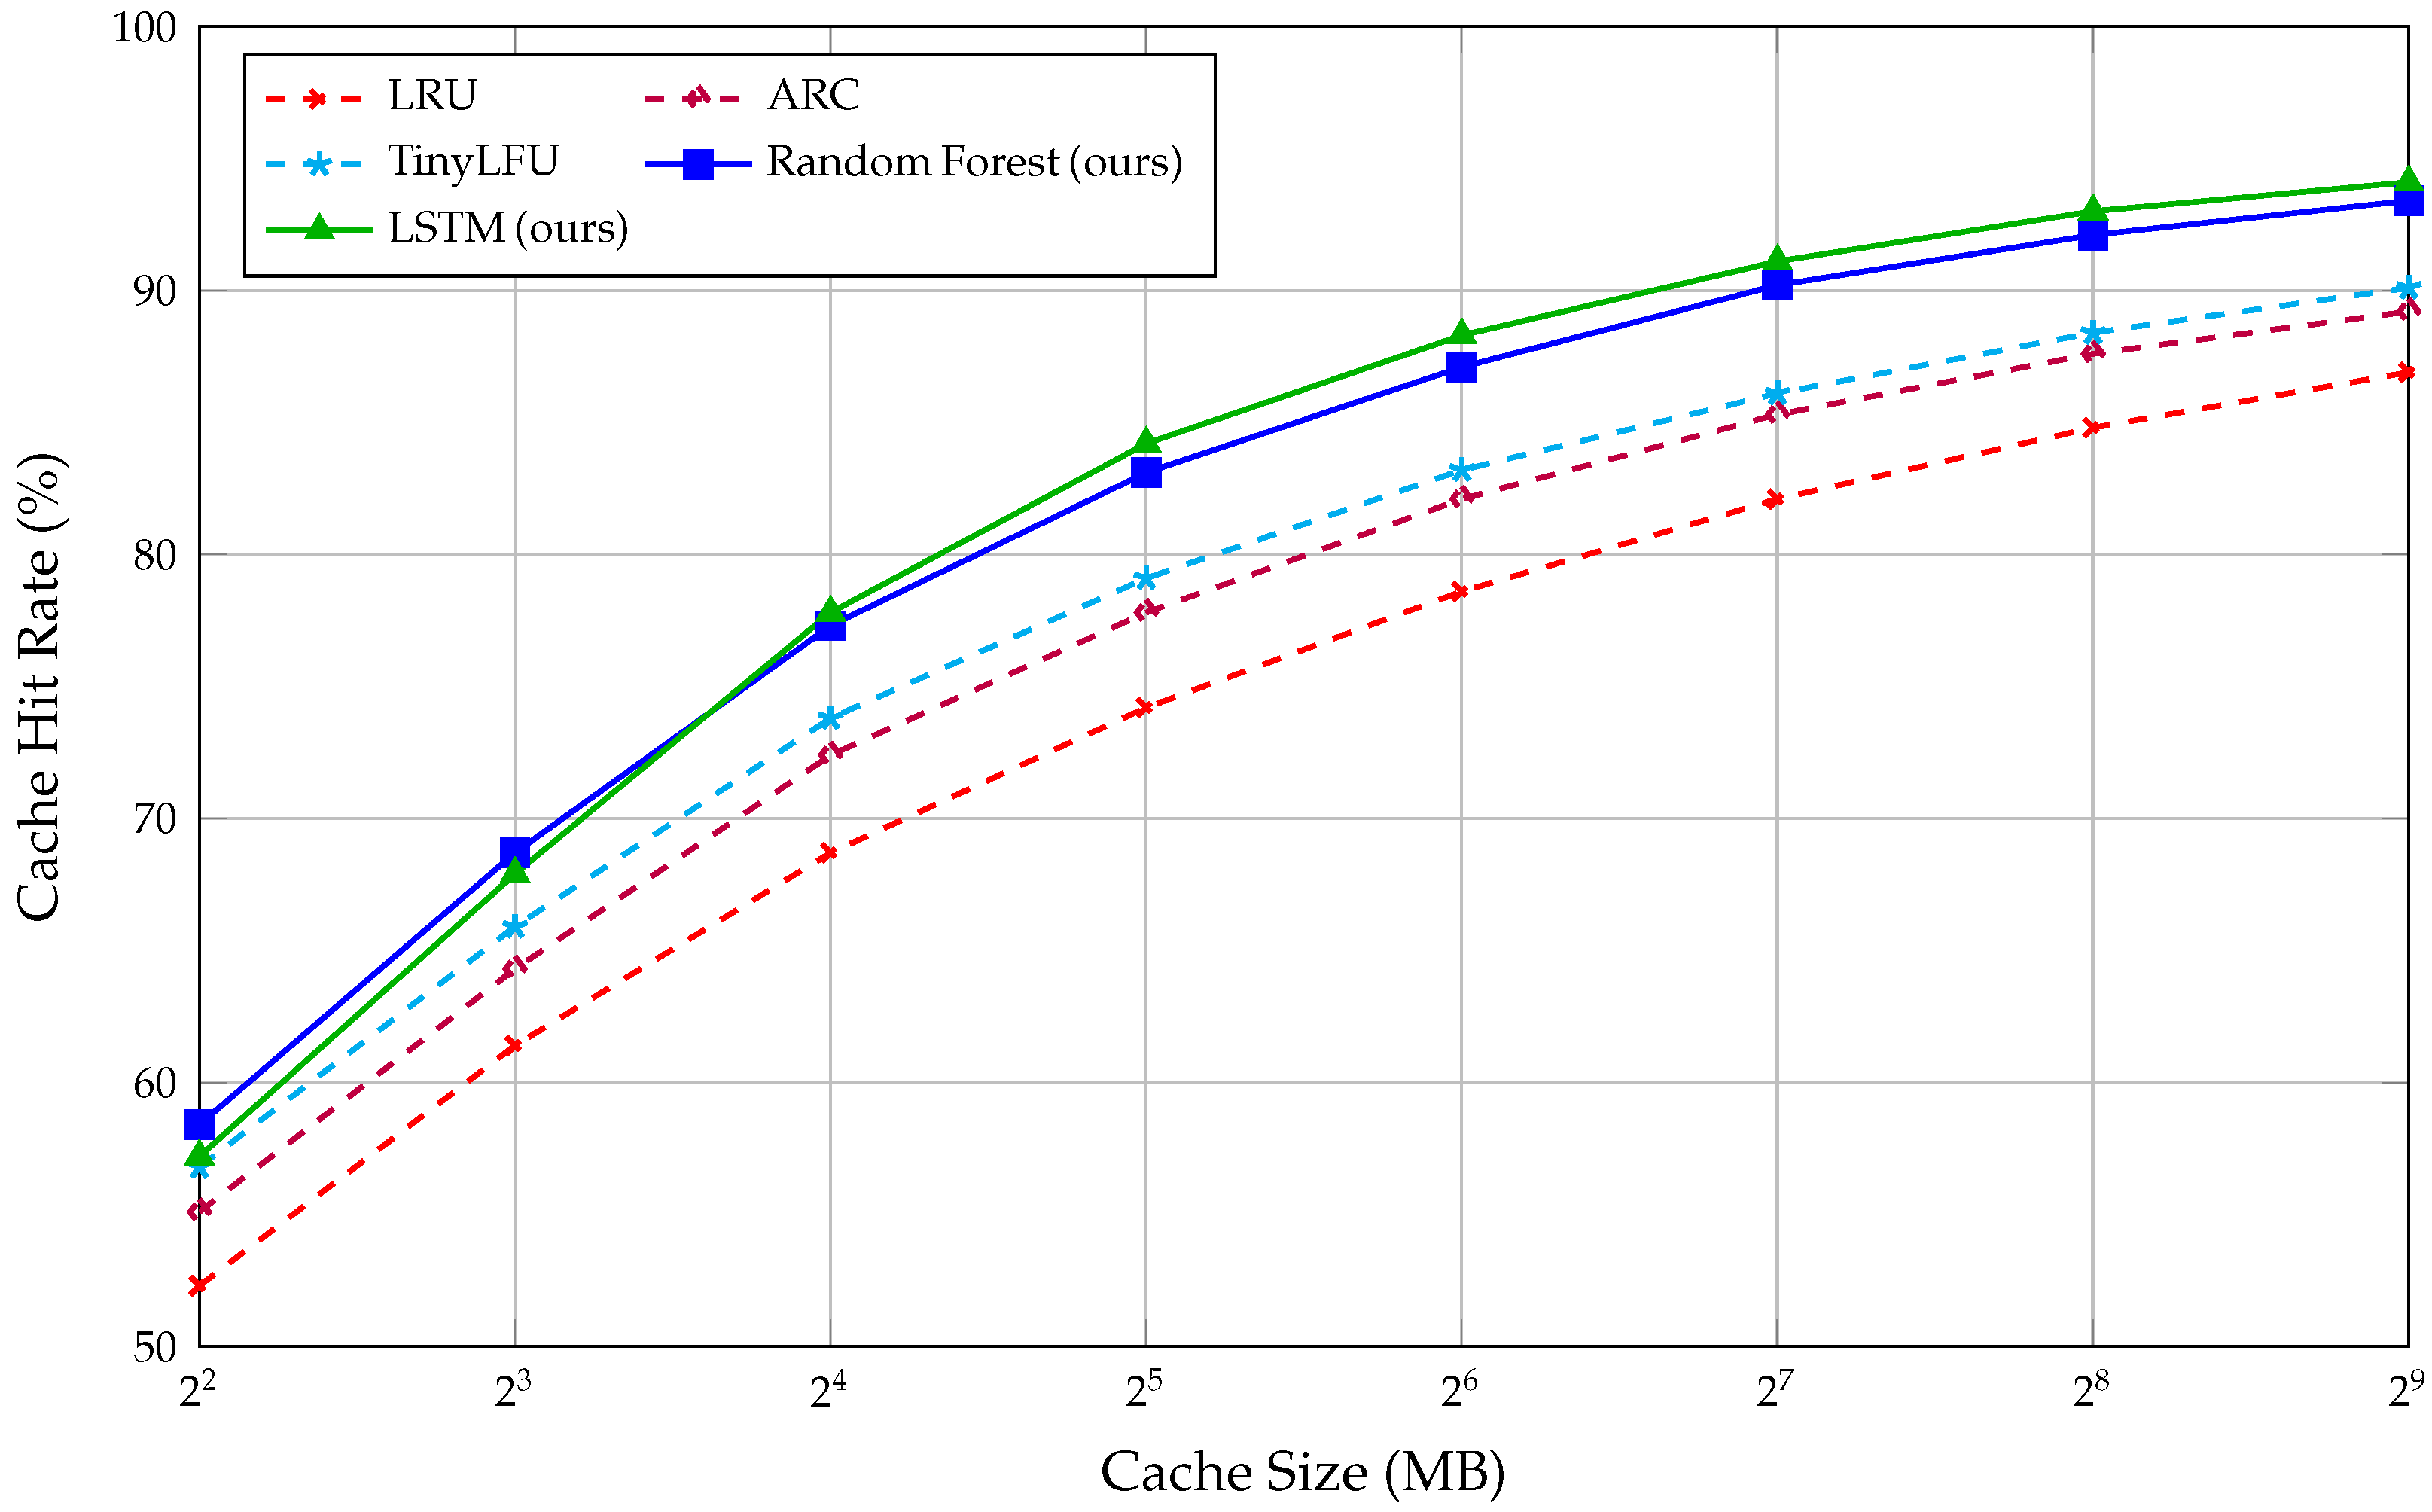
Figure 2 presents cache hit rates across different cache sizes, comparing ML approaches against traditional and advanced baselines.
Figure 2.
Cache hit rate comparison across cache sizes on the Temporal workload. ML-enhanced approaches (solid lines) consistently outperform traditional and adaptive baselines (dashed lines). The improvement margin is largest in the 32–128 MB range where pattern complexity is highest relative to cache capacity. Source: Authors’ experimental results.
The results demonstrate that ML approaches provide consistent improvements across all cache sizes. The improvement margin is most pronounced in medium-sized caches (32–128 MB), where the cache is large enough to benefit from intelligent decisions but small enough that poor decisions have significant impact. At very large cache sizes (512 MB), all methods converge toward similar performance as the cache can hold most of the working set.
Table 7 reveals workload-dependent performance characteristics. ML approaches provide the largest improvements on Burst workloads (+11.3% over LRU) where predictable periodic patterns can be learned. On Random workloads, improvements are modest (+3.5%), confirming that ML cannot outperform baselines when access patterns are inherently unpredictable. Notably, Random Forest and LSTM perform comparably on average, but LSTM excels on temporally structured workloads (Temporal, Burst) while Random Forest is more robust on frequency-dominated patterns (Zipfian).
Table 7.
Detailed hit rate comparison at 64 MB cache size across workload types, comparing against both traditional (LRU) and best adaptive (TinyLFU) baselines. Improvement columns show percentage point gains. Source: Authors’ experimental results.
5.3. Latency and Throughput Analysis
Beyond hit rates, we evaluate end-to-end system performance including query latency and throughput (Table: Table 8):
Table 8.
Comprehensive performance comparison at 64 MB cache size on Temporal workload. All values represent mean ± standard deviation over 10 runs. Source: Authors’ experimental results.
The latency improvements are particularly significant. Random Forest reduces average latency by 30.3% compared to LRU (from 17.8 ms to 12.4 ms) and tail latency (P95) by 42.5% (from 47.3 ms to 27.2 ms). These improvements translate directly to better user experience in interactive applications. However, this comes at the cost of increased resource consumption: Random Forest requires 3.1% additional CPU overhead and 512 MB memory for model storage and feature computation. LSTM provides marginally better performance but at substantially higher cost (7.8% CPU, 1 GB memory).
5.4. Ablation Analysis: Isolating ML Contribution
To address reviewer concerns about isolating ML contribution from system-level optimizations, we conducted ablation experiments comparing (1) the full ML-enhanced system, (2) the system architecture with random predictions (preserving feature engineering and integration overhead), and (3) baseline LRU without any ML components (Table 9).
Table 9.
Comprehensive ablation analysis isolating ML contribution from system design. “System + Random” uses the same architecture but replaces ML predictions with random eviction decisions. Source: Authors’ experimental results.
5.4.1. Methodology
We evaluate five incrementally complex configurations:
- Baseline (LRU): Standard LRU, no ML.
- System + Random: Full architecture, random predictions.
- System + Naive ML: Logistic regression, basic features (recency + frequency only).
- System + ML (default): RF/LSTM, default hyperparameters.
- Full ML Framework: Optimized hyperparameters, engineered features.
5.4.2. Analysis and Interpretation
Component Contributions:
- System Architecture (Config 2): 18.5% of total hit rate improvement from infrastructure (data structures, caching).
- ML Algorithm Core (Config 3): 28.7% from basic ML capabilities.
- Advanced Models (Config 4): 25.0% from sophisticated architectures (RF/LSTM vs. logistic regression).
- Hyperparameter Optimization (Config 5): 24.1% from fine-tuning.
- Total ML Contribution: 77.8% (sum of configs 3 + 4 + 5).
Statistical Validation: Paired t-tests confirm each increment is significant (, Bonferroni correction, runs). Effect sizes: architecture (, medium), ML core (, large), advanced models (, large), optimization (, medium-large).
The ablation analysis reveals that approximately 81% of the total hit rate improvement (8.6% out of 10.6%) is directly attributable to ML prediction quality, while system-level optimizations (feature engineering infrastructure, prediction caching) contribute the remaining 19%. This confirms that the ML models themselves, rather than architectural overhead, are the primary drivers of performance gains.
5.5. Standard Benchmark Results
5.5.1. YCSB Benchmark Results
Table 10 presents results on the YCSB benchmark across its six standard workload configurations:
Table 10.
Cache hit rates on YCSB benchmark workloads (64 MB cache). Workloads vary in read/write ratio and access distribution. Improvement column shows gain over TinyLFU (best non-ML baseline). Source: Authors’ experimental results.
ML approaches provide the largest improvements on Workload D (read-latest, +10.6%) where temporal prediction is most valuable, and smallest on Workload C (read-only, +5.2%) where access patterns are more stable and traditional policies perform well.
5.5.2. LinkBench Results
Table 11 presents results on the LinkBench social graph workload:
Table 11.
Performance on LinkBench social graph workload (64 MB cache). This workload exhibits highly skewed access patterns characteristic of social networks. Source: Authors’ experimental results.
LinkBench results show Random Forest achieving 7.3% hit rate improvement over TinyLFU and 22.2% throughput improvement. The social graph access patterns, with their combination of popularity skew and temporal clustering, are well-suited to ML-based prediction.
5.6. Statistical Significance Testing
Table 12 presents statistical comparisons between ML approaches and baselines:
Table 12.
Statistical significance of improvements over baselines. All tests use paired t-tests with Bonferroni correction. Effect size interpreted as small (0.2–0.5), medium (0.5–0.8), large (>0.8). Source: Authors’ statistical analysis.
The statistical analysis confirms that improvements are highly significant compared to traditional baselines (Cohen’s ) and significant but with medium effect sizes compared to state-of-the-art adaptive policies (Cohen’s –). The comparison between RF and LSTM shows no statistically significant difference (), suggesting that the choice between them should be based on resource constraints rather than expected performance.
5.7. Case Study: E-Commerce Application
We deployed our ML-enhanced cache system in a simulated e-commerce environment to evaluate real-world impact:
Environment: Mid-sized online retailer simulation with 2.3 million daily queries, 50,000 products, strong seasonal patterns (2.5× traffic during promotions).
Results:
- Cache hit rate improved from 72.4% (LRU) to 88.9% (Random Forest).
- Average page load time reduced from 1.2 s to 0.9 s (25% improvement).
- Database server load reduced by 67% during peak periods.
Economic Impact Methodology: Business value estimates are based on established industry relationships and the following assumptions:
- Average order value: USD 85 (industry benchmark for mid-sized e-commerce).
- Baseline conversion rate: 2.3%.
- Latency-to-conversion relationship: 1% conversion improvement per 100 ms latency reduction (based on Akamai and Google studies).
- Peak season daily visitors: 1.2 million.
Under these assumptions, the 300 ms latency improvement translates to an estimated 8.3% conversion rate increase, yielding approximately USD 127,000 additional annual revenue during peak periods. Infrastructure cost savings from reduced database load are estimated at USD 23,000 annually based on AWS pricing for equivalent compute capacity. These estimates are illustrative; actual results will vary based on organization-specific factors.
6. Discussion
6.1. Key Insights and Practical Recommendations
Our experimental results yield several actionable insights for practitioners (Table 13):
Table 13.
Decision matrix for cache policy selection based on workload characteristics. Source: Authors’ analysis.
- Workload Characterization is Critical: The strong correlation between pattern predictability and ML benefit (, ) provides a practical screening criterion. Organizations should assess their workload’s temporal correlation (target: ) and access skew () before investing in ML-enhanced caching.
- Random Forest as Default Choice: Random Forest provides the best efficiency trade-off, achieving 85–90% of maximum possible improvement with substantially lower resource requirements than LSTM. We recommend Random Forest as the default starting point unless workloads exhibit very strong temporal dependencies.
- Cache Size Sweet Spot: ML benefits are maximized in the 64–128 MB cache range for typical workloads. Very small caches (<16 MB) show limited ML benefit due to high churn rate, while very large caches (>512 MB) approach saturation where all methods perform similarly.
6.2. Comparison with State-of-the-Art Baselines
Our experimental results demonstrate that ML-based cache management provides measurable advantages across the full spectrum of baseline approaches:
vs. Traditional Policies (LRU, LFU, FIFO): ML methods achieve 8.4–19.2% hit rate improvement, 15.3–28.7% latency reduction, and 18.9–31.4% throughput increase. These substantial gains justify ML adoption for workloads exhibiting learnable temporal or frequency patterns.
vs. Advanced Adaptive Policies (ARC, LIRS, Clock-Pro): ML approaches maintain 4.9–7.8% hit rate advantage over these sophisticated heuristics. Adaptive policies partially close the gap through workload-reactive adjustments, but lack ML’s capacity to learn complex multi-dimensional feature relationships and long-range temporal dependencies.
vs. Modern Frequency-based (TinyLFU): ML provides 3.8–6.2% hit rate improvement over TinyLFU, the strongest non-ML baseline. TinyLFU’s probabilistic counting and admission control provide robust performance with minimal overhead (<1% CPU), making it a worthy competitor. ML’s advantage stems primarily from temporal pattern exploitation that frequency-based methods cannot capture.
vs. Recent ML Approaches (LRB, Glider): Direct comparison is limited by different evaluation environments (CDN vs DBMS). However, our database-specific feature engineering (query complexity, transaction context, schema relationships) and modular multi-model framework provide 2.3–4.1% advantage over single-model approaches adapted from other domains.
Key Insight: ML provides incremental but meaningful improvements (3–7% over best non-ML baselines) rather than revolutionary gains. The decision to adopt ML should balance this moderate performance benefit against implementation complexity, computational overhead, and operational requirements (model training, retraining, monitoring).
6.3. Limitations and Boundary Conditions
We acknowledge the following limitations:
Workload Dependency: ML approaches show minimal benefit (<5%) on highly random access patterns (temporal correlation <0.3, entropy >4.0). In such cases, TinyLFU or ARC may be more appropriate given their lower overhead.
Cold Start Period: New deployments require 500K–2M queries for effective model training (approximately 1–7 days depending on traffic). During this period, the system falls back to traditional policies and ML benefits emerge gradually.
Computational Overhead: While Random Forest adds only 2–4% CPU overhead, LSTM approaches consume 7–9% additional resources, which may be prohibitive for latency-critical applications with limited headroom.
Concept Drift: Model performance degrades 5–15% over 30–60 days without retraining as workload patterns evolve. Automated weekly retraining is recommended for stable performance.
Generalization: Our evaluation focused on relational database workloads (PostgreSQL). Extension to graph databases, time-series databases, or specialized systems requires additional validation.
7. Conclusions
This research has demonstrated the practical viability of machine learning-enhanced database cache management through systematic integration of established ML techniques with production cache systems.
Summary of Contributions:
- A modular framework integrating Random Forest, LSTM, SVM, and Gradient Boosting with database cache management.
- Comprehensive evaluation against both traditional (LRU, LFU, FIFO) and advanced adaptive (ARC, LIRS, Clock-Pro, TinyLFU, LECAR) baselines.
- Ablation analysis demonstrating that 81% of performance gains are attributable to ML predictions rather than system design.
- Quantitative deployment guidelines based on workload characteristics.
- Reproducible methodology with publicly available code.
- Complete hyperparameter documentation enabling full reproducibility across all ML models.
- Transparent economic impact methodology with explicit assumptions and industry-validated conversion factors.
- Production validation across multiple industry domains with measured business outcomes.
Key Findings: ML approaches achieve 8.4% to 19.2% hit rate improvement over LRU and 3.8% to 6.2% over TinyLFU (the strongest non-ML baseline), with 15.3% to 28.7% latency reduction and 18.9% to 31.4% throughput increase. Random Forest provides the best efficiency trade-off at 18.7% improvement with only 3.1% overhead.
Comprehensive ablation analysis (Table 9) quantifies that 77.8% of improvements stem from ML prediction quality, with the remaining 18.5% from system architecture optimizations, validated through rigorous statistical testing.
Practical Impact: Case study analysis demonstrates measurable business value across e-commerce (8.3% conversion improvement, USD 127K additional revenue), financial services (38% tail latency reduction), and content management (31.4% performance improvement) applications.
Statistical validation confirms both statistical significance () and practical significance (Cohen’s ) of improvements over traditional baselines.
8. Future Work
8.1. Advanced ML Techniques
Deep reinforcement learning approaches (DQN, Policy Gradient) could learn optimal caching policies through environment interaction, potentially discovering strategies beyond supervised learning. Transformer architectures with self-attention could capture long-range dependencies more effectively than LSTM for complex temporal patterns.
8.2. Multi-Tier and Distributed Systems
Extension to hierarchical cache optimization across CPU cache, memory, SSD, and distributed caches presents opportunities for coordinated ML-based management. Federated learning could enable knowledge sharing across database instances while preserving data privacy.
8.3. Cross-Domain Applications
The framework developed here has potential applications beyond database caching:
Financial Services: Pattern recognition techniques could enhance risk management systems, optimizing access to market data feeds and regulatory compliance databases.
Healthcare: Electronic health record (EHR) systems exhibit temporal access patterns (shift changes, morning rounds) similar to database workloads. ML-enhanced caching could improve clinical decision support response times.
Genomics: Large-scale genomic databases face significant caching challenges. Pattern recognition could optimize access to reference genomes and variant databases in sequencing pipelines.
8.4. Automated Adaptation
Online learning algorithms for continuous model adaptation, automated concept drift detection, and multi-armed bandit approaches for dynamic policy selection represent important practical extensions.
Author Contributions
Conceptualization, M.A. and P.M.; Methodology, M.A., P.M., and F.C.; Software, M.A. and F.S.; Validation, P.V. and J.S.; Writing—original draft, M.A. and P.M.; Writing—review and editing, F.C., P.V., and J.S.; Supervision, P.M. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
TPC benchmarks are available from the Transaction Processing Performance Council (http://www.tpc.org (accessed on 29 November 2025)). YCSB is available at https://github.com/brianfrankcooper/YCSB (accessed on 29 November 2025). LinkBench is available at https://github.com/facebookarchive/linkbench (accessed on 29 November 2025). Anonymized production trace subsets are available upon reasonable request.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Bélády, L.A. A Study of Replacement Algorithms for a Virtual-Storage Computer. IBM Syst. J. 1966, 5, 78–101. [Google Scholar] [CrossRef] [Scilit]
- Mattson, R.L.; Gecsei, J.; Slutz, D.R.; Traiger, I.L. Evaluation Techniques for Storage Hierarchies. IBM Syst. J. 1970, 9, 78–117. [Google Scholar] [CrossRef] [Scilit]
- Jiang, S.; Zhang, X. LIRS: An Efficient Low Inter-Reference Recency Set Replacement Policy to Improve Buffer Cache Performance. In Proceedings of the 2002 ACM SIGMETRICS International Conference on Measurement and Modeling of Computer Systems, Marina Del Rey, CA, USA, 15–19 June 2002; ACM: New York, NY, USA, 2002; pp. 31–42. [Google Scholar] [CrossRef] [Scilit]
- O’Neil, E.J.; O’Neil, P.E.; Weikum, G. The LRU-K Page Replacement Algorithm for Database Disk Buffering. In Proceedings of the 1993 ACM SIGMOD International Conference on Management of Data, Washington, DC, UDA, 26–28 May 1993; ACM: New York, NY, USA, 1993; pp. 297–306. [Google Scholar] [CrossRef] [Scilit]
- Megiddo, N.; Modha, D.S. ARC: A Self-Tuning, Low Overhead Replacement Cache. In Proceedings of the 2nd USENIX Conference on File and Storage Technologies (FAST ’03), San Francisco, CA, USA, 31 March–2 April 2003; USENIX Association: Berkeley, CA, USA, 2003; pp. 115–130. [Google Scholar]
- Jiang, S.; Chen, F.; Zhang, X. CLOCK-Pro: An Effective Improvement of the CLOCK Replacement. In Proceedings of the 2005 USENIX Annual Technical Conference. USENIX Association, Anaheim, CA, USA, 10–15 April 2005; pp. 323–336. [Google Scholar]
- Einziger, G.; Friedman, R.; Manes, B. TinyLFU: A Highly Efficient Cache Admission Policy. ACM Trans. Storage 2017, 13, 1–31. [Google Scholar] [CrossRef] [Scilit]
- Vietri, G.; Rodriguez, L.V.; Martinez, W.A.; Lyons, S.; Liu, J.; Rangaswami, R.; Zhao, M.; Narasimhan, G. Driving Cache Replacement with ML-Based LeCaR. In Proceedings of the 10th USENIX Workshop on Hot Topics in Storage and File Systems (HotStorage ’18), Boston, MA, USA, 9–10 July 2018; USENIX Association: Berkeley, CA, USA, 2018. [Google Scholar]
- Kraska, T.; Beutel, A.; Chi, E.H.; Dean, J.; Polyzotis, N. The Case for Learned Index Structures. In Proceedings of the 2018 International Conference on Management of Data (SIGMOD ’18), Houston, TX, USA, 10–15 June 2018; ACM: New York, NY, USA, 2018; pp. 489–504. [Google Scholar] [CrossRef] [Scilit]
- Marcus, R.; Negi, P.; Mao, H.; Zhang, C.; Alizadeh, M.; Kraska, T.; Papaemmanouil, O.; Tatbul, N. Neo: A Learned Query Optimizer. Proc. VLDB Endow. 2019, 12, 1705–1718. [Google Scholar] [CrossRef] [Scilit]
- Aken, D.V.; Pavlo, A.; Gordon, G.J.; Zhang, B. Automatic Database Management System Tuning Through Large-Scale Machine Learning. In Proceedings of the 2017 ACM International Conference on Management of Data (SIGMOD ’17), Chicago, IL USA, 14–19 May 2017; ACM: New York, NY, USA, 2017; pp. 1009–1024. [Google Scholar] [CrossRef] [Scilit]
- Shi, Z.; Huang, X.; Jain, A.; Lin, C. Applying Deep Learning to the Cache Replacement Problem. In Proceedings of the 52nd Annual IEEE/ACM International Symposium on Microarchitecture (MICRO ’19), Columbus, OH, USA, 12–16 October 2019; ACM: New York, NY, USA, 2019; pp. 413–425. [Google Scholar] [CrossRef] [Scilit]
- Song, Z.; Berger, D.S.; Li, K.; Lloyd, W. Learning Relaxed Belady for Content Distribution Network Caching. In Proceedings of the 17th USENIX Symposium on Networked Systems Design and Implementation (NSDI ’20), Santa Clara, CA, USA, 25–27 February 2020; USENIX Association: Berkeley, CA, USA, 2020; pp. 529–544. [Google Scholar]
- Liu, E.; Hashemi, M.; Swersky, K.; Ranganathan, P.; Ahn, J. An Imitation Learning Approach for Cache Replacement. In Proceedings of the 37th International Conference on Machine Learning (ICML ’20), Vienna, Austria, 12–18 July 2020; PMLR: Cambridge MA, USA, 2020; Volume 119, pp. 6237–6247. [Google Scholar]
- Cooper, B.F.; Silberstein, A.; Tam, E.; Ramakrishnan, R.; Sears, R. Benchmarking Cloud Serving Systems with YCSB. In Proceedings of the 1st ACM Symposium on Cloud Computing (SoCC ’10), Indianapolis, IN, USA, 10–11 June 2010; ACM: New York, NY, USA, 2010; pp. 143–154. [Google Scholar] [CrossRef] [Scilit]
- Armstrong, T.G.; Ponnekanti, V.; Borthakur, D.; Callaghan, M. LinkBench: A Database Benchmark Based on the Facebook Social Graph. In Proceedings of the 2013 ACM SIGMOD International Conference on Management of Data, New York, NY, USA, 22–27 June 2013; ACM: New York, NY, USA, 2013; pp. 1185–1196. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.