


Abstract
Unmanned aerial vehicle (UAV) inspection of transmission towers requires joint analysis of corridor geometry, tower components, and localized defects, whereas available datasets provide incompatible annotations at different scales. Tower-HMT is a hierarchical multitask network that shares a ConvNeXt-Tiny encoder and feature pyramid across corridor parsing, component parsing, missing-bolt localization, and component-condition recognition. Four public real-image datasets are organized by native supervision rather than merged into a flat label space. Task-conditioned feature modulation separates dataset statistics; topology and boundary losses preserve thin conductors and lattice edges; and a detached tower-probability gate supplies structural context to a high-resolution bolt head. Source-image groups define non-overlapping training, validation, and test partitions. On held-out data, the network achieved foreground mIoU values of 0.597 for tower-conductor parsing and 0.561 for box-conditioned component parsing, an AP50 of 0.123 for missing-bolt localization, and a macro-F1 of 0.925 for component-condition recognition. Boundary, class-wise, robustness, threshold-sensitivity, and latency results quantify the effects and limitations of hierarchical learning. The framework provides a reproducible real-image baseline for review-oriented inspection, while low missing-bolt localization accuracy and weak component masks remain the principal constraints.
1. Introduction
Overhead transmission lines constitute geographically dispersed infrastructure whose physical condition directly affects the reliability of electricity delivery. Towers, conductors, insulators, and connection hardware are exposed over long service periods to cyclic loading, corrosion, severe weather, vegetation encroachment, and other environmental disturbances. Detecting deterioration before it develops into a functional failure is therefore central to condition-based maintenance [1,2]. However, conventional ground patrols are limited by terrain, viewing distance, and accessibility, while close-range manual inspection is costly and may expose personnel to operational hazards. UAVs provide a practical means of acquiring repeatable, high-resolution observations from multiple viewing positions and have consequently become an important source of inspection data for transmission-line asset management. The interpretation of these data nevertheless presents a distinct set of computer-vision problems. Image scale can change substantially within a single flight, from a corridor-level view to a close-range observation of a bolted connection. A tower may occupy only a small part of one frame but extend across nearly the entire field of view in another. Conductors appear as elongated structures that are readily obscured by vegetation, glare, or background clutter; insulator strings and dampers contain repetitive visual patterns; and individual bolts may be reduced to only a few pixels after image resizing [3,4,5,6,7]. The inspection problem is therefore inherently hierarchical. Image analysis must proceed from locating towers and conductors within the corridor to identifying the relevant component or assembly, and finally to determining whether a local observation represents normal variation or a condition requiring maintenance attention. This dependence across spatial scales cannot be adequately represented as a collection of unrelated recognition tasks.
Inspection outputs acquire engineering value only after they are related to condition and failure risk. Lin and Miyauchi showed that inspection-derived condition scores can be combined with age-dependent failure rates and Weibull analysis to forecast equipment reliability [1]. The same inspection-to-reliability link can support replacement planning when preventive and failure-replacement costs are balanced through a constant-interval model [2]. Tower-HMT does not estimate failure rates or replacement ages; it supplies localized, image-based condition evidence that can be calibrated against utility inspection histories before being used in such asset-management models.
Most UAV-based transmission-line inspection systems treat scene parsing, component localization, and defect assessment as separate problems. Tower and conductor segmentation is learned from polygon annotations, component detection from bounding boxes, and defect recognition from cropped component images [8,9,10,11]. Architectures including U-Net, Mask R-CNN, DeepLabv3+, HRNet, Swin Transformer, DETR, Mask2Former, and PointRend have provided strong task-specific baselines [12,13,14,15,16,17,18,19], but this division reflects prevailing annotation practices more than the physical organization of the assets. Independently trained models repeatedly learn features associated with lattice boundaries, galvanized surfaces, and connection geometry, while defect classifiers operating on cropped images retain little information about the structural location of a candidate anomaly. The organization of public datasets further reinforces this separation. TTPLA provides aerial polygon annotations for towers and power lines [8]; STN PLAD covers several classes of power-line assets across substantial scale variation [9]; InsPLAD includes a broader component taxonomy and condition labels for selected assets [10]; and TTBM-DET-Det focuses on missing bolts, a small but operationally significant target [11]. Because these datasets differ in geographic origin, flight conditions, scene composition, and annotation protocol, their labels cannot be combined directly. An object left unannotated in one dataset cannot be assumed to be absent, and naïve pooling would consequently introduce false-negative supervision. The methodological challenge is thus to learn a common visual representation from heterogeneous annotations while retaining the semantics of each task and dataset.
This distinction is important because transmission-tower anomalies do not arise from a single physical process. Missing or loosened bolts alter load transfer through structural joints; corrosion reduces the effective section of a member and may obscure the appearance of fasteners; missing insulator caps affect the integrity of the insulating string; and bird nests introduce foreign material near energized equipment. Previous studies have examined corrosion quantification [20], tower damage inspection [21], tower-state recognition [22], and bolt defects [23,24,25,26], but their evaluation protocols generally remain confined to individual tasks. Operational inspection requires these observations to be associated within a consistent record linking corridor geometry, identified components, and local abnormalities. To maintain a direct correspondence with this application, the present study is limited to real transmission-tower imagery and crops of tower-mounted components. Images of bridge corrosion, building damage, generic structural steel, simulated defects, and procedurally rendered towers are excluded from both model development and qualitative evaluation.
Within this scope, Tower-HMT uses a shared ConvNeXt-Tiny encoder [27] and feature pyramid [28] to support four related inspection tasks. Feature-wise task conditioning handles dataset differences [29], while task-alternating updates regulate shared features; uncertainty weighting is a distinct strategy [30]. Separate segmentation heads operate at the corridor and component scales. Missing bolts are localized by an anchor-free heatmap head attached to the highest-resolution pyramid feature and constrained by a stop-gradient tower-probability gate, whereas a global classification head predicts component family and condition. The training objectives are selected according to the annotation form and spatial characteristics of each task: focal losses supervise localized targets [31,32], overlap and boundary terms refine segmentation [33,34,35,36], and topology regularization discourages discontinuities in thin conductor predictions [37,38]. Predictions of component condition are further examined using gradient-weighted class activation mapping [39].
This study presents Tower-HMT, a hierarchical multitask framework for joint corridor segmentation, component parsing, missing-bolt localization, and component-condition recognition using four heterogeneously annotated UAV datasets. Its main contributions are as follows. First, polygon-, bounding-box-, and image-level annotations are incorporated without treating unlabeled categories as negative samples. Second, bounded task-conditioned routing is integrated with a shared ConvNeXt–FPN to balance cross-task feature sharing and dataset-specific variation. Third, topology- and boundary-aware objectives, a stop-gradient tower-probability gate, and a high-resolution bolt branch are combined to support structural parsing and provide contextual guidance for small-target localization. Finally, source-group-disjoint partitions support unified evaluation of accuracy, robustness, threshold sensitivity, and inference latency.
The specific novelty lies in coordinating four native supervision types within one routed representation while preserving missing-label semantics, and in transferring tower context to the bolt branch through a detached structural prior. The claim is therefore about heterogeneous-supervision coordination and hierarchical context, rather than a new universal decoder or superiority of every task head.
2. Data and Problem Formulation
In this section, the data scope and learning problem are defined. Four real-image datasets are described, their native annotation formats are mapped to the corresponding inspection tasks, and the construction of non-overlapping training, validation, and test partitions is specified. These definitions establish the heterogeneous-supervision setting for subsequent model development and evaluation.
2.1. Real Tower-Image Sources
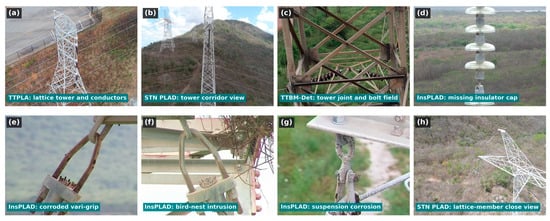
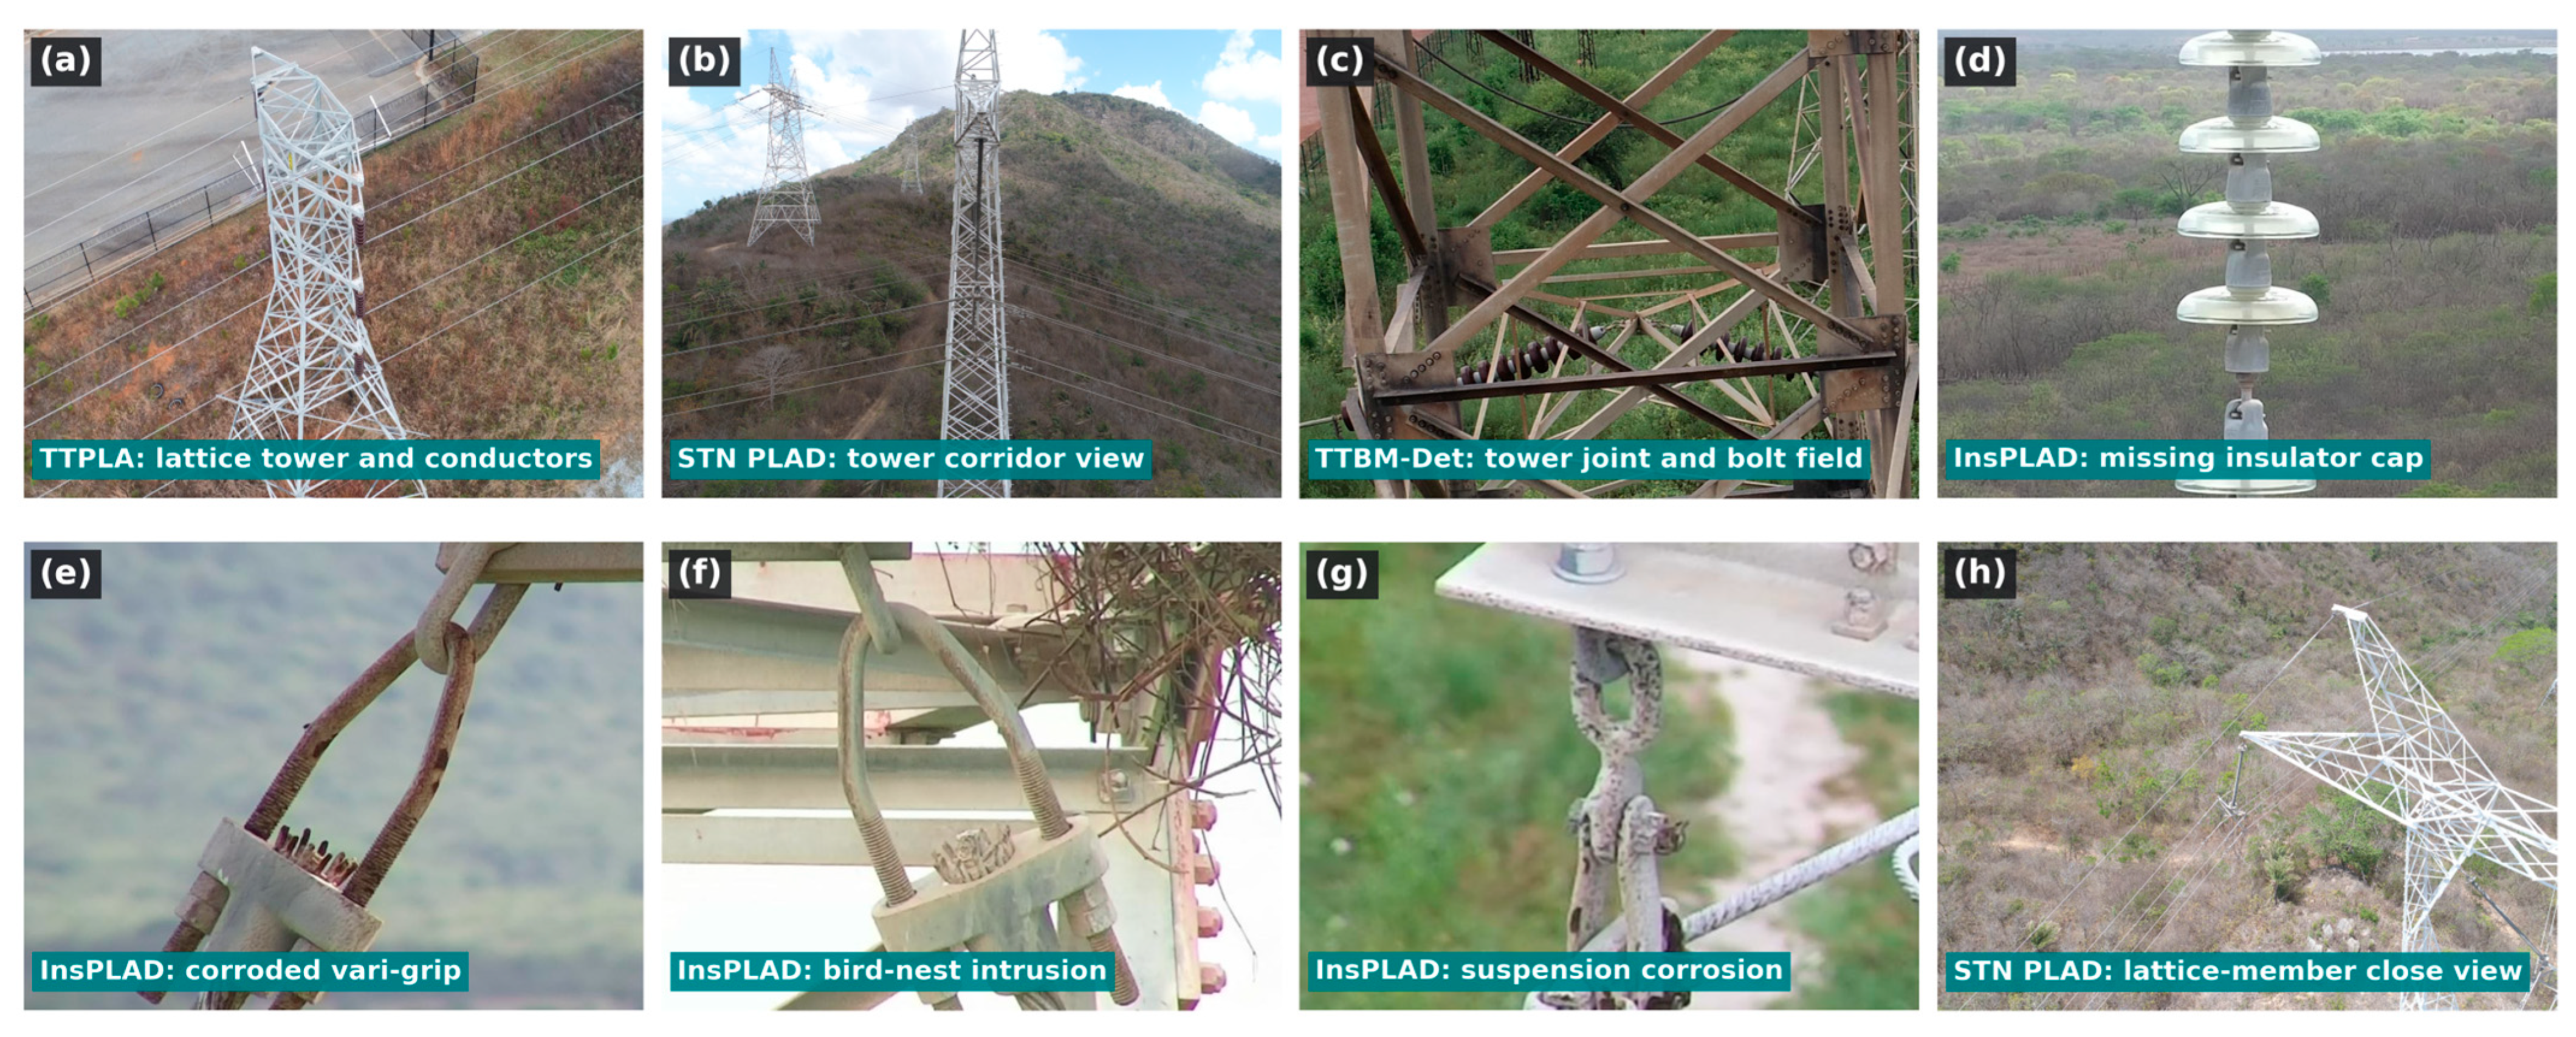
Figure 1 shows eight real-image panels from four public transmission-tower datasets. TTPLA and STN PLAD provide corridor and lattice-tower views, TTBM-DET-Det provides joint scenes with missing-bolt boxes, and InsPLAD provides condition-labelled component crops. The panels cover tower-scale geometry and component-scale abnormalities without synthetic or non-tower imagery.
Figure 1.
Eight real transmission-tower examples from four public datasets: (a) TTPLA lattice tower and conductors; (b) STN PLAD tower corridor; (c) TTBM-DET-Det joint and bolt field; (d–g) InsPLAD missing-cap, corrosion, and bird-nest conditions; and (h) an additional STN lattice-tower view.
Table 1 summarizes the four data sources and their native supervision. The held-out sets contain 576 TTPLA patches, 410 STN patches, 227 TTBM-DET images, and 3169 InsPLAD crops; source grouping prevents related images from crossing partition boundaries.
Table 1.
Public tower-image sources and the local group-isolated partitions (train/validation/test).
Corridor- and component-scale segmentation are constructed from two datasets with different annotation formats. At the corridor scale, TTPLA [8] provides conductor polygons and annotations for lattice, wooden, and tubular-concrete supports, which are consolidated into a single tower class. Source images are partitioned before division into 512 × 512 patches, preventing patches from the same image from appearing in both training and test subsets. Pixels assigned a mask value of 255 represent ambiguous overlap and are excluded from loss calculation and metric evaluation. At the component scale, bounding boxes for towers, insulators, spacers, dampers, and plates are obtained from STN PLAD [9]. Foreground evidence within each box is used to derive a box-conditioned mask, with a fallback procedure applied only when a stable foreground region cannot be recovered. Because these masks originate from box-level supervision rather than manually delineated contours, performance is assessed using semantic mIoU and boundary F1 without interpreting the masks as ground-truth component boundaries.
Small-defect localization is based exclusively on the downloaded release of TTBM-DET-Det, which contains 1508 real tower images annotated for missing bolts [11]. The official training, validation, and test partitions are retained. Because the targets occupy only a small proportion of the original images, the final localization stage uses a letterboxed input resolution of 512 × 768, compared with the 384 × 384 inputs used for segmentation and condition recognition. The detector estimates a center heatmap, object dimensions, and subpixel offsets. Bounding-box evaluation is restricted to this dataset, and no detection annotations are inferred from the other data sources.
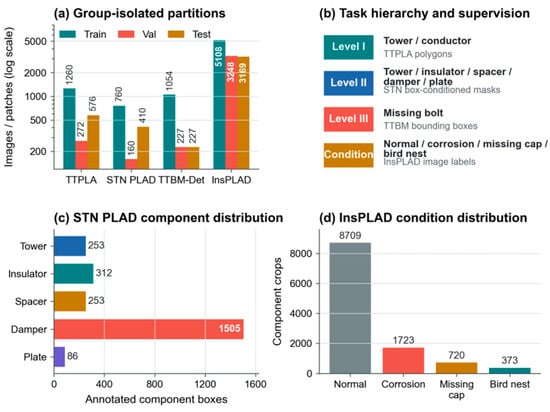
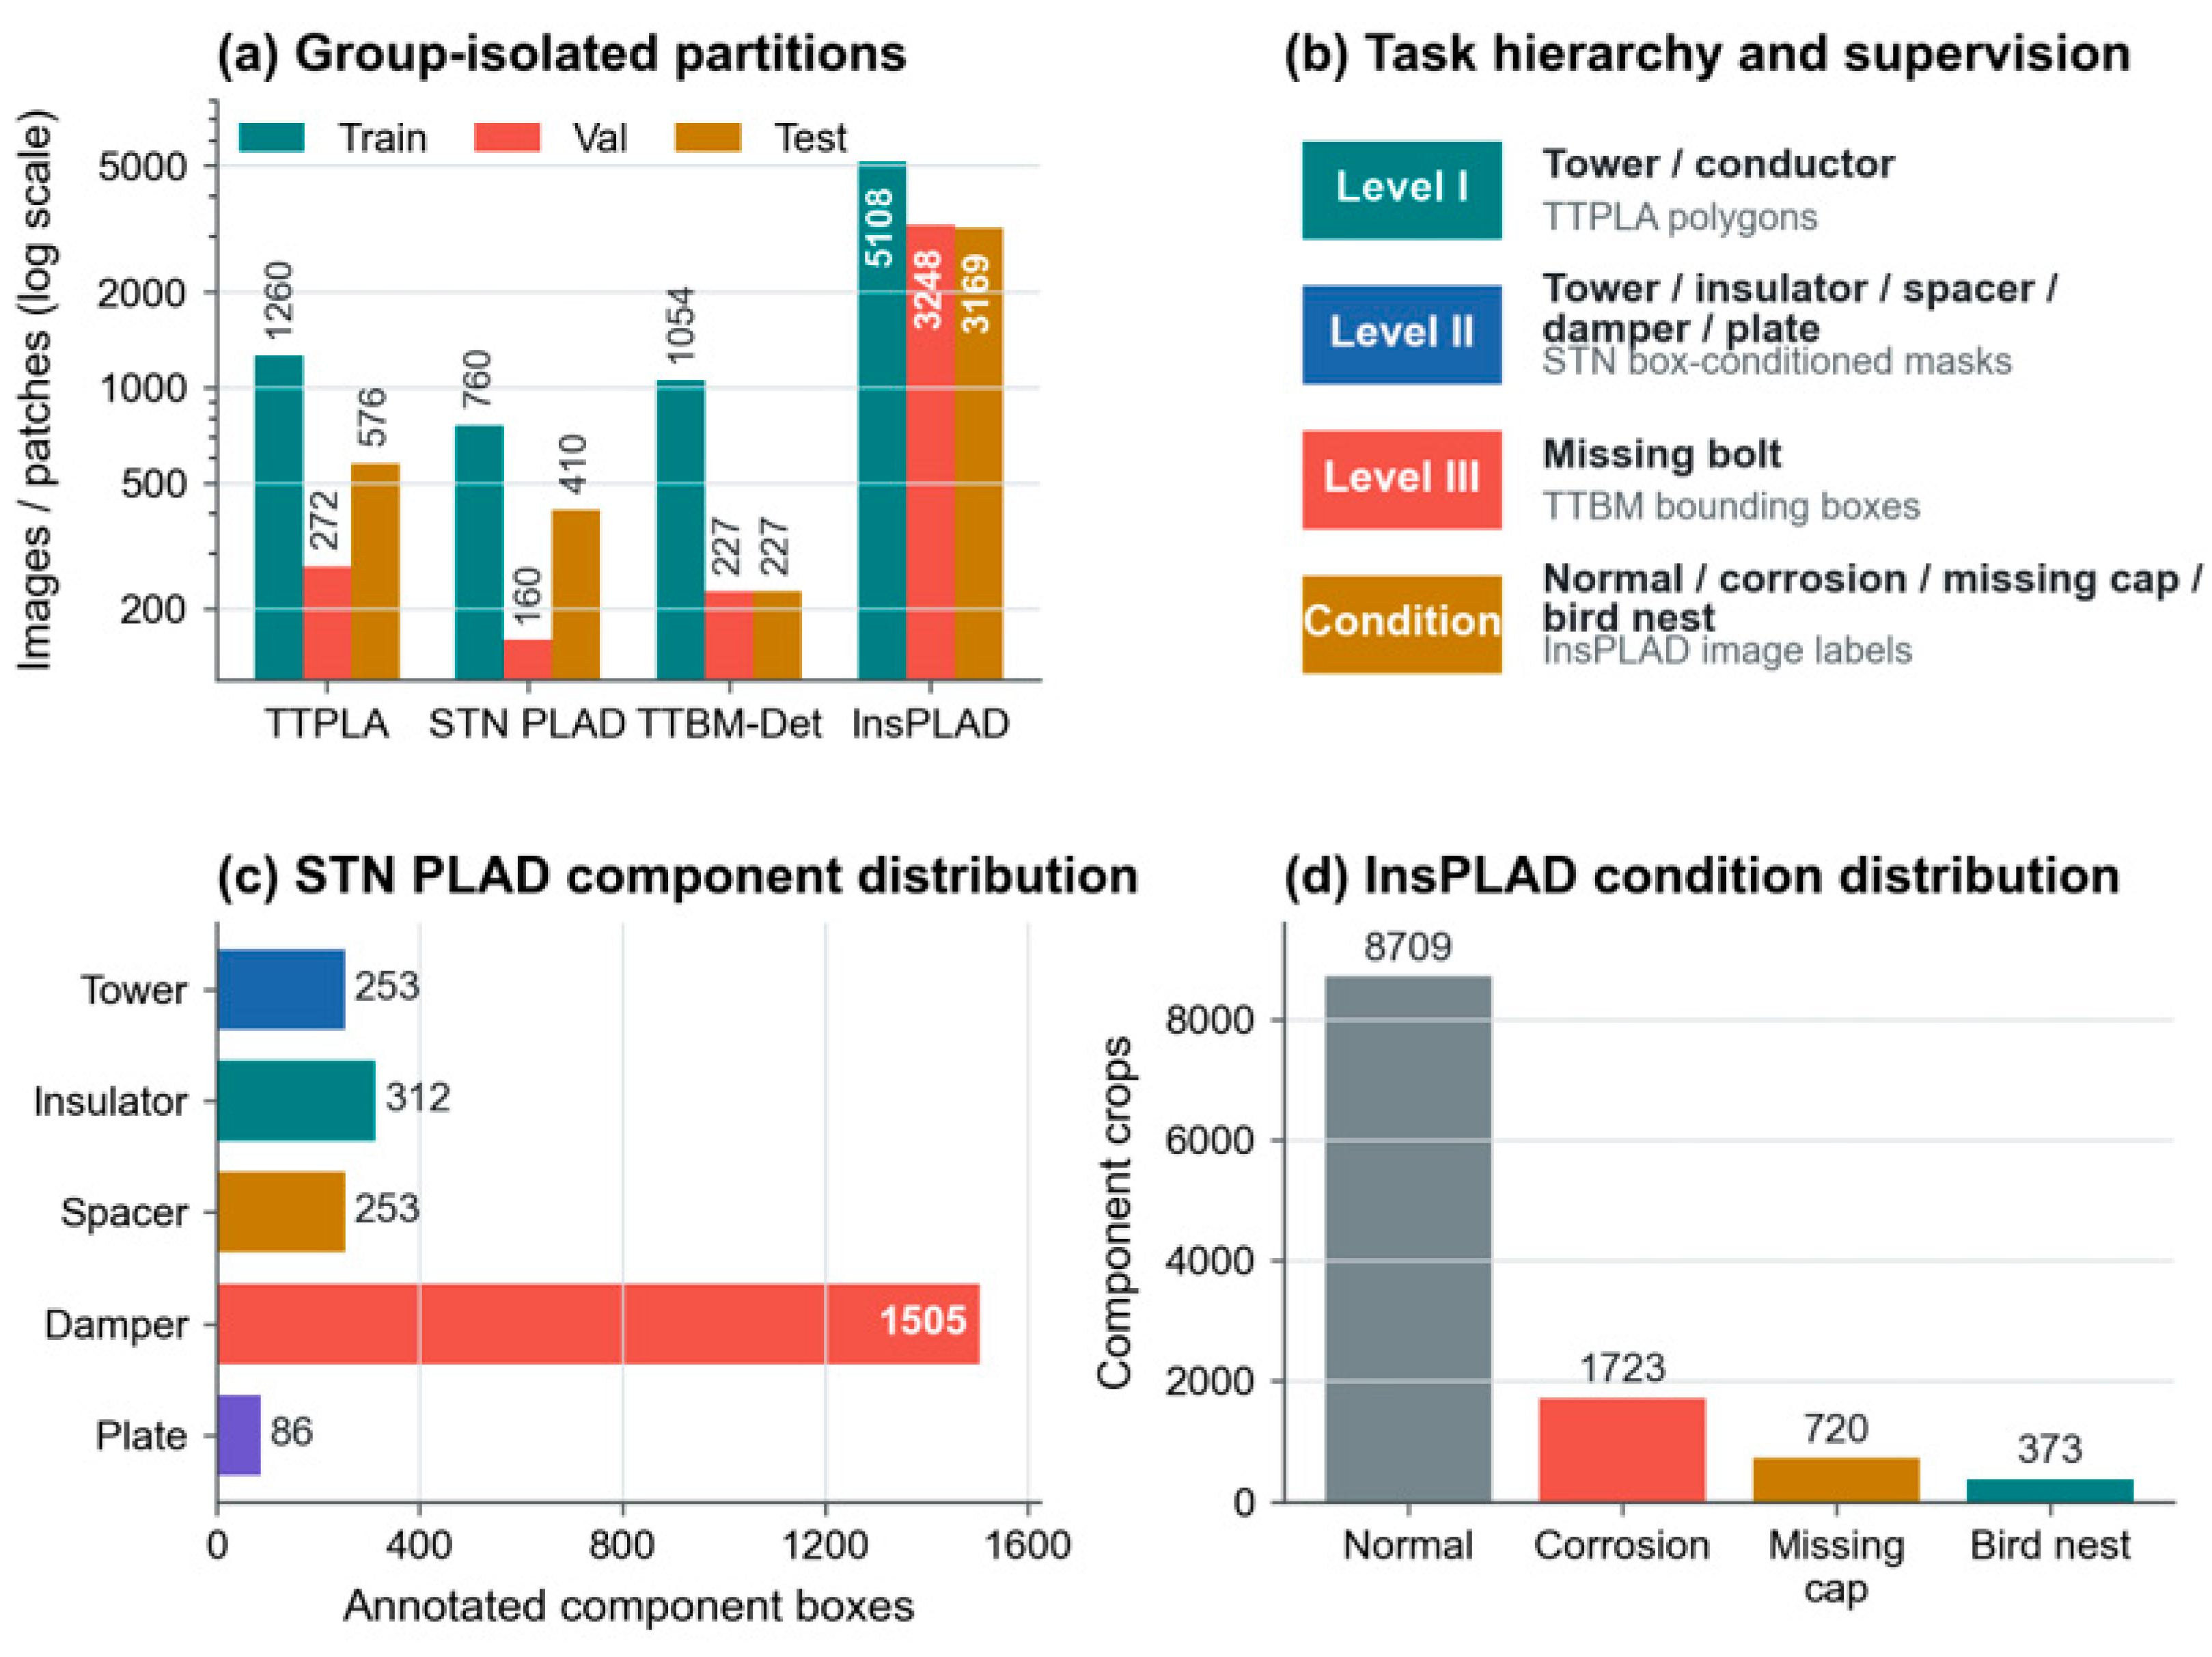
Image-level condition recognition required separate treatment because InsPLAD organizes supervision through directory labels rather than spatial annotations. The fault subset [10] was therefore recast into five component families and four condition states—normal, corrosion, missing cap, and bird nest. Synonymous labels, including good/normal and rust/corrosion, were standardized before training. The original training directory was retained as the local training set. Images in the supplied validation directory were grouped by source name and deterministically assigned to the local validation and test sets, preventing near-duplicate samples from the same source group from appearing in both partitions. A condition-weighted sampler was applied during training, whereas the natural class distribution was retained for validation and testing. Figure 2 summarizes the resulting training, validation, and test counts: 1260/272/576 TTPLA patches, 760/160/410 STN PLAD patches, 1054/227/227 TTBM-DET-Det images, and 5108/3248/3169 InsPLAD crops. It also relates each dataset to its supervision level and reports the component- and condition-class distributions.
Figure 2.
Dataset audit. (a) Local train, validation, and test counts; (b) supervision hierarchy; (c) STN PLAD component imbalance; and (d) InsPLAD condition imbalance. The logarithmic axis in (a) prevents the larger crop set from obscuring the segmentation datasets.
For reproducibility, a source group was formed by removing the final two crop-specific tokens from each InsPLAD filename. The SHA-256 hash of the group identifier and seed 20260717 was mapped to 100 buckets: 0–49 formed the local validation set and 50–99 the local test set. This deterministic rule produced 3248 validation and 3169 test crops and prevented a source group from entering both sets.
2.2. Hierarchical Tasks
Building on these dataset-specific annotations, the inspection problem is formulated as four related prediction tasks operating across three spatial scales. As summarized in Table 2, the outputs comprise three-class corridor segmentation, six-class box-conditioned component parsing including background, missing-bolt localization as a single anomaly category, and classification of four component-condition states. Each task is trained using its native supervision—pixel masks, bounding boxes, or image-level labels—without converting the annotations into a common representation.
Table 2.
Unified inspection hierarchy without forcing incompatible labels into one vocabulary.
To accommodate heterogeneous annotation regimes without introducing spurious negative labels, model optimization is organized by task. Let
denote the task set, and let be the dataset providing supervision for task . At each training iteration, a task is selected and a mini-batch is sampled. All batches are processed by the shared encoder, whereas task-conditioned modulation and the corresponding prediction head determine the task-specific output. Only the loss associated with the selected task is evaluated. Consequently, an InsPLAD crop without bolt annotations is not treated as a negative sample for bolt localization, and a TTBM-DET-Det image without component masks is not assigned to the background class. The absence of an annotation is thus treated as unavailable task supervision rather than evidence that the corresponding object is absent.
3. Tower-HMT Method
In this section, the architecture and training formulation of Tower-HMT are presented. A shared task-conditioned feature pyramid is coupled with task-specific heads for corridor parsing, component parsing, missing-bolt localization, and condition recognition, followed by the corresponding objectives and multitask optimization procedure.
To aid navigation, the method is organized in the order in which information flows through the network: shared encoding and routing (Section 3.1), task-specific segmentation heads and structural losses (Section 3.2), tower-gated bolt localization (Section 3.3), condition recognition (Section 3.4), and alternating optimization (Section 3.5).
3.1. Shared Encoder and Task-Conditioned Feature Pyramid
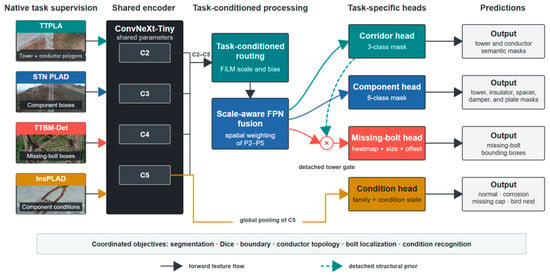
To accommodate the different spatial scales of corridor parsing, component analysis, and defect recognition, Tower-HMT constructs a shared feature hierarchy with task-dependent routing. As illustrated in Figure 3, ConvNeXt-Tiny generates the backbone features C2–C5, which are projected to 128 channels using lateral convolutions. Top-down addition followed by depthwise convolution produces the pyramid features , where Before scale fusion, each feature is modulated according to the active task:
in which denotes the active task, identifies the pyramid level, and is the task-conditioned form of . The vectors provide channel-wise scaling and offset terms, respectively, and are broadcast across the spatial dimensions. The symbol denotes channel-wise multiplication, is the channel-wise identity vector, and is applied element-wise. The four-task embedding table contains 1024 trainable parameters. This parametrization bounds the multiplicative factor within and the additive offset within , limiting perturbations to the pretrained features.
Figure 3.
Tower-HMT architecture. Four real tower-image domains share a ConvNeXt-Tiny encoder. Task-conditioned routing and learned pyramid fusion feed corridor, component, tiny bolt, and condition heads. Conductor topology and a detached tower gate supply structural regularization. The condition head receives the deepest encoder representation directly.
To align the routed features for multiscale fusion, each feature map is resized to the spatial resolution of . Accordingly, in Equation (3) refers to the resized feature for task at pyramid level . A learned single-channel projection then generates a spatial score for each level, and the resulting scores are normalized across all pyramid levels:
where denotes a spatial location on the grid, and is the one-channel scoring projection for level . The operator normalizes the scores across the four pyramid levels. is the resulting fused feature for task . This spatially varying weighting allows different regions to draw on pyramid features with different receptive fields without requiring a transformer decoder.
The fused feature map is refined by two depthwise-separable convolutional blocks. For missing-bolt localization, the routed feature is added to the refined representation with a fixed weight of 0.5 before tower-probability gating.
3.2. Segmentation Heads and Structural Objectives
Corridor- and component-level segmentation are handled by separate decoders. The corridor decoder predicts background, conductor, and tower, whereas the component decoder predicts background, tower, insulator, spacer, damper, and plate. Each decoder comprises two depthwise convolutional blocks followed by a 1 × 1 classifier. A parallel binary head predicts the combined boundary of all foreground classes. Its target is derived from a five-pixel morphological band, which accommodates local uncertainty in the box-conditioned STN masks while remaining sensitive to substantial leakage into adjacent background regions.
Because background pixels dominate both segmentation datasets, weighted cross-entropy is combined with foreground Dice and boundary binary cross-entropy. Conductor continuity is additionally regularized by soft clDice in the corridor task:
in which is the total segmentation loss, is the class-weighted cross-entropy loss, measures foreground overlap, and is the binary cross-entropy loss of the boundary head. The indicator equals 1 for corridor segmentation and 0 for component segmentation; consequently, is applied only to the corridor task. The coefficients determine the relative contribution of each term. Cross-entropy class weights are estimated from the training distribution and held fixed in all experiments.
The foreground Dice loss is defined as follows:
where is the number of foreground classes: for corridor segmentation and for component segmentation. The index denotes a foreground class, and indexes valid image pixels. is the predicted probability that pixel belongs to class , while is the corresponding ground-truth label. Pixels marked as ambiguous are excluded from all sums. The constant 1 prevents numerical instability when a class is absent.
For conductor topology, soft skeletons are obtained through four differentiable erosion–opening iterations. The clDice loss is computed as follows:
in which is a small numerical-stability constant; measures how much of the predicted skeleton lies within the reference conductor region, whereas measures how well the predicted conductor map covers the reference skeleton. Four iterations are retained for the masks because increasing the depth to eight more than doubled training time without consistently improving validation connectivity. The topology term is not applied to the tower class, as gaps and disconnected visible regions are compatible with lattice-tower geometry [37].
3.3. Tower-Gated Missing-Bolt Head
Missing bolts are localized at the finest pyramid resolution using an anchor-free center-based head. A Gaussian heatmap represents each annotated box center, while separate regressors estimate box size and the offset from the discrete grid location. During inference, local heatmap maxima are decoded, low-confidence candidates are removed, and non-maximum suppression eliminates overlapping duplicates. This formulation is better suited to small targets than assignment to a predefined anchor set.
To reduce responses at structurally implausible locations, the bolt branch incorporates the tower probability predicted by the corridor head. The probability map is aligned with the bolt feature grid, expanded by max pooling, and detached from gradient propagation:
where is the fused bolt feature, is the routed feature, and is the representation supplied to the localization head. The coefficient 0.5 controls the high-resolution residual, is the tower-probability map, and denotes dilation implemented by max pooling. The operator blocks gradients through the tower-prior branch, and controls the prior strength. The gate enhances tower-associated regions without suppressing features elsewhere.
The training objective combines a focal heatmap loss, a Smooth-L1 size loss weighted by 0.20, and a Smooth-L1 offset loss. During the refinement stage, the remaining network modules are frozen and only the 54,789 bolt-head parameters are optimized using letterboxed inputs. The same training schedule and input resolution are retained for all ablation variants.
3.4. Component-Condition Head
Unlike the segmentation and localization heads, condition recognition operates on component crops and is therefore based on a global representation. The deepest encoder feature is processed by global average pooling and passed to two classifiers. The primary classifier predicts four condition states, whereas an auxiliary classifier predicts five component families, providing component-level context for condition recognition.
in which is the total loss of the condition branch, and denotes cross-entropy. The vector contains the predicted logits for the four condition states, and is the corresponding ground-truth condition label. The vector contains the condition-class weights used to reduce the influence of the dominant normal class. Similarly, contains the component-family logits, and is the ground-truth component label. The coefficient 0.35 controls the contribution of the auxiliary component-classification loss.
Condition-balanced sampling is used during training, whereas the original class distribution is retained for validation and testing. Macro-F1 is adopted as the principal evaluation metric because it assigns equal importance to each condition class. Additionally, gradient-weighted class activation maps are used to examine the image regions supporting the condition predictions [39].
3.5. Coordinated Optimization
Task batches follow a randomized order, with one optimizer update per batch and no cross-dataset label padding. The active task loss defines each update. Across an epoch, task frequency πt is controlled by the per-task batch cap and the condition-balanced sampler, yielding the weighted expectation as follows:
where is the expected multitask objective, and is the proportion of scheduled mini-batches assigned to task , satisfying and . denotes the effective training distribution for task , including condition-balanced sampling where applicable. The variables and represent an input image and its native annotation, respectively, and is the loss associated with task .
This alternating schedule preserves the supervision structure of each dataset and does not require simultaneous gradient manipulation across tasks. Segmentation, localization, and classification losses are recorded separately to monitor task-level convergence. Checkpoint selection is based on the unweighted mean of corridor mIoU, component mIoU, missing-bolt AP50, and condition macro-F1, with all metrics expressed on the scale. Only validation results are used for model selection; test metrics are reserved for the final evaluation.
4. Experimental Design
In this section, the experimental protocol and empirical evaluation of Tower-HMT are presented. Controlled implementation settings and task-specific metrics are first specified, followed by performance comparisons, ablation studies, robustness and threshold analyses, and an assessment of inference efficiency.
4.1. Implementation and Controls
To isolate the effects of architectural changes, the training configuration and data partitions were held constant across all model variants. As summarized in Table 3, the feature pyramid contained 128 channels, with 384 × 384 inputs used for segmentation and condition recognition and 512 × 768 inputs used for bolt localization. The encoder was initialized from ImageNet-1K weights [40] and optimized using AdamW [41]. Learning rates of 2.5 × 10⁻⁴ and 1.8 × 10⁻⁵ were used for joint training and bolt refinement, respectively, together with cosine decay, gradient-norm clipping at 5.0, and bfloat16 mixed-precision training. Mini-batches contained eight segmentation patches, six detection images, or sixteen component crops according to the active task. A per-task batch cap prevented the larger condition dataset from dominating the update schedule. During bolt refinement, the largest batch size supported at 512 × 768 was used without gradient accumulation. A single random seed and identical source-group partitions were retained throughout all experiments. After the training configuration was fixed, data augmentation and model ablations were defined to preserve physical plausibility and experimental comparability. Augmentation was limited to standard image-domain transformations [42]. Horizontal flips, moderate gain and bias changes, and occasional mild Gaussian blur were applied to segmentation images. Horizontal flips, brightness/contrast variation, and light blur with transformed boxes were applied to detector images. Horizontal flips and photometric variation were applied to condition crops. Vertical flips and large arbitrary rotations were excluded because they produce orientations that are physically implausible with respect to gravity and the hardware. No synthetic towers, generated defects, copied damage patches, or non-tower structural photographs were used for training or evaluation.
Table 3.
Principal implementation settings.
Three variants were trained. Shared-FPN uses the ConvNeXt pyramid and four heads without feature modulation, boundary/topology loss, high-resolution detail residual, or tower gate. Task-routing adds bounded feature modulation while retaining the standard task-specific losses. Tower-HMT adds boundary supervision, conductor clDice, the finest-level residual, and the detached tower gate. Early stopping is validation-driven, so the selected epoch may differ across variants. The bolt-head refinement is then applied using the same maximum number of epochs and validation-based AP50 selection.
4.2. Evaluation Protocol
Evaluation was designed to capture task accuracy, boundary quality, and operational review burden. Corridor and component segmentation are assessed using foreground mIoU, foreground Dice, pixel accuracy, class-wise IoU, and tolerance-aware boundary F1. Corridor mIoU averages the IoUs of the conductor and tower classes, whereas component mIoU averages the IoUs of the tower, insulator, spacer, damper, and plate classes. Because the STN targets are box-conditioned masks, component scores quantify agreement with the prepared supervision rather than accuracy against manually delineated polygons. Boundary F1 is computed from the semantic predictions and is used to assess contour quality, including that of variants trained without boundary-loss supervision.
Missing-bolt localization is evaluated using AP50, AP75, mean AP over IoU thresholds from 0.50 to 0.95 [43], precision, recall, F1 at a confidence threshold of 0.25, and the number of predictions per image. Threshold curves are also reported to characterize the trade-off between recall and review workload. Condition recognition is assessed using macro-F1, accuracy, component-family macro-F1, and confusion matrices. Macro-F1 is treated as the primary measure because it prevents the dominant normal class from obscuring errors in corrosion, missing-cap, and bird-nest recognition.
Robustness is examined by applying brightness, blur, and compression perturbations to held-out real images. Sensitivity analyses vary the tower-prior coefficient α at inference and re-letterbox the TTBM-DET-Det test images at different resolutions, recording AP50 and latency. Activation and probability maps are used only for interpretation. Checkpoints are selected on validation data before final evaluation on the held-out test sets. Per-image outputs are retained for potential bootstrap and paired Wilcoxon analyses [44,45]; however, as the reported experiments use a single seed, conclusions are based on metric differences, class-wise errors, and failure cases rather than claims of statistical significance.
5. Results and Discussions
5.1. Optimization and Checkpoint Behavior
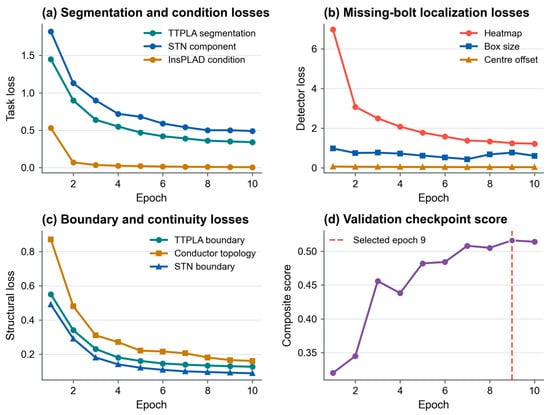
Following the definition of common training and evaluation controls, the learning dynamics were examined to determine whether the four tasks converged under the shared optimization schedule. Figure 4 shows a consistent decline in the segmentation, condition, boundary, and topology losses, with no evidence of late-stage divergence. The condition loss decreases most rapidly, indicating that the global classification head adapts earlier than the spatial prediction heads. By contrast, the conductor-topology loss declines more gradually than the boundary losses, which is consistent with the greater difficulty of preserving connectivity in thin and partially occluded conductors. Within the bolt branch, the heatmap term remains substantially larger than the size and offset terms throughout training. The principal localization difficulty therefore lies in identifying sparse bolt centers rather than refining box geometry after a candidate has been identified.
Figure 4.
Tower-HMT training dynamics. (a) Segmentation and condition losses; (b) missing-bolt heatmap, size, and offset losses; (c) structural objectives; and (d) composite validation score used for checkpoint selection. Curves are unsmoothed values recorded at each epoch.
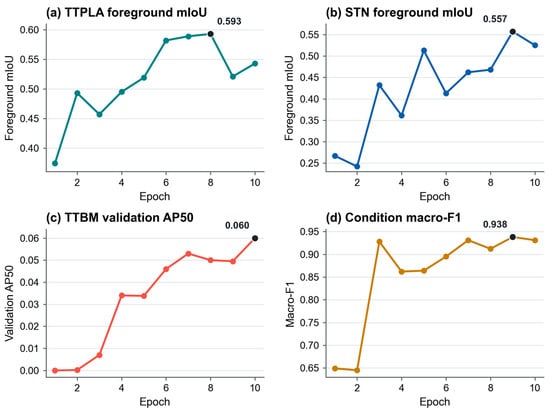
Validation performance is less monotonic than the training losses. As shown in Figure 5, TTPLA foreground mIoU improves relatively steadily and reaches 0.593 at epoch 8, whereas STN foreground mIoU exhibits larger fluctuations before attaining 0.557 at epoch 9. This difference is consistent with the stronger polygon supervision in TTPLA and the greater uncertainty of the box-conditioned STN masks. Condition macro-F1 rises rapidly after the second epoch and remains above 0.86 thereafter, although the fluctuations between epochs show that the near-zero training loss does not imply monotonic generalization. Missing-bolt AP50 improves more slowly and reaches only 0.060 at epoch 10, confirming that small-defect localization remains the most difficult task during joint training.
Figure 5.
Task-level validation trajectories for (a) TTPLA corridor segmentation, (b) STN box-conditioned component-parsing agreement, (c) TTBM-DET missing-bolt localization, and (d) InsPLAD condition recognition. Black markers denote the maximum of each individual curve, which need not coincide with the composite checkpoint.
The task-specific maxima occur at different epochs, reflecting competition between datasets, supervision types, and spatial scales within the shared representation. The composite validation score reaches its highest value at epoch 9 and changes only marginally at epoch 10. Selecting epoch 9 therefore retains the best STN and condition results while remaining close to the strongest TTPLA and bolt checkpoints. These results support the use of a composite validation criterion rather than checkpoint selection based on a single loss or task metric. They also motivate the subsequent bolt-specific refinement stage, since additional localization improvement is required after the shared multitask representation has stabilized.
5.2. Quantitative Comparison and Ablation
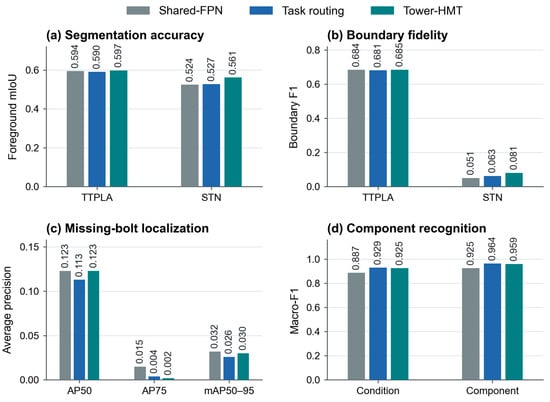
To assess whether the architectural additions provide consistent benefits across the heterogeneous task hierarchy, the ablation results are considered jointly. Table 4 and Figure 6 show clear task-dependent effects. Relative to Shared-FPN, Tower-HMT raises STN foreground mIoU from 0.524 to 0.561 and boundary F1 from 0.051 to 0.081, whereas the TTPLA changes are marginal. Condition macro-F1 improves from 0.887 to 0.925 but remains slightly below the value for task routing (0.929); bolt AP50 is unchanged at 0.123, and mAP50-95 decreases from 0.032 to 0.030. The complete design therefore benefits weakly supervised component parsing more clearly than corridor segmentation, condition recognition, or bolt localization. Since all variants were trained with a single seed, the observed differences should be interpreted as descriptive effect estimates rather than statistically conclusive improvements.
Table 4.
Held-out test performance of the controlled model variants.
Figure 6.
Controlled ablation across Shared-FPN, task routing, and Tower-HMT. (a) Foreground segmentation mIoU; (b) tolerance-aware boundary F1; (c) refined missing-bolt precision metrics; and (d) condition and component macro-F1. Numerical labels show the recorded held-out values.
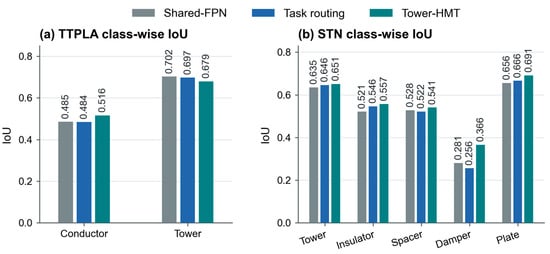
To identify the categories underlying the aggregate segmentation results, Table 5 and Figure 7 resolve IoU at the class level. On TTPLA, conductor IoU increases by 0.031 while tower IoU decreases by 0.023, indicating a redistribution of accuracy rather than a uniform improvement. On STN, all five foreground classes improve, with the largest gain for the damper class (0.281 to 0.366), followed by the insulator and plate classes. This pattern is compatible with improved representation of small or boundary-dominated structures. However, boundary loss, task routing, the high-resolution residual, and the tower gate are introduced jointly, while class frequency and weak-mask quality also vary across categories. The class-wise gains therefore cannot be attributed to a single module without additional controlled ablations and polygon-level validation.
Table 5.
Foreground class-wise IoU on the held-out segmentation tests.
Figure 7.
Class-wise IoU for (a) TTPLA conductor and tower masks and (b) STN tower, insulator, spacer, damper, and plate masks. STN values refer to box-conditioned supervision.
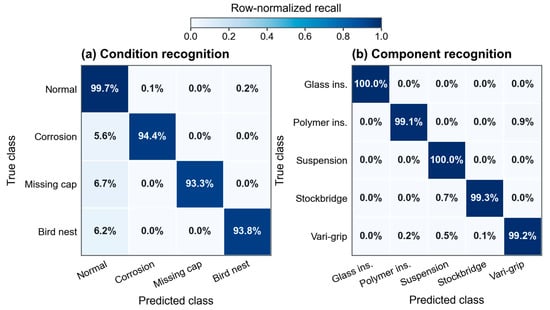
Figure 8 shows recall of 99.7% for normal components, compared with 94.4%, 93.3%, and 93.8% for corrosion, missing cap, and bird nest, respectively. Most errors in the less frequent conditions are assigned to the normal class rather than misclassified among fault categories. Consequently, the overall accuracy of 0.995 overstates performance on actionable conditions, and macro-F1 and class-specific recall provide a more informative summary. The nearly diagonal component matrix is consistent with the corresponding macro-F1 of 0.959, but this auxiliary result does not establish that condition decisions rely on defect-specific evidence. Probability calibration and evaluation under shifted class prevalence remain necessary before confidence scores are used for maintenance prioritization.
Figure 8.
Row-normalized confusion matrices for (a) condition and (b) component recognition on the natural held-out InsPLAD distribution. Percentages represent recalls within each true row.
5.3. Same-Split External Baselines and Multi-Seed Reproducibility
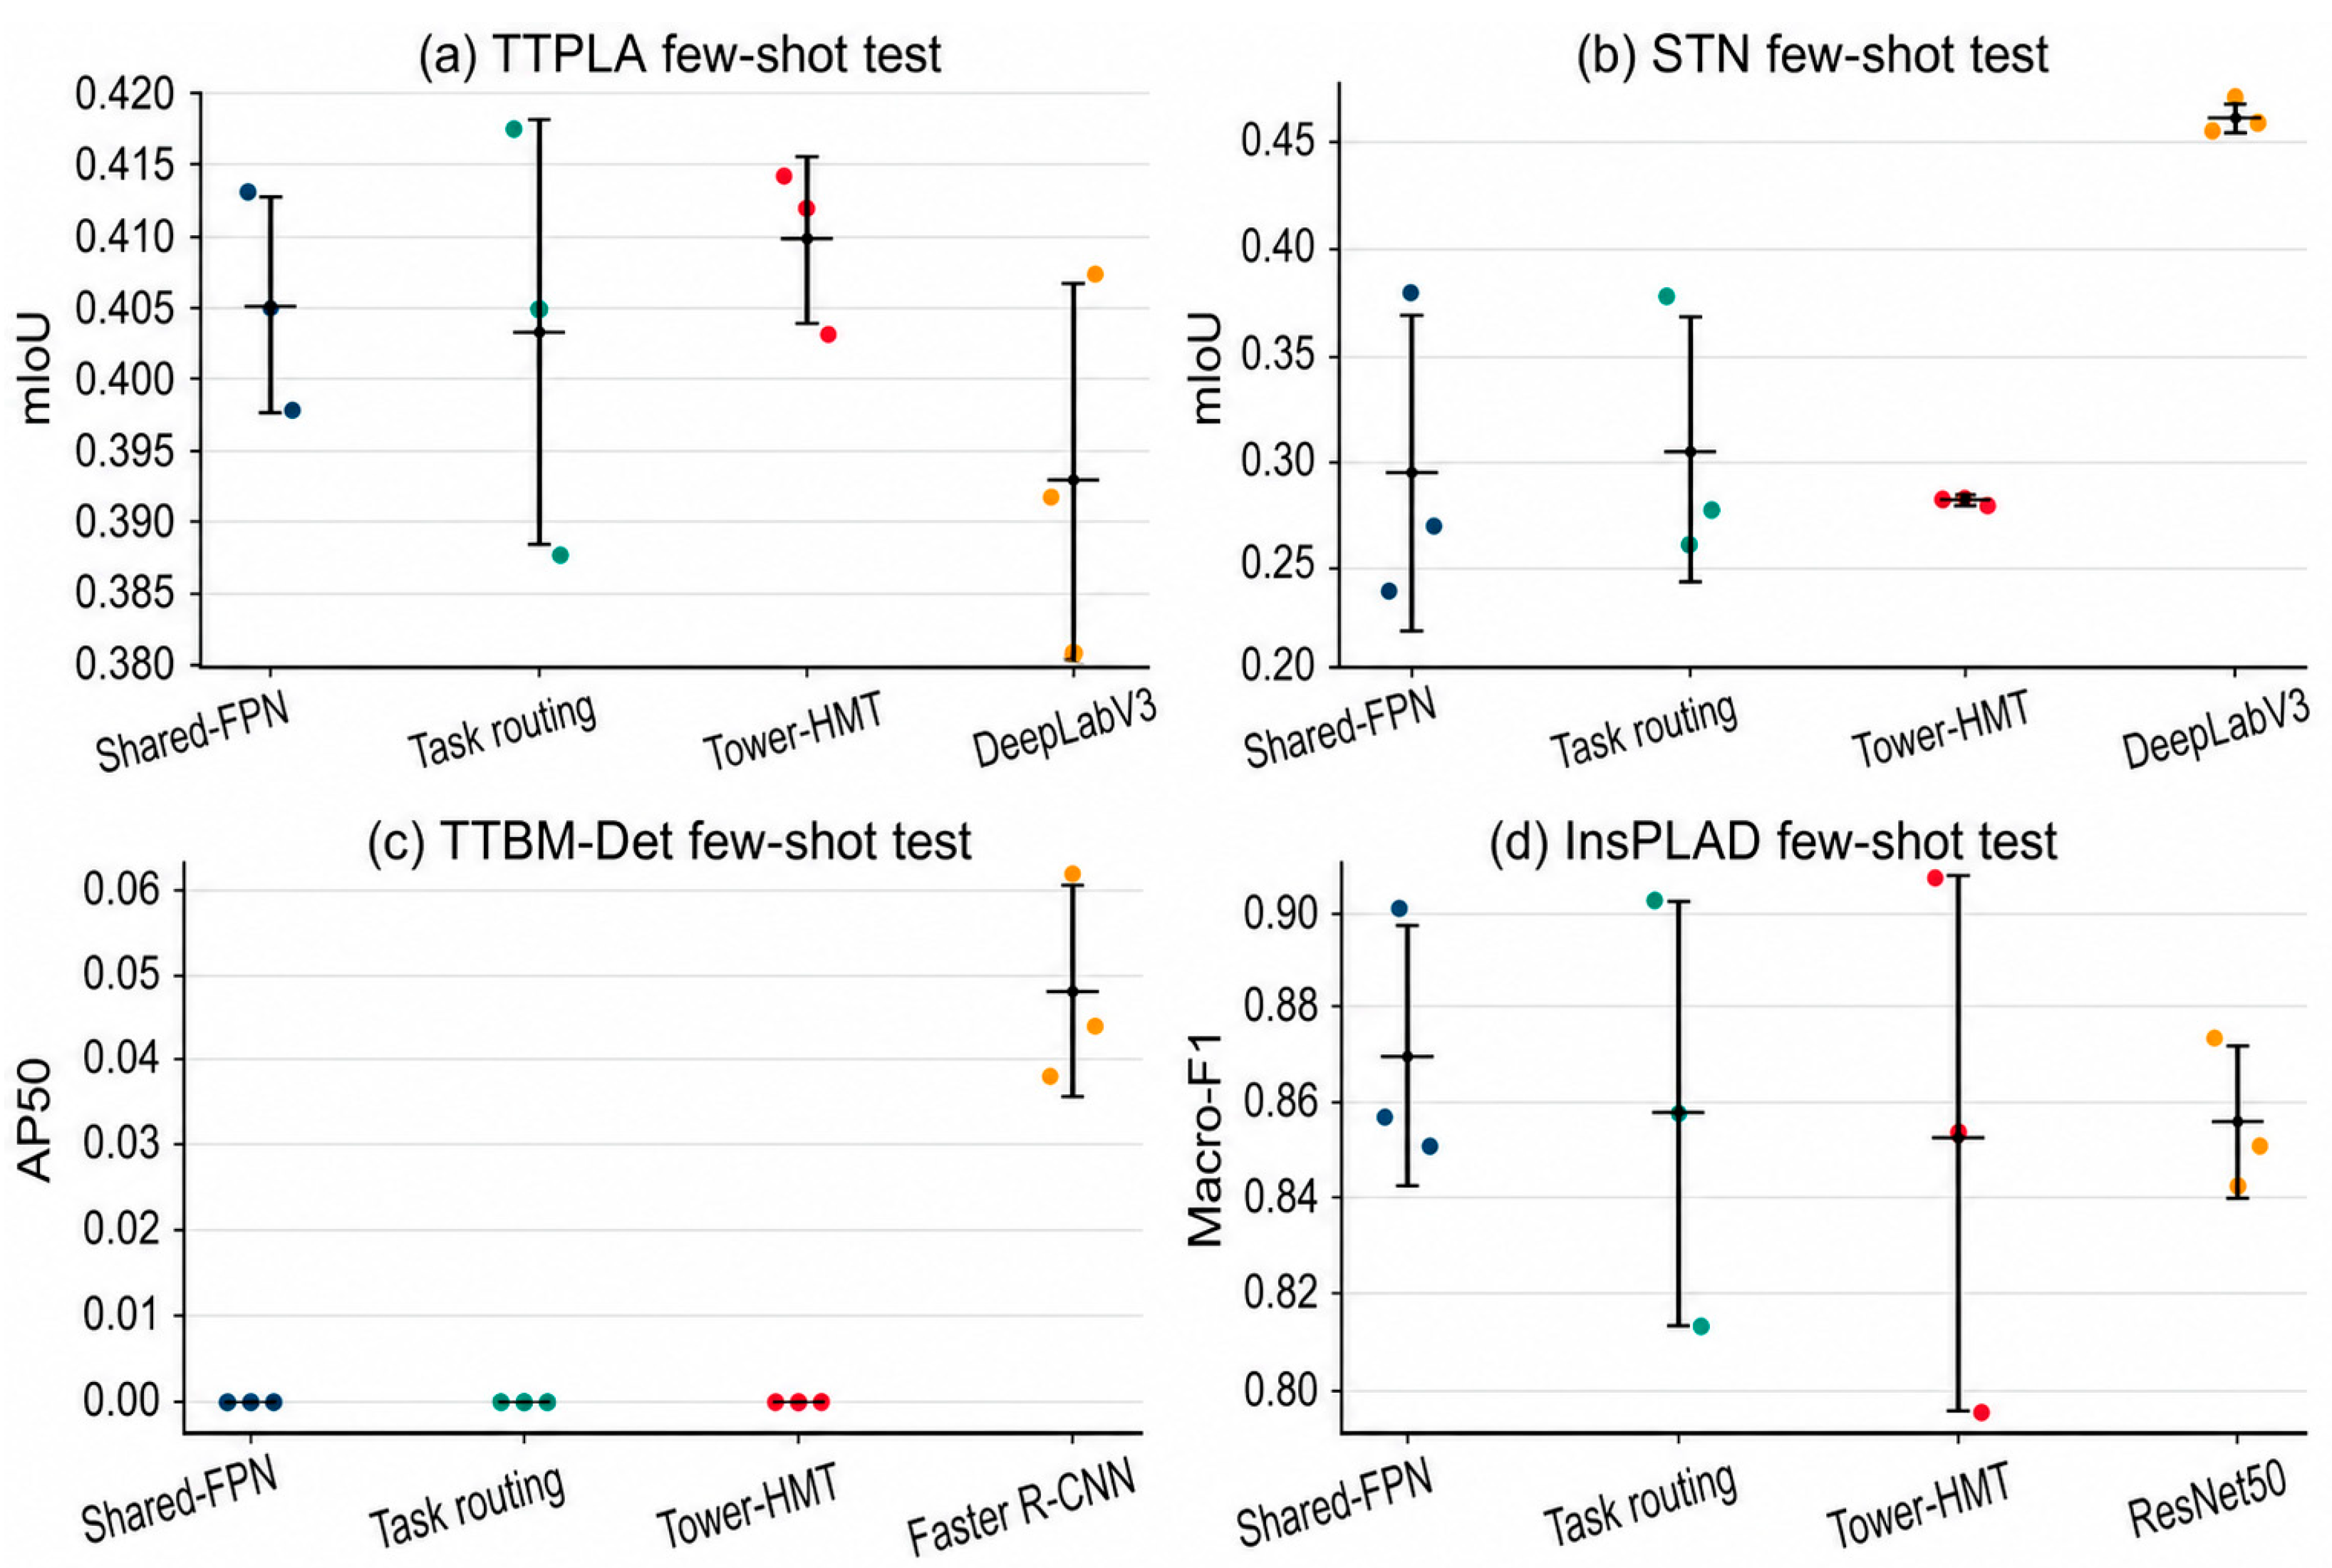
Table 6 and Figure 9 summarize the controlled few-shot results on the unchanged test sets. All methods in a task used the same deterministic training subset, and every point in Figure 9 corresponds to an independent initialization seed. Among the multitask variants, Tower-HMT achieved the highest TTPLA mIoU (0.4098 ± 0.0059), compared with 0.4051 ± 0.0077 for Shared-FPN and 0.4033 ± 0.0150 for task routing. The paired Tower-HMT minus Shared-FPN difference averaged +0.0048 and was positive in all three seeds, ranging from +0.0014 to +0.0074. This was the only small but directionally repeatable gain of the complete architecture in the low-shot study.
Table 6.
Controlled few-shot test performance under identical deterministic subsets and three training seeds (mean ± sample standard deviation).
Figure 9.
Controlled few-shot results on the unchanged test sets. Points denote individual seeds; black bars show the mean ± sample standard deviation. Each task-specific baseline used the same training subset and held-out test set as the multitask variants.
The task-specific comparators alter the interpretation of the single-run ablation. DeepLabV3-ResNet50 achieved an STN mIoU of 0.4701 ± 0.0081, clearly above Tower-HMT (0.2778 ± 0.0025) and the other multitask variants. Faster R-CNN-ResNet50-FPN reached 0.0481 ± 0.0126 AP50 on TTBM-Det, whereas the joint heatmap detector remained near zero without the high-resolution refinement stage. Under limited annotation, fine component masks and tiny boxes therefore benefited more from a specialized decoder and proposal-based localization than from hierarchical feature sharing alone.
Condition recognition was more competitive across architectures. Shared-FPN obtained the highest InsPLAD mean (0.8693 ± 0.0275), while the ResNet50 dual-head baseline, task routing, and Tower-HMT achieved 0.8556 ± 0.0162, 0.8576 ± 0.0446, and 0.8525 ± 0.0566, respectively. The overlapping dispersion and inconsistent paired signs do not support a repeatable Tower-HMT advantage. The larger variability also reflects balanced few-shot training evaluated on the unchanged, naturally imbalanced test distribution.
From an engineering perspective, the results favor a modular low-shot deployment: the hierarchical model can retain corridor-scale context and a shared representation, while a dedicated component segmenter and proposal-based bolt detector are used when only a small number of detailed annotations is available. The controlled comparison therefore supports a task-specific claim rather than broad superiority of one architecture across all inspection tasks.
5.4. Qualitative Tower-Scale and Component-Scale Evidence
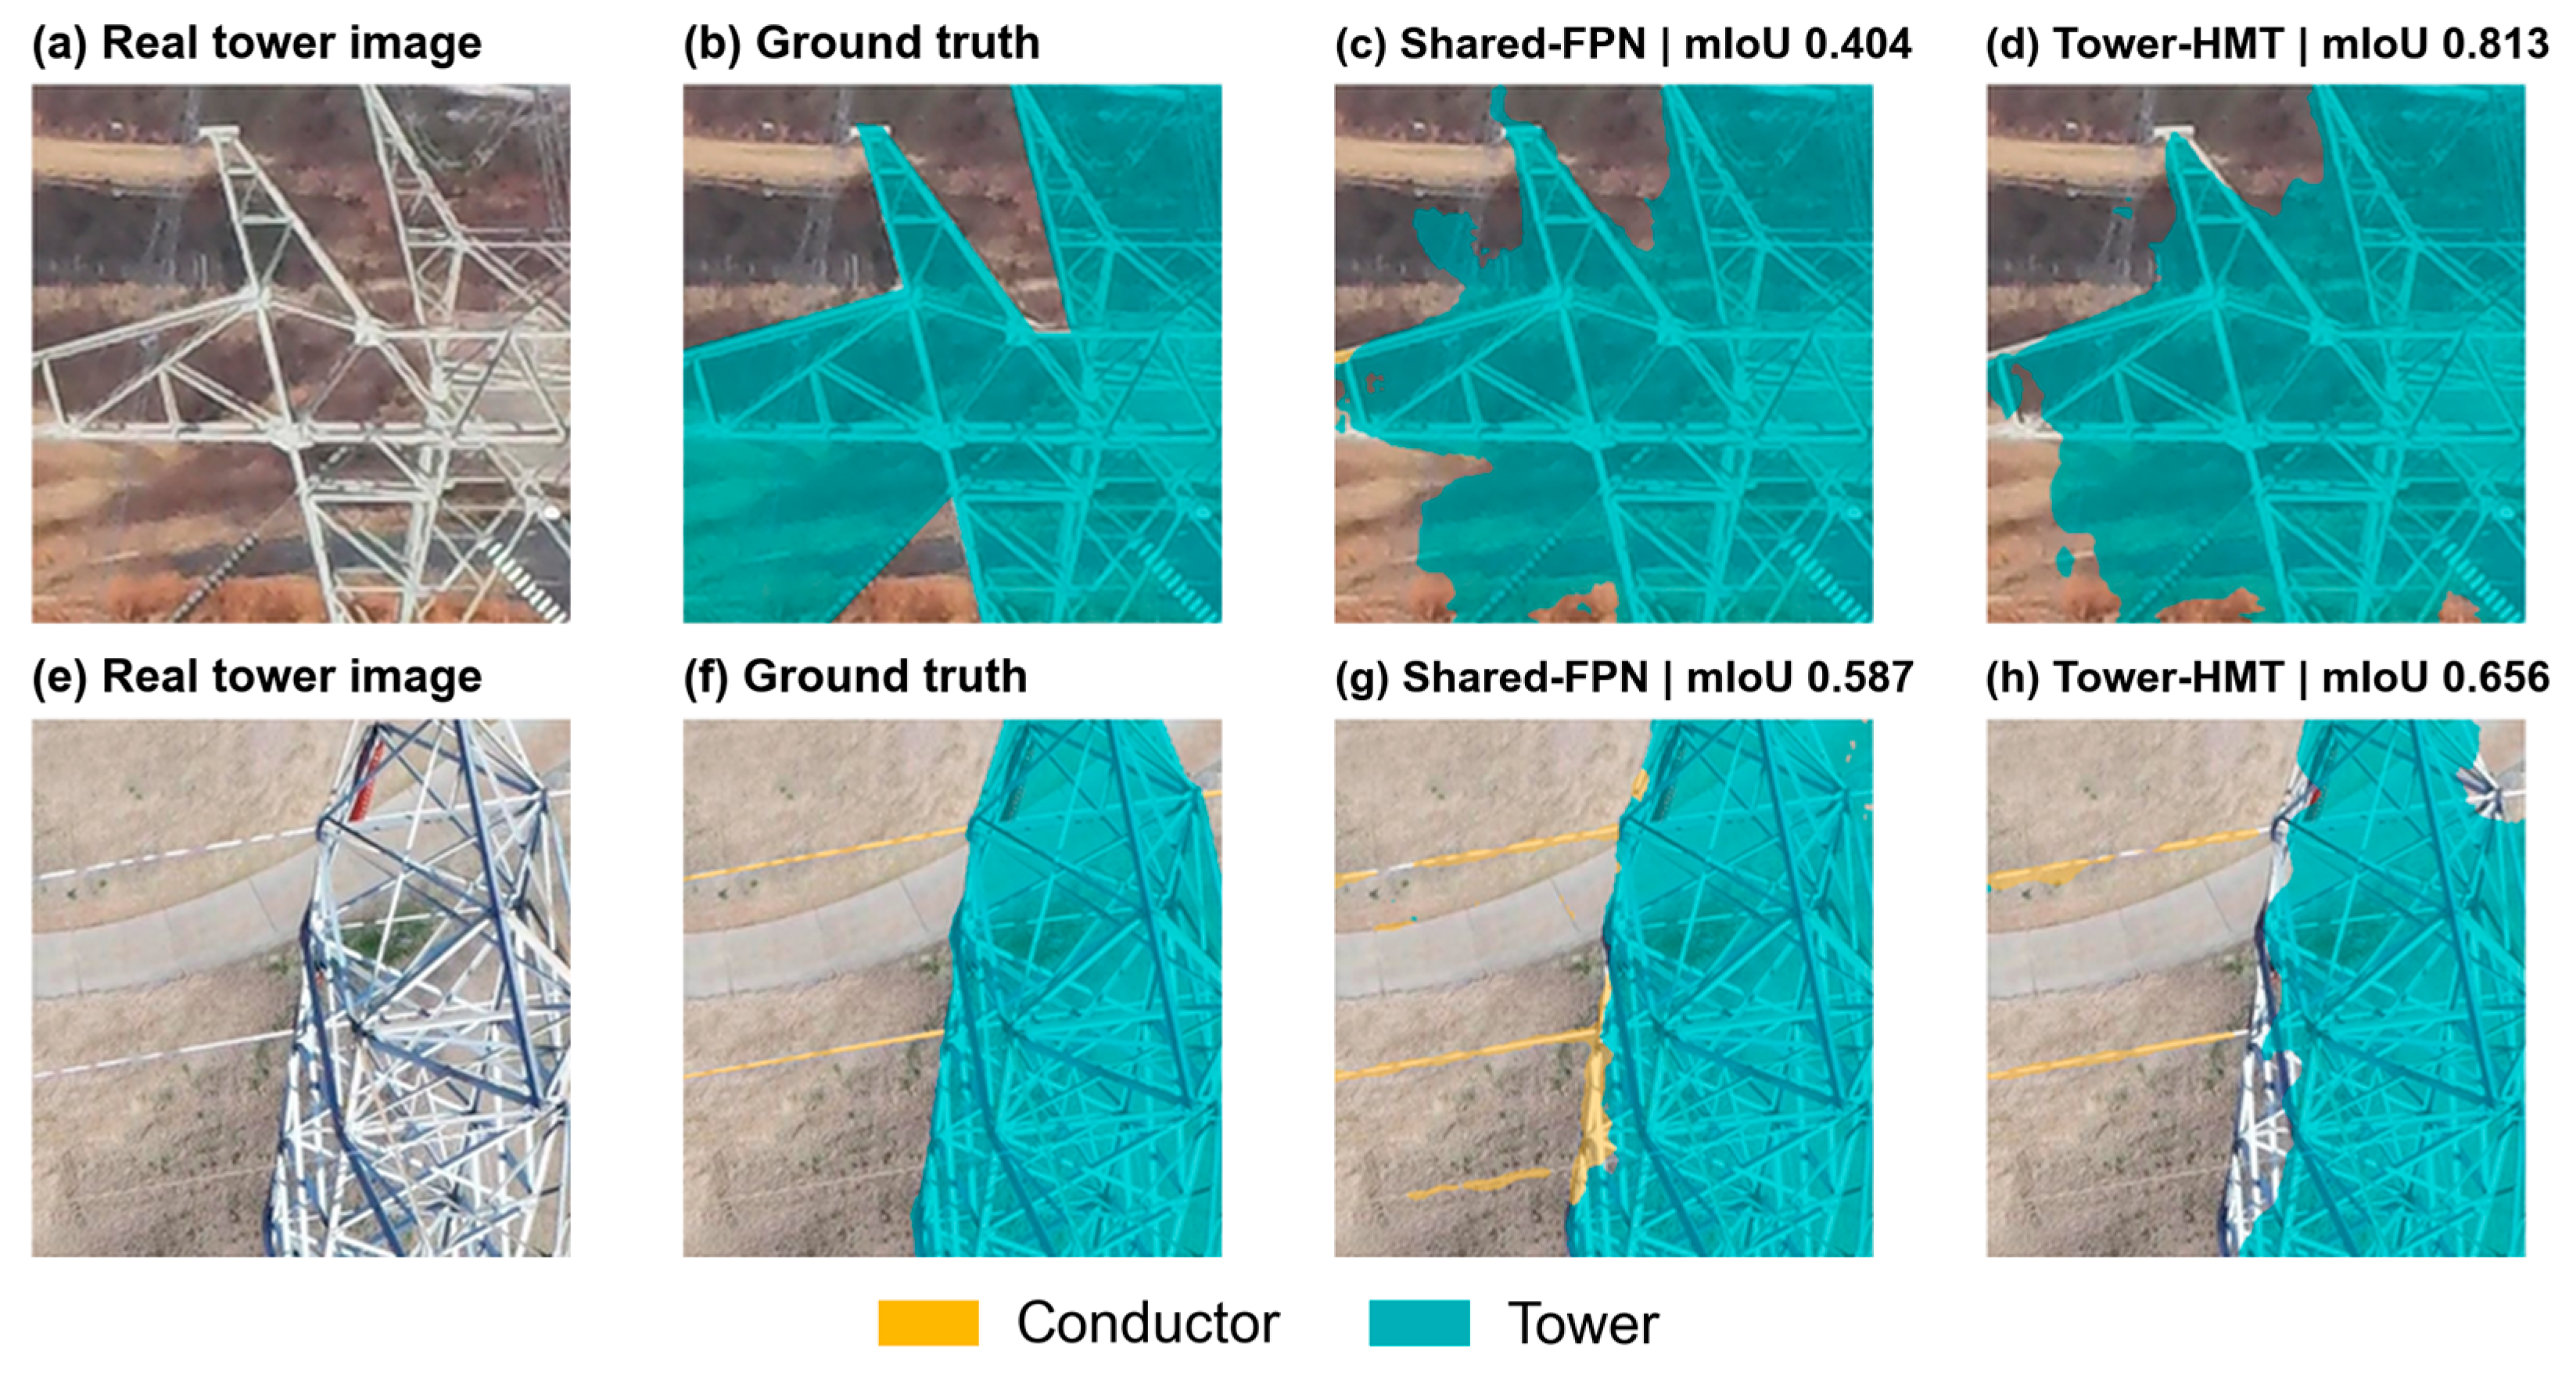
To complement the aggregate metrics with spatial evidence, representative held-out predictions are examined at tower scale. In Figure 10, Tower-HMT raises mIoU from 0.404 to 0.813 in the first example and from 0.587 to 0.656 in the second, mainly by recovering more continuous tower regions and reducing large omissions. The unequal gains indicate that the structural objectives are most effective when missing regions can be recovered from coherent lattice context. Residual errors along tower boundaries and thin conductors nevertheless show continued sensitivity to vegetation, low contrast, and overlapping steel members. These examples clarify the form of the improvement but, as selected cases, do not quantify how frequently it occurs across the test set.
Figure 10.
TTPLA qualitative comparison on real transmission-tower images. Each row shows the image, ground truth, Shared-FPN prediction, and Tower-HMT prediction. Colored overlays are produced directly from held-out masks and model outputs.
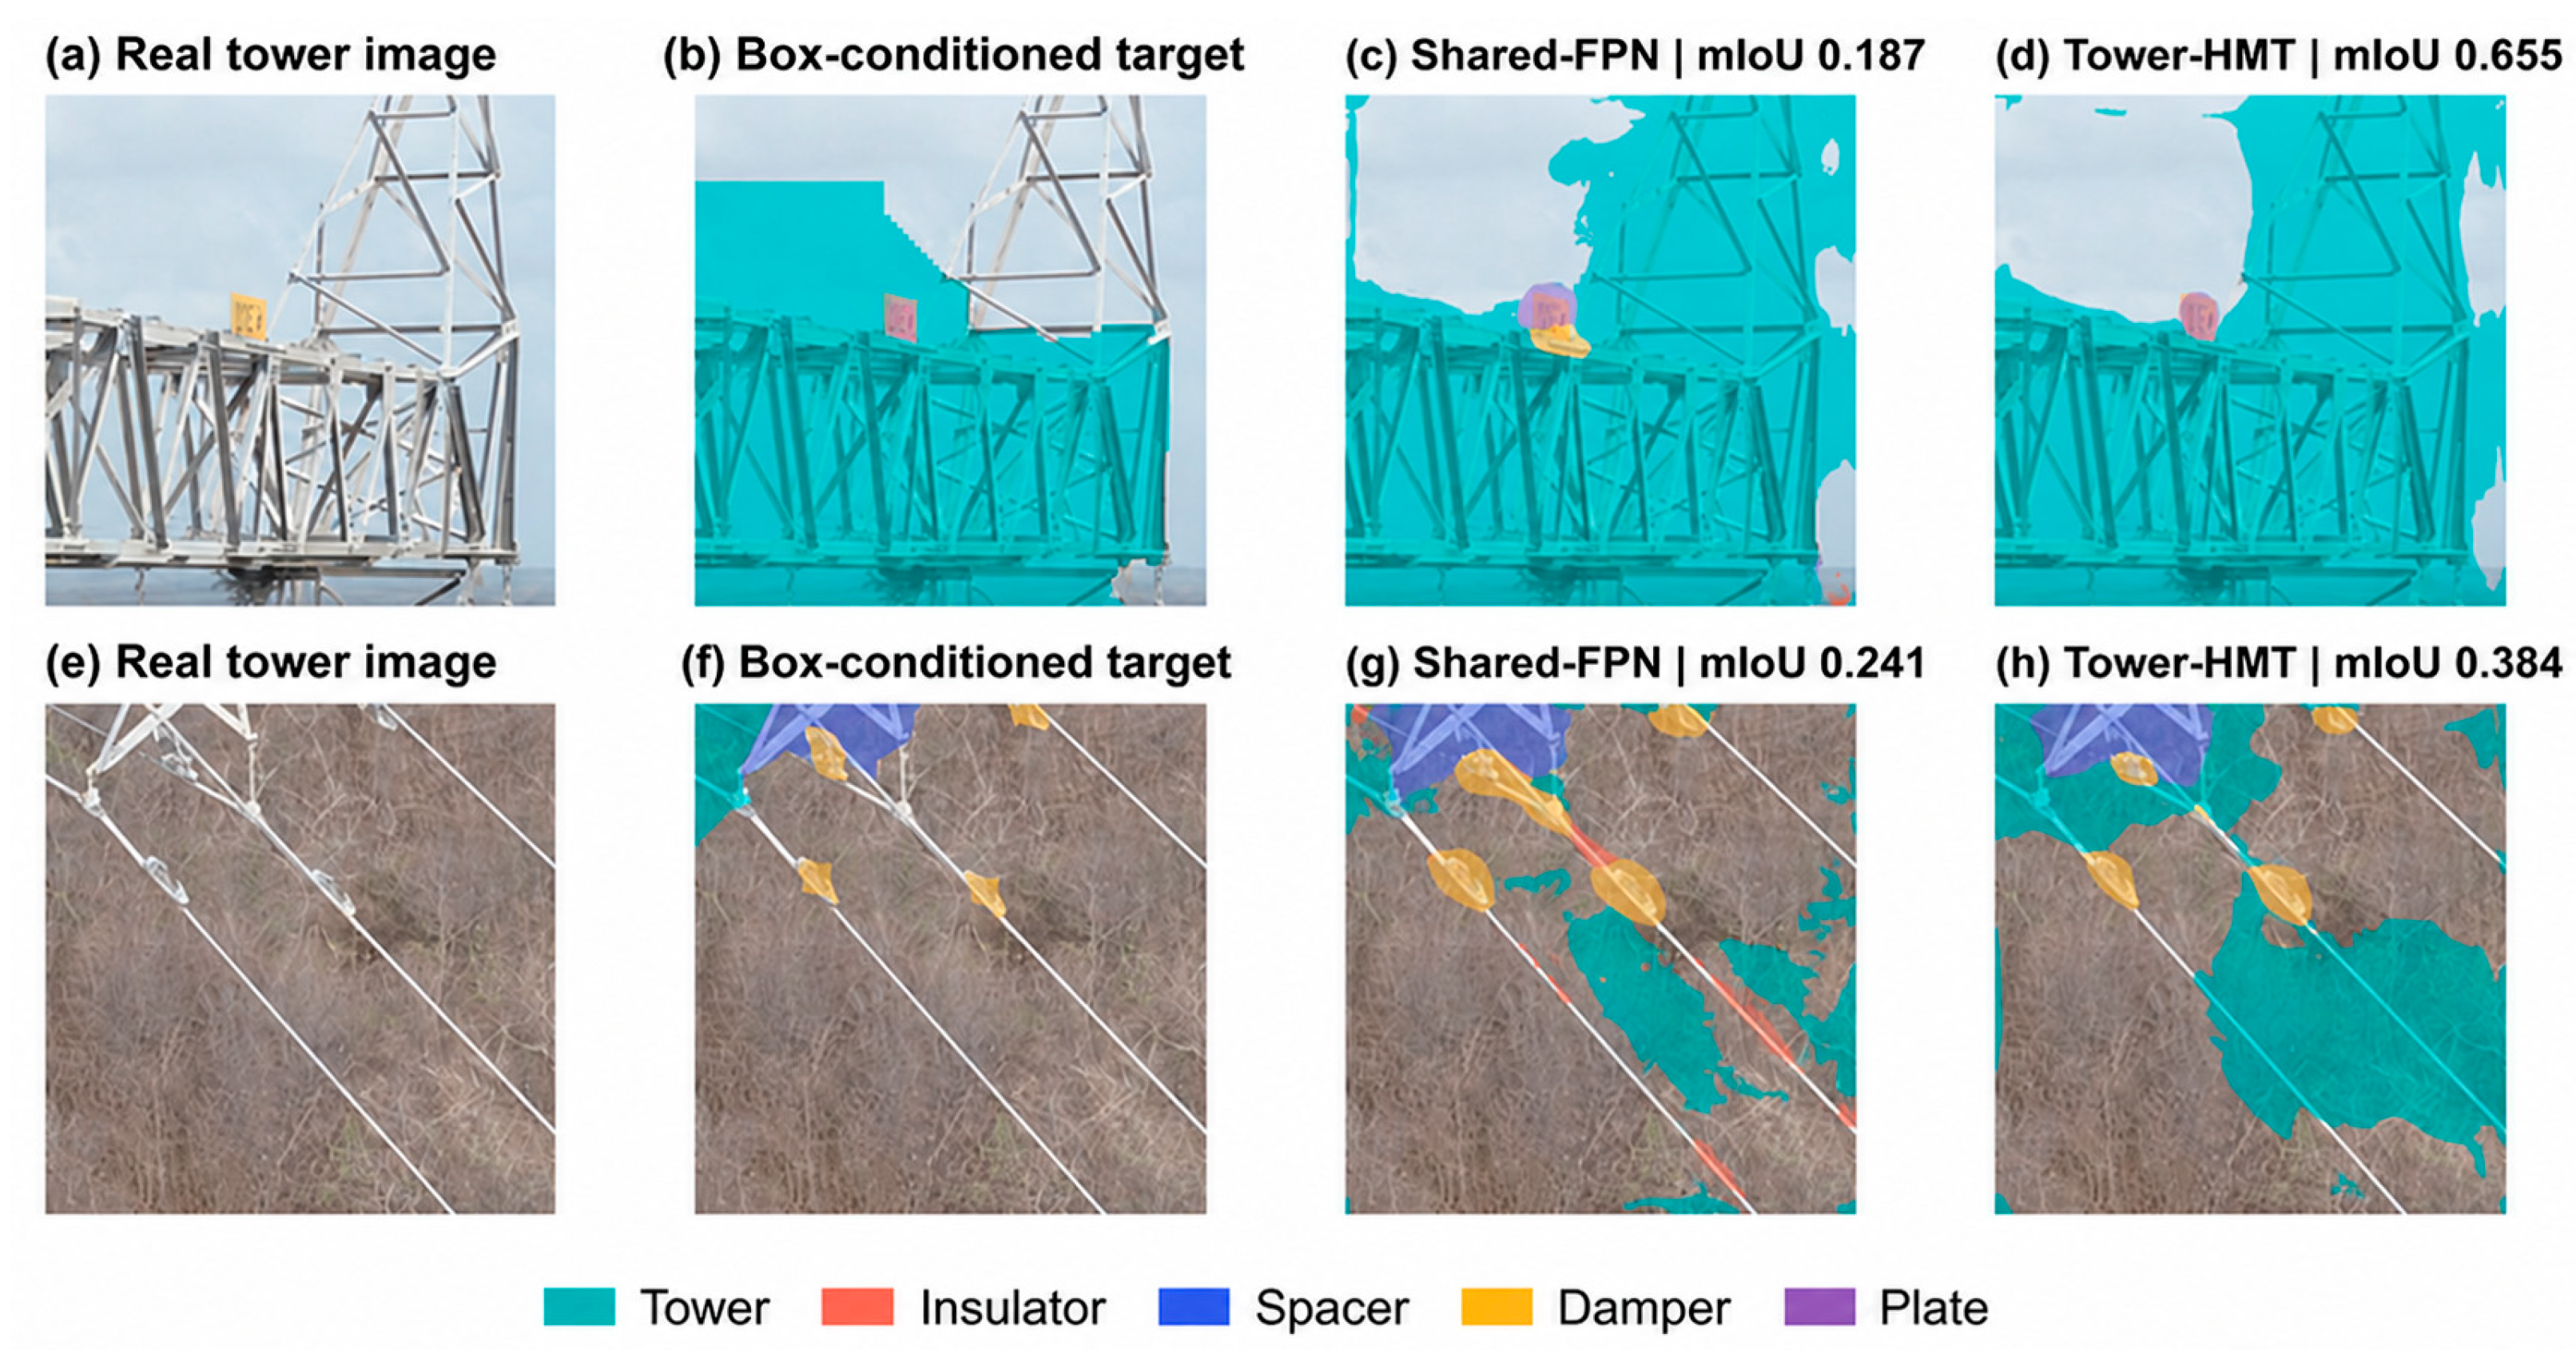
Component-scale results show a similar pattern. Figure 11 records mIoU gains from 0.187 to 0.655 and from 0.241 to 0.384, mainly through reduced foreground spill. Because the masks are box-conditioned, these values measure agreement with weak supervision rather than manual contour accuracy.
Figure 11.
Component parsing results on real lattice-tower images from STN PLAD. The reference masks and corresponding metrics are derived from box-conditioned supervision rather than manually delineated polygon annotations.
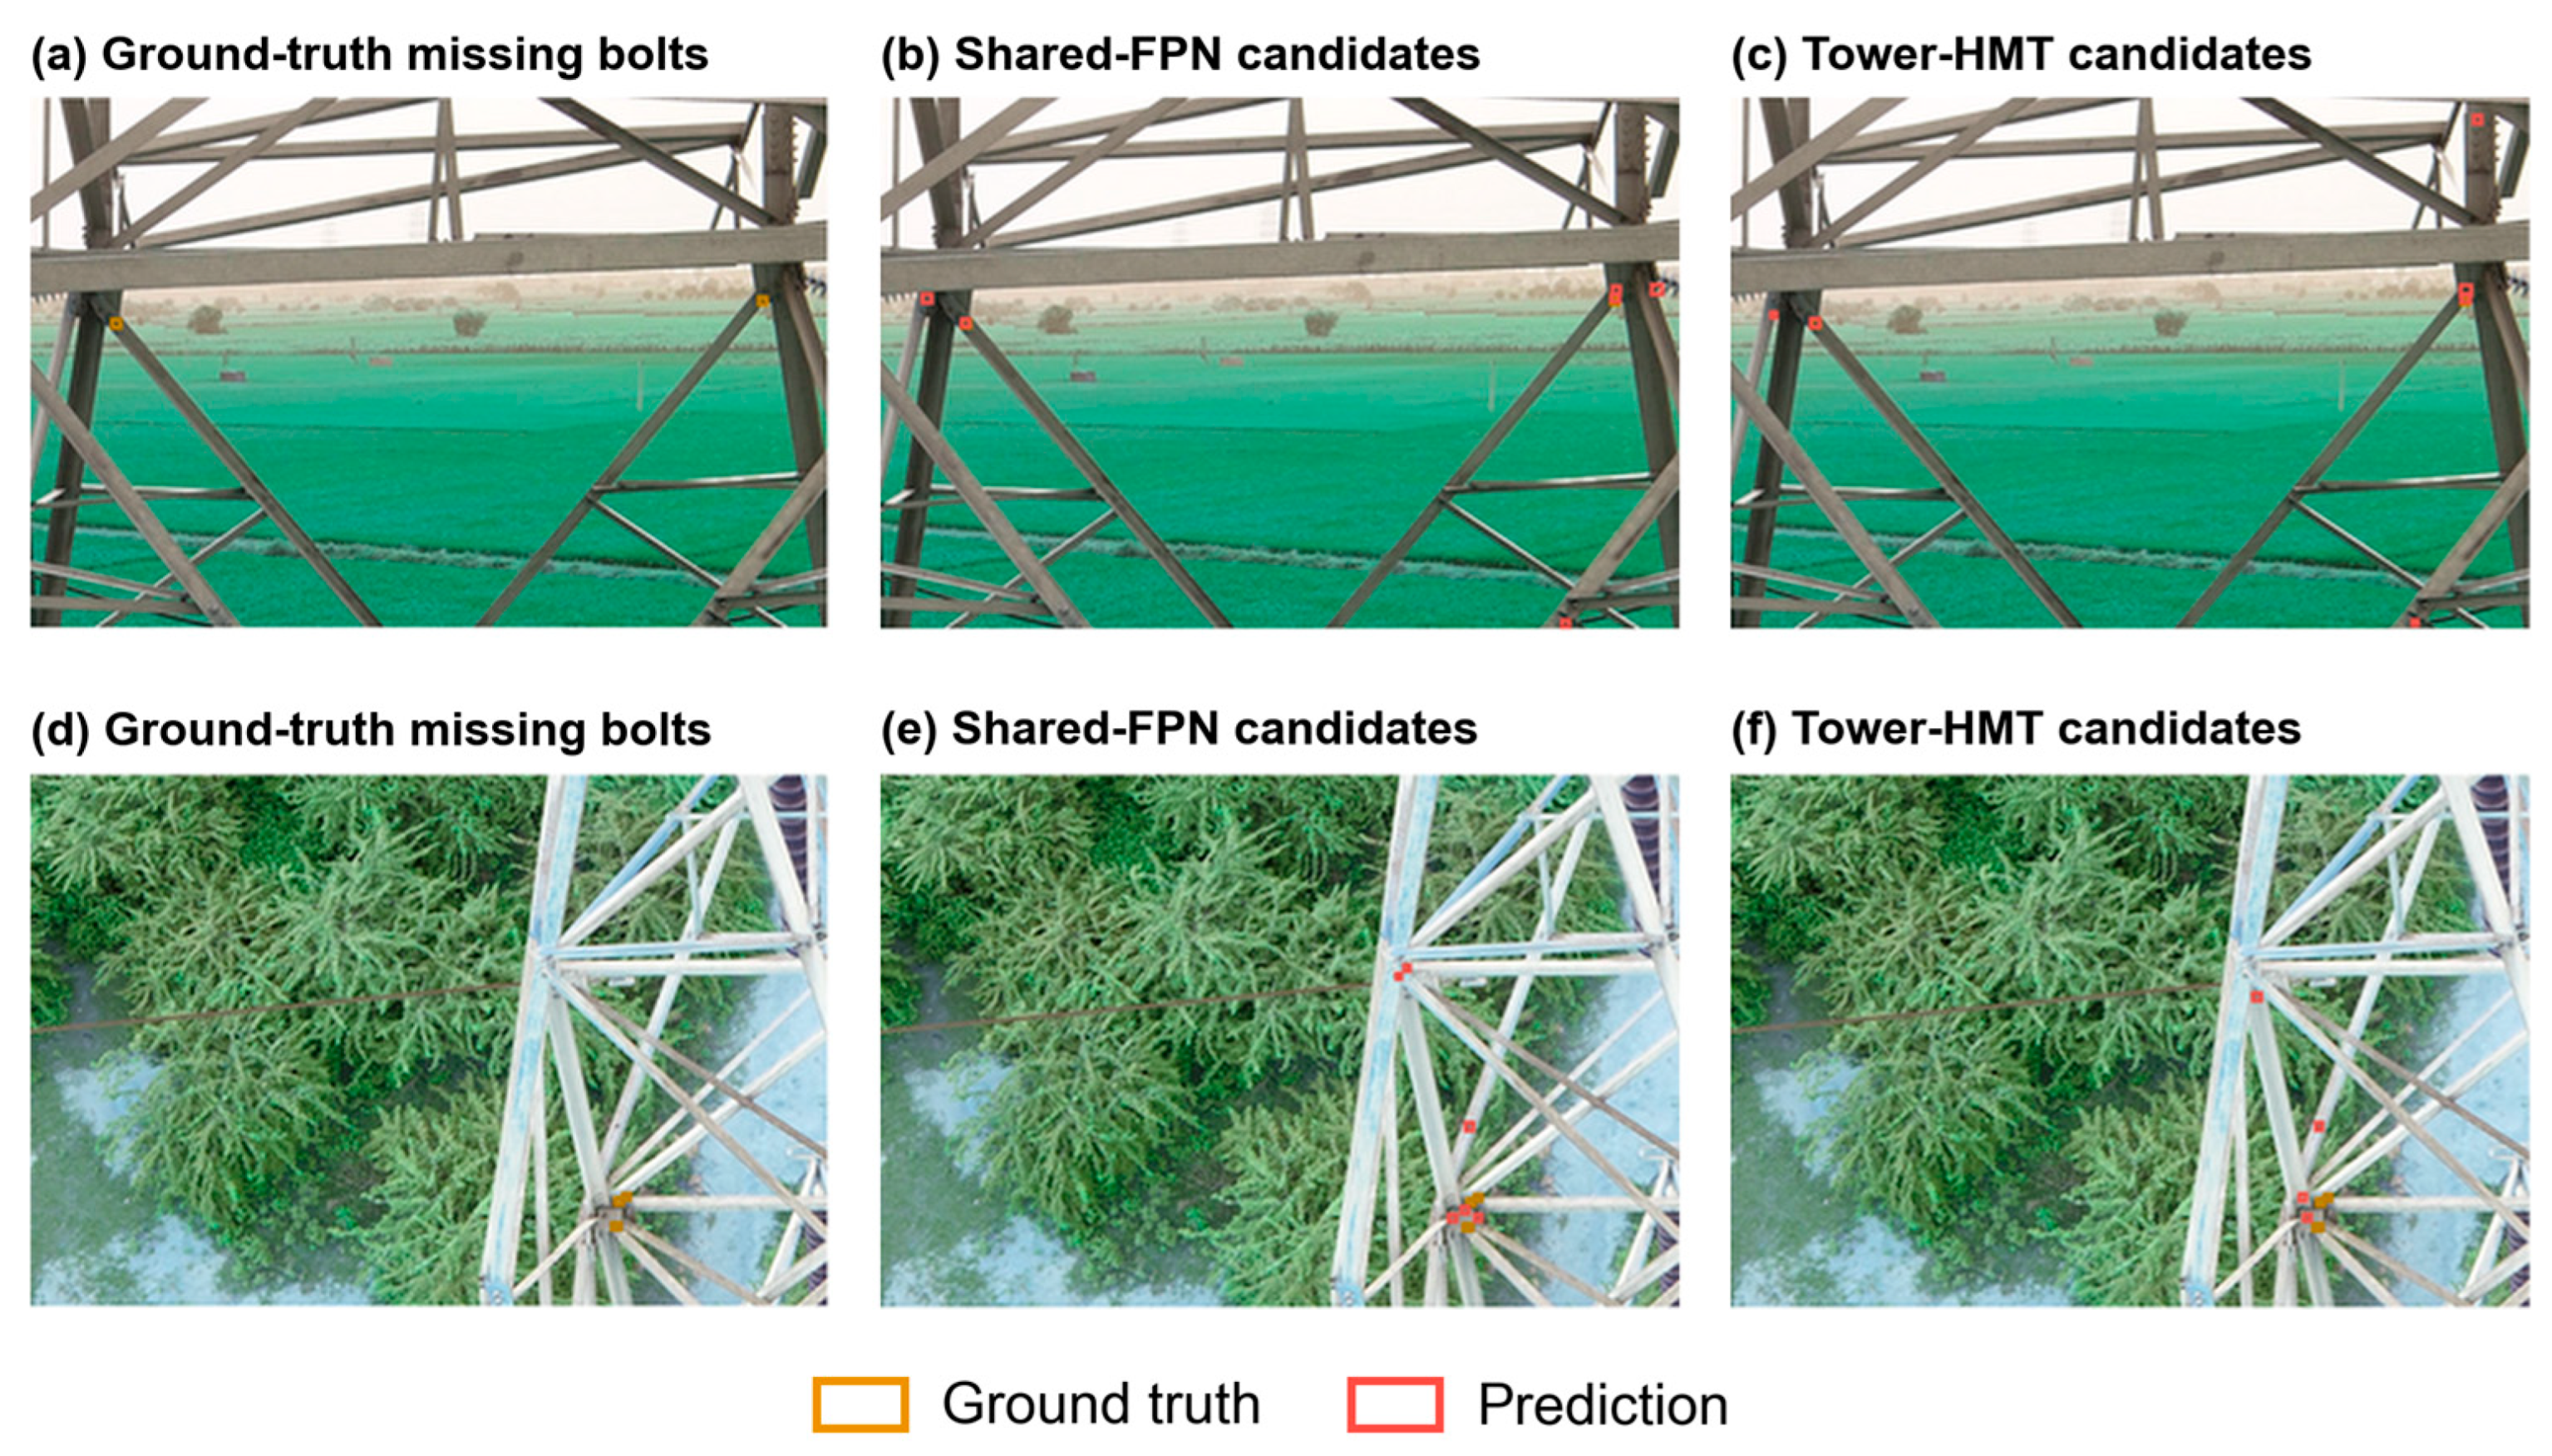
Missing-bolt localization remains more challenging than the other tasks. Figure 12 shows false candidates around repeated holes, plate edges, and lattice junctions, while predicted boxes often deviate from the small reference extents. This pattern explains the marked difference between AP50 and the stricter AP75 and mAP50-95 measures. Since many errors occur on genuine tower hardware, further improvement requires finer fastener representations and more accurate small-box regression rather than off-tower suppression alone.
Figure 12.
Missing-bolt localization on held-out real tower-joint scenes. Yellow boxes denote ground-truth annotations; red boxes denote decoded predictions with confidence labels. Shared-FPN and Tower-HMT use the same final input resolution and refinement schedule.
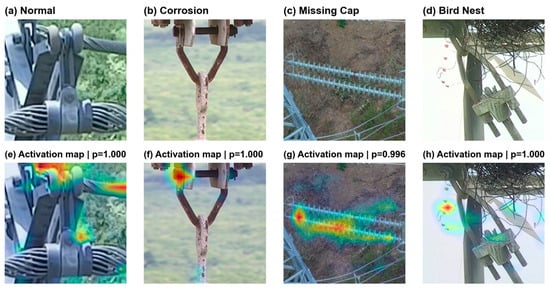
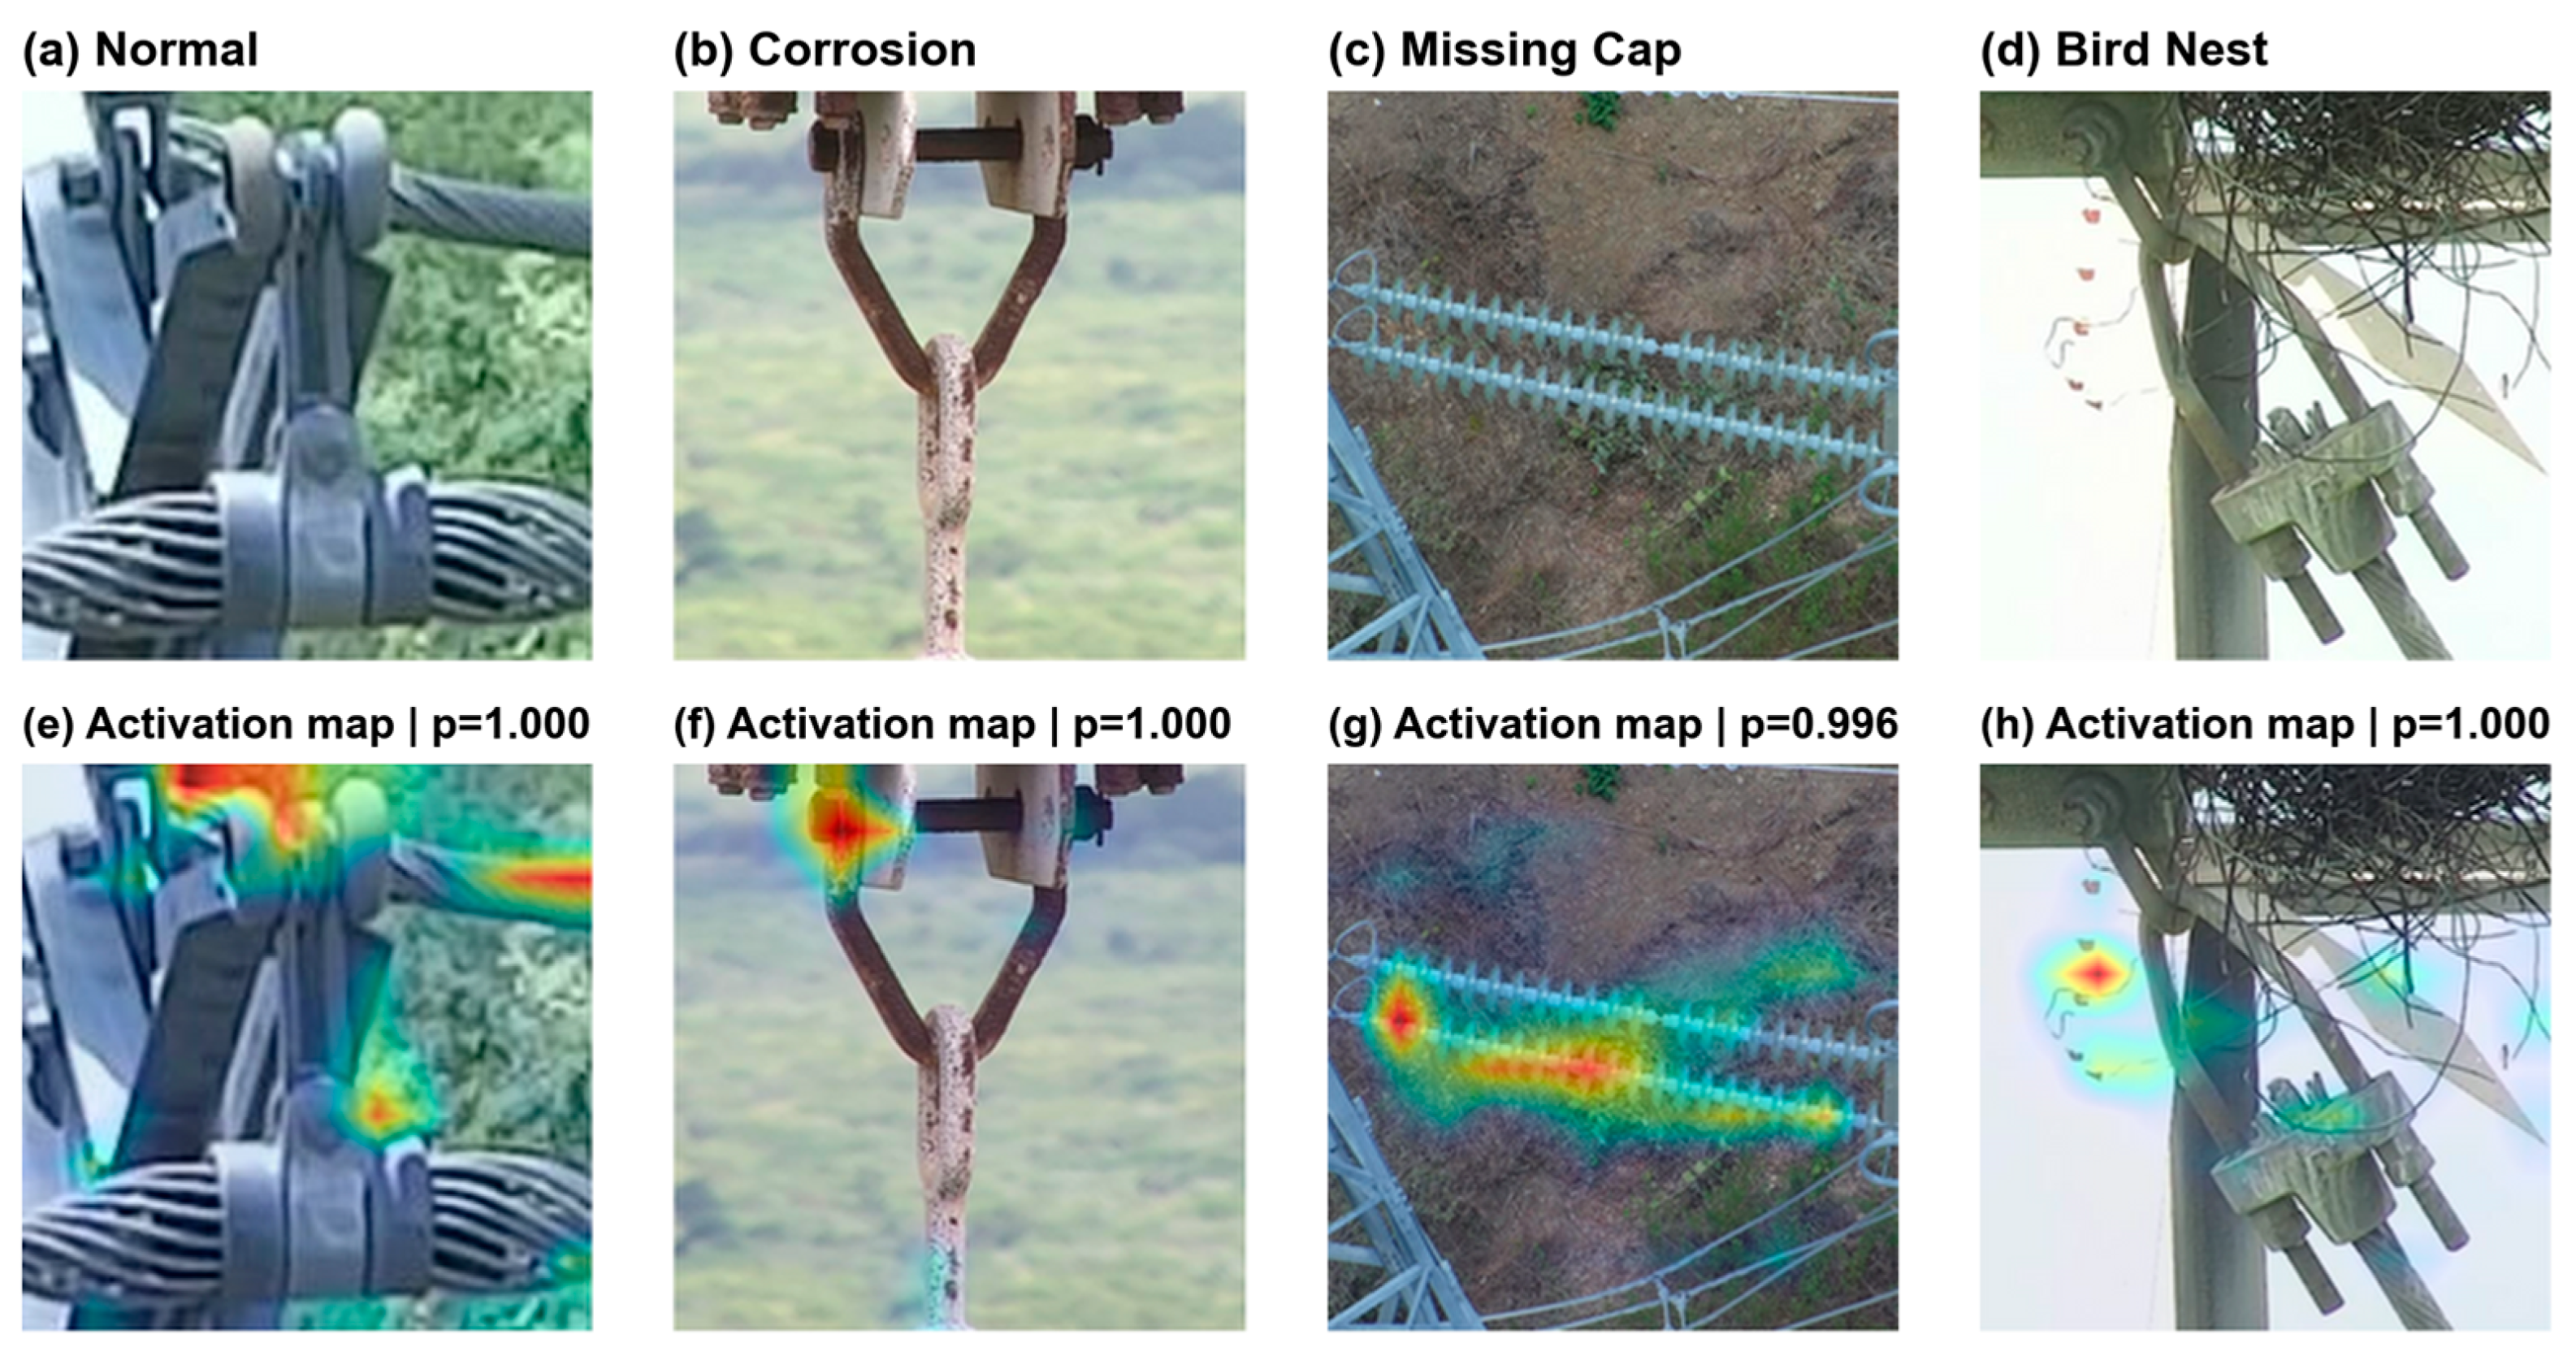
Condition recognition is further examined through activation maps. In Figure 13, abnormal predictions generally emphasize visibly altered hardware or foreign material, whereas the normal response is more diffuse. This correspondence supports case-level interpretation but does not constitute defect segmentation or causal evidence. The displayed probabilities remain model confidence scores and require calibration before operational use.
Figure 13.
Tower-component condition interpretation. Top row: real InsPLAD component crops. Bottom row: gradient-weighted activation maps for the predicted condition. Probabilities are shown for transparency; maps are explanatory outputs and are not used as labels. In the activation maps, warmer colors (red and yellow) indicate stronger model responses, whereas cooler colors (green and blue) indicate weaker responses.
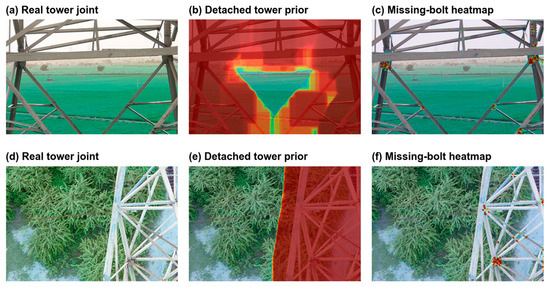
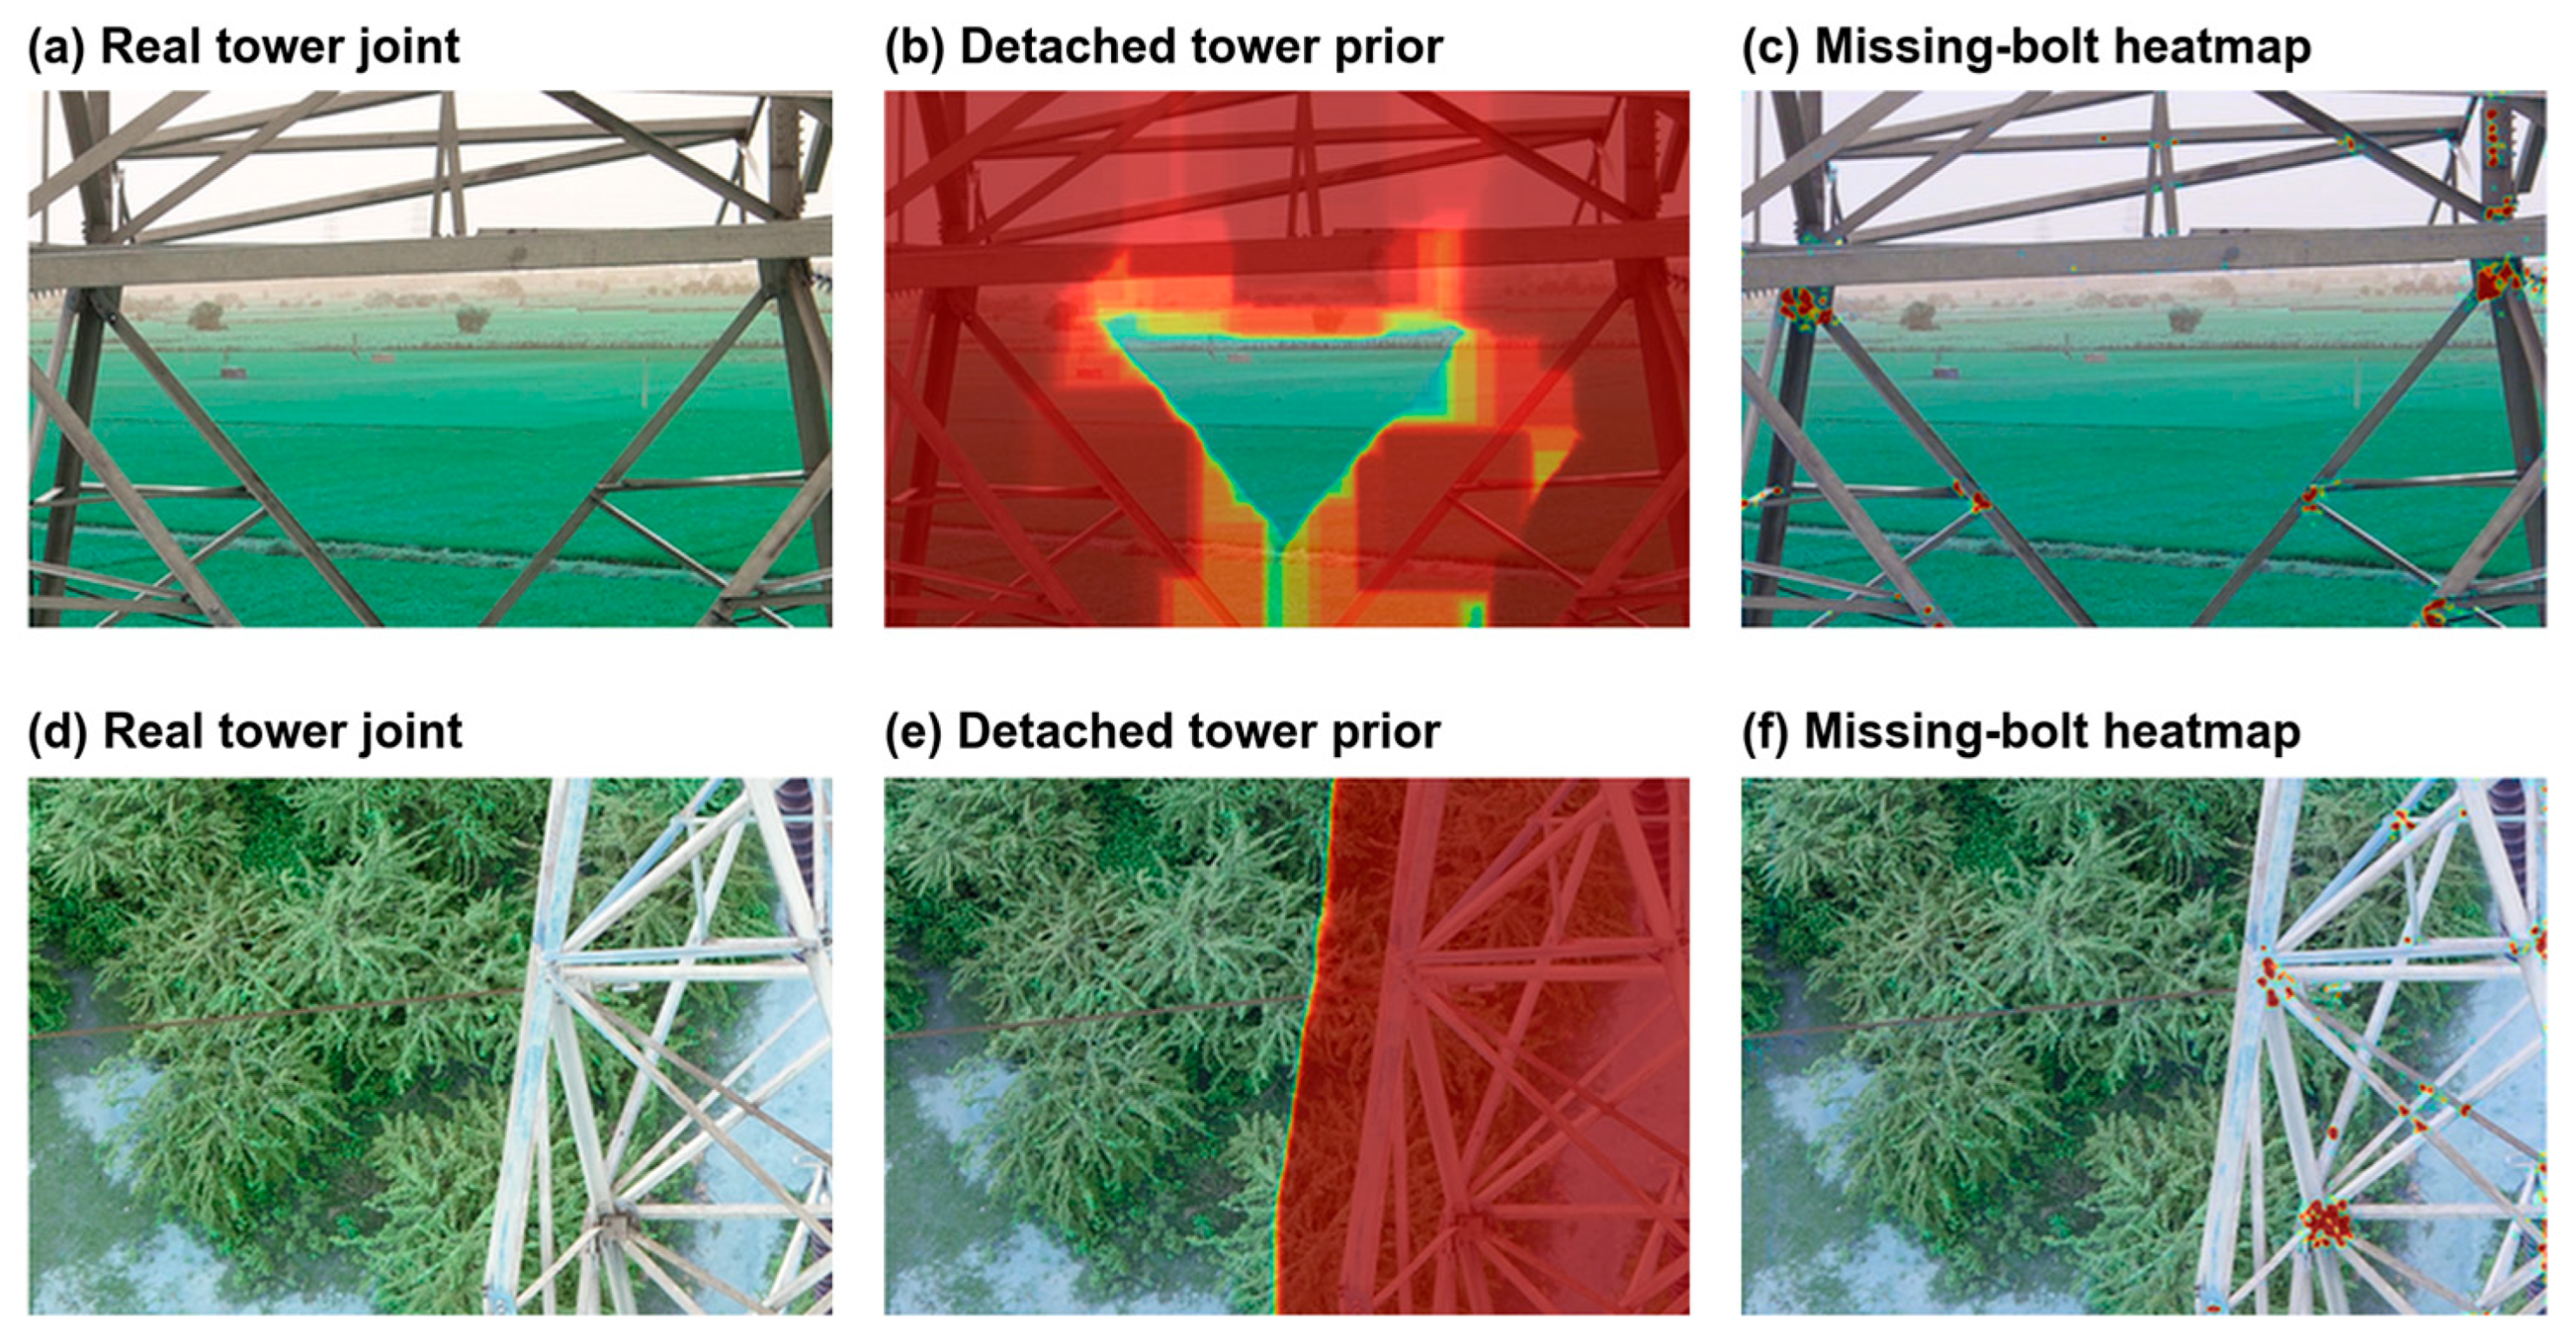
Finally, Figure 14 visualizes the detached tower prior and its spatial relationship with the bolt heatmap. The prior emphasizes responses in tower-associated regions while leaving off-tower features unsuppressed. The equal AP50 of Tower-HMT and Shared-FPN indicates that structural context alone cannot distinguish a missing bolt from similar tower details. The prior should therefore be regarded as a contextual constraint rather than direct defect evidence.
Figure 14.
Structural context on two real TTBM-DET tower scenes. Columns show the letterboxed image, detached and dilated tower prior, and missing-bolt heatmap. The prior is coarse by design; localization remains the responsibility of the heatmap, size, and offset heads. In the prior and heatmap visualizations, warmer colors indicate stronger responses, whereas cooler colors indicate weaker responses.
5.5. Robustness, Sensitivity, and Deployment Cost
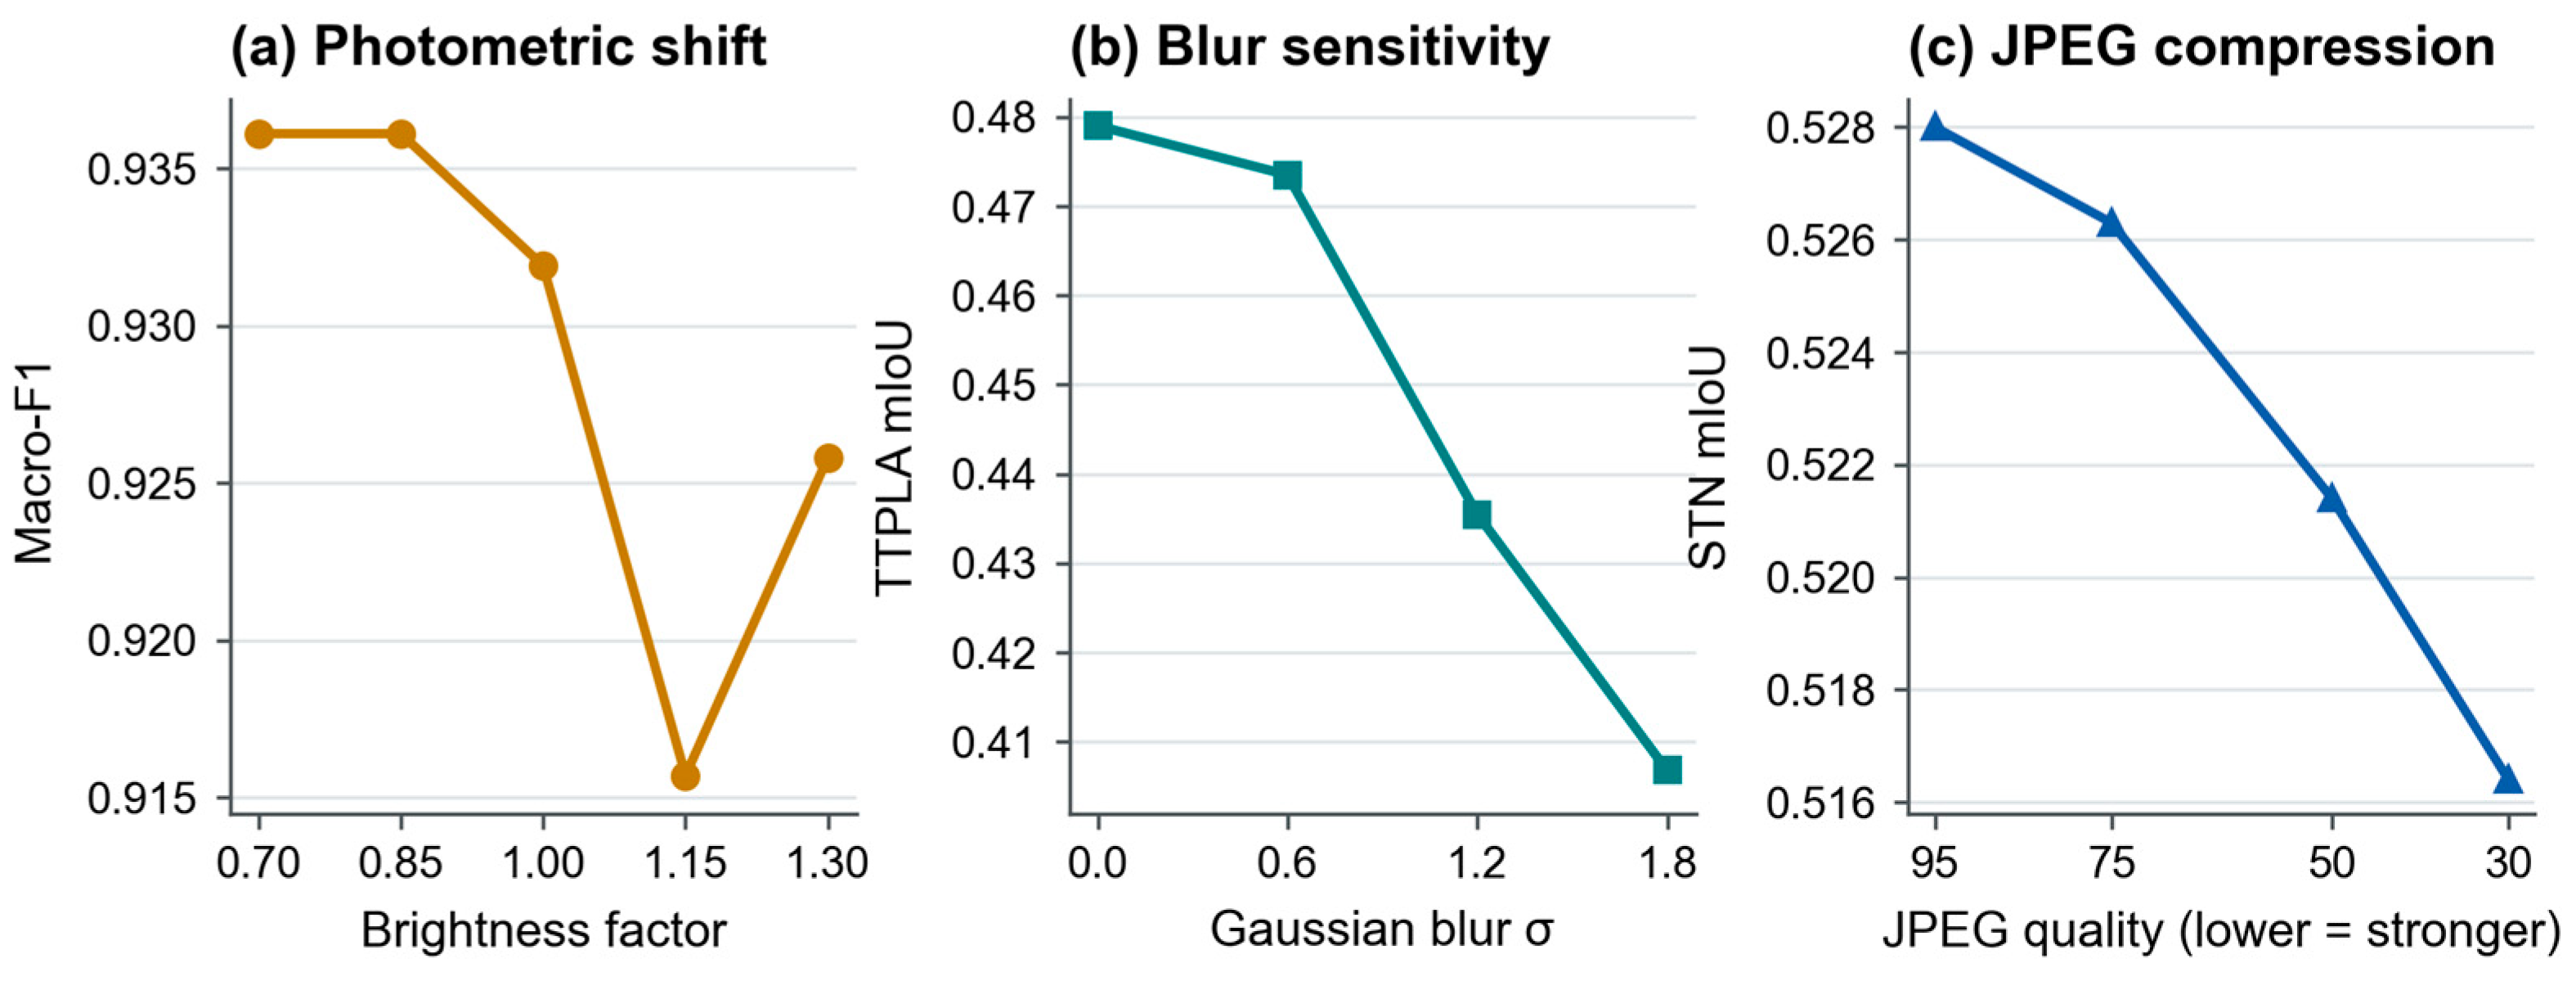
To evaluate whether the reported accuracy persists under plausible image degradation, robustness is examined with controlled perturbations. Figure 15 shows a non-monotonic condition macro-F1 range of 0.9157–0.9361 under brightness scaling, whereas Gaussian blur reduces TTPLA mIoU from 0.4790 to 0.4068. Lowering JPEG quality from 95 to 30 has a smaller effect on STN mIoU, which declines from 0.5280 to 0.5164. Among the tested perturbations, loss of fine spatial detail is therefore more damaging than compression artifacts, consistent with the dependence of conductors and lattice boundaries on high-frequency information. These curves remain diagnostic rather than comprehensive because they do not cover weather, sensor noise, viewpoint change, or the full temporal structure of flight-induced blur.
Figure 15.
Diagnostic robustness curves on fixed held-out subsets: (a) condition macro-F1 under brightness scaling; (b) TTPLA mIoU under Gaussian blur; and (c) STN mIoU under JPEG compression. The points represent measured model outputs rather than fitted extrapolations.
All robustness curves use fixed, index-preserving subsets of the held-out data: 192 TTPLA test patches, 192 STN test patches, and 512 InsPLAD test crops. Accordingly, the unperturbed points in Figure 15 are subset-specific diagnostics and are not expected to equal the full-test values in Table 4.
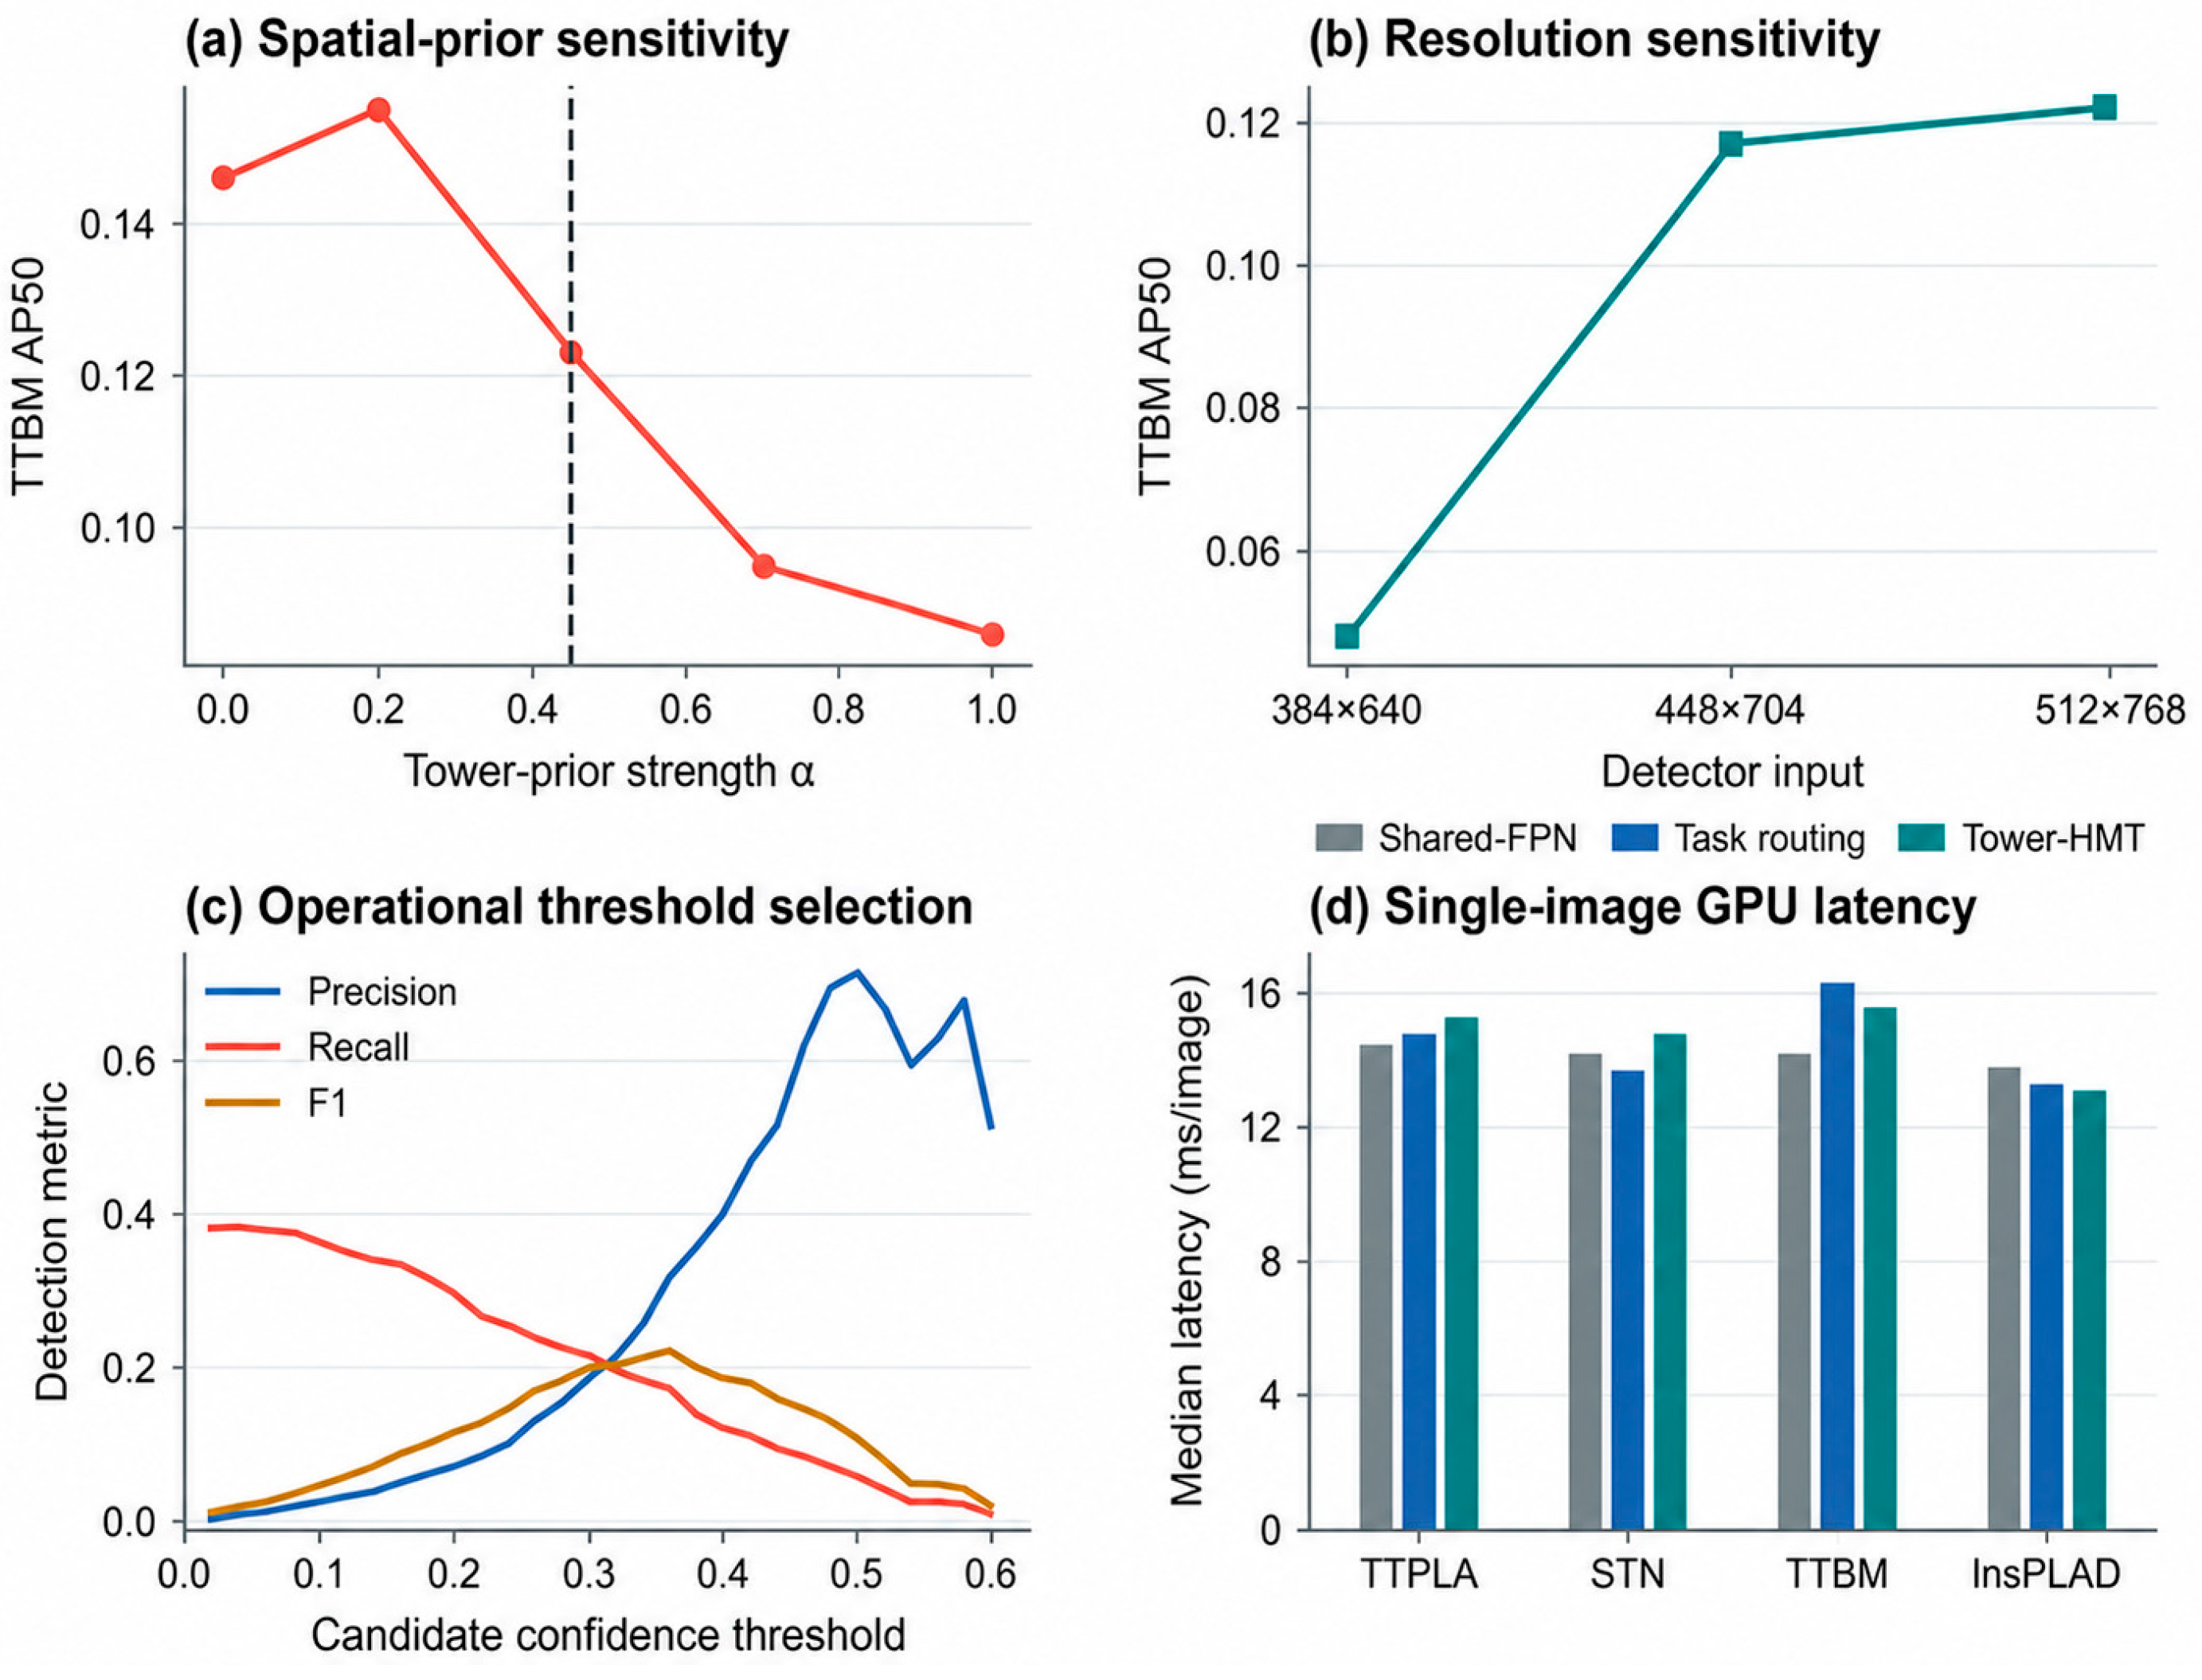
Sensitivity analysis then examines the two detector settings most likely to affect small-target localization. Figure 16 shows that stronger prior weighting is not uniformly beneficial: AP50 peaks at 0.155 for alpha = 0.20, compared with 0.123 at the preselected alpha = 0.45 and 0.086 at alpha = 1.00. Excessive gating may suppress candidates near uncertain plate or lattice boundaries even when they remain structurally plausible. Increasing the input from 384 × 640 to 448 × 704 raises AP50 from 0.048 to 0.117, followed by only a small increase to 0.123 at 512 × 768, indicating diminishing returns over the measured range.
Figure 16.
Parameter and operating analysis: (a) tower-prior strength; (b) detector resolution; (c) precision, recall, and F1 versus candidate threshold; and (d) median single-image GPU latency measured sequentially after warm-up.
The coefficient and resolution sweeps in Figure 16 were conducted after the model and its preselected operating configuration had been frozen. They are retained only as post hoc diagnostics of test-set sensitivity; no test-sweep value was used to select a checkpoint, revise alpha = 0.45, or change the reported 512 × 768 configuration.
Table 7 and Figure 16 jointly characterize the deployment trade-off. At the F1-maximizing threshold, precision is 0.319 and recall is 0.175, with 0.94 candidates per image; this limits review workload but misses most annotated bolts, so lower thresholds are preferable for recall-oriented screening. Across the four tasks, Tower-HMT requires 13.31–15.60 ms/image, compared with 13.91–14.50 ms/image for Shared-FPN. The largest Tower-HMT latency occurs on TTBM, consistent with its higher-resolution input, while the differences on the other tasks remain small.
Table 7.
Single-image median latency using a single NVIDIA GeForce RTX 5090 after warm-up (ms/image).
5.6. Failure Analysis
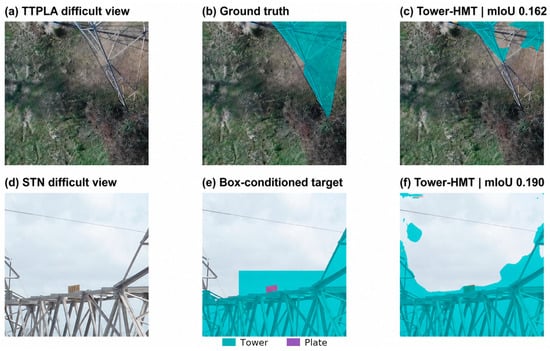
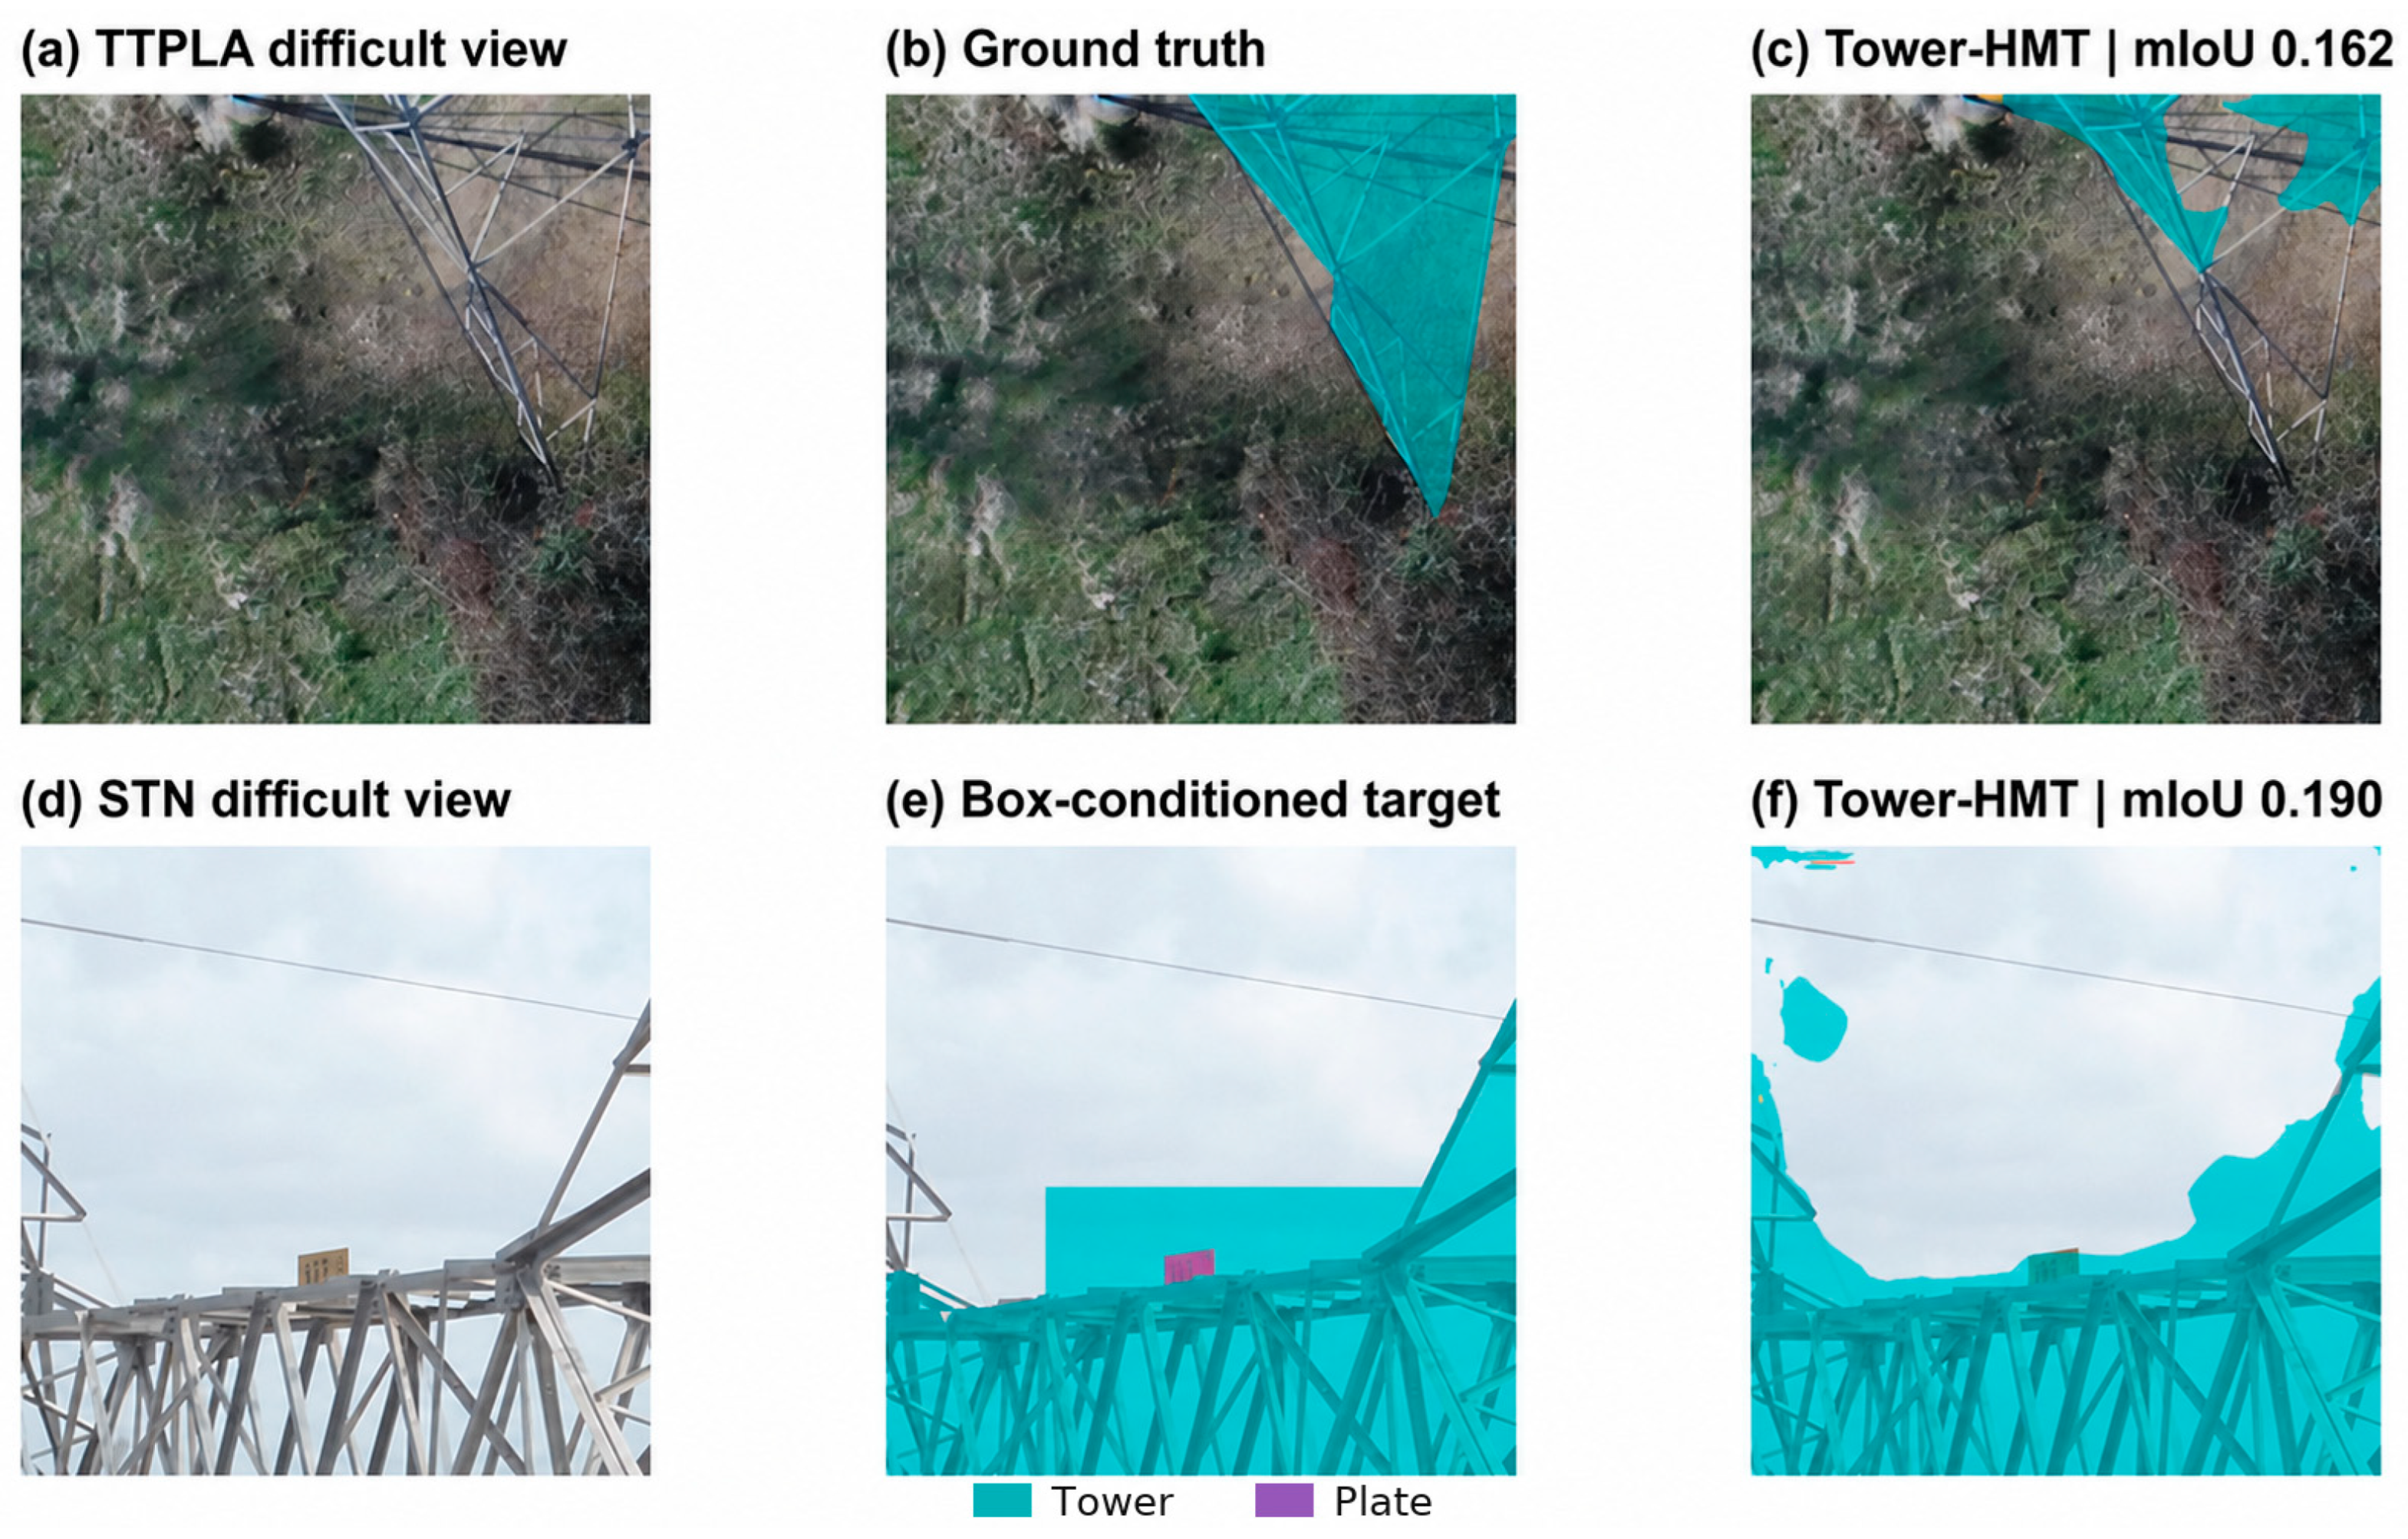
Finally, representative low-scoring cases are examined to identify conditions not captured by average metrics. In the TTPLA example in Figure 17 (mIoU 0.162), a small, oblique tower region is embedded in vegetation with limited contrast, leading to incomplete recovery and boundary displacement. In the STN example (mIoU 0.190), the predicted foreground spreads into the bright sky and departs from the box-conditioned target. Although the two cases differ in scale and supervision, both involve weak local separability between the target and its surroundings.
Figure 17.
Representative low-scoring held-out cases from the real tower datasets. (Top row): difficult TTPLA corridor patch, ground truth, and Tower-HMT output. (Bottom row): difficult STN component patch, box-conditioned target, and output. Images and masks are rendered without manual correction.
Taken together, Tower-HMT offers unified analysis across multiple inspection scales, representation sharing under heterogeneous supervision, and structural context for small-defect localization. By integrating corridor parsing, box-conditioned component parsing, missing-bolt localization, and condition recognition, the framework produces coherent outputs without forcing incompatible annotations into a common label space. The full-data results establish its value as a review-oriented baseline, while the controlled few-shot study narrows the architectural claim: a small, repeatable benefit is observed for TTPLA corridor parsing, but specialized single-task models remain preferable for low-shot STN parsing and missing-bolt detection.
Source-group separation limits within-source leakage but does not measure transfer to a new utility fleet. Sensor optics, flight altitude, season, weather, coating, tower design, and regional background can each shift the input distribution. The reported metrics therefore estimate generalization within the four source datasets, rather than guaranteeing cross-region performance. Deployment should be preceded by route-specific calibration, probability monitoring, and acceptance testing on locally annotated imagery.
6. Conclusions
This study developed Tower-HMT, a hierarchical multitask framework that jointly addresses corridor segmentation, component parsing, missing-bolt localization, and component-condition recognition using heterogeneous supervision from four public transmission-tower datasets. The framework combines a task-conditioned ConvNeXt–FPN backbone with topology- and boundary-aware segmentation objectives and a detached tower prior, thereby linking tower-scale structural information with component- and defect-level evidence. The main conclusions are as follows.
- (1)
- Tower-HMT provides a unified framework for hierarchical transmission-tower inspection while preserving task-specific supervision. In the principal full-data run, it achieved foreground mIoU values of 0.597 on TTPLA and 0.561 on STN PLAD, an AP50 of 0.123 on TTBM-Det, and a condition macro-F1 of 0.925 on InsPLAD.
- (2)
- The three-seed few-shot experiment shows that the architectural effect is task dependent. Tower-HMT yielded the highest and most stable TTPLA mIoU (0.4098 ± 0.0059), with a positive same-seed difference over Shared-FPN in all three runs. DeepLabV3 was stronger on STN (0.4701 ± 0.0081), and the multitask variants did not show a repeatable advantage for InsPLAD.
- (3)
- Missing-bolt localization remains the most challenging task because of the small target size and repetitive tower structures. In the principal run, the refined detector obtained an AP50 of 0.123, with precision of 0.319, recall of 0.175, and 0.94 candidates per image at the reported operating point. Under the six-epoch few-shot protocol without the high-resolution refinement stage, Faster R-CNN achieved 0.0481 ± 0.0126 AP50, whereas the joint heatmap variants remained near zero, demonstrating the importance of dedicated localization and scale-specific refinement.
- (4)
- Tower-HMT retains practical computational efficiency, with median inference times of 13.31–15.60 ms per image on an RTX 5090. The controlled three-seed study improves evidence on reproducibility under limited annotation, but broader validation still requires manually delineated component masks, repeated full-data experiments, and external utility fleets covering diverse tower designs and inspection conditions.
Supplementary Materials
The following supporting information can be downloaded at: https://www.mdpi.com/article/10.3390/app16178772/s1, File S1: Reproducibility Package.
Author Contributions
Conceptualization, H.S., K.L., R.M.; methodology, K.J., L.L.; software, D.M.; validation, K.L., K.J., L.L.; formal analysis, D.M., R.M.; investigation, D.M.; resources, K.J., L.L., X.W.; data curation, K.L., K.J., D.M.; writing—original draft preparation, H.S., K.L., D.M.; writing—review and editing, R.M.; visualization, X.W.; supervision, H.S., R.M.; project administration, H.S.; funding acquisition, R.M. All authors have read and agreed to the published version of the manuscript.
Funding
This research is financially supported by the Science and Technology Project of Shandong Electric Power Engineering Consulting Institute Co., Ltd. (No. 37-K2025-148).
Institutional Review Board Statement
Not applicable.
Data Availability Statement
The datasets used in this study—TTPLA, STN PLAD, InsPLAD, and TTBM-DET-Det—are publicly available from their respective project pages or repositories. An anonymized Supplementary File S1 accompanies this revision and contains the TTPLA and STN PLAD split manifests, the deterministic implementation of the InsPLAD split, scripts for generating and evaluating the STN box-conditioned masks, configuration records, and aggregate results. No third-party images are redistributed.
Acknowledgments
This work was supported by the Science and Technology Project of Shandong Electric Power Engineering Consulting Institute Co., Ltd. (Grant No. 37-K2025-148). The authors gratefully acknowledge the developers, annotators, and maintainers of the TTPLA, STN PLAD, InsPLAD, and TTBM-DET-Det datasets for making these resources publicly available and supporting research on transmission-tower inspection.
Conflicts of Interest
Ms. Hongzhu Song, Ms. Kaiyue Liu, Mr. Keqin Jia, Mr. Liyan Liu and Ms. Xiaomeng Wu were employed by Shandong Electric Power Engineering Consulting Institute Corp, Jinan, China. All authors declare no conflict of interest.
References
- Lin, O.Z.; Miyauchi, H. Reliability Forecasting in Distribution System Considering Variable Failure Rate: Combination of Equipment Inspection Method and Weibull Analysis. Int. Rev. Electr. Eng. 2017, 12, 67–72. [Google Scholar] [CrossRef] [Scilit]
- Lin, O.Z.; Miyauchi, H. Optimal Replacement Time of Electrical Components Based on Constant-Interval Replacement Model: Equipment Inspection Method and Weibull Analysis. Energy Power Eng. 2017, 9, 475–485. [Google Scholar] [CrossRef]
- Yetgin, O.E.; Benligiray, B.; Gerek, O.N. Power line recognition from aerial images with deep learning. IEEE Trans. Aerosp. Electron. Syst. 2019, 55, 2241–2252. [Google Scholar] [CrossRef] [Scilit]
- Zhang, H.; Yang, W.; Yu, H.; Zhang, H.; Xia, G.S. Detecting power lines in UAV images with convolutional features and structured constraints. Remote Sens. 2019, 11, 1342. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Wu, G.; He, W.; Fan, F.; Ye, X. Key target and defect detection of high-voltage power transmission lines with deep learning. Int. J. Electr. Power Energy Syst. 2022, 142, 108277. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Li, Z.; Liu, Y.; Sheng, G.; Jiang, X. Pin Bolt State Identification Using Cascaded Object Detection Networks. Front. Energy Res. 2022, 10, 813945. [Google Scholar] [CrossRef] [Scilit]
- Zhang, H.; Gao, L.; Gong, Y.; Liu, H.; Zhu, Y.; Yang, Y. RTF-SAW-YOLOv11: A Bolt Defect Detection Model for Power Transmission Lines under Low-Light Conditions. IEEE Access 2025, 13, 138640–138659. [Google Scholar] [CrossRef] [Scilit]
- Abdelfattah, R.; Wang, X.; Wang, S. TTPLA: An aerial-image dataset for detection and segmentation of transmission towers and power lines. In Proceedings of the ACCV 2020; Springer: Cham, Switzerland, 2021; pp. 601–618. [Google Scholar] [CrossRef] [Scilit]
- Vieira-e-Silva, A.L.B.; Felix, H.C.; Chaves, T.M.; Simoes, F.P.M.; Teichrieb, V.; dos Santos, M.M.; Santiago, H.D.C.; Sgotti, V.A.C.; Neto, H.B.D.T.L. STN PLAD: A dataset for multi-size power line assets detection in high-resolution UAV images. In Proceedings of the 2021 34th SIBGRAPI Conference on Graphics, Patterns and Images (SIBGRAPI); IEEE: Piscataway, NJ, USA, 2021; pp. 215–222. [Google Scholar] [CrossRef] [Scilit]
- Vieira-e-Silva, A.L.B.; Felix, H.C.; Simoes, F.P.M.; Teichrieb, V.; dos Santos, M.; Santiago, H.; Sgotti, V.; Neto, H.L. InsPLAD: A dataset and benchmark for power line asset inspection in UAV images. Int. J. Remote Sens. 2023, 44, 7294–7320. [Google Scholar] [CrossRef] [Scilit]
- Li, Z.; Lu, W.; Qin, J. CSA-YOLO: Cascaded Spatial Attention for Tiny Object Detection in Transmission Tower Inspection. arXiv 2016. [Google Scholar] [CrossRef] [Scilit]
- Ronneberger, O.; Fischer, P.; Brox, T. U-Net: Convolutional networks for biomedical image segmentation. In Proceedings of the MICCAI 2015; Springer: Cham, Switzerland, 2015; pp. 234–241. [Google Scholar] [CrossRef] [Scilit]
- He, K.; Gkioxari, G.; Dollár, P.; Girshick, R. Mask R-CNN. In Proceedings of the 2017 IEEE International Conference on Computer Vision, 2017; IEEE: Piscataway, NJ, USA, 2017; pp. 2980–2988. [Google Scholar] [CrossRef] [Scilit]
- Chen, L.C.; Zhu, Y.; Papandreou, G.; Schroff, F.; Adam, H. Encoder-decoder with atrous separable convolution for semantic image segmentation. In Proceedings of the ECCV 2018; Springer: Cham, Switzerland, 2018; pp. 833–851. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Sun, K.; Cheng, T.; Jiang, B.; Deng, C.; Zhao, Y.; Liu, D.; Mu, Y.; Tan, M.; Wang, X.; et al. Deep high-resolution representation learning for visual recognition. IEEE Trans. Pattern Anal. Mach. Intell. 2021, 43, 3349–3364. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liu, Z.; Lin, Y.; Cao, Y.; Hu, H.; Wei, Y.; Zhang, Z.; Lin, S.; Guo, B. Swin Transformer: Hierarchical vision transformer using shifted windows. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV); IEEE: Piscataway, NJ, USA, 2021; pp. 9992–10002. [Google Scholar] [CrossRef] [Scilit]
- Carion, N.; Massa, F.; Synnaeve, G.; Usunier, N.; Kirillov, A.; Zagoruyko, S. End-to-end object detection with transformers. In Proceedings of the ECCV 2020; Springer: Cham, Switzerland, 2020; pp. 213–229. [Google Scholar] [CrossRef] [Scilit]
- Cheng, B.; Misra, I.; Schwing, A.G.; Kirillov, A.; Girdhar, R. Masked-attention Mask Transformer for universal image segmentation. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2022; pp. 1290–1299. [Google Scholar] [CrossRef] [Scilit]
- Kirillov, A.; Wu, Y.; He, K.; Girshick, R. PointRend: Image segmentation as rendering. In Proceedings of the 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2020; pp. 9796–9805. [Google Scholar] [CrossRef] [Scilit]
- Savino, P.; Graglia, F.; Scozza, G.; Di Pietra, V. Automated corrosion surface quantification in steel transmission towers using UAV photogrammetry and deep convolutional neural networks. Comput. Aided Civ. Infrastruct. Eng. 2025, 40, 2050–2070. [Google Scholar] [CrossRef] [Scilit]
- Cambeiro Barreiro, A.; Seibold, C.; Hilsmann, A.; Eisert, P. Automated damage inspection of power transmission towers from UAV images. arXiv 2021, arXiv:2111.15581. [Google Scholar] [CrossRef] [Scilit]
- Yang, H.; Wang, S.; Chen, Y.; Yan, Z.; Cheng, Y.; Wang, T.; Wei, R. Improving power transmission tower state recognition in remote sensing images using cooperative Adaboost-MobileNet. Remote Sens. Lett. 2023, 14, 124–134. [Google Scholar] [CrossRef] [Scilit]
- Peng, L.; Wang, K.; Zhou, H.; Ma, Y.; Yu, P. YOLOv7-CWFD for real time detection of bolt defects on transmission lines. Sci. Rep. 2025, 15, 1635. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhang, K.; Lou, W.; Wang, J.; Zhou, R.; Guo, X.; Xiao, Y.; Shi, C.; Zhao, Z. PA-DETR: End-to-end visually indistinguishable bolt defects detection method based on transmission line knowledge reasoning. IEEE Trans. Instrum. Meas. 2023, 72, 5016914. [Google Scholar] [CrossRef] [Scilit]
- Deng, X.; He, M.; Zheng, J.; Qin, L.; Liu, K. Research progress on power visual detection of overhead line bolt defects based on UAV images. Drones 2024, 8, 442. [Google Scholar] [CrossRef] [Scilit]
- Yang, Z.; Zhao, Y.; Xu, C. Detection of missing bolts for engineering structures in natural environment using machine vision and deep learning. Sensors 2023, 23, 5655. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liu, Z.; Mao, H.; Wu, C.Y.; Feichtenhofer, C.; Darrell, T.; Xie, S. A ConvNet for the 2020s. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2022; pp. 11976–11986. [Google Scholar] [CrossRef] [Scilit]
- Lin, T.Y.; Dollár, P.; Girshick, R.; He, K.; Hariharan, B.; Belongie, S. Feature pyramid networks for object detection. In Proceedings of the 2017 IEEE Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2017; pp. 936–944. [Google Scholar] [CrossRef] [Scilit]
- Perez, E.; Strub, F.; de Vries, H.; Dumoulin, V.; Courville, A. FiLM: Visual reasoning with a general conditioning layer. In Proceedings of the the AAAI Conference on Artificial Intelligence; Association for the Advancement of Artificial Intelligence: Washington, DC, USA, 2018; Volume 32. [Google Scholar] [CrossRef] [Scilit]
- Kendall, A.; Gal, Y.; Cipolla, R. Multi-task learning using uncertainty to weigh losses for scene geometry and semantics. In Proceedings of the 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2018; pp. 7482–7491. [Google Scholar] [CrossRef] [Scilit]
- Zhou, X.; Wang, D.; Krähenbühl, P. Objects as points. arXiv 2019. [Google Scholar] [CrossRef] [Scilit]
- Lin, T.Y.; Goyal, P.; Girshick, R.; He, K.; Dollár, P. Focal loss for dense object detection. In Proceedings of the 2017 IEEE International Conference on Computer Vision, 2017; IEEE: Piscataway, NJ, USA, 2017; pp. 2999–3007. [Google Scholar] [CrossRef] [Scilit]
- Berman, M.; Triki, A.R.; Blaschko, M.B. The Lovász-Softmax loss: A tractable surrogate for the optimization of the intersection-over-union measure in neural networks. In Proceedings of the 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2018; pp. 4413–4421. [Google Scholar] [CrossRef] [Scilit]
- Sudre, C.H.; Li, W.; Vercauteren, T.; Ourselin, S.; Cardoso, M.J. Generalised Dice overlap as a deep learning loss function for highly unbalanced segmentations. In Proceedings of the DLMIA 2017; Springer: Cham, Switzerland, 2017; pp. 240–248. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Milletari, F.; Navab, N.; Ahmadi, S.A. V-Net: Fully convolutional neural networks for volumetric medical image segmentation. In Proceedings of the 2016 Fourth International Conference on 3D Vision; IEEE: Piscataway, NJ, USA, 2016; pp. 565–571. [Google Scholar] [CrossRef] [Scilit]
- Kervadec, H.; Bouchtiba, J.; Desrosiers, C.; Granger, E.; Dolz, J.; Ayed, I.B. Boundary loss for highly unbalanced segmentation. Med. Image Anal. 2021, 67, 101851. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Shit, S.; Paetzold, J.C.; Sekuboyina, A.; Ezhov, I.; Unger, A.; Zhylka, A.; Pluim, J.P.W.; Bauer, U.; Menze, B.H. clDice: A novel topology-preserving loss function for tubular structure segmentation. In Proceedings of the 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2021; pp. 16560–16569. [Google Scholar] [CrossRef] [Scilit]
- Hu, X.; Li, F.; Samaras, D.; Chen, C. Topology-Preserving Deep Image Segmentation. Adv. Neural Inf. Process. Syst. 2019, 32, 5658–5669. [Google Scholar]
- Selvaraju, R.R.; Cogswell, M.; Das, A.; Vedantam, R.; Parikh, D.; Batra, D. Grad-CAM: Visual explanations from deep networks via gradient-based localization. In Proceedings of the 2017 IEEE International Conference on Computer Vision; IEEE: Piscataway, NJ, USA, 2017; pp. 618–626. [Google Scholar] [CrossRef] [Scilit]
- Russakovsky, O.; Deng, J.; Su, H.; Krause, J.; Satheesh, S.; Ma, S.; Huang, Z.; Karpathy, A.; Khosla, A.; Bernstein, M.; et al. ImageNet large scale visual recognition challenge. Int. J. Comput. Vis. 2015, 115, 211–252. [Google Scholar] [CrossRef] [Scilit]
- Loshchilov, I.; Hutter, F. Decoupled Weight Decay Regularization. arXiv 2017, arXiv:1711.05101. [Google Scholar]
- Buslaev, A.; Iglovikov, V.I.; Khvedchenya, E.; Parinov, A.; Druzhinin, M.; Kalinin, A.A. Albumentations: Fast and flexible image augmentations. Information 2020, 11, 125. [Google Scholar] [CrossRef] [Scilit]
- Lin, T.Y.; Maire, M.; Belongie, S.; Hays, J.; Perona, P.; Ramanan, D.; Dollár, P.; Zitnick, C.L. Microsoft COCO: Common objects in context. In Proceedings of the ECCV 2014; Springer: Cham, Switzerland, 2014; pp. 740–755. [Google Scholar] [CrossRef] [Scilit]
- Efron, B.; Tibshirani, R.J. An Introduction to the Bootstrap; Springer: New York, NY, USA, 1993. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wilcoxon, F. Individual comparisons by ranking methods. Biom. Bull. 1945, 1, 80–83. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.