Article

AgentProphet: Source-Aware Multi-Agent Emerging Technology Forecasting for Upstream Decision-Making in AI-Based IoT Systems

1
School of Computer Science and Engineering, South China University of Technology, Guangzhou 510006, China
2
The Industrial Technology Research Center, Guangdong Institute of Scientific and Technical Information, Guangzhou 510006, China
3
Guangdong Laboratory of Artificial Intelligence and Digital Economy (SZ), Shenzhen 518107, China
*
Author to whom correspondence should be addressed.
These authors contributed equally to this work.
Appl. Sci. 2026, 16(13), 6787; https://doi.org/10.3390/app16136787
Submission received: 16 May 2026 / Revised: 10 June 2026 / Accepted: 11 June 2026 / Published: 6 July 2026
(This article belongs to the Special Issue Advances in Intelligent Decision-Making Systems)

Featured Application

This work can inform upstream intelligent decision-making for AI-based internet of things systems by providing data-level emerging technology prioritization and SMCC-oriented capability-planning cues under incomplete multi-source evidence.

Abstract

AI-based internet of things (IoT) systems increasingly require upstream decision-making mechanisms to identify emerging technologies that may shape future sensing–memory–communication–computation capabilities (SMCC). However, early technology signals are often weak, fragmented, and distributed across heterogeneous sources with different reliability levels, making reliable capability planning difficult. This paper proposes AgentProphet, a source-aware multi-agent framework for emerging AI technology forecasting in AI-based IoT systems. AgentProphet integrates evidence from papers, patents, policy documents, and reports into a unified concept space, and combines role-specialized agent reasoning, source-aware confidence calibration, and critic-guided refinement to generate target-year technology rankings. In the main balanced weak-signal forecasting task, AgentProphet achieves a Growth-Aware NDCG@10 of 0.410 ± 0.076 , improving over GRU, DirectLLM, DLinear, and ARIMA by 58.3%, 91.6%, 108.1%, and 314.1%, respectively. It also obtains the highest E-Gain@10 of 0.305 ± 0.060 , E-MAP@10 of 0.056 ± 0.008 , and NDCG@10 of 0.474 ± 0.039 . Cross-task robustness analysis shows that DirectLLM remains competitive, and can be stronger in sparser or more mature signal regimes. A qualitative case study maps the forecasted capability directions to representative SMCC concerns as a data-level interpretation of possible planning implications. These findings suggest that AgentProphet is most suitable for balanced weak-signal settings where early evidence is available but incomplete, rather than serving as a universally superior emerging technology forecaster.

1. Introduction

With the rapid advancement of large-scale artificial intelligence (AI) models, internet of things (IoT) systems are evolving from data-collection infrastructures toward intelligent environments with enhanced perception, reasoning, and decision-making capabilities [1,2]. Foundation models, retrieval-enhanced reasoning, graph-based learning, and multimodal perception are increasingly adopted in AI-based IoT applications, including smart cities, autonomous systems, industrial monitoring, and intelligent healthcare [3,4]. The deployment of these capabilities introduces new system-level requirements, including low-latency inference, distributed processing, memory and cache management, communication-efficient collaboration, and resource-constrained execution across heterogeneous devices. In this context, sensing–memory–communication–computation (SMCC) co-design offers a useful framework for coordinating sensing, memory, communication, and computation resources in large-scale AI-based IoT systems [5,6,7].
For AI-based IoT systems, SMCC-oriented capability planning is concerned not only with optimizing existing AI workloads, but also with anticipating how emerging AI technologies may affect future sensing, memory, communication, and computation requirements [5,6,7]. For example, retrieval-augmented generation may increase demands on distributed memory, cache management, and retrieval traffic; graph-based learning may introduce topology-aware communication and scheduling needs; and multimodal perception may reshape sensing workloads and edge–cloud inference partitioning [2,3,4]. Therefore, emerging AI technology forecasting can provide upstream evidence for resource allocation, capability planning, and long-term system evolution.
However, emerging AI technology forecasting is challenging because early signals are often weak, fragmented, and distributed across heterogeneous sources, including scientific papers, patents, policy documents, and reports [8,9]. These sources differ in timeliness, authority, technical depth, and noise level. Historical popularity extrapolation may miss low-visibility but high-growth technologies, while uniform treatment of heterogeneous sources may amplify noisy auxiliary evidence. This setting forms an incomplete-evidence decision problem: future technology states are only partially observable, and reliable prioritization requires both multi-source evidence integration and source-aware reliability control.
Existing approaches only partially address this requirement. Time-series, bibliometric, and patent-based methods mainly capture observable trend continuation, but often struggle under sparse early signals [8,10,11]. Heterogeneous technology text modeling supports concept organization and opportunity discovery, but typically focuses on representation, retrieval, or retrospective analysis rather than future-oriented prioritization [12,13,14,15]. Recent LLM-assisted forecasting methods offer stronger semantic abstraction and flexible prompt-based reasoning, yet they often operate on homogenized inputs and do not explicitly model source heterogeneity or calibrate weaker auxiliary evidence [16,17]. Moreover, generic ranking accuracy is insufficient for evaluating whether a method can identify technologies with weak historical visibility but substantive future growth potential.
To address these limitations, we propose AgentProphet, a source-aware multi-agent framework for emerging AI technology forecasting in AI-based IoT systems. AgentProphet aligns heterogeneous evidence into a unified concept space, preserves source-specific evidence profiles, and decomposes forecasting into evidence assessment, signal characterization, candidate ranking, source-aware confidence calibration, and critic-guided refinement. We further design a growth-aware and emerging-oriented evaluation protocol to assess future rise potential beyond conventional rank agreement.
Experiments on rolling forecasting tasks show that AgentProphet achieves stronger performance in the main weak-signal setting, especially on growth-aware and emerging-oriented ranking metrics. The application case study further illustrates how forecasted technologies can be mapped to SMCC-oriented capability planning cues for AI-based IoT systems. This case study is a data-level and conceptual mapping analysis rather than a hardware-integrated or system-level validation. Therefore, the findings should be interpreted as upstream forecasting evidence for future capability planning, while direct validation of latency, energy, communication overhead, resource utilization, reliability, and deployment quality are left for future work.
The main contributions of this work are summarized as follows:
  • We construct a source-aware concept evidence panel that aligns papers, patents, policy documents, and reports into a unified concept space while preserving source-specific evidence profiles for downstream forecasting and confidence calibration.
  • We develop AgentProphet, a role-specialized multi-agent framework with source-aware confidence calibration and critic-guided refinement for emerging AI technology ranking under incomplete multi-source evidence, with its main advantage positioned in balanced weak-signal forecasting settings.
  • We design a growth-aware and emerging-oriented evaluation protocol and provide a data-level SMCC-oriented case study to illustrate how forecasted AI technology directions can inform sensing, memory, communication, and computation capability planning in AI-based IoT systems.

2. Related Work

2.1. Multi-Source Evidence Integration for Technology Foresight

Technology foresight increasingly relies on heterogeneous evidence sources, including scientific publications, patents, policy documents, and industrial reports. These sources reflect different stages and perspectives of technological development. Scientific publications often capture early research exploration and conceptual emergence, patents indicate technical protection and potential translation, policy documents reveal strategic priorities and governance concerns, and reports provide industrial or market-oriented observations. Integrating these sources can enrich technology foresight by combining academic, technical, strategic, and industrial signals. However, such integration also introduces source heterogeneity in timeliness, credibility, technical depth, coverage, and noise level.
Prior studies have explored how heterogeneous scientific and technological texts can be aligned and integrated for downstream analysis. Magerman et al. examined latent semantic analysis for detecting similarity between patent documents and scientific publications [12], and Block et al. further studied semantic bridging between patents and publications in technological analysis [13]. Beyond direct cross-source association, intermediate semantic representations such as semantic networks and knowledge graphs have been used to organize technological concepts and their relationships. Sarica et al. proposed TechNet, a technology semantic network constructed from patent data [14], and Lee et al. combined deep learning-based text mining with a knowledge graph for technology opportunity discovery [15].
These studies show that semantic networks, similarity modeling, and knowledge graph-based representations can support technology analysis and opportunity discovery. However, their primary focus is often mapping, retrieval, or retrospective opportunity discovery rather than future-oriented ranking under uncertain and incomplete evidence. Moreover, heterogeneous sources are frequently integrated at the representation level, while their different reliability, coverage, and forecasting relevance are not explicitly calibrated for downstream forecasting. This motivates a source-aware evidence representation and integration strategy that preserves source-specific profiles instead of merging all evidence into a homogeneous signal.

2.2. Emerging AI Technology Forecasting

Emerging AI technology forecasting is closely related to broader studies on emerging technology detection, technology trend prediction, and weak-signal analysis. Existing methods have widely used patent analytics, bibliometric indicators, and time-series modeling to identify technologies with potential future strategic importance. Patent-based studies exploit structured technological signals to forecast future technology opportunities [10], while subsequent work has incorporated data augmentation, deep learning, and weak-signal detection to improve forecasting under sparse or limited observations [8,11,18]. Another related line of research predicts scientific topic or keyword trends from publication data, where neural models and time-series datasets are used to estimate future topic popularity [19,20]. Indicator-based studies further characterize emerging technologies through growth, novelty, impact, convergence, or timeliness-aware patterns [21,22].
Despite these advances, existing forecasting approaches often remain limited by single-source evidence, historical trend extrapolation, or task-specific indicator design. Hain et al. summarize the growing role of machine learning and AI in science, technology, and innovation mapping and forecasting [9]. However, many existing methods primarily capture observable trend continuation, while technologies with weak early visibility but strong future growth potential remain difficult to identify. This limitation is especially relevant to emerging AI technologies, whose early signals may be fragmented across scientific, technical, policy, and industrial sources [8,9,13]. Therefore, forecasting methods for AI-based IoT capability planning require not only trend modeling, but also evidence integration and evaluation criteria that emphasize weak-signal emergence.

2.3. Multi-Agent Reasoning for Decision Support

Recent studies have explored language-model-based reasoning and forecasting paradigms for complex decision-support tasks. Gruver et al. showed that large language models (LLMs) can perform zero-shot time-series forecasting by encoding numerical sequences as text and framing forecasting as next-token prediction [16]. PromptCast formulated time-series forecasting as a prompt-based sentence-to-sentence generation problem, demonstrating that language models can support flexible forecasting when temporal patterns are represented in natural language [17]. These studies suggest that LLMs can provide semantic abstraction and flexible reasoning for forecasting tasks. However, they are mainly designed for generic time-series settings and do not explicitly address emerging technology ranking under heterogeneous multi-source evidence.
In parallel, multi-agent LLM systems have been increasingly used for complex reasoning, task decomposition, tool use, and scientific discovery. AutoGen introduced a general framework for composing multiple conversational agents to solve complex tasks through interaction [23]. SciAgents integrated retrieval, reasoning, and critique for scientific discovery tasks, showing the potential of agent collaboration in knowledge-intensive research workflows [24]. Recent surveys further indicate that agentic LLM systems can support scientific automation, hypothesis generation, and decision-oriented reasoning [25]. These studies motivate the use of role-specialized agents to decompose complex forecasting and decision-support tasks into evidence assessment, candidate reasoning, refinement, and decision synthesis.
Nevertheless, existing LLM-assisted forecasting and multi-agent reasoning studies generally do not model heterogeneous evidence sources as distinct reliability-bearing signals. They also provide limited mechanisms for calibrating source-aware confidence or preventing weaker auxiliary evidence from dominating final ranking decisions. For emerging AI technology forecasting, this limitation is important because papers, patents, policy documents, and reports may provide complementary but unevenly reliable signals. AgentProphet addresses this gap by combining source-aware evidence modeling, role-specialized multi-agent reasoning, source-aware confidence calibration, and critic-guided refinement for upstream decision-making in AI-based IoT systems.

3. Materials and Methods

3.1. Problem Formulation

This study formulates emerging AI technology forecasting as a source-aware target-year ranking problem for upstream decision-making in AI-based IoT systems. Let S denote the set of heterogeneous evidence sources, including papers, patents, policy documents, and reports, and let C denote the set of canonical AI technology concepts obtained after cross-source alignment. Given historical observations within a window T h , the objective is to estimate the future prominence of each concept at a t and generate a ranked list that prioritizes technologies with credible future growth potential.
Formally, for each concept c C , AgentProphet observes its historical source-aware evidence profile X c before the target year t . The forecasting task is to produce a ranked list
R = [ c ( 1 ) , c ( 2 ) , , c ( K ) ] ,
where c ( j ) denotes the concept ranked at position j, and K denotes the length of the target-year recommendation list. The ranking is expected to prioritize candidate technologies that may exhibit substantive future growth rather than merely recover concepts with high historical frequency.
This objective differs from conventional popularity prediction. Rather than extrapolating historically frequent concepts, the goal is to rank technologies that have limited historical visibility but show early evidence of future growth. The task is challenging because early AI technology signals are sparse, fragmented, and unevenly distributed across papers, patents, policy documents, and reports. Since these sources differ in timeliness, authority, technical depth, and noise level, a uniform aggregation of evidence may obscure weak but credible emerging signals. We therefore formulate the task as uncertainty-aware prioritization under incomplete multi-source evidence.

3.2. Multi-Source Evidence Construction and Representation

We construct a four-source AI technology corpus from 2017 to 2025, covering academic papers, patents, policy documents, and reports. Papers and patents were collected from the Wanfang Data Knowledge Service Platform using a Selenium-based crawler. The search terms were defined by an AI technology keyword list, including intelligent agent, multimodal large language model, embodied intelligence, large-model reasoning, fine-tuning, reinforcement learning, foundation model, pre-trained language model, self-attention mechanism, and multi-head attention. Policy documents and reports were collected from both publicly available sources and authorized non-public materials. Policy documents were retrieved from official government websites, including national-level agencies and municipal governments in regions with active AI industrial development. Reports were collected from industry reports, enterprise technical reports, security research reports, and internally curated AI-related materials. The retrieval and selection process followed the same AI technology keyword scope used for papers and patents, covering terms related to intelligent agents, multimodal large language models, embodied intelligence, large-model reasoning, foundation models, reinforcement learning, and other representative AI technologies. Documents were included if they explicitly discussed AI policy directions, industrial development, technological trends, or annual AI hot-spot topics, and were excluded if they were duplicates, weakly related to AI, lacked identifiable publication years, or contained insufficient extractable text.
The evidence construction process was implemented in three main steps. Documents were retained if they were within the target time window, belonged to one of the four source types, and contained usable technology-related textual fields. Records were screened and excluded if they were outside the target-year range, lacked key year information, or contained no identifiable technology mentions. Duplicate records and repeated mentions within the same document were also checked during preprocessing and aggregation. For papers, titles, abstracts, keywords, classification codes, authors, and affiliations were retained when available. For patents, the raw collection included titles, abstracts, patent types, patent numbers, application or publication dates, and applicants when available; the evidence panel retained titles, years, and extracted core technology keywords for downstream aggregation. Policy and report PDFs were converted into structured records containing document identifiers, years, and core technology keywords. First, technology-related mentions are extracted from each source-year subset. Let M s , t denote the set of technology mentions extracted from source s S in year t. Technology mention extraction follows the CTLKE keyphrase-extraction design for Chinese technical literature [26]. Candidate technology mentions were mainly extracted from source-specific keyword fields, including original keywords and curated core-keyword fields, while document titles or identifiers were used as contextual information during alignment. The extraction prompts and cleaning rules were designed to emphasize technical noun phrases and AI-related keyphrases, while reducing overly general, non-technical, or incomplete expressions. Second, raw mentions are normalized and aligned into canonical concepts in C , so that lexical variants, abbreviations, and source-specific naming forms referring to the same underlying technology are consolidated. Concept normalization was implemented through a rule-first, candidate-linking, and review-queue strategy. Each raw mention was first surface-normalized by unifying letter case, punctuation, spacing, full-width and half-width forms, and common Chinese-English variants. Synonymous terms and abbreviations were then merged using manual alias rules, lexical matching, semantic similarity, and contextual consistency. Ambiguous mentions were disambiguated using available document-level context, source type, year, and co-occurring keyword information. High-confidence mappings were accepted automatically, while borderline cases were stored in a review queue for inspection. The accepted mention-to-concept links were finally aggregated into the source-aware term-year panel. Third, annual source-specific document-frequency statistics were calculated for each accepted concept to form the source-aware global concept panel.
For forecasting, the final experimental panel retains 974 concepts and 3158 nonzero concept-year rows. Primary-source evidence accounts for 96.49% of the nonzero panel evidence, and no concept is supported exclusively by auxiliary sources. This setting indicates that auxiliary evidence complements rather than replaces primary technical evidence in downstream forecasting.
After cross-source alignment, AgentProphet preserves source-resolved observations rather than collapsing all evidence into a single aggregated score. For each concept c C and year t, the source-aware evidence profile is represented as
x c , t = [ x c , t paper , x c , t patent , x c , t policy , x c , t report , cov c , t , f c , t total ] ,
where x c , t paper , x c , t patent , x c , t policy , and x c , t report denote source-specific document-frequency counts of concept c in papers, patents, policy documents, and reports, respectively. The term cov c , t denotes the number of sources with nonzero support, and f c , t total denotes the total document-frequency count across all sources. The historical evidence panel of concept c is denoted as
X c = { x c , t t T h } ,
where T h denotes the historical window. For models requiring complete yearly trajectories, missing concept-year observations are filled with zero source counts.
The resulting historical panel X c provides the basis for the history-only feature records used in downstream agent reasoning and confidence calibration. This representation preserves both temporal evolution and source-specific evidence distribution. AgentProphet explicitly distinguishes primary and auxiliary sources: papers and patents are treated as primary technical evidence, whereas policy documents and reports are treated as auxiliary contextual evidence. The latter may provide early signals about policy attention or industrial expectations, but they are potentially noisier and less technically specific. Therefore, auxiliary evidence is retained as complementary context, while source-aware weighting and confidence calibration prevent weaker contextual signals from being treated as equally reliable as primary technical evidence.

3.3. AgentProphet Framework

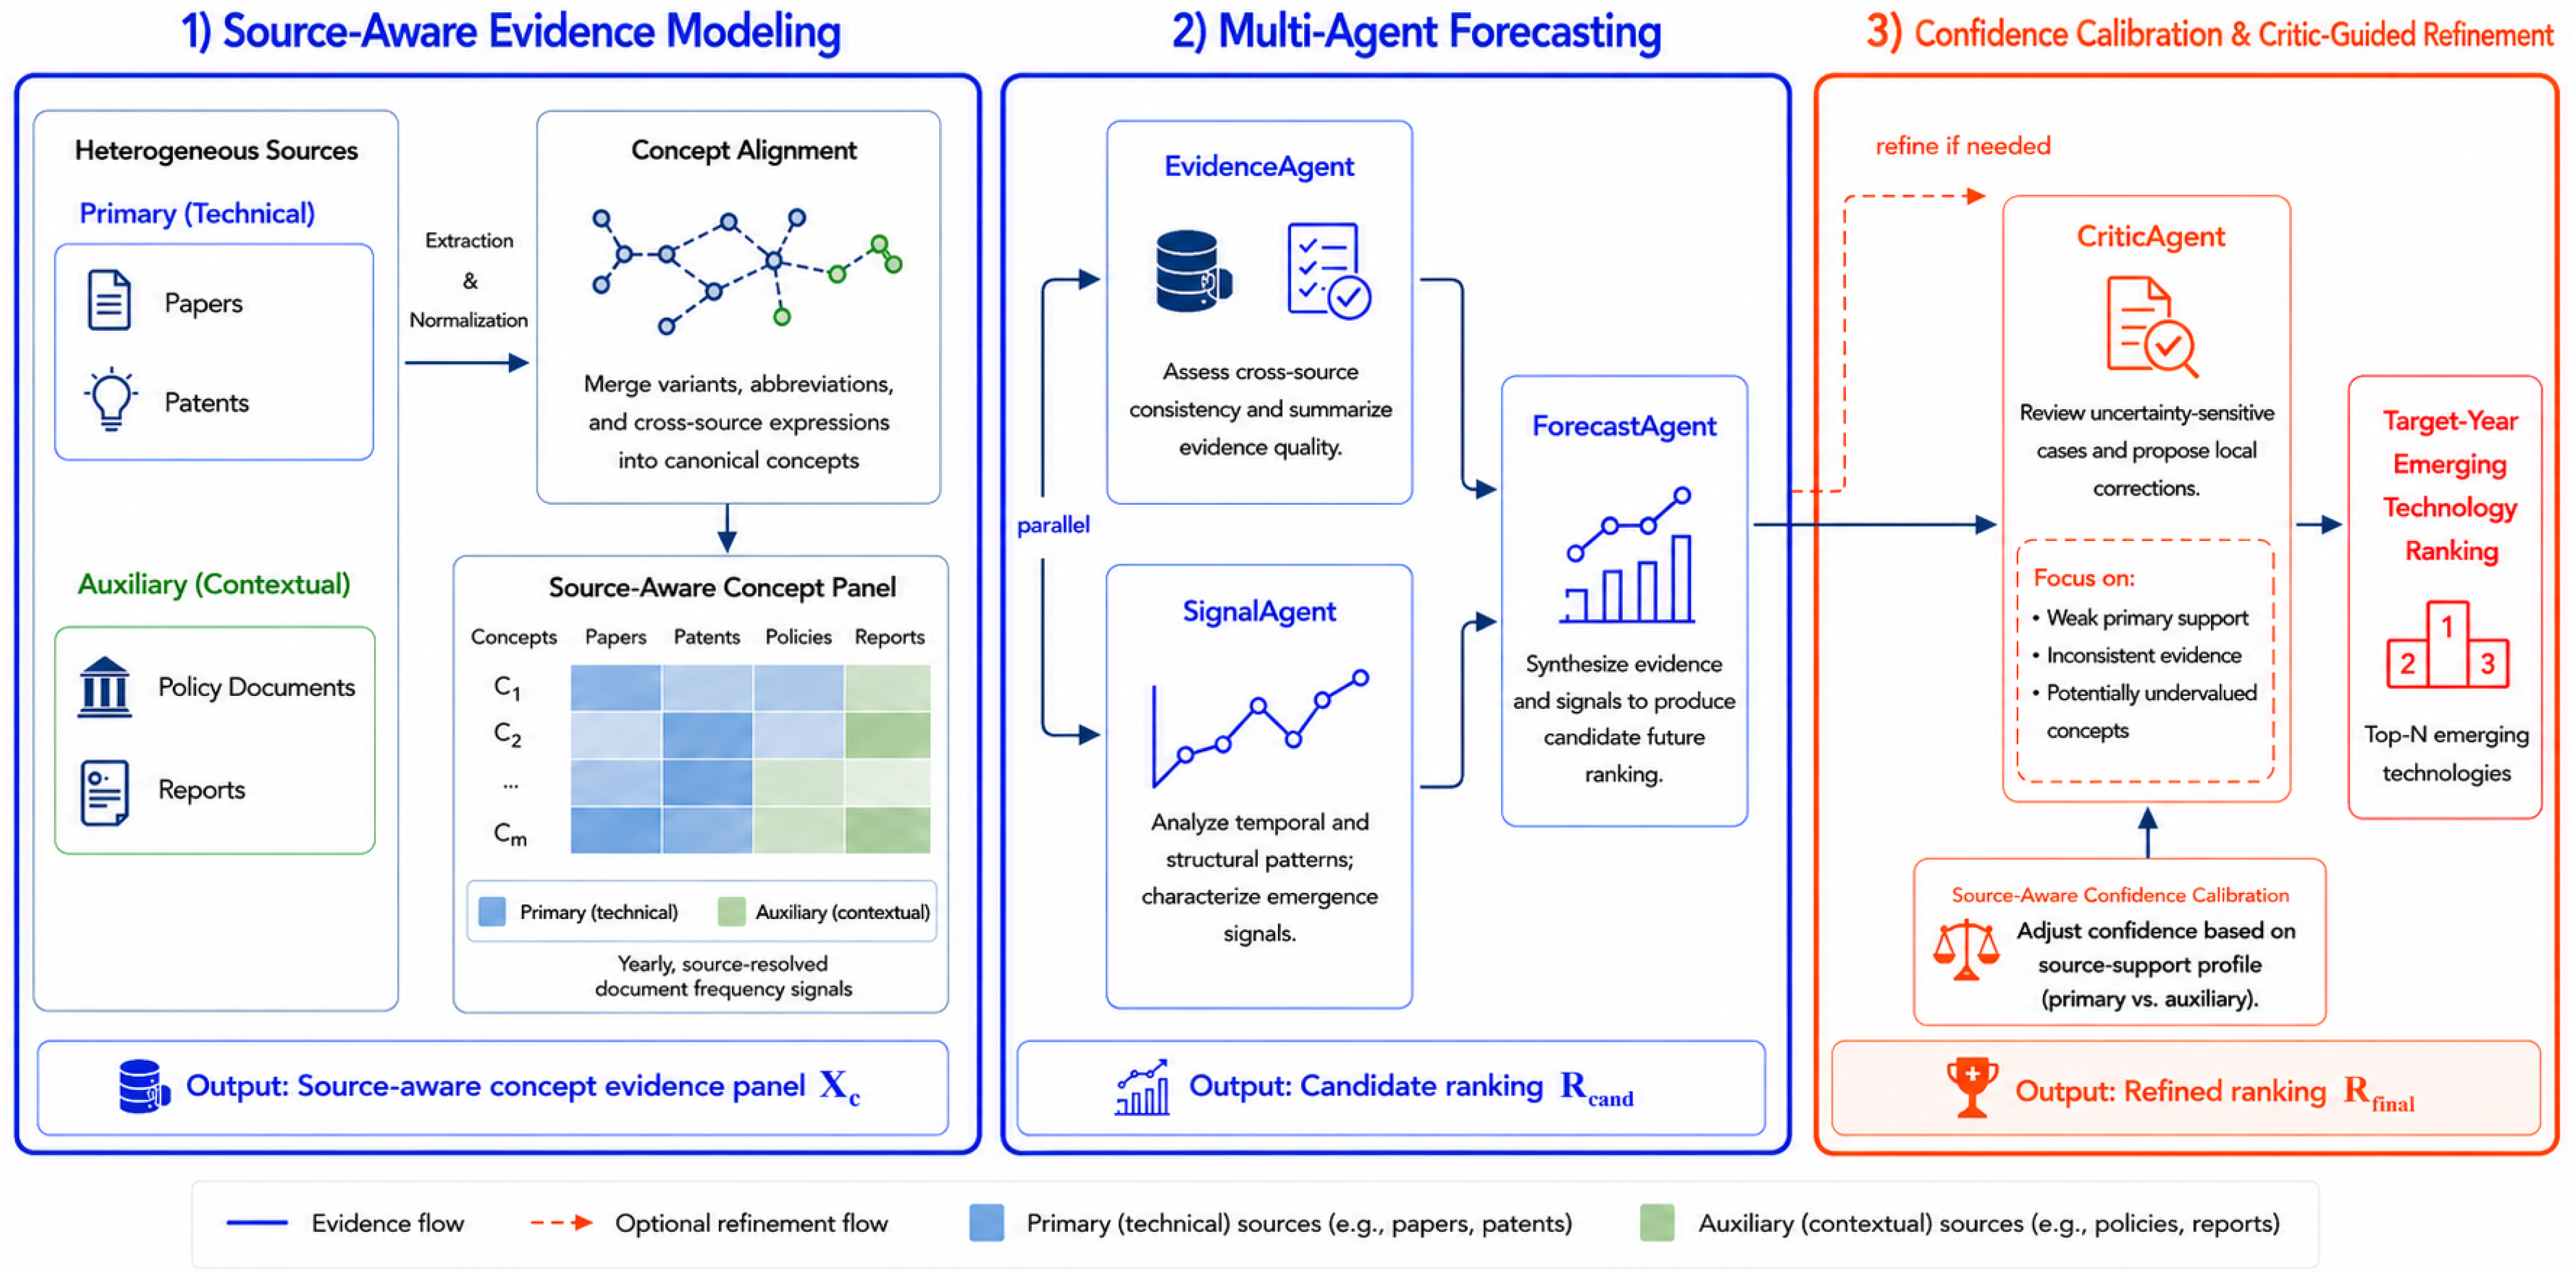
AgentProphet forecasts emerging AI technologies by integrating heterogeneous evidence with source-aware multi-agent reasoning, source-aware confidence calibration, and critic-guided refinement. As shown in Figure 1, the framework consists of three stages: source-aware evidence modeling, role-specialized multi-agent forecasting, and confidence-calibrated critic-guided refinement. Before agent collaboration, each candidate concept is converted into a compact history-only feature record, including last-year hotness, one-year growth, trend slope, support years, primary-source counts, auxiliary-source counts, recent source coverage, primary-source share, and emergence score. All agent prompts are restricted to observations no later than the historical-window end year, and the target-year or later outcomes are explicitly excluded from the prompt.
Based on the source-aware evidence panel, AgentProphet decomposes forecasting into four coordinated roles: EvidenceAgent, SignalAgent, ForecastAgent, and CriticAgent. This decomposition avoids a single undifferentiated generation step and separates evidence interpretation, signal characterization, candidate ranking, and trustworthiness-oriented review.
To make the multi-agent procedure reproducible, Table 1 summarizes the prompt objective, input fields, structured output schema, and downstream use of each agent. All agents are prompted with history-only evidence. The numerical panel is truncated at the end of the historical window, and the prompts explicitly prohibit the use of target-year or post-target outcomes. To improve transparency and reproducibility, the complete role prompts used by the agents and representative intermediate outputs generated during the forecasting procedure are provided in Supplementary File S1.
The AgentProphet forecasting module uses four role-specific agents. EvidenceAgent and SignalAgent are executed in parallel, and their tags are then passed to ForecastAgent. CriticAgent subsequently reviews the forecasted scores and applies bounded corrections when the evidence supports an adjustment.
The EvidenceAgent first computes a numerical evidence score and then uses the LLM to assign a source-quality tag. The raw evidence score is defined as
s ev raw = 0.45 p norm + 0.20 h norm + 0.20 g norm + 0.15 u norm ,
where p norm , h norm , g norm , and u norm denote normalized primary-source support, last-year hotness, one-year growth, and support-year coverage, respectively. The final evidence score is
s ev = s ev raw q ev ,
where q ev is set to 1.30 , 1.00 , and 0.60 for strong, moderate, and weak evidence, respectively. This step distinguishes credible primary or cross-source support from weak or auxiliary-source-dominated evidence, while treating short history as uncertainty rather than evidence failure.
The SignalAgent characterizes the temporal pattern of each concept. Its raw signal score is
s sig raw = 0.40 h norm + 0.30 g norm + 0.15 norm + 0.15 p norm ,
where norm denotes the normalized trend slope. The LLM assigns a stage label and a momentum score q mom [ 0 , 1 ] . The final signal score is
s sig = s sig raw 1 + ( m stage 1 ) q mom ,
where m stage is 1.50 , 1.20 , 0.90 , and 0.60 for emerging, growing, mature, and declining concepts, respectively.
The ForecastAgent combines numerical trajectory estimation with semantic forecasting. It outputs an absolute target-year hotness prediction h ^ c , t llm , a semantic trend label, and a semantic confidence score. The core fusion step can be summarized as
h ˜ c , t = ( 1 w c ) h ^ c , t num + w c h ^ c , t llm ,
where h ^ c , t num is the numerical trajectory estimate and w c is determined by evidence quality, semantic confidence, semantic trend, and momentum. The semantic weight and the LLM prediction are bounded before fusion to avoid uncontrolled amplification.
Finally, the CriticAgent reviews the ForecastAgent output using top predictions, emerging underdogs, evidence quality, semantic confidence, growth features, and source-support features. it applies a bounded multiplicative correction to the fused pre-critic target-year hotness score h ˜ c , t :
h ¯ c , t = α c h ˜ c , t .
where h ¯ c , t denotes the critic-corrected target-year hotness score and α c denotes the bounded multiplicative correction factor.
The CriticAgent is constrained to output α c [ 0.35 , 0.70 ] for strong penalties, α c [ 0.70 , 0.98 ] for moderate penalties, α c = 1.0 for unchanged predictions, α c [ 1.02 , 1.60 ] for moderate boosts, and α c [ 1.60 , 3.00 ] for strong boosts. Strong boosts are allowed only for low-base candidates with credible history-side support, such as high emergence score, early-signal evidence, cross-source support, or strong primary-source growth. The corrected scores are then further constrained by deterministic boundary rules and persistence residual calibration, preventing the critic from arbitrarily rewriting the ranking while still allowing correction of clearly underestimated emerging technologies.

3.4. Confidence-Calibrated Critic-Guided Refinement

The candidate ranking R cand generated by the ForecastAgent is not directly treated as the final output. In emerging technology forecasting, predicted rise potential and evidential reliability may diverge. A concept may appear promising due to repeated auxiliary signals, while another may have fewer but more credible primary-source observations. A ranking based only on forecast strength may therefore overestimate weakly grounded candidates.
To mitigate this issue, AgentProphet introduces a confidence-calibrated refinement layer. Confidence calibration adjusts the influence of candidate technologies according to their source-support profiles. Concepts with consistent primary-source support receive higher confidence, whereas concepts mainly supported by sparse or selective auxiliary evidence are treated more cautiously. This design preserves sensitivity to early weak signals while reducing the risk of weak-source dominance.
On top of the calibrated candidate list, the CriticAgent performs selective refinement before finalizing the target-year ranking. It focuses on uncertainty-sensitive cases, including highly ranked concepts with limited primary evidence, concepts with inconsistent source profiles, and potentially undervalued candidates supported by sparse but meaningful evidence. Rather than regenerating the full ranking, the CriticAgent provides localized corrections where the predicted ordering is insufficiently supported by the available evidence. After confidence calibration and critic-guided refinement, the final output ranking is denoted by R final .
Together, confidence calibration and critic-guided refinement form the trustworthiness control layer of AgentProphet. This layer improves ranking robustness under partial, noisy, and cross-source inconsistent evidence, making the final output R final more suitable for upstream capability planning in AI-based IoT systems.

3.5. Experimental Protocol and Implementation Details

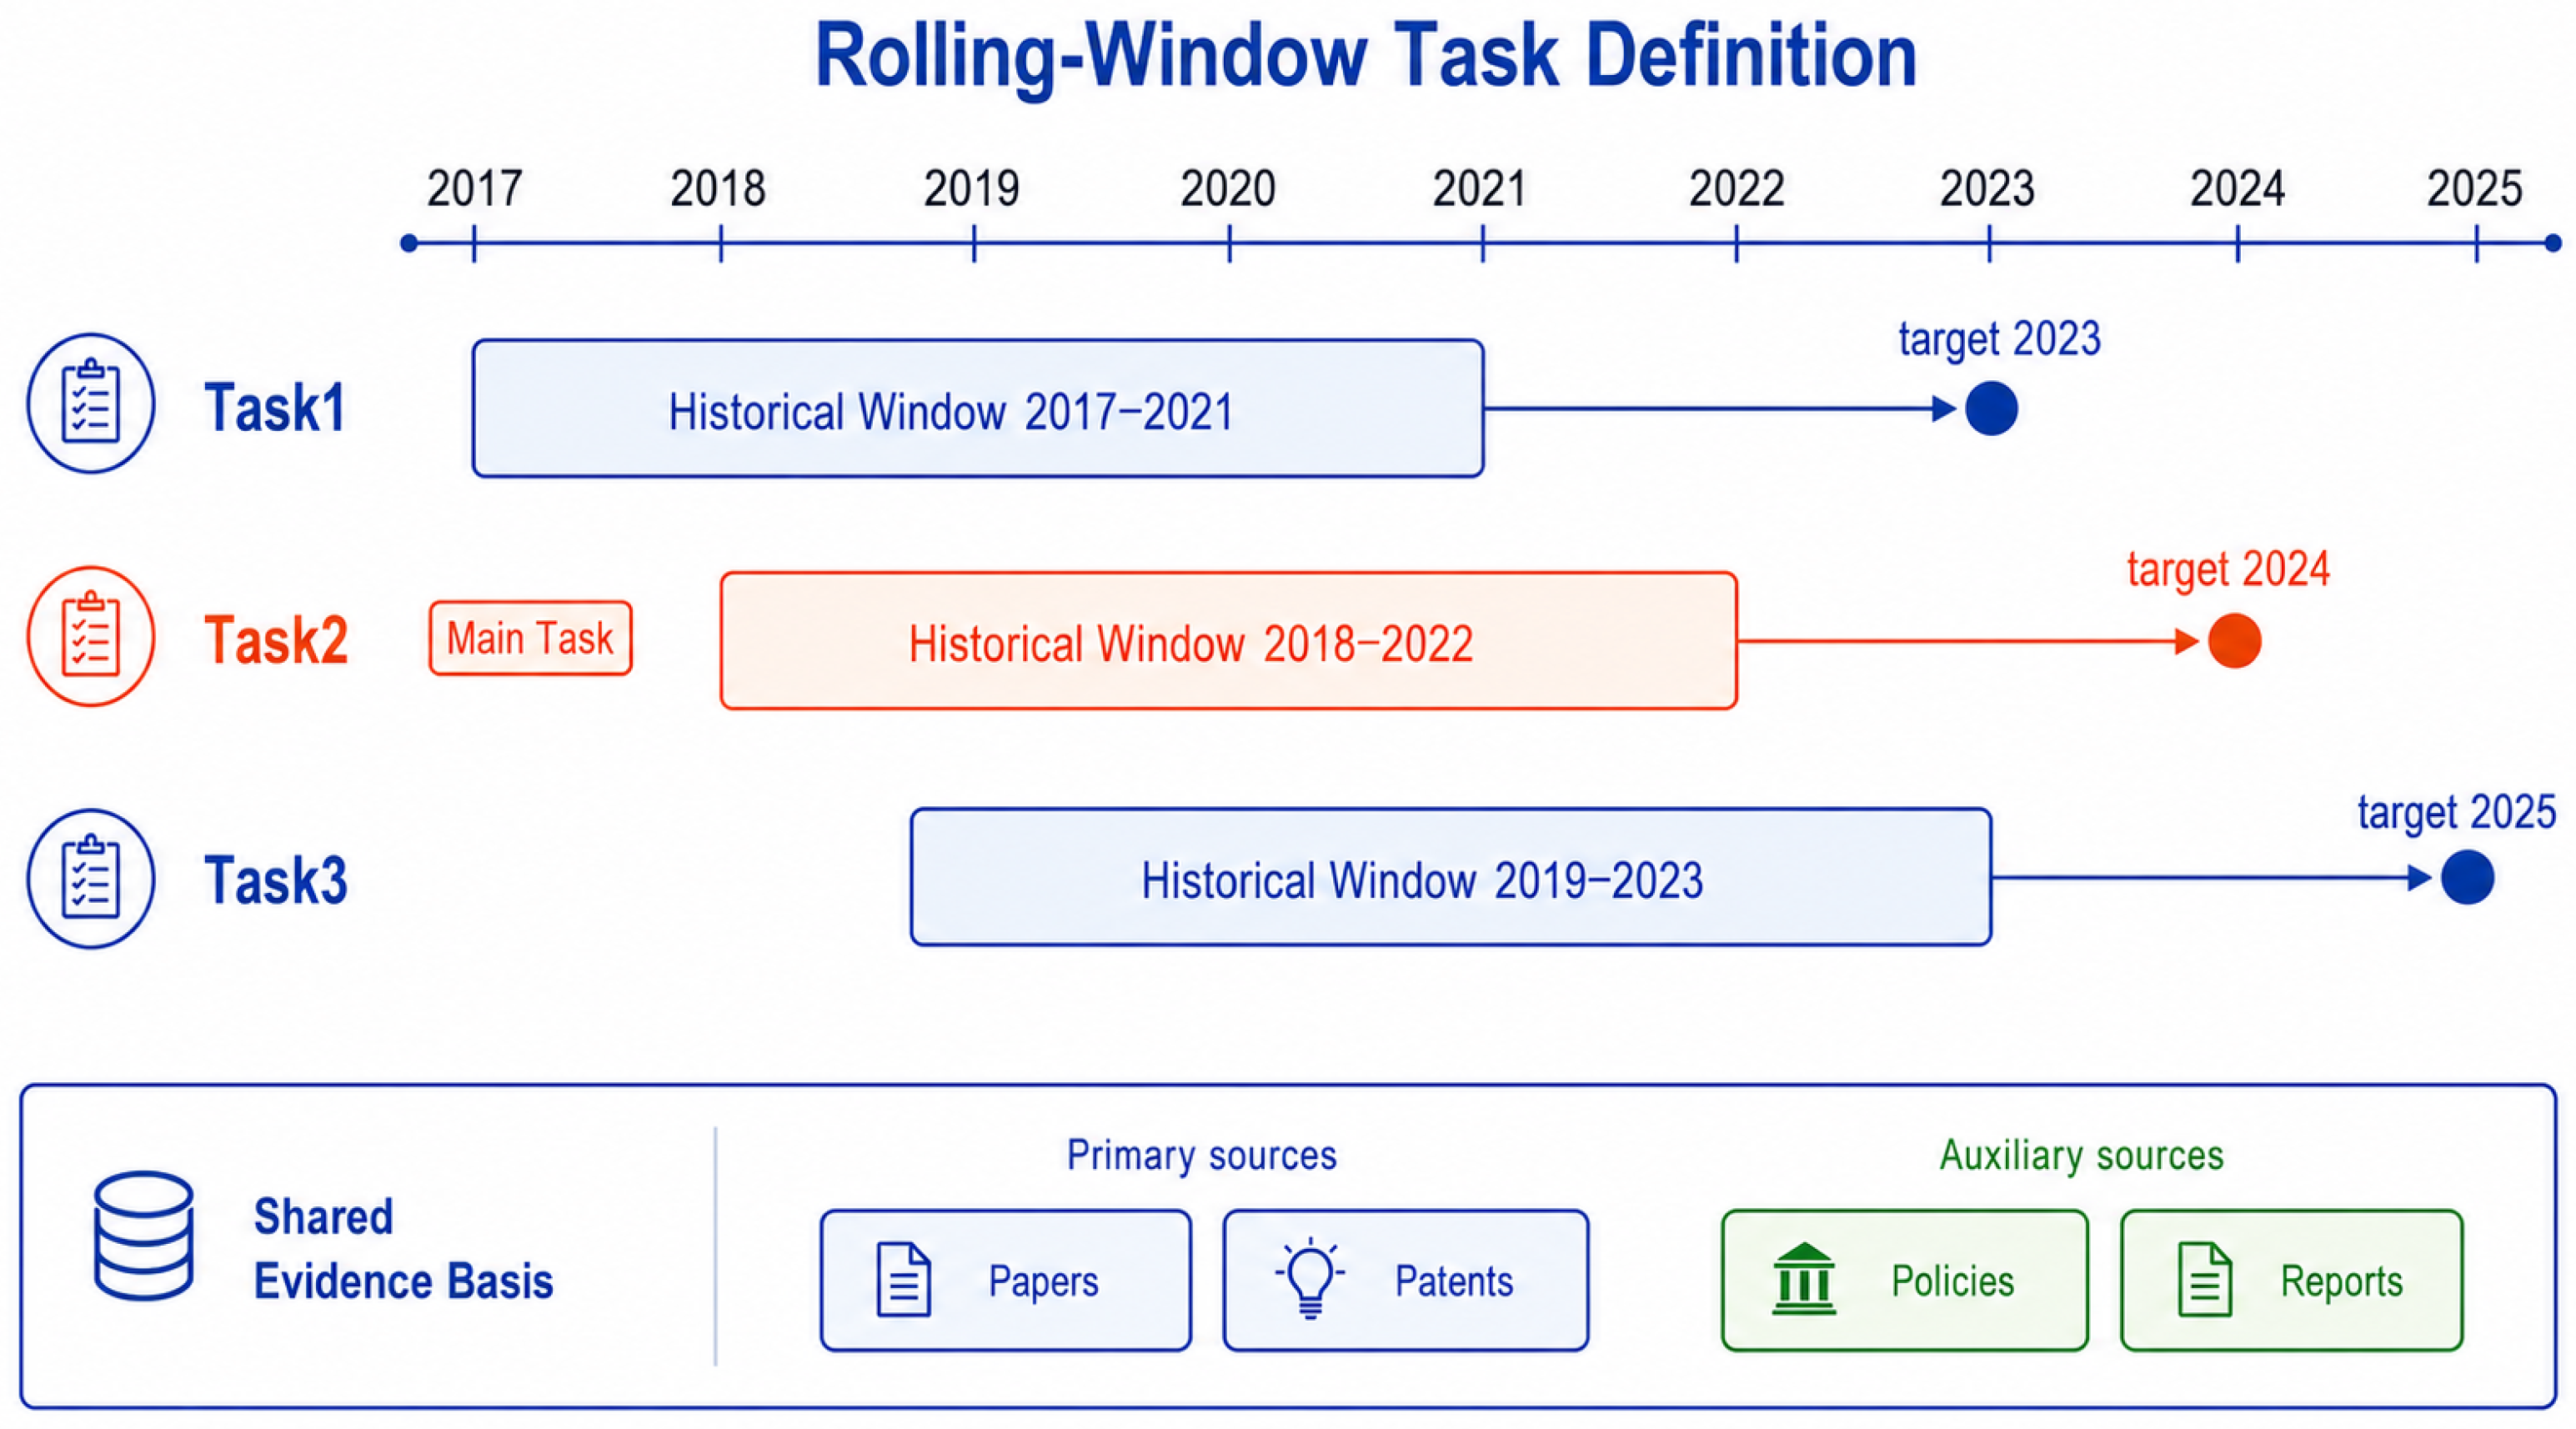
We use a rolling forecasting protocol to evaluate whether AgentProphet can identify emerging AI technologies before their future growth becomes fully observable. As shown in Figure 2, we instantiate three rolling forecasting tasks with a five-year history window and a two-year prediction horizon: Task1 (2017– 2021 2023 ), Task2 (2018– 2022 2024 ), and Task3 (2019– 2023 2025 ). This rolling design allows us to evaluate forecasting behavior under different signal-maturity regimes while keeping the history length consistent across tasks.
For each rolling forecasting task, we compute task-property diagnostics to characterize the corresponding signal regime. Let t 0 denote the last observed year in the historical window, t denote the target year, and h t ( c ) denote the weighted hotness of concept c in year t. The weighted hotness is computed from source-resolved counts as
h t ( c ) = 0.40 x c , t paper + 0.40 x c , t patent + 0.10 x c , t policy + 0.10 x c , t report .
These weights encode a fixed primary-source prior: papers and patents are treated as primary technical evidence and together receive 80% of the weight, while policy documents and reports are treated as auxiliary contextual evidence and together receive 20%. Papers and patents receive equal weights because they respectively represent scientific exploration and technical protection, whereas policy documents and reports receive equal but smaller weights because they may provide early contextual signals but have lower technical specificity. This prior is consistent with the corpus composition, where primary-source evidence accounts for 96.49% of nonzero panel evidence and no concept is supported exclusively by auxiliary sources. We therefore use auxiliary sources as complementary signals rather than allowing them to dominate the target-year ranking. The sensitivity of this fixed-prior choice is examined in Section 4.3.
Let Y 10 ( t ) denote the target-year Top-10 concepts ranked by h t ( c ) , and let H 10 ( t 0 ) denote the historical Top-10 concepts ranked by h t 0 ( c ) . The weak-signal emerging concept set is denoted as W 10 ( t ) . It is constructed from Y 10 ( t ) using history-window-only criteria.
First, historically prominent concepts are excluded by removing the Top-10 concepts ranked by last-year hotness, mean historical hotness, and primary-source support. Second, a target-year Top-10 concept is retained as a weak-signal emerging concept if it satisfies one of the following conditions: zero historical support but positive target-year hotness; early-signal status, defined by at most two support years, at least one primary-source observation, and positive one-year growth or positive trend slope; short historical support with support years no larger than max ( 2 , 0.60 | T h | ) ; or low-base challenger status, defined by h t 0 ( c ) 0.60 · h min Y 10 and an emergence score of at least 0.60, where h min Y 10 is the minimum hotness in Y 10 ( t ) . For nonzero-history candidates, the concept must also be observed for fewer than all history-window years, have positive one-year growth or positive trend slope, and satisfy h t ( c ) > h t 0 ( c ) . These criteria aim to capture that W 10 ( t ) captures target-year prominent concepts that were not already dominant in the historical window.
The emergence score used in the low-base challenger rule is computed from rank-normalized weak-signal features
e ( c ) = clip [ 0 , 1 ] ( 0.25 r low ( c ) + 0.30 r growth ( c ) + 0.20 r slope ( c ) + 0.15 r recent ( c ) + 0.10 r primary ( c ) + b ( c ) ) π ( c ) .
where r low ( c ) is the inverse percentile rank of last-year hotness, r growth ( c ) and r slope ( c ) are percentile ranks of one-year growth and trend slope, r recent ( c ) increases when support years are fewer, and r primary ( c ) is a log-damped primary-source support score. The bonus term b ( c ) adds 0.18 for early-signal concepts, 0.06 when r low ( c ) 0.60 with primary evidence, 0.08 when recent source coverage is at least two, 0.08 for bridge-rising concepts with at least two support years, at least six primary-source observations, and r low ( c ) 0.45 , and 0.05 for light-primary early concepts with recent primary evidence and r low ( c ) 0.55 . All bonus terms are applied only when the concept has positive one-year growth or a positive trend slope. The penalty π ( c ) is 0.20 for auxiliary-only concepts and 1.00 otherwise.
Based on these definitions, the four diagnostic properties are computed as follows:
Weak @ 10 = | W 10 ( t ) | ,
Overlap @ 10 = | Y 10 ( t ) H 10 ( t 0 ) | | Y 10 ( t ) H 10 ( t 0 ) | ,
Hist . hotness = 1 | W 10 ( t ) | c W 10 ( t ) h t 0 ( c ) ,
and 
Growth = 1 | W 10 ( t ) | c W 10 ( t ) max h t ( c ) h t 0 ( c ) , 0 .
When W 10 ( t ) = , the two average-based diagnostics, Hist. hotness and Growth, are set to 0.
Here, Weak@10 counts weak-signal emerging truths within the target-year Top-10, Overlap@10 measures the Jaccard overlap between historical and target-year Top-10 concepts, Hist. hotness reports their average pre-target weighted hotness, and growth reports their average positive target-year increase.
As shown in Table 2, Task2 and Task3 both contain four weak-signal truths at Top-10, but Task2 has the lowest historical–target Jaccard overlap, lower pre-target hotness than Task3, and the highest mean positive growth. Task1 represents a sparse zero-history setting, as its weak-signal truths have no historical hotness, whereas Task3 shows stronger continuation patterns, with higher historical–target overlap and higher pre-target hotness among weak-signal truths. Therefore, Task2 is used as the main diagnostic weak-signal setting, while Task1 and Task3 are retained as supplementary settings for cross-task analysis under sparse and more historically developed signal regimes, respectively.
We compare AgentProphet with five baselines: LastValue, ARIMA, DLinear, GRU, and DirectLLM. For each concept c, let h t ( c ) denote its weighted hotness in year t, and let x c , t denote the source-aware evidence vector consisting of paper, patent, policy, report, weighted-hotness, and source-coverage channels. Given a historical window ending at t 0 and a target year t , each baseline produces a non-negative prediction score s ^ t ( c ) for each candidate concept. Candidate concepts are ranked in descending order of s ^ t ( c ) .
LastValue is a strict persistence baseline that carries forward the weighted hotness observed in the final history year
s ^ t ( c ) = max h t 0 ( c ) , 0 .
Since the historical panel is dense, this baseline uses the value in the last observed year directly and does not backfill to the most recent nonzero observation.
ARIMA is a classical univariate time-series baseline fitted independently for each concept [27]. In our implementation, the model is fitted to the weighted-hotness sequence { h t ( c ) } t T h using an ARIMA ( 1 , 0 , 0 ) specification without a trend term
h t ( c ) = ϕ 1 h t 1 ( c ) + ϵ t ,
where ϕ 1 is the autoregressive coefficient and ϵ t is the error term. The fitted model forecasts the target-year score
s ^ t ( c ) = max h ^ t ( c ) , 0 .
For empty series, the prediction is set to zero; for constant or failed series, the method falls back to the last observed weighted hotness.
DLinear is implemented as a lightweight DLinear-style multivariate baseline [28]. It uses the same six historical evidence channels as GRU. Given a length-L window,
V c , t L + 1 : t = [ v c , t L + 1 , , v c , t ] ,
we first compute a moving-average trend component and a residual annual component
T c , t L + 1 : t = MA m ( V c , t L + 1 : t ) ,
S c , t L + 1 : t = V c , t L + 1 : t T c , t L + 1 : t ,
where MA m ( · ) denotes a moving average with window size m. The flattened annual and trend components are concatenated into a feature vector
z c , t = vec ( S c , t L + 1 : t ) ; vec ( T c , t L + 1 : t ) .
A ridge-regularized linear projection is then fitted
min w , b ( c , t ) w z c , t + b h t + 1 ( c ) 2 + α w 2 2 ,
and the fitted one-step projection is applied recursively over the forecasting horizon H = t t 0 . At each step, the predicted weighted-hotness channel is inserted into the next input window while the remaining channels are carried forward from the latest window state. The final recursive prediction is clipped to obtain
s ^ t ( c ) = max h ^ ( H ) ( c ) , 0 .
GRU is a neural sequence baseline over the same six-channel historical evidence representation [29]. Given the historical input window V c , t 0 L + 1 : t 0 , the sequence is encoded by a gated recurrent unit
h c , t 0 = GRU ( v c , t 0 L + 1 , , v c , t 0 ) ,
and the final hidden state is mapped to a one-step weighted-hotness prediction through feed-forward layers
h ^ ( 1 ) ( c ) = f θ ( h c , t 0 ) ,
where f θ ( · ) denotes the dense prediction head. target-year forecasting is then performed recursively over H = t t 0 steps by updating the weighted-hotness channel after each prediction
s ^ t ( c ) = max h ^ ( H ) ( c ) , 0 .
The implementation uses a GRU layer with 32 hidden units, followed by a 16-dimensional ReLU dense layer and a linear output layer. The model is trained with mean squared error loss and the Adam optimizer.
DirectLLM is a direct-prompt LLM baseline using the same history-derived concept features [16]. For each candidate concept c, we construct a compact feature summary ϕ ( c ; t 0 ) , including its last observed hotness, mean historical hotness, recent growth, trend slope, active years, and source-support statistics. Candidate summaries are grouped into batches and passed to the LLM with instructions to use only the provided history-derived features and public knowledge available before the cutoff year, without adding new terms or using target-year outcomes. The LLM is then asked to predict the absolute hotness of each candidate in the target year
h ^ t ( c ) = LLM P direct , ϕ ( c ; t 0 ) .
The final prediction score is clipped to be non-negative
s ^ t ( c ) = max h ^ t ( c ) , 0 .
Unlike AgentProphet, this baseline directly maps compact history-derived feature summaries to target-year hotness predictions, without role-specialized agent decomposition or critic-guided refinement.
Given the prediction scores defined above, we evaluate each method with metrics that distinguish ordinary target-year ranking accuracy from growth-oriented and emerging-oriented forecasting performance. In the following definitions, h ^ t ( c ) denotes the predicted target-year hotness score, equivalent to s ^ t ( c ) above.
The primary metric is Growth-Aware NDCG@10 (GA-NDCG@10), a growth-oriented variant of NDCG [30] adapted to technological emergence assessment [31,32]. The ground-truth and predicted positive growth are defined as
g ( c ) = max h t ( c ) h t 0 ( c ) , 0 ,
and
g ^ ( c ) = max h ^ t ( c ) h t 0 ( c ) , 0 .
Positive growth is further converted into graded relevance by log normalization
rel GA ( c ) = log 1 + g ( c ) max c log 1 + g ( c ) .
GA-NDCG@10 is then computed by applying NDCG@10 to the ranking induced by g ^ ( · ) , with rel GA ( · ) as the graded relevance score. This metric is treated as primary because it directly reflects the objective of prioritizing concepts with substantive future rise potential rather than preserving historical prominence.
We also report Emerging NDCG@10 (E-NDCG@10), Emerging Gain@10 (E-Gain@10), Emerging MAP@10 (E-MAP@10), and Standard NDCG@10. Emerging-oriented relevance combines future growth with low historical prevalence
rel E ( c ) = rel GA ( c ) 0.40 + 0.60 λ ( c ) ,
where λ ( c ) = 1 rankpct t 0 ( c ) is the low-base factor derived from the percentile rank of h t 0 ( c ) among candidate concepts.
A concept with lower historical hotness therefore receives a larger emerging-oriented relevance multiplier, while the constant 0.40 preserves relevance for high-growth concepts that are not strictly zero-history. E-NDCG@10 applies NDCG@10 to rel E ( · ) . E-Gain@10 is the accumulated normalized emerging relevance captured by the predicted Top-10 list
E - Gain @ 10 = c R 10 rel E ( c ) I 10 E .
where R 10 denotes the predicted Top-10 list, E 20 denotes the 20 highest emerging-relevance concepts, and I 10 E is the sum of the ten largest relevance values in E 20 .
E-MAP@10 computes relevance-weighted average precision over the predicted Top-10 list
E - MAP @ 10 = 1 I 10 E j = 1 10 P E ( j ) · rel E ( c ( j ) ) .
where c ( j ) is the concept at rank j and P E ( j ) = j 1 i = 1 j rel E ( c ( i ) ) . Concepts outside E 20 have zero emerging relevance in E-Gain@10 and E-MAP@10. Standard NDCG@10 uses target-year hotness as the conventional graded relevance reference.
All LLM-based methods use qwen3-max-2026-01-23. AgentProphet is run five times and reported as mean ± standard deviation to reflect the stochasticity of multi-agent LLM reasoning, while deterministic baselines and DirectLLM are reported as single values under fixed configurations.
Baseline Selection Rationale. The baseline methods are selected to cover the main methodological families relevant to weak-signal emerging technology forecasting under heterogeneous historical evidence. LAST VALUE is included as a persistence-based baseline, which tests whether target-year technology prominence can be explained by simple continuation of the most recent observations. ARIMA represents classical statistical time-series forecasting and evaluates whether univariate temporal extrapolation is sufficient for short-horizon technology forecasting. DLinear is adopted as a lightweight linear neural forecasting model, providing a stronger yet interpretable temporal baseline for multivariate historical evidence. GRU represents recurrent neural sequence modeling and tests whether nonlinear temporal dependencies in the historical evidence panel can improve forecasting performance. DirectLLM uses the same LLM backbone as AgentProphet but directly generates the technology ranking without source-aware decomposition, confidence calibration, or critic-guided refinement. It therefore serves as a key control for distinguishing the benefit of the proposed source-aware multi-agent framework from the effect of simply using an LLM.
Together, these baselines provide a controlled comparison across persistence-based continuation, classical time-series extrapolation, lightweight neural forecasting, recurrent neural forecasting, and direct LLM-based reasoning. This design is aligned with the objective of this study: to examine whether source-aware multi-agent reasoning improves the ranking of emerging AI technologies under weak historical signals and heterogeneous multi-source evidence. We therefore interpret the baseline comparison as a representative evaluation across complementary methodological families, rather than as an exhaustive benchmark of all possible technology-forecasting paradigms.
To ensure a fair and leakage-free comparison, all numerical baselines were configured using only pre-target historical data. For each rolling forecasting task, we constructed an internal validation split within the historical window, using the earlier years for model fitting and the last available pre-target year as the validation year. Hyperparameter configurations were selected or confirmed according to validation performance on the primary growth-aware ranking metric, and the selected configuration was then retrained on the full historical window before generating the target-year forecast. Under this protocol, DLinear was implemented with a sequence length of 3, a moving-average window of 3, and ridge regularization with ( α = 0.1 ). The GRU baseline used a sequence length of 3, a hidden size of 32, a mini-batch size of 256, 12 training epochs, Adam optimization, and a fixed random seed of 42. ARIMA was fitted independently for each concept-level time series, so that each concept was forecast only from its own historical observations. These parsimonious settings were adopted to match the short annual concept-level time series and to reduce the risk of overfitting or unstable estimation. For the controlled ablation study, the FULL, D3, D5, A2, A3, A4, and S2 variants share a fixed-prior protocol, so that each variant differs only in the targeted component.
Because the LLM backbone may have been exposed during pre-training to public information about technologies that became popular in 2024 or 2025, the evaluation may be affected by temporal knowledge contamination, which is a known concern in LLM-based evaluation [33,34]. We therefore treat the evaluation as contamination-aware rather than contamination-free. To reduce prompt-side and evidence-side leakage, all numerical evidence supplied to LLM-based methods is truncated at the end of the historical window. Candidate features are constructed only from observations no later than t 0 , and target-year hotness values are used only for evaluation. The prompts explicitly specify the allowed public-knowledge cutoff year, prohibit the use of target-year or later outcomes, and forbid adding new technology terms. In addition, LLM rationales and adjustment reasons are screened for post-cutoff-year references; unsafe free-text explanations are removed or excluded from downstream structured records and counted as semantic leakage flags.
This design separates two types of contamination risk. Prompt-side leakage refers to target-year or post-target evidence being included in the model input or prompt context; this is controlled by historical-window truncation, target-year exclusion from feature construction, and explicit prompt instructions. Parametric contamination refers to knowledge already stored in the pre-trained LLM; this cannot be fully eliminated without retraining or using a strictly time-bounded model. Therefore, our claims focus on controlling prompt-side and evidence-side leakage, while treating parametric contamination as a residual limitation.


4. Results

4.1. Main Results on Weak-Signal Forecasting

Table 3 presents the main results on Task2. As described in Section 3.5, Task2 is used as the main diagnostic weak-signal setting because it contains nontrivial emerging truths, the lowest historical–target Jaccard overlap, and the highest mean positive growth among the three rolling tasks. It is therefore suitable for evaluating whether a method can identify technologies with future rise potential rather than simply preserving historically frequent concepts.
AgentProphet achieves the best performance on four of the five Task2 metrics, including the primary GA-NDCG@10, E-Gain@10, E-MAP@10, and Standard NDCG@10. Its GA-NDCG@10 reaches 0.410 ± 0.076 , outperforming GRU ( 0.259 ), DirectLLM ( 0.214 ), DLinear ( 0.197 ), and ARIMA ( 0.099 ). This indicates a stronger ability to prioritize low-history concepts with substantive future growth potential.
The improvements on E-Gain@10 and E-MAP@10 further show that AgentProphet does not merely retrieve emerging candidates, but also ranks higher-gain candidates closer to the top. GRU obtains a slightly higher E-NDCG@10 score, suggesting that neural temporal models remain competitive for coarse-grained matching of some weak-signal candidates. In contrast, LastValue and ARIMA show similar behavior, reflecting the influence of continuation effects in short-horizon forecasting. Overall, the Task2 results support the effectiveness of source-aware multi-agent reasoning for growth-oriented emerging AI technology forecasting under incomplete multi-source evidence.

4.2. Ablation Study

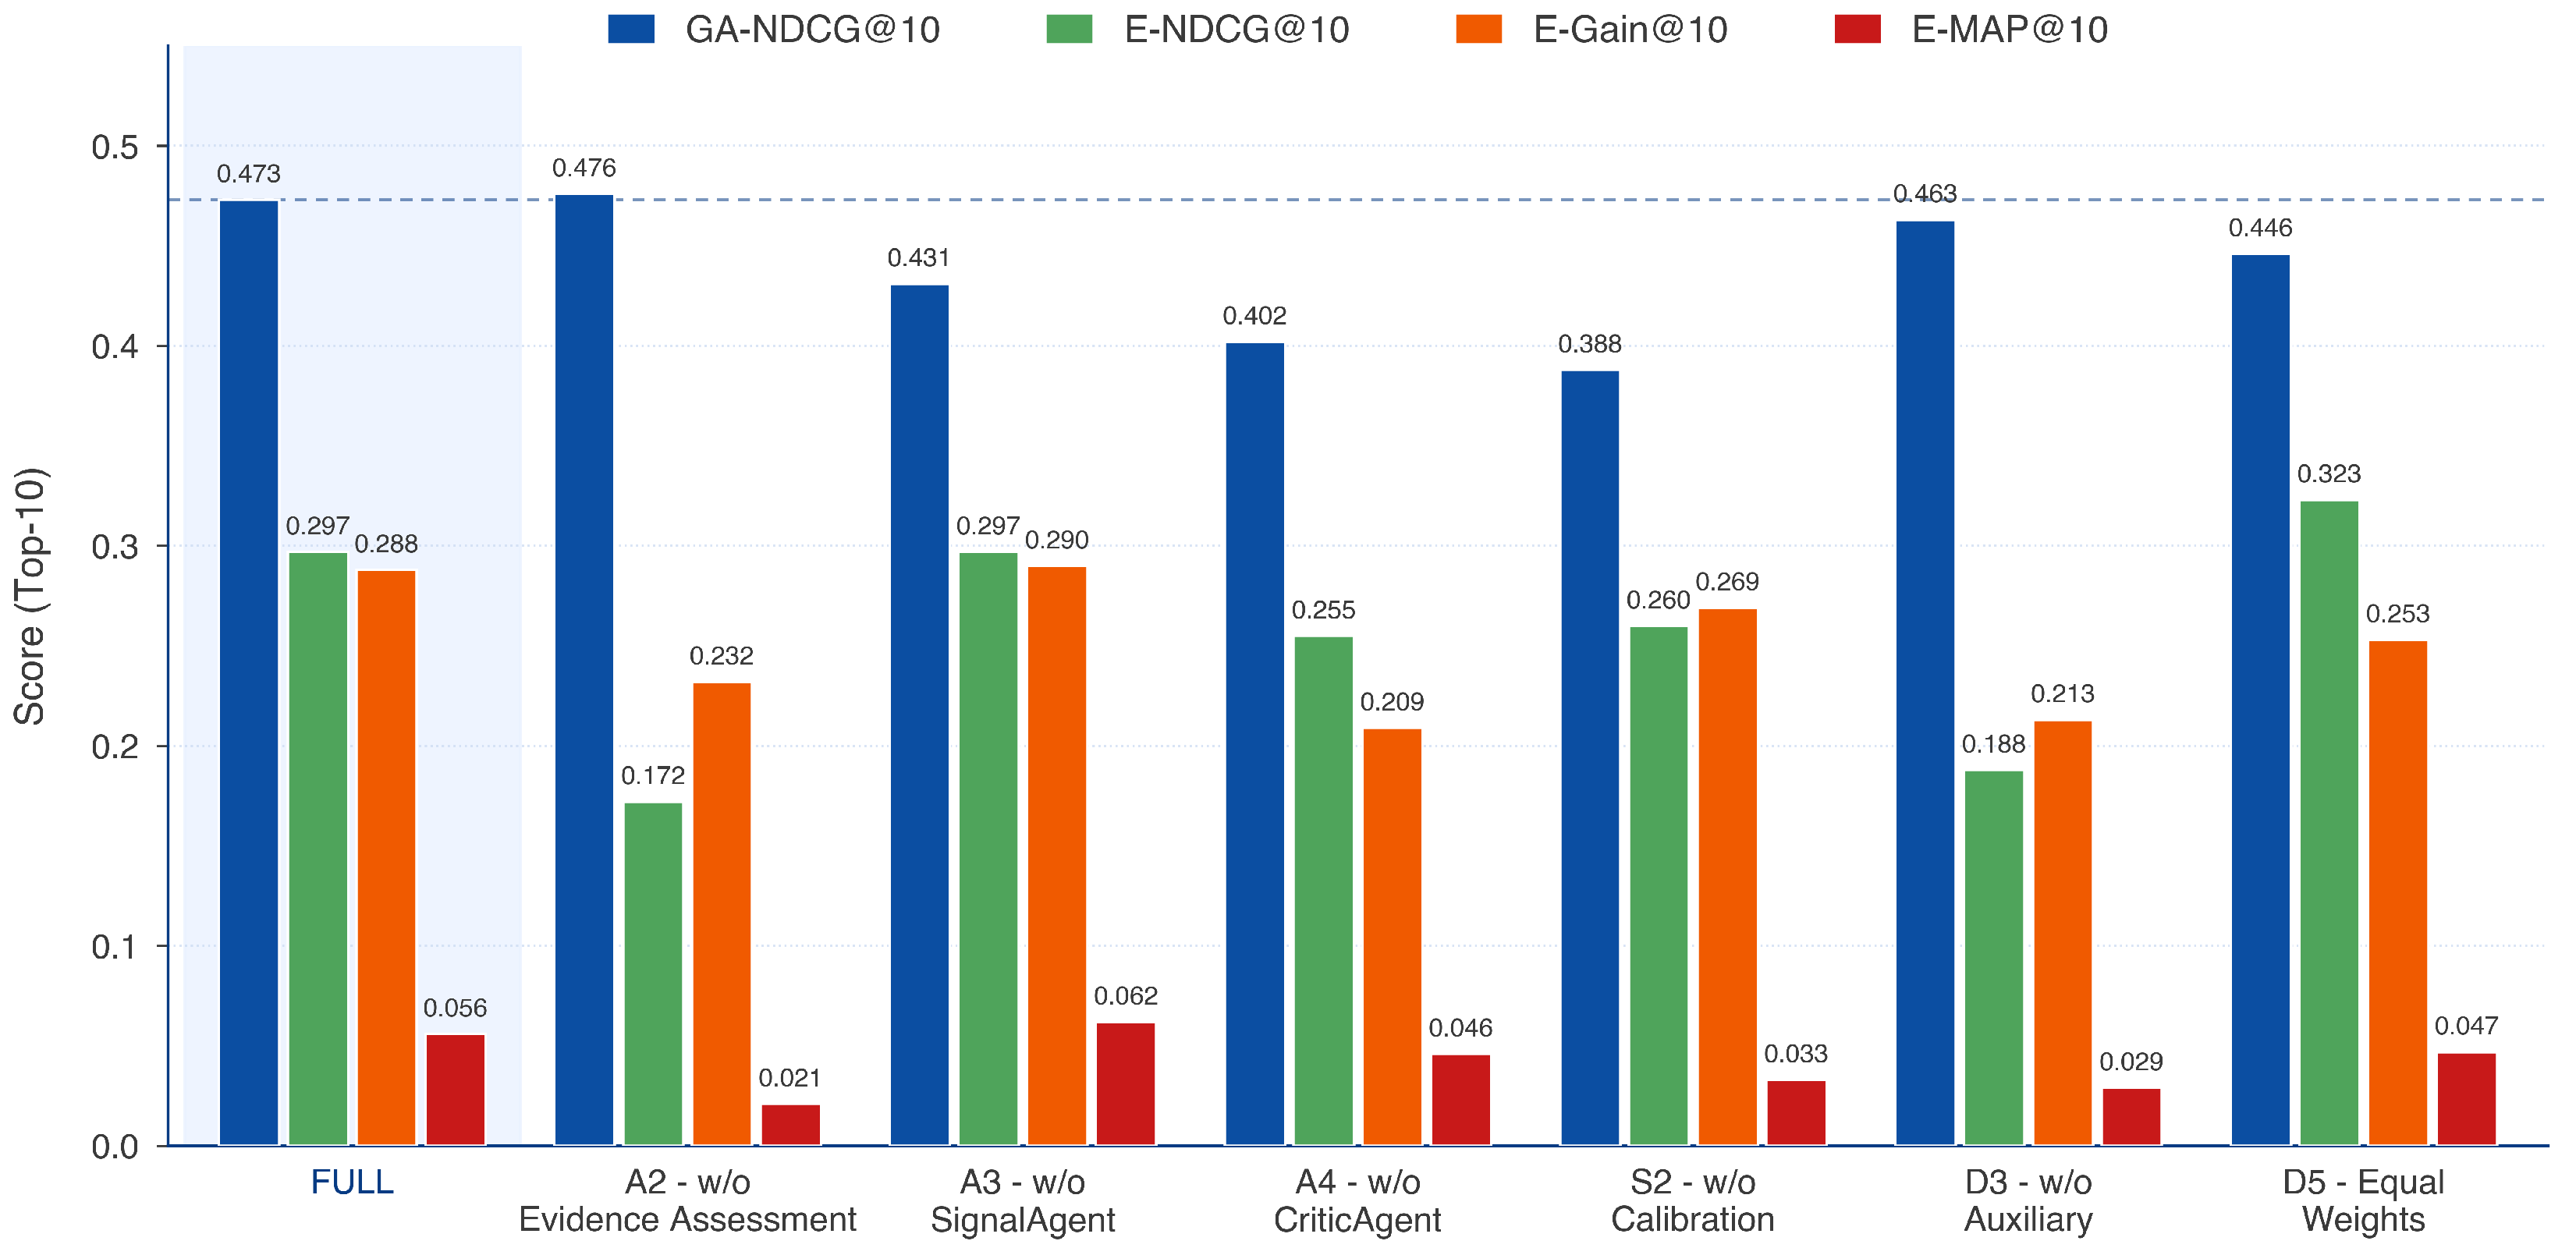
Figure 3 presents the controlled ablation results on Task2. The FULL configuration follows the fixed-prior protocol described in Section 3.5, so the ablation results should be interpreted as within-study comparisons among controlled variants rather than as direct comparisons with the five-run averaged results in Table 3.
The FULL configuration achieves a GA-NDCG@10 of 0.473 . Removing critic review (A4) reduces this score to 0.402 , while E-Gain@10 and E-MAP@10 decrease to 0.209 and 0.046 , respectively. Removing source-aware confidence calibration (S2) further reduces GA-NDCG@10 to 0.388 and E-MAP@10 to 0.033 . These declines indicate that critic-guided refinement and confidence-aware reasoning are important for stabilizing rankings under uncertain multi-source evidence.
Source-related ablations provide additional evidence for the source-aware design. Removing auxiliary sources (D3) only slightly reduces the primary metric from 0.473 to 0.463 , but weakens emerging-oriented metrics. Equal source weighting (D5) increases E-NDCG@10 to 0.323 , but lowers GA-NDCG@10, E-Gain@10, and E-MAP@10 compared with FULL. This suggests that auxiliary sources can provide complementary weak signals, but heterogeneous sources should not be treated as uniformly reliable.
A2 and A3 further reveal a multi-objective trade-off. A2 slightly improves GA-NDCG@10 to 0.476 , but substantially lowers emerging-oriented metrics, indicating that evidence-side semantic assessment helps preserve emerging-oriented ranking quality even when the growth-aware score is similar. A3 reduces GA-NDCG@10 to 0.431 while maintaining relatively strong E-Gain@10 and E-MAP@10, suggesting that the SignalAgent contributes to growth-sensitive trend characterization. Overall, the ablation results show that AgentProphet’s advantage is best understood as a balanced design across growth awareness, emerging prioritization, and ranking trustworthiness.

4.3. Robustness and Sensitivity Analysis

To further assess residual contamination risk from named technology terms, we conduct an anonymized Task2 robustness check. In this experiment, real technology names are replaced by anonymous identifiers, and the LLM receives only history-window source-year evidence profiles. The prompt explicitly prohibits inferring real technology names, products, events, or external world knowledge. This setting removes direct name-level semantic access to well-known technology terms and tests whether the forecasting procedure can still exploit historical multi-source trajectories.
As shown in Table 4, because the anonymized AgentProphet run uses a simplified anonymous candidate path with a reduced LLM-facing candidate set, this experiment is intended as a supplementary sanity check rather than a strict apples-to-apples replacement for the named main evaluation. The anonymized check shows that removing real technology names changes performance, suggesting that named semantic access affects model behavior and that parametric contamination cannot be completely ruled out. However, AgentProphet still obtains nonzero emerging-oriented performance under anonymous history-only inputs, with E-Gain@10 of 0.232, E-MAP@10 of 0.021, and NDCG@10 of 0.444. This suggests that the framework does not rely solely on memorized target-year popularity of named technologies; it also exploits historical source profiles, evidence quality, and trajectory structure. We therefore interpret the results as contamination-aware evidence rather than proof of a fully contamination-free LLM evaluation.
To evaluate robustness under different signal-maturity regimes, we report supplementary results on Task1 and Task3 in Table 5. Task1 corresponds to a sparser early-stage setting, whereas Task3 contains stronger continuation patterns. These two tasks complement the main Task2 setting and help clarify the boundary conditions of AgentProphet.
The cross-task results show that forecasting performance is sensitive to signal maturity. DirectLLM is more competitive on GA-NDCG@10 in Task1 and Task3, while AgentProphet obtains the best Task1 E-NDCG@10. Together with the task-property diagnostics in Table 2, these results indicate that AgentProphet is most effective in the balanced weak-signal regime represented by Task2. When signals are extremely sparse or already more mature, simpler LLM-based or continuation-sensitive baselines can become competitive. This clarifies the boundary condition of AgentProphet: it is designed for trustworthy weak-signal forecasting rather than uniformly dominating all signal regimes.
We further conduct a deterministic sensitivity analysis for the two design choices that directly affect emerging-oriented evaluation: source weights and weak-signal truth thresholds. For source weights, we recompute the source-weighted panel under six alternatives: equal sources ( 0.25 , 0.25 , 0.25 , 0.25 ) , primary only ( 0.50 , 0.50 , 0 , 0 ) , paper heavy ( 0.55 , 0.25 , 0.10 , 0.10 ) , patent heavy ( 0.25 , 0.55 , 0.10 , 0.10 ) , auxiliary upweighted ( 0.35 , 0.35 , 0.15 , 0.15 ) , and auxiliary high ( 0.30 , 0.30 , 0.20 , 0.20 ) .
For weak-truth construction, we compare the default threshold set with a stricter setting, a relaxed setting, and a stronger historical-prominence exclusion setting. The strict setting changes the short-history fraction from 0.60 to 0.40, the low-base factor from 0.60 to 0.40, and the minimum emergence score from 0.60 to 0.70. The relaxed setting changes these values to 0.80, 0.80, and 0.50, respectively. The historical-exclusion setting removes historical Top-20 concepts instead of historical Top-10 concepts.
As shown in Table 6, the Task2 diagnostic characterization is stable under most plausible source-weight perturbations. Equal weighting, primary-only weighting, auxiliary-upweighted weighting, and auxiliary-high weighting preserve the same Weak@10 value, historical–target overlap, target Top-10 set, and weak-truth set as the default protocol. Paper-heavy and patent-heavy variants change part of the target Top-10 set; the patent-heavy setting remains close to the default weak-truth set, whereas the paper-heavy setting shows a moderate change while preserving the same Weak@10 count. Threshold perturbation also leaves the target Top-10 unchanged; the strict setting reduces Weak@10 from four to three, while the relaxed and stronger historical-exclusion settings recover the default weak-truth set. These results support the use of the 0.4/0.4/0.1/0.1 fixed-source prior as a transparent main protocol, while indicating that the characterization of Task2 as a balanced weak-signal setting is not driven by a single weight or threshold choice.

4.4. Qualitative Case Study: SMCC-Oriented Capability Mapping

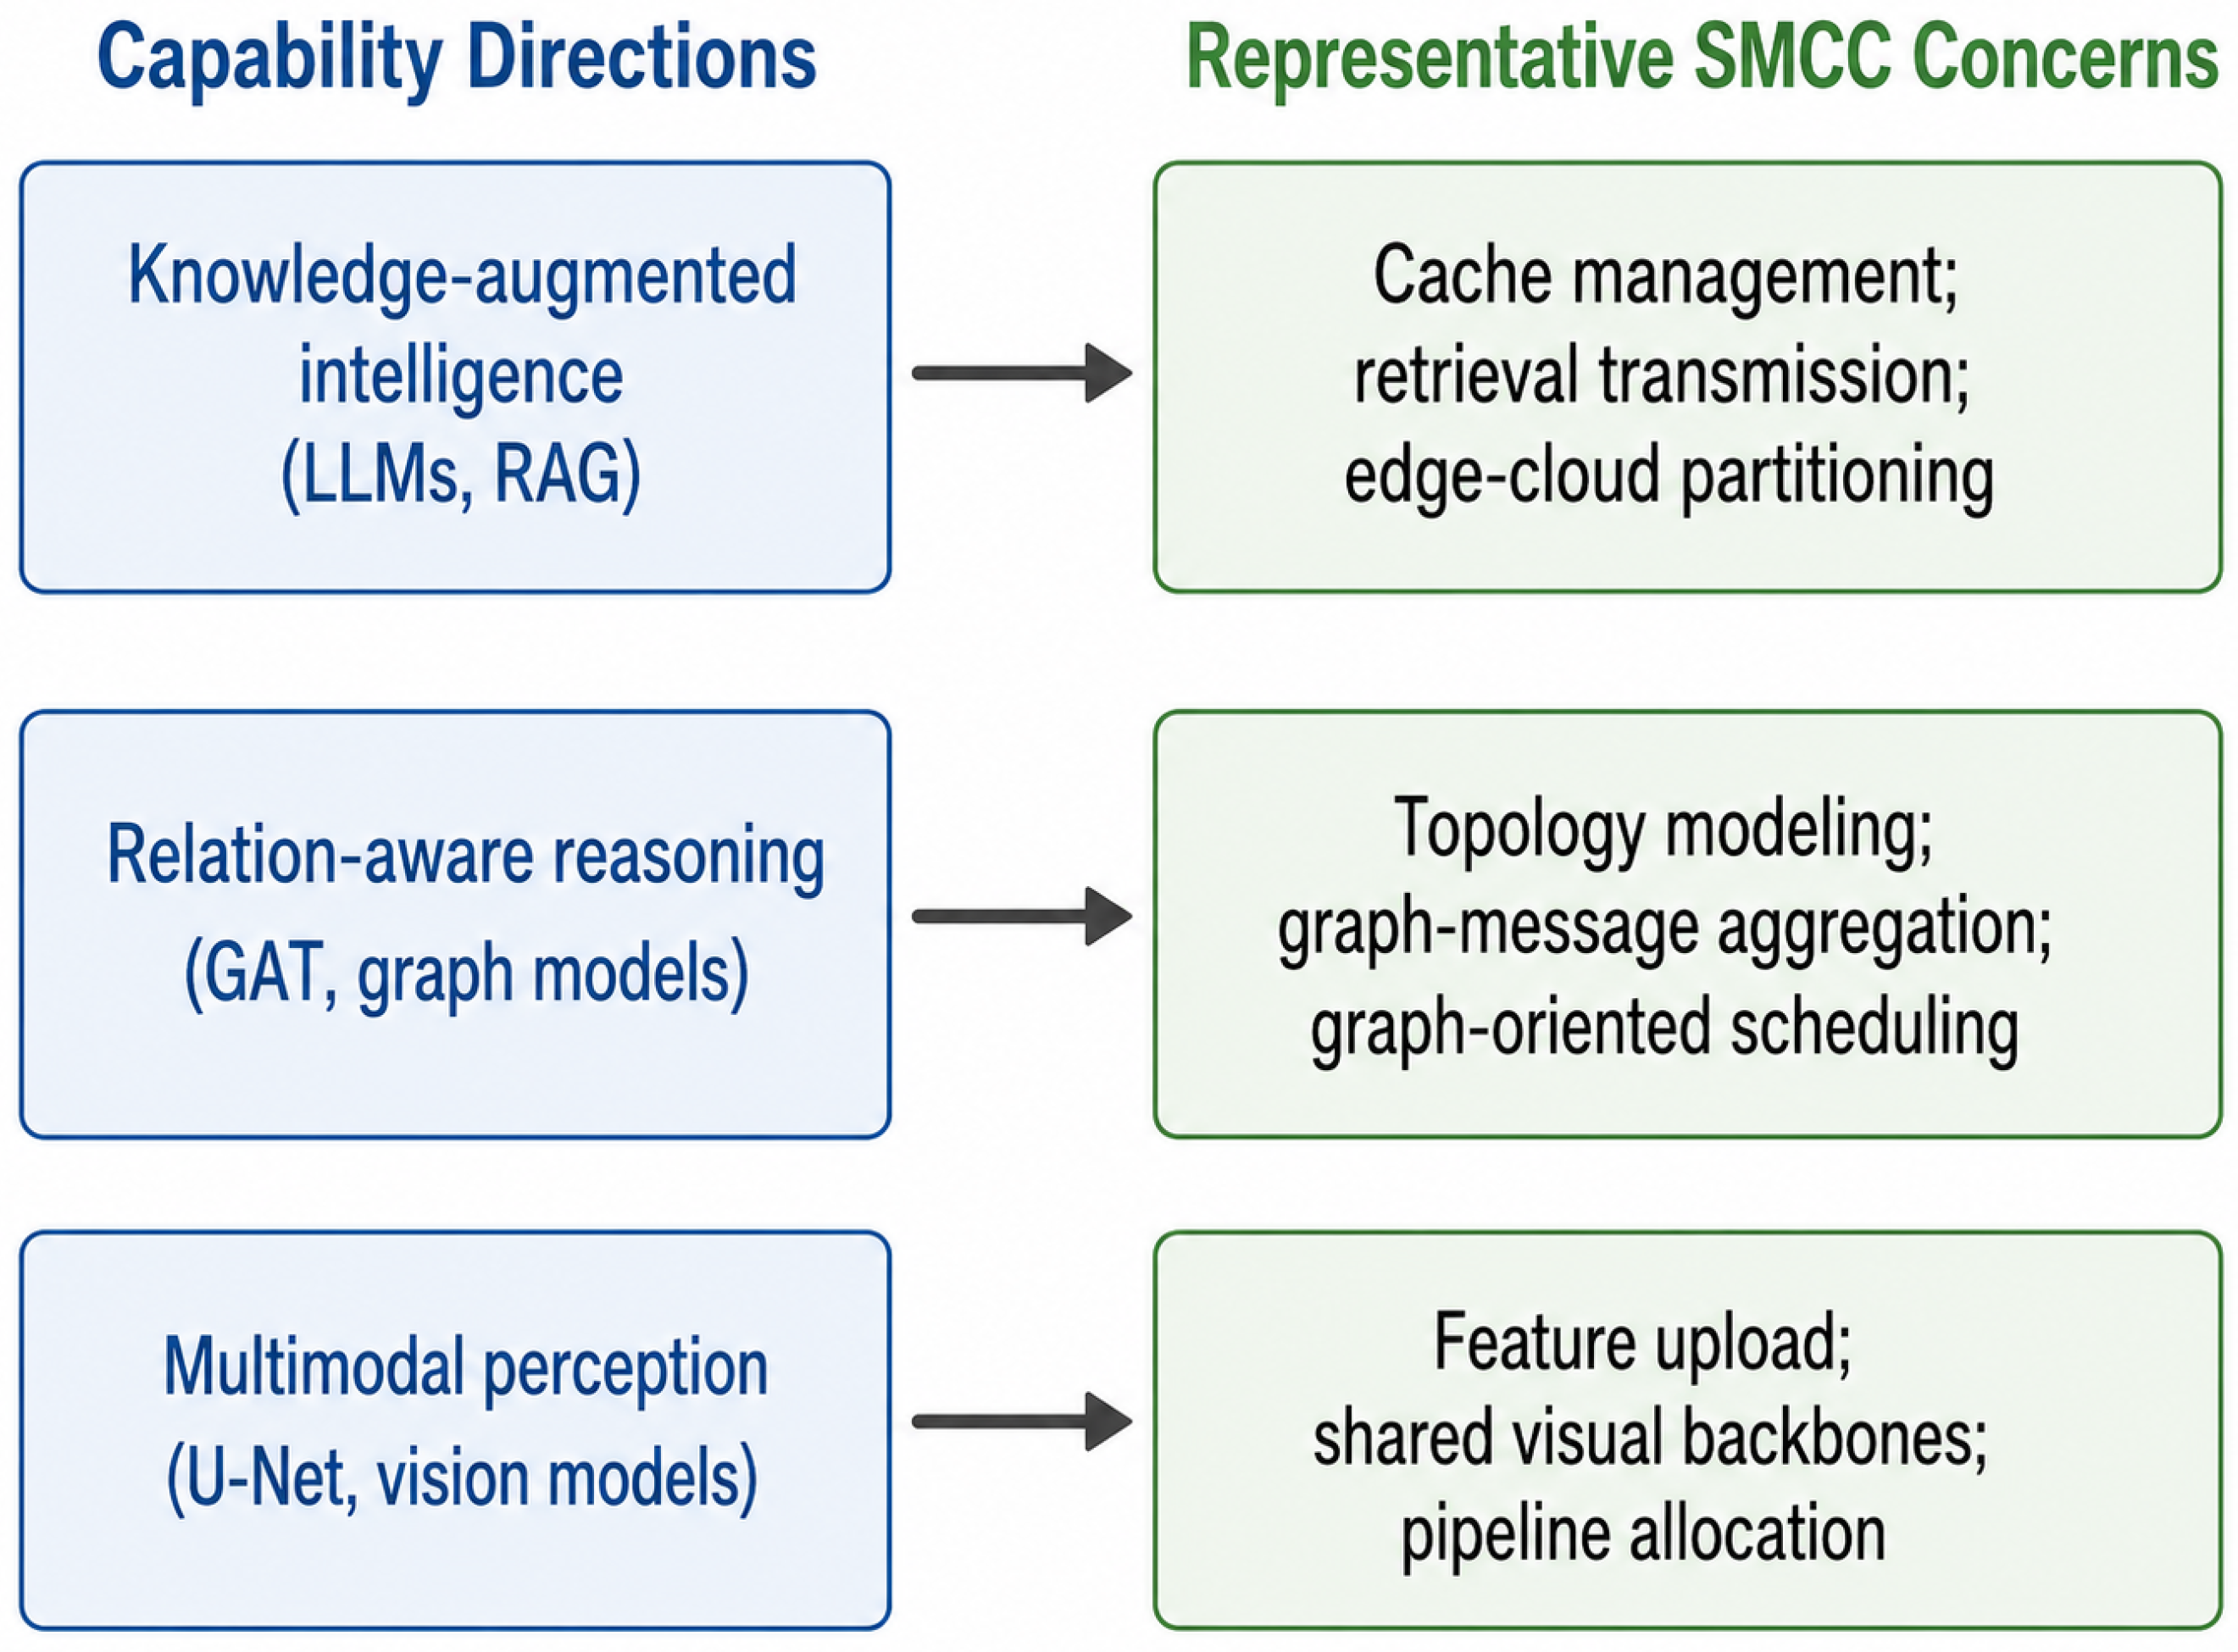
To examine the relevance of the forecasting results to AI-based IoT systems, we conduct a qualitative case study based on a representative Task2 run. AgentProphet ranks several technologies with potential system implications, including large language models, retrieval-augmented generation, graph attention networks, and U-Net. We group these technologies into three capability directions: knowledge-augmented intelligence, relation-aware reasoning, and multimodal perception.
As shown in Figure 4, the forecasted capability directions can be mapped to representative SMCC concerns [6,7]. Knowledge-augmented intelligence, represented by LLMs and retrieval-augmented generation, implies stronger demands on cache management, retrieval transmission, and edge–cloud partitioning. Relation-aware reasoning, represented by GAT and graph models, highlights topology modeling, graph-message aggregation, and graph-oriented scheduling. Multimodal perception, represented by U-Net and vision models, points to feature upload, shared visual backbones, and perception-to-decision pipeline allocation.
This case study is intended as a qualitative capability-mapping analysis rather than direct system-level validation of specific SMCC strategies. AgentProphet is not integrated into physical IoT hardware, edge devices, communication stacks, or deployed SMCC control loops in this study. Therefore, the case study does not show that an IoT system runs faster, at lower cost, more reliably, or with lower energy consumption after using AgentProphet. Instead, it illustrates how forecasted AI technology directions can serve as upstream data-level evidence to inform SMCC-oriented capability planning. Whether these cues improve concrete system outcomes such as latency, energy efficiency, communication overhead, resource utilization, reliability, or deployment quality requires future system-level experiments.

5. Discussion

5.1. Interpretation and Boundary Conditions

The results indicate that AgentProphet is most useful in balanced weak-signal settings, where early evidence is available but incomplete, heterogeneous, and not yet mature enough for simple continuation-based forecasting. Its advantage therefore lies less in universal forecasting dominance and more in uncertainty-aware prioritization under partial multi-source evidence.
The ablation results suggest that source-aware confidence calibration and critic-guided refinement are important for stabilizing rankings when evidence quality varies across papers, patents, policies, and reports. This supports the design choice of preserving source-specific evidence profiles rather than collapsing all signals into a homogeneous input.
For AI-based IoT systems, the SMCC-oriented case study should be interpreted as qualitative capability mapping rather than system-level validation. The present study shows how forecasted technology directions may inform upstream planning hypotheses, but it does not demonstrate improvements in latency, energy efficiency, communication overhead, resource utilization, or deployment reliability.

5.2. Limitations and Future Work

This study has three main limitations. First, the dataset is constructed from four source categories, including papers, patents, policy documents, and reports. Although these sources provide complementary scientific, technical, strategic, and industrial evidence, the coverage is still limited by the selected data platforms, query strategies, and document availability. In particular, reports and policy documents are fewer than papers and patents, which may affect the stability of auxiliary-source signals. Future work will expand the dataset to include broader international sources, open technical repositories, standards documents, and additional industrial evidence.
Second, the SMCC-oriented application analysis is a qualitative capability-mapping case study rather than a full system-level deployment or testbed validation. The observed usefulness of AgentProphet should be interpreted as task-dependent. The current findings are based on technology forecasting and SMCC-oriented capability mapping, and further validation is required before they can be generalized to other forecasting tasks, domains, evaluation settings, or downstream decision-making scenarios. The case study illustrates how forecasted technology directions may inform sensing, memory, communication, and computation planning, but it does not directly measure system-level improvements such as latency reduction, energy efficiency, communication overhead, edge–cloud resource utilization, reliability, or deployment cost. It also does not demonstrate integration with physical IoT hardware, edge–cloud middleware, or online resource-management modules. Future work will integrate AgentProphet with AI-based IoT testbeds to evaluate whether forecast-driven capability planning can improve concrete system performance and operational reliability.
Third, a remaining limitation is potential parametric contamination in LLM-based forecasting. Although all prompts and numerical evidence are restricted to the historical window, the pre-trained LLM may still contain public knowledge about technologies that became prominent in 2024 or 2025. The anonymized robustness check reduces direct access to named technology knowledge, but it cannot fully prove that all parametric knowledge effects are removed. Therefore, the results should be interpreted as contamination-aware rather than contamination-free. Future work will use time-bounded language models, frozen archival models, or fully anonymized forecasting protocols to further isolate temporal generalization from pre-trained world knowledge.

6. Conclusions

This paper proposed AgentProphet, a source-aware multi-agent framework for emerging AI technology forecasting for upstream decision-making in AI-based IoT systems. Motivated by SMCC-oriented capability planning, AgentProphet integrates heterogeneous evidence from papers, patents, policy documents, and reports into a unified concept space while preserving source-specific evidence profiles. By combining role-specialized agent reasoning, source-aware confidence calibration, and critic-guided refinement, the framework aims to identify technologies with weak historical visibility but substantive future growth potential under incomplete and heterogeneous multi-source evidence.
Rolling forecasting experiments demonstrated that AgentProphet achieves strong performance in the main balanced weak-signal setting, particularly on growth-aware and emerging-oriented ranking metrics. However, the supplementary Task1 and Task3 results show that DirectLLM can be more competitive under extremely sparse or more mature signal regimes. Therefore, the contribution of AgentProphet should be interpreted as conditional: it is most suitable for balanced weak-signal regimes, where early evidence is available but incomplete and not yet sufficiently mature for simple continuation-based or direct-prompt forecasting.
The SMCC-oriented case study further illustrated how forecasted AI technology directions can be mapped to representative capability-planning cues, including cache management, retrieval transmission, topology modeling, graph-message aggregation, feature upload, and edge–cloud partitioning. This mapping should be understood as a qualitative data-level interpretation rather than evidence of system-level deployment or performance improvement. The present study does not show that AgentProphet makes an IoT system faster, lower cost, more energy-efficient, or more reliable. Future work will explore broader data coverage, stronger contamination-aware or anonymized forecasting protocols, and system-level validation on concrete AI-based IoT or edge–cloud testbeds where latency, energy, communication overhead, resource utilization, cost, reliability, and deployment quality can be directly measured.

Supplementary Materials

The following supporting information can be downloaded at https://www.mdpi.com/article/10.3390/app16136787/s1, Supplementary File S1: Role prompts, input templates, output schemas, scoring rules, calibration formulas, critic intervention rules, and representative intermediate outputs and original Chinese canonical technology terms with English glosses for representative terms; Supplementary File S2: Processed concept-year panel and minimal concept-alignment outputs; Supplementary File S3: Main-experiment and ablation result CSV files reported in the manuscript; Supplementary File S4: Core analysis scripts for concept-panel construction, forecasting, and ablation.

Author Contributions

Conceptualization, T.C.; methodology, T.C. and H.W.; algorithm design, T.C. and H.W.; software, T.C.; validation, T.C.; formal analysis, T.C.; investigation, T.C. and G.K.; data collection and processing, H.W.; writing—original draft preparation, T.C. and G.K.; writing—review and editing, T.C., H.W. and G.K.; visualization, T.C.; supervision, H.W.; project administration, H.W.; funding acquisition, H.W. All authors have read and agreed to the published version of the manuscript.

Funding

This research was funded by the Guangdong Province Philosophy and Social Science Planning 2024 General Project, grant number GD24CTS01; the Guangdong Province Soft Science Research Program, grant number 2025B1010010006; the Open Research Fund from Guangdong Laboratory of Artificial Intelligence and Digital Economy (SZ), grant number GML-KF-24-03; the Guangdong Province Soft Science and Technological Innovation Governance Project under Grant, grant number 2024B0808010001; the Science and Technology Strategic Research Project of the Shenzhen Science and Technology Project, grant number RKX20250526095702004; and the National Science Foundation of China, grant number 42571512.

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

The processed concept-year panel, minimal concept-alignment outputs, agent prompt templates, core analysis scripts, and compact main-experiment and ablation result files supporting the analyses reported in this study are provided in the Supplementary Materials. Additional processed materials may be made available by the corresponding author upon reasonable request. Some source data cannot be publicly shared due to access restrictions or licensing constraints from the original data providers.

Conflicts of Interest

The authors declare no conflicts of interest. The funders had no role in the design of the study; in the collection, analyses, or interpretation of data; in the writing of the manuscript; or in the decision to publish the results.

Abbreviations

The following abbreviations are used in this manuscript:
RAGRetrieval-Augmented Generation
GATGraph Attention Network
NDCGNormalized Discounted Cumulative Gain
GA-NDCGGrowth-Aware Normalized Discounted Cumulative Gain
E-NDCGEmerging Normalized Discounted Cumulative Gain
E-GainEmerging Gain
E-MAPEmerging Mean Average Precision
GRUGated Recurrent Unit
ARIMAAutoregressive Integrated Moving Average

References

  1. Menon, U.V.; Kumaravelu, V.B.; Kumar, C.V.; Rammohan, A.; Chinnadurai, S.; Venkatesan, R.; Hai, H.; Selvaprabhu, P. AI-Powered IoT: A Survey on Integrating Artificial Intelligence With IoT for Enhanced Security, Efficiency, and Smart Applications. IEEE Access 2025, 13, 50296–50339. [Google Scholar] [CrossRef] [Scilit]
  2. Siam, S.I.; Ahn, H.; Liu, L.; Alam, S.; Shen, H.; Cao, Z.; Shroff, N.; Krishnamachari, B.; Srivastava, M.; Zhang, M. Artificial intelligence of things: A survey. ACM Trans. Sens. Netw. 2025, 21, 1–75. [Google Scholar] [CrossRef] [Scilit]
  3. Friha, O.; Amine Ferrag, M.; Kantarci, B.; Cakmak, B.; Ozgun, A.; Ghoualmi-Zine, N. LLM-Based Edge Intelligence: A Comprehensive Survey on Architectures, Applications, Security and Trustworthiness. IEEE Open J. Commun. Soc. 2024, 5, 5799–5856. [Google Scholar] [CrossRef] [Scilit]
  4. Shen, Y.; Shao, J.; Zhang, X.; Lin, Z.; Pan, H.; Li, D.; Zhang, J.; Letaief, K.B. Large language models empowered autonomous edge AI for connected intelligence. IEEE Commun. Mag. 2024, 62, 140–146. [Google Scholar] [CrossRef] [Scilit]
  5. Wen, D.; Zhou, Y.; Li, X.; Shi, Y.; Huang, K.; Letaief, K.B. A Survey on Integrated Sensing, Communication, and Computation. IEEE Commun. Surv. Tutor. 2025, 27, 3058–3098. [Google Scholar] [CrossRef] [Scilit]
  6. Yang, W.; Liew, Z.Q.; Lim, W.Y.B.; Xiong, Z.; Niyato, D.; Chi, X.; Cao, X.; Letaief, K.B. Semantic communication meets edge intelligence. IEEE Wirel. Commun. 2022, 29, 28–35. [Google Scholar] [CrossRef] [Scilit]
  7. Liang, C.; Du, H.; Sun, Y.; Niyato, D.; Kang, J.; Zhao, D.; Imran, M.A. Generative AI-Driven Semantic Communication Networks: Architecture, Technologies, and Applications. IEEE Trans. Cogn. Commun. Netw. 2025, 11, 27–47. [Google Scholar] [CrossRef] [Scilit]
  8. Ebadi, A.; Auger, A.; Gauthier, Y. Detecting emerging technologies and their evolution using deep learning and weak signal analysis. J. Inf. 2022, 16, 101344. [Google Scholar] [CrossRef] [Scilit]
  9. Hain, D.; Jurowetzki, R.; Lee, S.; Zhou, Y. Machine learning and artificial intelligence for science, technology, innovation mapping and forecasting: Review, synthesis, and applications. Scientometrics 2023, 128, 1465–1472. [Google Scholar] [CrossRef] [Scilit]
  10. Kyebambe, M.N.; Cheng, G.; Huang, Y.; He, C.; Zhang, Z. Forecasting emerging technologies: A supervised learning approach through patent analysis. Technol. Forecast. Soc. Change 2017, 125, 236–244. [Google Scholar] [CrossRef] [Scilit]
  11. Zhou, Y.; Dong, F.; Liu, Y.; Li, Z.; Du, J.; Zhang, L. Forecasting emerging technologies using data augmentation and deep learning. Scientometrics 2020, 123, 1–29. [Google Scholar] [CrossRef] [Scilit]
  12. Magerman, T.; Van Looy, B.; Song, X. Exploring the feasibility and accuracy of Latent Semantic Analysis based text mining techniques to detect similarity between patent documents and scientific publications. Scientometrics 2010, 82, 289–306. [Google Scholar] [CrossRef] [Scilit]
  13. Block, C.; Wustmans, M.; Laibach, N.; Bröring, S. Semantic bridging of patents and scientific publications–The case of an emerging sustainability-oriented technology. Technol. Forecast. Soc. Change 2021, 167, 120689. [Google Scholar] [CrossRef] [Scilit]
  14. Sarica, S.; Luo, J.; Wood, K.L. TechNet: Technology semantic network based on patent data. Expert Syst. Appl. 2020, 142, 112995. [Google Scholar] [CrossRef] [Scilit]
  15. Lee, M.; Kim, S.; Kim, H.; Lee, J. Technology opportunity discovery using deep learning-based text mining and a knowledge graph. Technol. Forecast. Soc. Change 2022, 180, 121718. [Google Scholar] [CrossRef] [Scilit]
  16. Gruver, N.; Finzi, M.; Qiu, S.; Wilson, A.G. Large language models are zero-shot time series forecasters. In Proceedings of the 37th International Conference on Neural Information Processing Systems, NIPS ’23, New Orleans, LA, USA, 10–16 December 2023; Curran Associates, Inc.: Red Hook, NY, USA, 2023; Volume 36, pp. 19622–19635. [Google Scholar] [CrossRef] [Scilit]
  17. Xue, H.; Salim, F.D. PromptCast: A New Prompt-Based Learning Paradigm for Time Series Forecasting. IEEE Trans. Knowl. Data Eng. 2024, 36, 6851–6864. [Google Scholar] [CrossRef] [Scilit]
  18. Noh, S.H. Predicting Future Promising Technologies Using LSTM. Informatics 2022, 9, 77. [Google Scholar] [CrossRef] [Scilit]
  19. Taheri, S.; Aliakbary, S. Research trend prediction in computer science publications: A deep neural network approach. Scientometrics 2022, 127, 849–869. [Google Scholar] [CrossRef] [Scilit]
  20. Kazmi, A.B.; Islam, M.A. DBLP-TKT: A Time-Series Dataset and Deep Learning Model for Academic Keyword Trend Prediction. Scientometrics 2026, 131, 1147–1183. [Google Scholar] [CrossRef] [Scilit]
  21. Jiang, M.; Yang, S.; Gao, Q. Multidimensional indicators to identify emerging technologies: Perspective of technological knowledge flow. J. Inf. 2024, 18, 101483. [Google Scholar] [CrossRef] [Scilit]
  22. Zhang, J.; Yan, B. Technology Convergence Prediction From a Timeliness Perspective: An Improved Contribution Index in a Dynamic Network. In Proceedings of the Joint Workshop of the 5th Extraction and Evaluation of Knowledge Entities from Scientific Documents (EEKE2024) and the 4th AI + Informetrics (AII2024), Changchun, China, 23–24 April 2024; CEUR-WS.org: Aachen, Germany, 2024; Volume 3745, pp. 34–39. [Google Scholar]
  23. Wu, Q.; Bansal, G.; Zhang, J.; Wu, Y.; Li, B.; Zhu, E.; Jiang, L.; Zhang, X.; Zhang, S.; Liu, J.; et al. AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversations. In Proceedings of the First Conference on Language Modeling(COLM 2024), Philadelphia, PA, USA, 7–9 October 2024. [Google Scholar]
  24. Ghafarollahi, A.; Buehler, M.J. SciAgents: Automating scientific discovery through bioinspired multi-agent intelligent graph reasoning. Adv. Mater. 2025, 37, 2413523. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  25. Zheng, T.; Deng, Z.; Tsang, H.T.; Wang, W.; Bai, J.; Wang, Z.; Song, Y. From Automation to Autonomy: A Survey on Large Language Models in Scientific Discovery. In Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, Suzhou, China, 4–9 November 2025; Christodoulopoulos, C., Chakraborty, T., Rose, C., Peng, V., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2025; pp. 17733–17750. [Google Scholar] [CrossRef] [Scilit]
  26. Chen, T.; Xiao, J.; Wang, H. CTLKE: Keyphrase Extraction Agent for Chinese Technical Literature. In Proceedings of the 2026 IEEE International Conference on Big Data and Smart Computing (BigComp), Guangzhou, China, 2–5 February 2026; IEEE: New York, NY, USA, 2026; pp. 354–357. [Google Scholar]
  27. Hyndman, R.J.; Khandakar, Y. Automatic Time Series Forecasting: The forecast Package for R. J. Stat. Softw. 2008, 27, 1–22. [Google Scholar] [CrossRef] [Scilit]
  28. Zeng, A.; Chen, M.; Zhang, L.; Xu, Q. Are transformers effective for time series forecasting? In Proceedings of the Thirty-Seventh AAAI Conference on Artificial Intelligence and Thirty-Fifth Conference on Innovative Applications of Artificial Intelligence and Thirteenth Symposium on Educational Advances in Artificial Intelligence, AAAI’23/IAAI’23/EAAI’23, Washington, DC, USA, 7–14 February 2023; Volume 37, pp. 11121–11128. [Google Scholar] [CrossRef] [Scilit]
  29. Cho, K.; van Merriënboer, B.; Gulcehre, C.; Bahdanau, D.; Bougares, F.; Schwenk, H.; Bengio, Y. Learning Phrase Representations using RNN Encoder–Decoder for Statistical Machine Translation. In Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP), Doha, Qatar, 25–29 October 2014; Association for Computational Linguistics: Stroudsburg, PA, USA, 2014; pp. 1724–1734. [Google Scholar] [CrossRef] [Scilit]
  30. Järvelin, K.; Kekäläinen, J. Cumulated gain-based evaluation of IR techniques. ACM Trans. Inf. Syst. (TOIS) 2002, 20, 422–446. [Google Scholar] [CrossRef] [Scilit]
  31. Ranaei, S.; Suominen, A.; Porter, A.; Carley, S. Evaluating technological emergence using text analytics: Two case technologies and three approaches. Scientometrics 2020, 122, 215–247. [Google Scholar] [CrossRef] [Scilit]
  32. Rennings, M.; Baaden, P.; Block, C.; John, M.; Bröring, S. Assessing emerging sustainability-oriented technologies: The case of precision agriculture. Scientometrics 2024, 129, 2969–2998. [Google Scholar] [CrossRef] [Scilit]
  33. Dong, Y.; Jiang, X.; Liu, H.; Jin, Z.; Gu, B.; Yang, M.; Li, G. Generalization or Memorization: Data Contamination and Trustworthy Evaluation for Large Language Models. In Proceedings of the Findings of the Association for Computational Linguistics: ACL 2024, Bangkok, Thailand, 11–16 August 2024; Ku, L.W., Martins, A., Srikumar, V., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 12039–12050. [Google Scholar] [CrossRef] [Scilit]
  34. Zhu, W.; Hao, H.; He, Z.; Song, Y.Z.; Jiao, Y.; Zhang, Y.; Hu, H.; Wei, Y.; Wang, R.; Lu, H. CLEAN–EVAL: Clean Evaluation on Contaminated Large Language Models. In Proceedings of the Findings of the Association for Computational Linguistics: NAACL 2024, Mexico City, Mexico, 16–21 June 2024; Duh, K., Gomez, H., Bethard, S., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 835–847. [Google Scholar] [CrossRef] [Scilit]
Figure 1. Overview of AgentProphet. The framework aligns heterogeneous technology evidence into a source-aware concept panel X c , performs role-specialized multi-agent forecasting to generate a candidate ranking R cand , and applies confidence calibration with critic-guided refinement to produce the final target-year emerging technology ranking R final .
Applsci 16 06787 g001
Figure 2. Rolling-window forecasting tasks. Task2 is used as the main diagnostic weak-signal setting, while Task1 and Task3 are retained for supplementary cross-task sensitivity analysis.
Applsci 16 06787 g002
Figure 3. Task2 ablation results. The dashed horizontal line marks the GA-NDCG@10 score of the FULL configuration, and the light-blue shaded area highlights the FULL reference configuration. FULL denotes the controlled full AgentProphet configuration; A2 removes evidence-side semantic assessment; A3 removes the SignalAgent stage; A4 removes critic review; S2 removes source-aware confidence calibration; D3 removes auxiliary sources; and D5 uses equal source weighting.
Applsci 16 06787 g003
Figure 4. Mapping from forecasted capability directions to representative SMCC concerns in AI-based IoT systems.
Applsci 16 06787 g004
Table 1. Input and output protocol of the four AgentProphet agents.
AgentPrompt Objective and Main InputsStructured Output and Downstream Use
EvidenceAgentAssesses multi-source evidence reliability using a history-derived evidence score, recent growth, trend slope, support years, primary/auxiliary-source support, source coverage, emergence score, early-signal status, and risk flags.Outputs an evidence-quality label (strong, moderate, or weak) and a concern field. The quality label adjusts the evidence score.
SignalAgentClassifies the temporal pattern of each concept using historical hotness, mean hotness, recent growth, trend slope, support years, recent primary support, recent source coverage, emergence score, and early-signal status.Outputs a stage label (emerging, growing, mature, or declining) and a momentum score in [ 0 , 1 ] . These values update the signal score.
ForecastAgentGenerates target-year hotness predictions from evidence quality, trend stage, momentum, candidate channel, historical hotness, growth, trend, support years, recent primary support, source coverage, and emergence score.Outputs predicted hotness, semantic trend (breakthrough, rising, stable, or fading), semantic confidence, and a short reason. The prediction is calibrated with numerical trajectory estimates.
CriticAgentReviews temporal-leakage risks, over-confident predictions, weakly supported candidates, and under-predicted emerging candidates using top predictions, emerging underdogs, evidence quality, semantic confidence, growth features, source support, and review channel.Outputs a bounded multiplicative factor, reason, and optional leakage flags. The factor is applied after deterministic bounding as a localized correction to the ForecastAgent prediction.
Table 2. Task-property diagnostics for the rolling forecasting settings.
TaskTargetWeak@10Overlap@10Hist. HotnessGrowth
Task1202320.3330.00043.75
Task2202440.1760.800117.25
Task3202540.4294.87517.83
Table 3. Main results on Task2. The upward arrows indicate that higher values are better. Bold values denote the best result for each metric. AgentProphet is reported as mean ± standard deviation over five runs, whereas deterministic baselines and DirectLLM are reported as single values under fixed configurations.
MethodGA-NDCG@10 ↑E-NDCG@10 ↑E-Gain@10 ↑E-MAP@10 ↑NDCG@10 ↑
LastValue0.0000.1230.1480.0130.364
ARIMA0.0990.1230.1480.0120.364
DLinear0.1970.1810.2320.0220.427
GRU0.2590.2960.1510.0360.386
DirectLLM0.2140.1670.2320.0190.438
AgentProphet0.410 ± 0.0760.289 ± 0.0250.305 ± 0.0600.056 ± 0.0080.474 ± 0.039
Table 4. Named Task2 results vs. anonymized Task2 robustness check.
MethodSettingGA-NDCG@10E-Gain@10E-MAP@10NDCG@10
DirectLLMNamed0.2140.2320.0190.438
DirectLLMAnonymous0.3270.1480.0130.364
AgentProphetNamed0.4100.3050.0560.474
AgentProphetAnonymous0.2110.2320.0210.444
Table 5. Supplementary cross-task results on Task1 and Task3. Bold numeric values indicate the best result in each metric column.
MethodTask1Task3
GA-NDCG@10E-NDCG@10GA-NDCG@10E-NDCG@10
LastValue0.0000.1120.0000.503
ARIMA0.1330.0670.1020.290
DLinear0.1750.1070.2590.331
GRU0.0910.0760.2230.525
DirectLLM0.2780.1120.4310.551
AgentProphet0.0830.1240.2040.507
Table 6. Sensitivity of Task2 diagnostics to source weights and weak-truth thresholds.
Weight SchemeThreshold SchemeWeak@10Overlap@10Top10 Jac. vs. DefaultWeak Jac. vs. Default
Default technical primaryDefault40.1761.0001.000
Equal sourcesDefault40.1761.0001.000
Primary onlyDefault40.1761.0001.000
Paper heavyDefault40.1760.8180.600
Patent heavyDefault50.2500.8180.800
Auxiliary upweightedDefault40.1761.0001.000
Auxiliary highDefault40.1761.0001.000
Default technical primaryStrict30.1761.0000.750
Default technical primaryRelaxed40.1761.0001.000
Default technical primaryExclude hist. Top-2040.1761.0001.000
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.