1. Introduction
Unmanned aerial vehicles (UAVs) have been widely adopted in inspection, monitoring, logistics, and emergency response because of their high mobility and flexible deployment [
1,
2,
3]. However, their endurance is still strongly constrained by the limited capacity and weight of onboard batteries [
1]. Wireless power transfer (WPT) provides a promising solution for autonomous return-to-base charging because it enables contactless energy replenishment without manual battery replacement or plug-in operation [
2,
4]. Fixed docking and charging platforms represent an important implementation form of autonomous UAV energy replenishment [
5,
6,
7,
8]. After the UAV is supported by such a platform, the landing structure establishes the nominal relative height and attitude of the charging coils, while a residual lateral offset may remain because of landing-position error and installation tolerance. This lateral offset changes the mutual coupling between the transmitting and receiving coils, reduces the coupling coefficient and transferred power, and may prevent the system from entering a stable high-efficiency charging state [
9,
10]. Therefore, accurate and low-complexity estimation of the residual lateral offset is an important requirement for fixed UAV wireless-charging platforms.
External vision- or radio-based localization methods can assist UAV landing and positioning [
11,
12,
13]. However, vision-based approaches rely on favorable imaging conditions and a clear line of sight, making them sensitive to illumination changes and occlusion. Radio-based approaches often require additional hardware or infrastructure and may be affected by multipath propagation and electromagnetic interference. These dependencies increase system complexity and deployment cost. Therefore, localization approaches that can be integrated directly into wireless charging systems have attracted increasing attention as a means of reducing reliance on external sensing infrastructure.
From the algorithmic perspective, existing misalignment detection and localization methods can be roughly divided into three categories. (1) The first category is model-driven or analytical estimation methods, in which coil offset is inferred from mutual-inductance models, magnetic-field distribution, or auxiliary sensing coils. These methods have good physical interpretability and usually require limited training data [
10,
14], but their accuracy strongly depends on coil parameters, vertical distance, attitude variation, and calibration conditions. (2) The second category is search- or fingerprint-matching-based methods, such as array-coil scanning, lookup tables, weighted nearest-neighbor matching, and coil-selection strategies [
15,
16]. These methods can adapt to nonlinear spatial magnetic-field distributions, but they often require online distance calculation, neighborhood search, or repeated array activation, which increases inference latency and limits their use in fast embedded closed-loop alignment. (3) The third category is data-driven regression methods, where machine learning models directly map multi-channel sensing signals to spatial coordinates [
16,
17,
18]. Such methods can learn nonlinear voltage–position relationships and reduce the need for explicit modeling. However, conventional lightweight models such as multilayer perceptrons usually treat each sampling point as an independent sample and cannot fully exploit the spatial continuity and neighborhood correlations contained in the induced-voltage fingerprint map.
Recent embedded-AI architectures, including depthwise-separable convolutional networks, compact Transformer models, and prototype-based EdgeML methods, have demonstrated promising performance in resource-constrained intelligent systems [
19,
20,
21]. Nevertheless, these methods are typically designed to exploit specific data structures, such as local spatial correlations, long-range dependencies, or prototype-based representations. Whether such architectural characteristics are advantageous for low-dimensional induced-voltage localization remains unclear and has not been systematically investigated in UAV wireless-charging alignment applications.
Graph neural networks (GNNs) provide a potential way to model such spatial correlations because sampling points in the localization area can be naturally organized as graph nodes [
22,
23]. In particular, graph attention networks can adaptively aggregate information from neighboring nodes and enhance the representation of local and regional spatial features [
22]. However, direct deployment of a graph model on a resource-constrained microcontroller is difficult because online graph construction and message passing introduce additional memory consumption and computational latency [
20,
21,
24]. This leads to a contradiction between localization accuracy and embedded deployability: high-capacity graph models are suitable for offline spatial feature learning, whereas compact feedforward networks are more suitable for real-time microcontroller unit (MCU) inference.
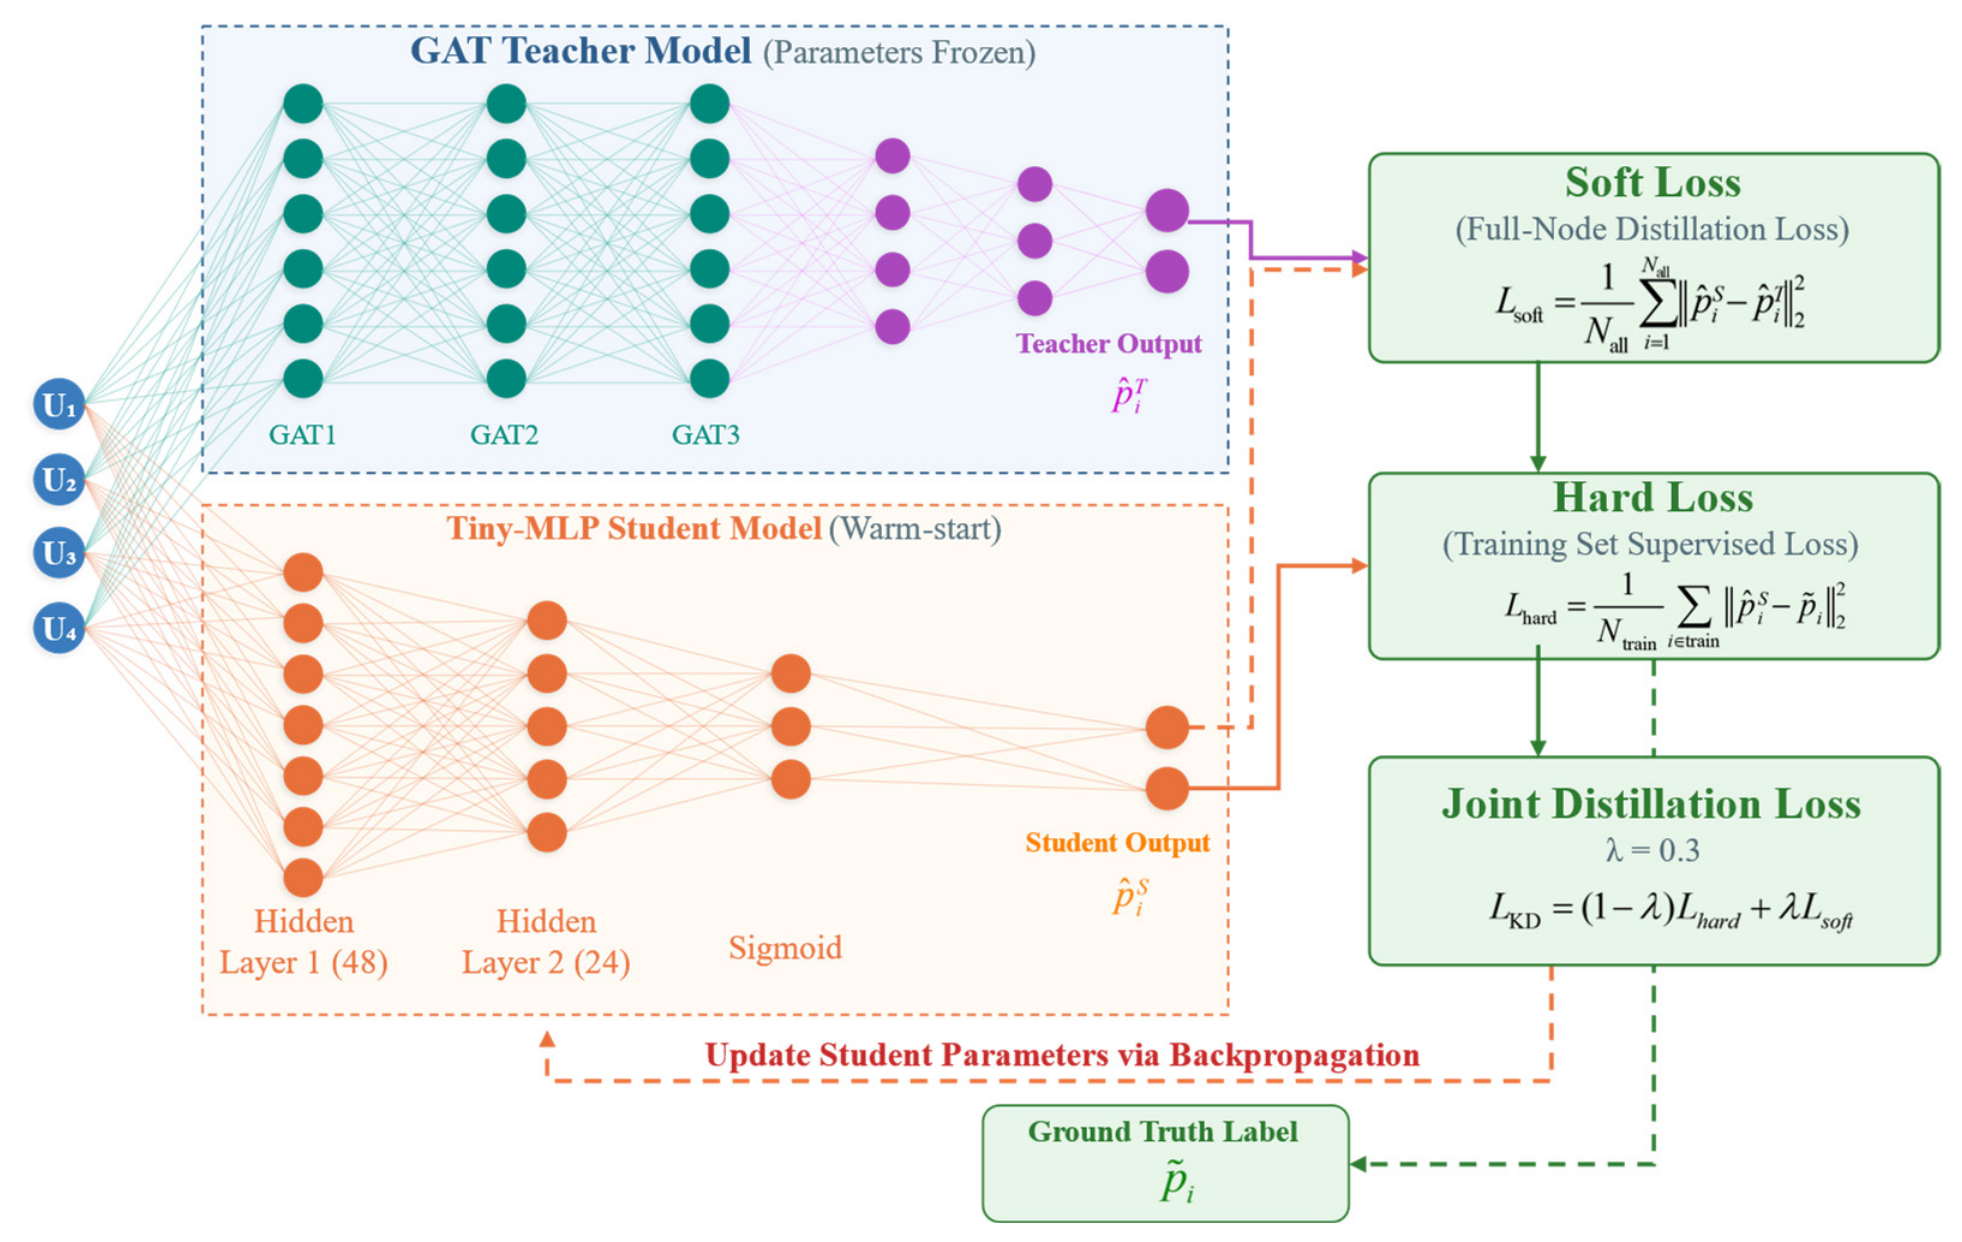
To address such issues, this study proposes a graph-attention-based knowledge distillation method for self-alignment localization in UAV wireless charging. In the offline stage, four-channel induced-voltage fingerprints are collected and organized into a multi-scale spatial graph, enabling the graph attention network (GAT) teacher model to learn neighborhood correlations in the voltage–position mapping. The learned spatial knowledge is then distilled into a lightweight Tiny-multilayer perceptron (Tiny-MLP), which is deployed on the MCU for online localization. In this way, the proposed method preserves the spatial modeling ability of graph learning while avoiding online graph construction and message passing, making it suitable for real-time closed-loop alignment control.
Key contributions of this paper are summarized as follows: (1) For the practical coil-misalignment problem in UAV self-aligning wireless charging, a four-channel induced-voltage localization scheme is developed, which realizes lateral offset estimation using the charging-platform sensing coils rather than external visual or ranging sensors. (2) To overcome the limitation of existing voltage-fingerprint localization methods that treat sampling points independently, a graph-structured fingerprint representation is constructed to introduce spatial neighborhood correlations into the voltage–position mapping. (3) To solve the deployment conflict between graph-based spatial modeling and MCU-based real-time control, a GAT-assisted knowledge distillation framework is proposed, in which spatial knowledge is learned offline by the GAT teacher and transferred to a lightweight Tiny-MLP for online closed-loop self-alignment.
The remainder of this paper is organized as follows.
Section 2 describes the system architecture and working principle, including the localization circuit, fingerprint-database construction, teacher–student models, and MCU deployment.
Section 3 presents the localization, ablation, and closed-loop alignment results.
Section 4 discusses the main findings, applicable operating conditions, and current limitations.
Section 5 concludes the paper and summarizes its engineering significance.
2. Materials and Methods
2.1. Structure of the UAV Wireless Charging Alignment Platform
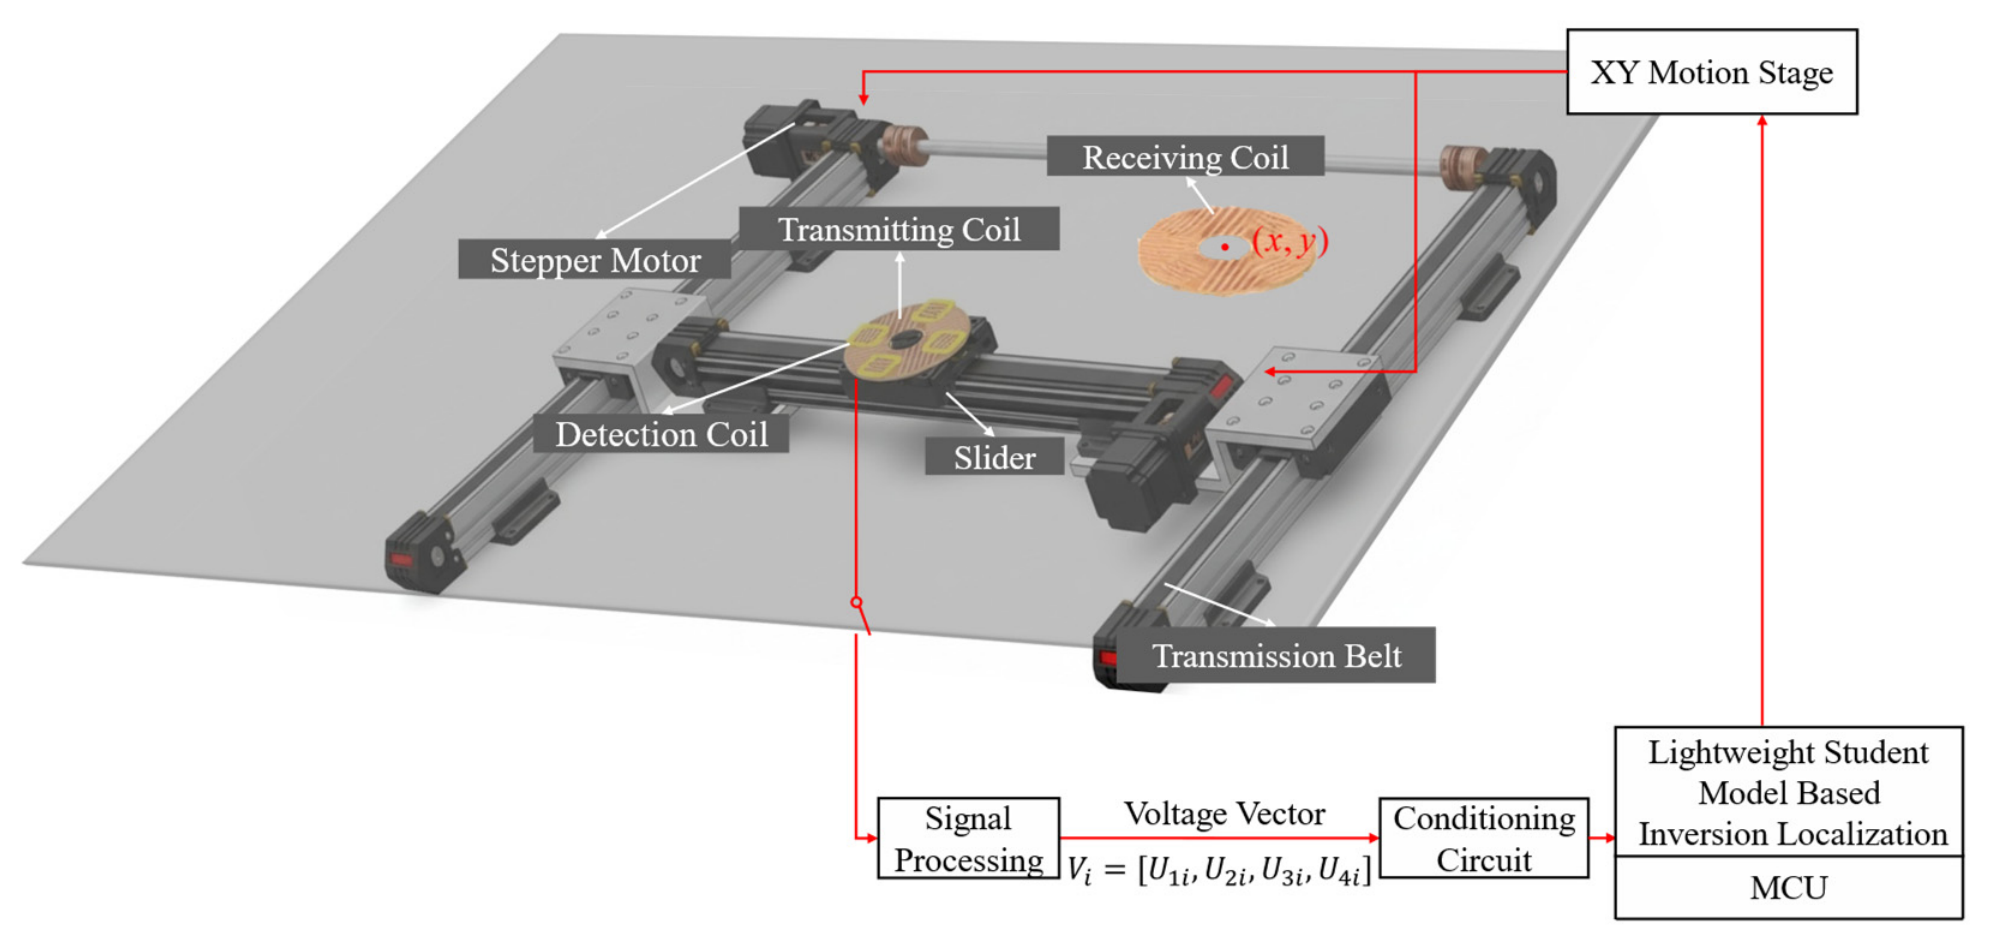
The system described in this study primarily comprises a wireless charging main circuit, a detection coil array, a controller, and a two-dimensional mobile platform, as shown in
Figure 1. The receiving coil is carried by the UAV, whereas the transmitting coil, detection coils, and alignment mechanism are integrated into the charging platform.
The alignment process begins after the UAV has landed and is stably supported by the platform. At this stage, the landing gear and supporting structure establish a repeatable relative geometry between the transmitting and receiving coils, including their nominal vertical separation and approximately parallel orientation. Landing-position error may nevertheless leave a lateral displacement between the coil centers, which is the alignment variable estimated and compensated in this study.
Before entering the energy-transfer mode, the transmitter generates a high-frequency magnetic field for alignment detection. The lateral position of the receiving coil changes the local coupling relationships, and the four detection coils arranged around the transmitting coil produce induced-voltage signals corresponding to the current lateral misalignment.
These induced-voltage signals are conditioned and then sampled by the controller. Based on the trained lightweight localization model, the controller estimates the current two-dimensional position of the receiving coil and calculates the corresponding offset relative to the target center. The XY platform is then driven to compensate for this offset, so that the receiving coil gradually approaches the center of the transmitting coil. After each movement, the system performs voltage sampling and position estimation again, forming an iterative closed-loop alignment process. Therefore, the overall alignment mechanism can be summarized as “sampling—inference—compensation”.
2.2. Localization Circuit Design and Localization Fingerprint
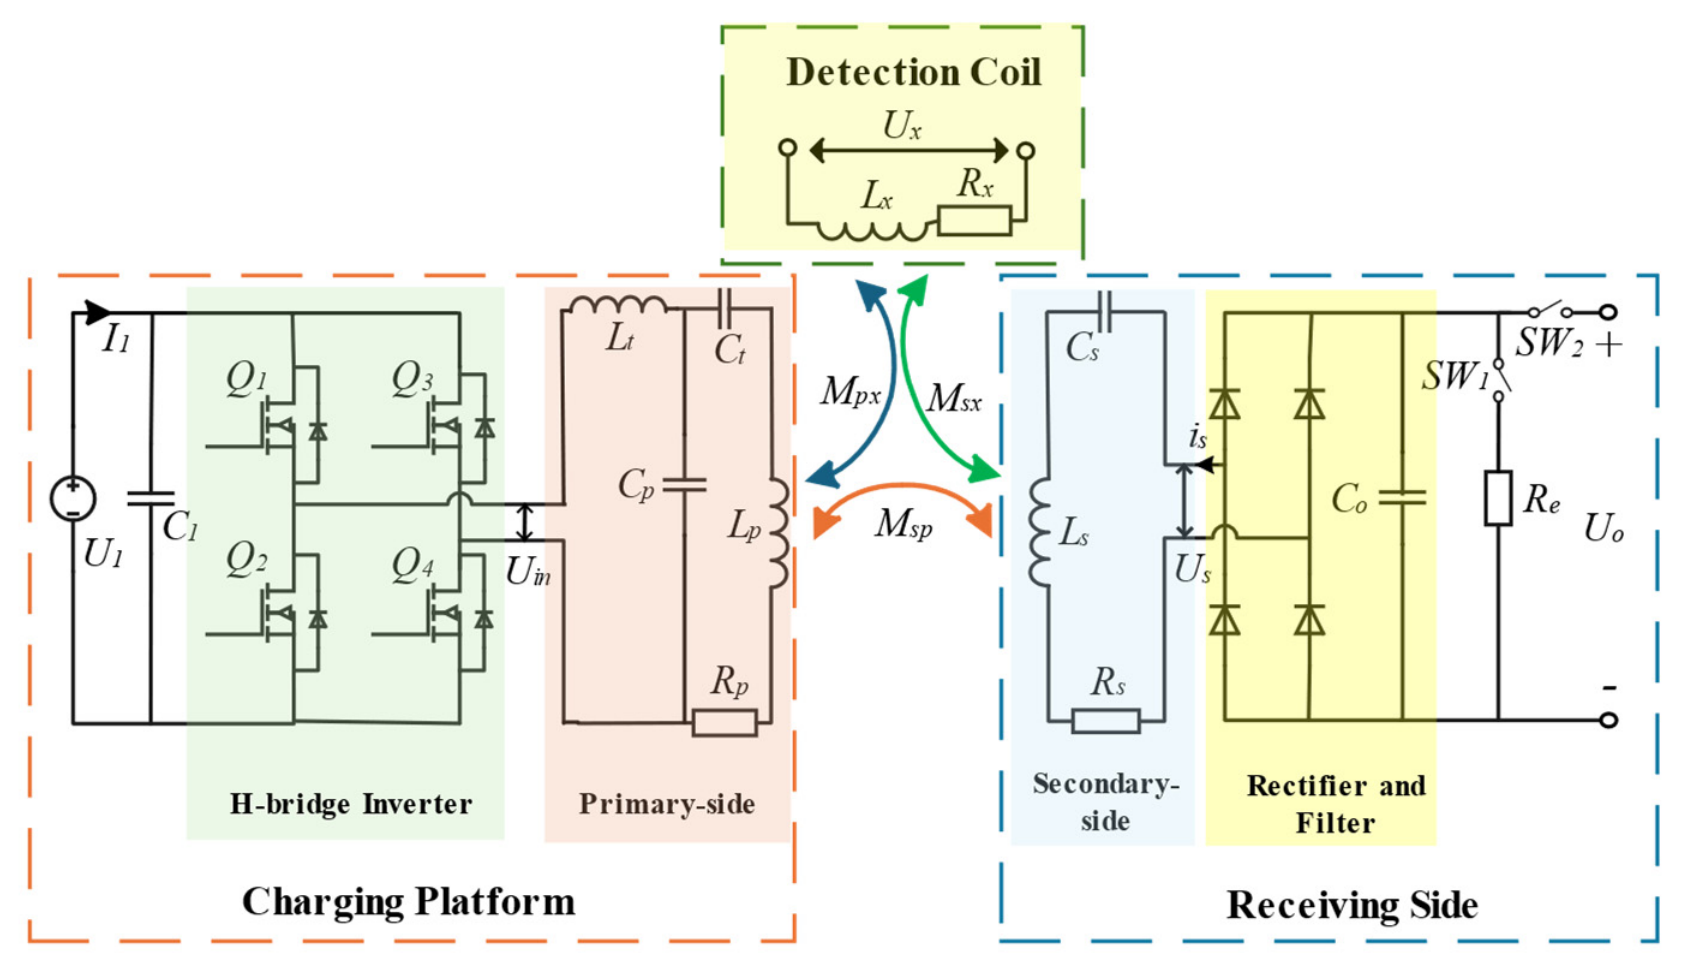
To meet the weight reduction requirements of UAV and the characteristics of the compensation network, an LCC-S resonant compensation structure is adopted [
25]. As shown in
Figure 2, the localization auxiliary array consisting of four coils arranged symmetrically is placed above the transmit coil. Only one detection coil is shown in the figure.
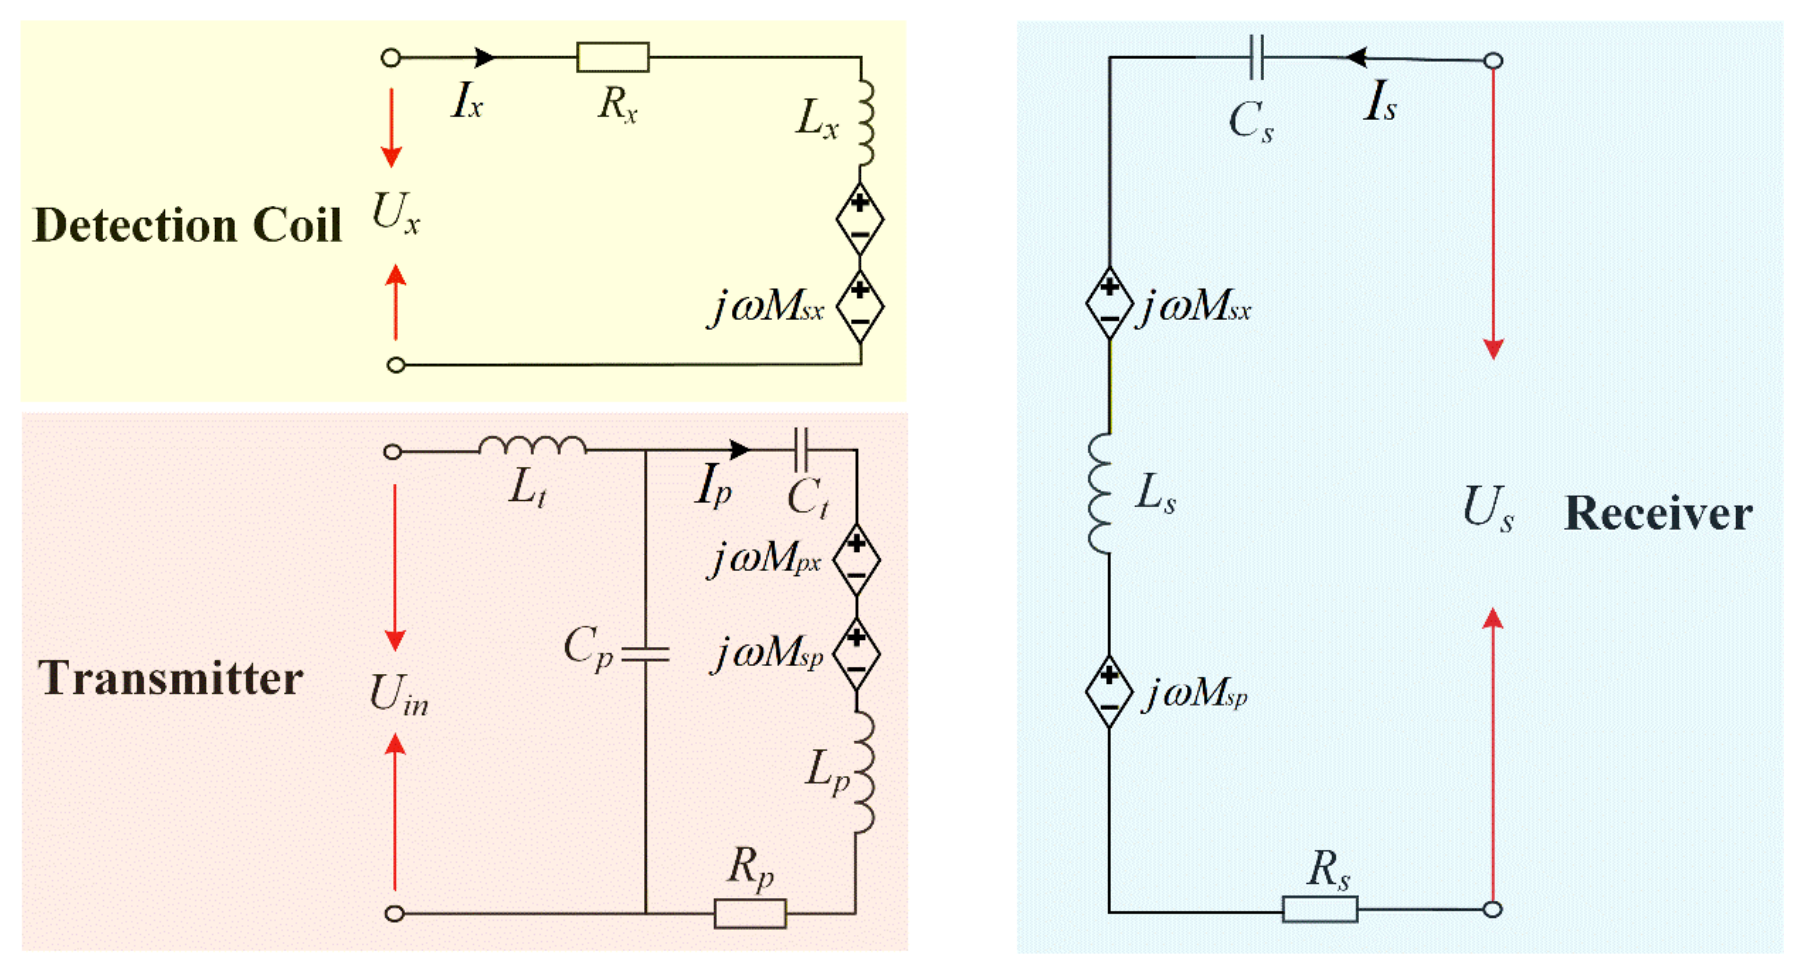
This circuit contains a power main circuit and a detection and control circuit. The primary side of the main circuit includes a full-bridge inverter, an LCC-S compensation network (, , ), and a transmitting coil (self-inductance , parasitic resistance ); the secondary side comprises a receiving coil (self-inductance , parasitic resistance ), a resonant capacitor , and a rectifier bridge (with a parallel filter capacitor ); the load side is controlled by and to switch between operating modes. When is open and is closed, the system operates in alignment detection mode, with a virtual load connected to establish a stable excitation and acquire measurements from the detection coil; when is closed and is open, the system switches to energy transfer mode for high-efficiency charging after alignment. The detection loop consists of an auxiliary coil magnetically coupled to the main power link, and a current-limiting resistor , which outputs an induced voltage () that characterizes the coupling state.
Since the resonant network suppresses higher-order harmonics, the fundamental-wave equivalent mutual inductance model (established in
Figure 3) is used to analyze the coupling relationship between the coils and the induced voltage:
Let the system operating frequency be
. When the transmitting coil and the detection coil are completely decoupled (
), Kirchhoff’s voltage law and the equivalent virtual load at the receiving side yield:
When the receiving coil is displaced relative to the transmitting coil, the mutual-coupling relationships among the transmitting, receiving, and detection coils change, resulting in corresponding variations in the four induced voltages. Vertical separation and roll/pitch deviations can also modify this voltage–position relationship. In the fixed post-landing platform considered in this study, however, these quantities are constrained by the landing and supporting structure and remain consistent during fingerprint acquisition and online localization. Their systematic effects are therefore incorporated into the calibrated fingerprint database rather than treated as unknown localization variables. If the nominal platform geometry changes, the fingerprint database should be recalibrated accordingly. Moreover, the transmitting and receiving coils are circular planar coils arranged in a stacked configuration and are rotationally symmetric about their normal axes; thus, yaw rotation does not change their ideal geometric overlap and is not independently estimated. The localization task is therefore formulated as a regression from the four induced voltages to the two-dimensional lateral coordinates.
2.3. System Localization Implementation
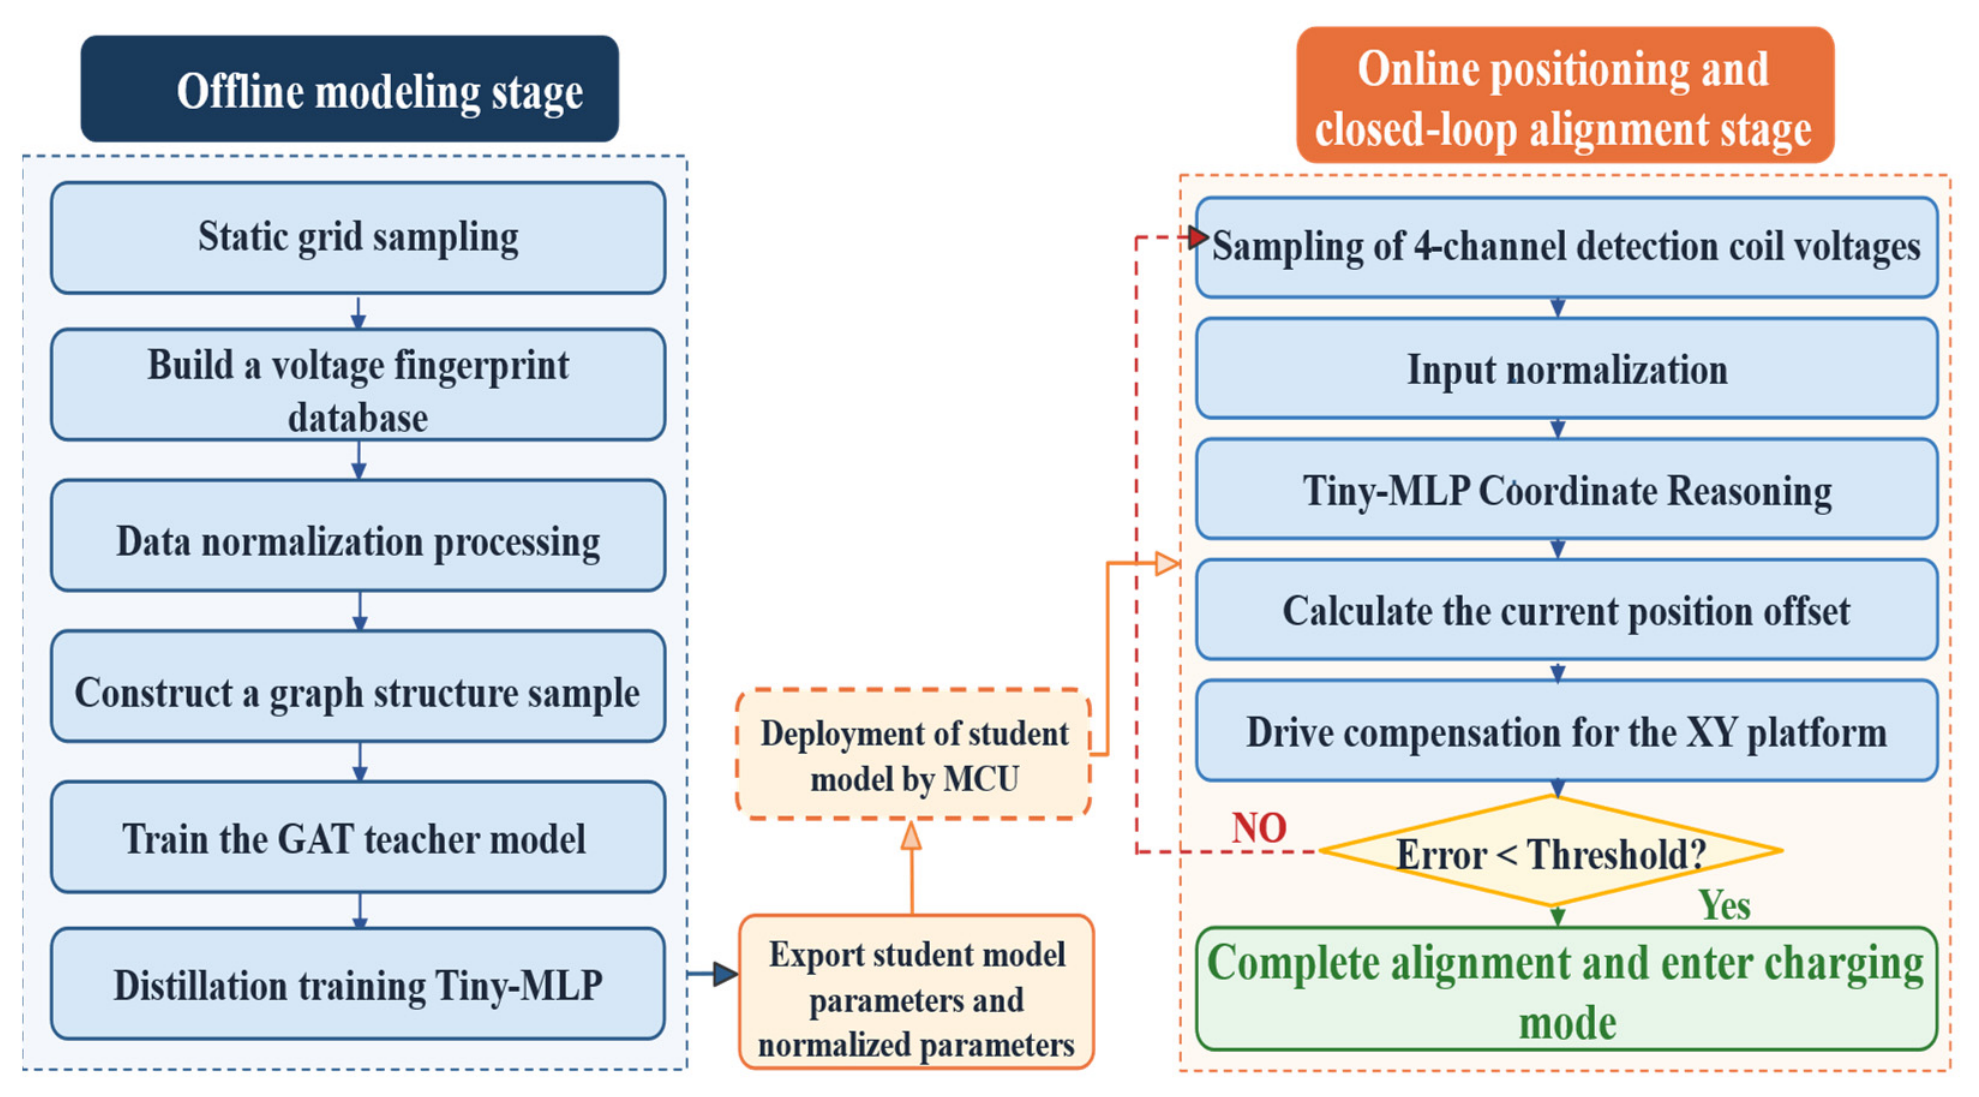
According to
Figure 4, a complete alignment control chain is established and partitioned into offline and online stages. In the offline stage, static sampling is performed within the target positioning area based on a preset grid. The four induced voltages and true coordinates corresponding to each sampling point are recorded to construct a static induced voltage fingerprint database. Subsequently, the GAT teacher model is trained based on this graph structure, and a lightweight Tiny-MLP student model suitable for online deployment is obtained through knowledge distillation. In the online stage, the MCU acquires four induced voltages and preprocesses the measurements using the normalization parameters saved offline. Then the Tiny-MLP model is invoked to output an estimated coordinate for the current position; the XY platform is controlled based on the offset between the predicted coordinates and the target center so as to perform positional compensation. Iterative corrections are made using a preset threshold until the charging state is triggered after meeting the alignment requirements.
2.4. Building of the Static Induced Voltage Fingerprint Database
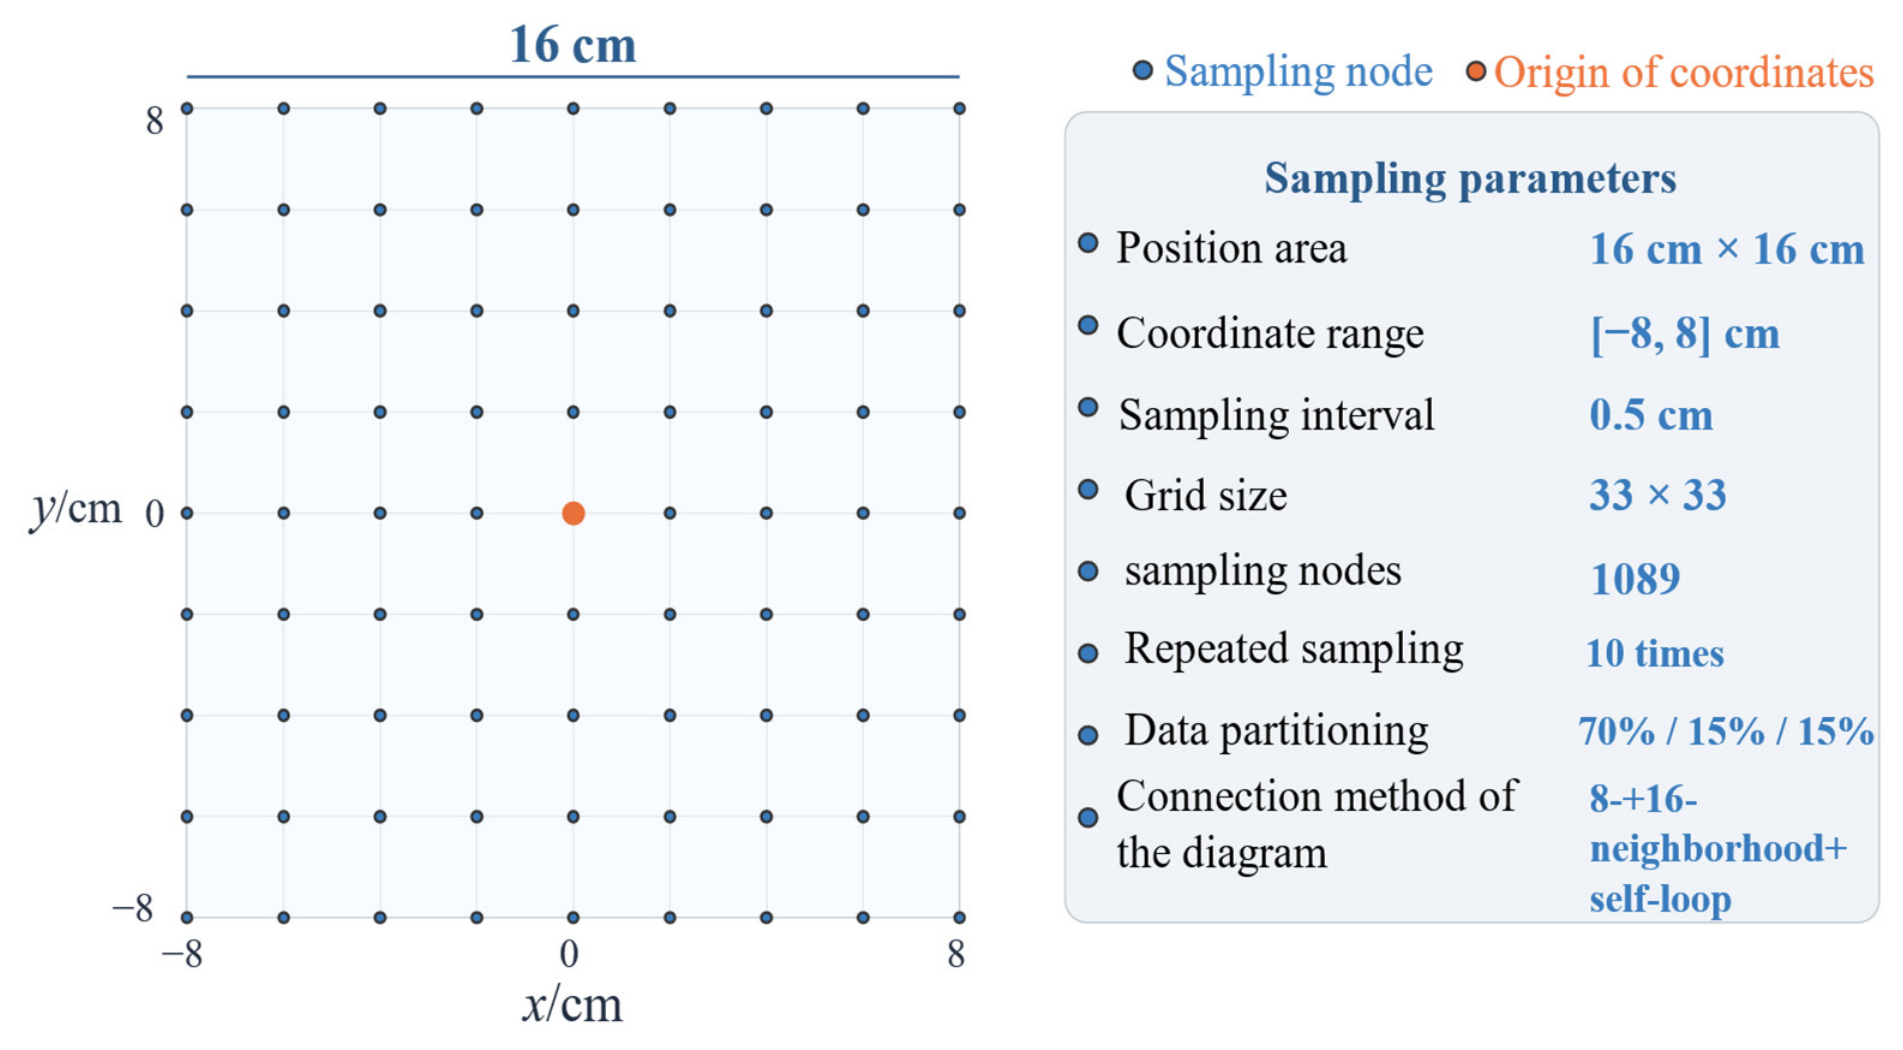
Static grid sampling is performed within the predefined position area, as shown in
Figure 5. The positioning area measures 16 cm × 16 cm, with a coordinate range of [−8, 8] cm and a sampling interval of 0.5 cm, resulting in a 33 × 33 grid size comprising 1089 sampling nodes. At each of the 1089 grid points, ten consecutive measurements were collected under the same excitation condition, and their mean was used as the fingerprint feature to reduce random measurement noise, analog-to-digital converter (ADC) fluctuation, and short-term excitation jitter. The dataset was randomly divided into 762 training nodes, 163 validation nodes, and 164 test nodes.
The static fingerprint database serves as the calibration of the complete physical charging platform rather than as a universal voltage lookup table. In addition to lateral position, the measured fingerprints inherently include the systematic effects of the actual coil parameters, nominal air gap, installation geometry, excitation circuit, signal-conditioning channels, and sensor gains of the prototype. The same platform configuration and signal-acquisition chain are used during online localization, ensuring consistency between calibration and inference. For another charging platform or a substantially modified hardware configuration, the same grid-sampling procedure can be used to establish a new fingerprint database, after which the proposed graph-learning and distillation framework is applied without changing its overall methodology.
Let the induced voltages output by the four detection coils at the
i-th sampling point be
,
,
and
, respectively. Then, the feature vector at this point is expressed as:
Its true coordinate label is denoted by
, then the entire dataset can be represented as:
Taking into account the local continuity of the induced voltage distribution in adjacent spatial regions, the sampling points are further organized into a graph-structured sample set:
where
V represents the set of nodes, corresponding to each sampling point;
E refers to the set of edges;
is the node feature matrix, where each row consists of four channels of induced voltages; and
is the node coordinate label matrix.
Inspired by grid-neighborhood graph construction for spatial graph learning [
23], this study first establishes single-scale 8-neighborhood connections at a distance of one grid step and further introduces a multi-scale graph structure by adding 16-neighborhood connections at a distance of two grid steps and self-loops for each node, thereby enabling the model to simultaneously capture both local details and broader spatial trends during message propagation. Let the planar coordinates of nodes
i and
j be
and
, respectively. The edge weights are then modeled using a Gaussian decay function based on Euclidean distance:
where
represents the grid spacing.
To determine an appropriate decay scale,
was swept over {0.5
, 1.0
, 1.5
, 2.0
, 3.0
} while keeping all other settings fixed, and the teacher mean absolute error (MAE) was evaluated on the validation set (
Table 1).
Although the validation MAE continued to decrease as σ increased, σ = 1.5 (i.e., ) was selected to preserve the locality of neighborhood aggregation and avoid making the multi-scale graph close to uniform weighting. This setting is used consistently in the following experiments.
To mitigate the impact of dimension differences in the samples, the Min-Max normalization is performed on the input voltage of each channel. Let the normalized result of the
k-th channel voltage (
) be:
where
and
denote the minimum and maximum values of the
k-th channel voltage in the training set, respectively. This normalization parameter will be deployed on the MCU alongside the student model parameters for online inference.
To address the training instability of lightweight student models during large-scale coordinate regression, normalization is also applied to the coordinate labels. Let the original coordinates be
; the normalized representation is given by:
where
,
. This transformation uniformly maps the target space to the range [0, 1], which contributes to reducing gradient fluctuations during the training of lightweight networks and aligns well with the Sigmoid constraint on the output layer of student model, thereby enhancing convergence stability. The key static-sampling and graph-construction parameters used in the fingerprint database are summarized in
Table 2.
2.5. GAT-Based Teacher Localization Model
Since conventional MLPs struggle to fully utilize the spatial correlation information between nodes within the localization area, a GAT is introduced as the teacher model to extract local topological features from graph structure fingerprints through a neighborhood attention aggregation mechanism.
Let the input features of node
i be
, which, after a linear transformation, are obtained as:
For node
i and its neighboring node
, the attention weight is defined as:
In the equation,
and
are learnable parameters, and
indicates vector concatenation. Given that the graph constructed in this study includes multi-scale edges and Gaussian distance weight
, the edge weight modulation term is incorporated into the attention calculation during actual implementation, so that the contributions of distant neighbors are subject to attenuation constraints prior to attention normalization. The normalized neighborhood weights are expressed as:
Then the aggregate output of node
i is:
where
represents a nonlinear activation function. After propagating through multi-layer graph attention, the node features are fed into a regression head to output coordinate prediction
.
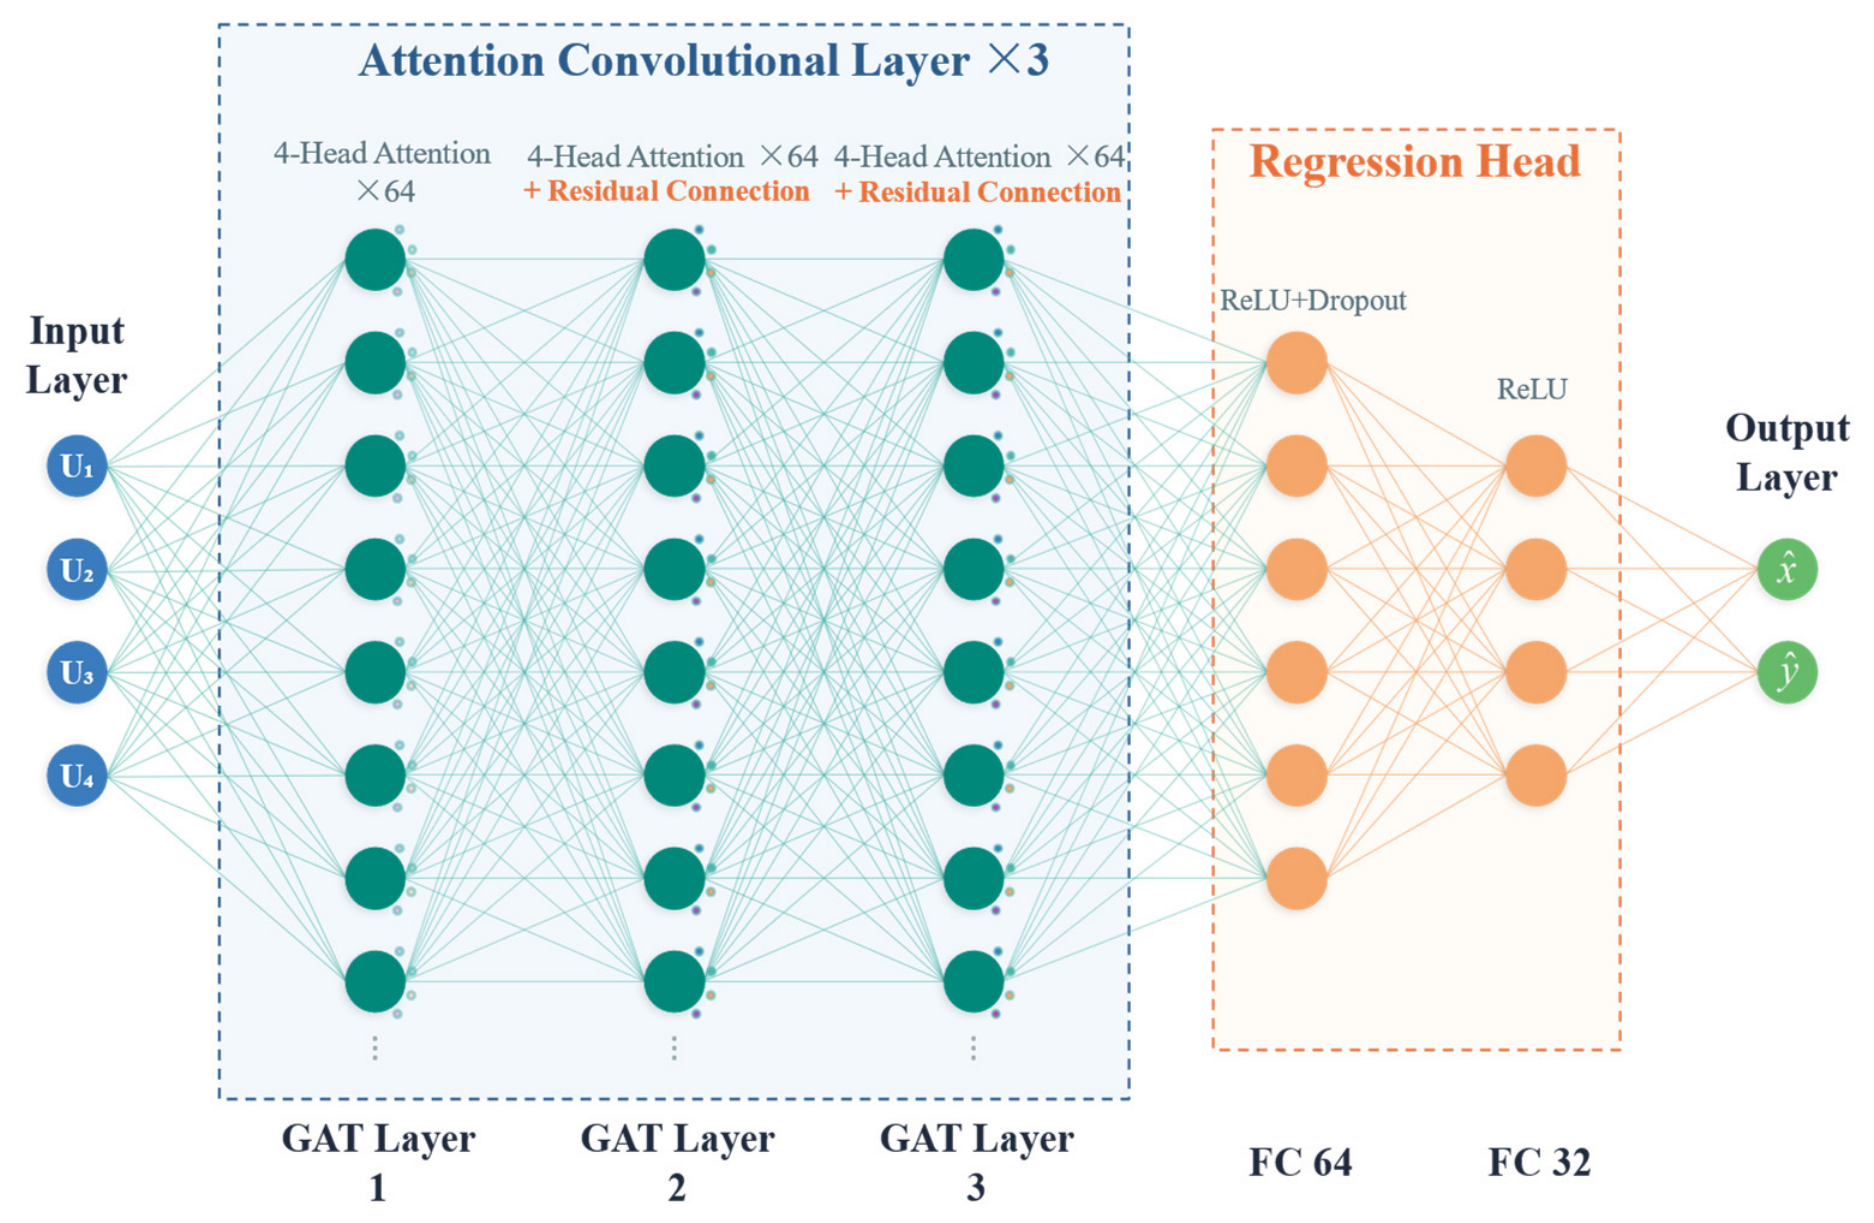
In practice, the teacher model adopts a 3-layer graph attention convolutional structure, with each layer using a 4-head attention mechanism. To improve training stability and feature representation, the following engineering optimizations are introduced:
- (1)
Layer Normalization is applied instead of BN to achieve more stable normalization of node-level features;
- (2)
Residual connections are introduced from the second layer onward to mitigate the gradient vanishing problem in deep graph networks;
- (3)
The rectified linear unit (ReLU) is replaced by exponential linear unit (ELU) activation function to mitigate the dying-ReLU problem;
- (4)
The multi-scale graph edge weights are incorporated into the attention coefficient calculation, allowing information from distant neighbors to be modulated by distance decay during propagation.
Following the graph attention layer, a three-layer fully connected regression head (64→32→2) is used, as shown in
Figure 6, which outputs the final 2D coordinate estimates in combination with Dropout regularization, thereby strengthening the teacher model’s ability to model spatial relationships.
When training the teacher model using a supervised regression objective, considering the possible small number of outlier samples in the position data, this study employs a weighted combination of the mean squared error (MSE) loss and the Huber loss:
where the MSE loss helps strengthen the model’s penalization of large prediction errors, while the Huber loss is more robust to outliers.
The AdamW optimizer is used during training, with weight decay set to , and initial learning rate set to ; and a learning rate scheduling strategy of “Warm-up for the first 30 epochs + follow-up cosine-smoothed decay” is adopted; gradient clipping is applied to prevent gradient explosion, and an early stopping mechanism is implemented; patience is set to 120 epochs, with a maximum training duration of 800 epochs. This training strategy facilitates stable training and superior validation in scenarios with small sample sizes and regular grids.
2.6. Student Model Building and MCU Deployment
2.6.1. Tiny-MLP Student Model and Knowledge Distillation Strategy
To achieve lightweight online localization, the Tiny-MLP student model is built in
Figure 7, which takes 4-dimensional induced voltages as input and outputs 2-dimensional coordinate estimates.
The deployed Tiny-MLP adopts a 4→48→24→2 architecture, with BN layers used after the two hidden layers during training. After BN fusion, the model contains 1466 parameters and retains a standard feedforward inference path.
Considering the instability of lightweight networks in large-scale coordinate regression, the following improvements are introduced to the student model.
First, coordinate normalization combined with a Sigmoid output constraint is applied. In this study, the coordinate labels are normalized within [0, 1] and a Sigmoid activation function is used on the student model output layer, thereby constraining the network output to this range to prevent out-of-bounds predictions. During online inference, the MCU performs de-normalization on the Sigmoid output to restore the actual coordinate values, thus significantly improving the trainability of lightweight networks.
Second, in order to accelerate the training convergence of Tiny-MLP, a BN layer is introduced after each of the two hidden layers. Since BN layers can be folded into adjacent fully connected layers during deployment [
26], BN is used only as a training aid in this study. To avoid storing additional means and variances on the MCU side, the BN parameters are fused into the preceding fully connected layer before deployment. Let the weights and biases of the fully connected layer be W and b, respectively, and the BN parameters be
,
,
,
,
, then the fused weights and biases are:
After fusion, the inference path of the deployed model remains a standard fully connected network, incurring no additional computational or memory overhead.
Subsequently, during the knowledge distillation, let the student model output be
, the teacher model output be
, and the ground truth label be
. This study adopts a joint distillation loss function:
where
λ denotes the distillation weight coefficients. The hard-label weight λ balances supervision from ground-truth labels against the teacher’s soft targets. As shown in
Table 3, a smaller λ yields lower validation error because the student leans more on the teacher’s smoother mapping; however, relying solely on soft targets (λ→0) makes the student fully dependent on the teacher and inherits any teacher bias, reducing robustness to teacher error. A moderate λ = 0.3 was therefore chosen to retain a meaningful contribution from the true labels while still benefiting from distillation.
Furthermore, this study introduces a warm-start initialization strategy: the Tiny-MLP is first trained under direct supervision to acquire preliminary localization capabilities; then its model parameters are used as the initial weights for the distillation student. This prevents the student model from getting stuck in poor local optima when starting from random points, thereby enhancing the stability of the distillation training and the final accuracy.
Other training settings for the student model are as follows: the Adam optimizer (Adaptive Moment Estimation) is used, with the initial learning rate at ; and the learning rate scheduling employs the ReduceLROnPlateau strategy with parameters set to factor = 0.5 and patience = 150.
To evaluate the robustness of the distillation improvement against random initialization, a paired multi-seed experiment was conducted using 20 student-model seeds. For each seed, a Tiny-MLP was first trained under hard-label supervision to obtain a common warm-start checkpoint, which was then duplicated into two branches with identical random states. The direct-continuation branch was further optimized using only the ground-truth labels, whereas the distillation branch was trained using the joint hard- and soft-label loss defined in Equation (15). Both branches used the same data split, initialization, learning rate, training budget, and early-stopping settings, while a fixed pretrained GAT teacher was maintained across all runs. Results are reported as the mean ± standard deviation over the 20 paired runs. The 95% confidence intervals of the paired reductions were estimated using 10,000 bootstrap resamples, and statistical significance was assessed using two-sided paired Wilcoxon signed-rank tests with Holm correction across MAE, RMSE, and P90.
2.6.2. MCU Deployment and Closed-Loop Control
The trained Tiny-MLP parameters, fully connected parameters after BN fusion, and voltage and coordinate normalization parameters are deployed to the MCU, so that the system can independently perform forward inference from 4-dimensional voltage inputs to 2-dimensional coordinate outputs at the edge, without relying on a host computer or complex graph operations. Compared to methods requiring online graph propagation, neighborhood search, or distance matching, the deployed Tiny-MLP involves only a few matrix-vector multiplications and activation operations, with a fixed computation path and stable runtime latency, making it more suitable for online control on general MCU platforms, as shown in
Table 4. For comparison, a smaller 4→32→16→2 configuration is also listed in
Table 4.
To ensure smooth charging, a closed-loop control strategy is introduced. Let the predicted current position be
, and the target center coordinates be
; then, the current alignment error can be expressed as:
At each iteration, the MCU drives the XY platform in the compensation direction of the predicted offset. After the movement is completed, the four induced voltages are sampled again and fed into the Tiny-MLP model to update the position estimate. The closed-loop process is repeated until the residual alignment error is less than the preset threshold of 0.5 cm or the maximum number of iterations is reached. In this study, the maximum number of iterations is set to five. If the residual error remains larger than the threshold after five iterations, the trial is regarded as unsuccessful; otherwise, the system switches from alignment detection mode to wireless charging mode.
2.7. Experimental Platform and Settings
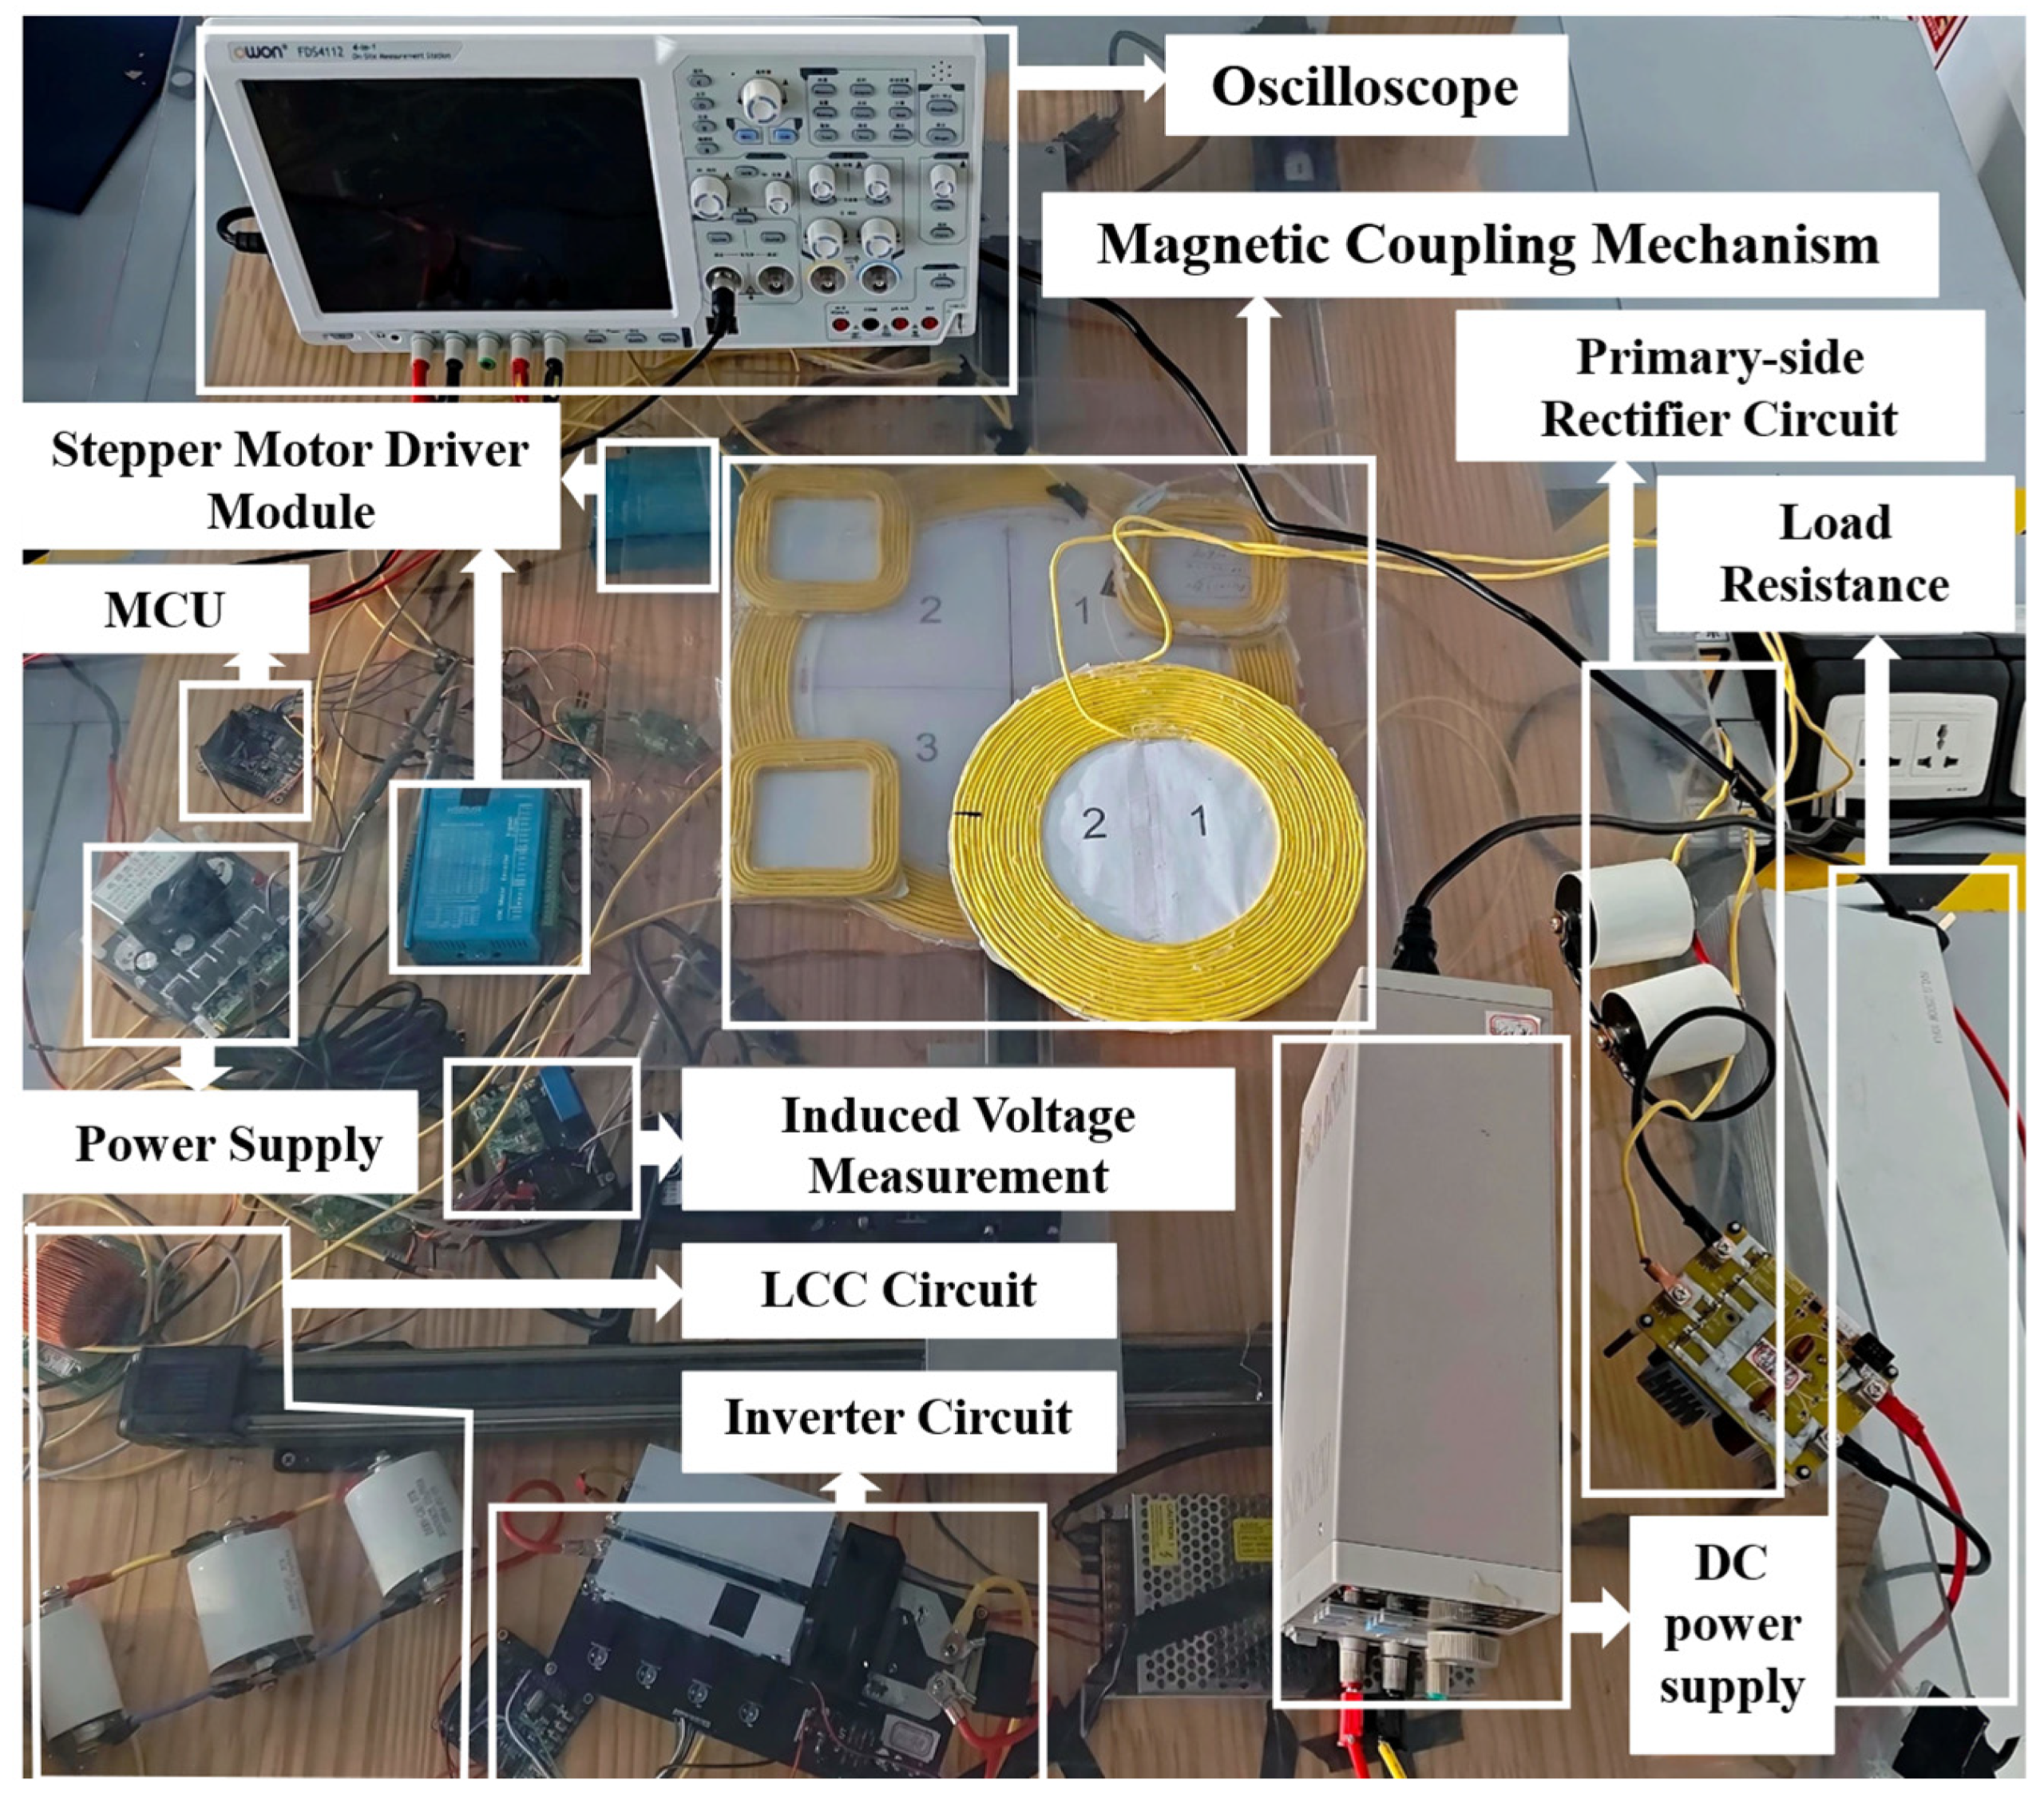
To verify the effectiveness of the proposed method, an alignment experimental platform for UAV wireless charging is constructed as shown in
Figure 8. All settings are consistent with those described earlier, and the system hardware parameters are listed in
Table 5.
In this prototype, the nominal vertical separation between the transmitting and receiving coils was set to 4.8 cm by the landing and mechanical support structure. The same physical configuration was used during fingerprint acquisition, model evaluation, and the 2000 closed-loop alignment trials. The experiments therefore evaluate the complete sensing-inference-compensation process on an actual hardware platform rather than using simulated voltage data or an idealized numerical model.
The deployment-oriented comparison included a MobileNet-style DS-CNN, a Tiny Transformer, ProtoNN, and ResMLP. The selected DS-CNN used 24 stem channels and 36 pointwise-convolution channels. The Tiny Transformer contained two encoder layers with a model dimension of 32, two attention heads, and a feedforward dimension of 64. ProtoNN used a projection dimension of 4 and 32 prototypes. All models used the same data split and normalization procedure, and their configurations were selected according to validation-set MAE before final evaluation on the test set.
3. Results
3.1. Localization Performance Comparison
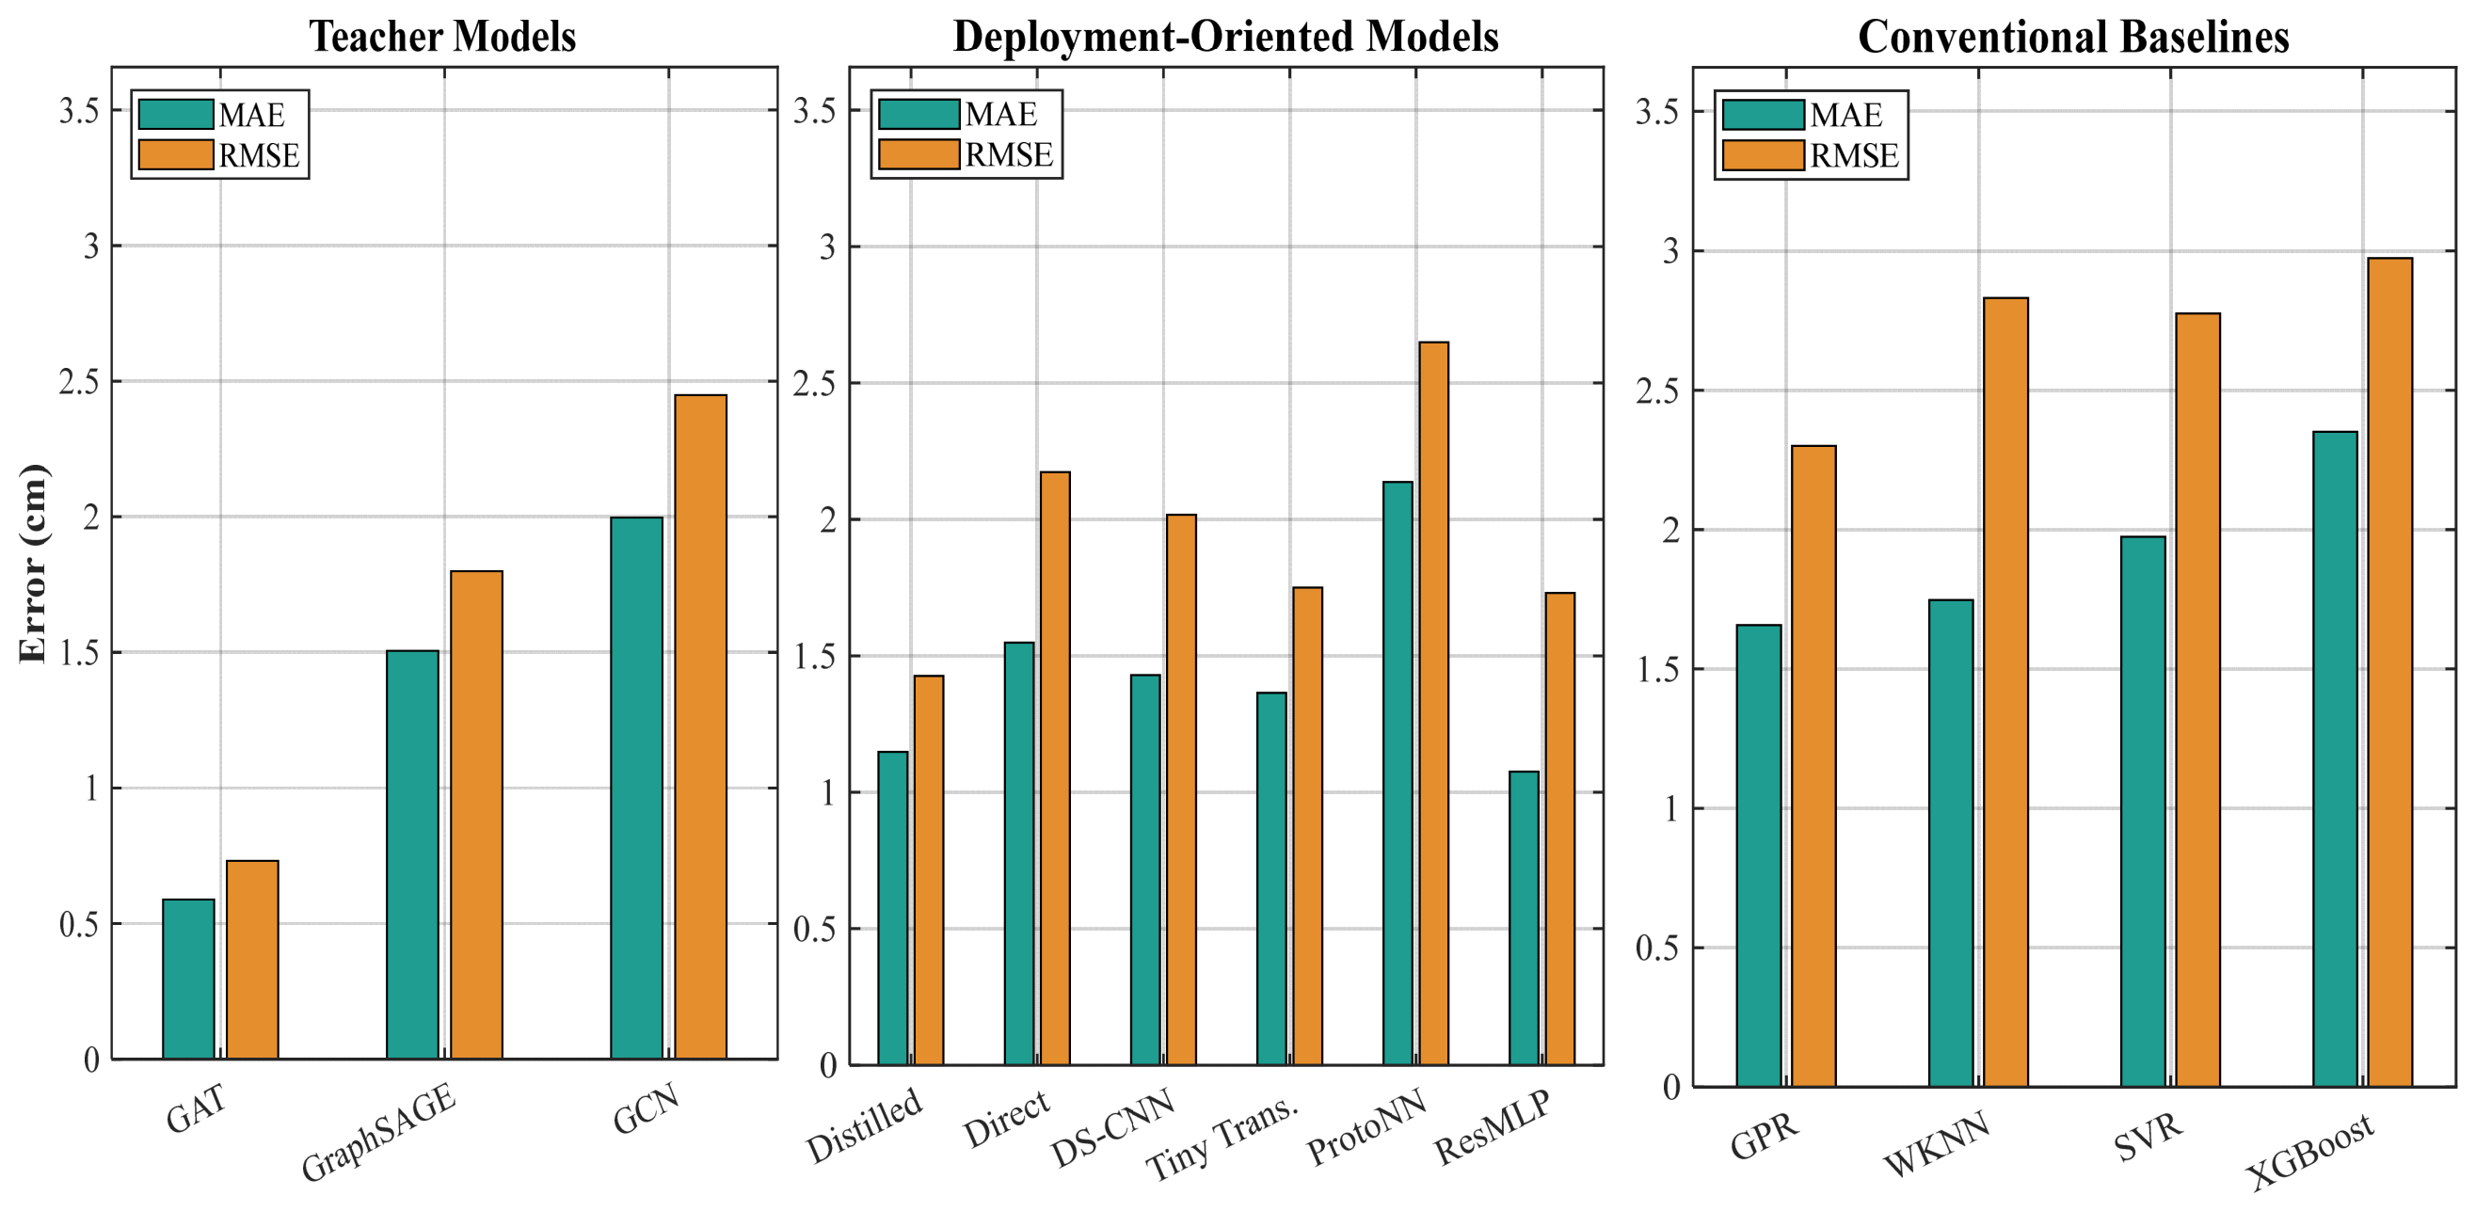
To comprehensively evaluate the proposed method, thirteen models were trained and tested on the same fingerprint dataset using an identical 762/163/164 training, validation, and test split. All localization metrics were calculated on the same 164-node test set. A fixed random seed of 42 was used for the cross-model comparison. According to their roles in the localization framework, the models were divided into three groups: graph-based teacher models, deployment-oriented localization models, and conventional baselines. The teacher group included GAT, GraphSAGE, and GCN. The deployment-oriented group included the directly trained and distilled Tiny-MLP models, MobileNet-style DS-CNN, Tiny Transformer, ProtoNN, and ResMLP. The conventional baseline group consisted of GPR, WKNN, SVR, and XGBoost. The results are summarized in
Table 6 and
Figure 9.
Table 6 shows that GAT achieved the best performance among the teacher candidates, obtaining the lowest MAE, RMSE, maximum error, and P90, and was therefore selected as the teacher model for knowledge distillation.
For the deployment-oriented models, knowledge distillation improved the performance of Tiny-MLP across all evaluation metrics. ResMLP achieved the lowest MAE, whereas the distilled Tiny-MLP obtained the lowest RMSE, maximum error, and P90. The distilled Tiny-MLP also outperformed DS-CNN, Tiny Transformer, ProtoNN, and the directly trained Tiny-MLP, indicating that it provides a favorable balance between localization accuracy and error stability.
Compared with the conventional baselines, including GPR, WKNN, SVR, and XGBoost, the distilled Tiny-MLP consistently achieved lower localization errors. These results demonstrate the effectiveness of combining graph-based spatial learning with a compact student network for embedded localization.
Figure 9 provides a role-based comparison of the evaluated models. Within the teacher group, GAT shows a clear advantage over GraphSAGE and GCN. Within the deployment-oriented group, ResMLP achieves the lowest MAE, whereas the distilled Tiny-MLP achieves the lowest RMSE and substantially lower error than the directly trained Tiny-MLP, DS-CNN, Tiny Transformer, and ProtoNN. The conventional baseline group exhibits generally higher errors, particularly in RMSE, indicating weaker control of large localization deviations.
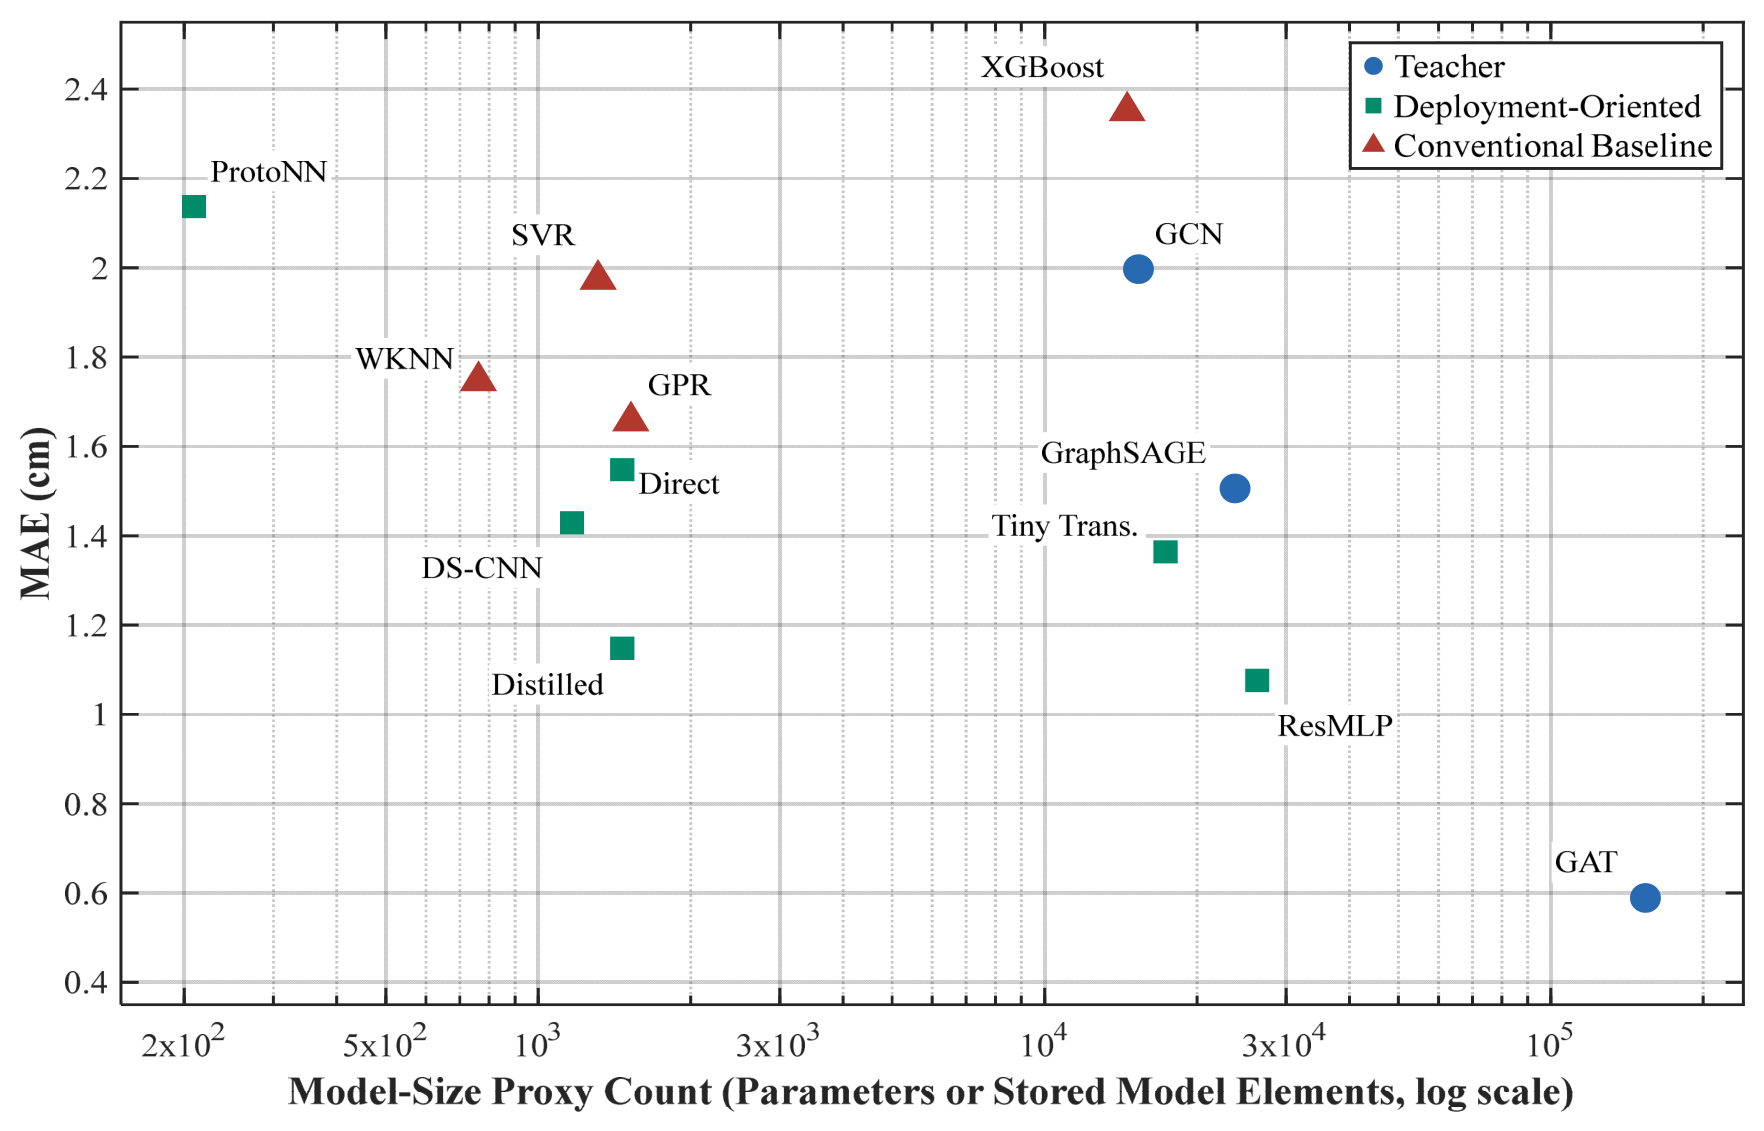
To further evaluate the balance between localization accuracy and implementation complexity,
Figure 10 plots the test MAE against a model-size proxy on a logarithmic scale. Because different model families adopt different representations, the horizontal coordinate denotes the principal stored model elements of each method, including network parameters, stored fingerprints, support vectors, or tree nodes.
As shown in
Figure 10, the GAT teacher achieves the lowest MAE but requires the largest model scale. ResMLP obtains a slightly lower MAE than the distilled Tiny-MLP, but uses substantially more parameters and exhibits higher RMSE, maximum error, and P90. Among the compact deployment-oriented models, the distilled Tiny-MLP achieves lower localization errors than the DS-CNN, Tiny Transformer, ProtoNN, and directly trained Tiny-MLP. For the present four-channel voltage-regression task, transferring the spatial mapping learned by the graph teacher to a compact feedforward network therefore provides a favorable balance between localization accuracy, error stability, and implementation complexity.
3.2. Training Convergence and Statistical Validation
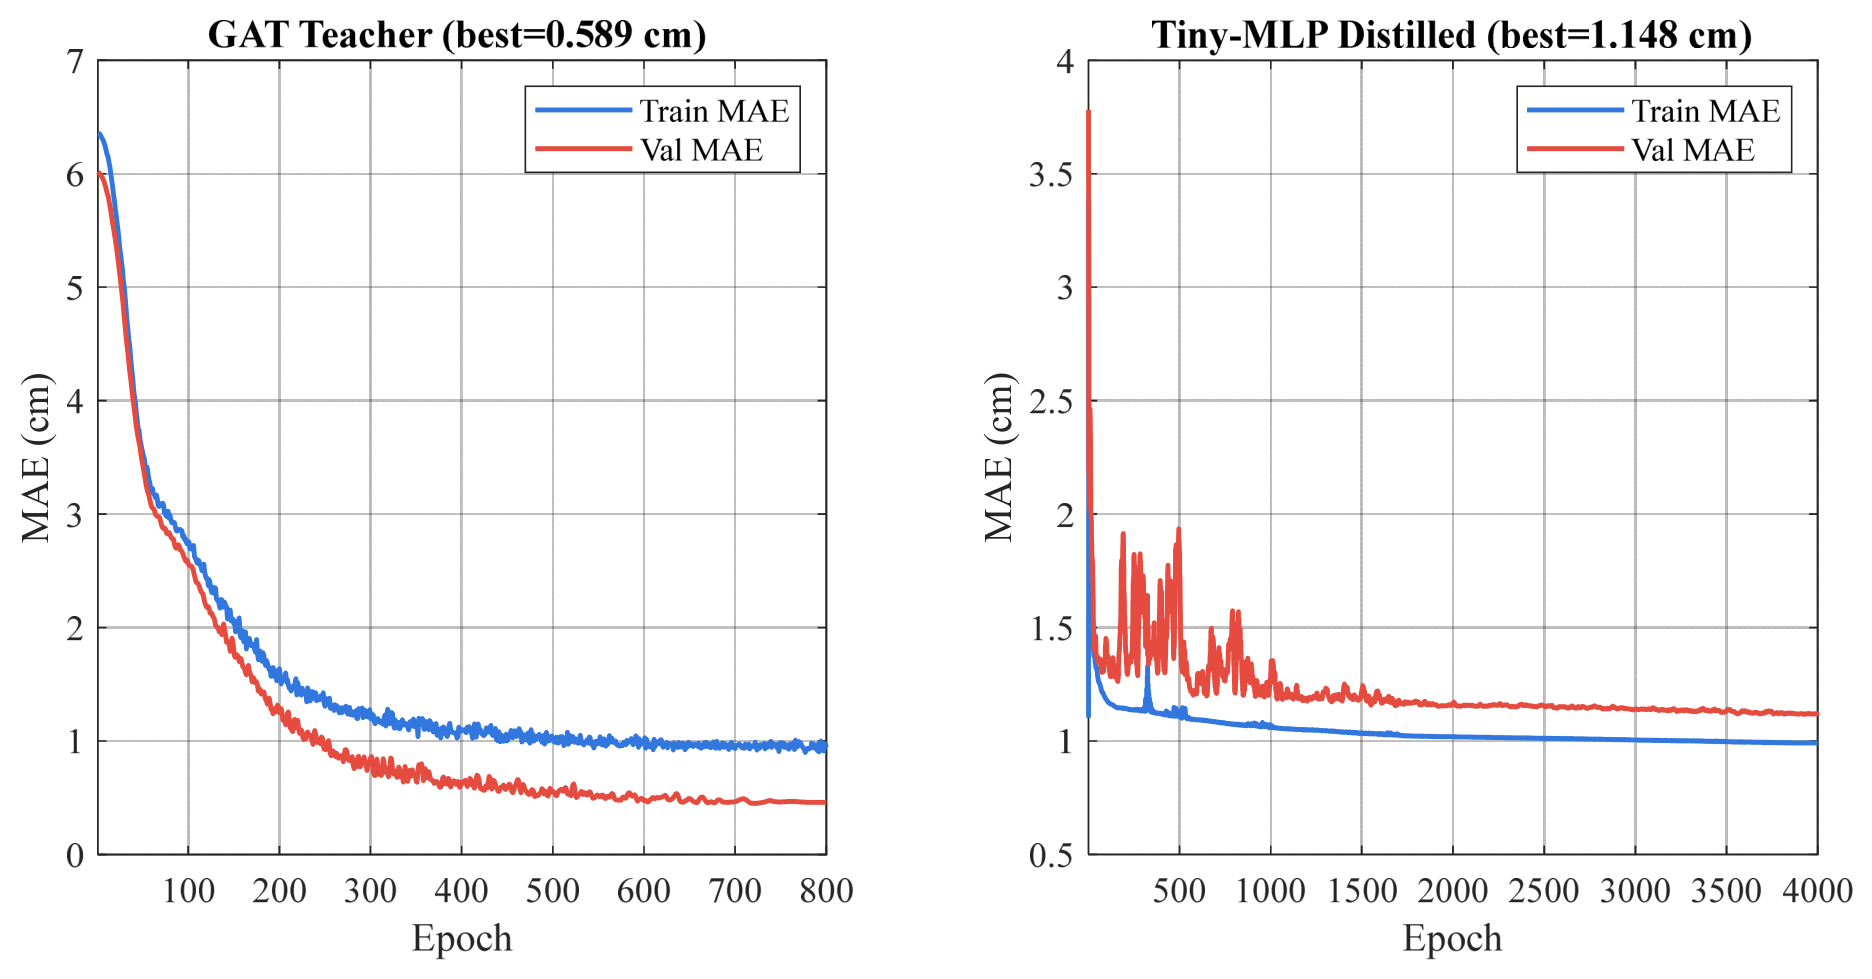
To examine both representative training convergence and the robustness of the knowledge-distillation improvement,
Figure 11 presents the training and validation MAE curves of the GAT teacher and distilled Tiny-MLP.
Table 7 summarizes their fixed-seed test performance together with that of the directly trained Tiny-MLP, while
Table 8 reports the paired multi-seed statistical results.
As shown in
Figure 11, the GAT teacher and distilled Tiny-MLP both exhibit stable convergence, with their validation curves remaining close to the corresponding training curves. The GAT teacher reaches a lower final error because of its stronger graph-based spatial representation, whereas the distilled Tiny-MLP retains a compact feedforward structure suitable for embedded inference. Since representative convergence curves alone cannot determine whether the improvement is robust to random initialization, the direct and distilled student models are further evaluated through the paired multi-seed analysis presented below.
Under the fixed-seed setting, knowledge distillation reduced the Tiny-MLP MAE from 1.548 cm to 1.148 cm. The RMSE, maximum error, and P90 were also reduced from 2.173, 8.973, and 3.424 cm to 1.426, 5.502, and 2.250 cm, respectively. These results correspond to reductions of 25.8% in MAE, 34.4% in RMSE, 38.7% in maximum error, and 34.3% in P90. To determine whether these improvements persist across different student-model initializations, a paired 20-seed evaluation was further conducted, as reported in
Table 8.
Across the 20 paired runs, knowledge distillation reduced the mean MAE from 1.531 cm to 1.142 cm, corresponding to a paired reduction of 0.389 cm (95% CI: 0.349–0.433 cm) and a mean relative reduction of 25.18%. Consistent reductions were also observed in RMSE and P90, and all differences remained statistically significant after Holm correction (p = 5.72 × 10⁻⁶). These results confirm that the improvement is robust across different student-model initializations.
3.3. Analysis of Test Set Error Distribution and Spatial Positioning Results
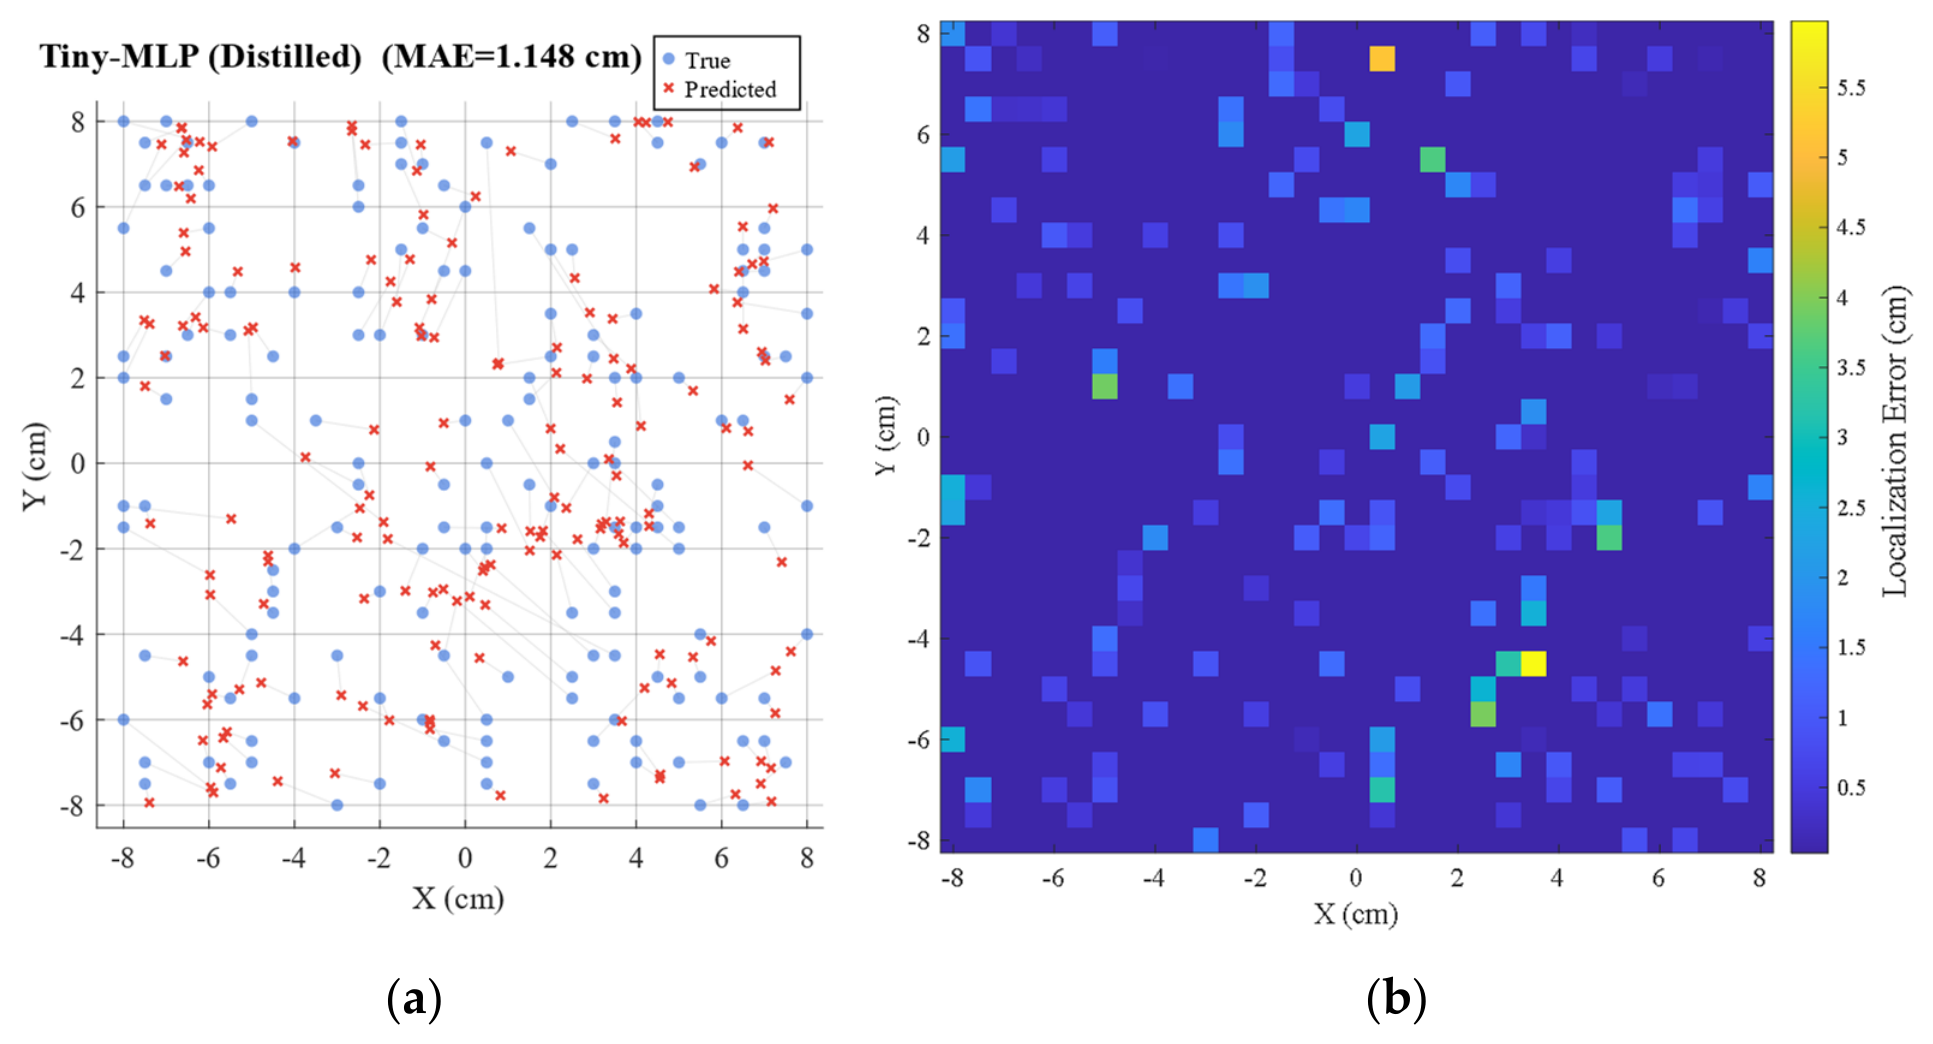
To further analyze the positioning performance on the test set, the predicted-point distribution and the spatial distribution of localization error are examined, as shown in
Figure 12.
As shown in
Figure 12a, the predicted points of the distilled Tiny-MLP follow the ground truth closely across the positioning area, indicating that the proposed optimizations effectively strengthen the student’s spatial representation. The error map in
Figure 12b further shows that the error remains low over most of the area, with only a few isolated hotspots near the boundaries and corners. These hotspots may be associated with reduced fingerprint discrimination in these regions. Overall, the distilled student maintains accurate and spatially consistent localization across the working area.
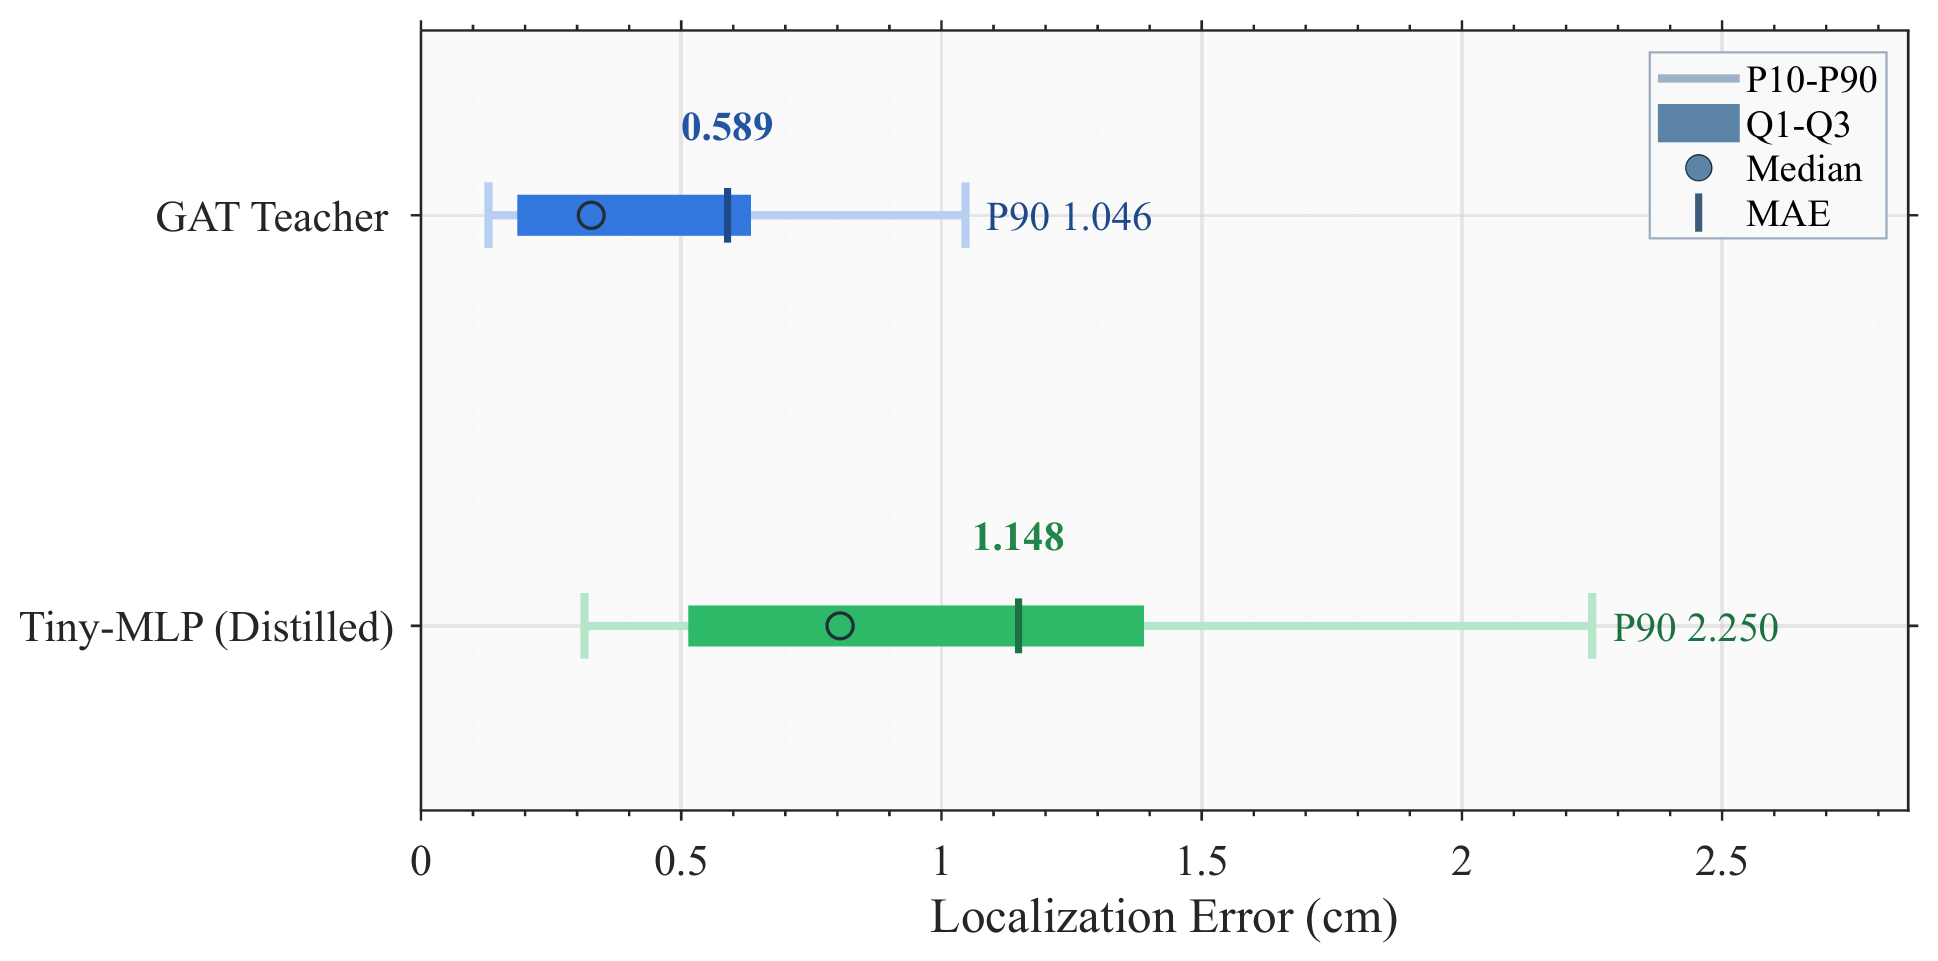
The error distributions of the two key models—the GAT teacher and the distilled Tiny-MLP—are compared in
Figure 13. The distilled student shows a narrow interquartile box with a low median error, and although its distribution sits slightly higher than the teacher’s, both its central tendency and upper tail (P90 = 2.250 cm) remain tightly bounded, indicating well-suppressed large errors and stable output. The teacher exhibits an even tighter distribution (P90 = 1.046 cm), consistent with its role as the higher-accuracy teacher reference that the lightweight student approaches.
3.4. Ablation Study
To assess the contribution of each design component, an ablation study was conducted by removing one component at a time from the full model while keeping all other settings fixed. The graph-structure component (16-neighborhood connectivity) was evaluated on the GAT teacher, and the training components (warm-start, Sigmoid output constraint, and BN-assisted training) on the distilled Tiny-MLP. All variants were evaluated on the same 164-node test set, as summarized in
Table 9.
For the teacher, removing the 16-neighborhood connections and retaining only the 8-neighborhood graph raises the MAE from 0.589 cm to 0.768 cm, confirming that the multi-scale structure provides useful regional context beyond immediate neighbors.
For the student, removing warm-start or BN-assisted training increases both MAE and the tail error (P90), indicating that these components improve convergence and suppress large deviations. Removing the Sigmoid constraint slightly increases the mean error and markedly increases the P90 error (from 2.250 cm to 2.364 cm); since the Sigmoid also bounds the output to a valid coordinate range and prevents out-of-range predictions, it is retained for its stability and tail-error benefits. Overall, each component contributes positively to either accuracy or robustness, supporting the proposed design.
3.5. Analysis of Closed-Loop Alignment Experiment Results
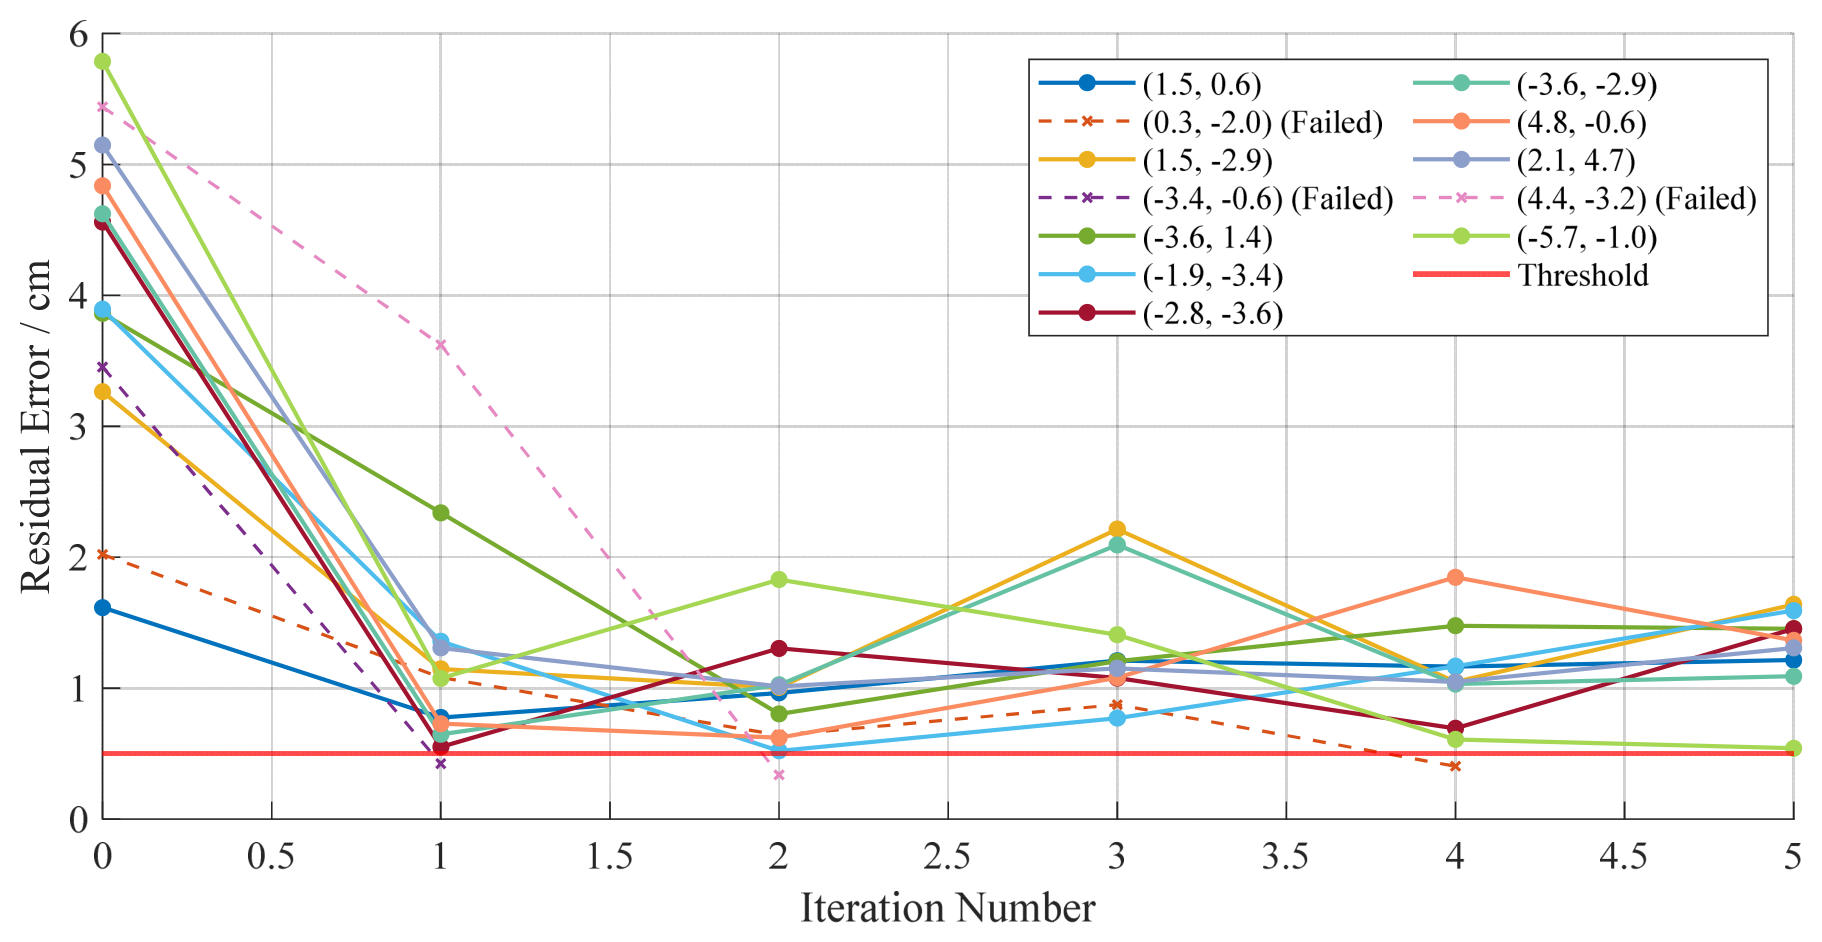
To verify the practical performance of the distilled Tiny-MLP in closed-loop alignment, an iterative “sampling—inference—compensation” process was established based on the two-dimensional offset predicted by the model, with the alignment threshold set to 0.5 cm and a maximum of five iterations per trial.
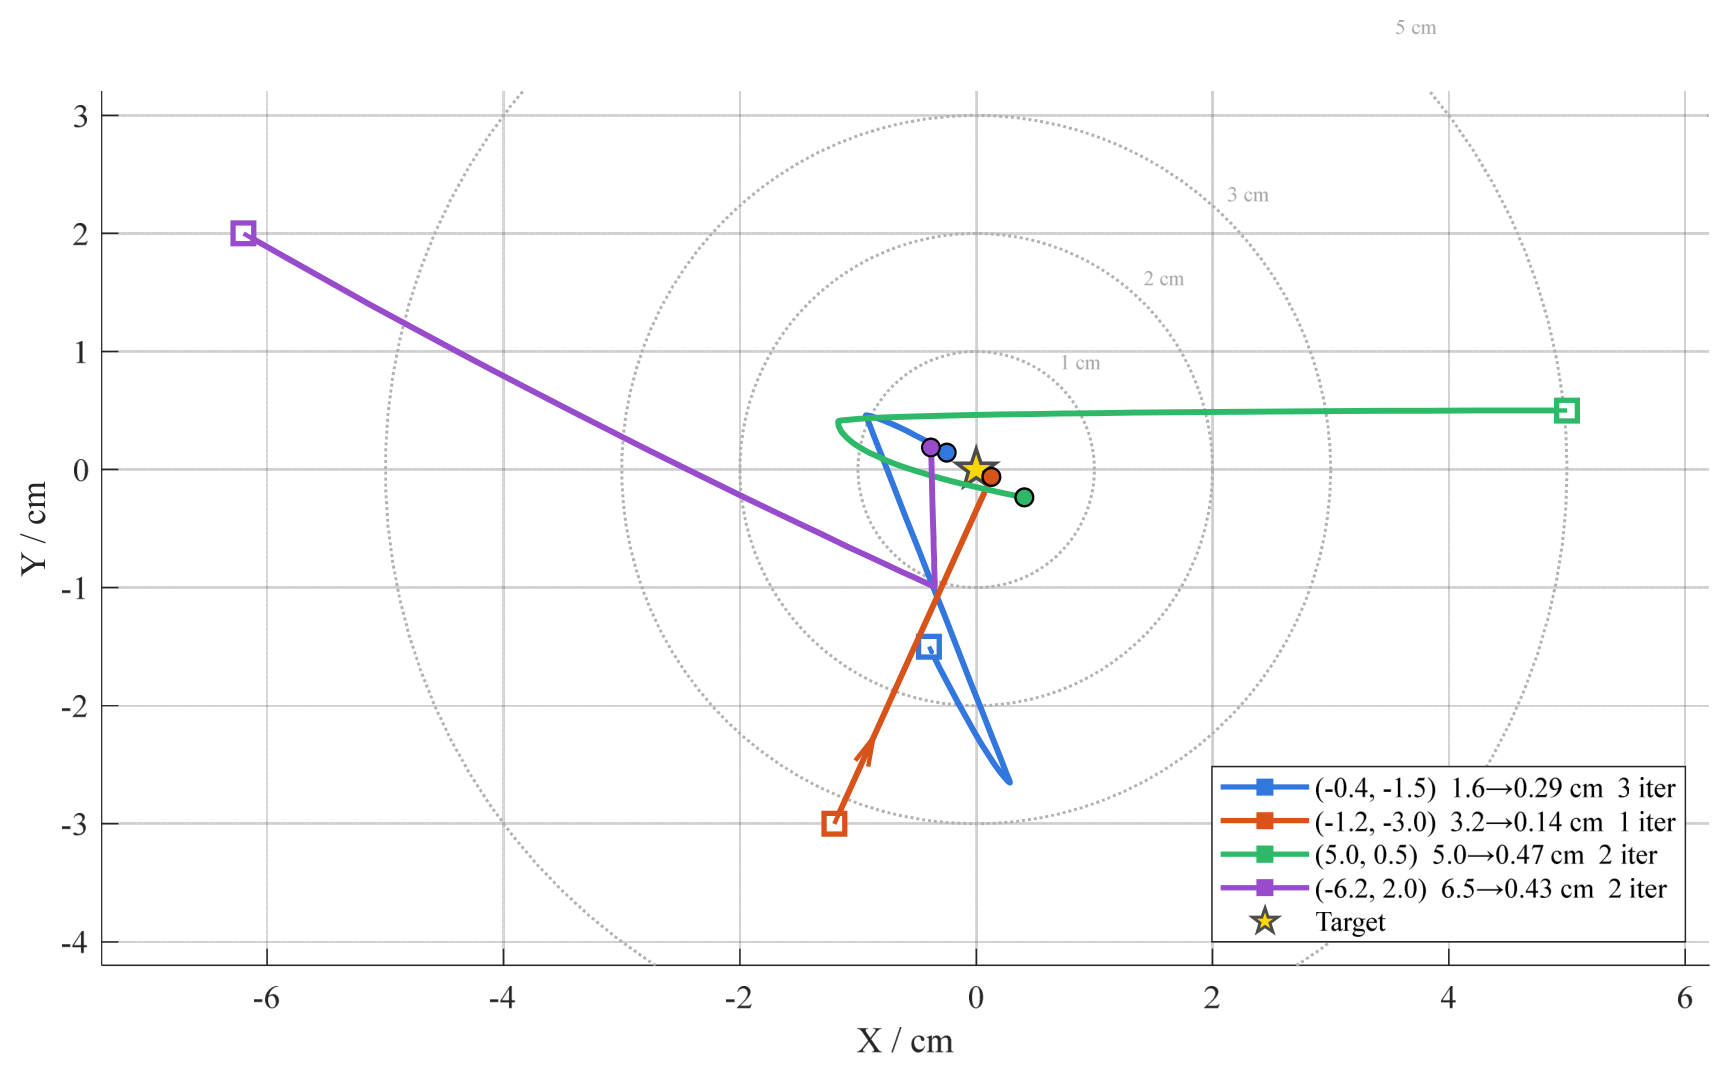
To statistically evaluate the overall alignment performance, 2000 closed-loop trials were conducted with randomly distributed initial positions across the positioning area. Under the 0.5 cm threshold, the system achieved an overall success rate of 85.5%, indicating that the proposed closed-loop strategy is effective over a wide range of random initial offsets. From these trials, a representative subset was further examined to analyze the convergence behavior in more detail, and 12 typical cases covering different initial-error ranges were selected for case-by-case illustration, as listed in
Table 10.
Among these 12 representative cases, 9 converged within the threshold; the successful ones required 2.9 iterations, reached a final error of 0.408 cm, and completed alignment in 0.42 s on average, showing that the deployed lightweight model can achieve effective correction within a small number of iterations. For the three cases that did not meet the 0.5 cm criterion within five iterations, the residual errors (0.738 cm, 0.890 cm, and 0.668 cm) were nonetheless substantially reduced from their initial offsets. These selected cases are intended to illustrate the per-trial convergence process rather than to re-estimate the overall success rate, which is given by the 2000-trial statistic above.
Figure 14 shows that, for the illustrated successful cases, the platform progressively approaches the target along the model-predicted compensation direction. This demonstrates that the distilled Tiny-MLP can provide effective directional and displacement information for closed-loop correction.
Figure 15 shows the curves of residual error versus the iteration number for 12 sets of samples, in which the error curves for successful samples mostly cross the 0.5 cm threshold line within a small number of iterations, while those for failed samples, although showing a downward trend, still fail to fall below the threshold within the maximum number of iterations. This indicates that the adopted closed-loop compensation method exhibits generally convergent behavior under the tested conditions. However, the accumulation of model prediction errors may still affect the final closed-loop accuracy for some samples with large offsets or in locally complex areas.
4. Discussion
The experimental validation targets a representative fixed UAV wireless-charging platform. Localization begins after the UAV is mechanically supported, so the nominal air gap and coil attitude are established before lateral alignment. The proposed method therefore estimates the residual lateral offset rather than the full pose of an unconstrained UAV during descent.
The induced-voltage mapping is platform-dependent and is calibrated through the static fingerprint database, which captures the electromagnetic and sensing characteristics of the assembled device. The trained model is therefore specific to a given hardware configuration, whereas the localization framework can be transferred to another platform by reconstructing its fingerprint database.
The experiments validate the complete sensing, localization, and closed-loop compensation process on physical hardware. Operation before stable mechanical support or under severe external disturbances remains outside the scope of the present study and will be investigated in future work.