


Abstract
This paper presents the Data Quality Assurance Model (DQAM), a formal model and multilayered architecture designed to guarantee data integrity and robustness in Reliable and Quality-Assured Information Systems. Recognising that inaccurate or corrupted sensor data can lead to system collapses and false alarms in critical services, the DQAM provides a standardised and systematic flow of actions to ensure data excellence for Artificial Intelligence (AI). The architecture is structured into three specialised layers (Acquisition, Processing, and AI Adequacy), implementing formal transformation functions that act as a rigorous filter against data degradation. A core contribution is the mapping of these functions to ISO/IEC 25012 and 5259-2 standards, providing a practical framework for reliable information management. It should be noted that quality dimensions regarding timeliness and data volume are outside the scope of this work, as they depend on external data issuers and end-service requirements. The model’s viability is validated through a real-world implementation on a university campus managing millions of data points, demonstrating its capability to optimise performance—achieving a speedup of up to 43%—and prevent service malfunctions. This work bridges the gap between raw IoT streams, and the high-integrity standards required by modern AI-driven applications.
1. Introduction
Currently, IoT environments generate large amounts of heterogeneous data that require extensive processing to produce high-quality datasets [1]. The quality of this data is essential, especially when using Artificial Intelligence (AI) technologies, where it is necessary to ensure that the data is error-free, complete and in the appropriate format for use [2,3]. Just as it is necessary to apply effective solutions for building software systems, it is necessary to create efficient systems for quality data adequacy [4].
The main problem arising from this need is the lack of standardised, flexible, scalable, efficient and adaptable solutions to ensure the quality of data from IoT devices and their transformation for use in AI environments. Existing approaches often result in repetitive processing tasks, a lack of control over data validity, and the need to update and modify processes when adapting data for different services, including those that use AI. An example of this type of approach is through ETL tools, which do not fully ensure data quality. ETLs are not geared towards objectives related to data excellence and error mitigation, but rather towards high productivity, loading speed, data type validation or some limited aspect of data quality. Quality assurance is a phase that must occur before the data reaches the persistence layer, ensuring proactive filtering before the data can be used for end services.
In previous work, we addressed this challenge from the perspective of anomaly detection in IoT data streams [5], demonstrating the importance of ensuring data quality in these environments. However, that approach treated quality issues as deviations from externally observable patterns, revealing the need for a complementary perspective that addresses data quality from within the data itself, systematising the transformations applied throughout its processing flow.
To solve this problem, a multi-layer model, divided into functions, is proposed to process and adapt data generated by IoT environments to meet the quality requirements of AI technologies and their use across different services. This model consists of three main layers: Acquisition Layer (AL); processing layer (PL); and AI Adequacy Layer (AIAL). Each layer is composed of functions that are executed sequentially, transforming the data as it progresses through the layers.
As a result, we have obtained a homogeneous data processing software solution that can be used with any IoT data source. This solution has been implemented on the University of Alicante campus. Without this solution, each tool and service that uses IoT data required its own data adequacy processes. With the new model and its implementation at the university, a single, flexible, configurable, adaptable, scalable and efficient data processing system is applied. A campus was chosen as the test environment because its size is similar to that of a small city, with respect to users, buildings, and sensor types. The university has various detection devices, ranging from devices that measure parameters within the campus, such as temperature, humidity, and capacity, to outdoor devices that collect data on the university’s lighting system, electric car charging, and even meteorological measurements.
The main contribution of this work is the standardisation and systematisation of the flow of actions to ensure data quality and its transformation for AI environments through a multi-layer system. This standardised approach facilitates the generation of valid, high-quality datasets while complying with ISO/IEC standards and enabling the simultaneous execution of operations for greater efficiency.
The rest of the article is organised into the following sections. Section 2 presents a review of the main works on data quality that are similar to our proposal. Section 3 presents the design of the proposed solution, including the definitions of all operations and the formal model. Section 4 describes the design of the conceptual software architecture that enables the implementation of the proposed model. Section 5 sets out the main benefits that the proposal brings to data quality assurance, including a comparison with the traditional methods reviewed and the limitations they present. Section 6 presents an implementation on a real university campus, where the proposal is validated and the model and architecture are demonstrated to be valid. Finally, Section 7 draws the main conclusions of the article together with proposals for future work.
2. State of the Art
The Internet of Things (IoT) has undergone a significant transformation in the last decade, evolving from an emerging concept to a ubiquitous technological infrastructure [6]. This network of devices connects everyday items such as vehicles and household appliances, as well as natural elements including animals, plants and environmental sensors [7], extending to various aspects such as intelligent business management [8], intelligent agriculture [9], intelligent transport [10], intelligent health [11], intelligent homes [12], and environmental safety [13].
Smart devices have become primary producers and consumers of big data, surpassing even humans in the volume of information they generate [14]. This transition presents multidimensional challenges, including software management, system performance, architectural decisions, data quality, and hardware limitations [15].
Currently, data is one of the most valuable assets in the IoT ecosystem, serving as the basis for strategic decisions, service development, and the creation of datasets for training Artificial Intelligence algorithms. The critical importance of these assets has given rise to the concept of “data quality”, defined as the possession of characteristics necessary for its effective use according to specific requirements [16]. It is essential to distinguish between data quality and information quality: data is defined as objective values about the physical world, while information contextualises data in systems that are understandable to users [17].
The scientific community has established taxonomies to categorise quality dimensions, with a six-dimensional approach being fundamental: accuracy (true reflection of the real situation), completeness (complete provision without loss), usability (frequency and relevance of access), concordance (consistency between sources), timeliness (capture at desired times), and data volume (quantity transmitted between sources and consumers) [18]. Within the concept of quality, the causes of degradation that can affect data must be considered. These causes include technical aspects such as computational constraints and sensor errors, environmental factors such as hostile conditions, and comprehensive issues including security vulnerabilities and privacy preservation techniques.
Today, some efforts are being made to address data quality problems through ad hoc solutions to specific issues. First, semantic validation frameworks use semantic web technologies to create intelligent validation layers. They employ ontologies to model IoT domains and semantic reasoners to validate data flows against consistency rules [19]. Notable implementations include three-layer frameworks that transform raw data into RDF streams using ontologies such as SmartSUM. Although they provide high transparency, they lack the flexibility to adapt to new scenarios without significant manual intervention.
On the other hand, the most widespread paradigm uses machine learning algorithms, treating quality issues as anomalies that deviate from standard patterns [20]. Reinforcement learning, exemplified by RLQN, allows agents to learn optimal decisions for real-time data cleaning [21]. Deep learning models such as ACNN-LSTM combine convolutional networks, LSTM, and attention mechanisms for subtle anomaly detection [22]. However, they operate as “black boxes,” making it difficult to understand the specific reasoning, hindering trust and auditing.
Recently, federated learning has emerged as a leading paradigm for addressing privacy constraints, enabling collaboration across multiple devices without sharing local raw data [23]. Its three-layer architecture uses technologies such as homomorphic encryption and optimised recurrent neural networks. However, it adds opacity as global models are mixtures of thousands of local models.
Finally, the well-known blockchain technology ensures integrity through decentralised and immutable records, which is valuable in environments with multiple parties that do not trust each other. Some logistics frameworks use permissioned blockchains and smart contracts that evaluate data based on dimensions such as accuracy, completeness, and consistency [24]. The fundamental limitation is that it guarantees immutability, but not initial correctness, leading to the development of hybrid systems that combine blockchain with machine learning, but without quality assurance [25].
As can be seen, AI is the main driver of digital transformation, enabling IoT data to be used both for environmental control and algorithm training. This has given rise to the concept of “SE4AI” (Software Engineering for Artificial Intelligence), which seeks to apply software engineering techniques to intelligent systems [26]. Research suggests that established principles for quality software should be applied to AI systems, ensuring requirements such as security, usability and scalability [27].
Organisations such as ISO/IEC JTC 1/SC 42 are developing frameworks for different purposes [28,29]. Specifically, the ISO/IEC 25012 standard [24] establishes a data quality model comprising fifteen characteristics organised into two categories: inherent characteristics (accuracy, completeness, consistency, credibility and timeliness) and system-dependent characteristics (availability, portability and recoverability). More recently, ISO/IEC 5259-2 [30] extends this framework specifically for analytics and machine learning contexts, building on ISO/IEC 25012 and adding characteristics relevant to AI/ML systems. In addition, ISO/IEC 25059 [31] provides a quality model for AI systems as a specific extension of the application to SQuaRE standards. Although the use of standards should be a generalised and widely applied requirement, there is still a significant gap in their practical application to IoT environments, manifested in specific solutions with proprietary APIs, inconsistent metrics and a lack of interoperability.
The literature also reveals a clear trend towards excessive specialisation by domain. Industrial IoT focuses more on accuracy and consistency for predictive maintenance using Lambda architectures [32]. Smart cities prioritise interoperability and situational awareness by implementing specific semantic frameworks. Those aimed at smart healthcare emphasise integrity and security with a direct impact on patient well-being, implementing dual-component architectures [33].
Comparative analysis shows that semantic rule-based systems provide high transparency with readable decisions that allow understanding why data was marked as invalid but lack flexibility for new scenarios. Deep learning models offer high adaptability and detection of novel anomalies, but operate as “black boxes”, hindering trust and auditing. Federated learning adds another layer of opacity. Specialisation results in technological silos with non-interoperable solutions, duplication of effort and barriers to adoption. Although hybrid solutions combining blockchain with ML, federated learning with cryptography, and federated learning with blockchain have emerged, they face limitations: high design complexity, prohibitive computational costs on resource-limited devices, increased attack surface, and the absence of standardised frameworks, resulting in ad hoc solutions.
This problem highlights a critical gap: the absence of comprehensive systematisation of the flow of actions to ensure data quality and transformation for AI environments. Solutions are needed that provide composability to assemble paradigms according to their specific contexts, configurability and extensibility to incorporate new techniques without complete re-engineering, and interoperability through standardised functions, overcoming current limitations of technological fragmentation, lack of standardisation and excessive domain specialisation.
3. Designing the Solution
This work proposes a systematisation of the operations to be carried out in data adequacy and quality assurance. This solution will be able to obtain information from any external, heterogeneous and unstructured data source, and apply a series of transformation functions that guarantee obtaining a complete data set, free of errors, within plausible ranges of values and in a format suitable for its use both for training and the execution of AI technologies. For the correct design of the solution, the requirements that the solution must meet will first be established, and then the formal model will be designed.
3.1. Requirement Specification
The proposed solution must ensure the greatest number of fundamental data quality principles while resulting in a flexible, adaptable system, and we will establish three main requirements.
- Requirement 1: It must ensure the successful transformation of heterogeneous and unstructured IoT data, generating high-quality data sets that meet the criteria of completeness, absence of errors and a format suitable for use in Artificial Intelligence technologies.
- Requirement 2: It must facilitate efficiency and performance optimisation, leading to a quantifiable improvement in system performance and a significant reduction in execution time, especially in environments with a high probability of invalid initial data or in computationally intensive processing operations.
- Requirement 3: Finally, it must ensure flexibility and adaptability in the use of data, allowing the solution to be customised to enable different services to consume data at the processing level most appropriate to their needs (quality RAW data, enriched or transformed for AI), without incurring additional processing or unnecessary dependencies.
These requirements seek to obtain a complete, comprehensive data flow that is faithful to its original source, thereby preventing actions that alter the data’s semantics. For example, actions such as anonymisation or data aggregation cannot be performed during the operational flow. Such actions should be performed after the DQAM and are conditional on the intended use of the final data, as they are functions unrelated to the quality requirements discussed in this paper.
3.2. Formal Definition of the Model
Formally, this Data Quality Assurance Model (DQAM) is defined as follows:
DQAM = <AL, PL, AIAL>
DQAM represents the complete quality assurance system, consisting of three layers: the Acquisition Layer (AL), the Processing Layer (PL), and the AI Adequacy Layer (AIAL).
The multi-layer structure allows for customisation of the processing level. Services can choose to use quality “raw” data generated in the first layer, enriched and contextualised data from the second layer, or data transformed for AI into the third layer. This modular approach provides flexibility and efficiency, allowing each service to use the data that best suits its needs. Each layer encompasses a set of specific functions to meet its layer-level quality objective, so each layer will define a specific quality level. At the same time, it allows each layer to define the characteristics that the resulting data must meet.
First, the Acquisition Layer (AL) is crucial because it ensures the raw materials needed to work with the data are obtained. By having a layer dedicated to data acquisition, regardless of what is done with the data afterwards, the availability of raw data from IoT devices is ensured.
Next, the Processing Layer (PL) focuses on enriching and contextualising the information. It performs more sophisticated operations to transform raw data into useful information. By adding information about the devices and the physical quantities measured, and by correcting errors and transforming values, this subsystem generates enriched, contextualised data ready for use in various services.
Finally, the AI Adequacy Layer (AIAL) is responsible for transforming the information to make it compatible with AI development environments, ensuring that the data is in a format suitable for training and executing AI algorithms.
All data will be subject to the same DQAM. We define data as a record coming from outside, and which may contain several values. Each layer (AL, PL and AIAL) is divided into different functions (Fi), which shall be executed sequentially. Each incoming data shall sequentially traverse all functions forming a layer. Each function (Fi) shall generate a result Data (Di), on which the next function to be performed depends. The value of i defines the operations and their order in each layer. Formally, these elements are defined as:
- W (World): Represents the external source of heterogeneous and unstructured data from which the initial flow is obtained.
- Di (Data): Represents a data record at a specific stage i. Each Di is equal to a list of <key, value> pairs, formally Di = [<key, value>].
- Fi (Function): Represents a specific transformation function that processes data Di. Each Fi is a function that transforms an element Di1 into another element of Di2. In addition, you can use an Internal Configuration (IC) for this transformation, ICi being IC the internal configuration necessary for the function Fi to perform its task. Formally Fi (Di1, ICi) → Di2.
- Di2 can be new data or produce an empty output, called d0, which represents an empty or null output. This occurs when a function detects that the data is not suitable to continue in the flow, activating the early filtering mechanism.
- The value of i is formally defined as i = < op1, op2, … opn >.
This subdivision of each layer into functions is necessary to identify all the operations required by the model. Section 3.3, Section 3.4 and Section 3.5 describe the general objectives of each function, which must be fulfilled in order for the rest of the subsequent tasks to be carried out.
A Fi function will produce d0 when it detects that the received Di is not suitable to continue with the sequence of transformations. It is this feature that ensures that, in DQAM, no unsuitable Di will ever reach the upper-layer services and applications. Another possibility is that Di has already fulfilled the objective of the next function Fi+1 in the workflow. In that case, Di can proceed directly to Fi+2. The operations of each layer are detailed below.
In general, several functions Fi are internal configuration functions that must be maintained and updated by a system administrator. This administrator will be responsible for ensuring that the configuration information is aligned with the latest physical characteristics of the infrastructure. The functions defined in the following sections have been determined based on the quality attributes to be addressed. Each function isolates operations that are similar in nature or that act on data with the same internal structure, as will be seen later in examples 1 to 17.
3.3. Acquisition Layer
Firstly, we have the layer for acquiring RAW data from IoT devices, AL. This layer consists of 4 operations: Read Data (RD), Data Complete (DC), Data Valid (DV), and Decode Data (DD). Formally i = <RD, DC, RV, DD>, so AL is formed by the following functions (Fi):
- FRD: Function that obtains data that has been generated by some source external to the AL system. We define that external source as World (W). Formally FRD (W) → DRD.
- FDC: Function that checks whether the received data is complete, i.e., contains the minimum information necessary to enter the processing sequence. Formally FDC (DRD) → DDC.
- FDV: Function to check whether the data is valid, i.e., contains an internal structure suitable for processing, formally FDV (DDC, ICDV) → DDV.
- FDD: This function transforms DDV into a format suitable for the rest of the layers. Formally defined as FDD (DDV, ICDD) → DDD.
The full formal definition of the AL would be as follows:
AL = <FRD, FDC, FDV, FDD, DRD, DDC, DDV, ICDV, DDD, ICDV>
3.4. Processing Layer
The PL is where the information shall be enriched, performing more sophisticated operations with respect to the previous layer. This layer comprises six operations: Enrich Device Information (EDI), Enrich Sensorisation Information (ESI), Error Correction (EC), Transform Values (TV), Replace Values (RV), and Create Sensorisation Package (CSP). Formally i = <EDI, ESI, EC, TV, RV, CSP>, so PL consists of the following functions (Fi):
- 5.
- FEDI: This function enriches the received data DDD by adding information about the physical device, ICEDI, from which W was originally obtained. Formally FEDI (DDD, ICEDI) → DEDI.
- 6.
- FESI: This function enriches the received data DEDI by adding information about the physical quantities it contains, ICESI. Formally FESI (DEDI, ICESI) → DESI.
- 7.
- FEC: This function performs specific error corrections on the data DESI, where error is understood as an inappropriate value and will depend on the magnitude. Formally FEC (DESI) → DEC.
- 8.
- FTV: Function to transform data values. Formally FTV (DEC) → DTV.
- 9.
- FRV: This function enriches the data received in DTV, replacing original values with values of the data’s own magnitudes. Formally FRV (DTV) → DRV.
- 10.
- FCSP: Function to create the appropriate data package before transforming it for use with AI technologies. Formally, FCSP (DRV) → DCSP.
The full formal definition of the PL would be as follows:
PL = <FEDI, FESI, FEC, FTV, FRV, FCSP, DEDI, DESI, DEC, DTV, DRV, DCSP, ICEDI, ICESI>
3.5. AI Adequacy Layer
The AIAL layer will be responsible for transforming the information obtained in the previous layer to make it compatible for use in AI development environments, performing operations more specific to this area than the previous layer. This layer is made up of eight operations: Array Transformation (AT), Renaming Variables (RNV), Transformation of Categorical Values (TCV), Selection of Characteristics (SC), Data Cleansing (DCL), Processing of Nulls (PN), Scaling and Standardisation (SS), and Publish (P). Formally i = <AT, RNV, TCV, SC, DCL, PN, SS, P>, so AIAL consists of the following functions (Fi):
- 11.
- FAT: This function is used to transform the numerical matrix structures of the data into a free format of this structure. Formally, FAT (DCSP) → DAT.
- 12.
- FRNV: Function to avoid having values with the same key in the data. Formally FRNV (DAT) → DRNV.
- 13.
- FTCV: Function to transform non-numeric data values to numeric. Formally FTCV (DRNV) → DTCV.
- 14.
- FSC: Function to select the final values to be used for the data. Formally FSC (DTCV) → DSC.
- 15.
- FDCL: Function to cleanse certain data values. Formally FDCL (DSC) → DDCL.
- 16.
- FPN: Function to deal with nulls in the data. Formally FPN (DDCL) → DPN.
- 17.
- FSS: Function to apply normalisation processes to the data. Formally FSS (DPN) → DSS.
- 18.
- FP: Function to store the data in the corresponding persistence system. FP (DSS) → DP.
The full formal definition of AIAL would be as follows:
AIAL = <FAT, FRNV, FTCV, FSC, FDCL, FPN, FSS, FP, DAT, DRNV, DTCV, DSC, DDCL, DPN, DSS, DP>
3.6. Data Quality Assurance Model
The DQAM is a set of layers that depend on each other to generate the final value for each layer. From a formal point of view, the sequence between layers can be defined as follows:
DQAM = AIAL (PL(AL(W)))
AL = FDD (FDV (FDC (FRD (W)))) → DDD
PL = FCSP (FRV (FTV (FEC (FESI (FEDI (AL)))))) → DCSP
AIAL = FP (FSS (FPN (FDCL (FSC (FTCV (FRNV (FAT (PL)))))))) → DP
This formalisation of the entire model is necessary to perform a rigorous mapping between the technical functions (Fi) and the quality dimensions required by international standards such as ISO/IEC 25012 and ISO/IEC 5259-2. Without a formal definition of what each function does and what data (Di) it generates, the correspondence with the standards would be purely subjective. This entire formal framework acts as a practical implementation framework for theoretical quality dimensions.
4. Conceptual Software Architecture
To materialise the previously designed concepts, it is necessary to propose a conceptual architecture that supports future software implementation. For this purpose, a layered architecture is proposed, within which sequential processes are developed. A general scheme of the proposed model is shown in Figure 1.
Figure 1.
Activity flow for data quality treatment differentiated by layers.
The conceptual software architecture proposes structuring the proposed model into three layers: Acquisition Layer, Processing Layer, and AI Adequacy Layer. All of them are divided into different functions, defined in the model, through which each incoming data will pass, until it reaches the end of the process. Each layer is structured as a sequence of interconnected processes, where the output of one process is the input to the next. The output of the last process of one layer becomes the input to the first process of the next layer. Some processes will rely on local configuration data to complete their tasks.
As shown, the model segments workflow operations, dividing large operations into smaller, sequential ones. The following sections describe the specific operations that each function will implement.
4.1. Acquisition Layer
In this layer, RAW data from IoT devices is collected, and initial steps to ensure data adequacy are taken. All messages will undergo the same adequacy process, starting with the following:
- Read Data: This operation reads the incoming RAW data of the message from the originating data source, typically an IoT sensor or IoT data collection platform.
- Data Complete: It will check if the data arrives empty, i.e., without content. If so, it is discarded as it contains no information to process.
- Data Valid: It checks if the data is valid, considering valid all the information necessary for the user, ignoring malformed packets or control messages, if they are not going to have an explicit use.
- Decode Data: The data is decoded by the required method. To determine the type of decoding required, the configuration systems that contain exact information about the transmitting device are consulted.
Acquisition Layer Example
To illustrate the various transformations, the internal configuration files for the relevant functions will be displayed, along with frames extracted from a TTN data hub.
- Read Data: In this example, a RAW data stream is received from the TTN hub, and the output is a manipulable JSON data structure with minimal internal information.
Example 1.
Read Data.
| Read Data |
| // RAW input (hexadecimal bytes from the device) |
| 0 × 17 0 × 41 0 × 00 0 × 64 0 × 0E 0 × 52 // Output (manipulable structure) { “dev_id”: “sensor-001”, “payload”: [0 × 17, 0 × 41, 0 × 00, 0 × 64, 0 × 0E, 0 × 52], “metadata”: { “time”: “2025-01-20T10:30:00Z”, “port”: 1 } } |
- 2.
- Data Complete: Of these three messages received, the first two are discarded as incomplete, and the third is accepted and moves on to the next phase.
Example 2.
Data Complete.
| Data Complete |
| // Discarded (empty message) |
| {} // Discarded (payload without content) { “dev_id”: “sensor-001”, “payload”: [] } // Accepted (contains processable data) { “dev_id”: “sensor-001”, “payload”: [0 × 17, 0 × 41, 0 × 00, 0 × 64, 0 × 0E, 0 × 52] } |
- 3.
- Data Valid: In this example, the first message contains an invalid payload and is discarded; in the second message, all fields contain valid data, and it is accepted for the next phase.
Example 3.
Data Valid.
| Data Valid |
| // Discarded (malformed structure) |
| { “dev_id”: “sensor-001”, “payload”: [0 × FF, 0 × FF] } // Accepted (valid message with sensor data) { “dev_id”: “sensor-001”, “payload”: [0 × 17, 0 × 41, 0 × 00, 0 × 64, 0 × 0E, 0 × 52] “port”: 1 } |
- 4.
- Decode Data: In the received message, the payload is decoded according to the internal configuration, with one value of a magnitude decoded every two bytes.
Example 4.
Decode Data Internal Configuration.
| Internal Configuration |
| { “yokogawa”: {“device_type”: “Yokogawa XS770A”, “decode”: [UINT8, UINT16, FLOAT16, FLOAT16, FLOAT16]}, “sushi”: {“device_type”: “Sushi Sensor Vibration”, “decode”: [UIN8, UINT16, FLOAT16, FLOAT16]} } |
Example 5.
Decode Data.
| Decode Data |
| // Input (payload in bytes) { “dev_id”: “sensor-001”, “payload”: [0 × 17, 0 × 41, 0 × 00, 0 × 64, 0 × 0E, 0 × 52] } // Decoding applied: // Byte 0–1: Temperature // Bytes 2–3: Humidity // Byte 4–5: Battery // Output (decoded and interpreted values) { “dev_id”: “sensor-001”, “temperature”: 23.5, “humidity”: 65, “battery”: 3.7 } |
4.2. Processing Layer
In this layer, further processing of incoming data from IoT devices is performed:
- 5.
- Enrich Device Information: Enriching data involves adding metadata, such as geolocation or sensitive information that the device does not send, among others.
- 6.
- Enrich Sensorisation Information: Again, it is about adding meta-information, but in this case about the sensor itself, for example, specific characteristics of the sensor, type of magnitudes, etc.
- 7.
- Error Correction: This activity performs a correction on the sensorised values if they are found to be incorrect. For example, in poorly calibrated sensors, a scale adjustment can be made.
- 8.
- Transform Values: Complex transformations are performed on the value. These transformations of the original value can generate two distinct sources of information from the same measurement, thereby extending the services that the sensorised information will feed.
- 9.
- Replace Values: This is responsible for replacing values in the data package, which are a priori static, with dynamic sensorised values. This step is very useful when we want to use the sensor’s generated information as meta-data for the data packet.
- 10.
- Create Sensorisation Package: The resulting sensorisation package is created with all generated meta-information formatted as needed and sent to the next layer.
Processing Layer Example
- 5.
- Enrich Device Information: Additional information about the device is added to each message to complete the context of the message.
Example 6.
Enrich Device Information Internal Configuration.
| Internal Configuration |
| { “sensor-001”: {“device”: { “location”: { “lat”: 40.4168, “lon”: −3.7038 }, “building”: “Building A”, “floor”: 2, “room”: “Office 1215” } “sensor-002”: {……} } |
Example 7.
Enrich Device Information.
| Enrich Device Information |
| // Input { “dev_id”: “sensor-001”, “temperature”: 23.5 } // Output (enriched with device data) { “dev_id”: “sensor-001”, “temperature”: 23.5, “device”: { “location”: { “lat”: 40.4168, “lon”: −3.7038 }, “building”: “Building A”, “floor”: 2, “room”: “Office 1215” } } |
- 6.
- Enrich Sensorisation Information: The sensor brand, accuracy, units, and specific sensorisation ranges are added.
Example 8.
Enrich Sensorisation Information Internal Configuration.
| Internal Configuration |
| { “sensor-001”: { “type”: “Yokogawa”, “magnitude”: “temperature”, “unit”: “celsius”, “precision”: 0.5, “range_min”: −40, “range_max”: 80 } “sensor-002”: {……} } |
Example 9.
Enrich Sensorisation Information.
| Enrich Sensorisation Information |
| // Input { “dev_id”: “sensor-001”, “temperature”: 23.5, “device”: {“...”} } // Output (enriched with sensor specifications) { “dev_id”: “sensor-001”, “temperature”: 23.5, “device”: {“...”}, “sensor”: { “type”: “Yokogawa”, “magnitude”: “temperature”, “unit”: “celsius”, “precision”: 0.5, “range_min”: −40, “range_max”: 80 } } |
- 7.
- Error Correction: We apply correction to the RAW value, decreasing the temperature by 2 degrees due to the proximity of an artificial heat source.
Example 10.
Error Correction.
| Error Correction |
| // Input (sensor with known calibration offset) { “dev_id”: “sensor-001”, “temperature”: 25.5, “calibration_offset”: −2.0 } // Output (corrected value) { “dev_id”: “sensor-001”, “temperature”: 23.5, “temperature_raw”: 25.5, “corrected”: true } |
- 8.
- Transform Values: This operation performs complex transformations on the original values, generating additional derived information. For example, the temperature in Celsius is converted to Fahrenheit and Kelvin.
Example 11.
Transform Values.
| Transform Values |
| // Input { “dev_id”: “sensor-001”, “temperature”: 23.5 } // Output (with transformed and derived values) { “dev_id”: “sensor-001”, “temperature_celsius”: 23.5, “temperature_fahrenheit”: 74.3, “temperature_kelvin”: 296.65 } |
- 9.
- Replace Values: We convert sensor data into device meta-information because this contextual data is only known to the device, for example, the battery status.
Example 12.
Replace Values.
| Replace Values |
| // Input (with static value) { “dev_id”: “sensor-001”, “temperature”: 23.5, “battery”: 3.7, “status”: “${BATTERY_STATUS}” } // Output (value replaced by calculated value) { “dev_id”: “sensor-001”, “temperature”: 23.5, “battery”: 3.7, “status”: “OK” } |
- 10.
- Create Sensorisation Package: This operation builds the final sensorisation package, bringing together all the generated information and metadata in a structured, standardised format, ready to be sent to the next processing layer.
Example 13.
Create Sensorisation Package.
| Create Sensorisation Package |
| { “id”: “msg-20250120-103000-001”, “timestamp”: “2025-01-20T10:30:00Z”, “device”: { “id”: “sensor-001”, “location”: {“lat”: 40.4168, “lon”: −3.7038}, “building”: “Building A” }, “measurements”: [ { “magnitude”: “temperature”, “value”: 23.5, “unit”: “celsius” }, { “magnitude”: “humidity”, “value”: 65, “unit”: “per cent” } ] } |
4.3. AI Adequacy Layer
In this layer, the processed data from the previous layers is obtained and will start its adequacy for use in the AI domain:
- 11.
- Array Transformation: The arrays that usually contain IoT data are removed, denormalising the packets and thus making them tractable by algorithms. This generates columnar data on the objects.
- 12.
- Renaming Variables: The processes of denormalisation and data adequacy can generate duplicate labels, so a renaming of labels must be carried out, so that they are unique and identifiable.
- 13.
- Transformation of Categorical Values: Since the algorithms do not support non-numeric values, the transformation of any categorical value to this format is performed.
- 14.
- Selection of Characteristics: A selection of relevant values is made, eliminating those that do not provide useful information, obtaining a minimised dataset.
- 15.
- Data Cleansing: Data cleansing will be carried out, eliminating possible duplicates or inadequate series.
- 16.
- Processing of Nulls: Null values that are often inadequate in training models are dealt with, either by setting suitable values for the algorithms or by discarding the fields.
- 17.
- Scaling and Standardisation: Numerical data is scaled and standardised to avoid unwanted effects on the algorithms, as AI training or real-time execution does not behave properly when the range of values is very irregular.
- 18.
- Publish: Finally, the resulting data is sent to the persistence layer. This persistence layer is seen as a service layer from the device’s point of view, abstracted from the concrete storage technology.
AI Adequacy Layer Example
- 11.
- Array Transformation: This operation removes array or nesting structures. In the example, all fields are structured at the same level, and new labels are created by combining the original labels and the position index in the arrays.
Example 14.
Array Transformation.
| Array Transformation |
| // Input (measurements in array) { “dev_id”: “sensor-001”, “measurements”: [ {“magnitude”: “temperature”, “value”: 23.5}, {“magnitude”: “humidity”, “value”: 65}, {“magnitude”: “battery”, “value”: 3.7} ] } // Output (column format) { “dev_id”: “sensor-001”, “measurements_0_magnitude”: “temperature”, “measurements_0_value”: 23.5, “measurements_1_magnitude”: “humidity”, “measurements_1_value”: 65, “measurements_2_magnitude”: “battery”, “measurements_2_value”: 3.7 } |
- 12.
- Renaming Variables: In the example, labels with generic text are renamed with text that describes their content to make them easier to understand and use. In this case, the “measurements_X” fields are renamed according to their magnitude.
Example 15.
Renaming Variables.
| Renaming Variables |
| // Input (automatically generated labels) { “dev_id”: “sensor-001”, “measurements_0_value”: 23.5, “measurements_1_value”: 65, “measurements_2_value”: 3.7, “device_location_lat”: 40.4168, “device_location_lon”: −3.7038 } // Output (descriptive and unique labels) { “dev_id”: “sensor-001”, “temperature”: 23.5, “humidity”: 65, “battery”: 3.7, “latitude”: 40.4168, “lon”: −3.7038 } |
- 13.
- Transformation of Categorical Values: This operation converts categorical values into numerical representations, which is essential for processing by machine learning algorithms that only operate with numerical data. The example shows two possible encodings of categorical values, converting text to a value or text to an element on a scale.
Example 16.
Transformation of Categorical Values.
| Transformation of Categorical Values |
| // Input (with categorical values) { “dev_id”: “sensor-001”, “temperature”: 23.5, “humidity”: 65, “battery”: 3.7, “quality”: “good”, “location_type”: “indoor” } // Output—Ordinal encoding { “dev_id”: 1, “temperature”: 23.5, “humidity”: 65, “battery”: 3.7, “quality”: 2, “location_type”: 0 } // Alternative output—One-Hot Encoding { “dev_id_sensor001”: 1, “temperature”: 23.5, “humidity”: 65, “battery”: 3.7, “quality_good”: 1, “quality_medium”: 0, “quality_bad”: 0, “location_indoor”: 1, “location_outdoor”: 0 } |
- 14.
- Selection of Characteristics: In the example, only the position, temperature and humidity characteristics are selected, eliminating signal strength and other values that will not be used.
Example 17.
Selection of Characteristics.
| Selection of Characteristics |
| // Input (all sensor characteristics) { “dev_id”: 1, “temperature”: 23.5, “humidity”: 65, “battery”: 3.7, “latitude”: 40.4168, “lon”: −3.7038, “rssi”: −85, “snr”: 7.5, “packet_count”: 12.456, “quality_good”: 1, “quality_medium”: 0, “quality_bad”: 0 } // Output (features relevant for weather prediction) { “temperature”: 23.5, “humidity”: 65, “lat”: 40.4168, “lon”: −3.7038 } |
- 15.
- Data Cleansing: In the example, duplicate packets with the same timestamp and records with values that are anomalous to the series are removed so as not to compromise the quality of the training or the model’s predictions.
Example 18.
Data Cleansing.
| Data Cleansing |
| // Input (uncleaned sensor time series) [ {“ts”: “10:30:00”, “temperature”: 23.5, “humidity”: 65}, {“ts”: “10:30:00”, “temperature”: 23.5, “humidity”: 65}, {“ts”: “10:30:01”, “temperature”: 39.9, “humidity”: −50}, {“ts”: “10:30:02”, “temperature”: 23.6, “humidity”: 64}, {“ts”: “10:30:03”, “temperature”: 23.4, “humidity”: 66} ] // Output (cleaned time series) [ {“ts”: “10:30:00”, “temperature”: 23.5, “humidity”: 65}, {“ts”: “10:30:02”, “temperature”: 23.6, “humidity”: 64}, {“ts”: “10:30:03”, “temperature”: 23.4, “humidity”: 66} ] |
- 16.
- Processing of Nulls: This operation handles null values, which are problematic for most machine learning algorithms. Depending on the defined strategy, replacement values can be inserted, affected fields can be deleted, or special markers can be applied. Example: The first output replaces nulls with the mean of the previous value, and in the second, the feature is deleted.
Example 19.
Processing of Nulls.
| Processing of Nulls |
| // Input (sensor with null readings) { “temperature”: 23.5, “humidity”: null, “battery”: 3.7, “lat”: 40.4168, “lon”: null } // Output—Option A: Insertion by historical average { “temperature”: 23.5, “humidity”: 55.0, “battery”: 3.7, “lat”: 40.4168, “lon”: −3.7038 } // Output—Option B: Removal of fields { “temperature”: 23.5, “battery”: 3.7, “lat”: 40.4168 } |
- 17.
- Scaling and Standardisation: The example shows data standardisation according to the ranges of each characteristic.
Example 20.
Scaling and Standardisation.
| Scaling and Standardisation |
| // Input (sensor values in heterogeneous scales) { “temperature”: 23.5, “humidity”: 65, “battery”: 3.7, “latitude”: 40.4168, “lon”: −3.7038 } // Output—Min-Max Scaling (range 0–1) // temperature: range [−40, 80] // humidity: range [0, 100] // battery: range [2.5, 4.2] // lat: range [36, 44] // lon: range [−10, 5] { “temperature”: 0.529, “humidity”: 0.650, “battery”: 0.706, “latitude”: 0.552, “lon”: 0.420 } |
- 18.
- Publish: This final operation sends the processed data to the persistence layer, in our case, the MySQL database.
Example 21.
Publish.
| Publish |
| { “id”: “ai-msg-20250120-103000-001”, “timestamp”: 1737369000, “features”: { “temperature”: 0.529, “humidity”: 0.650, “battery”: 0.706, “latitude”: 0.552, “lon”: 0.420 } } |
5. Discussion of Benefits to Data Quality and Limitations of the Model
The following section highlights the main and additional benefits of the proposal, as well as the limitations identified.
5.1. Main Benefits
The multi-layer structure allows for customisation of the processing level, enabling the use of high-quality RAW data in the first layer, enriched and contextualised data in the second layer, or data specifically transformed for AI in the third layer. The application or service that needs the data will determine the layer from which it uses the data, ensuring the required level of quality. This systematic approach to the flow of actions ensures compliance with the fundamental principles of data quality previously studied: accuracy (A), integrity (I), usability (U) and consistency (C). There are two other properties, timelines and data volume, that the model does not affect, as these are properties that depend on the data issuer and/or the service that will use the data, which we do not know at these stages of processing. Table 1 summarises the fundamental principles that the data achieves after passing through each layer, and then justifies why each activity contributes to each principle.
Table 1.
Summary of the quality principles by function. “✓” indicates compliance with the principle, “-” indicates non-compliance.
Below is a mapping of the list of operations and their contribution to the corresponding ISO 25012 quality property that they implement.
5.1.1. Accuracy
- Data Valid: By discarding data with incorrect structures, it ensures that the information truly reflects the actual situation, preventing misinterpretations and directly contributing to “error-free” data.
- Error Correction: This operation corrects inappropriate values, ensuring that the data “accurately reflects the situation in the real world”.
- Replace Values: This ensures that the meta-information is dynamic and reflects the current reality, improving the reliability of the data and, therefore, its accuracy.
- Data Cleansing: By removing inconsistencies, duplicates or errors, this activity directly contributes to ensuring that data is “error-free” and, therefore, accurate.
- Processing of Nulls: Improper handling of null values can introduce systematic errors in subsequent analyses, so proper management helps maintain data accuracy by avoiding misinterpretations resulting from poorly processed missing values.
5.1.2. Integrity
- Read Data: Its function is to capture the complete and unaltered data flow from the source, which is a first step in ensuring that IoT devices send all data received.
- Data Complete: This function directly ensures that essential data is not missing, ensuring that the data moving through the system is “complete”.
- Data Valid: Validates structural consistency, ensuring that all necessary information is present and processable.
- Processing of Nulls: By managing null values, this function ensures that there are no “holes” in the data that could compromise its completeness and consistency, also contributing to the integrity of the data set.
- Publish: By ensuring that quality information is stored reliably and completely, it implicitly supports the integrity of the final data set.
5.1.3. Usability
- Decode Data: This activity is critical for usability, as it ensures that data is in the right format for use by subsequent layers and services.
- Enrich Device Information: By providing valuable additional context, this function makes the data more relevant and applicable for various services, improving its usability.
- Enrich Sensorisation Information: This activity improves the understanding and applicability of data by providing key meta-information for its interpretation and use, which is directly needed for usability.
- Transform Values: By adapting and expanding the applicability of data, it enables its use in a wider range of scenarios and services, which directly applies usability.
- Replace Values: This activity also improves usability by making data packages more relevant and dynamic for data consumers.
- Create Sensorisation Package: This function organises and structures data optimally for subsequent consumption, including preparation for AI technologies, ensuring that it is in a format that facilitates its usability.
- Array Transformation: This transformation is crucial for the usability of data in AI environments, as it converts it into a format that is directly processable and efficient for algorithms.
- Renaming Variables: By ensuring that variables are unique and clearly identifiable, it prevents errors and ambiguities in the training and execution of AI models, making the data more suitable for use.
- Transformation of Categorical Values: This adapts the data to the specific input requirements of AI algorithms, making it usable for training and execution.
- Selection of Characteristics: By optimising the dataset for AI models, removing noise and redundant information, it improves the performance and efficiency of algorithms, which translates into greater usability of the data.
- Processing of Nulls: This activity also improves the usability of data for AI algorithms, which often do not handle nulls directly, ensuring that data is in the right format for use.
- Scaling and Standardisation: This prepares numerical data to be optimal for the performance of AI algorithms, contributing to its usability.
- Publish: This activity contributes to usability by ensuring that data, once processed and validated, is available and accessible to consumer services, especially those using AI.
5.1.4. Concordance
- Enrich Device Information: Contributes to concordance by establishing and providing uniform metadata about devices, which is essential for coherently correlating information from different IoT devices and ensuring that devices of a similar nature report data are comparable and consistent with each other.
- Enrich Sensorisation Information: By standardising sensor information, it makes it easier for measurements of the same physical quantity, even if they come from different sensors or devices, to be compared and consistent with each other, a key aspect of concordance.
- Transform Values: By applying standardised transformations, it ensures that data derived from different sources that reflect related effects remain consistent and comparable, which in turn facilitates the identification of patterns and correlations between different sources of information.
- Scaling and Standardisation: By normalising different numerical characteristics to a common and comparable scale, it is ensured that data from different sources, or representing correlated effects, are intrinsically consistent with each other. This is particularly important since, when integrating data from multiple sensors, even if they operate with different measurement ranges, they monitor related events.
5.1.5. Correspondence with ISO/IEC Standards
The four quality principles guaranteed by DQAM are consistent with the inherent characteristics of data quality defined in ISO/IEC 25012 [25]. This international standard establishes a data quality model comprising fifteen characteristics from two perspectives: inherent and system-dependent. The correspondence between DQAM and the characteristics of the ISO/IEC 25012 standard, summarised objectively in Table 2, is as follows:
Table 2.
Comparison between the DQAM and the ISO/IEC 25012 standard.
The following explains how each function contributes to meeting the requirements of the standard:
- The accuracy of DQAM corresponds directly to the “Accuracy” characteristic of ISO/IEC 25012, defined as the degree to which the data correctly represents the actual value of the intended attribute.
- ○
- Data Validation: Discards incorrect structures to ensure that the information reflects the actual situation.
- ○
- Error Correction: Adjusts inappropriate values (such as calibration errors) to reflect physical reality.
- ○
- Replace Values: Ensures that metadata is dynamic and up to date.
- ○
- Data Cleansing: Removes duplicates and serial errors that would contaminate the analysis.
- ○
- Null Processing: Prevents misinterpretations arising from poorly managed missing values.
- ○
- Selection of Characteristics: Minimises the dataset by removing noise and redundant information.
- The integrity of DQAM conforms to the “Completeness” characteristic of ISO/IEC 25012, which refers to the degree to which the subject data has values for all expected attributes.
- ○
- Data Read: Captures the complete, original data stream from the source.
- ○
- Data Completeness: Verifies that messages are not empty and contain the minimum required information.
- ○
- Null Processing: Manages gaps in the data using insertion or deletion strategies to maintain the integrity of the dataset.
- ○
- Publish: Ensures that quality information is stored reliably and completely.
- The usability of DQAM corresponds to the “Understandability” characteristic of ISO/IEC 25012, defined as the degree to which the data can be understood and used by the intended users.
- ○
- Data Decoding: Converts raw bytes into a format that can be interpreted by humans and applications.
- ○
- Enrichment (Device and Sensor Information): Adds context (location, sensor type, units) that makes the data relevant and usable.
- ○
- Value Transformation: Expands the applicability of the data (e.g., converting Celsius to Fahrenheit) for different use cases.
- ○
- Array Transformation: Converts nested structures into columnar formats that are efficient for AI algorithms.
- ○
- Variable Renaming: Eliminates ambiguities through unique and identifiable labels.
- ○
- Scaling and Standardisation: Prepares numerical data for optimal performance of AI models.
- The consistency of DQAM complies with the “Concordance” characteristic of ISO/IEC 25012, which refers to the extent to which data is free of contradictions and consistent with other data.
- ○
- Data Enrichment: Establishes uniform metadata that enables data from different devices to be correlated consistently.
- ○
- Sensor Standardisation: Ensures that measurements of the same physical quantity are comparable with one another, even if they come from different sensors.
- ○
- Scaling and Standardisation: Normalises different numerical scales to a common range, enabling the consistent integration of multiple data sources.
- ○
- Data Cleansing: By removing anomalous or inconsistent records, it enhances the internal consistency of the time series.
In addition, the AIAL addresses data preparation requirements for machine learning, as described in ISO/IEC 5259-2 [30], which extends ISO/IEC 25012 specifically to analytics and machine learning contexts. This correspondence shows that DQAM provides a practical implementation framework for the theoretical quality dimensions established by international standards.
5.2. Comparison with Other Solutions
If we compare DQAM with existing systems, we can see that the proposal presents significant differences compared to the use of semantic validation [2], ML/DL [21], federated learning (FL) [23] or blockchain [10], summarised in Table 3. Among all the features, it is noteworthy that, on the one hand, DQAM addresses several data quality properties, while others focus on security or integrity. Above all, and very importantly, in terms of computational requirements, DQAM focuses on minimising the required resources to ensure a high-quality data flow. This allows it to be implemented in environments with real-time or pseudo-real-time requirements, which is essential in IoT environments with multiple massive data flows.
Table 3.
Summary of the differences between semantic validation (SV), blockchain (BC), ML/DL, federated learning (FL), and DQAM.
5.3. Additional Benefits
Although not the intended objective, another benefit has been improved performance in environments with a high probability of incomplete data or failures. This section illustrates examples of how DQAM can impact systems that process IoT data streams.
The proposed solution is based on a segmented execution pipeline, in which, throughout the process, inappropriate values are discarded, and appropriate values are enriched and transformed to continue the process. This information filtering represents an improvement over the original execution time when the segmented system was not used.
Furthermore, the system allows efficient use of available operations; i.e., it is not necessary to wait for an incoming piece of data to complete the entire sequence of operations before another piece of data can be processed, as all operations run in parallel and may operate on different data in each function.
If we formally define the time improvement this represents, we can distinguish the following elements:
- TF: Time for each function. This time will be adjusted to increase or decrease based on external system factors, such as the types of connections used between sensors.
- TE: Extra time for queries to the stage configuration files, as shown in Figure 1.
The total system will have a maximum execution time to obtain adequate data for each layer:
- TAL: Time to obtain a Processable Data from the Acquisition Layer. This time will include the sum of each TF and TE belonging to its layer.
- TPL: Time to obtain a Useful Data that has been enriched from the Processing Layer. This time will include the sum of each TF and TE belonging to its layer.
- TAIAL: Time to obtain a Data Applicable to Artificial Intelligence from the AI Adequacy Layer. This time will include the sum of each TF belonging to its layer.
Each layer has a time cost, which, in the worst case, equals the sum of the time costs of each function within that layer: TAL, TPL, TAIAL.
Across the three defined times per layer, the performance improvement between a monolithic system and the multi-layer proposal can be calculated using Amdahl’s law [34], dividing the execution time of the system without improvements by the execution time of the multi-layer system, as shown in Equation (1).
where WET indicates execution time for entire task without using the enhancement, and ET indicates execution time for entire task using the enhancement when possible.
Although Amdahl’s law is traditionally used to calculate performance improvements in parallelisation, it is also used in its broader sense of systems engineering to compare the execution time of a complete task without an improvement to the time with that improvement [35].
To help understand the system’s improvement, let us consider an initial data flow FL that arrives at the system at a rate of n data per second.
Suppose that, within this flow, there is a probability Pnp that a piece of data, after passing through the Acquisition Layer, cannot be processed correctly by the subsequent layers of the model. This could be due to errors in data acquisition, incompatible formats, or other conditions that prevent its proper processing. In this case, the data is discarded in the first layer.
When applying the first layer of this filter, unprocessable data flow is identified and discarded, which can be calculated as FLnp = FL × Pnp. The data flow that continues for processing in the subsequent layers is referred to as FL’, where FL’ = FL × (1 − Pnp).
The performance improvement is due to the time saved by avoiding unnecessary processing of invalid data in subsequent layers.
Considering that TPL and TAIAL are the processing times of the PL and AIAL layers, respectively, without the first-layer filter, both processable and non-processable data pass through the monolithic system, consuming time and resources. With the introduction of the filter, the FLnp non-processable data is eliminated before reaching these layers, resulting in a total time saving of FLnp × (TPL + TAIAL) for every n data.
This time saving translates directly into improved system productivity. Productivity can be defined as the amount of useful work performed per unit of time. By avoiding the processing of useless data, the system can focus its resources on processing valid data and increasing overall efficiency.
To clarify the impact on performance, let us consider the following examples:
First, a situation where we have a high data flow but a low probability of unprocessable data arriving, setting the following parameters:
- Initial data flow (FL): 1000 data/s.
- Probability of non-processable data (Pnp): 0.05 (5%).
- Processing time in PL (TPL): 0.01 s/data.
- Processing time in AIAL (TAIAL): 0.02 s/data.
In this case, the unprocessable data flow is FLnp = 1000 × 0.05 = 50 data/s. The time saved for every 1000 data in the flow is 50 × (0.01 + 0.02) = 50 × 0.03 = 1.5 s. This means the system now has an additional 1.5 s per 1000 messages received to devote to other tasks. The reduction in effective execution time for the workload translates into improved performance.
To calculate the improvement, assuming that the monolithic system has a similar time cost to the layered system, following Equation (1), we have:
The system improvement is quantified at 5%.
Secondly, in a situation where we have a low data flow but a high probability of unprocessable data arriving, we set the parameters:
- Initial data flow (FL): 100 data/s.
- Probability of non-processable data (Pnp): 0.3 (30%).
- Processing time in PL (TPL): 0.1 s/data.
- Processing time in AIAL (TAIAL): 0.2 s/data.
Here, the unprocessable data flow is FLnp = 100 × 0.3 = 30 data/s. The time saved for every 100 data items is 30 × (0.1 + 0.2) = 30 × 0.3 = 9 s. Although the initial flow is lower, the high proportion of unprocessable data yields significant time savings (9 s per 100 data items).
Comparing again with a monolithic system, the improvement is calculated as:
The system’s improvement is quantified at 43%.
The effectiveness of filtering in layers is more noticeable when the probability of unprocessable data is high, and the subsequent processing layers are “expensive” in terms of time. Similarly, the saving effect produced by the second PL layer when discarding unprocessable elements can be observed.
To empirically verify the improvement provided by DQAM, the model’s performance was analysed under real-world operating conditions. Over a 12-day period, the total number of messages received by the system and the number of messages discarded for failing to meet quality requirements were recorded during randomly selected time slots. The results, shown in Table 4, indicate that DQAM removes more than 68,000 invalid messages from the execution pipeline during the observed period, resulting in an overall processing speedup of over 18%. Beyond this quantitative improvement in efficiency, the key finding from a quality perspective is that these 68,000 messages would have reached the consumer applications and services in the absence of DQAM, contaminating the data on which these services operate; with the model in production, this filtering is performed once in the data infrastructure, before the incorrect data can propagate.
Table 4.
Number of messages captured for analysis, number of messages discarded, and the improvement achieved by reducing the number of messages in the flow.
5.4. Quantitative Impact on Quality Dimensions
To quantify the impact of DQAM on the quality dimensions (accuracy, integrity, usability, and concordance), a 12-day sample was taken, with a random time slot recorded each day and all messages received by the platform during that interval analysed. For each message, a record was kept of which functions of the DQAM workflow required an effective transformation. As a result of the construction of the formal model, when a function acts on a message, it improves the intrinsic quality of the data along the quality dimensions associated with that function, in accordance with the standards set out in Table 4. For example, the implementation of the ‘Null processing’ function implies a simultaneous improvement in the dimensions of accuracy, integrity and usability.
Table 5 summarises the sampling results measured in messages per hour. For each day monitored, the following are reported: the total number of messages captured in the flow during the observed time slot (FL), the number of messages to which at least one action related to each dimension (A/I/U/C) has been applied, and the percentage of the total messages for the day. The ‘Average’ row summarises the average performance for the period. The results show that DQAM produces an average improvement of 19.30% in accuracy, 6.90% in integrity, 16.27% in usability, and 6.56% in concordance. It should be noted that these percentages represent the intrinsic improvement produced by the DQAM in each dimension on the actual flow data and are obtained as a direct consequence of the formal traceability between model functions and normative dimensions.
Table 5.
Measurement of the number of messages per hour, at random times of the day over a 12-day period. The columns A/I/U/C (n) indicate the number of messages processed by a function affecting that quality dimension. The columns A/I/U/C (%) indicate the percentage of those messages that are processed by a function affecting that quality dimension.
5.5. Model Limitations
The proposed multi-layer conceptual architecture has proven to be highly effective in systematising and customising the flow of actions to ensure data quality and its transformation for AI environments. In addition, it has achieved a significant improvement in system performance and efficiency through its segmented execution flow and early filtering of unprocessable data. However, this solution requires more sophisticated distributed architectures that enable control of simultaneous operations and further leverage the computational resources available during execution. This added complexity may make it unsuitable for use when, for example, data sources are not very numerous or heterogeneous.
Another limitation of the solution is the fact that we ensure four of the six most important fundamental principles according to current regulations and frameworks. This is because there are principles that depend on elements or conditions external to what the DQAM proposal can control, either because they are intrinsic characteristics of the device over which our system has no influence, or because they are requirements of the end services where they are used, and are therefore subsequent to everything our proposal does.
As for the two quality dimensions that the model does not address (timeliness and data volume), these are beyond the scope of DQAM because they depend directly on IoT devices. The model operates as a processing layer that receives data once it has been generated and transmitted, so it cannot influence the transmission frequency or the size of the packets sent. For example, if a sensor is configured to transmit every 10 min, DQAM cannot change this cadence. Similarly, if a device sends a limited data load due to hardware or energy-saving restrictions, the model cannot expand that information. These dimensions must be managed at the device configuration or network infrastructure level before the data reaches the DQAM stream.
Another relevant limitation is the dependence on manual configurations. Several DQAM functions use Internal Configuration (IC) files with information about device specifications, sensor characteristics, decoding parameters, and expected data structures. If an administrator enters incorrect configurations or fails to update them when the physical infrastructure changes, the system may discard valid data or process it incorrectly on a systematic basis. For example, if a device is modified to include fewer sensors, reducing its payload from 20 bytes to 10 bytes, the decoding function will interpret the packets as malformed, rejecting readings that are actually valid. This dependency highlights the need to develop automatic mechanisms in the future to detect unknown devices, identify sustained changes in device behaviour, and alert to possible configuration mismatches.
Another significant limitation is the reliance on manual configurations. The “Decode Data”, “Enrich Device Information”, and “Enrich Sensor Information” functions use internal configuration (IC) files that contain information on device specifications, sensor characteristics, decoding parameters, and expected data structures. If this IC is incorrect or unavailable, it entails the following series of risks:
- Discarding potentially valid messages due to an incorrect specification of the internal structure.
- Incorrect decoding of message payloads due to an incorrect structure of the expected bytes.
- Enriching messages for one type of device with data from another when they are incorrectly identified in the configuration.
- Failure to identify device types because they are not registered in the IC, thereby discarding the messages.
- Failure to identify the nature of a sensor’s measurements because they are not properly identified in the IC, thereby discarding that data.
- Incorrectly assigning information relating to one measurement to another of a different nature within the same device.
For example, if a device is modified to include fewer sensors, reducing its payload from 20 bytes to 10 bytes, the decoding function will interpret the packets as malformed and reject readings that are in fact valid.
This dependency highlights the need to develop mechanisms in the future that facilitate the mitigation of these risks. To this end, two mitigation methods have been established and are currently under development. The first is the creation of a verified catalogue of valid ICs associated with sensor device brands and models. This simplifies the configuration task for administrators, as they have ICs that align with each brand’s public datasheets. Secondly, research is underway on the development of an IC verification tool, for example, to ensure that all message bytes are considered for processing by the functions and that the ranges of decoded values are within the possible ranges of their magnitudes.
6. Implementation and Validation
The proposed solution has been implemented in a real infrastructure, the University of Alicante, where there are different types of sensor devices, both inside and outside the buildings. In addition, there are also laboratories with experimental systems where the sensor devices have very diverse characteristics. Our campus has 64 buildings with more than 1500 rooms in different areas. Each space can house different devices, such as temperature, humidity, air quality, open-door and -window sensors, and presence-detection sensors. Outdoors, there are weather stations, soil moisture sensors, particle presence sensors, light sensors, and other sensors.
Initially, the university had developed an ad hoc solution to process the different types of data obtained daily. In this solution, each service that uses a sensor performs its own data acquisition, processes the data to adapt and correct it as necessary, and, in some cases, even services that already use AI adapt the data for the algorithms. This system was built as new sensors were added, so it was initially very efficient and performed minimal processing. However, as the systems became more complex and, above all, as several sensors began to be combined across various services, maintaining them became unviable and inefficient. Figure 2 shows a diagram of the previous ad hoc system with some services. According to this layout, when each service was created, tasks that performed the same action were unnecessarily repeated, such as acquisition by each data source or processing data from the same source in different services. The same problem occurred when consulting device information and its corresponding configurations, resulting in numerous requests being made at the same time to retrieve information from different services. A major problem with this scheme is that when a sensor changes, the code for all affected processes must be modified, creating a maintenance burden.
Figure 2.
First ad hoc solution for data flow at the University of Alicante, including duplicate processes.
The fact that each service must implement its own processes to adapt raw data to the application’s needs and limitations, and to apply corrections and transformations, makes it difficult for the service to focus on its main activities, such as providing this data to users through a real-time visualisation system. In addition, the resources allocated to that service are wasted. When data is stored from the moment it is received from the devices and then sent to higher layers for processing, there is no control over whether that data is valid, or whether, on the contrary, attempting to process it will generate an error, which could cause the service to stop completely.
Following the proposed solution design and architectural model, the entire data processing system has been rebuilt, including the quality assurance process. The current system incorporates the new workflow for acquiring, processing, and adapting the data for the different uses to which it will be put. The university’s new solution is shown in Figure 3.
Figure 3.
Current solution for data flow at the University of Alicante.
As described, there is now only one connection from each sensor source to the Acquisition Layer, so there is a single data-reading process. The functions described (1 to 4) are carried out in the Acquisition Layer (AL), producing a single output data stream for each sensor. In the example in Figure 3, Water Service uses data directly from this Acquisition Layer, as it is a basic activity-monitoring service. This means that the data flow from the water sensor does not continue through the next processing layer (PL). The other two data sources, Wi-Fi and Electric Car, do enter the Processing Layer and undergo the functions of this layer (5 to 10). At the output of the PL, two services use this data, Wi-Fi Service and Wi-Fi&Car Service. Now, the data used across multiple services has been processed only once, by the same functions, with minimal computational cost.
Finally, the Wi-Fi data continues to pass through the last layer of AIAL, becoming data-ready for use in the Intelligent Wi-Fi Service.
Figure 3 shows that all the logic related to data acquisition, processing and transformation is concentrated in the new layers of the model. This avoids duplicating processes across various services; there is only one codebase that implements them. This new solution standardises data acquisition, processing, and AI adequacy, with the flexibility to use only the data from the layer required for each service. As shown in Figure 3, each service will consume the data from the layer it needs, depending on the final transformation of the data required. Other applications that use the same data source will not have to re-run the adequacy of their information. All information is processed, accessible to any service that requires it, and assured of the required data quality.
To demonstrate the improvement achieved with the new workflow, we have analysed the latencies generated by each function and compared the results of processing the data using the old scheme (Figure 2) with those using the new workflow (Figure 3). For the analysis, we assume that each activity has the same latency in both the old and new models, since the internal function being performed is the same. The time spent in communication between functions is negligible, since the functions are executed on the same machine and involve memory writes. The difference lies in the fact that previously each service only needed to execute specific actions, whereas now, when taking the output from a layer, all the functions it contains must be executed.
In contrast, each data source (e.g., Wi-Fi) now only needs to execute a function in the new model once, whereas under the old scheme (Figure 2) it needed to be executed several times; for example, function 1, “Read Data”, was executed three times, once for each specific service. Table 5 shows the times, in milliseconds, required to execute each function in each model. The ‘Functions’ column lists the names of the 18 functions included in the new model and relates them to those performed in the previous model. The Time (ms) column indicates the average execution time of the function.
As mentioned previously, the measured time is independent of whether it is measured in the old or the new model; internally, the task is the same. The Wi-Fi Service column indicates the execution time of the functions related to that service in Figure 2. The same applies to the Intelligent Wi-Fi Service and Wi-Fi&Car Service columns, where specifically, the execution time of the functions for each of the two data sources used is indicated, and finally, for the Water Service. As shown in Table 6, the Acquisition Layer requires activities 1 to 4, so the total time to process data up to this layer is 480.22 ms. For the Processing Layer, an average time of 1477.98 ms is required (including functions 1 to 10). And for the AI Adequacy Layer, a total time of 2572.85 ms is required (as it must pass through all the functions).
Table 6.
Measurement of the average execution time for each function and the execution time of the functions involved in the Wi-Fi Service, Intelligent Wi-Fi Service, Wi-Fi and Car Service and Water Service. The Total row indicates the total time taken to execute all DQAM functions in sequence, and to execute the functions involved in each service.
If we analyse what happened in the previous model (Figure 2), a single record from the Wi-Fi data source, which was used by three services, required the same function to be executed multiple times, meaning that each service had duplicate functions; for example, function 1, ‘Read Data’, is executed up to three times. However, in the new model, each function is executed only once (although more functions may be executed than were previously essential).
If we analyse each data source, we obtain the following, Table 7. The Data Source column lists each data source used, and for DQAM or the Old Model, it indicates the time and functions to be executed. For the Wi-Fi data source, since a service utilising the data operates at the highest level, a record passes through the 18 functions, taking a total of 2572.85 ms, whereas for the Old Model, since numerous functions are repeated, it takes 4250.40 ms. Herein lies the true benefit of the proposal: when a data source has duplicate functions, more time is spent and a latency improvement of almost 40% is achieved. For the Electric Car data source, however, as Processing Layer data is used, more functions (from 1 to 10) are executed than were executed exclusively in the Old Model, increasing the time from 1151.29 ms to 1477.98 ms. In this case, performance worsens by almost 30%. In the case of the Water data source, the same actions are performed, so the times are similar, and there is neither an improvement nor a deterioration. Overall, the new system achieves a 23% latency improvement for the same example services. Although this analysis only concerns those services, it is worth noting that the same data source is used across various services; therefore, the more it is used, the greater the saving in execution time, as there are no duplicate functions (or code).
Table 7.
Summary of function execution times for each data source. The table shows the time taken by DQAM for each source, and the time taken by the old model. The Improve column shows the improvement achieved by DQAM through the avoidance of function duplication.
Finally, a major benefit of this approach is that solutions now focus solely on their own business logic, providing the services and functionality for which they were designed, without having to invest resources or logic in acquiring, preparing, and ensuring the adequacy of IoT data sources. This implies an implicit improvement in system maintainability, as software engineers now only have to focus on maintaining the service, while data quality engineers handle the rest of the processes.
7. Conclusions
This paper has presented the design and validation of a multi-layer conceptual model and architecture for data quality assurance and adequacy in IoT environments for AI technologies.
Firstly, the implementation of the model has enabled the standardisation of the actions required to generate high-quality, valid datasets ready for use in AI. This approach consolidates similar operations into a single process, eliminating the duplication inherent in previous ad hoc solutions, thereby improving the system’s consistency and maintainability and reinforcing its robustness by centralising control over data validity and correctness, critical elements that previously constituted vulnerabilities for dependent services.
In addition, the proposed architecture, based on a segmented execution flow, has demonstrated a significant improvement in system performance and efficiency. The early filtering mechanism for unprocessable data reduces execution time by avoiding unnecessary processing in later layers, thereby maximising productivity and utilising computational resources more efficiently. This design also allows simultaneous execution of functions, enabling new data to occupy an operation once the previous data has moved to the next, contributing to a scalable, time-efficient solution.
Flexibility and adaptability are inherent in the multi-layer design, allowing data-consuming applications to access information at the processing level best suited to their specific requirements. Whether it is raw data from the first layer, enriched data from the second, or data transformed for AI from the third. This modularity centralises the processing logic and lightens the computational load on the end applications, allowing them to focus on their core functions.
Furthermore, adopting a systematic approach to data generation and quality assurance for AI ensures compliance with fundamental data quality principles, such as accuracy, completeness, usefulness, and consistency, as well as with architectural requirements established by international standards such as ISO/IEC. This translates into greater security, reliability and robustness of the overall system, ensuring that the data meets the quality attributes required by the services. The proposal, therefore, shows advantages over traditional approaches as it ensures a greater number of quality principles.
The solution presented in this work requires deployment based on distributed systems in order to leverage further the computational resources required during its execution. Therefore, as future work, a solution will be designed with dynamic workflow redirection capabilities between nodes, with corresponding dynamic resource provisioning. This feature is essential for scaling performance and adaptability in large, variable infrastructure environments, aiming to elevate system optimisation and robustness. This distributed architecture would allow the operations of each layer to be located in the most appropriate resources and even balance provisioning to meet computing needs when data flows are high.
This proposed distributed architecture is being developed in coordination with the DQAM for the FOG layer. This architecture is structured on two levels: a processing level, where data acquisition and processing operations are executed; and a control level, responsible for system monitoring and decision-making on load distribution. The control level comprises two types of elements: a coordinator node, which calculates the optimal distribution of computational load among available nodes; and a balancer node, which manages traffic routing to processing nodes. Communication among all these components is carried out using a lightweight protocol, the Simple FOG Management Protocol (SFMP), designed specifically for automated resource management, and it also ensures fault-tolerance mechanisms through substitute elements and activity-check messages. This work is being undertaken by other members of the research team and will enable the scalable deployment of the DQAM, dynamically leveraging the computational resources available during the execution of each layer’s functions.
Finally, another line of future work is geared towards extending the DQAM to address specific data quality requirements for Artificial Intelligence systems, in line with the ISO/IEC 25059 standard. Although the current model guarantees fundamental dimensions such as accuracy, integrity, usability and consistency, AI systems have additional requirements related to fairness and absence of bias in training data. Aspects such as the representativeness of datasets, the detection of bias in value distributions, and the traceability of data sources are increasingly relevant to ensuring that machine learning models do not produce unfair results. It is therefore proposed to expand the AIAL with specific functions that allow these aspects to be evaluated and mitigated, ensuring that the data processed by DQAM is not only technically correct but also ethically appropriate for use in AI systems.
Author Contributions
Conceptualization, L.A.M. and J.V.B.M.; methodology, J.V.B.M.; software, L.A.M. and J.V.B.M.; validation, L.A.M., J.V.B.M., C.C.A. and D.S.P.; formal analysis, L.A.M.; investigation, L.A.M.; resources, J.V.B.M.; data curation, L.A.M. and J.V.B.M.; writing—original draft preparation, L.A.M.; writing—review and editing, J.V.B.M., C.C.A. and D.S.P.; visualisation, J.V.B.M.; supervision, J.V.B.M. and D.S.P.; project administration, J.V.B.M.; funding acquisition, J.V.B.M. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by the PID2023-152566OB-I00 project “Preventive maintenance of digital infrastructures through the application of Artificial Intelligence for the diagnosis and prediction of anomalies” financed by MICIU/AEI/10.13039/501100011033 and FEDER, UE; project “Adaptive control of urban supply systems” under Grant UAIND22-01B of the Vice-Rectorate for Research of the University of Alicante; and CENID2026/03—‘Design of digital intelligence systems for the creation of resilient infrastructure. Improving diagnostics to enhance the efficiency of critical service management’ by the Digital Intelligence Centre of the Province of Alicante CENID, Diputación de Alicante.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
No new data were created or analysed in this study. Data sharing is not applicable to this article.
Acknowledgments
During the preparation of this manuscript, the author(s) used Grammarly for the purposes of sentence polishing and rephrasing. The authors have reviewed and edited the output and take full responsibility for the content of this publication.
Conflicts of Interest
The authors declare no conflicts of interest. The funders had no role in the design of the study; in the collection, analyses, or interpretation of data; in the writing of the manuscript; or in the decision to publish the results.
Abbreviations
The following abbreviations are used in this manuscript:
| ACNN-LSTM | Asymmetric Convolutional Neural Network—Long Short-Term Memory |
| AI | Artificial Intelligence |
| DL | Deep Learning |
| DQAM | Data Quality Assessment Model |
| ETL | Extract, Transform, and Load |
| FL | Data Flow (Initial) |
| FL’ | Processed Data Flow (Effective) |
| FLnp | Non-processable Data Flow |
| IoT | Internet of Things |
| ISO/IEC JTC | ISO/IEC Joint Technical Committee |
| JSON | JavaScript Object Notation |
| LSTM | Long Short-Term Memory |
| ML | Machine Learning |
| MySQL | My Structured Query Language |
| Pnp | Probability of Non-processable Data |
| RAW | Unprocessed Data (Format) |
| RDF | Resource Description Framework |
| RLQN | Reinforced Learning for Quality Networks |
| SE4AI | Software Engineering for Artificial Intelligence |
| SQuaRE | Systems and Software Quality Requirements and Evaluation |
| TTN | The Things Network |
References
- Mansouri, T.; Sadeghi Moghadam, M.R.; Monshizadeh, F.; Zareravasan, A. IoT data quality issues and potential solutions: A literature review. Comput. J. 2023, 66, 615–625. [Google Scholar] [CrossRef] [Scilit]
- Elouataoui, W.; El Alaoui, I.; El Mendili, S.; Gahi, Y. An advanced big data quality framework based on weighted metrics. Big Data Cogn. Comput. 2022, 6, 153. [Google Scholar] [CrossRef] [Scilit]
- DeMedeiros, K.; Hendawi, A.; Alvarez, M. A survey of AI-based anomaly detection in IoT and sensor networks. Sensors 2023, 23, 1352. [Google Scholar] [CrossRef] [Scilit]
- Ain, N.; Vaia, G.; DeLone, W.H.; Waheed, M. Two decades of research on business intelligence system adoption, utilisation and success: A systematic literature review. Decis. Support Syst. 2019, 125, 113113. [Google Scholar] [CrossRef] [Scilit]
- Muñoz, L.A.; Martínez, J.V.B.; Pérez, F.M.; Fonseca, I.L. Anomaly detection system for data quality assurance in IoT infrastructures based on machine learning. Internet Things 2024, 25, 101095. [Google Scholar] [CrossRef] [Scilit]
- Teh, H.Y.; Kempa-Liehr, A.W.; Wang, K.I.K. Sensor data quality: A systematic review. J. Big Data 2020, 7, 11. [Google Scholar] [CrossRef] [Scilit]
- Das, B.; Jain, P.C. Real-time water quality monitoring system using Internet of Things. In Proceedings of the International Conference on Computing, Communication and Electronics (Comptelix), Jaipur, India, 1–2 July 2017; pp. 78–82. [Google Scholar]
- Delgosha, M.S.; Hajiheydari, N.; Talafidaryani, M. Discovering IoT implications in business and management: A computational thematic analysis. Technovation 2022, 118, 102236. [Google Scholar] [CrossRef] [Scilit]
- Virk, L.; Noor, M.A.; Fiaz, S.; Hussain, S.; Hussain, H.A.; Rehman, M.; Ahsan, M. Smart farming: An overview. In Smart Village Technology: Concepts and Developments; Singh, S.K., Singh, A.K., El-Hassan, N., Keshri, A.K., Eds.; Springer: Cham, Switzerland, 2020; pp. 191–201. [Google Scholar]
- Rathore, M.M.; Ahmad, A.; Paul, A.; Jeon, G. Efficient graph-oriented smart transportation using internet of things generated big data. In Proceedings of the 11th International Conference on Signal-Image Technology & Internet-Based Systems (SITIS), Bangkok, Thailand, 23–27 November 2015; pp. 512–519. [Google Scholar]
- Hajiheydari, N.; Delgosha, M.S.; Olya, H. Scepticism and resistance to IoMT in healthcare: Application of behavioural reasoning theory with configurational perspective. Technol. Forecast. Soc. Change 2021, 169, 120807. [Google Scholar] [CrossRef] [Scilit]
- Sovacool, B.K.; Del Rio, D.D.F. Smart home technologies in Europe: A critical review of concepts, benefits, risks and policies. Renew. Sustain. Energy Rev. 2020, 120, 109663. [Google Scholar] [CrossRef] [Scilit]
- Saeed, F.; Paul, A.; Rehman, A.; Hong, W.H.; Seo, H. IoT-based intelligent modelling of smart home environment for fire prevention and safety. J. Sens. Actuator Netw. 2018, 7, 11. [Google Scholar] [CrossRef] [Scilit]
- Karkouch, A.; Mousannif, H.; Al Moatassime, H.; Noel, T. Data quality in internet of things: A state-of-the-art survey. J. Netw. Comput. Appl. 2016, 73, 57–81. [Google Scholar] [CrossRef] [Scilit]
- Kim, S.; Del Castillo, R.P.; Caballero, I.; Lee, J.; Lee, C.; Lee, D.; Lee, S.; Mate, A. Extending data quality management for smart connected product operations. IEEE Access 2019, 7, 144663–144678. [Google Scholar] [CrossRef] [Scilit]
- Alwan, A.A.; Ciupala, M.A.; Brimicombe, A.J.; Ghorashi, S.A.; Baravalle, A.; Falcarin, P. Data quality challenges in large-scale cyber-physical systems: A systematic review. Inf. Syst. 2022, 105, 101951. [Google Scholar] [CrossRef] [Scilit]
- Tilly, R.; Posegga, O.; Fischbach, K.; Schoder, D. Towards a conceptualisation of data and information quality in social information systems. Bus. Inf. Syst. Eng. 2017, 59, 3–21. [Google Scholar] [CrossRef] [Scilit]
- Liu, C.; Nitschke, P.; Williams, S.P.; Zowghi, D. Data quality and the Internet of Things. Computing 2020, 102, 573–599. [Google Scholar] [CrossRef] [Scilit]
- Du, Y.; Wang, Z.; Leung, C.; Victor, L. Blockchain-based data quality assessment to improve distributed machine learning. In Proceedings of the International Conference on Computing, Networking and Communications (ICNC), Honolulu, HI, USA, 20–22 February 2023; pp. 170–175. [Google Scholar]
- Ferrag, M.A.; Maglaras, L.; Moschoyiannis, S.; Janicke, H. Deep learning for cyber security intrusion detection: Approaches, datasets, and comparative study. J. Inf. Secur. Appl. 2020, 50, 102419. [Google Scholar] [CrossRef] [Scilit]
- Mohammed, A.F.Y.; Sultan, S.M.; Lee, J.; Lim, S. Deep-reinforcement-learning-based IoT sensor data cleaning framework for enhanced data analytics. Sensors 2023, 23, 1791. [Google Scholar] [CrossRef] [Scilit]
- Ullah, I.; Mahmoud, Q.H. Design and development of a deep learning-based model for anomaly detection in IoT networks. IEEE Access 2021, 9, 103906–103926. [Google Scholar] [CrossRef] [Scilit]
- Alazab, M.; RM, S.P.; M, P.; Maddikunta, P.K.R.; Gadekallu, T.R.; Pham, Q.-V. Federated learning for cybersecurity: Concepts, challenges, and future directions. IEEE Trans. Ind. Inform. 2022, 18, 3501–3509. [Google Scholar] [CrossRef] [Scilit]
- ISO/IEC 25012:2008; Software Engineering—Software Product Quality Requirements and Evaluation (SQuaRE)—Data Quality Model. ISO: Geneva, Switzerland, 2008. Available online: https://www.iso.org/standard/35736.html (accessed on 16 April 2026).
- Ahmed, M.; Taconet, C.; Ould, M.; Chabridon, S.; Bouzeghoub, A. IoT data qualification for a logistic chain traceability smart contract. Sensors 2021, 21, 2239. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ratnayake, R.; Liyanage, M.; Murphy, L. Evaluating data trust in blockchain-based IoT systems using machine learning techniques. In Proceedings of the IEEE 22nd Consumer Communications & Networking Conference (CCNC), Las Vegas, NV, USA, 10–13 January 2025. [Google Scholar]
- Carleton, A.; Shull, F.; Harper, E. Architecting the future of software engineering. Computer 2022, 55, 89–93. [Google Scholar] [CrossRef] [Scilit]
- Horneman, A.; Mellinger, A.; Ozkaya, I. AI Engineering: 11 Foundational Practices; Software Engineering Institute, Carnegie Mellon University: Pittsburgh, PA, USA, 2019; Available online: https://www.sei.cmu.edu/documents/582/2019_019_001_634648.pdf (accessed on 16 April 2026).
- Chang, W. ISO/IEC JTC 1/SC 42 (AI)/WG 2 (Data) Data Quality for Analytics and Machine Learning (ML); National Institute of Standards and Technology: Gaithersburg, MD, USA, 2024. Available online: https://nvlpubs.nist.gov/nistpubs/ai/NIST.AI.100-5.pdf (accessed on 16 April 2026).
- ISO/IEC 5259-2:2024; Artificial Intelligence—Data Quality for Analytics and Machine Learning (ML)—Part 2: Data Quality Measures. ISO: Geneva, Switzerland, 2024. Available online: https://www.iso.org/standard/81860.html (accessed on 16 April 2026).
- ISO/IEC 25059:2023; Software Engineering—Systems and Software Quality Requirements and Evaluation (SQuaRE)—Quality Model for AI Systems. ISO: Geneva, Switzerland, 2023. Available online: https://www.iso.org/standard/80655.html (accessed on 16 April 2026).
- Duan, L.; Da Xu, L. Data analytics in industry 4.0: A survey. Inf. Syst. Front. 2024, 26, 2287–2303. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Tabassum, M.; Mahmood, S.; Bukhari, A.; Alshemaimri, B.; Daud, A.; Khalique, F. Anomaly-based threat detection in smart health using machine learning. BMC Med. Inform. Decis. Mak. 2024, 24, 347. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Hennessy, J.L.; Patterson, D.A. Computer Architecture: A Quantitative Approach, 5th ed.; Elsevier: Amsterdam, The Netherlands, 2011. [Google Scholar]
- Poolla, C.; Saxena, R. On extending Amdahl’s law to learn computer performance. Microprocess. Microsyst. 2023, 96, 104745. [Google Scholar] [CrossRef] [Scilit]
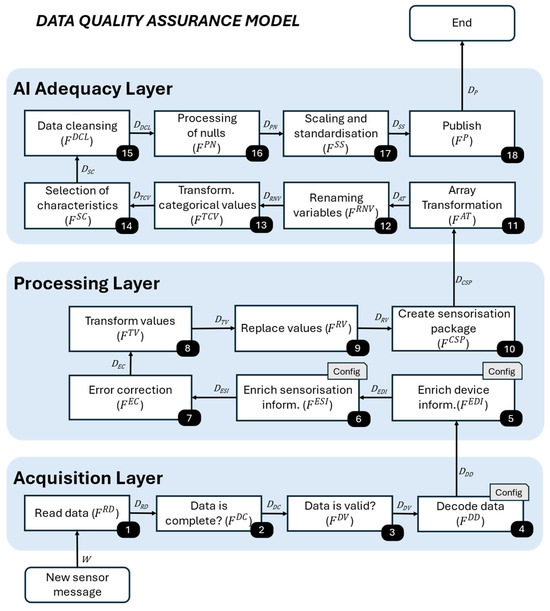
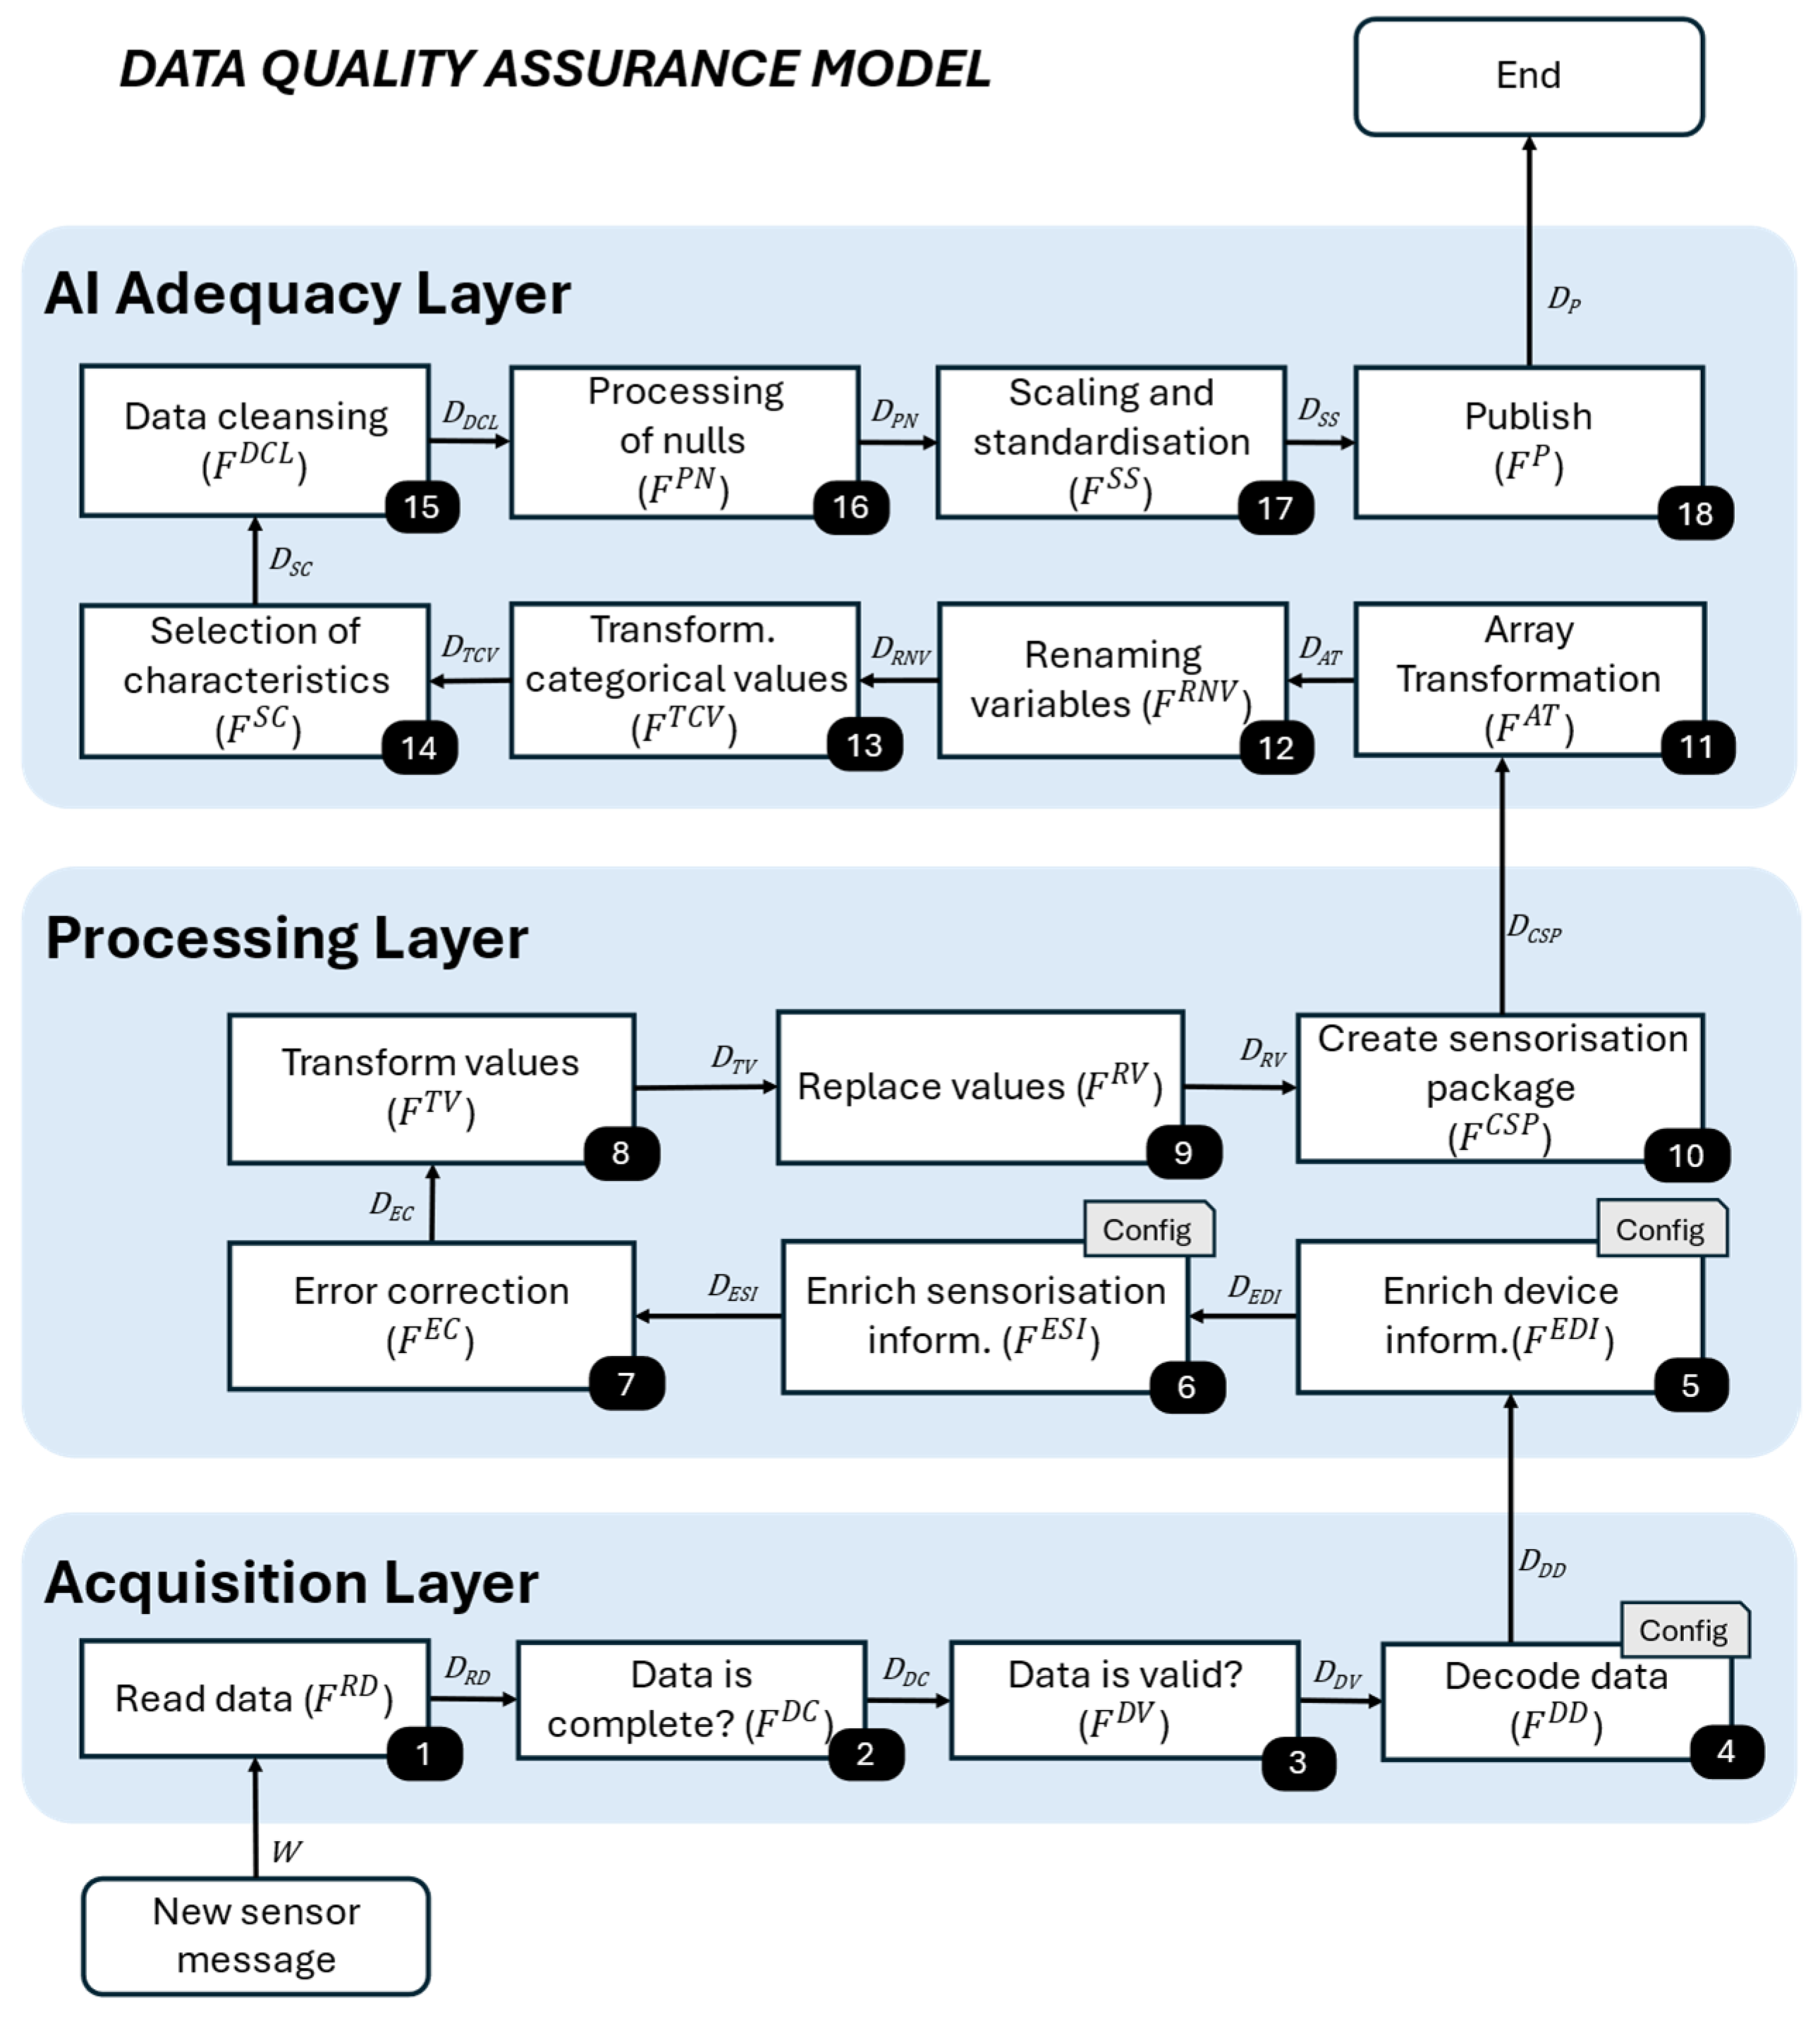
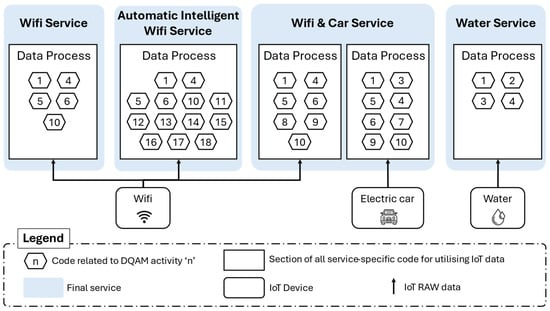
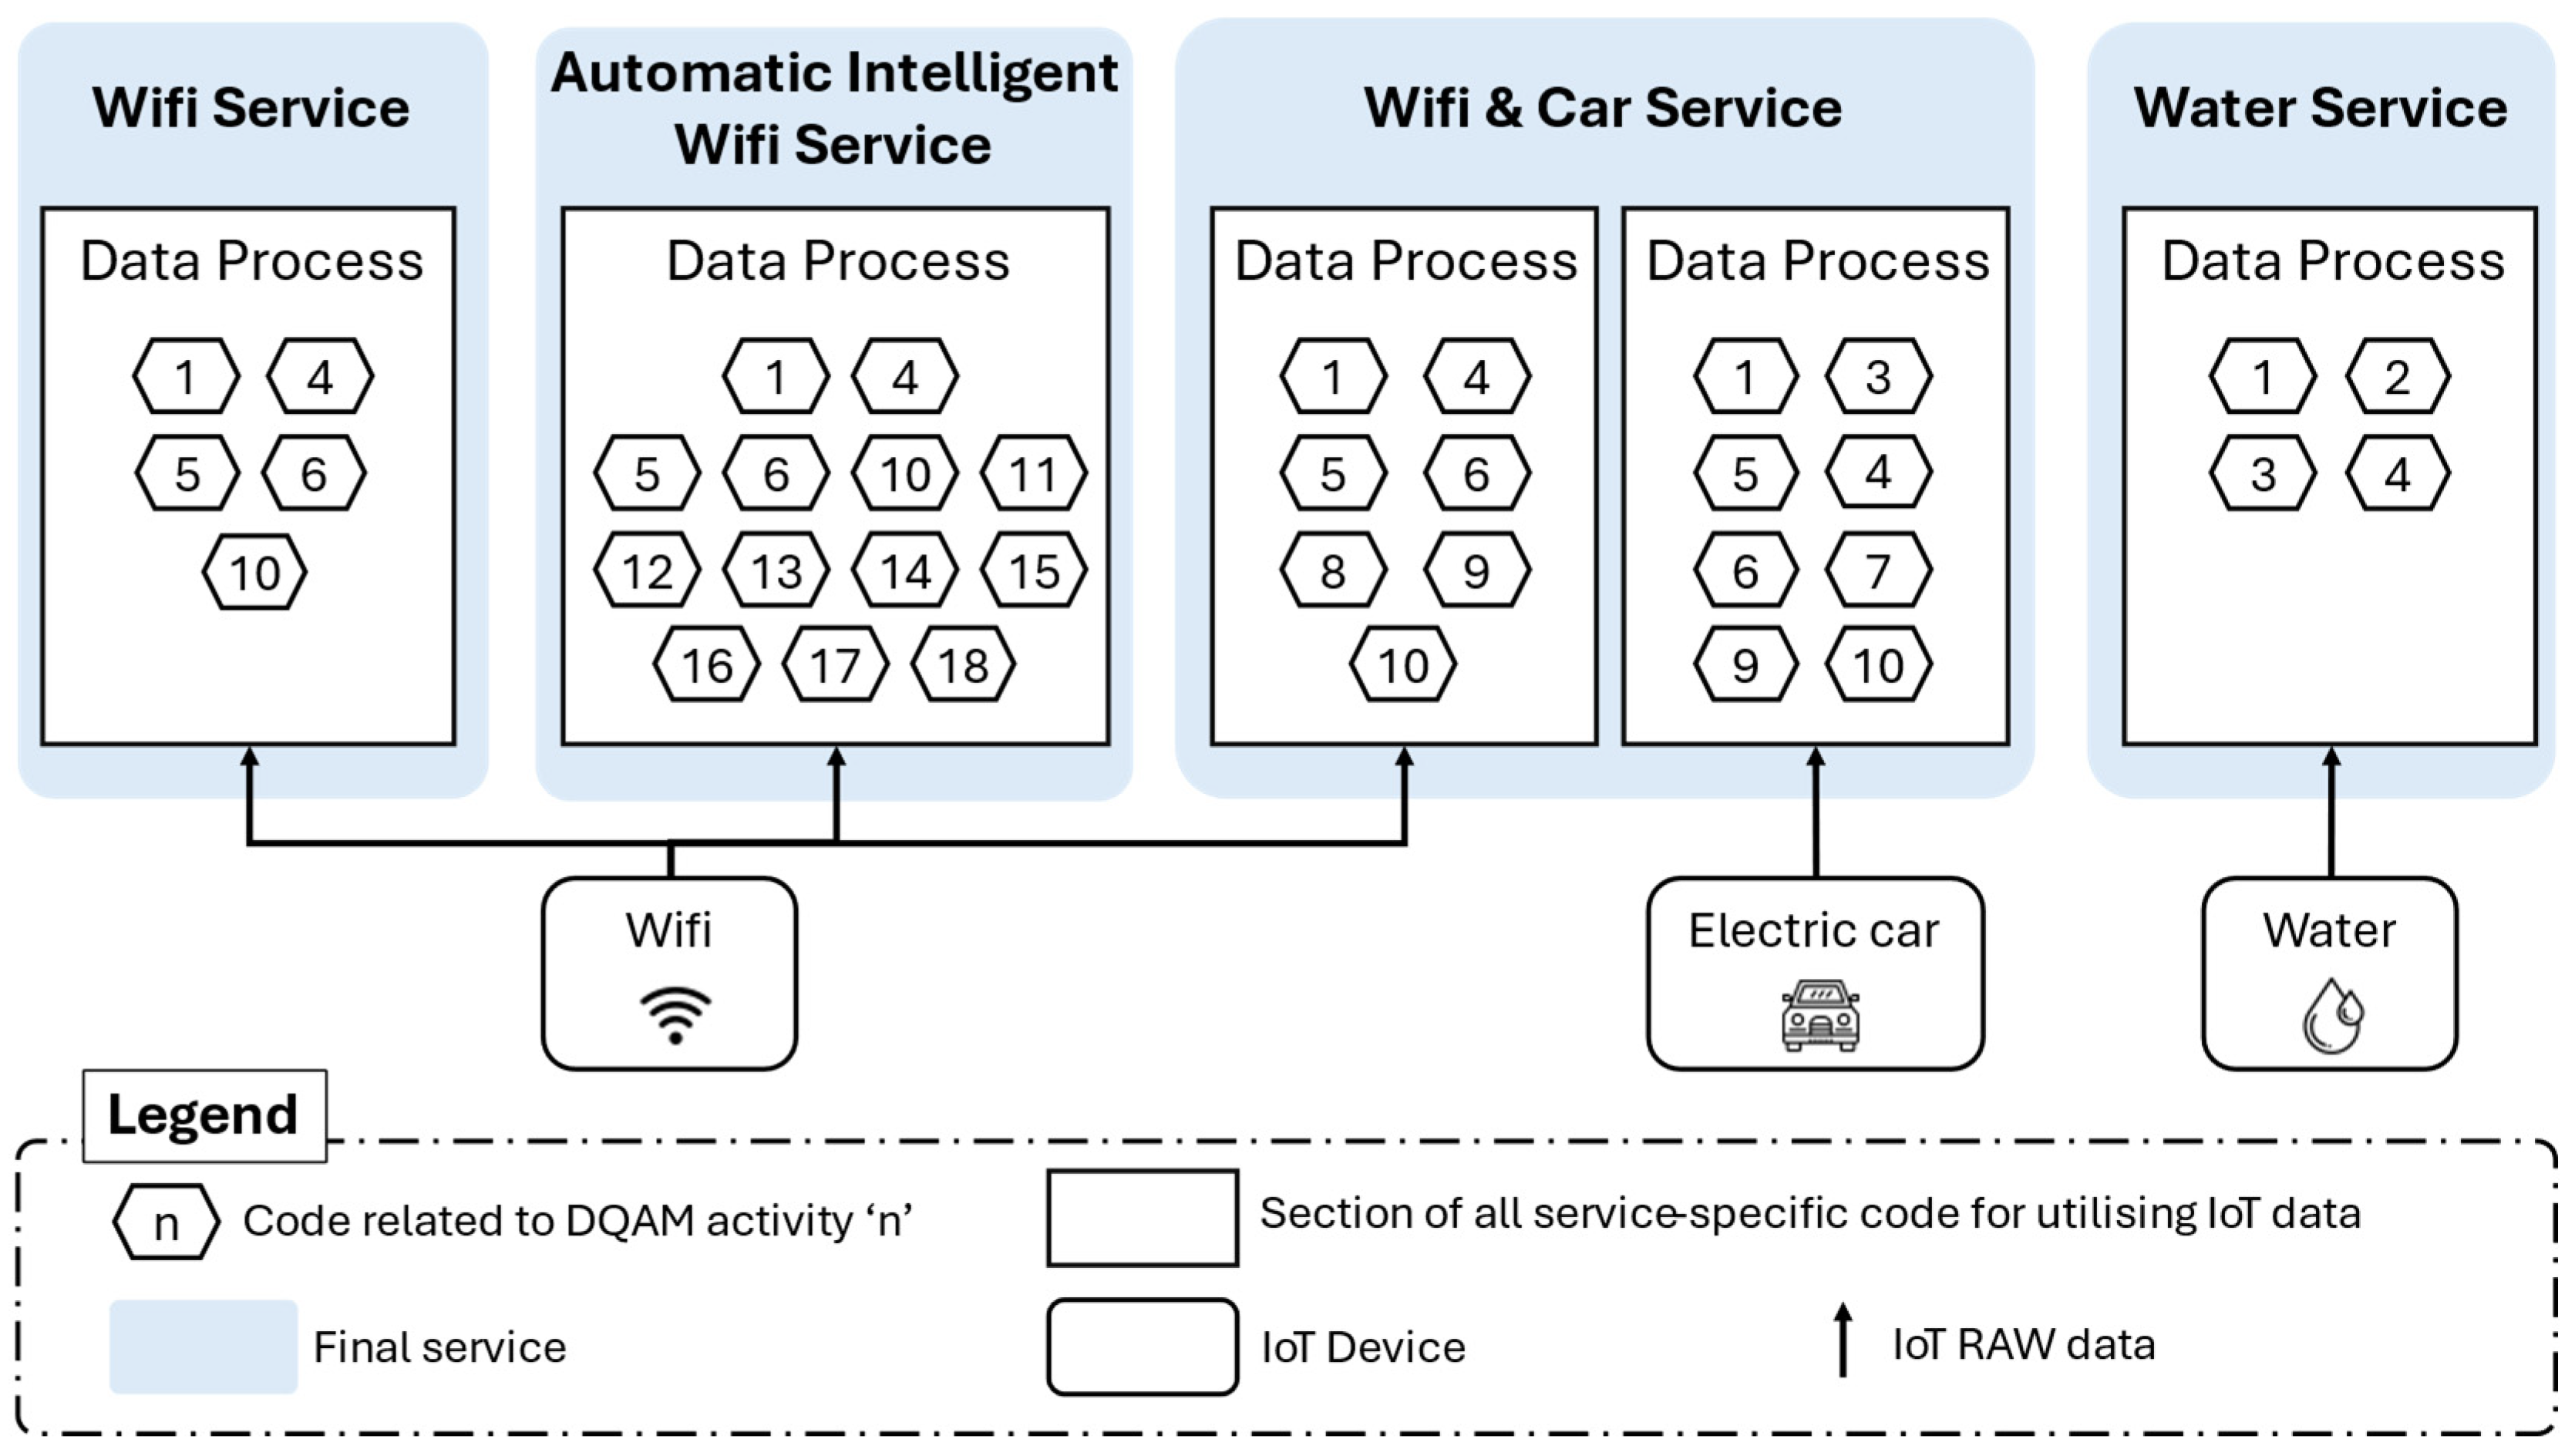
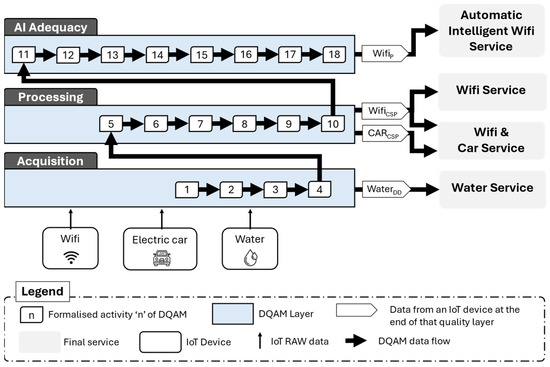
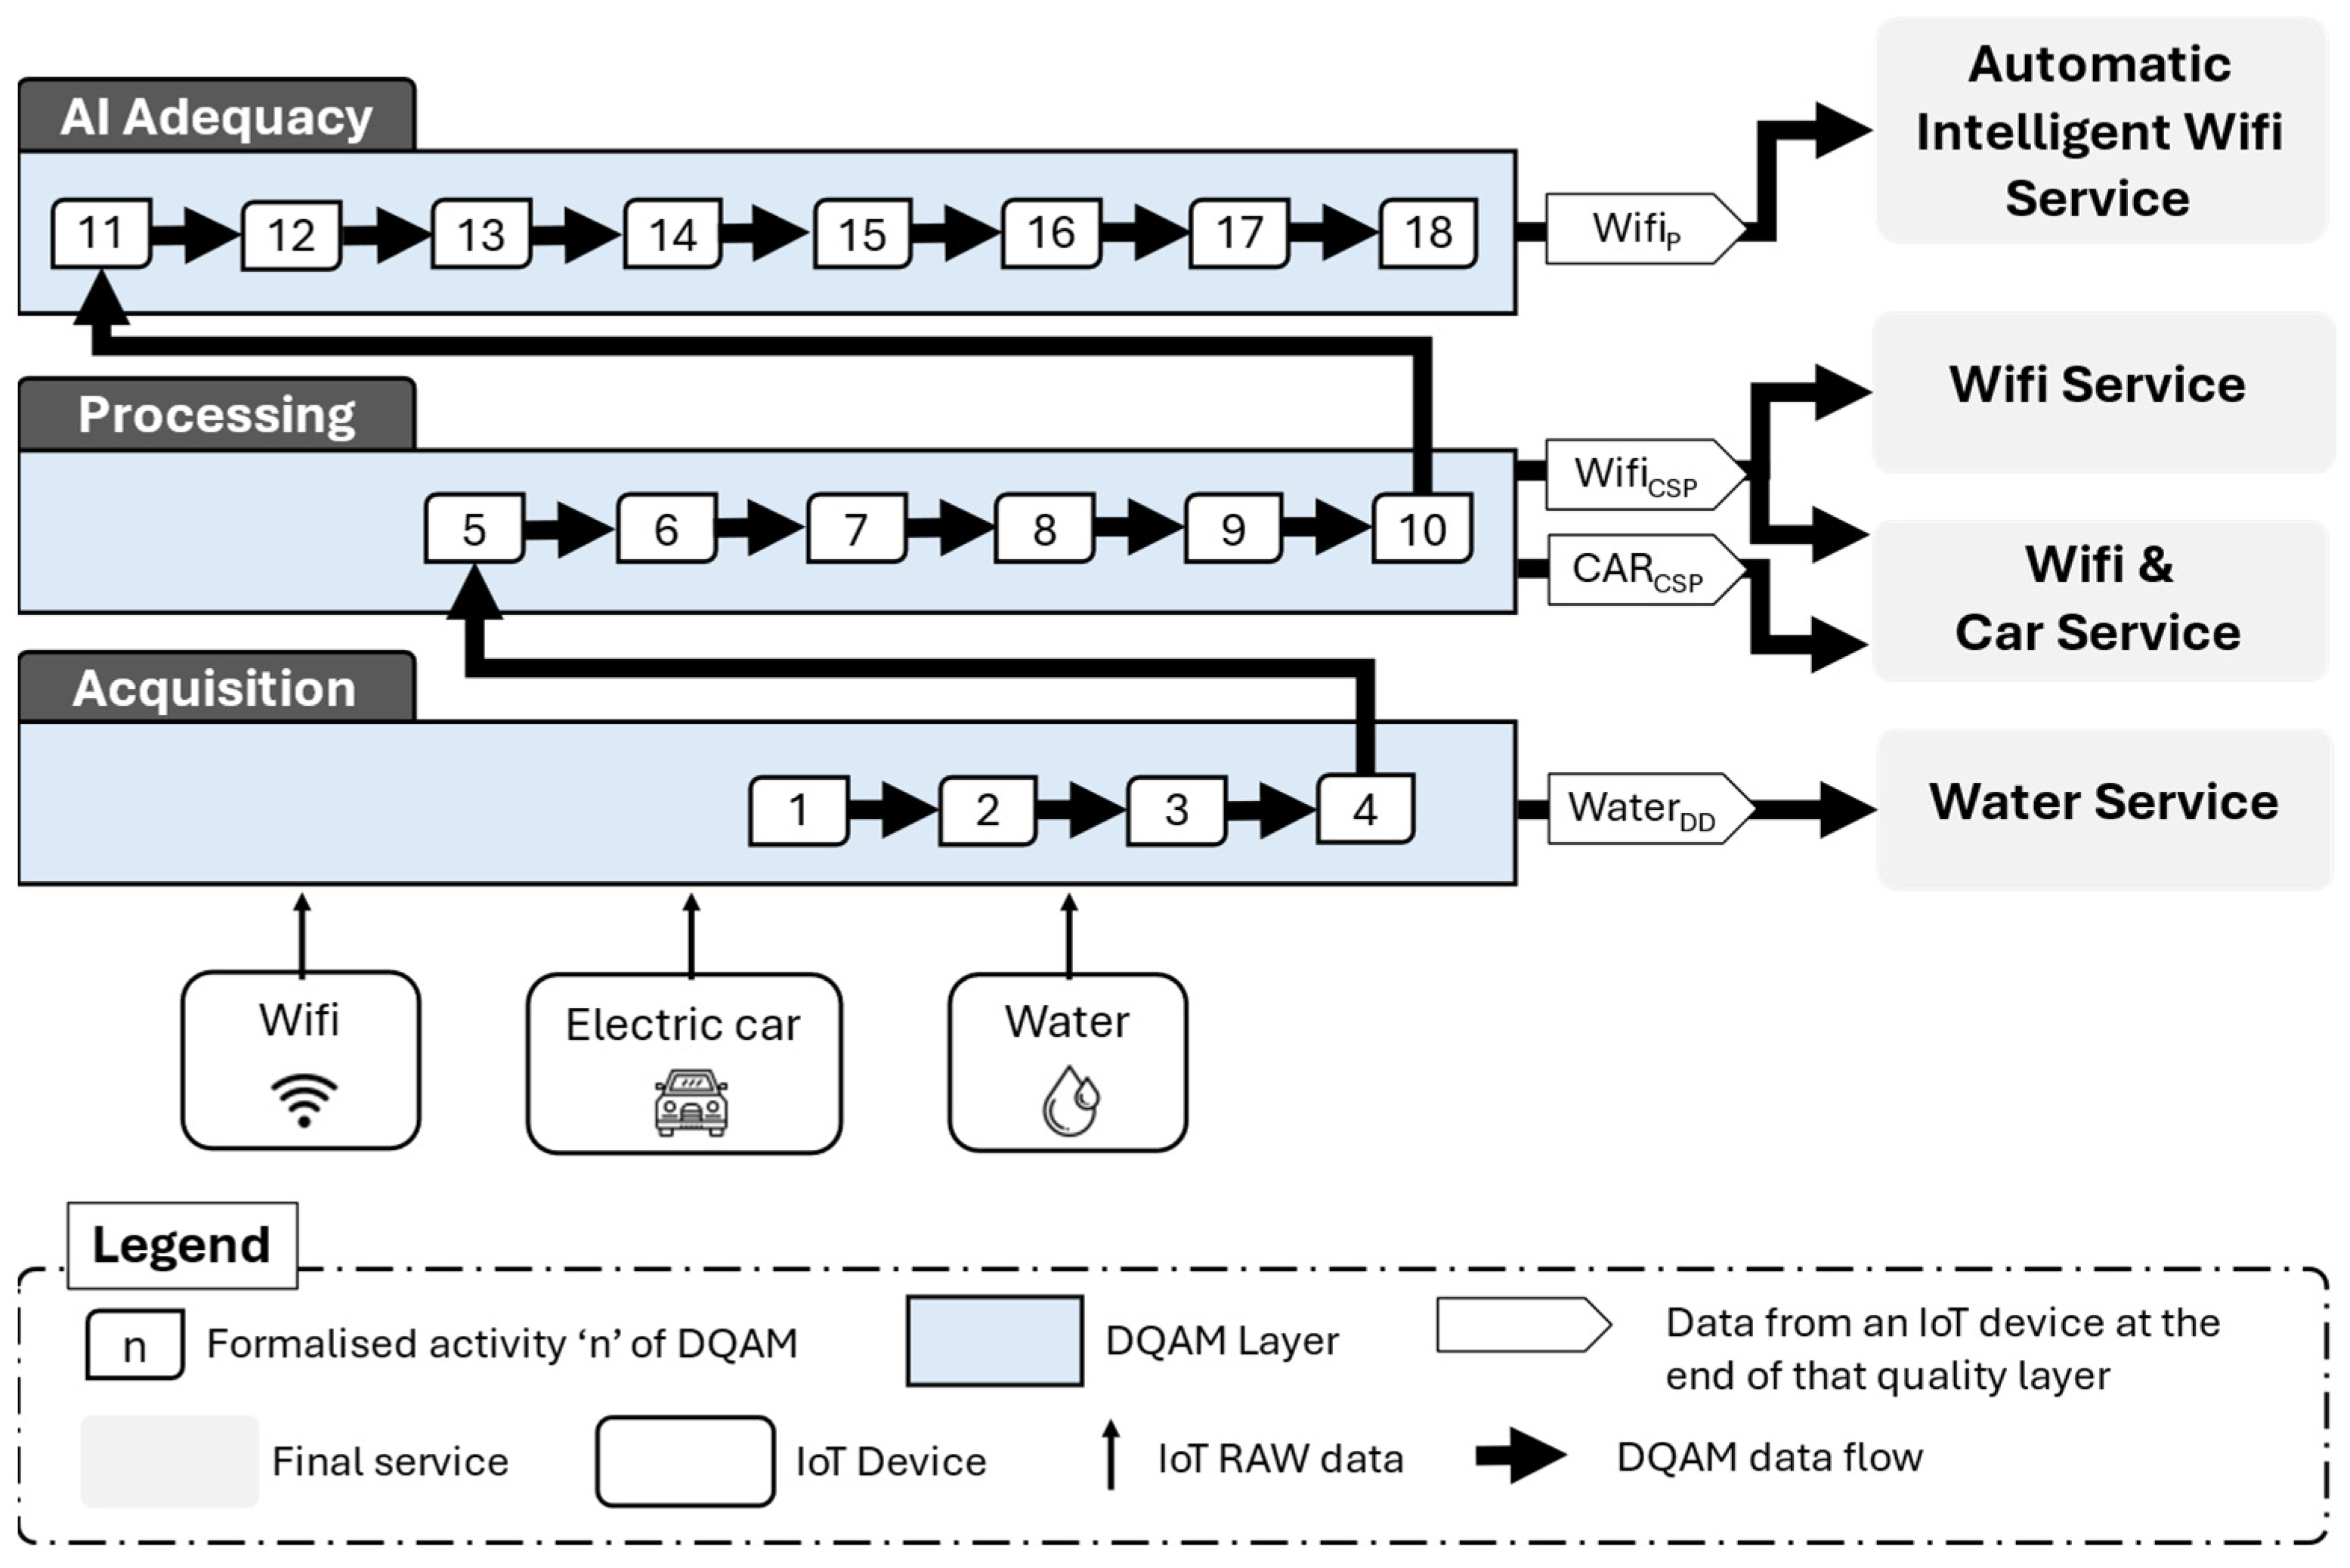

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.