


Abstract
Visual body-tracking techniques have seen widespread adoption in applications such as motion analysis, human–machine interaction, tele-robotics and extended reality (XR). These systems typically provide 2D landmark coordinates corresponding to key limb positions. However, to construct a meaningful 3D kinematic model for body joint reconstruction, a mapping must be established between these visual landmarks and the underlying joint parameters of individual body parts. This paper presents a method for constructing a 3D kinematic model of the human hand using calibrated 2D landmark-tracking data augmented with depth information. The proposed approach builds a hierarchical model in which the palm serves as the root coordinate frame, and finger landmarks are used to compute both forward and inverse kinematic solutions. Through step-by-step examples, we demonstrate how measured hand landmark coordinates are used to define the palm reference frame and solve for joint angles for each finger. These solutions are then used in a visualization framework to qualitatively assess the accuracy of the reconstructed hand motion. As a future work, the proposed model offers a foundation for model-based hand kinematic estimation and has utility in scenarios involving occlusion or missing data. In such cases, the hierarchical structure and kinematic solutions can be used as generative priors in an optimization framework to estimate unobserved landmark positions and joint configurations. The novelty of this work lies in its model-based approach using real sensor data, without relying on wearable devices or synthetic assumptions. Although current validation is qualitative, the framework provides a foundation for future robust estimation under occlusion or sensor noise. It may also serve as a generative prior for optimization-based methods and be quantitatively compared with joint measurements from wearable motion-capture systems.
1. Introduction
Within the past decades, hand tracking through various ambient sensing modalities has been gaining a considerable attention given its potential applications in many areas [1,2,3,4]. One of the immediate applications of such tracking and recognition is through the development of human–machine interaction, virtual reality, and tele-robotics. In addition, through increased precision in sensing modalities such as RGB-D sensing and through advances in deep-learning tracking models, it is now possible to establish a more accurate description of tracking hand landmarks defined through its various key anatomical locations. However, discerning the information regarding these spatial landmark data and constructing an accurate kinematic hand model faces several fundamental challenges. First, the human hand exhibits kinematic redundancy, with many degrees of freedom (DoF) leading to multiple possible configurations for the same fingertip position. Second, singularities may arise in certain joint configurations, complicating inverse kinematics. Third, anatomical variability across individuals can affect model generalizability. Our method addresses these by employing a hierarchical model structure that reduces redundancy through localized transformations, mitigating singularities through stable axis assignments, and leveraging real measurement data to accommodate anatomical differences. This approach enables practical estimation and reconstruction of realistic hand poses in diverse conditions.
1.1. Literature Review
1.1.1. Non-Invasive Hand-Tracking Systems
The sensing of hand and limb motion is a critical area of study with diverse applications, including human–computer interaction (HCI), virtual reality interfaces, and the monitoring of athletic performance. Existing commercial sensor systems often pose challenges due to their invasive nature, requiring users to wear specialized equipment, such as gloves or markers. This has created a need for alternative, non-invasive approaches.
One such effort is DigitEyes by Rehg et al. [5], a vision-based hand-tracking system that leverages a kinematic model to extract line and point features from grayscale images of unmarked hands. It enables real-time tracking for applications like 3D mouse interaction. Further advancing grayscale-based tracking, Rehg et al. [6] introduced a method capable of recovering the state of a 27-degrees-of-freedom (DoF) hand model using only standard grayscale video input. These early studies highlight the complexity of accurately modeling highly articulated mechanisms such as the human hand, which involve a vast state space and intricate visual patterns.
1.1.2. Depth-Based and Anatomically Constrained Models
The introduction of depth sensors has significantly improved the robustness and precision of 3D hand pose estimation. However, a persistent challenge is ensuring that predictions comply with anatomical constraints. Addressing this, Isailovic et al. [7] proposed an anatomical filter that accepts 3D tracker outputs and corrects the resulting 26-DoF hand vectors using biomechanical limitations, thereby enhancing realism.
Alternative sensing modalities have also been explored. For example, Li et al. [8] presented Aili, a table-lamp system that reconstructs hand skeletons without cameras or wearables. Using LED panels and low-cost photodiodes, it derives 2D binary blockage maps to infer hand position and shape, demonstrating a seamless blend of sensing and everyday utility.
Other studies focus on marker-based validation. Cereatti et al. [9] developed a multi-camera system with 24 surface markers to reconstruct finger kinematics in real time. Their method relies on a rigid-body model with 22 DoFs and includes automatic calibration for joint axes and rotation centers. This system has been validated on thumb flexion, grasping, and pointing tasks.
1.1.3. Kinematic Modeling from Anatomical Landmarks
The importance of anatomical accuracy extends beyond human motion. For instance, Haufe et al. [10] introduced a detailed kinematic model of Drosophila legs using anatomical landmarks such as condyles, which better capture the natural orientation of oblique joint axes. In the context of human-hand tracking, Ji and Yang [11] proposed a hierarchical topology-based method. Their approach defines global palm orientation and local finger-joint connectivity, then uses angle-based features with a regression forest to estimate 3D joint positions.
Pena et al. [12] contributed a simulation framework for manipulation and grasping based on a 25-DoF skeletal hand model. Their model incorporates palm arching and additional wrist/carpometacarpal joint DoFs, enhancing anatomical fidelity. They define joint relationships using Denavit–Hartenberg parameters, allowing for workspace estimation and detailed motion simulation.
1.1.4. Recent Advances in Adaptive and Probabilistic Modeling
Recent research emphasizes anatomical constraints, adaptiveness, and probabilistic modeling in hand kinematics. Zimmermann and Brox [13] introduced a hybrid learning model integrating biomechanical priors for real-time 3D pose estimation. Lapresa, Zollo and Cordella [14] developed a subject-specific adaptation framework that updates kinematic parameters online. Xu and Lee [15] formulated a probabilistic estimation approach that accounts for occlusions and enforces anatomical plausibility via joint limit constraints. These works illustrate a growing shift toward anatomically informed, subject-adaptive models—principles that also motivate the framework proposed in this paper.
1.1.5. MediaPipe-Based Tracking and Limitations
MediaPipe-based solutions have gained traction due to their efficiency and wide deployment. Amprimo et al. [2] validated both the standard Google MediaPipe Hand (GMH) model and a depth-enhanced variant (GMH-D), showing improved spatial accuracy in clinical hand assessments when compared against motion-capture ground truth. Similarly, Pfisterer et al. [16] demonstrated that fusing MediaPipe landmarks with RGB-D data from RealSense sensors could improve gesture recognition in human–robot interaction scenarios.
While these systems effectively enhance landmark accuracy through depth integration, they largely treat the tracked keypoints as direct pose inputs without explicitly modeling the underlying kinematics. In contrast, our approach introduces a fully articulated hierarchical kinematic model. We define local coordinate frames for each joint, solve both forward and inverse kinematics based on spatial geometry, and reconstruct hand postures using Unity3D (version 2023.2.20f1) for visual validation. This framework offers high interpretability, facilitates simulation, and supports future extensions under noisy or incomplete observations.
2. Background Material
2.1. Sensor Specifications
To ensure accurate 3D measurements of hand landmarks, we employed the Intel RealSense D435i RGB-D camera (Intel Corporation, Santa Clara, CA, USA) as our sensing device. The D435i integrates a high-resolution RGB sensor (1920 × 1080 at 30 frames per s) with an active infrared stereo depth sensor (1280 × 720 at 30 frames per s). The depth sensing operates within a range of 0.2 to 10 m, with a stereo baseline of 50 mm and field of view of approximately . The sensor provides synchronized RGB and depth frames, enabling frame-by-frame fusion of 2D image coordinates and calibrated depth values. In our experimental setup, the RealSense SDK v2.56.1 was used to extract aligned RGB and depth frames. All depth measurements were calibrated in millimeters and subsequently converted into 3D spatial coordinates using the camera’s intrinsic parameters, as detailed in Appendix A.
2.2. MediaPipe
MediaPipe Hand [17] (Google AI Edge Portal) is a hand-tracking framework that provides a solution for detecting and estimating the 2D hand landmarks in video streams using a single RGB camera. The MediaPipe Hand model tracks 21 distinct hand landmarks, which is achieved through a pipeline that integrates hand detection, keypoint localization, and pose estimation. The pixel coordinates in the RGB image for each hand landmark can be expressed as a pair of values or in vector form:
here, and represent the pixel coordinates of the ith landmark with respect to the image buffer frame. These landmark coordinates can then be calibrated in order to associate the representative pixel coordinates to the physical coordinate with respect to the sensor frame.
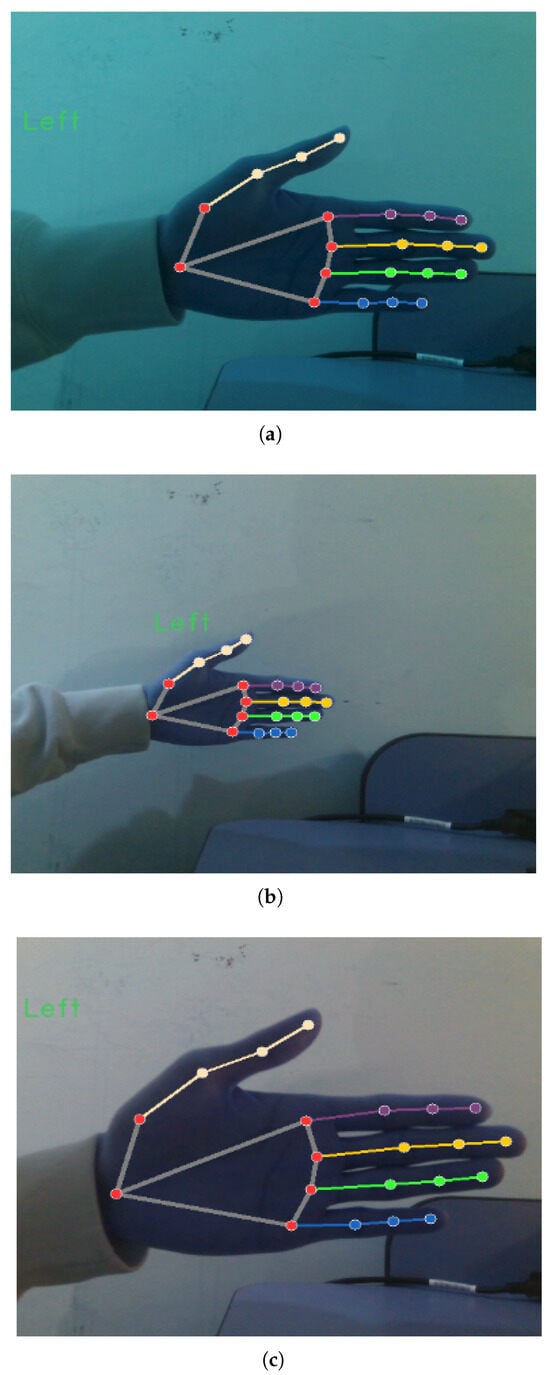
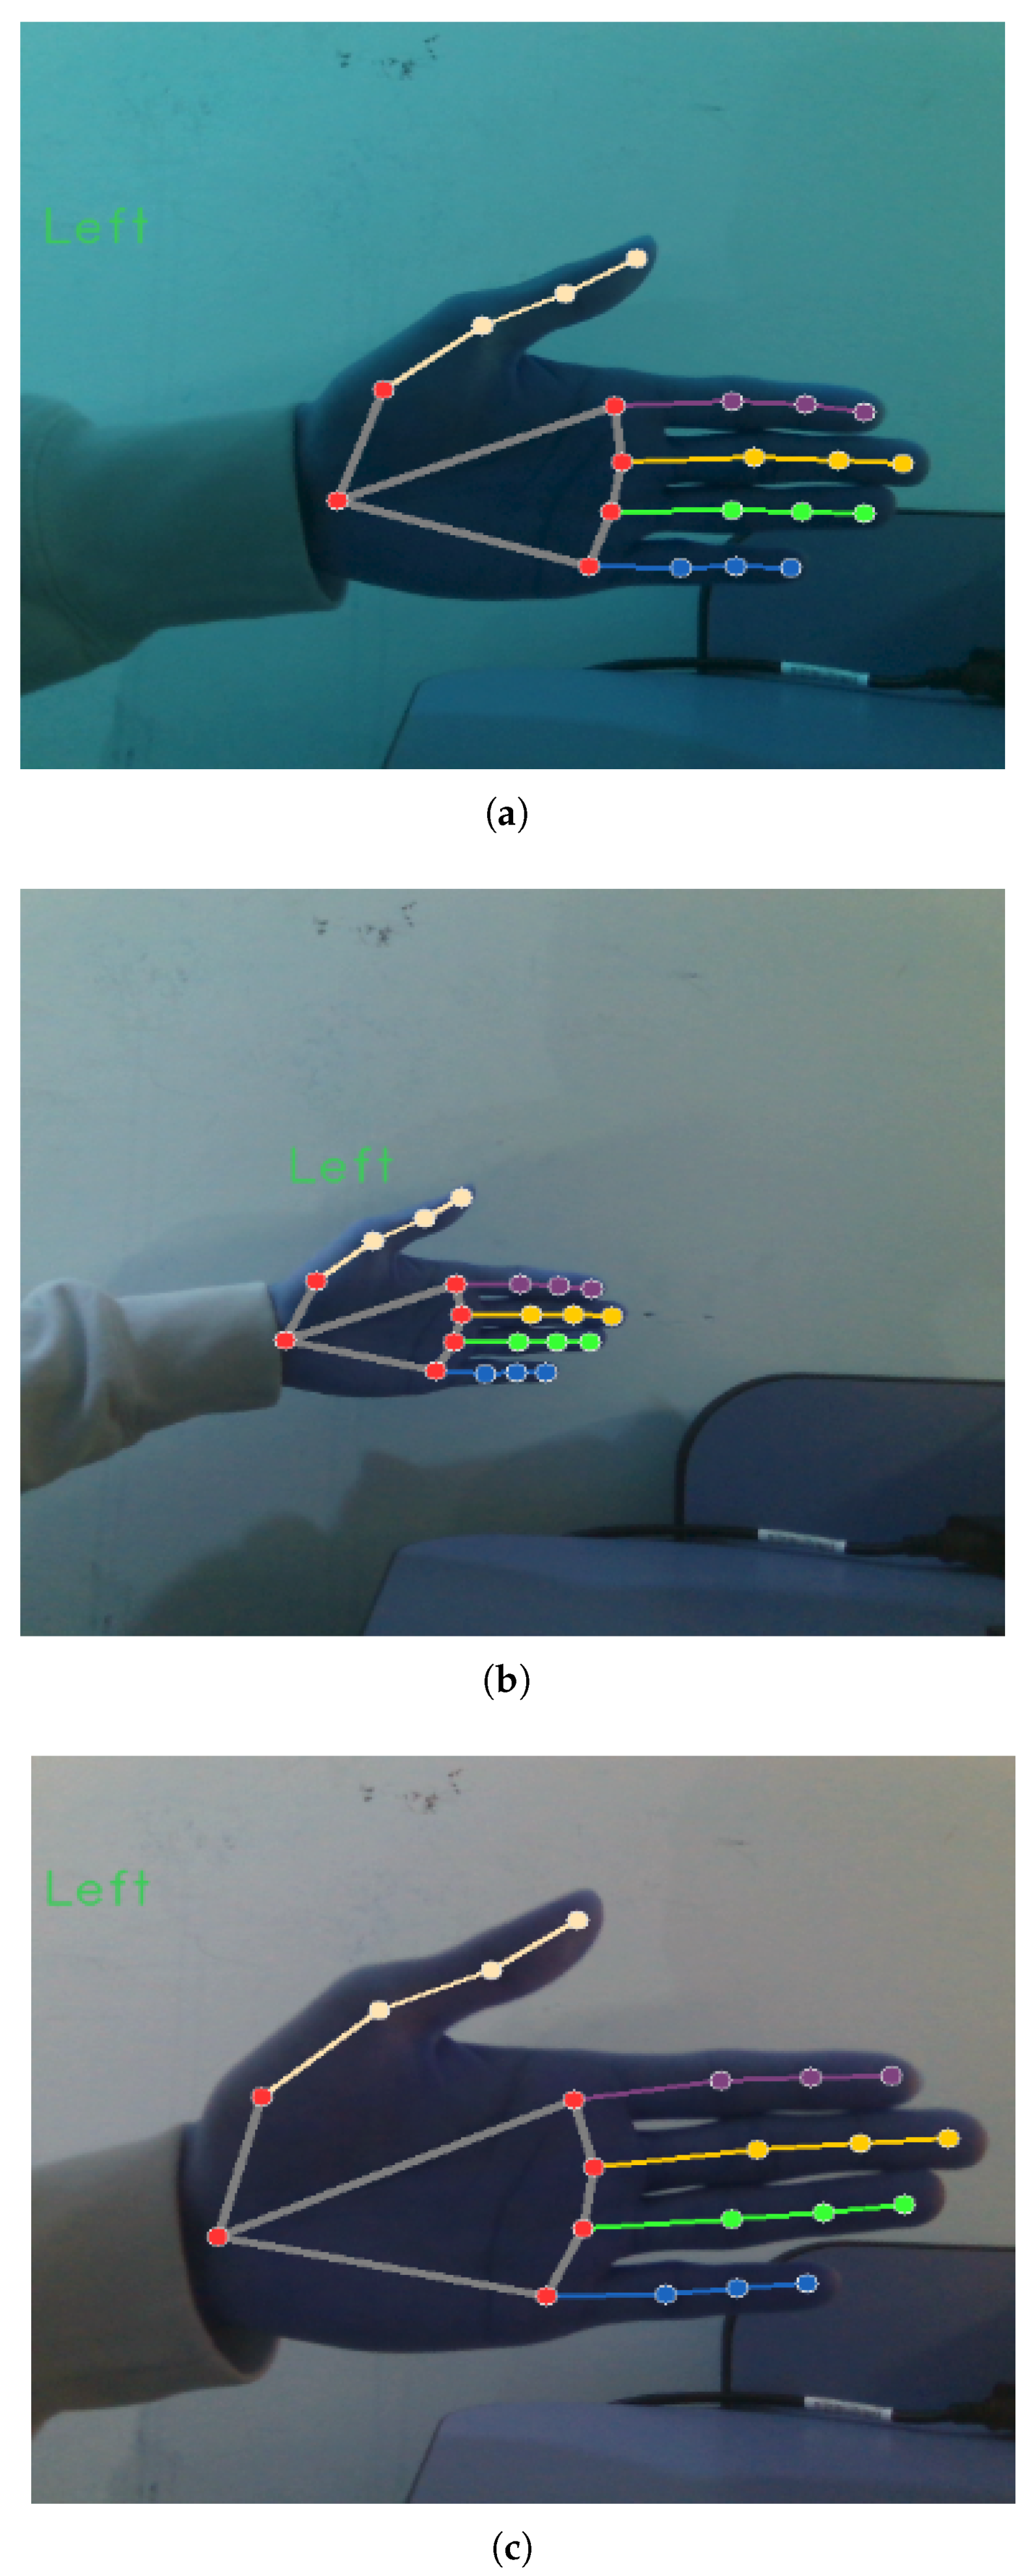
In order to associate additional coordinate measure to the existing 2D measurement, MediaPipe also offers an estimate of the physical distance of the landmarks with respect to the sensor frame. For example, Figure 1 illustrates three distinct tracking frames of a continuous hand movement sequence between calibrated the near to far distances with respect to the sensor.
Figure 1.
Three screenshots of hand movement at the start, middle, and ending points. (a) The hand starts to move from approximately m near the sensor. (b) The hand reaches a distance of around m and begins to move back. (c) The hand is near the sensor again, stopping at around m.
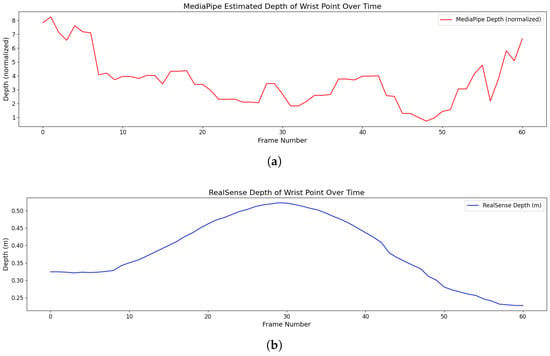
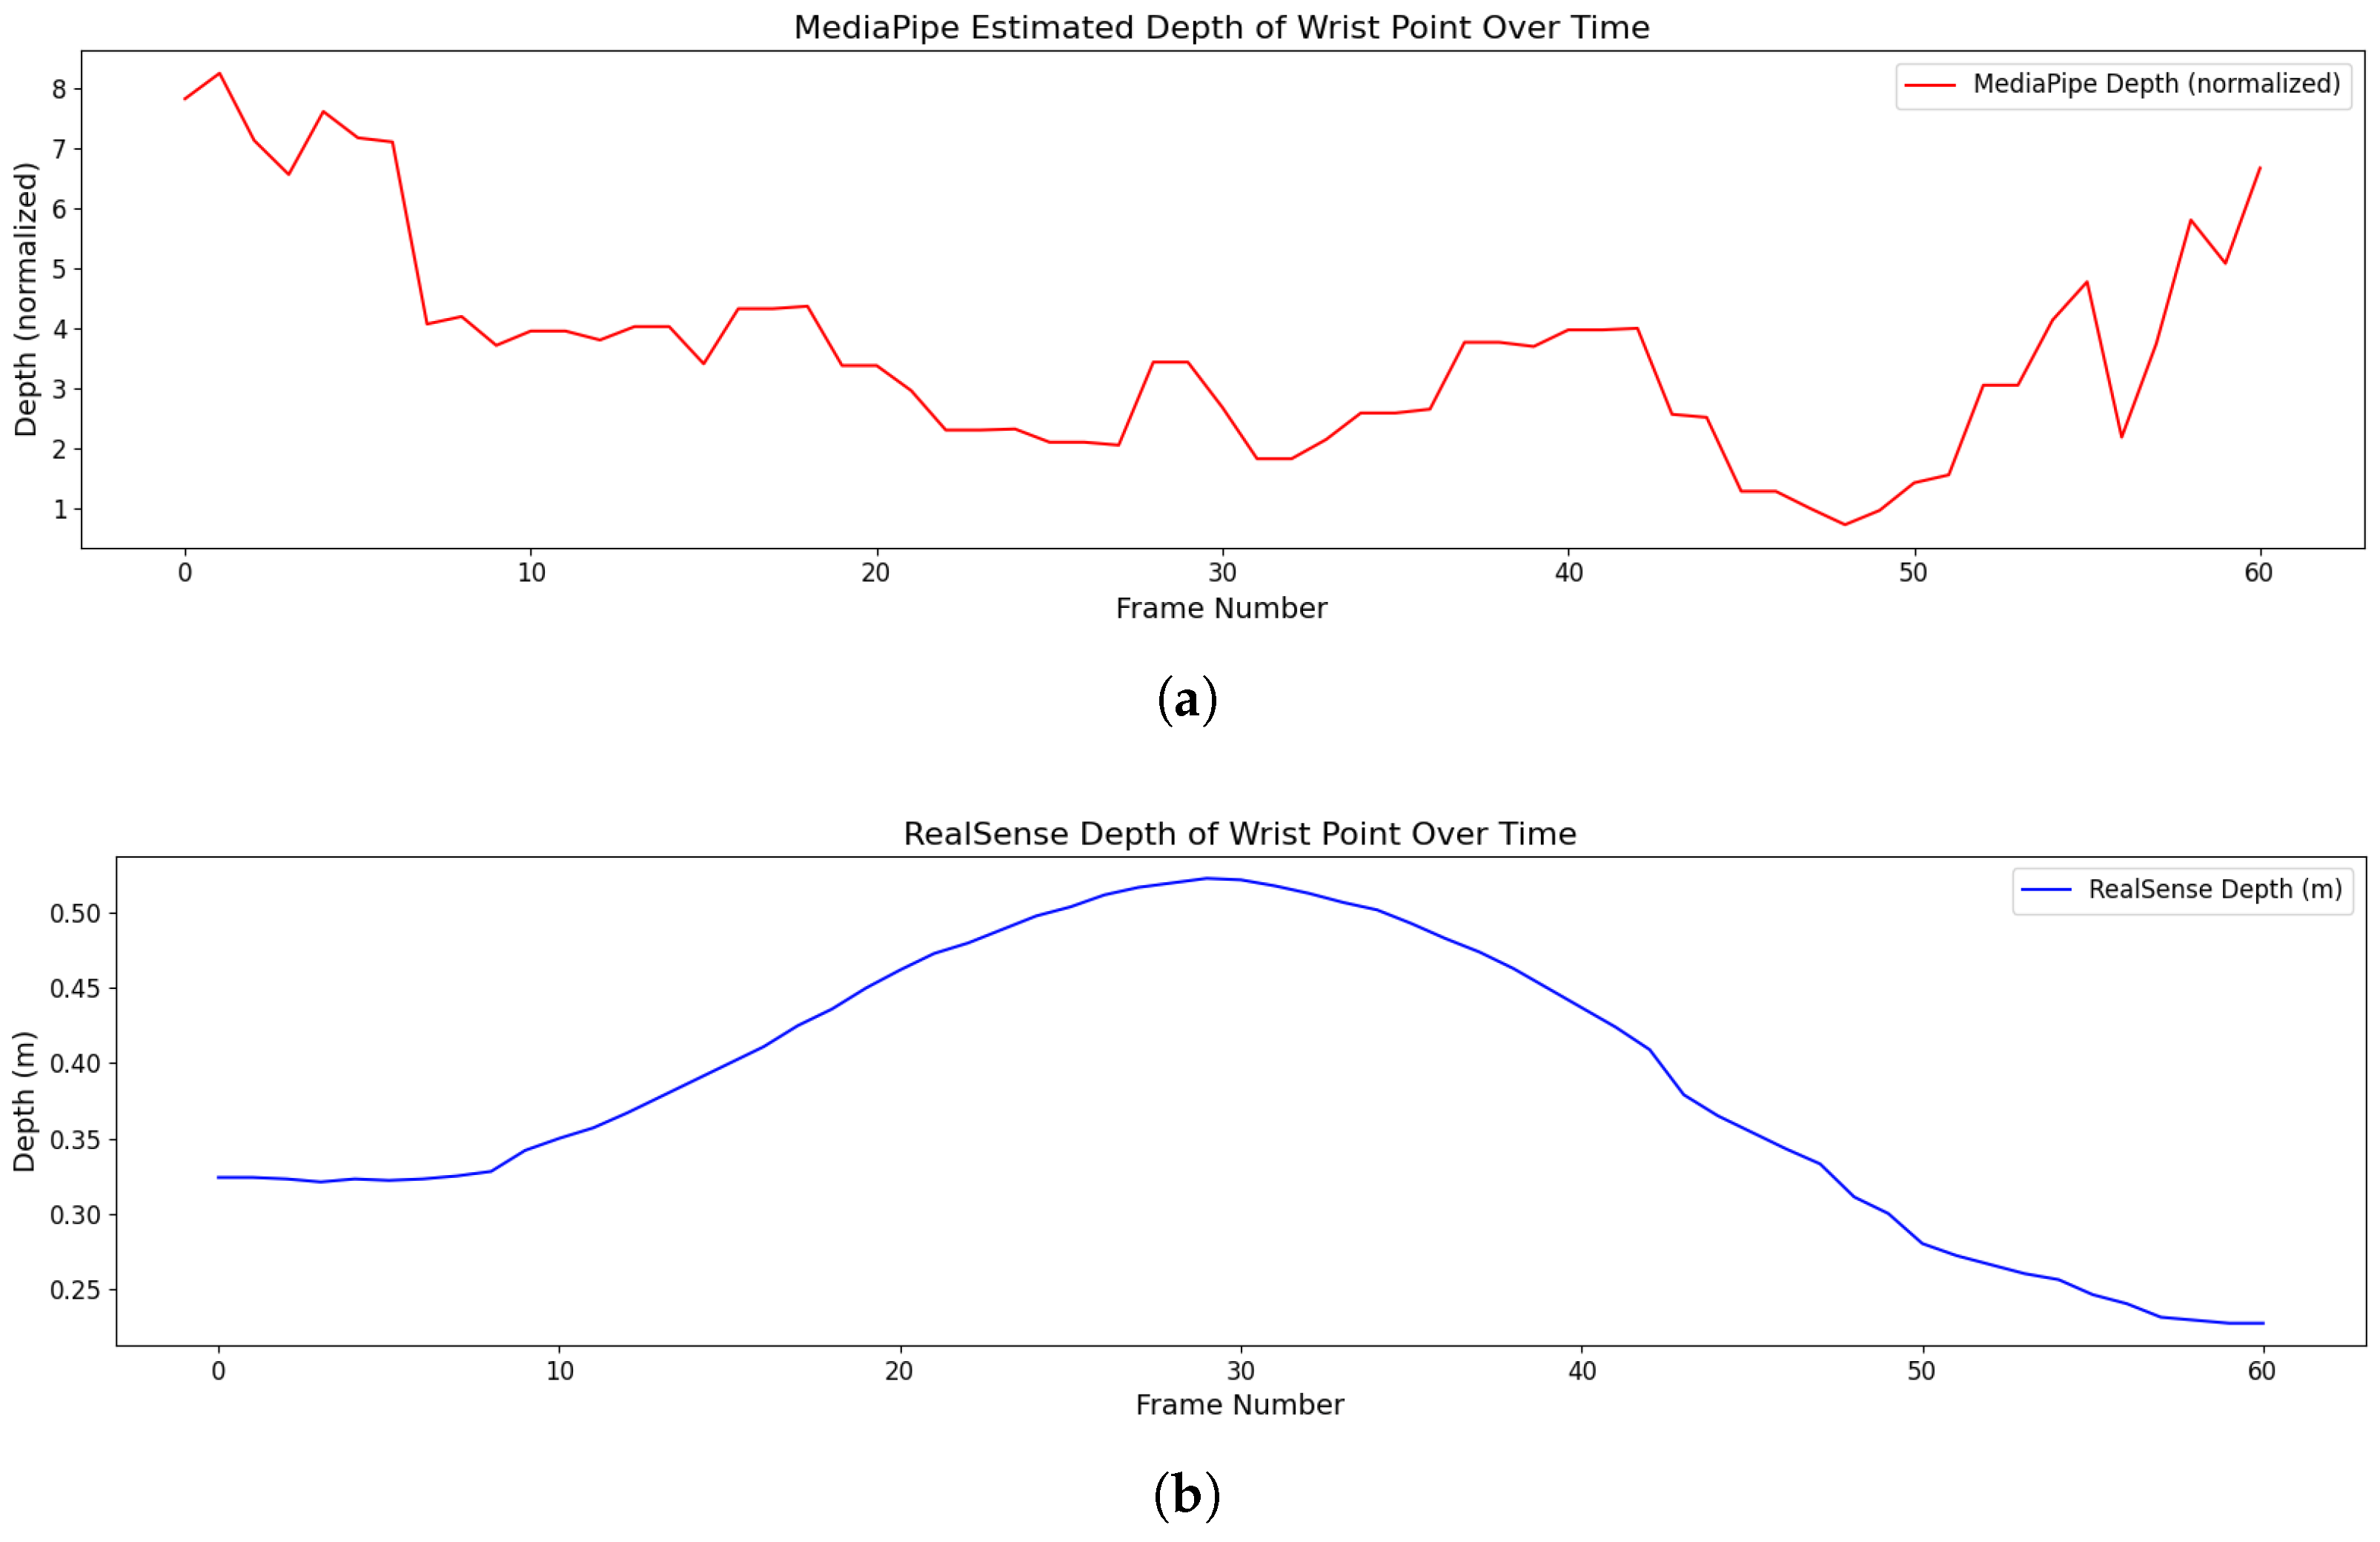
As can be seen in Figure 2a, the estimated depth values of the tracked landmarks provided by MediaPipe algorithm are not consistent. To remedy this inconsistency, we have utilized an RGB-D sensor which can offer a calibrated depth or distance of the measured landmarks with respect to the sensor frame. Comparing the results of Figure 2b with Figure 2a, the advantages of utilizing an additional sensing modality which can be fused with the information obtained from the MediaPipe tracking algorithm can be observed (See Appendix A). In addition, since MediaPipe’s depth estimation is not calibrated to real-world physical units, this renders it ineffective for fulfilling the objectives of this paper.
Figure 2.
Comparison of depth values (a) estimated by MediaPipe and (b) measured by RealSense D435 sensor for wrist point (landmark 0) over time.
This integration replaces the relative depth estimates from the MediaPipe Hand model with the actual depth values obtained from the Intel RealSense RGB-Depth sensor (Intel Corporation, Santa Clara, CA, USA). The 2D pixel coordinates , initially estimated by MediaPipe, along with their corresponding depth values captured by the depth sensor, are converted into real-world 3D spatial coordinates using the camera’s intrinsic parameters—specifically, the focal lengths , , and the principal point offsets , (see Appendix A for further details on aligning the RGB image pixels with the depth buffer). Notably, in the RGB and depth buffers may differ and require calibration). This transformation enables the calculation of the accurate real-world 3D spatial coordinates and the ith hand landmark, with respect to the sensor. The conversion can be expressed mathematically as:
In the next section, we present a method on how to construct the kinematic model of the hand using the spatial information of these tracked landmarks. The overall kinematic model comprises the local root coordinate frame associated with the palm describing the position and transformation of the hand with respect to the world coordinate frame, i.e., the sensor coordinate, and a collection of coordinate frames and an associated transformation matrix describing the kinematic model of the finger with respect to the palm-coordinate frame.
3. Hand Kinematic Model Definitions
In this section, we present an approach for constructing the kinematic model of the hand based on the spatial landmarks’ tracking information. We first define the kinematic world coordinate frame, according to which all the coordinates of the hand landmarks are measured. The definition of the origin of the local hand coordinate frame based on the landmark definitions of MediaPipe is presented in Section 3.2, followed by definitions of hand kinematic parameters presented in Section 3.3.
3.1. The World-Frame Definition
When we are defining a model for a moving hand within a three-dimensional space, two primary parameters are necessary for describing the state of the hand at any given time, namely position and orientation. The description of these parameters is inherently relative, as both the position and orientation of an object such as the whole hand is always referenced with respect to the origin and three pre-defined orthogonal axes of a fixed universal (world) coordinate frame, also referred to as the global frame.
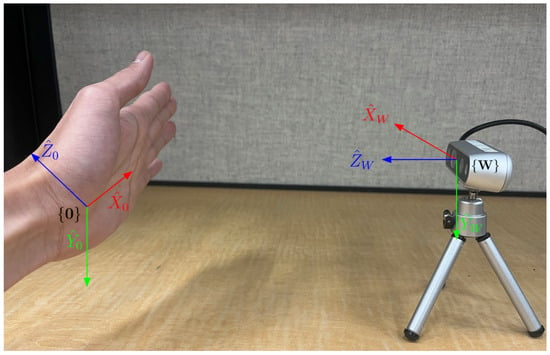
By convention, the world frame, denoted by , is usually attached to a non-moving object, thereby enabling all hand movements to be described with respect to it. In this paper, the sensor frame, located at the center of the sensor, is adopted as the world frame, as is shown in Figure 3.
Figure 3.
An example of principal axes of the local wrist frame (attached to the hand) and the world frame (attached to the sensor).
We denote the unit vectors representing the three principal directions of the world frame as , and . To align with the 2D image-frame systems, where pixel coordinates originate from the upper-left corner, axes and are oriented to the right and downwards, respectively. This alignment simplifies the process of mapping 2D image pixels to 3D real-world coordinates using physically calibrated measurable quantities (see Appendix A). Finally, using the right-hand rule, we establish that the axis points from the sensor toward the objects, which aligns with the depth data measurement, representing the distance between the hand and the sensor.
3.2. Definitions of Hand Hierarchical Coordinate Frames
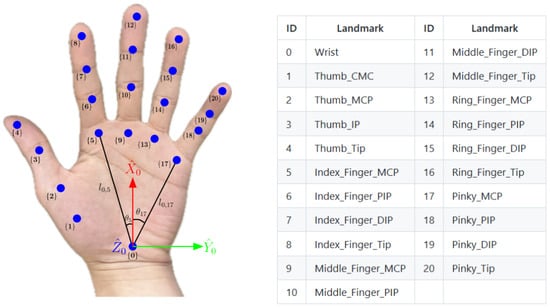
In the world coordinate frame , the hand’s position can be located, and further the rotational joint angle of each finger joint can be described by defining local (or relative) coordinate frames. The wrist frame , which is affixed to the wrist of the hand with origin defined at the wrist landmark is define relative to the world frame. While the definition of this relative coordinate frame is arbitrary, as shown in Figure 4, we define the of the wrist frame to be aligned with the general direction of finger flexion; the unit vector is oriented from the wrist towards the root of the middle finger, while is orthogonal to the palm plane defined by the other axes, resulting in a direction that points towards the back of the hand by assuming that the front of the hand faces the sensor.
Figure 4.
Hierarchical local frames to and parameters of the hand palm.
The kinematic model of the hand is based on 21 landmarks, including 1 root (the wrist) and 20 links (phalanges) across the five fingers. Each link is assigned a corresponding local frame, allowing for a description of the position and rotation of each link.
This model employs a hierarchical structure of local frames corresponding to anatomical joints. As shown in Figure 4, the first layer includes local frames , , , , and at the metacarpophalangeal (MCP) joints, defined with respect to the root frame . The second layer consists of local frames , , , , and at the proximal interphalangeal (PIP) joints, defined relative to the first layer. Similarly, frames , , , , and at the distal interphalangeal (DIP) joints form the third layer. Finally, the fourth layer comprises frames , , , , and at the fingertips.
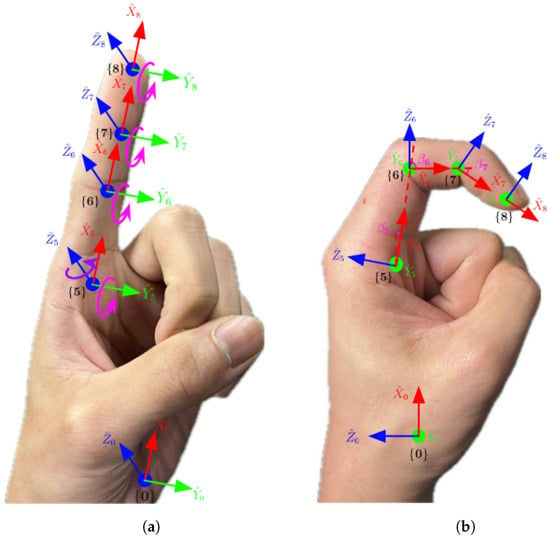
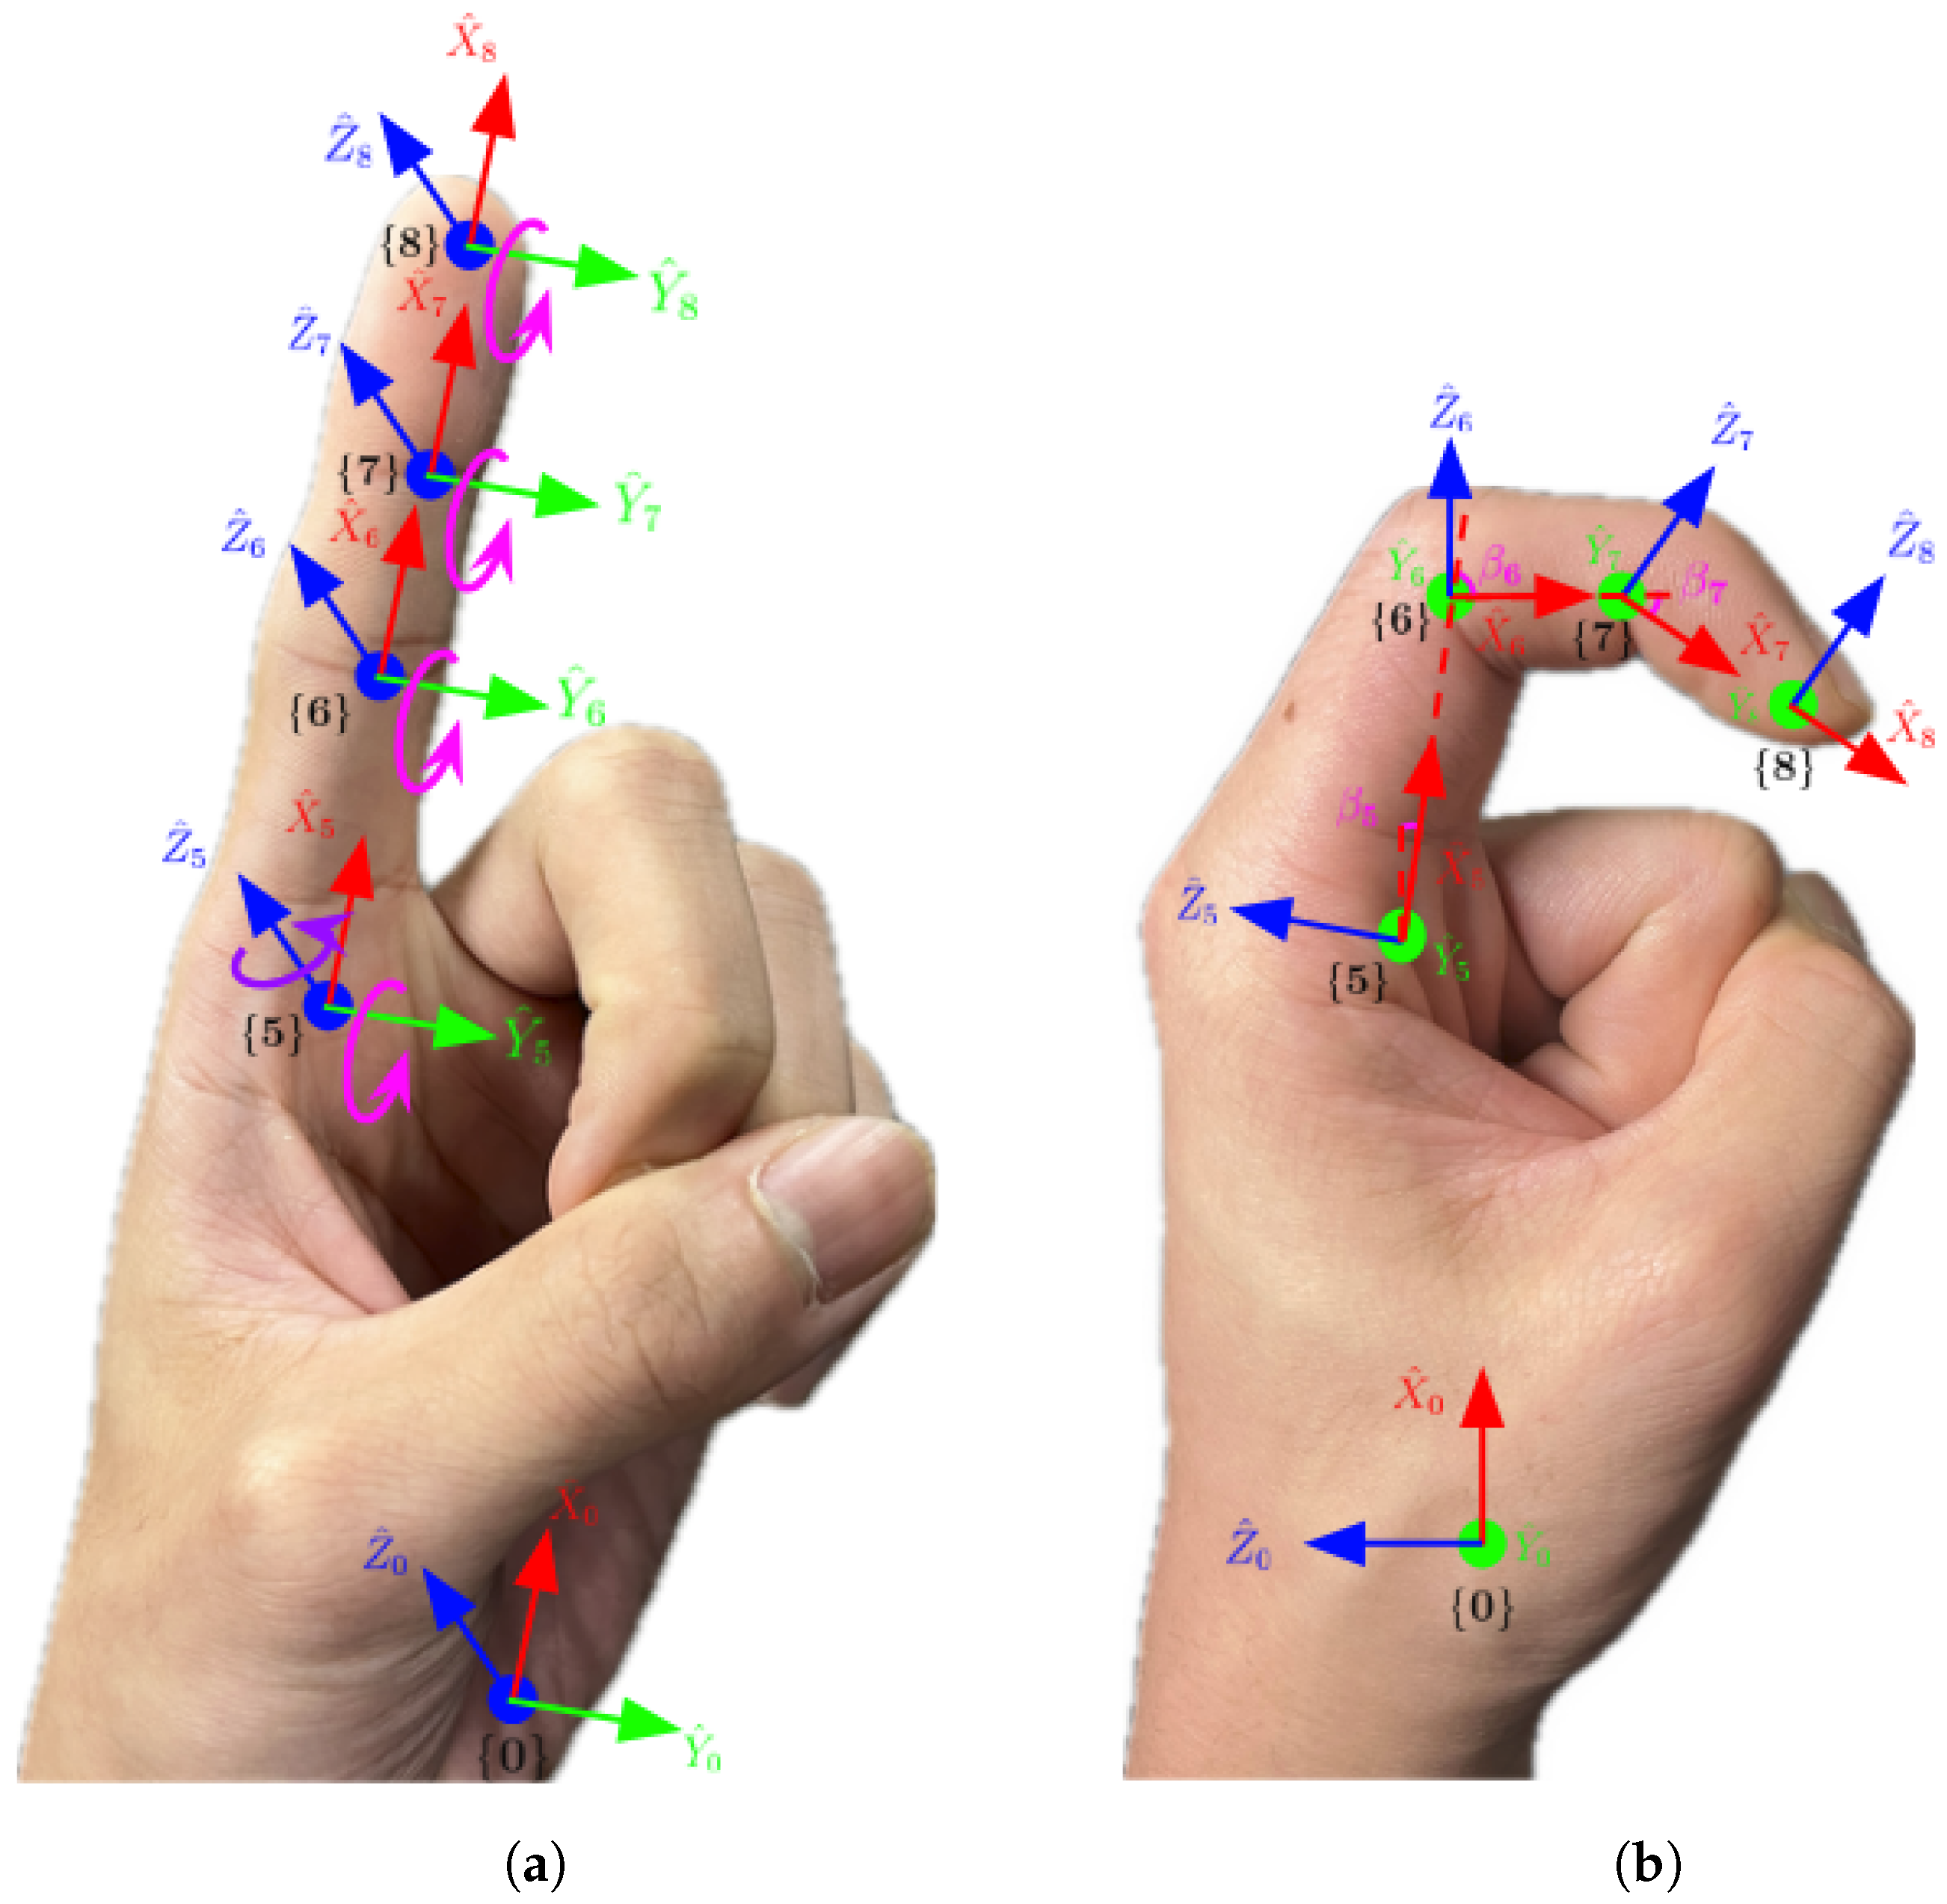
Each metacarpophalangeal (MCP) joint, or finger root, possesses two degrees of freedom (DOF), enabling it to flex and extend (bend up and down) as well as abduct and adduct (move side to side). When the root of a finger is fixed, and the finger is bent up and down, the proximal interphalangeal (PIP) and distal interphalangeal (DIP) joints each exhibit one DOF. Consequently, the workspace (the area the fingertip can reach) of a finger is a two-dimensional plane. Each of the five fingers can thus be modeled as a kinematic chain comprising three links connected by three revolute joints, with parallel rotation axes. The axes of the local frames for each finger align with the axes of the revolute joints, pointing to the page, as illustrated in Figure 5. The axes for each of the three joints orient towards the origin of the subsequent frame. For example, along the index finger, points to the origin of local frame , to the origin of local frame , and to the origin of local frame . Note that since is located at fingertip and has no DOF, aligns with . The axes of the local frames are assigned using the right-hand rule. This layered approach effectively models the intricate kinematic structure of the human hand. Although the present approach primarily includes grasping and natural resting poses, the model is capable of representing a wider range of joint configurations.
Figure 5.
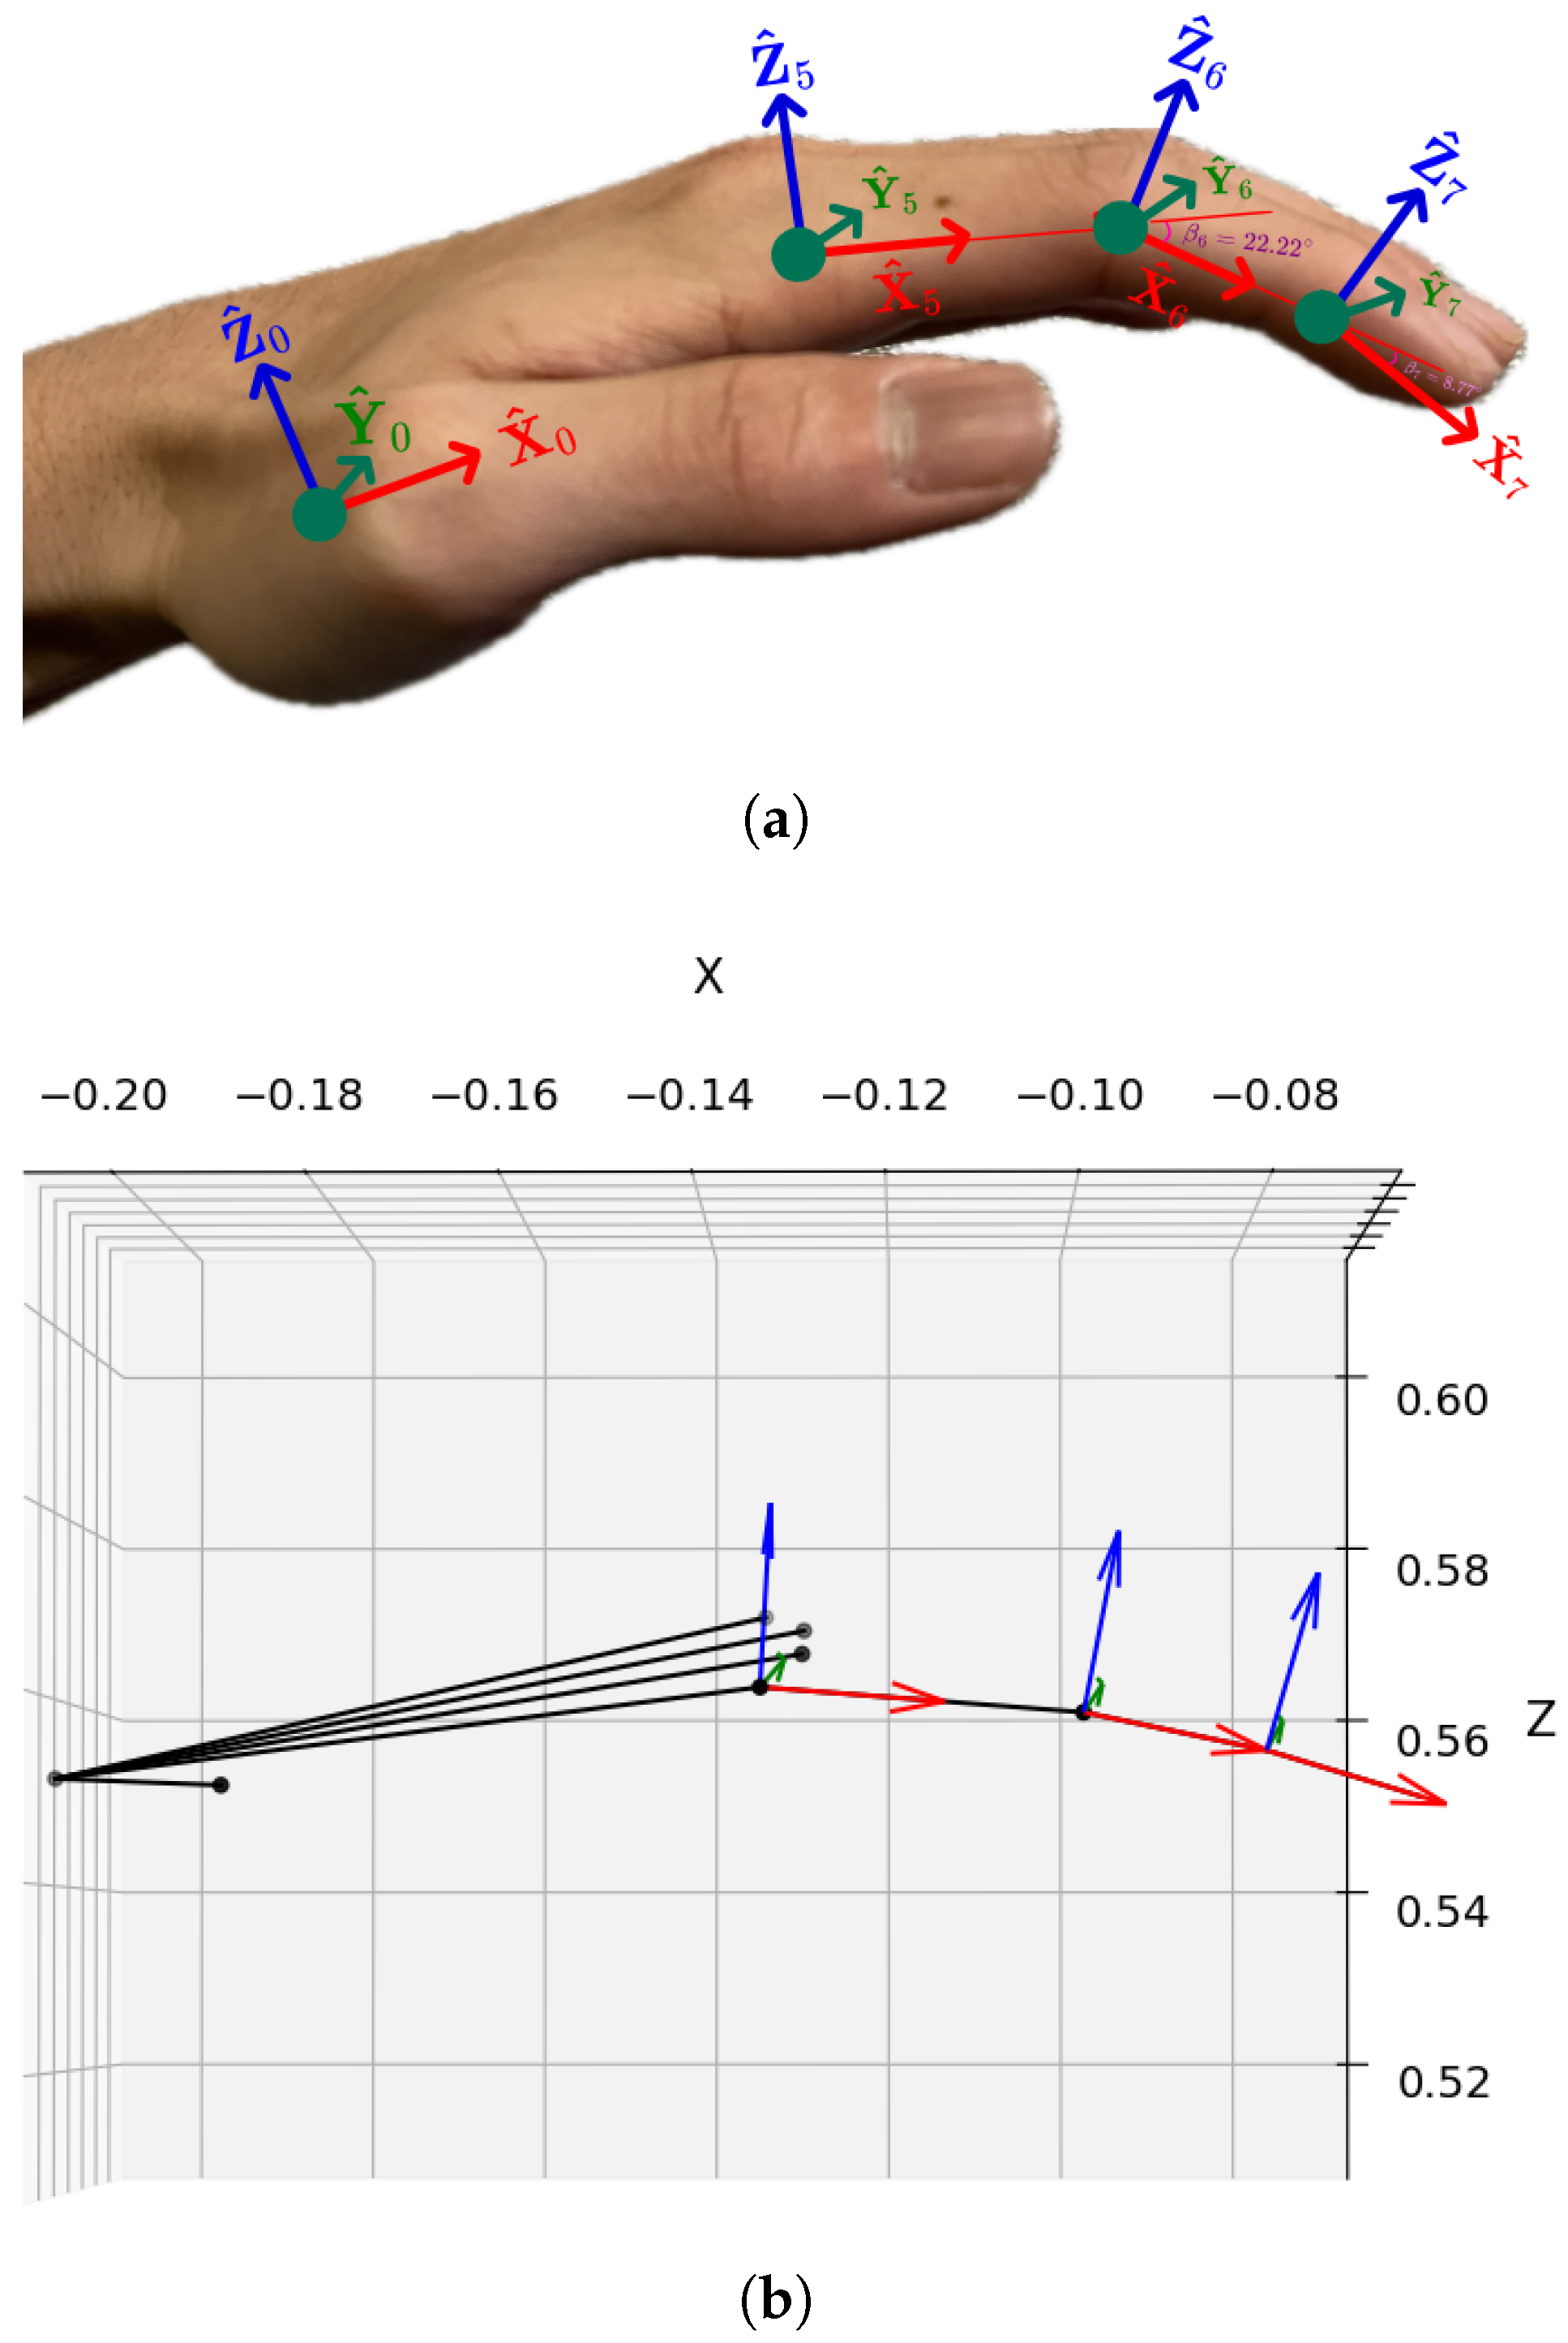
Assignments of local frames to on the index finger. (a) A frontal view (with slight rotation offset) of a straight index finger. (b) lateral view of a bent index finger.
3.3. Hand Kinematic Parameters
Kinematic modeling involves a mathematical framework to represent the motion properties of a system such as a robot or a human hand, without considering the forces that cause the movements. It provides a way to describe, for example, the positions and orientations of the interconnected segments or links within the structure relative to each other and fixed world frame. This model is essential, for example, in understanding and predicting how joint movements translate into overall hand movement.
In this context, forward kinematics refers to the process of calculating the positions and orientations of the fingertips and intermediate links of the hand relative to the wrist and the world frame, given known joint angles and the fixed kinematic parameters of the hand. This computation starts from the base frame (e.g., the wrist) and propagates outward through the hand kinematic chain. On the other hand, inverse kinematics focuses on determining the joint angles needed to achieve a specific kinematic configuration of the hand.
In this subsection, we define the parameters of the kinematic model for the palm and fingers. The next section presents methods to resolve these kinematic model parameters for the hand using data collected from the MediaPipe Hand model and the RGB-D sensor.
Palm Parameters:In this paper, we represent the model of the palm as a planar structure in three-dimensional space. We assume that the wrist and the roots of the five fingers lie on a single plane, specifically the xy-plane of the local frame . A set of 16 parameters are defined, where the initial six parameters are time-varying while the five length and five angle parameters are assumed to be constant:
- Position Parameters: The position vector specifies the distance of translation between the origins of the wrist frame and the world frame along , and , respectively.
- Orientation Parameters: The orientation of the local frame is defined by the Euler angles ; these angles describe the sequential rotations around axes , , and .
- Base Length Parameters: The lengths represent the fixed distances between the origin of the local frame and the origins of local frames , , , , and . These measurements, in centimeters, are spatial relationships between the wrist and finger roots.
- Angle Parameters: The angles describe the rotational offset between the axis and the axes , , , , and , respectively. These angles, measured in radians, are pivotal for capturing the hand’s natural articulation around the axis.
Parameters of Fingers: As shown in Figure 5, each finger requires three length parameters (as constraints) and four angle parameters (between 0 to 90 degrees) to define its pose, amounting to a total of 35 parameters for all five fingers:
- Base-Length Parameters: A set of 15 parameters determines the fixed lengths of the three links , and , within each finger, where :
- Angle Parameters for Finger Roots: A set of 10 parameters describes five pairs of rotation angles and around axes and for the root joints of each finger, where :
- Angle Parameters for Other Joints: A set of 10 parameters describes five pairs of rotation angles and for the PIP and DIP joints around corresponding of each finger, :
4. Hand Hierarchical Transformations
To effectively track human-hand movements and reconstruct its corresponding kinematic representation for graphical reconstruction, it is essential to represent the position and orientation of each joint’s local coordinate frame in 3D space and the corresponding joint parameters of each finger. We introduce a systematic approach for resolving these parameters through transformations between adjacent coordinate frames. The input parameters are spatial coordinates of 21 hand landmarks provided by the MediaPipe through RGB-D sensor, which are position parameters of each origin of the local frame with respect to world frame , denoted as vector for , (Section 3.1). Table 1 shows the representation of these measured 3D spatial coordinates for each joint of the thumb, index, middle, ring, and little fingers.
Table 1.
Measured 3D spatial coordinates of 21 hand landmarks (in meters).
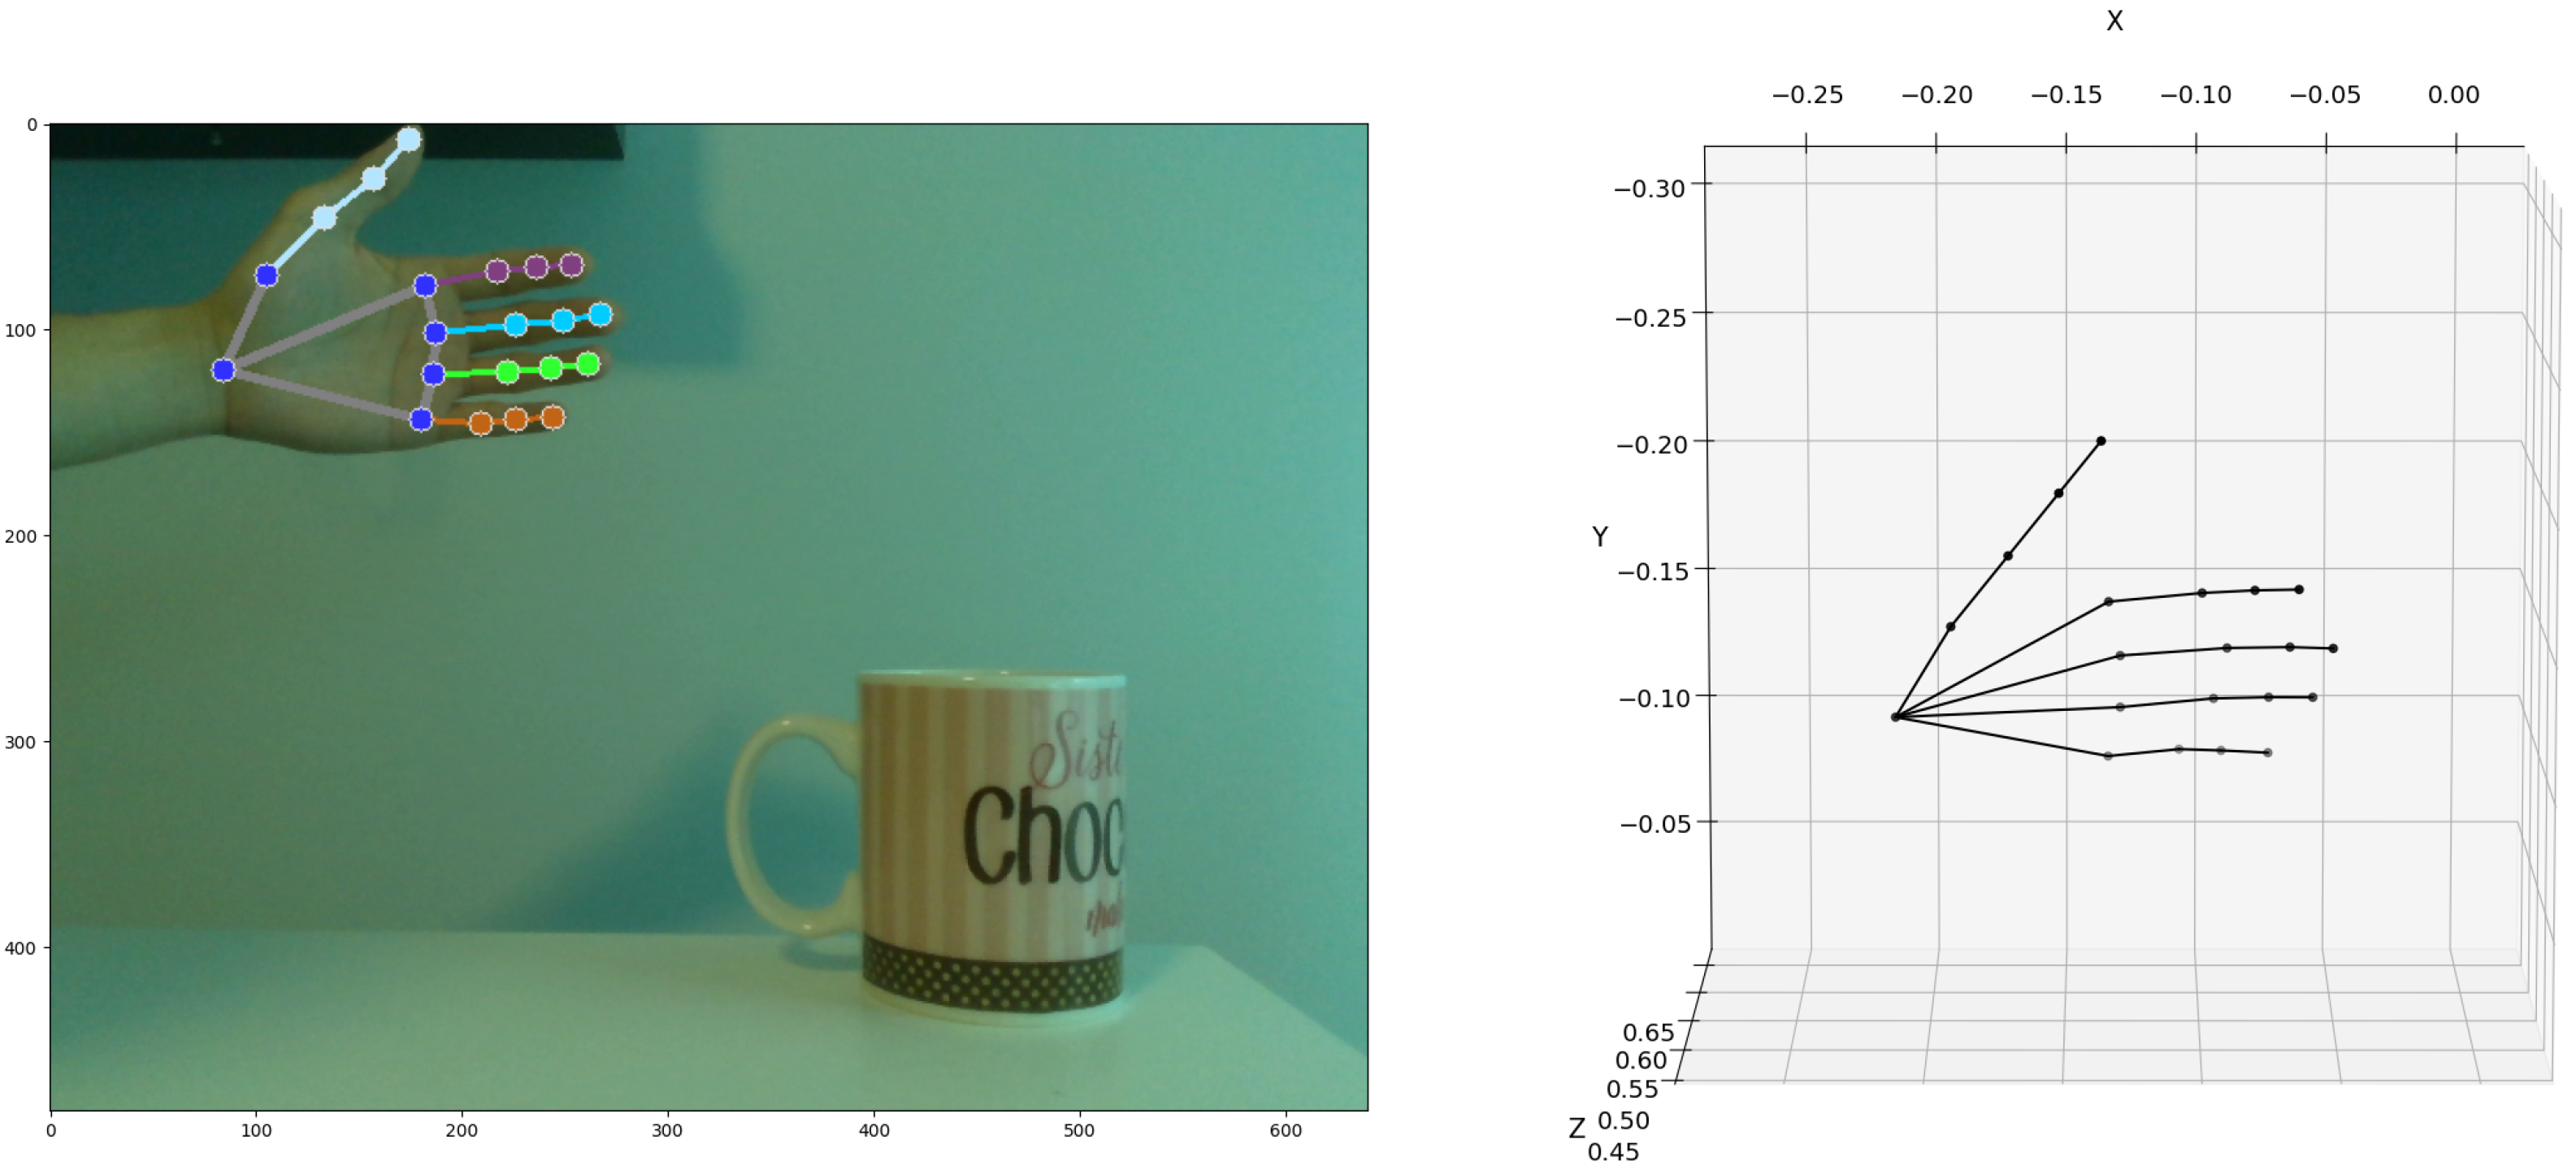
Figure 6 shows the 2D hand-tracking data and the corresponding raw 3D calibrated measured data reconstruction. On the left, the RGB image shows a hand in a front-facing position, where key hand landmarks are tracked using the MediaPipe framework. These landmarks are accurately projected onto the image plane, ensuring comprehensive coverage of all joint locations. On the right, we visualize the 3D point cloud of these landmarks using depth data from an RGB-D sensor. The depth values associated with each landmark are mapped to their respective x and y coordinates derived from the MediaPipe are mapped to the depth buffer (Appendix A).
Figure 6.
A visualization of the 2D pixels of MediaPipe hand tracking and 3D spatial points.
Table 2 provides the 3D hand landmark data in meters relative to the world frame, where the origin is aligned with the RGB-D sensor. The positive x-axis extends to the right, the positive y-axis points downward, and the z-axis represents the depth from the sensor.
Table 2.
An measured example of 3D spatial coordinates of 21 hand landmarks.
It is important to note that the fixed-length parameters used in this study are derived from the physical measurements of a single individual. While this enables precise modeling for a given user, the approach does not capture variability in hand sizes or joint constraints across the population. As such, unrealistic joint configurations may arise if this model is applied directly to users with different hand geometries. Future work will explore methods to generalize the model by incorporating user-specific calibration procedures or employing learning-based techniques to estimate anatomical parameters from motion data.
In the following section, we present a numerical example illustrating the process of resolving parameters for hierarchical transformations in the index finger after each transformation definition.
4.1. Resolution of Palm-Coordinate Frame
In this subsection, we present the method for computing the palm’s orientation and position which is used as the hand local coordinate system at .
Position Parameters:The position vector , directly measured from Mediapipe and the RGB-D sensor, specifies the distance of translation between the origins of the wrist frame and the world frame along , , and , respectively. For example, the position vector:
indicates that the wrist landmark is located 0.21 m to the left, 0.11 m above the sensor, and 0.54 m away from the sensor, as measured by the MediaPipe through calibrated RGB-D measures.
Orientation Parameters: In the kinematic model of the hand, the orientation of the palm is with respect to the world frame is parameterized by three degrees of freedom (DOF). Let , , and represent rotations about axes , , and , respectively, where , , and denote the corresponding rotation angles. Given the set of Euler angles , the orientation matrix of the wrist frame can be computed by converting the Euler angles to a rotation matrix:
where each column of denotes the principal directions of the wrist frame in terms of the world frame . This matrix encapsulates the wrist’s orientation in the global coordinate system.
To resolve the palm’s orientation parameters, we first define the of the wrist frame as the normalized vector between landmark 5 (base of the index finger) and landmark 13 (base of the ring finger). These two landmarks provide a consistent reference indicator for of the construction of the palm’s orientation matrix, or:
Next, we define the as the normal vector to the above defined palm plane. We define this vector through selection of two vectors: one from landmark 0 (wrist) to landmark 9 (base of the middle finger) and as:
Finally, the unit vector is determined using the right-hand rule, ensuring a consistent and orthogonal coordinate construction:
Given the description of in terms of the palm landmarks, the parametrization of the hand orientation with respect to the world frame can be described using three Euler angles , which can be obtained through inverse calculation as:
Given the position vector of the hand wrist as , the position and orientation of frame are determined. We represent the final pose matrix of the palm using a homogeneous transformation matrix:
Given the above resolved palm-coordinate frame from the landmark data, we can construct the homogeneous transformation matrix of the palm-coordinate frame located at landmark with respect to the world frame as:
Figure 7.
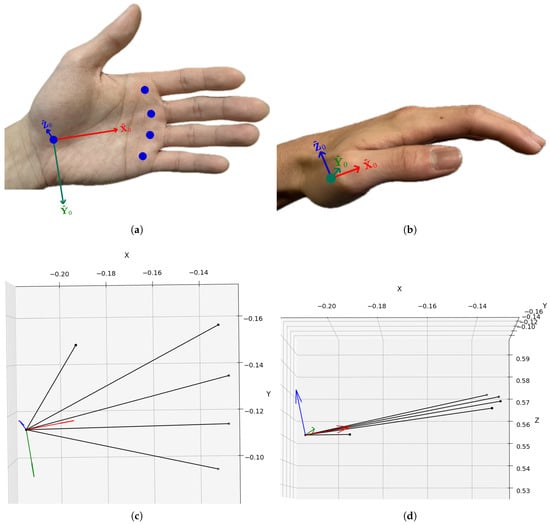
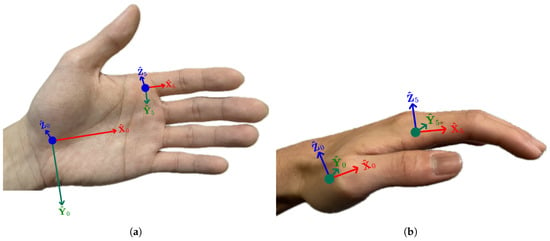
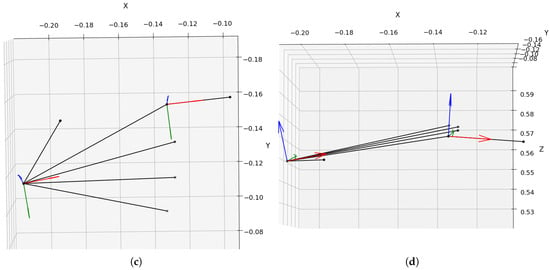
An example of the coordinate of palm frame located at landmark . (a,c) Frontal view (demonstrates a slight counter-clockwise rotation of the hand around ). (b,d) Side view (demonstrates a counter-clockwise rotation () around and a slight clockwise rotation around the ).
When comparing these values to Figure 3, the negative value of can be attributed to the slight counter-clockwise rotation of the hand around . This can be verified by comparing the y-coordinates of landmarks 0 and 9, where and , indicating an upward shift. Similarly, the negative value of corresponds to a slight counter-clockwise rotation around (pointing downward), which is corroborated by comparing the depth values of landmarks 0 and 9: and . Additionally, by checking the depth values of the index-finger root () and little-finger root (), we conclude that the hand exhibits a slight clockwise rotation around the , as indicated by the positive value of the corresponding angle.
Base-Length Parameters: The base lengths represent the distances between the origin of the local frame and the origins of local frames , , , , and at the first layer. These measurements, in centimeters, are computed by:
Using Equation (13), we compute the distances between the wrist and each of the finger-base landmarks. These lengths are critical for defining the spatial relationships between the wrist and finger joints, which are fundamental for kinematic modeling and inverse kinematic calculations. The results are expressed both in meters and centimeters for clarity:
These values quantify the distances from the wrist landmark to the base joints of the thumb (), index finger (), middle finger (), ring finger (), and little finger ().
Angle Parameters: The angles describe the rotational offset between the axis and the axes , , , , and , which correspond to the bases of the thumb, index, middle, ring, and little fingers, respectively. Since we assume that local frames of the first layer for each finger, , , , , and lie within the -plane of the wrist frame , the relative positions of these frames with respect to , denoted by , can be expressed as:
Here, is computed by Equation (13) and is the angle that describes the rotation required to align each finger’s base frame with the wrist frame. To compute the angles , we can use Equation (15) to match the observed positions of the finger-base landmarks relative to the wrist in the world frame. Specifically, given the known measured coordinates of landmarks in the world frame , we can map these coordinates into the local wrist frame . This transformation is achieved by applying the inverse of the transformation matrix , which encodes the position and orientation of the wrist frame relative to the world frame:
In the local wrist frame, the transformed positions are parameterized as given in Equation (15). We can solve for as:
where and are the x- and y-components of the transformed vector .
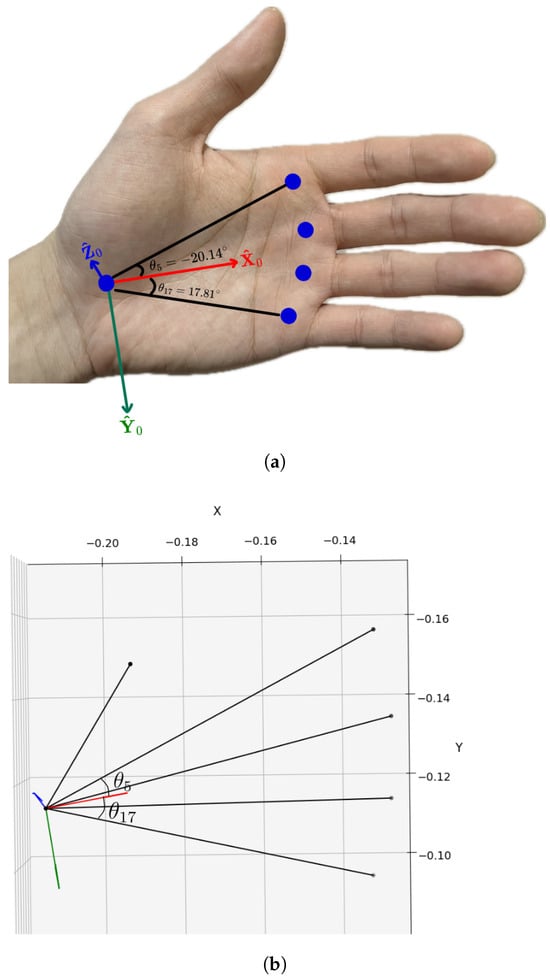
Given Equations (16) and (17), we calculate the angular parameters for the fingers relative to the wrist frame (Figure 8). By transforming the world coordinates of each finger base into the wrist coordinate frame, we can compute the corresponding angle parameters as follows:
Figure 8.
(a,b) Visualization of the computation for the angle parameters and which is a rotation around of the measured hand palm. (a) Palm frontal view and (b) its associated landmark coordinates representation.
4.2. Resolving Layered Parameters of Fingers in Hierarchical Transformations
In the kinematic model of the hand as introduced in previous section, the metacarpophalangeal (MCP), proximal interphalangeal (PIP), and distal interphalangeal (DIP) joints are organized within a hierarchical structure. Each joint’s local coordinate frame is derived from its parent joint’s frame, establishing a consistent chain of transformations from the base of the finger to the fingertip. This section provides a comprehensive explanation of how the parameters for these hierarchical transformations are resolved, detailing how each joint’s movement is propagated along the kinematic chain to accurately model finger rotations.
First Layer (at MCP Joints): Each MCP joint has two DOF, enabling it to bend up and down and move side to side; five pairs of rotation angles and around axes and for the root joints of each finger are defined in the previous section. Thus, the orientation of local frames at MCP joints with respect to wrist frame can be expressed as:
To compute the angles and based on the rotation matrix , we can utilize the geometric relationship between these axes and the wrist frame’s axes. Along each of the five fingers, the axes for each of the three joints orient towards the origin of the next joint’s frame; therefore
Based on the kinematic model we defined, the axes of the local frames for each finger align with the axes of the revolute joints, which are perpendicular to both the corresponding and , the z-axis of the wrist. By computing the cross product of and , we get
Finally, the unit axes of the local frames at the first layer are calculated as the cross product of the corresponding and :
By integrating with the transformed position vectors , we obtain the transformations at the first layer:
and at the first layer can be extracted from the element in the third row, third column and the second row, second column of the rotation matrix in Equation (19):
Transformation to the First Layer of the Measured Index Finger: Based on Equations (19)–(24), the three principal unit vectors for the local frame at the root of the index finger can be derived as follows:
We then form the rotation matrix using these unit vectors:
The angle parameters at the index finger MCP joint can now be calculated as:
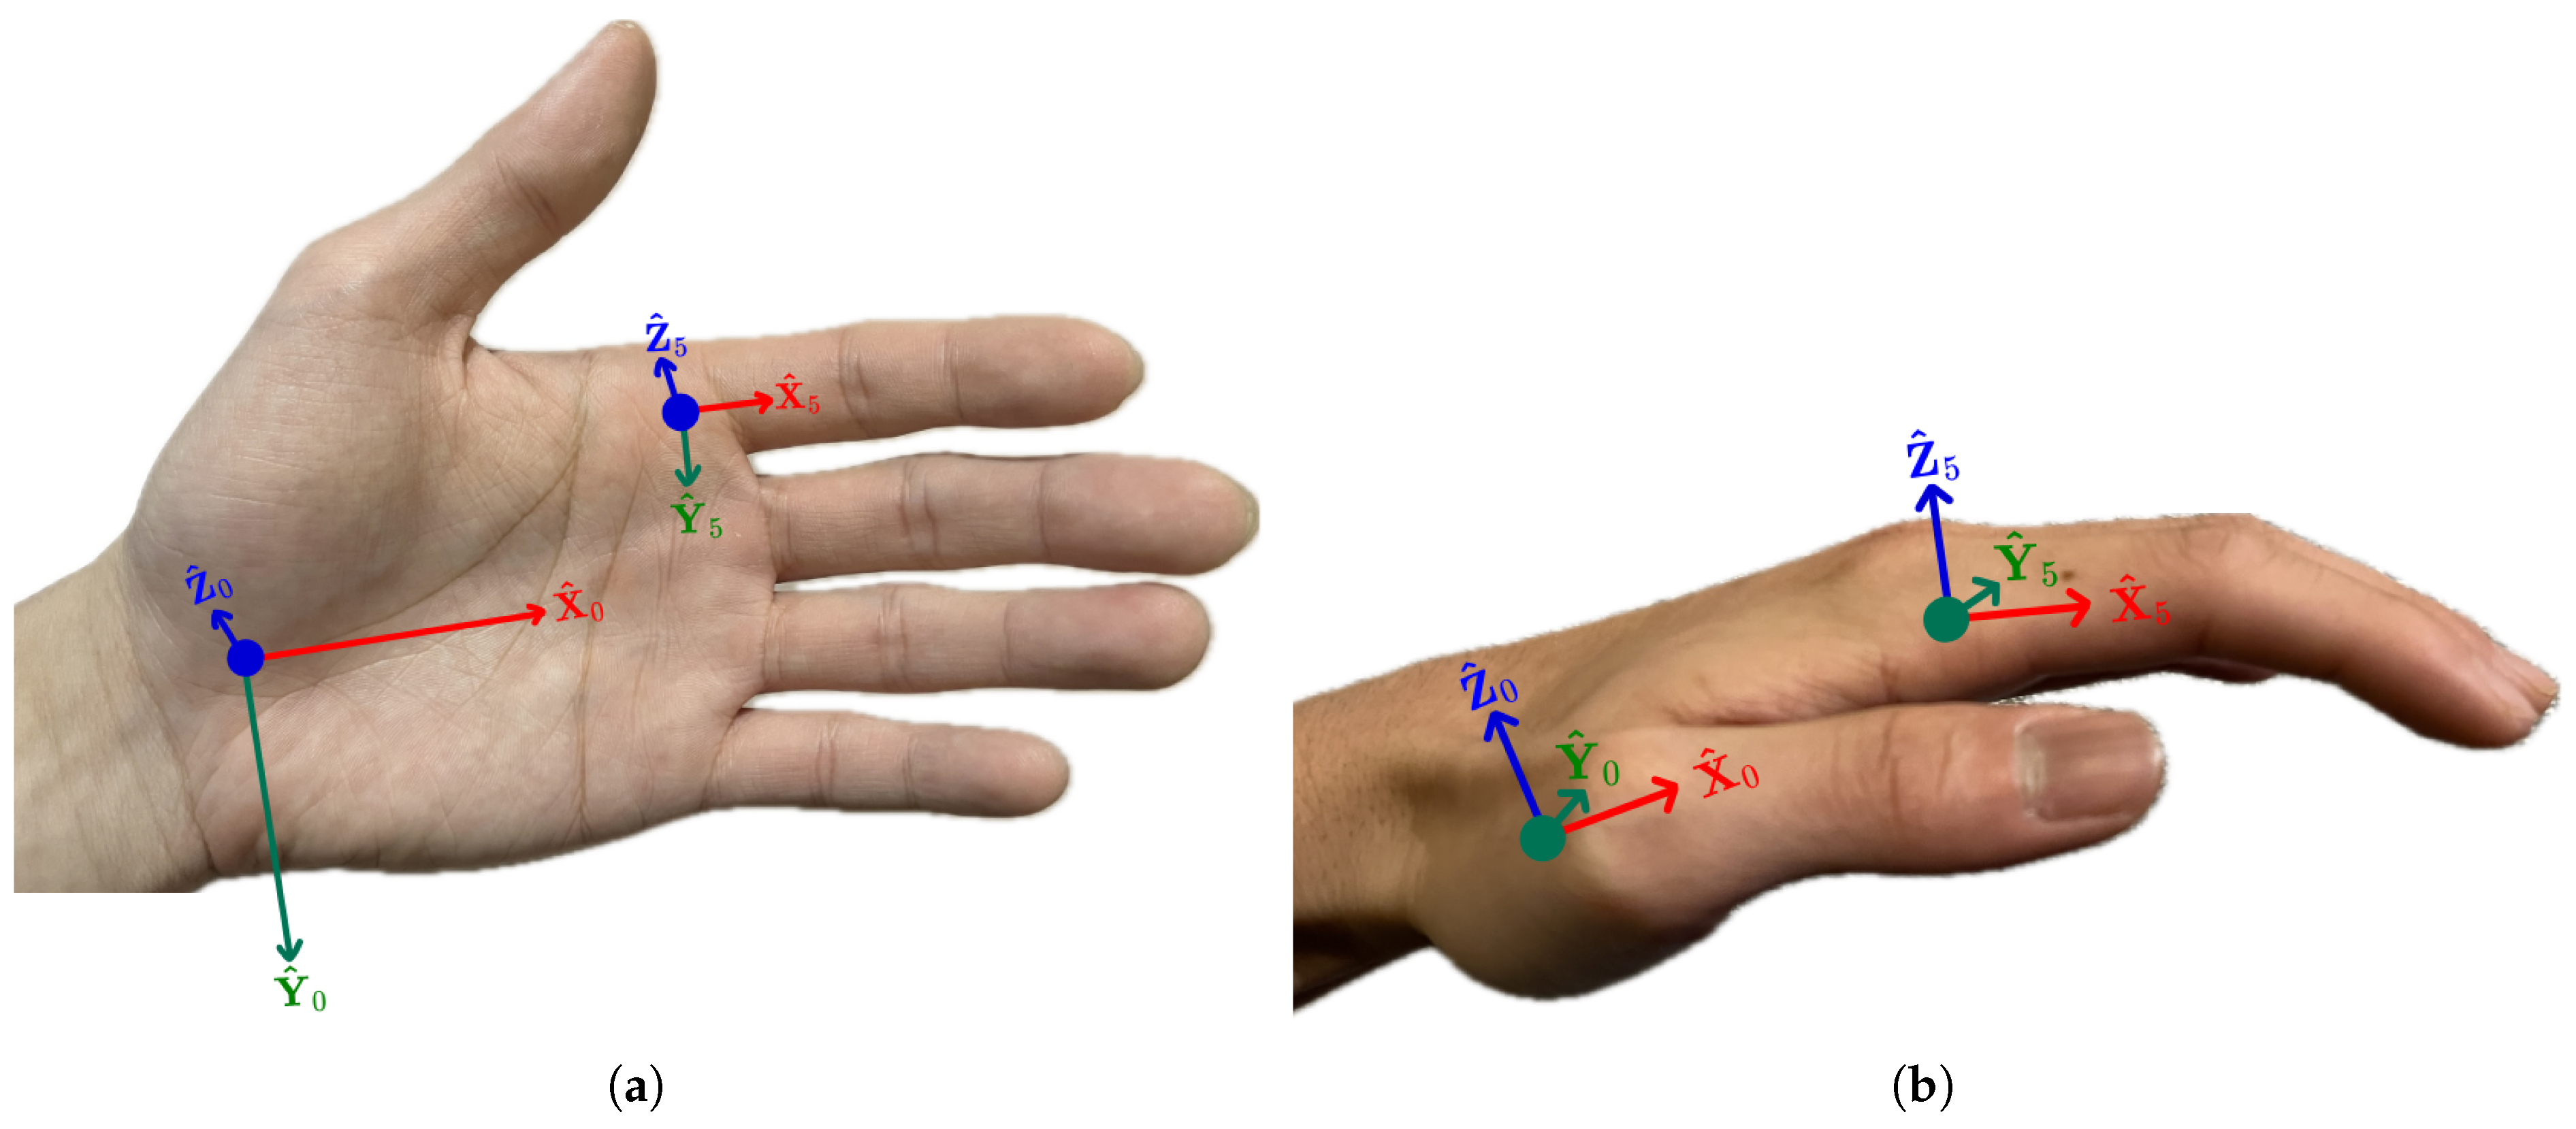
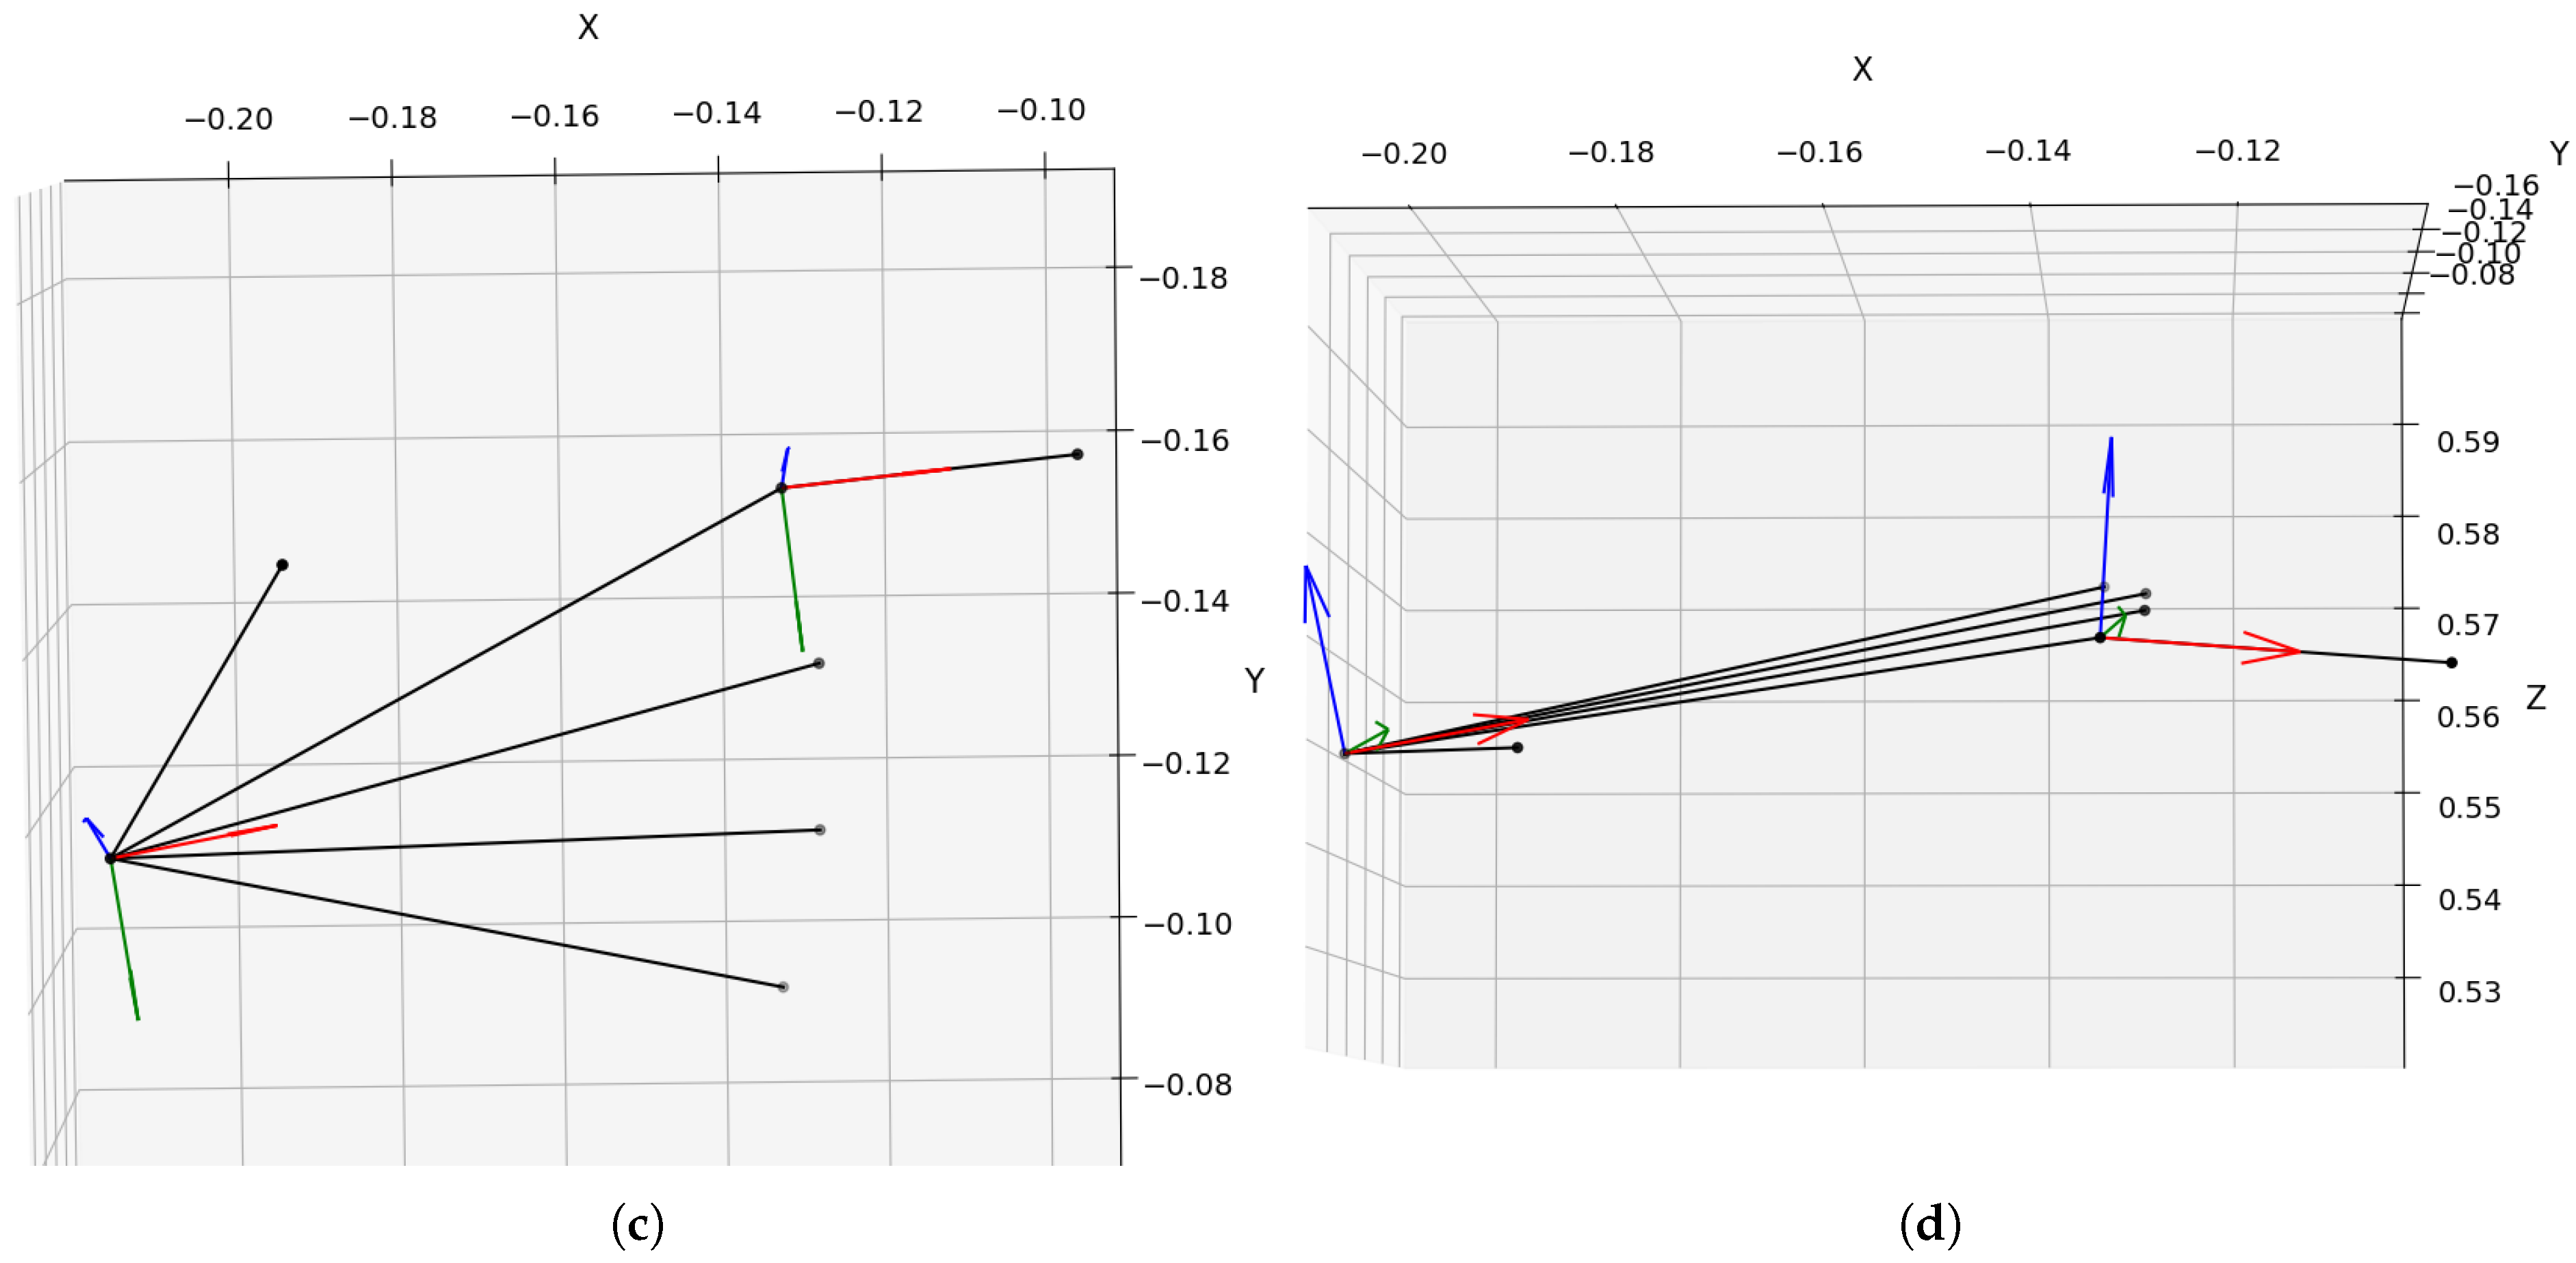
As shown in Figure 9, the local frame , corresponding to the index finger MCP joint, can be described by a rotation relative to the wrist frame first by about and then by about . Additionally, there is a translation of m along and m along . The transformation matrix that defines the relationship between the index finger root and the wrist frame can be expressed as:
Figure 9.
Axes of frames and of the palm. (a,c) frontal view (verifies a slight clockwise () rotation of the hand around ). (b,d) side view (verifies a clockwise rotation () around ).
This transformation provides the full description of the index finger’s MCP joint in relation to the wrist frame, accounting for both rotational and translational movements.
Second and Third Layer (at PIP and DIP Joints): Each of the five fingers can be modeled as a kinematic chain consisting of three links connected by three revolute joints, with parallel rotation axes. The PIP and DIP joints, which form the second and third layers of this chain, each possess a single DOF. Consequently, the rotation of each joint in these layers can be fully described by a single rotational parameter for the PIP joint and for the DIP joint, where . These angles represent the flexion-extension motions at the respective joints and are defined as the angle between and for the PIP joint and between and for the DIP joint.
Since all finger movements are considered locally within each kinematic chain, relative to the base frames of each finger root (i.e., , , , , and ), the rotation angles will be computed based on the relative orientations of the joints within the preceding joint’s frame:
where
Similarly, for the angle parameters at the third layer:
where
The orientation matrix of the local frame at joint j relative to its parent joint is given by:
Similarly, the orientation matrix of the local frame at joint (DIP joint) relative to joint j (PIP joint) is:
By integrating the translation vectors, the relative positions of the joints can be expressed as:
The complete transformations at the second layer (PIP joint) and the third layer (DIP joint) are then obtained as follows:
Transformations to the Second and Third Layer of the Measured Index Finger: Since all finger movements are modeled locally within each kinematic chain, relative to the base frames of each finger root, the rotation angles are computed based on the relative orientations of consecutive joints within the preceding joint’s frame. This hierarchical transformation approach ensures consistent rotational relationships between joints as they propagate along the kinematic chain.
First, the position vectors , and are calculated by transforming the parent wrist frame into the local frame of the base joint (the MCP joint of the index finger, ):
To compute the rotation angle at the second layer (PIP joint), we perform a scalar product of the position vectors relative to the local frames. The angle is derived as follows:
For the angle parameters at the third layer (DIP joint), the rotation angle is computed similarly to the previous layer. Using the relative orientations of the joints, we can express as follows:
Here, each of and represents the flexion at the PIP and DIP joint of the index finger, as shown in Figure 10.
Figure 10.
(a,b) shows axes of frames , and of the index finger, which confirms a natural clockwise rotation of and a slight clockwise rotation of around the parallel rotational axis at PIP joint and DIP joint).
The orientation of the local frame at the second joint (PIP joint) of the index finger relative to its parent joint (MCP joint) is represented by the matrix, which is defined by the rotation angle around the local -axis:
Similarly, the orientation matrix for the local frame at the third joint (DIP joint) relative to the second joint (PIP joint) is:
The translational displacements between consecutive joints are defined by the following translation vectors:
The complete transformation matrices at the second (PIP joint) and third layers (DIP joint) are constructed by combining the rotation matrices with the corresponding translation vectors. The transformation matrix from the MCP joint to the PIP joint is given by:
Similarly, the transformation matrix from the PIP joint to the DIP joint is:
Finally, note that the frame is located at the fingertip and, by design, has no degrees of freedom (DOF). As a result, the transformation matrix from joint (DIP joint) to the fingertip is a simple identity matrix with a translation vector representing the fixed length between joint and the fingertip . This is given by:
Since there is no rotation or additional degrees of freedom at the fingertip, this transformation matrix simply translates the local frame by the fixed length , which represents the distance between the DIP joint and the fingertip. This final transformation completes the kinematic chain of the index finger, preserving the hierarchical structure of the transformations from the MCP joint to the fingertip.
5. Kinematic of Hand for Graphical Reconstruction in Unity
After resolving the kinematic parameters of the hand model, we implemented a reconstruction of a simulated human hand in Unity. Unity’s advanced rendering capabilities enable realistic, interactive visualizations, which are essential for validating the accuracy of both the hand model and the reconstruction process. By reconstructing the hand’s movement from the kinematic data, we can analyze the accuracy of joint movements, finger articulation, and interactions with objects in a virtual environment. In this section, we detail the process of implementing a rigged hand model in Unity, the definition of local coordinate frames, and the conversion of kinematic model parameters into Unity’s coordinate system.
5.1. Unity Environment and Rigged Hand Model
Unity version 2022.3.5f1 (Long-Term Support) was used to implement and visualize the reconstructed kinematic hand model. A rigged avatar hand model with 16 joints (one wrist joint and three joints for each of the five fingers) was imported from the Unity Asset Store. Each joint in the model is controlled via local coordinate frames and arranged hierarchically to reflect the anatomical structure of the human hand.
Scripts written in C# were developed to update joint rotations in real time using computed kinematic parameters. The Unity camera was aligned to mimic the depth sensor’s viewpoint, ensuring that tracked and reconstructed hand movements were spatially consistent. Due to Unity’s use of a left-handed coordinate system, we explicitly inverted the y-axis and transformed all rotational parameters accordingly to match the right-handed sensor coordinate system defined in Section 3.
5.2. Left-Handed Frame in Unity
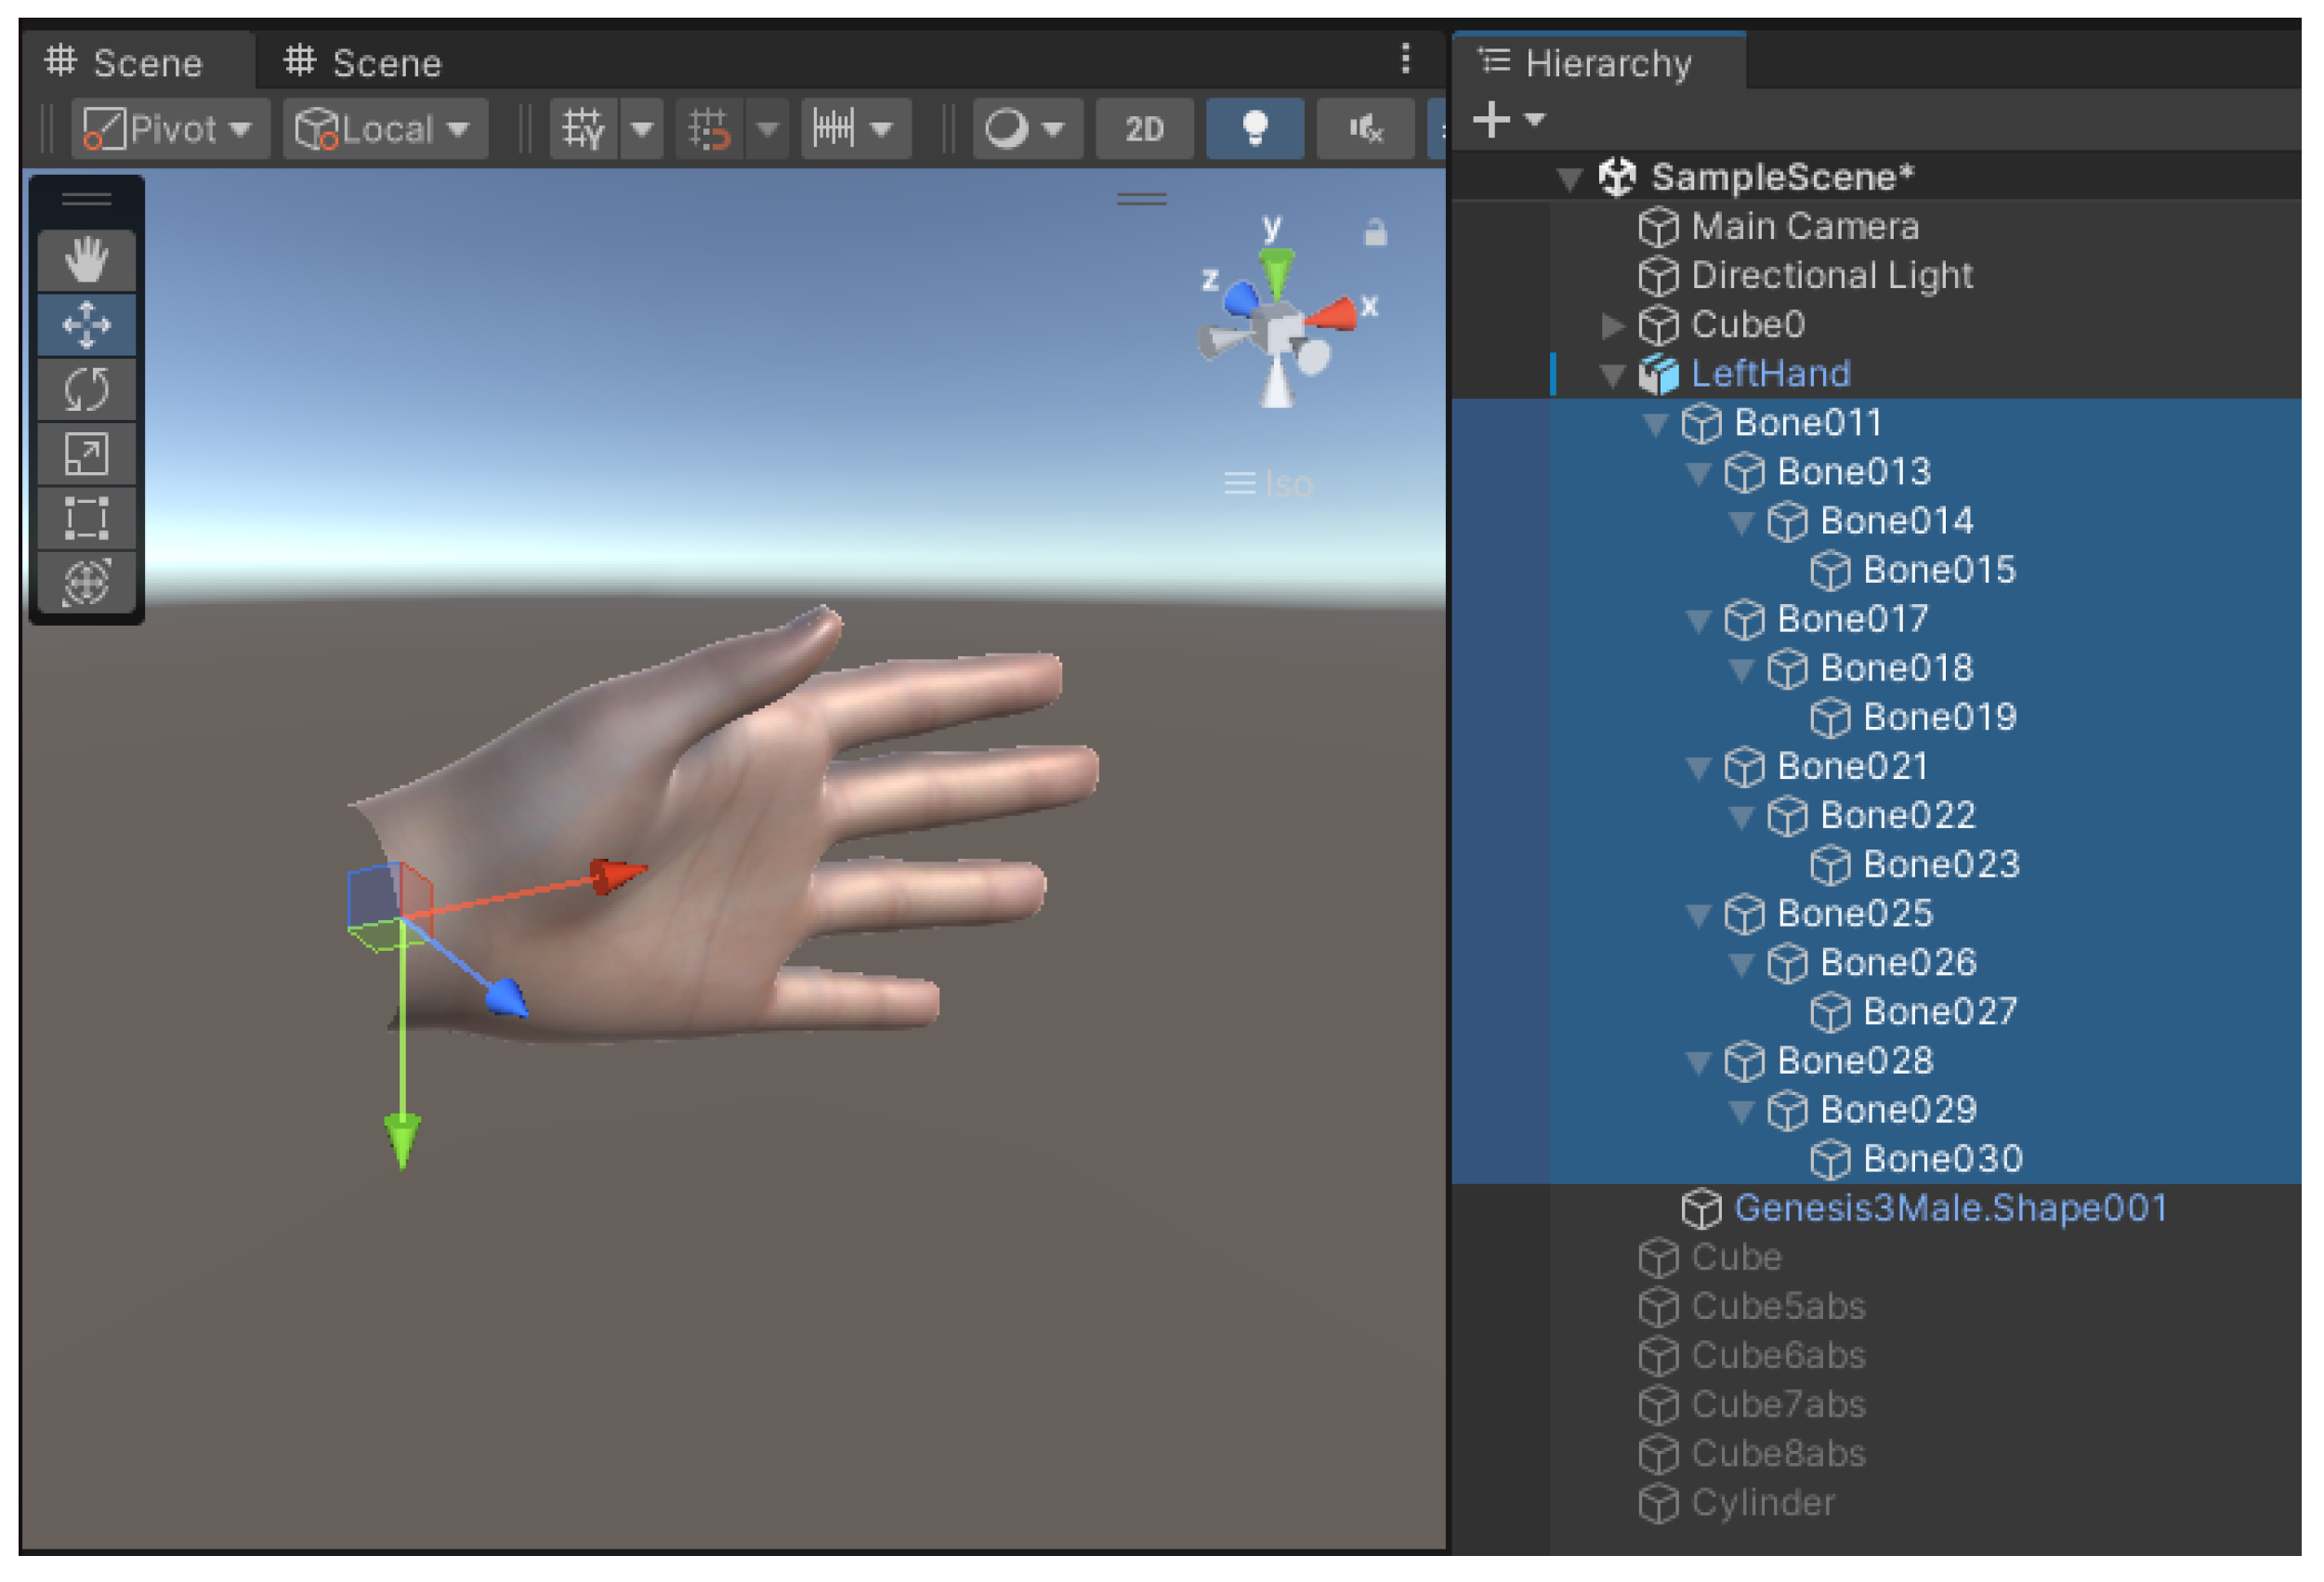
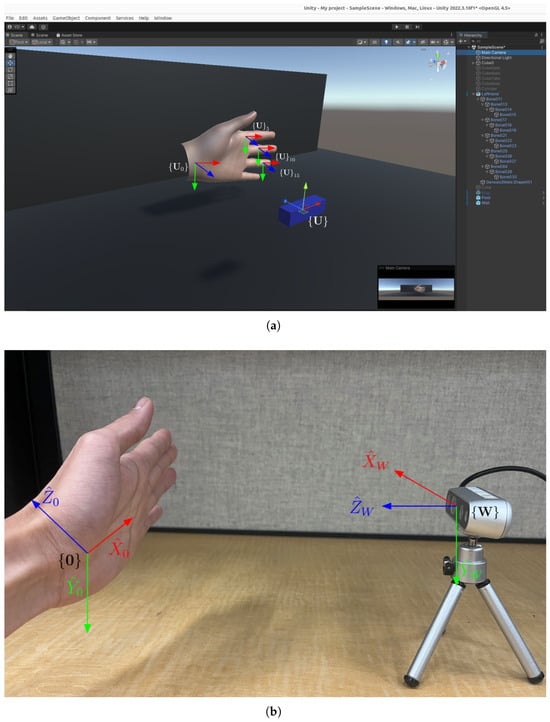
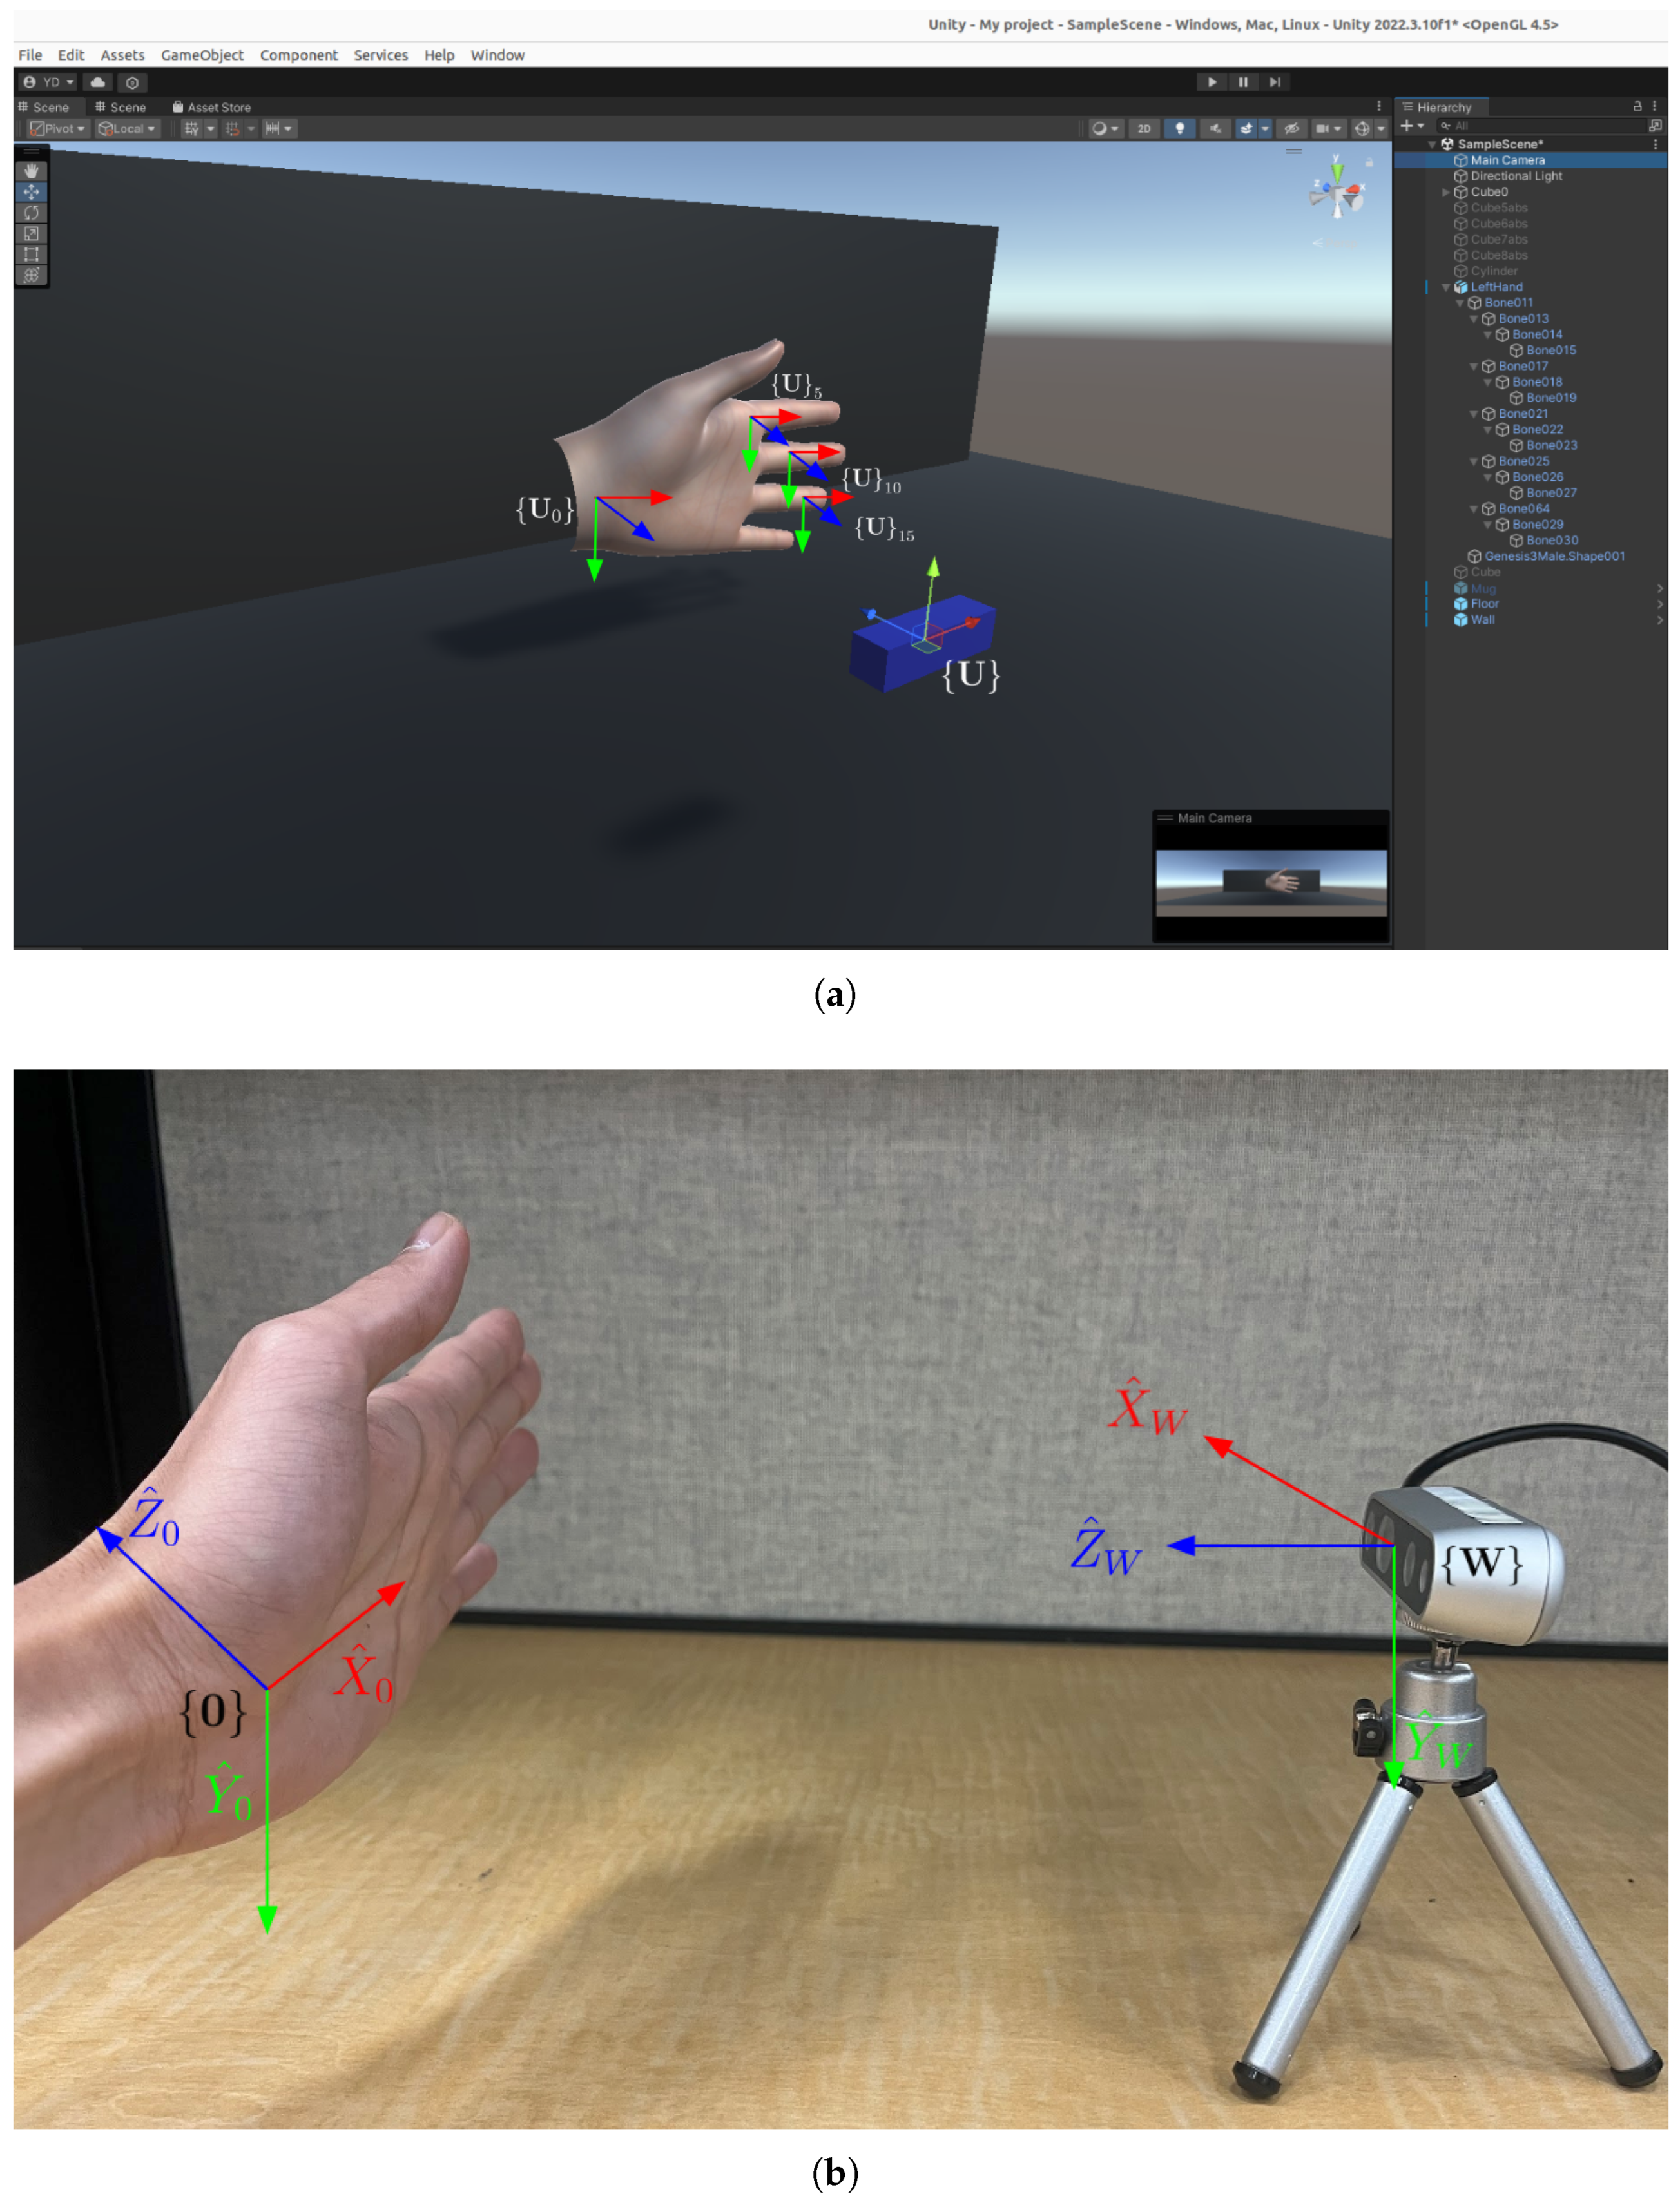
To graphically visualize hand movements, we utilize a rigged hand model in Unity, which replicates the actual texture and motion of the human hand. As shown in Figure 11, the hand model contains 16 movable joints, including the wrist and three joints for each of the five fingers , excluding the fingertips.
Figure 11.
Avatar hand model and hierarchical frame in Unity.
In the rigged hand model, each joint is represented by a local coordinate frame , for that is oriented relative to the parent’s coordinate frame. The wrist frame , being the root joint, serves as the origin for the hand’s coordinate system. Each subsequent joint has its own local frame, which is updated based on the joint’s current orientation and position.
In Unity, a camera object defines the viewer’s perspective, capturing the scene and rendering 3D objects. In our setup, we define the camera’s coordinate frame as , which corresponds to the depth sensor’s frame in the real-world setup. This camera object is positioned in Unity to mimic the physical sensor’s viewpoint, ensuring the virtual hand model moves in sync with real-world hand movements.
As stated previously, the world frame, denoted as , is established at the center of the depth sensor and defined by three orthogonal axes: , , and . In this setup, points to the right, points downward, and extends outward from the sensor toward the objects being tracked.
However, Unity uses a left-handed coordinate system for its camera object, where and in the camera frame align with the and of the world frame, respectively. The key difference is the orientation of the Y-axis: in Unity’s camera frame , it points upward, opposite to the downward-pointing in the world frame. This inversion must be accounted for when transforming the hand model’s parameters to ensure that the visualized hand movements in Unity accurately reflect the real-world hand tracked by the depth sensor.
5.3. Transformation from Hand Kinematic Model to Rigged Hand
Once the joint angles have been resolved in the kinematic model using the hierarchical structure of the hand, they need to be mapped to the corresponding joint angles in Unity.
As shown in Figure 12, the local coordinate frames in the rigged hand model and the hand kinematic model are highly consistent in their definitions. Both models use a hierarchical structure, and the orientation of the x- and y-axes across the 16 joints is the same. However, a notable difference exists between the two models: the kinematic model utilizes a right-handed coordinate system, while the rigged hand model in Unity adopts a left-handed coordinate system. As a result, the z-axes in the two systems point in opposite directions. In the rigged hand model, the z-axis points perpendicular to the palm, facing toward the camera, whereas in the kinematic model, the z-axis points away from the hand and the camera.
Figure 12.
A comparison of frame definition in the rigged hand and kinematic model. (a) Unity model and local frames in the rigged hand. (b) World and local frames in the hand kinematic model.
Thus, in order to properly reconstruct hand movements in Unity, the parameters from the kinematic model must undergo a transformation. This transformation involves two key steps: coordinate transformation and local frame transformation.
Coordinate Transformation: If a point has coordinates in the right-handed coordinate system , and we define a left-handed coordinate system at the same origin with the same x- and y-axes but with the z-axis pointing in the opposite direction, the coordinates of the point in the left-handed coordinate system will be . In matrix form, this transformation can be expressed as:
where the transformation matrix to switch from a right-hand system to a left-hand system is as follows:
This transformation accounts for the difference in the handedness of the two coordinate systems, ensuring that the joint positions in Unity’s left-handed frame correctly correspond to the real-world positions tracked by the right-handed kinematic model.
Local Frame Transformation: Since the rigged hand and the kinematic hand model differ in their local coordinate frame conventions, the rotation matrices for each joint must also be transformed to reflect this change. Consider a local coordinate frame in the right-handed system , where its orientation is represented by the rotation matrix . At the origin of this right-handed coordinate system , we can define a corresponding left-handed coordinate system where the x- and y-axes remain the same, but the z-axis points in the opposite direction. We now seek to compute the orientation matrix for the local coordinate frame in this left-handed system.
Let represent an arbitrary point in the right-handed system. After applying the rotation matrix, the transformed point in is:
In the left-handed coordinate system , the corresponding points before and after rotation are represented by:
Therefore, the transformed point in the left-handed system can be expressed as:
Thus, the orientation matrix of the local coordinate frame in the left-handed system is:
Since the matrix represents a reflection operation, and reflections are involuntary transformations (applying them twice returns the original state). When we multiply by itself:
It follows that:
In summary, to transform the hand kinematic model’s local coordinate frames to the rigged hand’s left-handed coordinate system in Unity, the orientation matrix for each of the 16 joints must be transformed using Equation (51). This ensures that all joint rotations and movements are accurately mapped from the real-world right-handed system to Unity’s left-handed system. For example, using the rotational transformation matrices , , defined in the previous section using measured data, we can compute their corresponding rotation matrix in left-handed coordinate system:
5.4. Quaternions Representation for Joint Rotations
In Unity, rotations are most effectively represented using quaternions. Quaternions offer a robust method to represent rotations without suffering from gimbal lock, which can occur when using Euler angles. A quaternion is defined by four components: , where w represents the scalar part, and forms the vector part, indicating the axis of rotation.
Given a rotation matrix obtained from the kinematic model, the corresponding quaternion is derived as follows:
where is the rotation angle, and is the normalized axis of rotation. This representation ensures that all joint rotations are smooth and efficient for computational purposes in Unity.
To convert a 3 × 3 rotation matrix into a quaternion, the components of the quaternion are calculated from the matrix elements [18]. The matrix is of the form:
and the quaternion components are computed as:
Finally, the signs of , , and are adjusted based on the off-diagonal elements of the rotation matrix to ensure consistency with the direction of rotation:
Therefore,
produces
and
Finally,
While the current implementation assumes full visibility of all 21 landmarks, we acknowledge that occlusions—either from self-shadowing or external objects—can impair direct observation of certain joint positions. The proposed kinematic model, by establishing a hierarchical and constraint-based structure, allows for integration with future estimation methods such as Bayesian networks or optimization schemes to infer occluded landmarks. Addressing such occlusion scenarios is a natural extension of this work.
6. Discussions and Conclusions
6.1. Discussions
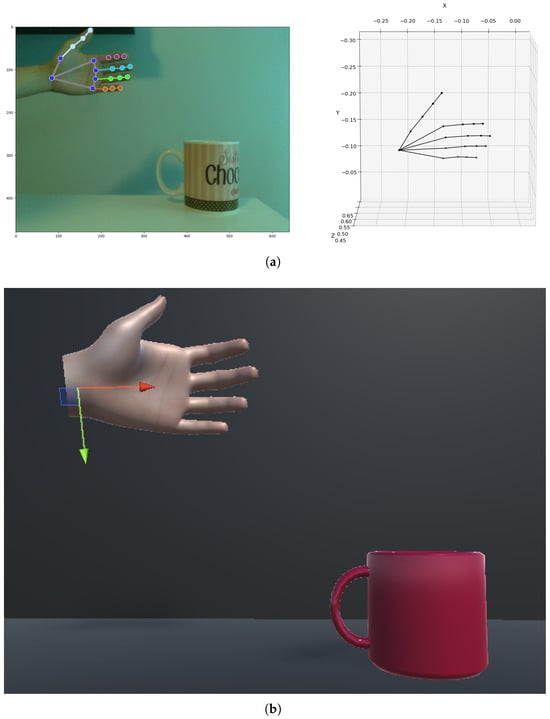
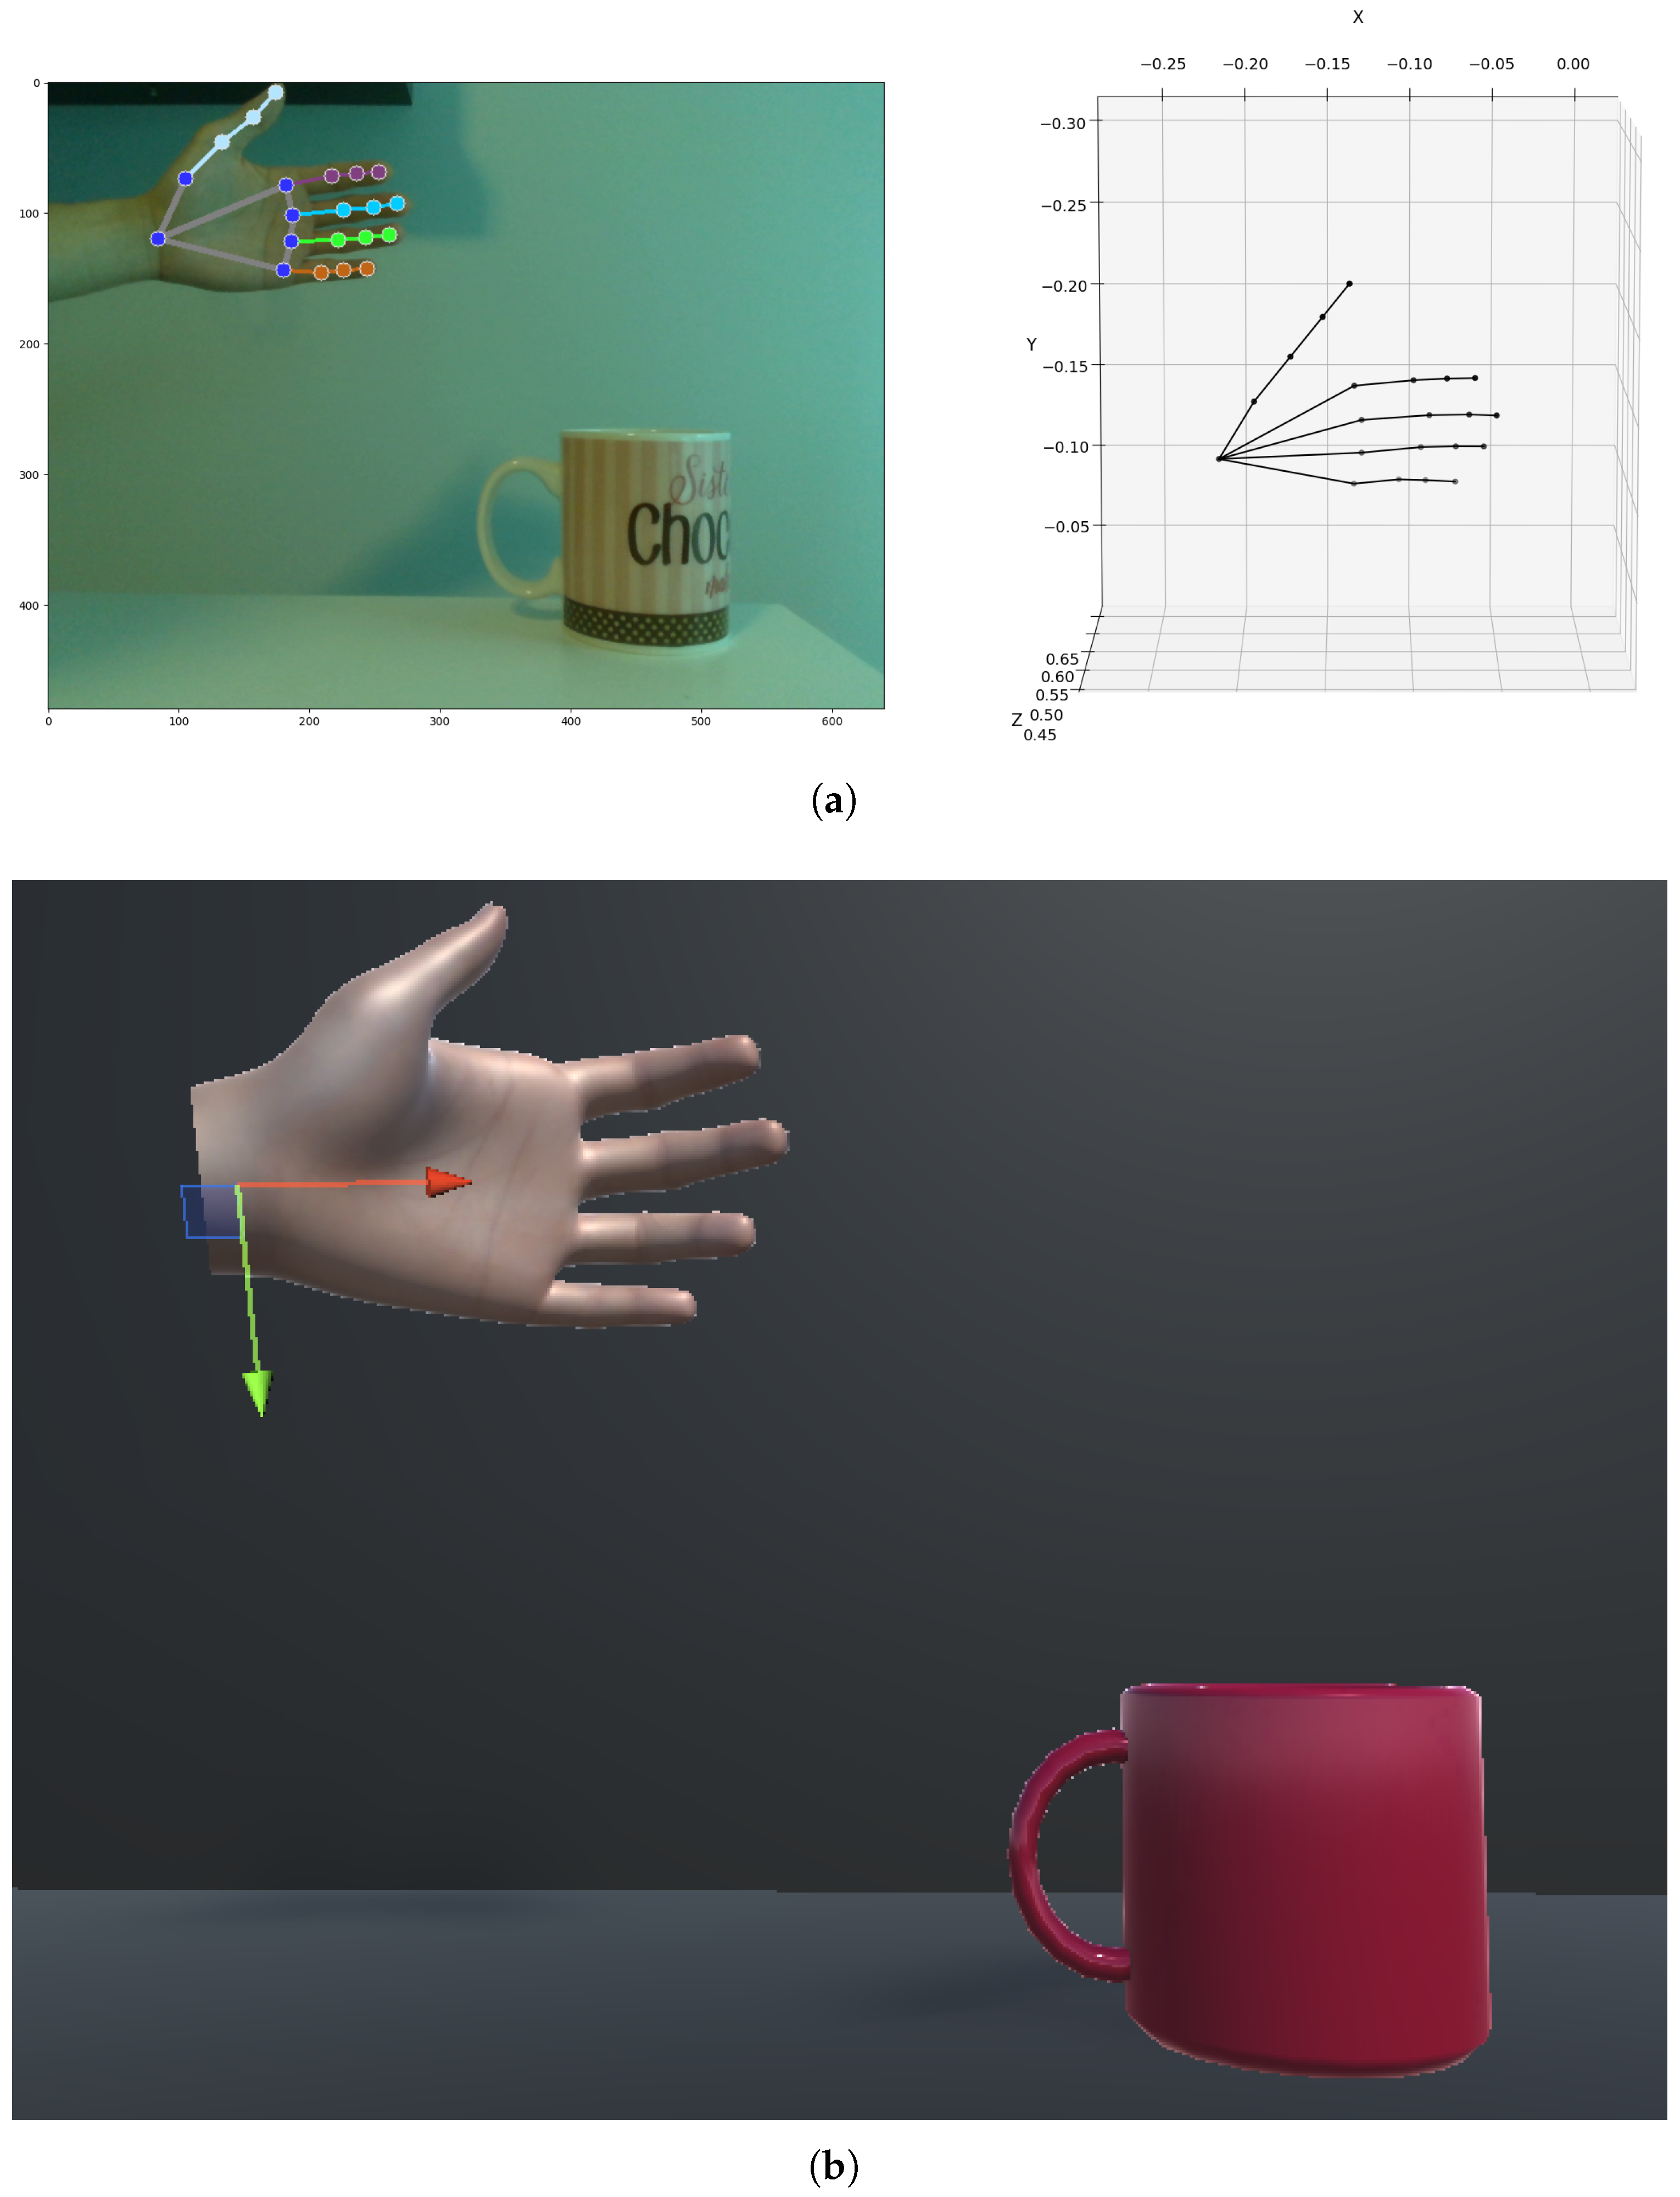
This paper presents various steps in developing a kinematic model of a dexterous hand using hand-pose-tracking data augmented with depth measures. The modeling method and the corresponding kinematic solutions were demonstrated through various measured data in resolving a hand kinematic parameters from captured RGB-D data. The 21 landmarks detected by MediaPipe were identified using calibrated RGB images where the corresponding depth values were measured (Figure 13). However, it was observed that as the hand moves, the data tends to become noisy. For instance, when the hand moves along a trajectory from the top left to the bottom right of the image, while MediaPipe continues to detect the 21 landmarks consistently, the associated depth values can contain outliers or even return invalid zero values. These discrepancies in the depth data can arise from factors such as occlusions, rapid hand movements, or limitations in the sensor’s precision.
Figure 13.
(Left): (a) shows a sample MediaPipe output visualizing the 21 detected hand landmarks overlaid on RGB-D data. (b) shows Unity visualization of the hand model reconstructed using the resolved kinematic parameters, synchronized with the real hand’s movement.
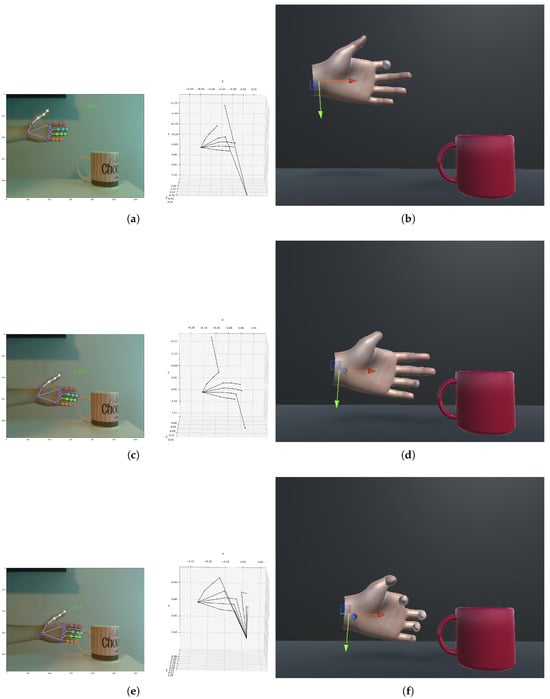
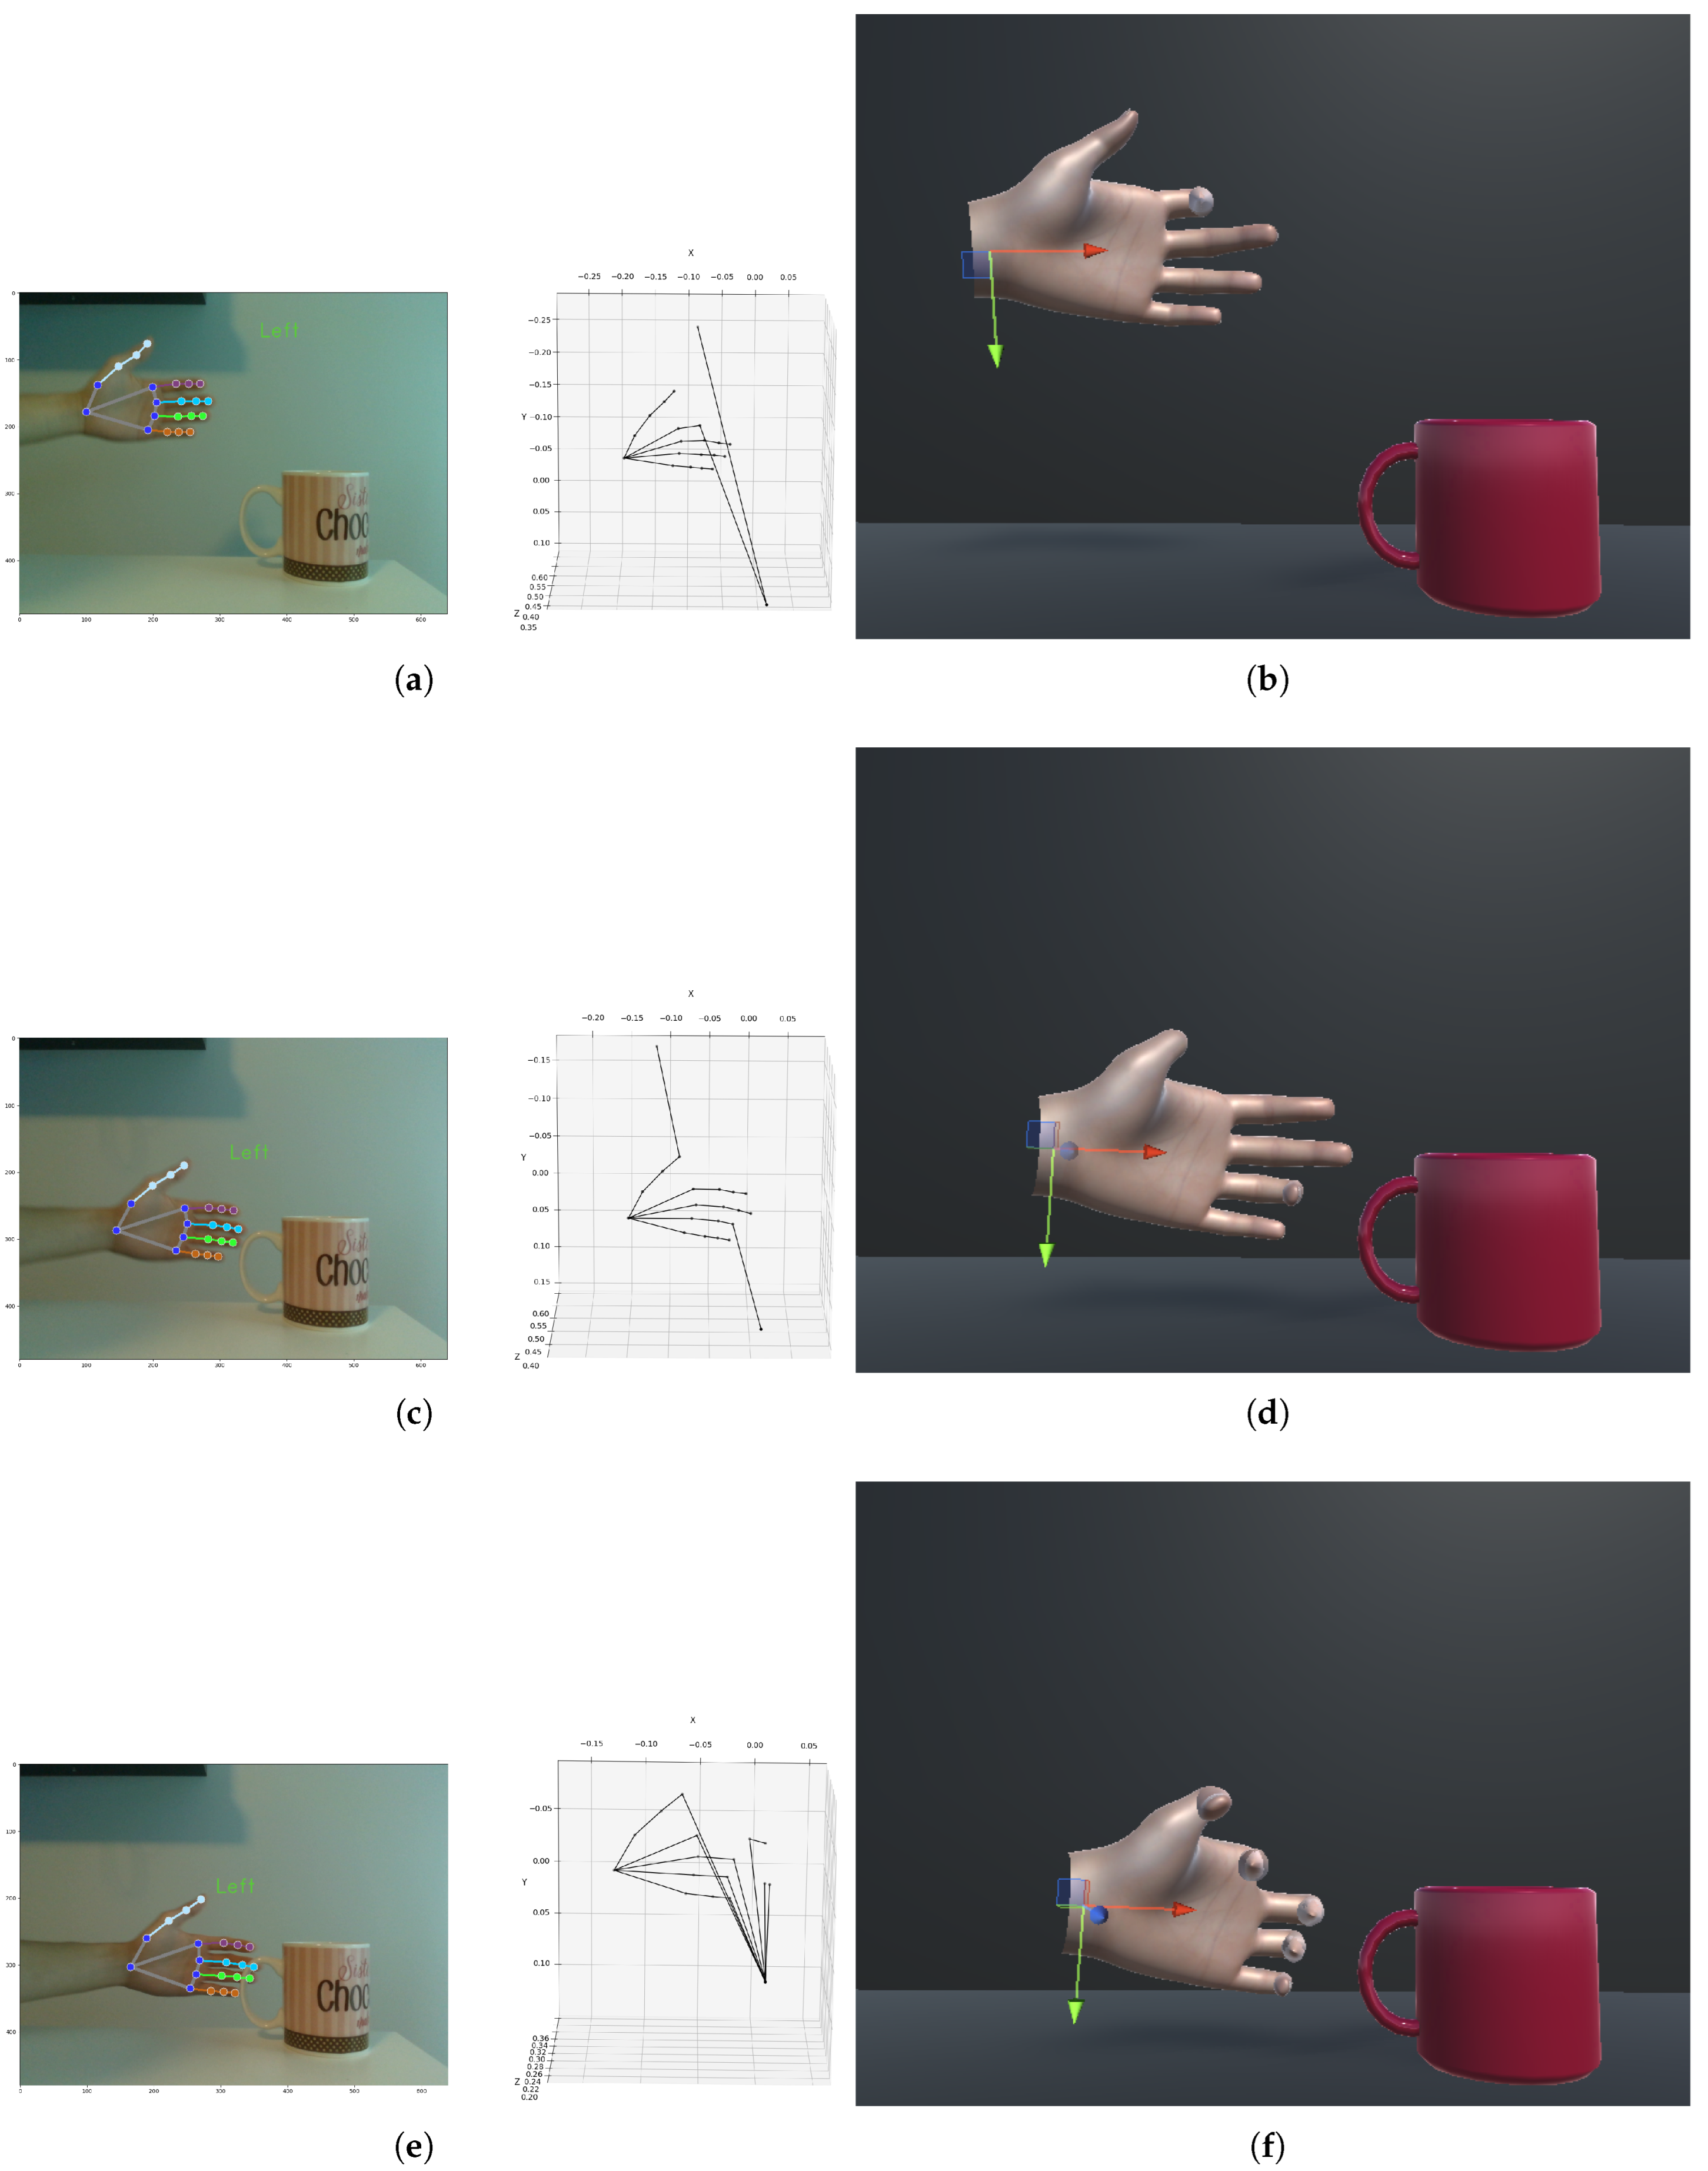
As an example, Figure 14 illustrates the process of the hand approaching a cup in three consecutive stages. In Figure 14a, the last two joints of the index finger show irregular depth data: one is recorded as 0, and the other as a far-off value (likely the distance to the white wall behind the hand, instead of the finger itself). In Figure 14b, the corresponding reconstruction in Unity shows the misalignment, where the index finger in the virtual hand model differs from the actual position of the real index finger. In Figure 14c, depth outliers are detected in both the thumb and the ring finger, resulting in erroneous positioning. The Unity reconstruction in Figure 14d reflects this discrepancy. In Figure 14e, as the fingertips of four fingers are slightly occluded by the cup’s handle, their depth values are recorded as 0. This further contributes to inaccuracies in the Unity reconstruction, as shown in Figure 14f, where the fingers deviate from their true positions due to the occlusion-induced depth errors.
Figure 14.
Consecutive stages of a hand approaching a cup, demonstrating depth inaccuracies and their effect on the Unity reconstruction. The key distinction lies in the corrupted depth input, shown in (a,c,e), which leads to deviation in the reconstructed kinematic pose, shown in (b,d,f), highlighting the impact of sensor noise on the estimation process.
To address such issues in proper kinematic resolutions, the use of prior knowledge, such as fixed user’s finger lengths, and the use of inverse kinematic model as constraints can be used to better estimate missing and erroneous landmarks. This can offer an approach to calculate the best angular parameters for reconstructing accurate hand movements in Unity, even when sensor data is incomplete or noisy.
6.2. Conclusions and Future Work
This paper presents a structured methodology for constructing a 3D kinematic model of the human hand based on spatially calibrated landmark data. The proposed model establishes a hierarchical coordinate system rooted at the palm and resolves both forward and inverse kinematic parameters for each finger joint. These results are integrated into a graphical reconstruction framework in Unity, enabling qualitative validation through simulated hand visualization. The main contributions of this work include the formulation of a hierarchical kinematic model driven by real-world sensor data, the derivation of joint parameters through geometric transformations, and the demonstration of pose reconstruction using a visualization platform.
While the current study focuses on single-subject modeling and offline data, future research will expand the framework in several directions [19,20]. We plan to incorporate wearable motion-capture devices to obtain ground-truth joint measurements, which will allow for a quantitative evaluation of the model’s accuracy. Comparative studies with state-of-the-art hand-pose estimation techniques will also be conducted to benchmark performance under various conditions, including sensor noise and occlusion. Additionally, we aim to extend the system for real-time tracking and modeling across different users, capturing dynamic hand interactions more effectively. To enhance robustness, we intend to integrate model-based estimation with data-driven methods such as neural networks or Bayesian inference frameworks. Finally, we envision applications of the proposed model in rehabilitation monitoring, and teleoperation systems, where accurate and interpretable hand motion representation is crucial. These extensions will further strengthen the generalizability and practical relevance of the presented approach.
Author Contributions
Conceptualization, S.P.; methodology, S.P. and Y.D.; software, Y.D.; validation, Y.D.; resources, S.P.; original draft preparation, S.P. and Y.D.; writing—review and editing, S.P. and Y.D.; visualization, Y.D.; supervision, S.P.; funding acquisition, S.P. All authors have read and agreed to the published version of the manuscript.
Funding
The research was funding through the Natural Sciences and Engineering Research Council of Canada.
Data Availability Statement
Dataset available on request from the authors.
Conflicts of Interest
The authors declare no conflict of interest.
Appendix A. Camera Calibration and RGB-Depth Pixel Association
This appendix provides a detailed explanation of the process to associate 2D pixels in the RGB stream with corresponding depth information. We utilize both the intrinsic and extrinsic calibration parameters of the intel RealSense D435 sensors, which enable the projection of 2D pixels to 3D space and subsequently map these 3D coordinates between the depth and RGB camera coordinate systems.
Appendix A.1. Intrinsic and Extrinsic Calibration
In a multi-sensing systems, the correct association of pixel information across different sensor modalities (e.g., RGB and depth) relies on accurate calibration. Camera calibration involves both intrinsic and extrinsic parameters:
Intrinsic parametersdefine the internal characteristics of each camera, such as and are the focal length of the camera in the x and y directions. and are the principal point offsets (the center of the image plane).
For the RGB and depth cameras of D435, the intrinsic calibration matrices are given as:
- RGB camera intrinsics:
- Depth camera intrinsics:
These parameters are for projecting pixel coordinates from image space to camera space.
Extrinsic parameters describe the geometric relationship between the RGB and depth cameras in terms of rotation and translation. The transformation between the two sensing coordinate systems is expressed through the following extrinsic matrix:
where R is the rotation matrix and t is the translation vector:
The rotation matrix R captures the orientation difference between the sensors, while the translation vector t accounts for the physical position discrepancies. These extrinsic parameters are essential for transforming 3D coordinates from the depth camera space to the RGB camera space. Based on the extrinsic parameters given, it suggests that the RGB and depth cameras are closely aligned in both orientation and position. The values in R are very close to an identity matrix (i.e., 1 on the diagonal and very close to 0 for the off-diagonal elements). This indicates that the depth and RGB cameras have almost no relative rotation transformation with respect to each other. The minor deviations from 1 and 0 on diagonals reflect a very small rotational misalignment, which could be due to slight manufacturing tolerances. The largest translation is along the x-axis (about 1.47 cm). This is typical in many stereo camera set-ups, where the cameras are placed side by side with a small baseline distance between them. The translations along the y-axis (0.03 cm) and z-axis (0.04 cm) are very small, indicating that the cameras are nearly aligned along the vertical and depth axes.
Appendix A.2. Aligning Depth to RGB Stream of the Sensor
In the RealSense SDK, aligning the depth frame to the RGB (color) frame involves transforming the 3D points corresponding to depth values into the RGB camera’s coordinate system. This ensures that for each pixel in the RGB image, there is a corresponding pixel in the depth image, allowing us to associate depth information with color data accurately. Therefore, we can directly access associated depth value of each from RGB stream and project 2D pixels to 3D space based on intrinsic parameters of RGB camera.
Projecting 2D Pixels to 3D Space (in cm)—A depth frame provides the distance from the camera to the surface at each pixel . The depth image is stored as a 2D array:
where h is the image height, and w is the image width. These are based on the resolution configuration of the camera stream.
Given a pixel from the RGB image and its associated depth value , we first project this 2D pixel to its corresponding 3D position in the camera’s coordinate system. The projection is governed by the following equations, utilizing the intrinsic matrix K:
The result is a 3D point for each pixel in the depth image, forming the point cloud of the scene.
Numerical Example—The camera has the following intrinsic parameters:
- Image resolution: pixels.
- Focal length: , .
- Principal point: , .
Given a pixel of a wrist landmark with a depth value , the 3D coordinates of the point can be computed as follows:
Thus, the 3D point corresponding to pixel is m.
References
- Rahman, M.M.; Uzzaman, A.; Khatun, F.; Aktaruzzaman, M.; Siddique, M. A comparative study of advanced technologies and methods in hand gesture analysis and recognition systems. Expert Syst. Appl. 2025, 266, 125929. [Google Scholar] [CrossRef] [Scilit]
- Amprimo, G.; Masi, G.; Pettiti, G.; Olmo, G.; Priano, L.; Ferraris, C. Hand tracking for clinical applications: Validation of the Google MediaPipe Hand (GMH) and the depth-enhanced GMH-D frameworks. Biomed. Signal Process. Control 2024, 96 Pt A, 106508. [Google Scholar] [CrossRef] [Scilit]
- Diaz, C.; Payandeh, S. Preliminary Experimental Study of Marker-based Hand Gesture Recognition System. J. Autom. Control Eng. 2014, 2, 242–249. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Payandeh, S. Hand Motion and Posture Recognition in a Network of Calibrated Cameras. Adv. Multimed. 2017, 1, 1–25. [Google Scholar] [CrossRef] [Scilit]
- Rehg, J.M.; Kanade, T. DigitEyes: Vision-based hand tracking for human-computer interaction. In Proceedings of the 1994 IEEE Workshop on Motion of Non-Rigid and Articulated Objects, Austin, TX, USA, 11–12 November 1994; pp. 16–22. [Google Scholar] [CrossRef] [Scilit]
- Rehg, J.M.; Kanade, T. Visual tracking of high DOF articulated structures: An application to human hand tracking. In Computer Vision — ECCV’94, Lecture Notes in Computer Science; Eklundh, J.O., Ed.; Springer: Berlin/Heidelberg, Germany, 1994; Volume 801, pp. 35–46. [Google Scholar] [CrossRef] [Scilit]
- Isaac, J.H.; Manivannan, M.; Ravindran, B. Corrective Filter Based on Kinematics of Human Hand for Pose Estimation. Front. Virtual Real. 2021, 2, 663618. [Google Scholar] [CrossRef] [Scilit]
- Li, T.; Xiong, X.; Xie, Y.; Hito, G.; Yang, X.; Zhou, X. Reconstructing Hand Poses Using Visible Light. Proc. Acm Interactive Mobile Wearable Ubiquitous Technol. 2017, 1, 71. [Google Scholar] [CrossRef] [Scilit]
- Cerveri, P.; De Momi, E.; Lopomo, N.; Baud-Bovy, G.; Barros, R.M.L.; Ferrigno, G. Finger Kinematic Modeling and Real-Time Hand Motion Estimation. Ann. Biomed. Eng. 2007, 35, 1989–2002. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Haustein, M.; Blanke, A.; Bockemühl, T.; Bockemühl, A. A leg model based on anatomical landmarks to study 3D joint kinematics of walking in Drosophila melanogaster. Front. Bioeng. Biotechnol. Sec. Biomech. 2024, 12, 1357598. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ji, Y.; Li, H.; Yang, Y.; Li, S. Hierarchical topology based hand pose estimation from a single depth image. Multimed. Tools Appl. 2018, 77, 10553–10568. [Google Scholar] [CrossRef] [Scilit]
- Peña-Pitarch, E.; Falguera, N.T.; Yang, J. Virtual human hand: Model and kinematics. Comput. Methods Biomech. Biomed. Eng. 2012, 17, 568–579. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zimmermann, C.; Brox, T. A Hybrid Model for Real-Time 3D Hand Pose Estimation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), Nashville, TN, USA, 19–25 June 2021. [Google Scholar]
- Lapresa, M.; Zollo, L.; Cordella, F. A user-friendly automatic toolbox for hand kinematic analysis, clinical assessment and postural synergies extraction. Front. Bioeng. Biotechnol. 2022, 10, 1–16. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Xu, Y.; Lee, G.H. Probabilistic Modeling of Hand Pose Under Occlusions with Anatomical Constraints. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 1–6 October 2023. [Google Scholar]
- Pfisterer, A.; Li, X.; Mengers, V.; Brock, O. A Helping (Human) Hand in Kinematic Structure Estimation. arXiv 2025, arXiv:2503.05301. [Google Scholar] [CrossRef] [Scilit]
- Zhang, F.; Bazarevsky, V.; Vakunov, A.; Tkachenka, A.; Sung, G.; Chang, C.L.; Grundmann, M. MediaPipe Hands: On-device Real-time Hand Tracking. arXiv 2020, arXiv:2006.10214. [Google Scholar] [CrossRef] [Scilit]
- Shoemake, K. Animating rotation with quaternion curves. ACM SIGGRAPH Comput. Graph. 1985, 19, 245–254. [Google Scholar] [CrossRef] [Scilit]
- Ahmad, A.; Migniot, C.; Dipanda, A. Tracking Hands in Interaction with Objects: A Review. In Proceedings of the 13th International Conference on Signal-Image Technology & Internet-Based Systems (SITIS), Jaipur, India, 4–7 December 2017; pp. 360–369. [Google Scholar] [CrossRef] [Scilit]
- Cheng, W.; Kim, E.; Ko, J.H. HandDAGT: A Denoising Adaptive Graph Transformer for 3D Hand Pose Estimation. In Proceedings of the European Conference on Computer Vision (ECCV), Milan, Italy, 29 September–4 October 2024. in press. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).