


Abstract
Nowadays, due to the developments in technology and the effects of the pandemic, people have largely switched to e-commerce instead of traditional face-to-face commerce. In this sector, the product variety reaches tens of thousands, which has made it difficult to manage and to make quick decisions on inventory, promotion, pricing, and logistics. Therefore, it is thought that obtaining accurate and fast forecasting for the future will provide significant benefits to such companies in every respect. This study was built on the proposal of creating a cluster-based–genetic algorithm hybrid forecasting model including genetic algorithm (GA), cluster analysis, and some forecasting models as a new approach. In this study, unlike the literature, an attempt was made to create a more successful forecasting model for many products at the same time inside of single product forecasting. The proposed CBGA model success was compared separately to both the single prediction method successes and only genetic algorithm-based hybrid model successes by using real values from a popular B2C company. As a result, it has been observed that the forecasting success of the model proposed in this study is more successful than the forecasting made using single models or only the genetic algorithm.
Keywords:
big data; data mining; e-commerce; demand forecasting; genetic algorithm; cluster analysis 1. Introduction
While managers, shareholders, and people who want to invest in a particular business want to make decisions about the future, they want to be informed about what the future will bring. Today, one of the areas intensively studied in the literature to meet this need is demand forecasting. To date, we have seen the applications of many models, from simple models to time series, such as artificial neural networks, in this field. In the studies we examined, we can see that there are a small number of applications in the e-commerce sector, which use has increased significantly after the pandemic. When we investigate the reasons for this situation, we see that the product diversity in this field, the variability of sales data, the accessibility of these data, and the lack of a clear trend are effective. If you are a manager in this sector, you will need more dynamic and adaptable solutions than the tools produced to date. For this reason, this study was inspired by the idea of investigating whether hybrid modeling, which is successful in different problems, can be successful by applying it to this field.
The developing internet environment has become a communication tool that not only supports personal use but also supports commercial activities. The method known as one of these use cases is e-commerce. E-commerce, on the other hand, is a system approach that combines transactions using telecommunication networks, improves business relations, and also enables the sharing of business information [1]. One of the difficult areas of e-commerce today is B2C businesses, which may encounter many operational problems. In particular, ensuring the effective management of many products at the same time is one of the problems faced by e-commerce businesses. Considering the past data while forecasting the demand for the products and considering the future as a continuation assumption of the past intensified the use of the concept of time series in solving the problem [2].
The COVID-19 pandemic has had a major influence on people all over the world. This has also influenced consumers to shop online owing to their apprehensions regarding safety. Therefore, this has opened up huge opportunities for online retailers and platforms to increase their sales and revenue and, at the same time, posed several challenges [3]. With the effect of COVID-19, the e-commerce market has grown incredibly and has become the first market for the whole world instead of the traditional face-to-face market. The expansion of the e-commerce market has also increased the variation of online products offered on the market in this field. The intense competition in e-commerce products causes delivery times to gain importance. This makes it difficult for businesses to manage the supply chain. Many competing products at the same time are under the influence of consumer dynamism in many respects. The dynamism of the problem reveals the need to keep the forecasting horizon short and to increase its forecasting success further.
It is observed that different organizations employ different forecasting techniques based on their requirement from these methodologies: traditional statistical models, machine learning, deep learning models, and hybrid models [4].
When we look at the recent history of demand forecasting, a lot of models like time series, artificial neural networks, deep learning, and heuristic methods have been used before. Especially, time series analysis models such as moving average, regression, exponential smoothing, seasonal exponential smoothing, and causal modeling allow for scalable deviation. Our study is about how it is possible that these models, which are used alone in the literature, can produce more successful results when combined. Within this purpose, the demand forecasting problem for the e-commerce sector has been formulated as an optimization problem for minimizing MSE (mean square error) accuracy values for multiple products sold online. The solution space for this optimization problem is too big for solving with traditional methods or linear or nonlinear optimization models. Therefore, a metaheuristic optimization method is needed. Due to the popularity and easy application, the possibility of genetic algorithms in this field was selected in this study. On the other hand, increased product variation is also a big problem for demand forecasting in the e-commerce sector. Therefore, online companies are looking for easy and quick forecasting solutions for their products because of dynamic sectoral conditions. They already have limited qualified employees in data or statistical analysis. This personnel shortage can only be met with software that is easy, quick, and successful. Using the similarities of products and their clustering as a forecasting improver to build a model that can be successful in a large number of products at the same time is one of the most original contributions of this study to the literature. In this way, demand forecasting for a large number of products can be made faster and forecast accuracy can be increased, which is one of the reasons for starting this study.
As a result, the first aim of this study was to create a cluster-based genetic algorithm (CBGA) model that will both increase the forecasting accuracy and provide fast results by combining methods for the e-commerce sector with high product counts. The next objectives of this study were to compare the performance of the proposed CBGA model with the standalone and product–by-product forecasting accuracy of the models and to also develop this model as software in the e-commerce sector. In comparison, the MSE value was taken into account as an indicator of the forecasting accuracy.
With the contribution of popular e-commerce company XYZ.com, which sells office products in Turkey, by providing data to the study, the study was tested with real environment data for forecasting.
2. Related Works
2.1. Determining the Demand Forecasting Performance
Demand forecasting, according to Armstrong (1988), is defined as the steps taken to form a basis for the decision-making processes of a product selected as likely to be studied in the future without guarantee. Forecasting the future is one of today’s most fundamental problems for scientists, operators, and institutions. Especially in uncertain economies, the changes created by consumer behavior negatively affect foresight success. However, it is possible to achieve successful results with many forecasting models developed. The methods used in forecasting the demand for a product can be grouped in the literature as mechanical and conventional, time-series-based, artificial intelligence-based, and heuristic approaches [5].
Performance measurement in demand forecasting is usually done by forecasting accuracy measurement. In a study by Winklhofer et al. (1996) in which they evaluated the literature of their horizon, they focused on the characteristics that affect prediction accuracy. As a result of the evaluation of the process characteristics, they concluded that the growth of the forecast time horizon had a negative effect, the use of consultants and computers in forecasting increased accuracy, and the number of forecasting methods selected had a positive effect, but on the other hand, the use of a combination of methods had no effect. However, these judgments and method combinations have changed due to the development of computer technologies and methods [6]. Another study to evaluate the demand forecasting literature in detail was carried out by Gooijer and Hyndman (2006). The authors, who drew attention to the last 25 years of demand forecasting methods, stated that the use of the forecasting horizon varies by minute, daily, weekly, or annual horizons in many studies. On the other hand, the estimated areas remained limited in areas such as the electricity load, monthly store sales forecast, population forecast, and tourism demand forecast. Gooijer and Hyndman (2006) summarized that the MSE, RMSE, MAPE, and many more formulas are used to calculate forecast success. Table 1 shows all the performance criteria used [7].
Table 1.
Demand forecast performance indicators [7].
2.2. Studies about Demand Forecasting Models
As stated by Ludwig et al. (2009), as one of the nonlinear optimization problems in their studies, the forecasting process for oil production was carried out with genetic algorithm and artificial neural network-based models. The authors argued that choosing from input variables would increase the success of the prediction model. This study is important in terms of revealing how important the selection of variables is for the estimation process [8]. Chodak (2009) proposed a model for demand forecasting in internet markets. According to this suggestion, taking advantage of product features to increase the chances of success in demand forecasting can minimize the error level. The proposed model took into account variables such as the status of the product on the showcase, price, lead time, number of products running together, and order frequency. The study, which used 14-month data as a learning process, estimated the next 2 months with MAPE values with 20% and 10.8% absolute errors, respectively, in the model established by the genetic algorithm [9].
Sayed et al. (2009) developed a hybrid genetic algorithm-based forecasting model. With this model, which they call the BAFI structure, MSE is the fit function, and the mean squared error is an objective function. They created a forecasting model that would work differently in different situations by using the cause–effect diagram. To investigate the performance of the proposed model, they evaluated the forecasting success according to individual statistical methods for different trends and seasonality conditions. The model they proposed provided the lowest error rate, at around 20% in all conditions. As a result of their studies, the authors emphasized that more models should be used, and at the same time, more successful results can be obtained by changing the genetic algorithm tuning parameters and initial conditions [10]. In a study that argued that traditional methods are not effective in estimating financial time data, Huang (2011) modeled the raw input data financially with wavelet analysis in the first stage and transformed it into a time–scale surface area for forecasting and then divided this surface into various areas with the spectral clustering algorithm. In the second stage, as a result of these distinctions, predictions were made using artificial neural network support vector sets and traditional models. He used the RMSE (root mean square error) indicator while investigating the forecast performances. As a result of his studies, he concluded that the prediction success of the time–scale hybrid model that he proposed is higher than that of traditional methods [11]. In another study, Hasin et al. (2011) also took into account some general variables to improve daily consumption forecasts in the retail sector. In the variables, they dealt with weekends or weekdays; holiday days; low, medium, and high price levels; brand categories; and seasons. It was seen that the forecasts made on a weekly and daily basis were better than Holt–Winter’s model. In their study, they also evaluated the results by combining the model they developed with the genetic algorithm [12].
In their study, Wang and Petropoulos (2016) compared expert estimates with the best estimation method selection and combination of estimations and investigated the effect of this on the inventory management performance. Forecast selection and combination improved both the inventory and forecast performance over other models or expert forecasts. On the other hand, it was found to be the best strategy for minimizing the total cost and maximizing the estimation accuracy measured by the MAE [13].
In another study on the combining of methods, Pwasong and Athasivam (2018) proposed a model for the combination of the ARFIMA and LRNN methods. Running the model on NNPC’s estimation of gasoline production, the authors concluded that the proposed model outperformed the prediction success of the two models alone [14].
Chan et al. (2019) compared the forecasting performances of six different time series models (MA, ARMA, MARS, GM, SVM, and ANN) for container forecasting. As a result of the analysis, they found that the support vector machine method gave the best results in all cases. The result of the low prediction success of artificial neural networks in the related problem is one of the prominent results [15].
Moscatelli et al. (2020) performed a performance analysis by comparing machine learning models, which have been widely used in estimations in recent years, with statistical models such as logistic regression in assumed risk assessment estimations. The results of the analysis show that machine learning models are more successful when there is a limited set of information, but this advantage decreases when there is precise information such as credit behavior. The researchers used the financial ratios of 300,000 non-financial Italian companies between 2011 and 2017 as a huge dataset in their studies [16].
According to Pan and Zhou (2020), traditional data mining technology cannot successfully exploit enormous data in the electrical supply, because it relies on time-consuming and labor-intensive characteristic engineering. They claim that convolutional neural networks can efficiently utilize a vast quantity of data and can automatically extract effective features from the original data with increased availability. In their study, a convolutional neural network was utilized to mine e-commerce data to anticipate commodities sales, while weight attenuation technology and transfer learning technology were employed to increase the accuracy of commodity sales forecasting. To validate the effectiveness of their suggested technique, they compared the following algorithms: data analysis autoregressive integral moving average (ARIMA), convolutional neural network (CNN), single CNN, and photonic deep neural network (PDNN). Experiments on large-scale datasets revealed that their model may significantly increase the accuracy of sales forecasting [17].
The findings of the literature indicate a distinct trend in the use of ML and DL methods for manufacturing demand forecasting. This pattern illustrates how certain techniques—like neural networks and long short-term memory—can manage complicated demand patterns better than more traditional statistical techniques [18].
The accuracy of demand forecasting methods is considerably increased by using AI techniques alone or in combination with statistical techniques. In their literature review article, Mediavilla et al. (2022) analyzed 23 different methods that were successfully applied in demand forecasting between 2017 and 2021, clearly demonstrating the use of deep learning techniques [19].
The performance of five machine learning regression methods—random forest, extreme gradient boosting, gradient boosting, adaptive boosting, and artificial neural network algorithms—was examined in the study in comparison to a hybrid model—the RF-XGBoost-LR—that was suggested for sales forecasting of a retail chain, taking into account various forecasting accuracy parameters. A retail company’s weekly sales data were taken into account while analyzing projections, and the hybrid RF-XGBoost-LR model was found to perform better than the other models when evaluated using a variety of performance criteria [20].
Gustriansyah et al. (2022) aimed to increase the success of sales forecasting by using the data mining technique k-means and the best–worst method model in the sales forecasting of retail products. The researchers, who said that they increased the quality of clustering products with the k-means algorithm, showed that, with this new model, which they named SalesKBR, the sales forecasts had a reasonable level of accuracy, and they predicted with a small error rate of 27.12%. The authors suggested that more successful results can be obtained in different sectors with different models, which were limited because their studies were in the retail sector and the dataset was relatively small [21].
Fu and An (2022) presented a hybrid neural network sales forecasting model based on the voting–ensemble approach. They claimed that their experiments demonstrated the high accuracy of a hybrid model in sales forecasting, enabling businesses to optimize inventory management and enhance logistics benefits [22]. They also mentioned that Shi (2013) asserted that the grey neural network based on a genetic algorithm can better forecast future changes in sales volumes compared to time series regression and a BP neural network model [23].
To estimate product demand in an e-commerce firm, Chaudhuri and Alkan (2022) presented an optimized forecasting model: an extreme learning machine (ELM) model paired with the Harris Hawks optimization (HHO) algorithm. The suggested ELM-HHO model’s performance was also compared to that of classic ELM, ELM auto-tuned using Bayesian Optimization (ELM-BO), a Gated Recurrent Unit (GRU)-based recurrent neural network, and Long Short-Term Memory (LSTM) recurrent neural network models. The results showed that the suggested technique outperforms the existing product demand forecasting models in terms of prediction accuracy, and it can be used in real-time to estimate future product demand based on sales data from the previous week [24].
The goal of the study of Neelakandan et al. (2023) was to create and test a model for forecasting online product sales over a wide range of online product types. A continuous Stochastic Fractal Search (SFS) approach for optimizing the parameters of a deep learning modified neural network (DLMNN) was described by the authors, along with an analysis of a time series dataset. A RMSE, a MAE, and a MBE comparison of the SFS-DLMNN methodology with other popular methods such as the PSO, WOA, BRNN, and GA models were carried out by the authors. The results showed that their machine-learning technique produced improved outcomes with lower values [25].
Zhang and Kim (2023) offered a network model for enterprise sales forecasting based on a mix of enterprise sales forecasting from the standpoint of digital management and neural networks. To improve sales forecasting and supply chain management, the authors provided a hybrid learning method that combined seasonal mode and support vector regression analysis. This hybrid model can investigate time series features and gain more valuable information to create a network capable of extracting more discriminative features. The authors forecasted the sales of clothing product types that were sensitive to seasonal effects and had a long sales cycle and used seasonal factors to process the data. Their suggested model had better accuracy for predicting the future sales demand of garment enterprises and boosted the model training speed and reaction time [26].
According to Ramos et al. (2023), forecasting methodologies are important in assisting decision-making in e-commerce. Deep learning approaches (namely deep neural networks) were utilized by the literature to measure the “learning” ability to extract important insights from data. When compared to other simpler neural networks (e.g., multilayer perceptron architectures), “long memory” neural networks (e.g., long short-term memory architectures) are offered as the best alternative by [27].
According to Aguiar-Pérez and Pérez-Juárez (2023), deep learning methods have demonstrated better performance than conventional forecasting methods in energy demand. It is a fact that big data are essential to overcoming the obstacles of renewable energy integration, since smart grids produce large amounts of data. Thus, big data technologies are becoming more and more essential in load forecasting as electric vehicles are gradually being introduced [28]. In their review article, Habbak et al. (2023) also mentioned that, in comparison to other approaches, AI-based load forecasting techniques utilizing machine learning and neural network models in the energy industry have demonstrated the highest forecast performance, obtaining higher overall RMS and MAPE values [29].
Tang et al. (2023) outlined the main functions of the AI-predicting inventory model and offered optimization recommendations for e-commerce enterprises. When compared to other models in the case company, the AI forecasting model XGBoost exhibited the highest predictive accuracy and significantly increased the accuracy of inventory forecasting [30].
Swaminathan and Venkitasubramony (2024) classified the forecasting demand methods in fashion products into two categories: qualitative and quantitative methods. While the qualitative methods include techniques such as expert judgment, Delphi, and analytic hierarchy process, the quantitative methods embrace statistical and heuristics-based methods (time series-based models, Bayesian method-based, heuristic-based, panel data-based models, and others); artificial intelligence (AI); machine learning (ML); and hybrid methods (fuzzy-based, NN-based, clustering and classification, and grey-based hybrid models). AI and ML-based forecasting methods are classified as neural networks (NNs); deep learning; convolutional neural networks (CNNs); evolutionary neural networks (ENNs); extreme learning machine (ELM); and classification (Bayesian networks, genetic algorithm, random forest, and k-nearest neighbor). According to the authors, the utilization of machine learning forecasting models to tackle the demand fluctuations in the fashion industry has been recognized as an area where ongoing research would have a significant impact on the business. As companies expand into new channels or markets, ML-based forecasting has helped them produce more accurate projections and increase consumer involvement [31].
Gaboitaolelwe et al. (2024) compared the forecasting performance of ML models, including AdaBoost, multilayer perceptron neural network, support vector regression (SVR), random forest (RF), lasso regression, gradient boost, and extreme gradient boost, by using historical power production data. They found that the random forest model performs the best when forecasting model performances are ranked according to skill score results. The optimized multilayer perceptron NN forecasting model is the least effective aside from the baseline models [32]. According to Bender et al. (2024), the use of ML and AI approaches is becoming more prevalent in demand forecasting systems, which are constantly progressing and offer promising tools to increase forecasting accuracy [33].
2.3. Original Contribution of the Work
It is possible to come across studies in the literature on estimating the sales of businesses. When the nearly 50 years of studies in the literature are evaluated, demand forecasting studies, which started with time series, continue with artificial neural networks, deep learning, heuristic methods, and studies using various models. Demand in the market for information technology products in a heavily competitive environment is unstable due to increasing competition, changing consumer trends, and rapid innovation in product processing technologies. In this case, the use of time series analysis techniques such as moving average, regression, exponential smoothing, seasonal exponential smoothing, and causal modeling allows for scalable deviations to occur. Traditional models are biased, and these biased estimates can adversely affect production planning and product scheduling [34]. However, these models, which are insufficient alone, can reproduce more successful results when combined. The method of combining estimates is an estimation method that is used to combat the question of which methods should be used together instead of choosing the best method [35]. The consolidation of estimates is usually achieved by multiplying and summing individual method estimates with a given weight ratio. In this way, it is possible to obtain a new and more successful forecast from existing forecasts. Demand forecasting studies, which find wide applications in many sectors, have difficulty in finding the same application area in the e-commerce sector. Developing new technologies and the use of smart devices have brought people access to information and ease of transactions, and the e-commerce market has expanded rapidly in the last 10 years. With the effect of the recent pandemic, traditional face-to-face trade became impossible for a long time, and at this point, the e-commerce market has grown incredibly and has become the first market for the whole world. The expansion of the e-commerce market has also increased the variety of online products offered on the market in this field. As a result of this, e-commerce managers difficulty in making and monitoring decisions. On the other hand, it is possible to accelerate product management decisions for these businesses by using the demand forecasting method. As an important contribution to the literature in this study, which finds little application area in the e-commerce sector, it has been tried to provide a model proposal with better forecast performance than other methods to realize the demand forecasting of sales for multiple products and achieve rapid results in a huge product variety while doing this.
The genetic algorithm method, which has the quality of lifesaving in optimization problems with a large solution space, cluster analysis made with the k-means technique, which has an important place in data mining, and historical forecasting models will increase the prediction performance in e-commerce. This created an important belief about our tests. The example of success achieved in this study will ensure that similar studies will increase in the future, so that more studies will take place in e-commerce in the future, and a unique auxiliary tool will be obtained when these studies are put into practice, like the software developed in this study. In an environment of uncertainty, managers will be able to find answers to many questions, such as which products should we sell, how should we determine the inventory policies on the products, and which products should we use for promotions with this assistant.
3. Materials and Methods
3.1. Materials
The data for the study were taken from one of Turkey’s leading office products B2C sites. The e-commerce company periodic inventory control method was selected and was weekly. For this purpose, approximately 13 months of the company’s visit and sales data were examined, and the weekly combined data were used. Due to the dynamic structure of the sector, the weekly forecasting horizon was used because of the selected e-commerce company’s supply chain and inventory control policies. In the study, 53 weeks and 15,525 sales data for 50 different products selected by the relevant website administrators were used in testing the proposed demand forecasting model, measuring its performance, and comparing it to other methods.
For the proposed demand forecasting model, characteristic variables describing the products were needed. In the selection of variables, the variables suggested in the literature and the opinions of industry experts were taken into account. Therefore, 14 data variables as the demand density, visitor density, profitability, popular product or not, customer type, XYZ.com company price position, competitor count, minimum price at competitors, maximum price at competitors, XYZ.com price, supplier count (whom sold the product to XYZ.com), daily sales quantity, sold day count, and order count were selected for the 50 products as the study’s materials.
3.2. Methods
3.2.1. B2C E-Commerce
With the development of internet technology, web-based trade structures, the types of e-commerce and mobile commerce, have made great progress as the generation of online commerce. Especially in the last ten years, e-commerce applications have increased, and it is thought that it will remain a commercial area that will maintain its importance for a long time. As the structures of businesses have changed with e-commerce, their understanding of commerce has also had to undergo a major change [36]. On the other hand, the B2C e-commerce model refers to electronic transactions between business organizations and their customers. This model can be applied to any business that sells products or services to its customers over the internet. Changes in business processes in the retail industry have been made to ensure that these processes are compatible with e-commerce.
3.2.2. Cluster Analysis
Cluster analysis with the k-means technique was preferred in data mining in the study and frequently preferred in the clustering of products in the literature. A cluster analysis was performed in the Statistica v13.3 package program. Cluster analysis is an effective tool in scientific or managerial inquiry. It groups a set of data in a d-dimensional feature space to maximize the similarity within the clusters and minimize the similarity between two different clusters. The k-means method is a widely used clustering procedure that searches for a nearly optimal partition with a fixed number of clusters. It uses an iterative hill climbing algorithm [37]. Calculation was preferred in determining the number of clusters. The determination of the number of clusters is a separate field of study in the literature. There are also alternative methods, such as heuristics and index scans, for determining the number of clusters in which expert opinions are generally taken into account. It is thought that using the calculation method that is considered in the dynamic structure will be faster.
3.2.3. Selection of Forecasting Methods
In demand forecasting, one of the decision variables examined in the literature is the forecast horizon to be used. In some studies, the horizon was chosen on a daily, weekly, or monthly basis. Hasin et al. (2011), in their study, took into account the forecasts daily [12]. However, they evaluated the problem since there is a physical market and products with high daily consumption. It is seen as extremely normal that they tend to the forecast horizon daily. When we look at the data of the e-commerce site with the selected dataset in the proposed model, it is seen that the number of the same products that receive orders every day (the rate of sales days is close to 100%) is very low. For this reason, it was thought that it would be logical to only focus on the weekly or monthly forecast horizon alternatives in the decision problem. As a result, a weekly time horizon was chosen in the proposed model.
Following the horizon selection, the final issue is deciding which estimation methods will be used for the combination. The studies in the literature were examined to select the estimation methods to be used. Information about some studies and the methods they used are shown in Table 2.
Table 2.
Some of the estimation methods preferred in the literature.
As can be seen in Table 2, there are many examples of different methods. There are examples of hybrid studies in the e-commerce sector. In our proposed model, which aims to improve the demand forecast performance upon hybridization of the methods, both traditional estimation methods were chosen, and the selected methods were combined with cluster analysis and genetic algorithms. The estimation methods and calculation equations used in this study are as follows:
Simple Mean Model (SM): The simple arithmetic mean of the observation values of the previous t horizon can be taken as the predictive value of the next horizon, the horizon (t + 1).
Moving Average Model (MA): This method proposed by [44,45] to eliminate randomness in the time series and takes into account the last k-horizon averages. If the average is to be used as k-horizon averages, this model is preferred. The purpose of this model is to always ensure that a certain number of last horizons have an impact on the forecast. In the study, the simple moving average model was preferred, and two different alternative 2-horizon and 3-horizon models were used for this model.
Simple Exponential Smoothing (ES): Brown (1963) transformed a stationary time series into a fixed model based on Holt’s formula [46]. From this point of view, he proposed the simple exponential smoothing method. Prediction value: is described and used. An important factor in this model is the α coefficient. While this value is selected between 0 and 1, this value is used to decrease the effect coefficient of the past horizons exponentially.
Holt’s Two-Parameter Linear Exponential Smoothing Model (HOLT): It is one of the best methods among time series models. Holt’s Two-Parameter Linear Exponential Smoothing Method uses two smoothing constants and three equations to make the estimation. These equations are
Holt–Winter’s Model (WINTERS): One of the successful methods, the Holt model cannot achieve the desired success when it is under the influence of a seasonal series. By adding the seasonality parameter to the Holt method, the Winters model has been obtained, and it has been demonstrated that it can be used in series with seasonal characteristics. In the analyzed data, it is thought that the company has seasonal products. In Winter’s method, where there are two different calculation models, additive and multiplicative, the summative model is preferred. The equations for this model are as follows:
Simple Regression Analysis (LINR): In this estimation model, which is one of the statistical methods, the model is expressed as a linear model for estimation. In simple linear regression analysis, the reciprocal relationship of the dependent variable with only one independent variable is defined by a linear function. A simple linear regression equation:
3.2.4. Genetic Algorithm
Genetic algorithm (GA) makes it possible to find the best solution in a larger search space than traditional programs. The vast majority of organisms have two common processes to survive: natural selection and sexual reproduction. The first step is to select individuals who will survive in the population, and the second is to ensure that new individuals are produced by a recombination of chromosomes. Based on these two principles, the genetic algorithm works to find the most probable solution for optimization problems that cannot be solved by traditional methods [47].
The demand forecasting problem is an optimization problem that cannot be solved by traditional methods. The main aim of this study is to determine 6 forecasting methods combining coefficients for 50 selected products. All coefficients could be changed between 0 and 1 with a decimal. There is a large solution space, and it is almost impossible to find the right coefficients in this solution space by using linear methods. This study is intended to determine the most accurate coefficients to be able to predict with the most accuracy which has the minimum mean square error (MSE). Therefore, the problem cannot be solved by conventional optimization methods. For this reason, a metaheuristic method could be used, so the GA method was used in the proposed hybrid demand forecasting model.
3.2.5. Proposed Hybrid Forecasting Model: Cluster-Based Genetic Algorithm (CBGA)
Nowadays, demand forecasting methods combining inside of a single use are frequently preferred. For this reason, the proposal of combining demand forecasting methods with certain weighting coefficients is considered in the study. While combining demand forecasting methods on e-commerce, it is taken into account that there may be three different scenarios. These scenarios are:
- Creating a separate forecasting optimization model for each product: Because there are too many products, it is a long computational process and needs to be repeated continuously. It can be solved with linear optimization tools. However, high commercial packages may be needed. The optimization of the result it will produce is locally certain.
- Creating a common forecasting optimization model covering all products: The result it produces can be found quickly. There is a single combination formula for all products, so it is predicted to perform worse than the first case.
- Creating a predictive optimization model for clustered products: It is possible to give both fast and successful results. Since products with similar structures are clustered together, the performance of the joint estimation formula to be established will be quite high compared to the previous models.
If we consider demand forecasting as an optimization problem, the objective function of it will be forecast accuracy or error. In the study, accuracy measurements such as the MSE (mean square error) value were used.
While optimizing demand forecasting, two different GA solutions are compared. These two solutions are:
- Optimizing demand forecasting on a product basis;
- Optimizing demand forecasting on a cluster basis (CBGA).
Demand forecast optimization model by minimizing the MSE:
where is the selected product count from the product cluster for the optimization problem, and is the mean squared error for the product . The MSE is defined by in here with
where is the product count, is the period count, which is based on this problem, is the actual sales volume for product at period , and is the final forecasting sales volume for the same product.
For minimizing the optimization problem, some constraints should be given for providing the right solution mathematically:
where is the forecasting method number, is the forecasting sales volume for product at period by using method , is the combined weight of this forecasting, and is the hybrid forecasting sales volume for product at period . When the model is constrained by because it is equal to or higher than zero because of the negative forecasting sales volume is not intended.
where every method’s combined weight must be between 0 and 1.
While the forecasting sales volume must be equal to or greater than zero,
shows that at least 2 or more forecasting periods must exist for the problem scope.
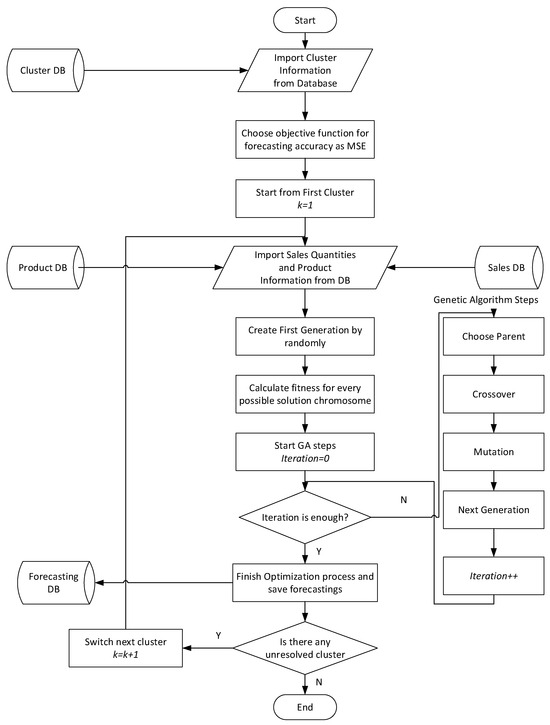
The proposed model in this study, a flow with a structure as in Figure 1, is to find solutions for many products at the same time. As can be seen from here, both descriptive information about the products and information on sales and the competition enable us to cluster the products, and it is thought that the result will be improved by running GA as a result of the clusters obtained.
Figure 1.
Proposed CBGA model: cluster analysis and demand forecasting with GA.
In the scenario proposed in Figure 1, demand forecasting optimization is targeted on a cluster basis for the sales of selected e-commerce products. Traditional GA steps in the proposed model, cluster-based demand forecasting, have been restructured for optimization by adapting them to the demand forecasting structure in e-commerce. Suggested GA steps for cluster-based demand forecasting:
Starter Population: The population size was selected between 50 and 200 by increasing the steps to 50.
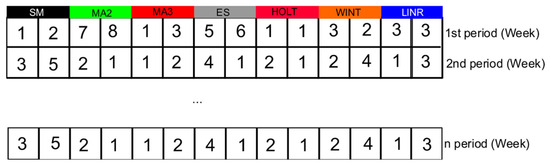
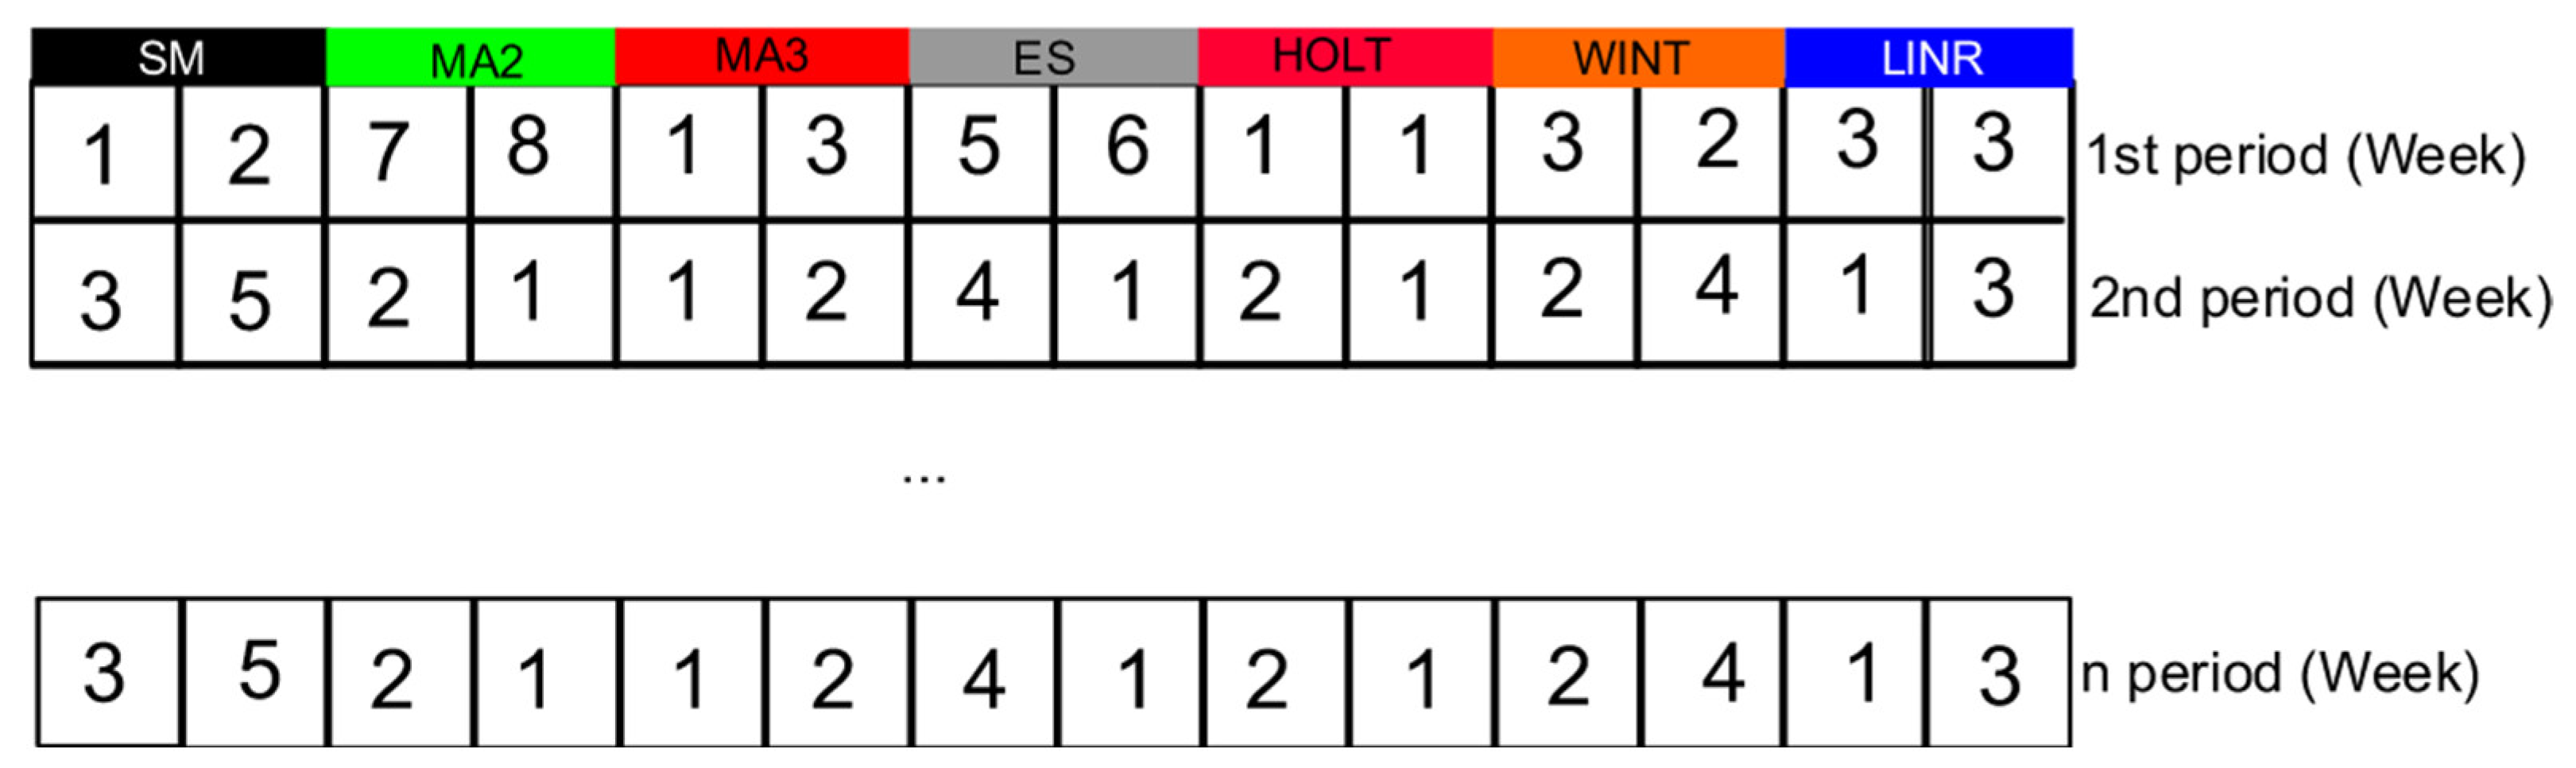
Solution Representation: A gene sequence was generated for each cluster. In the proposed chromosome structure in each horizon, it is decided how much the weight of each method will be. For example, considering a 5-horizon prediction, considering that there are 7 different methods for each horizon in the chromosome structure, every method has two boxes by defining the weight between 0 and 99, so every chromosome with 5 × 7 × 2 = 70 gene lengths will be formed. If the binary variable weight (1.0) is to be used, this value will be 5 × 7 = 35. The chromosome representation is given in Figure 2.
Figure 2.
Solution representation—structure of the chromosome.
- Calculation of fitness: Fitness is calculated by replacing the forecast weights shown in Figure 3 in the relevant horizons and calculating the final forecast values for that horizon. As a result of this calculation, fitness can be calculated by taking into account the MSE, MAPE, and MAE values. The MSE value was preferred in the study for testing.
- Parent selection: The roulette wheel method is preferred. According to this method, the chance of selection of each chromosome in the chromosome pool is shared in proportion to its fitness value. With the randomly generated decimal value between 0 and 1, it is decided which chromosomes will be the parent chromosomes.
- Crossover: Single-point crossover is used as the crossover method. However, as the number of horizons increases, the number of genes will also increase. Therefore, it will not be possible to reach good solutions in the solution space, or it will be necessary to make a large number of iterations. For this reason, crossover was applied by considering the matrix structure. In this context, as seen in Figure 4, first a random point is selected, the chromosome is divided into two separate matrices by going down the matrix columns, and then a new individual is formed with a piece from the mother and father. The steady-state crossover method was chosen. That is, the crossover is performed at each iteration.
- Mutation: According to the model, whether or not each gene mutates is carried out by considering the mutation rate. For the mutation rate, 10% was chosen for the lower limit, and the upper limit was increased by 10 steps up to 100%.
- Generation changes and grid search: After the child chromosomes are produced, they are added to the place of the two worst individuals in the chromosome pool. Another issue in GA is parameter selection. For this, a grid search application was made for which the most suitable setting parameters were determined.
Figure 3.
Crossover operation.
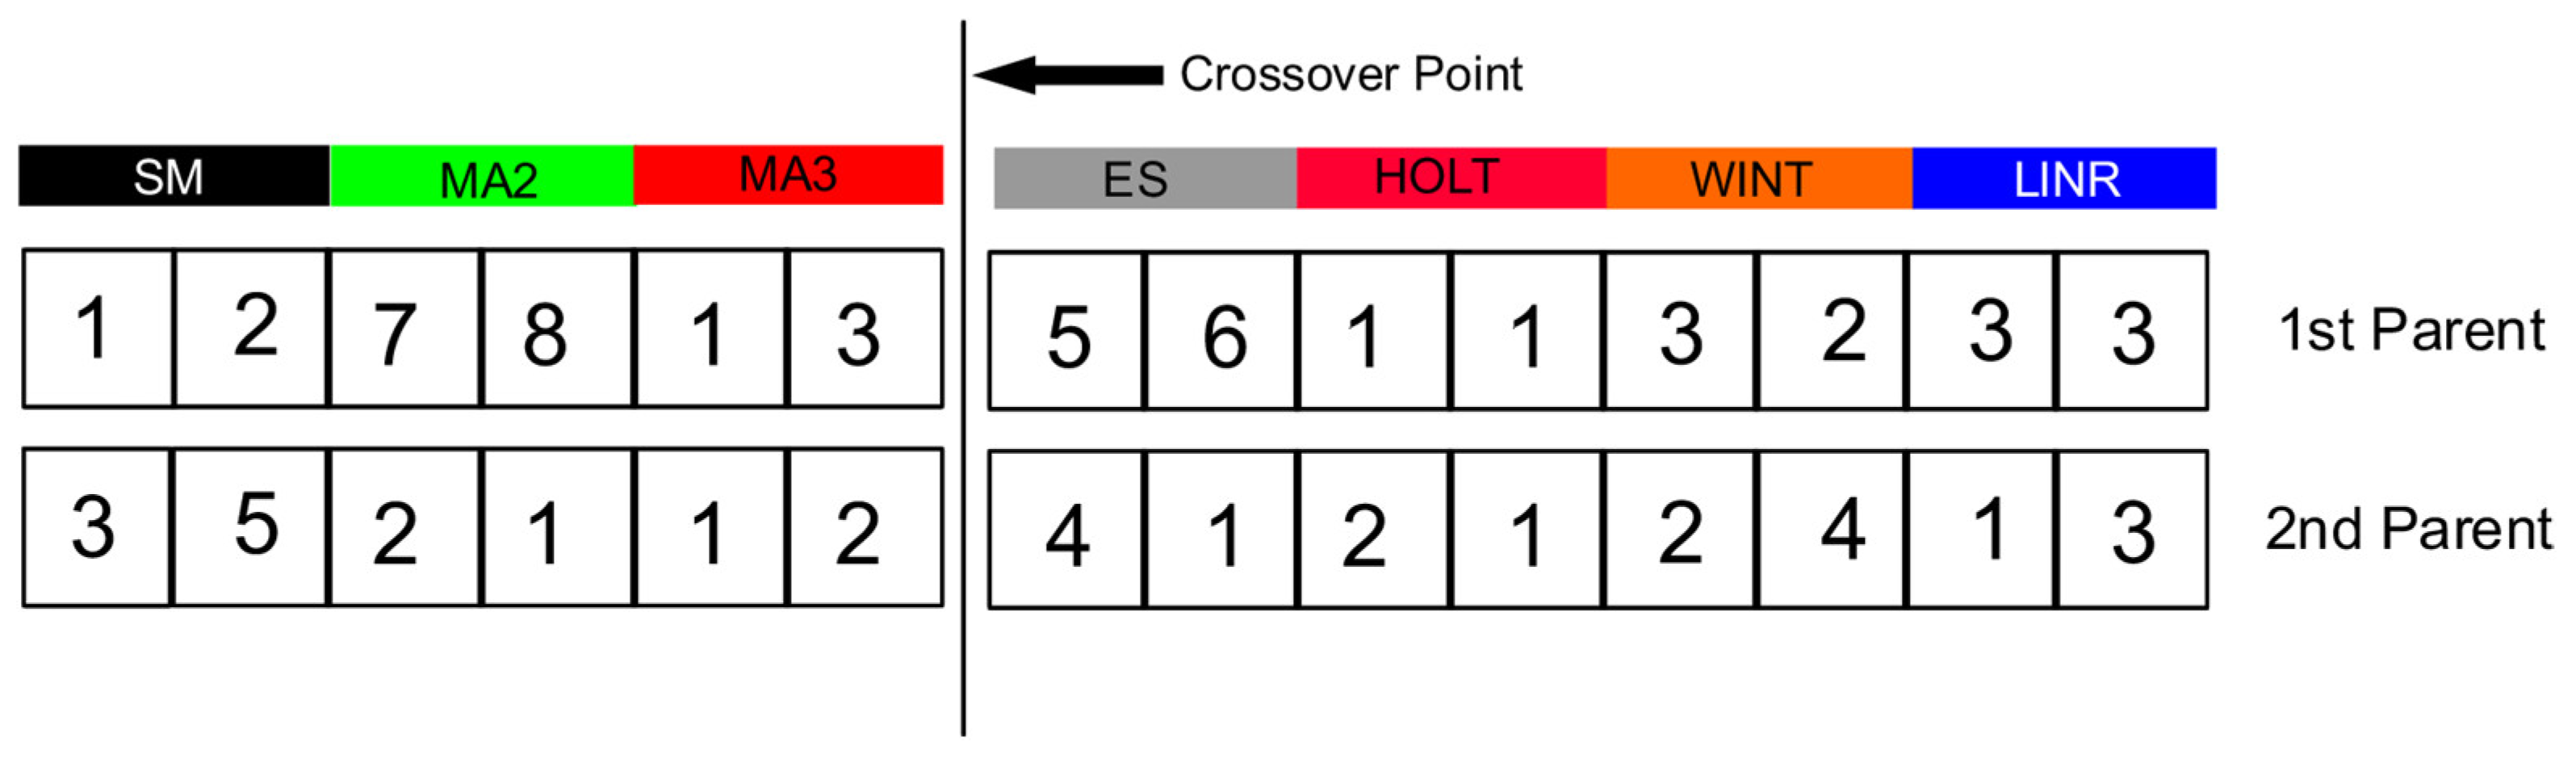
Figure 4.
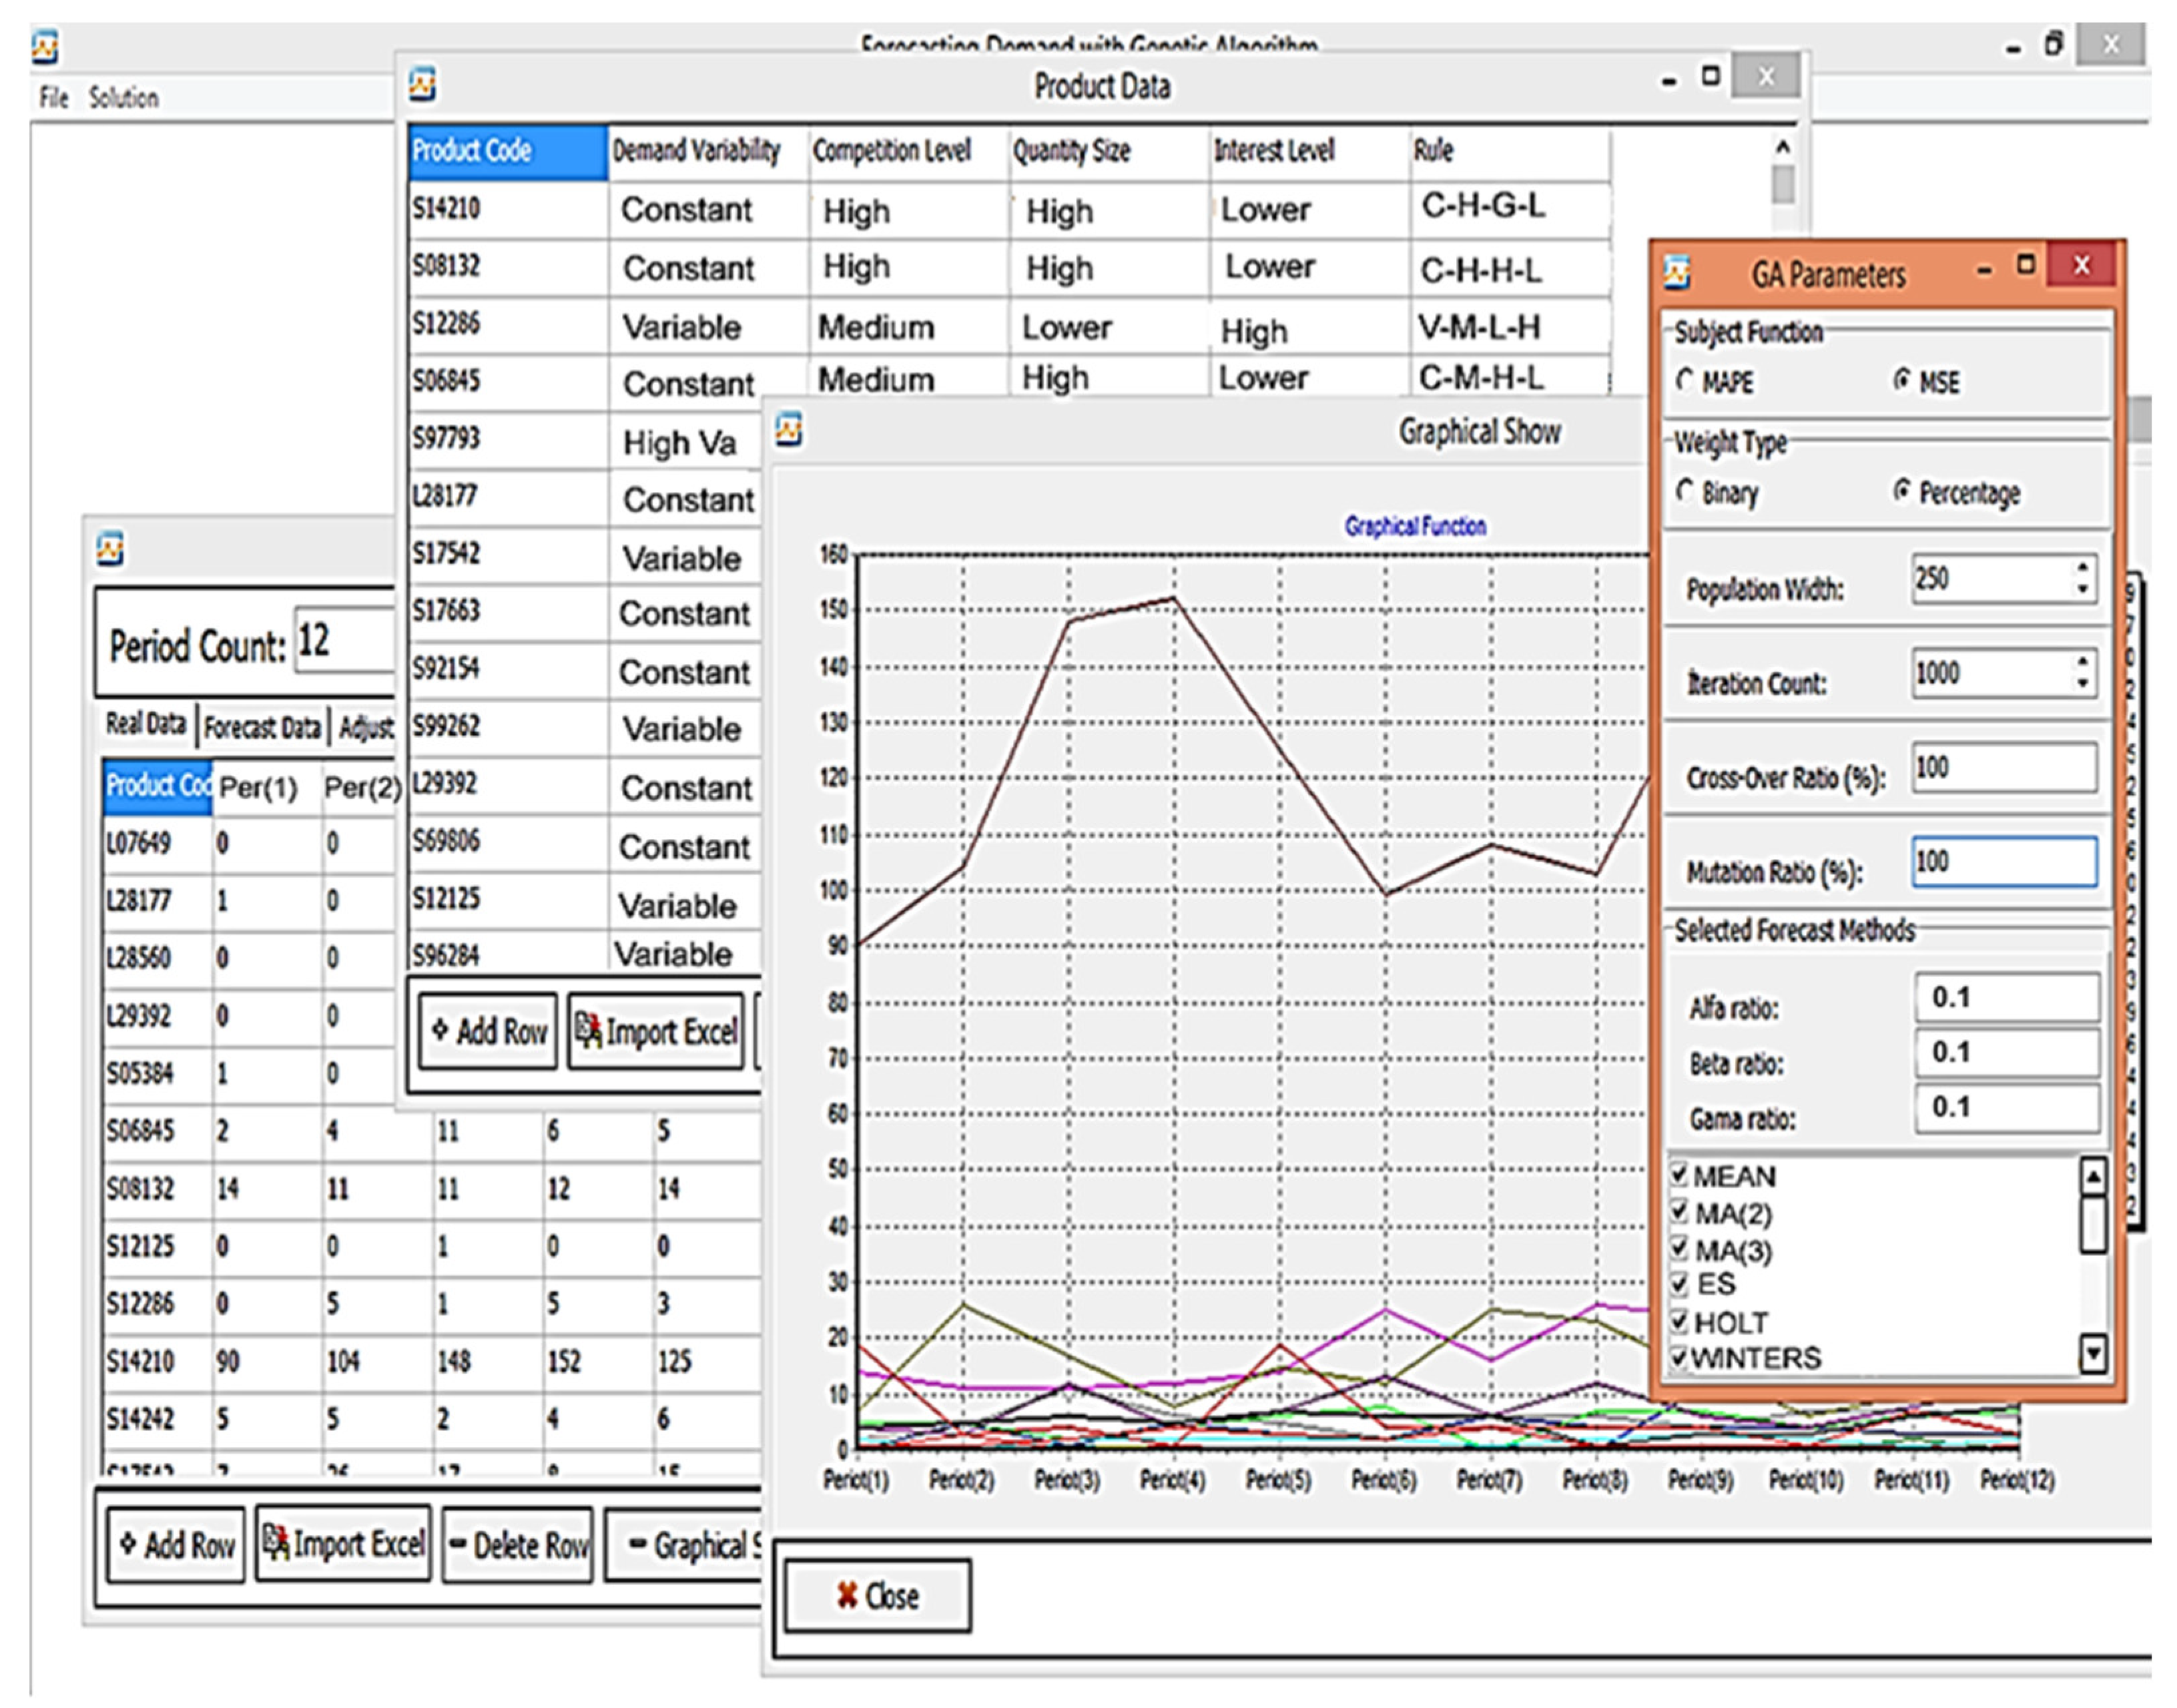
Developed software.
3.2.6. Developed Software
Since it is not possible to develop the proposed model with the existing software on the market, software was developed using the Delphi 7 programming language to test the success of the proposed hybrid method. This software receives sales data from a XLS file and can display both single-method results and the suggested model success results by running the proposed model. A section of the software developed is shown in Figure 4.
4. Results
4.1. Cluster Analysis Findings
For cluster analysis, first, 13 input variables were selected. These variables and their values are presented in Table 3 for every selected product.
Table 3.
Selected variables for cluster analysis.
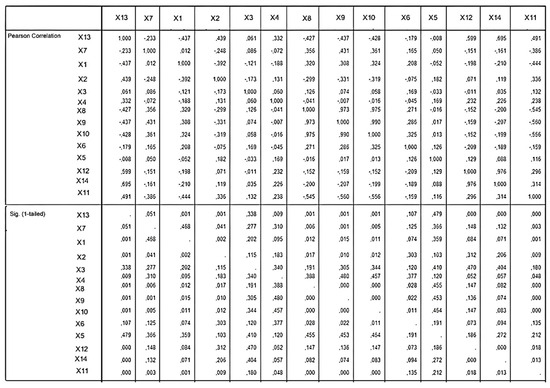
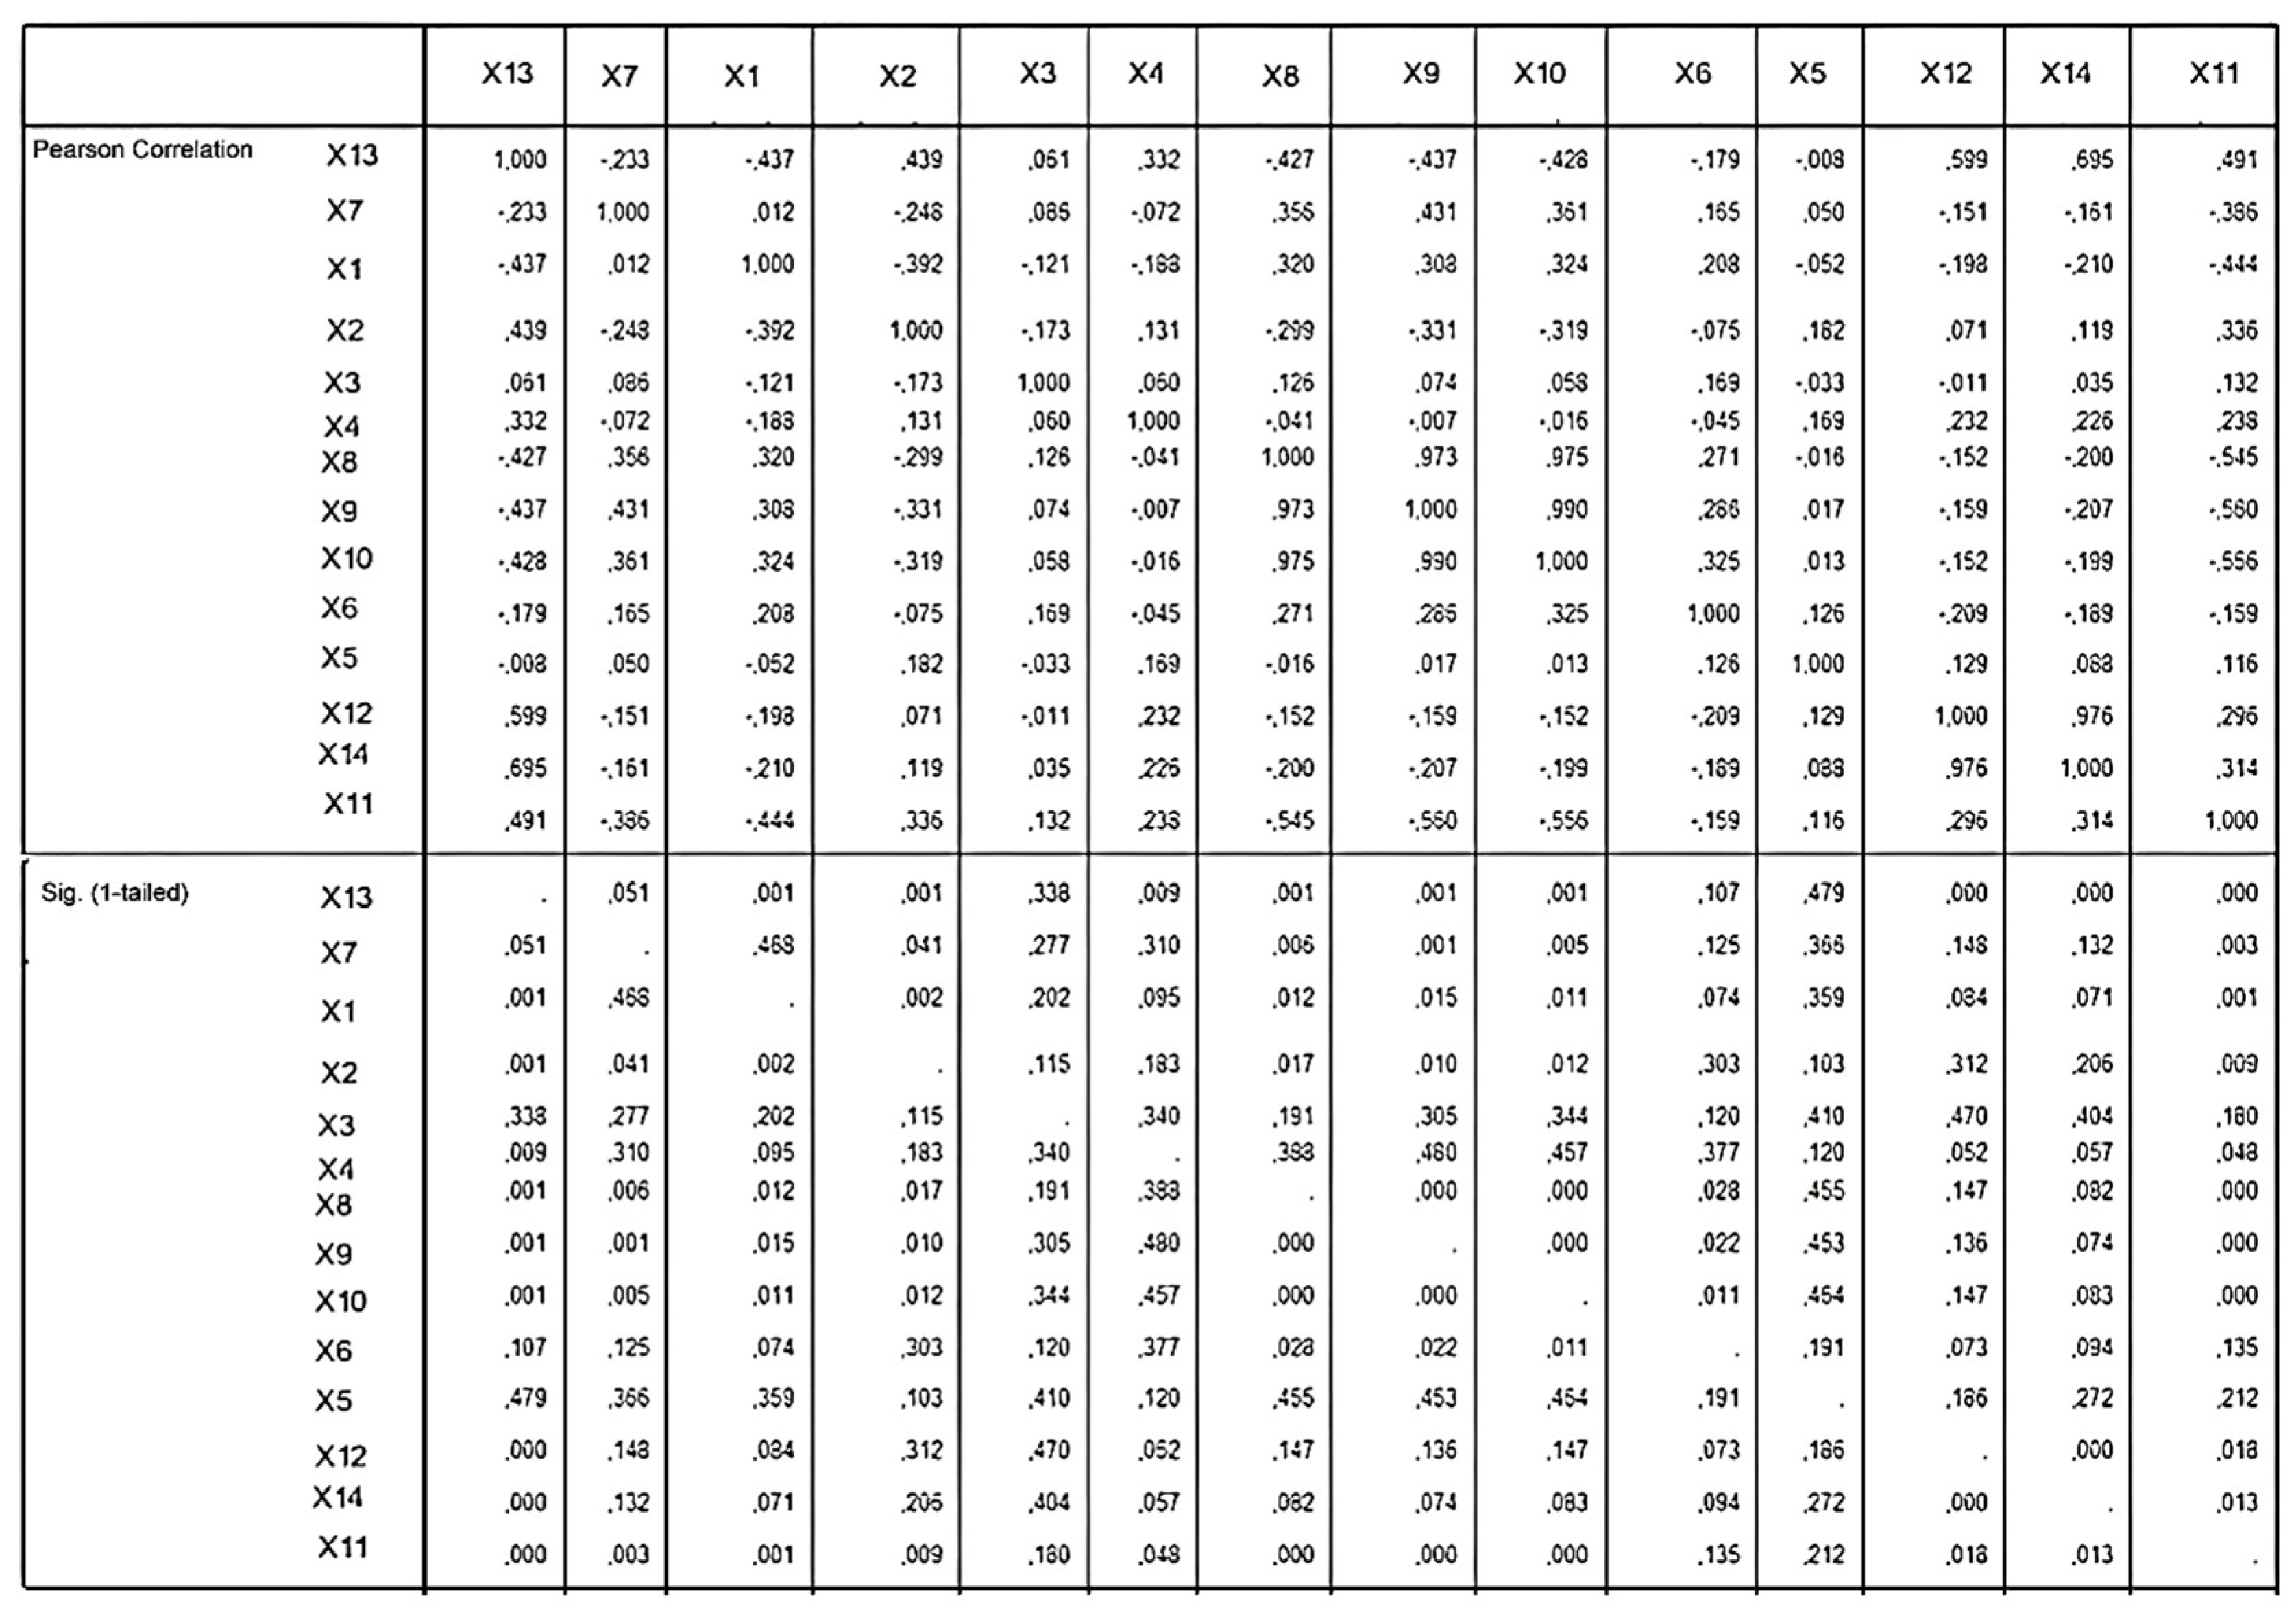
A statistical correlation analysis was also made for the selected variables’ data with the SPSS v22.0 software package. Figure 5 shows the results of the correlations among the data variables.
Figure 5.
Data correlation analysis results with SPSS.
If Figure 5 is examined, it is seen that there is generally no correlation between the variables. On the other hand, it is thought that there is a correlation between some variables. In some of the studies in the literature, it is thought that the coefficients should be below 0.70; otherwise, there is a correlation between the coefficients among the variables. In some studies, this value is accepted as 0.90, and the coefficients above are considered to have a high correlation between the two variables. Considering the value of 0.90, it can be seen that there is a correlation between the variable data of minimum price, XYZ.com price, and maximum price. The fact that these variables are correlated with each other is an expected situation due to their relationships. It is assumed that this situation will not have any effect on the method to be applied.
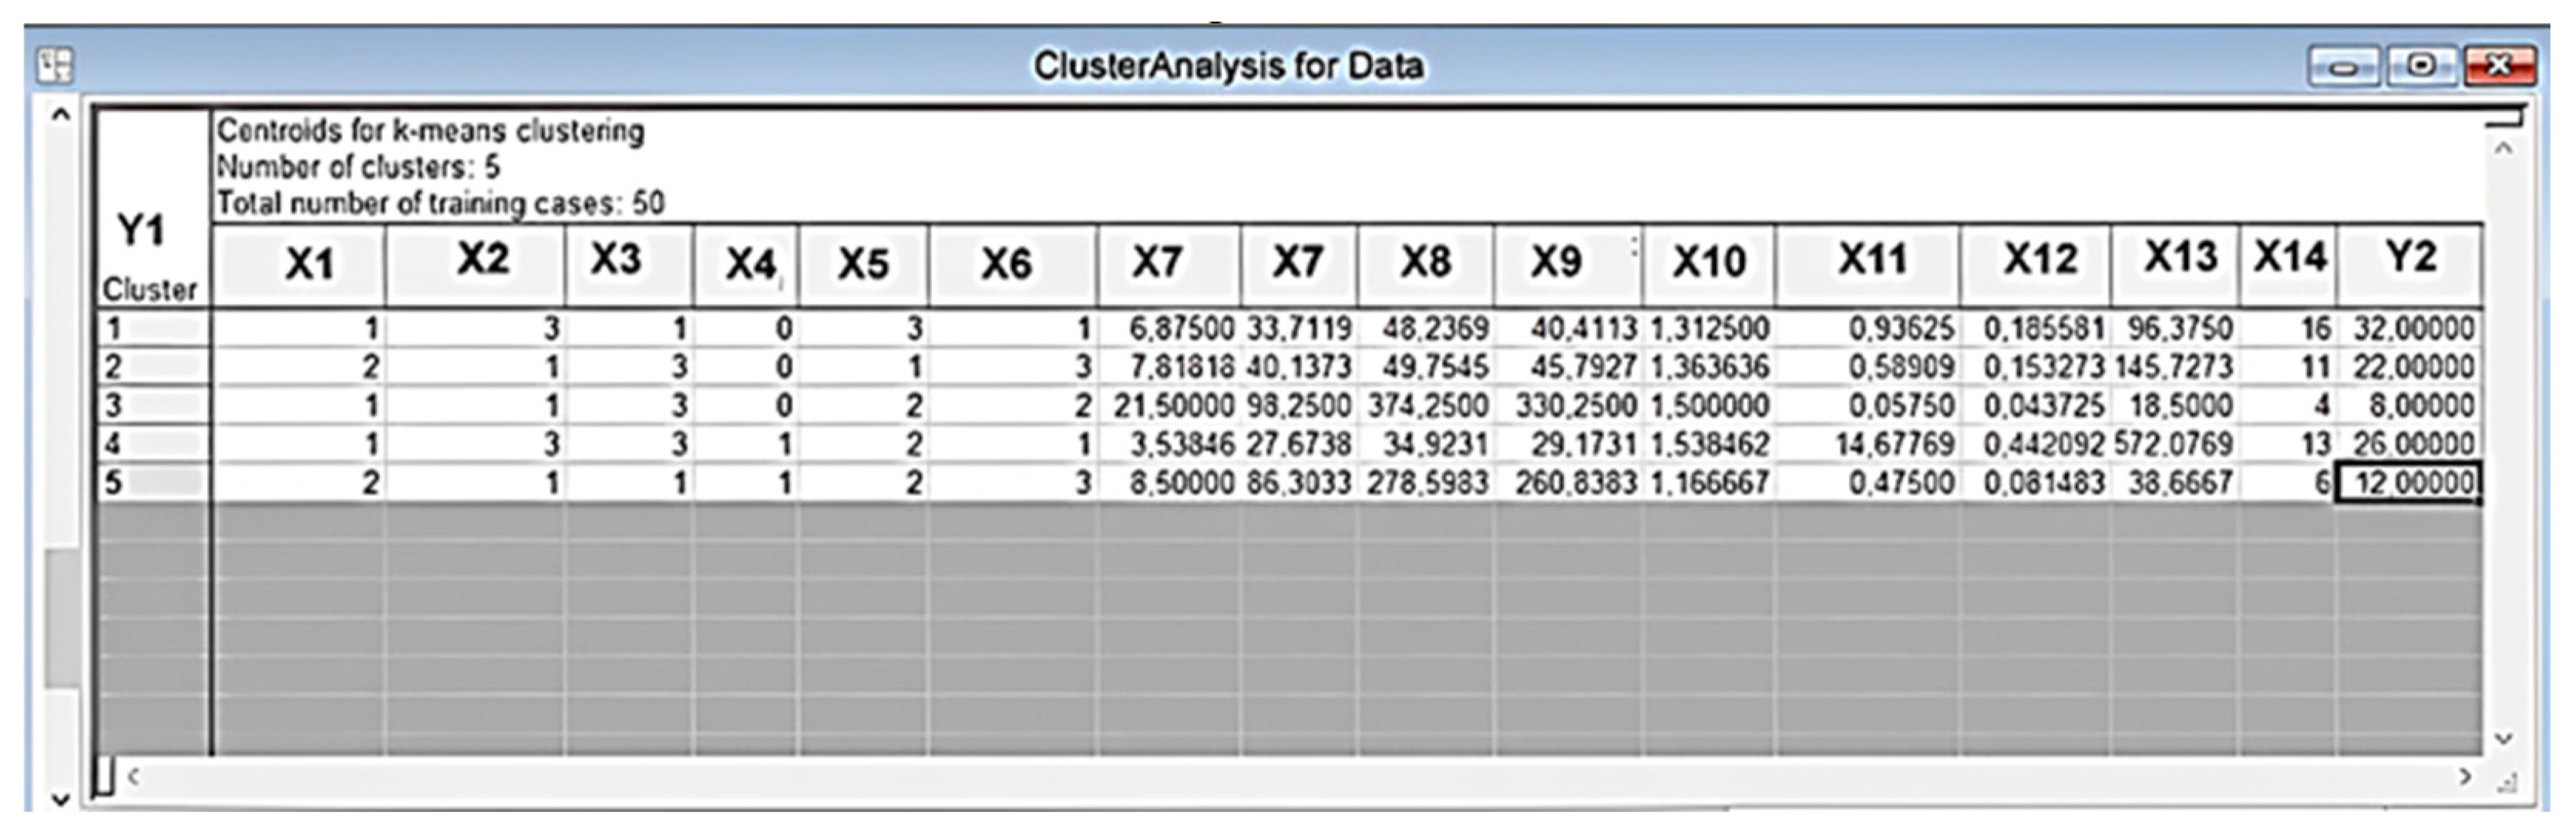
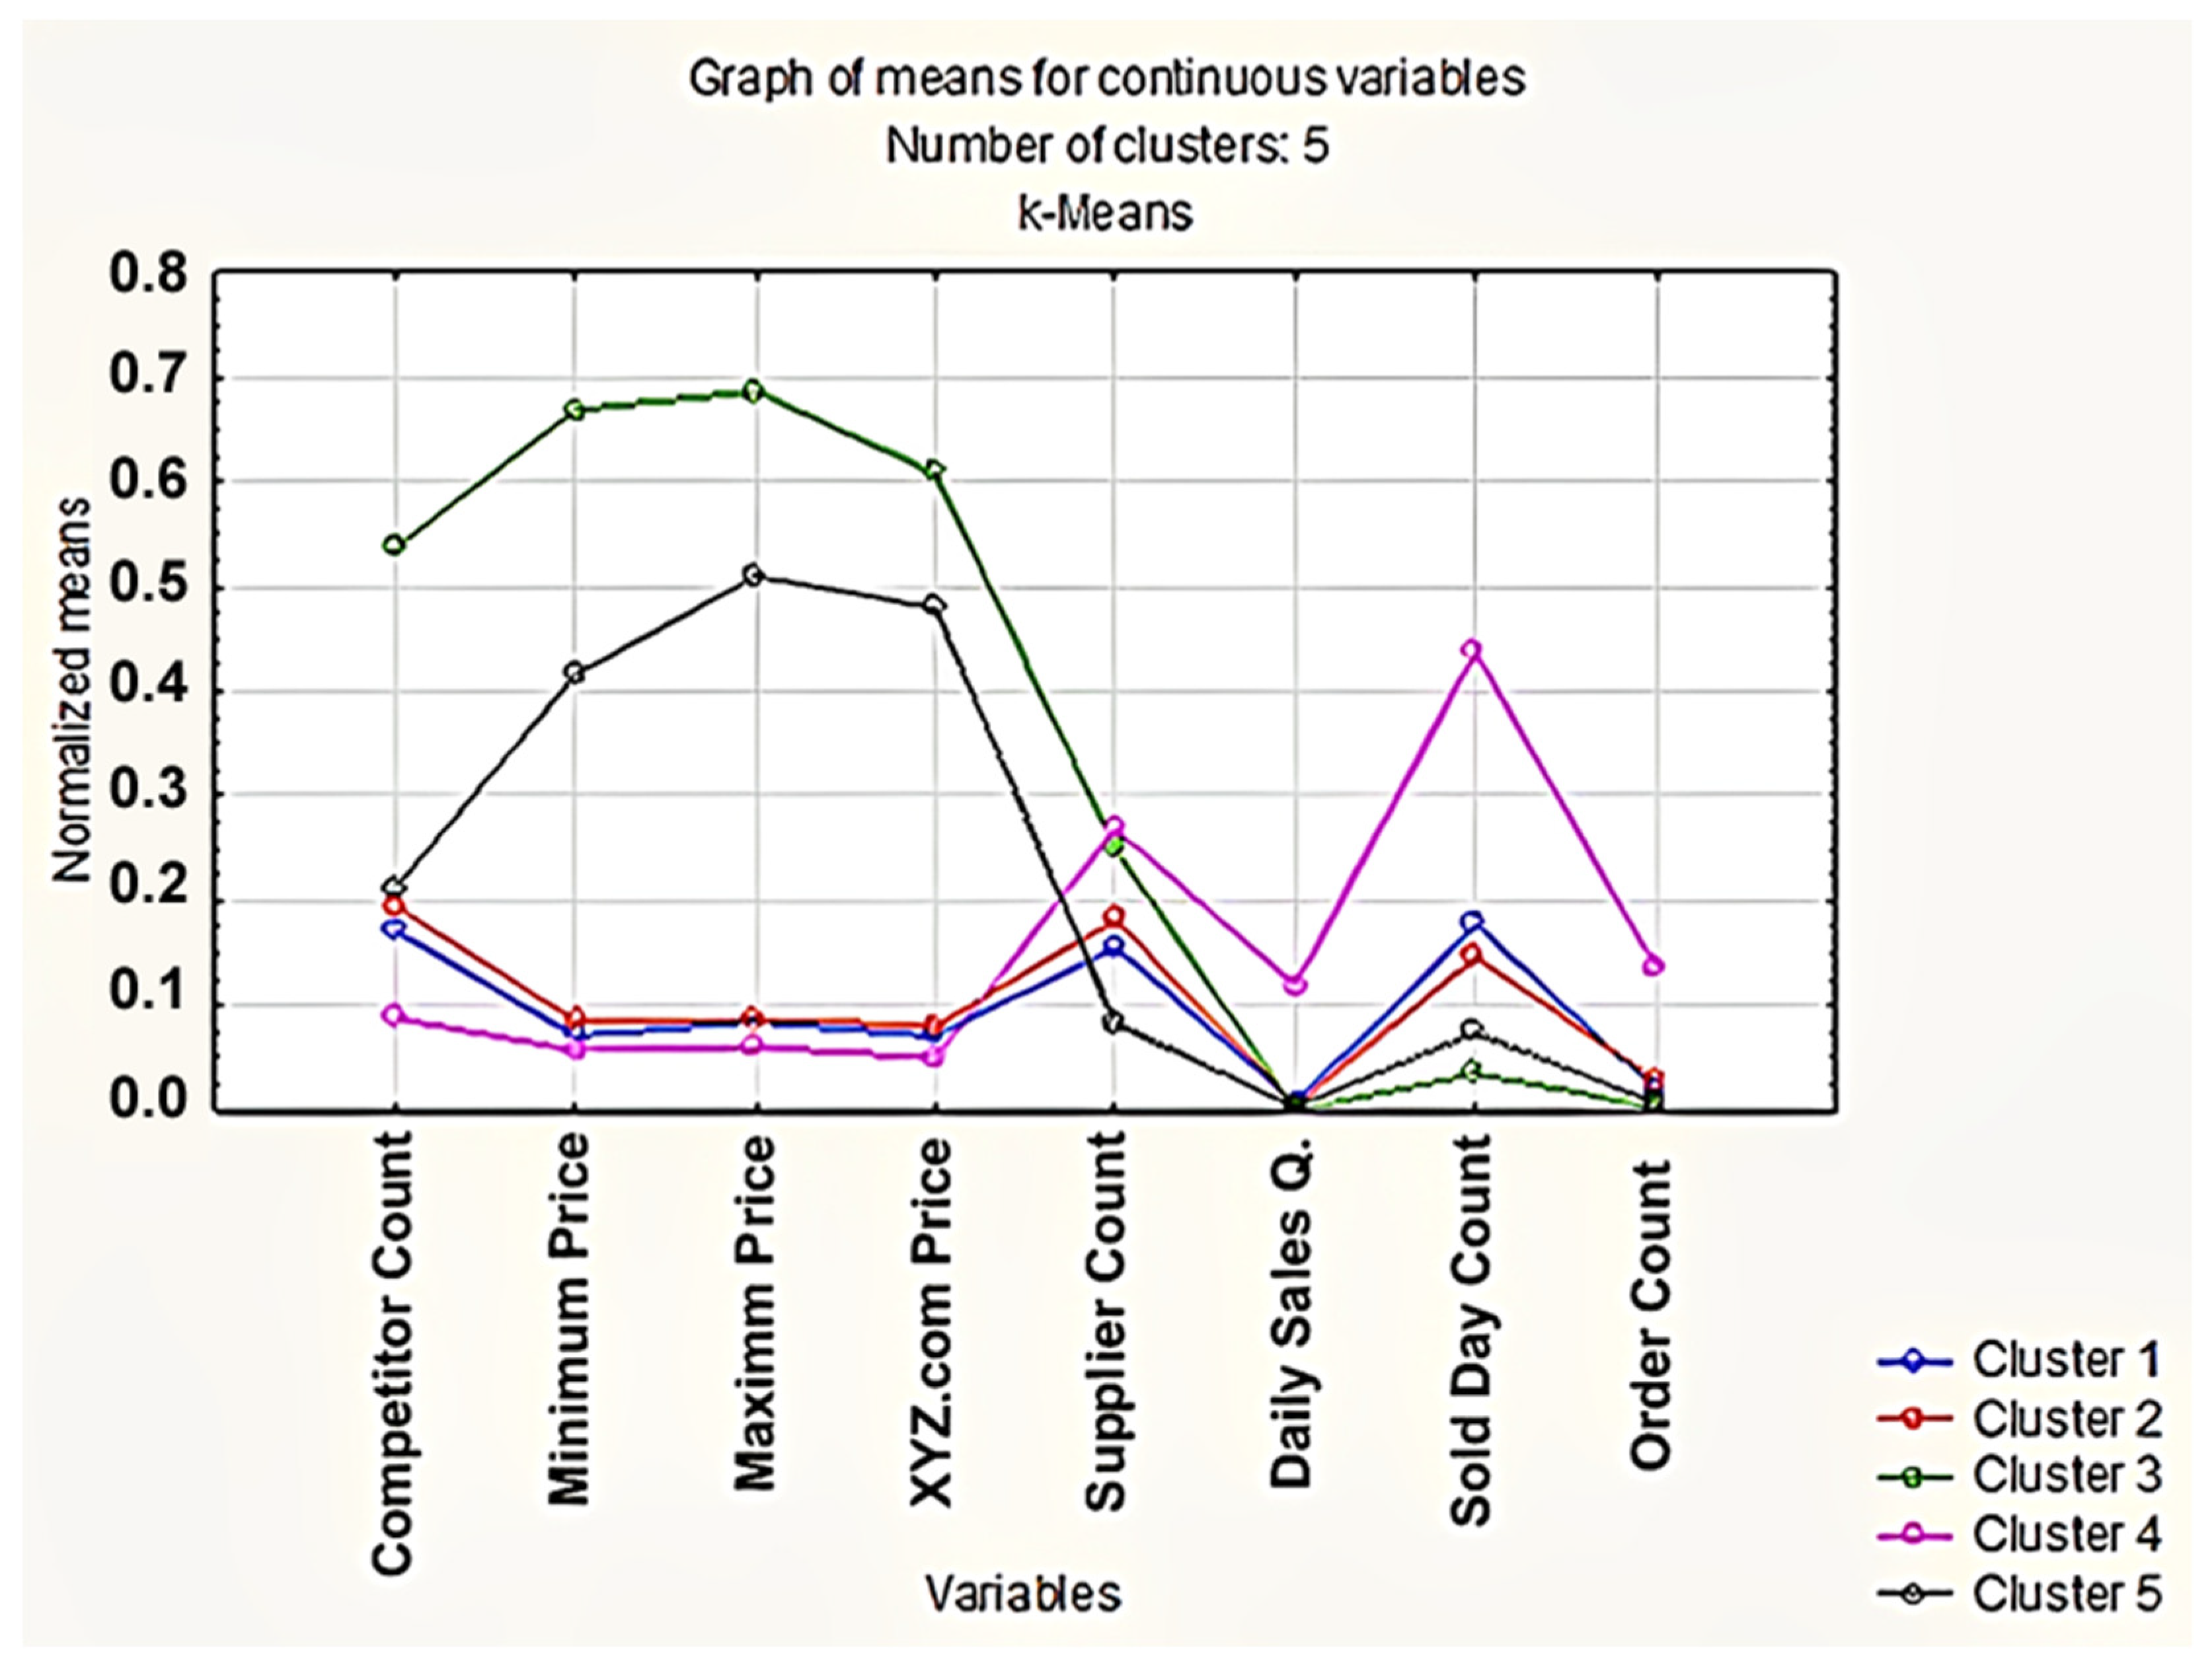
In the dataset, since 50 products represent the number as the n value, the k value is the number of clusters, which is determined as five. In other words, the products will be separated into five separate clusters at this stage by the cluster analysis method. Offered by the Statistica v13.3 statistical analysis package program, some of the variables included in the cluster analysis performed with the cluster plugin are categorical and some are continuous variables. The centroid means of the clusters produced (Y1 and Y2) can be seen in the outputs of the Statistica package program in Figure 5. It is seen that the first cluster has the highest product count, with 16 products according to the Y2 output. It is followed by products with a high-order frequency with 13 products. In Figure 6, the mean values of the variables based on clusters are also given.
Figure 6.
Product cluster analysis and centroid means.
Figure 7 shows the cluster separation according to the selected variables. Cluster 4 (Cluster 4) shows the products with the highest quality in terms of sales performance.
Figure 7.
K-means plots for five clusters.
4.2. Selection of Genetic Algorithm Tuning Parameters with Grid Search
Methods such as genetic algorithms are classified as evolutionary algorithms in the literature. The solution performance of these algorithms changes according to the selected parameters. According to Karafotias et al. (2014), the success of evolutionary algorithms depends on the correct selection of parameters [48]. For a good performance, the parameter values should be chosen carefully. This is also called parameter value tuning. The optimal parameter values can also change in each run of evolutionary algorithms. This is known as the parameter control problem, and it may be necessary to do many runs or replications to solve it.
If the required maximum is known to be within a finite area defined by the upper and lower bounds of each of the independent variables, then the grid search method can be applied. This method systematically searches all of the possible states. For this purpose, one must set up a grid over the area of interest and evaluate the objective function at each node of the grid. After the computation of the objective function values in all the nodes of the grid, we might interpolate and find a maximum between the gridlines [49].
Therefore, in this study, a grid search algorithm was used for parameter tuning. Performing a grid search when finding the correct parameter settings affects the performance in different scenarios, and the most ideal parameter values were investigated. In this model, the method weights were accepted as binary (0 or 1), 30 replications were made for comparisons, and the average error values were taken into account. At this stage of the study, the MSE value, which is one of the important performance values for demand forecasting, was used for the purpose—namely, fitness calculation. The parameter settings in the study are:
- The possible mutation rate is set to (10, 20, 30……90, 100).
- The possible number of iterations is set to (50, 100, 150).
- The possible population size is set to (50, 100, 150).
Considering 90 possible scenarios for the sales data, the GA was run, and its forecasting ability was measured using the MSE value. It is possible to see some of these scenarios and their results in Table 4.
Table 4.
Scenario results for the GA parameter selection.
As seen in Table 4, the case where the mutation rate is 40%, the population size is 50, and the number of iterations is 150 represents the GA solution with the best minimum error. The crossover ratio was not chosen as a tuning parameter in the study. In a few studies in the literature, it was seen that this ratio has no effect, or it was concluded that it was less effective than the other parameter values. For example, Rexhepi et al. (2013) said that the mutation rate is beneficial in small population sizes [50]. However, they concluded that the mutation rate in large populations slightly improves the solution. For this reason, it was thought that the mutation rate would have a significant effect, since the population size was small compared to the selected parameter values. Boyabatlı and Sabuncuoğlu (2001), in their work, tried to determine the main effects of ANOVA by performing several trials for the parameters of the crossover rate, mutation rate, population size, and number of iterations [51]. In the dataset they tested, they stated that the crossover rate parameter had an insignificant effect, and the population size had a negative effect. In the machine scheduling problem set they examined, they also determined the best mutation value as 40%.
4.3. Comparing MSE Forecasting Accuracy between a Single Model and Combined Model with GA
Using the results of genetic algorithm parameter selection, the parameters to be used for the demand forecast values to be optimized for the e-commerce sales dataset were decided. By using these parameters, a comparison was made between the single model MSE accuracy value and the combined model with genetic algorithm MSE accuracy values. For 22 randomly selected products, the MSE values are shown in Table 5.
Table 5.
The success of the methods alone and non-clustered GA comparisons.
In Table 5, while, without clustering, the GA model shows the best forecasting performance in 16 out of 22 products, it plays the role of the second-best forecasting method in 3 products according to the single model performance.
4.4. Comparisons between GA and Proposed CBGA
As you see in Table 4, some products’ forecasting errors are very high. For example, the product coded S14210 is a good example for this. When we look at the sales volume of this product, we can see that it has sold with a high sales volume. This shows the need to perform optimization estimates on a cluster basis. For GA, it is thought that the forecast performance may be adversely affected as it tries to model a forecast structure that will work well for many products at the same time. For this reason, GA prediction success was measured in the clustered products for the same parameter values by passing to the second scenario as the proposed model CBGA. It is possible to see the estimation performance according to the MSE values of the products in Cluster 1 in Table 6 before and after clustering. According to cluster analysis, Cluster 1 consists of 16 products in Table 6.
Table 6.
Change in MSE value comparisons before clustering and after at Cluster 1 products.
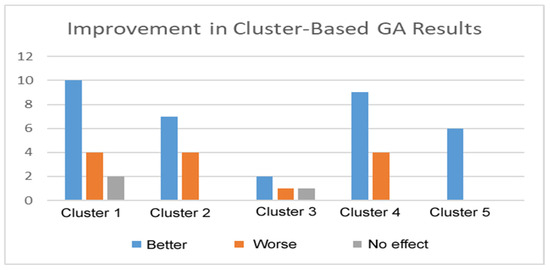
It can be seen that the CBGA MSE accuracy value was better than the GA model for 10 products out of 16 products.
Another cluster, cluster 5, consists of six products. Table 7 shows the change in the estimation performances of the products included in cluster 5.
Table 7.
Change of solution before and after the cluster 5 analysis.
Improvements were achieved in all products included in the cluster given in Table 6. There was an improvement of around 10–15% in many products when the CBGA model was used. Improvement of the CBGA can be seen at all clusters with increased product forecasting success. The highest was experienced in Cluster 5. In Figure 8, it is possible to see a summary the GA and CBGA comparison graph showing the general situation. The vertical axis shows the product numbers for the relevant cluster.
Figure 8.
Comparison between non-clustered GA and CBGA-based MSE values.
When Figure 8 is examined, the cluster-based genetic algorithm model, CBGA, is a method that increases success according to the MSE performance criteria. The forecast was even better in 40 out of 47 products for the 50 selected products. As there were no sales data for the other three products, a comparison could not be made.
5. Discussions
In their review study, Karl (2024) examined the prediction models used in the field of e-commerce in the literature [52]. According to this review, the algorithm used most frequently is the random forest algorithm, followed by support vector machine neural networks, logistic regression, gradient boosting, ordinary least squares regression, adaptive boosting, linear discriminant analysis (LDA), and CART. The papers focusing on return volume used time series forecasts like (autoregressive) moving averages (MA), single exponential smoothing (SES), and Holt–Winters smoothing (HWS) more frequently than ML algorithms. The literature review in this field showed us that a hybrid model such as the one in this study has not been used before and that the work done and the results obtained in this sense are important.
In this study, 15,525 sales data from 53 weeks for 50 selected products sold by a popular B2C company in Turkey were used. This study’s scope is e-commerce that has high product variation and has almost ten thousand products. Demand forecasting solutions for this sector must be dynamic, easily applicable, and more successful. It would be correct to evaluate the basic problem that this study addresses with the proposed model in two stages. The first stage is to investigate the contribution of hybridizing and using forecasting models, which have examples in the literature for different problems, to forecasting success. In this context, undoubtedly, the main problem is the selection of weight ratios. To test whether the right decision has been made in this regard, it is necessary to determine an objective variable and turn it into an optimization problem with certain limits. However, when the solution space is considered, it is seen that traditional optimization models are insufficient to solve the optimization problem addressed in this study. In this case, it was necessary to continue by choosing a metaheuristic optimization method, and the genetic algorithm method was used in this regard. The first stage results showed that the prediction performance was highly good. For higher success, different metaheuristics in the literature, such as tabu search, simulated annealing, or ant colony algorithms, can also be considered in future studies.
The second stage of the study is to find out to what extent the proposed CBGA model, which includes the k-means cluster analysis technique in the forecasting process, can improve the success achieved by the genetic algorithm. The results showed that the proposed new model has greatly improved the genetic algorithm solution, which provides good results just like an incomplete complement and optimizer. Undoubtedly, this is how the results turned out for the selected dataset. Considering more products here and expanding the data scope may perhaps deepen the algorithm results.
6. Conclusions
In the e-commerce sector, which has a dynamic and variable structure, managers have to make and implement decisions at the same speed. Therefore, there is a need for solutions that will contribute to the decision-making processes of managers in this field. Demand forecasting has been one of the tools widely used by managers in making decisions in finance, industry, services, energy, and other sectors. Using the forecast outputs, inventory decisions, purchasing policies, marketing activities, and production activities are also directed. On the other hand, as far as it is examined, demand forecasting studies in the field of e-commerce have also been found in the literature. In the studies in the literature, time series, analytical methods, artificial neural networks, and regression-based methods have been applied for demand forecasting. While some studies focused on combining method estimations, some studies used individual estimation methods on a single-product basis. However, it is thought that most models proposed in the literature will be difficult to implement in the e-commerce sector, and low success will be achieved due to the huge multiproducts. Undoubtedly, the characteristics of the sector mentioned in the original contributions section are also effective in this. This study was built on the proposal of creating a hybrid forecasting model, which is suitable for the structure of the sector and an approach that has become widespread in demand forecasting in recent years. By using the proposed model in this study, which uses genetic algorithm and cluster analysis as one of the data mining techniques, test results with real e-commerce sales data showed that the hybrid model CBGA both produces faster predictions and increases the prediction performance for a large number of products. In testing the proposed cluster-based GA forecasting model, 15,525 sales data from 53 weeks for 50 selected products sold by the selected B2C company in Turkey were used. In this model in which a large number of categorical and numerical variables are used, the prediction performance has increased in 40 of the 50 selected products. Moreover, the estimations made with the GA model have gained more success than other methods. The forecast horizons are selected as weekly. According to the results obtained:
- In the cluster analysis in which the k-means method was used, it was concluded that this method also increased the estimation success of GA for MSE values. Therefore, when the non-clustered and clustered conditions of 50 products were compared, the proposed CBGA performance increased in 40 out of 47 frequently sold products after cluster analysis. Especially in almost all products with high-order volumes, GA did very well and recovered.
- At the same time, the grid search method was preferred in the study to obtain the correct values of the GA tuning parameters to increase the solution performance.
- In the study, demand-based values and e-commerce-based characteristic values were taken into account to obtain a better solution for the demand forecasting problem. It was also seen in the tests that this suggestion was successful.
- The fact that the coefficients created by the proposed CBGA method can be updated in each horizon improves the demand forecasting performance and prevents the repetition of past errors.
Today, electronic commerce, which has replaced traditional commerce websites, should prefer models that are suitable for their dynamic structures. Also, software has been developed in this study, and working by establishing a connection between the developed software and e-commerce sites will help site managers make more dynamic and successful decisions.
Despite the success achieved in this study, it must be said that there are some limitations. The first of these is the number of products selected. It is estimated that there are at least 10,000 different products on an average e-commerce site. Therefore, the number of 50 products represents a very small audience to evaluate the success of the model. On the other hand, this study was based on weekly time horizon forecasts. However, on some e-commerce sites, decisions may change even daily. Finally, in the e-commerce sector, only a single website’s data were used. More website data, especially from different product groups, may also be required to test the success of the model.
A limited number of demand forecasting models was used in this study. It would be appropriate to increase the number of models taken into consideration. In future studies, the success of prediction can be increased by integrating models such as ARMA, SARMA, ARIMA, or machine learning.
Author Contributions
Conceptualization, H.O.Y., M.Ö. and S.A.Y.; methodology, H.O.Y. and M.Ö.; software, M.Ö.; validation, H.O.Y., M.Ö. and S.A.Y.; formal analysis, H.O.Y., M.Ö. and S.A.Y.; investigation, H.O.Y., M.Ö. and S.A.Y.; resources, M.Ö.; data curation, M.Ö.; writing—original draft preparation, M.Ö. and S.A.Y.; writing—review and editing, H.O.Y. and S.A.Y.; visualization, M.Ö. and H.O.Y.; supervision, H.O.Y. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data presented in this study are available on request from the corresponding author. The data are not publicly available due to privacy.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Zwaas, V. Electronic Commerce: Structures and Issues. Int. J. Electron. Commer. 1996, 1, 3–23. [Google Scholar]
- Du, X.F.; Leung, S.C.H.; Zhang, J.L.; Lai, K.K. Demand forecasting of perishable farm products using support vector machine. Int. J. Syst. Sci. 2013, 44, 556–567. [Google Scholar] [CrossRef] [Scilit]
- Dinesh, S.; MuniRaju, Y. Scalability of e-commerce in the COVID-19 era. Int. J. Res. GRANTHAALAYAH 2021, 9, 123–128. [Google Scholar] [CrossRef] [Scilit]
- Ingle, C.; Bakliwal, D.; Jain, J.; Singh, P.; Kale, P.; Chhajed, V. Demand Forecasting: Literature Review on Various Methodologies. In Proceedings of the 2021 12th International Conference on Computing Communication and Networking Technologies (ICCCNT), Kharagpur, India, 6–8 July 2021; pp. 1–7. [Google Scholar] [CrossRef] [Scilit]
- Armstrong, J.S. Research Needs in Forecasting. Int. J. Forecast. 1988, 4, 449–465. [Google Scholar] [CrossRef] [Scilit]
- Winklhofer, H.; Diamantopoulos, A.; Witt, F.S. Forecasting practice: A review of the empirical literature and an agenda for future research. Int. J. Forecast. 1996, 12, 193–221. [Google Scholar] [CrossRef] [Scilit]
- Gooijer, J.; Hyndman, R. 25 years of series forecasting. Int. J. Forecast. 2006, 22, 443–473. [Google Scholar] [CrossRef] [Scilit]
- Ludwig, O.; Nunes, U.; Schnitman, L.; Lepikson, H. Review Applications of information theory, genetic algorithms, and neural models to predict oil flow. Commun. Nonlinear Sci. Numer. Simul. 2009, 14, 2870–2885. [Google Scholar] [CrossRef] [Scilit]
- Chodak, G. Genetic Algorithms in the Forecasting of Internet Shops Demand; MPRA Paper No. 34034; Wrocław University of Technology: Wrocław, Poland, 2011; Available online: https://mpra.ub.uni-muenchen.de/34034/ (accessed on 26 June 2024).
- Sayed, E.H.; Gabbar, H.; Fouad, S.; Ahmed, K.; Miyazaki, S. A hybrid statistical genetic-based demand forecasting expert system. Expert Syst. Appl. 2009, 36, 11662–11670. [Google Scholar] [CrossRef] [Scilit]
- Huang, S.C. Integrating spectral clustering with wavelet-based kernel partial least square regressions for financial modeling and forecasting. Appl. Math. Comput. 2011, 217, 6755–6764. [Google Scholar] [CrossRef] [Scilit]
- Hasin, M.; Ghosh, S.; Shareef, M. An ANN Approach to Demand Forecasting in Retail Trade in Bangladesh. Int. J. Trade Econ. Financ. 2011, 2, 154–160. [Google Scholar] [CrossRef] [Scilit]
- Wang, X.; Petropoulos, F. To select or to combine? The inventory performance of model and expert forecasts. Int. J. Prod. Res. 2016, 54, 5271–5282. [Google Scholar] [CrossRef] [Scilit]
- Pwasong, A.; Sathasivam, S. Forecasting comparisons using a hybrid ARFIMA and LRNN models. Commun. Stat. Simul. Comput. 2018, 47, 2286–2303. [Google Scholar] [CrossRef] [Scilit]
- Chan, H.K.; Xu, S.; Qi, X. A comparison of time series methods for forecasting container throughput. Int. J. Logist. Res. Appl. 2019, 22, 294–303. [Google Scholar] [CrossRef] [Scilit]
- Moscatelli, M.; Parlapiano, F.; Narizzano, S.; Viggiano, G. Corporate default forecasting with machine learning. Expert Syst. Appl. 2020, 161, 113567. [Google Scholar] [CrossRef] [Scilit]
- Pan, H.; Zhou, H. Study on convolutional neural network and its application in data mining and sales forecasting for E-commerce. Electron. Commer. Res. 2020, 20, 297–320. [Google Scholar] [CrossRef] [Scilit]
- Moroff, N.U.; Kurt, E.; Kamphues, J. Machine Learning and Statistics: A Study for Assessing Innovative Demand Forecasting Models. Procedia Comput. Sci. 2021, 180, 40–49. [Google Scholar] [CrossRef] [Scilit]
- Mediavilla, M.A.; Dietrich, F.; Palm, D. Review and analysis of artificial intelligence methods for demand forecasting in supply chain management. Procedia CIRP 2022, 107, 1126–1131. [Google Scholar] [CrossRef] [Scilit]
- Mitra, A.; Jain, A.; Kishore, A.; Kumar, P. A comparative study of demand forecasting models for a multi-channel retail company: A novel hybrid machine learning approach. In Operations Research Forum; Springer International Publishing: Cham, Switzerland, 2022; Volume 3, p. 58. [Google Scholar]
- Gustriansyah, R.; Ermatita, E.; Rini, D.P. An approach for sales forecasting. Expert Syst. Appl. 2022, 207, 118043. [Google Scholar] [CrossRef] [Scilit]
- Fu, C.; An, R. Research on E-commerce Mathematical Forecasting Model based on Hybrid Neural Network. In Proceedings of the 2022 IEEE 2nd International Conference on Electronic Technology, Communication and Information (ICETCI), Changchun, China, 27–29 May 2022; pp. 785–787. [Google Scholar]
- Shi, L. Prediction of mini washing machine sales by time series and neural network. J. Anhui Univ. Technol. 2013, 33, 69–73. [Google Scholar]
- Chaudhuri, K.D.; Alkan, B. A hybrid extreme learning machine model with harris hawks optimisation algorithm: An optimised model for product demand forecasting applications. Appl. Intell. 2022, 52, 11489–11505. [Google Scholar] [CrossRef] [Scilit]
- Neelakandan, S.; Prakash, V.; PranavKumar, M.S.; Balasubramaniam, R. Forecasting of E-Commerce System for Sale Prediction Using Deep Learning Modified Neural Networks. In Proceedings of the 2023 International Conference on Applied Intelligence and Sustainable Computing (ICAISC), Dharwad, India, 16–17 June 2023; pp. 1–5. [Google Scholar]
- Zhang, X.; Kim, T. A hybrid attention and time series network for enterprise sales forecasting under digital management and edge computing. J. Cloud Comput. 2023, 12, 13. [Google Scholar] [CrossRef] [Scilit]
- Ramos, F.R.; Pereira, M.T.; Oliveira, M.; Rubio, L. The memory concept behind deep neural network models: An application in time series forecasting in the e-Commerce sector. Decis. Making Appl. Manag. Eng. 2023, 6, 668–690. [Google Scholar] [CrossRef] [Scilit]
- Aguiar-Pérez, J.M.; Pérez-Juárez, M.Á. An insight of deep learning-based demand forecasting in smart grids. Sensors 2023, 23, 1467. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Habbak, H.; Mahmoud, M.; Metwally, K.; Fouda, M.M.; Ibrahem, M.I. Load forecasting techniques and their applications in smart grids. Energies 2023, 16, 1480. [Google Scholar] [CrossRef] [Scilit]
- Tang, Y.M.; Chau, K.Y.; Lau, Y.Y.; Zheng, Z. Data-intensive inventory forecasting with artificial intelligence models for cross-border e-commerce service automation. Appl. Sci. 2023, 13, 3051. [Google Scholar] [CrossRef] [Scilit]
- Swaminathan, K.; Venkitasubramony, R. Demand forecasting for fashion products: A systematic review. Int. J. Forecast. 2024, 40, 247–267. [Google Scholar] [CrossRef] [Scilit]
- Gaboitaolelwe, J.; Zungeru, A.M.; Yahya, A.; Lebekwe, C.K.; Vinod, D.N.; Salau, A.O. Machine learning based solar photovoltaic power forecasting: A review and comparison. IEEE Access 2023, 11, 40820–40845. [Google Scholar] [CrossRef] [Scilit]
- Bender, B.; Bretschneider, S.; Fattah-Weil, J. Advances in Demand Forecasting: A Systematic Review of Methods, The Role of AI, and Data Strategies in Manufacturing. AMCIS 2024, 7, 1790. [Google Scholar]
- Huang, M.G.; Chang, P.L.; Chous, Y.C. Demand forecasting and smoothing capacity planning for products with high random demand volatility. Int. J. Prod. Res. 2008, 46, 3223–3239. [Google Scholar] [CrossRef] [Scilit]
- Lin, C.C.; Tang, Y.H.; Shyu, J.Z.; Li, Y.M. Combining forecasts for technology forecasting and decision making. J. Technol. Manag. China 2010, 5, 69–83. [Google Scholar] [CrossRef] [Scilit]
- Wu, J.H.; Hisa, T.L. Analysis of E-commerce innovation and impact: A hypercube model. Electron. Commer. Res. Appl. 2004, 3, 389–404. [Google Scholar] [CrossRef] [Scilit]
- Kim, K.J.; Ahn, H. A recommender system using GA K-means clustering in an online shopping market. Expert Syst. Appl. 2008, 34, 1200–1209. [Google Scholar] [CrossRef] [Scilit]
- Thomassey, S.; Fiordaliso, A. A hybrid sales forecasting system based on clustering and decision trees. Decis. Support Syst. 2006, 42, 408–421. [Google Scholar] [CrossRef] [Scilit]
- Kotsialos, A.; Papageorgiou, M.; Poulimenos, A. Long-term sales forecasting using holt–winters and neural network methods. J. Forecast. 2005, 24, 353–368. [Google Scholar] [CrossRef] [Scilit]
- Yu, Y.; Choi, T.M.; Hui, C.L. An intelligent fast sales forecasting model for fashion products. Expert Syst. Appl. 2011, 38, 7373–7379. [Google Scholar] [CrossRef] [Scilit]
- Ma, S.; Fildes, R. Retail sales forecasting with meta-learning. Eur. J. Oper. Res. 2021, 288, 111–128. [Google Scholar] [CrossRef] [Scilit]
- He, Q.Q.; Wu, C.; Si, Y.W. LSTM with particle Swam optimization for sales forecasting. Electron. Commer. Res. Appl. 2022, 51, 101118. [Google Scholar] [CrossRef] [Scilit]
- Schmidt, A.; Kabir, M.W.U.; Hoque, M.T. Machine Learning Based Restaurant Sales Forecasting. Mach. Learn. Knowl. Extr. 2022, 4, 105–130. [Google Scholar] [CrossRef] [Scilit]
- Makridakis, S.; Wheelright, S. Forecasting Methods for Managementy for the 21st Century; The Free Press: Florence, MA, USA, 1989. [Google Scholar]
- Hanke, J.E.; Reitsch, A.G. Business Forecasting; Allyn and Bacon: Boston, MA, USA, 1981. [Google Scholar]
- Brown, R.G. Smoothing, Forecasting and Prediction of Discrete Time Series; Prentice Hall: Kent, OH, USA, 1963. [Google Scholar]
- Holland, J.H. Genetic algorithms. Sci. Am. 1992, 267, 66–73. [Google Scholar] [CrossRef] [Scilit]
- Karafotias, G.; Hoogendoorn, M.; Eiben, Á.E. Parameter control in evolutionary algorithms: Trends and challenges. IEEE Trans. Evol. Comput. 2014, 19, 167–187. [Google Scholar] [CrossRef] [Scilit]
- Ataei, M.; Osanloo, M. Using a Combination of Genetic Algorithm and the Grid Search Method to Determine Optimum Cutoff Grades of Multiple Metal Deposits. Int. J. Surf. Min. Reclam. Environ. 2004, 18, 60–78. [Google Scholar] [CrossRef] [Scilit]
- Rexhepi, A.; Maxhuni, A.; Dika, A. Analysis of the impact of parameters values on the Genetic Algorithm for TSP. IJCSI Int. J. Comput. Sci. Issues 2013, 10, 3. [Google Scholar]
- Boyabatlı, O.; Sabuncuoğlu, H. Parameter Selection in Genetic Algorithms. Syst. Cybern. Inform. 2001, 2, 4. [Google Scholar]
- Karl, D. Forecasting e-commerce consumer returns: A systematic literature review. Manag. Rev. Q. 2024. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2024 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).