


Abstract
A denoising algorithm was proposed for point cloud with high-density noise. The algorithm utilized geometric metrics on the statistical manifold and applied the idea of clustering K-means based on local statistical characteristics between noise and valid data. First, by calculating the expectation and covariance matrix of the data points, the point cloud with high-density noise was projected onto the Gaussian distribution family manifold, aiming to form the parameter point cloud. Afterwards, the geometry metrics were assigned to the manifold, and the K-means algorithm was applied to cluster the parameter point cloud, so as to classify the valid data and noise. Furthermore, in order to analyze the robustness of the means with different metrics, the approximate values of their influence functions were calculated, respectively. Finally, simulation analysis was conducted using the algorithm based on geometric metrics to verify the effectiveness in point cloud denoising.
1. Introduction
Point cloud denoising is a widely used data processing technique in various fields, such as 3D reconstruction, indoor positioning systems and positioning, intelligent manufacturing, virtual reality and augmented reality, and geological exploration and seismic research [1]. With the ability to improve the quality and accuracy of point cloud data and provide a reliable data foundation for other applications. Point cloud denoising aims to effectively eliminate noise points, smooth the reconstructed surface model, and maintain the original topology and geometric characteristics of the sampled surface. When the density of a point in a local area of the point cloud is significantly higher or lower than that of the surrounding points, it is referred to as high-density noise or low-density noise, respectively. The presence of high-density noise can be determined by calculating the density or number of points in the local neighborhood using methods such as nearest neighbor distance or K-nearest neighbor. In specific applications, thresholds for high-density and low-density noise can be established through experiments and optimizations based on actual requirements.
The popular point cloud processing platform ‘Point Cloud Library’ offers denoising methods such as radius outlier removal and statistical outlier removal, but these are only suitable for low-density noise data [1]. Recently, a new approach using Wasserstein curvature has been proposed for point cloud denoising; however, it mistakenly identifies some real information in flat areas as noise [2].
The K-means algorithm is known for its low time complexity and fast running speed, making it suitable for processing most continuous variable data [3]. It performs well in dealing with data sets that have spherical clustering structures and can complete clustering in a short period of time. However, the traditional K-means algorithm only considers Euclidean distance when calculating the similarity between samples and does not account for the statistical structure of point cloud. This limitation makes it challenging for the algorithm to distinguish between random noise and valid data [3,4]. To address this issue, a clustering algorithm is proposed based on the neighborhood density of each data in [5,6]. On the manifold, the local geometric structure of noise and valid data are inconsistent, and thus the data with similar local geometric characteristics need to be considered as the same cluster. In [7,8], a K-means clustering algorithm is used to denoise point cloud, but only a few metrics are adopted to calculate the distance on the manifold. Meanwhile, the influence function, which aims to evaluate the robustness of the mean induced by each metric to outliers, is not analyzed in these studies.
This manuscript extends our previous ideas in [8] by proposing a point cloud denoising method based on the geometry of the Gaussian distribution family manifold. The manifold is endowed with five metrics, including the Euclidean metric, the affine-invariant Riemannian metric, the log-Euclidean metric, the Kullback–Leibler divergence as well as the symmetrized Kullback–Leibler divergence [9]. To evaluate the robustness of the mean endowed by each metric to outliers, the influence functions of geometric metrics are calculated. As stated in [10], it can be very difficult to solve the matrix equations for the influence functions directly, so we calculate the approximate values of these influence functions. To evaluate the denoising effects of these metrics, the true positive rate (TPR), the false positive rate (FPR), and the signal–noise rate growing (SNRG) are adopted. TPR refers to the proportion of correctly predicted positive cases among all actual positive cases. A higher TPR means less real data loss. In fact, higher TPR, higher SNRG, and lower FPR indicate that the algorithm can better distinguish between real data and noise. Our proposed algorithm will be evaluated by the above three standards.
The contributions in this paper are summarized as follows.
(1) A K-means clustering algorithm is proposed to denoise point cloud with high-density noise by leveraging the difference in local statistical characteristics between noise and valid data. The algorithm operates on a Gaussian distribution family manifold.
(2) By calculating the expectation and the covariance matrix of the data points, we map the original point cloud onto the Gauss distribution family manifold to form the parameter point cloud. Next, the metrics are assigned to the manifold, and the K-means method is applied to cluster the parameter point cloud, aiming to classify the original point cloud.
(3) With the purpose of analyzing the robustness of the means with different metrics, the approximate values of their influence functions are calculated, respectively. The simulation results demonstrate that using geometry metrics yields better denoising effects compared to using the Euclidean metric. Additionally, mean influence functions with geometry metrics exhibit greater robustness than that with the Euclidean metric.
The rest of the current work is structured as follows. Briefly, Section 2 introduces the Riemannian framework of the Gaussian distribution family manifold. Section 3 proposes a K-means clustering algorithm to denoise point cloud with high-density noise and calculates the approximate values of their influence functions with different metrics. In addition, Section 4 presents the effectiveness of the proposed algorithm to denoise point cloud and verifies our obtained properties of influence functions.
2. Preliminaries
In this study, the set of all symmetric matrices can be indicated:
Moreover, the set of all symmetric positive-definite matrices can be indicated using:
where means that the quadratic form in terms of all non-zero n-dimensional vectors x.
The difference between two positive-definite matrices can be determined using a distance, a divergence, or other measures. It is crucial to accurately specify these metrics correctly in the application, because the different metrics on will lead to its different geometric structures.
2.1. Metrics on
On , some metrics can be used as the measurements. Here, we introduce five specific measures including the Frobenius metric, the affine-invariant Riemannian metric, the log-Euclidean metric, the Kullback–Leibler divergence, and the symmetric Kullback–Leibler divergence.
(1) Euclidean Distance
The Frobenius metric (FM) on is indicated by
where refers to the trace of “·” and . Then, with the metric (3) becomes a manifold. The tangent space at the point can be represented by . Also, the tangent space at U can be recognized as , as is an open subset of . The Euclidean distance with the metric (3) corresponds to
(2) Riemannian Distance
The manifold is transformed into a Riemannian manifold, which is equipped with the affine-invariant Riemannian metric (AIRM) at point U
where I represents the identity matrix, and . With the metric (5), the curvature of is non-positive [11,12]. The distance of two points induced by the AIRM is provided by the length of the local geodesic:
However, the calculation cost of the AIRM distance is usually time-consuming in practical applications. An alternative option is the log-Euclidean metric (LEM), which can be indicated as:
where and indicate the differential map at the point U.
The LEM distance between U and W could be written as
which is obviously more concise than the AIRM distance.
(3) Divergences
Other geometric measures can be equipped on the manifold [13]. One widely used measure on Riemannian manifolds is the Kullback–Leibler divergence (KLD), also known as Stein loss or log-determinant divergence [14]. The KLD between two points U and W can be indicated as:
The symmetric Kullback–Leibler divergence (SKLD) is the Jeffreys divergence [15], and the divergence between U and W is represented by
When dealing with optimization problems on manifolds, it is often necessary to calculate the gradient of the objective function , which can be achieved using the covariant/directional derivative correlated with a given metric, such as a Riemannian metric etc:
with the curve and . The curve is linearized and can be re-expressed by
2.2. Geometric Means on
The arithmetic mean of m positive real numbers can be obtained by
where represents the value of u that minimizes within the range of . For a given set of m matrices , the mean can be obtained by solving the following minimum problem:
The arithmetic mean, which is triggered by the Frobenius metric (3), is represented as
It is shown that the geometric mean of a set of matrices on may not have an explicit expression, which can be numerically calculated by a fixed point iterative algorithm [16,17,18]. Table 1 presents the algorithms used to calculate the geometric means.
Table 1.
Geometric means corresponding to different metrics.
3. Point Cloud Denoising Algorithm Based on Geometric Metrics
Let us represent the point cloud with the scale as
In terms of any , the q-nearest neighbor method can be adopted for selecting the neighborhood , with the abbreviation of . Next, we calculate the expectation and covariance matrix of the data points in , respectively. Therefore, we map original data point cloud onto the Gaussian distribution family manifold, aiming to acquire the parameter point cloud as follows
Then, the local statistical mapping is represented as
and satisfies
Based on the local statistical mapping , the image of the point cloud refers to the parameter point cloud [7].
3.1. K-Means Clustering Algorithm on the Basis of Geometric Metrics
Since and are shown to be topologically homeomorphic [19], the geometric structure on can be triggered by setting the metrics on . In addition, we denote the distance on as:
and the barycenter of the parameter point cloud is indicated:
where the barycenter represents the geometric center of . The distance and barycenter rely on the selection of the metric on . The distance functions in the following algorithm can be induced by FM, AIRM, LEM, KLD, or SKLD, and the geometric means corresponding to each metric can be found in Table 1.
The local statistical structure of the valid data and that of random noise are very different, so we use the K-means clustering algorithm to divide into two categories. The algorithm for clustering data and noise is presented below:
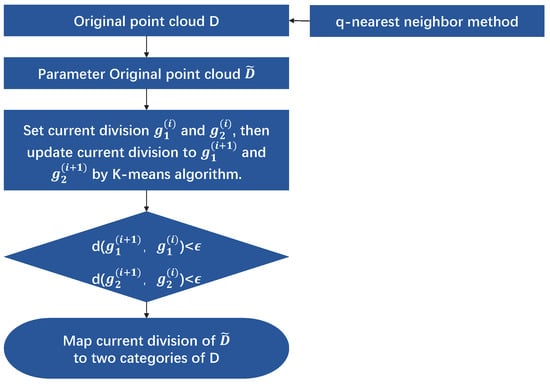
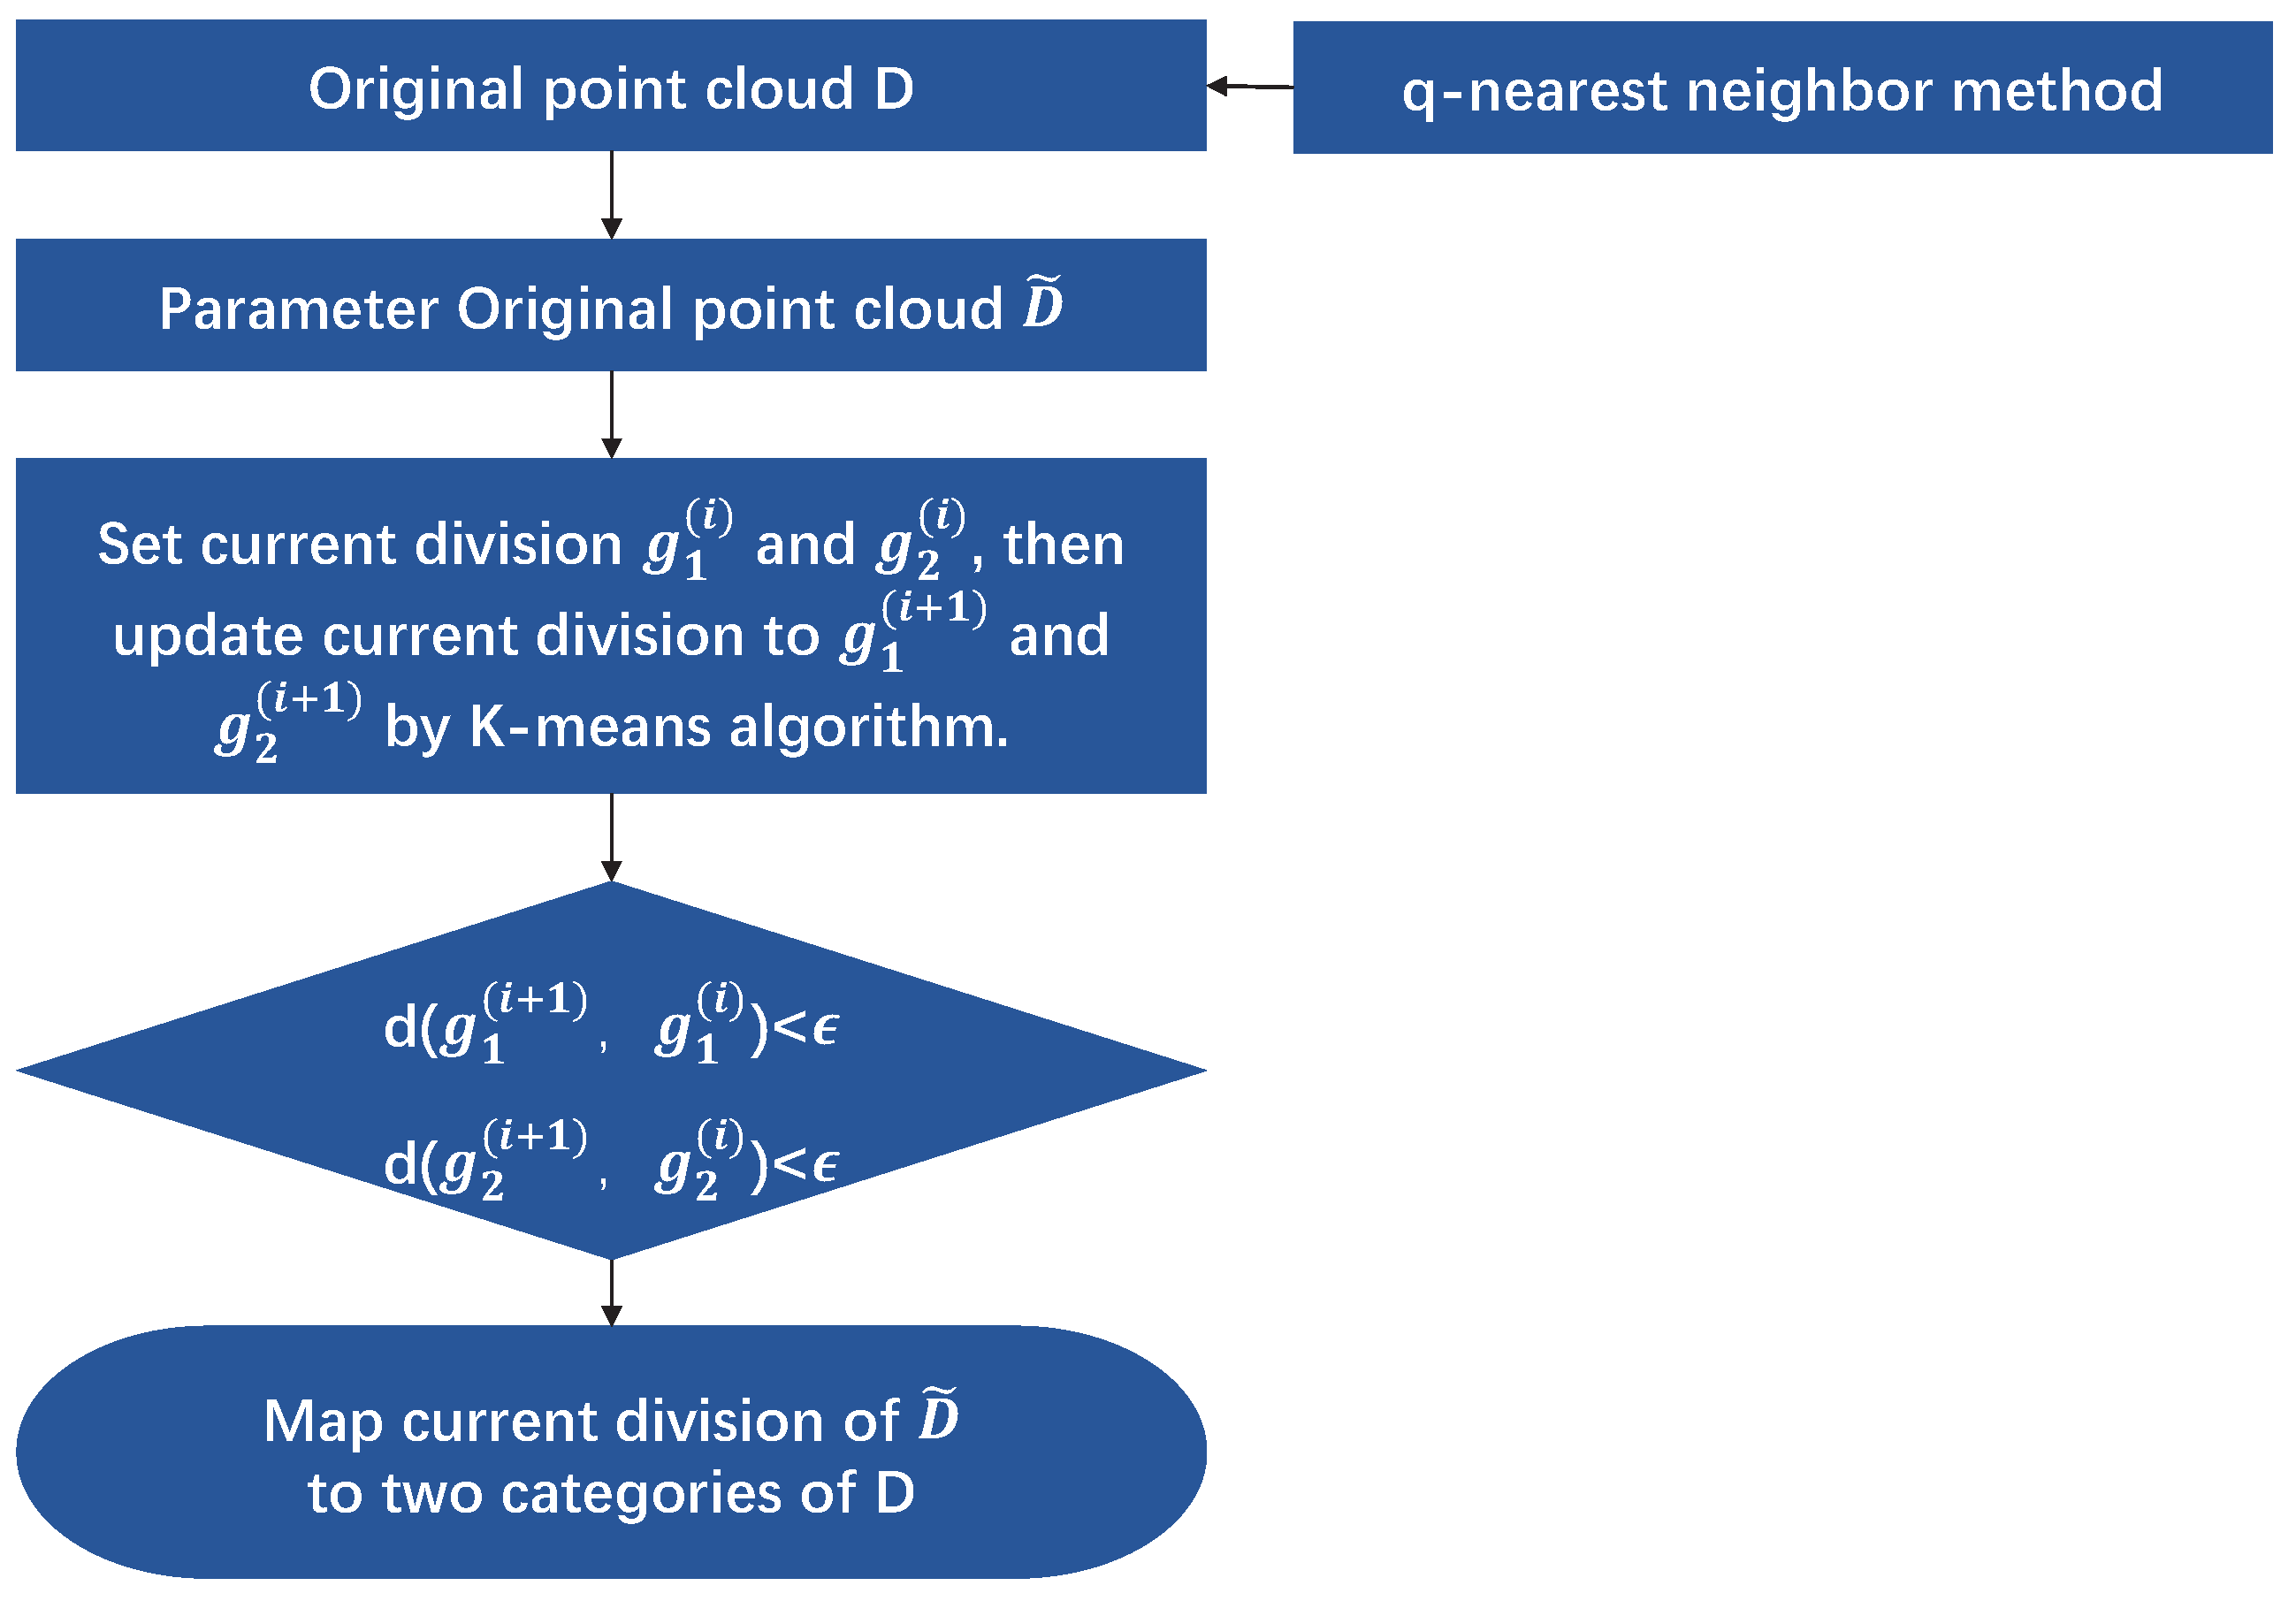
Figure 1 shows the flowchart of Algorithm 1. The efficiency of the algorithm is dependent on selecting the metrics on , and it will be shown that the geometric metrics have more advantages than the Euclidean metric in the following text.
| Algorithm 1 Algorithm for clustering signal and noise |
|
Figure 1.
Flowchart of Algorithm 1.
3.2. Influence Functions of Different Metrics
In order to analyze the robustness of geometric means when symmetry positive-definite matrices are contaminated by outliers, we adopt the influence function. To show that it is more suitable to assign geometric metrics than the Euclidean metric in Algorithm 1, we will describe the influence functions of the arithmetic mean and the geometric means.
Let indicate the mean of m symmetry positive-definite matrices with FM (AIRM, LEM, KLD, or SKLD), and let be the mean by supplementing a set of l outliers with a weight to [20,21].
Next, we can define as:
and the norm as
The influence functions of the arithmetic mean and the AIRM mean can be found in Refs. [10,22], as follows.
Proposition 1.
The influence function of the arithmetic mean for m symmetry positive-definite matrices and l outliers with a weight can be expressed as:
Proposition 2.
The influence function of the AIRM mean for m symmetry positive-definite matrices and l outliers is given by
Before the influence functions of the LEM mean, the KLD mean, as well as the SKLD mean are presented, the following lemmas are given to calculate them [23,24].
Lemma 1.
Let V and be an invertible matrix that does not have eigenvalues in the closed negative real line, and let be its principal logarithm, then we have that
- 1.
- Both V and commute with for any .
- 2.
- The following identities are valid thatand
Lemma 2.
Suppose that is a real matrix for , then we have
Lemma 3.
For any invertible matrix , the following identity holds
Then, the influence functions of the LEM mean, the KLD mean, and the SKLD mean are presented as:
Proposition 3.
The influence function of the LEM mean for m symmetry positive-definite matrices and l outliers is represented by
Proof.
See Appendix A. □
Proposition 4.
The influence function of the KLD mean for m symmetry positive-definite matrices and l outliers is represented by
Proof.
See Appendix B. □
Proposition 5.
The influence function of the SKLD mean for m symmetry positive-definite matrices and l outliers is represented by
Proof.
See Appendix C. □
4. Simulations and Results
The following section presents numerical experiments to demonstrate the denoising effect of Algorithm 1. It also compares the norms of the mean influence functions with FM, AIRM, LEM, KLD, and SKLD. In these simulations, all samples on can be generated using the equation:
where refers to a random matrix generated by MATLAB.
A. Numerical Simulations
In this example, the distance function induced by FM, AIRM, LEM, KLD, or SKLD is used in Algorithm 1, and the denoising effect caused by these metrics is compared, where the experimental data employ the 3D point cloud of Teapot.ply. Teapot.ply is one of the built-in data in MATLAB and can also be obtained through some open-source projects, such as the Stanford 3D Scanning Repository. In MATLAB, Teapot.ply is an example model that is often used to demonstrate and test 3D graphics processing and visualization functions. It is stored in PLY file format and contains three-dimensional geometric information representing a teapot.
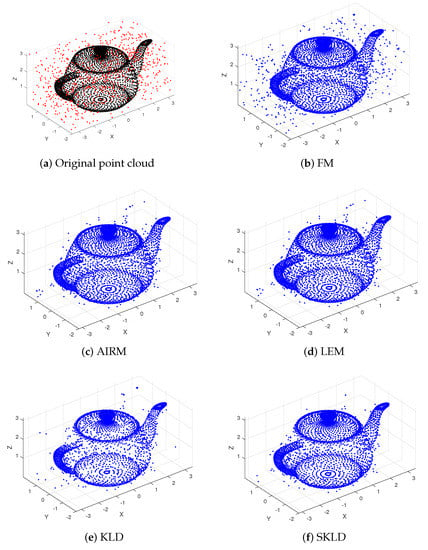
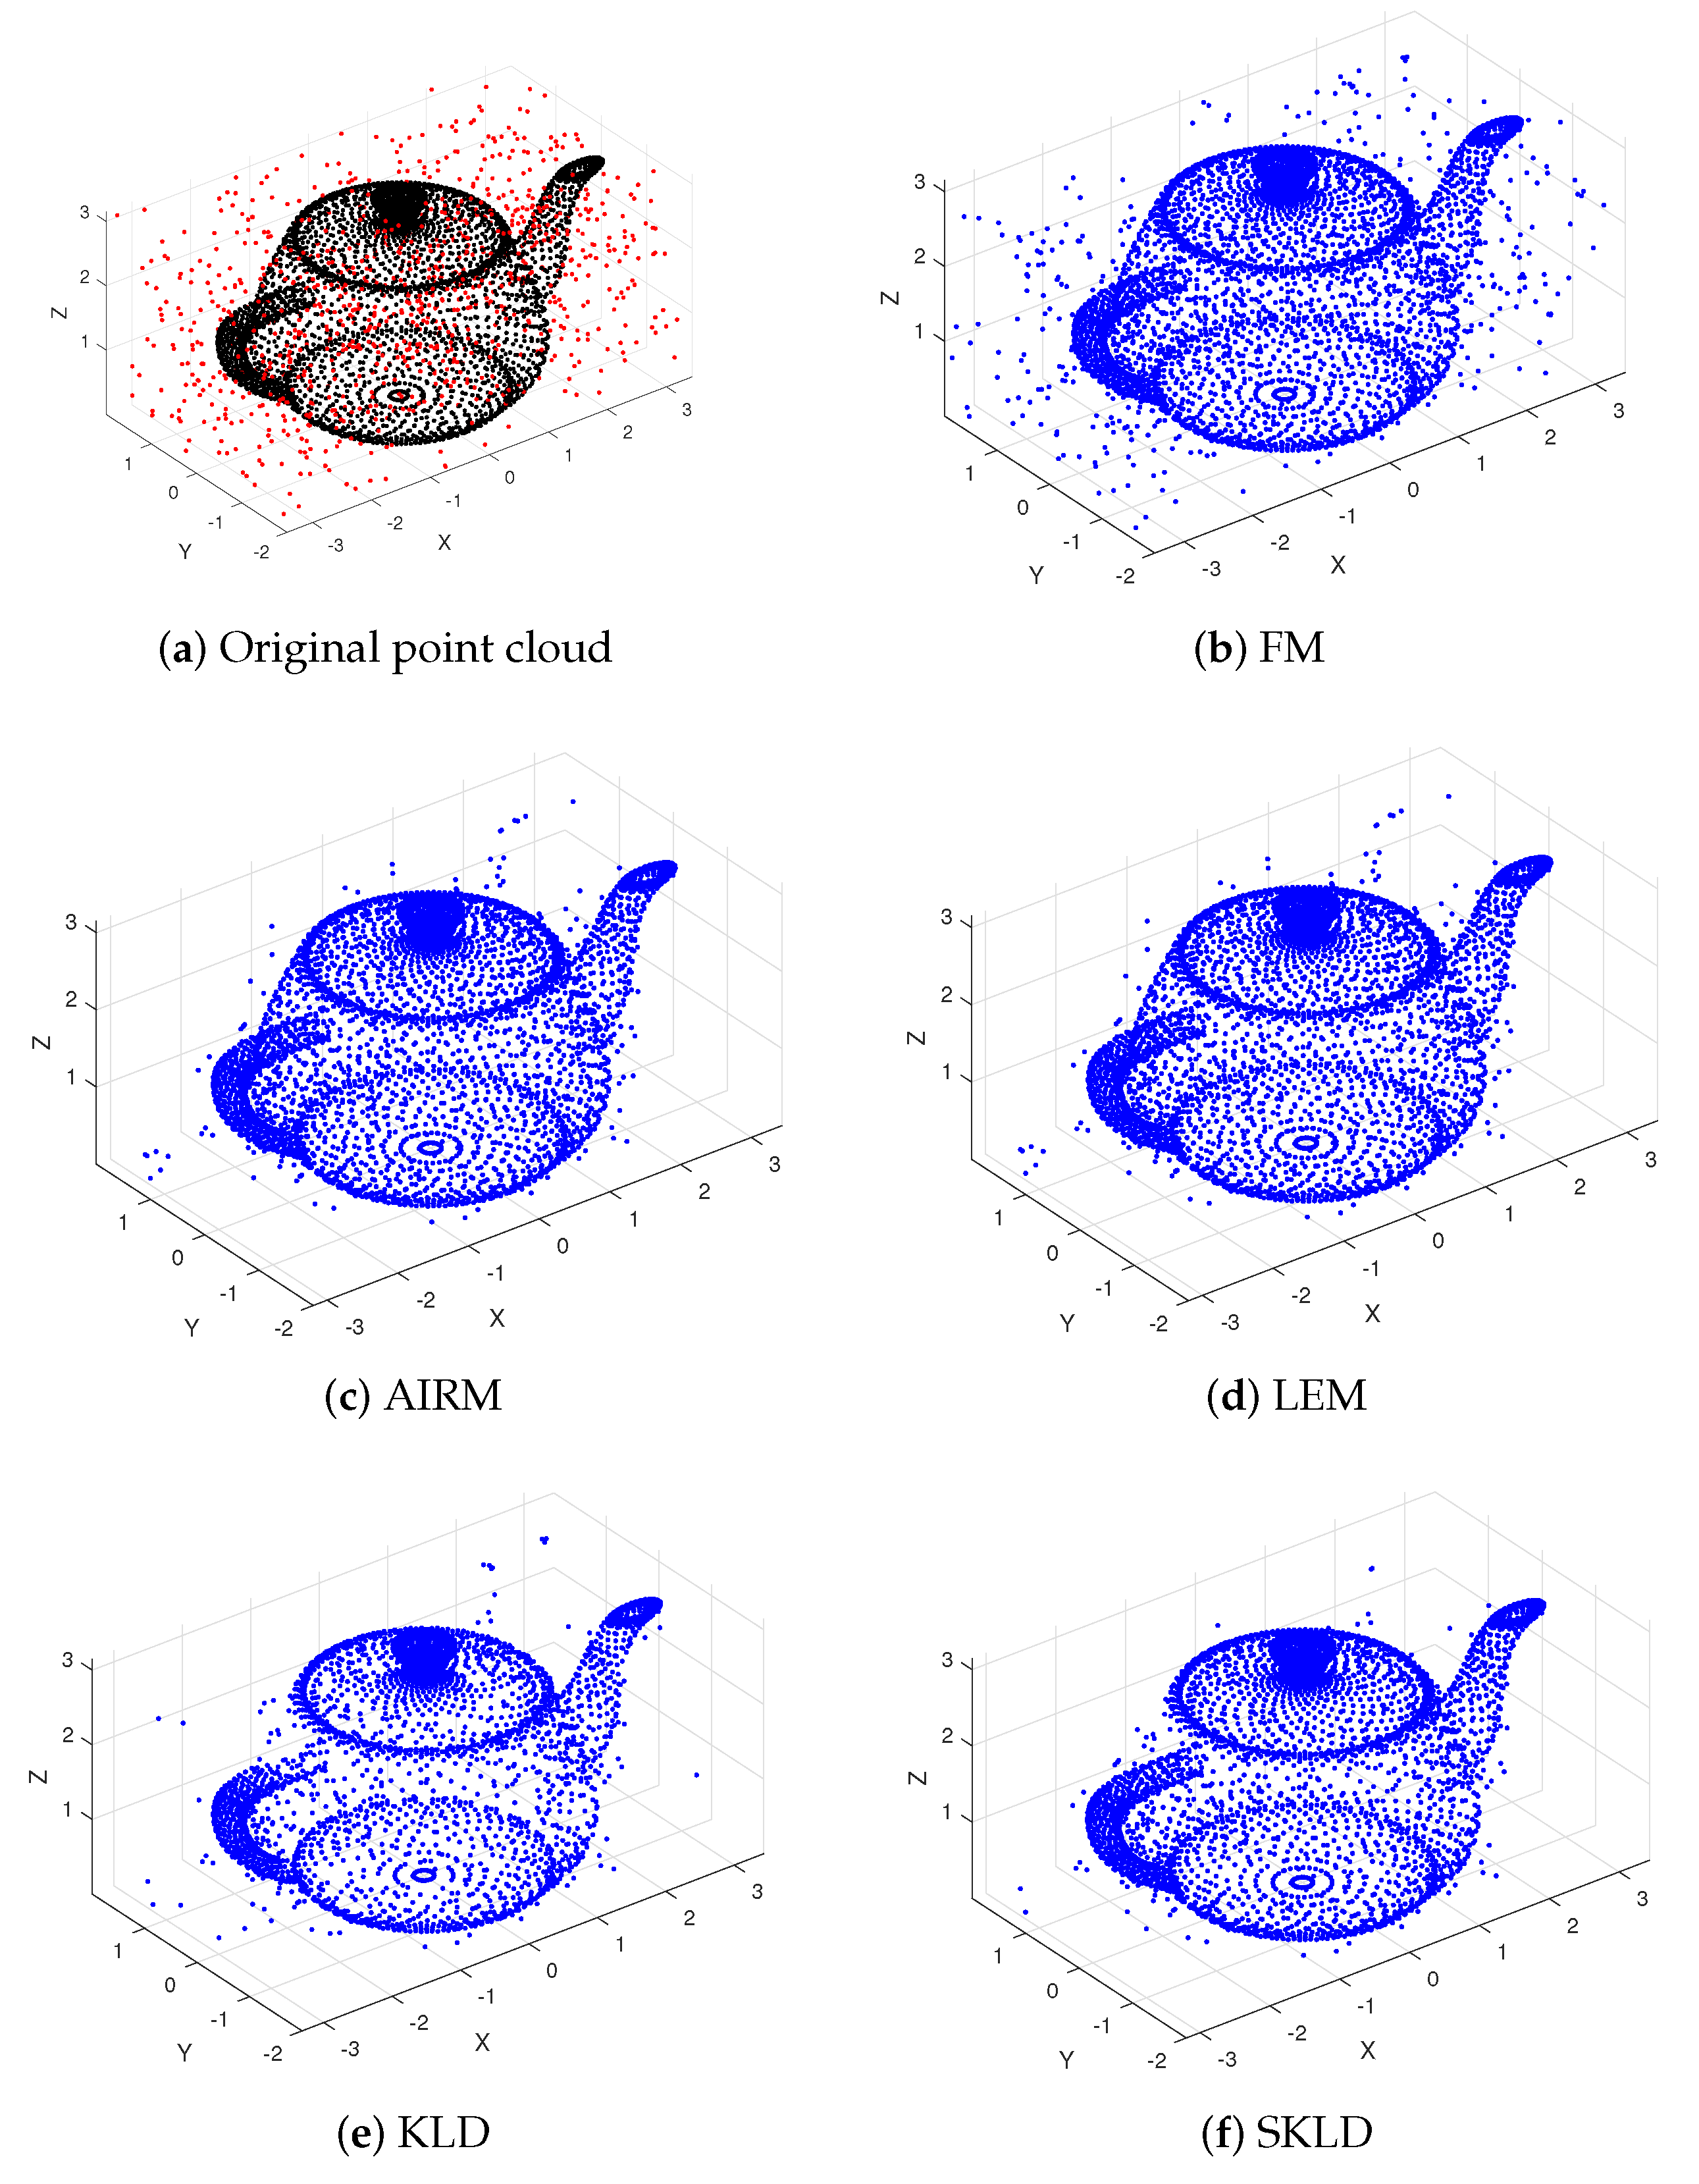
As shown in Figure 2a, background noise can be distributed uniformly with a signal-to-noise ratio (SNR) of 4137:1000. Taking and , Figure 2b–f present the denoised images of the original point cloud using Algorithm 1, according to FM, AIRM, LEM, KLD, and SKLD, respectively. From Figure 2b, it can be observed that Algorithm 1, which is based on the Euclidean metric, still has a significant amount of noise points remaining in the image. Figure 2c,d show that Algorithm 1 performs well in removing noise points when using AIRM and LEM. Figure 2e,f illustrate that Algorithm 1, utilizing KLD or SKLD, effectively denoises the image but also removes some real data points from the teapot. It is evident that Algorithm 1 on the basis of the Euclidean metric is not as effective as other geometric metrics.
Figure 2.
Comparison of point cloud before and after denoising.
B. Results and Discussions
To evaluate the denoising effects of these metrics, true positive (TP), false positive (FP), false negative (FN), and true negative (TN) are adopted. Then, the true positive rate (TPR), the false positive rate (FPR), and the signal–noise rate growing (SNRG) are defined by
where represents the number of real data, and stands for the number of noises.
In Table 2, we have an SNR of 4137:1000 and 4137:2000. As higher TPR, higher SNRG, and lower FPR indicate that the algorithm can better distinguish between real data and noise, the highest TPR, the lowest FPR, and more than SNRG are displayed in bold. From Table 2, it is evident that Algorithm 1 based on the Euclidean metric generally has a higher FPR, lower TPR, and lower SNRG. Conversely, geometric metrics tend to lower FPR, higher TPR, and higher SNRG. Among them, Algorithm 1 with KLD and SKLD exhibits a lower FPR due to the removal of some valid data points in Figure 2e,f. Therefore, Table 2 demonstrates the advantages of using geometric metrics (AIRM, LEM, KLD, and SKLD) over the Euclidean metric.
Table 2.
Comparison of denoising results.
To compare the robustness of influence functions with different metrics, we consider simulations involving 100 randomly generated symmetry positive-definite matrices along with l-injected outliers. We examine four scenarios: and 100 to analyze the effect of outlier numbers on influence function robustness.
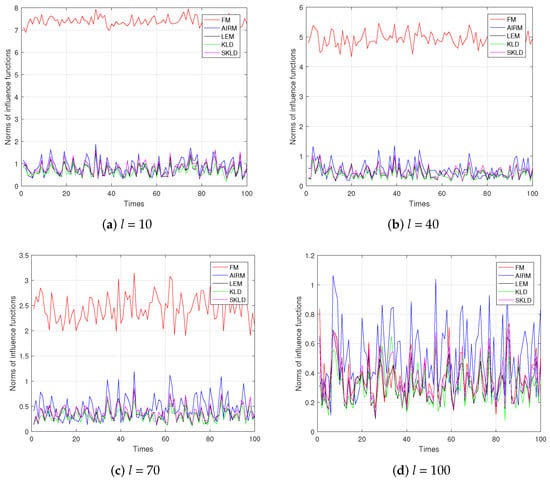
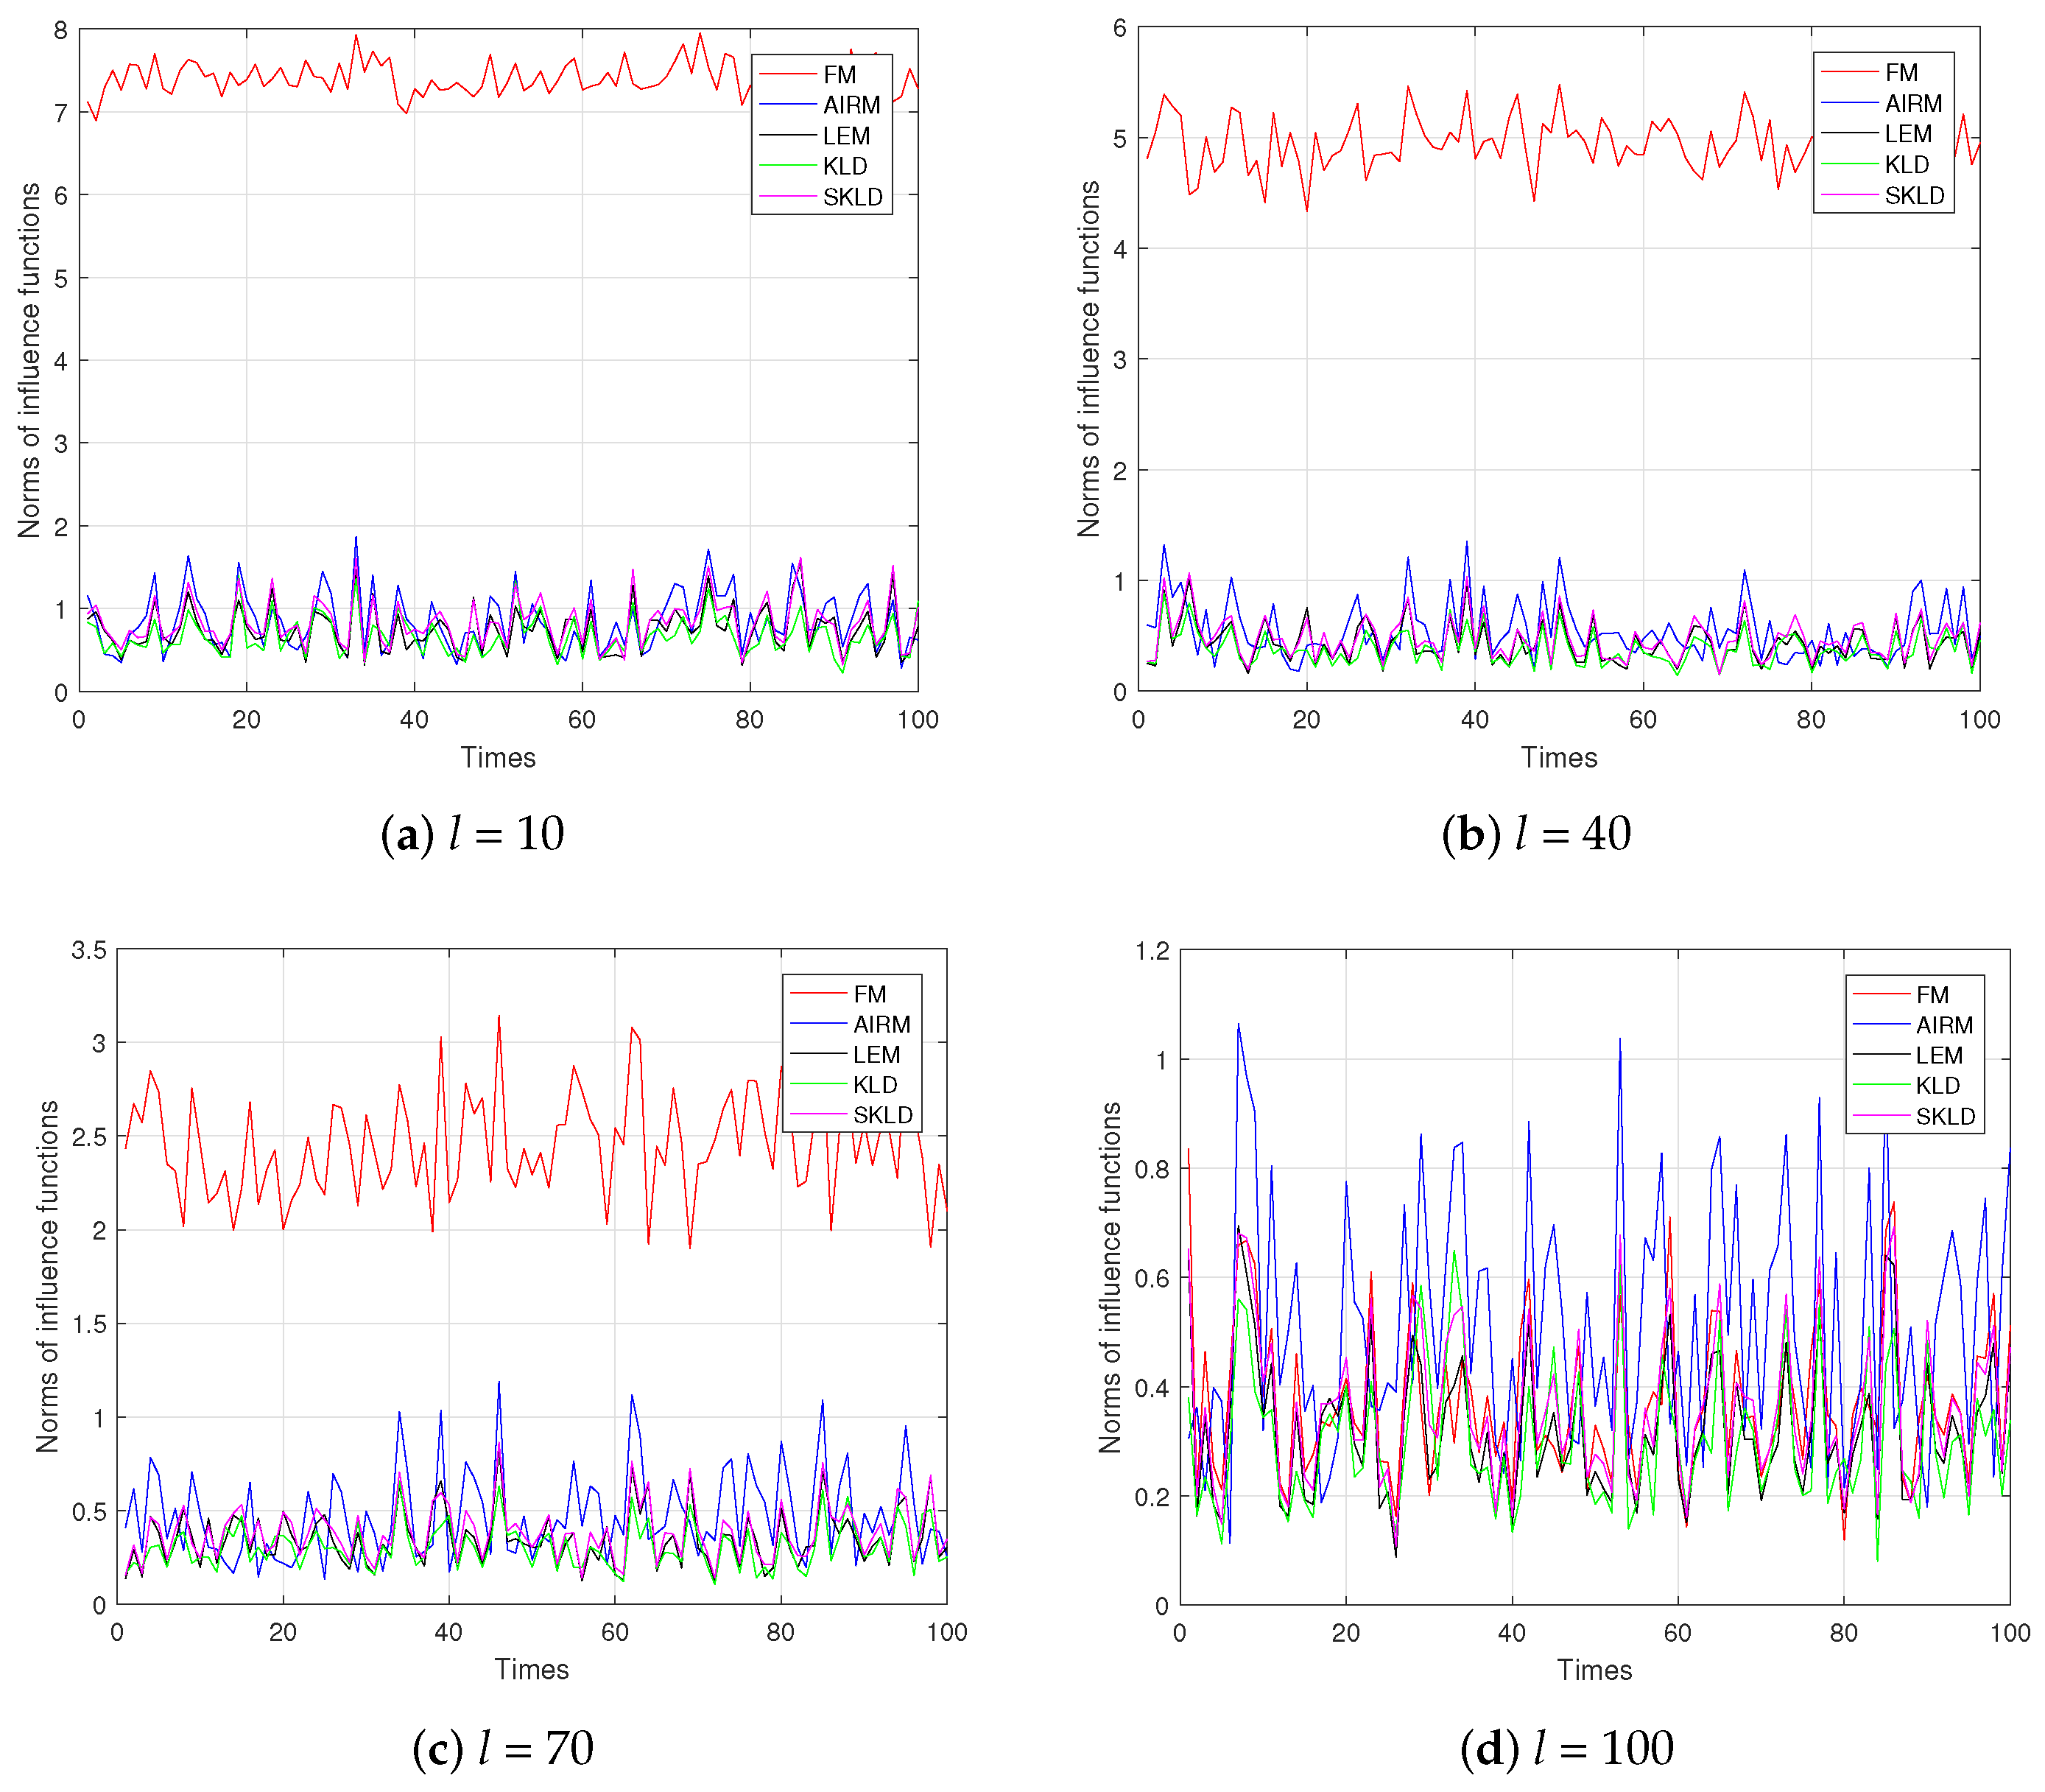
From Propositions 1–5 as a basis for calculation norms of influence functions, we repeat simulations for each scenario (, or 100) one hundred times, as shown in Figure 3. It can be seen that the norms of the influence functions corresponding to the geometric metrics (AIRM, LEM, KLD, and SKLD) are not sensitive to changes in outlier numbers; they remain within a range close to one, regardless of if l is set from 10 up to 100. On the other hand, norms associated with Euclidean metric (FM) fluctuate significantly—decreasing from around seven or eight down towards one when l increases from 10 up to 100. Therefore, geometric means are almost independent of the number of outliers, and more stable than the arithmetic mean.
Figure 3.
Norms of influence functions.
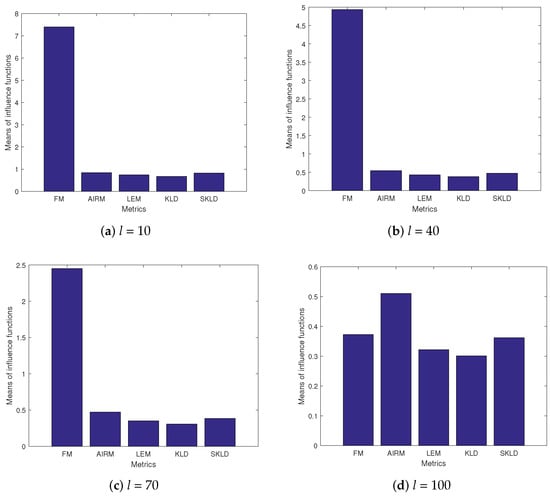
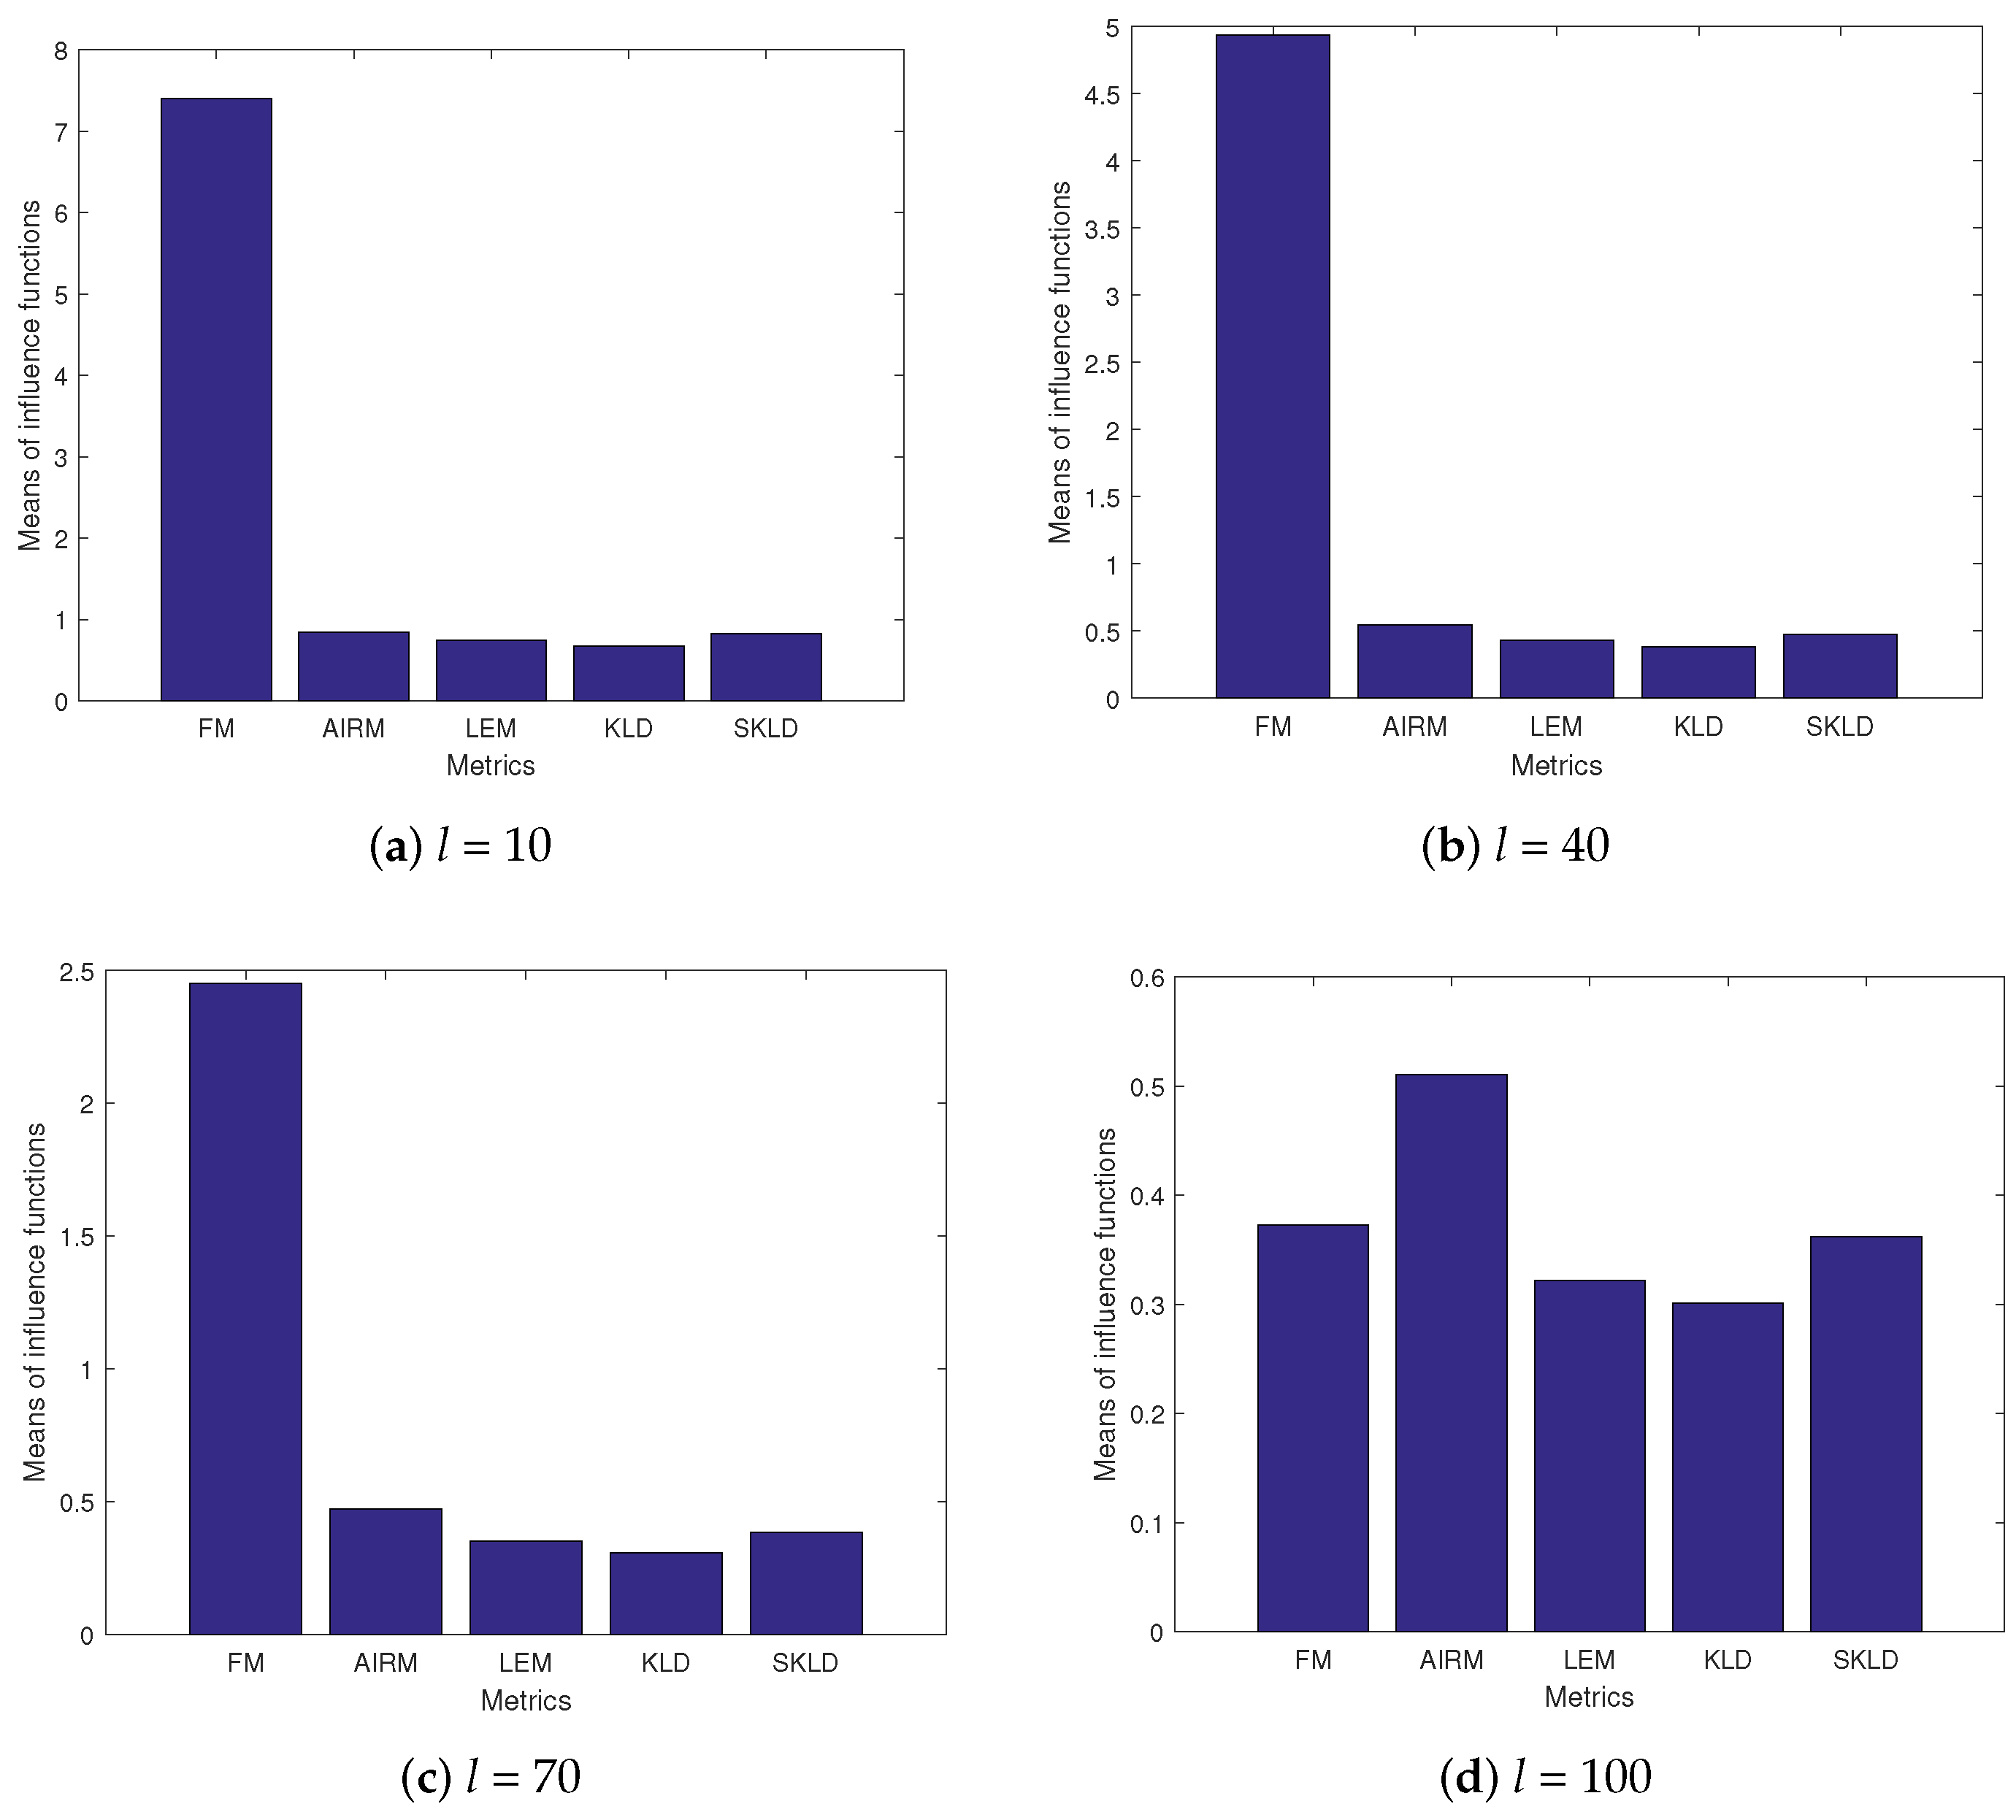
Figure 4 provides an intuitive representation by illustrating average norms across all simulations for each metric type (Euclidean vs Geometric). As observed in Figure 3, results hold true here as well: FM consistently yields larger norm values compared to those obtained using geometric metrics when considering various values for l such as 10, 40, and 70, respectively. Furthermore, Figure 4 shows that if the number of outliers with the FM is 100, which is close to the number of symmetry positive-definite matrices used in simulations, influence functions for FM and geometric metrics become increasingly similar. This further supports the notion that geometric means are more robust than arithmetic means, as demonstrated by Figure 4.
Figure 4.
Means of influence functions.
C. Complexity Analysis
Next, the computational complexity of the mean matrices with FM, LEM, AIRM, KLD, and SKLD will be demonstrated, whose formulas can be obtained from (15) and Table 1. Then, the computational complexity of the influence functions according to FM, LEM, AIRM, KLD, and SKLD will be also given, whose expressions are shown in Propositions 1–5. For iterative algorithms, we only calculate the complexity of single-step iterations.
This subsection demonstrates the computational complexity of mean matrices for FM, LEM, AIRM, KLD, and SKLD. The formulas can be obtained from (15) and Table 1. Additionally, the computational complexity of influence functions according to these metrics is provided in Properties 1–5. For iterative algorithms, only the complexity of single-step iterations is considered. Let us assume we have m symmetry positive-definite matrices and l outliers. It is assumed that the complexity of a single element is O(1), and . When calculating the matrix exponential of a symmetric matrix and the half power of a symmetric positive-definite matrix, the eigenvalue decomposition is needed to perform. Thus, we have that and .
Table 3 shows that the arithmetic mean has the lowest computation time followed by KLD and SKLD means. As the complexity of each step of the AIRM mean is equivalent to that of the LEM mean, so the LEM mean has a much faster calculation speed than the AIRM mean.
Table 3.
Computational complexity of means.
From Table 4, it can be seen that calculating the influence functions with the FM takes less time than those with the geometric metrics. Among geometric metrics, the longest calculation time is the influence function corresponding to the AIRM, followed by that corresponding to the LEM, and the shortest calculation time is the influence function induced by the KLD and the SKLD. This difference arises due to the iterative algorithm requirement for calculating AIRM.
Table 4.
Computational complexity of influence functions.
5. Conclusions
To conclude, a novel point cloud denoising algorithm is proposed in combination with the K-means algorithm. By calculating the expectation and covariance of the data points, this algorithm utilizes geometric metrics on the statistical manifold to map the original data point cloud to the Gaussian distribution family manifold, forming a parameter point cloud. Additionally, different measure structures are constructed on the Gaussian distribution family manifold, and the K-means method is used for clustering the parameter point cloud, aiming to cluster the corresponding original data. The robustness of different means with various metrics is analyzed by calculating their approximate influence functions. Simulations show that Algorithm 1 with the geometry metrics can obtain a better denoising effect than that with the Euclidean metric, and the geometric means are more robust than the arithmetic mean. We use three criteria (TPR, FPR, and SNRG) to evaluate the denoising effect of Algorithm 1 corresponding to different metrics. Simulations indicate that the algorithm corresponding to the Euclidean metric has a lower TPR and a higher FPR in most cases. SNRG is the most important criteria, which represents the promotion of signal-to-noise ratio through Algorithm 1. Table 2 shows that the SNRG of Algorithm 1 with geometric metrics is generally higher than that with the Euclidean metric.
However, it should be noted that although denoising algorithms based on geometric metrics have the advantages of high TPR, low FPR, and high SNRG, it faces higher computational complexity than those utilizing the Euclidean metric, reaching . Additionally, computational complexity according to KLD and SKLD also reaches . This represents a drawback of denoising algorithms employing geometric metrics.
In this manuscript, Algorithm 1 is only used for numerical simulation of point cloud denoising, and can also be applied to specific tests in the future. Ultrasonic testing with a manipulator is an important non-destructive testing method used to detect the internal defects of materials with complex structures. Before the manipulator detects the workpiece, the laser instrument is used to collect the point cloud data of the workpiece for 3D reconstruction. However, the point cloud data collected by laser instruments often contains a significant amount of redundant or invalid points. Algorithm 1 can be used to these redundancies and improve the quality of point cloud data. This will result in reduced noise and more accurate models, ultimately enhancing subsequent processing effects.
Author Contributions
Investigation, X.D.; Methodology, X.D. and L.F.; Software, X.Z.; Writing—original draft, X.D.; Writing—review and editing, X.D., L.F. and X.Z. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by National Natural Science Foundation of China grant number 61401058.
Data Availability Statement
The experimental data employ 3D point cloud of Teapot.ply. Teapot.ply is one of the built-in data in MATLAB and can also be obtained through some open source projects, such as the Stanford 3D Scanning Repository.
Acknowledgments
The authors would like to thank the anonymous reviewers for their detailed and careful comments, which helped improve the quality of presentation.
Conflicts of Interest
The authors declare no conflict of interest.
Appendix A
Proof of Proposition 3.
Let represent the objective function to minimize m symmetry positive-definite matrices as follows:
Suppose , we can choose an appropriate so that is positive-definite. In fact, A belongs to the tangent vector space , and the geodesic passing through U in the direction of A with respect to the Frobenius inner product is given by
According to Proposition 2.2.5 of [25], stays within under the condition that is not too large. Therefore, we may select the appropriate to guarantee . Then, the gradient of can be computed as follows by (12)
The rest of the analysis is to calculate the two differential terms of the above identity. Using Lemmas 1–3, we obtain
and
Then, we obtain
and thus
Let be the objective function, aiming to minimize the symmetry positive-definite matrices as follows
then we have
Note that is the mean of m symmetry positive-definite matrices and l outliers , so we obtain , that is,
with the purpose of obtaining the linear term about , this study differentiates (A8) and sets . Thus, we obtain
As represents the mean of m symmetry positive-definite matrices , we obtain that
Next, we take the trace of Equation (A9) and apply Lemmas 1– 3 to obtain
Based on the arbitrariness of , this study can obtain the influence function of the LEM mean that
This can finish the proof. □
Appendix B
Proof of Proposition 4.
Let be the objective function in order to minimize m positive-definite matrices as follows
Suppose , then the gradient of can be computed as follows by (12)
The rest is to calculate the differential term of the above identity. Using Lemmas 1–3, we obtain
Consequently, we obtain
Let be the objective function to minimize the symmetry positive-definite matrices as follows
then we have
As , we have
with the aim of obtaining the linear term about , this study differentiates (A16) and sets . Thus, we obtain
Note that
consequently,
Next, we substitute (A19) into (A17) and take the trace of Equation (A17) to obtain the influence function of the KLD mean:
□
Appendix C
Proof of Proposition 5.
Let be the objective function to minimize m symmetry positive-definite matrices as follows
According to (12), the gradient of is computed by:
with . Using (A18), we obtain
Consequently, we obtain the gradient of that
Let be the objective function to minimize symmetry positive-definite matrices as follows
then we have
As , we have
In order to acquire the linear term concerning , this study differentiates (A25) and sets , namely,
Note that
we substitute (A27) into (A26) and take the trace of Equation (A26) to obtain the influence function of the SKLD mean that
□
References
- Rusu, R.; Cousins, S. 3D is here: Point cloud library (PCL). In Proceedings of the IEEE International Conference on Robotics and Automation, Shanghai, China, 9–13 May 2011. [Google Scholar]
- Luo, Y.; Yang, A.; Sun, F.; Sun, H. An efficient point cloud processing approach via Wasserstein curvature. In Proceedings of the IEEE International Conference on Artificial Intelligence and Computer Applications (ICAICA), Dalian, China, 28–31 June 2021; pp. 847–851. [Google Scholar]
- Jain, A.K. Data clustering: 50 years beyond K-means. Pattern Recognit. Lett. 2010, 31, 651–666. [Google Scholar] [CrossRef] [Scilit]
- Maronna, R. Data Clustering: Algorithms and Applications; Chapman and Hall: London, UK, 2013. [Google Scholar]
- Zhu, Y.; Ting, K.M.; Carman, M.J. Density-ratio based clustering for discovering clusters with varying densities. Pattern Recognit. 2016, 60, 983–997. [Google Scholar] [CrossRef] [Scilit]
- Rodriguez, A.; Laio, A. Clustering by fast search and find of density peaks. Science 2014, 334, 1492–1496. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Sun, H.; Song, Y.; Luo, Y.; Sun, F. A Clustering Algorithm Based on Statistical Manifold. Trans. Beijing Inst. Technol. 2021, 41, 226–230. [Google Scholar]
- Duan, X.; Ji, X.; Sun, H.; Guo, H. A non-iterative method for the difference of means on the Lie Group of symmetric positive-definite matrices. Mathematics 2022, 10, 255. [Google Scholar] [CrossRef] [Scilit]
- Hua, X.; Ono, Y.; Peng, L.; Xu, Y. Unsupervised learning discriminative MIG detectors in nonhomogeneous clutter. IEEE Trans. Commun. 2022, 70, 4107–4120. [Google Scholar] [CrossRef] [Scilit]
- Hua, X.; Ono, Y.; Peng, L.; Cheng, Y.; Wang, H. Target detection within nonhomogeneous clutter via total Bregman divergence-based matrix information geometry detectors. IEEE Trans. Image Process. 2021, 69, 4326–4340. [Google Scholar] [CrossRef] [Scilit]
- Yair, O.; Ben-Chen, M.; Talmon, R. Parallel transport on the cone manifold of SPD matrices for domain adaptation. IEEE Trans. Image Process. 2019, 67, 1797–1811. [Google Scholar] [CrossRef] [Scilit]
- Luo, G.; Wei, J.; Hu, W.; Maybank, S.J. Tangent Fisher vector on matrix manifolds for action recognition. IEEE Trans. Image Process. 2020, 29, 3052–3064. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ye, L.; Yang, Q.; Chen, Q.; Deng, W. Multidimensional joint domain localized matrix constant false alarm rate detector based on information geometry method with applications to high frequency surface wave Radar. IEEE Access 2019, 7, 28080–28088. [Google Scholar] [CrossRef] [Scilit]
- Csiszar, I. Why least squares and maximum Entropy? Ann. Stat. 1991, 19, 2032–2056. [Google Scholar] [CrossRef] [Scilit]
- Menendez, M.L.; Pardo, J.A.; Pardo, L.; Pardo, M.C. The Jensen-Shannon divergence. J. Frankl. Inst. 1997, 334, 307–318. [Google Scholar] [CrossRef] [Scilit]
- Charfi, M.; Chebbi, Z.; Moakher, M.; Vemuri, B.C. Using the Bhattacharyya mean for the filtering and clustering of positive definite matrices. In Geometric Science of Information; Springer: Berlin, Germany, 2013; pp. 551–558. [Google Scholar]
- Hua, X.; Cheng, Y.; Wang, H.; Qin, Y.; Li, Y. Geometric means and medians with applications to target detection. IET Signal Process. 2017, 11, 711–720. [Google Scholar] [CrossRef] [Scilit]
- Arsigny, V.; Fillard, P.; Pennec, X.; Ayache, N. Geometric means in a novel vector space structure on symmetric positive-definite matrices. SIAM J. Matrix Anal. Appl. 2007, 29, 328–347. [Google Scholar] [CrossRef] [Scilit]
- Amari, S. Information Geometry and Its Applications; Springer: Tokyo, Japan, 2016. [Google Scholar]
- Hua, X.; Cheng, Y.; Wang, H.; Qin, Y. Information geometry for covariance estimation in heterogeneous clutter with total Bregman divergence. Entropy 2018, 20, 258. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Hua, X.; Peng, L.; Liu, W.; Cheng, Y.; Wang, H.; Sun, H.; Wang, Z. LDA-MIG detectors for maritime targets in nonhomogeneous sea clutter. IEEE Trans. Geosci. Remote Sens. 2023, 16, 5101815. [Google Scholar] [CrossRef] [Scilit]
- Hua, X.; Cheng, Y.; Wang, H.; Qin, Y. Robust covariance estimators based on information divergences and Riemannian manifold. Entropy 2018, 20, 219. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Higham, N.J. Functions of Matrices: Theory and Computation; SIAM: Philadelphia, PA, USA, 2008. [Google Scholar]
- Moakher, M. A differential geometric approach to the geometric mean of symmetric positive-definite matrices. SIAM J. Matrix Anal. Appl. 2005, 26, 735–747. [Google Scholar] [CrossRef] [Scilit]
- Schwartzman, A. Random Ellipsoids and False Discovery Rates: Statistics for Diffusion Tensor Imaging Data. Ph.D. Thesis, Stanford University, Stanford, CA, USA, 2006. [Google Scholar]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2023 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).